Tag: AI Search

  • How to Build a Cross-Channel SEO Strategy for AI Search

    How to Build a Cross-Channel SEO Strategy for AI Search

    If your website gives one answer, a retailer gives another, and community discussions repeat an outdated claim, an AI system has no clean version of your brand to trust. You can rank well in traditional search and still be described inaccurately when an answer is assembled from several public surfaces.

    The fix is not to publish everywhere at once. Build a controlled source of truth, earn corroboration for its important claims, and use real audience conversations to expose what your internal language misses. That turns cross-channel SEO from a collection of campaigns into an operating system for AI visibility.

    Treat AI visibility as a verifiable-consensus problem

    Traditional SEO often treats the indexed page as the main unit of work. AI search expands that unit. Generated answers can be informed by websites, press coverage, retail platforms, social posts, user-generated content, YouTube and Reddit discussions. An optimized page remains important, but it cannot reliably overcome a wider ecosystem of missing, vague or contradictory information.

    This does not mean every channel needs the same copy. It means the important facts must survive every retelling. A product name, capability, limitation, use case or availability statement can be expressed differently in a product page, interview, retailer listing and community response. The underlying claim should not change unless a version, market or other stated condition explains the difference.

    A practical cross-channel model has three layers:

    • Definition: Your owned properties state what the product, service or organization is, what it does, who it serves and where its limits are.
    • Validation: Relevant external entities independently confirm the claims that matter to a buyer or evaluator.
    • Experience: Customers and communities discuss how those claims hold up in real situations, using language that may differ from your internal terminology.

    Start by creating a claim registry rather than another keyword spreadsheet. Give each important claim its own row and record:

    • The question a person would ask before needing the claim.
    • The approved factual answer, written without promotional language.
    • Any version, location, plan, customer type or other condition that changes the answer.
    • The team responsible for confirming the fact.
    • The primary page where the fact should be explained.
    • The retailer listings, profiles, media materials and other external surfaces that repeat it.
    • The event that should trigger a review, such as a product, policy, price or availability change.

    This registry separates three problems that teams often mix together. A missing fact is a content problem. A hard-to-extract fact is a structural problem. A conflicting fact is a governance problem. Publishing more content only solves the first one.

    Key takeaways

    • Make your owned website the clearest and most current expression of each priority claim.
    • Pursue relevant third-party corroboration, not backlink volume without context.
    • Keep facts consistent across channels while adapting the format and language to each audience.
    • Use community discussions to find unanswered questions and weak brand associations, not to manufacture praise.
    • Give one SEO lead authority to route evidence, resolve conflicts and decide which layer needs work next.

    Phase 1: Make owned pages the cleanest truth source
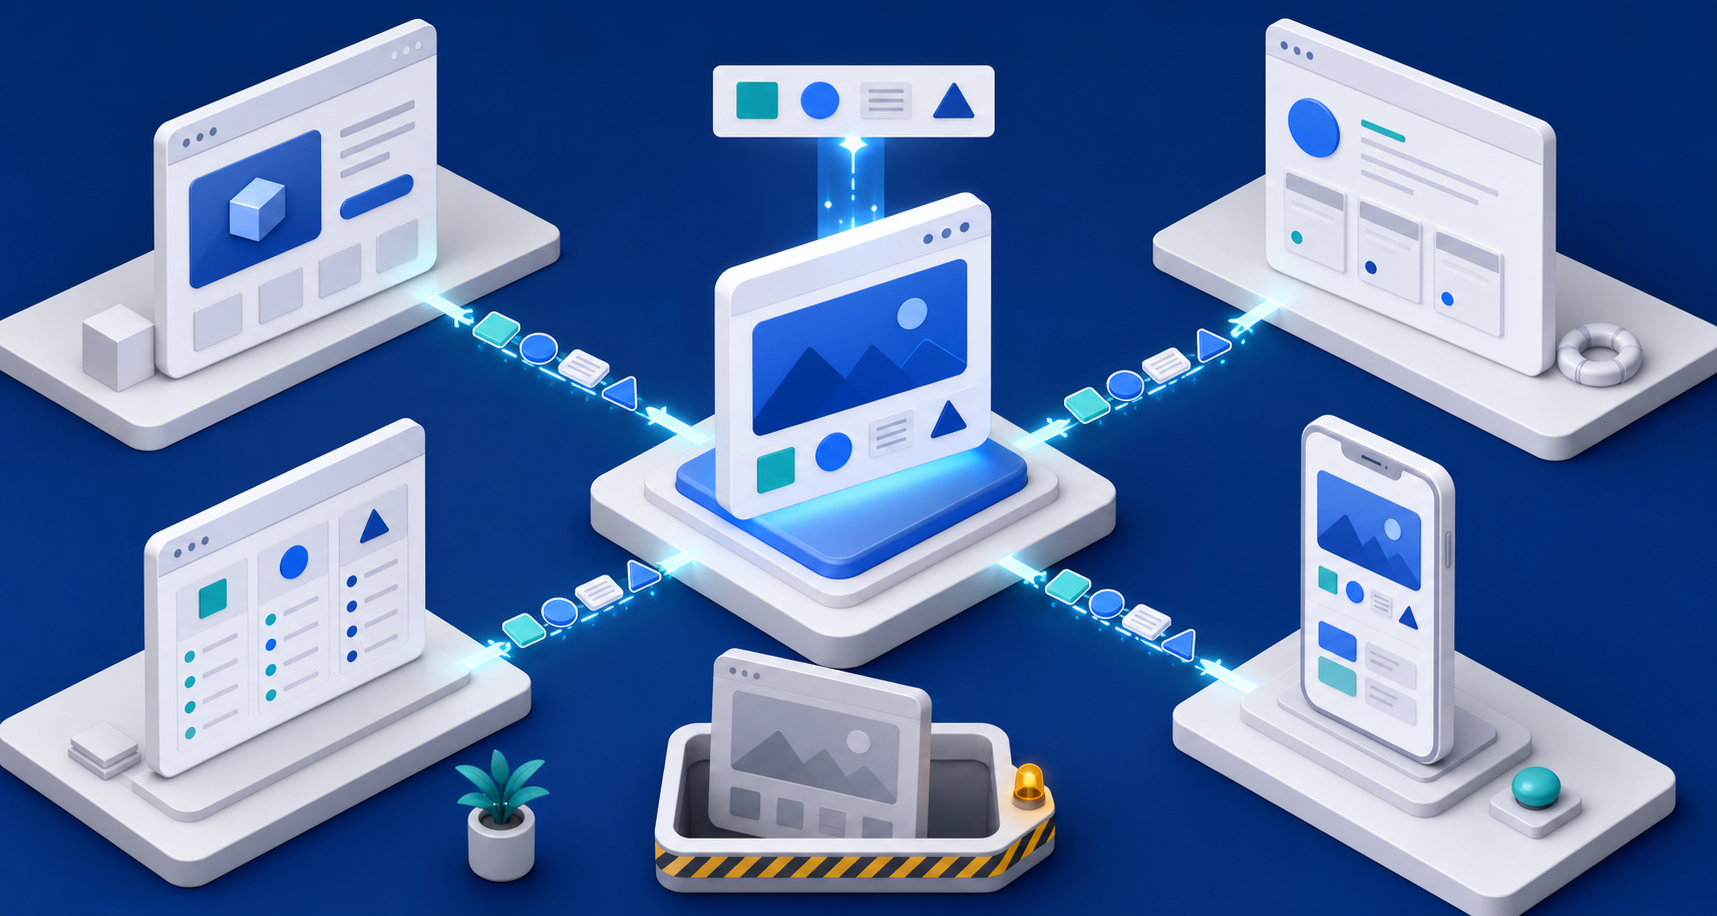
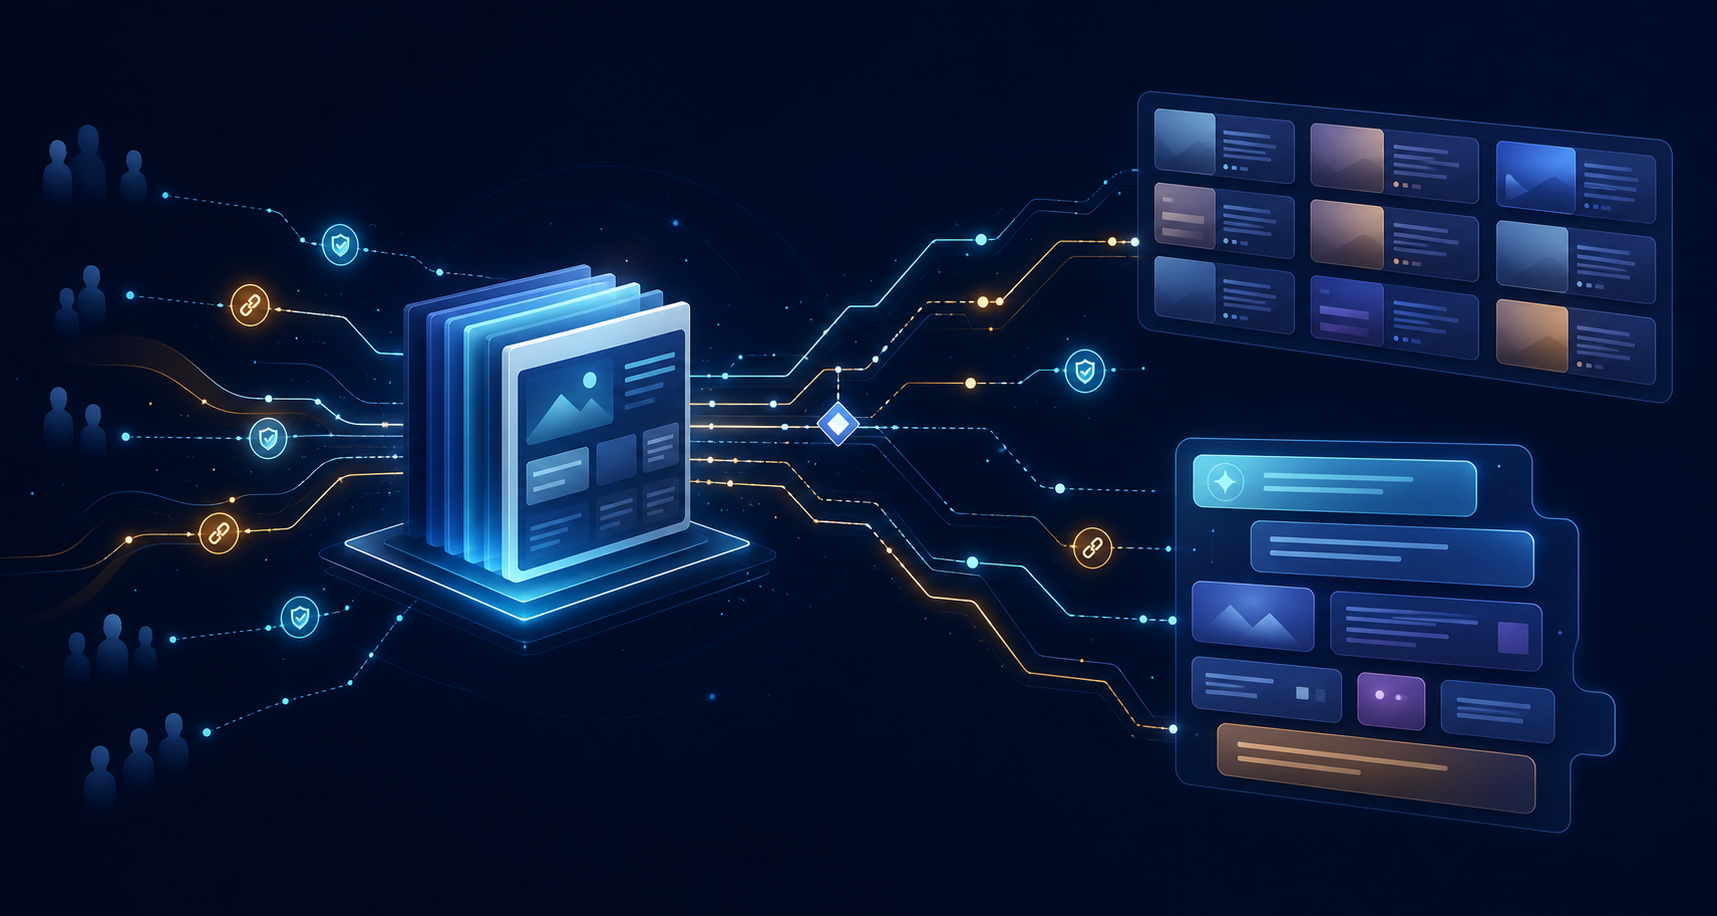
    A central information module distributes matching visual tokens to organized desktop and mobile page components, with an obsolete module set aside.

    Begin with the surfaces you control. Before you try to influence how an AI system describes your brand, make sure it can find an unambiguous answer on your site. The work shifts from optimizing only for search terms toward presenting facts in a form machines can extract accurately.

    The first input should come from customer-facing reality. Ask sales, support and product teams which questions recur, which capabilities prospects misunderstand and which details customers discover too late. Search demand can tell you that a topic matters. These teams can tell you what a useful answer must contain.

    Turn that input into an owned-content workflow:

    1. Collect the actual questions. Preserve the audience’s wording, including comparisons, constraints and use-case language. Do not translate everything into internal product vocabulary before the content team sees it.
    2. Assign each question to one primary page. A reader and a machine should not have to reconcile several pages to determine the basic answer. Supporting pages can add context, but one page should carry the complete claim.
    3. State the answer explicitly. Name the relevant entity, capability and condition in the same passage. Replace phrases such as “flexible options are available” with the options, eligibility rules or limitations you can actually substantiate.
    4. Structure the supporting detail. Use descriptive headings, direct explanatory paragraphs, lists for genuine sets of items and tables for attributes that readers need to compare. Keep labels stable when the same concept appears on several pages.
    5. Match structured data to visible content. Schema and JSON-LD should represent facts a reader can verify on the page. Markup is another machine-readable expression of the page, not a place to introduce a stronger or different claim.
    6. Install a change path. When the underlying product fact changes, the owner should know which page, markup, feed, retailer record and communications material must be reviewed.

    A useful answer pattern is simple: identify the thing, answer the question, qualify the answer, and show the evidence or detail needed to interpret it. For example, a capability section can follow this template: “[Product] supports [named capability] for [applicable users or plans]. It works through [relevant method]. It does not include [important limitation].” The brackets must be replaced with approved facts, not broad marketing language.

    Do not confuse extractability with brevity. A one-sentence answer can establish the fact, while the surrounding page explains selection criteria, exceptions, setup or consequences. The goal is to make the core answer easy to lift without stripping away a condition that changes its meaning.

    Phase 1 is ready to support wider distribution when:

    • Every priority question has an approved answer and a responsible subject-matter owner.
    • Each answer has a clear primary location on the site.
    • Visible copy, structured data and first-party product feeds agree.
    • Important qualifications are written beside the claim rather than buried on an unrelated page.
    • Teams can identify which records must change when the fact changes.

    If those conditions are not met, external promotion will distribute ambiguity. Fixing the owned layer first gives every other team something dependable to reference.

    Phase 2: Turn external coverage into factual corroboration

    Once your owned facts are stable, identify where an external voice would make them more credible or discoverable. AI search can validate information across the public web, and independent mentions may carry more weight than a brand repeating its own narrative. That changes the purpose of outreach: you are not merely acquiring links; you are building a coherent body of relevant corroboration.

    Plan earned visibility claim by claim. For each one, decide:

    • What needs validation: a capability, use case, category association, product detail or other approved fact.
    • Who needs the answer: the audience and decision context in which the claim matters.
    • Which external surface fits: specialist media, a retailer page, an affiliate resource, a video, an expert contribution or another relevant entity.
    • What can be substantiated: the product detail, demonstration, documentation, customer evidence or subject-matter access available to support the claim.
    • Where the complete answer lives: the owned page external coverage should be able to verify.
    • Who maintains consistency: the person responsible for checking published details and resolving conflicts.

    This is a better filter than a domain list sorted only by link metrics. A citation is useful when the external entity is relevant to the subject, the context supports the intended association, and the claim remains understandable. A passing brand mention on an unrelated page may add little. A detailed, accurate reference in the right niche can help both a potential customer and a system trying to validate the answer.

    PR should operate as a continuing narrative function rather than a sequence of disconnected launches. A single approved theme can support a media pitch, expert commentary, a video brief, organic social material and updates to partner resources. Reuse the factual core, but adapt the treatment to the channel. Identical copy is not required; factual agreement is.

    Commerce pages deserve the same attention as editorial coverage. Retailer product detail pages can act as external verification points for specifications, availability and product positioning. Audit them against the claim registry. If a marketplace lists an old attribute or uses a name that no longer matches the site, decide whether the difference reflects a legitimate version or market. If it does, label that condition. If it does not, correct the conflicting record rather than publishing another page that adds a third answer.

    Give communications teams a compact evidence package for every priority narrative:

    • The exact claim and its important qualifications.
    • The audience question it answers.
    • The primary owned URL containing the full explanation.
    • The approved product details or evidence that support it.
    • The terms that must remain consistent across coverage.
    • The likely objection or misunderstanding the content should address.
    • The person who can approve a factual correction.

    This keeps creative work flexible without allowing the facts to drift. It also makes monitoring actionable. When a mention is incomplete, classify the gap: wrong fact, missing qualification, weak context, outdated terminology or no link to a complete answer. Each class points to a different correction.

    Phase 2 is working when relevant external entities repeat the same factual core, retailer records agree with first-party product data, and PR themes build on one another instead of resetting with each campaign. The aim is not artificial uniformity. It is enough independent agreement that an evaluator can determine what is true without guessing.

    Phase 3: Use community signals without manufacturing them

    Owned pages explain your position. Earned coverage adds independent context. Community material reveals whether people use, understand or challenge the same narrative. AI systems can draw on Reddit, YouTube, review sites and niche communities when interpreting public preferences and perceptions, so recurring questions in those spaces belong in your search intelligence.

    Treat community work as listening and service, not a placement exercise. Fabricated praise, undisclosed promotion and scripted imitation of customer language can damage trust. They also produce poor strategic data because the team ends up measuring its own intervention instead of learning what customers actually think.

    Build a community insight log around observable conversations. Capture:

    • The question or comparison being discussed.
    • The exact words people use for the need, product category and desired outcome.
    • The answer receiving support and the reason participants find it credible.
    • The misconception, missing fact or negative experience behind disagreement.
    • Whether your owned content already resolves the issue.
    • The team that can act: product, content, support, PR, commerce, paid media or community management.

    Keep facts and sentiment separate. “This plan includes a feature” is a claim that can be verified. “This option feels easier” is a preference that depends on the user and context. Both are useful, but they should not be processed as the same kind of evidence. The first may require a factual correction; the second may reveal an audience association you need to understand.

    When participation is appropriate, answer the question in the community’s own context. Disclose the brand relationship, correct factual errors without attacking the person, and link to your site only when the destination materially helps. A clear limitation can be more useful than a promotional response because it prevents the wrong buyer from carrying an inaccurate expectation forward.

    Community insight should also inform paid and partner channels. Repeated audience language can become an ad-copy hypothesis. A persistent objection can shape a landing-page test. A misunderstood distinction can be added to an influencer brief or affiliate resource. These channels can expand and test a message, but their performance does not prove that the underlying product claim is true. Keep the approved claim registry as the factual control.

    Use a closed loop rather than a listening report that disappears into a folder:

    1. Capture a recurring question, association or misunderstanding.
    2. Classify it as a factual gap, language gap, experience issue or product issue.
    3. Route it to the team that can resolve the cause.
    4. Update the owned answer when the public information is incomplete.
    5. Brief PR, commerce, social, affiliate and paid teams on the corrected narrative.
    6. Return to the relevant community only when you can add a transparent, useful answer.

    Phase 3 is mature when community managers can trace repeated questions to content or product decisions, paid teams test language drawn from genuine demand, and partners receive the same factual guardrails as internal teams. The output is not a larger volume of brand posts. It is a more accurate understanding of how people describe and evaluate the brand.

    Run SEO as the cross-channel decision function
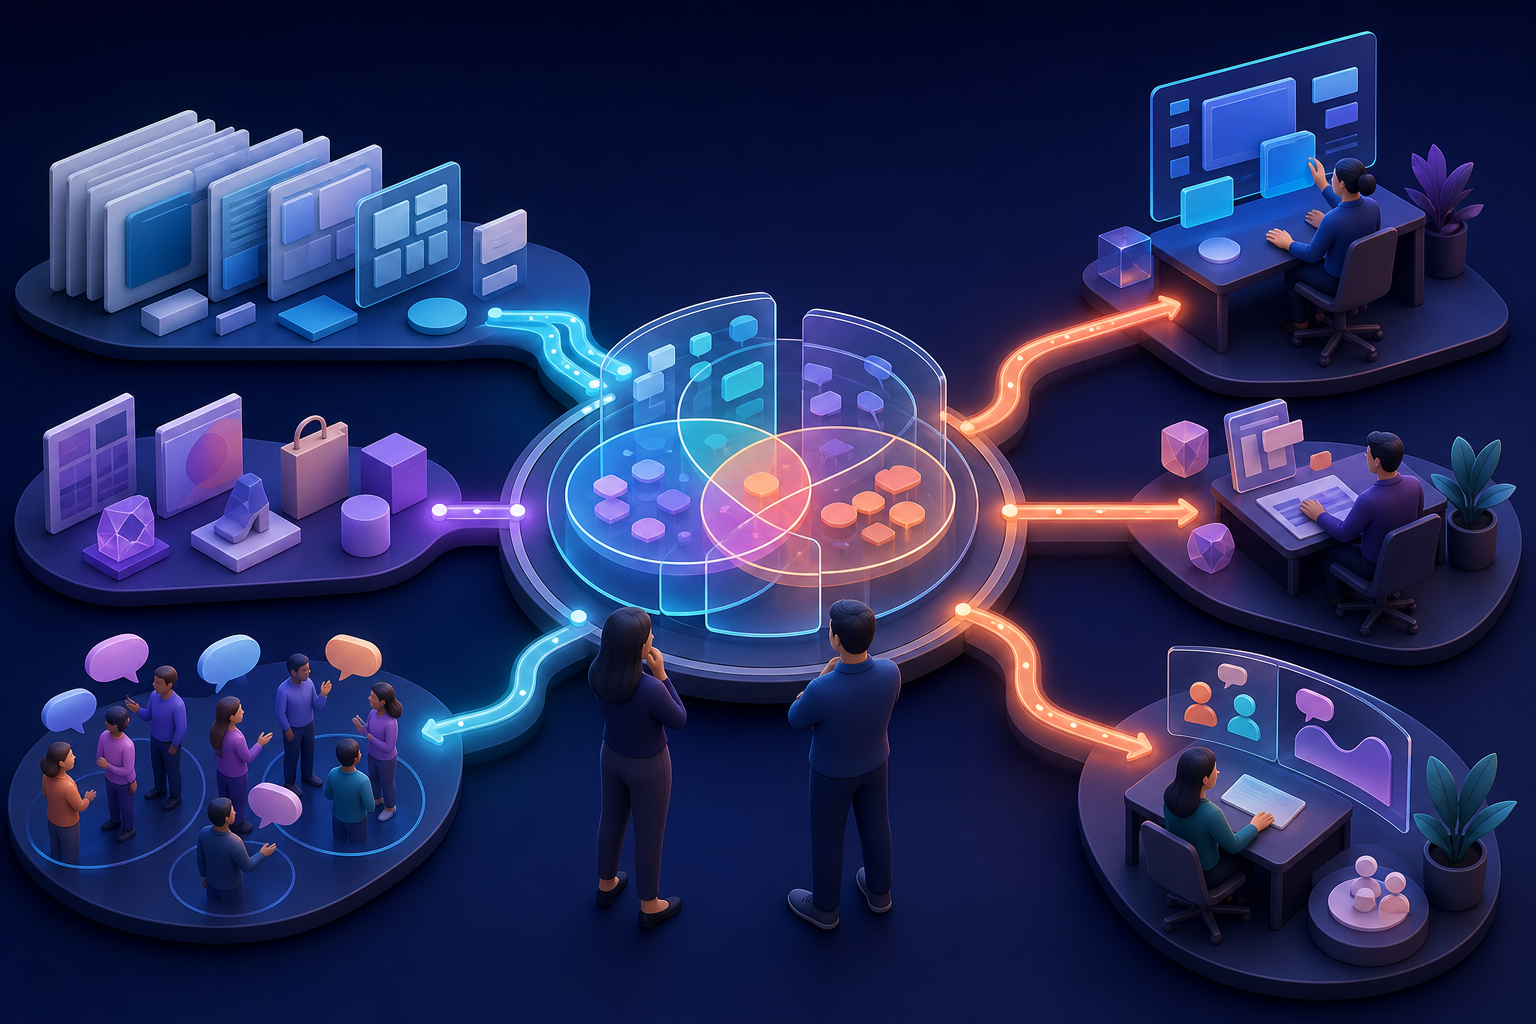
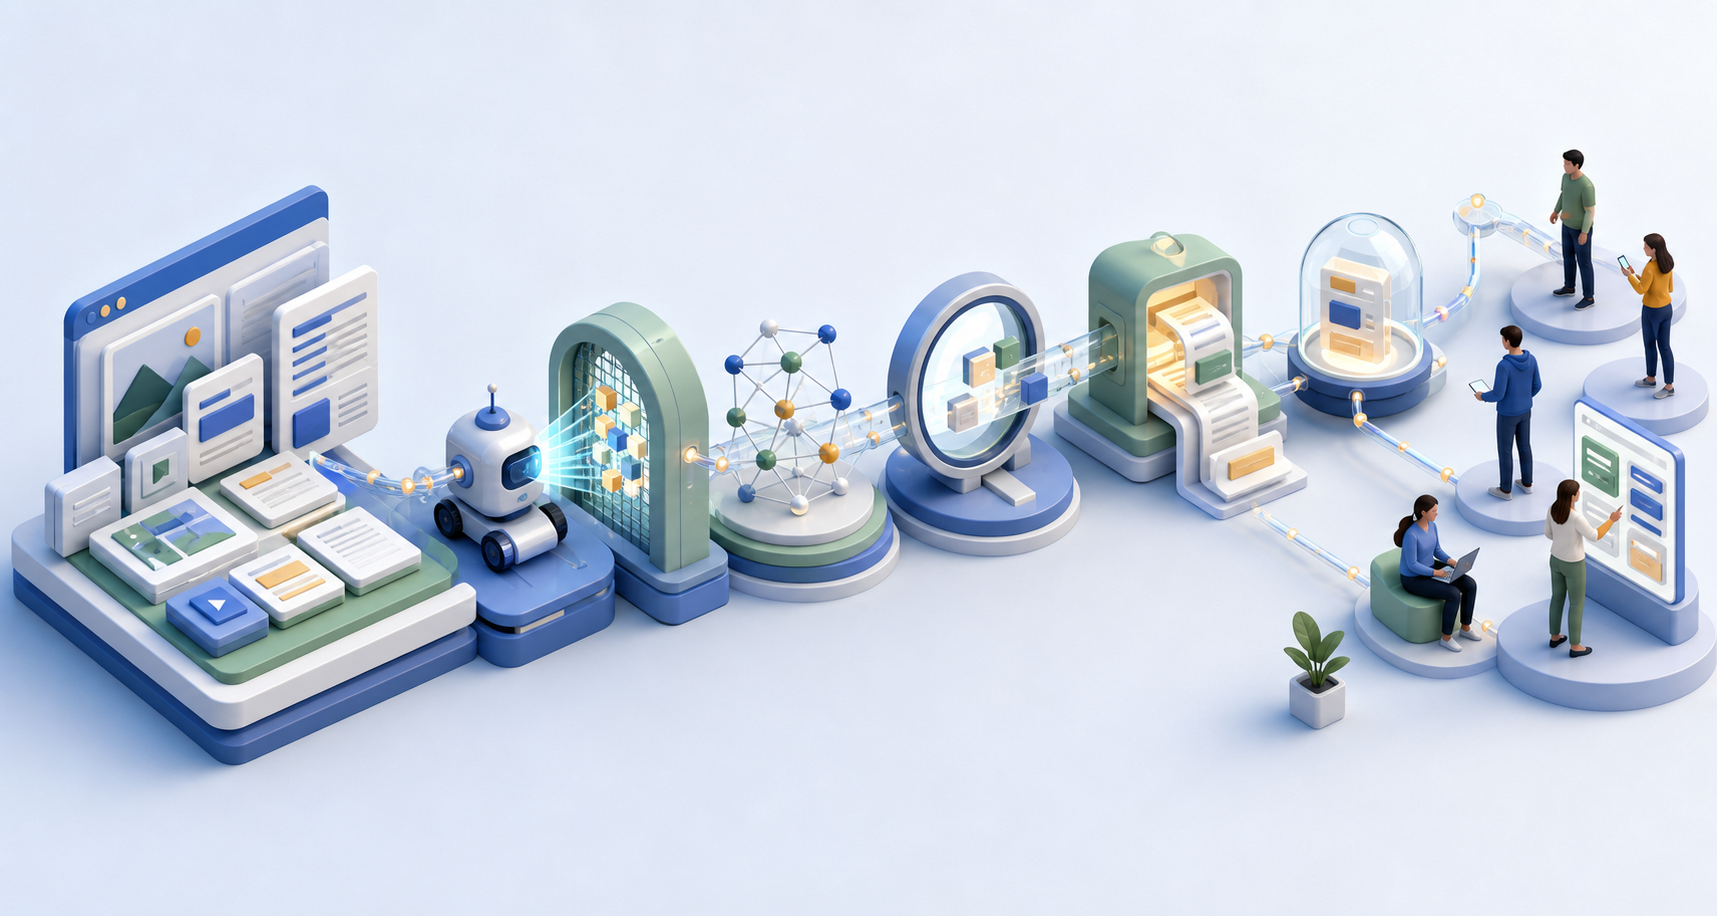
    Owned-page modules, media artifacts, and community conversations flow into a central decision mechanism watched by two strategists, then branch toward three workstations.

    Cross-channel execution fails when SEO can identify a problem but cannot convene the teams that own its cause. The SEO lead needs a meaningful seat in strategy, with responsibility for routing search intelligence, setting priorities and coordinating the AI search operating system. That person is a decision owner, not an approval bottleneck for every sentence.

    A dedicated internal lead is a practical default because product knowledge, organizational context and internal relationships matter. An agency can add outside pattern recognition, specialist execution and additional capacity, but it should strengthen a named internal owner rather than leave the operating model ownerless.

    The exchange between teams should be explicit:

    TeamInput to the SEO leadWhat it receivesShared decision
    ContentSubject expertise, editorial judgment and creation capacityAudience questions, optimization requirements and performance gapsWhich owned answer needs to be created or improved
    PR and communicationsBrand messaging, media relationships and outreachSearch trends, mention gaps and authority targetsWhich claim needs independent corroboration
    Commerce and marketplacesProduct records, reseller feedback and purchase-stage questionsProduct-page requirements and identified inconsistenciesWhich external listings need correction or expansion
    Social and communityAudience language, engagement patterns and recurring concernsPriority themes, factual references and response contextWhich conversation requires listening, content or participation
    Web developmentTechnical infrastructure, templates and site constraintsImplementation priorities and extraction requirementsWhich structural change removes the largest information gap
    Creative and paid mediaVisual assets, campaign feedback and message-test resultsAudience themes, factual guardrails and landing-page prioritiesWhich message should be expressed or tested next

    Give the group one decision log. For each issue, record the affected claim, evidence, conflicting surfaces, owner, chosen action and review trigger. This prevents a correction from being trapped in an SEO ticket while retailer copy, media briefs and social responses remain unchanged.

    Measure the failure mode, not just visibility

    A single AI visibility score may tell you that something changed, but it cannot tell you what to fix. Use a diagnostic scorecard tied to the three phases:

    • Answer accuracy: For a stable set of priority questions, record the generated answer, the cited or surfaced URLs and the exact factual error or omission. Keep the platform, query wording and observation context with the record because generated responses can vary.
    • Owned fact coverage: Check whether each priority claim has a complete primary page, an approved owner and machine-readable markup where appropriate.
    • Cross-channel agreement: Compare the primary page with important retailer listings, profiles, media materials and partner pages. Classify differences as valid conditions, stale records or true contradictions.
    • Relevant authority coverage: Track which priority claims receive substantive mentions from entities that matter in the niche. Do not reduce this to a raw backlink count.
    • Community question closure: Track whether recurring questions lead to an answer, content change, product escalation or documented decision. Engagement alone does not show that the information problem was solved.
    • Business relevance: Connect the monitored questions to the pages and actions that matter to the audience. Visibility for an irrelevant association is not a successful outcome.

    The scorecard should tell you which phase deserves the next unit of effort:

    • If the generated answer is factually wrong and your site is also unclear, return to Phase 1.
    • If your site is explicit but the claim lacks credible external support, prioritize Phase 2.
    • If the facts are correct but the language or preferences in the answer do not reflect customer reality, investigate Phase 3.
    • If channels contradict one another, pause broader distribution and resolve ownership before adding more campaigns.
    • If visibility improves without helping the intended audience act, revisit the question set, landing experience and business relevance rather than chasing more mentions.

    Start with one decision area, not the whole brand

    You do not need an immediate company-wide reorganization. Choose one product, service or decision area with meaningful demand and visible information gaps. Build its claim registry, assign its primary pages, compare its most important external records, and inspect how people discuss it in relevant communities. That contained scope will expose the handoffs your operating model needs without turning the first attempt into an inventory of the entire internet.

    At your next planning meeting, bring one disputed or under-supported claim instead of a generic request for more AI content. Decide who owns the fact, where its complete answer belongs, which independent entities could validate it, and which audience conversations can test your understanding. Once that path works, apply it to the next decision area. Cross-channel AI search strategy becomes manageable when each expansion begins with a verified claim, not another channel calendar.
    References

  • AI Search Marketing Optimization: A Practical Operating System

    AI Search Marketing Optimization: A Practical Operating System

    Your page can hold a respectable organic position and still disappear inside an AI-generated answer. It can also earn a citation that sends no qualified business your way. Visibility, attribution, and commercial value are related, but they are not the same result.

    Effective AI search marketing optimization connects those results. You make the right page discoverable, turn it into a clear and defensible answer, give machines enough context to interpret it correctly, and measure whether that visibility influences a useful decision.

    Start with the decision you want to influence

    Do not begin with a tool, a prompt-tracking dashboard, or a vague goal to appear in more AI answers. Begin with the decision your audience is trying to make and the page that should help them make it. Testing tools without a defined purpose creates activity, but it does not tell you whether the work improved pipeline, retention, sales, or another business outcome.

    Traditional SEO and Generative Engine Optimization, or GEO, overlap, but they emphasize different outcomes. SEO helps a page become discoverable in search results. GEO extends the job to selection, citation, and accurate representation inside generated answers. You need both. A page that cannot be found is unlikely to be used, while a discoverable page with an ambiguous answer gives an AI system little reason to rely on it.

    Plan the work around three gates:

    • Discovery: Can search and AI systems crawl, index, retrieve, and associate the page with the question?
    • Selection: Does the page contain a direct answer, credible evidence, clear entities, and useful context?
    • Action: If a person reaches the page, is the next step relevant to the question that brought them there?

    A weakness at any gate limits the value of the other two. More schema will not fix an inaccessible page. Better rankings will not rescue an evasive answer. More citations will not create revenue if the cited page addresses an informational query but pushes an unrelated sales action.

    Build a query-to-page map before editing content

    1. Name the business outcome. Choose a concrete result such as a qualified inquiry, product evaluation, account creation, purchase, or successful implementation.
    2. Identify the decision stage. Decide whether the reader is defining a problem, comparing approaches, checking risk, validating a provider, or preparing to act.
    3. Write the question in the reader’s language. Use a complete question, not a two-word keyword. Record important constraints such as audience, use case, platform, location, or product category.
    4. Assign a primary answer page. Avoid making several pages compete to answer the same question. Create a separate page only when the intent, answer, or required evidence changes materially.
    5. Specify the proof. Record what will substantiate the answer: original data, a primary reference, product documentation, a transparent method, an expert byline, or a concrete example.
    6. Choose the next action. Match it to the reader’s stage. Someone defining a problem may need a diagnostic or related explanation; someone comparing options may need requirements, limitations, or implementation details.

    The resulting brief should identify the audience, decision, question set, direct answer, evidence, important entities, intended action, and success signal. This prevents a common failure mode: optimizing a page for a phrase without deciding what useful role the page is supposed to play.

    Turn each important page into a set of answer units

    A page-shaped slab separates into modular content cards that assemble into a compact answer object.

    An answer unit is a self-contained section that resolves one meaningful question. It is not a fragment written for a robot. It is a compact piece of useful reasoning that still makes sense if an AI system extracts it from the surrounding page.

    Build each answer unit in this order:

    • A descriptive heading: State the question or decision plainly instead of inserting a vague keyword label.
    • A direct opening answer: Give the conclusion before background, brand positioning, or a long definition.
    • The mechanism: Explain why the answer holds and what causes the result.
    • The evidence: Support factual claims with current, authoritative material or clearly described original evidence.
    • The boundary: State when the answer changes, what it does not cover, and which tradeoffs matter.
    • The next step: Tell the reader what to check, change, compare, or measure.

    For example, a section titled What is AI search marketing optimization? should not open with a history of search. It can answer directly: AI search marketing optimization combines technical discoverability, answer-focused content, entity clarity, supporting evidence, and performance measurement so a brand can be found and represented accurately in generated search experiences. The following paragraphs can then distinguish SEO, AEO, and GEO, explain their overlap, and show the reader what to implement.

    Use the extraction test when editing. Read the opening answer without its heading or previous paragraph. If words such as it, this, or they make the subject unclear, name the subject again. If the answer requires several paragraphs of setup, move the conclusion forward. If it makes an absolute claim but the explanation later introduces exceptions, put the most important qualifier in the answer itself.

    Clear headings, front-loaded answers, lists, tables, authoritative support, and plain language make information easier to parse and reuse. Apply each format according to its job. Use prose for reasoning, a list for a sequence or criteria, and a table only when a reader needs to compare repeated fields across several options.

    Do not turn every page into a wall of shallow questions. Keep related questions together when they support one decision. Split a section only when the reader would reasonably search for the answer on its own or when the answer needs distinct evidence. A coherent page provides context that isolated snippets cannot.

    Make evidence, entities, and schema tell the same story

    Readable formatting cannot compensate for unsupported claims. Before adding structured data, strengthen the page as a source. Give every important factual claim evidence that is appropriate to its weight. Explain the method behind original data. Link to primary authorities when they are available. Identify the author and relevant credentials. Remove or revise statistics that can no longer be verified.

    Entity clarity matters as much as sentence clarity. A company name, product name, author, service, location, and category should not change casually between the page copy, metadata, structured data, author profile, and other first-party pages. When several names are genuinely necessary, explain their relationship instead of expecting a machine to infer it.

    Schema markup can express those relationships in a machine-readable form. It is an interpretation aid, not a citation switch. Use a type because it truthfully describes the visible page, not because the type appears on an optimization checklist.

    Primary page jobPotential schema typeWhat the visible page must support
    Publish an editorial explanationArticleHeadline, author, publication details, dates, and the article body
    Answer recurring questionsFAQPageThe same questions and answers displayed to readers
    Teach a procedureHowToThe ordered steps, requirements, and relevant outcomes
    Establish organizational identityOrganizationConsistent name, URL, logo, and organizational details
    Describe a productProductAccurate product information that is also visible on the page

    Article, FAQ, HowTo, Organization, and Product markup can help machines interpret the purpose and structure of suitable pages. The markup still has to agree with the content. FAQPage markup attached to invisible answers, Product properties that contradict the offer, or an author entity with inconsistent names creates ambiguity instead of resolving it.

    Use this structured-data review before publishing

    • Choose the schema type that matches the page’s main visible purpose.
    • Include only properties that you can support with accurate, accessible information.
    • Use consistent names and identifiers for the page, author, publisher, organization, and product.
    • Make dates, prices, availability, steps, and other changeable details agree with the visible content.
    • Validate the JSON-LD syntax and review the meaning of the output, not just whether the validator reports an error.
    • Update structured data whenever the corresponding page content changes.

    Treat the content and JSON-LD as two expressions of one claim. If your team cannot agree on what the page is about, who created it, or what entity it describes, schema will encode the disagreement rather than solve it.

    Measure citations without losing sight of business value

    Two measured pathways lead from a generated answer to source-reference tokens and to a qualified business outcome.

    Ranking reports alone cannot show whether an AI system names, cites, or accurately describes your brand. At the same time, a citation count cannot tell you whether the underlying questions matter commercially. Your scorecard needs visibility, representation, and outcome metrics.

    Competition for a citation can be tight because generated answers may use only two to seven cited sources on average. That makes the denominator important. Ten citations mean little without knowing the number and value of the prompts tested.

    Create a repeatable prompt panel

    1. Select prompts from the query-to-page map rather than inventing a disconnected list for the tracking tool.
    2. Record the AI product, exact prompt, relevant market or account context, and test date.
    3. Capture the generated answer and its cited links. Do not record only a yes-or-no visibility score.
    4. Label each result separately as a brand mention, linked citation, recommendation, comparison inclusion, or no appearance.
    5. Judge whether the answer attributes facts correctly and represents the brand, product, and limitations accurately.
    6. Annotate content, schema, technical, and distribution changes so movement can be connected to a plausible intervention.
    7. Repeat comparable observations before treating movement as a trend. A single generated response is an observation, not a stable performance conclusion.

    Use that panel to calculate metrics with clear definitions:

    • Answer presence: The share of tracked prompts in which the brand or domain appears.
    • Citation rate: The share of tracked prompts that include a link to your domain.
    • Citation share: Your cited appearances compared with the cited appearances of the competitors in the same panel.
    • Attribution accuracy: The share of appearances that assign claims, products, capabilities, and limitations correctly.
    • Qualified engagement: The behavior of detectable AI referrals on the destination page, interpreted in the context of the query.
    • Business contribution: Leads, purchases, assisted conversions, pipeline, retention, or another outcome chosen before optimization begins.

    Not every AI-influenced visit will arrive through an easily labeled referral. A person may read an answer and return later through branded search or a direct visit. Treat observable referrals as one signal, preserve campaign and conversion tracking where possible, and avoid claiming attribution that the data cannot support.

    Measurement should stay connected to genuine business goals. Set diagnostic rules before you review a test. If citations rise but qualified engagement does not, inspect query relevance, the destination page, and the next action. If mentions rise while accuracy falls, repair explicit facts and entity consistency. If visibility remains absent, check crawlability, indexing, topical coverage, evidence, and the strength of competing answers before rewriting everything.

    Keep AI automation inside accountable guardrails

    AI can accelerate query clustering, outlining, extraction, schema drafting, content review, and monitoring summaries. It can also reproduce an incorrect premise across many pages faster than a manual workflow. Scale the review system with the production system.

    Assign each automated task a risk level. Internal ideation and formatting are usually easier to reverse. Public factual claims, structured data, live publishing, customer information, and campaign spending deserve tighter controls because an error can affect trust, privacy, visibility, or money.

    Before automating a workflow, document:

    • The owner: One person or role remains accountable for the released result.
    • The permitted inputs: Specify which documents and data the system may use, including information that must never enter the workflow.
    • The success condition: Name the business or quality improvement the automation is expected to produce.
    • The failure condition: Define what would stop publication or trigger a rollback, such as an unsupported claim, conflicting schema, privacy exposure, or a material brand error.
    • The review point: Identify where a qualified person checks facts, meaning, brand fit, ethics, and technical validity.
    • The recovery path: Preserve versions and know how to remove or replace a faulty output.

    Accountability remains with the marketer and organization, even when a model produced the draft or a platform executed the change. Governance is therefore part of search optimization, not a separate administrative concern. The person responsible for performance should participate in decisions about data use, approvals, brand safety, and monitoring.

    Key takeaways

    • Optimize for a specific audience decision and assign one primary page to answer it.
    • Write self-contained answer units that lead with the conclusion, explain the mechanism, show evidence, and state important limits.
    • Use structured data only when it accurately mirrors visible content and stable entity relationships.
    • Track mentions, citations, citation share, attribution accuracy, qualified engagement, and business contribution separately.
    • Benchmark a fixed prompt panel before changing a page so later observations have a meaningful comparison point.
    • Give every AI-assisted workflow an owner, permitted inputs, review point, failure condition, and recovery path.

    Start with one page tied to qualified demand. Build its query brief, rewrite its highest-value answer sections, align the evidence and JSON-LD, and benchmark the relevant prompts before publishing the change. That gives you a controlled learning loop you can improve and repeat, rather than a collection of disconnected AI tactics.

    References

  • How to Protect Brand Visibility in Google AI Search

    How to Protect Brand Visibility in Google AI Search

    You search your brand in Google and the AI-generated answer sounds confident, polished, and wrong. An old complaint has become a present-tense fact. A forum opinion outweighs your published policy. Or your brand is visible, but the answer frames it in a way no conventional ranking report would reveal.

    You cannot solve that problem by publishing more generic brand content. You need to identify the exact claim Google is repeating, trace the information environment behind it, correct the weakest evidence, and make the current facts easier to retrieve and interpret. This gives you a practical way to do that.

    Separate visibility from accurate representation

    A brightly lit geometric object appears distorted in one mirror and accurately reflected in another.

    A high organic ranking tells you that a page can be found. It does not tell you whether Google will use that page in an AI answer, whether the answer will cite it, or whether the resulting description will represent your brand accurately.

    That distinction matters because Google AI Overviews can draw information from conversational platforms such as Reddit and Quora. In some cases, old or inaccurate discussions can be resurfaced without enough context. An anecdote may then sit beside an official statement without a clear distinction between personal experience, verified fact, and current policy.

    This creates three separate jobs for your team:

    JobQuestion it answersWhat to inspect
    DiscoverabilityCan Google find and understand your material?Indexable pages, internal links, crawl access, page purpose, and entity naming
    InclusionDoes your material influence the AI answer?Citations, linked pages, quoted facts, and competing domains
    RepresentationIs the answer accurate, current, and properly qualified?Individual claims, dates, scope, omitted context, and opinion presented as fact

    Do not combine these into one visibility score. A brand can rank well but be represented poorly. It can also be described accurately without receiving a citation. Each condition requires a different response.

    Key takeaways

    • Audit what Google says about your brand, not only where your pages rank.
    • Break an AI answer into individual claims before deciding how to respond.
    • Correct factual errors at the pages and platforms that support them; publishing an unrelated positive story will not repair the evidence chain.
    • Make official facts explicit, dated, scoped, and consistent across visible copy and structured data.
    • Treat legitimate criticism differently from false or outdated claims. Reputation management should improve accuracy, not erase disagreement.

    Audit the questions that can change a decision

    Searching only your brand name produces an incomplete audit. People encounter reputation problems through questions about trust, policies, products, comparisons, and specific incidents. Build your query set around those decisions.

    Start with query families such as:

    • Identity: what is the brand, who owns it, where does it operate, and which similarly named entity is it?
    • Trust: is the brand legitimate, reliable, safe, or suitable for a particular use?
    • Customer experience: what problems do customers report, and how does support handle them?
    • Policies: what are the refund, cancellation, warranty, privacy, or eligibility terms?
    • Products and services: what does an offering include, exclude, cost, or require?
    • Comparisons: how does the brand differ from a named alternative, and what tradeoffs matter?
    • Events: what happened during a controversy, outage, recall, policy change, or other decision-relevant development?

    Add the language customers actually use. Support tickets, sales objections, review themes, branded search terms, and community discussions can expose questions that your marketing navigation does not. The goal is not to generate every conceivable prompt. It is to cover the questions where a wrong answer could change trust or action.

    For each query, use the following workflow:

    1. Save the query exactly as entered. Small wording changes can turn a factual lookup into a request for opinions.
    2. Capture the complete AI answer, its visible citations, linked pages, and any language expressing uncertainty.
    3. Record the date, location context, account state, device context, and other setup details needed to repeat the check.
    4. Split the answer into atomic claims. A statement about poor support, for example, might contain separate claims about response availability, refund handling, complaint volume, and current policy.
    5. Label each claim as accurate, incomplete, outdated, unsupported, subjective, or attached to the wrong entity.
    6. Map the page or discussion that appears to support each problematic claim. If no visible citation supports it, record that rather than guessing.
    7. Assign a correction owner and a verification step. Ownership may sit with content, SEO, public relations, customer support, product, or legal review depending on the claim.

    Prioritize consequence before sentiment. A mildly negative opinion is usually less urgent than a false statement about eligibility, pricing, safety, availability, contractual terms, or the identity of the company. An error that could cause a customer to take the wrong action should move ahead of a complaint that is unpleasant but clearly framed as opinion.

    Also check whether the claim is reproducible. One captured answer is evidence of an occurrence, not proof that every searcher sees the same thing. Use a documented setup and repeat the important query variants before estimating the size of the problem.

    Repair the evidence chain, not just your homepage

    Blank source documents and archive objects connect to a clear sphere through an evidence chain with one broken link being repaired.

    When a misleading answer cites a community thread, rewriting your homepage may have little effect on that specific claim. The correction needs to reach the part of the information environment that is unclear, stale, or unsupported.

    Choose the response according to the type of problem:

    • Factual error: publish the correct fact on the most relevant official page and provide the primary evidence that supports it. If a third-party page contains the error, send its owner the exact sentence, correction, evidence URL, and applicable date.
    • Outdated fact: state what changed, when the current position took effect, which products or regions it covers, and whether the old condition still applies anywhere.
    • Missing qualification: add the condition that changes the meaning. A policy may depend on product type, purchase channel, location, account status, or another clearly defined circumstance.
    • Identity collision: use the full entity name, location, legal or trading relationship, and distinguishing details consistently. Create an explicit clarification page if people regularly confuse separate organizations.
    • Legitimate complaint: acknowledge the underlying experience and explain the current resolution path. Do not relabel a genuine customer opinion as misinformation merely because it is unfavorable.
    • Unsupported generalization: answer with bounded language and checkable facts. A handful of complaints does not establish a universal condition, but a vague assurance that customers are happy does not rebut it either.
    • Operational failure: fix the underlying process. Content cannot permanently compensate for a policy or customer experience that continues to generate the same criticism.

    A useful correction packet is short and specific. It should contain the disputed claim, the corrected wording, the evidence, the effective date, the affected product or market, and a contact who can answer verification questions. This format gives editors, community moderators, partners, and internal teams something they can act on without reconstructing the issue themselves.

    When you respond in a forum, write for the later reader as much as the current participant. Identify your relationship to the brand, answer the factual point directly, link to the relevant evidence, and stop once the correction is clear. Arguing through every comment can make the factual answer harder to find. Fabricated endorsements and undisclosed brand advocacy are not correction strategies.

    Do not create a public rebuttal page for every fringe remark. Repeating an obscure accusation on an authoritative brand domain may give it a clearer association with your entity. A dedicated response becomes more reasonable when the claim is already discoverable, affects a real decision, and requires context that cannot fit on an existing policy, product, or company page.

    Publish facts that machines cannot easily misread

    AI-readable content is not content written in a robotic style. It is content in which the subject, claim, scope, date, and evidence are difficult to confuse.

    For every brand fact that affects a decision, inspect the page that is supposed to establish it:

    • Answer the central question near the beginning. Do not bury the current policy below a long brand narrative.
    • Name the entity and offering explicitly. Pronouns and internal product nicknames can create ambiguity when a passage is read outside the page.
    • State scope beside the claim. If a term applies only to a region, plan, product version, or purchase channel, put that condition in the same passage.
    • Show the effective or reviewed date where freshness changes the meaning. A generic site copyright date does not establish when a policy was checked.
    • Explain exceptions in plain language. A clean headline followed by contradictory fine print is easy for people and machines to misinterpret.
    • Link related facts to a stable, canonical destination. Conflicting policy summaries across help pages, campaign pages, PDFs, and partner sites create avoidable uncertainty.
    • Identify editorial or organizational ownership. Readers should be able to tell who maintains the information and how to report an error.
    • Keep critical facts in accessible HTML rather than only inside images, video, or downloadable material.

    Structured data can reinforce this clarity, but it cannot certify a claim or suppress criticism. Use JSON-LD that matches the visible page. Choose a schema type that describes the actual entity or content, connect consistent identifiers, and include only properties you can support on the page. Organization markup can clarify organization-level identity; product markup belongs with an actual product; FAQ markup should reflect questions and answers people can see. Markup that contradicts the page creates another inconsistency rather than an authority signal.

    Technical health belongs in the same operating program but a different diagnostic lane. Crawl restrictions, broken internal links, inaccessible content, accidental duplication, and unstable pages can obstruct your official information. Core Web Vitals and AI visibility also deserve careful separation: improving page experience may strengthen the site, but it does not correct an external factual error by itself. If the AI answer repeats a stale forum claim, a performance score is not the evidence repair.

    Review consistency outside your site as well. Business profiles, social biographies, distributor pages, app listings, support portals, press materials, and executive profiles should not disagree on basic identity or policy facts. You do not need identical prose everywhere. You do need compatible facts, dates, names, and relationships.

    Build a reputation workflow that survives the next answer

    A one-time cleanup will not catch narrative drift. Products change, policies change, complaints accumulate, and old discussions remain available. Monitoring should therefore be tied to both a recurring review and events that alter what searchers need to know.

    Recheck priority queries after a product launch, policy revision, naming change, service disruption, public controversy, major correction, or update to a page that previously supported the wrong answer. Keep the original captures so you can distinguish a genuine change from a difference in wording.

    Your scorecard should track more than whether the brand appears:

    • Presence: does an AI-generated answer appear for the query?
    • Accuracy: which atomic claims are correct, incomplete, unsupported, outdated, or misattributed?
    • Source mix: do the visible links include official material, independent reporting, community discussion, or pages unrelated to the correct entity?
    • Freshness: do the answer and supporting pages reflect the current policy or product state?
    • Framing: are opinions labeled as opinions, or converted into broad factual language?
    • Consequence: could the answer change a purchase, support action, application, visit, or trust decision?
    • Remediation status: which page, platform, or process is being corrected, who owns it, and what evidence will show that the work is complete?

    Set escalation rules before a problem becomes emotional. A false claim involving safety, legal status, contractual terms, or another high-consequence matter should go to the relevant subject-matter and legal reviewers before a public response is improvised. A current service complaint belongs with the operational owner as well as the reputation team. A low-consequence opinion with no factual error may need observation, not intervention.

    The objective is not to force every AI answer to sound positive. It is to make important answers accurate, current, attributable, and properly qualified. That standard gives SEO, content, public relations, support, and leadership a shared definition of success.

    Start with the branded query where an incorrect answer could do the most damage. Capture the result, split it into claims, and repair the first weak link in the evidence chain. Once that workflow works for one query, apply it to the rest of your decision-critical set. That is how Google AI reputation management becomes an operating practice instead of a reaction to the next unpleasant screenshot.

    References

  • How Publishers Can Adapt as AI Reduces Search Traffic

    How Publishers Can Adapt as AI Reduces Search Traffic

    Your stories can keep ranking and still deliver fewer visits. When an AI answer absorbs the headline fact, definition, or short explanation, the reader may finish the task without opening your page. That changes the value of a ranking, but it does not make search irrelevant.

    If you run a publishing operation, the wrong response is to produce more interchangeable articles and hope volume compensates for a lower click-through rate. You need to identify the pages AI can replace, make your distinctive work easier to cite, preserve a compelling reason to visit, and connect that visibility to revenue.

    Key takeaways

    • Do not treat every lost organic visit as the same problem. Separate easily answered queries from stories that provide original evidence, continuing updates, analysis, or utility.
    • AEO and GEO should make your claims easier to understand and attribute. They cannot make generic content distinctive or guarantee inclusion in an AI answer.
    • Give readers the direct answer, then earn the visit with proof, depth, freshness, tools, or an ongoing relationship.
    • Measure search visibility, AI citations, referral traffic, audience retention, and revenue as separate stages. A citation is not a visit, and a visit is not a business result.
    • Keep investing in technical SEO while reducing your dependence on any single distribution platform.

    Find the search traffic AI can replace

    A publisher sorts text-free story tiles on a table, separating generic content from reporting based on interviews, photography, investigations, and community coverage.

    A 43% decline in publisher search referrals by 2029 has been projected. That is a planning estimate, not a guaranteed result for every publisher. Your actual exposure depends on what people search for, what your pages provide, and whether an AI interface can satisfy the need without sending the reader elsewhere.

    Start with a page-level exposure map. Export your organic landing pages with their impressions, clicks, entrances, conversions, and revenue contribution where available. Group pages by template and query purpose rather than reviewing thousands of URLs as unrelated items.

    <!– wp:list {
  • AI-Era Copywriting: Turn Positioning Into Recommendations

    AI-Era Copywriting: Turn Positioning Into Recommendations

    Your team can produce more words than ever, yet your homepage may still leave a buyer asking three basic questions: Is this meant for me? Does it solve my problem? Why should I believe you?

    That gap is where copywriting matters in AI-era marketing. You do not need another layer of generic content. You need language that makes your offer easy for a person to choose and easy for a generative system to match to the right buying situation.

    Key takeaways

    • AI has reduced the value of generic explanation, not the value of persuasion. Information can be compressed; a credible reason to choose you still has to be established.
    • Write from the buyer’s situation rather than from a broad description of your company. State who the offer is for, what problem it solves, how it works, and what supports the claim.
    • Generative engine optimization is partly a positioning problem. Your brand must be available as a relevant solution when a person describes a need, not merely visible for a category keyword.
    • Create separate pages only for meaningfully different decisions. If the audience, offer, proof, and next step are unchanged, changing a few nouns does not justify another page.
    • Use AI to organize evidence, expose gaps, and produce controlled variations. Keep positioning, promises, exclusions, and factual approval under human control.
    • Judge copy by commercial movement: qualified visits, revenue-page actions, lead quality, conversions, and branded demand. Raw traffic is not the final objective.

    Start with the decision, not the draft

    Hands arrange audience, problem, and proof symbols around a product prototype while a blank sheet and capped pen sit nearby.

    A page can be accurate, readable, and optimized without helping anyone decide. That usually happens when the writing explains a category but never establishes a position inside it.

    AI is particularly capable of summarizing, synthesizing, matching patterns, and compressing familiar information. That makes undifferentiated publishing easier to reproduce and easier to replace. It does not remove the need to influence a real choice. In practice, AI exposed the difference between informational production and persuasive copywriting.

    Before writing a headline, complete a positioning brief. If your team cannot agree on the brief, polishing sentences will only conceal the disagreement.

    <!– wp:list {
  • How to Turn AI Search Visibility Into Useful Engagement

    How to Turn AI Search Visibility Into Useful Engagement

    Your page can be readable, technically clean and still fail in AI search in two very different ways: it may never be selected, or it may be cited without giving anyone a reason to continue. Those are not the same problem, so they should not get the same fix.

    The practical goal is not the largest possible mention count. It is a reliable path from a query, to a useful AI-generated answer, to a next step your page is uniquely equipped to support. That requires content an AI system can extract without misreading and an experience worth visiting after the immediate answer is known.

    Separate AI visibility from user engagement

    AI visibility is often treated as a single metric, but it contains several handoffs. A page can succeed at one and fail at the next. Unless you record them separately, you won’t know whether to rewrite the answer, improve the landing experience or leave the page alone.

    HandoffWhat must happenTypical failure to inspect
    Machine comprehensionThe system can identify the subject, answer, conditions and supporting information.Vague headings, buried conclusions, ambiguous pronouns or missing context.
    Answer selectionThe page is useful enough to inform or support the generated response.The section does not answer the exact task, lacks necessary qualification or is difficult to extract cleanly.
    Reader continuationThe searcher has a legitimate reason to open the cited page.The page merely repeats the answer already visible in search.
    On-page outcomeThe visit leads naturally to a relevant decision or action.The landing section, next step or call to action does not match the original query.

    Google has said it tries AI Overviews for different kinds of questions, retains them when people find them useful and removes them when engagement is weak. The learning can then influence whether the feature appears for similar questions.

    That statement is easy to overread. It describes engagement with AI Overviews as a search feature. It does not establish that clicks on an individual publisher determine whether that publisher is cited. On this evidence, you should not present publisher click-through rate as a confirmed AI citation ranking factor.

    The distinction changes your diagnosis. If no AI result appears for a query, the feature itself may not have been served. If an AI result appears but your page is absent, inspect the page’s relevance, clarity, accessibility and support. If the page is cited but attracts little useful activity, examine what remains for the reader to learn or do. These conditions may look identical in a traffic chart, but they call for different work.

    Build answer units that can be extracted without losing context

    An intact modular information block is lifted from a larger structure with its supporting pieces attached, beside a second block broken into loose fragments.

    Machine-friendly writing is not robotic writing. It is writing in which the question, answer and boundaries stay together. Concise headings, plain language, structured data, accessible mobile delivery, fast loading and current information can all make content easier for AI systems to interpret and use. None of them guarantees inclusion, but each removes an avoidable source of uncertainty.

    1. Replace topic-label headings with task-specific headings. Implementation is a topic; How do you implement the change without losing existing data is a question with an identifiable answer.
    2. Put the conclusion before the long explanation. A reader and an extraction system should not have to reconstruct your position from several setup paragraphs.
    3. Attach qualifications to the claim they limit. If an answer applies only to a particular platform, plan, region, use case or version, name that boundary in the same answer unit.
    4. Use explicit nouns when a pronoun could point to more than one thing. Repeating a product, feature or process name is better than leaving the meaning of it or this unclear.
    5. Separate the direct answer from its support. State the answer, explain why it holds, show the conditions or exceptions, and then provide the evidence or example.
    6. Use lists for real sequences and criteria. Use a table only when the reader needs to compare the same fields across several options. Formatting should reveal the relationship between facts, not decorate the page.
    7. Make freshness visible where it matters. Review facts that can change, identify the applicable version or period, and remove outdated claims instead of relying on a generic updated date.
    8. Apply schema that describes the visible content and the correct entity or page type. Markup should reinforce what the page clearly says; it cannot repair an answer that is vague, unsupported or missing.
    9. Check whether the useful content is actually accessible. The page needs to load reliably, work on mobile and expose its main information without avoidable technical barriers.

    A strong answer unit is complete enough to stand on its own but connected to deeper material. For a choice query, that usually means naming who should choose each option, the constraint that changes the recommendation and any important exception. For a process query, it means stating the starting condition, the ordered actions and how the reader can tell the task is complete.

    Do not split a necessary qualification into a distant section simply because the page looks cleaner that way. An extracted sentence can become misleading when its boundary is several screens away. Put optional depth elsewhere; keep meaning-critical context beside the answer.

    Schema belongs at the end of this editorial sequence, not the beginning. First make the visible page accurate and structurally clear. Then use markup to identify what is already there. Schema is a description layer, not a substitute for the thing being described.

    Offer continuation value without withholding the answer

    An AI response may satisfy the basic question before the searcher visits you. If your page offers only the same fact in many more words, the click has no clear payoff. The answer is not to hide the conclusion or manufacture curiosity. Give the immediate answer plainly, then provide value the generated summary cannot conveniently deliver.

    • For an understand query, add boundaries, examples, exceptions and the relationship to easily confused concepts.
    • For a decide query, add selection criteria, trade-offs, disqualifying conditions and a path through the decision.
    • For a do query, add the complete workflow, prerequisites, reusable templates, implementation details and checks that reveal whether the result is correct.
    • For a verify query, show dates, scope, definitions, assumptions and the evidence needed to assess the claim.
    • For a product or service query, connect each option to the situation it fits instead of presenting an undifferentiated feature list.
    • For a visual query, use images that help a person identify, compare, match or complete the task. Add nearby text that explains what the image demonstrates and why it matters.

    Visual continuation deserves particular attention when the task is naturally visual. Visual search usage was reported as growing 70% year over year, with around 1 billion people using tools such as Google Lens. If your audience is trying to identify an object, compare a product, match an outfit or solve a physical-world problem, a text-only page leaves part of the task unanswered.

    That does not mean adding generic images to every page. The image must carry information. Show the relevant differences, label important features, provide useful captions and place the visual beside the decision or instruction it supports. Decorative imagery creates weight without creating continuation value.

    The call to action should continue the same job. Someone asking what a concept means may be ready for an example, checklist or implementation path, but not an immediate sales conversation. Someone comparing options may need a requirements worksheet or a deeper breakdown of trade-offs. Do not make a generic contact button the only route forward.

    Place the next step beside the section that earns it. A citation may land the reader in the middle of a long page, so the relevant explanation and action cannot depend on a journey from the top. Every major answer section should work as a useful entry point.

    Measure each handoff at the query level

    Colored glass spheres follow separate channels through selection gates and answer platforms, with some continuing to books and research tools at the end.

    Page-level organic traffic cannot tell you which handoff failed. A citation can appear without producing many visits, and a traffic change can come from something unrelated to AI visibility. Build a small, repeatable query-level record so that your edits have a diagnosis behind them.

    1. Define a fixed query set around real user tasks. Group together questions that express the same job, even when the wording differs. The unit you are managing is the query need, not an isolated keyword.
    2. Record the starting search state. Note whether an AI answer appears, which page is cited, what role the citation plays and whether the generated response already completes the task.
    3. Inspect the cited or candidate section. Record its heading, direct answer, qualifications, supporting material, visible freshness cues and relevant structured data.
    4. Name the continuation asset. Identify exactly what the reader gains by visiting: a decision framework, workflow, example, tool, template, visual explanation, evidence trail or another concrete resource.
    5. Name the desired on-page action. It might be reading the implementation section, using a tool, downloading a relevant resource, subscribing or beginning a commercial step. Choose the action that fits the query rather than the action that is easiest to count.
    6. Change the layer associated with the failure. Keep extraction-oriented edits separate from landing-page and call-to-action edits when possible, or you will not know which change affected the outcome.
    7. Repeat the observation using the same method. Compare AI-result presence, citation presence, landing behavior and meaningful actions instead of collapsing them into one success label.

    A practical log can contain these fields: query, user task, AI answer present, cited domain, cited URL, role of the citation, answer gap, continuation asset, intended action, observed outcome and next edit. This is enough to expose patterns without pretending that you can see the platform’s internal ranking process.

    Interpret the patterns carefully. No AI answer across a query group may mean the feature is not being retained for that kind of question; it is not proof of a page penalty. An AI answer with no citation from you points toward comprehension, relevance or selection. A citation with no useful visit points toward weak continuation value. Visits without the intended action point toward an expectation or landing-experience mismatch.

    Keep commercial exposure in a separate column. AI-powered search experiences may include ads around shopping, comparisons and product research, with sponsored material intended to remain distinguishable. A paid placement, an organic citation and a brand mention are different outcomes. Combining them will make both your visibility reporting and your budget decisions less reliable.

    Keep the observation method stable as well. Small personalization adjustments can alter ordering, such as moving video higher for someone who frequently clicks videos. A casual spot check is therefore a weak baseline. Use the same query definitions and checking procedure, preserve what you observed and look for a repeated pattern before assigning a cause.

    Key takeaways

    • Treat AI-result presence, publisher citation, site visit and meaningful on-page action as separate outcomes.
    • Do not call publisher click-through rate a confirmed citation ranking factor based on statements about engagement with AI Overviews as a feature.
    • Write answer units in which the question, conclusion, conditions and supporting detail remain understandable when extracted.
    • Use schema to describe accurate visible content, not to compensate for weak or ambiguous writing.
    • Answer the immediate question fully, then earn the visit with decision support, implementation depth, evidence, tools or task-relevant visuals.
    • Track a stable set of queries by user task, diagnose the failed handoff and keep paid exposure separate from organic citations.

    Start with the query that matters most and inspect the whole path. Capture the current search result, rewrite the weakest answer unit, add one honest continuation asset and align the next action with the original task. Then observe citation and on-page behavior separately. That gives you a testable improvement cycle instead of another vague AI visibility initiative.

    References

  • How to Build Content That Earns Visibility in AI Search

    How to Build Content That Earns Visibility in AI Search

    Your pages can rank, answer the right questions, and still disappear when someone asks an AI assistant for help. Publishing more content will not necessarily solve that. The missing piece is often the chain between the user’s decision, the evidence on your page, the format an answer engine selects, and the citation it ultimately shows.

    You need a content system that can earn inclusion across generated answers without turning useful pages into fragments written for machines. That means choosing queries more carefully, making claims easier to verify, using video where demonstration matters, and measuring citations separately from rankings and clicks.

    Stop treating AI visibility as one ranking

    A central content page connects through branching pathways to abstract response, voice, video, and source-card formats.

    Traditional rank tracking gives you a position for a query, device, location, and search engine. AI visibility is less tidy. The same question can produce a brand mention, an owned citation, a third-party citation, a video, or no reference to you at all. A single visibility score can hide those differences.

    The scale of that variation is not theoretical. Across 85 million citations from ChatGPT, Gemini, and AI Overviews, citation origins were organized into eight distinct categories. The practical lesson is that being visible is not only a matter of getting one page selected. You also need to understand which kinds of material supply answers in your market.

    Your plan also has to account for different discovery systems. AI-assisted discovery now spans ChatGPT, Perplexity, Google AI, and Siri, among other interfaces. Absence from one response does not prove universal invisibility, while one favorable citation does not establish broad coverage.

    Build your strategy around decision clusters rather than isolated keyword variants. A decision cluster is the connected set of questions someone asks while trying to understand, compare, choose, implement, or troubleshoot something. For each cluster, define:

    • The decision: What is the person trying to do, and what would a useful answer let them decide?
    • The canonical asset: Which owned page should provide the complete, maintained answer?
    • The evidence: Which claims, examples, specifications, or demonstrations make that answer credible?
    • The supporting formats: Would the user benefit from a video, visual demonstration, comparison, or other representation?
    • The target surfaces: Which search engines and AI assistants matter to this audience?
    • The success signals: Are you looking for an accurate mention, an owned citation, a video inclusion, referral traffic, or some combination?

    This prevents a common planning error: producing several pages that repeat the same basic answer while leaving the actual decision unsupported. One strong canonical page, backed by the right evidence and formats, is usually a better foundation than a collection of near-duplicates.

    Build a complete human answer, then make its evidence legible

    Two people assemble a page while glowing lines connect its content blocks to source cards, a camera demonstration, and comparison shapes.

    The wrong response to AI search is to break every subject into tiny pages or disconnected answer fragments. Google has explicitly discouraged creating special bite-sized content for LLMs and has warned against maintaining one version for people and another for generative systems. Google has acknowledged that narrow tactics may sometimes show an advantage, but its stated direction is toward systems that reward content made for people.

    That is Google’s position, not proof that concise passages never help an AI system. The useful distinction is between fragmentation and structure. Fragmentation removes the context a reader needs. Structure keeps the complete explanation while making its answer, reasoning, proof, and limits easy to locate.

    A citation-ready page should give the reader the following elements in a natural order:

    <!– wp:list {
  • How to Improve AI Search Visibility and Earn More Citations

    How to Improve AI Search Visibility and Earn More Citations

    Your page can rank, answer the right question, and still disappear when someone asks ChatGPT, Gemini, or another answer engine. If that is happening, rewriting the entire site is not your first move. You need to identify which part of the visibility chain is failing.

    Treat AI search visibility as a sequence: the page must be accessible, relevant to the question, easy to interpret, clear about the entity behind it, and strong enough to reuse or cite. This workflow helps you find the broken link, fix the right page, and measure the result without mistaking referral traffic for the whole outcome.

    Diagnose the visibility problem before changing content

    A technician inspects five connected glass chambers, with one dark chamber interrupting the illuminated pipeline.

    AI visibility is not one result. An answer engine can reproduce your idea without naming you, mention your brand without linking to it, cite a page without sending a visit, or describe your business inaccurately. Those outcomes require different fixes, so do not collapse them into one metric called AI traffic.

    Click-only reporting is especially misleading in answer-led search. One estimate puts the zero-click share of AI-powered searches at 83%. Even if the exact share differs among platforms and query types, a large part of your visibility may never appear as a conventional website session.

    The audience at stake is substantial, with 900 million weekly users attributed to ChatGPT and 650 million users to Gemini. That scale does not mean every brand needs to optimize for every prompt. It means you should identify the questions that influence discovery, evaluation, and trust in your particular market.

    Separate the outcomes you want to measure

    • Answer presence: Does the response cover the idea, method, product category, or recommendation your page addresses?
    • Brand presence: Is your brand named, implied without attribution, or absent?
    • Owned citation: Does the response link to a page you control, and is it the correct page for the claim?
    • Representation accuracy: Is the description current, complete enough for the query, and free from material errors?
    • Referral activity: Does the platform send a measurable visit after showing the answer?

    A citation is valuable, but it is not automatically a good result. A stale product page, an outdated brand description, or a citation attached to the wrong claim can create visible misinformation. Record accuracy alongside presence.

    Build a query-to-page map

    Before you edit a page, write down the questions for which you want it to appear. Use the language a real buyer, practitioner, or researcher would use. A vague topic such as “AI SEO” is not a testable target; a full question such as “How do I measure whether my company appears in AI-generated answers?” is.

    1. Collect questions from the stages that matter to your audience: problem recognition, explanation, comparison, selection, implementation, troubleshooting, and verification.
    2. Record the audience and constraint inside each question. A beginner seeking a definition needs a different answer from a marketing lead evaluating platforms.
    3. Assign one best existing URL to each question. If several URLs compete for the same job, choose a primary page and clarify the supporting roles of the others.
    4. Separate branded prompts from unbranded prompts. Do not average “What is Brand X?” with “What tools solve this problem?” because the first tests recognition while the second tests discovery.
    5. Run a baseline on the answer surfaces that matter to you. Save the exact prompt, response, cited URLs, platform, mode, date, and any retrieval setting exposed by the interface.
    6. Label the outcome using the five fields above before deciding what to change.

    One missing mention is an observation, not a diagnosis. Generated responses can change between runs and modes. Compare like with like, repeat important tests over time, and look for patterns across related questions before you conclude that a page is invisible.

    Protect the SEO foundation and clarify your entity

    AI optimization does not remove the need for technical and editorial SEO. The foundations that help search engines discover, interpret, and evaluate a page also support AI citation visibility. An answer-first rewrite cannot rescue a URL that is blocked, incorrectly canonicalized, isolated from the site, or missing its important content from the delivered HTML.

    Confirm that the intended page is eligible

    • The URL returns a successful response and does not require a sign-in, form submission, or user action to reveal the core answer.
    • Robots controls and page-level indexing directives do not block the intended content.
    • The canonical reference points to the URL you actually want systems to treat as primary.
    • The title, main heading, opening copy, and internal anchor text describe the same dominant subject.
    • Important text is present in accessible page content, not confined to an image, animation, or interaction with no readable equivalent.
    • The page is linked from a relevant hub, navigation path, or supporting page rather than existing as an orphan.
    • The sitemap, internal links, redirects, and canonical signals agree about the preferred URL.
    • Near-duplicate pages have distinct jobs or are consolidated so that they do not compete with conflicting answers.

    Use the inspection and indexing tools available in your search platforms to check the preferred URL. A clean technical result does not guarantee an AI citation; it only removes preventable eligibility problems. That distinction matters because it stops you from treating every visibility failure as a writing problem.

    Give systems one coherent version of your brand

    A recognizable company can still be missing from ChatGPT conversations when brand strength is not supported by AI-focused visibility work. Start by removing ambiguity from your own site.

    Write a canonical description using this structure: [Brand] is a [specific category] for [specific audience] that helps with [primary job], within [important scope or limitation]. The sentence should distinguish you from an adjacent category without relying on slogans. Keep the underlying facts consistent across your home page, About page, product pages, author profiles, and structured data, even when the surrounding prose changes.

    • Use the same official brand, product, and author names wherever they identify the same entity.
    • State what the organization does, whom it serves, and where or under what conditions it operates.
    • Maintain clear About, contact, editorial, and author information appropriate to the site.
    • Connect products, services, authors, and topics to the organization with visible copy and sensible internal links.
    • Reconcile old descriptions instead of allowing contradictory positioning to survive on legacy pages.
    • Keep names, canonical URLs, authorship, and dates aligned between visible content and JSON-LD.

    Independent references can help people and systems corroborate what your site claims, but relevance matters more than collecting mentions indiscriminately. Pursue editorially justified coverage, citations, profiles, and partnerships in places your audience would reasonably consult. Low-quality directories that repeat marketing copy add noise rather than clarity.

    Write answer units that remain useful when extracted

    A page does not become citation-ready merely because it is long or comprehensive. The useful passage must still make sense when separated from the rest of the page. Clear content patterns make information easier for an AI system to cite and easier for a person to understand.

    Put the direct answer at the start of each intent section

    Use a descriptive question or task heading, then answer it in the first paragraph beneath that heading. Add explanation, evidence, examples, and exceptions afterward. Do not make the reader cross an origin story, trend summary, or sales pitch to discover your actual position.

    1. Name the question or task. The heading should describe the decision the section resolves.
    2. Give the direct answer. State the conclusion in language that can stand alone.
    3. Add the scope. Identify the audience, platform, use case, or condition under which the answer holds.
    4. Support the claim. Provide the reasoning, evidence, process, or directly linked factual basis.
    5. State the exception. Explain when the answer changes or when another approach is preferable.
    6. Give the next action. Tell the reader what to inspect, change, compare, or record.

    Weak: “AEO is an important strategy that can help brands succeed in a changing digital landscape.”

    Useful: “Answer engine optimization structures content so an answer system can identify and reuse a direct response. It complements SEO because the page still needs to be accessible, relevant, and understandable before its answer can be selected.”

    The second version defines the term, explains its relationship to SEO, and avoids promising a citation. A reader can use it without needing the paragraph before it. That is the standard to apply to definitions, comparisons, procedures, and recommendations throughout the page.

    Make every important claim easy to verify

    • Replace vague pronouns with the product, platform, method, or organization the sentence concerns.
    • Carry necessary qualifiers into the claim itself. Do not hide the audience, time period, or limitation several paragraphs away.
    • Link the words that contain the supported fact rather than dropping an unexplained reference at the end of the page.
    • Distinguish documented facts from your recommendation. “This platform does X” and “we would choose it when Y matters” are different kinds of statements.
    • Use dates where a specification, product behavior, price, policy, or market fact can become stale.
    • Show decision criteria instead of declaring a universal winner. Explain which constraint changes the recommendation.
    • Use a table only when readers genuinely need to compare the same fields across alternatives.
    • Remove conflicting numbers, names, and definitions across related pages before adding more copy.

    Do not manufacture certainty to sound quotable. A qualified statement is more useful than a sweeping one because it tells the answer system and the reader where the claim applies. If the available evidence does not support a precise number or causal claim, write the narrower conclusion you can defend.

    Use JSON-LD as a consistency layer

    Structured data can express identity, authorship, page relationships, and other facts in a machine-readable form. It does not replace visible content, and no schema property acts as a request to be cited.

    • Describe only content and entities that genuinely exist on the page or site.
    • Use the most specific truthful types and properties that fit the visible material.
    • Keep entity names, canonical URLs, authors, publication details, and dates consistent with the page.
    • Do not mark up hidden answers, invented reviews, unsupported claims, or content a reader cannot verify.
    • Validate the syntax, then separately review whether the meaning is accurate. Technically valid markup can still describe the wrong thing.
    • Update the JSON-LD when a material visible fact changes instead of letting metadata preserve an obsolete version.

    Think of JSON-LD as corroborating metadata. The visible answer carries the explanation; the structured data helps make the entities and relationships less ambiguous.

    Give each URL one dominant job

    A single oversized page often tries to define a topic, compare options, document implementation, answer support questions, and establish the brand. That makes it harder to assign a clear query to a clear destination. Build a small set of pages with distinct purposes instead:

    • Explainer pages define the topic, its boundaries, and the concepts a newcomer must understand.
    • Decision pages compare approaches using explicit criteria, tradeoffs, and fit.
    • Task pages walk a reader through a process, including prerequisites, validation, and common failure points.
    • Evidence pages hold data, methods, policies, specifications, or other material that supports important claims.
    • Entity pages establish who the organization and authors are, what they do, and how their work relates to the topic.

    Connect those pages with descriptive internal links. The explainer can introduce the decision page, the decision page can cite the evidence page, and each can connect the subject matter to the relevant organization or author. The result is a coherent information system rather than a collection of isolated keyword targets.

    Measure mentions, citations, and accuracy separately

    Three transparent instruments separately collect signal halos, source links, and matching geometric pieces.

    Traditional rank tracking gives you a position for a query. AI visibility requires a richer record because the result is a generated answer with several possible forms of attribution. Create a ledger in which each row represents one exact prompt on one specified surface and mode.

    FieldWhat to recordWhat it helps you decide
    Technical eligibilityClear, blocked, canonical conflict, inaccessible content, or unknownWhether to fix discovery and delivery before rewriting
    Answer matchComplete, partial, incorrect, or absentWhether your target question and page content align
    Brand presenceNamed, represented without a name, or absentWhether the system connects the answer to your entity
    Owned citationCorrect URL, wrong owned URL, or noneWhether the intended page is being used as support
    Citation accuracyCurrent, incomplete, stale, or misappliedWhether consolidation or factual correction is required
    Competing citationDomain, page type, claim supported, and apparent advantageWhat format, evidence, or query coverage your page lacks
    Referral activityAttributed session or no measurable visitHow much visible citation activity becomes website traffic

    Save the answer itself, not only your grade. When a result changes, you need to see whether the platform adopted your definition, switched citation URLs, added your brand, or merely changed its phrasing.

    Let the pattern choose the fix

    • The intended URL is blocked or canonicalized elsewhere: resolve the technical conflict before changing the prose.
    • The page is accessible but does not directly answer the prompt: repair the query-to-page match and add a self-contained answer section.
    • The answer is present but the brand is absent: make the relationship between the expertise, claim, author, and organization explicit without turning the passage into an advertisement.
    • The brand is mentioned but no owned page is cited: strengthen the supporting claim, its visible evidence, and the internal path to the best reference URL. Continue tracking the mention as a separate outcome.
    • An outdated URL is cited: update redirects, internal links, canonical signals, visible facts, and structured data so they point toward the current destination.
    • The description is inaccurate: correct the authoritative page on your site and reconcile conflicting legacy copy. Do not simply publish another version of the same fact.
    • Competitors are cited for a narrower question: compare the exact passage and evidence that answer the prompt. Do not respond by increasing word count across an unrelated page.
    • Visibility appears only on branded prompts: build content for the unbranded problems and decisions that precede brand awareness.

    Use a controlled improvement cycle

    1. Freeze the baseline prompt set and save the platform, mode, date, answer, mentions, and citations.
    2. Resolve blocking, indexing, canonical, rendering, and internal-link problems.
    3. Rewrite the opening answer for the highest-value query assigned to the page.
    4. Add any missing scope, evidence, exception, authorship, or date needed to make the answer defensible.
    5. Align visible entity facts and JSON-LD with the preferred description and URLs.
    6. Run the same prompts under comparable conditions and record the full new answers.
    7. Expand the change to related pages only after the result improves answer coverage, representation accuracy, mentions, or citations.

    Calculate answer coverage, brand mention coverage, owned citation coverage, and accurate representation separately. Each metric should use the relevant tested prompts as its denominator. Segment the results by intent so that strong performance on branded verification questions cannot conceal weak performance on unbranded discovery or selection questions.

    Referral sessions still matter, but they are a downstream measure. A zero-click answer can expose the brand, shape a shortlist, or repeat a definition without creating an immediately attributable visit. Keep traffic and conversions in the scorecard while resisting the temptation to use them as the only evidence that answer optimization worked.

    Key takeaways

    • Measure answer presence, brand mentions, owned citations, representation accuracy, and referral activity as different outcomes.
    • Map complete, natural-language questions to one preferred page before making AI-specific edits.
    • Fix access, indexing, canonical, rendering, and internal-link problems before treating invisibility as a copywriting failure.
    • Start each intent section with a direct answer that includes its necessary scope and can stand alone when extracted.
    • Keep brand facts consistent across visible content, entity pages, internal links, and JSON-LD.
    • Use structured data to clarify truthful relationships, not to invent authority or request a citation.
    • Compare repeated tests under comparable conditions and let the failure pattern determine the next change.

    Start with the unbranded question whose absence matters most to your business. Assign its best page, capture the current answer, and fix the first failed link in the chain. At the next review, you should be able to say which query-page combination improved and what changed, not merely whether an AI system seems to know your brand.

    References

  • SEO and GEO Visibility Signals: What to Measure and Fix

    SEO and GEO Visibility Signals: What to Measure and Fix

    If your pages rank well but your brand rarely appears in AI-generated answers, the results are not contradictory. Search rankings, AI mentions, citations, and accurate brand representation are different visibility outputs. They overlap, but they are not interchangeable.

    Your job is not to choose between the labels SEO and GEO. It is to identify which signals affect discovery, measure each surface in a defensible way, and connect visibility to an outcome your business values. That requires a clearer system than a single visibility score.

    Treat SEO and GEO as connected, not interchangeable

    Traditional search remains a major discovery channel despite the growth of AI assistants, and AI search has not simply replaced Google Search. At the same time, AI interfaces have become another place where people research problems, compare options, and encounter brands.

    The sensible response is an expansion of your visibility strategy, not a wholesale pivot. Strong technical SEO, useful content, clear site architecture, and earned authority remain valuable. But SEO performance does not guarantee AI visibility, because an AI system can form an answer from a different combination of pages, entities, citations, and off-site references.

    Use these decision rules when deciding where to invest:

    • If organic search produces qualified traffic or revenue, protect that foundation. Do not weaken successful pages to pursue an unproven AI tactic.
    • If customers use AI tools while researching your category, add GEO measurement alongside your existing SEO reporting.
    • If you do not yet know how your audience uses AI, run a contained discovery program before moving a large share of your budget.
    • If AI visibility is growing but business outcomes are not, inspect the prompts, answer context, citations, and measurement denominator before assuming the channel is valuable.

    This framing also prevents a common strategic mistake: treating every AI mention as proof that a campaign worked. Visibility is an intermediate output. You still need to know what caused it, what the answer said, and whether it influenced a useful action.

    Read visibility as a chain of inputs, outputs, and outcomes

    An isometric chain of website pages, processing gates, linked document fragments, answer modules, and people taking actions.

    SEO and GEO reporting becomes confusing when inputs, outputs, and business outcomes appear in the same chart as if they were equivalent. A backlink, a search impression, an AI citation, and a sale can all matter, but each describes a different part of the system.

    Measurement layerExamplesQuestion it answersWhat you should do with it
    Controllable inputsCrawlable pages, clear topic coverage, accurate entity details, supporting evidence, internal links, valid structured dataHave we made our information accessible and understandable?Use these signals to diagnose and prioritize changes, not to declare success.
    External inputsRelevant backlinks, independent brand mentions, reviews, expert references, and coverage on trusted third-party sitesDoes the wider web corroborate what we say about ourselves?Look for missing authority, reputation, and distribution rather than rewriting the same page repeatedly.
    SEO visibility outputsSearch impressions, query coverage, result position, clicks, and landing-page trafficCan searchers find and choose our pages?Segment by query, page, device, market, and search feature where the data allows.
    GEO visibility outputsBrand mentions, linked citations, unlinked references, recommendation context, and factual accuracyIs the brand represented in generated answers, and how?Retain the underlying answers and classify the role of each appearance.
    Business outcomesQualified visits, direct discovery, branded demand, leads, assisted conversions, sales, and retentionDid visibility contribute to something the organization values?Use outcomes to decide whether an optimization program deserves more investment.

    The distinction between a brand mention and a citation deserves particular attention. A citation tells you that a system surfaced a source. It does not necessarily mean the brand was recommended, described correctly, or made memorable. An unlinked brand mention may influence discovery without producing an immediate referral visit. A linked citation may produce no clicks at all.

    For that reason, explicit brand mentions are a central GEO visibility signal, while citations should be measured as a separate dimension. Record what role the brand played in the answer:

    • Primary recommendation
    • One option in a comparison
    • Alternative or secondary choice
    • Supporting example
    • Cited information source
    • Incidental mention
    • Incorrect or irrelevant association

    This classification keeps a negative, inaccurate, or incidental appearance from being counted as equivalent to a relevant recommendation. It also gives the content, PR, reputation, and SEO teams a shared diagnosis instead of an unexplained score.

    External evidence belongs near the top of that diagnosis. Off-site brand mentions can carry substantial weight in AI visibility, much as independent references help establish credibility in search. If your own pages are complete but the wider web rarely connects your brand with the topic, publishing another lightly differentiated page may not address the missing signal.

    Measure AI answers as samples, not fixed rankings

    Several translucent answer cards show different arrangements of source tiles and links around one central query orb.

    A conventional rank tracker observes an ordered search result under defined conditions. Those conditions can still affect what appears, but the tracker can capture a recognizable result page at a particular moment.

    Generated answers require a different measurement model. They are probabilistic and can vary across repeated or personalized interactions. The same wording does not promise the same answer, citations, or brand set every time. A single response is therefore evidence of one observation, not a permanent rank.

    Prompt demand introduces another limitation. Exact prompt search volumes are not publicly available, so volume estimates from visibility platforms should not be treated like verified query counts. A prompt may be commercially important without being common, while a frequently tested prompt in your dashboard may not reflect how customers actually ask the question.

    A defensible AI visibility sampling protocol

    1. Build prompt families from customer language. Use sales questions, support requests, site-search terms, search queries, product comparisons, and objections. Group them by discovery, evaluation, decision, and post-purchase intent.
    2. Define the test conditions. Record the AI product or interface, any exposed model information, date, market, language, persona instructions, and whether the test ran in a fresh or continuing conversation.
    3. Repeat the observations. Run important prompts more than once under consistent conditions. Keep natural wording variants in a separate group so you can distinguish response variability from a changed question.
    4. Save the underlying evidence. Store the prompt, full response, cited URLs, observed brands, and test conditions. A dashboard score without the answer behind it is difficult to audit.
    5. Classify the context. Mark whether your brand was recommended, compared, cited, merely listed, or represented incorrectly. Add a manual accuracy review for claims that matter to customers.
    6. Report the denominator. Every percentage should identify the prompts, engines, conditions, and number of sampled responses it covers. Do not present a percentage from a curated prompt set as market-wide visibility.
    7. Compare periods consistently. Keep a stable benchmark set for trend reporting. Add emerging prompts separately so growth in the test library does not masquerade as a visibility decline.

    From that dataset, calculate metrics whose meanings are explicit:

    • Brand occurrence rate: sampled responses mentioning your brand divided by all sampled responses in the defined set.
    • Citation rate: sampled responses linking to your domain divided by all sampled responses in the defined set.
    • Mentioned-response citation rate: responses that both mention and link to you divided by responses that mention you. This separates brand recognition from source selection.
    • Context distribution: the share of mentions classified as recommendations, comparisons, examples, citations, incidental appearances, or errors.
    • Accuracy rate: reviewed mentions that describe the brand and offering correctly divided by all reviewed mentions.
    • Business response: qualified referrals, branded discovery, assisted conversions, or other agreed outcomes associated with the visibility program.

    Call the first five sampled visibility metrics. Do not call them traffic forecasts unless you have separate evidence connecting them to demand. When the sample is small or the answers vary sharply, label the result as directional.

    A useful AI visibility tool should expose the exact prompts and responses, preserve test conditions, distinguish mentions from citations, show variability, and let you export the raw evidence. Be cautious when a platform hides its denominator, presents estimated prompt volume as known demand, or implies that its score guarantees future inclusion. No monitoring or automation tool can guarantee a place in generated answers.

    Improve signals in an order that protects search performance

    Once you identify a weak visibility signal, resist the urge to rewrite everything for AI. Start with the earliest broken link in the signal chain. That produces a cleaner test and reduces the risk of damaging pages that already perform in search.

    1. Protect technical discoverability. Confirm that important pages are accessible, internally linked, indexable where intended, and not undermined by conflicting canonical, robots, or redirect instructions. An AI experiment is not a reason to ignore ordinary crawl and indexing problems.
    2. Resolve the reader’s question clearly. Put the direct answer near the point where the question is introduced. Define the subject, identify who the answer applies to, explain important conditions, and support the conclusion. Clear writing helps people first and also reduces ambiguity for systems processing the page.
    3. Make the entity unambiguous. Use a consistent brand name, offering description, authorship, and organizational relationship across relevant pages. If two products, companies, or people have similar names, state the distinction plainly.
    4. Strengthen verifiable support. Connect material claims to evidence a reader can inspect. Replace circular claims and unsupported superlatives with concrete descriptions, primary references where available, and visible qualifications.
    5. Use structured data as clarification. JSON-LD should accurately represent entities and facts already supported by visible content. Treat it as a consistency layer, not as proof that an AI assistant will mention or cite the page.
    6. Earn relevant off-site corroboration. Look for the sites, communities, publications, reviews, and expert resources your audience already trusts. The goal is an accurate, editorially meaningful connection between your brand and its subject, not a large pile of manufactured mentions.
    7. Retest the affected prompt family. Preserve the old observations, repeat the defined sample, and inspect both occurrence and context. Then check whether any movement reaches qualified traffic, branded discovery, leads, or revenue.

    Do not sacrifice a useful page merely to make isolated sentences easier to quote. Removing necessary context, repeating entities unnaturally, publishing near-duplicate answer pages, or changing a successful information architecture without evidence can create more problems than it solves. GEO tactics that conflict with established SEO principles can hurt search performance.

    The same caution applies to off-site work. Relevant independent mentions can be valuable, but mention count alone is a poor target. Ask whether the external page is credible, topically relevant, accessible, accurate, and likely to be encountered by the audience you want. A misleading mention can create the wrong association just as easily as a useful mention can reinforce the right one.

    Allocate effort according to audience behavior and business value

    The right SEO-to-GEO budget cannot be derived from industry excitement. It depends on how your own audience divides its attention among AI, search engines, social platforms, and other sources. That makes audience evidence part of visibility measurement, not a separate marketing exercise.

    Create one channel allocation sheet with the following fields:

    • Audience-use evidence: customer interviews, sales and support language, first-party site search, analytics, and a consistent “how did you find us?” field where appropriate.
    • Visibility output: search impressions and clicks for SEO; sampled mentions, citations, context, and accuracy for GEO.
    • Business outcome: qualified visits, leads, assisted conversions, sales, or another outcome that reflects the role of the channel.
    • Evidence confidence: verified first-party data, directional sample, modeled estimate, or untested assumption.
    • Next decision: protect, expand, repair, investigate, or stop.

    That sheet makes several common situations easier to handle. If search produces revenue and AI use among your customers is uncertain, keep the SEO engine healthy while establishing a modest GEO baseline. If customers routinely use AI during evaluation but your brand is absent, investigate topic coverage and external corroboration. If mentions rise without referral traffic, inspect unclicked discovery, branded demand, assisted outcomes, and mention context before declaring success or failure.

    If a visibility score rises while every meaningful outcome remains flat, audit the score before increasing the budget. Check whether the tested prompt set changed, whether more engines or responses were added, whether the denominator is visible, and whether your brand appeared as a real recommendation or an incidental reference.

    Key takeaways

    • SEO rankings, AI mentions, citations, and business results are separate signals. Report them separately.
    • Measure generated answers as repeated samples under recorded conditions, not as permanent rankings.
    • Use brand occurrence, citation presence, context, and accuracy together. A visibility score alone cannot tell you whether the appearance was useful.
    • Treat prompt-volume figures as estimates unless a platform exposes verified usage data.
    • Preserve the SEO work already producing value. Add GEO work where audience behavior and business evidence justify it.
    • When on-site information is already strong, examine relevant off-site mentions before commissioning another rewrite.

    In your next reporting cycle, separate inputs, visibility outputs, and business outcomes. Keep a stable prompt sample, retain the answers behind every score, and choose one missing signal to improve. You will learn more from that controlled change than from trying to optimize an entire site for an opaque AI metric.

    References

  • How to Choose a Healthcare Marketing and SEO Agency

    How to Choose a Healthcare Marketing and SEO Agency

    You’re not trying to find the healthcare agency with the best pitch deck. You’re choosing a team that will influence how patients, clinicians, or buyers discover and judge your organization before they ever contact you. The wrong choice can waste budget, but it can also create avoidable privacy, compliance, and reputation risk.

    If every proposal looks interchangeable, your selection brief is probably too loose. Define the acquisition job, score evidence consistently, and make each finalist work through the same real scenario. That will tell you far more than a list of services or awards.

    Key takeaways

    • Choose the agency around your actual constraint: organic visibility, local discovery, broader demand generation, reputation, or a specialized healthcare buying journey.
    • Give the most weight to relevant healthcare work, experienced leadership, and the people who will deliver the account. Longevity alone is weak evidence.
    • Ask finalists to diagnose the same service line, location, product, or search problem. Compare their reasoning and operating process, not just their promises.
    • Measure qualified actions and business outcomes alongside rankings, traffic, local visibility, and AI mentions.
    • Treat privacy, clinical review, account ownership, data access, and offboarding as selection requirements rather than details to negotiate later.

    Start with the job you need the agency to do

    Healthcare marketing agency, medical SEO agency, digital agency, and growth partner are not interchangeable labels. An SEO specialist may be the right choice when your central problem is organic discovery. A broader medical marketing agency may fit better when search has to work alongside positioning, creative, paid media, website development, and reputation management.

    The label still won’t settle the decision. Even within plastic-surgery SEO, agency approaches range from thought-leadership and ghostwritten content to branding, advertising assets, and search-optimized web development. Two firms can both claim the same specialty while selling fundamentally different operating models.

    Write a one-page acquisition brief before you request proposals. It should answer:

    • What are you promoting? Name the service line, procedure, facility, product, or clinical capability. Do not use a broad instruction such as “grow organic traffic.”
    • Who must act? Distinguish patients, caregivers, referring clinicians, administrators, procurement teams, or other buyers. Their questions and decision paths are not the same.
    • Where does the decision happen? Specify the geographic market, locations, service area, or sales territory that matters.
    • What action has value? Name the intended conversion: an appointment request, qualified phone call, referral inquiry, consultation, demonstration, or another defined action.
    • What is blocking growth? State what you currently know about weak visibility, poor conversion, technical problems, unclear positioning, thin content, local competition, or inadequate measurement.
    • What cannot be compromised? Record clinical-review requirements, privacy boundaries, brand rules, technology constraints, accessibility needs, and internal approval responsibilities.

    If you cannot describe the baseline confidently, make discovery and measurement design the first required deliverable. Do not let an agency fill the uncertainty with publishing volume. Activity is not a diagnosis.

    Specialization should match the difficult part of your assignment. A practice-focused local agency may understand location pages, clinician profiles, map visibility, and appointment conversion. A medical-device marketer may be better prepared for a longer journey involving technical education and organizational buyers. A plastic-surgery specialist may bring relevant procedure-language and aesthetic-market experience. Ask for proof in the exact part of healthcare that makes your project difficult; a generic healthcare logo wall is not enough.

    Build an evidence scorecard before you hear the pitches

    A healthcare selection committee sorts blank evaluation cards and reviews supporting material on a tablet.

    A practical 100-point starting scorecard gives 30 points to notable healthcare clients, 30 to founder involvement and leadership experience, 20 to reviews, 10 to median employee tenure, and 10 to years in business. The value of that framework is not mathematical precision. It forces you to decide what counts as evidence before a polished presentation starts influencing the decision.

    Adjust the weights to your assignment, but do it before proposals arrive. Company age, for example, can be a modest durability signal rather than a deciding factor; another medical-agency screening model assigned only 5% to the year founded. A long operating history does not prove that a team understands current local results, AI discovery, technical SEO, or your clinical market.

    Relevant healthcare evidence

    Give credit for similarity, not fame. The useful case is the one that resembles your service, audience, geography, buying process, and regulatory environment. Ask the agency to show the starting condition, the work it controlled, the outcome, and the measurement method. A traffic chart without its date range, query mix, conversion definition, and business context cannot establish patient or buyer acquisition.

    Named clients are easier to verify, but confidentiality can be legitimate. When a firm cannot identify a client, ask for a sanitized account structure, sample deliverable, reporting view, and reference whose identity can be disclosed privately. Do not award full credit for an anonymous result that cannot be examined at all.

    Leadership and delivery ownership

    Founder involvement can indicate accountability, but it is not a substitute for an experienced delivery team. Find out who will perform strategy, technical work, content development, local optimization, analytics, and account management after the sale. Ask which decisions require senior review and who handles escalation when clinical, technical, or performance concerns appear.

    Score the proposed team, not the people on the agency’s website. Request names, roles, relevant healthcare experience, availability, and any planned subcontracting. If staffing may change, the contract should explain how replacements are approved and what level of experience must be preserved.

    Reviews, continuity, and operating history

    Read reviews for evidence about the work you are buying. Look for the scope, problem, delivery behavior, and result rather than treating the average score as self-explanatory. A detailed account of technical SEO or patient-acquisition work is more informative than broad praise about responsiveness.

    Employee tenure matters because repeated handoffs can erase context and slow execution. Ask about the tenure and workload of your proposed team, how account knowledge is documented, and what happens when someone leaves. Agency-wide averages do not tell you whether your assigned strategist will remain available.

    Use privacy readiness, clinical approval, access ownership, conflict rules, and prohibited tactics as pass-or-fail gates. A high weighted score should not compensate for a failure in any area that could create legal, patient-safety, data, or reputation exposure. Your compliance or legal leadership should define those gates for your organization.

    Make each finalist show you its operating system

    Agency strategists and healthcare stakeholders examine an abstract workflow that connects search, review, and appointment stages.

    Give every finalist the same bounded scenario: one priority service line, location, procedure, product, or audience; the relevant page or website area; a current reporting snapshot; and the constraints from your brief. If the material is sensitive, sanitize it. The goal is to observe how the team frames a problem, not to collect free strategy.

    Ask each agency to walk through these components:

    1. Discovery diagnosis. Which patient or buyer questions matter, which search surfaces are relevant, what can be learned from the current site, and what information is still missing?
    2. Prioritization. What would the team address first, what would it defer, and what evidence supports that order?
    3. Content production. Who interviews subject-matter experts, drafts the material, checks search intent, verifies facts, secures approval, publishes revisions, and owns future updates?
    4. Technical and local execution. How will the agency inspect crawlability, indexation, templates, internal linking, page experience, redirects, location information, and business-profile consistency where those issues apply?
    5. Authority development. How will it earn or strengthen trustworthy mentions without relying on manipulative links, fabricated credentials, or low-quality placements?
    6. Measurement. How will discovery activity connect to qualified calls, forms, appointments, referrals, consultations, demonstrations, or pipeline events?

    A capable team should be willing to state what it does not know. Be cautious when a firm can produce a complete answer before it has access to analytics, search data, site architecture, conversion definitions, or the people responsible for care and sales.

    Ask what SEO means across Google, local results, and AI answers

    Your audience may encounter your organization through Google, local maps, and ChatGPT, so “improve SEO” is too vague for a statement of work. Ask the agency to identify the surfaces it will address, the work attached to each one, and what can actually be measured.

    For conventional search, the answer may include technical accessibility, search-intent coverage, internal linking, local information, and conversion paths. For answer engines and generative systems, it may include clear entity information, consistent facts, well-structured explanations, attributable expertise, citations, and monitoring of sampled responses. Structured data can make page information easier for machines to interpret, but it is not a guarantee of a ranking, citation, or AI recommendation.

    No agency controls the output of a frontier model. Reject guarantees of permanent ChatGPT placement or a deterministic “AI rank.” A defensible AI-visibility plan should name the prompts or question sets being observed, the market and audience assumptions, the date of each observation, the systems tested, and the distinction between a direct citation, an unlinked mention, and no visibility. It should also explain how those observations change the content or authority plan.

    Require a clinical, privacy, and publishing workflow

    The agency should not be the final authority on clinical claims, patient consent, privacy obligations, or the legal acceptability of advertising language. Require a responsibility map that names the drafter, clinical reviewer, compliance or legal approver, publisher, and person responsible for later corrections. Your own qualified advisers must define the rules that apply to your organization, jurisdiction, service, and data.

    Do not send identifiable patient information into agency tools, analytics platforms, content systems, or AI workflows unless your privacy and security leaders have approved the exact use, vendor, access model, retention policy, and contractual protections. Better attribution does not justify an unauthorized data flow.

    Ask the agency to demonstrate its correction process as well as its creation process. Healthcare facts, clinician details, locations, availability, and service information can change. You need a clear route for urgent corrections, routine review, version history, and removal of outdated material.

    Connect reporting and contract terms to the same outcome

    Rankings and traffic can diagnose visibility, but neither proves that the program is producing appropriate demand. Build a measurement ladder that separates leading signals from business results:

    • Visibility signals: relevant query coverage, impressions, local-result presence, indexed priority pages, branded versus non-branded discovery, and dated observations of AI mentions or citations.
    • Engagement signals: qualified visits, calls, form starts, completed inquiries, appointment requests, referral actions, or product-interest events appropriate to the journey.
    • Business outcomes: accepted inquiries, booked consultations, appointments, qualified opportunities, demonstrations, or another outcome your organization can validate.
    • Quality guardrails: factual corrections, approval breaches, tracking failures, indexation problems, accessibility defects, irrelevant demand, and other failure modes that should never disappear inside an aggregate performance chart.

    Define every important term before work begins. Decide what makes an inquiry qualified, how duplicate actions are treated, whether branded searches are reported separately, how phone calls are categorized, and where the authoritative business record lives. Attribution will rarely be perfect, but inconsistent definitions make it actively misleading.

    The contract should reinforce the measurement plan rather than obscure it. Confirm:

    • Which deliverables are included and how completion or acceptance is determined.
    • Which named roles will serve the account and what subcontractors may access.
    • Who owns the domain, website, content, creative assets, structured data, business profiles, analytics properties, advertising accounts, dashboards, and raw exports.
    • Which systems the agency can access, which data it may collect, and how access is removed.
    • How fees, media spending, software costs, and third-party production expenses are separated.
    • How new requests, scope changes, clinical corrections, and urgent technical work are authorized.
    • What happens at termination, including credential transfer, source files, documentation, historical data, active campaign settings, and deletion of retained copies.
    • Whether competitive conflicts, territory restrictions, or exclusivity terms apply.

    Keep critical accounts under your organization’s ownership and grant the agency appropriate access. If the relationship ends, you should not have to negotiate for your own domain, analytics history, local listings, advertising data, content, or credentials. Have qualified legal, privacy, security, and compliance professionals review terms that affect their areas.

    Use red flags to make the final decision simpler

    A weak proposal often reveals itself through what it avoids. Treat these as reasons to investigate further or remove a finalist:

    • A guarantee of a top Google position, permanent AI citation, or fixed patient-acquisition outcome that the agency cannot control.
    • A strategy that could be sent unchanged to a hospital, specialty practice, plastic surgeon, medical-device company, or unrelated business.
    • Case evidence that shows traffic growth but cannot explain query relevance, qualified actions, attribution, or business impact.
    • A content plan built around publishing volume before anyone has inspected technical health, existing content, search demand, subject-matter access, and approval capacity.
    • An AI-search plan that consists only of generating more text or adding schema, with no explanation of entity clarity, evidence, citations, monitoring, or content quality.
    • A sales presentation led by senior experts followed by an account plan that does not identify the delivery team.
    • No documented workflow for clinical review, privacy approval, factual corrections, or escalation.
    • A demand that the agency own your domain, analytics, advertising account, business profiles, or other core digital property.
    • Reporting that blends branded and non-branded discovery, all locations, or every conversion into one favorable total.
    • Defensiveness when you ask what failed, what remains uncertain, or which work will not be done.

    Run reference conversations around operating behavior, not satisfaction alone. Ask who actually performed the work, how the agency handled corrections and disagreement, whether reporting matched the client’s records, what changed after the sale, and how assets were handed back. Listen for specific processes and examples rather than adjectives.

    Then have each stakeholder score the finalists independently before discussing the result. If two agencies finish close, choose the team that draws the clearest line from a real discovery problem to a qualified action, shows the strongest governance around that work, and leaves you in control of your data and assets.

    Your next step is simple: write the one-page acquisition brief, set the score weights and pass-or-fail gates, and send the same scenario to every finalist. The agency that can make the work concrete before the contract is the one most likely to keep it concrete afterward.

    References