Tag: AI Search

  • Local Discovery in Google and ChatGPT: A Practical Plan

    Local Discovery in Google and ChatGPT: A Practical Plan

    If your business appears in Google for one service but disappears for a broader search, adding more reviews may not solve the problem. If ChatGPT overlooks you, turning every keyword into a long conversational question may not solve it either.

    Local discovery starts with recognition: can the system confidently identify what your business is, what it offers and where it operates? Selection comes next. Your strategy should strengthen that identity first, then give Google, ChatGPT and prospective customers enough evidence to choose you.

    Google has to recognize you before it can rank you

    Google does not begin every local search by lining up all nearby businesses and comparing reviews, links and proximity. It first has to decide which businesses plausibly satisfy the query. That eligibility decision precedes the familiar ranking competition.

    This distinction changes how you diagnose weak local visibility. A business that is not recognized as an eligible match cannot review its way to the top of that result set. The immediate problem is interpretation, not popularity.

    Your business name and primary category are central to that interpretation. Google processes them as a combined identity signal: the name communicates how the business identifies itself, while the category supplies a structured description of what kind of business it is. Together, they create an entity boundary around the searches Google can confidently associate with you.

    The boundary changes with query breadth. A narrow service query may require a close match between the requested service and your recognized identity. A broad query such as “restaurants” creates a larger eligible set because many categories and business concepts can satisfy it. Once the set exists, reviews, clicks, relevance and real-time facts such as whether a location is open can help distinguish the candidates.

    A highly specific business name can reinforce a niche interpretation while making a broader interpretation less obvious. That is not a reason to add keywords to your official business name. It is a reason to keep the name accurate, choose the most truthful primary category and understand which queries that combination naturally supports.

    Run this eligibility audit before starting another general link or review campaign:

    1. List your commercially important query families. Write the service and location combinations customers actually use, including both specialist and broad category terms.
    2. Separate narrow queries from broad ones. “Emergency dentist in [area]” asks for a more specific interpretation than “dentist in [area].” Do not assume one result represents the other.
    3. Place your exact business name and primary Google Business Profile category beside each family. Ask whether that pair makes you an obvious candidate without relying on a human to infer services that are not stated.
    4. Mark each family clear, ambiguous or outside the boundary. “Outside” is acceptable when the service is not genuinely part of your business. The objective is accurate eligibility, not visibility for every adjacent phrase.
    5. Correct factual mismatches first. If the primary category understates or misrepresents the core business, fix that identity issue before treating reviews or links as the main remedy.

    You can use result patterns as a working diagnosis, although they are not proof of Google’s internal decision. If you are absent for a highly specific service you genuinely provide, inspect the identity and service signals first. If you appear for specialist queries but not broader ones, your entity boundary may be too narrow. If you appear consistently but lose position, selection signals are the more plausible next area to investigate.

    Design for the short local prompts people actually use

    Using ChatGPT does not automatically turn a local transaction into a long conversation. In observed local healthcare and aesthetic service searches, 75% of sessions contained at least one keyword-style prompt. Participants often entered compact combinations such as a service and location instead of explaining their full situation in a sentence.

    The same behavior appeared in the length of the interaction. Forty-five percent of sessions ended after one prompt, the overall average was about 2.1 prompts and 34% of follow-up prompts simply asked for more results. These observations came from a limited set of local healthcare and aesthetic tasks, so they should not be treated as a universal law for every market. They do, however, give you a strong reason not to abandon concise service-and-location language.

    For a one-shot prompt, your first-answer visibility matters. You cannot depend on every user conducting a long dialogue that eventually uncovers your business. You need to be understandable from compact intent such as “dentist 11214,” “chiropractor [city]” or “hair transplant [area].”

    Give each real service a clear discovery layer

    A service page should make its basic proposition recoverable without requiring interpretation across several paragraphs. Near the beginning of the page, state:

    • The plain-language name of the service.
    • The business or practitioner providing it.
    • The city, neighborhood or genuine service area.
    • What the service includes and, just as importantly, what it does not include.
    • The next step a prospective customer can take.

    This is not an instruction to repeat the same keyword mechanically. It is an instruction to remove avoidable ambiguity. If a visitor has to infer the service from brand language such as “complete transformation solutions,” an automated system has to resolve the same ambiguity.

    Do not create a separate thin page for every rearrangement of the same phrase. Build pages around real distinctions: a separate service, a location where the service is genuinely available or a decision that needs materially different information. A page should exist because the offer is distinct, not because the word order changed.

    Add the evidence a person needs after discovery

    Keyword clarity may help a system understand the candidate, but it does not finish the customer’s decision. People searching for local services still move among websites, social profiles and reviews. Your page should therefore answer the practical questions that arise after recognition: availability, location, relevant qualifications, service scope, appointment process and any constraints that could make the business unsuitable.

    Keep transactional content concise, but do not remove useful explanations merely to imitate a short prompt. Longer, question-led content remains valuable when the user’s intent is informational. The mistake is making an extended conversational format the only place where a transactional service is named clearly.

    Build one consistent local facts layer for both paths
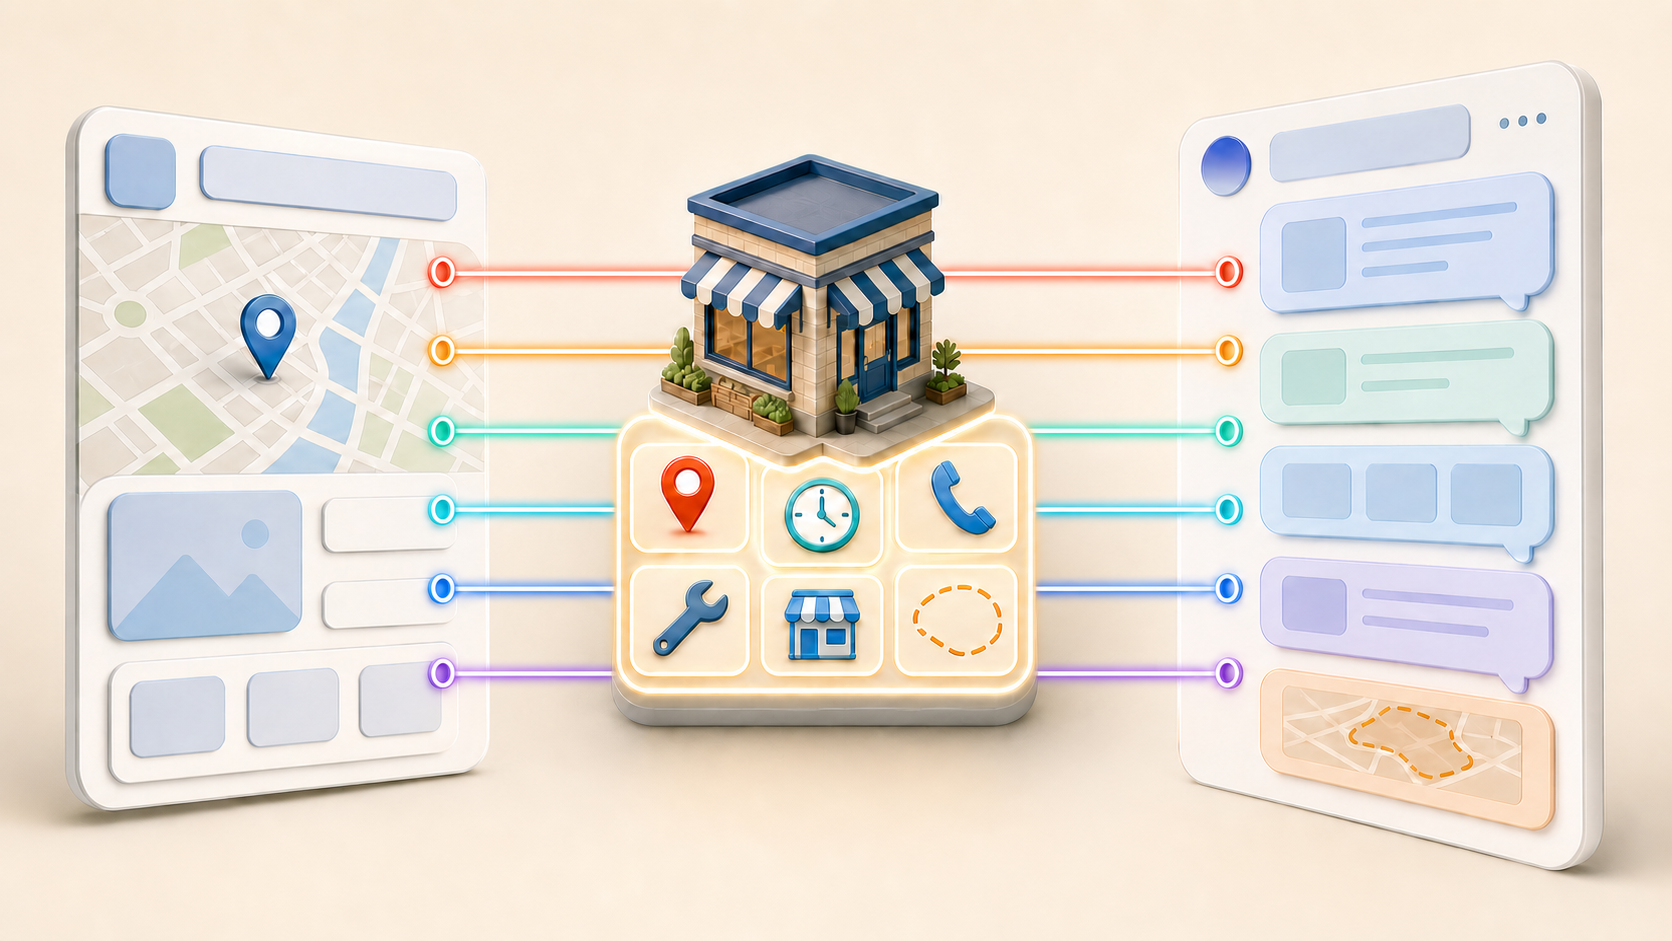
    A central business building and fact symbols connect consistently to a map interface and a conversational assistant interface.

    You do not need a “Google identity” and a separate “ChatGPT identity.” You need one accurate public description of the business that remains coherent wherever a customer or system encounters it. The platforms can produce different results, but contradictory source facts make recognition harder in either environment.

    Fact to alignWhy it mattersWhat to inspect
    Business nameEstablishes the entity’s self-identificationGoogle Business Profile, website header and contact information, major public profiles
    Primary categoryDefines the structured business type and helps set the eligibility boundaryWhether it truthfully represents the core offer rather than a secondary service
    ServicesConnects narrow prompts with specific capabilitiesProfile services, service-page headings and visible descriptions
    Location or service areaConnects the business to local intentContact page, location pages and public profiles
    Hours and availabilityCan affect results when the user needs an open businessHoliday hours, temporary closures and discrepancies between profiles and the site
    Decision evidenceHelps an eligible candidate earn selectionReviews, qualifications, policies, service details and clear next steps

    Start with the highest-authority fields you directly control. Confirm the exact business name, primary category, current hours, location and core services in Google Business Profile. Then compare those facts with the website. Correct contradictions before expanding the site with more articles.

    Next, standardize the vocabulary used for genuine services. A business can keep its brand voice while still using the ordinary nouns customers put into short prompts. If your profile calls an offering one thing, the service page calls it another and customers use a third term, connect those terms explicitly in visible copy instead of expecting a system to infer the relationship.

    Structured data belongs after this factual alignment. If you publish local business or service markup, make it reflect the verified information visible on the page. Do not use markup to introduce an alternative identity, an unsupported service or different hours. Machine-readable inconsistency is still inconsistency.

    Apply corrections in this order:

    1. Identity: official name, core business type and primary category.
    2. Offer: the services the business actually provides and the distinctions among them.
    3. Place and time: location, service area, hours and availability.
    4. On-page explanation: one substantial destination for each real service-and-location need.
    5. Selection evidence: accurate reviews, qualifications, policies and useful decision details.

    This order prevents a common waste of effort. Reviews and links may strengthen an eligible candidate, but they do not repair a basic misunderstanding about what the business is. Identity work and selection work support different stages of discovery.

    Measure recognition separately from selection
    A visual sequence moves from identifying one relevant storefront on a street to narrowing several business cards and highlighting a final choice.

    A single visibility score will hide the problem you need to fix. Build a small, repeatable prompt set and record two separate outcomes: whether your business enters consideration and what happens after it does.

    Start with 12 prompts as a manageable diagnostic baseline. This is a working set, not a platform requirement:

    • Four narrow prompts: a specific service plus city, neighborhood or postal code.
    • Four broad prompts: the primary business category plus the same locations.
    • Four constraint prompts: a service and location combined with a real decision factor such as current availability or a relevant specialty.

    Run the same core set in Google and ChatGPT. For ChatGPT, also test the natural follow-up “more results” because expansion requests made up a substantial share of the observed follow-ups. Preserve the exact wording instead of rewriting prompts between checks; otherwise, you will not know whether the business changed or the test changed.

    For every prompt, record:

    • Inclusion: did the business appear at all?
    • Interpretation: was it described as the correct type of business and matched to the correct service?
    • Accuracy: were the location, hours, service and other stated facts correct?
    • Selection: did it appear in the initial result or only after expansion, and what evidence was presented with it?
    • Context: the date, prompt wording and any visible citation or destination, so the observation can be compared later.

    Do not treat a manual prompt check as a permanent rank. Results can vary, and the two platforms do not expose the same discovery process. The value of the record is diagnostic: it shows repeated patterns across a controlled set.

    Use those patterns to choose the next action:

    Observed patternLikely area to inspect first
    Absent from narrow and broad Google queriesBusiness identity, primary category and basic location eligibility
    Present for narrow Google queries but absent for broad onesWhether the recognized entity boundary is narrower than the intended market
    Present in Google but absent from ChatGPT checksWhether public service-and-location information is explicit, consistent and supported by usable decision details
    Present in ChatGPT but absent from relevant Google resultsGoogle Business Profile identity and the name-category relationship
    Present in both but rarely selected earlyReviews, accurate availability, usefulness of landing pages and other selection evidence
    Present with incorrect factsThe conflicting public profile or page before any visibility campaign continues

    These are triage rules, not claims about a platform’s private logic. Use them to decide where to inspect, then verify the underlying facts. Change one class of signal at a time – identity, service content or selection evidence – and rerun the same set. A change log will tell you more than an expanding collection of unrelated prompts.

    Key takeaways

    • Local visibility begins with eligibility. Google must recognize the business as a plausible match before reviews, links and other ranking signals can differentiate it.
    • Your business name and primary category form a combined identity signal. Audit that pair against both narrow service queries and broad category queries.
    • Do not abandon keywords for elaborate ChatGPT prompts. In one set of local healthcare and aesthetic searches, 75% of sessions included keyword-style input and 45% ended after one prompt.
    • Use one consistent facts layer across your profile, website, public profiles and structured data: accurate identity, services, location, hours and decision evidence.
    • Track recognition separately from selection. Absence, incorrect interpretation and weak placement are different problems and require different work.

    Your next move is small and concrete: choose four narrow queries and four broad ones, place your exact business name and primary category beside them, and mark where the match becomes ambiguous. That sheet will show whether you need to repair recognition or strengthen the evidence that earns selection.

    Once the identity is clear, carry the same service and location facts through the pages and profiles a customer can encounter. Then repeat the same prompts. Local discovery becomes manageable when you stop treating every absence as a ranking problem.
    References

  • How SEO Agencies Should Adapt Their Strategy for AI Search

    How SEO Agencies Should Adapt Their Strategy for AI Search

    Your agency can still improve rankings and lose the decision. An AI assistant can satisfy an informational query before a prospect visits a website, while that prospect may later use Google to verify the recommendation. If reporting starts and ends with positions, sessions, and last-click conversions, a meaningful part of the journey remains invisible.

    Adapting does not require abandoning SEO or relabeling ordinary content work as generative engine optimization. You still need crawlable pages, sound information architecture, useful content, links, and measurable demand. You also need an operating layer that makes the client’s brand easy to retrieve, interpret, validate, and represent accurately across AI and traditional search.

    Key takeaways for agency leaders

    • Keep technical and content SEO as the eligibility layer. Indexing creates an opportunity to be selected; it does not guarantee selection.
    • Plan campaigns around user decisions, concepts, entities, and supporting evidence, not isolated keywords and URLs.
    • Create a controlled source of truth before scaling content with AI. Conflicting names, claims, prices, and market details weaken the whole brand representation.
    • Give international pages separate URLs when they contain genuine market differences, such as pricing, availability, compliance information, local intent, or local evidence.
    • Measure mentions, citations, recommendations, factual accuracy, and commercial outcomes separately. They are different signals, and no universal AI ranking combines them.
    • Write contracts around work the agency controls and outcomes it can influence. Do not promise a fixed position or guaranteed inclusion in a generated answer.

    Your product is no longer just a ranking report

    Rankings remain useful. They reveal demand, competition, landing-page performance, and changes in conventional search visibility. The mistake is treating them as a complete account of discovery.

    AI search introduces a different sequence. A person can ask for an explanation, compare options inside the generated response, verify a recommendation through Google, and visit only when ready to act. The brand can therefore influence a decision without receiving the first click. It can also receive a click after the assistant has framed the brand inaccurately.

    A Semrush forecast that AI search could surpass organic traffic by 2028 makes this a reasonable planning scenario, but it is still a forecast. It is not a deadline, and it is not a reason to neglect Google. Build for a mixed discovery environment in which search engines, assistants, review sites, editorial lists, and owned pages all contribute to the same decision.

    Agency capabilityKeepAdd
    ResearchSearch demand, keyword groups, intent, competitorsDecision questions, prompt scenarios, entity ambiguity, evidence gaps
    ContentUseful pages that satisfy intent and support conversionSelf-contained answer passages, explicit entity relationships, claim-to-evidence mapping
    AuthorityRelevant editorial links and brand coverageRelevant list inclusion, brand-entity work, and review evidence
    TechnicalCrawling, indexing, canonicals, internal links, rendering, hreflangStructured-data consistency, stable entity identifiers, market-variant governance
    ReportingRankings, clicks, conversions, revenueMentions, citations, recommendations, factual accuracy, market representation

    This changes the campaign brief. A useful brief should identify the decision the user is making, the entity that must be understood, the claims required to answer the question, the evidence supporting those claims, the market in which they apply, and the action the client wants the user to take. A target keyword and preferred URL can still appear, but they no longer carry the whole strategy.

    It also changes the commercial conversation. The agency is not merely increasing visits to a page. It is improving the probability that a brand becomes an eligible, understandable, credible option during discovery and verification. That is a broader job, so the scope and measurement plan must be broader too.

    Rebuild production around entities, claims, and evidence

    An isometric content workflow connects a central subject to claims, source documents, expert input, data, product details, and published pages.

    A search engine can index a page without prioritizing it, and an AI system can retrieve information without representing the business correctly. Clear identity matters: the system needs to resolve the company, its brands, its products or services, the relevant market, and the evidence behind material claims. AI synthesis also works across concepts and entities rather than following an agency’s page-by-page campaign plan. That is why indexing and isolated page optimization are no longer sufficient measures of visibility.

    Create a controlled brand source of truth

    Before commissioning another content batch, create an entity and claim register. This should be a working operational record shared by SEO, content, public relations, developers, localization teams, and whoever approves product or legal claims.

    • Entity: Record the official public name, recognized aliases, parent or subsidiary relationship, product families, and the preferred canonical page.
    • Claim: Write the approved statement precisely. Separate factual attributes from positioning language and opinions.
    • Evidence: Attach the owned URL that substantiates the claim and any credible independent corroboration.
    • Scope: Mark the products, audiences, languages, and markets to which the claim applies. A global default should not silently overwrite a local exception.
    • Status: Assign an owner, approval state, and condition that triggers review, such as a price, policy, availability, or product change.
    • Machine representation: Record the stable entity identifier and the structured-data nodes that should express the same facts.

    The register prevents content writers, public relations teams, feeds, landing pages, and regional sites from publishing different versions of the same fact. That matters because uncoordinated publishing can create semantic drift. A newer or apparently more authoritative page may then become the preferred representation even when it belongs to the wrong market or no longer reflects the client’s strategy.

    Map real decisions to answerable evidence

    Keyword research tells you how people search. An AI-search plan also needs to capture what they are trying to decide. Build a question-to-evidence map using demand data, sales objections, support questions, on-site search, existing customer language, and the comparisons that repeatedly appear in the market.

    1. List the questions people ask while learning, comparing, verifying, and choosing. Do not limit the list to questions that already contain the client’s brand.
    2. Group equivalent questions by concept and user decision. Different wording should not create a separate content assignment when the required answer is the same.
    3. Identify every entity the answer depends on: the company, product, service, location, audience, standard, feature, or market.
    4. Assign a canonical answer and supporting evidence. If the business cannot substantiate an important claim, mark it as an evidence gap instead of asking a writer to make the language sound more certain.
    5. Choose the owned page that should carry the complete answer, then identify supporting pages that provide context without contradicting it.
    6. Find external validation where trust depends on more than an owned assertion. Relevant editorial lists, accurate brand mentions, local affiliations, and substantive reviews can support this layer.
    7. Resolve conflicting facts before publishing. More content amplifies a contradiction; it does not settle it.

    Each important answer passage should survive a simple extraction test. It should make sense when read without the surrounding introduction, name the relevant entity instead of relying on vague pronouns, state material conditions or market limits, and point to evidence where the claim needs support. Avoid unsupported superlatives. Best, leading, safest, and most trusted are weak answer material when the page never establishes the basis for them.

    This is also the safest way to use generative writing tools. Feed them the approved entity record, claim boundaries, evidence URLs, market scope, and content assignment. Review the output against those inputs before publication. The main quality risk is not awkward prose; it is a plausible sentence that changes a condition, drops a regional qualifier, or combines two claims the business cannot actually support.

    Use JSON-LD to clarify facts, not invent them

    Implement structured data after the source of truth is settled. Where applicable, connect Organization, Product, Service, Person, and Article nodes through stable @id values. Use the same entity names and relationships in visible copy, metadata, feeds, and JSON-LD.

    Markup should express facts that a visitor can verify on the page or through an appropriate linked source. If the product feed, page copy, and JSON-LD disagree, fix the underlying system of record instead of deciding that only the markup needs to be correct. Schema can reduce ambiguity and improve machine readability. It cannot manufacture authority or guarantee inclusion, citation, or a fixed position in an AI response.

    Owned consistency still needs independent support. For a local business, reviews should contain genuine details about the service, place, or outcome rather than agency-written keyword patterns. For a brand operating across countries, local expertise, affiliations, and market-specific authority can matter more than global brand strength alone. Record useful third-party corroboration in the same evidence system so content and outreach teams know which claims already have support and which do not.

    Keep technical SEO, but give every control the right job

    International SEO exposes weak AI-search architecture quickly. The same entity appears in several languages, prices and policies vary, regional teams publish independently, and global authority is not always local authority. Technical controls help machines discover and route those versions, but they cannot compensate for pages that say nothing meaningfully different.

    Decide when a market page earns a separate URL

    A country or regional page deserves its own URL when it represents a real market variation. Use this test before expanding the site architecture:

    • Pricing, currency, purchasing terms, or available offers differ.
    • Legal disclosures, regulatory language, or compliance requirements differ.
    • Product availability, delivery, support, or service coverage differs.
    • The local audience has a materially different intent, use case, terminology, or decision process.
    • The page can provide local evidence, such as appropriate reviews, affiliations, expertise, or market-specific proof.

    A translated page can still serve a language need even when the underlying offer is global. What it cannot do is create market differentiation merely by changing the language. Thin localization may leave the system with several pages answering the same intent, and the English version may still be favored globally when the alternatives add no clearer local value.

    Separate routing signals from selection signals

    • URLs and canonicals organize distinct resources and consolidate duplicates. They do not prove that a regional page is useful.
    • Indexability makes a page eligible for conventional retrieval. It does not ensure that the page will be prioritized in a generated response.
    • Hreflang still helps traditional search engines return the appropriate language or regional version. Its influence is more limited in AI-mediated retrieval, where clear market differences and unambiguous data must exist before selection.
    • Localization aligns the answer with local intent, conditions, terminology, and evidence. This is content and product work, not a tag implementation.
    • Local authority validates the brand within the market. Global links and recognition do not automatically establish local relevance.

    Extend the central claim register with a regional override record. For every variable fact, store the global default, local value, reason for the difference, approved URL, responsible owner, and affected locales. Regional teams can then make necessary changes without silently redefining the entire brand.

    Audit the final system in both directions. First, find local pages that are little more than translations and decide what genuine market value they should add. Second, find facts that should be consistent but have drifted across countries. Pay particular attention to brand names, product relationships, price conditions, availability, support promises, and compliance language. A technically flawless hreflang implementation will not resolve contradictory claims.

    Measure selection, accuracy, and commercial movement separately

    Analysts observe three connected views representing AI source selection, factual verification, and a customer's movement toward a commercial decision.

    There is no single AI-search metric equivalent to a stable universal rank. A brand can be mentioned but not recommended, recommended but not cited, cited through the wrong page, or described inaccurately. Combining those states into one visibility percentage hides the problem the agency actually needs to fix.

    Use a layered scorecard

    Eligibility and clarity cover the parts of the system you can inspect directly:

    • Crawling, rendering, indexation, canonicalization, internal linking, and hreflang status
    • Structured-data validity and agreement with visible content
    • Completeness of entity records and claim evidence
    • Consistency across pages, feeds, profiles, and market versions
    • Coverage of priority decisions and supporting concepts

    Selection and representation describe what happens on each relevant AI surface:

    • Mentioned: The brand or product appears in the response.
    • Cited: The response links to or names an owned or third-party source connected to the brand.
    • Recommended: The brand is presented as a suitable option for the stated need.
    • Accurate: Material claims, relationships, conditions, and market details are represented correctly.
    • Actionable: The user receives a useful route to verify the claim, visit the correct page, or take the intended next step.

    Commercial movement connects visibility to the client’s actual objective:

    • Identifiable referral visits from AI platforms
    • Qualified leads, sales, bookings, or other agreed conversions from those visits
    • Assisted conversions where the available analytics can support the connection
    • Lead quality and customer-reported discovery information, when collected consistently
    • Branded search and direct traffic as contextual trends, not automatic proof of AI impact
    • Organic visits that support verification after an AI-assisted discovery journey

    Do not reclassify unexplained direct traffic as AI traffic. Do not claim that a rise in branded search proves an assistant caused it. Use those signals as supporting context and state the attribution limit clearly.

    Make prompt monitoring reproducible

    Your monitoring set should represent real audience decisions, not prompts engineered to force the client’s name into an answer. Include non-branded learning, comparison, selection, and verification questions. Segment them by market and language when the expected answer genuinely differs.

    • Save the exact prompt and any context supplied with it.
    • Record the platform, model or interface when visible, language, market assumption, and observation date.
    • Capture the complete relevant response, not only the favorable sentence.
    • Log mentions, recommendations, cited domains, cited URLs, material claims, and factual errors separately.
    • Repeat observations under comparable conditions and report the pattern. A favorable screenshot is an example, not a rank.
    • Keep platform findings separate before producing a combined executive view. Different products can retrieve, synthesize, and cite differently.

    Use the observations to choose work, not merely to produce charts. An inaccurate product relationship points back to entity governance. A correct mention with no supporting citation suggests an evidence or authority gap. A citation to an irrelevant market page points to localization and routing. Strong representation with no commercial action may reveal a weak landing experience or an offer mismatch.

    Rewrite the client promise around control and influence

    An agency can control technical implementation, owned content, structured data, internal governance, measurement design, and the quality of outreach. It can influence independent coverage, reviews, citations, and AI selection. It cannot guarantee a fixed answer, exact wording, universal visibility, or a permanent position on a third-party platform.

    Make that boundary explicit in the scope of work. A defensible AI-search engagement can promise an audited entity register, a decision-question baseline, prioritized technical and content fixes, a structured-data plan, authority-building work, market consistency checks, and a repeatable observation protocol. Report completed interventions and observed changes without turning correlation into certainty.

    Client reviews should answer practical questions: Where did the brand become more or less selectable? Which factual errors appeared? Which owned and independent pages were cited? What evidence gap is blocking the next priority decision? Did qualified demand or pipeline move alongside visibility? What intervention will test the next hypothesis?

    Before adding another AI-search package to the service menu, apply this operating model to an active account with a clear offer and usable evidence. Build the entity register, map decision questions to claims, inspect the relevant AI surfaces, and fix the highest-consequence contradictions before scaling production. That gives your team a strategy it can execute and your client a result that can be inspected, challenged, and improved.

    References

  • AI and Organic Search Traffic: How to Diagnose a Decline

    AI and Organic Search Traffic: How to Diagnose a Decline

    If your organic dashboard is down, “AI killed search” is an easy diagnosis and a useless one. It does not tell you whether rankings slipped, search demand changed, or the results page satisfied more people before they clicked. Each problem requires a different response.

    The wider market is not in free fall, but an average cannot protect an individual site. You need to identify where your click opportunity has narrowed, protect the queries tied to business outcomes, and make priority pages useful beyond the answer already visible in search.

    Key takeaways

    • Estimated organic traffic across 40,000 of the largest U.S. sites declined 2.5% year over year, which indicates contraction rather than the disappearance of search.
    • AI Overviews appeared on roughly 30% of measured results pages and were associated with a 35% reduction in organic click-through rate when present, with informational queries carrying more exposure.
    • Do not treat every traffic loss as an AI problem. Separate lost rankings, lower impressions, weaker click-through rates, analytics discrepancies, and changes in query mix.
    • Keep the direct answer easy to extract, then give the reader decision criteria, evidence, tools, comparisons, or a next step worth clicking for.
    • Measure conversions and other business outcomes alongside clicks. Losing low-value informational visits is different from losing high-intent demand.

    Treat the market data as context, not your diagnosis

    Organic search traffic across 40,000 of the largest U.S. websites fell an estimated 2.5% year over year. The measurement used Similarweb visit data covering February through December 2024 and January through November 2025. Over the 2025 period, total search-engine traffic increased 0.4%, while Google traffic increased 0.8%.

    That is not evidence of an industry-wide collapse. It is evidence of a modest aggregate decline in organic visits while search activity, considered more broadly, remained approximately stable. The distinction matters because “search is dying” leads teams to abandon a channel, while “some searches produce fewer clicks” leads them to diagnose where the economics have changed.

    The aggregate also hides a sharp distribution by site size. The ten largest sites gained 1.6% in organic traffic, while sites ranked between the top 100 and top 10,000 experienced more noticeable declines. A stable market can therefore coexist with a painful loss for a mid-sized publisher. Scale, brand demand, topic mix, and exposure to particular result-page features can produce very different outcomes.

    The numbers are estimates, not a census of every search or a forecast for your domain. Similarweb combines opt-in panels, ISP and mobile-carrier information, public web signals, and direct site measurements. Comparisons against first-party Google Search Console and Google Analytics data produced a median correlation of 0.86 across the sites checked. That supports using the data for market direction, but it does not make 2.5% an acceptable loss, a benchmark, or an expected result for your site.

    Your own page and query data must decide what you do next. If your organic decline is materially larger than the market movement, do not explain the gap with a broad AI narrative. Find the pages, intents, devices, countries, and result-page conditions that account for it.

    Separate ranking loss from AI-related click compression

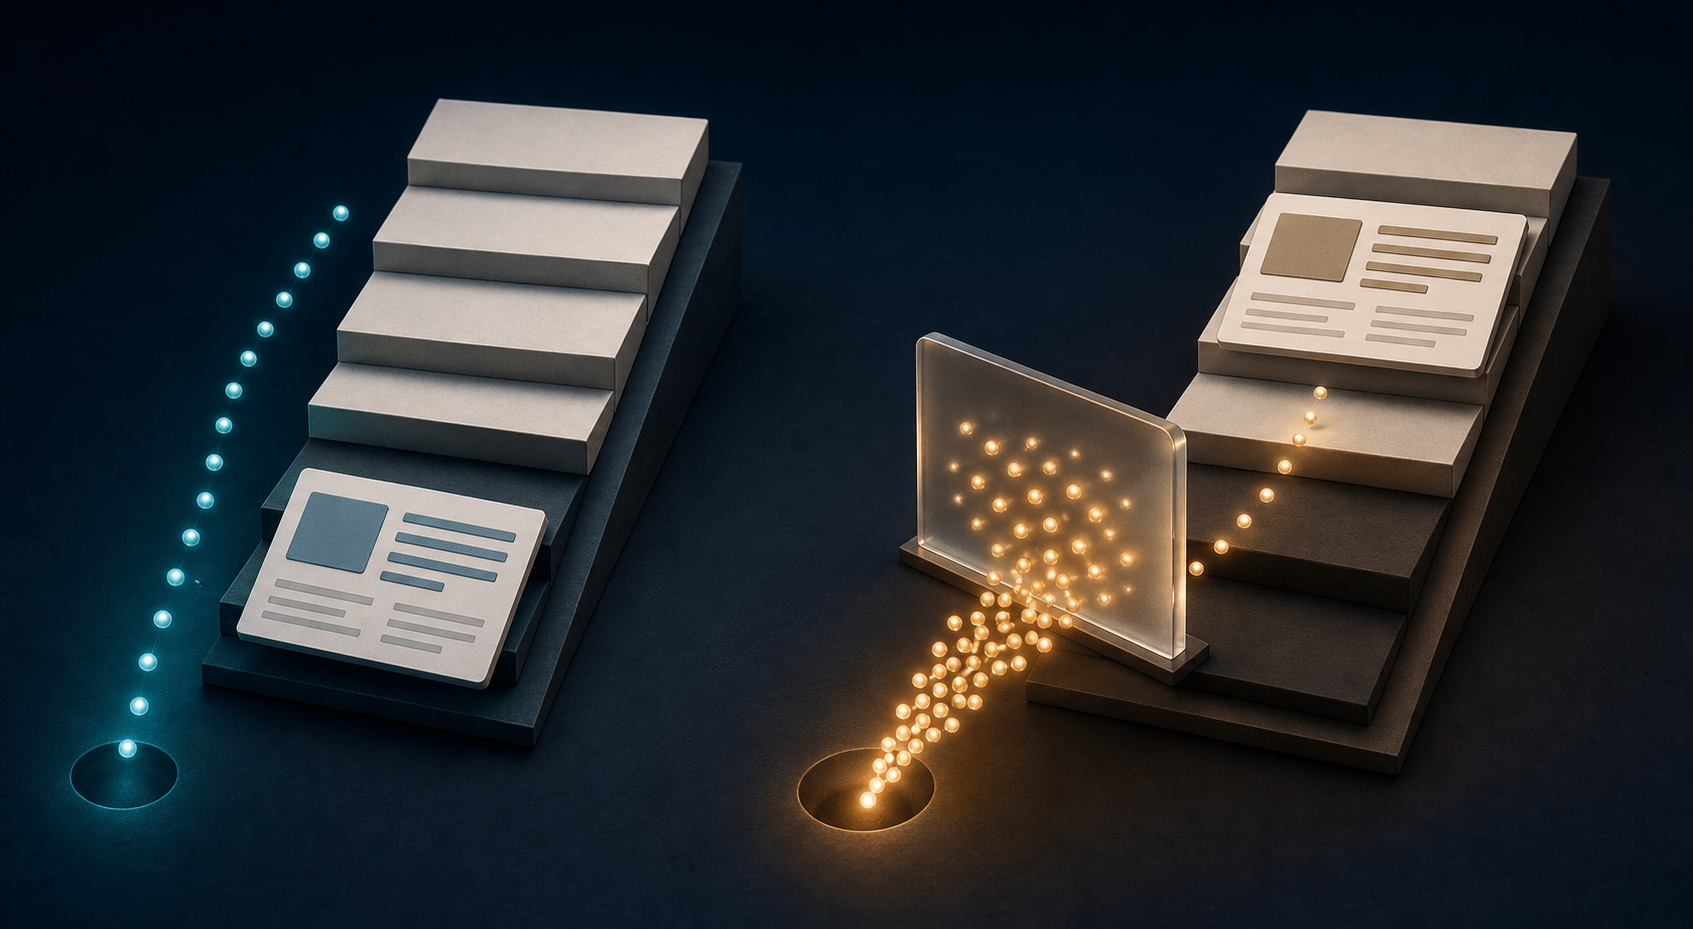
    Two parallel search journeys show one webpage tile dropping down a stack while another remains prominent but receives fewer glowing particles.

    AI Overviews create a real click-through problem, but not a uniform one. They appeared on roughly 30% of measured search results, predominantly for informational queries. When an AI Overview was present, organic click-through rate was 35% lower. Commercial and transactional searches were notably less affected.

    Do not multiply those two percentages and treat the result as your expected traffic loss. AI Overviews are not distributed randomly across queries. A reference publisher answering many definitions and how-to questions can have much greater exposure than a business whose visibility comes mostly from product, service, comparison, branded, or purchase-oriented searches.

    Build a diagnostic sheet with a row for each important page-query combination. Include the landing page, query, primary intent, current and comparison-period impressions, clicks, click-through rate, average position, AI Overview presence, other prominent search features, and the business outcome associated with the visit. This keeps a site-wide average from hiding the mechanism behind the loss.

    1. Export matching periods from Google Search Console. Use a year-over-year comparison when seasonality affects demand, and segment by page, query, device, and country before drawing conclusions.
    2. Assign each material query a primary intent: informational, commercial or comparison, transactional, branded, or navigational. Imperfect classification is still more useful than treating every click as equivalent.
    3. Compare impressions, position, and click-through rate together. A click decline means little until you know which of those inputs changed.
    4. Inspect the live result pages for representative queries. Record whether an AI Overview is present, what it answers, which pages it cites, where your result appears, and which other features compete for attention. Note the date, location, and device because result layouts can vary.
    5. Connect affected landing pages to conversions, qualified leads, revenue, subscriptions, or the outcome your site is designed to produce. This establishes whether you lost business demand or visits that rarely moved beyond the initial answer.
    Pattern in your dataWhat it may indicateWhat to check next
    Impressions and position are stable, but click-through rate fallsThe result page may be absorbing more clicks through an AI Overview or another featureInspect the affected queries and compare the answer visible in search with the additional value on your page
    Average position falls on the same page-query combinationsA ranking problem, not merely click compressionCheck relevance, content quality, internal linking, indexability, technical changes, and competing results
    Impressions fall while positions remain broadly stableLower demand, a changed query mix, or reduced eligibility across related searchesCompare individual queries and countries rather than relying on the site-wide impression total
    Search Console clicks remain stable while analytics sessions fallA measurement or channel-classification discrepancyCheck landing-page tracking, consent behavior, channel rules, and the date of analytics changes
    Clicks fall but conversions remain stableThe lost traffic may have carried relatively little business valueIdentify which intents disappeared before spending resources to restore the volume
    High-intent clicks and conversions fall togetherA direct demand-capture problemPrioritize the affected commercial pages and queries over broad informational traffic recovery

    Average position deserves particular care. It can change because your query mix changed, even when the rankings for your most important queries did not. Make decisions from stable page-query segments wherever possible, not from one domain-level average.

    Build pages for the part of the task search cannot finish

    A person's hands use comparison pieces, controls, and modular tools at a workbench to turn a simple information card into a completed solution.

    A simple informational query may no longer require a visit when the result page supplies a sufficient answer. Making your content vague will not recover that click. It will make the page less useful to readers and less understandable to the systems evaluating it.

    Keep the immediate answer concise, accurate, and easy to extract. Then design the page around the decision or action that follows. The search result can state a fact; your page should help the reader apply it under real constraints.

    1. Answer the primary question near the start. State the conclusion, the conditions under which it holds, and any limitation that would materially change the answer.
    2. Add continuation value. Useful options include decision criteria, trade-offs, a worked process, comparisons based on explicit factors, calculation inputs, downloadable templates, or original observations with a transparent methodology.
    3. Show the next relevant question. Link an informational page to a comparison, implementation, service, product, or evaluation page only when that destination is the natural next step for the same reader.
    4. Strengthen higher-intent pages. Because commercial and transactional searches have been less affected by AI Overviews, pages supporting evaluation and action deserve focused attention. Make compatibility, constraints, process, evidence, and the next step explicit.
    5. Use structured data to describe what the page genuinely contains. Choose a schema type that matches the primary entity, keep JSON-LD consistent with visible content, and do not mark up claims or attributes a reader cannot verify on the page. Schema can improve machine interpretation; it cannot guarantee a ranking, citation, or click.
    6. Match the edit to the diagnosed loss. If rankings fell, address the ranking problem. If rankings held while click-through rate fell, improve the page’s distinctive value and its path to a meaningful next action. Rewriting everything as an “AI optimization” project obscures that difference.

    For informational content, ask one hard question during the audit: after a searcher has read the short answer, what legitimate reason remains to visit? “More words” is not a reason. A defensible recommendation, a transparent comparison, a tool, a reusable workflow, or evidence that changes the decision can be.

    Do not mass-delete or redirect pages because the domain total declined. Redirecting changes which URL can rank and can be difficult to unwind cleanly. Export the page-query history, record the current target, and consolidate only when multiple pages genuinely serve the same intent and one clear destination can satisfy it. A market trend is not enough evidence to erase a page’s accumulated search value.

    Measure business contribution, not traffic volume alone

    Organic search still accounts for approximately 90% of the measured clicks between organic results and ads, compared with about 10% for advertising. The ad share increased by roughly two percentage points, but that modest shift does not support the claim that paid listings have broadly replaced organic opportunity.

    That does not mean every organic click retains its former value. It means you should avoid abandoning SEO or reallocating budget based on a general story about AI or ads. Make the decision from a scorecard that separates visibility, traffic, and business contribution.

    • Search capture: impressions, clicks, click-through rate, and position, segmented by page, query intent, device, country, and observed result-page features.
    • Business contribution: conversions, qualified leads, revenue, subscriptions, assisted outcomes, and conversion rate by organic landing page where your measurement supports them.
    • AI discovery: referral visits from identifiable AI assistants, observed mentions or citations for priority questions, and the landing pages receiving that exposure. Keep these separate from organic search so channel changes remain visible.
    • Content action: whether each declining page needs ranking remediation, stronger continuation value, consolidation, a better internal path, or no action because the lost visits did not support a meaningful outcome.

    Use explicit decision rules. A high-intent page losing rankings and conversions belongs near the top of the backlog. A stable-ranking page losing informational clicks to an AI Overview needs deeper decision support and a stronger route to the next task. A page losing clicks while retaining its conversions may not need traffic restored at any cost. If clicks remain stable but outcomes fall, investigate the offer, page experience, tracking, or audience fit before blaming search.

    AI exposure may contribute to later branded searches or direct visits, but ordinary analytics cannot prove that relationship from timing alone. Monitor branded-query demand and direct traffic if the possibility matters to you, then label the finding as directional unless you have a reliable attribution method.

    Start with the page-query combinations responsible for your largest high-intent loss. If position fell, fix the SEO problem. If position held and click-through rate fell where an AI Overview appears, preserve the direct answer while adding value that helps the reader decide or act. Recheck the same segment after new data accumulates. That turns a vague fear about AI into a measurable work queue.

    References

  • Machine-Only Pages in Search: When and How to Use Them

    Machine-Only Pages in Search: When and How to Use Them

    You don’t need to build a second website for bots just because your team wants more visibility in AI search. You need to identify what machines cannot reliably retrieve, understand, or verify on the page you already publish.

    A machine-only page can solve that problem, but only when it acts as another representation of the same facts. If it becomes a hidden version of your business, it creates duplicate content, governance problems, and a familiar cloaking question: why is a crawler receiving information your visitors cannot inspect?

    A separate page must solve a real extraction problem

    The label “machine-only” covers several very different implementations. It might mean a public text-first companion to an interactive page, a structured feed generated from the same database, an alternative response selected by media type, or content delivered only when a particular bot identifies itself. Those choices do not carry the same risk.

    The practical case for machine-only pages in AI search begins with a genuine mismatch: a useful human interface is not always an efficient extraction surface. Product configurators, interactive tools, dashboards, long documentation sets, and frequently updated records can make essential facts difficult to isolate. A compact representation can remove interface mechanics without changing the underlying information.

    That does not mean every difficult page needs a duplicate. Start with the canonical page and inspect the response a crawler can actually retrieve. Check whether the subject, answer, qualifications, evidence, and update state are present without a login, a cookie-dependent session, or a sequence of interactions. If they are missing, fix the main page first whenever that also improves the visitor’s experience.

    Observed problemBetter first moveWhen a separate representation may be justified
    The page’s subject or answer is ambiguousRewrite the title, headings, summary, and entity referencesOnly when a compact record must combine facts that legitimately remain distributed in the human interface
    Core facts appear only after interactionAdd a server-delivered summary containing the essential factsWhen the interactive product must remain dynamic but the underlying public record can be published independently
    A long document is difficult to navigateAdd descriptive sections, anchors, a contents list, and explicit version informationWhen machines need a stable consolidated representation spanning a versioned document set
    The team merely wants a page “for AI”Define the failed retrieval or extraction task firstNot until a reproducible failure shows what the alternative page must improve

    A useful decision rule is simple: do not create a separate surface unless you can name the extraction failure, reproduce it, and specify the field or relationship the new representation will make clearer. “More AI visibility” is an outcome you may want, but it is not a technical requirement and it does not tell a developer what to build.

    Keep the representation separate from the truth

    A transparent central vault sends the same colored geometric facts to a visual page and a machine-readable array.

    The safest architecture has one editorial source of truth and multiple generated views. The human page can emphasize explanation, navigation, visual comparison, and conversion. The machine representation can emphasize explicit entities, stable identifiers, complete qualifications, provenance, and predictable structure. The facts must remain the same.

    Run a parity test before you debate formats. Place the human and machine versions side by side and ask:

    • Do they identify the same entity, product, organization, policy, or event?
    • Do they make the same factual claims?
    • Does every condition, exception, unit, territory, audience, and status survive the transformation?
    • Do they point to the same canonical evidence?
    • Do their version and update fields describe the same publishing state?
    • Could a person with the machine URL inspect the representation without pretending to be a bot?

    If the answer fails on facts, qualifications, or freshness, you do not have two representations. You have two competing records. That is a content-governance defect even before search policies enter the discussion.

    Bot-specific delivery deserves particular caution. Changing presentation because a client requests a machine-readable media type can be a clean form of content negotiation when the facts remain equivalent. Changing claims because the request carries a named crawler identity is harder to defend. It also makes testing fragile: a renamed, proxied, or unidentified client may receive a different truth.

    Do not publish private, licensed, customer-specific, or security-sensitive information on a machine page. A URL omitted from navigation is still a public URL, and robots directives are not access control. If a representation requires authorization, put it behind real authentication and treat it as a controlled feed or API rather than a public search page.

    Decide what the alternate URL is supposed to be

    Your indexing choices should follow the page’s job:

    • Extraction companion: The alternate is public but derivative. Link back to the primary page, identify that page as the canonical destination, and avoid presenting the companion as another search landing page.
    • Independent landing page: The alternate is intended to appear in conventional search. Give it distinct value for people, include it in normal navigation, and accept that it is no longer meaningfully machine-only.
    • Controlled data service: The representation exists for approved agents or partners. Use authentication, documented permissions, versioning, and an operational support plan. Do not rely on public search discovery.

    Canonical and indexing directives express intent; they do not repair contradictory content. Decide which URL should be found, which should be presented to searchers, and which is merely a derivative representation. Record those decisions in the technical specification before launch.

    Build it as a governed publishing surface

    A machine page should not be an AI-written summary generated after publication. Summarization introduces another interpretation layer precisely where you need factual stability. Generate both views from shared fields, using deterministic templates wherever possible.

    1. Define the content object. Model the organization, product, service, location, person, document, or event independently of either page layout.
    2. Write a representation contract. Specify the required fields, allowed values, relationships, validation rules, and treatment of missing information.
    3. Choose the canonical record. Every machine representation should expose the URL or stable identifier of the human-facing record it describes.
    4. Generate both outputs from shared fields. A correction to a claim, date, status, or qualification should update every public representation through the same publishing event.
    5. Keep the output inspectable. Return a normal successful response, use a stable URL, and avoid requiring bot impersonation merely to view public information.
    6. Validate before publication. Block or flag output when required fields are empty, identifiers do not resolve, evidence links fail, or the generated representation has fallen behind its canonical record.
    7. Plan retirement. When the canonical content is removed, merged, or superseded, update or retire the machine representation in the same workflow.

    The representation contract is where most of the value lives. For each eligible content type, include only fields that help a machine identify, interpret, or verify the record:

    • An unambiguous entity name and type
    • A literal summary that states what the record is about
    • Stable internal or public identifiers
    • The canonical human-facing URL
    • Primary claims with their necessary conditions, units, scope, and status
    • Relationships to relevant entities, expressed with clear labels
    • Evidence or citation links already supported by the canonical content
    • Version, effective-date, expiration, or last-updated fields when those concepts apply
    • A language or territory designation when the facts vary by locale

    Completeness does not mean copying every navigation label, promotional module, or design instruction. It means preserving everything required to interpret a claim correctly. If a price depends on territory, a policy has an effective date, or a feature applies only to one plan, the qualifier belongs beside the claim. A shorter record that removes the qualifier is not cleaner; it is wrong.

    Apply the same rule to JSON-LD and other structured data. Structured markup should describe the content and entities the page genuinely represents. Do not use it as a second channel for claims absent from the governed record. If your HTML, machine view, and structured data disagree, adding more markup increases ambiguity rather than authority.

    Measure whether machines can use it correctly

    Abstract crawler devices pass geometric fact tokens through validation gates, with one mismatch separated for review.

    A crawler request in a server log proves that a request occurred. It does not prove that the system understood the entity, retained the qualifications, trusted the evidence, cited the page, or sent a visitor. Treat delivery as the beginning of measurement, not the result.

    Build a fixed evaluation set from the questions each content type should answer. For a product, that might cover identity, purpose, eligibility, compatibility, availability, and important limitations. For documentation, it might cover the applicable version, prerequisites, procedure, expected result, and known exceptions. Use the same questions on the canonical page and the proposed machine representation.

    • Delivery: Can the approved client retrieve the representation without an accidental session, cookie, or interface dependency?
    • Extraction: Can each required field be recovered accurately, including its label and relationship to the subject?
    • Qualification: Do conditions and exceptions remain attached to the claims they constrain?
    • Identity resolution: Can the record be distinguished from similarly named products, organizations, locations, or versions?
    • Evidence integrity: Do cited links resolve, and does the canonical material support the associated claim?
    • Parity: Does a field-by-field comparison reveal any unauthorized difference between representations?
    • Freshness: Does a publishing change reach the machine representation through the expected workflow?
    • Search outcome: Is there a verified change in discovery, correct citation, qualified referral traffic, or another outcome defined before launch?

    Compare extracted values against the governed fields, not against another generated summary. AI output can be one test client, but it should not become the ground truth used to grade itself.

    Watch for failure signals that call for intervention: stale machine records, stripped qualifications, unresolved entity references, duplicate landing pages appearing where only one was intended, or a growing page count without a corresponding improvement in the extraction task. These are reasons to pause expansion, fix the publishing contract, or retire the alternate surface.

    Roll out by content type rather than sitewide. Choose one reproducible extraction failure, preserve the pre-launch result, publish the smallest representation that addresses it, and repeat the evaluation. Keep a rollback path. If the canonical page can absorb the improvement without compromising its human purpose, prefer that simpler architecture.

    Key takeaways

    • A machine-only page is useful only when it fixes a defined retrieval, extraction, identity, or verification problem.
    • The human and machine views may differ in structure, but their facts, qualifications, evidence, and publishing state must remain aligned.
    • Generate both representations from one governed content model instead of summarizing one page into another.
    • Public machine pages must not contain information you expect navigation, robots directives, or obscurity to protect.
    • Measure correct extraction and business outcomes separately from crawler activity.
    • Expand only after a small rollout demonstrates that the alternate representation solves the failure you designed it to solve.

    Your next move is not a sitewide machine-page project. Pick one important page, write down the exact fact or relationship machines currently misread, and test whether a clearer canonical page fixes it. Build a companion representation only when that test gives you a specific reason to maintain one.

    References

  • Search Visibility Fundamentals That Still Matter in AI

    Search Visibility Fundamentals That Still Matter in AI

    If your pages still rank but your brand is absent from AI-generated answers, you may assume you need a separate AI search playbook. Start lower in the stack: can each system reach your information, understand what it means, and find enough reasons to trust it?

    Your goal is not to produce a different version of the business for every interface. Build a dependable information layer that serves search engines, AI systems, and the person making a decision. The order matters: access first, meaning next, confidence after that, and usefulness throughout.

    AI search added a new output, not a new foundation

    Traditional rankings still matter, but they no longer describe the full discovery journey. AI systems can surface a brand, product, or fact without sending a visit, which means rankings and clicks reveal only part of your visibility.

    It helps to separate two outcomes:

    • Destination visibility: a search result or AI citation gives the user a path to your site.
    • Answer visibility: your brand or information appears directly in a generated response, whether or not the user clicks.

    The more valuable outcome depends on the task. Someone checking an address or availability may only need a fact. Someone evaluating an expensive or complicated purchase may need the full page. Measure both outcomes instead of treating every search as a race for the same click.

    Do not confuse appearance with success, either. If an AI response names your brand but gives the wrong policy, location, capability, or product detail, that is a visibility failure. You were discovered, but the information layer did not preserve your meaning.

    SEO, AEO, and GEO can therefore be treated as different views of the same visibility stack:

    1. Access: the information is public, crawlable, fast, and reliably retrievable.
    2. Interpretation: the entity, page purpose, attributes, and relationships are unambiguous.
    3. Confidence: important facts agree across your site and other relevant surfaces, while authority, reviews, and reputation support them.
    4. Usefulness: the content resolves the user’s actual question and makes the next step clear.

    Audit those layers in that order. Rewriting a paragraph will not remove a crawler block. Adding schema will not reconcile conflicting business information. Brand mentions cannot rescue an answer that never addresses the user’s need.

    Make important facts easy to retrieve and hard to misread

    Illuminated objects representing facts sit in organized compartments connected by clear paths to a retrieval mechanism and an AI node.

    Begin with the information that must remain correct when someone evaluates your business. Depending on the organization, that could include identity, offerings, locations, availability, service areas, compatibility, policies, contact details, and the qualifications attached to a claim.

    Create a fact map before changing pages. For each important fact, record:

    • the approved value or wording;
    • the primary page or system that owns it;
    • every page, profile, feed, or markup field where it is repeated;
    • the person or team responsible for approving changes;
    • the event that should trigger an update.

    This turns content accuracy into an operating process. Without an owner and an update path, a changed policy can remain correct on its main page while an old version survives in structured data, a business profile, or a comparison page.

    Check retrieval before rewriting the answer

    A page can look fine in a logged-in browser and still be difficult for a crawler to use. Check the public experience rather than relying on the CMS preview.

    • Can an unauthenticated visitor reach the preferred URL through a logical internal-link path?
    • Does the URL return a normal successful response without requiring a login, form submission, or dismissible screen?
    • Do robots directives permit the crawlers you intend to serve?
    • Do redirects and canonical signals lead to the page that owns the information?
    • Is the important text available in the rendered page rather than appearing only after an optional interaction?
    • Does the page respond consistently and quickly enough to be retrieved without repeated failures?

    These checks are not legacy housekeeping. Fast, trustworthy, crawlable data remains the foundation for conventional ranking systems and LLM-based discovery alike. A system cannot select information it cannot obtain.

    Then remove ambiguity from the content

    Once retrieval works, inspect the answer itself. Put the direct response close to the question it resolves. Name the entity instead of relying on a chain of vague pronouns. Carry essential qualifiers such as plan, version, region, audience, or limitation into the sentence that contains the claim.

    A useful answer pattern is: [Product] supports [requirement] for [qualifying plan, version, or region]. [Limitation] applies. That structure is more extractable and safer for the reader than a broad claim followed by an exception several paragraphs later.

    Headings should describe the decision being made, not merely the theme of the page. Flexible plans is a theme. Monthly and annual billing options is a decision-relevant label. The heading, answer, supporting details, and next step should all refer to the same intent.

    Use JSON-LD to express visible facts when an appropriate schema vocabulary and property exist. The markup should mirror the page, not become a private version of the truth. If the page carries an old value and the structured data carries a new one, adding more markup only creates another conflict. Correct the owning data first, update the visible content, and then regenerate its machine-readable representation.

    Build trust by controlling facts, not by decorating claims

    AI visibility is often discussed as if it were mainly a content-format problem. Formatting helps interpretation, but accuracy, consistency, reviews, and brand authority also affect whether a brand is surfaced.

    Trust is not a field you can add to schema. It grows when a claim is specific, its context is visible, the underlying fact remains consistent, and other relevant signals do not contradict it. Work through four kinds of alignment:

    • Identity alignment: use the correct organization, location, product, and service names wherever those entities appear.
    • Claim alignment: make sure summaries, detail pages, structured data, feeds, and profiles agree on material facts and qualifications.
    • Time alignment: update changed hours, availability, policies, offers, and capabilities at their owner before updating downstream copies.
    • Reputation alignment: monitor reviews and public feedback for recurring factual confusion. If several people misunderstand the same condition, inspect the page and profile information that shaped the expectation.

    Consistency does not mean repeating the same paragraph everywhere. A support page, product page, and business profile can use different wording. The underlying facts must agree.

    A simple source hierarchy prevents many conflicts. Let the primary business system or canonical page own the fact. Let visible page copy explain it. Let structured data represent it. Let profiles and feeds distribute it. Let editorial content point back to the owner instead of quietly redefining the fact.

    When a conflict appears, correct the owner first and work downstream. Editing only the most visible copy creates temporary agreement while leaving the same error ready to return during the next update.

    Brand recognition and site performance can strengthen visibility, but they work only after the platform is accessible and understandable. Authority is an amplifier, not a substitute for a functioning information layer.

    Audit visibility in the order failures actually occur

    A beam passes through an open gateway, an organizing chamber, supporting anchors, and a clear lens before reaching a person.

    A useful audit should tell you what failed, not merely assign a score. Use the same diagnostic sequence for traditional results and AI-generated answers.

    1. Build a decision-focused query set. Start with the questions people need answered before they can identify, evaluate, choose, or use your offering. Draw language from customer support, sales conversations, on-site search, and audience research where those inputs are available.
    2. Capture a baseline on each relevant surface. For conventional search, record the page shown, how it is described, and whether the result supports the intended task. For AI responses, record whether the brand appears, whether the facts are accurate, whether a source is linked, and which page is selected.
    3. Trace the answer to its owner. Identify the page or data system that should supply the correct fact. If no reliable owner exists, you have an information architecture problem before you have a ranking problem.
    4. Classify the first observable failure. An inaccessible page indicates a technical access issue. A retrieved but misunderstood answer points toward unclear content, entity confusion, or inadequate structured representation. A wrong value points toward conflicting data. A clear and accessible answer that is repeatedly omitted calls for closer examination of coverage, authority, reputation, and competition.
    5. Fix dependencies from the bottom up. Restore access, establish the canonical fact, improve visible wording, align structured data, update relevant profiles or feeds, and then strengthen supporting authority signals.
    6. Run the same checks again. Keep query wording and evaluation criteria consistent. AI outputs can vary, so do not treat a single response as a settled measurement. Look for repeated improvement in inclusion, accuracy, source selection, and the quality of any resulting visits.

    The classification is a working diagnosis, not proof of a ranking factor. Its purpose is to narrow the next investigation. If the correct page cannot be retrieved, there is little value in debating prose. If the page is available but carries conflicting facts, acquiring more mentions may spread the problem rather than solve it.

    Keep conventional metrics such as rankings and clicks, but add measures suited to answer visibility: whether the brand is included, whether material facts are correct, whether the right source is cited, and whether the user has a useful next step. A blended visibility score can be convenient, but it should never conceal which layer failed.

    The final quality check belongs to the user. Can a person confirm the answer without guessing? Are the conditions and limitations adjacent to the claim? Is the next action clear? Customer satisfaction remains the practical goal; crawlability and structured data are how you become eligible to serve it at scale.

    Key takeaways

    • AI search changes where an answer may appear, but it still depends on accessible, understandable, trustworthy information.
    • Optimize a shared information layer instead of creating conflicting versions for search engines, AI systems, and business profiles.
    • Fix crawlability and retrieval before rewriting content or expanding schema.
    • Give each material business fact an owner, a canonical location, and a defined path to every place it is repeated.
    • Keep visible content and JSON-LD aligned; structured data clarifies facts but cannot repair a contradictory source of truth.
    • Measure answer inclusion and factual accuracy alongside rankings and clicks.

    Start with the highest-value customer question your brand should answer without ambiguity. Trace its answer from the owning data to the page, markup, relevant profiles, search result, and AI response. Fix the first break you find, then move to the next question.

    Add new tools only when they help you observe or maintain one of those layers. A new visibility score is useful when it directs a repair; it is not the repair itself.

    References

  • GEO Optimization Myths: What Holds Up Under Scrutiny

    GEO Optimization Myths: What Holds Up Under Scrutiny

    Your GEO backlog probably contains a mix of sensible maintenance, plausible experiments, and tactics that became urgent only because enough people repeated them. The hard part isn’t finding another recommendation. It’s deciding which recommendations deserve your budget, developer time, and editorial attention.

    You can make that decision without pretending every uncertainty has been resolved. Grade the evidence, match the evidence requirement to the cost of being wrong, and keep proven hygiene separate from speculative AI-search tactics.

    Before you accept a GEO tactic, grade the claim

    Three abstract claim objects rest on supports of different stability beside a magnifying glass and precision balance on a laboratory workbench.

    GEO discussions often collapse several different questions into one: Is the mechanism technically plausible? Has anyone observed an effect? Can the effect be repeated? Does it apply to your pages, queries, and target AI systems? Is it valuable enough to justify implementation?

    A confident answer to the first question doesn’t answer the other four. Use the following ladder to identify what you actually have:

    1. Statement: Someone has made a claim, such as “this file helps AI systems cite your site.” Repetition and popularity do not move it beyond this level.
    2. Fact: A specific, verifiable condition is established. For example, a named platform explicitly documents support for a feature.
    3. Data: You have observations, such as crawler requests, citation records, or changes in visibility. Data can be genuine without showing what caused the result.
    4. Evidence: The observations are connected to a defined hypothesis, and credible alternative explanations have been considered.
    5. Proof: The evidence is strong enough to support the conclusion within a clearly stated scope. Many GEO claims never reach this level.

    You don’t need proof before every low-cost, reversible test. You do need a higher standard before approving a site-wide deployment, changing hundreds of pages, creating recurring editorial work, or promising a visibility result to a client. The larger the cost of being wrong, the higher you should climb before acting.

    Write a short claim card before adding a tactic to your roadmap:

    • Exact claim: What is supposed to improve?
    • Target system: Which named search engine, chatbot, or AI interface is expected to respond?
    • Mechanism: How would the change produce the result?
    • Observable outcome: What would you measure if the claim were true?
    • Evidence level: Do you have a statement, fact, data, evidence, or proof?
    • Cost of error: What work, money, or opportunity would be lost if the claim failed?
    • Decision: Ship, test, monitor, or reject.

    This exercise exposes vague advice quickly. “Optimize for LLMs” isn’t testable. “Adding this file will cause a named crawler to request specified pages more often” is testable, even if the answer turns out to be no.

    Watch your own reasoning as carefully as the claim. Confirmation bias makes supporting examples feel decisive while contrary examples receive extra scrutiny. Binary thinking turns “not proven” into “useless” and “technically possible” into “required.” Neither move is sound. A tactic can be plausible but unverified, useful for one purpose but not another, or worth monitoring without being worth implementing.

    Myth 1: Every site now needs an llms.txt file

    The promise behind llms.txt is attractive: place information in a centralized file so AI systems can find, understand, and cite your material more easily. The missing piece is demonstrated support. The current case rests largely on advocacy rather than proof of meaningful adoption or citation gains, so llms.txt has not earned essential-infrastructure status.

    That conclusion is narrower than “llms.txt will never matter.” A proposed convention can gain support later. It can also remain optional, be interpreted differently across platforms, or never produce the business outcome attached to it. Your roadmap should preserve that uncertainty.

    Use three checks before prioritizing implementation:

    1. Look for explicit support from the system you care about. A general claim about “AI” isn’t enough. You want documentation or another verifiable indication tied to a named platform.
    2. Define the observable behavior. Decide whether success means recognized crawler activity, different crawl volume, improved retrieval, more citations, or something else. Those are separate outcomes.
    3. Compare the test with the displaced work. Even a technically easy file has an opportunity cost if it delays page corrections, internal linking, schema maintenance, or content that answers an unmet query.

    If a stakeholder insists on adding the file, treat it as an experiment rather than a completed optimization. Record the version you published, the intended system, the expected behavior, and the evidence that would justify keeping or expanding the work. If you can identify relevant bots in server logs, preserve a before-and-after view of their requests. Don’t convert an ambiguous traffic or citation change into a success claim without ruling out concurrent content, technical, and demand changes.

    Move llms.txt from “monitor” to “test” when a reputable platform documents support or you can observe relevant crawler behavior. Move it from “test” to “ship” only when the result matters to your actual visibility goal. Until then, it shouldn’t block work with a clearer purpose.

    Myth 2: Schema is either an AI ranking lever or useless

    Schema markup attracts two equally unhelpful positions. One treats it as a direct switch for AI visibility. The other dismisses it if a chatbot doesn’t publicly confirm that it uses the markup. Both confuse possible uses with demonstrated outcomes.

    Schema remains sensible SEO hygiene, but there is no solid proof that adding it increases visibility in AI answers. That distinction should appear in your business case. Implement schema because it gives machines a consistent description of entities and page content where the markup is appropriate. Don’t promise citations, rankings, or chatbot inclusion that the evidence cannot support.

    A defensible schema workflow is straightforward:

    • Match the markup to the page. The structured description should agree with what a person can actually see and verify.
    • Choose a type for its meaning. Don’t select a type only because someone has attached an AI-visibility claim to it.
    • Maintain structured and visible content together. When names, relationships, offers, authorship, or other marked-up details change, update both representations.
    • Validate the implementation. Syntax errors and contradictory properties undermine the basic hygiene case before AI visibility even enters the discussion.
    • Separate the hypotheses. “The markup is valid and accurate” can be confirmed independently from “the markup increased AI citations.” Track them as different questions.

    This changes how you prioritize a schema project. Fix invalid, stale, or misleading markup because those are identifiable defects. Add appropriate markup when it improves the site’s structured representation. Be cautious with an expensive expansion whose only justification is an unsupported promise of AI exposure.

    It also protects future analysis. If you deploy schema at the same time as a rewrite, technical cleanup, and distribution campaign, a later visibility change cannot be assigned confidently to the markup. Either isolate the change where practical or document the concurrent work and keep the conclusion modest.

    Myth 3: Changing a date makes content fresh

    Freshness is more credible as a factor than many speculative GEO tactics, but it is easy to imitate cosmetically. Changing a publication date, swapping a few words, or adding an unrelated paragraph doesn’t make the answer more current.

    The relevant question is whether the query benefits from newer information. Some pages answer stable questions. Others contain details that become incomplete, inaccurate, or misleading as their subject changes. Search systems can retain historical change patterns, so substantive updates matter more than superficial refreshes.

    Use this refresh sequence:

    1. Classify the query. Decide whether a newer answer would materially help the person searching. Don’t force a refresh cadence onto a stable topic without a content reason.
    2. Recheck the answer, not just the metadata. Identify claims that are no longer accurate, missing developments that change the decision, and sections that no longer satisfy the query.
    3. Make the correction visible in the body. Replace obsolete material, add genuinely necessary context, and remove advice that no longer holds.
    4. Update the date only when the revision earns it. The displayed date should communicate a meaningful editorial change, not manufacture a freshness signal.
    5. Keep an internal change record. Note what changed and why so future reviewers can distinguish maintenance from cosmetic rewriting.
    6. Evaluate the relevant page and query. A change tied to one time-sensitive need shouldn’t be presented as evidence for a universal site-wide refresh tactic.

    Before approving a refresh, ask the editor to complete one sentence: “This revision gives the reader a better answer because…” If the answer only mentions the date, word count, or a desire to look active, the page probably doesn’t need that revision. Put the effort into a page with an identifiable accuracy or completeness gap instead.

    Build a GEO roadmap that can survive uncertainty

    A sturdy stone path with experimental side platforms crosses a misty landscape from an organized digital workbench toward a clear horizon.

    You don’t need one verdict for every tactic. Use three operating lanes so uncertain ideas don’t compete as equals with necessary maintenance:

    • Ship: Work with an established purpose and a clear quality standard. Accurate content and appropriate, valid schema belong here even when you make no separate AI-visibility promise.
    • Test: Plausible, reversible changes with a defined hypothesis, observable outcome, and acceptable opportunity cost. A speculative feature can enter this lane without being presented as best practice.
    • Watch: Claims that depend on future platform adoption or currently lack a measurable mechanism. llms.txt belongs here unless support or your own relevant observations justify a controlled test.

    For every test, set the decision rules before looking at the result. State what would count as support, what would count as failure, which confounding changes you will track, and what action follows each outcome. This prevents a team from redefining success after an ambiguous result.

    Review the watch lane when something material changes, not merely because another confident thread appears. Useful triggers include explicit platform documentation, identifiable crawler behavior, repeatable data connected to the claimed outcome, or a change in business requirements. A new opinion without new evidence doesn’t require a new implementation.

    Be equally careful with automated summaries of GEO claims. A summary can compress away scope, uncertainty, failed alternatives, and the difference between correlation and causation. When a recommendation could create significant work, inspect the underlying argument and any dissenting interpretation before approving it.

    Key takeaways

    • You don’t currently need llms.txt as standard GEO infrastructure. Monitor verifiable platform support and test it only against a defined outcome.
    • Use schema as accurate, maintainable SEO hygiene. Don’t sell it internally as a proven shortcut to AI citations.
    • Refresh content when a query needs a materially newer or more complete answer. A changed date isn’t a substantive update.
    • Require stronger evidence as implementation cost, irreversibility, and opportunity cost increase.
    • Sort work into ship, test, and watch lanes so proven maintenance doesn’t lose resources to speculative tactics.

    On your next planning pass, add an evidence level and an observable outcome to every GEO task. Start with inaccurate pages and defective schema, reserve a controlled lane for plausible experiments, and leave unsupported requirements in monitoring. Your roadmap will become easier to defend because each task has a reason stronger than repetition.

    References

  • AEO Strategy: Execution, Measurement, and Agency Selection

    AEO Strategy: Execution, Measurement, and Agency Selection

    You are probably not short of AEO ideas. The harder decision is where to put the budget: more content, technical changes, measurement, or an agency promising visibility in ChatGPT and other answer engines. If you make that choice from a list of supposedly popular prompts, the program can look busy without becoming useful.

    Build the program backward from a customer decision and a business result. That gives your team a way to prioritize work, judge whether it is succeeding, and tell the difference between a capable AEO agency and a persuasive sales presentation.

    Build the strategy backward from a customer decision

    AEO should not begin with a giant prompt list. Begin with a decision a real customer needs to make: which option fits, whether a claim can be trusted, what a product does, how two approaches differ, or what to do next. Then identify the facts, evidence, and pages needed to support a reliable answer.

    For planning purposes, use a practical distinction between AEO and GEO. AEO makes a direct answer clear, retrievable, and well supported. GEO helps the same information retain its meaning and authority when a generative system combines it with other material. The disciplines overlap enough that AEO and GEO tactics belong in one operating program, not in competing teams with separate content calendars.

    Write a one-page decision brief before commissioning content or technology. It should answer:

    • Business outcome: What should improve if the program works: qualified inquiries, purchases, applications, adoption, retention, or another defined result?
    • Audience: Who is making the decision, and what do they already know?
    • Decision: What choice or next step should your content help that person complete?
    • Answer territory: Which questions can your organization answer with genuine expertise or first-party evidence?
    • Proof: Which approved facts, methods, policies, credentials, product details, or original data can support the answer?
    • Conversion path: What useful action should remain available after an answer engine satisfies the immediate question?
    • Ownership: Who approves factual claims, maintains the underlying page, and responds when information changes?

    This brief is the boundary of the strategy. A topic that attracts attention but cannot influence the chosen decision, demonstrate expertise, or lead to a useful next action is a weak priority.

    Prompt-volume estimates do not fix that problem. A prompt is not a stable unit of demand: the same need can be expressed in many ways, conversational context changes the wording, and an AI system may reformulate the request before producing an answer. That is why prompt volume should not carry the business case for AEO.

    Use prompts as a research panel instead. Group them by customer need, decision stage, and subject. Prioritize each group using business relevance, your ability to provide a defensible answer, the quality of your existing coverage, and the consequence of being absent or misrepresented. This produces a manageable question portfolio without pretending that an estimated volume is equivalent to audited search demand.

    Turn the customer journey into an answer system

    An isometric customer journey connected to blank answer cards, source documents, product objects, and technical nodes.

    AI discovery is not a separate funnel that ends when your brand is mentioned. People use answer engines while exploring a problem, narrowing options, validating a claim, preparing to act, and using what they selected. Treating AI discovery as part of the customer journey prevents a common mistake: optimizing only broad awareness questions while leaving comparison and action-stage questions unanswered.

    Journey momentWhat the person needsYour content jobUseful next action
    ExploreA clear view of the problem, category, or available approachesDefine the subject, explain the options, and establish scope without forcing a saleRead a deeper explanation or assess the problem
    NarrowCriteria that separate plausible choicesShow differences, trade-offs, use cases, and disqualifying conditionsCompare relevant options or review requirements
    ValidateEvidence that a claim, provider, or method is credibleExpose the basis of claims, limitations, policies, credentials, and first-party proofInspect evidence or confirm fit
    ActEnough certainty to complete the next stepAnswer practical questions about process, eligibility, implementation, or purchaseApply, buy, book, contact, or begin setup
    UseHelp getting value or resolving a problemProvide accurate instructions, troubleshooting, and policy informationComplete the task or reach appropriate support

    Design the answer architecture

    Build content around question families rather than publishing a separate page for every wording variation. One maintained page can answer the central question, while supporting pages handle comparisons, implementation details, evidence, and edge cases. Link them so a person or retrieval system can move from a short answer to its substantiation without guessing which page is authoritative.

    A useful answer unit contains:

    • A direct response: State the answer before background material, provided the question can be answered without a critical qualification.
    • Scope: Identify who, what, or which situation the answer applies to.
    • Reasoning: Explain why the answer holds and which criteria affect it.
    • Evidence: Connect material claims to inspectable facts, methods, policies, credentials, or original data.
    • Trade-offs: Say when an alternative may be more appropriate and where the answer has limits.
    • Entity clarity: Use consistent names for the organization, product, service, location, person, and concept being discussed.
    • A next step: Offer an action that follows naturally from the decision instead of interrupting it with an unrelated conversion request.

    Structured data should express the same entities and relationships that a reader can verify on the page. It cannot repair an unsupported claim, settle contradictions between pages, or make thin content authoritative. If the visible content, structured data, product feed, policy page, and organizational profile disagree, fix the underlying information before adding more markup.

    Give production a definition of done

    AEO execution usually crosses content, subject expertise, technical SEO, development, analytics, and brand governance. Without an explicit handoff, every contributor can complete a task while the final answer remains incomplete. Use one workflow:

    1. Select a question family. Tie it to the audience, journey moment, decision, and business outcome in the brief.
    2. Assemble a fact pack. Collect approved claims, definitions, evidence, policies, entity names, known limitations, and the internal owner of each important fact.
    3. Audit the existing answer. Find duplicate pages, buried explanations, unsupported assertions, contradictory details, obsolete material, and missing conversion paths before creating anything new.
    4. Write the content specification. Record the central question, direct response, necessary qualifiers, supporting evidence, related questions, authoritative URL, internal links, structured-data requirements, and intended next action.
    5. Review for factual integrity. Have the appropriate subject owner approve consequential claims and limitations. Editorial polish is not a substitute for this review.
    6. Run technical quality control. Confirm that the preferred page is publicly reachable, its important answer is present in accessible page content, canonical signals are consistent, indexing is not accidentally blocked, internal links work, and markup agrees with visible information.
    7. Publish and observe. Inspect how representative questions are answered, record inaccurate or missing claims, and feed those findings back into the maintained page and fact pack.

    A page is not done merely because it contains the target phrase or passes a markup test. It is done when the answer is clear, its limits are visible, its material claims are supportable, the responsible owner has approved it, and the next step works.

    Measure visibility without pretending it is demand

    A useful AEO scorecard separates observation from value. Visibility tells you whether and how your organization appears. Engagement tells you whether people continue to your owned experience. Business outcomes tell you whether the program influences a result that matters. Combining those layers into one opaque score hides the reason performance changed.

    Measurement layerWhat to recordDecision it supports
    Answer visibilityBrand inclusion, citation, linked page, answer placement, and presence across representative question familiesWhere your organization is absent or difficult to retrieve
    Answer qualityAccuracy, completeness, correct entity identification, appropriate qualification, and treatment of important claimsWhich facts or pages need correction, clarification, or stronger support
    Owned engagementAI referrals, landing-page behavior, completed next steps, and assisted journeys where they can be observedWhether AI exposure produces useful interaction rather than a mention alone
    Business outcomesQualified inquiries, applications, purchases, activation, retention, or the outcome named in the decision briefWhether continued investment is justified and which journey areas deserve attention

    Treat your monitored prompts as a fixed diagnostic panel, not a census of all AI demand. Include high-value question families from each relevant journey stage, along with natural wording variations. For every observation, retain the exact prompt, intent family, platform or interface, displayed model label when available, language, location, account state, observation date, answer, citations, linked pages, and your quality assessment.

    Those fields matter because an answer can vary with wording, context, interface, model behavior, location, and personalization. If the testing conditions change, label the break instead of presenting the new result as a clean continuation of the old one.

    Evaluate every important answer along separate dimensions: present or absent, cited or uncited, accurate or inaccurate, useful or unhelpful. A brand can be visible and still be described incorrectly. It can be cited while the wrong page receives the link. It can also provide the answer without earning a click. Those outcomes require different actions and should not collapse into a single visibility percentage.

    Do not treat an AI referral as the only sign of influence, but do not assign commercial value to a no-click mention without evidence either. Connect observable referrals and conversions where possible, use assisted-journey evidence cautiously, and label what cannot be attributed. Honest measurement is more useful than a precise-looking number built on assumptions.

    Choose an agency by inspecting the work, not the vocabulary

    A client team examines blank content mockups, a technical model, and an abstract dashboard while presentation screens remain in the background.

    Before issuing an RFP, decide which operating model you need. Keep the program in-house when your content, technical, analytics, and subject-matter teams can own the workflow and only need focused training or tooling. Use a hybrid model when internal teams should retain strategy and factual ownership but need specialist support for audits, measurement, structured data, or production. Consider a broader agency engagement when coordination and execution capacity are the actual constraints.

    An agency cannot control whether a frontier model includes or cites a brand. It can improve the clarity, accessibility, consistency, evidence, and measurement of the information available to those systems. Evaluate bidders on those controllable contributions.

    Make the RFP demand inspectable outputs

    A structured AI-search RFP can reveal whether a bidder has genuine execution depth, but only if it asks for more than credentials and a dashboard tour. Give every bidder the same business objective, customer journey, known constraints, sample content, available data, approval process, and expected handoffs. Then require concrete responses:

    • Problem diagnosis: Which customer decisions and answer gaps should be addressed first, and why?
    • Question architecture: How will the agency build and maintain question families without treating guessed prompt volume as audited demand?
    • Content method: What will a content specification contain, and how will the team obtain and approve evidence?
    • Technical method: How will the agency inspect accessibility, canonicalization, internal linking, entity consistency, structured data, and conflicts across owned properties?
    • Measurement design: Which visibility, quality, engagement, and business signals will be reported separately? What can and cannot be attributed?
    • Working model: Who owns strategy, fact approval, writing, implementation, testing, and refresh decisions on both sides?
    • First-phase plan: Which deliverables will be produced first, what dependencies could block them, and what evidence will determine the next phase?
    • Transferable assets: Will you receive the question set, raw observations, content specifications, technical findings, data exports, documentation, and account access needed to continue the work?
    • Relevant evidence: Can the agency show the baseline, intervention, measurement method, limitations, result, and its own role in a comparable engagement?

    Score each response using the same criteria and scale. Favor clear prioritization, factual discipline, technical competence, measurement honesty, and an operating model your team can sustain. A bidder should be able to explain what it will deliberately not do as clearly as what it proposes.

    For finalists, run the same controlled working exercise. Provide a representative page, an approved fact pack, a customer decision, and a small set of observed AI answers. Ask each team to diagnose the highest-priority problem, improve an answer block, identify technical or factual conflicts, define acceptance criteria, and explain how it would measure the change. If the exercise creates usable strategic work, compensate the participants rather than disguising free consulting as procurement.

    Recognize the red flags before you sign

    • Guaranteed inclusion or citation: No agency can promise what an independent answer engine will generate.
    • Prompt volume presented as demand truth: Ask how the estimate was produced, what it represents, and which decisions would change if it were wrong.
    • A dashboard without a decision model: More charts do not compensate for the absence of business outcomes, journey priorities, and defined actions.
    • Schema sold as a standalone solution: Markup can clarify supported information; it cannot manufacture authority or reconcile contradictory facts.
    • Mentions treated as success: Visibility without accuracy, relevance, evidence, or business connection can create risk rather than value.
    • No plan for subject-matter review: An agency that cannot explain how consequential claims are approved is treating factual integrity as an editorial afterthought.
    • Opaque methods or inaccessible data: You should understand how prompts are selected, how outputs are classified, and which raw material sits behind reported scores.
    • No exit path: If the work disappears when the contract ends, the engagement has not built an organizational capability.

    Before work starts, put deliverables, approval responsibilities, access, data retention, asset ownership, reporting definitions, and handoff requirements into the agreement. Ambiguity here does not create flexibility. It postpones a dispute until the first missed dependency or the end of the engagement.

    Key takeaways

    • Start AEO with a customer decision, business outcome, evidence base, and owner. Do not start with estimated prompt volume.
    • Treat prompts as a representative diagnostic panel organized by intent and journey stage, not as a complete measure of market demand.
    • Build maintained answer systems: direct responses, clear scope, inspectable evidence, consistent entities, useful internal paths, and matching structured data.
    • Measure answer visibility, answer quality, owned engagement, and business outcomes separately so the team knows what to change.
    • Select an agency through inspectable work, explicit handoffs, honest measurement, and proof of operating discipline. Reject guarantees that depend on systems the agency does not control.

    Your next move is small and concrete: choose one valuable customer decision, write its decision brief, and audit the pages that currently answer it. That exercise will show whether your immediate constraint is evidence, content, technical implementation, measurement, or capacity. If you approach agencies afterward, you will be buying against a defined need instead of asking a vendor to define the need for you.

    References

  • YouTube in Google AI Health Answers: A Publisher Playbook

    YouTube in Google AI Health Answers: A Publisher Playbook

    If you publish health information, YouTube’s lead among domains cited in Google AI health answers can trigger the wrong response: produce more videos, copy the format already being cited, and assume visibility will follow. That conclusion goes beyond the evidence and creates real risk when the subject is treatment, cancer diets, laboratory results, or another decision that could affect someone’s care.

    A better response is to make every important health claim inspectable. You need to know what the AI answer says, whether its citation supports that exact wording, which qualifiers survived summarization, and whether your own video and page tell the same medically reviewed story. Here is a practical way to do that without treating YouTube as either a shortcut to AI visibility or an inherently unreliable format.

    Read the YouTube number without drawing the wrong conclusion

    Across 50,807 health-related searches in Germany, AI Overviews appeared for more than 82% of the inquiries examined. That level of coverage matters because an AI-generated summary can become the first layer of health information a searcher sees, before any hospital page, journal, association, or video is opened.

    YouTube accounted for 4.43% of all citations and was the most-cited individual domain. The percentage and the ranking need to be read together. YouTube led a fragmented field; it did not supply most health citations. A 4.43% citation share is evidence of meaningful visibility, not evidence that Google prefers every video over every medical page.

    The credibility mix is more consequential. Only 34.45% of citations came from sources classified as more reliable medical sources, while nearly two-thirds were classified as lacking strong medical or evidence-based credibility. Academic journals and government health organizations together represented only about 1% of citations. Those classifications do not prove that every citation outside the medical group was wrong, but they expose a large verification problem.

    AI citations also followed a different pattern from conventional rankings. YouTube placed first by AI citation frequency but only 11th in organic results, and just 36% of pages cited by AI appeared in Google’s organic top 10. You therefore cannot use top-10 rankings as a complete proxy for AI visibility. You also cannot assume that an AI citation proves a page or video is the strongest medical result.

    These figures are observational. They do not reveal a YouTube ranking factor, prove why a particular citation was selected, or establish a permanent worldwide pattern beyond the German query set examined. Google has also disputed whether selected examples of risky advice were fairly represented in context and maintains that AI Overviews generally link to trustworthy material. For publishers, that disagreement makes context checking more important, not less.

    Key takeaways

    • YouTube was the leading cited domain, but its 4.43% share does not mean video supplied most health information.
    • AI citation visibility and top-10 organic visibility are related measures, not interchangeable ones.
    • A platform is a container, not a medical credibility signal. Evaluate the speaker, evidence, wording, scope, and review process.
    • Your goal should be a claim that remains accurate when extracted, summarized, and separated from the rest of the page or video.

    Audit the health claim, not just the cited domain

    A magnifying glass examines an abstract claim across layered video, research paper, and AI response materials on a clinical review desk.

    A domain-level report can tell you where citations concentrate. It cannot tell you whether a specific AI sentence is supported. That requires a claim-level audit. Use the following process for queries tied to diagnosis, treatment, medication, diet during a serious illness, test interpretation, or another decision with a meaningful health consequence.

    1. Capture the complete answer. Record the exact query, wording of the AI Overview, locale, capture date, every citation, and the sentence or passage attached to each citation. Do not save only the part that mentions your brand.
    2. Break the answer into individual claims. Separate definitions, causal statements, recommendations, thresholds, and statements about who is affected. One paragraph may contain several claims even when Google attaches only one citation.
    3. Map every claim to its alleged support. Ask whether the cited destination supports the exact statement, merely discusses the same topic, or contradicts the summary once its qualifications are restored.
    4. Inspect the video beyond its title. Identify the speaker, relevant credentials, publisher, publication or review date, transcript, references, and the surrounding segment. A title or short extracted passage can sound more certain than the full explanation.
    5. Check the missing qualifiers. Look for the population, condition, stage, exclusions, uncertainty, and boundary between general education and individualized advice. A summary can preserve the main clause while dropping the words that made it safe.
    6. Compare AI and organic visibility separately. Record whether the cited URL appears in the top 10, but do not automatically reject it when it does not. With only 36% overlap in the examined results, organic position is useful context rather than a verdict on the AI citation.
    7. Assign a risk owner. SEO can document the extraction problem, but a qualified medical reviewer should decide whether a consequential health claim is clinically supportable. Keep that approval attached to the exact claim and version reviewed.

    A simple red, amber, and green workflow helps you decide what to fix first:

    • Red: The answer could prompt someone to start or stop treatment, alter a medically significant diet, treat a laboratory result as a diagnosis, or delay professional care, and the citation does not clearly support the action. Escalate it for medical review and do not amplify the claim while that review is unresolved.
    • Amber: The central point may be supportable, but the AI answer loses a population, limitation, uncertainty, or other qualifier. Rewrite the source material so the qualifier travels with the claim rather than appearing several sentences later.
    • Green: The claim is narrow, educational, supported by the destination, and represented with its material context intact. Continue monitoring it because the wording or citation set can change.

    These colors are editorial priority labels, not clinical validity scores. If you are personally deciding whether to change a treatment, cancer-related diet, or interpretation of a liver blood test, an AI Overview and its cited video are not substitutes for a qualified clinician who knows your situation.

    Build a claim package that remains credible outside YouTube

    The useful unit of health publishing is not the video, page, or schema record. It is the claim package: a bounded answer, the evidence supporting it, the person accountable for reviewing it, the people to whom it applies, and the caveats required to keep it accurate. Video can carry that package well, but only if its authority survives outside the platform.

    Make the spoken answer safe to extract

    • State the question and answer in the narration. Do not leave the key qualification only in the description, a pinned comment, or an end card.
    • Keep the caveat beside the claim. If a recommendation applies only to a defined group or depends on professional assessment, say that in the same spoken passage. Distance makes it easier for summarization to separate the claim from its boundary.
    • Identify who is speaking and reviewing. Give relevant, verifiable credentials and distinguish the presenter from the medical reviewer when they are different people.
    • Separate education from individualized direction. Explain what a term, test, or treatment generally means without implying that the viewer has a diagnosis or should change care based on the video alone.
    • Expose the evidence trail. Put supporting references in the description and make clear which reference supports which major claim. A generic reading list is harder to audit.
    • Correct the transcript and captions. Names of conditions, tests, treatments, and qualifications are precisely where automated transcription errors can distort meaning. The transcript should match the reviewed spoken version.
    • Review clips as independent objects. A short clip may circulate without the full video’s introduction or disclaimer. It must retain any qualifier necessary to prevent the excerpt from becoming misleading.

    Give the video a companion page with the same accountable answer

    The companion page should not be a thin transcript built only to host an embed. It should let a reader verify the claim without watching the video and let an editor detect when the page and video have drifted apart.

    • Place the reviewed answer and its material limitation in the same section as the embedded video.
    • Show who wrote, presented, and medically reviewed the material. Do not collapse those roles into one vague byline.
    • Display the review date and update both assets when a substantive claim changes. A fresh page date attached to an unchanged old video creates false alignment.
    • Attach evidence to the claim it supports. Avoid sending readers through a long references list to guess which item belongs to which statement.
    • Use headings that reflect real questions, then answer each question directly before expanding on it. This improves clarity even when no AI system cites the page.
    • Check that the video’s title, thumbnail, description, transcript, page summary, and structured data all describe the same scope. A broad title paired with a heavily qualified answer invites misinterpretation.

    JSON-LD can clarify the visible video’s title, creator, publication details, and relationship to the page. It cannot turn an unsupported claim into medical evidence. Keep every structured value consistent with what a user can see, and never mark up credentials, reviewers, dates, or medical relationships that the page does not truthfully establish.

    Measure AI citations without manufacturing a success story

    A researcher reviews abstract citation nodes on a monitoring board beside a balance scale holding verified and uncertain evidence tokens.

    A citation dashboard becomes misleading when several different denominators are labeled citation rate. Define each metric before you compare a page, video, competitor, or reporting period.

    MetricCalculationWhat it tells you
    AI Overview coverageQueries showing an AI Overview divided by all queries checkedHow often the feature appears for your tracked query set
    Owned citation presenceQueries citing one of your assets divided by queries showing an AI OverviewHow often your content enters an available AI answer
    Owned citation shareYour citation appearances divided by all citation appearances capturedYour portion of the citation pool under the same counting method
    Video citation mixCited videos divided by all cited assets in your datasetWhether video is over- or underrepresented in your own topic set
    Context fidelityOwned citations represented accurately divided by all owned citation appearances reviewedWhether visibility preserves the meaning and limitations of your content
    Organic overlapAI-cited URLs also appearing in the organic top 10 divided by all AI-cited URLsHow much AI sourcing overlaps with conventional ranking visibility

    The reported 4.43% YouTube figure used all citations as its denominator. Do not compare it with the percentage of queries containing a YouTube link or the percentage of cited domains that are video platforms; those answer different questions. Preserve citation appearances, unique URLs, unique domains, and queries as separate counts.

    Track the same query set and locale with a consistent capture method. Record the page and video independently, even when they belong to one claim package. When visibility changes after an update, treat the result as an observation rather than proof that a transcript edit, schema field, embed, or review note caused the change.

    Most importantly, do not count every citation as a win. An AI answer that cites your asset while stripping away a crucial limitation can create more reputational and health risk than no citation at all. Context fidelity belongs beside visibility in every report sent to editorial, medical, legal, or leadership teams.

    Choose the next publishing move by consequence, not format

    You do not need to convert your entire health library into video. Start with a bounded set of ten queries where a misleading answer could affect treatment, diet during a serious illness, test interpretation, or a decision to seek professional care. That set is small enough for claim-level review and important enough to reveal whether your current process protects users.

    1. Capture each AI Overview, its citations, and the corresponding organic top 10.
    2. Split every answer into claims and apply the red, amber, or green editorial label.
    3. Select the highest-consequence unsupported or decontextualized claim, regardless of whether its current citation is a video or page.
    4. Create or revise one medically reviewed claim package: spoken answer, transcript, companion page, evidence mapping, reviewer ownership, and accurate structured data.
    5. Recheck the same query set after publication, keeping the denominator and locale unchanged.
    6. If the asset gains a citation, verify the summarized wording before reporting success. If it does not, keep the improved content; the safety and clarity gains still matter to every person who reaches it directly.

    YouTube’s citation lead is a reason to inspect video more carefully, not a reason to imitate it blindly. Make your next health answer narrow enough to verify, complete enough to survive extraction, and accountable to a qualified reviewer. Then measure whether Google cites the right claim in the right context.

    References

  • How to Build AI Search Visibility With a Practical AEO System

    How to Build AI Search Visibility With a Practical AEO System

    You may already have pages that rank, attract links, and explain your offer well. Then a prospective customer asks an AI assistant the same question your page answers, and your brand is missing, misrepresented, or mentioned without a useful link.

    That gap needs a different workflow. AI search is changing user behavior, website traffic, brand visibility, and citation patterns. Answer Engine Optimization, or AEO, gives you a practical way to respond: choose the questions that matter, publish answers that can stand on their own, make important claims verifiable, and measure whether answer systems represent you accurately.

    Start with the decision behind the search

    AEO is not a contest to place more question phrases on a page. It is the work of making the right answer easy to locate, understand, verify, and attribute. That starts with the decision the reader is trying to make.

    Suppose someone asks whether a product is suitable for a regulated team. A broad page about product benefits may contain relevant language, but it does not necessarily resolve that decision. The useful answer has to identify the relevant product, state the applicable conditions, explain what the product does and does not cover, and point the reader toward evidence or a sensible next step.

    Build an answer map before revising content. Create a row for each meaningful audience question and record:

    • Audience: Who is asking, and what context changes the answer?
    • Decision: What will the person decide after receiving a satisfactory answer?
    • Primary question: What would they actually ask, in plain language?
    • Direct answer: What is the shortest accurate response you can support?
    • Conditions: Where does the answer depend on product version, location, use case, plan, eligibility, or another constraint?
    • Evidence: Which first-party page, original record, policy, specification, or other authoritative material supports the claim?
    • Entity: Which brand, person, product, service, or concept must be identified without ambiguity?
    • Destination: Which page should a reader visit when they need detail or want to act?

    This map stops a common content problem: one page trying to answer every possible intent. If the same wording hides materially different decisions, create separate answer paths. A buyer comparing options needs different context from a customer troubleshooting an implementation, even when both use similar nouns.

    Prioritize questions by relevance, not by how easy they are to turn into headings. Start with questions that sit close to a meaningful decision and for which you have defensible evidence. Do not manufacture an answer merely because a query appears attractive. An unsupported response creates a representation problem, not an optimization win.

    Turn each important page into a usable answer asset

    A generic web page separates into modular answer, evidence, comparison, process, and source components that flow into abstract AI response windows.

    An answer asset is a page or section that remains useful when encountered outside the reader’s original navigation path. It identifies its subject, gives a direct response, preserves necessary qualifications, and shows where the claim comes from. It should still reward someone who reads the whole page; extractability is not an excuse for thin or robotic writing.

    1. Put the conclusion in the first useful paragraph. Do not make the reader cross a long scene-setting introduction before learning whether the page addresses the question.
    2. State the scope next to the answer. If a claim applies only under certain conditions, keep those conditions in the same section. A detached disclaimer does not repair an overbroad sentence.
    3. Use headings that describe real subproblems. A heading such as eligibility requirements communicates more than a vague label such as important considerations. The heading should help a person predict the content beneath it.
    4. Support the claim where it appears. Place the relevant link, explanation, methodology, or first-party record next to the statement it supports. A generic references list cannot tell the reader which evidence belongs to which claim.
    5. Resolve ambiguous names. Introduce acronyms, distinguish similarly named products, and make relationships between the publisher, author, product, and subject explicit.
    6. Give the reader a next action. Link to the detailed specification, comparison, policy, calculator, contact route, or implementation step that logically follows the answer.

    Use a simple extraction test during editing. Copy the target section into a blank document without its navigation, title tag, or surrounding paragraphs. Ask whether a new reader can identify the question, understand the answer, see its boundaries, and determine who is making the claim. If not, add the missing context to that section rather than assuming the rest of the website will supply it.

    Clarity does not mean reducing every subject to a short definition. Some questions require a process, comparison, exception, or tradeoff. Give the direct answer first, then provide the depth the decision requires. The goal is a self-contained answer followed by useful reasoning, not a collection of isolated snippets.

    Keep conventional search foundations in place as you do this work. A page still needs clear internal paths, accessible content, sensible canonical handling, and working technical delivery. AEO adds answer structure and verifiability; it does not make an inaccessible page available to a system that cannot retrieve it.

    Make identity and evidence consistent before adding schema

    An answer engine can mention the right brand and still get the claim wrong. It can also cite a page without making the relationship between the page, publisher, author, and product clear. Treat accurate representation as a separate objective from simple visibility.

    Create a claim ledger for statements that influence a customer’s decision. Record the exact claim, the page where it appears, its supporting evidence, the person responsible for it, and when it was last reviewed. Include product capabilities, limitations, policies, availability, compatibility, pricing statements, credentials, and comparative claims where they are relevant to your business.

    The ledger gives your team a concrete maintenance rule: when the underlying fact changes, update every dependent page. Check prominent claims across product pages, service pages, author profiles, company information, support material, and policy pages. If those surfaces disagree, readers and automated systems are left to infer which version is authoritative.

    Remove language you cannot substantiate. Terms such as best, leading, guaranteed, and universally compatible are not made trustworthy by repetition. Replace them with a bounded claim, publish the evidence, or delete them.

    Only then should you use structured data to describe what the visible page already establishes. Structured data is a translation layer, not a substitute for evidence. It can clarify the page type, the entity being discussed, and relationships among the publisher, author, subject, offer, or other relevant entities. It cannot force an answer engine to cite you, make an unsupported statement true, or repair contradictory content.

    • Choose the most specific page and entity types that the visible content genuinely supports.
    • Keep marked-up names, descriptions, identifiers, relationships, and claims consistent with the rendered page.
    • Connect entities only when the relationship is real and clear to a reader.
    • Use stable, canonical identifiers and URLs under your control where your implementation supports them.
    • Validate generated markup after changing a template, plugin, content model, or publishing workflow.
    • Remove stale fields instead of leaving old values in code that visitors cannot see.

    Audit the rendered page and its structured data together. If the markup describes a different product, author, date, or claim, fix the underlying publishing process rather than patching individual fields indefinitely. The durable order is visible truth first, consistent entity information second, and structured representation third.

    Measure mentions, citations, accuracy, and traffic separately

    A central AI response portal branches toward visual symbols for mentions, source citations, answer accuracy, and website visits.

    Traditional rank tracking asks where a URL appears for a query. AEO measurement has several possible outcomes: your brand may be absent, named, described, recommended, cited, linked, or visited. Those events are related, but they are not interchangeable.

    Create a fixed prompt inventory from the answer map. Include the primary audience wording and meaningful variants that preserve the same intent. Separate branded prompts from unbranded prompts so an answer to a question containing your company name does not inflate your view of discovery.

    For every observation, retain the exact prompt, the answer surface or mode, relevant account or location context, the observation date, the response, cited pages, linked URLs, and any material accuracy problem. Generative responses can vary, so a conclusion without that context is difficult to reproduce or investigate.

    Keep the core measures explicit:

    • Mention rate: the share of tracked prompts for which the brand or relevant entity appears.
    • Citation rate: the share for which one of your pages is identified as support.
    • Link rate: the share that provides a usable path to your site. Do not assume every citation produces a clickable visit.
    • Accurate-representation rate: the share of appearances in which the material claims are correct and properly qualified.
    • Referral traffic: visits that analytics can attribute to an AI answer surface.
    • Conversion: the meaningful action taken after an attributable visit, using the same business definition applied to other channels.

    Do not collapse these observations into a single visibility score unless you document the weighting and preserve the underlying data. A flattering mention with no evidence is not equivalent to an accurate citation. A citation for an irrelevant prompt is not inherently valuable. A qualified recommendation near a real decision can matter more than frequent appearances in loosely related answers.

    Use the pattern of outcomes as a working diagnosis:

    • If relevant competitors are repeatedly supported and you are absent, inspect whether you have a coverage, evidence, accessibility, or entity-clarity gap.
    • If you are mentioned inaccurately, compare the generated claim with your claim ledger and look for conflicting or outdated pages.
    • If you are cited but not linked, inspect whether the cited page offers a clear destination and whether the answer already satisfies the entire need.
    • If links produce visits but not useful actions, review intent alignment and the landing experience before declaring the visibility successful.
    • If a change appears to improve one prompt, check related prompts before generalizing the result.

    Review the same prompt groups after meaningful content, entity, or schema changes. Keep a change log so you can connect movement to a plausible intervention. The purpose is not to claim perfect attribution. It is to replace screenshots and anecdotes with a repeatable record your content, SEO, analytics, and brand teams can examine together.

    Key takeaways

    • Start AEO with the audience’s decision, not a list of question-shaped keywords.
    • Give each important question a direct, bounded, self-contained answer with nearby evidence.
    • Treat brand identity, claim accuracy, citation, linking, and traffic as separate parts of visibility.
    • Use structured data to express visible truth and entity relationships, never to manufacture authority.
    • Track a fixed prompt inventory with enough context to reproduce observations and diagnose changes.

    Begin with one high-value question you can answer defensibly. Complete its answer-map row, repair the strongest relevant page, reconcile its claims across your site, align the structured data, and add the prompt to your measurement log. Once that chain works from question to evidence to observation, apply it to the next decision that matters.

    References

  • Gemini Trends and Personal Intelligence: An SEO Workflow

    Gemini Trends and Personal Intelligence: An SEO Workflow

    You have a topic worth covering, but two questions are blocking the brief: which language reflects real search demand, and whether the answer will remain relevant when Gemini knows something about the person asking.

    Google’s Gemini integrations now touch both questions. Gemini in Google Trends can suggest related terms and place them into a trend comparison. Personal Intelligence can use selected information from connected Google apps to shape an individual response. The opportunity is useful, but only if you keep those signals separate: Trends helps you map public demand, while Personal Intelligence introduces private context.

    Treat the integrations as two different signal layers

    The Trends integration is an editorial research tool. You give it a keyword or a natural-language description, and Gemini proposes related search terms for comparison. Personal Intelligence operates later in the journey. With the user’s permission, Gemini can draw on information associated with Search, Gmail, Google Photos, and YouTube to produce a response that may be more useful to that person.

    Gemini surfaceInputUseful decisionWhat it cannot establish
    Google Trends ExploreA keyword or natural-language topicWhich terms, variants, and rising questions deserve closer investigationWhether a term will convert, whether two terms share the same intent, or whether you should publish a separate page for each suggestion
    Personal IntelligenceA prompt plus the Google apps and history the user has chosen to connectWhich details could make an answer more relevant in a particular personal contextA universal ranking position, a reusable audience profile, or access to other users’ private context

    This distinction prevents two common mistakes. A rising query is not automatically a content brief, and a personalized answer is not automatically a public search result. The first is a lead that needs editorial judgment. The second is an individual output whose conditions must be recorded before you draw conclusions from it.

    Access conditions also matter when you plan a workflow. The Trends redesign was introduced through a gradual desktop rollout, so the Gemini control may not appear in every interface at the same time. Personal Intelligence initially launched as a U.S. beta for Google AI Pro and AI Ultra subscribers using personal Google accounts across the web, Android, and iOS; Workspace accounts were excluded from that initial availability. Treat those as launch conditions to verify in the account you will actually use, not as permanent assumptions.

    Turn Gemini’s Trends suggestions into a defensible query map

    Blank query tokens pass through an analysis lens, branch into thematic clusters, and organize into page modules.

    The useful output from Gemini in Trends is not a list of titles. It is a query map: a record of how people describe a problem, which terms appear related, and where the language may represent a genuinely different need. Build that map before you decide whether to update a page, add a section, or create something new.

    1. Start with the editorial decision. Write the question you need the data to resolve. For example: Do searchers treat two product categories as alternatives, or are they looking for different jobs to be done? A clear decision keeps Gemini’s suggestions from becoming an unfiltered brainstorming exercise.
    2. Describe the topic in natural language. In the desktop Explore interface, use Suggest search terms and enter either a seed keyword or a sentence describing the audience and problem. Natural language is especially useful when the market uses several labels and you do not yet know which one belongs in the comparison.
    3. Curate the suggestions before accepting them. Ask whether each term describes the same entity, the same task, a narrower condition, or an unrelated meaning. Remove ambiguous lookalikes. Keep a term when it exposes a meaningful vocabulary choice or a separate intent worth testing.
    4. Compare the terms as a group. The redesigned interface allows more terms to be compared and gives each one a distinct icon and color. Look for divergence, convergence, and sudden movement. Similar movement can indicate a shared external trigger, but it does not prove that searchers want the same answer.
    5. Inspect the rising queries for the mechanism behind the movement. The updated timeline exposes twice as many rising queries as the earlier layout. Use them to identify new modifiers, questions, products, or events that may explain the trend. Treat a rising query as an investigation lead, not a forecast that demand will last.
    6. Make one of three explicit content decisions. Add a missing answer to an existing page when the intent is already covered. Create a focused page when the searcher needs a materially different answer. Put the term on a watchlist when the meaning or durability is still unclear.

    Your query map should record the core question, accepted term variants, excluded ambiguities, notable rising queries, and the content decision attached to each cluster. Save the comparison context shown in Trends as well. Without that record, a later editor cannot tell whether a page was built around sustained demand, a temporary spike, or an AI-generated suggestion that was never validated.

    Do not publish one page per suggested term. If several phrases express the same task, a single strong page can define the shared concept and use the variants naturally. Separate pages make sense only when the reader needs a different decision, procedure, constraint, or outcome. That is an information-architecture choice, not something Gemini can decide from term similarity alone.

    Build pages for context without trying to predict the user

    Personal Intelligence changes the selection problem. Gemini was already able to retrieve information from connected apps; in the announced Gemini 3 implementation, it can reason across that information and use it in recommendations. Your public page cannot know the private facts available in a particular conversation. It can, however, make its answer easy to adapt when different facts matter.

    • Lead with the stable answer. State what remains true regardless of the user’s history. Do not bury the definition, process, or central recommendation beneath persona language.
    • Branch on explicit conditions. Label the cases that change the answer: platform, account type, experience level, objective, compatibility requirement, or other relevant constraint. A reader and an answer system should be able to identify the applicable branch without inferring what the page meant.
    • Name entities consistently. Use the canonical product, organization, feature, and version names that the answer depends on. Introduce genuine search-language variants from your Trends map, but do not alternate among labels in a way that makes separate concepts look identical.
    • Explain relationships in visible prose. State which feature belongs to which product, which step precedes another, and why a condition changes the recommendation. Do not expect a heading, internal link, or schema property to carry an important relationship by itself.
    • Separate facts from judgment. Identify what a feature does before recommending who should use it. Personalized systems may combine a factual passage with private context, so an unsupported universal recommendation is especially fragile.
    • Keep structured data aligned with the page. JSON-LD should describe entities, authorship, content types, and other information that visitors can verify in the visible content. The announced Gemini integrations do not establish a new Gemini-specific schema or a markup switch that guarantees selection in personalized answers.

    Consider a hypothetical page about organizing a photo library. A context-ready page would answer the universal setup question first, then separate paths for finding images, sharing collections, creating a backup, and cleaning up duplicates. It would not guess which path applies to the reader. It would label the paths clearly enough for the reader or an answer system to select the relevant one.

    This is the practical GEO implication: public content establishes what your organization knows, while personal context can influence which part of that knowledge is useful. You control the clarity, completeness, and consistency of the public material. You do not control the private context or the final selection, so promises of guaranteed personalized visibility do not hold up.

    Measure public visibility and personalized usefulness separately

    One blank content page connects to separate stations for measuring anonymous public visibility and private personalized usefulness.

    A personalized Gemini response can vary with connected apps, personalization settings, and past conversations. Compressing all of that into one rank number strips away the conditions that produced the answer. Use a small controlled test matrix instead.

    Run a controlled visibility check

    1. Record the demand evidence. Save the Trends prompt, comparison set, relevant rising queries, date, and comparison context visible in the interface. This becomes the public-demand side of the test.
    2. Document the personalization state. Establish a baseline with personalization off. If you test a connected condition, record which permitted apps are active without copying private contents into the report.
    3. Hold the prompts constant. Use the same wording, task, and follow-up sequence across conditions. If you change the prompt and the personalization state at once, you will not know which change affected the response.
    4. Log treatment instead of claiming a fixed rank. Record whether your page or brand appeared, which question the response answered, which details it used, whether it cited or linked to a public page, and whether it represented the entity accurately.
    5. Translate differences into content changes carefully. Revise a page only when the test exposes a public-content gap, such as an omitted condition, unclear entity relationship, outdated fact, or unsupported recommendation. You cannot repair a private-context mismatch by adding speculative personal details to the page.
    6. Repeat under the same conditions. After an editorial change, rerun the fixed prompts with the same documented settings. The useful comparison is the change in answer quality and representation under matched conditions, not a screenshot from an unrelated conversation.

    Make privacy part of the test design

    Personal Intelligence is off by default and lets the user choose which apps to connect. Connected apps do not personalize every response automatically, and users can manage past chats and provide feedback when personalization misses the mark. Those controls are not implementation details. They are variables that determine what your test actually measures.

    Do not ask employees, clients, or research participants to expose personal Gmail, Photos, Search, or YouTube information merely to generate a marketing screenshot. Use only an account and data that the owner has explicitly authorized for the test. If private information affects an output, report the pattern at a high level and omit the underlying email, image, search, or viewing history.

    The initial exclusion of Workspace accounts also means you should not present a personal-account test as proof of an enterprise workflow. Google indicated that Personal Intelligence would expand to Search in AI Mode, but a planned expansion is not the same as universal availability. Verify the feature, account type, country, and personalization state whenever you interpret a result.

    Key takeaways

    • Use Gemini in Google Trends to expand and compare a query cluster, not to automate your editorial calendar.
    • Treat rising queries as clues about changing language or demand. Validate their meaning before creating or restructuring a page.
    • Prepare for personalized answers by publishing a stable core answer with clearly labeled branches for the conditions that change it.
    • Keep visible content and JSON-LD consistent. Neither markup nor trend data guarantees inclusion in a personalized Gemini response.
    • Measure public demand and personalized usefulness as separate layers, documenting the prompt, account state, app connections, and answer treatment.
    • Keep private Google data out of shared SEO artifacts unless the data owner has explicitly authorized its use.

    Start with one existing page rather than a site-wide overhaul. Build its query map in Trends, add the most important missing conditional branch, and run one baseline and one authorized personalized check with the same prompt. That gives you a defensible editorial action now, plus a repeatable method as Gemini’s integrations reach more accounts and search surfaces.

    References