Tag: AI Overviews

  • How to Build an AI Search Citation Strategy That Compounds

    How to Build an AI Search Citation Strategy That Compounds

    Your organic rankings can hold steady while the visibility those rankings used to create quietly disappears. On parts of LinkedIn’s B2B marketing sites, non-brand awareness traffic fell by as much as 60% across specific topics even though rankings remained stable. The answer itself had started absorbing the discovery that once required a click.

    You now need a strategy for being retrieved, understood, trusted, mentioned, and cited before a prospect reaches your site. This is not a replacement for SEO. It is a way to make your SEO, content, digital PR, structured data, and measurement work together around the answers people receive from ChatGPT, AI Overviews, Bing, and other answer interfaces.

    Key takeaways

    • Optimize for the questions that shape a decision, not every prompt that happens to mention your category.
    • Treat the initial question and its follow-ups as one journey. The first answer often establishes the sources that later turns build upon.
    • Make every important page easy to extract and verify: state the answer early, define entities clearly, qualify claims, and place evidence beside the claim it supports.
    • Combine owned content with credible external corroboration. A page can be accurate and still lose citations if the wider information environment does not support it.
    • Measure answer presence, citation quality, accuracy, and business response separately. Referral traffic alone cannot show how much influence AI answers created.

    Build a citation map before producing more content
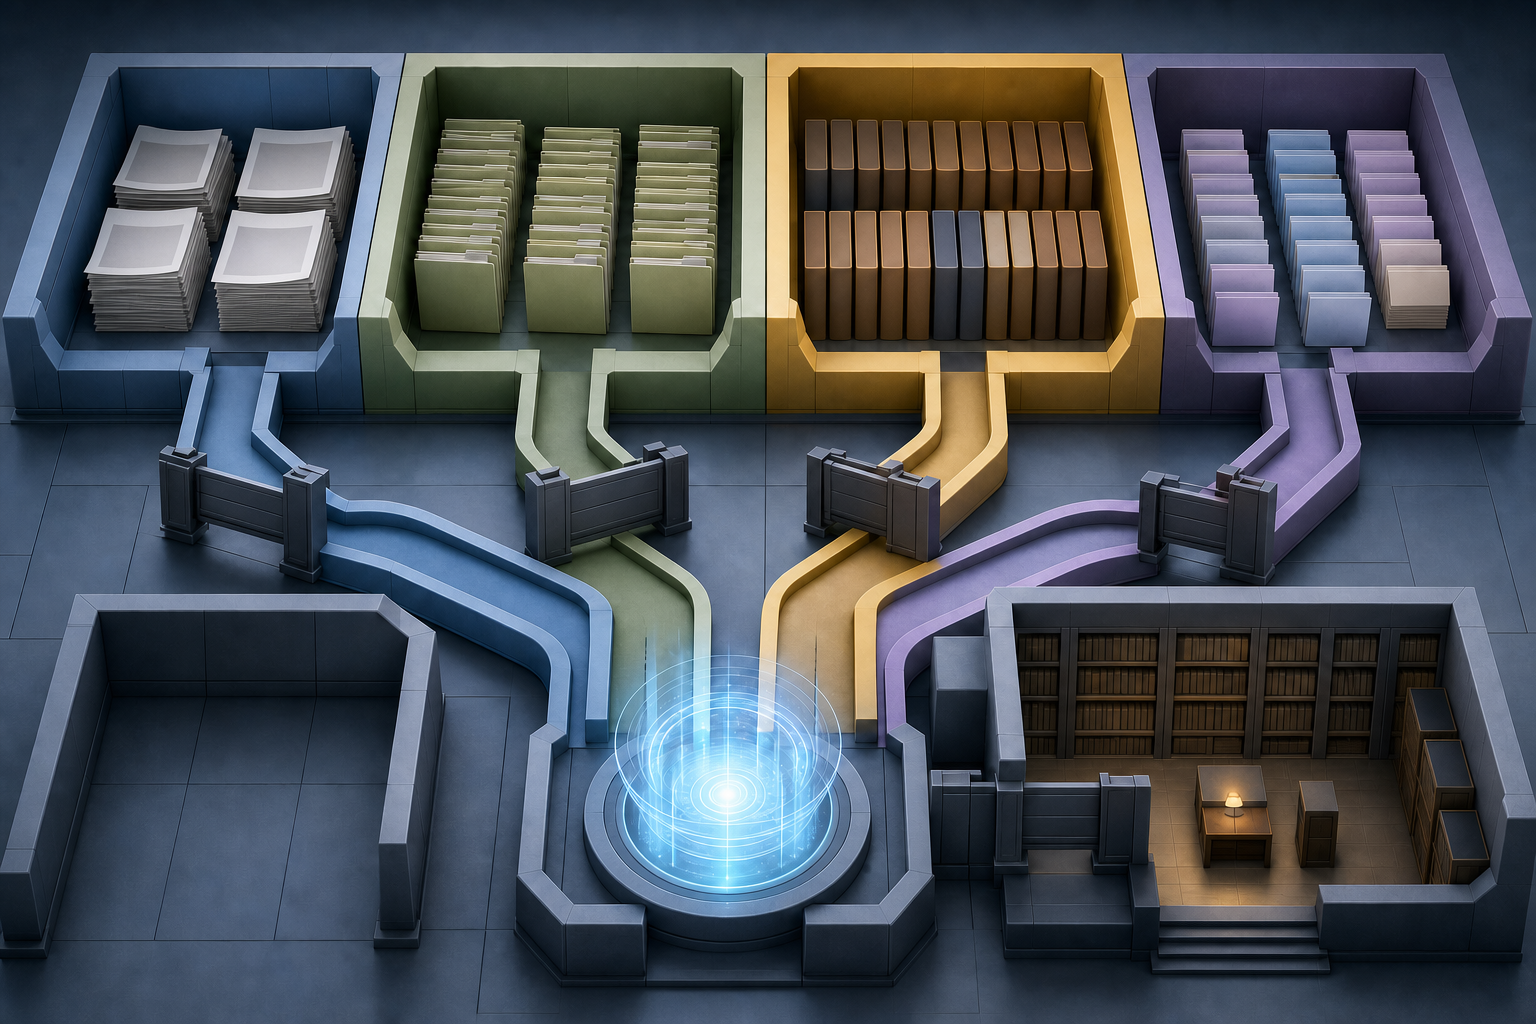
    An isometric network of blank document tiles, source pillars, topic spheres, and verification markers sits on a planning table.

    A keyword list tells you what people search. A citation map tells you what an answer engine needs in order to answer, which claims require support, and where your brand deserves to appear. That distinction prevents a common failure: publishing more broadly while leaving the commercially important questions unanswered.

    Start with the decision, not the query volume

    Choose questions by the decision they influence. A high-volume definition may create awareness, but a lower-volume question about suitability, implementation, risk, or cost may determine whether your company enters the consideration set. The right target is the intersection of audience need, business relevance, and evidence you can genuinely provide.

    For each topic, record:

    • The audience: who is asking and what they already understand.
    • The decision: what they are trying to choose, approve, reject, or do next.
    • The opening question: the broad request likely to begin the session.
    • The follow-up questions: the constraints, comparisons, objections, and requests for proof that narrow the answer.
    • The claims required: definitions, criteria, trade-offs, facts, limitations, and procedures needed for a complete response.
    • The best evidence: first-party documentation, original data, an official definition, a transparent method, or independent corroboration.
    • The current citation candidates: your relevant URL and the external domains already associated with the topic.
    • The gap: what is missing, ambiguous, unsupported, outdated, or difficult to extract.

    This becomes your operating document. Content teams can see what to publish, PR teams can see which claims need external validation, technical teams can see which entities need clearer markup, and analysts can see which answer journeys to monitor.

    Plan for the first answer and the follow-up chain

    Across 700,000 ChatGPT conversations containing web citations in the fourth quarter of 2025, most citations were captured in the first turn. Wikipedia was prominent for general knowledge, while other cited domains tended to cluster around particular topics. That dataset is directional rather than a universal rule, but it makes the opening answer too important to treat as a generic awareness prompt.

    The opening page should establish the core definition, entities, framing, and evidence. Supporting pages can then handle comparisons, exceptions, implementation details, and objections. Link them through descriptive anchor text so the relationship is legible to readers and machines. Do not force one oversized page to answer every possible branch.

    At the same time, do not optimize for an isolated prompt. Bing’s worldwide multi-turn search can retain context for follow-up questions, reflecting a broader move from disconnected searches to continuing conversations. Test whether your brand remains relevant when the user adds a budget, industry, location, compatibility requirement, risk concern, or alternative. A citation won on a broad question is weak if your evidence disappears as soon as the decision becomes specific.

    Prioritize citation-map gaps using three judgments: the consequence of being absent or wrong, the quality of evidence available, and your realistic ability to become a credible source. Work first where all three are strong. A topic with business value but no defensible evidence is not ready for content production; it needs product documentation, data, expert input, or independent validation first.

    Make each page easy to extract, verify, and reuse

    Answer engines do not cite a page merely because it ranks or repeats the right phrase. The page has to contain a passage that can survive extraction: the meaning must remain clear when the passage is separated from the title, surrounding copy, navigation, and brand context.

    Build citation-ready answer units

    Put the direct answer immediately after a descriptive heading. Then provide the reason, evidence, qualifier, and next action. This gives an answer engine a concise passage to retrieve without stripping away the conditions that make the claim accurate.

    A citation-ready unit usually contains:

    • A named subject: identify the product, organization, process, standard, audience, or platform instead of relying on vague pronouns.
    • A direct claim: answer the heading before adding history, scene-setting, or promotional language.
    • A boundary: state the version, market, audience, situation, or limitation when the answer is not universal.
    • Adjacent evidence: place the supporting method, data, documentation, or link beside the claim rather than in a distant resources page.
    • A freshness signal: show when material was published or materially reviewed, and explain version-dependent changes in the body.
    • Clear ownership: identify the organization and, where relevant, the qualified person responsible for the content.

    Read the passage without its page title. If you cannot tell what is being discussed, who the advice applies to, or why the statement should be trusted, the passage is not ready to serve as evidence.

    Separate readability, retrievability, and credibility

    These are related but different jobs. A well-written page can still be difficult to retrieve if its headings are generic. A well-structured page can still be untrustworthy if its claims have no evidence. An authoritative page can still be unusable if the answer is buried inside a long narrative.

    • Readability: use plain language, short paragraphs, descriptive headings, and lists only where the material is genuinely sequential or categorical.
    • Retrievability: keep each section focused on one recognizable question, name entities consistently, and use internal links that explain the relationship between pages.
    • Credibility: show methods, limitations, accountable authorship, primary evidence, and corrections. Remove claims that exist only because competitors repeat them.

    Clear headings, semantic hierarchy, accessibility, fresh expert content, and strong information structure remain useful in AI-led discovery. These practices sound familiar because they are extensions of durable SEO and content-quality work. Their value now reaches beyond rankings into whether a passage can be understood and reused inside an answer.

    Use JSON-LD to clarify, not to compensate

    Use JSON-LD to describe entities and content that are already visible on the page. Connect the organization, author, article, product, and other relevant entities consistently across your site. Choose schema types that match the page rather than the search feature you hope to obtain.

    Structured data cannot turn a vague assertion into evidence, make an anonymous page authoritative, or guarantee an AI citation. It is a clarification layer. If the visible copy and markup disagree, fix the copy and data model instead of adding more markup. The strongest implementation makes the same entity relationships clear in the prose, internal links, metadata, and JSON-LD.

    Build corroboration, correction, and budget into one workflow
    A transparent modular workflow turns blank source pages and evidence objects into reusable information blocks connected to reference nodes.

    Owned content is essential because it gives you a canonical place to define your products, policies, evidence, and terminology. It is not sufficient for every kind of claim. Answer engines may rely on broad reference sites for general knowledge and topic-specific domains for specialized questions. Your citation strategy therefore needs both a strong canonical page and an accurate external information environment.

    Earn corroboration where it has a legitimate reason to exist

    Start by classifying each important claim. Product specifications and company policies belong in first-party documentation. Claims about market importance, comparative performance, or category leadership usually need transparent evidence or independent support. Definitions may be better anchored to an originating standard, institution, or primary text than to your marketing page.

    Then pursue the external format that fits the claim: expert commentary, documented partnerships, reputable profiles, original research with a disclosed method, or coverage that adds independent analysis. The objective is not to scatter identical brand language across domains. It is to make accurate facts available in places that have their own editorial reason to mention them.

    Do not treat Wikipedia prominence as permission to manufacture a presence there. A reference page is valuable only when the subject meets its standards and independent citations support the material. Promotional editing creates a fragile signal and a reputation risk. If the evidence is not strong enough for independent editors to verify, improve the evidence rather than the entry.

    Run an explicit misinformation correction loop

    When an AI answer is wrong, save enough context to reproduce the problem: the platform, mode, exact prompt, relevant prior turns, market, answer text, citations, and observation date. A screenshot alone is useful for evidence but poor for diagnosis because it may omit the conversational context that shaped the response.

    1. Classify the error. Determine whether the answer is outdated, factually false, attributed to the wrong entity, missing a limitation, or merely absent.
    2. Trace the claim. Open the cited URLs and find the wording or ambiguity that could have produced the answer.
    3. Repair the canonical record. Update the appropriate owned page with a direct correction, clear entity names, supporting evidence, and the relevant qualifier. Preserve a stable URL where practical.
    4. Repair corroborating pages. Ask legitimate publishers, partners, directories, or profile owners to correct inaccurate information they control. Do not request language their evidence cannot support.
    5. Retest the journey. Repeat the opening question and the important follow-ups. Record whether the answer, mention, and cited URL changed.
    6. Keep the case open until accuracy stabilizes. An immediate retest can show whether the problem persists, but retrieval and model updates do not follow a schedule you control.

    This work crosses organizational boundaries. LinkedIn organized AI-search work across SEO, PR, editorial, product marketing, and other teams, including efforts to correct misinformation and publish content designed for AI visibility. You may not need a formal task force, but every tracked issue needs a named owner and a route to the team that can fix the underlying fact.

    Fund the workstream, not the AEO label

    AEO pricing models affect both the budget and where resources can be applied. Compare proposals by the work they actually fund rather than by a single visibility promise. A complete program may need diagnosis, evidence creation, content editing, technical presentation, authority development, monitoring, correction, and measurement. Paying for only the dashboard tells you where you are absent but does not create a credible reason to include you.

    Before approving an internal budget or vendor proposal, ask:

    • Does prompt monitoring include opening questions and contextual follow-ups?
    • Will you receive the answer text, cited domains, exact cited URLs, and observation context?
    • Does content work include implementation and editorial review, or only recommendations?
    • Who supplies and validates the evidence behind new claims?
    • What does authority development mean in practice, and which placements or outreach activities are excluded?
    • Who owns misinformation cases from discovery through correction and retesting?
    • How will AI visibility data connect to web analytics, branded demand, sales conversations, and conversions?

    Budget first for the bottleneck. If your pages are vague and unsupported, monitoring more prompts will document the same weakness in greater detail. If your canonical content is already clear and authoritative, the next constraint may be external corroboration or measurement. Reassess the bottleneck as the program develops instead of locking every workstream into the same level of spending.

    Measure influence without pretending every answer produces a click

    AI visibility and referral traffic are not interchangeable. A user can see your brand, accept a cited claim, ask several follow-ups, and visit later through a branded search or direct navigation. Another user can click immediately. Standard analytics can observe the second path more easily than the first.

    The imbalance is already visible in practice. LinkedIn reported triple-digit growth in LLM-referred visits to its B2B marketing sites while the channel remained a small portion of overall traffic. That is one company’s experience, not a universal benchmark. It illustrates why a fast-growing referral segment can still understate the influence of answer-led discovery.

    Build a scorecard with separate layers:

    • Answer coverage: whether the monitored answer addresses the topic accurately and completely enough to support the user’s decision.
    • Brand presence: whether your organization, product, expert, or terminology appears, and what role it plays in the answer.
    • Citation presence: whether a citation supports the passage where your brand or claim appears, rather than merely appearing elsewhere in the response.
    • Citation ownership: whether the cited URL is owned, earned, neutral, or controlled by another commercial party.
    • Accuracy: whether the answer preserves material conditions, limitations, version details, and entity relationships.
    • Journey depth: whether your visibility survives the follow-ups that move the user from orientation to evaluation and action.
    • Business response: LLM referrals, engagement, conversions, branded-search movement, direct demand, and qualitative evidence from sales or support conversations.

    Store the platform, search mode, prompt, conversational context, market, observation date, response, and citations with every evaluation. AI answers can vary, so a single manual query should be treated as an observation, not a performance trend. Use a stable prompt set for comparison, but review it when customer questions or product conditions change.

    Read combinations of metrics instead of chasing one visibility score:

    • Rankings stable, clicks down, answer mentions up: the answer interface may be satisfying more awareness demand before the click. Improve downstream calls to action, but do not describe the visibility as an SEO loss without examining the answer.
    • Mentions up, citations flat: the brand may be recognized without being selected as evidence. Strengthen claim-level proof and legitimate corroboration.
    • Owned citations up, accuracy weak: inspect the exact cited passage. Ambiguous wording, missing qualifiers, or entity confusion may be making the page easy to retrieve but unsafe to reuse.
    • Referral growth high, total volume small: treat it as a directional signal. Evaluate visit quality and conversions without presenting the channel as a replacement for established acquisition sources.
    • Visibility unchanged after a content refresh: check retrieval, internal linking, technical accessibility, evidence quality, and external corroboration before repeatedly rewriting the same page.

    Start with the commercially important question for which an inaccurate or absent answer carries the greatest consequence. Map its conversation, repair the canonical page, add defensible corroboration, and monitor the whole path through follow-up questions. Once that loop works, extend it to the next decision. That is how AI-search visibility becomes a repeatable operating capability instead of a collection of prompt screenshots.

    References

  • SEO as a Brand and Performance Channel: The New Reality

    SEO as a Brand and Performance Channel: The New Reality

    I’ve come to realize that SEO now serves as both a brand and performance channel. The traditional traffic model has been disrupted by AI Overviews and zero-click SERPs, making brand strength crucial for SEO ROI.

    For years, SEO was straightforward: rank higher, get more traffic, then boost the sales pipeline. However, this simple equation is rapidly evolving, much to the frustration of marketing leaders.

    With AI Overviews and users getting answers directly from LLMs, the idea of “rank and receive traffic and leads” is less effective now. Even top keyword positions don’t guarantee the clicks they once did.

    This shift has sparked challenging discussions in boardrooms. Executives often question, “If traffic is down, how can we measure SEO success?”

    It’s obvious now: the traffic model has changed, yet the demand for ROI remains. We must treat SEO as a brand-dependent performance channel, not just a traffic provider.

    Why traffic and pipeline are no longer in lockstep

    Linear attribution has never fully reflected the dynamic nature of organic search. While ChatGPT isn’t replacing Google, it’s augmenting it.

    Users now verify information across platforms due to skepticism of search and LLM results. Where research once happened solely within Google’s ecosystem, it has become more scattered.

    Today’s organic search is akin to a pinball machine, with buyers bouncing across channels unpredictably. This introduces complexity that traditional attribution software struggles to follow.

    Such complexity has broken the linearity executives crave. Traffic and pipeline charts, once aligned, now often diverge.

    Across B2B SaaS portfolios, a common pattern emerges: organic sessions may be flat or declining, yet rankings for high-intent terms stay stable, and the pipeline from organic search grows.

    This mismatch doesn’t indicate SEO failure. Rather, it shows that traffic is no longer a reliable business impact measure.

    The traffic lost to zero-click searches often consists of informational, low-intent content. What remains is higher-intent traffic, closer to conversion.

    We’re seeing the “atomization” of search demand. Short-head, broad keywords are declining, while specific, long-tail queries with higher intent are rising.

    Many leaders mistakenly react to dropping sessions by pushing for quantity, aiming to regain the lost numbers through top-of-funnel content. This often inflates vanity metrics without delivering qualified leads.

    ```json
{
  "alt": "Metrics table showing increases in demo requests, pipelines, and other areas, but a 2% decrease in organic traffic highlighted.",
  "caption": "Despite organic traffic slightly dipping by 2%, other key metrics like demo requests and conversion rates soar, showcasing business growth.",
  "description": "This image displays a metrics table with a focus on conversion and pipeline metrics. It indicates substantial increases in demo requests (up 130%) and other areas, despite a highlighted 2% decrease in organic traffic. The data suggests overall positive performance with significant growth in multiple areas, emphasizing the message 'Traffic Flat → Revenue Up!' SEO, performance metrics, and business analytics keywords are relevant."
}
```

    SEO ROI is now the downstream outcome of brand traction

    For years, SEO was viewed as a pure performance channel. We believed optimizing some keywords would suffice.

    In reality, SEO has always depended on brand strength. The rise of AI-driven engines highlights this, expecting reputations, not just keywords.

    If your brand lacks authority, technical optimizations alone won’t elevate your status. Brand strength determines organic performance limits. Search engines seek web-wide consensus, and weak associations hinder results.

    Brand strength for LLMs means owning topical authority, aligning with customer queries, being validated by trusted sources, and having clear positioning.

    SEO captures pre-existing demand validated by your brand, not creating it from nothing.

    The new defensibility metrics for SEO

    As traffic no longer headlines KPIs, new defensibility metrics are necessary. Successful teams focus on revenue and reputation impact, not just volume.

    Metrics proving business impact include stable top-10 rankings for commercial keywords, increased Ahrefs traffic value, stable solution page traffic, growing homepage traffic, and developing LLM referral traffic.

    When pipeline per organic visitor rises, even with falling sessions, the dialogue shifts from “SEO is broken” to recognizing SEO’s evolution.

    Modern SEO is moving from acquisition to influence

    Successful SEO isn’t about recovering traffic but influencing buyer decisions and enhancing organic visibility. In an AI-first context, zero-click doesn’t imply zero-value.

    SEO remains key in building market readiness, positioning brands as authorities even before buyers enter the funnel.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Publisher Controls for Google AI Overviews and AI Mode

    Publisher Controls for Google AI Overviews and AI Mode

    You have a decision to prepare for, but not yet a reliable switch to flip. Google has discussed letting publishers opt out of AI Overviews and AI Mode, yet it has not disclosed a clear, feature-specific implementation. Adding a guessed crawler rule or sitewide directive now could affect more than the AI feature you meant to control.

    Do the policy work first. Decide which content you would exclude, what outcome would justify exclusion, how you would detect collateral damage, and what would trigger a rollback. Then, if Google releases a documented control, you can test it as an operating decision instead of reacting with a blanket yes or no.

    The opt-out question is ahead of the actual control

    Google has been exploring ways for websites to opt out of AI-generated search features. What publishers still need is the operational detail: whether a control would apply to AI Overviews, AI Mode, or both; whether it could be used on individual URLs or only an entire site; how quickly a change would take effect; and whether it would alter eligibility for traditional search.

    Until those questions have documented answers, nobody can responsibly give you an exact implementation recipe. A directive intended for an AI training crawler is not automatically a control for an AI-generated search result. A general search restriction is not automatically limited to AI. The names may sound related, but the scope and business consequences are different.

    Publishers are already divided on the underlying choice. In an X poll with more than 350 responses, 33.2% said they would block Google, 41.9% said they would not, and 24.9% were unsure. Treat that as evidence of a real strategic disagreement, not as a representative estimate of the entire publishing market.

    The disagreement makes sense because “block AI” is not a business objective. One publisher may prioritize broad discovery. Another may place more value on controlling the reuse of expensive original work. A third may want visibility in AI results but only when those appearances send qualified readers or reinforce the brand. You cannot resolve those positions with a technical toggle alone.

    Keep three decisions separate in every internal discussion:

    • AI training access: whether a named crawler may collect content for a training-related purpose.
    • Traditional search access: whether Google can crawl, index, and present a page in established search results.
    • AI search presentation: whether content can contribute to or appear in AI Overviews and AI Mode.

    That distinction matters because 79% of nearly 100 leading UK and US news websites were blocking at least one AI training crawler. That shows publishers are actively managing training access. It does not establish that the same sites have opted out of Google AI search features, or that a training-crawler block would produce that result.

    Build the policy around content classes, not one domain-wide answer

    Different types of unlabeled publishing materials are sorted into compartments and routed separately toward or away from an abstract AI portal.

    A sitewide decision is simple to announce and difficult to evaluate. Your domain probably contains pages with different economics and different jobs: original reporting, evergreen reference material, product or service pages, subscriber content, documentation, archives, and pages built primarily to acquire search visitors. A future control may or may not support URL-level rules, but your policy should be ready for that possibility.

    Create an inventory by template or content class. You do not need to classify every URL manually. Start with the groups that account for most of your search traffic, revenue, subscriptions, leads, or editorial investment.

    1. Name the page class. Use a stable label such as original news, analysis, evergreen guide, product page, documentation, archive, or subscriber-only content.
    2. State its primary job. Choose one: attract new readers, convert demand, retain subscribers, establish authority, support customers, or generate direct revenue.
    3. Record its dependency on Google discovery. Use your own impressions, clicks, landing sessions, conversions, and revenue rather than an editorial assumption.
    4. Identify the use you want to control. Say “AI Overviews and AI Mode” if that is the target. Do not write only “AI,” because that leaves training, search presentation, and other uses mixed together.
    5. Assign a provisional status: allow, exclude when a verified control exists, or include in the first test.
    6. Name the owner who can approve implementation and the owner who can order a rollback.

    The three provisional statuses keep uncertainty visible without forcing a premature technical change:

    • Allow: discovery is the dominant objective, so the current state remains in place unless measured harm changes the decision.
    • Exclude when possible: the content conflicts with a declared reuse or rights policy, but implementation waits for a documented control whose scope is understood.
    • Test: the trade-off is uncertain, so the content becomes a candidate for a limited, reversible experiment.

    Add the reason beside every status. “Editorial leadership requested it” is an approval trail, not a decision rule. A usable reason sounds like this: “These pages depend on search acquisition, so exclusion will be retained only if targeted AI use declines without pushing qualified organic visits or conversions below our predeclared guardrails.”

    If Google ultimately offers only a domain-wide setting, your classification work still matters. It shows which page groups carry the benefit and which carry the cost. That gives leadership a defensible basis for accepting or rejecting the broader control.

    Decide what success and failure look like before changing anything

    A publisher test fails when the team changes a setting first and chooses the interpretation later. Traffic can move for many reasons. If your success criteria remain unwritten, almost any result can be used to defend the decision someone already preferred.

    Build a measurement sheet with four layers:

    • Business outcome: qualified leads, purchases, subscriptions, advertising value, or another result tied to the selected page class.
    • Search referral outcome: impressions, clicks, click-through rate, landing sessions, and the queries sending those visits.
    • AI feature observation: whether the chosen URLs or brand appear for a fixed set of queries in AI Overviews or AI Mode.
    • Technical guardrails: continued crawling, indexation, and appearance in the traditional search surfaces you intended to preserve.

    Do not assume your normal analytics can isolate every AI feature appearance. If they cannot, create a manual observation set. Select queries before the test, record the page and feature being checked, keep the location, account state, and device conditions as consistent as practical, and save dated evidence. The purpose is not to estimate all AI visibility from a small sample. It is to check whether the behavior of known query-URL pairs changed after the control.

    Use queries where the page had previously appeared in the targeted feature whenever possible. If an AI Overview does not appear for a query on a later check, that single absence does not prove the exclusion worked; the feature itself may not have appeared. Verification needs to distinguish “the feature was present without our content” from “the feature was not present at all.”

    Write the retention rule in advance. A practical template is:

    We will retain exclusion for [content class] only if the targeted use declines in our logged sample, organic search outcomes remain above our chosen floor, the primary business metric stays within its guardrail, and traditional search eligibility shows no unintended change.

    Publisher decision template

    Choose the floors from your own historical volatility and business tolerance. There is no credible universal percentage that tells every publisher when loss of reach is worth greater content control. A subscription publisher, a lead-generation site, and an advertising-funded newsroom can assign very different values to the same traffic movement.

    Test a documented control with the smallest reversible scope

    A single article tile is tested in a transparent chamber while an operator monitors indicator lights beside a rollback lever.

    When Google publishes an actual control, verify what it governs before deploying it. The label is not enough. Read for its target feature, supported scope, interaction with traditional search, activation behavior, verification method, and rollback procedure. If the documentation does not answer one of those questions, record it as an unresolved risk rather than filling the gap with an assumption.

    Then run the test in this order:

    1. Choose a narrow cohort. Prefer one content class or template over the entire site when the documented control permits it.
    2. Select a comparison cohort. Match pages as closely as practical on purpose, query demand, historical performance, update pattern, and publication timing.
    3. Capture a baseline. Include a period that reflects your normal publishing or business cycle, and note promotions, seasonal events, migrations, algorithm changes, or major editorial updates that could distort it.
    4. Freeze avoidable confounders. Do not simultaneously rewrite titles, change internal links, redesign templates, or move URLs unless those changes are part of the test.
    5. Apply one documented control. Log the exact setting, scope, time, implementer, approver, and expected outcome.
    6. Verify the target behavior. Check the tracked query-URL pairs and confirm that any observed change concerns AI Overviews or AI Mode rather than a broader loss of search access.
    7. Compare business results and guardrails. Use the predeclared rule, not a newly chosen metric that happens to support the preferred conclusion.
    8. Roll back if the blast radius is larger than intended. Preserve the implementation log so the team can separate recovery from later unrelated changes.

    If the control is sitewide only, you lose the cleanest form of an internal comparison. Do not pretend a before-and-after chart proves causation. Keep a dated change log, use the same tracked query set, document concurrent events, and require stronger evidence before making the setting permanent.

    Operational cost belongs in the result as well. A page-level control that must be maintained across several publishing systems creates a different burden from a stable sitewide setting. Record implementation time, quality-assurance failures, ownership gaps, and rollback effort. A policy that cannot be maintained reliably is not an effective control, even when its strategic intent is sound.

    Key takeaways

    • Google has discussed publisher opt-outs for AI Overviews and AI Mode, but a clear feature-specific implementation has not been established here.
    • Blocking an AI training crawler is not the same as opting out of an AI-generated search feature.
    • Classify content by business purpose and Google dependency before choosing allow, exclude, or test.
    • Predeclare the target behavior, primary business metric, search guardrails, technical checks, and rollback condition.
    • When a documented control arrives, begin with the smallest reversible cohort its scope permits.

    Your useful next step is a one-page control brief, not a speculative configuration change. Assign an owner, classify the page groups that matter, capture their baseline, and list the documentation questions Google must answer. When a real control becomes available, you will be ready to evaluate it with evidence instead of making a domain-wide bet under deadline pressure.

    References

  • Publisher Opt-Outs From Google AI Search: A Practical Plan

    Publisher Opt-Outs From Google AI Search: A Practical Plan

    You want Google Search to keep finding your work, but you may not want that work used to produce answers in AI Overviews or AI Mode. The problem is that changing the wrong control could limit ordinary Search visibility without giving you the AI-specific choice you intended.

    Don’t add a guessed directive or treat every Google AI control as interchangeable. Google has confirmed that it is exploring updates that would let sites opt out of Search generative AI features, but it did not provide a launch date, directive name, implementation syntax, or final description of the consequences. Your useful work now is to separate the controls, define your decision criteria, and prepare a reversible rollout.

    The proposed opt-out is not an implementation instruction

    Google identified AI Overviews and AI Mode as the Search generative experiences at issue. It also said any new publisher control must preserve the usefulness of core Search and avoid creating a fragmented or confusing experience. That tells you why the problem is difficult, but not how the eventual mechanism will behave.

    Until Google publishes the actual specification, nobody can responsibly tell you what token to add, whether the setting will work at the domain, directory, or page level, how quickly a change will take effect, or whether opting out will alter links, previews, rankings, or eligibility elsewhere in Search. Those are unresolved product questions, not details you should fill in by analogy.

    Key takeaways

    • Google is exploring a dedicated opt-out for Search generative features; the disclosed proposal did not include deployable syntax or a release date.
    • Google-Extended addresses how site content helps train Gemini models. It should not be treated as a confirmed AI Overviews or AI Mode opt-out.
    • Robots controls, preview controls, model-training controls, and Search generative controls answer different questions.
    • Do not precommit to opting in or out until you know the final control’s scope and its relationship with ordinary Google Search.
    • Prepare an inventory, measurement baseline, approval owner, and rollback plan before the mechanism arrives.

    Separate four control layers before changing anything

    An isometric publishing system sends a page through four separate adjustable gates representing discovery, crawler access, previews, and generative processing.

    The phrase “AI opt-out” is too broad to drive a technical change. It can refer to training a model, generating a search answer, displaying an extract, or accessing a page for core Search. Write down which use you mean before evaluating any directive.

    Control layerWhat Google has describedThe decision it addresses
    Core Search access and appearanceLong-standing publisher controls based on standards such as robots.txtHow Google may access and handle content for ordinary Search
    Search-result presentationControls for Featured Snippets and image previews, which can also be relevant to AI OverviewsHow much content Google may show as a preview or extract
    Gemini model trainingGoogle-ExtendedWhether site content may help train Gemini models
    Search generative useA proposed, not yet specified, opt-out for AI Overviews and AI ModeWhether content may be used in Google’s generative Search experiences

    The most important distinction is between model training and generation at search time. Google discussed Google-Extended as a Gemini training control and then described a separate control under consideration for Search generative features. That separate treatment means the presence of Google-Extended does not establish that a page is excluded from AI Overviews or AI Mode.

    If an audit, policy, or vendor report labels your site “opted out of Google AI” solely because Google-Extended is present, ask for product-specific evidence. The accurate statement is narrower: the setting concerns Gemini training. Keep the Search generative status marked as unresolved until Google publishes a dedicated mechanism and its scope.

    Structured data is separate as well. Schema markup helps machines interpret entities, attributes, and relationships on a page; it is not a consent or exclusion directive. Continue improving useful structured data for discoverability, but do not represent it internally as a way to grant or deny generative use.

    Decide what you are protecting and what you depend on

    Google’s stated position is that AI Overviews help people discover content and explore more topics. That is the platform’s case for generative Search, not a guarantee that your pages will receive qualified visits, conversions, subscriptions, or revenue. Your decision has to reflect how each part of your publishing business creates value.

    Start with two questions: how important is Google discovery to this content, and how strict is your policy on generative reuse? Those answers may differ across a single domain. A public help center, subscriber analysis, licensed database, product catalog, and evergreen editorial library do not necessarily need the same rule.

    • If discovery is the priority and reuse concerns are limited: do not promise an opt-out in advance. Preserve the current configuration, establish a baseline, and evaluate the documented effects when the control is released.
    • If control is the priority and Search discovery is secondary: prepare the internal approval to opt out, but make deployment conditional on confirmation that the mechanism does what your policy requires.
    • If your content portfolio is mixed: make granularity a go-or-no-go criterion. A path-level or page-level option could support different policies; a domain-wide switch could force a much larger business decision.
    • If you cannot quantify the tradeoff: plan a limited, reversible test if the final mechanism supports one. Do not turn uncertainty into a sitewide default.

    For every content family, record the outcome that matters on your own site: advertising consumption, a lead, a sale, a subscription, a download, account usage, or support deflection. Then record the competing concern: licensing limits, exclusivity, editorial policy, brand representation, or a general preference against generative use. This turns an abstract argument about AI into an explicit operating decision.

    Do not assume that the future opt-out will remove your words from a generated answer while preserving a citation, or that it will leave ordinary Search performance untouched. Do not assume the opposite either. Google has said it wants new controls to avoid breaking Search, but the final interaction has not been specified.

    If third-party licenses or contracts limit machine use, have the person responsible for those rights review the final specification before deployment. A technical setting can support a rights policy, but the mere presence of a setting does not establish that contractual obligations have been satisfied.

    Build a publisher decision package before launch

    Four publishing professionals review blank documents, a server model, abstract dashboard shapes, and two color-coded pathways around a meeting table.

    The fastest safe response to a new control will come from work that does not depend on its syntax. Build one compact decision package now so your SEO, editorial, legal, product, and engineering teams are not debating first principles after a release.

    1. Assign one accountable owner. Name the person who will confirm the final documentation, collect stakeholder approval, authorize production changes, and own rollback. Consultation can be broad; deployment authority should not be ambiguous.
    2. Inventory content by policy-relevant group. Use hostnames, directories, templates, or content types rather than starting with individual URLs. Record the business owner, discovery goal, onsite outcome, third-party rights, and desired AI policy for each group.
    3. Document the controls already in production. Capture your current robots.txt rules, Featured Snippet and image-preview choices, Google-Extended configuration, relevant page-level directives, and the systems that generate them. Label each control by its actual purpose.
    4. Save a pre-change baseline. Export organic Search impressions and clicks, important landing-page actions, conversion or subscription outcomes, and a representative record of crawl and index status. Preserve the reporting definitions so the later comparison uses the same measurements.
    5. Write a conditional decision. Use language such as: “Opt out for this section only if the final control covers AI Overviews and AI Mode, supports directory-level scope, and does not remove the section from core Search.” A condition is useful before launch; guessed syntax is not.
    6. Prepare change and rollback records. Your deployment entry should capture the exact directive, affected properties, implementation location, approver, release time, validation result, monitoring owner, and reversal procedure.

    A useful inventory can be a single sheet with columns for hostname, path or template, content owner, revenue or user outcome, Search dependency, rights constraints, existing Google controls, preferred generative policy, required granularity, approver, and rollback owner. The point is not to score every URL. It is to expose where one sitewide setting would combine content with different needs.

    Keep the measurement claim modest. A before-and-after change can show whether important site outcomes moved, but it may not prove that the opt-out caused the movement. Search demand, rankings, publishing volume, and product changes can move at the same time. Log other releases and compare equivalent content groups where the final control makes that possible.

    Require clear answers before production deployment

    When Google releases a control, read its final documentation as a specification. A headline saying that publishers can opt out is not enough. Your owner should be able to answer every question below with product documentation before approving a change.

    • Product coverage: Does the control apply to AI Overviews, AI Mode, or both? Does it cover every content format you publish?
    • Prohibited use: Does it prevent content from contributing to generated text, or does it also change links, citations, extracts, images, and previews?
    • Scope: Can you configure it by domain, subdomain, directory, template, page, or asset?
    • Core Search interaction: What happens to crawling, indexing, ranking eligibility, result links, Featured Snippets, and image previews?
    • Relationship with existing controls: Which rule wins when robots, preview, Google-Extended, page-level, and Search generative settings differ?
    • Processing: How does Google discover a change, how long may processing take, and what happens to content processed before the change?
    • Verification: Is there a testing tool, status report, inspection result, or other way to confirm that Google recognized the setting?
    • Reversibility: How do you restore eligibility, and is restoration processed on the same timetable as exclusion?

    If the mechanism is delivered through robots.txt, validate the public production file rather than only the CMS setting that is supposed to generate it. Check the response status, exact user-agent grouping, syntax, and the version served through your CDN. Confirm that an automated deployment cannot overwrite it. A misplaced rule in robots.txt can affect more than the feature you intended to control.

    If Google uses a page-level meta directive or HTTP response header instead, inspect the server-rendered HTML and live headers across representative templates. Check canonical and alternate versions, cached pages, and any CMS plugin that can emit competing directives. These are conditional validation steps; Google has not specified which delivery method the proposed control will use.

    For now, document your existing settings, correct any internal claim that Google-Extended already excludes AI Overviews, and set a release trigger. When Google publishes the final scope and syntax, your owner can compare them with the decision package, approve a narrow rollout where possible, and monitor the outcomes that matter to your business. Until that trigger is met, the right preparation is governance and measurement, not speculative code.

    References

  • How Google Counts Impressions When One URL Appears Twice

    How Google Counts Impressions When One URL Appears Twice

    You see your page cited inside an AI Overview and again as a traditional blue link. It looks like two pieces of search-result real estate, so you expect Google Search Console to report two impressions. It won’t.

    When the same URL appears in both places for the same query and search experience, Google Search Console records one impression rather than two. Once you understand what is being counted, you can stop treating the result as a tracking fault and start measuring the extra visibility separately.

    Key takeaways

    • The same URL appearing in an AI Overview and a traditional blue link produces one Search Console impression for that search experience.
    • Google treats an AI Overview as one position, with the links inside it sharing that position under the usual impression rules.
    • Repeated appearances of the same URL in the current set of results are aggregated rather than counted as separate impressions.
    • One impression does not mean there was only one placement. It means Search Console has compressed those placements into one URL-level count.
    • Keep Search Console performance data and observed SERP placement data in separate reporting layers if you need to evaluate AI Overview visibility.

    The counting rule follows the URL, not the number of boxes

    One webpage tile branches into two different search result placements while passing through a single counting gate.

    An impression is tied to the visibility of a link within the current set of search results. Google does not issue another impression merely because the same URL is presented in a second search feature on that results page.

    This matters because an AI Overview may contain several links while occupying a single position. Each link in the Overview shares that position and remains subject to the standard visibility rules. If one of those URLs also appears in the blue links below, the extra occurrence does not create a second impression for that URL.

    What happens in one search experienceHow to interpret the impression countWhat not to assume
    The same URL appears in an AI Overview and a blue linkOne impression is counted for that URLThe second placement was not necessarily missed or ignored
    The same URL appears more than once in the current resultsThe occurrences are aggregatedEach visual instance does not receive its own impression
    The user scrolls past the URL and returns to itNo additional impression is created within that results experienceRepeated visibility does not restart the counter
    Two different URLs from the same site appearThe same-URL clarification does not determine the resultDo not extend a URL-level rule to an entire domain without separate evidence

    The last distinction is important. The rule is about the same URL. It does not establish that every appearance from the same brand, domain, or group of similar pages will be consolidated. When you investigate a discrepancy, compare URLs rather than counting logos, domains, or visually similar listings.

    One impression does not mean one placement

    Search Console’s count is easy to misread as an inventory of everything Google displayed. It is not. In this situation, one impression can represent a URL that occupied two visibly different parts of the results page.

    That compression limits what you can conclude from the number alone. A single recorded impression cannot tell you whether the searcher noticed the AI Overview citation, the blue link, or both. It also cannot isolate the incremental effect of securing both placements.

    • Do conclude: the URL received one qualifying Search Console impression under Google’s counting rules.
    • Do not conclude: the URL appeared only once on the results page.
    • Do conclude: the Search Console impression total should not be manually doubled to reflect two observed placements.
    • Do not conclude: the second appearance had no value simply because it did not add another impression.
    • Do conclude: dual placement can reinforce brand visibility and credibility.
    • Do not conclude: that reinforcement produced a specific traffic or conversion lift unless you have separate evidence.

    This is the practical distinction between measurement and presence. Search Console measures the impression according to its rules. The results page may still give the searcher two opportunities to encounter your page. Those are related facts, but they are not interchangeable metrics.

    Audit dual appearances without rewriting Search Console data

    If your dashboard appears to be missing an impression, first test whether the expected second impression came from counting the same URL twice on one results page. Use a short audit that preserves the reported data while documenting the SERP layout.

    1. Define the suspected duplication. Record the query, the URL, and the two elements in which you observed it. Use labels such as AI Overview and blue link instead of writing only that the page ranked twice.
    2. Verify that it is the same URL. Do not treat two pages from one domain as though they were automatically one reporting unit. If the displayed addresses differ, flag that difference rather than forcing the same-URL rule onto them.
    3. Capture the search-result composition. Note whether the URL appeared in the AI Overview, the traditional results, or both. This is placement evidence, not an adjustment to Search Console.
    4. Leave the Search Console impression unchanged. If the same URL occupied both placements in the same search experience, one impression is the expected result. Adding a second impression in a spreadsheet would make your derived total incompatible with Google’s count.
    5. Check the reporting model. A dashboard that creates one row per SERP feature may duplicate a shared impression when those rows are added together. Keep the impression in one performance record and store the placement labels separately.
    6. Repeat the observation before making a strategic claim. A single captured results page can confirm that dual placement is possible. It cannot, by itself, establish how often the pattern occurred across the full reporting period.

    This process also helps you identify the real problem. If the count matches the same-URL rule, there is no impression-counting error to fix. The missing element is a separate record of where the URL appeared.

    Report Search Console performance and SERP coverage separately

    A divided workspace shows one recorded impression on an analytics screen and two observed placements on a search results page.

    A useful report needs two layers. The first preserves Google’s performance data. The second describes the search features you observed. Combining them into one placement-based impression total creates false precision.

    Search Console performance layer

    Keep the query, URL, impressions, and other Search Console metrics together. Do not clone the record simply because the URL also appeared in an AI Overview. If you create separate AI Overview and blue-link rows, allocate placement labels without assigning the same impression to both rows and then summing them.

    SERP observation layer

    For each observation, store the query, exact URL, whether an AI Overview link was present, whether a blue link was present, and whether both occurred together. Include when the observation was made so nobody mistakes a captured result for a permanent search layout.

    The clean reporting language is: dual placement was observed, while Search Console counted the same URL once under its impression rules. Avoid saying that impressions doubled, that Search Console undercounted visibility, or that the second appearance generated a known incremental benefit. None of those claims follows from the impression total.

    Use the same distinction when setting targets. Search Console impressions can track reported URL visibility over time. A separate coverage field can track whether you are present in an AI Overview, a blue link, or both. That gives stakeholders two honest signals instead of one inflated number.

    The next time one URL occupies both parts of the results page, don’t adjust the impression count. Add a dual-placement annotation, preserve Google’s number, and evaluate the extra surface coverage as its own signal.

    References

  • AI and Organic Search Traffic: How to Diagnose a Decline

    AI and Organic Search Traffic: How to Diagnose a Decline

    If your organic dashboard is down, “AI killed search” is an easy diagnosis and a useless one. It does not tell you whether rankings slipped, search demand changed, or the results page satisfied more people before they clicked. Each problem requires a different response.

    The wider market is not in free fall, but an average cannot protect an individual site. You need to identify where your click opportunity has narrowed, protect the queries tied to business outcomes, and make priority pages useful beyond the answer already visible in search.

    Key takeaways

    • Estimated organic traffic across 40,000 of the largest U.S. sites declined 2.5% year over year, which indicates contraction rather than the disappearance of search.
    • AI Overviews appeared on roughly 30% of measured results pages and were associated with a 35% reduction in organic click-through rate when present, with informational queries carrying more exposure.
    • Do not treat every traffic loss as an AI problem. Separate lost rankings, lower impressions, weaker click-through rates, analytics discrepancies, and changes in query mix.
    • Keep the direct answer easy to extract, then give the reader decision criteria, evidence, tools, comparisons, or a next step worth clicking for.
    • Measure conversions and other business outcomes alongside clicks. Losing low-value informational visits is different from losing high-intent demand.

    Treat the market data as context, not your diagnosis

    Organic search traffic across 40,000 of the largest U.S. websites fell an estimated 2.5% year over year. The measurement used Similarweb visit data covering February through December 2024 and January through November 2025. Over the 2025 period, total search-engine traffic increased 0.4%, while Google traffic increased 0.8%.

    That is not evidence of an industry-wide collapse. It is evidence of a modest aggregate decline in organic visits while search activity, considered more broadly, remained approximately stable. The distinction matters because “search is dying” leads teams to abandon a channel, while “some searches produce fewer clicks” leads them to diagnose where the economics have changed.

    The aggregate also hides a sharp distribution by site size. The ten largest sites gained 1.6% in organic traffic, while sites ranked between the top 100 and top 10,000 experienced more noticeable declines. A stable market can therefore coexist with a painful loss for a mid-sized publisher. Scale, brand demand, topic mix, and exposure to particular result-page features can produce very different outcomes.

    The numbers are estimates, not a census of every search or a forecast for your domain. Similarweb combines opt-in panels, ISP and mobile-carrier information, public web signals, and direct site measurements. Comparisons against first-party Google Search Console and Google Analytics data produced a median correlation of 0.86 across the sites checked. That supports using the data for market direction, but it does not make 2.5% an acceptable loss, a benchmark, or an expected result for your site.

    Your own page and query data must decide what you do next. If your organic decline is materially larger than the market movement, do not explain the gap with a broad AI narrative. Find the pages, intents, devices, countries, and result-page conditions that account for it.

    Separate ranking loss from AI-related click compression

    Two parallel search journeys show one webpage tile dropping down a stack while another remains prominent but receives fewer glowing particles.

    AI Overviews create a real click-through problem, but not a uniform one. They appeared on roughly 30% of measured search results, predominantly for informational queries. When an AI Overview was present, organic click-through rate was 35% lower. Commercial and transactional searches were notably less affected.

    Do not multiply those two percentages and treat the result as your expected traffic loss. AI Overviews are not distributed randomly across queries. A reference publisher answering many definitions and how-to questions can have much greater exposure than a business whose visibility comes mostly from product, service, comparison, branded, or purchase-oriented searches.

    Build a diagnostic sheet with a row for each important page-query combination. Include the landing page, query, primary intent, current and comparison-period impressions, clicks, click-through rate, average position, AI Overview presence, other prominent search features, and the business outcome associated with the visit. This keeps a site-wide average from hiding the mechanism behind the loss.

    1. Export matching periods from Google Search Console. Use a year-over-year comparison when seasonality affects demand, and segment by page, query, device, and country before drawing conclusions.
    2. Assign each material query a primary intent: informational, commercial or comparison, transactional, branded, or navigational. Imperfect classification is still more useful than treating every click as equivalent.
    3. Compare impressions, position, and click-through rate together. A click decline means little until you know which of those inputs changed.
    4. Inspect the live result pages for representative queries. Record whether an AI Overview is present, what it answers, which pages it cites, where your result appears, and which other features compete for attention. Note the date, location, and device because result layouts can vary.
    5. Connect affected landing pages to conversions, qualified leads, revenue, subscriptions, or the outcome your site is designed to produce. This establishes whether you lost business demand or visits that rarely moved beyond the initial answer.
    Pattern in your dataWhat it may indicateWhat to check next
    Impressions and position are stable, but click-through rate fallsThe result page may be absorbing more clicks through an AI Overview or another featureInspect the affected queries and compare the answer visible in search with the additional value on your page
    Average position falls on the same page-query combinationsA ranking problem, not merely click compressionCheck relevance, content quality, internal linking, indexability, technical changes, and competing results
    Impressions fall while positions remain broadly stableLower demand, a changed query mix, or reduced eligibility across related searchesCompare individual queries and countries rather than relying on the site-wide impression total
    Search Console clicks remain stable while analytics sessions fallA measurement or channel-classification discrepancyCheck landing-page tracking, consent behavior, channel rules, and the date of analytics changes
    Clicks fall but conversions remain stableThe lost traffic may have carried relatively little business valueIdentify which intents disappeared before spending resources to restore the volume
    High-intent clicks and conversions fall togetherA direct demand-capture problemPrioritize the affected commercial pages and queries over broad informational traffic recovery

    Average position deserves particular care. It can change because your query mix changed, even when the rankings for your most important queries did not. Make decisions from stable page-query segments wherever possible, not from one domain-level average.

    Build pages for the part of the task search cannot finish

    A person's hands use comparison pieces, controls, and modular tools at a workbench to turn a simple information card into a completed solution.

    A simple informational query may no longer require a visit when the result page supplies a sufficient answer. Making your content vague will not recover that click. It will make the page less useful to readers and less understandable to the systems evaluating it.

    Keep the immediate answer concise, accurate, and easy to extract. Then design the page around the decision or action that follows. The search result can state a fact; your page should help the reader apply it under real constraints.

    1. Answer the primary question near the start. State the conclusion, the conditions under which it holds, and any limitation that would materially change the answer.
    2. Add continuation value. Useful options include decision criteria, trade-offs, a worked process, comparisons based on explicit factors, calculation inputs, downloadable templates, or original observations with a transparent methodology.
    3. Show the next relevant question. Link an informational page to a comparison, implementation, service, product, or evaluation page only when that destination is the natural next step for the same reader.
    4. Strengthen higher-intent pages. Because commercial and transactional searches have been less affected by AI Overviews, pages supporting evaluation and action deserve focused attention. Make compatibility, constraints, process, evidence, and the next step explicit.
    5. Use structured data to describe what the page genuinely contains. Choose a schema type that matches the primary entity, keep JSON-LD consistent with visible content, and do not mark up claims or attributes a reader cannot verify on the page. Schema can improve machine interpretation; it cannot guarantee a ranking, citation, or click.
    6. Match the edit to the diagnosed loss. If rankings fell, address the ranking problem. If rankings held while click-through rate fell, improve the page’s distinctive value and its path to a meaningful next action. Rewriting everything as an “AI optimization” project obscures that difference.

    For informational content, ask one hard question during the audit: after a searcher has read the short answer, what legitimate reason remains to visit? “More words” is not a reason. A defensible recommendation, a transparent comparison, a tool, a reusable workflow, or evidence that changes the decision can be.

    Do not mass-delete or redirect pages because the domain total declined. Redirecting changes which URL can rank and can be difficult to unwind cleanly. Export the page-query history, record the current target, and consolidate only when multiple pages genuinely serve the same intent and one clear destination can satisfy it. A market trend is not enough evidence to erase a page’s accumulated search value.

    Measure business contribution, not traffic volume alone

    Organic search still accounts for approximately 90% of the measured clicks between organic results and ads, compared with about 10% for advertising. The ad share increased by roughly two percentage points, but that modest shift does not support the claim that paid listings have broadly replaced organic opportunity.

    That does not mean every organic click retains its former value. It means you should avoid abandoning SEO or reallocating budget based on a general story about AI or ads. Make the decision from a scorecard that separates visibility, traffic, and business contribution.

    • Search capture: impressions, clicks, click-through rate, and position, segmented by page, query intent, device, country, and observed result-page features.
    • Business contribution: conversions, qualified leads, revenue, subscriptions, assisted outcomes, and conversion rate by organic landing page where your measurement supports them.
    • AI discovery: referral visits from identifiable AI assistants, observed mentions or citations for priority questions, and the landing pages receiving that exposure. Keep these separate from organic search so channel changes remain visible.
    • Content action: whether each declining page needs ranking remediation, stronger continuation value, consolidation, a better internal path, or no action because the lost visits did not support a meaningful outcome.

    Use explicit decision rules. A high-intent page losing rankings and conversions belongs near the top of the backlog. A stable-ranking page losing informational clicks to an AI Overview needs deeper decision support and a stronger route to the next task. A page losing clicks while retaining its conversions may not need traffic restored at any cost. If clicks remain stable but outcomes fall, investigate the offer, page experience, tracking, or audience fit before blaming search.

    AI exposure may contribute to later branded searches or direct visits, but ordinary analytics cannot prove that relationship from timing alone. Monitor branded-query demand and direct traffic if the possibility matters to you, then label the finding as directional unless you have a reliable attribution method.

    Start with the page-query combinations responsible for your largest high-intent loss. If position fell, fix the SEO problem. If position held and click-through rate fell where an AI Overview appears, preserve the direct answer while adding value that helps the reader decide or act. Recheck the same segment after new data accumulates. That turns a vague fear about AI into a measurable work queue.

    References

  • Unveiling Google’s New AI Overviews with Gemini 3 Pro

    Unveiling Google’s New AI Overviews with Gemini 3 Pro

    Recently, I’ve noticed that Google has started using Gemini 3 Pro to create AI Overviews on their search platform. This change primarily enhances the handling of more complex search queries.

    Back in November, Google announced this improvement for AI Mode results. Then, in December, they began implementing Gemini 3 Flash for AI Mode. Now, it’s exciting to see Google integrating Gemini 3 Pro for generating AI Overviews.

    Gemini 3 Pro is now crafting AI Overviews for complicated queries in English, accessible globally to all Google AI Pro & Ultra subscribers.

    What Google Shared with Us. Robby Stein, VP of Product at Google Search, expressed this in his recent update:

    • “Update: AI Overviews now tap into Gemini 3 Pro for complex topics.”
    • “Behind the scenes, Search will intelligently route your toughest Qs to our frontier model (just like we do in AI Mode) while continuing to use faster models for simpler tasks.”
    • “Live in English globally for Google AI Pro & Ultra subs.”

    Why It Matters to Me. The AI Overviews you see might look quite different than they did recently. Google’s consistent efforts to refine its Gemini models signify ongoing improvements in their AI technologies within Google Search, which includes both AI Overviews and AI Mode.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • YouTube in Google AI Health Answers: A Publisher Playbook

    YouTube in Google AI Health Answers: A Publisher Playbook

    If you publish health information, YouTube’s lead among domains cited in Google AI health answers can trigger the wrong response: produce more videos, copy the format already being cited, and assume visibility will follow. That conclusion goes beyond the evidence and creates real risk when the subject is treatment, cancer diets, laboratory results, or another decision that could affect someone’s care.

    A better response is to make every important health claim inspectable. You need to know what the AI answer says, whether its citation supports that exact wording, which qualifiers survived summarization, and whether your own video and page tell the same medically reviewed story. Here is a practical way to do that without treating YouTube as either a shortcut to AI visibility or an inherently unreliable format.

    Read the YouTube number without drawing the wrong conclusion

    Across 50,807 health-related searches in Germany, AI Overviews appeared for more than 82% of the inquiries examined. That level of coverage matters because an AI-generated summary can become the first layer of health information a searcher sees, before any hospital page, journal, association, or video is opened.

    YouTube accounted for 4.43% of all citations and was the most-cited individual domain. The percentage and the ranking need to be read together. YouTube led a fragmented field; it did not supply most health citations. A 4.43% citation share is evidence of meaningful visibility, not evidence that Google prefers every video over every medical page.

    The credibility mix is more consequential. Only 34.45% of citations came from sources classified as more reliable medical sources, while nearly two-thirds were classified as lacking strong medical or evidence-based credibility. Academic journals and government health organizations together represented only about 1% of citations. Those classifications do not prove that every citation outside the medical group was wrong, but they expose a large verification problem.

    AI citations also followed a different pattern from conventional rankings. YouTube placed first by AI citation frequency but only 11th in organic results, and just 36% of pages cited by AI appeared in Google’s organic top 10. You therefore cannot use top-10 rankings as a complete proxy for AI visibility. You also cannot assume that an AI citation proves a page or video is the strongest medical result.

    These figures are observational. They do not reveal a YouTube ranking factor, prove why a particular citation was selected, or establish a permanent worldwide pattern beyond the German query set examined. Google has also disputed whether selected examples of risky advice were fairly represented in context and maintains that AI Overviews generally link to trustworthy material. For publishers, that disagreement makes context checking more important, not less.

    Key takeaways

    • YouTube was the leading cited domain, but its 4.43% share does not mean video supplied most health information.
    • AI citation visibility and top-10 organic visibility are related measures, not interchangeable ones.
    • A platform is a container, not a medical credibility signal. Evaluate the speaker, evidence, wording, scope, and review process.
    • Your goal should be a claim that remains accurate when extracted, summarized, and separated from the rest of the page or video.

    Audit the health claim, not just the cited domain

    A magnifying glass examines an abstract claim across layered video, research paper, and AI response materials on a clinical review desk.

    A domain-level report can tell you where citations concentrate. It cannot tell you whether a specific AI sentence is supported. That requires a claim-level audit. Use the following process for queries tied to diagnosis, treatment, medication, diet during a serious illness, test interpretation, or another decision with a meaningful health consequence.

    1. Capture the complete answer. Record the exact query, wording of the AI Overview, locale, capture date, every citation, and the sentence or passage attached to each citation. Do not save only the part that mentions your brand.
    2. Break the answer into individual claims. Separate definitions, causal statements, recommendations, thresholds, and statements about who is affected. One paragraph may contain several claims even when Google attaches only one citation.
    3. Map every claim to its alleged support. Ask whether the cited destination supports the exact statement, merely discusses the same topic, or contradicts the summary once its qualifications are restored.
    4. Inspect the video beyond its title. Identify the speaker, relevant credentials, publisher, publication or review date, transcript, references, and the surrounding segment. A title or short extracted passage can sound more certain than the full explanation.
    5. Check the missing qualifiers. Look for the population, condition, stage, exclusions, uncertainty, and boundary between general education and individualized advice. A summary can preserve the main clause while dropping the words that made it safe.
    6. Compare AI and organic visibility separately. Record whether the cited URL appears in the top 10, but do not automatically reject it when it does not. With only 36% overlap in the examined results, organic position is useful context rather than a verdict on the AI citation.
    7. Assign a risk owner. SEO can document the extraction problem, but a qualified medical reviewer should decide whether a consequential health claim is clinically supportable. Keep that approval attached to the exact claim and version reviewed.

    A simple red, amber, and green workflow helps you decide what to fix first:

    • Red: The answer could prompt someone to start or stop treatment, alter a medically significant diet, treat a laboratory result as a diagnosis, or delay professional care, and the citation does not clearly support the action. Escalate it for medical review and do not amplify the claim while that review is unresolved.
    • Amber: The central point may be supportable, but the AI answer loses a population, limitation, uncertainty, or other qualifier. Rewrite the source material so the qualifier travels with the claim rather than appearing several sentences later.
    • Green: The claim is narrow, educational, supported by the destination, and represented with its material context intact. Continue monitoring it because the wording or citation set can change.

    These colors are editorial priority labels, not clinical validity scores. If you are personally deciding whether to change a treatment, cancer-related diet, or interpretation of a liver blood test, an AI Overview and its cited video are not substitutes for a qualified clinician who knows your situation.

    Build a claim package that remains credible outside YouTube

    The useful unit of health publishing is not the video, page, or schema record. It is the claim package: a bounded answer, the evidence supporting it, the person accountable for reviewing it, the people to whom it applies, and the caveats required to keep it accurate. Video can carry that package well, but only if its authority survives outside the platform.

    Make the spoken answer safe to extract

    • State the question and answer in the narration. Do not leave the key qualification only in the description, a pinned comment, or an end card.
    • Keep the caveat beside the claim. If a recommendation applies only to a defined group or depends on professional assessment, say that in the same spoken passage. Distance makes it easier for summarization to separate the claim from its boundary.
    • Identify who is speaking and reviewing. Give relevant, verifiable credentials and distinguish the presenter from the medical reviewer when they are different people.
    • Separate education from individualized direction. Explain what a term, test, or treatment generally means without implying that the viewer has a diagnosis or should change care based on the video alone.
    • Expose the evidence trail. Put supporting references in the description and make clear which reference supports which major claim. A generic reading list is harder to audit.
    • Correct the transcript and captions. Names of conditions, tests, treatments, and qualifications are precisely where automated transcription errors can distort meaning. The transcript should match the reviewed spoken version.
    • Review clips as independent objects. A short clip may circulate without the full video’s introduction or disclaimer. It must retain any qualifier necessary to prevent the excerpt from becoming misleading.

    Give the video a companion page with the same accountable answer

    The companion page should not be a thin transcript built only to host an embed. It should let a reader verify the claim without watching the video and let an editor detect when the page and video have drifted apart.

    • Place the reviewed answer and its material limitation in the same section as the embedded video.
    • Show who wrote, presented, and medically reviewed the material. Do not collapse those roles into one vague byline.
    • Display the review date and update both assets when a substantive claim changes. A fresh page date attached to an unchanged old video creates false alignment.
    • Attach evidence to the claim it supports. Avoid sending readers through a long references list to guess which item belongs to which statement.
    • Use headings that reflect real questions, then answer each question directly before expanding on it. This improves clarity even when no AI system cites the page.
    • Check that the video’s title, thumbnail, description, transcript, page summary, and structured data all describe the same scope. A broad title paired with a heavily qualified answer invites misinterpretation.

    JSON-LD can clarify the visible video’s title, creator, publication details, and relationship to the page. It cannot turn an unsupported claim into medical evidence. Keep every structured value consistent with what a user can see, and never mark up credentials, reviewers, dates, or medical relationships that the page does not truthfully establish.

    Measure AI citations without manufacturing a success story

    A researcher reviews abstract citation nodes on a monitoring board beside a balance scale holding verified and uncertain evidence tokens.

    A citation dashboard becomes misleading when several different denominators are labeled citation rate. Define each metric before you compare a page, video, competitor, or reporting period.

    MetricCalculationWhat it tells you
    AI Overview coverageQueries showing an AI Overview divided by all queries checkedHow often the feature appears for your tracked query set
    Owned citation presenceQueries citing one of your assets divided by queries showing an AI OverviewHow often your content enters an available AI answer
    Owned citation shareYour citation appearances divided by all citation appearances capturedYour portion of the citation pool under the same counting method
    Video citation mixCited videos divided by all cited assets in your datasetWhether video is over- or underrepresented in your own topic set
    Context fidelityOwned citations represented accurately divided by all owned citation appearances reviewedWhether visibility preserves the meaning and limitations of your content
    Organic overlapAI-cited URLs also appearing in the organic top 10 divided by all AI-cited URLsHow much AI sourcing overlaps with conventional ranking visibility

    The reported 4.43% YouTube figure used all citations as its denominator. Do not compare it with the percentage of queries containing a YouTube link or the percentage of cited domains that are video platforms; those answer different questions. Preserve citation appearances, unique URLs, unique domains, and queries as separate counts.

    Track the same query set and locale with a consistent capture method. Record the page and video independently, even when they belong to one claim package. When visibility changes after an update, treat the result as an observation rather than proof that a transcript edit, schema field, embed, or review note caused the change.

    Most importantly, do not count every citation as a win. An AI answer that cites your asset while stripping away a crucial limitation can create more reputational and health risk than no citation at all. Context fidelity belongs beside visibility in every report sent to editorial, medical, legal, or leadership teams.

    Choose the next publishing move by consequence, not format

    You do not need to convert your entire health library into video. Start with a bounded set of ten queries where a misleading answer could affect treatment, diet during a serious illness, test interpretation, or a decision to seek professional care. That set is small enough for claim-level review and important enough to reveal whether your current process protects users.

    1. Capture each AI Overview, its citations, and the corresponding organic top 10.
    2. Split every answer into claims and apply the red, amber, or green editorial label.
    3. Select the highest-consequence unsupported or decontextualized claim, regardless of whether its current citation is a video or page.
    4. Create or revise one medically reviewed claim package: spoken answer, transcript, companion page, evidence mapping, reviewer ownership, and accurate structured data.
    5. Recheck the same query set after publication, keeping the denominator and locale unchanged.
    6. If the asset gains a citation, verify the summarized wording before reporting success. If it does not, keep the improved content; the safety and clarity gains still matter to every person who reaches it directly.

    YouTube’s citation lead is a reason to inspect video more carefully, not a reason to imitate it blindly. Make your next health answer narrow enough to verify, complete enough to survive extraction, and accountable to a qualified reviewer. Then measure whether Google cites the right claim in the right context.

    References

  • AdSense Revenue Declines: How to Diagnose the Real Cause

    AdSense Revenue Declines: How to Diagnose the Real Cause

    Your AdSense revenue has fallen sharply, but your traffic looks normal. The expensive mistake is to assume that SEO is responsible and immediately change your content, schema, ad layout, or site architecture. Those changes can erase the evidence you need and introduce a second problem.

    You can usually narrow the cause by comparing pageviews, ad impressions, page RPM, and eCPM across the same sites, countries, devices, and ad units. The goal is not to explain every dollar immediately. It is to identify whether traffic, ad delivery, advertiser demand, or reporting broke first.

    First, identify which number actually broke

    An icon-based diagnostic pathway separates website activity, ad delivery, advertiser demand, and reporting problems across devices and regions.

    Revenue is the result, not the diagnosis. Page RPM tells you how much revenue you earned per thousand pageviews. eCPM tells you how much revenue was generated per thousand ad impressions. A fall in either metric matters, but the surrounding numbers tell you where to look.

    Start with equivalent, complete reporting periods. Do not compare a partial day with a completed day. Then examine the metrics in this order:

    1. Independent traffic: Check pageviews or sessions outside AdSense. This establishes whether fewer people actually reached the site.
    2. Ad impressions: Compare the change in ad impressions with the change in pageviews. A much larger impression decline points toward serving, rendering, consent, or placement problems.
    3. Page RPM: If traffic is stable but page RPM collapses, the problem is monetization rather than the number of visits alone.
    4. eCPM: If ad impressions remain comparatively stable while eCPM falls, weaker auction pricing or a change in traffic mix becomes more plausible.
    5. Rendered ads: Open representative pages and confirm whether the expected ad slots appear. Missing ads are operational evidence, not merely a dashboard fluctuation.

    This distinction mattered during a severe episode that began late on January 14 and intensified on January 15. Publishers reported eCPM and page RPM declines of up to 70%, simultaneous effects across multiple sites, and ads partially or completely disappearing. Google also acknowledged systemic Google Ad Manager problems involving declining AdX match rates and reduced delivery from Google Ads and DV360, with web and mobile web display inventory particularly affected.

    That acknowledgement is important, but it does not prove that the Ad Manager incident explained every AdSense account’s decline. Your own metric sequence still matters. A platform incident can coexist with a traffic loss, a local implementation fault, or a reporting anomaly.

    Pattern you seeMost plausible problem areaWhat to check next
    Traffic and ad impressions fall together while page RPM is comparatively stableAudience acquisition or search visibilityAnalytics, server logs, landing pages, and Search Console performance
    Traffic is stable but ad impressions fall or ads disappearAd serving, rendering, consent, policy, or implementationLive pages, affected templates, ad code, consent states, policy notices, and recent deployments
    Traffic and ad impressions are stable but eCPM fallsAuction demand, match rate, or traffic-mix changeCountry, device, site, and ad-unit segments
    Revenue changes without corresponding movement in the underlying metricsReporting delay or anomalyPlatform notices and whether reported figures are subsequently revised
    Traffic, impressions, and RPM all fallMore than one problem may be presentDiagnose the traffic and monetization changes separately

    Use the blast radius to separate local faults from platform failures

    The first useful question is not simply, “How much revenue did we lose?” Ask, “Where did the decline begin, and where did it not happen?” A single account-wide average can hide the answer.

    1. Split by site. If unrelated sites in the same account decline at the same time, a shared platform or demand problem becomes more plausible. If only one site changes, inspect that site’s deployments, templates, audience, and policy status.
    2. Split by country. Advertising demand and delivery can move differently by market. A global average may therefore make a regional problem look universal.
    3. Split by device. A mobile-only decline points toward different templates, consent behavior, viewport rendering, or mobile-web delivery.
    4. Split by ad unit or placement. A failure concentrated in one unit is a different problem from an account-wide eCPM decline.
    5. Compare the onset time. Metrics that change together are more likely to share a cause. Changes beginning at different times should be treated as separate events until the data connects them.

    Regional differences during the January episode show why this segmentation matters. Self-reported losses for U.S.-focused sites ranged from 35% to 70%, while selected European country domains reported declines ranging from 63% to 90%. These were publisher reports, not official performance benchmarks, so they should not be used to predict your expected loss. They do demonstrate that a single blended percentage can conceal materially different market behavior.

    Blast-radius analysis produces probabilities, not certainty. Several sites failing simultaneously makes a shared dependency more plausible, but it does not rule out a common change made across those sites. Check shared consent management, ad code, deployment pipelines, CDN rules, and account settings before concluding that the platform is solely responsible.

    Do not confuse monetization failure with an SEO or AI-search loss

    A search ranking change reduces revenue by reducing or changing visits. It does not directly explain why the same pageviews suddenly produce far fewer ad impressions or why previously visible ad slots stop rendering.

    An unconfirmed Google Search ranking update coincided with the reported AdSense decline. That timing creates a reasonable hypothesis, but timing alone is not causation. Test it with independent traffic data:

    • If Search Console clicks and analytics traffic decline while page RPM remains stable, investigate search visibility and landing-page losses.
    • If traffic remains stable while page RPM or ad impressions collapse, prioritize monetization and serving diagnostics.
    • If traffic and page RPM decline together, maintain two incident tracks. Fixing or explaining one does not automatically explain the other.
    • If organic traffic volume is stable but eCPM changes by country or device, examine audience mix before blaming rankings.

    AI Overviews were also raised as a possible indirect factor because those search-result experiences displayed no ads during the period being discussed. However, no causal connection was established between AI Overviews and the sudden publisher revenue collapse. Treat AI-search displacement as a longer-term distribution question unless your referral and landing-page data show that it caused the traffic change in front of you.

    The same discipline applies to AEO, GEO, and structured data. Schema can help machines interpret content, and answer-focused optimization may improve discoverability, but neither can repair a falling AdX match rate or restore an ad slot that is not being served. Measure AI visibility, AI referrals, organic clicks, ad delivery, and revenue as separate layers. Connect them only when the data supports the connection.

    Respond without destroying the evidence

    An analyst documents untouched website analytics under a transparent cover while modification tools remain set aside.

    Broad changes made during an unexplained incident create confounding variables. If you alter ad density, templates, consent logic, content, and internal links at once, you will not know whether the original problem recovered or your intervention changed the result.

    1. Record the onset. Note when the decline first appears and which account, site, country, device, and ad-unit views show it.
    2. Preserve the baseline. Export or capture the relevant pageview, ad-impression, page RPM, eCPM, and revenue reports before dashboard values or date ranges change.
    3. Verify traffic independently. Use analytics, server logs, and Search Console rather than relying on an AdSense pageview metric alone.
    4. Test representative pages. Check more than the homepage. Include major templates, mobile and desktop layouts, important countries you can validly test, and the consent states your site supports.
    5. Review shared dependencies. Inspect policy notices, consent-management changes, ads.txt changes, ad-code changes, recent releases, caching, CDN behavior, and security rules that could prevent requests or rendering.
    6. Check platform communications. Match any acknowledged incident to your affected product, inventory type, geography, and onset time. A status notice is evidence only when its scope fits your metrics.
    7. Change one layer at a time. If the evidence identifies a local fault, make the smallest relevant correction and annotate it. Keep SEO and content changes out of an ad-serving test.

    Communicate the same distinction internally. “Revenue is down” is not an operational diagnosis. A useful incident note says, for example, that traffic is stable, mobile-web ad impressions fell across several sites, and no site deployment preceded the change. That statement tells technical, editorial, and financial teams what is known without pretending the cause is settled.

    If the decline affects payroll, debt, tax payments, or another consequential financial decision, work from confirmed cash and account data rather than an assumed recovery. An accountant or financial adviser should review any irreversible response to a temporary or disputed dashboard event.

    Plan for a decline that does not fully recover

    An overnight incident and a structural revenue decline require different responses. The first calls for controlled diagnosis. The second calls for a business-model decision.

    Some publishers reported losses of 70% to 80% extending back to mid-2025. Those reports do not prove that traditional content sites are being systematically deprioritized, and they should not be treated as a forecast for every publisher. They do show why waiting for a dashboard to return to an old high can become a strategy of its own.

    If your decline persists after serving and reporting issues are excluded, build the plan from your observed economics:

    • Chart RPM by segment, not just account. Identify which sites, countries, devices, templates, and topics still produce sustainable returns.
    • Map concentration risk. Record how much of the site’s operation depends on one ad platform, one search channel, or one high-value audience segment.
    • Use a conservative operating case. Budget from revenue you can verify, not from an assumption that a previous RPM will return.
    • Evaluate adjacent revenue models against audience intent. Sponsorships, subscriptions, services, commerce, or affiliate revenue are useful only when they fit why the audience visits. Adding an unrelated monetization layer can damage trust without replacing the lost income.
    • Build direct audience access. Email subscriptions, repeat visits, and recognizable brand demand reduce dependence on any single discovery interface, including traditional search and AI-generated answers.
    • Track AI discovery separately. Measure citations, referral traffic, branded searches, conversions, and revenue where possible. AI visibility is not a business outcome until you can connect it to audience or commercial value.

    Key takeaways

    • Stable traffic with falling ad impressions points toward serving or rendering before it points toward SEO.
    • Stable impressions with falling eCPM makes auction demand or audience mix more plausible.
    • Simultaneous declines across unrelated sites suggest a shared dependency, but they do not prove a platform-wide cause.
    • A coincident search update or AI feature is a hypothesis until traffic and landing-page data connect it to the loss.
    • Preserve reports and change one layer at a time so that recovery remains measurable.
    • A persistent decline needs a lower-risk revenue plan, not indefinite dependence on a rebound.

    Your next move is to export the affected metrics and write a one-sentence diagnosis that the numbers support. If you cannot yet say whether traffic, impressions, or eCPM broke first, do not redesign the site. Find that missing comparison. Once the failure is classified, you can act on the correct system instead of spending an ad-delivery incident on an SEO fix.

    References

  • How to Protect Brand Visibility in Google AI Search

    How to Protect Brand Visibility in Google AI Search

    You search your brand in Google and the AI-generated answer sounds confident, polished, and wrong. An old complaint has become a present-tense fact. A forum opinion outweighs your published policy. Or your brand is visible, but the answer frames it in a way no conventional ranking report would reveal.

    You cannot solve that problem by publishing more generic brand content. You need to identify the exact claim Google is repeating, trace the information environment behind it, correct the weakest evidence, and make the current facts easier to retrieve and interpret. This gives you a practical way to do that.

    Separate visibility from accurate representation

    A brightly lit geometric object appears distorted in one mirror and accurately reflected in another.

    A high organic ranking tells you that a page can be found. It does not tell you whether Google will use that page in an AI answer, whether the answer will cite it, or whether the resulting description will represent your brand accurately.

    That distinction matters because Google AI Overviews can draw information from conversational platforms such as Reddit and Quora. In some cases, old or inaccurate discussions can be resurfaced without enough context. An anecdote may then sit beside an official statement without a clear distinction between personal experience, verified fact, and current policy.

    This creates three separate jobs for your team:

    JobQuestion it answersWhat to inspect
    DiscoverabilityCan Google find and understand your material?Indexable pages, internal links, crawl access, page purpose, and entity naming
    InclusionDoes your material influence the AI answer?Citations, linked pages, quoted facts, and competing domains
    RepresentationIs the answer accurate, current, and properly qualified?Individual claims, dates, scope, omitted context, and opinion presented as fact

    Do not combine these into one visibility score. A brand can rank well but be represented poorly. It can also be described accurately without receiving a citation. Each condition requires a different response.

    Key takeaways

    • Audit what Google says about your brand, not only where your pages rank.
    • Break an AI answer into individual claims before deciding how to respond.
    • Correct factual errors at the pages and platforms that support them; publishing an unrelated positive story will not repair the evidence chain.
    • Make official facts explicit, dated, scoped, and consistent across visible copy and structured data.
    • Treat legitimate criticism differently from false or outdated claims. Reputation management should improve accuracy, not erase disagreement.

    Audit the questions that can change a decision

    Searching only your brand name produces an incomplete audit. People encounter reputation problems through questions about trust, policies, products, comparisons, and specific incidents. Build your query set around those decisions.

    Start with query families such as:

    • Identity: what is the brand, who owns it, where does it operate, and which similarly named entity is it?
    • Trust: is the brand legitimate, reliable, safe, or suitable for a particular use?
    • Customer experience: what problems do customers report, and how does support handle them?
    • Policies: what are the refund, cancellation, warranty, privacy, or eligibility terms?
    • Products and services: what does an offering include, exclude, cost, or require?
    • Comparisons: how does the brand differ from a named alternative, and what tradeoffs matter?
    • Events: what happened during a controversy, outage, recall, policy change, or other decision-relevant development?

    Add the language customers actually use. Support tickets, sales objections, review themes, branded search terms, and community discussions can expose questions that your marketing navigation does not. The goal is not to generate every conceivable prompt. It is to cover the questions where a wrong answer could change trust or action.

    For each query, use the following workflow:

    1. Save the query exactly as entered. Small wording changes can turn a factual lookup into a request for opinions.
    2. Capture the complete AI answer, its visible citations, linked pages, and any language expressing uncertainty.
    3. Record the date, location context, account state, device context, and other setup details needed to repeat the check.
    4. Split the answer into atomic claims. A statement about poor support, for example, might contain separate claims about response availability, refund handling, complaint volume, and current policy.
    5. Label each claim as accurate, incomplete, outdated, unsupported, subjective, or attached to the wrong entity.
    6. Map the page or discussion that appears to support each problematic claim. If no visible citation supports it, record that rather than guessing.
    7. Assign a correction owner and a verification step. Ownership may sit with content, SEO, public relations, customer support, product, or legal review depending on the claim.

    Prioritize consequence before sentiment. A mildly negative opinion is usually less urgent than a false statement about eligibility, pricing, safety, availability, contractual terms, or the identity of the company. An error that could cause a customer to take the wrong action should move ahead of a complaint that is unpleasant but clearly framed as opinion.

    Also check whether the claim is reproducible. One captured answer is evidence of an occurrence, not proof that every searcher sees the same thing. Use a documented setup and repeat the important query variants before estimating the size of the problem.

    Repair the evidence chain, not just your homepage

    Blank source documents and archive objects connect to a clear sphere through an evidence chain with one broken link being repaired.

    When a misleading answer cites a community thread, rewriting your homepage may have little effect on that specific claim. The correction needs to reach the part of the information environment that is unclear, stale, or unsupported.

    Choose the response according to the type of problem:

    • Factual error: publish the correct fact on the most relevant official page and provide the primary evidence that supports it. If a third-party page contains the error, send its owner the exact sentence, correction, evidence URL, and applicable date.
    • Outdated fact: state what changed, when the current position took effect, which products or regions it covers, and whether the old condition still applies anywhere.
    • Missing qualification: add the condition that changes the meaning. A policy may depend on product type, purchase channel, location, account status, or another clearly defined circumstance.
    • Identity collision: use the full entity name, location, legal or trading relationship, and distinguishing details consistently. Create an explicit clarification page if people regularly confuse separate organizations.
    • Legitimate complaint: acknowledge the underlying experience and explain the current resolution path. Do not relabel a genuine customer opinion as misinformation merely because it is unfavorable.
    • Unsupported generalization: answer with bounded language and checkable facts. A handful of complaints does not establish a universal condition, but a vague assurance that customers are happy does not rebut it either.
    • Operational failure: fix the underlying process. Content cannot permanently compensate for a policy or customer experience that continues to generate the same criticism.

    A useful correction packet is short and specific. It should contain the disputed claim, the corrected wording, the evidence, the effective date, the affected product or market, and a contact who can answer verification questions. This format gives editors, community moderators, partners, and internal teams something they can act on without reconstructing the issue themselves.

    When you respond in a forum, write for the later reader as much as the current participant. Identify your relationship to the brand, answer the factual point directly, link to the relevant evidence, and stop once the correction is clear. Arguing through every comment can make the factual answer harder to find. Fabricated endorsements and undisclosed brand advocacy are not correction strategies.

    Do not create a public rebuttal page for every fringe remark. Repeating an obscure accusation on an authoritative brand domain may give it a clearer association with your entity. A dedicated response becomes more reasonable when the claim is already discoverable, affects a real decision, and requires context that cannot fit on an existing policy, product, or company page.

    Publish facts that machines cannot easily misread

    AI-readable content is not content written in a robotic style. It is content in which the subject, claim, scope, date, and evidence are difficult to confuse.

    For every brand fact that affects a decision, inspect the page that is supposed to establish it:

    • Answer the central question near the beginning. Do not bury the current policy below a long brand narrative.
    • Name the entity and offering explicitly. Pronouns and internal product nicknames can create ambiguity when a passage is read outside the page.
    • State scope beside the claim. If a term applies only to a region, plan, product version, or purchase channel, put that condition in the same passage.
    • Show the effective or reviewed date where freshness changes the meaning. A generic site copyright date does not establish when a policy was checked.
    • Explain exceptions in plain language. A clean headline followed by contradictory fine print is easy for people and machines to misinterpret.
    • Link related facts to a stable, canonical destination. Conflicting policy summaries across help pages, campaign pages, PDFs, and partner sites create avoidable uncertainty.
    • Identify editorial or organizational ownership. Readers should be able to tell who maintains the information and how to report an error.
    • Keep critical facts in accessible HTML rather than only inside images, video, or downloadable material.

    Structured data can reinforce this clarity, but it cannot certify a claim or suppress criticism. Use JSON-LD that matches the visible page. Choose a schema type that describes the actual entity or content, connect consistent identifiers, and include only properties you can support on the page. Organization markup can clarify organization-level identity; product markup belongs with an actual product; FAQ markup should reflect questions and answers people can see. Markup that contradicts the page creates another inconsistency rather than an authority signal.

    Technical health belongs in the same operating program but a different diagnostic lane. Crawl restrictions, broken internal links, inaccessible content, accidental duplication, and unstable pages can obstruct your official information. Core Web Vitals and AI visibility also deserve careful separation: improving page experience may strengthen the site, but it does not correct an external factual error by itself. If the AI answer repeats a stale forum claim, a performance score is not the evidence repair.

    Review consistency outside your site as well. Business profiles, social biographies, distributor pages, app listings, support portals, press materials, and executive profiles should not disagree on basic identity or policy facts. You do not need identical prose everywhere. You do need compatible facts, dates, names, and relationships.

    Build a reputation workflow that survives the next answer

    A one-time cleanup will not catch narrative drift. Products change, policies change, complaints accumulate, and old discussions remain available. Monitoring should therefore be tied to both a recurring review and events that alter what searchers need to know.

    Recheck priority queries after a product launch, policy revision, naming change, service disruption, public controversy, major correction, or update to a page that previously supported the wrong answer. Keep the original captures so you can distinguish a genuine change from a difference in wording.

    Your scorecard should track more than whether the brand appears:

    • Presence: does an AI-generated answer appear for the query?
    • Accuracy: which atomic claims are correct, incomplete, unsupported, outdated, or misattributed?
    • Source mix: do the visible links include official material, independent reporting, community discussion, or pages unrelated to the correct entity?
    • Freshness: do the answer and supporting pages reflect the current policy or product state?
    • Framing: are opinions labeled as opinions, or converted into broad factual language?
    • Consequence: could the answer change a purchase, support action, application, visit, or trust decision?
    • Remediation status: which page, platform, or process is being corrected, who owns it, and what evidence will show that the work is complete?

    Set escalation rules before a problem becomes emotional. A false claim involving safety, legal status, contractual terms, or another high-consequence matter should go to the relevant subject-matter and legal reviewers before a public response is improvised. A current service complaint belongs with the operational owner as well as the reputation team. A low-consequence opinion with no factual error may need observation, not intervention.

    The objective is not to force every AI answer to sound positive. It is to make important answers accurate, current, attributable, and properly qualified. That standard gives SEO, content, public relations, support, and leadership a shared definition of success.

    Start with the branded query where an incorrect answer could do the most damage. Capture the result, split it into claims, and repair the first weak link in the evidence chain. Once that workflow works for one query, apply it to the rest of your decision-critical set. That is how Google AI reputation management becomes an operating practice instead of a reaction to the next unpleasant screenshot.

    References