Tag: AI-generated Content

  • Multimodal SEO for a Search Journey Built Around Images

    Multimodal SEO for a Search Journey Built Around Images

    Visual discovery is becoming a journey rather than a single search feature. People can encounter an idea in an image gallery, inspect it through a social video, refine it with a multimodal query and, in some cases, ask an AI search experience to generate a new visual without visiting a publisher.

    For search teams, the practical challenge is therefore larger than image optimization. Multimodal SEO must make pages, media, structured data and distributed brand profiles easy for machines to interpret and useful enough for people to continue exploring.

    Visual discovery is moving ahead of the conventional query

    Two reported Google changes illustrate how the opening stage of search may be changing. The Google Images redesign article describes a personalized, browseable homepage built around an immersive gallery rather than the service’s historically dominant search box. Search by text, voice or image reportedly remains available, but browsing, saving and returning to visual collections become more prominent parts of the experience.

    That distinction matters because a gallery can create demand before a person has formulated a precise query. Instead of asking for a known object, destination or style, a user can move among related images and gradually clarify an interest. Saved collections can also extend that process across sessions. In this environment, relevance is not limited to matching a typed phrase; an asset must also be suitable for recommendation, visual comparison and thematic grouping.

    The travel SEO source reports a parallel pattern in a commercially important category. It describes search results in which hotel tools, prices, maps, advertisements, directory modules and social videos can appear before a conventional organic listing. For discovery-oriented travel searches, it also reports short-form material from TikTok, Instagram and YouTube appearing within Google’s results. The Images report focuses on Google’s own gallery, while the travel analysis focuses on blended search surfaces, but together they point to the same strategic shift: discovery can happen through a sequence of visual modules without beginning or ending on a brand website.

    This does not make the website irrelevant. It changes its role. A site becomes one authoritative node in a larger system that may include image results, business listings, social profiles, video platforms, structured feeds and AI-generated answers.

    Multimodal visibility depends on interpretable page structure
    A layered webpage illustration connects images, video, page sections, and metadata-like nodes with luminous lines.

    Image quality alone cannot explain how a machine should understand a visually complex page. The visual-semantics source argues that document meaning is communicated through layout, hierarchy and function as well as text. Cards, calculators, comparison modules, tables, filters and buttons establish relationships that may not be expressed in an ordinary paragraph. A price beside one hotel image, for example, must not be confused with the price attached to an adjacent property.

    The source connects this problem to research and patents involving vision-based page segmentation, HTML-aware processing, structured information cards and layout-aware document understanding. These materials do not establish that every described method is a current ranking system. They do, however, illustrate the underlying retrieval problem: a search engine needs boundaries that reveal which labels, values, images and actions belong together.

    This makes multimodal SEO partly an information-architecture discipline. Semantic HTML, coherent component boundaries, descriptive headings and clear associations among captions, controls and media help define the meaning of a region. The objective is not decorative polish for its own sake. It is a page whose visible and structural hierarchies agree about the primary purpose.

    The same source discusses Google’s concept of a “centerpiece annotation” as a way of identifying primary content. It also reports a large programmatic case study in which a calculator was moved from the bottom of a page to the top and made visually prominent as part of 19 changes. Across more than 100,000 pages, the source reported clicks rising from 3.47 million to 4.53 million and impressions from 84.1 million to 167 million after the broader update. The author explicitly cautioned that the effect of the calculator could not be isolated perfectly, so the result should be treated as directional evidence rather than a controlled proof.

    The more transferable lesson is that a page’s principal utility should be easy to locate and extract. The travel analysis reaches a compatible conclusion from a different angle: concise entries, interactive maps and clearly separated itinerary, cost and timing information can serve fragmented user needs more directly than a long, undifferentiated guide. Both sources support designing content in meaningful modules, although neither justifies fragmenting a page merely to manufacture more components.

    Search assets now extend beyond images and webpages

    A multimodal strategy has to distinguish between assets a brand controls and experiences a platform assembles. On the controlled side are original images, page modules, video, structured data, inventory feeds and profile information. On the assembled side are galleries, carousels, maps, AI summaries and other interfaces that decide how those inputs are combined.

    The travel source makes this distinction concrete. It recommends treating real-time accommodation prices, availability, inventory, taxes and fees in Google Hotel Center as essential search infrastructure. It likewise emphasizes accurate Google Business Profile categories, amenities, location information and other attributes. Its argument is that visibility for a filtered request can depend on structured facts, review sentiment and geographic information, not persuasive destination copy alone.

    The same analysis treats social profiles as distributed landing pages because travelers may use public videos and posts for reassurance without reaching the primary domain. That approach implies consistent branding and factual context across each asset: the subject should be recognizable, the location should be unambiguous and the account should connect visibly to the business or entity it represents. The source also reports that Google Search Console introduced social and video content analytics, reinforcing the need to evaluate search exposure beyond conventional webpage clicks.

    Google’s reported addition of text-to-image generation inside AI Overviews introduces a different kind of competition. According to the source, the feature uses Google’s Nano Banana model to create a custom image from a prompt and was announced for English-language rollout in regions supporting image creation in AI Mode. Because the source describes an announced rollout rather than a mature outcome study, its traffic implications remain uncertain.

    Even so, the strategic tension is clear. A gallery can recommend an existing publisher image, while a generative interface can satisfy some visual needs by producing a new one. Publishers therefore cannot rely solely on being the nearest aesthetic match to a prompt. Assets gain defensibility when they carry information or evidence that generation cannot simply substitute: an original product view, a documented location, a useful comparison, a demonstration, a current inventory state or a recognizable brand perspective.

    A practical model for multimodal SEO
    Multiple cameras capture an object while connected image, video, three-dimensional, augmented-reality, and synthetic visual assets branch outward.

    A useful audit can examine four connected properties: findability, interpretability, usefulness and continuity. Findability asks whether important media and data are available to search systems through crawlable pages, supported feeds and public profiles. Interpretability asks whether the entity, subject, location and relationships among page elements are clear. Usefulness asks whether the asset helps someone compare, decide or act. Continuity asks whether the same facts and identity remain consistent as the journey moves between the website, image search, maps, social platforms and AI interfaces.

    At the page level, the audit should begin with the centerpiece. The principal image, tool or answer should align with the page title and visible heading, while unrelated navigation and promotional elements should not interrupt its meaning. Each repeated card or listing needs a stable internal structure so that its name, image, attributes, price and action remain associated. Mobile presentation deserves particular attention because a component that appears coherent on a wide screen can become ambiguous when its elements stack.

    At the asset level, optimization should preserve factual context rather than reducing every image to a keyword target. Descriptive surrounding copy, captions where they help readers, meaningful file handling and accessible alternatives all contribute to understanding. Originality should also have a purpose: a distinctive visual is more valuable when it demonstrates something, documents something or makes a decision easier.

    At the ecosystem level, the canonical business facts should agree across the site, feeds, profiles and public media. Measurement should then separate exposure from destination traffic. Search impressions and clicks remain useful, but they do not capture every discovery touchpoint described in the sources. Teams also need to watch the visibility of visual assets, engagement with off-site content, feed accuracy and the actions users take after arriving. Because the reported interfaces can satisfy needs within Google, a fall in click-through rate does not automatically reveal whether visibility, demand or commercial outcomes have weakened.

    Key takeaways

    • Visual discovery can begin with browsing and recommendation before a user enters a fully formed query.
    • Multimodal SEO includes layout, component boundaries and structured relationships, not just image files and alternative text.
    • Feeds, business profiles and social accounts can function as search assets alongside the primary website.
    • Generative images may reduce some visits for generic visual needs, increasing the value of original, factual and decision-supporting media.
    • Performance measurement should connect cross-surface exposure with user actions and business outcomes instead of relying on webpage clicks alone.

    The next advantage will come from connecting disciplines that are often managed separately: technical SEO, visual production, interface design, structured data, social distribution and analytics. As search becomes more capable of browsing, interpreting and generating visuals, the strongest assets will be those that retain clear meaning wherever the journey encounters them.

    References

  • Why I Judge AI Deliverables by Outcomes, Not Effort

    Why I Judge AI Deliverables by Outcomes, Not Effort

    When I think about AI deliverables, I keep coming back to a simple scenario: a client receives two pieces of work.

    Both deliverables solve the problem they were hired to solve. Both are accurate, useful, and tied to the same business outcome. The client is happy, and from the outside, there is no meaningful difference in the results.

    Then the client learns that one took 20 hours to create, while the other took 20 minutes. That is when the uncomfortable questions begin.

    Was AI involved? Should the faster deliverable cost less? Is the person who completed it less skilled because they found a faster, more efficient way to reach the same result?

    What I find most interesting is how differently many of us react to AI depending on which side of the transaction we are on. I love using AI when it saves me time, but I also understand why customers can feel uneasy when they discover AI helped create something they paid for.

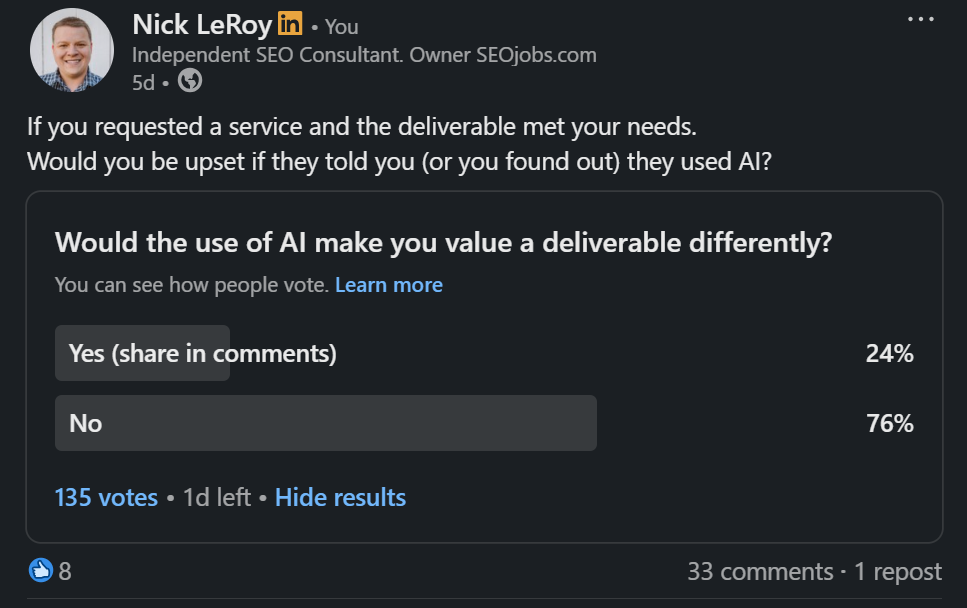
    I recently ran a LinkedIn poll asking a simple question: if the outcome is great, do we really care how it was made?

    The responses reinforced something I have been thinking about for a while. Many of the strongest objections people have to AI are not really about quality at all.

    The Time vs. Value Fallacy

    I think part of the discomfort comes from the fact that we have spent decades tying value to effort.

    Long hours feel valuable. Fast work feels suspicious. Struggle often gets mistaken for expertise.

    The harder something appears to be, the easier it becomes to justify the price attached to it.

    There is an old story about a ship engine that stopped working. After multiple failed attempts to repair it, the owners brought in an engineer with decades of experience. He inspected the engine, tapped it once with a small hammer, and the machine roared back to life.

    His invoice was $10,000.

    Image

    The owners were furious and demanded an itemized bill. The response was simple: hammer tap, $2. Knowing where to tap, $9,998.

    People debate whether that story is true or just a useful tale for people like me who believe in value-based pricing. But whether it really happened almost does not matter. The lesson still holds.

    People are not paying for the tap. They are paying for the expertise behind it.

    That is what makes AI such an important topic for me. It forces us to confront a question many of us have avoided for years: are we paying for expertise, or are we paying for visible effort?

    Those are not always the same thing.

    The Objections That Actually Matter

    To be clear, I do not think every objection to AI is unreasonable. I have shared plenty of my own concerns, and some of them are serious.

    In fact, I think the strongest arguments against AI have very little to do with how quickly something was created.

    Risk matters. Hallucinations matter. Bad recommendations matter. Compliance, privacy, and security concerns matter. Accountability matters.

    Those are legitimate concerns. What stands out to me is that none of them has much to do with how long it took to create the deliverable.

    They are questions of trust.

    Can the output be trusted? Can the recommendation be defended? Can someone confidently stand behind the work if it is questioned six months from now?

    ```json
{
  "alt": "SEO For Lunch Newsletter by Nick Leroy, featuring actionable SEO insights.",
  "caption": "Join Nick Leroy's SEO For Lunch: Your go-to source for actionable SEO insights served directly to your inbox.",
  "description": "This image promotes Nick Leroy's 'SEO For Lunch' newsletter, emphasizing actionable SEO insights. It features a smiling person against a dark blue background with the newsletter's branding, '#SEOFORLUNCH,' and website details. The design includes graphic elements like a fork and knife, alongside the tagline 'Not Your Average Table Talk.'"
}
```

    Because when something goes wrong, nobody gets to blame the AI. The employee is accountable. The consultant is accountable. The company is accountable.

    That is why I have always found the quality debate to be the least interesting part of the conversation. The more important question is not whether AI was involved. It is whether the outcome is trustworthy enough for someone to put their name behind it.

    The Outcome Test

    The more I think about AI, the less interested I become in whether it was used.

    Instead, I find myself asking a different set of questions. Was the outcome accurate? Was it useful? Was it better than the alternative? Would I be willing to stand behind it with my name, reputation, and credentials on the line?

    If the answer to all of those questions is yes, then I have a hard time arguing that the production method matters more than the result.

    I suspect this is where many people become uncomfortable because it shifts the conversation away from tools and back toward results.

    Ironically, this is also where humans become more important, not less.

    The future is not machines versus humans. I know, "The Terminator" and "I, Robot" movies will never feel the same. The real shift is humans using AI versus humans who refuse to adapt.

    The premium will not come from avoiding AI. It will come from judgment, taste, decision-making, communication, and accountability.

    AI can accelerate execution, but people still decide what should be built, what should be published, and what risks are acceptable. More importantly, people are still responsible for the outcome.

    The people who lose to AI will not be the ones using it. They will be the ones still evaluating effort while everyone else is measuring outcomes.

    This post first appeared on the author’s website and is republished here with permission.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • How to Align Claude With Your Brand Voice Consistently

    How to Align Claude With Your Brand Voice Consistently

    You ask Claude for a polished draft, but the result sounds like polished AI: competent, smooth, and interchangeable with everyone else’s content. Repeating your preferred tone or asking it to sound more human rarely fixes the underlying problem.

    You need to turn brand voice from a subjective impression into instructions Claude can apply and your team can review. With clear rules, representative examples, and a repeatable editing loop, Claude can reflect your brand voice without merely copying an old draft.

    Translate your brand voice into observable choices

    An editor's hands organize unlabeled sliders, dials, colored tokens, and differently sized blocks on a neutral workspace.

    Words such as friendly, authoritative, bold, and conversational are too open to interpretation. A financial adviser and a fitness coach can both sound friendly while using completely different language, pacing, evidence, and calls to action.

    Build a compact voice card that describes what a writer should do on the page. Cover these areas:

    • Audience: Name the reader, what they already understand, and the decision they are trying to make.
    • Relationship: Decide whether the brand acts as a specialist, teacher, peer, challenger, or reassuring adviser.
    • Sentence behavior: Describe the preferred pace, paragraph length, use of contractions, and tolerance for jargon.
    • Vocabulary: List preferred terms, words that require explanation, and language the brand avoids.
    • Evidence: Explain when claims need examples, data, citations, qualifications, or practical next steps.
    • Point of view: Specify when to use you, we, the company name, or a neutral construction.
    • Formatting: Define how headings, lists, calls to action, and emphasized text should work.
    • Boundaries: Identify tones the brand must never adopt, such as smug, alarmist, vague, or overly promotional.

    Make every rule testable. Replace be clear with explain technical terms on first use. Replace sound confident with state the recommendation directly, then explain its limits. Replace avoid hype with remove unsupported superlatives, urgency, and promises of guaranteed results.

    Add contrast when a rule could be misunderstood. For example: direct, not abrupt; informed, not academic; warm, not chatty; persuasive, not pushy. These boundaries help Claude distinguish your intended voice from a nearby but unsuitable one.

    Choose examples that teach judgment, not imitation

    Examples show Claude how your rules interact in real writing. Use approved material that still represents the brand. A rushed email, an outdated landing page, and an executive’s personal writing style can introduce conflicting signals.

    Label why each example belongs

    Do not paste examples into the prompt without explanation. Mark the behavior Claude should learn from each one:

    • This opening names the reader’s problem before introducing the company.
    • This explanation defines the technical term without talking down to the reader.
    • This transition moves from evidence to a recommendation without overstating certainty.
    • This call to action describes the next step without manufacturing urgency.

    Also distinguish voice from content. Tell Claude that names, claims, prices, dates, product details, and recommendations in an example are not facts for the new draft. They are reference material only for language, structure, and tone.

    Include useful negative examples

    A rejected line becomes valuable when you explain the rejection. Pair it with an approved rewrite and a reason. The reason might be that the original buries the answer, uses an empty superlative, assumes too much knowledge, or turns a measured claim into a guarantee.

    Negative examples work best when they are close to acceptable. Obvious failures teach little. A plausible sentence that misses your voice reveals the boundary Claude needs to recognize.

    Give Claude a prompt with clear layers

    A reliable brand prompt separates permanent voice rules from the current assignment. This prevents campaign details from being mistaken for lasting brand principles and makes the setup easier to reuse.

    Use this sequence when assembling the prompt:

    1. Set the role. Identify the brand, the type of writer Claude should act as, and the responsibility it has to the reader.
    2. Define the reader and outcome. State who the content serves, what brought that person to the page, and what they should understand or do afterward.
    3. Insert the voice card. Include observable language rules, preferred vocabulary, formatting conventions, and prohibited tendencies.
    4. Add annotated examples. Explain which behaviors to reproduce and which factual details not to carry into the new work.
    5. Provide task facts. Supply the brief, approved claims, required links, product information, and any material that must appear.
    6. Set hard constraints. Name the required format, scope, compliance boundaries, and anything Claude must not infer.
    7. Request a self-check. Ask Claude to identify any voice rule it could not satisfy and flag missing facts instead of filling gaps.

    Keep priorities explicit. Accuracy and legal or editorial constraints come before style. Voice rules come before decorative flourishes. Examples demonstrate delivery but do not override the approved facts in the brief.

    If the assignment is complex, ask for an outline before the full draft. Review whether the planned argument suits the reader and brand posture. Fixing a structural mismatch at that stage is easier than polishing an entire draft built on the wrong approach.

    Review voice alignment with evidence

    Do not approve a draft because it feels roughly on-brand. Review it against the voice card and point to the language that passes or fails each rule.

    • Does the opening address the reader’s actual concern, or does it begin with background they did not ask for?
    • Are recommendations stated directly and supported at the level your brand expects?
    • Would the intended reader understand every technical term without leaving the page?
    • Does the draft preserve uncertainty where the available facts are limited?
    • Are paragraphs, headings, and lists consistent with your publishing conventions?
    • Does the call to action offer a relevant next step rather than switching into sales language?
    • Could a competitor publish the draft unchanged? If so, which brand-specific judgment or vocabulary is missing?

    When something fails, give Claude a diagnostic correction. Instead of make this warmer, identify the behavior: the paragraph sounds distant because it uses abstract nouns and never addresses the reader. Ask for a revision that speaks to you, keeps the technical meaning, and removes the abstract phrasing.

    Save recurring corrections as new voice rules. If editors repeatedly remove inflated claims, add an explicit rule about claim strength. If introductions repeatedly take too long to reach the answer, define what the opening must accomplish. Your editing history should improve the system, not disappear into individual drafts.

    Turn a successful prompt into a content workflow

    Two team members inspect content pages moving through a modular workflow of transparent frames, review lenses, and adjustment controls.

    Brand alignment breaks when every writer maintains a different prompt. Store the approved voice card, examples, exclusions, and review checklist in one controlled location. Give the material an owner and update it when the brand changes.

    Separate the workflow into clear responsibilities:

    • Brand owner: Approves voice rules, terminology, and representative examples.
    • Subject specialist: Supplies facts, qualifications, and claims that may be made.
    • Prompt owner: Maintains the reusable instructions and resolves conflicts between them.
    • Editor: Checks the draft against the brief, voice card, and publishing requirements.
    • Approver: Accepts the final communication risk rather than assuming the model has done so.

    Track failures by type. Voice drift, unsupported claims, weak structure, missing context, and formatting errors need different fixes. A voice rule will not repair a thin brief, and another example will not resolve contradictory product facts.

    Test revisions with the same assignment whenever possible. If you change the voice card and the brief at once, you cannot tell which change improved the result. Keep approved outputs as benchmarks, but continue reviewing new drafts; consistency is a managed process, not a one-time prompt.

    Key takeaways

    • Replace broad adjectives with observable rules about wording, structure, evidence, and reader treatment.
    • Use current, approved examples and label the behavior Claude should learn from each one.
    • Keep voice instructions, task facts, examples, and hard constraints in separate prompt layers.
    • Review drafts against explicit criteria and turn repeated editorial corrections into reusable rules.
    • Assign ownership for the voice system so every writer works from the same approved standard.

    Start with one approved asset and extract the decisions that make it sound like your brand. Build the voice card, run a real assignment through it, and record every correction. That gives you something more durable than a good draft: a system your team can improve each time it publishes.

    References

  • Google Content Quality: How AI-Assisted Pages Can Rank

    You have an AI-assisted page ready to publish, but one question is holding it up: will Google treat the content as low quality because a model helped write it? Rewriting every sentence by hand is not the answer. Neither is publishing the model’s first draft and hoping formatting or schema will make it competitive.

    The practical job is to create a page whose claims a human editor can defend. That matters in conventional search and in AI-generated answers. Google has acknowledged using protections against manipulative, low-quality listicles in both Search and Gemini, while ranking data show that detectable AI writing patterns are associated with much weaker performance at the top of Google. The useful response is better evidence and editorial judgment, not an attempt to disguise the production method.

    Ranking data does not prove that Google penalizes AI

    Across 42,000 blog pages classified for a Semrush analysis, human-authored content occupied Google’s number-one position 80% of the time, compared with 9% for purely AI-generated content. Human-authored pages also appeared more often throughout the top 10, while pages classified as AI-generated became more common in lower positions on the first results page.

    Those numbers are a warning against unchecked automation, but they are not evidence of a direct AI penalty. GPTZero was used to classify the pages, and AI detectors can misclassify human, mixed, and machine-generated writing. Because writing type and ranking position were observed together, the result is correlation. It does not reveal which signals Google used or establish that authorship method caused the rankings.

    That distinction changes what you should do. Do not run every draft through an AI detector and rewrite it until the detector returns a preferred label. A detector score is not a Google quality score, and prose that looks human can still be generic, inaccurate, or commercially biased.

    Instead, test whether the page contains judgment that survives scrutiny:

    • Decision value: Does the page help a specific reader choose, fix, avoid, or understand something?
    • Evidence: Can you trace every consequential claim to genuine experience, a supplied record, or a reliable reference?
    • Boundaries: Does the recommendation say who it is for, when it applies, and when it does not?
    • Editorial ownership: Has a named person or accountable team decided that the claims are accurate and worth publishing?
    • Original contribution: Does the page add an explanation, distinction, method, or decision rule beyond what a model could infer from common web copy?

    A human-written page that fails those tests is still weak. An AI-assisted page that passes them has a defensible reason to exist. That is a more useful quality distinction than human versus machine.

    Content quality breaks where evidence and independence are implied

    The clearest failure pattern appears in commercial listicles. A brand publishes a "best tools" page, includes products it has not tested, assigns unexplained scores, and places its own product first. The page looks like an independent evaluation even though the outcome, evidence, and publisher relationship are hidden.

    This is not just a question of writing style. The page is making an evidence claim: that someone performed a fair comparison and has grounds for the ranking. A fluent AI draft can make that unsupported claim sound more convincing, which increases the problem rather than solving it.

    What the page claims to beEvidence it needsHow to frame it honestly
    Independent reviewGenuine use or testing by the reviewerIdentify what was tested, how it was tested, and any limits that affected the conclusion.
    Feature comparisonVerifiable product facts and declared comparison criteriaCall it a researched comparison and do not imply firsthand use that did not occur.
    Owned recommendationSupport for each claim plus a clear material-relationship disclosureState that the publisher owns or sells one of the products and explain how the recommendation was reached.
    Customer testimonialA genuine statement from the person to whom it is attributedPreserve the speaker’s meaning and do not create, rewrite, or assign praise that the person did not provide.

    Use "best" only when you can defend the category

    A defensible winner needs more than a score. Define the audience, use case, eligibility rules, criteria, weighting, evidence type, exclusions, and material relationships. If changing an unstated preference could reverse the result, you do not have an objective ranking. You have an editorial preference that should be presented as one.

    Conditional recommendations are usually more useful than universal winners. "Best for teams that need a self-hosted workflow" gives the reader a decision condition. "Best overall" conceals the condition and invites you to defend a much broader claim.

    If you did not test the products, remove language such as "we found," "our test showed," or "after using." You can still compare documented capabilities, but label the work accurately. A researched feature matrix is not a review, and turning it into one with confident prose does not create the missing experience.

    Treat disclosure as part of the answer

    Including your own product in a comparison is not the same as presenting the comparison as independent. Put the relationship where a reader will encounter it before relying on the ranking. A disclosure buried after the recommendations does not help someone interpret the claims that came first.

    The legal exposure deserves separate attention. The FTC’s Consumer Review Rule, 16 CFR Part 465, took effect in October 2024 and prohibits deceptive practices involving reviews and testimonials, including presenting company-controlled material as independent, reviewing products that were not actually used, and attributing reviews to people who did not write them. Penalties can reach $53,088 per violation.

    These are editorial risk controls, not a legal opinion about your page. If you publish testimonials, comparative scores, endorsements, or rankings involving your own product, have qualified counsel assess the specific presentation and relationships. Do that before scaling the template across many URLs, because repeating the same defect multiplies the exposure.

    Build a human-led workflow around verifiable claims

    AI is valuable when its role is explicit. Among 224 SEO professionals surveyed, 87% retained substantial human involvement and 64% used a human-led, AI-assisted process. Speed was the main benefit for 73%, while only 19% credited AI with improving quality. That gap is the operating principle: automation can accelerate production, but your workflow must create quality somewhere else.

    A reliable process separates transformation from judgment:

    1. Write the reader’s decision first. Complete this sentence before drafting: "After reading this page, the reader should be able to decide whether…" If you cannot finish it precisely, the page does not yet have a useful purpose.
    2. Create a claim ledger. For every important assertion, record the proposed wording, supporting evidence, applicable limit, commercial relationship, and person responsible for verification. Unsupported claims should not enter the prompt as facts.
    3. Give AI a closed evidence set. Ask it to organize only the material you supply, preserve uncertainty, mark missing support, and avoid inventing experience. This makes omissions visible instead of allowing fluent filler to hide them.
    4. Add the human decision layer. A subject-matter editor chooses which evidence matters, resolves conflicts, defines tradeoffs, and decides when no recommendation is justified. These are editorial decisions, not sentence-generation tasks.
    5. Run an adversarial review. Challenge every superlative, score, testimonial, first-person experience claim, and statement about a competitor. Ask what proof would be required if the affected company or customer disputed it.
    6. Edit for direct retrieval. Give each section one clear job, answer its heading promptly, name the entity being discussed, and keep conditions next to the claims they qualify. This improves comprehension for readers and reduces the chance that an answer system extracts an unqualified statement.
    7. Approve facts separately from prose. A smooth final edit can introduce errors by changing scope or certainty. Recheck names, figures, dates, links, disclosures, and recommendation conditions after the prose is polished.

    Within this process, AI can reorganize notes, propose outlines, identify repetition, generate alternative explanations, and convert approved information into another format. It should not manufacture a test, infer customer sentiment, create a score, or turn a product relationship into an independent recommendation.

    Structured data comes after the editorial work. JSON-LD can clarify the entities and content already visible on the page, but it cannot supply missing evidence or convert an opinion into a verified fact. Keep markup aligned with the visible wording, authorship, review status, and relationships. A technically valid schema implementation attached to a misleading page only makes the underlying claim more structured.

    Audit existing AI content by risk, not detector score

    Do not mass-delete pages because a detector labels them as AI-generated. Detector classifications are uncertain, and deleting a useful URL can discard rankings, links, internal pathways, and conversion history without fixing the actual editorial weakness.

    Start with pages where quality and commercial risk overlap:

    • "Best," "top," and comparison pages that rank your product first.
    • Reviews of products your team cannot show it used or tested.
    • Pages with numerical or categorical scores but no reproducible method.
    • Testimonials whose author, wording, permission, or origin cannot be verified.
    • Templates that repeat the same recommendation across many queries with only nouns changed.
    • Pages where citations exist but do not support the sentence beside them.

    Choose a page-level action

    • Keep: The page answers a real decision, supports its claims, discloses relevant relationships, and contributes useful judgment. Improve clarity without rewriting it merely to change an AI score.
    • Rebuild: The topic is valuable, but the evaluation lacks evidence. Obtain the missing evidence, revise the method, and have a human editor make the recommendation again.
    • Reframe: The factual material is sound, but the page implies testing that did not happen. Convert it into a documented feature comparison, directory, or selection checklist and remove review language.
    • Retire or consolidate: The page adds no unique decision support and duplicates a stronger URL. Check traffic, backlinks, internal links, and business value before changing the URL or status.

    If a page contains potentially fabricated reviews, false firsthand claims, or undisclosed company-controlled recommendations, remove the questionable claims from public view and involve counsel. That is different from a routine quality refresh and should not wait for the next editorial cycle.

    Use a stop-ship publication gate

    Do not publish when any of these statements is true:

    • The page claims firsthand use, but nobody can identify who used the product or what was done.
    • A score cannot be reproduced from the stated criteria and evidence.
    • Your own product wins, but ownership or another material relationship is not clear before the recommendation.
    • A testimonial cannot be matched to the person and words behind it.
    • A consequential factual claim has no support, or its citation supports a narrower claim than the prose makes.
    • The draft hides uncertainty by converting "may," "for this use case," or "based on documented features" into an absolute conclusion.

    Once those failures are cleared, improve usefulness. Put the direct answer near the question it resolves. Separate observed facts from editorial judgment. Include the condition that would change the recommendation. Remove paragraphs that merely restate the keyword. Make every heading earn its place by helping the reader do, decide, or notice something distinct.

    Key takeaways

    • Do not treat an AI detector result as a Google ranking verdict; use evidence, decision value, and editorial accountability as the quality test.
    • Use AI to transform approved material and accelerate production, while people retain responsibility for truth, tradeoffs, recommendations, and publication.
    • Do not imply independent testing, customer experience, or objective scoring unless you can prove it and disclose relevant commercial relationships.
    • Define who a recommendation is for and what would change it; conditional advice is more defensible and more useful than an unsupported universal winner.
    • Audit high-risk comparison and review pages first, then rebuild, reframe, or retire each URL according to its evidence and unique value.
    • Add schema only after the visible content is accurate; structured data can describe a claim, but it cannot make the claim true.

    Choose one commercially important AI-assisted page and build its claim ledger before touching the prose. Remove anything you cannot support, expose the method and relationships, and let a human editor make the final recommendation. That single page will give you a reusable quality standard for every brief, prompt, comparison, and schema deployment that follows.

    References

  • Google Performance Max Seasonal Theming: A Practical Workflow

    Google Performance Max Seasonal Theming: A Practical Workflow

    Your strongest Performance Max asset group is already doing useful work. A seasonal push creates an awkward choice: change proven creative under pressure, or build another variation from scratch.

    Google’s seasonal theming offers a more controlled route. You can clone an existing asset group, apply a theme to the copy, and review generated image and text variations while the original remains intact. The speed is useful, but the output still needs human judgment. Treat the feature as a production shortcut, not an automatic campaign strategy.

    Know what Google changes – and what it leaves alone

    Seasonal theming starts with assets you already have. It does not redesign the offer, replace every format, or resolve inconsistencies between the ad and its destination. That boundary matters because the generated version can look finished before it is ready to run.

    • Images: Google can reuse existing images and create variations with themed backgrounds. The product, person, or main subject is still inherited from your starting material, so inspect edges, scale, contrast, and composition rather than judging the background alone.
    • Text: The tool can suggest seasonal headlines and descriptions, but the text refresh is limited. Read the resulting assets as a set. A new seasonal headline can still be paired with older language that changes its meaning or weakens the message.
    • Video: Existing videos are not replaced. A winter image set beside an unmistakably summer video is not a minor aesthetic issue; it makes the asset group feel assembled rather than intentional.
    • The original asset group: The unthemed version remains intact. That gives you a safer starting point for experimentation and a clean asset set to return to if the seasonal treatment does not fit.

    The available themes cover promotional treatments, seasons, and specific cultural moments:

    Theme familyAvailable optionsBest planning question
    PromotionalSale; Studio/EditorialIs the message about a real offer, or only a different visual treatment?
    SeasonalWinter; Spring; Summer; FallDoes the season match the market, product use, and destination experience?
    Cultural momentsChristmas; Black Friday/Cyber Monday; Halloween; Valentine’s Day; Easter; Mother’s Day; Father’s Day; Hanukkah; New Year; Lunar New Year; Back to SchoolIs this moment genuinely relevant to the audience and the offer?

    Choose the narrowest accurate theme. A popular holiday is not automatically the right creative frame. If the product, promotion, or audience has no meaningful connection to it, a generic season or editorial treatment will usually be easier to keep coherent.

    Decide whether seasonal theming fits the job

    The feature works best when the campaign strategy is already sound and only the presentation needs to change. Before opening the theme menu, separate a creative refresh from a campaign rebuild.

    Use the shortcut when the underlying message is stable

    • The existing asset group already promotes the right product, audience need, value proposition, and action.
    • The seasonal idea can be communicated through backgrounds and a limited set of text changes.
    • The current video remains suitable, or the concept can tolerate video that is less seasonally explicit.
    • You have someone available to review every generated asset before it can spend campaign budget.
    • You want a variation of a proven concept while preserving the original group.

    Build or edit more manually when the campaign itself changes

    • The seasonal promotion introduces a different product, price, bundle, eligibility rule, or call to action.
    • The concept depends on new video, product photography, illustration, or a sequence that a background treatment cannot create.
    • Your brand system requires precise art direction that generated background variations are unlikely to preserve without substantial correction.
    • The promotion has legal, geographic, inventory, or timing conditions that must be expressed exactly.
    • The cultural moment requires nuance beyond familiar seasonal symbols.

    Access is also a practical constraint. The option can appear within Asset Groups ahead of major holidays, or as Apply theme to existing asset group while you set up a new one. If it is not visible in your account, do not make the launch depend on assumed access. Move to the manual creative route while there is still time to review it properly.

    Move from a proven asset group to a reviewed seasonal version

    An abstract workflow shows a proven advertising asset group being duplicated, seasonally restyled, and sent for human review.

    A disciplined workflow keeps the convenience from becoming a source of accidental claims, mismatched formats, or unclear test results.

    1. Write a one-sentence seasonal brief. Name the customer moment, the exact offer or message, the featured product, and the intended action. If you cannot state those four elements cleanly, generated creative will not solve the underlying ambiguity.
    2. Select the asset group for message fit. A high-performing group is a useful starting point only when its product and proposition belong in the seasonal promotion. Do not clone a winner whose success came from a different category or customer need.
    3. Apply one theme to the cloned version. Keep the first variation interpretable. Combining a holiday treatment, a new offer, a different product emphasis, and a rewritten brand voice makes it hard to identify what helped or hurt.
    4. Inventory what actually changed. List the image variations, new or revised headlines, descriptions, and untouched video assets. This turns a visually impressive preview into an auditable set of changes.
    5. Correct the gaps manually. Rewrite vague text, remove unsupported promotional language, replace unsuitable source imagery, and address video continuity. Generated output is a draft even when individual assets look polished.
    6. Check the destination experience. The landing page should continue the same season, product, offer, and timing. If the ad promises a seasonal sale but the page makes visitors hunt for it, the creative has moved faster than the customer journey.
    7. Launch it as a controlled change. Record the theme, manual edits, offer, destination, and activation period. Where operationally possible, avoid bundling unrelated campaign changes into the same evaluation window.

    Naming discipline helps once several moments overlap. Use an internal label that identifies the base asset group, theme, offer, and version. The label does not improve delivery, but it prevents your team from reviewing or activating the wrong seasonal copy.

    Review the combinations, not just the individual assets

    A reviewer compares a grid of assembled ad variations while individual image and copy components appear in a separate asset tray.

    A generated image can be attractive and still be commercially wrong. The most consequential failure is usually not an obvious visual artifact. It is a polished asset that implies the wrong offer, date, product use, or cultural context.

    Review areaWhat can go wrongWhat to do before launch
    Image fidelityThemed backgrounds create awkward edges, unrealistic scale, low contrast, or a setting that changes how the product appears to be used.Open every variation at a useful size. Check the main subject, logo, text embedded in the image, shadows, edges, and background context.
    Text combinationsA seasonal headline is paired with an older description that contradicts it, dilutes the offer, or changes the intended tone.Read plausible headline-description pairings as complete ads. Rewrite any asset that works only when viewed alone.
    Video continuityUntouched video communicates a different season, setting, product, or promotion from the new images.Supply a suitable video through normal asset editing, or make the overall theme neutral enough that the current video remains credible.
    Offer accuracySale-oriented language implies a discount, scope, or urgency that the business cannot substantiate.Match every promotional phrase against the approved offer. Confirm products, locations, exclusions, availability, and timing before spending begins.
    Landing-page continuityThe ad introduces a seasonal promise that disappears after the click.Verify that the destination visibly supports the same product and offer, and that the next action is immediately clear.
    Cultural fitFamiliar symbols are used for an audience or market where they feel irrelevant, inaccurate, or reductive.Have someone familiar with the intended audience review the treatment. If the context is uncertain, choose a broader seasonal or editorial theme.
    Brand and complianceGenerated backgrounds, language, or urgency fall outside brand rules or required approval processes.Run the cloned group through the same brand, legal, and promotional review used for manually produced advertising.

    Do not approve the group from a single preview. The feature changes only part of the asset set, so quality depends on how old and new elements coexist. The review unit is the complete seasonal asset group.

    Measure the seasonal version without overstating the result

    Seasonal periods change customer demand as well as creative. Better results during Black Friday, Christmas, or Back to School do not prove that the generated theme caused the improvement. Start by defining what success means for this campaign, then interpret performance in that commercial context.

    • Choose the decision metric in advance. Use the outcome that already governs the campaign, such as conversion value, return on ad spend, cost per acquisition, or qualified lead volume. Do not select whichever metric looks most flattering afterward.
    • Document the demand context. Record the promotion, product availability, destination changes, and seasonal period. These factors can move performance independently of creative quality.
    • Keep the claim proportional to the setup. If the original and themed asset groups run concurrently without controlled exposure, treat the comparison as directional. Do not describe ordinary automated delivery as a clean A/B test.
    • Use the available asset-group and asset reporting. Aggregate campaign performance can hide a weak seasonal variation if other assets continue to carry results.
    • Make an explicit post-season decision. Retire event-specific claims when they cease to be true. Preserve notes on the theme, manual corrections, and performance so the next seasonal build starts with evidence rather than memory.

    The original asset group remaining intact is operationally valuable, but it does not make every comparison controlled. Preservation reduces creative risk; measurement quality still depends on what else changed and how delivery was allocated.

    Key takeaways

    • Seasonal theming is best for changing the context around an already-correct message, not rebuilding campaign strategy.
    • Google can generate themed image backgrounds and suggest some seasonal text while leaving the original asset group intact.
    • Video is not replaced, and the text refresh is limited, so old and new assets must be reviewed together.
    • The right theme is the most accurate one for the product, market, offer, and audience – not necessarily the most prominent holiday.
    • A themed clone is not automatically an A/B test. Seasonal demand and automated delivery can affect the comparison.
    • Generated creative should pass the same offer, landing-page, cultural, brand, and compliance checks as manually produced advertising.

    Start with the asset group whose message best fits the seasonal opportunity, write the brief before opening the theme menu, and build the review checklist before anything goes live. If the idea cannot survive the unchanged video or an exact offer check, give it the manual creative work it needs.

    References


  • AI Gambling Content on News Sites: An Audit and Recovery Plan

    AI Gambling Content on News Sites: An Audit and Recovery Plan

    Your news site can look credible at the domain level while a growing section underneath it is serving a different business entirely. If casino pages, fabricated contributors, unexplained redirects, or generic betting copy have appeared after an ownership or commercial change, you need to determine whether you have an editorial-quality problem or a reputation-abuse problem.

    That distinction changes the response. Editing a few weak paragraphs will not fix a system designed to turn inherited authority into gambling-affiliate revenue. You need to audit who controls publication, why the pages exist, where their links lead, and whether the people named on them are real and accountable.

    Key takeaways

    • AI is usually the scaling mechanism, not the core abuse. The core problem is using a trusted news domain to rank commercially motivated pages that would struggle to earn visibility on their own.
    • Do not base your decision on writing style or an AI-detector score. Confirm the editorial chain, author identity, affiliate relationship, outbound destinations, ownership history, and publication pattern.
    • Not every gambling page on a news site is abusive. Public-interest reporting, industry analysis, and sports coverage can be legitimate when editorial purpose remains primary and commercial relationships are subordinate and disclosed.
    • Freeze suspect publishing before you clean up. Preserve records, classify every affected URL, remove deceptive identity claims, and address the access or contract that allowed the pages to appear.
    • Author schema, affiliate disclosures, or an AI label cannot rescue a page whose real purpose is to exploit the publisher’s reputation.

    AI is the accelerant; inherited trust is the asset

    Calling this an AI-content problem is accurate but incomplete. A new gambling site can generate just as much copy without possessing a news brand’s history, links, returning audience, or established search visibility. The valuable asset is the host domain’s reputation. AI makes it cheaper to cover more queries and replace more human work once that reputation is under commercial control.

    The documented pattern has involved acquiring established sports, gaming, and technology publications, retaining enough legitimate material to preserve credibility, and then increasing casino and cryptocurrency coverage. Former employees said original reporting was removed while AI-generated pages and fabricated author profiles expanded. Affiliate links supplied the commercial path, including arrangements connected to player losses.

    That sequence matters because it gives you a better diagnostic question than “Was this written by AI?” Ask: “Would this page have been commissioned, placed on this domain, and promoted in this way if the domain had no inherited authority?” If the honest answer is no, investigate the business model behind the URL.

    Google describes attempts to exploit an established site’s ranking reputation through scaled publishing as site reputation abuse, with manual action and removal from the search index among the possible consequences. AI use alone does not establish that purpose. A human-written casino landing page can be abusive, while an AI-assisted investigation into gambling regulation can still serve a legitimate editorial purpose. Intent, control, accountability, and reader value have to be examined together.

    One documented operation does not prove that every newsroom with casino content follows the same sequence. Treat the pattern as a risk model, not a verdict. Your own CMS, contracts, author records, link destinations, and editorial decisions must supply the evidence.

    Audit the publishing system, not just the prose

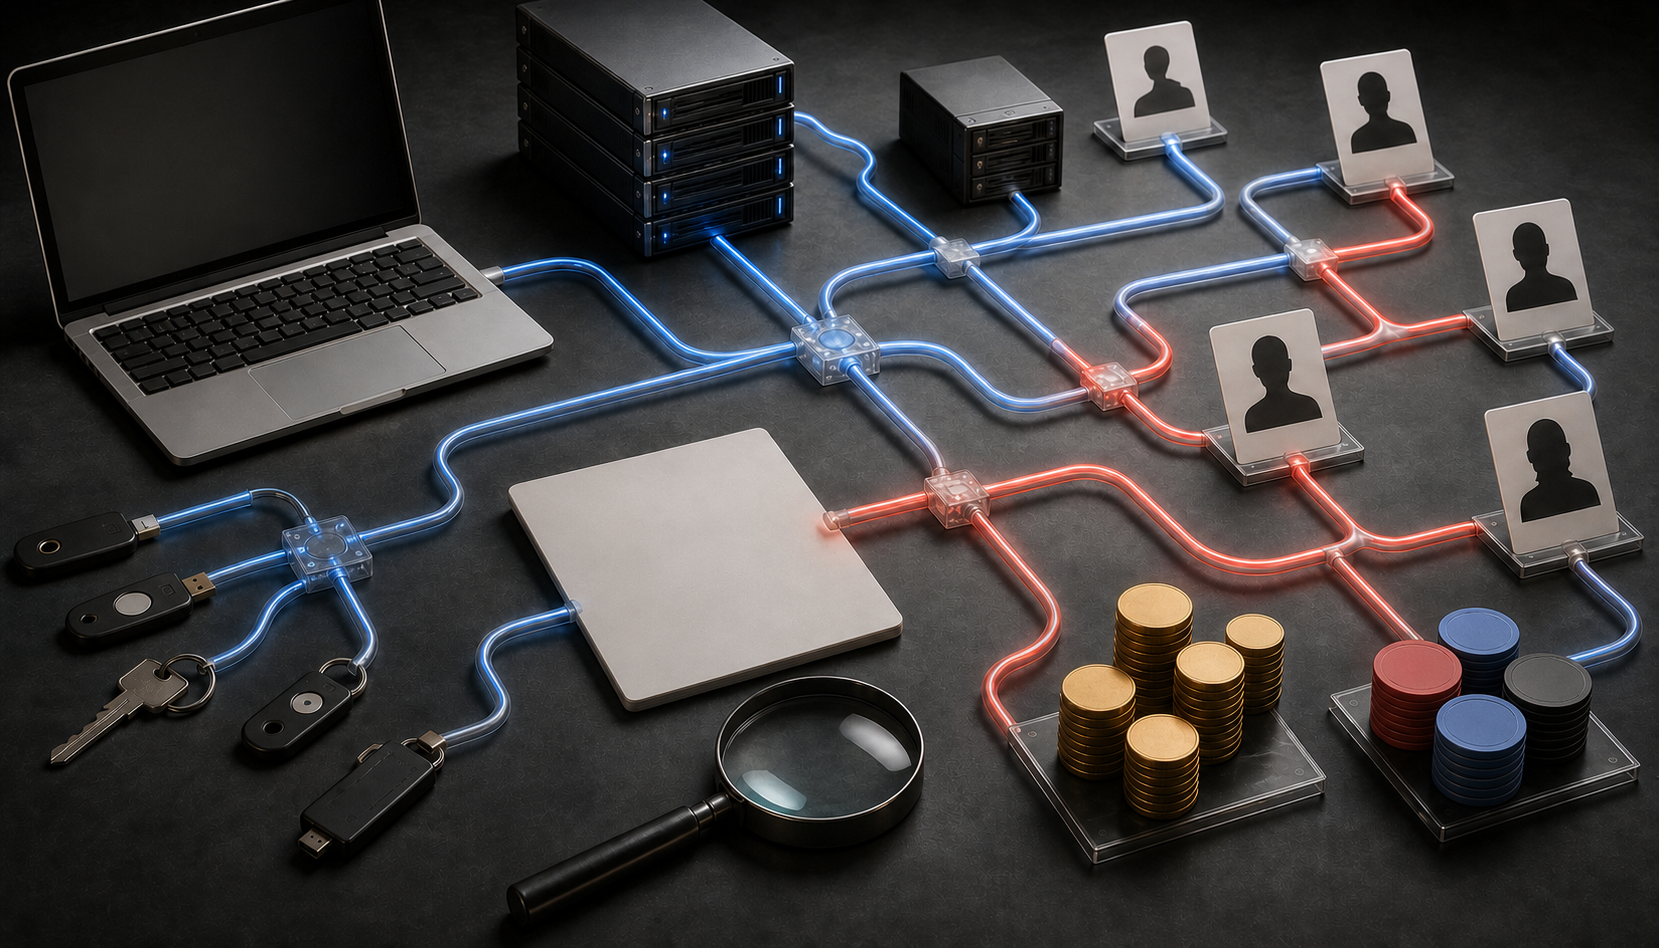
    Evidence table with a laptop, servers, access tokens, profile cards, casino chips, coins, and branching pathways under a magnifying lens.

    Start with an inventory. A handful of visible pages rarely shows the full footprint because the same operation may use directories, author archives, old templates, redirected URLs, or pages that are absent from navigation. Combine your CMS export, XML sitemaps, crawl data, server or analytics records, and Google Search Console data where you have access.

    Record one row per URL with the title, topic, publication and modification dates, named author, assigning editor, content owner, template, indexability, canonical target, structured-data author, internal links, outbound domains, redirect destinations, affiliate identifiers, and current classification. Include deleted or unpublished records when the CMS retains them. Chronology often reveals the commercial pivot more clearly than any single page.

    SignalWhy it deserves attentionWhat to verify before acting
    Casino or cryptocurrency coverage expands after an ownership, contractor, or leadership changeThe topical pivot may reflect a new affiliate model rather than audience demandAcquisition documents, editorial plans, partner agreements, CMS users, and the first publication dates
    Authors have thin, duplicated, or unverifiable profilesA fabricated byline removes accountability and misrepresents who produced the pageAssignment records, employment or contributor records, editor correspondence, revision history, and identity details supplied by the person
    Pages repeatedly send readers to casino offers or comparison pagesThe primary purpose may be acquisition rather than reportingFinal redirect destinations, affiliate parameters, commercial contracts, disclosure placement, and who approved each domain
    Original reporting is removed, buried, or replaced by templated commercial pagesThe publisher’s accumulated reputation is being separated from the work that earned itCMS revisions, backups, navigation changes, redirect maps, and archived internal records
    Search visibility drops or a manual action appearsThe problem may already affect the whole publishing property, not only the gambling sectionThe exact Search Console notice, affected patterns, index coverage, canonical behavior, and alternate URLs carrying the same material

    Trace the money and every outbound hop

    Review the commercial path in read-only fashion. Record the visible call to action, the first linked domain, every redirect, the final operator, and any tracking value. Do not register, deposit money, submit personal data, or bypass access controls to complete the audit. The objective is to document what the publisher sends a reader toward, not to transact with it.

    Then connect those destinations to contracts and payments. Identify the legal party receiving revenue, the person who approved the relationship, the compensation model, and any intermediary that can change a destination without another editorial review. A disclosure may tell readers that a commercial relationship exists, but it does not answer whether inherited authority is being exploited or whether the destination was properly vetted.

    An offshore operator is not automatically unlawful in every jurisdiction. It does create a verification burden because gambling promotion, licensing, age restrictions, and consumer protections depend on where the publisher and reader are located. Before retaining or republishing an offer, have counsel familiar with the relevant jurisdictions assess it. An SEO audit cannot make that legal determination.

    Verify authorship as an accountability chain

    A profile photo and biography are not enough. For each contributor, confirm who assigned the work, who created the CMS account, who edited the page, where the draft originated, who checked factual claims, and who can correct it now. A real person’s name attached without their knowledge is still deceptive. A generic “Editorial Team” byline is not a valid repair if nobody inside the organization accepts responsibility for the content.

    Compare the visible byline with the Article and Person data emitted by the page. The name, publisher, reviewer, profile URL, and sameAs references should describe the same real editorial relationship shown to readers. Structured data should map accountable facts; it should never be used to manufacture an expert, disguise an affiliate, or make a synthetic persona look established.

    Reconstruct the timeline and access path

    Place ownership events, staffing changes, new CMS accounts, template deployments, affiliate contracts, and topic growth on one timeline. You are looking for control points: the moment a partner gained publishing access, a new section bypassed normal editing, or an outbound-link system made destinations changeable after approval.

    This separates individual page defects from systemic abuse. If the same account created false authors, generated pages, and inserted commercial links, removing the URLs without revoking that control leaves the mechanism intact. If a contract grants an external party broad publishing rights, the problem may persist even after a password change.

    Separate legitimate coverage from reputation exploitation

    Do not bulk-delete everything containing the words casino, betting, or gambling. A news organization may have valid reasons to cover regulation, addiction, sports sponsorship, corporate results, consumer risk, crime, or technology. Destruction without classification can erase legitimate journalism, break useful links, and make later review harder.

    Use the following questions as an editorial triage model. They are not a substitute for Google’s own case-specific decision or legal advice.

    1. What job does the page perform? A reporting page helps the reader understand an event, claim, risk, or decision. An acquisition page is organized around sending the reader to an operator.
    2. Why does it belong on this publication? Audience need, newsroom expertise, and an established coverage remit are defensible reasons. Access to a strong domain is not.
    3. Who commissioned and controlled it? Identify an accountable editor and the editorial rationale. “The partner supplied it” is a warning, especially when the partner also benefits from clicks or losses.
    4. What evidence is unique to the page? Look for original reporting, attributable analysis, transparent methodology, or clearly sourced facts. Generic rewrites surrounding a commercial link provide little editorial justification.
    5. Is the author real and responsible? Confirm the person, assignment, expertise, edits, and correction path. Do not infer legitimacy merely because a profile exists.
    6. Is monetization subordinate to editorial purpose? Commercial links should not dictate the topic, conclusion, rankings, or recommendation. Disclosure is necessary when a relationship exists, but disclosure does not neutralize a compromised purpose.
    7. Would you publish it without search traffic or affiliate payment? This counterfactual exposes pages whose only rationale is borrowed ranking power.

    Classify each URL as keep, rebuild, remove, or escalate. Keep pages with a defensible public-interest purpose and accountable production. Rebuild pages where the subject belongs but the sourcing, identity, disclosures, or commercial balance do not. Remove pages built primarily to exploit inherited reputation. Escalate anything involving disputed ownership, contractual duties, regulatory exposure, impersonation, or evidence that may need to be preserved.

    An AI label does not change that classification. Neither does fluent prose. The relevant question is whether a responsible newsroom stands behind the page and can show why it exists.

    Contain the abuse before attempting a ranking recovery

    Containment comes first because continued publication can enlarge the affected footprint while the audit is underway. Recovery work should follow a controlled sequence.

    1. Pause suspect publishing and link changes. Freeze the affected workflow, not the entire newsroom, unless you cannot isolate it safely. Preserve access and activity records before disabling accounts.
    2. Create a recoverable evidence set. Back up the database and relevant files. Save the URL inventory, rendered pages, structured data, redirect chains, contracts, CMS histories, and approval records. If litigation, employment action, a regulatory inquiry, or contractual conflict is possible, let counsel set the retention process before anything is destroyed.
    3. Remove unauthorized control. Revoke unneeded CMS accounts, API keys, deployment access, redirect management, affiliate dashboards, and shared credentials. Review scheduled jobs and integrations that can recreate deleted pages.
    4. Apply the URL decisions. Keep legitimate reporting, rebuild salvageable coverage, and remove abusive pages. A removed page with no genuine replacement should return an appropriate not-found response. Redirect only when a truly equivalent destination exists; sending every deleted URL to the homepage hides the cleanup rather than preserving meaning.
    5. Clean the surrounding architecture. Update menus, category archives, author archives, internal links, sitemaps, canonical tags, feeds, related-content modules, and cached versions. Check subdomains and alternate templates so the same material is not still indexable elsewhere.
    6. Correct identity and schema. Delete fabricated profiles, restore accurate bylines, name accountable editors where appropriate, and align Article, Person, and Organization data with visible facts. Do not transfer a fake persona’s history to a new generic identity.
    7. Address the search action shown to you. If Google Search Console displays a manual action, use the process and scope described there after the cleanup is complete. Document what caused the problem, what was removed, what access changed, and which controls now prevent recurrence.

    Do not promise a quick return to previous visibility. In the documented pattern, some publications were deindexed, abandoned, closed, or affected by layoffs after penalties. Those outcomes show why ranking recovery is not the only objective. You are also protecting readers, employees, contributors, commercial partners, and the brand’s remaining credibility.

    Measure progress by more than aggregate organic traffic. Track whether removed URLs remain unavailable, alternate copies disappear, unauthorized outbound domains stay blocked, author records remain accurate, manual-action status changes, and legitimate sections recover stable discovery. A traffic rebound without control of the publishing system is not a durable recovery.

    Build controls around access, money, and identity

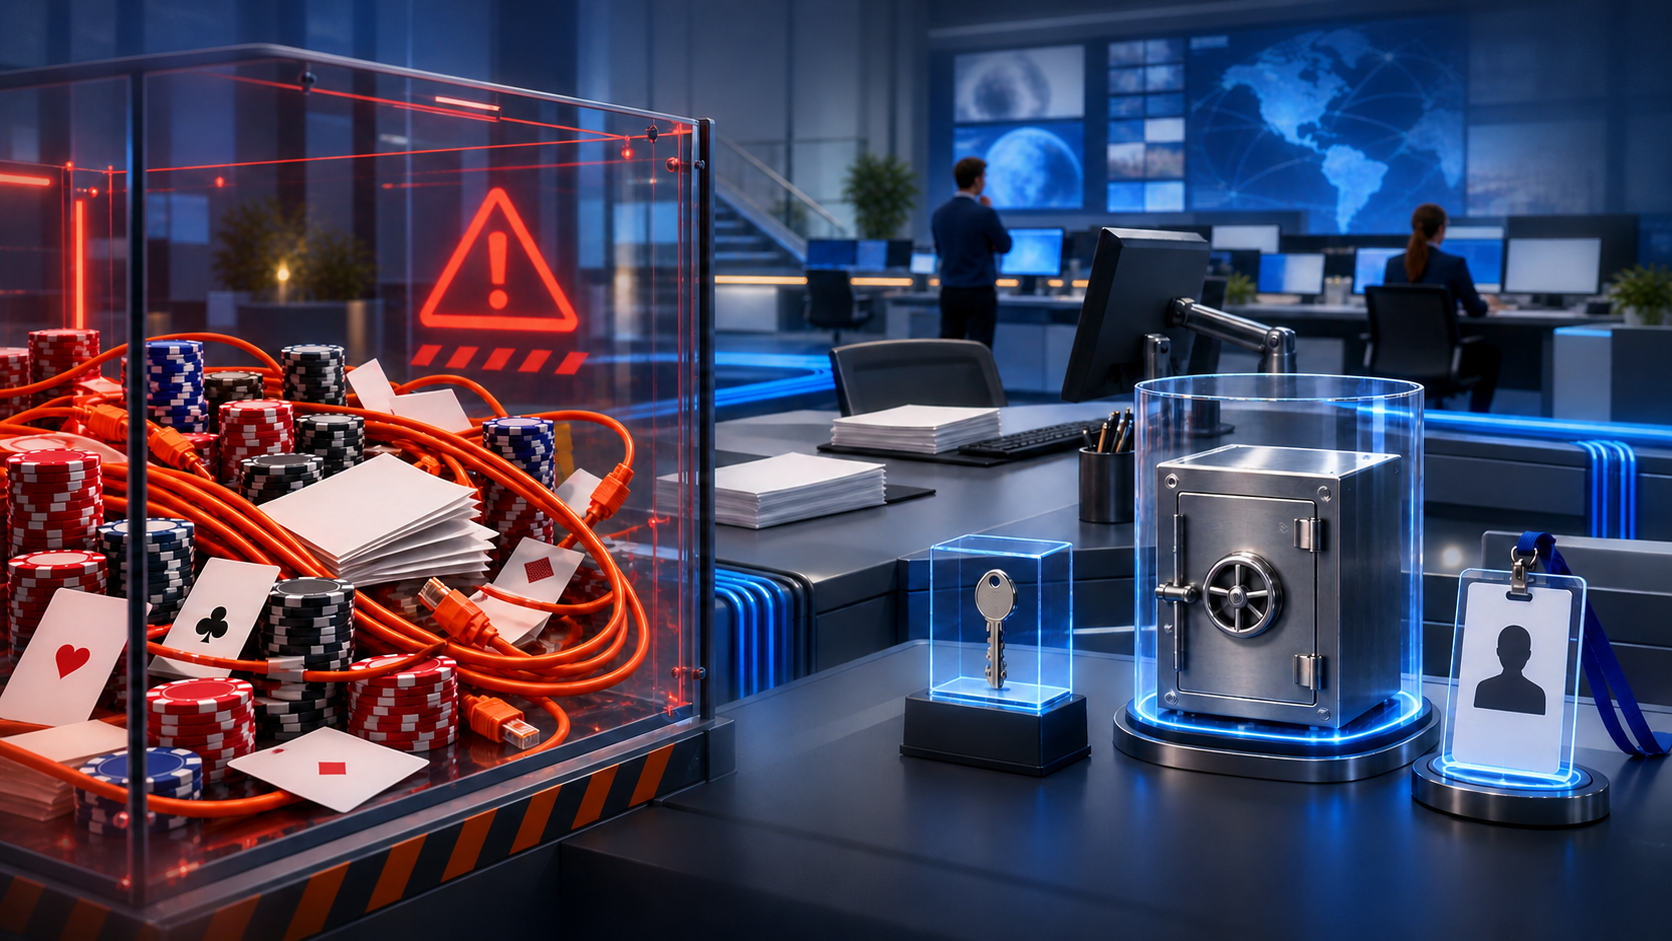
    News operations room with casino-related materials and cables isolated behind a transparent barrier beside locked access, payment, and identity controls.

    A policy that merely requires human editing will not prevent recurrence. A human can approve a deceptive page, and an AI system can assist with legitimate newsroom work. Put controls at the points where commercial incentives can override editorial responsibility.

    • Require a named internal owner for every section. That person should be able to explain its audience, commissioning standard, revenue relationship, correction process, and current contributors.
    • Separate publication from commercial destination control. Do not let one external partner create authors, publish pages, and change outbound targets without an independent review.
    • Maintain an approved-domain register. Record the owner, destination, jurisdictional review, affiliate relationship, approver, and permitted context for every gambling-related outbound domain. Re-review a link when its final redirect destination changes.
    • Make author creation a governed action. Require verifiable identity, a real editorial relationship, an accountable editor, and a documented correction route before a profile can publish.
    • Validate structured data against the CMS record. Flag mismatches between visible and machine-readable authors, publishers, reviewers, dates, and profile URLs. Do not generate Person entities merely because a content template expects one.
    • Review commercial topic pivots explicitly. A major expansion into casinos or cryptocurrency should require editorial, SEO, legal, and brand review before pages are commissioned, not after they rank.
    • Include publishing access in acquisition due diligence. Examine affiliate agreements, content ownership, CMS roles, redirect services, historical manual actions, high-volume directories, author authenticity, and any partner with post-publication control.
    • Audit AI workflows by risk, not by tone. Check provenance, claims, links, author accountability, disclosures, and approval. Polished language is not evidence of safe production.

    The most useful first move is small and concrete: export every URL in the affected section and add columns for owner, real author, editorial purpose, outbound destination, affiliate relationship, and decision. Any row you cannot complete has identified a control gap. Resolve those gaps before the next page is published.

    References


  • How Google AI Overviews and Spam Updates Change Marketing

    How Google AI Overviews and Spam Updates Change Marketing

    If your Google traffic or paid-search return has softened, the worst response is to treat every decline as the same problem. An AI Overview can take a click without changing your ranking. A spam-related visibility loss can remove a page from contention. Higher ad costs can hide inside a stable account average.

    Your first job is to identify which mechanism changed. Only then should you move budget, rewrite content, adjust bids, or retire pages. Here is a practical way to diagnose the impact and build a marketing strategy that is less dependent on any single version of Google Search.

    Two Google changes can create the same traffic decline

    AI Overviews change the search results page before the click. They can answer part of the query, present comparisons, cite selected pages, and push traditional listings or ads farther down the screen. A spam update works differently: it can change whether Google considers a page worthy of visibility at all.

    Both can produce fewer sessions, leads, and sales, but they require different responses. If your ranking and impressions remain relatively stable while click-through rate falls, the results-page experience may be absorbing demand. If impressions and rankings disappear across a recognizable group of pages, investigate content quality, indexation, site patterns, and query eligibility before blaming the interface.

    The paid-search picture is equally easy to misread. Adthena tracked millions of ads across six major industries from late December 2025 through January 2026. Aggregate performance initially appeared stable, but query-, industry-, and device-level results exposed material differences in click-through rate and cost per click. This is vendor-supplied, observational evidence rather than a universal forecast, so use it as a diagnostic pattern, not a fixed benchmark for your account.

    Low-trust organic growth can be even more fragile. Three new domains targeting welding, plumbing, and electrical school queries used public data, programmatic AI-generated copy, aggressive internal linking, and thousands of bottom-funnel pages. Each domain reached roughly 200 in-market clicks within a couple of months before falling to zero around a December spam update. Because several weak signals were bundled together, the result does not prove that one tactic caused the loss. It does show how little remains when a site’s only defensible asset is temporary ranking visibility.

    When performance changes, ask three separate questions: Did Google change your eligibility to appear? Did the results page reduce the need to click? Did the economics of acquiring the remaining clicks deteriorate? Do not choose a remedy until you can answer them.

    Diagnose the failure before changing campaigns or content

    An analyst compares three evidence stations representing intercepted clicks, filtered web pages, and a more expensive advertising auction.

    Start with the smallest useful unit: a query group, its landing pages, and the devices on which it appears. Sitewide traffic and accountwide return on ad spend are outcome metrics. They rarely tell you why the outcome changed.

    Signal you observeLikely mechanism to investigateWhat to inspect nextDecision it supports
    Organic impressions fall across a page groupRanking, indexation, demand, or query-eligibility changeAffected queries, indexed URLs, page templates, publication patterns, and the timing of the declineRepair a technical issue, improve or consolidate weak pages, or accept a demand shift
    Organic impressions remain, but click-through rate fallsAI Overview or another results-page feature is satisfying or displacing the clickThe live results page for the query on desktop and mobile, including citations and competing result typesImprove how the page earns attention, target a later decision, or change the value assigned to that visit
    Paid click-through rate falls where an AI Overview appearsAd displacement or reduced need to visit an advertiserSearch terms, device, ad position, AI Overview presence, and conversion value after the clickChange bids, messaging, or budget for that query cluster
    Cost per click rises while margin contractsA higher price for the remaining visibilityQuery-level revenue, acquisition cost, conversion quality, and device splitCap exposure, improve post-click economics, or move spend to a stronger intent group
    Clicks fall but conversion rate remains stableAn acquisition problem rather than an obvious landing-page problemTraffic source, search feature exposure, query mix, and impression volumeRestore qualified reach before rebuilding a page that still converts

    Seasonality, tracking failures, changing demand, budget limits, and competitor activity can imitate some of these signals. Verify that measurement definitions and conversion tracking remained consistent before assigning the loss to a Google change. A coincident update is a clue, not proof.

    Build a query-level change log

    For every commercially important query cluster, record the landing page, intent, device, AI Overview presence, organic impressions, organic clicks, paid impressions, paid clicks, cost per click, conversions, and business value. Add the date you observed a meaningful change and the action taken in response.

    Keep desktop and mobile separate. AI Overviews appeared less frequently on mobile in the observed industries, but limited screen space allowed them to displace ads more aggressively when they did appear. Desktop showed heavier AI Overview exposure in areas such as Technology and Education, while still leaving more physical room for ads below the generated answer. A combined device average can conceal both conditions.

    Intent also changes the risk. Comparison content appeared frequently in AI Overviews for Telecom, Technology, and Retail queries. News and FAQ themes were more prominent in Healthcare and Financial Services, where an answer may filter out low-intent visitors before they consume paid budget. Problem-solving content appeared in only 0-2% of the observed AI Overview themes. Treat those patterns as hypotheses to test in your own market, not as permanent rules.

    Rebuild paid search around profitable unanswered intent

    AI Overviews do not make paid search uniformly ineffective. They change which questions still need a commercial click. Your objective is not to preserve the old click volume at any price. It is to buy the searches where your offer can advance a decision that the generated answer has not completed.

    • Separate comparison queries. If the AI Overview already summarizes product categories, features, or alternatives, generic ad copy adds little. Give the searcher a reason to continue: a relevant offer, concrete availability, a decision tool, a qualifying detail, or a landing page built for the next unresolved choice.
    • Protect problem-solving queries that remain productive. The low AI Overview presence observed for this theme makes it a useful place to look for resilient demand. Confirm the pattern in your own results pages before reallocating spend.
    • Keep brand intent distinct. Automotive searches showed more resilience where people continued past summaries for brand information. Brand behavior should not be blended with non-brand discovery because it can make a vulnerable campaign look healthier than it is.
    • Do not overpay for filtered curiosity. If an AI Overview answers a broad FAQ and the remaining clicks rarely convert, a lower click total may be beneficial. Judge the query by qualified outcomes and margin, not by traffic alone.

    Cost pressure also varies by market. Technology queries associated with AI Overviews consistently carried higher costs per click in the observed period. Automotive and Retail costs were more similar with and without AI Overviews, while even modest increases could matter in Financial Services because clicks were already expensive. The practical lesson is not that every advertiser should cut bids. It is that an account average cannot tell you where visibility became uneconomic.

    Overlay AI Overview presence on search-term performance, then evaluate click-through rate, cost per click, conversion quality, acquisition cost, and revenue together. A lower click-through rate can still be acceptable if poor-fit visitors were filtered out. A stable conversion rate can still produce a revenue problem if qualified click volume collapses. A higher cost per click can still work if the resulting customer value supports it.

    Use contained query clusters when testing bid or message changes. An accountwide adjustment can spend more money without revealing whether the cause was device displacement, query intent, creative relevance, or a changing results page. Preserve a comparison group, document the change, and judge the result on profit rather than recovered clicks.

    Replace scalable SEO output with content competitors cannot clone

    The old content-production question was often how many keyword variants a team could publish. The better question now is what would remain valuable if Google stopped sending traffic tomorrow.

    AI is not automatically the problem. Google draws the policy line around purpose: using automation or AI-generated content primarily to manipulate rankings can violate its spam policies. A useful AI-assisted page can still help a real reader. A thousand interchangeable pages assembled from public data remain interchangeable, no matter how polished their templates look.

    Before approving a page or template, ask:

    • Does it contain original information, analysis, or experience that is not available from the same public inputs?
    • Is a qualified person accountable for the claims, especially on a high-stakes topic?
    • Does the page solve a distinct user problem, or does it merely swap a location, profession, product, or adjective into an existing template?
    • Would someone save, cite, share, revisit, or use it if the page had no ranking position?
    • Can the content reach its intended audience through an owned channel, partnership, community, paid campaign, or direct referral?
    • Does internal linking help the visitor move to a related decision, or does it exist mainly to force crawl coverage?

    Strong content moats can take several forms: original benchmarks, a transparent assessment, an interactive decision tool, expert analysis, first-party observations, or a well-moderated body of user knowledge. A financial forecasting company, for example, could use expert conversations to identify current forecasting gaps, validate whether its product addresses them, and turn the result into an assessment supported by credible benchmarks. That asset can create discovery, sales conversations, and community discussion even if it never wins the highest-volume generic keyword.

    This model produces fewer pages and slower feedback, but it creates something harder to replace. Original research, expert insight, vertical user knowledge, partnerships, and distribution beyond search give a business more than temporary keyword coverage. They also give AI systems and human readers a clearer reason to cite or seek out the brand.

    Technical optimization still matters. Clear entities, accurate structured data, accessible page architecture, and consistent authorship information can help machines interpret what you publish. They cannot manufacture authority or originality. Schema makes a claim legible; it does not make the claim credible.

    Do not mass-delete pages simply because traffic fell after an update. Removal can destroy useful history, links, and demand that might recover through improvement. First group pages by purpose and quality. Keep and strengthen pages with distinct value. Consolidate overlapping variants into the strongest destination and map redirects before removal. For pages that exist only to capture a keyword permutation, consider a reversible exclusion while you verify that they serve no user or business need.

    Build a marketing system that can absorb the next change

    A strategy team operates a circular network of expert content, product demonstrations, community, email, paid search, and a website around a shifting search gateway.

    You cannot prevent Google from changing the interface, ranking systems, or advertising environment. You can prevent one change from becoming a companywide emergency.

    1. Maintain a search-exposure layer in reporting. Track AI Overview presence, device, query intent, organic visibility, ad placement, and economics alongside traffic and conversions.
    2. Set decisions at the query-cluster level. Define when a cluster should be protected, tested, reduced, or retired. Do not let a healthy brand campaign subsidize an unprofitable generic segment without making that choice explicit.
    3. Tie major content to a defensible asset. Require original evidence, accountable expertise, a useful tool, proprietary analysis, or community knowledge before committing to a large content build.
    4. Separate demand capture from demand creation. Search captures people already asking. Research, partnerships, communities, public relations, paid distribution, and owned audiences can create recognition before the search begins.
    5. Record channel dependency. Know which leads, revenue streams, and content programs would fail if non-brand Google traffic disappeared. That exposure should influence budget and content priorities before a decline occurs.

    Key takeaways

    • An AI Overview click loss and a spam-related ranking loss can look similar in a traffic dashboard, but they need different remedies.
    • Segment search performance by query intent and device because aggregate averages can hide both displacement and rising acquisition costs.
    • Optimize paid search for profitable unanswered intent, not for restoring every lost click.
    • Use AI to support genuinely useful content, not to multiply public information across interchangeable pages.
    • Build fewer, more defensible assets and distribute them through channels you can influence beyond Google.

    Start with the revenue-bearing query cluster showing the clearest change. Inspect the live results page, isolate the device and intent involved, and test a contained response. Once you know whether the problem is eligibility, displacement, or economics, you can scale the fix without dismantling the parts of your marketing system that still work.

    References

  • How Human Experience Becomes a Search Visibility Advantage

    How Human Experience Becomes a Search Visibility Advantage

    You have a technically sound page. It targets the right query, uses sensible schema markup, and has enough authority to compete. Yet its visibility stalls, or the traffic it earns does little for the business. Adding another keyword variation is unlikely to solve that problem.

    The missing layer is often the experience after discovery: how quickly the visitor understands the answer, whether the evidence feels credible, whether the page supports the next decision, and whether the brand leaves a reason to return. You can improve that layer without pretending that one behavior metric is a direct ranking switch.

    Treat human experience as a visibility system, not a ranking toggle

    Asking whether user experience is a ranking factor produces an incomplete answer. It encourages you to hunt for a single measurable signal when the practical issue is a chain of outcomes.

    • Discovery: The search result makes a clear promise that matches the query.
    • Understanding: The landing page delivers that promise before asking the visitor to work through background, branding, or a sales pitch.
    • Trust: The visitor can see who is responsible for the information, what evidence supports it, and where its limits are.
    • Decision: The content helps the visitor compare options, avoid a mistake, or complete the next task.
    • Continuity: The rest of the site, product, and conversion journey remains consistent with what the search result promised.
    • Memory: The experience is distinct and useful enough for the visitor to recognize or seek out the brand later.

    Human Experience Optimization, or HXO, connects SEO, UX, conversion, and brand signals around the experience people actually have. SEO gets the right person to the page. UX helps that person understand and use it. Conversion design gives the person an appropriate next step. Brand consistency makes the promise believable across repeated encounters.

    This does not mean that every analytics event is a confirmed algorithmic input. Bounce rate is an especially weak shortcut. A visitor can leave because the page failed, because the answer was immediately useful, or because the next step happened somewhere you do not measure. Time on page has the same ambiguity. A long session can reflect careful engagement or simple confusion.

    Use behavior data as diagnostic evidence, not as a ranking-factor scorecard. The operational question is not whether you can force visitors to stay longer. It is whether the page lets the intended visitor complete the intended job with confidence.

    Audit the whole path from search promise to next decision

    Three professionals inspect connected stations representing discovery, evidence, usability, and the visitor's next decision.

    A conventional SEO audit can confirm that a page is crawlable, relevant, internally linked, and eligible for enhanced search features. An experience audit starts where that work leaves off. It follows one real search need through the result, page, evidence, action, and downstream experience.

    Do not begin with the homepage or an abstract sitewide persona. Choose a query cluster that already matters, identify the principal landing page, and write the visitor’s immediate job in one sentence. Use a concrete formulation such as: decide whether this approach fits my situation, fix this specific problem, compare these options, or understand what to do next.

    1. Check the search promise. Compare the title, description, and visible result features with the page’s opening. If the result promises a direct answer but the page opens with company history, the experience is broken before the visitor evaluates your expertise.
    2. Test answer latency. Find the earliest point where the visitor can extract a usable answer. Definitions and context should come before the answer only when they are necessary to use it safely or correctly.
    3. Remove interpretation work. Replace broad advice with decision rules, constraints, examples, sequences, and consequences. The visitor should not have to translate a generic principle into the action your team already understands.
    4. Inspect trust at the claim level. A general author biography cannot support every assertion. Put relevant experience, methodology, citations, limitations, or accountable ownership near the claims that need them.
    5. Evaluate the next step. The call to action should follow from the job the visitor came to complete. A person seeking a definition may need a related explanation. A person choosing an implementation path may need requirements, tradeoffs, or a consultation. Sending both to the same generic conversion block creates friction.
    6. Follow the handoff. Open the form, product page, documentation, email, or checkout that comes next. Confirm that its terminology, scope, and expectations match the landing page. Search visibility has limited value when the experience falls apart immediately after the click you wanted.

    Record each break as a mismatch, not a vague quality complaint. Useful labels include promise mismatch, delayed answer, missing evidence, unclear boundary, inaccessible interaction, premature conversion request, and inconsistent handoff. A precise label gives the responsible team something it can fix.

    Then prioritize by consequence. A decorative layout issue usually matters less than a missing answer. A missing answer matters less than a misleading claim that could send the visitor toward the wrong decision. Fix the point where trust or task completion first fails, because improvements farther down the path cannot compensate for a visitor who never reaches them.

    Make first-hand experience change the answer

    Hands examine a physical component with measuring tools, samples, a blank notebook, and a camera beside an abstract digital content panel.

    Well-structured summaries are easy to produce, especially with generative AI. Structure alone is therefore a weak differentiator. First-hand experience becomes valuable when it supplies information an aggregator would not know: the condition that changed the outcome, the step that created unexpected friction, the tradeoff that only appeared during implementation, or the boundary beyond which the recommendation stopped working.

    Do not confuse signals of experience with experience itself. An author box, a headshot, a claim that something was tested, or a polished first-person voice may make a page look more credible. None of them proves that the underlying answer came from direct work.

    Before drafting, build an evidence inventory for the question:

    • What has your team done, observed, built, measured, or decided directly?
    • Under what conditions did that experience occur?
    • Which artifacts can substantiate it, such as a process record, original analysis, worked example, or documented result?
    • What went differently from the initial expectation?
    • Which conclusion is judgement rather than established fact?
    • Where does the team’s direct knowledge end and external evidence begin?

    Use that inventory to alter the substance of the page. If the experience does not change the recommendation, add a useful constraint, reveal a failure mode, clarify a sequence, or narrow the claim, it is probably decorative.

    This is also where responsible AI-assisted publishing draws a hard line. AI can help organize material, expose gaps, or turn rough notes into a clearer structure. It cannot create first-hand evidence that the organization does not possess. Do not manufacture an anecdote, test, customer conversation, or implementation detail to make a draft sound human. If you only have synthesis, label and support it as synthesis. If the query requires direct experience you do not have, obtain that experience from an accountable subject-matter expert or choose a question you can answer honestly.

    The same distinction applies to E-E-A-T. Bios and citations are useful interfaces, but experience, expertise, authority, and trust work as a continuing business pattern. Editorial standards, transparent claims, corrections, consistent positioning, and accountable ownership have to support what the page says. You cannot add them as a finishing component after the business and content make conflicting promises.

    Give SEO, UX, and conversion teams one shared outcome

    Human experience usually degrades at team boundaries. SEO owns the query and search result. Editorial owns the explanation. Design owns the interface. Conversion specialists own the call to action. Product or sales owns what happens after it. Each part can meet its local target while the visitor experiences a single, disjointed journey.

    A shared page brief prevents that split. For every important landing page, define:

    • the audience situation, not just a keyword;
    • the task the visitor needs to complete;
    • the direct answer or decision the page must enable;
    • the first-hand and external evidence available;
    • the material uncertainty, exception, or limitation;
    • the appropriate next step for this intent;
    • the experience that follows that step; and
    • the person accountable for keeping the promise accurate.

    This brief changes the review conversation. Instead of asking whether every department supplied its component, ask whether the visitor can move from query to decision without encountering a contradiction, an unexplained claim, or an unnecessary demand.

    Measure the journey without inventing an HXO score

    There is no need to collapse human experience into one proprietary-looking number. Keep the measures tied to the stage they diagnose:

    • Discovery: impressions, result clicks, query mix, and whether the page attracts the audience it was designed to help.
    • Comprehension: use of relevant page elements, completion of the intended task, internal searches, and repeated questions that the page should already answer.
    • Trust: return visits, branded demand, direct feedback, and engagement with evidence or authorship information where those elements matter.
    • Action: qualified conversions, progression to the appropriate next step, and abandonment at the handoff.
    • Downstream fit: whether the conversion, product, or support experience reveals that the page created the wrong expectation.

    Interpret these measures by page type and intent. A concise reference page should not be judged against a detailed comparison page. A visitor who gets an immediate answer may generate a short session without having a poor experience. A long session is not a success if the person is searching repeatedly for a missing requirement.

    Look for combinations of evidence. Healthy impressions with weak clicks may point to an unclear promise, weak brand recognition, or poor result presentation. Strong clicks followed by little task completion may indicate an intent mismatch, a delayed answer, or interaction friction. Sustained engagement without the appropriate next action can expose missing proof, an unsuitable call to action, or unresolved objections. These are hypotheses to verify with page inspection, user feedback, and journey data, not automatic diagnoses.

    Improve one complete journey at a time

    Sitewide experience programs become vague quickly. Start with one commercially or strategically important query cluster and its principal landing page. Gather the search data, page analytics, recurring audience questions, conversion path, and available first-hand evidence. Run the journey audit, identify the earliest consequential break, and make the smallest change that resolves it.

    Compare performance over a complete, like-for-like reporting period. Keep query intent, page type, seasonality, and unrelated site changes in view before attributing movement to the edit. Document what changed, why it changed, what evidence supported the decision, and what the outcome taught you. Feed that learning into the next content brief so experience quality becomes an operating loop rather than a periodic redesign project.

    Key takeaways

    • Human experience affects visibility through the full path from search promise to understanding, trust, action, and later brand recognition.
    • Do not optimize bounce rate or time on page in isolation. Use behavior data to investigate whether the intended visitor completed the intended job.
    • Audit a specific query-to-action journey and label each failure as a concrete mismatch that an owner can resolve.
    • First-hand experience is useful only when it changes the answer with original evidence, constraints, tradeoffs, observations, or limitations.
    • E-E-A-T depends on accountable business and editorial practices; a bio or citation cannot compensate for unsupported or inconsistent claims.
    • Give SEO, content, UX, conversion, and downstream teams one shared brief and measure each stage according to its purpose.

    Choose one landing page that matters and follow it as a visitor would, beginning with the exact search promise and ending after the next action. Fix the first point where the experience stops being clear, credible, or consistent. That is the most practical place to turn human usefulness into durable search performance.

    References

  • AI-Era Copywriting: Turn Positioning Into Recommendations

    AI-Era Copywriting: Turn Positioning Into Recommendations

    Your team can produce more words than ever, yet your homepage may still leave a buyer asking three basic questions: Is this meant for me? Does it solve my problem? Why should I believe you?

    That gap is where copywriting matters in AI-era marketing. You do not need another layer of generic content. You need language that makes your offer easy for a person to choose and easy for a generative system to match to the right buying situation.

    Key takeaways

    • AI has reduced the value of generic explanation, not the value of persuasion. Information can be compressed; a credible reason to choose you still has to be established.
    • Write from the buyer’s situation rather than from a broad description of your company. State who the offer is for, what problem it solves, how it works, and what supports the claim.
    • Generative engine optimization is partly a positioning problem. Your brand must be available as a relevant solution when a person describes a need, not merely visible for a category keyword.
    • Create separate pages only for meaningfully different decisions. If the audience, offer, proof, and next step are unchanged, changing a few nouns does not justify another page.
    • Use AI to organize evidence, expose gaps, and produce controlled variations. Keep positioning, promises, exclusions, and factual approval under human control.
    • Judge copy by commercial movement: qualified visits, revenue-page actions, lead quality, conversions, and branded demand. Raw traffic is not the final objective.

    Start with the decision, not the draft

    Hands arrange audience, problem, and proof symbols around a product prototype while a blank sheet and capped pen sit nearby.

    A page can be accurate, readable, and optimized without helping anyone decide. That usually happens when the writing explains a category but never establishes a position inside it.

    AI is particularly capable of summarizing, synthesizing, matching patterns, and compressing familiar information. That makes undifferentiated publishing easier to reproduce and easier to replace. It does not remove the need to influence a real choice. In practice, AI exposed the difference between informational production and persuasive copywriting.

    Before writing a headline, complete a positioning brief. If your team cannot agree on the brief, polishing sentences will only conceal the disagreement.

    <!– wp:list {
  • How to Humanize LLM-Assisted Content With Better Research

    How to Humanize LLM-Assisted Content With Better Research

    You have an LLM draft that is clean, complete, and strangely forgettable. Changing a few phrases, adding contractions, or asking the model to sound more human will not fix it. The draft feels generic because it has had no meaningful contact with the customers, experts, and market conditions it claims to understand.

    Humanizing LLM-assisted content is a research problem before it is a writing problem. Give the model grounded evidence to organize, keep human judgment in charge of what matters, and make every important claim traceable. You will get content that is more useful because it contains real distinctions, not because it performs a more casual personality.

    Human content starts with evidence, not tone

    A model can imitate a conversational register. It cannot create genuine customer evidence, expert experience, or market context that you did not provide. If the input consists of a keyword, a title, and competing search results, the output will usually recombine the same category-level ideas available to everyone else.

    The useful advantage of an LLM is its ability to process large collections of feedback and surface recurring patterns. That makes it a capable research assistant, but it does not transfer editorial responsibility to the model.

    Separate the work into three roles:

    • Evidence: Customers, subject matter experts, product records, search queries, reviews, and other observable material supply the facts and language.
    • Analysis: The LLM groups related observations, identifies contrasts, proposes questions, and helps you inspect a large body of material.
    • Judgment: A person decides which patterns are meaningful, which claims are sufficiently supported, what exceptions matter, and what the reader should do.

    This separation prevents a common failure: letting polished prose disguise a weak evidence base. A confident paragraph is not proof that the underlying pattern is real.

    Before drafting, build a compact evidence brief. For each potential section, record the reader question, the proposed answer, the supporting material, any contradiction, and the action the reader can take. If a proposed answer has no supporting material, label it as a gap. Do not ask the model to fill that gap with a plausible anecdote.

    Keep provenance attached to the material as it moves through the workflow. A customer comment should retain an anonymous record identifier. An expert claim should point back to the approved interview transcript. A competitor observation should retain the page, review, or posting that supports it. Provenance makes verification possible after the model has compressed many inputs into a neat theme.

    Build an auditable customer-language pipeline

    Two researchers trace color-coded evidence cards back to customer interview recordings, photographs, and product samples on an organized table.

    Customer feedback is where generic content often becomes specific. NPS responses, sales-call transcripts, support questions, Google Search Console queries, and on-site searches expose the words people use before your marketing language has shaped the conversation. Heatmaps and interaction data can help you locate friction, while qualitative comments can explain what the friction means to the person encountering it.

    Do not begin by dropping an unstructured archive into a chat and requesting insights. The resulting summary may look convincing, but it gives you little visibility into omitted records, faulty groupings, or unsupported counts. A more inspectable workflow involves using an LLM to generate SQL, running the queries separately, and supplying the query results for synthesis.

    1. Normalize the raw material. Store one response or interaction per record. Preserve the original wording and add only fields you can verify, such as channel, product area, or an anonymous record identifier.
    2. Define the question before querying. Ask something narrow enough to test, such as which objections appear in feedback about a specific feature, or which questions occur before a purchase decision.
    3. Use the LLM to draft the query. Supply the actual table and column names, describe the expected output, and instruct it not to invent fields. Treat the generated SQL as code that requires review.
    4. Run and validate the query outside the model. Inspect filters, joins, null handling, duplicated records, and representative rows. Compare the result with a small set you have already read.
    5. Give the verified result to the LLM. Ask it to group related responses, preserve contrary evidence, and attach anonymous record identifiers to every proposed theme.
    6. Iterate on the question. A broad theme such as ease of use is not yet an insight. Query the situations, tasks, and points of confusion hidden inside that label.

    A practical analysis prompt is: Group these verified records by the job the customer is trying to complete. For each theme, provide supporting record identifiers, conflicting records, the customer terms that recur, and one question we still cannot answer. Do not infer a motive unless the wording supports it.

    The instruction to preserve conflicting records matters. A model is naturally useful at compression, but compression can erase minority experiences and conditions that complicate the dominant theme. Those complications are often what make a page trustworthy. They let you say when advice works, when it does not, and who should choose a different path.

    Handle sensitive material before it reaches any LLM. Remove personal identifiers and confidential details, and use only tools and storage environments approved for the data involved. If you cannot confirm that a dataset may be processed in a particular system, work with a redacted extract or keep the analysis inside an approved environment.

    Your final customer-language output should not be a cloud of themes. Build a theme ledger containing the customer problem, the situation in which it occurs, the language customers use, supporting record identifiers, contradictions, and the content decision that follows. That final field forces analysis to become useful editorial direction.

    Interview experts without asking them to write the page

    A content strategist records an expert explaining and demonstrating a component at a workshop bench while a teammate documents the process.

    Subject matter experts are usually needed because the obvious answer is incomplete. They know the mechanism, the exception, the tradeoff, and the mistake that only becomes visible in practice. Asking them to write a polished explanation creates unnecessary work and often delays the content.

    Use an LLM as the interviewer, not as a substitute for the expert. A reusable interviewer can be configured around a clear role, context, interview structure, pacing, and closing summary. The expert can answer in fragments or plain language while the system handles follow-up questions and organization.

    Give the interviewer these instructions:

    • Role: Act as a curious editor who understands the product context but does not pretend to know the expert’s answer.
    • Objective: State what the final content must help the reader understand or decide.
    • Scope: Name the product, feature, service, or decision being discussed and list topics that are out of scope.
    • Pacing: Ask one question at a time. Follow an answer before moving to the next prepared topic.
    • Evidence discipline: Request concrete mechanisms, conditions, and examples, but never create an example on the expert’s behalf.
    • Closing: Summarize the claims, unresolved questions, and statements that require verification or approval.

    Do not open with an invitation to explain everything about the subject. Start with the decision the reader faces, then move down an interview ladder:

    1. What does the reader usually misunderstand at this point?
    2. What actually happens, and what causes it?
    3. Which conditions change the answer?
    4. What is the most common avoidable mistake?
    5. What tradeoff should the reader understand before choosing?
    6. What would you need to see before recommending a different approach?

    Each answer should shape the next question. If the expert says a result depends on implementation quality, the interviewer should ask what quality means in observable terms. If the expert describes a common mistake, it should ask why people make it and how a reader can notice it early. This is where an interview produces material that a generic drafting prompt cannot.

    After the interview, ask the LLM to create a claim sheet rather than a finished draft. Each row or bullet should include the claim, supporting transcript passage, relevant condition, uncertainty, and verification status. Send that condensed sheet to the expert for correction. Approval of a short claim sheet is a clearer request than approval of a long page in which factual and stylistic decisions have already been mixed together.

    Only then should the transcript feed the drafting process. Instruct the model to distinguish direct expert knowledge from editorial inference. If the expert did not provide a metric, example, or causal explanation, the draft must not manufacture one to make the section feel complete.

    Use competitor research to find the missing angle

    Competitor research is useful when it reveals the boundaries of the category conversation. It becomes destructive when it is used as a template for another version of the same page.

    Different public signals answer different questions. Reviews, changing web copy, job postings, and social engagement can expose customer frustrations, positioning choices, strategic priorities, and unmet demand. None of these signals should be treated as conclusive on its own.

    • Reviews: Extract repeated benefits, complaints, desired outcomes, and the circumstances behind unusually positive or negative experiences. Keep verified wording separate from your interpretation.
    • Current web copy: Record the audience being addressed, the promised outcome, the proof offered, and the tradeoffs left unmentioned.
    • Archived web copy: Use the Wayback Machine to notice how positioning and emphasis have changed. Treat the change as an observation, not proof of why the business made it.
    • Job postings: Note capabilities the company appears to be building. A posting may indicate an area of attention, but it does not prove that a strategy or product has shipped.
    • Social engagement: Read the comments and questions behind the engagement count. Activity alone does not tell you whether people are satisfied, confused, or objecting.

    Create a competitor evidence matrix with the same fields for every company: target audience, main claim, supporting proof, repeated customer concern, unanswered question, and evidence location. Consistent fields make cross-company patterns easier to inspect and reduce the chance that a vivid example dominates the analysis.

    Then ask the LLM: Compare these records without ranking the companies. Separate extracted evidence from inference. Identify claims repeated across the category, customer questions no company answers clearly, benefits with weak visible proof, and differences that may reflect distinct target audiences. Mark unknowns instead of resolving them.

    The output is not your content plan yet. Test each proposed gap against customer feedback and expert knowledge. A topic is not valuable merely because competitors have ignored it. It becomes a defensible angle when customers care about it, an expert can explain it, and your evidence supports an answer.

    Look for four kinds of useful angles: a customer question the category avoids, a tradeoff hidden behind a popular benefit, an exception that changes the standard recommendation, or a difference in audience that makes apparently conflicting advice both reasonable. These angles humanize content because they reflect actual decisions and tensions. They do not depend on decorative storytelling.

    Draft, verify, and edit for a recognizable point of view

    Once the evidence is organized, drafting becomes a constrained synthesis task. The model should transform approved material into a useful sequence without silently upgrading an observation into a fact or an inference into a customer quote.

    1. Define one reader and one decision. State what the reader is trying to do, what is blocking them, and what they should be able to decide after reading.
    2. Build an evidence outline. Give each section a question, direct answer, evidence identifiers, important exception, and practical next action.
    3. Draft only from the evidence pack. Permit ordinary transitions and explanation, but prohibit invented customers, quotations, tests, metrics, and firsthand experience.
    4. Expose missing support. Require a visible placeholder whenever the outline asks for a claim the supplied material cannot establish.
    5. Verify before polishing. Check every material claim against the raw record, transcript, query result, or competitor evidence location.
    6. Edit for judgment. Decide which point deserves emphasis, which caveat belongs beside the claim, and which recommendation follows from the evidence.

    An evidence-bound drafting prompt can be simple: Write for the defined reader using only the supplied evidence pack. Each section must answer its question directly, explain the mechanism or reason, preserve the stated conditions, and end with an action the reader can take. Keep evidence identifiers in the draft for review. If support is missing, insert [EVIDENCE GAP]. Do not invent a quote, metric, customer, test, or example.

    Run a humanization pass that can fail the draft

    Do not judge the result by asking whether it sounds human. Use tests with observable failure conditions:

    • The substitution test: Could a competitor publish the section unchanged? If so, add a supported distinction or remove the generic section.
    • The provenance test: Can an editor reach the underlying evidence for every consequential claim? If not, qualify, verify, or delete the claim.
    • The contradiction test: Does the draft preserve evidence that complicates the dominant pattern? If not, restore the relevant condition or exception.
    • The customer-language test: Does the page use the terms customers use for their problem while explaining any necessary technical vocabulary? If not, return to the feedback records.
    • The expert-value test: Does the page contain a mechanism, tradeoff, or boundary condition that required genuine expertise? If not, the interview stayed too shallow.
    • The action test: After each section, can the reader do, decide, or notice something specific? If not, the section is probably commentary rather than guidance.

    Remove evidence identifiers only after verification. Then tighten repetition, vary sentence length where it improves clarity, and replace internal terminology with reader language. Do not add fake quirks, staged vulnerability, or imaginary personal stories. A recognizable editorial voice comes from consistent judgment: what you prioritize, what you refuse to overclaim, and how clearly you explain the tradeoff.

    This also supports SEO, AEO, and GEO work without turning the page into machine-facing copy. Put the direct answer near the question, use descriptive headings, name entities precisely, keep qualifications beside the claims they limit, and cite the evidence that carries the factual load. Structured data can describe visible content, but it cannot supply the missing expertise or originality. No formatting choice guarantees search or LLM visibility.

    Key takeaways

    • Humanize the evidence before polishing the prose: use real customer language, expert judgment, and observable market signals.
    • Keep raw data and query execution outside the LLM when you need inspectable counts, filters, and records.
    • Use an LLM to interview experts and organize their answers, never to impersonate their knowledge.
    • Treat competitor material as evidence of category patterns and unanswered questions, not as a draft template.
    • Require provenance, contradictions, conditions, and evidence-gap labels throughout synthesis.
    • Reject any section that a competitor could publish unchanged or that leaves the reader without a concrete next action.

    Take the next generic draft you planned to polish and pause it. Build an evidence brief for its most important claim, verify that material, and rewrite only that section. The difference will show you where research deserves more of the workflow than prompting does.

    References