Tag: AI-generated Content

  • Google DeepMind Nano Banana Pro: A Marketer’s Workflow

    Google DeepMind Nano Banana Pro: A Marketer’s Workflow

    If your team can already make one attractive AI image, the harder problem is repeatability. Can the same product, character, visual hierarchy, and approved copy survive the next ten versions without a cleanup cycle wiping out the time you saved?

    Google DeepMind’s Nano Banana Pro is relevant because it brings stronger reasoning, multi-reference consistency, text rendering, and targeted editing into one image workflow. Its value, however, depends less on the first impressive render than on how you brief, review, publish, and test the resulting assets.

    Decide whether the job matches Nano Banana Pro

    Nano Banana Pro builds on the original Nano Banana and combines image generation and editing with Gemini 3 Pro’s reasoning capabilities. That combination is designed for more controlled production work, not merely open-ended image prompting.

    Those capabilities make Nano Banana Pro a strong candidate when your bottleneck is controlled variation: adapting one approved concept into new layouts, markets, scenes, or campaign treatments. It is less convincing as an unsupervised authority for exact logos, prices, measurements, product claims, or factual diagrams. Those elements still need deterministic files, approved copy, and human sign-off.

    Access should also be treated as product-dependent. The rollout was described as progressive across Google’s platforms, while image-generation enhancements were made available in Google Ads. Confirm that the surface your team intends to use actually provides the required controls before you redesign a production process around it.

    Build a controlled brief, not a clever prompt
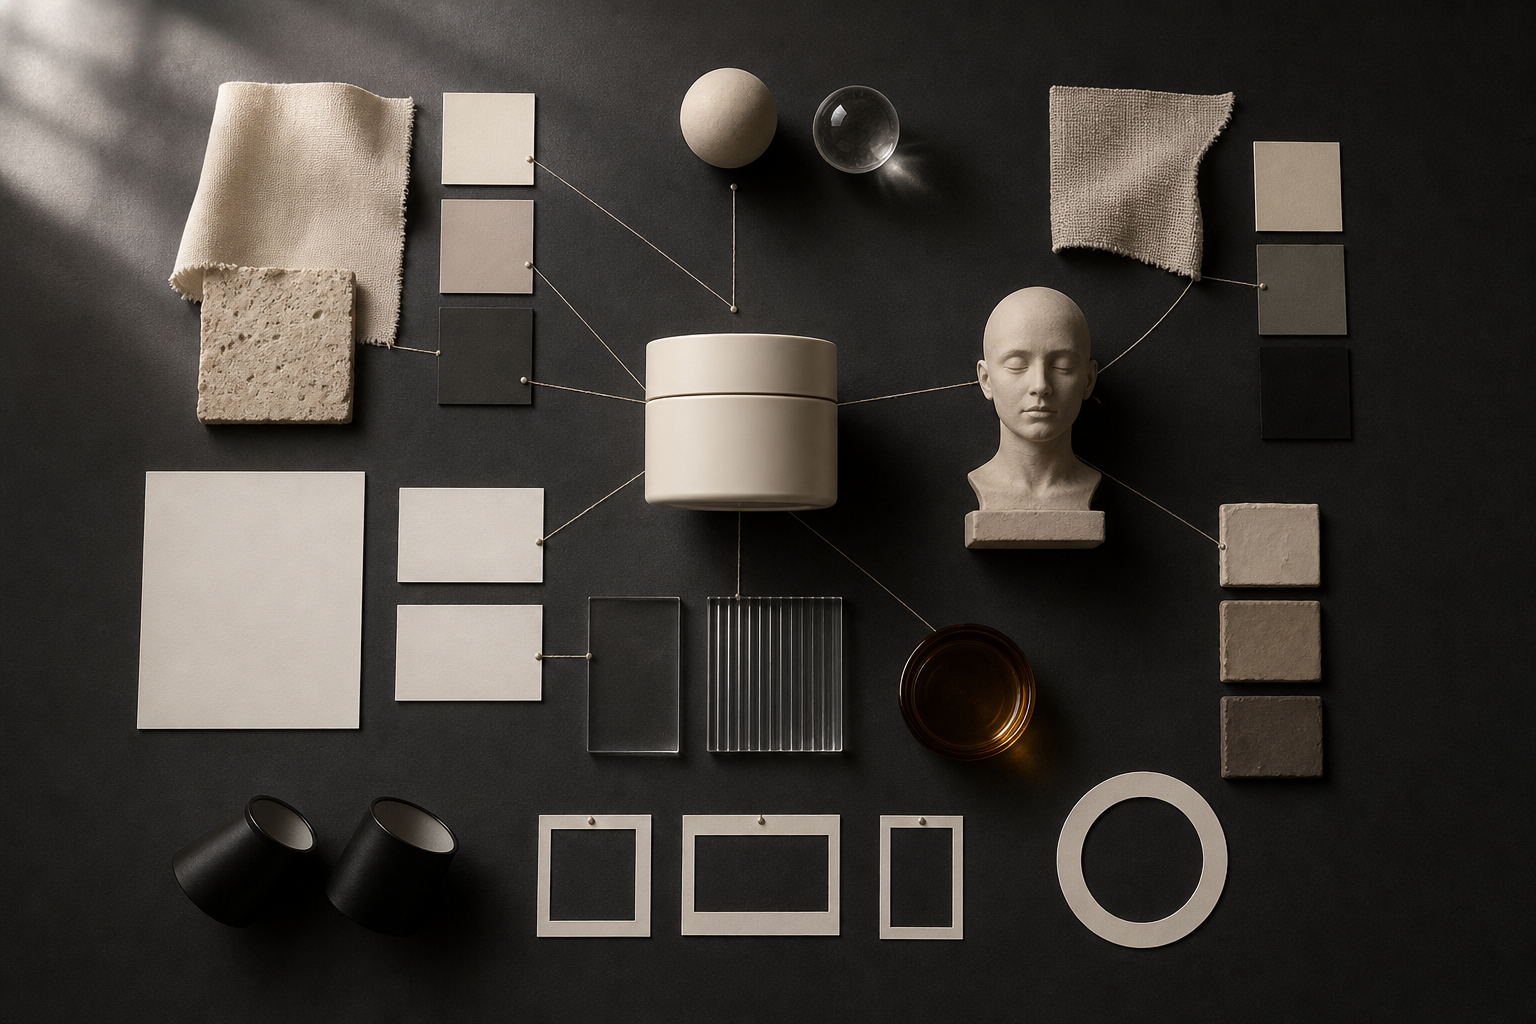
    An overhead workspace shows an unbranded product, character model, color swatches, material samples, and blank composition cards arranged as a controlled visual brief.

    A clever sentence may produce an interesting image. It rarely produces a dependable asset system. For repeatable work, separate the business objective, reference material, fixed constraints, creative variables, and approval criteria.

    1. Define the asset’s job. State where the image will appear, who it is for, what it must communicate, and what action it supports. A product-page hero, paid-ad variant, visual explainer, and storyboard frame need different compositions even when they share a subject.
    2. Curate the reference set. Nano Banana Pro can work across up to 14 inputs, but that is a ceiling rather than a target. Include only references with a clear role, then label each role: product geometry, character appearance, palette, environment, lighting, typography direction, or composition.
    3. List the non-negotiables. Specify what must remain unchanged, such as product proportions, wardrobe, brand colors, approved terminology, packaging structure, or the number and position of objects. Do not hide these requirements inside a long mood description.
    4. Separate creative variables. Name the elements that may change: background, camera angle, lighting, crop, season, supporting props, or emotional tone. This gives the model room to work without making every part of the asset unstable.
    5. Supply approved on-image copy. Put every required word in a dedicated field, including capitalization, punctuation, language, and desired line breaks. Multilingual rendering is useful only after a qualified reviewer has approved the translation itself.
    6. Describe the composition explicitly. Identify the focal subject, foreground and background relationship, viewing angle, negative space, intended crop, lighting direction, color treatment, and required aspect ratio. Terms such as premium or cinematic are too broad unless you explain what they mean visually.
    7. Approve one master before making variants. Resolve product shape, character continuity, hierarchy, copy, and overall art direction in a master image. Only then use localized edits and detailed visual controls to create derivatives.
    8. Record what produced the approved result. Save the references, prompt, approved copy, output, requested edits, intended channel, and reviewer decisions together. Without that record, the next campaign starts as another guessing exercise.

    A reusable Nano Banana Pro brief

    You can turn the workflow into a short production template. Replace each instruction with project-specific language:

    • Objective: Create an image for a named page, campaign, or presentation and state the decision or action it should support.
    • Reference roles: Input 1 controls product shape; input 2 controls palette; input 3 controls character appearance; input 4 controls composition.
    • Must preserve: List the objects, proportions, colors, expressions, terminology, and layout relationships that cannot change.
    • Scene and treatment: Define environment, camera position, focal length in plain visual terms, lighting direction, depth, color balance, and mood.
    • Exact copy: Provide the approved words, language, capitalization, punctuation, and hierarchy. Instruct the system not to add other text.
    • Output: State the required aspect ratio, placement of negative space, and any crop-safe area your channel needs.
    • Edit rule: Preserve every approved element and change only the named variable in each revision.

    The edit rule is especially important. Instead of asking for a better version, request a defined delta: keep the subject, pose, product, copy, palette, and framing unchanged; adjust only the background lighting. A narrow instruction gives you a result that is easier to compare and approve.

    Review the image like a production asset
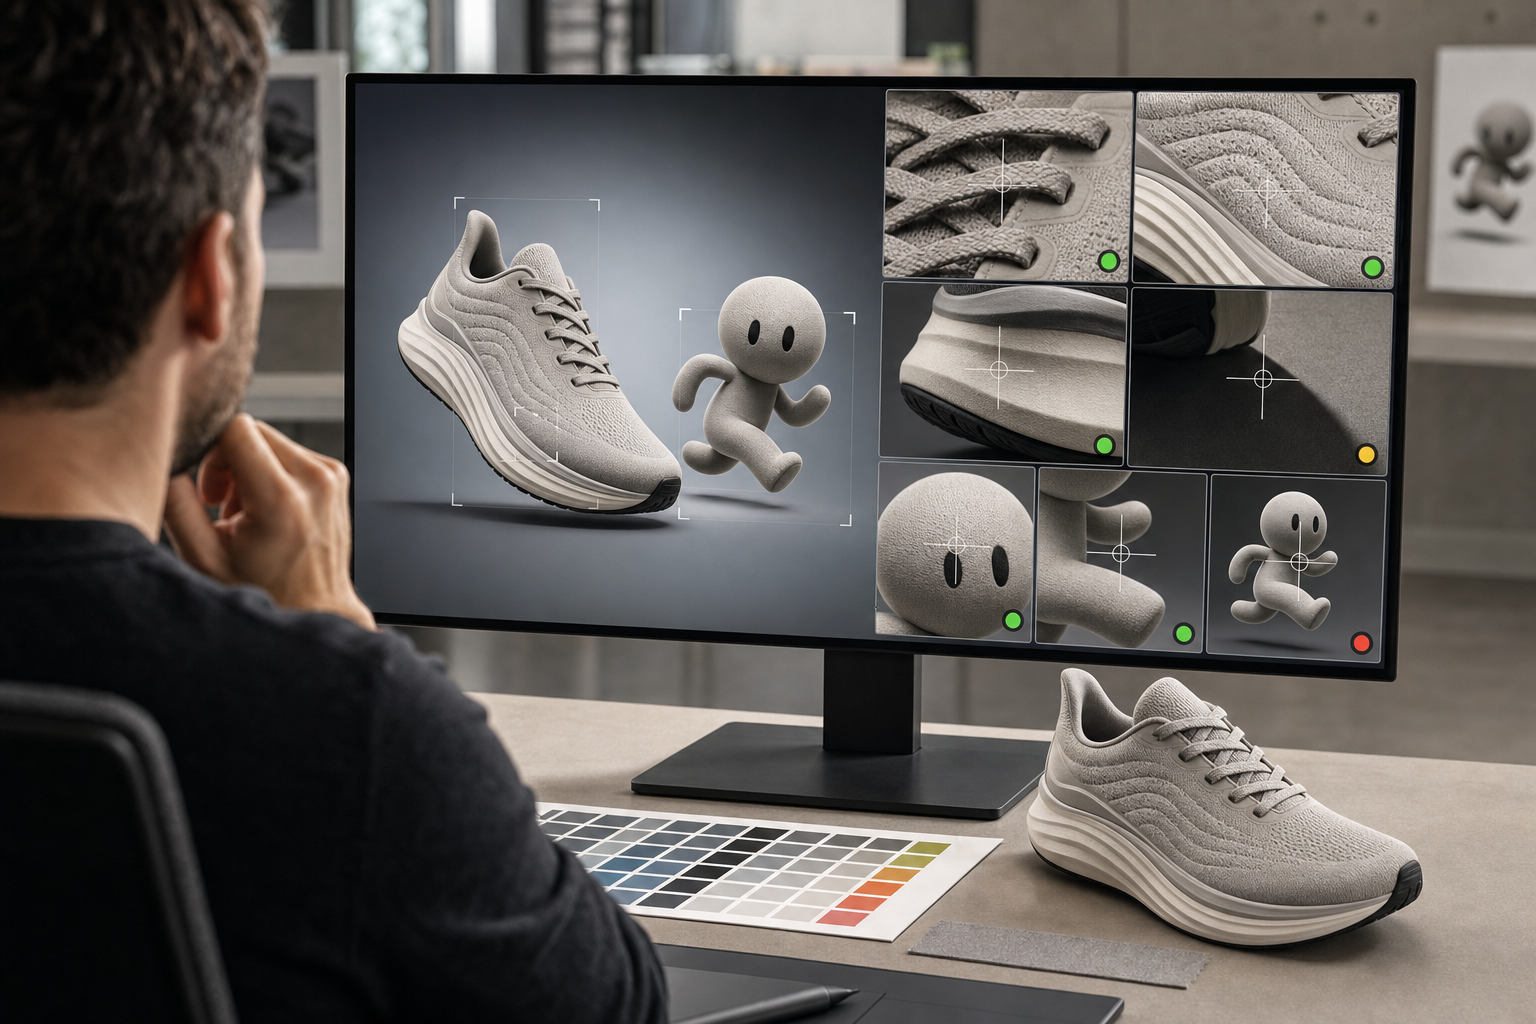
    A reviewer compares an unbranded running shoe on a monitor with a physical sample while inspecting enlarged details, shadows, and materials.

    Rendering quality and correctness are different tests. Text may look polished while containing a substituted character. A product may remain recognizable while its controls, label, or proportions drift. Search-connected context may help the model build a scene, but it does not transfer responsibility for the scene’s claims to Google.

    • Check text character by character. Compare every word, numeral, unit, punctuation mark, and line break with the approved copy. Review the exported size as well as the large preview; small labels can fail only after resizing.
    • Review each language independently. Legibility does not prove that a translation is accurate, culturally appropriate, or compliant with your terminology. Give a fluent reviewer the copy and the rendered image, not the image alone.
    • Compare products and brand elements with their references. Inspect silhouettes, component count, labels, materials, colors, logo geometry, and relative scale. If exactness is mandatory, replace generated brand marks or copy with approved production assets.
    • Verify factual content against approved data. Recheck names, quantities, relationships, ingredients, annotations, and visualized facts. For an infographic, keep the underlying data and its provenance with the review record.
    • Inspect continuity across the set. Look beyond facial resemblance. Check clothing details, accessories, object placement, shadows, materials, and environmental logic from one image to the next.
    • Test the real crop. Preview every destination rather than assuming one output will adapt cleanly. Confirm that the focal subject, required copy, and important context remain visible wherever the image will appear.
    • Provide a text equivalent. If an image contains information needed to understand the page, repeat that information in HTML. Alt text should describe the image’s purpose in context, not become a list of target keywords.

    Assign ownership before review begins. A creative owner can approve composition and consistency, a subject or language owner can approve claims and copy, and a channel owner can approve crop, accessibility, and placement. A general request for everyone to check everything usually leaves the riskiest detail without a named decision-maker.

    If repeated local corrections begin changing previously approved areas, return to the master and regenerate the derivative from there. A chain of patched exports is harder to reproduce, audit, and update than one approved base with documented variations.

    Make each output useful to search systems and ad testing

    For SEO, AEO, and GEO content

    A generated image can explain an idea, establish context, or make a page easier to scan. It cannot replace the page’s evidence. If the answer exists only inside pixels, you make it harder for people using assistive technology and for systems that depend on accessible page text to interpret and cite the underlying information.

    • Place the image beside the passage it supports rather than treating it as detached decoration.
    • Repeat essential labels, claims, instructions, and data in visible HTML. For a detailed infographic, provide a compact text explanation or accessible transcript.
    • Write alt text around the image’s function on that page. Describe what a reader needs to understand; do not paste a keyword list or duplicate a long caption.
    • Add a caption when the visual needs a title, data context, methodology note, or explanation that would be awkward in alt text.
    • Use consistent names for products, entities, and concepts in the image, heading, body copy, and metadata. Visual creativity should not introduce new terminology for the same thing.
    • Where the page’s existing schema type supports an image property, connect it to the final image URL and keep the structured description aligned with the visible page. JSON-LD expresses a relationship; it does not verify that a generated claim is true.

    This distinction matters for Search-connected generation. Real-world context can accelerate visual creation, but it is not a citation or a provenance record. Keep the factual basis of the image visible, inspectable, and consistent with the surrounding content.

    For Google Ads and campaign experiments

    Nano Banana Pro’s availability through Google Ads can reduce the handoff between asset creation and campaign setup. That convenience does not demonstrate that an image will improve performance. Treat every generated variation as a creative hypothesis.

    • Start with one approved master so visual differences are intentional rather than accidental.
    • Change one meaningful variable per test, such as background context, camera angle, product emphasis, or lighting treatment.
    • Keep the offer, audience, landing experience, and other campaign conditions stable when you need to learn whether the visual caused the difference.
    • Choose the decision metric before launching. A higher click-through rate may be useful, but it should not justify broader spend if the campaign’s actual conversion or cost objective deteriorates.
    • Name and archive variants by the changed variable. Labels such as blue-background or close-product-crop are more useful than final-7.
    • Do not increase spend merely because a generated asset looks more polished. Use your normal budget controls until performance against the campaign objective supports the change.

    The production advantage is the ability to explore more controlled variations without rebuilding every asset manually. The measurement advantage appears only when those variations remain controlled enough to teach you something.

    Key takeaways

    • Nano Banana Pro is most useful for constrained visual production: consistent references, exact copy requirements, localized edits, and planned variants.
    • Although it can work across as many as 14 inputs, use only the references that have a defined role in the output.
    • Approve one master before creating derivatives, and request one explicit change at a time.
    • Readable multilingual text, Search-connected context, and polished rendering still require language, factual, product, and brand review.
    • For search content, keep essential information in HTML and align the image with visible copy, alt text, captions, and applicable structured data.
    • For advertising, evaluate generated variants through controlled tests rather than assuming faster production or better-looking creative will improve results.

    Start with one existing asset that already creates expensive variation work. Define what must stay fixed, choose one variable, produce and approve a master, then run a small controlled test. If Nano Banana Pro preserves the constraints and makes the next version easier to reproduce, it belongs in the production workflow. If it cannot, keep it upstream as a concept and storyboard tool.
    References

  • Google Content Quality: A Publisher Accountability Framework

    Google Content Quality: A Publisher Accountability Framework

    If you approve sponsored pages, let partners contribute content, publish at AI speed, or operate an acquired domain, your quality risk starts before anyone writes the copy. It starts with why the page exists, why it belongs on your site, and who is answerable for it.

    A polished page can still be vulnerable when its main purpose is to borrow a trusted domain’s ranking signals for an unrelated query. A byline, disclosure, or human edit doesn’t automatically fix that mismatch. You need a publishing system that can distinguish legitimate monetization from reputation exploitation before the distinction is made for you.

    Quality is a publishing-system decision, not a copy score

    Google’s site reputation abuse policy targets content that uses an established site’s reputation to gain search visibility it would struggle to earn on its own. The policy was introduced in March 2024 and refreshed in November 2024. The later clarification matters: involvement or oversight by the host publisher doesn’t necessarily resolve the problem if exploiting the host’s ranking signals remains the main purpose.

    That makes readability a weak proxy for safety. An accurate, well-edited page can still have a reputation-abuse problem. A poorly written page can be low quality without being reputation abuse. A sponsored page can provide genuine audience value, but its commercial label alone tells you neither whether it belongs nor whether it deserves search visibility.

    The practical question is not merely, Is this content good? Ask, Why is this content being published here? That forces you to inspect audience fit, editorial value, commercial intent, operational control, and dependence on the host site’s authority.

    Publisher accountability and platform accountability must also remain separate. A reported European Commission investigation was being prepared under the Digital Markets Act around allegations that Google’s enforcement disadvantages news publishers that rely on promotional or sponsored content. Those allegations do not establish that every affected page was legitimate, or that every enforcement action was wrong. They do show why publishers need defensible practices while platforms need clear, consistent boundaries.

    Key takeaways

    • Judge content by its purpose, audience fit, and added value, not by polish alone.
    • Sponsored, affiliate, partner, and white-label content need explicit ownership and the same factual standards as editorial work.
    • Human review and disclosure are controls, not automatic exemptions from reputation-abuse concerns.
    • AI scale and acquired-domain history create different risks, so audit them separately.
    • Keep a decision record for commercially sensitive content so you can explain why it belongs, who approved it, and what evidence supports it.

    Run a purpose test before revenue content enters production

    The cheapest time to reject a risky page is before a partner brief, keyword list, or AI prompt becomes a finished asset. Add a purpose gate to intake and make the requester answer the following questions in writing.

    1. Does the topic match the audience promise? A regular reader should understand why this subject appears under your brand. Domain fit is an internal governance test here, not a claim that Google publishes a numerical relevance threshold.
    2. Would you still publish it without the site’s existing search reputation? This counterfactual exposes pages whose business case depends almost entirely on borrowed visibility. It is a diagnostic question, not an official safe harbor.
    3. What value does the publisher add? Identify the reporting, analysis, expert judgment, original data, useful tool, or editorial transformation that would disappear if the page were moved to a generic host.
    4. Who selected the topic and target query? Record whether the idea came from your newsroom, an advertiser, an affiliate team, a lead-generation partner, or an outside vendor. The origin does not decide quality by itself, but hidden control makes accountability impossible.
    5. Can the commercial relationship be understood immediately? State who funded, commissioned, supplied, or benefits from the content. Disclosure protects reader understanding, though it does not repair weak relevance or unsupported claims.
    6. Who has final authority? Name the person who can demand evidence, reject the draft, correct it after publication, or remove it even when doing so conflicts with a revenue commitment.
    7. Is the page part of a broader pattern? A single defensible page can look different from a scaled directory targeting unrelated, lucrative queries. Review the program, vendor, template, and folder rather than approving each URL in isolation.

    No answer should operate as a standalone pass or fail. The strongest warning pattern is weak audience fit, little publisher-added value, and a business case that collapses without the host domain’s reputation. Better prose cannot solve that combination.

    Use the completed gate to choose an explicit outcome. Publish through the normal editorial workflow when the page serves the established audience and adds defensible value. Revise when the value is real but ownership, disclosure, evidence, or positioning is unclear. Decline or relocate the concept when the only persuasive reason to place it on the site is the site’s ability to rank.

    Do not reduce this decision to whether a page is sponsored. Advertising can support legitimate publishing. The accountability failure occurs when the commercial arrangement changes what gets published while obscuring who made the decision, what the reader receives, or why the content belongs on that property.

    Build an evidence trail into the editorial workflow

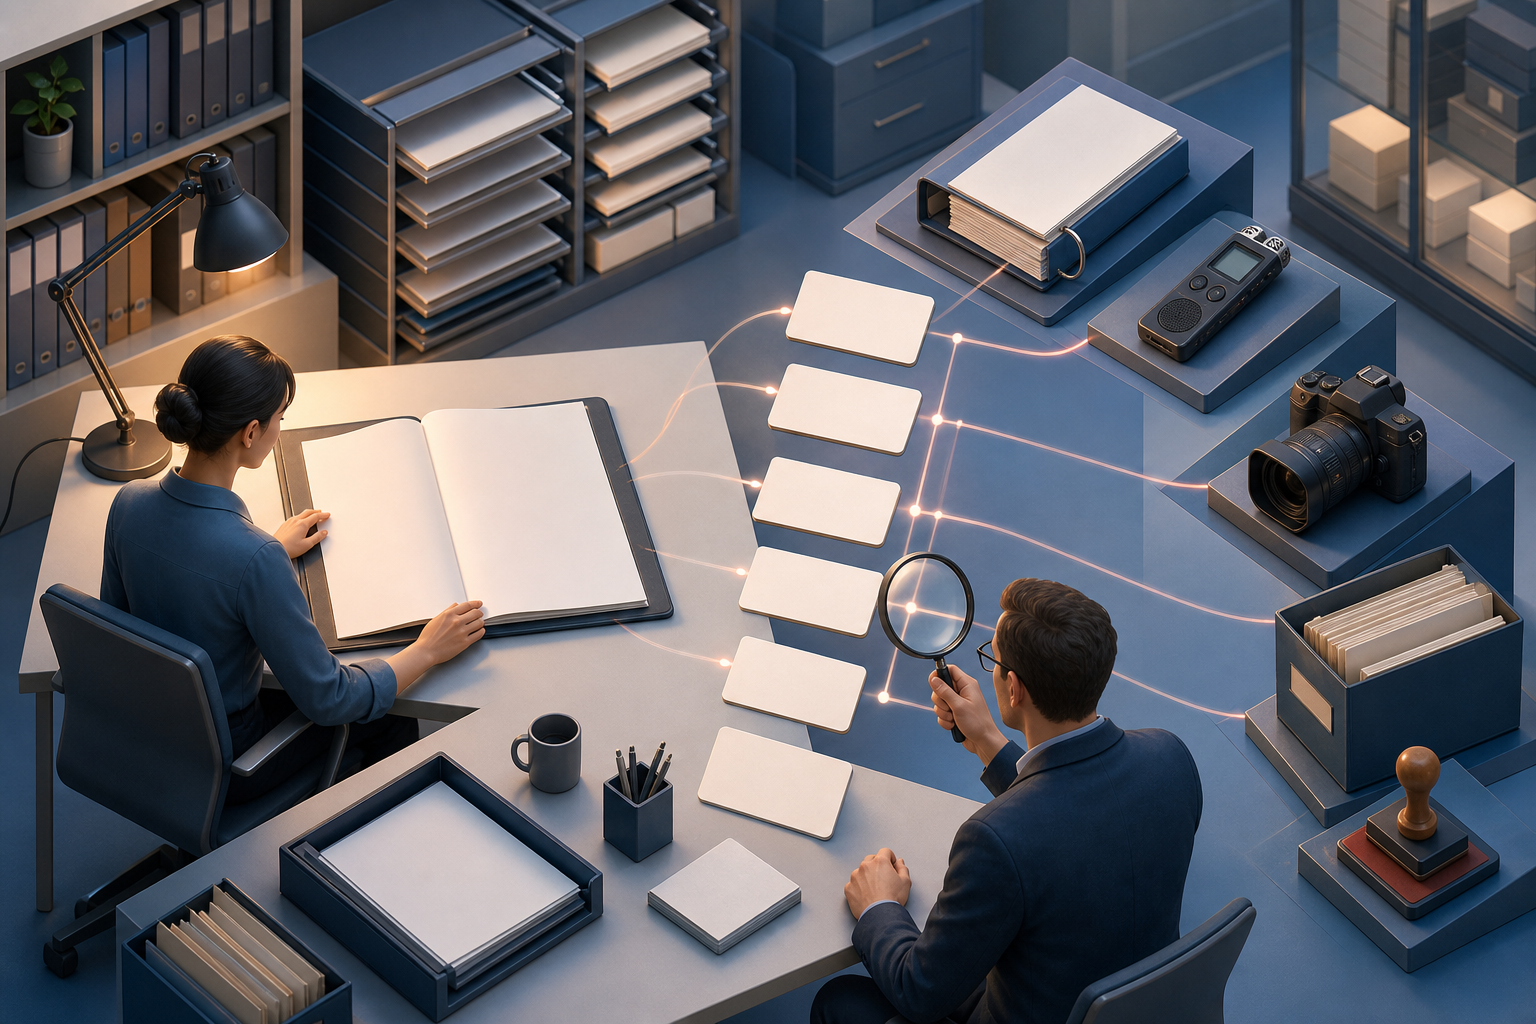
    An editor and reviewer trace blank content cards to source documents, an interview recorder, a camera, and approval records.

    A policy that lives in a slide deck will fail when a sales deadline, vendor backlog, or traffic opportunity arrives. Put the decision fields inside the workflow used to request, draft, approve, publish, update, and retire content.

    Every commercially sensitive or externally produced URL should have a release record containing:

    • the requesting team or partner;
    • the intended reader and the reader’s actual task;
    • a short explanation of why the topic belongs on the site;
    • the commercial arrangement and beneficiaries;
    • the publisher-added value;
    • the evidence checked for factual claims;
    • the use of AI, syndication, templates, or outside production;
    • the accountable editor and final approver;
    • the corrections contact; and
    • the condition that would trigger revision, deindexing, or removal.

    Separate contribution from publication authority. A partner may submit a draft, but that does not require giving the partner direct publishing access. An editor may improve style, but someone must also approve the claims, audience fit, and commercial framing. On a small team, one person may hold several roles; the decisions still cannot be anonymous.

    Review at the program level as well as the page level. Track live URLs by partner, author, directory, template, and business model. Flag pages with no active owner, unusual growth in output, repeated corrections, unresolved factual questions, or a commercial relationship that is missing from the visible page. These indicators tell you where to inspect; they should not be blended into a fictional universal quality score.

    Keep Search and Discover performance separate in reporting. A burst of distribution does not prove that a page is accurate, original, or aligned with your audience. Treat sudden success as a reason to inspect the production pattern, especially when it follows a new vendor, template, topic cluster, or domain acquisition.

    Structured data belongs to the same accountability system. JSON-LD should reflect the visible page and the real publishing relationship. It cannot turn a misleading page into a trustworthy one, and it should not identify an author, publisher, date, or content type that the reader cannot reconcile with what is on the page. Validate markup, but also verify that the entities and relationships represented by it are true.

    Corrections complete the loop. Give readers and staff a clear route to report an error, assign the report to an owner, record the decision, and update every place where the claim appears. If the same mistake repeats across a template or partner feed, fix the production mechanism rather than patching URLs one at a time.

    Control AI scale and inherited domain reputation separately

    AI-generated spam and acquired-domain abuse can appear together, but they fail in different ways. AI increases the speed and volume at which unsupported or fabricated claims can be published. An expired domain can provide the appearance of inherited trust even when its new subject, ownership, and editorial operation have little connection to the property people previously encountered.

    The distribution risk is not theoretical. Fake AI stories were documented receiving tens of millions of Google Discover views within a week. A database tracking the wider pattern had more than 8,300 French entries, alongside 300 English and 150 German entries. The suspected playbook included buying expired domains with previously trusted reputations and filling them with fabricated material.

    For AI-assisted production, make review capacity the constraint on output. A draft should not move directly from generation to publication. Require an accountable editor to inspect factual assertions, names, dates, quotations, links, and the relationship between the headline and body. Record what was checked and what changed. If the team cannot review the additional volume, reduce the volume rather than silently lowering the release standard.

    Set operational stop conditions. Pause a prompt, template, vendor, or automated workflow when errors repeat, corrections begin clustering, supporting evidence cannot be located, or pages are shipping without assigned reviewers. A halt should apply to the mechanism producing the risk, not merely to the latest URL caught with an error.

    For an acquired or expired domain, complete a separate due-diligence record before publishing at scale:

    • Document the domain’s former topic, audience, ownership, and publishing identity.
    • Map legacy URLs and redirects, especially those receiving links or visits for a subject the new operation no longer covers.
    • Identify whether the new business plan depends on preserving signals from unrelated historical content.
    • Do not redirect unrelated legacy URLs wholesale to new commercial pages merely to retain visibility.
    • Review sudden changes in topic, publishing volume, authorship, templates, and monetization as one combined pattern.
    • Keep access, ownership, and security records so an unexplained publishing change can be investigated quickly.

    Google said its systems keep most spam out of Discover while acknowledging that a more specific fix was being developed for the reported fake-AI pattern. That is a useful warning for publishers: enforcement can lag a new tactic on a particular surface. Your controls must protect readers even during that gap; temporary distribution is not evidence that the tactic is acceptable.

    Respond to a visibility change without destroying good content

    A publishing team inspects and sorts modular web-page tiles while preserving healthy pages and isolating others for review or repair.

    When traffic drops, broad panic edits can erase evidence and damage pages that were not part of the problem. Find the boundary first. Your goal is to identify the shared production decision behind affected URLs, not to rewrite every headline on the site.

    1. Locate the affected surface. Separate ordinary Search from Discover, then compare directories, templates, content types, authors, partners, publication periods, and commercial models.
    2. Map the pattern. Review affected and unaffected pages from the same workflow. That comparison helps distinguish a program-level issue from a weak individual URL.
    3. Freeze the implicated mechanism. Pause new output from the relevant partner, prompt, template, or directory while you inspect it. Preserve briefs, drafts, approvals, change histories, and access logs.
    4. Classify the failure. Decide whether the main problem is factual accuracy, absent editorial value, audience mismatch, hidden commercial control, scaled off-topic publishing, or reliance on an acquired domain’s former reputation.
    5. Choose the remedy that matches the cause. Correct demonstrable errors, add missing value where the topic legitimately belongs, clarify real relationships, consolidate duplication, or remove content whose purpose cannot be defended. Cosmetic rewrites will not fix a purpose problem.
    6. Repair the workflow. Change permissions, intake requirements, review ownership, vendor terms, prompts, templates, or monitoring so the same mechanism cannot immediately recreate the pages you just addressed.

    Keep the evidence even when the platform gives you little explanation. For every disputed group of pages, you should be able to show its intended audience, commissioning path, commercial relationship, factual support, editorial contribution, accountable owner, and corrective action. That packet is useful for internal decisions whether or not it produces a platform remedy.

    Google still carries responsibility for defining its boundaries, applying them consistently, addressing false positives, and distinguishing manipulation from ordinary publishing models. The reported European scrutiny is important precisely because legitimate publisher revenue and search-quality enforcement can collide. Publisher governance does not settle that dispute, but it prevents a weak internal process from becoming the only available explanation.

    Before your next partner campaign or AI-scaled batch goes live, audit the directory with the clearest mismatch between site audience and commercial topic. Give each page an owner and a written purpose. Pause anything that cannot explain both why it belongs and what your publication adds. That is a manageable change, and it moves quality accountability to the point where you can still act.

    References

  • Google Opal for Scalable AI Content Without Scaled Spam

    Google Opal for Scalable AI Content Without Scaled Spam

    Your bottleneck is not generating another draft. It is knowing whether the next draft deserves to exist. Google Opal can widen production quickly, but the same speed that helps a campaign can also multiply weak claims, overlapping pages, and editorial work.

    If you are deciding whether to use Opal at scale, build the controls before the volume. The safest operating model has three parts: one governed fact base, one clear job for every asset, and a human release decision for every publishable URL.

    Scale the production system, not the number of URLs

    Opal can turn a single product concept into blog posts, social captions, and video advertising scripts. That one-to-many pattern can be useful because each channel asks the content to do a different job.

    A blog post might answer a buyer’s question in detail. A social caption might introduce the idea to someone who was not looking for it. A video script might demonstrate the product or frame the problem visually. The underlying facts can remain consistent while the format, depth, and immediate purpose change.

    The trouble starts when a team treats every generated variation as a new search page. Changing a keyword, location, audience label, or product name does not automatically create a new reason to publish. If the reader receives substantially the same answer, the outputs are variants of one asset rather than independent URLs.

    Google’s scaled content abuse policy is concerned with producing many pages mainly to influence rankings, especially when those pages are unoriginal and add little value. Generative AI used to manufacture large amounts of low-value content is one example of that risk. The presence of AI is not the decisive issue. The purpose and usefulness of the resulting pages are.

    Scale itself is not a verdict either. Google’s apparent acceptance of Reddit using AI to translate pages at scale illustrates the distinction: a transformation can expand access to existing information instead of manufacturing search inventory. That does not create blanket permission for automated publishing, but it shows why volume alone is the wrong test.

    Before opening Opal, make an output map. Give every proposed asset the following fields:

    • Audience: Who specifically needs this asset?
    • User task: What are they trying to understand, compare, decide, or complete?
    • Distinct value: What will they get here that is not already available on your existing page?
    • Format: Why is a blog post, landing page, caption, or video script the right container?
    • Destination: Will it become an indexable URL, update an existing URL, or live only in a distribution channel?
    • Owner: Who can approve, merge, revise, or reject it?

    If two rows have the same audience, task, evidence, answer, and destination, consolidate them before generation. That single check prevents a campaign plan from quietly becoming a doorway-page plan.

    Ground Opal in a reusable source packet

    An organized central source packet connects to several distinct content formats on a clean creative workspace.

    A product concept is enough to inspire copy, but it is not enough to govern factual content. When the input is vague, a fluent output can hide assumptions, omit necessary qualifiers, or turn a positioning idea into an unsupported claim.

    Build a source packet before you generate anything. This becomes the controlled factual layer shared by the article, social copy, scripts, and future updates. Include:

    • Approved facts: Product capabilities, limitations, compatibility details, terminology, and other statements the content may treat as true.
    • Claim provenance: The internal record, public evidence, subject-matter owner, or approved page supporting each important claim.
    • Entity names: The exact names of the company, product, feature, category, people, places, standards, and versions involved.
    • Prohibited claims: Comparisons, guarantees, performance statements, or implications the available evidence does not support.
    • Audience context: What the intended reader already knows, what decision they face, and what would make the answer useful.
    • Unique contribution: The explanation, example, method, data, opinion, or decision support that gives the asset a reason to exist.
    • Canonical relationship: Which page owns the main answer and how each derivative should refer back to it.
    • Next action: What the reader should be able to do after consuming the asset.

    The packet should also define how Opal handles missing information. A practical generation contract is: use supplied facts for specific claims, preserve every qualification, flag unsupported gaps, and never convert a creative suggestion into a factual assertion. Asking for a visible marker such as [NEEDS EVIDENCE] is more useful than letting a plausible sentence pass unnoticed.

    Have the workflow return a claim ledger with the draft. The ledger does not need to be elaborate. It should identify each verifiable assertion, the packet item supporting it, and any statement that still requires review. This turns fact-checking from a hunt through polished prose into a finite approval task.

    The source packet also gives you an update path. When a product fact changes, revise the controlled record first, identify the affected assets, and update them from the same approved information. Without that shared layer, every derivative becomes an independent copy that can drift away from the truth.

    Put human decisions at the points automation cannot judge

    A human editor operates decision gates along an automated content pipeline, approving one page and diverting uncertain items for review.

    Human review should not mean correcting punctuation after generation. A polished unsupported claim is still unsupported, and an elegant duplicate page is still a duplicate page. Reviewers need authority to decide whether an asset should exist at all.

    1. Intent gate: Before generation, confirm the asset serves a named user task. Reject briefs whose only purpose is covering another keyword variation.
    2. Claim gate: Compare the draft and claim ledger with the source packet. Remove or qualify anything that cannot be traced to approved information.
    3. Value gate: Identify the passage that makes this asset more useful than the canonical page or an existing competitor-independent answer. If that passage does not exist, merge or rework the draft.
    4. Editorial gate: Remove generic setup, repeated conclusions, false certainty, and transitions that merely restate headings. Make the answer direct enough that a reader does not have to excavate it.
    5. Release gate: Decide whether the output becomes an indexable page, an update to an existing page, a non-indexed campaign asset, or discarded material.

    Apply the full set of gates to every indexable URL. A social caption or advertising script may need a lighter structural review, but it still needs factual and brand approval because it draws from the same claims. A publishing template cannot absorb that responsibility; generated outputs can fail in different ways even when they share a prompt.

    Where possible, separate generation from final approval. The person accountable for throughput will naturally see usable material in an almost-finished draft. An approver accountable for accuracy, usefulness, and site quality has a different incentive and can stop unnecessary pages before they enter the index.

    Measure the workflow by accepted assets and resolved user tasks, not raw drafts. Draft count rewards regeneration. Published URL count rewards fragmentation. A useful operating record instead tracks why an asset was accepted, merged, revised, or rejected. Those decisions reveal whether Opal is removing production friction or simply moving the bottleneck into review.

    Make useful content legible to search and AI systems

    SEO, AEO, and GEO work cannot manufacture value after generation. They can make existing value easier for search engines and language models to identify, extract, and connect to the right entity or question. Treat optimization as a clarity layer.

    • Answer the primary question near the start instead of delaying it behind a generic introduction.
    • Use headings that describe real decisions, distinctions, risks, or steps rather than repeating broad keywords.
    • Name products, organizations, features, standards, and versions consistently so the subject does not shift across assets.
    • Keep qualifications next to the claims they limit. Do not hide them in a note at the bottom.
    • Link derivative assets to the page that owns the complete explanation, and update that canonical page when the core answer changes.
    • Use examples only when they illuminate the reader’s task. A generated example that adds no information is decoration, not evidence.
    • Add structured data only for information that is present and visible on the page. JSON-LD describes content; it cannot compensate for a thin or unsupported answer.
    • Use FAQ content only when distinct questions require distinct answers. Do not turn heading variations into artificial question-and-answer padding.

    Then run a release audit from the reader’s side. Ask:

    • Can we state the user’s task in one clear sentence?
    • Does the page deliver information, reasoning, or utility that its closest existing page does not?
    • Can every consequential claim be traced to the source packet?
    • Would the page still help someone who received the link if search rankings disappeared?
    • Does the title promise exactly what the body delivers?
    • Are product names, qualifiers, and conclusions consistent with the related captions and scripts?
    • Does any structured data match the visible page rather than an intended or generated version of it?
    • Are we publishing this URL because a person needs it, or because the workflow happened to produce it?

    The answers should lead to an explicit disposition. Publish an asset with a distinct job, grounded claims, and a complete answer. Merge an asset whose useful material belongs on an existing page. Rework one with a valid user task but inadequate evidence or differentiation. Keep a campaign variation out of the index when it serves distribution rather than search. Discard an output whose only remaining purpose is expanding keyword coverage.

    This is how one product concept can support a coherent content system: the canonical page owns the durable answer, channel assets adapt it for their environments, and the source packet keeps every expression aligned. Opal can accelerate the transformations without being allowed to decide that every transformation deserves a URL.

    Key takeaways

    • Use Google Opal to scale governed transformations across channels, not near-duplicate indexable pages.
    • Require a unique audience task and a distinct contribution before generating a new search asset.
    • Ground every output in a reusable source packet containing approved facts, prohibited claims, entity names, and provenance.
    • Make human review a publish, merge, rework, or reject decision rather than a copy-editing step.
    • Use SEO, AEO, GEO, internal links, and structured data to clarify genuine value, never to substitute for it.
    • Judge the system by accepted, useful assets and consistent claims rather than drafts produced or URLs published.

    Before your next Opal run, choose one product concept, build its source packet, and map each proposed output to a real user task. Generate the channel set only after that map survives review. Scale further when the workflow repeatedly produces assets your editors would choose to publish even without the pressure to produce more.

    References

  • How to Protect Brand Authenticity in AI-Assisted Content

    How to Protect Brand Authenticity in AI-Assisted Content

    You need to publish more useful content without turning your brand into a production line of polished, interchangeable pages. AI can remove hours of mechanical work, but it can also remove the judgment, specificity, and recognizable point of view that make your content worth choosing.

    The answer is not to keep AI out of the workflow. It is to decide where efficiency belongs, where a human must remain accountable, and what every page has to prove before you publish it.

    Content quality must serve the reader and the retrieval system

    AI is valuable because it can increase speed and automate repeatable work. The problem begins when a team treats faster production as evidence of better content.

    A page can be grammatically clean, keyword-aware, and structurally complete while still failing the reader. It may repeat familiar advice, hide the answer beneath an introduction, make claims it cannot support, or sound as though no identifiable organization chose the words.

    In the AI era, useful content has to pass several different tests:

    • Accuracy: Can you trace every meaningful factual claim to reliable evidence, and have you preserved any necessary limits or uncertainty?
    • Usefulness: Can the reader make a decision, complete a task, or notice a problem they would otherwise miss?
    • Specificity: Does the page explain the mechanism, constraint, sequence, example, or trade-off behind its advice?
    • Distinctiveness: Does it contain a judgment, method, explanation, or framing that reflects what your brand actually knows and believes?
    • Retrieval clarity: Can a relevant passage stand on its own when a search engine or answer system extracts it from the surrounding page?
    • Brand coherence: Do the vocabulary, promises, evidence standards, and level of certainty match the rest of your site?

    These tests catch different failures. Accurate but generic content is forgettable. Distinctive but unsupported content is risky. Search-ready content that reads like a machine-generated template may earn an impression without earning trust. A page is ready only when it is useful, supportable, recognizable, and easy to interpret.

    Keep human judgment where trust is created

    The safest division of labor is based on accountability, not on whether a task appears easy. Let AI transform approved material. Keep people responsible for deciding what is true, what matters, what the brand believes, and what the reader should do.

    AI is well suited to bounded transformations such as reorganizing notes, proposing outlines, generating headline alternatives, turning a long explanation into a checklist, identifying repeated language, and adapting an approved passage to another format. Those tasks have visible inputs and reviewable outputs.

    Human ownership matters most at the points where an error would change meaning or weaken trust:

    • Selecting the audience, search intent, and decision the page must support.
    • Choosing evidence and deciding which claims the evidence can genuinely carry.
    • Contributing subject expertise, exceptions, operational details, and a defensible point of view.
    • Setting the boundary between established fact, editorial judgment, inference, and uncertainty.
    • Approving promises about products, outcomes, customers, compliance, or performance.
    • Accepting final responsibility for the published page and its structured data.

    For claims that need proof, do not treat model memory as evidence. A fluent sentence can still be unsupported, overgeneralized, or detached from the conditions that made the original claim true.

    Give the model a content contract, not a loose prompt

    A prompt that asks for an authoritative SEO page leaves the important decisions unresolved. Before drafting, create a short content contract with fields an editor can inspect:

    • Reader situation: What has brought this person to the page, and what do they already understand?
    • Reader job: What should they be able to decide or do after reading?
    • Primary claim: What is the clearest answer you are prepared to defend?
    • Evidence packet: Which approved facts, documents, examples, and internal expertise may the draft use?
    • Brand position: What does your organization believe that a generic overview would not say?
    • Claim boundaries: What must not be asserted, implied, invented, or generalized?
    • Voice constraints: Which language patterns should appear, and which should be removed?
    • Retrieval target: Which question deserves a concise, self-contained answer within the page?
    • Next action: What useful step should the reader take, even if they never become a customer?

    Then run the work in an explicit sequence:

    1. A subject owner approves the reader job, primary claim, evidence, and brand position.
    2. AI proposes an outline in which every section resolves a distinct reader question.
    3. An editor removes sections that exist only to make the page look comprehensive.
    4. AI drafts from the approved contract and evidence packet.
    5. A factual pass checks claims, qualifiers, entity names, citations, and unsupported implications.
    6. A separate brand pass checks judgment, vocabulary, tone, repetition, and generic phrasing.
    7. An optimization pass improves headings, answer units, internal links, metadata, and relevant structured data without changing the approved meaning.
    8. A named human owner approves the visible content and machine-readable representation together.

    Separating the passes matters. If one reviewer tries to verify facts, improve voice, shorten sentences, and inspect schema at the same time, the visible polish can distract from a weak claim or an unhelpful answer.

    Turn brand voice into an editing system

    An editor adjusts an unlabeled instrument that turns plain gray tiles into varied designs with a consistent color palette and material style.

    Authenticity does not depend on a human typing every sentence. It comes from a consistent relationship between what your brand knows, what it believes, what it promises, and what it publishes. AI can help express that relationship, but it cannot invent it responsibly.

    Labels such as friendly, expert, bold, or conversational are too subjective to guide a draft. Replace them with observable editorial rules:

    • Beliefs: Record the principles that shape your recommendations. For example, visible content should answer the question before structured data describes the answer.
    • Audience contract: State what you owe the reader. This might include explaining constraints, separating evidence from opinion, and never hiding the practical answer behind a sales pitch.
    • Proof habits: Define when claims need links, examples, named entities, qualifications, or review by a subject expert.
    • Language choices: List preferred terminology, prohibited hype, acceptable contractions, sentence-length tendencies, and the technical terms that must remain precise.
    • Boundaries: Document claims the brand will not make, including guarantees, fabricated experience, invented customer stories, and unsupported comparisons.
    • Approved examples: Save real passages that demonstrate the voice and annotate why they work. A model needs patterns, not just adjectives.

    Consider the difference between a generic claim and an owned editorial position.

    Generic: AI is transforming content marketing and helping businesses improve efficiency.

    Owned: Use AI to compress mechanical work. Keep evidence selection, claim boundaries, and final judgment with an accountable editor.

    The second version is not stronger because it sounds more colorful. It makes a decision, draws a boundary, and tells the reader what to do differently. That is the material from which a recognizable brand voice is built.

    Use a swap test during editing: if a competitor could publish the paragraph unchanged, it probably lacks an owned insight. Do not add a slogan merely to make it sound branded. Add the missing judgment, mechanism, example, limitation, or operating rule.

    Also remove simulated experience. If your organization did not run a test, interview a customer, inspect an account, or observe a result, the draft must not imply that it did. Explain what you know and how you know it. Honest limits are part of brand voice.

    Make content easy for people and answer systems to use

    Optimization for AI search does not require stripping personality from the page. It requires making the important meaning easy to locate, interpret, and reuse without distortion.

    Build important sections as self-contained answer units:

    1. Use a heading that names the actual question or decision.
    2. Answer it in the opening sentence without forcing the reader through background first.
    3. Explain why the answer holds or how the mechanism works.
    4. Name the condition, exception, version, audience, or limitation that changes the advice.
    5. Give the reader a concrete next action.
    6. Link the words carrying an evidence-dependent claim, rather than attaching an unexplained list of links.

    The opening answer provides clarity. The mechanism and limitation provide trust. The recommended action is where brand judgment becomes visible. You can therefore write a passage that is both extractable and distinctly yours.

    Run a context test on each candidate answer unit. Copy the passage into a blank document and ask:

    • Is the subject named, or does the passage depend on a vague pronoun?
    • Can a reader tell whether the statement is a fact, recommendation, definition, or opinion?
    • Are material conditions and exceptions still present?
    • Does the passage identify the product, organization, feature, standard, or audience precisely?
    • Would the passage remain accurate if displayed without the preceding paragraph?

    If the answer unit fails outside its original context, revise the language rather than stuffing more keywords into it.

    Consistency also matters across the site. Use one canonical name for your organization, products, services, features, and authors. Explain genuine synonyms, but do not rotate terminology simply to create lexical variety. Unnecessary variation makes it harder for a person or system to determine whether two passages refer to the same entity.

    Apply the same discipline to JSON-LD and other structured data. Markup should represent the visible page accurately. It should not introduce credentials, ratings, offers, authorship, answers, or relationships that the reader cannot verify in the content. Schema can clarify a strong page; it cannot supply the substance the page is missing.

    Finally, use internal links to connect a concise answer with the deeper proof behind it. A summary page can resolve the immediate question, while a supporting page explains the method, terminology, evidence, or implementation. This creates a useful path for readers without forcing every page to become an exhaustive encyclopedia.

    Replace output metrics with a publish gate and feedback loop

    A circular track carries blank page-shaped objects through a human review station, with one sent back for revision and another released to waiting readers.

    Traditional quality metrics are not enough for AI-first content. Word count, production volume, grammar checks, and a passing optimization score can describe the artifact or workflow, but they cannot establish that the page is accurate, useful, distinctive, or trusted.

    A useful measurement system separates four kinds of signals:

    • Production signals: Track drafting time, approval loops, substantial rewrites, and where work repeatedly returns to an earlier stage. These reveal workflow efficiency, not content quality by themselves.
    • Integrity signals: Track unsupported-claim flags, citation gaps, correction requests, entity inconsistencies, and mismatches between visible content and structured data.
    • Brand signals: Track prohibited language, failed swap tests, unapproved promises, simulated experience, and sections that lack an identifiable editorial position.
    • Discovery signals: Where your tools can observe them, track the queries that surface the page, branded and non-branded visibility, citations or mentions in answer experiences, and referrals from AI interfaces.
    • Outcome signals: Match the page to its intended job, such as a completed setup, qualified inquiry, subscription, product comparison, or movement to a deeper supporting page.

    Read these signals together. Faster production accompanied by more factual corrections means the workflow moved effort downstream rather than removing it. Strong visibility with weak outcomes may indicate that the page answers the query but does not help with the decision behind it. Good engagement with repeated swap-test failures means the page may be useful while doing little to build brand recognition.

    A composite quality score can help you prioritize review, but it should not own the publishing decision. Use a simple editorial gate:

    • Block: A material claim lacks evidence, the page invents experience, a required limitation is missing, an entity is misrepresented, or structured data asserts something the visible page does not support.
    • Revise: The answer is buried, advice remains generic, sections repeat one another, the next action is unclear, or the language fails the brand’s documented rules.
    • Publish: The page answers a real reader need, important claims are supportable, brand judgment is visible, answer units survive the context test, and a named owner accepts responsibility.

    After publication, feed what you learn back into the system. Log corrections with their causes. Add strong and weak passages to the annotated voice examples. Update the content contract when reviewers keep fixing the same omission. Revisit important pages when the offer, evidence, entity information, or reader decision changes.

    Key takeaways

    • Use AI for bounded, reviewable transformations; keep people accountable for evidence, judgment, promises, and approval.
    • Define brand voice through beliefs, proof habits, language rules, boundaries, and annotated examples rather than vague tone adjectives.
    • Write self-contained answer units that give a direct answer, explain the mechanism, preserve limitations, and recommend a useful action.
    • Keep entity language, visible content, internal links, and structured data consistent.
    • Measure production efficiency separately from integrity, brand distinctiveness, discovery, and reader outcomes.
    • Block publication when a material claim, implied experience, or machine-readable assertion cannot be supported.

    Start with one commercially important page. Write its content contract, mark every evidence-dependent claim, run the swap and context tests, and compare its structured data with what a reader can actually see. The weaknesses you find will tell you exactly which rules your wider AI content workflow needs next.

    References