Tag: AI Automation

  • Google Ads AI Automation: A Practical Control Framework

    Google Ads AI Automation: A Practical Control Framework

    You are not choosing between manual Google Ads and a black box. You are deciding which decisions the system may make, what evidence it may use, and which mistakes it must never be allowed to make.

    If AI Max, journey-aware bidding, or demand-led budgeting is on your roadmap, build that control system before you enable more automation. The safest operating model is simple: let AI handle frequent, reversible decisions, while you keep firm boundaries around landing-page eligibility, business goals, spending, and measurement.

    Control has moved upstream of the individual decision

    Advertisers often judge control by counting settings: keywords, bids, URL rules, daily budgets, and exclusions. That worked when campaign management centered on direct instructions. AI-driven campaigns change the location of control. You increasingly govern the inputs and boundaries, while the system makes more of the execution decisions inside them.

    This is still control, but only when your inputs express the business clearly. A page feed full of loosely classified URLs is not a meaningful boundary. A conversion setup that treats every lead as equally valuable is not a meaningful objective. A flexible budget with no period-level ceiling is not a financial policy.

    Before automating a campaign decision, assign it to one of five layers:

    Control layerQuestion you must answerProper division of responsibility
    EligibilityWhich pages, products, locations, or offers may receive traffic?You define the allowed set; automation works only inside it.
    ObjectiveWhich measurable action represents progress, and which represents business value?You define and validate the signals; automation responds to them.
    EconomicsHow much may be spent, over what period, and for what return?You set the financial limits; automation allocates within them.
    ExecutionWhich eligible opportunity should receive the next unit of spend?Automation can make the high-frequency decision.
    EvidenceWhat would prove that automation improved the business outcome?You set the evaluation standard and decide whether to continue.

    The distinction matters because execution errors and policy errors have different consequences. A single imperfect bid may be recoverable. A campaign-wide permission to send traffic to the wrong section of a large site can waste money repeatedly. Keep direct controls where an error would be expensive, difficult to detect, or hard to reverse.

    Protect landing-page eligibility before activating AI Max
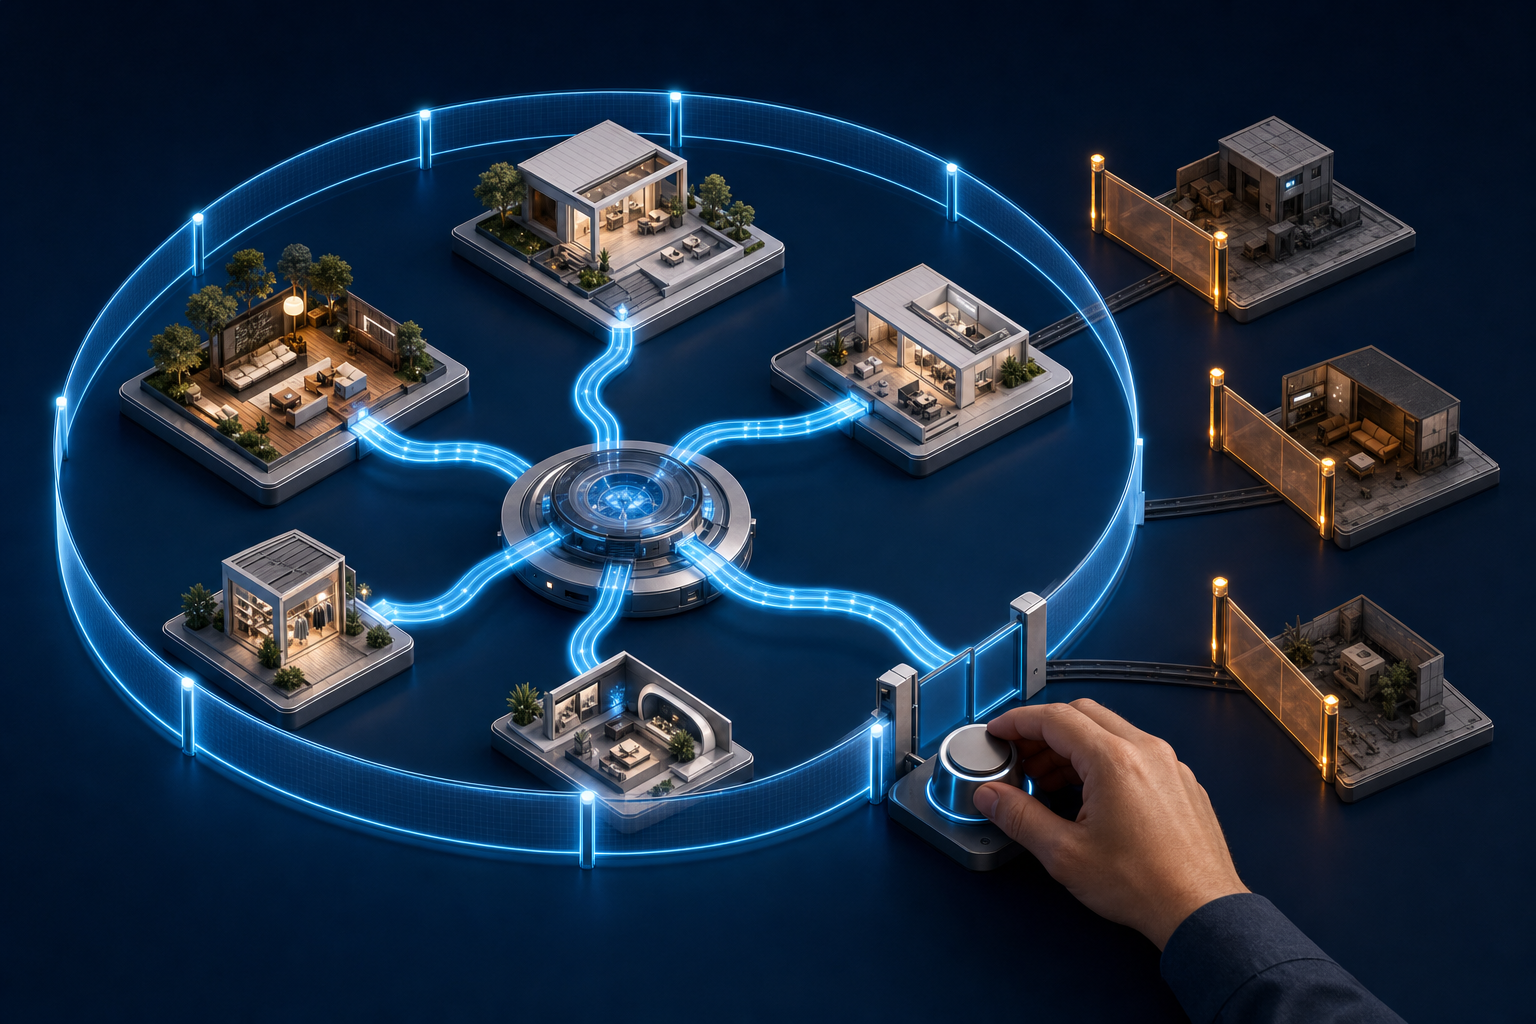
    Glowing traffic routes lead only to landing-page platforms enclosed by a transparent eligibility boundary, while other destinations remain behind closed gates.

    Landing-page control is the most immediate gap for teams moving from Dynamic Search Ads to AI Max. DSA could be arranged around categories, URL paths, and page rules that reflected a site’s architecture. AI Max does not reproduce every one of those targeting methods. In particular, the familiar “page contains” condition is not fully supported.

    That does not mean AI Max has no URL controls. It means you need to translate structural rules into explicit inventory inputs. Available mechanisms include URL rules and combinations, page feeds with custom labels, ad-group URL inclusions, and campaign-level exclusions.

    For a large or structured site, make that translation as a separate migration project:

    1. List the pages that are allowed to receive paid traffic. Do not begin with the whole index and remove bad pages later. Start with a deliberate eligible set. A mistaken exclusion can block useful demand, but an overly broad inclusion can repeatedly spend against irrelevant, unavailable, or low-value pages.
    2. Classify eligible pages with stable custom labels. Labels should describe business meaning such as product family, service line, region, margin group, lead type, or promotional eligibility. Avoid labels that merely repeat temporary campaign names; they become useless when the account structure changes.
    3. Use ad-group inclusions to create local relevance. An ad group should receive only the URL groups appropriate to its intent and offer. If every ad group can reach every eligible page, the page feed is an inventory list rather than a targeting control.
    4. Use campaign exclusions for non-negotiable boundaries. Apply them where a page class must not receive traffic from that campaign. Record the business reason for each exclusion so a future cleanup does not remove a safeguard that looks redundant.
    5. Check the resulting landing pages, not just the configuration. Review where real traffic lands and ask whether the page matches the user’s likely intent, presents the intended offer, and supports the conversion action used by bidding.

    Custom labels are the key design choice. A label such as “campaign-7” tells the system where a URL happened to be used. A label such as “enterprise-demo-eligible” states a policy. The second survives campaign reorganizations and gives you a reusable boundary for testing.

    Be especially cautious with migrated DSA rules. Unsupported rules may continue functioning as read-only legacy rules that cannot be edited. That makes them dependencies, not durable controls. Document what each one permits or blocks, then recreate the intended outcome with page feeds, labels, inclusions, or exclusions where possible. Do not build a new operating model around a setting you can no longer maintain.

    AI Max already applies an inventory-aware safeguard for out-of-stock items, but stock status is only one reason a page may be unsuitable. A page can be technically available while carrying the wrong offer, serving the wrong market, or producing poor downstream value. Keep your own eligibility model for those business distinctions.

    Google has also signalled future account-level exclusions based on page content and titles. Treat those as prospective capabilities until they are present and usable in your account. A planned control cannot protect current spend.

    Give automated bidding an optimization brief it can actually follow

    Automated bidding cannot infer the distinction between a convenient measurement event and a valuable business outcome. If your account reports both as equivalent conversions, the system receives permission to pursue whichever is easier to generate.

    That risk becomes more important as Google gives bidding a wider view of the customer journey. Journey-aware Bidding is a beta capability that can incorporate non-biddable conversions as additional journey context. More context can help only when the events are reliable and their roles are clear. An event should not be included merely because it is measurable.

    Write a conversion map before changing the bidding system. For each event, record:

    • What the user actually did.
    • Whether the event is a progress signal or the business outcome.
    • Whether it is recorded consistently across campaigns and devices.
    • Whether duplicates, spam, cancellations, or low-quality leads can inflate it.
    • Which team owns its definition and can explain a sudden change.
    • Whether the event’s value reflects the economics you want the campaign to pursue.

    Consider a campaign that records an inquiry form immediately but learns lead quality later. The form is useful journey evidence, but it is not automatically equivalent to a qualified opportunity or sale. If the system sees only form volume, it can improve the reported metric while sending the sales team more poor-fit leads. The automation is following the brief it received; the brief is the problem.

    Use three tests for every signal you expose to bidding:

    1. Interpretability: Can you describe the event in one sentence without vague terms such as “engagement” or “intent”?
    2. Stability: Would a tracking, form, or CRM change alter the event count without changing actual demand?
    3. Economic direction: If the system produced more of this event, would that usually move the business toward revenue, margin, retention, or another declared outcome?

    If an event fails one of those tests, repair or separate it before asking AI to use it. Adding an unreliable signal does not create a fuller customer journey. It creates a larger measurement surface for the bidding system to exploit unintentionally.

    Apply the same discipline to expansion features. Google reported that Smart Bidding Exploration produced 27% more unique converting users and has said the capability is expanding beyond Search into Performance Max and Shopping. Treat that figure as a vendor-reported result, not a profitability guarantee for your account. Unique converting users, conversion quality, revenue, and profit answer different questions.

    Your test should therefore have two scorecards. The platform scorecard can include conversion volume and unique converters. The business scorecard should use the downstream outcome that justifies the spend. Expansion earns a larger rollout only when both move in an acceptable direction.

    Automate budget pacing without outsourcing financial policy
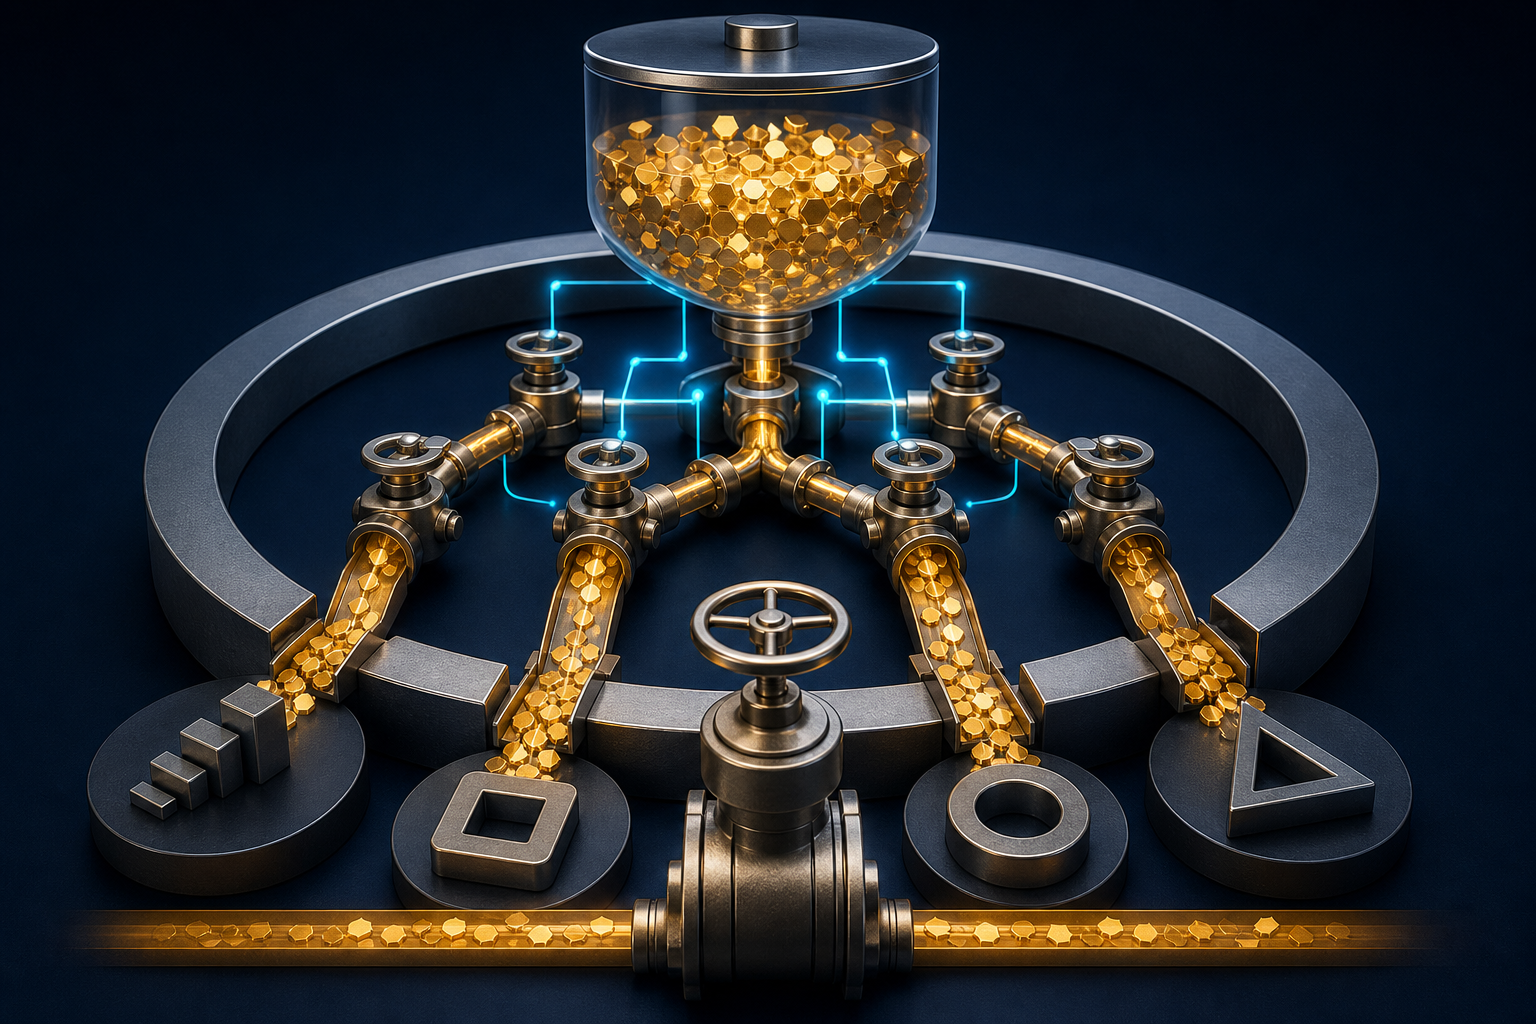
    A transparent reservoir distributes golden tokens through automated valves while a separate master gate limits the total flow.

    Demand-led budgeting changes when money is spent, not why the money is available. It can increase spend when the system detects stronger opportunity and conserve it when demand is weaker. Total budgets can also shift management away from repeated daily changes toward a defined spending period.

    That can remove genuine operational work. Advertisers using total budgets saw a Google-reported 66% reduction in manual budget adjustments. But fewer adjustments measure workload, not commercial success. A campaign can require less maintenance and still spend against low-quality conversions or an unsuitable product mix.

    Before enabling demand-responsive pacing, write down four constraints outside the campaign interface:

    • The hard period ceiling: the maximum amount the campaign is authorized to spend over the relevant period.
    • The unit-economics condition: the business result that must remain acceptable as spend increases.
    • The capacity condition: the inventory, fulfillment, sales, or service limit beyond which additional demand loses value.
    • The intervention condition: the specific measurement or business change that requires a human review, pause, or budget reduction.

    This matters because the system can respond to demand visible in the advertising environment, but it does not automatically know every private constraint in your business. If cash timing, fulfillment capacity, or lead-handling capacity cannot tolerate a high-spend day, flexible pacing creates financial exposure unless you constrain the period and monitor the limiting resource.

    Do not pool campaigns under one flexible budget merely because they share a channel. Keep materially different economics separate. A campaign optimized for immediate purchases and one optimized for leads with delayed qualification should not inherit the same scaling decision unless you can compare their downstream value on a consistent basis.

    Budget automation should be the last layer you expand, not the first. First confirm that eligible traffic reaches appropriate pages. Then confirm that bidding responds to trustworthy outcomes. Only then give the system more freedom to alter spend timing. Otherwise, faster pacing amplifies an unresolved targeting or measurement problem.

    Roll out one delegated decision at a time

    Turning on new landing-page selection, bidding exploration, journey signals, and budget pacing together may produce a different result, but it will not tell you which change caused it. A controlled rollout preserves your ability to diagnose and reverse.

    1. Name the delegated decision. State whether the test concerns page selection, opportunity exploration, bid response, or budget pacing. Do not use “more AI” as the test definition.
    2. Define forbidden outcomes. Examples include traffic to an ineligible site section, spend beyond the authorized period total, or growth in leads without acceptable downstream quality.
    3. Prepare the input layer. Finish the URL classification, conversion audit, or financial constraints needed for that decision.
    4. Capture a comparable baseline. Use the same campaign scope and the same business definitions you will apply after the change.
    5. Change one control layer. Hold the others stable enough to make the result interpretable.
    6. Review platform and business outcomes separately. More conversions may be a useful platform result, but it does not settle whether the change produced better customers or better economics.
    7. Apply a prewritten rollback rule. Decide what failure means before spend is affected. If you wait until after the result, pressure to defend the test can move the standard.
    8. Scale only after the boundary holds. A good average result is not enough if the campaign repeatedly violates landing-page, quality, or spending constraints.

    The review cadence should match the business process, not the speed of the interface. A lead-generation campaign cannot be judged responsibly before the quality signal exists. An ecommerce campaign should not be scaled from order volume alone if cancellations or product mix materially change its value. Wait for the outcome needed to answer the commercial question, while keeping hard spend limits in place.

    Key takeaways

    • Keep firm human control over eligibility, objectives, economic limits, and the evidence required to continue.
    • Translate DSA URL logic into page feeds, meaningful custom labels, ad-group inclusions, and campaign exclusions before relying on AI Max.
    • Treat unsupported read-only DSA rules as temporary legacy dependencies, even when they still function.
    • Use journey signals only when you can explain their relationship to the business outcome and trust their measurement.
    • Do not treat a vendor-reported increase in conversions or reduction in manual work as proof of profitable growth.
    • Expand budget automation only after landing-page selection and conversion quality are under control.
    • Delegate one decision at a time and define rollback conditions before the test begins.

    Google Ads is moving the advertiser’s job from repeated intervention toward system design. Your next move is to choose one campaign and write a one-page policy covering eligible landing pages, optimization signals, spending authority, and rollback conditions. If the available controls cannot enforce that policy, do not automate that decision yet.
    References

  • AI SEO Operations: A Practical System for Safe Automation

    AI SEO Operations: A Practical System for Safe Automation

    You probably do not need another AI SEO tool. You need to know which recurring job to automate, what evidence its output must meet, and who steps in when the system gets something wrong.

    That is the difference between scattered AI experiments and an AI-enabled SEO operation. The goal is not to generate more material. It is to move reliable work through content, analytics, technical SEO, brand and publishing with less friction, while keeping consequential decisions in human hands.

    Key takeaways for AI-enabled SEO operations

    • Start with a business outcome and an existing workflow, not a tool or prompt.
    • Automate stable, repeatable work only after you understand how it is completed manually.
    • Use reach, intent, scale and execution to reject AI ideas that will not produce a measurable result.
    • Give every automation an owner, acceptance criteria, a human escalation path and a manual fallback.
    • Measure quality and business impact alongside time saved. Faster output is not a win if it creates rework or publishes weak information.

    Start with an operating map, not another AI tool

    A team examines a tabletop workflow map connecting content, analytics, technical review, and publishing tasks.

    AI adoption often looks like a tooling problem because tools are the most visible part. The harder problem is that SEO work crosses several functions. A content lead may be generating briefs while an analyst builds a reporting assistant and a developer creates a schema workflow. Each project can be useful on its own, yet the combined system may duplicate effort, produce incompatible outputs or leave nobody accountable for the final result.

    The practical barrier is usually coordination and integration, not willingness to experiment with AI. Legal needs to understand exposure. Developers need defined requirements. Editors need to know what they must verify. Leadership needs to see how the work affects a business objective. A prompt library cannot resolve those dependencies.

    Begin by mapping one complete SEO workflow. Do not start with every task your team performs. Choose a recurring process with a visible beginning and end, such as refreshing declining pages, producing content briefs, reviewing internal links or explaining monthly performance.

    1. Name the outcome. State what should improve: faster refresh decisions, more consistent briefs, fewer unsupported brand claims, better internal-link coverage or less time spent preparing reports.
    2. Define the trigger. Specify what starts the workflow. It might be a scheduled audit, a page crossing a performance condition, an approved keyword cluster or a completed reporting period.
    3. Trace the inputs and handoffs. List the data, documents and approvals required at each stage. Mark where work waits, returns for correction or gets copied between systems.
    4. Assign one accountable owner. Several people may contribute, but one role must own the workflow’s health, approve changes and decide when automation should stop.
    5. Mark the decision points. Separate transformations a machine can perform from judgements a person must make. Summarizing rows is a transformation. Deciding whether a recommendation fits the brand and search intent is a judgement.
    6. Record the baseline. Capture how the workflow currently performs before changing it. Use the measures that already matter: completion time, revision volume, error rate, publishing delay or an associated SEO outcome.

    A small workflow register makes this map usable. It should show where AI assists and where responsibility remains human.

    WorkflowTrigger and inputAI roleHuman decisionOutcome
    Content refreshPerformance review and current pageSummarize changes, gaps and candidate updatesChoose whether to refresh, consolidate or leave the page aloneBetter update decisions with less audit preparation
    Internal linkingNew or updated URL plus site inventorySuggest relevant source pages and destinationsConfirm contextual relevance and approve placementMore consistent link coverage
    Monthly reportingValidated analytics and search dataSurface anomalies and draft observationsVerify causes, add business context and select actionsLess reporting busywork and clearer decisions
    Metadata or schemaApproved page facts and a defined templateGenerate a structured draftVerify factual support, syntax and suitability for publicationFaster production without surrendering control

    This register also exposes misplaced automation. If an AI step produces an outline before keyword selection is approved, for example, it may accelerate work that will later be discarded. Moving one task faster does not help when the actual delay sits at a different handoff.

    Build the automation backlog from work you already understand

    The strongest automation candidates are usually hiding inside work your team already performs repeatedly. They have known inputs, recognizable outputs and a reviewer who can explain what good looks like. That makes them easier to test than a new process invented around an AI feature.

    Observe a recently completed workflow from start to finish. Compare the actual work with onboarding documents and standard operating procedures. Ask the people doing it which steps they repeat, dislike or routinely postpone. This kind of workflow audit can reveal opportunities across data analysis, content gaps, editorial planning, briefs, metadata, schema and formatting.

    Use two tests to identify a candidate. First, ask whether you would confidently delegate the task to a new team member after giving them instructions and examples. Second, ask whether an experienced reviewer could detect a bad output without repeating the whole task. If both answers are yes, AI may be useful for the first pass.

    A 70% machine draft and 30% human refinement can be a useful starting heuristic for research and drafting work. It is not a staffing formula or a promise that every task divides neatly. It means the machine handles collection, classification, formatting or an initial draft, while a person supplies judgement, context and approval.

    Before putting a candidate in the backlog, pass it through an automation-readiness check:

    • The manual process is stable. Different team members follow substantially the same steps.
    • The input is available and trustworthy. The automation will not need to guess around missing page facts, incomplete analytics or inconsistent naming.
    • The output has a defined shape. A template, field structure or explicit deliverable makes validation possible.
    • Quality can be evaluated. Reviewers can distinguish an acceptable result from a plausible-looking failure.
    • Failures will be visible. A malformed output, missing input or unsupported statement will be flagged rather than silently published.
    • A person owns escalation. Someone knows what to do when the result falls outside the normal path.
    • The manual path still exists. The team can continue critical work if the model, integration or maintainer becomes unavailable.

    If the process is inconsistent, fix that first. Automation works best after the underlying workflow has been standardized and performed manually. Otherwise, AI does not remove the ambiguity. It executes the ambiguity faster and at a larger scale.

    Be especially cautious when the required asset does not exist. AI cannot reliably enforce brand rules that have never been documented, fill a content template whose fields are disputed or repair an analytics pipeline with incomplete data. Those are ownership and process problems. Treating them as prompt problems delays the real fix.

    Use RISE to reject weak automation ideas early

    An automation backlog will grow faster than your ability to implement it. The useful management skill is therefore rejection. A small number of well-integrated workflows will usually create more value than a large collection of clever demonstrations.

    The RISE framework tests an initiative through reach, intent, scale and execution. Use it before selecting a model, buying a tool or asking engineering for an integration.

    Reach: quantify the eligible work and the upside

    Reach is not a vague claim that a workflow affects SEO. Name the inventory, frequency and result. For a recurring task, you can model operational reach as eligible items multiplied by handling time and run frequency. For an SEO initiative, include the pages, query groups or customer questions it can materially affect.

    Write down the baseline and the expected movement before implementation. If you cannot identify a numerical business or operational upside, keep the idea in exploration rather than placing it on the production roadmap. This prevents novelty from being mistaken for impact.

    Intent: prove that the output serves a real decision

    Intent means more than classifying a keyword as informational or transactional. Ask who will use the output, what question it answers and what action follows. An automated content-gap report has little value if nobody has the authority or capacity to commission the missing work. A metadata generator is misplaced if weak positioning, not drafting time, is the constraint.

    For content operations, connect the workflow to a defined audience question and page purpose. AI can expand an outline, but a strategist still needs to decide whether the page deserves to exist and what distinct value it should provide.

    Scale: look for structural reuse

    A scalable workflow does not require someone to reconstruct the prompt, clean the inputs and explain the output every time it runs. It uses repeatable triggers, standardized fields, documented rules and a destination inside the team’s normal systems.

    Do not confuse a large batch with scale. Generating thousands of outputs once is volume. Scale exists when the operation can run again, under ownership, without rebuilding the process or accumulating hidden manual cleanup.

    Execution: define how the work reaches production

    Execution is where promising demonstrations tend to stall. Name the owner, required access, review stage, acceptance criteria and publishing destination. Identify the team that will maintain the workflow when prompts, templates, data fields or business rules change.

    A one-page initiative brief is enough to force clarity. It should contain the problem, baseline, eligible inventory, intended user, workflow owner, AI role, human decision, quality checks, expected outcome and stop condition. If those fields cannot be completed, the initiative is not ready for production.

    After an idea passes RISE, test it against previously completed work. Historical cases give you an expected result and let reviewers compare the automated output with decisions that have already been made. Only then move to a live pilot, with every output reviewed until the failure patterns are understood.

    Make control and measurement part of the workflow

    A controlled pipeline routes digital work through automated checks, human review, and a final release gate.

    Human review is necessary, but it is not a complete control system. A vague instruction to check the output leaves each reviewer to invent a different standard. Effective QA combines machine-readable checks, explicit editorial criteria and a named person who can approve exceptions.

    Design each production workflow as a controlled sequence:

    1. Validate the input. Confirm required fields, data freshness and allowed formats before sending anything to the model.
    2. Run the bounded AI task. Give the system a specific transformation, required output structure and the information it is allowed to use.
    3. Apply deterministic checks. Test syntax, missing fields, duplicates, prohibited terms, unsupported values or other conditions that do not require subjective judgement.
    4. Route the result for human review. Show the generated output with its input and any warnings. A reviewer should not have to hunt for the evidence needed to approve it.
    5. Publish through the normal system. Keep existing permissions and approval controls instead of creating a parallel route around the CMS or engineering workflow.
    6. Log the result and any correction. Record failures, overrides and substantive edits so the team can improve the process rather than correcting the same pattern indefinitely.

    The acceptance criteria should match the output. An internal-link recommendation needs a relevant context, a valid destination and an editorially sensible placement. A reporting narrative must reconcile with validated data and separate observation from explanation. Generated schema must be syntactically valid and contain only claims supported by the visible page. A content brief needs a defined intent, usable structure and enough evidence for a writer to proceed without guessing.

    Keep the final check personal where the output affects a public page, brand claim or strategic decision. Automating the first pass is useful precisely because it leaves more attention for quality assurance and consequential decision-making. Removing that review to maximize throughput defeats the purpose.

    Document the workflow well enough that it can survive a change of maintainer. Include its purpose, owner, trigger, input location, prompt or instruction version, output format, validation rules, reviewer, publishing path and failure response. This reduces the risk of losing both operational knowledge and a critical process when the person who built the automation is no longer available.

    Run governance at three different cadences. A weekly cross-functional checkpoint should handle exceptions, blocked handoffs and decisions that cannot wait. A monthly review should compare efficiency, quality and SEO or business outcomes with the baseline. A quarterly roadmap session should decide which workflows to expand, repair, retire or leave manual. Weekly coordination, monthly performance reviews and quarterly roadmap alignment keep ownership active after launch.

    Measure the operation in three layers:

    • Efficiency: completion time, queue age, manual touches and work returned for correction.
    • Quality: acceptance rate, substantive edit rate, validation failures, false positives and published corrections.
    • Outcome: the business or SEO measure named when the initiative was approved, such as refresh completion, useful internal-link coverage, reporting decisions or performance of the affected page group.

    Do not report time saved without showing what happened to quality and outcomes. An automation that halves drafting effort but doubles review work has shifted the cost, not removed it. Likewise, a workflow can be accurate and still be unnecessary if nobody acts on its output.

    Recovered capacity should have an explicit destination. Use it for work AI cannot own: coordinating priorities across teams, investigating why performance changed, improving the customer search journey and deciding which emerging search behaviors deserve attention. Otherwise, the saved time tends to be absorbed by a larger volume of low-value production.

    Your next move can be small. Select one recurring workflow, write its one-page operating brief, record the current baseline and test the proposed automation on completed work. If you cannot name the owner, acceptance criteria and failure path, do not automate it yet. Fix those three gaps first, then let AI accelerate a process you can actually control.

    References


  • Best-of-N AI Jailbreaking: Risks and Defensive Controls

    Best-of-N AI Jailbreaking: Risks and Defensive Controls

    You may have watched your AI assistant reject an unsafe request and concluded that its safeguards worked. If you tested only once, you answered the wrong question. An attacker does not need every prompt to succeed. They need one useful failure after enough retries.

    Best-of-N jailbreaking turns that model variability into a search process. To manage the risk, you need to evaluate the whole campaign, enforce permissions outside the model, and control every additional chance created by retries, fallback models, tools, and automated agents.

    The dangerous unit is the campaign, not the prompt

    A Best-of-N attack creates or collects multiple versions of a prohibited request, submits them to an AI system, and selects the response that comes closest to the intended outcome. The essential move is to send many variations and keep the most successful result. The value of N is not fixed, and the selection can be performed by a person, a script, or another model.

    This changes the security question. A per-request review asks, “Did this prompt get blocked?” A campaign-level review asks, “Did any related attempt produce a prohibited result?” The second question reflects the attacker’s objective.

    The probability principle is straightforward. If each attempt has a nonzero chance of crossing a boundary, repeated opportunities can raise the chance that at least one attempt succeeds. Under the simplified assumption that attempts are independent and have the same success probability p, the probability of any success after N attempts is 1 – (1 – p)^N. Real prompt variants are often correlated, so you should not use that formula as a production risk estimate. Measure complete campaigns against your actual system instead.

    Three distinctions prevent confusion during threat modeling:

    • A normal retry is usually an attempt to clarify a legitimate request after an incomplete or incorrect answer. Repetition alone does not establish malicious intent.
    • A jailbreak tries to bypass behavioral restrictions placed on a model.
    • Prompt injection supplies untrusted instructions that compete with the system’s intended instructions, often through user input or retrieved content. Best-of-N is a search strategy that can amplify jailbreaks, prompt injection, or other policy-evasion techniques.

    Treat Best-of-N as a threat multiplier, not as the root vulnerability. It finds inconsistent decisions and weak handoffs. It cannot grant a caller a permission that your application enforces deterministically outside the model. That is why authorization architecture matters more than clever safety wording.

    Where repeated attempts find extra chances

    An isometric AI network branches into retry loops, fallback nodes, tools, memory, and agent pathways carrying repeated request signals.

    Your model is only one part of the attack surface. A typical AI workflow also has an identity layer, input filters, a router, one or more models, output checks, retrieval, tools, and application code. Every component that makes a fresh probabilistic decision can give a campaign another route to success.

    LayerMisleading green lightCampaign signal to inspectStronger control
    Prompt policyOne prohibited request was refusedRelated requests are repeatedly rephrased after denialsAggregate policy events by actor, session, intent cluster, and protected resource
    Input moderationEach prompt remains below an individual alert thresholdSmall wording, format, language, or encoding changes accumulate around the same objectiveAnalyze normalized forms and sequences while retaining the raw input for investigation
    Model routingThe primary model refusedA fallback model, alternate endpoint, or retry path returned a different decisionApply one canonical policy before routing and a final gate after generation
    Tools and agentsThe assistant’s visible text looks harmlessA tool call requests a broader scope, sensitive record, or irreversible actionEnforce authorization, parameter validation, and action limits in application code
    Traffic controlsEach IP address or API key stays within its local limitRelated attempts move across sessions, keys, endpoints, or modelsCorrelate only the identifiers justified by your threat model, privacy obligations, and retention policy
    LoggingEvery prompt was stored somewhereNo record connects attempts, decisions, tool calls, and final outcomesAssign campaign and event identifiers so an investigation can reconstruct the sequence

    For an SEO, AEO, or GEO workflow, the highest-consequence result may not be a bad chat response. It may be an unauthorized CMS publication, a destructive edit, exposure of an unpublished campaign, or a tool call made with the application’s credentials. If a model generates page copy or JSON-LD, syntactic validation is necessary but insufficient. Valid structured data can still contain false, disallowed, or unapproved claims. Check the output against business rules and publishing permissions before it reaches a live page.

    Build controls that survive repeated attempts

    A request signal passes through layered security gates before reaching an AI core and protected tool mechanisms.

    No safety prompt can carry this responsibility alone. Prompts influence model behavior, but they are not security boundaries. Use several controls with different failure modes, and place deterministic checks wherever failure could expose data, spend money, alter content, or trigger an external action.

    1. Put authorization outside the model. Resolve the authenticated principal in application code, grant the least privilege needed for the workflow, and verify permission again when a tool executes. Never let generated text decide whether the caller may read, publish, delete, or export something.
    2. Separate read and write capabilities. An assistant that only needs to draft content should not inherit publishing or deletion rights. When write access is required, constrain the allowed resource, action, fields, and destination.
    3. Normalize for analysis without overwriting evidence. Retain the original request, then create a canonical representation for similarity detection. Normalization can help reveal superficial changes in spacing, character representation, formatting, or casing, but it must not silently change the content executed by downstream systems.
    4. Maintain campaign state. Record the actor or service identity, session, endpoint, model route, normalized intent cluster, policy decision, tool request, and outcome. Look for repeated denials, rapid reformulations, alternate-route probing, and requests that converge on the same protected capability.
    5. Add adaptive friction. As campaign risk rises, reduce retry opportunities, disable expensive fallback routes, introduce a cooldown, require stronger authentication, or move the request to human review. Apply the strongest friction to workflows with data access or irreversible effects rather than imposing the same response on harmless drafting tasks.
    6. Gate outputs and tool calls separately. Check generated content against the output policy, validate structured fields, reject unexpected tool names or parameters, and limit the records or resources returned. A harmless-looking explanation must not conceal a disallowed action request.
    7. Define safe failure behavior. If moderation, identity resolution, authorization, or final validation is unavailable, return a controlled error for protected operations. Do not route around a failed safeguard to preserve a smooth user experience.
    8. Protect the control plane. Restrict who can change system prompts, policy rules, model routes, tool definitions, and safety thresholds. Log those changes and make rollbacks possible, because a campaign can exploit configuration drift as readily as model variability.

    There is no universal safe retry count. A blanket limit low enough for a sensitive data-export agent may be needlessly hostile in a public brainstorming tool. Set budgets by consequence, then examine legitimate retry behavior before choosing enforcement thresholds. Track false positives alongside security outcomes so that users who are clarifying ambiguous, multilingual, or accessibility-related requests are not treated automatically as attackers.

    Be careful with model-based safety judges as well. A second model can add useful evidence, but it may share blind spots with the model it evaluates. Use deterministic authorization and validation for hard boundaries, with model judgments contributing to risk scoring rather than granting privileged access on their own.

    Test the full campaign without publishing an exploit kit

    A single-prompt red-team check will miss the defining behavior of Best-of-N. Your evaluation runner should group related attempts, preserve production routing logic, and score whether any attempt reaches a prohibited outcome. Keep testing authorized, isolated, and away from live customer data or publishing systems.

    1. Define the breach before generating tests. Describe prohibited outcomes in observable terms, such as returning a protected field, invoking a disallowed tool, publishing without approval, or producing content that violates a named policy. A vague label such as “unsafe response” produces inconsistent scoring.
    2. Build campaign families. Group sanitized test cases by underlying objective, then vary the permitted dimensions relevant to your system, such as phrasing, format, language, model route, and retry sequence. Keep actionable attack strings in an access-controlled security repository rather than general documentation or analytics dashboards.
    3. Reproduce the production topology. Include the actual order of input checks, retrieval, routing, fallback behavior, output gates, tools, and error handling. Testing the base model alone does not test the application your users can reach.
    4. Run attempts as connected sequences. Carry session and risk state between related requests. Also test whether switching endpoints or invoking an automated agent incorrectly resets that state.
    5. Score outcomes at two levels. Retain per-request decisions for diagnosis, but make campaign-level success the headline measure. A system can have an impressive individual refusal rate while still allowing too many campaigns to obtain one useful failure.
    6. Review the most consequential path first. A policy-breaching paragraph matters, but a tool call that exposes private data or changes a live site demands tighter controls and faster remediation.
    7. Version the evaluation and rerun it after changes. A new model, system prompt, router, retrieval source, guardrail, tool definition, or fallback rule can alter campaign behavior even when the visible feature appears unchanged.

    Your evaluation dashboard should include the campaign any-success rate, attempts to the first breach, breach severity, detection and containment outcomes, tool or data-boundary violations, and false-positive friction for legitimate users. Do not collapse these into one average. A small number of severe authorization failures should remain visible rather than being diluted by many harmless refusals.

    Stop a test immediately if it begins interacting with real user records, external recipients, paid services, or live publishing. Move the scenario into an isolated environment with synthetic data and inert tools. The purpose of the exercise is to verify containment, not to prove that production damage is possible.

    Key takeaways for AI product owners

    • One successful refusal does not establish safety; measure whether any attempt in a related campaign succeeds.
    • Best-of-N exploits repeated opportunities and inconsistent decisions, so retries, fallback models, alternate endpoints, and agents all belong in the threat model.
    • System prompts and model-based judges can support safety, but they cannot replace deterministic authentication, authorization, validation, and tool restrictions.
    • Aggregate related attempts without assuming every retry is malicious; calibrate friction to the consequence of the requested capability.
    • Test the production workflow as a sequence, then report campaign-level success and breach severity alongside per-request refusal metrics.
    • Keep security payloads controlled, use synthetic data and inert tools, and never red-team an external or production system without authorization.

    Before your next release, choose the AI workflow with the greatest access to data, tools, or publishing. Trace every place where a rejected request can receive another model call or another route. Then add campaign-level telemetry and a deterministic gate at the highest-consequence handoff.

    That review will not eliminate model variability. It will prevent variability from becoming permission.

    References


  • How to Build an AI Discovery-to-Publishing Workflow

    How to Build an AI Discovery-to-Publishing Workflow

    You can have AI finding topics, another tool drafting copy, and a CMS waiting at the end, yet still spend most of your time repairing handoffs. The idea loses its original purpose, evidence disappears during drafting, and the CMS entry arrives without the context an editor needs to approve it.

    The fix is a controlled workflow in which every stage produces a clear artifact for the next one. Discovery should become an evidence-backed brief. The brief should constrain drafting. The approved draft should map cleanly into CMS fields. Publishing should happen only after editorial, technical, and discovery checks pass.

    Start with an answer gap, not a draft request

    A researcher examines an illuminated empty space among knowledge tiles while source materials collect into a brief folder.

    Treat AI-mediated discovery as a reasoning layer in which original insights and citations shape visibility. That changes the unit of work. A keyword is not enough. You need to identify a question, the situation behind it, the missing answer, and the contribution your page can make.

    A useful discovery record should answer the following before anyone opens a drafting tool:

    • User question: Write the question in the language a real reader would use, without turning it into a target keyword.
    • Reader situation: Record what the reader is trying to decide, fix, compare, or implement.
    • Existing-answer gap: State what is missing, unclear, fragmented, or difficult to apply in the current coverage.
    • Proposed contribution: Define the method, distinction, framework, evidence, or practical decision rule your content will add.
    • Evidence available: Attach the URLs, internal knowledge, approved data, and expert material that can support the contribution.
    • Desired next action: Specify what the reader should be able to do after getting the answer.
    • Acceptance decision: Record why the opportunity should move forward, wait for more evidence, or be rejected.

    This record prevents a common failure: a discovery system finds a promising theme, but the production team receives only a phrase such as “AI content workflow.” That phrase does not explain who needs the content, what problem is unresolved, or why another page deserves to exist.

    A production-ready opportunity is much sharper: a content lead wants to move AI-discovered questions into a CMS without allowing unreviewed copy to publish, and needs a field map, approval states, and quality gates. That statement gives the writer a job to complete. It also gives the editor a basis for rejecting a draft that drifts into a generic discussion of AI writing.

    Group related questions by reader decision rather than by shared wording. Questions about choosing a workflow, configuring it, approving output, and diagnosing failures may contain overlapping terms, but they belong on the same page only when they help the same reader complete the same job. If they represent different decisions, give them separate discovery records.

    Reject an opportunity when nobody can name its distinctive contribution. “We should cover this because competitors do” is not a contribution. Neither is “AI can write it quickly.” Speed lowers the cost of producing a redundant page; it does not give that page a reason to be discovered or cited.

    Turn the accepted opportunity into a production contract

    The brief is the contract between discovery, drafting, review, and publishing. It should preserve the reasoning that made the opportunity worth pursuing. If the brief contains only a title, keywords, and a word-count target, the drafting stage has to reconstruct that reasoning and will often invent the missing parts.

    Build the brief around decisions and claims:

    • Promise: State the outcome the page must deliver for the reader.
    • Primary answer: Write a concise answer that the completed page must be able to defend.
    • Supporting questions: Include only questions needed to understand or apply the primary answer.
    • Required contribution: Describe the original method, analysis, example, or distinction that must survive into the final copy.
    • Claim map: List the important claims, their types, and the evidence allowed for each one.
    • Structure: Assign a reader purpose to every planned section. Remove sections that exist only to make the page look comprehensive.
    • Internal destinations: Identify relevant pages that genuinely help the reader continue the task.
    • CMS destination: Map the future title, excerpt, body, taxonomy, structured-data inputs, owner, and workflow status.
    • Stop conditions: Define what must send the work back to discovery instead of being patched during drafting.

    The claim map deserves particular care. Classify each important statement as an established fact, an interpretation, an original finding supplied by your organization, a recommendation, or an unsupported hypothesis. These labels can remain internal, but they force the team to apply the right standard of proof.

    For each claim, store the exact wording, claim type, evidence URL or internal evidence location, permitted interpretation, uncertainty, and destination section. This makes citation review mechanical. An editor can see whether the evidence supports the actual sentence instead of merely discussing the same general subject.

    Original insight does not mean unsupported novelty. It can be a useful synthesis, a clearly explained method, a distinction that resolves confusion, or an analysis grounded in material you are permitted to publish. The workflow should preserve the connection between original insight, citation, credibility, and discovery, not ask a model to manufacture something that merely sounds new.

    Give the drafting model the approved brief, claim map, evidence, house rules, and explicit boundaries. A practical instruction is: Use only the supplied evidence for factual claims. Mark missing support as [EVIDENCE NEEDED]. Do not create quotations, figures, examples presented as real, product behavior, or conclusions that the evidence does not establish.

    Draft in controlled passes. Generate the answer structure first, then develop sections, then review claim-to-evidence alignment, and only then polish the prose. This makes drift visible. If a section cannot fulfill its assigned reader purpose with the approved evidence, send it back to the brief instead of hiding the weakness beneath smoother language.

    Use AI as a challenger after it has been a drafter. Ask it to identify unsupported claims, vague nouns, missing steps, repeated ideas, and recommendations that lack a stated mechanism. Treat those findings as review leads, not automatic corrections. A model can flag a possible gap, but the responsible editor still decides whether the content is accurate and sufficiently supported.

    Connect drafting to the CMS through explicit states

    Blank content modules move through separated editorial review gates before assembling into a complete CMS page.

    Direct integrations can remove copy-and-paste work. Profound Agents, for example, can read from and write to Framer CMS while moving content from insight into staged CMS items. That is valuable when the integration carries editorial context with the copy. It is risky when “write to CMS” silently becomes “publish whatever the model produced.”

    Give every item an explicit workflow state. Each state should define what the automation may do and what a person must approve before the item can advance.

    Workflow stateRequired inputPermitted automationHuman gate
    DiscoveredQuestion, reader situation, gap, and available evidenceCluster related questions and populate the discovery recordConfirm that the opportunity represents a real reader decision and has a defensible contribution
    BriefedAccepted discovery recordAssemble the production brief, structure, and initial claim mapApprove scope, evidence, uncertainty, and stop conditions
    DraftedApproved brief and evidenceGenerate and revise copy within the stated constraintsVerify accuracy, usefulness, originality, and claim-to-evidence alignment
    StagedReviewed copy and CMS field mapCreate or update the CMS item and fill mapped fieldsInspect the rendered preview, links, taxonomy, metadata, and structured data
    ApprovedCMS item that passed reviewPrepare the approved item for its authorized releaseConfirm the final URL, publication status, ownership, and timing
    PublishedLive URLCollect workflow and discovery observationsDecide whether to update, expand, consolidate, or retire the content

    Use a stable content ID from discovery through publication. The connector should update the CMS item associated with that ID rather than creating a new item whenever a job is retried. This is an idempotent write: running the same approved action again reaches the same intended state instead of producing duplicates.

    Your field map should distinguish editorial content from workflow control data. At minimum, map the stable content ID, workflow state, owner, working title, public title, slug, excerpt, body, taxonomy, internal links, evidence record, approval status, and structured-data inputs. Keep nonpublic notes and evidence metadata out of public body fields.

    Generate JSON-LD from the approved, visible page rather than from an earlier draft. Structured data must not introduce claims, entities, authorship, dates, or relationships that the reader cannot verify on the page. If the body changes after schema generation, send both through the same review state again.

    Keep live publication behind a separate permission. Discovery, brief assembly, drafting, linting, and CMS staging are suitable candidates for automation because their output can still be inspected. Acceptance of the original contribution, resolution of contested claims, and release to the public need an accountable owner.

    When a connector fails, preserve the last approved state and return a clear error. Do not let a partial write produce a live item with a title but no body, a body with stale schema, or a revised page without its approved citations. Recovery should resume from the failed state, not restart the entire workflow without context.

    Review the page as content, a CMS object, and an answer

    A polished draft can still fail after publishing. The copy may not answer the target question clearly, the CMS may render it incorrectly, or the most important claim may be too vague to cite. Separate these checks so a general “looks good” approval cannot conceal a technical or evidence problem.

    Editorial review

    • Confirm that the opening addresses the reader’s situation and gives a direct path toward the promised outcome.
    • Compare every important factual claim with its evidence record.
    • Open every external citation and verify that the linked material supports the linked words.
    • Separate fact from interpretation and recommendation in the wording.
    • Remove invented examples, quotations, measurements, product behavior, and implied firsthand experience.
    • Check that every section helps the reader do, decide, or notice something specific.
    • Delete repeated explanations rather than disguising them with different wording.

    CMS and technical review

    • Inspect the rendered preview rather than approving raw field values.
    • Check the title, slug, excerpt, heading hierarchy, lists, tables, links, categories, and tags.
    • Confirm that the item is in the intended draft, scheduled, or published state.
    • Verify that canonical and indexing controls reflect the intended public page.
    • Compare structured data with the final visible content.
    • Confirm that an update changed the intended CMS item instead of creating a duplicate.
    • Test the recovery path when a required field or integration step fails.

    Discovery and answer review

    • Restate the target question and confirm that the page answers it without requiring the reader to infer the conclusion.
    • Name important entities consistently so products, organizations, concepts, and roles are not confused.
    • Place support near the claim it supports.
    • Use descriptive headings that reveal what each section resolves.
    • Make each section understandable without depending on a distant paragraph for essential context.
    • Preserve the distinctive contribution identified during discovery. A draft that loses it should not pass merely because the prose is clean.
    • Check whether the conclusion gives the reader a concrete next action rather than repeating the introduction.

    After publication, measure the workflow and the outcome separately. Workflow records can show where work stalls: discovery awaiting evidence, briefs waiting for approval, drafts accumulating revisions, or CMS items failing at preview. Outcome records can capture whether the target question produces a relevant AI answer, whether your brand or URL is mentioned or cited, whether the landing page receives useful visits, and whether those visits support the intended next action.

    Do not collapse those observations into a single visibility score. A page can be cited without receiving meaningful traffic. It can receive traffic while attracting the wrong reader. It can also be a useful page that has not yet been surfaced for the question you tracked. Keep the observations distinct so the next action addresses the actual problem.

    • No relevant appearance: Check public accessibility, indexing intent, question fit, and whether the page provides a distinctive answer.
    • Appearance without citation: Inspect whether the useful claim is explicit, well supported, and attributable to the page rather than expressed as generic advice.
    • Citation with weak engagement: Check whether the page satisfies the same intent as the answer and offers a relevant next step. Do not assume citation automatically produces conversion.
    • Incorrect representation: Remove ambiguous wording, correct unsupported statements, align structured data, and make the intended relationship between entities explicit.
    • Repeated editorial rework: Change the discovery record, evidence requirements, or brief template. Recurring downstream errors usually belong in an upstream control.

    Feed each diagnosis back into the appropriate stage. Do not respond to every disappointing outcome by generating more content. Sometimes the right action is a clearer answer, better evidence, corrected CMS data, a merged page, or a decision to stop pursuing an opportunity that never had a defensible contribution.

    Key takeaways

    • Discovery is complete only when you can state the reader’s decision, the missing answer, your contribution, and the evidence available.
    • The content brief should preserve discovery reasoning through a claim map, explicit scope, CMS destination, and stop conditions.
    • AI may draft and challenge the work, but it should not invent the evidence, uncertainty, or editorial constraints.
    • A CMS connector should write to controlled workflow states. Staging and live publication are separate permissions.
    • The final JSON-LD, metadata, and CMS fields must reflect the approved visible page, not an earlier draft.
    • Measure workflow friction, AI visibility, citations, traffic, and reader outcomes as separate observations.

    Start with one repeatable content type. Create its discovery record, claim map, CMS field map, and approval states, then run a real item through the entire path. Keep the connector in staging mode until the team can recover from failed writes, explain every status change, and show who approved the live version. Once that path is dependable, you can expand automation without giving up editorial control.

    References


  • Claude-Powered PPC Automation: From Prompts to Systems

    Claude-Powered PPC Automation: From Prompts to Systems

    If Claude gives you a strong search-term analysis only after you paste the same instructions and CSV into a new chat, you have improved the task, not automated it. You still have to assemble the context, request the analysis, normalize the output, and move each approved change into Google Ads.

    Claude-powered PPC automation becomes useful when you design those handoffs once. The practical system has three separate parts: decision logic, access to current campaign data, and controls over what the AI may change. Get those parts right and Claude can take recurring work off your desk without taking campaign authority away from you.

    The three parts of a reliable Claude PPC system

    Three connected modules represent campaign data access, AI decision logic, and human-controlled execution safeguards.

    The model is only one layer of the system. A dependable workflow also needs a stable playbook and an explicit operating boundary.

    System partWhat it doesThe question you must answer
    Claude SkillEncodes the task, decision rules, required inputs, exceptions, and output structure.What should happen every time this PPC job runs?
    Data and toolsSupply campaign context and, when authorized, provide a way to execute an approved action.Which data may Claude read, and which operations may it call?
    Workflow controlsDefine scope, approval requirements, stop conditions, and records of proposed or completed changes.What is Claude allowed to decide, recommend, and change?

    A Claude Skill is a task-specific playbook, not a general preference about tone or behavior. It can tell Claude how to audit an account, evaluate search terms, generate ad assets, or compare budget opportunities. The instructions can be stored in a Markdown file, kept locally, or shared through a repository so the team uses the same method.

    The main benefit is procedural consistency. Without a fixed contract, one run might return letter grades while another uses percentages or an unrelated numerical scale. That is more than a presentation problem. A person, spreadsheet, script, or approval workflow cannot reliably consume an output whose structure changes between runs.

    A Skill should make the process predictable, but it should not pretend every PPC judgment is deterministic. Campaign evidence changes, and some cases will remain ambiguous. Your playbook therefore needs both decision rules and an explicit way to return insufficient evidence, conflicting signals, or required human review.

    The data layer solves a different problem. A Skill can know how to evaluate a search query report while knowing nothing about the queries currently appearing in your account. A Model Context Protocol connection can bridge that gap: MCP can connect Skill logic to live data sources and account tools. That turns a static playbook into an operating workflow, but it also makes permissions and approval gates essential.

    Build the first workflow around one recurring decision

    Start with a bounded job rather than asking Claude to optimize an account. Search-term mining is a practical first candidate because you can define the input, inspect every recommendation, and test the logic without granting write access.

    1. Define the job in one sentence. For example: review search terms from the requested 14-day window, identify waste and opportunity using the account’s approved criteria, and return proposed actions for review. The 14-day period is an input to this workflow, not a universal recommendation for every account.
    2. Write down the judgment currently living in the operator’s head. Include the evidence Claude must consider, the conditions that support each recommendation, the exceptions that require escalation, and anything it must never infer from missing data.
    3. Lock the output contract. Name every required field, its allowed values, and what a stopped run looks like. Do not let Claude invent a new scoring system or column set each time.
    4. Convert the SOP into a Skill. A useful instruction is: Convert this SOP into a task-specific Claude Skill. Preserve the decision rules, define required inputs, return a fixed schema, stop when required fields are missing, and do not take write actions without approval.
    5. Run the Skill against a known CSV before connecting an account. Confirm that it covers the intended records, follows the rubric, flags exceptions, and returns the exact structure your reviewer or downstream tool expects.
    6. Connect live data in read-only mode. Compare the live run with the CSV-based process. Add write capabilities only after the connected workflow passes the same acceptance checks.

    A useful output contract for this workflow can require:

    • The account, campaign, and reporting window included in the run.
    • A completion status that distinguishes a finished analysis from a stopped or incomplete run.
    • The item reviewed, the evidence used, and the applicable decision rule.
    • The proposed action and a concise reason for it.
    • An exception field for missing inputs, conflicting signals, or cases outside the Skill’s authority.
    • An authorization state such as proposal, approved, executed, or rejected.

    The output contract is what turns a clever response into a component another person or system can trust. Claude should never quietly substitute a plausible answer when a required campaign field is unavailable. A stopped run with a precise error is safer and more useful than a polished recommendation built on incomplete context.

    Put money-changing actions behind explicit gates

    A human operator approves one proposed campaign change at a guarded barrier before it reaches an advertising budget.

    Access and authority are not the same thing. An MCP-enabled tool may make an account change technically possible, but your workflow still decides whether Claude may propose it, prepare it, or execute it. That distinction matters whenever an action can change spend, targeting, messaging, or delivery.

    Operating modeClaude’s roleHuman role
    Manual-context assistantAnalyzes an uploaded report and returns structured recommendations.Exports data, checks the result, and implements every change.
    Connected analystPulls permitted live data and prepares account-specific proposals.Reviews and approves each proposed action before execution.
    Controlled operatorExecutes only approved action types within the defined scope and constraints.Sets policy, handles exceptions, reviews logs, and can stop the workflow.

    Most teams should move through these modes in order. Live read access removes manual report handling without immediately exposing the account to automated edits. Proposal-only operation then shows whether the logic behaves well under current conditions. Controlled execution comes last, after the team knows which exceptions appear in real runs.

    Before enabling any write action, add these controls to the workflow:

    • Default-deny permissions. Claude may read or modify only the accounts, campaigns, objects, and action types explicitly included in scope.
    • Action-specific approval. Treat applying an existing extension, creating an ad experiment, changing a search-term response, and reallocating budget as separate permissions.
    • User-defined financial boundaries. A budget workflow must operate inside limits set by the account owner rather than deciding its own acceptable spend change.
    • Fail-closed behavior. Missing data, an invalid schema, an unavailable tool, or an out-of-scope request should stop the run instead of triggering a best guess.
    • A preview of the exact modification. The reviewer should see what object will change, its current state, the proposed state, and the reason before approving it.
    • An audit trail. Preserve the input scope, Skill version, findings, approval state, tool response, and execution result so a later reviewer can reconstruct what happened.
    • A conflict rule. Give each task one canonical Skill, because overlapping audit or optimization Skills can reintroduce the inconsistency the system was built to remove.
    • A recovery plan. Document how an executed change will be reversed when reversal is available. Keep irreversible or poorly understood actions manual.

    Budget reallocation deserves the tightest gate because it moves money between campaigns. A recommendation can still be automated: Claude can compare the permitted data, explain the proposed shift, and prepare the action. Execution should remain subject to the account owner’s constraints and approval until the workflow has demonstrated reliable behavior in proposal-only mode.

    Use acceptance checks rather than impressions when deciding whether a workflow is ready. The run should always return the required fields, stop on missing inputs, stay inside its declared scope, expose the evidence behind each proposal, and show the planned modification before execution. If any of those checks fail, improve the Skill or connection before expanding its authority.

    Choose PPC tasks by controllability, not novelty

    The best first automation is not necessarily the task consuming the largest budget or producing the most visible output. It is the task whose rules can be written clearly, whose evidence can be inspected, and whose mistakes can be contained.

    PPC workflowWhat the Skill should standardizeFirst safe deploymentExpanded deployment
    Search-term miningThe evaluation rubric, required evidence, exception handling, and recommendation format.Analyze an uploaded report and return proposals for review.Pull live search-term data and implement only separately approved actions.
    Ad copy generationHow landing-page information, keywords, user intent, and value propositions become proposed ad assets.Generate structured drafts for human review.Identify underperforming ads, prepare alternatives, and create an approved experiment.
    Account auditingThe checklist, severity logic, supporting evidence, and distinction between findings and remedies.Return a consistent audit with no account changes.Use live account data and apply permitted remedies, such as attaching an existing extension where appropriate.
    Budget reallocationThe comparison method, constraints, explanation, and escalation conditions.Produce proposed reallocations with no write access.Execute approved shifts inside account-owner limits and record every result.

    These four workflows can all progress from manual data handling to connected execution, but they should not receive the same authority by default. Search-term analysis, ad generation, account auditing, and budget reallocation involve different consequences and therefore need different approval paths.

    Score a candidate workflow against five practical questions before building it:

    • Does the task recur often enough that removing handoffs will matter?
    • Can an experienced operator state the decision rules without relying on unexplained instinct?
    • Are the required inputs available in a stable, inspectable form?
    • Can a reviewer verify the recommendation before the account changes?
    • Can the impact of an error be contained to a narrow scope?

    If the answers are weak, connecting more tools will not improve the workflow. Clarify the SOP first. Automation magnifies whatever is encoded: good judgment becomes repeatable, while an ambiguous process becomes ambiguous at greater speed.

    For a first deployment, we would favor a proposal-only search-term or account-audit workflow. Both make it easy to compare Claude’s output with an existing human process. Ad experiments can follow once asset review is defined. Budget execution belongs later because its consequences reach spend directly.

    Frequently asked questions

    What is Claude-powered PPC automation?

    It is a workflow in which a Claude Skill applies a repeatable PPC playbook, data connections supply the required campaign context, and explicit permissions determine whether Claude analyzes, proposes, or executes an action. A chat response alone is assistance; automation also handles the recurring context and handoffs.

    Do you need MCP to use a Claude Skill for PPC?

    No. You can run a Skill against a manually uploaded CSV and implement its recommendations yourself. MCP becomes relevant when you want Claude to retrieve live data or use connected account tools. Start with manual or read-only data if the Skill’s decision logic has not yet been validated.

    Which PPC workflow should you automate first?

    Choose a recurring workflow with written rules, inspectable inputs, a fixed output, and limited consequences when something goes wrong. Search-term mining or a checklist-based audit is usually easier to validate than autonomous budget reallocation. Keep the first version proposal-only so you can judge the logic before granting execution authority.

    How do you prevent inconsistent Claude outputs?

    Use one canonical Skill for the task, define required fields and allowed values, state how exceptions must be returned, and stop the run when required data is missing. Remove or narrow competing Skills that could handle the same request. Test structural consistency before connecting the output to another tool.

    Take the next recurring search-term review or account audit and write down its rubric, output contract, and stop conditions. Test that process on a CSV, connect live data in read-only mode, and grant write access only after the workflow passes explicit acceptance checks. That sequence turns Claude from another prompt window into a PPC system you can supervise.

    References


  • PPC Salary Polarization: A Plan for the Stalled Middle

    PPC Salary Polarization: A Plan for the Stalled Middle

    If you are six to 15 years into PPC and your pay has barely moved, adding another platform badge probably will not solve the problem. The market is not discounting every paid search professional equally. It is separating people who execute campaigns from people who influence revenue, margin, budgets and business decisions.

    That distinction gives you something useful to work with. You can benchmark the role you actually hold, identify the work keeping you in the compressed middle and build evidence for a better-paid agency, in-house or independent position.

    Key takeaways

    • U.S. median pay recovered to $87,500 for practitioners with three to five years of experience in 2026, but the six-to-nine-year median fell to $100,000 and the 10-to-15-year median remained close to its recent plateau.
    • Your employment model matters. In-house medians exceeded agency medians in every U.S. experience band reported for 2026, although the unusually high six-to-nine-year in-house figure was influenced by outliers.
    • AI fluency is becoming an expected capability rather than a separate reason to pay more. The valuable question is what decisions you make with the time automation gives back.
    • The strongest promotion case connects campaign choices to the commercial metrics your company uses, while stating attribution limits honestly.
    • Salary medians are market signals, not promises. Compare the same country, city, employment model, scope and compensation structure before judging an offer.

    The salary curve starts branching after five years

    The compressed part of the market becomes visible when you follow U.S. median pay by experience from 2022 through 2026:

    Experience20222023202420252026
    3-5 years$80,000$80,016$80,000$75,000$87,500
    6-9 years$100,000$110,000$108,000$110,000$100,000
    10-15 years$125,000$150,000$136,000$133,500$135,000
    15+ years$150,000$134,000$144,000$140,000$150,000

    The three-to-five-year rebound matters: employable early-to-mid-career practitioners are not simply being pushed toward lower pay. The pressure is more concentrated. The six-to-nine-year median returned to its 2022 level, while the 10-to-15-year median stayed between $133,500 and $136,000 for three consecutive years. That is nominal stagnation before you consider any loss of purchasing power.

    Experience still matters, but years alone no longer explain the result. U.S. practitioners in the 10-to-15-year band included top salaries above $300,000 alongside a $135,000 median. That spread is salary polarization in practical terms: people with similar time in the field can occupy very different economic roles.

    Do not turn the median into the salary you believe you are owed. The 2026 figures came from 445 practitioners across more than 50 countries, so smaller slices can move with the respondent mix. Use the numbers to ask why your role sits where it does, then compare your responsibilities with positions on the other side of the divide.

    Do not import a U.S. benchmark into another market

    Country and city can change the benchmark substantially. In the U.K., the 10-to-15-year median fell from £60,000 in 2025 to £50,000 in 2026. Across Europe, the corresponding median rose from €50,000 in 2024 to €65,625 in 2026, while the three-to-five-year median fell to €37,200, below its 2022 level. Berlin sat higher than the broader European figure, at approximately €76,000 for the 10-to-15-year band.

    Your benchmark should therefore match the market in which the employer sets pay, not merely the market in which its customers live. Compare currency, location, employment type and experience band before you use any figure in a negotiation. A global median may be interesting, but a local role with comparable scope is the more relevant reference.

    The senior gender gap needs its own audit

    Women slightly out-earned men at two earlier U.S. career stages in 2026: $87,500 versus $85,000 at three to five years, and $135,000 versus $130,000 at 10 to 15 years. The direction reversed sharply at 15 or more years. Men had a $150,000 median and women had a $120,000 median, a 25% gap relative to the women’s median.

    Those medians identify a disparity; they do not establish a single cause. Negotiation, promotion paths and access to high-value commercial relationships may contribute, but the aggregate numbers cannot isolate their effects.

    If you are assessing your own position, look beyond title and tenure. Record the accounts, budgets, revenue decisions and executive forums you are trusted to influence. Ask for the compensation band, the criteria for its upper end and the scope required for the next level. If you manage a team, compare pay and opportunity across people doing genuinely comparable work, then inspect who receives strategic accounts, client exposure, sponsorship and revenue ownership. A pay-equity review that ignores access to those career-making assignments will miss part of the mechanism.

    Your employment model is part of your compensation

    A continuous desk scene presents agency workstations, an in-house business setting, and an independent consultant's studio as three distinct employment environments.

    A job title does not tell you how close the role sits to a commercial decision. The 2026 U.S. agency and in-house medians make that difference visible:

    ExperienceAgency medianIn-house medianIn-house difference
    3-5 years$80,000$89,000+$9,000
    6-9 years$90,000$170,000+$80,000
    10-15 years$123,545$140,000+$16,455
    15+ years$120,000$140,000+$20,000

    The $170,000 in-house median for six to nine years was affected by outliers, so it should not be treated as a dependable offer target. The broader pattern is more useful: every in-house median exceeded the agency equivalent, and the 10-to-15-year difference was $16,455. The agency median also slipped from $123,545 at 10 to 15 years to $120,000 at 15 or more years. Seniority without a material change in scope did not produce a higher median in that slice.

    Agency experience can still build broad category knowledge, rapid diagnostic skill and exposure to many business models. The compensation problem appears when the role remains packaged as campaign delivery. Automation makes repeatable execution harder to bill as scarce expertise, and an agency cannot sustainably pay high salaries from work clients perceive as interchangeable.

    In-house roles can place paid media closer to forecasting, finance, product, inventory, sales and customer economics. That proximity creates an opportunity to influence decisions larger than the media account. It does not happen automatically. An in-house specialist who only receives a budget and returns a dashboard can remain execution-bound even with a better title.

    Independence creates a different ceiling. U.S. freelancers with comparable senior experience had median income of $202,895, compared with an agency median of $123,545, a difference of roughly $79,000 in the available data. Do not interpret that difference as an automatic raise. Freelance income and employee salary are not equivalent: benefits, taxes, business expenses, unpaid selling time, demand volatility and time off can all change what reaches you and how predictable it is.

    Treat employment model as a strategic variable rather than an identity. You do not need to leave agency work merely because an in-house median is higher. You do need to know whether your current environment can give you commercial ownership, high-value relationships and evidence that another employer or client will recognize.

    AI fluency is the floor, not the compensation case

    AI can make you faster without making your role more valuable. PPC professionals were saving approximately 5.2 hours per week with AI, yet corporate compensation practices point in the same direction: 61% of companies required AI skills while 55% offered no additional benefits for having them.

    The message is not that AI is unimportant. It is that tool access and basic fluency are becoming normal job requirements. A prompt library, automated analysis or faster draft is useful operational evidence, but it does not by itself prove that you should occupy the upper end of a salary band.

    Separate three kinds of value when you describe your work:

    • Task speed: You produce queries, briefs, summaries, variants or first-pass analyses faster.
    • Decision quality: You verify the output, identify missing context, reject weak recommendations and choose an appropriate action.
    • Commercial ownership: You connect that action to revenue, margin, forecast risk, customer quality or another metric the business uses to allocate money.

    The first layer can save time. The second protects the business from confident but incomplete output. The third gives leaders a reason to expand your scope and compensation.

    Reinvest the time AI saves in work that is difficult to commoditize. Meet the people who own finance, sales or product assumptions. Learn which conversions become profitable customers and which merely make the dashboard look healthy. Document where attribution is uncertain. Turn a recurring performance update into a recommendation that states the decision, expected business effect, risk and next check.

    When an AI-generated report arrives, the valuable person is not the one who can restate it most quickly. It is the person who can explain what is credible, what is missing and what the company should do next.

    Build evidence that you own outcomes, not just campaigns

    A paid media strategist presents abstract business results to colleagues from finance, sales, and product during a meeting.

    A vague claim that you are strategic will not move a compensation discussion. Build a small body of evidence that lets a hiring manager, client or executive see how you think. You can do this inside your current job before changing roles.

    1. Start with a real decision. Choose a budget allocation, measurement dispute, audience change, channel trade-off or forecast question you influenced. Routine optimizations are less persuasive unless they changed a larger decision.
    2. Name the business constraint. State what limited the choice: margin, inventory, lead quality, sales capacity, brand rules, measurement reliability or another genuine constraint. This demonstrates that you were not optimizing an account in isolation.
    3. Show your reasoning. Record the alternatives you considered, why you rejected them and what evidence changed your view. A result without reasoning can look accidental and is difficult for another employer to generalize.
    4. Follow the metric beyond the platform. Connect the paid-media signal to the furthest reliable business outcome available. Stop where the evidence stops instead of claiming credit for revenue you cannot support.
    5. Include uncertainty and downside. Explain attribution limitations, external factors and what could have invalidated the decision. Senior judgment includes knowing when the data cannot carry a confident conclusion.
    6. State what happened next. Record the action taken, the observed result and how the result influenced a subsequent budget or strategy decision. Remove confidential names and figures before using the case outside the company.

    A useful case-study sentence follows this structure: Because [business constraint], we chose [decision] over [alternative], which affected [business metric] during [relevant period]; [limitation] means the result should be interpreted as [appropriate level of confidence].

    Translate the metric ladder for your business model

    ROAS and CTR can be useful diagnostic metrics, but they are not interchangeable with profit. Your evidence should show that you understand the chain between an ad-platform result and the economic outcome the company values.

    • For ecommerce, follow reported conversion value toward realized revenue, gross margin or contribution margin where those figures are available. Call out returns, discounts or product-mix effects when they change the interpretation.
    • For lead generation, distinguish a form submission from a qualified opportunity and a qualified opportunity from closed revenue. If sales feedback is missing, identify that gap rather than presenting lead volume as the final outcome.
    • For subscriptions, separate initial acquisition from activation, retention and customer economics. A cheaper signup is not necessarily a more valuable customer.

    You do not need to own every downstream function. You need to understand how paid media enters the system, which handoffs can break and what evidence is required before the company increases or withdraws investment.

    Change the questions in your performance meetings

    The questions you ask reveal whether you are operating at campaign or business level. Bring questions that can change an allocation decision:

    • Which conversion event is most closely connected to realized revenue?
    • Which costs or downstream losses are absent from the current ROAS calculation?
    • What would make us reduce spend even if platform efficiency improved?
    • Where does sales, finance or product data disagree with the ad-platform view?
    • What decision will leadership make from this dashboard?
    • What evidence would justify moving more budget, and what evidence would stop us?

    Capture the answers and incorporate them into the next recommendation. That creates a visible record of scope expansion instead of waiting for a title change to prove you are ready.

    Choose the lane you are actually preparing for

    The right next move depends on the kind of risk, access and responsibility you want. Use the salary data to identify possibilities, then test whether the role gives you the conditions needed to create higher-value evidence.

    LaneWhat to seekEvidence to buildMain risk to examine
    AgencyCommercial strategy, executive client access, measurement ownership and influence over account directionDecisions that improve client economics, resolve strategic uncertainty or expand trusted scopeA senior title that still consists mainly of repeatable campaign delivery
    In-houseAccess to finance, product, sales, inventory and forecasting decisionsBudget recommendations connected to unit economics and company prioritiesA channel silo that receives targets but cannot influence the assumptions behind them
    Freelance or consultancyA differentiated problem, identifiable buyers, pricing power and a repeatable way to win workCredible outcome cases, a clear offer and proof that clients value your judgmentTreating business income as employee-equivalent pay without accounting for costs and volatility

    Before applying or negotiating, audit a representative period of your calendar. Label each substantial task as execution, decision support or business-outcome work. Then inspect the evidence, not just the time spent. If nearly every artifact is a build sheet, optimization log or platform dashboard, your strategic contribution may be real but invisible. Replace one recurring status report with a decision memo that links performance to a commercial choice.

    Use that memo in a scope conversation. Explain the decisions you already influence, show the evidence and ask what additional ownership is required for the target role and compensation band. If the employer cannot define that path or provide access to the necessary work, you have learned something more useful than a generic promise about future progression.

    Your next move does not have to begin with a resignation. Begin by changing the unit of value you present: from campaigns completed to decisions improved. That shift will tell you whether your current role can grow with you or whether it is time to take your evidence somewhere that prices it differently.

    References


  • How to Build an AI-Era SEO Stack That Improves Visibility

    How to Build an AI-Era SEO Stack That Improves Visibility

    You are probably not short of AI SEO tools to evaluate. The harder problem is deciding which ones deserve a place in your stack when several products generate briefs, audit pages, track prompts, suggest schema, and summarize reports in slightly different ways.

    The answer is not to buy the platform with the longest AI feature list. Build a system in which every tool produces evidence, that evidence leads to a named decision, and a person verifies the result before it changes a page. That gives you a stack that can support conventional search, answer engines, and generative search without paying for three versions of the same dashboard.

    Choose tools by the decision they improve

    Tool consolidation and AI adoption are happening at the same time. In the 2025 MarTech Replacement Survey’s cohort of 154 marketers who had replaced an application in the preceding year, 43.8% cited cost reduction, while 37.1% considered AI capabilities crucial and 33.9% wanted AI features in a new tool. Those figures describe one survey cohort, not the entire market, but they expose the decision most SEO teams now face: add AI capability without adding another layer of overlapping cost.

    Start by inventorying decisions rather than products. Your working stack needs to cover these jobs:

    • Technical discovery: identify crawling, indexing, rendering, internal-linking, response-code, and metadata problems that block or weaken discovery.
    • Demand and intent: connect queries and audience questions to the page that should answer them.
    • Content evaluation: find omissions, ambiguity, outdated information, weak evidence, and intent mismatches.
    • Entity and structured-data management: make the people, organizations, products, topics, and relationships on a page explicit and internally consistent.
    • Search and AI visibility monitoring: record rankings, impressions, mentions, linked citations, cited URLs, and the accuracy of generated descriptions.
    • Workflow and reporting: turn findings into tickets, briefs, annotations, summaries, and accountable next actions.

    One platform may cover several jobs. That is useful only when the outputs remain specific enough to act on. A single interface filled with generic scores is not an integrated stack; it is a consolidated reporting problem.

    Use a keep, replace, remove, or build audit

    Assign every current tool to one of four buckets:

    • Keep it when it produces evidence you use, fits the workflow, and has a clear owner.
    • Replace it when an important requirement is missing, the data cannot be exported, or another product can remove genuine duplication.
    • Remove it when nobody can name a recent decision that changed because of its output.
    • Build a narrow utility when your process, data model, or reporting logic is genuinely specific to your business.

    For each product, complete this sentence: “When the tool shows ______, the owner does ______, and success is checked with ______.” A blank in any position reveals the real gap. You may have a data problem, an ownership problem, or a validation problem rather than a software problem.

    Do not accept “AI-powered” as a requirement. Translate it into an observable capability. For example: classify a crawl export by likely impact; preserve citations when summarizing evidence; identify the URL cited in an answer; generate JSON-LD from approved fields; or turn approved metrics into a report narrative without changing the underlying numbers.

    Custom software has become more plausible for these narrow jobs. Homegrown applications accounted for 8.1% of replacements in the 2025 survey, up from 3.4% in 2024. That is evidence of renewed interest, not proof that building is automatically cheaper. Buy common infrastructure such as crawling when a mature product already solves the problem. Consider building the small connector, classification rule, or reporting layer that reflects how your organization actually works.

    Make vendors demonstrate the evidence trail

    A useful evaluation should begin with your data and end with your decision. Give each shortlisted tool the same representative input, then inspect the complete path from evidence to recommendation.

    • Can you see the page, query, answer, citation, crawl row, or measurement behind a recommendation?
    • Can you export the raw evidence and the processed result in a usable format?
    • Can you distinguish observed facts from the tool’s interpretation?
    • Can you segment results by page type, intent, market, language, or another dimension that matters to your decisions?
    • Can a reviewer correct the output without rebuilding the workflow outside the product?
    • Can you connect the finding to an owner, ticket, brief, or content update?
    • Does the tool replace an existing cost, or does it merely add a new dashboard?

    If a vendor can show a polished recommendation but not the evidence behind it, treat the output as a hypothesis. That distinction matters more in AI search because an answer can change across prompts and contexts. A tool that preserves the prompt, response, cited URL, date, and evaluation conditions gives you something you can audit. A visibility score without those components is much harder to interpret.

    Put AI on high-friction work, not final judgment

    AI earns its place in an SEO workflow when it reduces the effort between raw input and a reviewable result. It should not quietly become the authority that decides whether a claim is true, a page satisfies intent, or code is safe to deploy.

    Use a repeatable prompt specification rather than an improvised request. Give the model the page’s purpose, audience, target query or task, approved evidence, constraints, required output format, and review criteria. Tell it how to mark uncertainty and what it must not invent. The last instruction is especially important when the input does not contain enough evidence to complete every field.

    Accelerate content work without outsourcing expertise

    Several practical AI-assisted SEO workflows share the same pattern: the model creates options or performs a first pass, while a person supplies expertise and approves what gets published.

    • First drafts: provide a real brief, audience, intended angle, target query, source material, and exclusions. Ask for a structure before a full draft. The editor must then add original reasoning, examples supported by evidence, and the publication’s voice.
    • Content refreshes: give the model the existing page, its target intent, performance context, and current approved facts. Ask it to separate missing coverage, stale material, unsupported claims, structural problems, and optional expansion ideas. Verify each proposed change rather than accepting a rewritten page wholesale.
    • Titles and descriptions: generate variations within your supplied constraints, then choose or combine them manually. Check that each option accurately describes the page; an enticing promise that the page does not fulfill is not optimization.
    • FAQ development: use AI to organize questions found in query research and audience conversations. Remove duplicates, verify that each question belongs on the page, and write answers from approved evidence. Do not manufacture an FAQ merely to create schema.
    • Alt text: supply the image and its function in the surrounding page, not just a filename. Review the result for accessibility and accuracy. A target keyword belongs only when it naturally helps describe the image.

    The quality check is simple: can the reviewer identify what was supplied by the evidence, what was inferred by the model, and what was added by an expert? If those layers are blended together, the workflow is too opaque for reliable publishing.

    Use AI as a technical interpreter and code assistant

    Technical SEO often contains small, high-friction tasks that suit supervised generation:

    • Translate an error message or log excerpt into plain language, possible causes, evidence needed, and reversible diagnostic steps.
    • Generate a regular expression for a clearly described Google Search Console filter, then test it against examples that should and should not match.
    • Classify a crawl export into issue types and propose an order of investigation, while preserving the original rows used for each recommendation.
    • Generate JSON-LD from approved page facts and a named schema type, then compare every value with the visible page before validation.

    AI-generated code can be syntactically tidy and still be wrong. Test regular expressions on a limited dataset. Validate structured data before deployment. Treat suggested fixes to templates, redirects, canonical tags, robots directives, or rendering behavior as code changes that require review and a rollback path.

    Separate reporting observations from explanations

    AI can help scan performance exports for anomalies, compress a long report into an executive summary, or draft the narrative connecting several approved metrics. The model should never be allowed to turn correlation into a confident cause.

    Require reporting output in four labeled parts:

    • Observation: what changed in the supplied data.
    • Possible explanations: hypotheses that could account for the change.
    • Evidence still needed: data required to distinguish those explanations.
    • Next action: the check, experiment, or decision an owner should make.

    This structure makes AI useful without hiding uncertainty. It also creates prompts worth saving. A maintained prompt library for recurring briefs, crawl analysis, metadata, reporting, and schema tasks is more valuable than repeatedly improvising requests, because the inputs, constraints, and review standard become part of the operating process.

    Optimize pages for retrieval, comprehension, and citation

    A modular webpage with organized content and source cards is scanned, and one relevant passage is retrieved into an answer sphere.

    An AI visibility tool cannot compensate for a page that is inaccessible, unfocused, internally inconsistent, or difficult to support with a citation. Conventional SEO remains the retrieval layer. Answer engine optimization and generative engine optimization add a comprehension and representation layer on top of it.

    Build each important page around a clear evidence path:

    1. Assign one dominant intent. Decide which real question, comparison, task, or decision the page should resolve.
    2. State the direct answer early. Do not make a reader or retrieval system work through several paragraphs before discovering the page’s position.
    3. Break complex material into answerable units. Use descriptive headings, a direct explanation, applicable conditions, necessary caveats, and the supporting detail needed to act.
    4. Keep entity names and attributes consistent. A product, organization, person, date, or feature should not acquire different names or conflicting descriptions across the title, body, metadata, structured data, and linked pages.
    5. Support important claims where they appear. Link the words carrying the fact, and distinguish evidence from your interpretation.
    6. Connect related pages deliberately. Internal links should tell a reader what the destination adds, not rely on vague anchor text.
    7. Confirm technical availability. The intended canonical page must be crawlable, indexable where appropriate, renderable, and free from contradictory directives.

    This approach also makes editorial review easier. A reviewer can inspect one answer unit at a time and ask whether it is clear, supported, current, and useful. That is a better quality control mechanism than chasing an aggregate optimization score.

    Treat schema as a translation layer, not a ranking switch

    Structured data gives machines explicit labels for information that may otherwise be expressed only in prose. It can clarify what a page and its entities represent, but it does not repair weak content, establish that an unsupported claim is true, or guarantee a citation in an AI answer.

    Use this schema workflow:

    1. Extract the facts that are visibly present on the page.
    2. Select a schema type that accurately represents that page, such as Article for an editorial page or FAQ when genuine questions and answers appear in the visible content.
    3. Generate or author the JSON-LD from those approved facts.
    4. Compare every populated property with the visible page, including names, descriptions, dates, relationships, and URLs.
    5. Validate the markup. AI can generate Article or FAQ JSON-LD quickly, but the resulting code should still be checked with Google’s Rich Results Test where applicable.
    6. Publish through a controlled template or field mapping so later page edits do not leave stale values in the markup.
    7. Recheck the rendered page and structured data after deployment.

    Validation proves that a parser can understand the code and may surface eligibility issues. It does not prove that the data is accurate, that a search feature will appear, or that a language model will cite the page. Those remain separate checks.

    Schema also should not become an isolated technical project. AI-search strategy increasingly connects technical foundations, content, social activity, public relations, mentions, and citations. The practical lesson is not that every channel needs another tool. It is that your content and reporting systems need a shared view of the entities, claims, questions, and pages the organization wants to be known for.

    Measure AI visibility without disguising it as rank tracking

    An analyst compares how identical glowing inputs produce different webpage fragments and citation markers across several answer portals.

    Rank tracking records an ordered search result under defined conditions. AI answer monitoring records a generated response that may vary with wording, context, system behavior, market, and time. Putting both into one visibility score may be convenient, but it can hide what actually changed.

    Keep the layers separate in your scorecard:

    Measurement layerRecordDecision it supports
    Technical availabilityCrawl state, indexability, canonical target, rendering result, structured-data validityWhether the page can participate as intended
    Conventional searchQuery, landing page, impressions, clicks, position context, conversion outcomeWhere discoverability or intent alignment needs work
    Generated answersExact prompt, engine, date, answer, brand mention, linked citation, cited URL, factual accuracyWhether the brand is represented, supported, and described correctly
    Content operationsAI-assisted task, reviewer changes, rejection reason, approved output, workflow ownerWhere automation saves effort or creates rework
    Stack economicsLicense cost, active use, duplicated output, integration burden, maintenance ownerWhether to keep, replace, remove, or build

    Clicks remain useful, but they cannot describe every zero-click or AI-generated experience. That is one reason teams now seek tools that can measure visibility beyond traditional rankings and clicks. Do not solve that limitation by treating every brand mention as equivalent. An unlinked mention, a citation to your page, a citation to someone else’s page, and an inaccurate description are four different outcomes.

    Create a repeatable AI-answer benchmark

    Build the benchmark from questions that matter to the business, not prompts chosen because the brand already performs well. Include the informational questions, comparisons, objections, and decision-stage tasks that your priority pages are meant to resolve.

    1. Freeze the wording of each benchmark prompt and document its intended user intent.
    2. Record the engine, market or language conditions, date, complete response, citations, and cited URLs.
    3. Capture a baseline before changing content, templates, structured data, internal links, or external promotion.
    4. Change a single meaningful variable where the workflow allows it, and annotate every other known change.
    5. Run the same benchmark on a planned cadence rather than testing only when you expect a favorable answer.
    6. Look for repeated patterns across relevant prompts before claiming that an optimization caused the outcome.

    A mention is not automatically a success. Review whether the answer gives the correct name, category, attributes, limitations, and relationship to the user’s question. Also record which URL earned the citation. If an outdated page or a third-party page is repeatedly cited, that finding should lead to a different action than a simple absence from the answer.

    Measurement should also expose automation failures. Record which AI suggestions were rejected and why. Repeated factual corrections point to an evidence or prompting problem. Repeated voice corrections point to an editorial specification problem. Repeated technical corrections point to a workflow that needs stronger tests, not a model that needs more freedom.

    Key takeaways and your first move

    • Choose an AI SEO tool only when you can name the decision it improves, the evidence it preserves, the owner who acts, and the way the result will be checked.
    • Keep conventional crawling, indexing, intent, and content quality at the base of the stack. AI visibility monitoring adds a measurement layer; it does not replace the retrieval layer.
    • Use AI for first passes, classification, variants, interpretation, and formatting. Keep factual approval, strategic judgment, and deployment control with a qualified reviewer.
    • Make pages easier to retrieve and cite by answering a defined question, using consistent entities, supporting claims in place, and connecting related pages clearly.
    • Use schema only when it matches visible content. Validate the code and verify the facts separately.
    • Track generated answers with their exact prompts, citations, cited URLs, conditions, and accuracy. Do not compress unlike outcomes into one unexplained visibility score.

    Your first move does not require a new subscription. Open the current stack inventory and complete the evidence-action-validation sentence for every tool. Remove the entries nobody can complete. Then choose one recurring workflow with visible friction, such as turning a crawl export into reviewed tickets or turning an approved brief into a review-ready draft. Define its inputs, output, owner, and checks before testing automation.

    Once that workflow is reliable, extend the same operating model to structured data and AI-answer monitoring. You will know what to buy because the missing capability will be explicit, and you will know whether it worked because the evidence trail already exists.

    References


  • How to Use AI Review Replies in Google Business Profile

    How to Use AI Review Replies in Google Business Profile

    One click can turn an unanswered review queue into a wall of polite, interchangeable replies. That is faster, but it is not the outcome you want. A useful response shows the reviewer, and every prospective customer reading along, that someone understood the actual experience.

    If Google’s AI reply control appears in your Google Business Profile, treat it as a drafting layer inside a human approval process. The goal is not to publish more words. It is to respond faster without inventing facts, exposing customer information, making promises you cannot keep, or sanding every reply down to the same generic apology.

    First, verify what the AI control does in your account

    Google has conducted a limited test of AI-generated review replies within Google Business Profile. The tested feature creates a proposed response that a business can review, edit, and manually submit.

    Do not assume every profile has the same interface or publication flow. Availability has varied between accounts and individual reviews. Documented appearances included the United States, Brazil, and India, while the feature was not yet broadly visible in Europe. Some prompts focused on older unanswered negative reviews.

    The most important variation concerns bulk use. At least one observed version could generate suggestions for multiple reviews. Experiences differed after generation: some still involved a review step, while others appeared more automated and required no edits. That difference matters because generating twenty drafts is reversible; publishing twenty unchecked replies under your business name is not.

    Before touching your backlog, use one low-risk positive review to inspect the actual workflow. Confirm whether the tool only creates a draft, whether any bulk action pauses for approval, which user is publishing, and which location profile is active. If you cannot clearly identify the final approval step, do not use the bulk option.

    This caution is not an argument against AI assistance. Thoughtful review engagement can influence trust and conversion decisions. It is an argument for putting the speed in the drafting stage, where mistakes are still easy to correct.

    Match human oversight to the risk of the review

    Three review-response situations show increasing human oversight from a routine compliment to a serious customer complaint.

    Not every review needs the same amount of editing. A short five-star comment is different from a complaint involving a disputed charge, a safety concern, or personal information. Use the review’s factual and reputational risk, not the size of your queue, to decide how much authority AI receives.

    Review typeAppropriate role for AIRequired human check
    Simple positive reviewCreate a short first draftMake sure the reply reflects what the reviewer actually wrote and adds no invented detail
    Specific praise naming an employeeDraft an acknowledgementCheck spelling, context, privacy, and your policy on repeating employee names publicly
    Star rating with no written commentSuggest a brief neutral responseDo not infer a visit, purchase, problem, or reason that the reviewer never stated
    Mixed or negative service reviewProvide a structure, not a finished answerVerify the incident, any corrective action, the contact route, and every promise
    Claim involving safety, discrimination, payment, personal data, or legal actionNo autonomous publicationEscalate to the responsible manager and publish only an approved, factual response

    The dividing line is not positive versus negative. It is whether the reply could create a false factual record, disclose something private, or commit the business to an action. A warm thank-you usually has little exposure. A sentence claiming that a refund was processed has much more.

    Negative reviews also demand more than a longer apology. Generic language such as “we strive to provide excellent service” can make the reply feel automated because it does not identify what went wrong or what the customer should do next. Use AI to establish a calm tone, then replace abstractions with verified detail.

    Build a review-to-reply workflow that catches AI mistakes

    An overhead desk scene shows a customer review moving through AI drafting, fact-checking, privacy review, and human approval.

    A reliable process separates understanding, drafting, verification, and publication. When those tasks collapse into one button, a plausible sentence can escape before anyone asks whether it is true.

    1. Confirm the profile and context. Check the business location, star rating, review text, review date, and any named service or employee. Multi-location teams should be especially careful: a polished response posted from the wrong location is still wrong.
    2. Classify the review before generating anything. Decide whether it is praise, a question, a mixed experience, a service failure, or a sensitive allegation. A five-star review containing a complaint is not simple praise. A one-star rating with no text does not give you an incident to explain.
    3. Create a small set of usable facts. Separate what the reviewer publicly stated from what your team has verified. Useful facts can include the location, service named, confirmed action already taken, approved contact channel, and role responsible for follow-up. If a detail is neither in the review nor verified internally, leave it out.
    4. Decide what the response must accomplish. A reply should normally do one primary job: thank the customer, acknowledge a problem, answer a question, correct a material misunderstanding, or move a sensitive discussion to an appropriate channel. Do not let the generated draft wander across all five.
    5. Generate the draft, then edit sentence by sentence. Keep a sentence only if it acknowledges a real detail, supplies verified information, or gives the customer a useful next step. Remove filler, excessive apologies, promotional language, and service or location keywords inserted for their own sake.
    6. Run a pre-publication check. Verify every proper noun, operational claim, promise, contact method, and time-sensitive statement. Make sure the tone fits the review. Do not request or repeat addresses, card details, health information, account data, or other sensitive information in a public reply.
    7. Close the operational loop. Publish the response, but route the underlying issue to the team that can fix it. If several reviews mention the same delay, handoff, product problem, or communication gap, the important result is not a larger collection of apologies. It is a corrected process.

    Assign ownership before volume increases. Someone should be responsible for low-risk approvals, someone should handle sensitive escalations, and location managers should know which statements they are allowed to make. Otherwise, the AI tool may reduce drafting time while adding an approval bottleneck that nobody owns.

    Edit generated replies into specific, human responses

    You do not need a different writing system for every review. You need a few reliable response shapes and the judgment to fill them only with information you can support.

    For a positive review, reflect one meaningful detail

    A practical shape is: thank the reviewer, mention one detail they supplied, and close without turning the response into an advertisement.

    Template: Thanks, [reviewer name, if appropriate]. We are glad [specific detail from the review] made your [visit or service experience] easier. We appreciate you taking the time to mention it.

    One detail is enough. Do not repeat the full review, invent what the customer purchased, or attach a string of services and place names in the hope of gaining search visibility. A review reply is a customer-service message, not a miniature landing page.

    For a negative review, move from acknowledgement to action

    A useful negative-review reply has three parts: acknowledge the experience described, state only what has been verified, and provide an appropriate next step. It does not need to settle the entire dispute in public.

    When the event and next step are verified: We are sorry your order was not ready at the confirmed time. Please contact [approved channel] with [non-sensitive identifier] so [responsible role] can review what happened and follow up.

    When important facts are still unknown: We are sorry to hear about the delay you described. We would like to understand what happened. Please contact [approved channel] so [responsible role] can review the details with you.

    The second version acknowledges the complaint without pretending the business has already completed an investigation. Do not write that an issue was fixed, a refund was issued, an employee was disciplined, or an event never happened unless the statement has been verified and approved for public release.

    For an older unanswered review, acknowledge the timing

    AI prompts may bring older negative reviews back into the queue. Do not publish a reply that reads as if the incident occurred yesterday. If accurate, open with a simple acknowledgement: We are sorry we missed your feedback when you first shared it. Then provide a contact route that is valid now.

    A late reply can still show prospective customers how the business handles criticism. It should not promise a retroactive resolution that the current team cannot provide. If no meaningful next step remains, keep the response brief, acknowledge the gap, and avoid manufacturing activity merely to make the reply sound complete.

    Key takeaways

    • Treat every AI-generated reply as an unverified draft until a person checks its facts, promises, tone, and privacy implications.
    • Test the exact approval flow in your own Google Business Profile before using any bulk-generation option.
    • Use AI more freely for low-risk acknowledgements and require stronger human review as factual or reputational exposure increases.
    • Personalize with details the reviewer supplied, not plausible details the AI added.
    • Move sensitive cases to an approved private channel without repeating customer information in public.
    • Use patterns in reviews to fix the underlying operation rather than automating repeated apologies.

    Start with one low-risk reply and write a short approval rule before working through the backlog. Once the same checks reliably protect single drafts and bulk suggestions, you can increase speed without handing your public reputation to an unchecked generator.

    References


  • How to Build an AI-Assisted SEO Workflow You Can Trust

    How to Build an AI-Assisted SEO Workflow You Can Trust

    You have the data. The problem is getting Google Search Console, GA4, Google Ads, and AI visibility signals into the same decision before the opportunity goes stale. Copying numbers between tabs is slow, and asking an AI assistant to interpret an unstructured pile of exports is fast but difficult to trust.

    A useful AI-assisted SEO workflow fixes both problems. Scripts collect a defined set of data, the AI analyzes local files under explicit rules, and you approve every consequential action. The goal is not automated SEO judgment. It is faster, traceable analysis that gives your judgment better inputs.

    Start with the decision, not the AI tool

    The most common design mistake is automating a report before deciding what the report should change. That produces a polished summary, not a workflow. Begin with one recurring question that currently takes too long to answer.

    A strong first use case is paid-organic overlap: which paid search terms consume budget even though related organic queries already perform well? This question becomes much easier when an assistant can examine Google Ads search terms alongside Search Console query and page data. It also exposes an important boundary: organic visibility alone does not prove that paid coverage is unnecessary.

    Define the decision before you build anything. For paid-organic overlap, the decision might be whether a term should remain unchanged, receive a controlled bid test, or be investigated further. The AI should identify candidates and show its evidence. It should not label spend as waste or change a campaign on its own.

    Write a small analysis contract for the question:

    • Decision: Identify search terms that may justify a paid-coverage test because corresponding organic queries and landing pages are already strong.
    • Time window: Use one explicit date range across every compatible dataset. If a file covers a different period, flag it instead of silently joining it.
    • Unit of analysis: Keep the search term, organic query, landing page, and campaign visible. Do not collapse everything into a keyword total.
    • Matching rule: Show exact normalized matches first. Put close or semantic matches in a separate group so a human can inspect them.
    • Evidence: Return the relevant metrics, file names, and row references behind every candidate.
    • Allowed outcomes: Use labels such as keep, test, and investigate. Avoid definitive labels such as waste unless your business rules actually establish that conclusion.
    • Exclusions: State which terms or campaigns should not be evaluated automatically, including any branded, defensive, regulated, or strategically protected coverage.

    This contract does more than improve the prompt. It tells you which data must be collected, which joins are legitimate, and where human review belongs. If you cannot describe the decision in these terms, adding another API will not make the workflow useful.

    Build a small, auditable SEO data project

    Four abstract data sources connect to a compact set of organized file folders and a central analysis workspace.

    You do not need a data warehouse to begin. A practical local project can separate configuration, fetchers, platform data, and generated reports. That separation makes failures easier to diagnose and prevents an AI-generated conclusion from being mistaken for raw platform data.

    Project areaWhat belongs thereOperating rule
    ConfigurationClient details and the property or account identifiers needed by each fetcherKeep secrets out of this file; configuration and credentials are different things
    FetchersOne Python script for each platform, such as Search Console, GA4, Google Ads, or AI visibilityEach script should collect data and save it without making strategic recommendations
    DataRaw or normalized JSON files, separated by platform and refreshDo not overwrite the evidence used for a previous decision
    ReportsAnalysis tables, exceptions, recommendations, and review notesEverything here is derived and should be reproducible from the data files

    The collection layer should be deterministic. Given the same credentials, request, and date range, a fetcher should retrieve and store the same type of data. The AI belongs above that layer, where language and reasoning are useful. This distinction prevents a vague instruction from changing both the data collection method and the interpretation at the same time.

    Set up the project in this order:

    1. Create one project directory per client or site. Separate directories reduce the chance of mixing property identifiers, files, or recommendations.
    2. Configure authentication. A Google Cloud service account can support Search Console and GA4 access, while Google Ads requires its own OAuth setup. Grant only the access the workflow needs.
    3. Specify each fetcher in plain language. Name the platform, property, date range, dimensions, metrics, output location, and required error behavior. An AI coding assistant can draft the Python, but you still need to inspect and test it.
    4. Save platform data separately. Search Console query and page performance, GA4 traffic data, Google Ads search terms, and AI citation data should remain distinguishable even when a later analysis combines them.
    5. Add a refresh manifest. Record when each file was created, the period it covers, the account or property it belongs to, and whether collection completed successfully.
    6. Test with a narrow request. Pull a small, known date range first. Compare several returned rows with the platform interface before trusting a larger refresh.

    Keep credentials outside the project data and out of version control. If a credential is exposed, revoke or rotate it rather than assuming deletion from a file has removed the risk. Read-only access is the safer default for an analysis workflow; campaign edits and site changes should remain separate, deliberate operations.

    One agency workflow reports roughly an hour for the foundational setup, about 35 minutes to configure a new client, and about 20 minutes for a monthly refresh. Treat those figures as observations from one implementation, not universal benchmarks. Your first setup will depend on authentication, account complexity, field requirements, and how much validation you build in. The useful promise is repeatability, not a particular stopwatch result.

    Use prompts that produce evidence, not commentary

    Once the files exist, resist the easy prompt: analyze my SEO data. It gives the model too much freedom to decide what matters, how platforms should be joined, and which gaps can be ignored. A production prompt should define the question, permitted files, join logic, output structure, and stopping conditions.

    Separate validation from interpretation

    Run a validation prompt before asking for strategy. Tell the assistant to inventory the files, report their date ranges, identify missing or empty datasets, check whether property identifiers agree with the configuration, and list fields that are unavailable. It should stop if a required input is absent.

    Only then run the decision prompt. This two-pass pattern matters because an articulate model can produce a plausible recommendation from incomplete data. A visible failure is safer than a polished answer built on a missing Ads export or the wrong Search Console property.

    Give the assistant a reusable analysis template

    A practical prompt can follow this structure:

    • Role: Act as an analyst. Do not alter files, accounts, campaigns, or site content.
    • Question: State the single business or SEO decision the analysis must support.
    • Inputs: List the exact directories and files the assistant may use.
    • Checks: Confirm account identifiers, date coverage, required fields, and successful refresh status before analysis.
    • Method: Describe the allowed joins and calculations. Require exact matches to remain separate from inferred or semantic matches.
    • Output: Return a candidate table, an exception table, and a short decision note. Every row should identify its supporting files and metrics.
    • Uncertainty: Mark conclusions as observed, calculated, inferred, or recommended. If the files cannot answer something, say that directly.

    For paid-organic overlap, ask for search terms with spend and conversion context, their matched organic queries, the relevant organic pages, the match type used by the analysis, and the reason each term deserves review. Require unmatched terms and ambiguous mappings in a separate exception table. That exception table often matters more than the recommendation list because it shows where automation is least trustworthy.

    For content analysis, change the unit of analysis from search term to page. Ask the assistant to map Search Console query and page performance to the corresponding GA4 page data, report any path-normalization assumptions, and keep platform metrics under their original names. Do not let it merge differently defined metrics into a synthetic score unless you supplied and approved the formula.

    For AI search visibility, citation data exported from tools such as Scrunch or Semrush can be added as CSV or JSON. Keep that dataset in its own directory and label its collection method. A citation or mention is not automatically equivalent to an organic click, a GA4 session, or a conversion. Use the combined view to investigate relationships, not to pretend the platforms measure the same event.

    Install a review gate before any SEO action

    An analyst inspects abstract evidence tiles at a closed gate before approving workflow actions.

    Traceability is what turns an interesting AI answer into an operational workflow. A recommendation should survive a simple challenge: can another person find the supporting rows, repeat the calculation, and explain why the proposed action follows?

    Use this review gate before changing bids, briefs, internal links, structured data, or published content:

    1. Verify identity and time. Confirm that every dataset belongs to the intended property or account and covers the expected period.
    2. Inspect collection exceptions. Empty files, partial refreshes, changed field names, and authentication failures must be resolved or carried into the analysis as explicit limitations.
    3. Recalculate a sample. Manually reproduce several important joins or calculations from the underlying rows. Include at least one recommendation and one excluded case.
    4. Challenge the matching logic. Exact query matches are not automatically equivalent when intent, geography, device context, landing pages, or brand strategy differ. Semantic matches require even more scrutiny.
    5. Separate fact from judgment. A metric is observed, a ratio may be calculated, a relationship may be inferred, and an action is recommended. The report should not blur those categories.
    6. Check the downside. Reducing paid coverage can affect visibility, testing capacity, or strategically important terms. Editing content or structured data can create indexing or accuracy problems. Use a reversible test when the consequence is uncertain.
    7. Record the decision. Save what was approved, rejected, or deferred, who reviewed it, and which input refresh supported it. The next cycle needs this context.

    Do not ask the model whether its own answer is correct and treat the response as validation. Give it a separate adversarial task: find rows that contradict the recommendation, identify alternative explanations, and list the additional data that would change the conclusion. Then inspect the evidence yourself.

    This is the right mental model: the assistant is a fast analyst working from bounded files, not the owner of SEO strategy. AI can accelerate extraction and cross-platform analysis, but strategic judgment and verification still belong to the human reviewer. Review its work with the same care you would apply to output from a new team member who is capable but unfamiliar with the account.

    Key takeaways for a repeatable operating loop

    • Automate collection before interpretation. Scripts should retrieve and store defined data; the AI should reason over those files without silently changing how they were produced.
    • Start with one decision. A recurring question such as paid-organic overlap gives the workflow a clear input contract, output, and review standard.
    • Preserve the evidence chain. Keep raw platform data separate from derived reports, timestamp each refresh, and require file and row references for recommendations.
    • Make uncertainty visible. Exact matches, semantic matches, missing data, assumptions, observations, and recommendations should never appear as one undifferentiated answer.
    • Keep consequential actions human-approved. Use read-only access for analysis and move campaign or site changes into a separate, reversible approval process.
    • Save decisions, not just reports. The monthly loop should retain what changed, why it changed, and what the next refresh must measure.

    Pick the SEO decision that consumed the most manual reconciliation in your last reporting cycle. Write its analysis contract, connect only the datasets required to answer it, and test the workflow on a narrow date range. Once the evidence survives review, schedule the refresh. Add the next use case only after the first one reliably changes a real decision.

    References