Tag: AI Automation

  • Google Ads AI Automation: A Practical Oversight Framework

    Google Ads AI Automation: A Practical Oversight Framework

    You’re probably not worried that Google Ads lacks automation. You’re worried that the account can spend real money, distribute real creative, or create a policy problem before anyone can explain what happened.

    Good oversight doesn’t require a person to second-guess every machine-made suggestion. It requires you to decide in advance where AI may observe, recommend, execute, and enforce – and what evidence, limits, and recovery path each level requires. That turns automation into a controlled operating system instead of an open-ended permission slip.

    Give automation a job description, not blanket trust

    “Do we trust the AI?” is the wrong approval question. Trust isn’t a single setting, and the risk changes with the task. An assistant can be useful for finding an issue while being unqualified to change the account that contains it.

    • Observe: summarize performance, identify patterns, or surface assets and settings for inspection.
    • Recommend: diagnose a problem and propose a setting, campaign, measurement, or creative change.
    • Execute: change bids, budgets, reach, goals, assets, or other live account controls.
    • Enforce: restrict delivery, flag a policy concern, suspend an account, or route an appeal.

    Each step needs a stronger control than the one before it. Observation may require a quick accuracy check. A recommendation needs current account evidence. Execution needs a defined scope, financial limits, an owner, and a rollback path. Enforcement needs an evidence trail and a reliable way to challenge an incorrect decision.

    Ads Advisor illustrates why those distinctions matter. In hands-on use, it drew on the wider web and challenged default settings, including a suggestion to deselect Display Network and Search Partners when creating a Search campaign. That doesn’t make those settings universally wrong. It shows that an AI assistant can introduce a useful question rather than simply repeat Google’s defaults.

    The same assistant also produced questionable performance diagnoses and referred to an obsolete Tools & Settings > Conversions path. Breadth of information and freshness of information are separate qualities. A confident answer can still depend on an old interface, the wrong reporting scope, or an incomplete reading of the account.

    Ads Advisor’s limited autonomy creates another important distinction: advice that stops before implementation is safer than an unexplained account change, but it isn’t automatically safe. A person can still turn weak guidance into an expensive action. Before accepting any recommendation, require clear answers to these questions:

    • Goal fit: Which business outcome is this supposed to improve, and is that the outcome the campaign is actually configured to pursue?
    • Current evidence: Which live account data supports the diagnosis? Can you reproduce the observation in the current Google Ads interface?
    • Exact scope: Which campaign, network, audience, asset, conversion action, or account setting would change?
    • Reversibility: What could the change affect, and how would you restore the previous state?
    • Accountability: Who approves the change, who checks the result, and who intervenes if a stop condition is reached?

    If the assistant cannot identify the affected object or the evidence behind its recommendation, you don’t yet have a change request. You have a hypothesis. Investigate it, but don’t grant it execution authority.

    Put the strictest gates around money, measurement, and assets
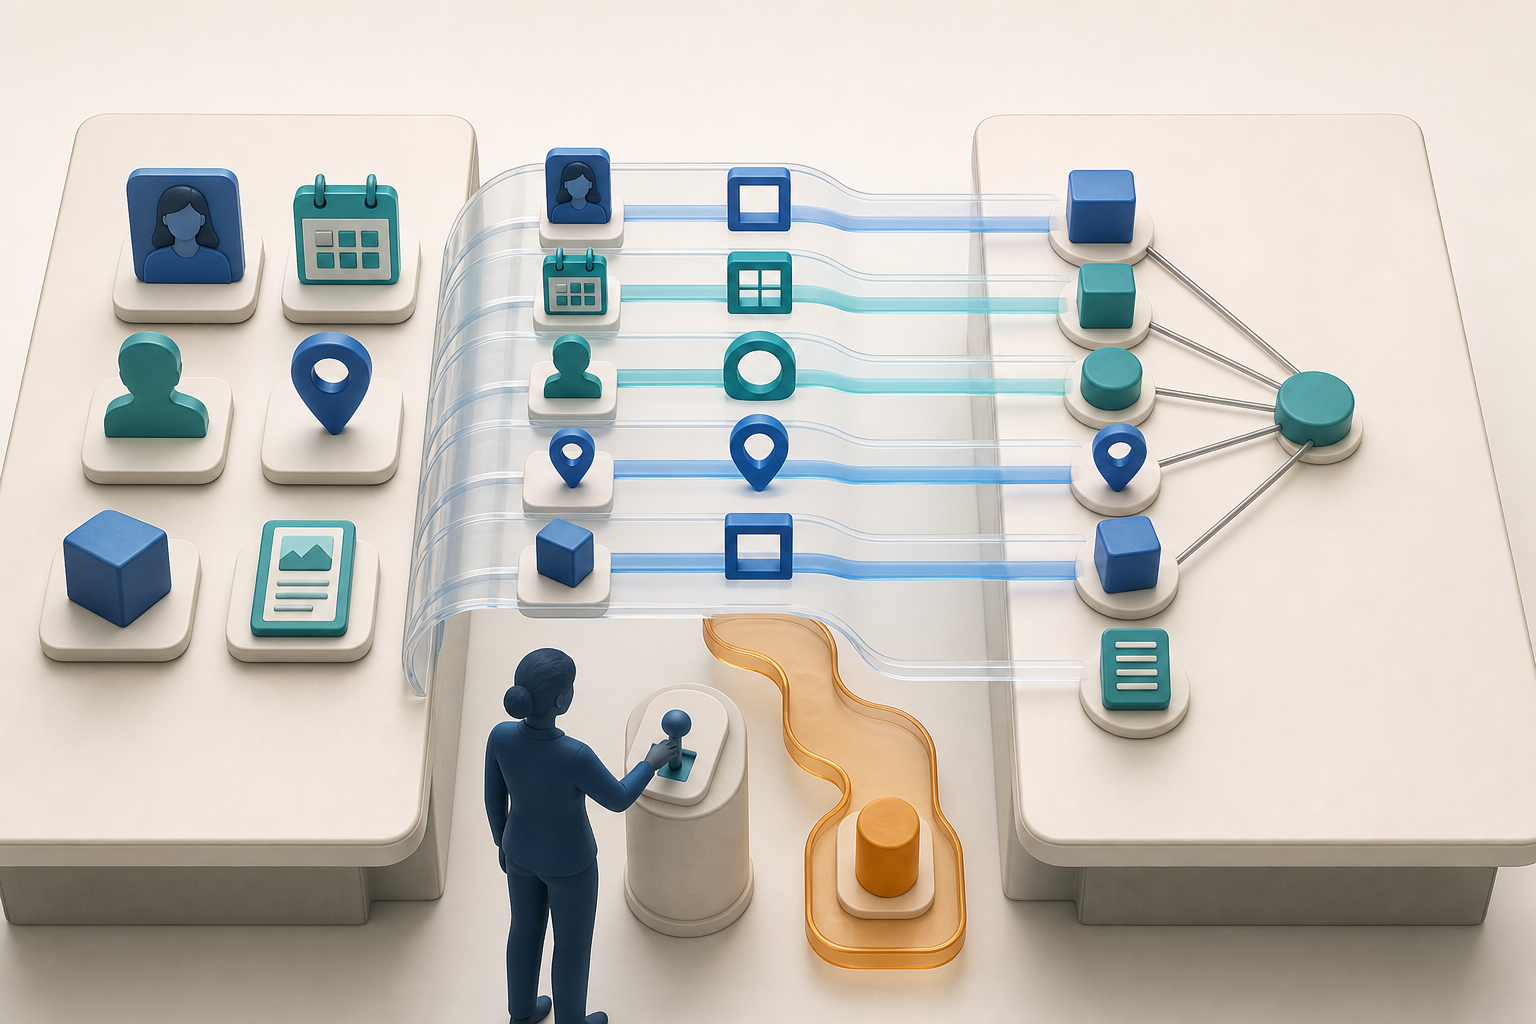
    Budget tokens, measurement markers, and creative tiles pass through separate approval gates before entering an automated advertising system.

    Oversight should follow consequence, not novelty. A fresh headline suggestion and an automatic budget decision may both use AI, but they don’t deserve the same approval path. The practical dividing lines are financial exposure, measurement integrity, distribution rights, and account access.

    Automation areaUseful role for AIRequired human gate
    Campaign adviceSurface possible causes, settings, and checksVerify the live interface, reporting scope, business objective, and account evidence
    Spend and reachPropose or execute changes within an approved strategyDefine eligible campaigns, protected settings, financial boundaries, and stop conditions
    Conversion measurementIdentify anomalies or recommend outcome signalsConfirm what counts as a conversion and whether it represents real business value
    Creative selectionSurface, combine, or distribute available assetsVerify provenance, usage rights, brand suitability, destination, and placement context
    Policy enforcementDetect suspected violations and prioritize casesPreserve the evidence behind decisions and maintain a documented appeal path

    Define an automation envelope for spend and measurement

    An automation envelope is a short specification of what the system may optimize and where its authority ends. Write it before enabling execution, not after an unexpected result.

    • Business goal: State the outcome in commercial terms, then identify the Google Ads conversion signal being used as its proxy.
    • Scope: Name the campaigns, networks, markets, products, audiences, and assets that are eligible. Anything not named remains outside the envelope.
    • Permission level: Specify whether AI may observe, recommend, draft, or execute. Don’t let a recommendation tool quietly become an approval mechanism.
    • Protected constraints: Record the budgets, brand rules, excluded areas, legal requirements, and measurement definitions that automation may not alter.
    • Stop conditions: Define the events that force review, such as a broken conversion signal, unexpected distribution, a policy warning, or a proposed expansion beyond the approved scope.
    • Owner: Assign a person who can inspect the account, approve changes, and reverse them. “Marketing” or “the agency” is not a usable owner.

    Don’t borrow a universal percentage or generic performance threshold for this envelope. Materiality depends on your economics, normal conversion volume, sales cycle, and tolerance for wasted spend. Set boundaries from the account’s real financial model, then document why they are appropriate.

    Treat conversion configuration as a financial control. An automated campaign can optimize efficiently toward the wrong outcome if a primary signal stops representing revenue, qualified demand, or another intended result. Any material change to conversion definitions should trigger a fresh approval of the automation envelope.

    Treat suggested creative as unverified inventory

    Creative automation introduces a different risk: finding an asset isn’t the same as having permission to distribute it. An experimental Performance Max workflow has surfaced videos previously used in X campaigns inside Suggested creatives. Those videos were uploaded to a YouTube channel linked to the advertiser, while a disclosure identified Pathmatics by Sensor Tower as the third-party provider behind the sourcing.

    Google prompts advertisers to confirm that they hold the necessary usage and distribution rights. It also clarified that the experiment concerns reuse of social creative, not the addition of X ad inventory to the Google Display Network. That distinction matters: the system is suggesting an asset, not proving ownership or announcing a new media placement partnership.

    Require a provenance record before approving any suggested asset. It should identify the original file, rights holder, permitted channels and markets, approval status, expiration or usage restrictions, and the YouTube destination that will host it. Check music, talent, stock footage, agency, and creator agreements separately where they apply. Permission to run something on one social platform may not include every Google placement or a new public hosting location.

    If you cannot establish the chain of rights, don’t publish the asset. Use an owned replacement, obtain written clearance, or have qualified counsel resolve a disputed license. The specific downside isn’t merely an off-brand ad: it can be unauthorized distribution, a contractual breach, or an asset appearing somewhere the rights holder never approved.

    Run meaningful recommendations through a change record

    A recommendation becomes auditable only when you translate it into a proposed account change. “Improve PMax performance” is not auditable. “Replace these named assets in this campaign because the current set lacks the approved message” is closer: it identifies the object, action, and reasoning that a reviewer can inspect.

    1. Save the baseline. Capture the relevant settings, conversion definition, asset state, distribution scope, and performance view before anything changes.
    2. Rewrite the recommendation as a testable claim. State what is believed to be wrong, which evidence supports that belief, what will change, and what result would count as improvement.
    3. Inspect the live account. Confirm that the referenced setting and metric still exist, use the intended reporting scope, and apply to the named campaign. A stale menu path is a reason to investigate, not proof that the underlying idea is wrong.
    4. Bound the blast radius. Limit the change to the smallest useful scope and identify every downstream object it can affect, including spend, reach, conversion reporting, product feeds, landing pages, and hosted creative.
    5. Record approval and recovery. Name the approver, executor, review trigger, protected constraints, stop conditions, and exact rollback action.
    6. Judge the outcome on a consistent basis. Compare the same scope and measurement definition, note outside changes, and decide whether to retain, extend, revise, or reverse the change.

    Ask an AI advisor to provide its account observations, reasoning, exact affected settings, assumptions, and uncertainty. An explanation isn’t proof of accuracy, but the absence of one is an approval blocker. You still need to reproduce important observations in the account rather than trusting the assistant’s description of the interface.

    Avoid stacking unrelated changes when you need to learn what caused the result. If budget, targeting, creative, and conversion measurement all change together, the final performance number won’t tell you which recommendation helped. Narrow the scope or separate unrelated changes so the record can support a decision rather than merely describe activity.

    The record doesn’t need to become paperwork for every spelling correction. Require it when a recommendation can materially change spend, reach, measurement, creative distribution, compliance, or account access. Those are the moments when reversibility and accountability matter more than speed.

    Prepare for automated enforcement before access is interrupted
    Two advertising specialists manage a paused campaign pipeline using an evidence archive, backup access key, and manual recovery control.

    Automation is also operating on the enforcement side of Google Ads. Google reports that Gemini-enhanced detection helped reduce incorrect account suspensions by more than 80%, while appeal processing became 70% faster and 99% of appeals were resolved within 24 hours.

    Those are encouraging Google-reported outcomes, not a guarantee for an individual advertiser. “Resolved” means a decision was reached; it does not mean 99% of suspended advertisers were reinstated. The reported improvements also accompanied clearer policy language and changes to internal review and appeal processes, so it would be too simple to credit every gain to Gemini alone.

    Faster handling changes how quickly you may receive an answer. It doesn’t remove the need to prove your case. Maintain an account recovery file while campaigns are healthy:

    • Official account and business identifiers, billing details, and current authorized contacts.
    • The policies relevant to your ads, products, claims, landing pages, and business model.
    • Snapshots of live ads, assets, feeds, destinations, and landing pages sufficient to show what was running when a notice appeared.
    • A change history that distinguishes automated actions from manual edits and identifies the responsible owner.
    • Licenses, approvals, registrations, or other supporting records relevant to regulated claims and creative rights.
    • A concise chronology template for the notice, suspected cause, verified facts, corrective action, and evidence submitted with an appeal.

    If a suspension occurs, preserve the original notice and relevant account state before making broad edits. Map the alleged violation to the exact ad, asset, destination, product, billing detail, or account relationship involved. Correct what you can verify, then submit an appeal that separates evidence from assumptions. Unrelated changes can obscure the cause and make your own chronology harder to defend.

    Don’t build business continuity around the expectation of a favorable appeal. Keep channels you control – such as your website, customer communications, and organic visibility – healthy enough that a paid-platform interruption isn’t your only route to market. That won’t restore an Ads account, but it reduces the pressure to make rushed or poorly documented compliance decisions.

    Key takeaways for Google Ads AI oversight

    • Delegate observation and option generation more freely than live execution or enforcement.
    • Require every material recommendation to identify its goal, current evidence, exact scope, owner, stop condition, and rollback path.
    • Set financial and measurement boundaries from your actual business economics, not a generic tolerance copied from another account.
    • Validate a recommendation in the live Google Ads interface because a plausible answer can still rely on stale navigation or incomplete data.
    • Treat a suggested creative asset as a lead, not a license; provenance and distribution rights need independent approval.
    • Read fast appeal-resolution figures carefully: a resolved appeal is not necessarily a successful reinstatement.
    • Measure oversight by traceability and controlled outcomes, not by how many automated features are enabled.

    Start with one active campaign. Write down its automation envelope, name the human owner, and inspect the next material AI recommendation against the approval questions above. If it passes, implement the smallest reversible version and preserve the baseline. If it doesn’t, you have found the control gap before it reaches the budget, the customer, or the policy system.

    As Google Ads becomes more autonomous, the durable advantage won’t come from accepting automation first or rejecting it outright. It will come from knowing exactly where the machine’s authority ends – and making that boundary visible enough for your team to operate.
    References

  • How to Automate WordPress Schema for AI Search Visibility

    How to Automate WordPress Schema for AI Search Visibility

    You have useful pages, a WordPress schema tool, and no clear way to tell whether AI search systems can understand the site. The missing piece is usually not another markup type. It is a dependable connection between what each page says, how its meaning is represented in JSON-LD, and what happens every time an editor changes it.

    Your goal is not to generate the largest possible block of schema. It is to publish accurate, retrievable, maintainable structured data without losing editorial control. That requires a content contract, an automated processing lifecycle, explicit exceptions, and measurements that distinguish successful generation from actual search visibility.

    Key takeaways

    • Schema helps machines interpret a page, but it cannot compensate for blocked access, weak answers, interchangeable content, or missing authority signals.
    • Choose schema from the visible purpose of the page. Do not force every WordPress URL into Article, BlogPosting, FAQPage, or Speakable markup simply because your tool supports those types.
    • Automate the complete publishing lifecycle: detect changes, queue work, generate markup, validate it, store it, inject it, retry failures, and report exceptions.
    • Keep global exclusion rules and per-page switches. Editors need a safe way to stop incorrect markup without changing code.
    • Measure coverage, validity, queue health, and content-to-schema consistency before treating rankings, citations, or AI mentions as evidence that the automation worked.

    Schema supports AI visibility, but it does not create it

    JSON-LD is a translation layer. It gives machines explicit labels for a page, its subject, and the relationships among named entities. It does not make a thin page authoritative, turn an unsupported claim into a fact, or guarantee that Google AI Overviews, ChatGPT, Gemini, or Microsoft Copilot will cite the URL.

    A practical AI visibility model has five connected parts: retrievability, alignment, differentiation, authority, and entity mapping. Schema mainly strengthens retrievability and entity interpretation. It can also reinforce alignment by making the page type and relationships explicit, but the visible content still has to do most of the work.

    • Retrievability: The relevant content must be accessible, rendered, and easy to extract. A technically perfect JSON-LD block is useless when the page itself is unavailable to the system evaluating it.
    • Alignment: The page should answer the query directly, using headings and concise passages that make the answer easy to locate. Schema can identify the page, but it cannot supply an answer that is absent from the body.
    • Differentiation: Original data, concrete examples, case material, or a defensible point of view gives an answer-selection system a reason to use your page instead of another broadly similar result.
    • Authority: Clear authorship, relevant citations, reputable links, and external recognition help support trust. Adding an author field to JSON-LD does not manufacture expertise that the site never demonstrates.
    • Entity mapping: Consistent names and meaningful internal links clarify how people, organizations, products, topics, and pages relate to one another. Structured data should encode those real relationships rather than inventing new ones.

    Informational intent deserves particular attention. In one reported query set, 88.1% of queries that triggered AI Overviews were informational. That does not mean every informational page will appear. It means your template should reveal a clear answer early, then provide the evidence, qualifications, and detail that make the answer worth selecting.

    Diagnose the weakest layer before editing schema. If the page cannot be retrieved, fix access and rendering. If the answer is buried, revise the content structure. If the page is indistinguishable from competing pages, add original value. If the markup contradicts the visible page, fix the automation. Treating all four failures as a schema problem wastes time and can leave the actual visibility constraint untouched.

    Define a content-to-schema contract before you automate

    Editorial content objects cross a translucent bridge into matching connected data entities while an editor manages an exception lane.

    A schema generator needs rules, not just a prompt. Before you connect it to the WordPress publish action, define what each content template means, which visible fields are authoritative, and which conditions make a schema feature ineligible.

    Visible page conditionSchema decisionAutomation rule
    An editorial page has a headline, body, publication context, and author informationUse Article or BlogPosting as the main typePopulate it from saved WordPress fields and approved editorial metadata
    A general page explains a service, organization, policy, contact route, or other non-editorial subjectUse WebPage as the main typeDo not force Article merely because the URL appears in the WordPress Pages or Posts interface
    The rendered page contains a genuine question-and-answer sectionAdd FAQPage where appropriateGenerate only from questions and answers that remain visible and factually supported on that URL
    The page contains short, stable passages suitable for spoken deliveryAdd Speakable markup where appropriatePoint only to visible passages that still make sense when read without the surrounding layout
    The page is excluded by its purpose, URL pattern, category, tag, or editorial decisionSuppress some or all schema outputRecord the exclusion as intentional rather than reporting it as a processing failure

    The contract should answer five questions for every template:

    1. What is the human purpose of this page? A tutorial, company page, legal notice, category archive, and sales page are not interchangeable just because WordPress stores them in similar tables.
    2. What is the main entity? Name the person, organization, product, service, event, or subject the page is actually about. Use the same public name throughout the page, metadata, schema, and relevant internal links.
    3. Which primary type describes that purpose most narrowly without overstating it? Choose the type after classifying the content, not from a site-wide default that happens to be convenient.
    4. Which secondary features are visibly supported? FAQPage and Speakable should be conditional additions, not default decorations applied to every URL.
    5. What should stop output? Draft status, missing required fields, conflicting metadata, an exclusion rule, unsupported generated text, or an editorial override should prevent publication or route the item for review.

    Keep the visible page and the structured representation synchronized. If an editor changes a headline, removes an FAQ, replaces an author, or materially rewrites the answer, the corresponding JSON-LD must change too. If an on-page FAQ is disabled, FAQPage markup should normally be suppressed unless the same questions and answers remain visible elsewhere on that page. Separating those controls in the interface can be useful, but the publishing policy still needs to prevent invisible or contradictory claims.

    Entity mapping also needs editorial discipline. Name important entities explicitly, link them to the most relevant internal destination, and avoid switching casually among abbreviations, product labels, or organization names. Automation can preserve a relationship model once you define it. It cannot reliably decide that two inconsistent names represent the same real-world entity without authoritative site data.

    Automate the publishing lifecycle, not just JSON generation

    A circular publishing workflow moves a web page through generation, validation, deployment, scanning, and feedback, with one flawed item diverted for review.

    Generating JSON-LD once when somebody clicks Update is not a dependable system. Model calls can fail, scheduled tasks can stall, fields can be incomplete, and bulk edits can trigger more work than the site can safely process at once. A production workflow needs a queue and an observable state for each job.

    1. Detect a meaningful content event. Queue work when a page is first published or when an update changes a field that affects the structured representation. Do not regenerate merely because an unrelated administrative value changed.
    2. Capture the authoritative page state. Wait until WordPress has saved the canonical title, body, author data, taxonomy, URL, and feature settings. Generating from a half-saved state is how stale or contradictory markup reaches the front end.
    3. Queue the job. Give it a visible status such as queued, processing, completed, needs attention, or intentionally excluded. Editors should not have to infer processing state from whether markup eventually appears.
    4. Generate from constrained inputs. Supply approved fields and explicit rules. If AI is used for FAQ or Speakable content, require the output to remain grounded in facts already supported by the page.
    5. Validate before injection. Confirm that the output is valid JSON-LD, contains the intended type, and matches the rendered content. Syntax validation alone is not enough.
    6. Persist a known-good result. Store successful output separately from an in-progress attempt so a transient failure does not replace valid markup with an empty or malformed block.
    7. Inject and verify. Confirm that the structured data appears on the public canonical page, not only inside the WordPress dashboard or a preview response.
    8. Retry and escalate failures. Retry transient errors, cap repeated attempts, and move persistent failures into a visible attention state with enough diagnostic detail to act on them.

    WordPress scheduling deserves special treatment. WP-Cron depends on site activity and can become unreliable in some hosting configurations. Your automation should expose queue health, include retry logic, and provide a safe fallback when scheduled processing does not run. A job that remains queued indefinitely is not a successful automation simply because no error message appeared.

    Use event-driven regeneration as the default. A weekly or monthly refresh can be useful for pages whose generated markup may become stale even without an editor touching them, but a refresh schedule should not conceal a broken update trigger. You also need a controlled bulk rebuild for migrations, major template changes, prompt changes, or schema-policy revisions. Bulk work should enter the same queue and validation path as ordinary updates so it does not bypass your safeguards.

    Build exceptions into the lifecycle from the start. Global rules based on URL patterns, categories, and tags are useful for entire content families. Per-page switches are necessary for edge cases. The most practical control set lets an editor disable the main schema, FAQ output, Speakable output, visible generated FAQs, or all injection without deleting the saved page or changing PHP.

    Make intentional exclusions visible in reporting. Otherwise, an excluded legal page and a failed editorial page both look like missing coverage, and your dashboard sends the team toward the wrong fix.

    Guard the output, then measure the system behind it

    Stop inaccurate or duplicate markup before it ships

    Before enabling a new injector, inspect what the theme, SEO plugin, ecommerce plugin, and custom code already publish. Two tools can emit competing descriptions of the same page. More schema is not automatically better; duplicate or contradictory entities make the machine-readable version less clear.

    • Open the public page and locate every JSON-LD block, not just the block displayed in your plugin dashboard.
    • Identify which component owns each block and decide which system is authoritative for each schema type.
    • Compare names, URLs, authors, dates, questions, answers, and entity relationships with the rendered page.
    • Check that excluded pages contain no residual output from a cache or a second plugin.
    • Validate the final public URL with an appropriate structured-data testing tool, including Google Rich Results validation when you are targeting a supported Google search feature.

    A passing rich-results test confirms only what that validator checks. It does not promise an AI Overview, an LLM citation, a ranking gain, or even display of a rich result. Keep validation and visibility reporting separate so the team does not turn technical eligibility into a performance claim.

    AI-generated FAQs require an additional content check. Reject questions the page does not genuinely answer, answers that introduce unsupported facts, and wording that conflicts with the main body. If an answer would need a subject-matter review before appearing as ordinary prose, it needs the same review before appearing in JSON-LD. Hiding it inside machine-readable markup does not reduce the accuracy requirement.

    Review the data path as carefully as the markup. Confirm what page content leaves WordPress, where schema documents and logs are stored, whether the model API key is transmitted to an intermediary, how connectivity can be disabled, and what happens to queued work when access or billing changes. Sites handling confidential, regulated, or unpublished information should not send that material to an external model without an approved data-handling policy.

    The WordPress implementation also needs ordinary application security. Administrative actions should verify nonces and permissions. Inputs should be sanitized, displayed values escaped, JSON output encoded safely, and database queries prepared through WordPress APIs. Logs should reveal failures without exposing API keys, private content, or unnecessary personal data.

    Measure coverage, operations, and outcomes separately

    The number of schema documents generated is a workload metric, not a visibility result. Use three measurement layers so you can tell where the system is failing:

    • Coverage and correctness: Track eligible pages, completed pages, intentional exclusions, missing output, validation errors, content mismatches, and duplicate emitters. Break coverage down by Article, BlogPosting, WebPage, FAQPage, and Speakable so a healthy total does not hide a broken type.
    • Operational health: Track queued, processing, retried, failed, and attention-required jobs. Show recent activity and the age of unresolved work. A queue total without failure context cannot tell an editor whether to wait or intervene.
    • Search outcomes: Monitor the landing pages and query families the work was intended to help. Review search visibility, engagement, brand mentions, and inclusion in relevant AI-generated answers where you can observe them. Keep these outcomes tied to the page and deployment change rather than claiming a site-wide effect from a schema count.

    Record the deployment date, affected template, schema-policy version, and URLs changed. First confirm that coverage and validity improved. Then examine retrieval and search engagement. Finally, run consistent AI visibility checks for the questions that matter to the business. If the technical layers are healthy but the page remains absent, return to answer quality, differentiation, authority, and entity clarity instead of generating a larger JSON-LD block.

    Start with one WordPress content template whose fields and editorial purpose are predictable. Write its content-to-schema contract, connect it to the queue, add validation and exclusions, and watch the full update cycle on public pages. Expand only after that template produces accurate markup and actionable failure states. Schema automation becomes valuable when it is quiet, observable infrastructure rather than a recurring cleanup project.

    References

  • CrushPress AI Actions: Reliable Workflow Automation

    CrushPress AI Actions: Reliable Workflow Automation

    If your AI visibility process ends with a crowded inbox, an unassigned alert, or a spreadsheet nobody revisits, automating it will only produce clutter faster. A useful Action must turn a meaningful signal into an owned decision, preserve the evidence behind it, and define how you will know the work is finished.

    The practical promise behind Actions is to reduce repetitive handling and make AI visibility work more efficient. Real reliability, however, comes from the workflow around the automation: the trigger, decision rule, evidence, owner, review gate, and verification step.

    Define the decision before you automate the task

    Start with a recurring decision that currently requires someone to collect the same information, apply the same rule, and route the result. Do not start with a vague goal such as “improve AI visibility.” An Action cannot execute that goal because it does not identify what changed, what should happen next, or who can approve the response.

    A better starting question is: “What decision keeps waiting because the evidence is scattered?” In an AI visibility workflow, that might be whether a new brand claim needs correction, whether a missing citation points to a content gap, whether a tracked answer changed enough to investigate, or whether an observation is merely noise that should be logged without creating work.

    Write a workflow contract before configuring the Action. It should contain:

    • Outcome: The operational result you want, such as an approved correction task or a content brief ready for review.
    • Trigger: The observable event that starts the workflow. Describe the event, not the desired conclusion.
    • Required evidence: The fields that must exist before the workflow is allowed to continue.
    • Decision rule: The condition that separates “act,” “review,” “observe again,” and “ignore.”
    • Output: One bounded deliverable with a predictable structure.
    • Owner: The role responsible for accepting, rejecting, or completing the output.
    • Stop condition: The point at which the Action must end rather than starting another loop.
    • Verification rule: The evidence required to mark the result as checked, not merely completed.

    For example, “alert the SEO team when visibility drops” is not yet a workflow. “When a tracked query produces a materially different answer, capture the old and new observations, classify the change, and create an investigation brief for the named owner” is much closer. It specifies a trigger, evidence, classification, output, and destination without pretending the automation already knows the cause.

    Use a simple readiness test: can the owner make the intended decision from the Action’s output without reopening every tool used upstream? If not, the automation has moved the repetitive work rather than removed it.

    Build a closed loop for AI visibility changes

    Glowing signals converge into a beacon that moves through a circular observation, action, and verification system.

    AI-generated answers can vary across runs, models, interfaces, languages, and locations. A single observation is therefore evidence of what appeared in that context, not automatic proof of a durable visibility trend. Your workflow should preserve that context before it attempts to classify the result.

    A practical visibility loop

    1. Observe: Start from a defined query or query set on a chosen AI surface. Avoid mixing unrelated prompts into one trigger.
    2. Capture: Save the exact prompt, answer, model or interface, observed time, relevant language or market, cited pages, and any brand or competitor mentions needed for review.
    3. Compare: Evaluate the observation against a declared expectation or earlier observation. Keep the raw evidence alongside the comparison.
    4. Classify: Route the result into a limited set of operational states, such as no meaningful change, uncertain result, incorrect claim, missing mention, citation gap, content gap, or competitor displacement.
    5. Act: Produce one appropriate output. That might be a correction task, investigation brief, content brief, structured-data review, escalation, or no-action record.
    6. Verify: Recheck the same success criterion in a planned observation window, while retaining the model and interface context.

    The separation between observation and classification matters. If an Action turns every changed answer into an optimization task, ordinary output variation becomes a queue of false emergencies. A classification stage lets you require more evidence when the result is ambiguous and reserve immediate action for clear, consequential problems.

    Example: route a potentially incorrect brand claim

    Suppose a tracked answer contains a claim that conflicts with your approved brand facts. The Action should not jump directly to rewriting a page or publishing corrective content. Design the loop like this:

    • Trigger: A captured answer contains a claim that appears inconsistent with the approved fact set.
    • Evidence packet: Include the exact prompt, complete surrounding answer text, AI surface, cited URLs, observation context, conflicting approved fact, and link to the canonical internal record.
    • Decision gate: A reviewer confirms whether the statements actually conflict and whether the issue is consequential.
    • Action: Create a correction plan that identifies the canonical page, structured data, documentation, or third-party information requiring investigation.
    • Approval: Require an authorized owner to approve any public edit, deletion, or external response.
    • Verification: Confirm that the approved source of truth was corrected, then record later AI observations separately from the operational completion.

    This distinction prevents an important reporting error. Completing a content or data correction proves that your team performed the approved work. It does not prove that the correction caused a particular model to change its answer. Track “work completed” and “visibility outcome observed” as separate states.

    Verification should test the original condition

    A generic “done” status tells you that a task moved through the system. It does not tell you whether the initiating problem was resolved. Write the verification rule when you create the workflow, using the same language as the trigger.

    If the trigger is an incorrect brand claim, verification asks whether the approved source of truth is now accurate and whether later observations still contain the claim. If the trigger is a citation gap, verification asks whether the target page became a stronger, accessible source and whether subsequent answers cite it. If the trigger is a visibility change, verification repeats the planned observation method rather than substituting a different prompt or surface.

    Make every handoff carry its own evidence

    A brittle automation often fails at the handoff. The Action detects something real, but the destination receives a title such as “Check AI visibility” with no prompt, answer, comparison, or reason for the priority. The assignee must reconstruct the investigation before making a decision.

    Prevent that failure by treating the evidence packet as part of the deliverable. Every routed item should answer these questions:

    • What was observed? Preserve the exact text or structured result, not only a generated summary.
    • Where did it occur? Identify the AI surface, model or interface when available, query, language, market, and relevant source URLs.
    • What changed? Show the comparison or rule that activated the workflow.
    • Why was it classified this way? Expose the decision rule instead of presenting the label as unquestionable.
    • What remains uncertain? Label suspected causes as hypotheses. Do not let generated explanations masquerade as established facts.
    • What should the owner decide? Ask for a specific approval, rejection, prioritization, correction, or investigation decision.
    • What would close the item? State both the operational completion condition and the later visibility check.

    Route by issue type before routing by team. “Content,” “technical,” or “communications” may describe a destination, but they do not explain the problem. A useful classification identifies the issue first: unsupported claim, stale canonical fact, inaccessible source, weak answer coverage, structured-data inconsistency, or uncertain observation. The destination can then follow from that diagnosis.

    Measure decision quality, not automation volume

    Task count is a poor success metric. A noisy workflow can create many tasks while making the team slower. Use operational measures that reveal whether the Action improves the decision process:

    • Useful-signal rate: How often reviewers agree that a routed item deserved attention.
    • Time to ownership: How long a valid signal remains unassigned or undecided.
    • Rework: How often the owner must retrieve missing evidence, change the classification, or rebuild the requested output.
    • Closure quality: How often completed items include the required approval and verification record.
    • Repeated failure: Which triggers, fields, or destinations create the same rejection or exception pattern.
    • Observed outcome: Whether later checks satisfy the declared visibility criterion, recorded without claiming unsupported causation.

    Review rejected and corrected outputs as design feedback. If reviewers repeatedly change the same classification, the rule is probably ambiguous. If they repeatedly ask for the same missing field, add it to the evidence contract. If valid items stall after assignment, the problem is ownership rather than detection.

    Add review gates and failure controls before scaling

    Two professionals pass a transparent evidence case through a guarded review checkpoint with inspection and recovery controls.

    The right automation boundary depends on the consequence of being wrong. Capturing evidence is reversible. Publishing a factual claim, deleting content, changing structured data, contacting an external party, or altering permissions can create reputational, technical, or legal exposure. Put explicit approval in front of those actions and provide the reviewer with a preview or difference view wherever possible.

    Automate preparation before irreversible choices

    A sensible responsibility split looks like this:

    • Safe to automate: Evidence capture, formatting, deterministic field validation, duplicate detection, status updates, routing, and creation of a reviewable draft.
    • Automate with review: Intent grouping, issue classification, priority suggestions, root-cause hypotheses, content recommendations, and proposed schema changes.
    • Require explicit approval: Publishing, deletion, public corrections, external outreach, access changes, and any claim whose accuracy or wording carries material consequences.

    Generated drafts should remain drafts until an accountable person approves them. This is especially important when the input is an AI-generated answer: the workflow is processing an output that may itself be incomplete, variable, or wrong.

    Give failures a visible destination

    An Action is not ready merely because its successful path works. It is ready when a failed run is legible, contained, and recoverable. Build or document these controls around it:

    • Required-field validation: Stop the workflow when the evidence needed for a decision is missing.
    • Duplicate protection: Use a stable combination of query, observation, issue, and destination so repeated detection does not create competing tasks.
    • Scoped permissions: Give the workflow access only to the systems and operations it needs.
    • Bounded retries: Prevent a failing destination from producing an uncontrolled loop of repeated attempts.
    • Visible exceptions: Send failed and uncertain runs to a named owner with the input, error state, and last successful step intact.
    • Versioned rules: Record which prompt, classification logic, template, and approval policy produced each output.
    • Recovery path: Preserve the prior state or require a reversible draft when an automated step could change content or data.

    If a particular control is not available inside the Action itself, put it in the surrounding operating process. Do not assume that a successful status means the destination accepted the right data, that a retry is harmless, or that a generated classification is safe to publish.

    Roll out with known cases before live expansion

    1. Replay resolved cases: Feed the workflow examples whose correct routing and outcome are already known. Include ambiguous, duplicate, incomplete, and no-action cases.
    2. Run in shadow mode: Let the Action produce a log or draft without changing production content or contacting anyone externally.
    3. Limit the live scope: Start with one trigger family, one output type, and a named owner who can inspect exceptions.
    4. Correct the contract: Update missing fields, ambiguous rules, permissions, and failure handling based on actual review patterns.
    5. Expand by pattern: Reuse the proven structure for adjacent workflows while keeping each Action’s trigger, owner, and success condition explicit.

    Name each workflow so its behavior is obvious: “trigger → decision → outcome.” A name such as “tracked claim conflict → reviewer confirmation → correction plan” is easier to operate than “AI monitoring automation.” It also makes overlapping or redundant Actions easier to spot.

    Key takeaways

    • Automate a recurring decision with a defined outcome, not a broad ambition such as improving visibility.
    • Preserve the prompt, answer, AI surface, comparison, and source context before classifying a visibility change.
    • Keep operational completion separate from later AI visibility observations; the latter does not automatically prove causation.
    • Make the evidence packet complete enough for the owner to decide without reconstructing the investigation.
    • Require human approval for publishing, deletion, external communication, permissions, and consequential factual or structured-data changes.
    • Scale only after duplicate handling, visible exceptions, ownership, verification, and recovery work on known cases.

    Your best first CrushPress AI Action is the recurring visibility decision that consumes attention without requiring novel judgment every time. Define its evidence packet, make its output reviewable, and test its failure path. Once that loop closes reliably, use the same contract to automate the next decision.

    References