Tag: AI Automation

  • How to Automate AEM Content Updates with Profound Agents

    How to Automate AEM Content Updates with Profound Agents

    You have an AI visibility finding, a clear content fix, and an Adobe Experience Manager workflow standing between the two. The diagnosis may take minutes. The ticket, CMS handoff, review, and update can take much longer.

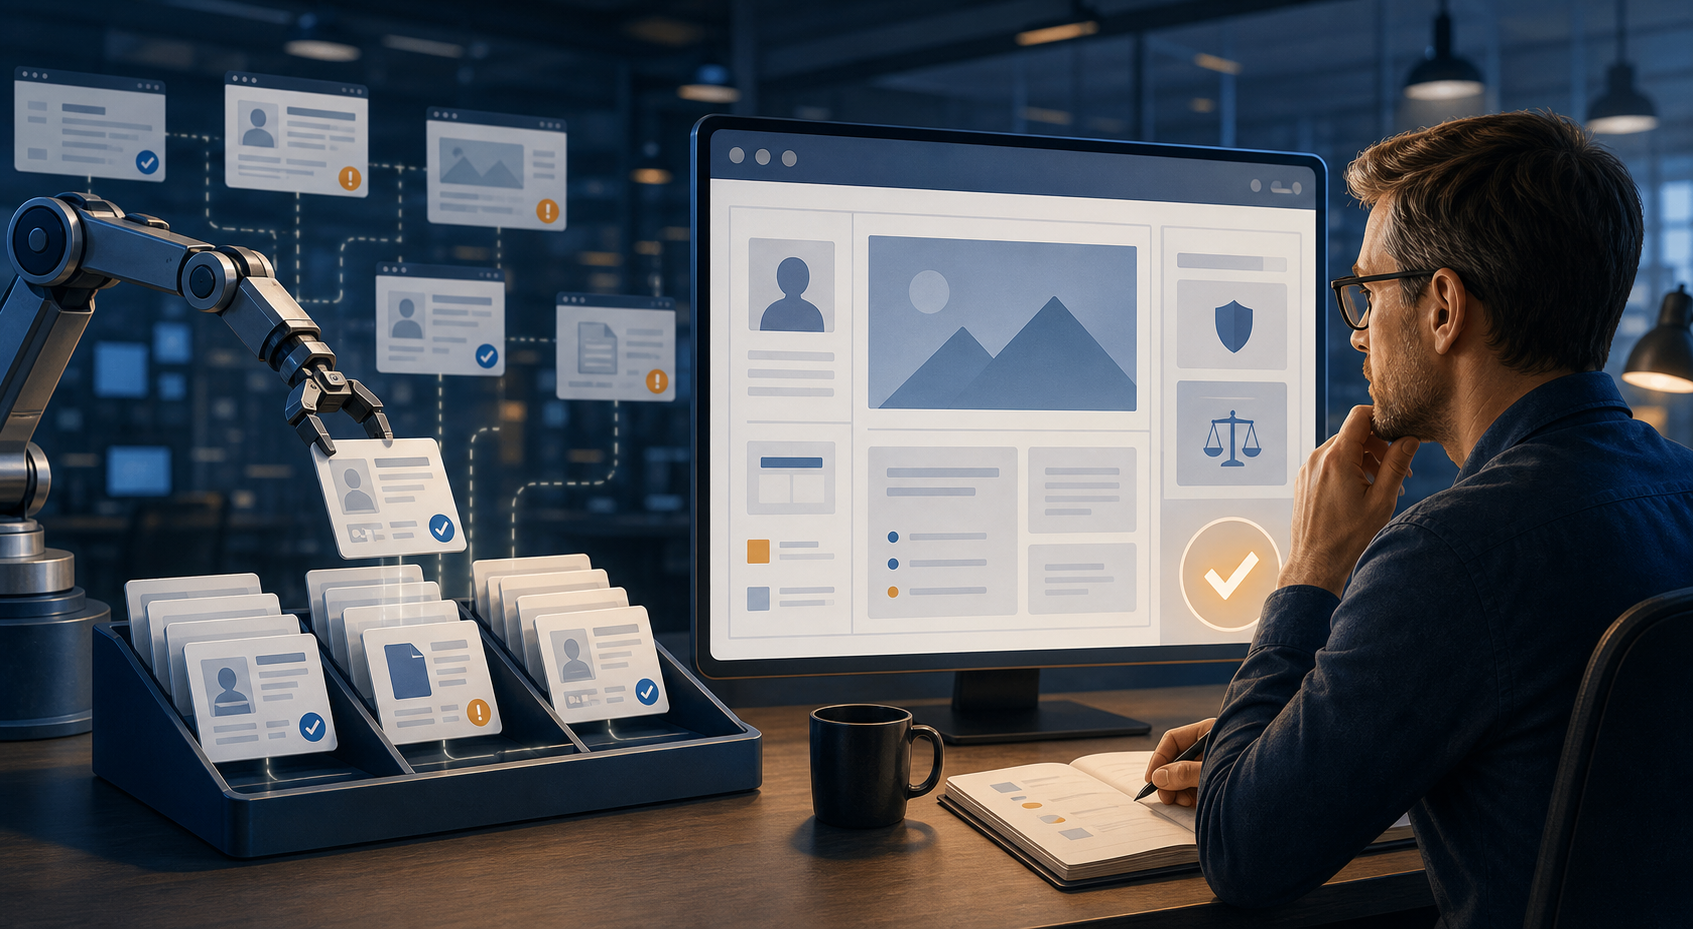
    Profound Agents can now List, Search, Get, Create, and Update Content Fragments in Adobe Experience Manager. That gives you a direct route from an approved insight to a controlled CMS change. The important word is controlled: the safest design is not an agent with unrestricted publishing power, but a bounded workflow that retrieves the right fragment, proposes a field-level change, passes validation, and writes only after the required approval.

    What the AEM nodes actually let you automate

    The integration operates on AEM Content Fragments. In a workflow design, give each available action a narrow job:

    • List supports inventory work when the workflow needs to inspect a defined collection of fragments.
    • Search helps locate candidates related to a target entity, topic, path, locale, or other supplied criterion.
    • Get retrieves the exact fragment before any decision or write occurs.
    • Create adds a new Content Fragment when no suitable canonical fragment exists.
    • Update changes an existing fragment that already represents the intended entity or content unit.

    This distinction matters because a Content Fragment is not the same thing as a rendered web page. A page may reference the fragment, transform its fields through a component, expose it through an API, or combine it with content from other systems. If the target copy is hard-coded in a component or owned by another service, changing a Content Fragment will not necessarily change that copy.

    The named action set also does not include a separate Publish action. Do not treat a successful Create or Update operation as proof that the new content is live. Document the downstream activation, deployment, cache, and rendering steps in your implementation. Then verify the delivered page or endpoint, not only the object stored in AEM.

    Get should normally precede Update. Without that read step, the agent may work from an old brief, overwrite a newer human edit, or modify a fragment that merely resembles the intended target. Retrieval is part of the safety model, not administrative overhead.

    Build the workflow around a write contract

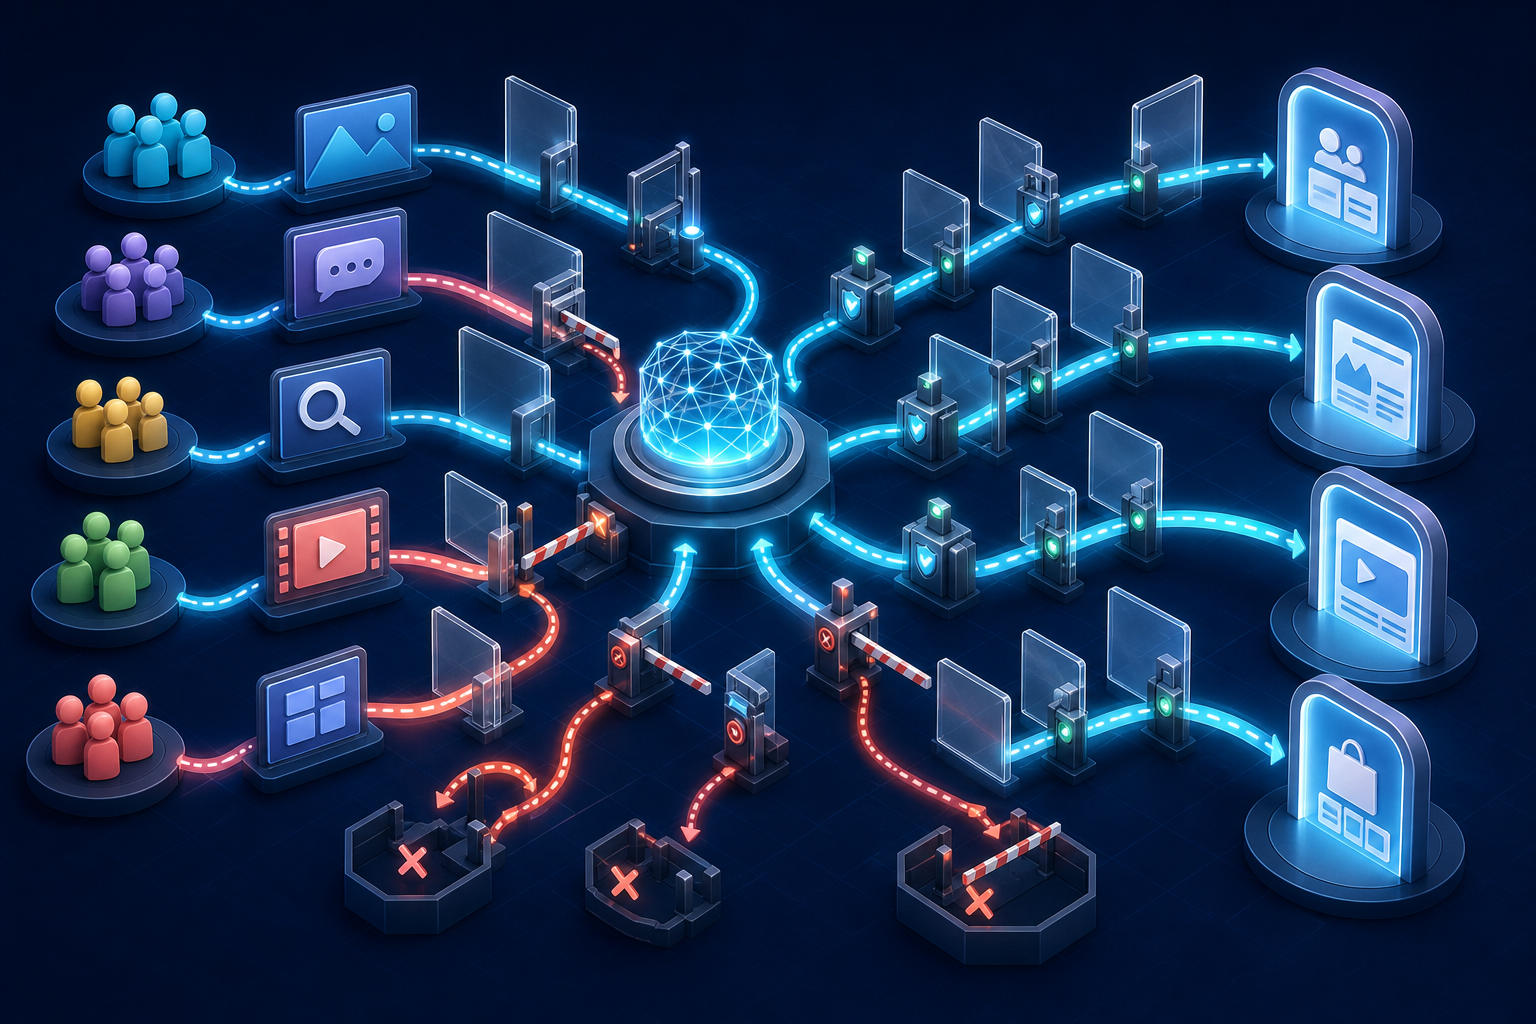
    A validation gate directs approved modular changes into matching fields of a single structured content fragment.

    Start with one content model, one permitted content root, one locale, and one repeatable use case. A focused pilot might update an approved answer field in an existing fragment. A poor first pilot gives the agent authority to rewrite product claims across several models and markets.

    Before connecting an insight to an AEM write, define a write contract. This is the machine-readable boundary that tells the workflow what it may change and when it must stop.

    • Target scope: the allowed AEM path, Content Fragment Model, brand, market, and locale.
    • Permitted actions: whether the run may Search and Get only, Update an existing fragment, or Create a new one.
    • Writable fields: the specific fields the agent may alter. Treat identifiers, ownership fields, workflow state, canonical references, and other structural fields as immutable unless the use case requires them.
    • Evidence inputs: the approved facts, URLs, product data, and editorial instructions the generated copy must follow.
    • Stop conditions: no match, multiple plausible matches, a model mismatch, a locale mismatch, missing evidence, failed validation, or a fragment that changed after retrieval.
    • Approval rule: who must accept the field-level diff before the write and whether a separate approval is required before activation.
    • Completion record: the target identifier or path, operation used, fields changed, prior and new values, validation result, reviewer, and downstream publication state.

    With that contract in place, use the nodes in a deliberate sequence:

    1. Receive a qualified opportunity. Supply the target query or audience need, the reason for the change, the approved evidence, and the expected content destination. Do not ask the agent to infer business truth from a visibility gap.
    2. Locate candidate fragments. Use Search for a targeted lookup or List within a tightly bounded collection.
    3. Resolve one exact target. Match on stable attributes such as an approved identifier, path, model, entity, and locale. A similar title is not enough.
    4. Retrieve the current fragment. Use Get so the workflow can preserve existing fields and compare the current value with the proposed value.
    5. Choose Create, Update, or stop. Make this an explicit decision rather than allowing a failed search to become an automatic Create.
    6. Generate a field-level patch. Ask for only the fields that need to change. Avoid regenerating the entire fragment when one answer, description, or evidence field is the actual target.
    7. Validate before writing. Check the Content Fragment Model, required fields, allowed values, link formats, locale, evidence constraints, and any length rules imposed by the destination.
    8. Review the diff. Show a human reviewer the exact old and new values, along with the evidence behind the change. Reviewing polished prose without the prior value hides unintended deletions.
    9. Execute and verify. Run Create or Update, retrieve the stored result, complete the separate activation process where required, and inspect the rendered destination.

    Keep the AEM write at the end of the sequence. Insight generation, drafting, and validation can fail safely. A write changes shared production content and therefore needs the strongest preconditions.

    Choose Create or Update without multiplying content

    Update when the canonical content object already exists

    Use Update when the existing fragment represents the same entity, intent, locale, and reusable content unit. The gap should be field-level: an incomplete answer, stale description, missing supporting detail, or another change that belongs inside the established object.

    Send a patch containing only approved changes. Replacing the full fragment increases the chance of losing fields the agent was never meant to edit. Retrieve again immediately before the write if another editor or workflow could have changed the target since the first read. If the integration exposes a revision or version value, use it to reject a write based on stale state.

    Create only when a genuinely new reusable object is needed

    Use Create when the required content has no canonical fragment and the new object has a defined model, destination, owner, locale, and lifecycle. A new topic alone is not enough. The content also needs a known consumer: a page component, application, API response, campaign experience, or another delivery path that will use the fragment.

    The common failure is creating a new fragment for every visibility finding. That produces near-duplicates, splits ownership, and makes later updates ambiguous. Search first, inspect likely matches, and stop for review when more than one candidate could be canonical. A failed or inconclusive search should never silently authorize creation.

    Retries need the same discipline. Record a unique run identifier and the intended target so a retried workflow cannot create the same fragment twice. For updates, record the retrieved state or revision so a retry cannot overwrite a more recent edit without detection.

    Protect content quality, structured data, and production state

    A structured content fragment is protected by quality checks, a field-preserving lattice, and a sealed production access gate.

    Model the information that answer systems need

    AEM automation works best when important information has an explicit field instead of being buried in one large rich-text block. Depending on your content model, useful fields can include a concise answer, supporting explanation, named entity, approved evidence URL, audience or locale, review status, owner, and review date. These are design recommendations, not fields that Profound creates for you.

    Keep factual generation constrained to approved evidence. An AI visibility finding can identify a missing answer or weak topic representation, but it does not establish the underlying product, legal, pricing, or policy facts. The workflow should stop when the supplied evidence cannot support the proposed claim.

    Do not turn the fragment into a bag of repeated search phrases. Write the direct answer a person needs, use consistent entity names, preserve necessary qualifications, and add supporting detail only where it improves understanding. The goal is a clearer canonical answer, not a visible record of every query variant that triggered the workflow.

    Structured content and structured data are related, but they are not interchangeable. Updating a Content Fragment does not automatically update the JSON-LD emitted by the rendered page unless your delivery layer maps those fragment fields into the markup. Verify the visible HTML and the resulting JSON-LD separately. If they describe the same entity or claim, they should remain aligned after the update.

    Put operational controls around every write

    Treat generated content as untrusted input until it passes your rules. The AEM nodes provide the content operations; your surrounding workflow still needs access, validation, review, recovery, and publication controls.

    • Use an AEM identity with the least access needed for the approved path and model.
    • Separate development or test targets from production targets, and prove the workflow against representative non-production fragments first.
    • Allowlist paths, models, locales, and writable fields. Do not rely on prompt wording as the only permission boundary.
    • Prefer field-level patches to full-object replacement.
    • Re-fetch the fragment before Update and stop if the current state no longer matches the reviewed state.
    • Preserve a recoverable prior version or snapshot before changing production content.
    • Keep content writing separate from activation or publication so each can have its own approval rule.
    • Log the evidence, retrieved target, proposed diff, validation outcome, write result, and final delivery state.

    The announced AEM action set covers List, Search, Get, Create, and Update; it does not name Delete. That reduces one obvious failure path, but Update can still remove or replace valuable field content. Recovery and diff review remain necessary.

    Measure delivery separately from visibility

    A successful node execution means the requested AEM operation completed. It does not prove that the correct experience rendered, that a search system discovered the change, or that an AI answer will use it.

    Track the workflow in three layers. First, confirm operational correctness: one target, the intended action, valid fields, and an approved diff. Second, confirm delivery: the stored fragment, activation state, rendered page or endpoint, links, metadata, and JSON-LD. Third, observe discovery outcomes through your normal crawling, indexing, search, and AI visibility monitoring. Keep those layers separate so a rendering failure is not mistaken for a content-strategy failure.

    Changes in AI answers are especially difficult to attribute to one edit. Record what changed and where, but do not treat a later answer difference as proof that the fragment update caused it. The defensible result is a verified content improvement and a traceable delivery path; visibility remains an outcome to monitor.

    Key takeaways

    • Profound Agents can List, Search, Get, Create, and Update AEM Content Fragments, which removes a manual CMS handoff from an approved optimization workflow.
    • Get before Update, and require one unambiguous target. No match or multiple matches should stop the write.
    • Use Update for an existing canonical object and Create only for a defined new content unit with a known consumer and owner.
    • Limit every run by path, model, locale, operation, and writable field. Review the exact diff rather than the new copy in isolation.
    • Verify AEM storage, publication, rendering, and JSON-LD separately. A completed content operation is not the same as a live or discoverable change.

    Start with one low-risk fragment family and one field-level optimization pattern. Write the contract, test the stop conditions, require diff approval, and trace the result through rendering and structured data. Expand the scope only when repeated runs select the right object, preserve untouched fields, and produce a recoverable audit trail.

    References


  • Human-Led AI Workflows for SEO: A Practical System

    Human-Led AI Workflows for SEO: A Practical System

    You don’t need to choose between banning AI from SEO and letting an agent run your site. The useful middle is a workflow in which AI accelerates analysis and production while a person remains accountable for the decisions that can affect rankings, crawlability, brand trust, and measurement.

    Your goal is not to put a human approval step at the end of an automated content factory. It is to place human judgment at the few points where a plausible answer can become an expensive mistake: choosing the page, defining its unique contribution, validating its evidence, approving the technical change, and interpreting the result.

    Human-led means retaining decision authority, not doing everything manually

    AI is genuinely useful for clustering keywords by intent, identifying content gaps, analysing pages, and producing first-pass outlines. Those tasks compress a large amount of reading and organisation. They do not require the model to decide what your site should publish or change.

    The boundary should be based on authority. Let AI transform information, expose patterns, draft options, and run checks. Keep a person responsible for choosing the objective, accepting the evidence, resolving conflicts, approving live changes, and deciding whether an experiment worked.

    That distinction matters because fluency is not reliability. A model can produce a tidy keyword map, persuasive rationale, polished page, and confident recommendation even when the underlying choice is wrong. It may not know that a proposed URL conflicts with an existing page, that a claim lacks support, or that a template renders essential content only after client-side JavaScript runs.

    Google’s stated position is that using AI to produce content is not inherently against its guidelines when the result is helpful and made for people. The operational risk is therefore not the presence of AI. It is publishing low-value or technically unsound work because nobody tested whether the output deserved to exist.

    Key takeaways

    • Use AI to analyse evidence and generate options; do not let it define success or approve its own work.
    • Separate opportunity selection, research, briefing, drafting, technical validation, publication, and measurement into distinct gates.
    • Require a unique contribution before drafting. A new keyword target is not, by itself, a reason to create a new URL.
    • Route every live change through a reviewable diff, a validation checklist, and a rollback plan.
    • Measure one declared hypothesis against the pages and metric the change could actually affect.

    Turn the workflow into gates with visible pass conditions

    A human reviewer inspects five abstract SEO workflow stages separated by approval gates on a studio table.

    A single prompt that asks for research, strategy, a draft, optimisation, and publication collapses several different decisions into one answer. By the time you see the finished page, the model has already assumed the search intent, selected the format, decided whether to create or update a URL, filled evidence gaps, and judged its own quality.

    Break that chain apart. Each stage should produce an artifact that the next reviewer can inspect. A pass condition should be observable rather than subjective: not good quality, but target intent is named, competing URLs were checked, every factual claim has support, and the proposed contribution is absent from the comparison set.

    StageAI contributionHuman decisionRequired artifact
    1. OpportunitySummarise query, page, conversion, and competitive data; surface patterns and anomalies.Choose the business and user problem worth solving.A work order with the target audience, objective, metric, scope, and exclusions.
    2. Intent and URL mappingCluster queries, describe likely intents, and identify potentially competing pages.Decide whether to create, consolidate, refresh, redirect, or stop.A query-to-URL map that names the current owner and proposed owner of each intent.
    3. EvidenceOrganise supplied data, first-hand notes, examples, and references; flag unsupported claims.Confirm provenance and decide what may be published.An evidence pack in which every input has an owner or traceable origin.
    4. Information gainCompare the planned coverage with ranking pages and identify repetition or gaps.Determine whether the page adds a useful fact, method, example, tool, dataset, or point of view.A one-sentence unique-contribution statement plus the evidence needed to deliver it.
    5. Brief and draftBuild an outline, draft sections, suggest internal links, and mark open questions.Correct the framing, verify claims, remove filler, and protect the brand’s position.A draft with unresolved questions clearly marked rather than silently completed.
    6. Technical preflightRun repeatable checks on metadata, links, structured data, indexation directives, and rendered content.Inspect the actual change and resolve conflicts or failures.A pass-or-fail report tied to the exact URL, build, or commit being reviewed.
    7. ReleasePrepare a diff, change log, test instructions, and rollback steps.Approve the specific version that will go live.A recorded sign-off and a recoverable previous state.
    8. MeasurementCollect the declared metric and summarise what changed.Judge causality, retain or reverse the change, and select the next test.An append-only experiment record, including inconclusive results.

    The information-gain gate belongs before the draft. If the only proposed difference is a longer word count, a new title, or rearranged coverage, stop. Ask for first-hand evidence, proprietary data, a concrete workflow, a useful tool, or a sharper answer to a neglected part of the intent. A gated system prevents average ideas from becoming finished pages merely because drafting is cheap.

    A useful gate prompt is narrow: Review this opportunity as an SEO decision, not as a writing task. Using the target query, existing URL map, ranking-page notes, and evidence pack, return the dominant intent, the URL that should own it, any cannibalisation risk, the unique contribution, missing evidence, and one verdict: pass, revise, or stop. Do not fill evidence gaps with assumptions.

    The verdict remains advice. The human reviewer should be able to explain why the page should exist without repeating the model’s wording. If you cannot state the intended reader, unmet need, unique contribution, and correct URL in plain language, the opportunity has not cleared the gate.

    Keep AI away from unreviewed changes to the live site

    A human operator reviews abstract page and code modules in a staging area before allowing them into a protected live website environment.

    The most important permission boundary sits between proposing a change and applying it. Read access to analytics, crawls, keyword sets, page inventories, and content repositories can create enormous leverage. Unrestricted write access to a CMS, routing configuration, templates, redirects, canonical tags, robots directives, structured data, or measurement code creates a different risk class.

    A live-site failure shows why. An AI system asked to recommend keywords and build the necessary pages produced two new URLs that largely copied the homepage while changing the title tag and H1. After six months, the two dedicated pages had zero impressions and zero clicks in Google Search Console, while the homepage continued to receive the relevant queries. This is one site’s result, not a universal performance benchmark. The reusable lesson is the failure mode: the system satisfied the surface instruction to create targeted pages without giving either page a distinct purpose.

    The same cloning pattern appeared on a separate project, where a batch of keyword-targeted pages copied the homepage and changed little beyond their titles. That is what a human URL-mapping gate should catch before a draft exists. Microsoft has also confirmed that Bing’s models can group near-duplicate URLs and select an unintended representative, so duplication can obscure which page should appear in conventional search and AI-generated answers.

    Use a change packet whenever AI proposes work that could reach production. The packet should contain:

    • Exact scope: every URL, template, file, rule, and structured-data type affected.
    • Before-and-after diff: the actual text or configuration change, not a prose summary.
    • Purpose: the user problem, target intent, and expected mechanism of improvement.
    • Evidence: the data and approved claims used to justify the change.
    • Conflict check: existing URLs, keywords, canonicals, redirects, and templates that could overlap.
    • Validation plan: what will be checked in staging and again after release.
    • Rollback: how to restore the previous state without reconstructing it from memory.
    • Measurement: the page-specific metric and the condition that would count as a valid result.

    Then perform the preflight against the built page, not the intended page. Confirm that the title, H1, main content, internal links, canonical URL, indexation directives, and structured data are present in the delivered output. Check that structured data describes visible content and approved claims. Inspect server-returned HTML as well as the browser-rendered page when essential content depends on JavaScript.

    That last check matters beyond Google. One practitioner’s measurement found ClaudeBot downloaded a JavaScript bundle in 24% of its requests but did not execute it. Treat that as one observed implementation behaviour, not a guaranteed rate for every site or bot. The practical response is still sound: do not assume a page is machine-readable because it looks complete in your browser.

    For routine work, let the system create a CMS draft, branch, pull request, or staging build. Require a named person to approve URL creation or deletion, redirects, canonical changes, indexation controls, template-wide edits, bulk internal links, measurement code, and publication. AI can produce the checklist and flag deviations; it should not be the sole reviewer of its own output.

    Measure a declared hypothesis instead of rewarding activity

    Human control is also necessary after publication. An automated report can find a favourable movement and attach it to the latest task, even when the changed pages could not have caused that movement. That creates a learning system that rewards coincidence.

    Define the experiment before the change. Use one sentence: If we make this change to these pages, we expect this metric to move because this user or crawler problem will be reduced. Name the affected URLs, the baseline, the primary metric, any guardrail metric, the review window, and the evidence that would make the outcome valid. Choose the review window based on the site’s crawl patterns, traffic, and decision cycle rather than inventing a universal deadline.

    Keep each run narrow enough to interpret. A bounded agent can read the roadmap, state file, and prior log, then recommend one justified action. It can also recommend no change when the evidence is weak. If you permit execution, constrain it to a reviewable draft or branch unless the action has already been proven safe, is reversible, and falls inside an explicitly approved class.

    The experiment log should record:

    • the hypothesis and why the action should affect the selected metric;
    • the exact pages and elements changed;
    • the baseline and date range used;
    • the model, instructions, evidence pack, and workflow version involved;
    • the human reviewer and approval decision;
    • the release date and any confounding changes;
    • the observed result, including negative and inconclusive outcomes;
    • the decision to retain, revise, reverse, or run a follow-up test.

    Use a strict causal rule: a metric movement does not count if the shipped change did not touch the pages or mechanism that metric represents. In one autonomous run, average position improved from 48 to 39, but the result was logged as inconclusive because the change affected pages outside the measured target set. That is the behaviour you want from an AI-assisted testing system. Its job is to preserve the truth of the experiment, not to manufacture wins.

    Do not hide rejected recommendations or failed tests. They reveal which inputs are missing, which instructions are ambiguous, and which permission boundaries need tightening. An append-only log turns human review from an approval ritual into operational memory.

    Install a minimum viable workflow before expanding automation

    You do not need to redesign the whole SEO operation at once. Start with one recurring unit of work, such as content briefs, refresh recommendations, internal-link opportunities, or schema proposals. Pick a task that happens often enough to expose patterns but can still be reviewed carefully.

    1. Write the work order. Name the user problem, business objective, primary metric, allowed inputs, prohibited actions, and person accountable for approval.
    2. Disable direct publication. Route output to a draft, ticket, branch, or staging environment. Preserve the original state.
    3. Create three reusable templates. Use an evidence pack for inputs, an acceptance checklist for review, and an experiment log for outcomes.
    4. Pilot a small batch. Ten items can be enough to expose recurring rejection reasons without turning the pilot into a production commitment. This is a practical batch size, not a performance threshold.
    5. Classify every intervention. Record whether the reviewer corrected intent, URL choice, evidence, factual accuracy, duplication, brand framing, technical implementation, or measurement.
    6. Improve the system at the earliest failed gate. If reviewers repeatedly catch duplicate intent at final QA, move the URL-map check ahead of drafting. Do not solve an upstream decision problem with more downstream editing.
    7. Expand one permission at a time. Grant a new capability only when its inputs, output, reviewer, validation, and rollback path are explicit.

    Before any item goes live, ask the reviewer five questions: Why should this page or change exist? What evidence supports it? What exactly will change? What could it conflict with or break? How will we know whether it worked? A missing answer is a stop signal, not an invitation for the model to improvise.

    The next time your team asks to automate more SEO, automate the collection, comparison, drafting, checking, and documentation first. Keep the decision rights visible. Once the workflow can show its evidence, its diff, its reviewer, and its result, you can increase speed without surrendering control of what your site becomes.

    References


  • Leading RevOps Firms: How to Choose a Fractional Agency

    Leading RevOps Firms: How to Choose a Fractional Agency

    You are not buying RevOps in the abstract. You are deciding whether an outside team can repair your revenue engine without slowing sales, damaging CRM data, or leaving you with an expensive system nobody internally knows how to run.

    The difficult part is that fractional leadership, managed operations, CRM implementation, enablement, and AI automation are often sold under the same label. The right choice depends less on which firm tops a general leaderboard and more on the work you need someone to own. This guide helps you identify that work, match it to leading RevOps firms, and test whether a candidate can deliver it.

    Key takeaways

    • Choose the engagement model before the agency. Embedded fractional ownership, managed RevOps, project implementation, and coaching solve different problems.
    • Match lifecycle breadth to the actual break. A problem spanning marketing, sales, onboarding, retention, and expansion needs broader coverage than a contained CRM or outbound project.
    • Do not mistake a long platform list for operational depth. Test the candidate against a real workflow, data model, integration, or handoff from your environment.
    • Make every AI claim concrete. Require a named workflow, defined data access, approval rules, evaluation criteria, logs, failure handling, and a human owner.
    • Replace generic ranking weights with your own priorities. Published 2026 methodologies give substantially different weight to leadership, platforms, AI implementation, and lifecycle scope.
    • Treat recognizable client logos as context, not proof of fit. Even the ranking methodologies used for this shortlist assigned notable clients only 5% of the total score.

    Choose the RevOps engagement model before the firm

    A leadership team compares three visual pathways representing fractional leadership, managed operations, and technical implementation services.

    Fractional describes how you access leadership or operating capacity. It does not guarantee that a senior operator will be embedded in your team, that the agency will configure systems, or that it will cover the complete customer lifecycle. Confirm the operating model in the contract rather than relying on the label.

    • Embedded fractional ownership: Choose this when no internal leader owns the revenue system across functions. The outside operator should make decisions, coordinate stakeholders, prioritize work, and remain accountable for implementation rather than merely recommend changes.
    • Managed RevOps or RevOps as a Service: Choose this when you have an ongoing queue of administration, reporting, automation, data, and process work but do not want to assemble an internal team. The central buying question is how strategic decisions and recurring execution are divided.
    • Project-based specialist: Choose this for a bounded migration, CRM rebuild, routing redesign, CPQ implementation, outbound system, or integration. A contained scope should have explicit deliverables, acceptance tests, change controls, and a handoff owner.
    • Coaching, methodology, or enablement: Choose this when your internal team can implement but needs a common sales process, operating language, management cadence, or training system. Do not buy advisory work if your real constraint is a lack of hands-on capacity.

    Map the failure before contacting vendors. Trace the customer path from acquisition through qualification, opportunity management, closed-won, onboarding, adoption, renewal, and expansion. Mark the point where ownership becomes unclear, data stops moving, or teams begin using conflicting definitions.

    If failures appear across Marketing Operations, Sales Operations, and Customer Success Operations, favor a full-lifecycle team. If the problem stays inside a known system or workflow, a specialist may be faster and easier to govern. If your team knows what to do but applies it inconsistently, coaching may be sufficient. If nobody has authority to decide what should happen, you need an accountable fractional leader before you need more tools.

    A useful buying brief fits in one sentence: We need an accountable owner to improve this lifecycle handoff in these systems, with success judged by these business and operational measures. If you cannot complete that sentence, use discovery to define the problem before committing to a large implementation.

    Leading RevOps firms, organized by the work they fit

    No firm is the universal best choice. The table below treats leading RevOps companies as a fit map: what each appears equipped to handle, followed by the issue you should validate before signing.

    FirmConsider it whenWhat to validate
    DomestiqueYou are a B2B SaaS company seeking embedded, full-lifecycle coverage across Marketing Operations, Sales Operations, Customer Success Operations, platform implementation, and agentic infrastructure. Its reported capabilities include more than 60 senior operators, work with more than 250 B2B organizations, and hands-on AI agents and MCP integrations.Confirm which senior operators will work on your account, their allocated capacity, and the leadership participation expected from your team. The fractional-agency assessment specifically notes that active client leadership involvement is important at the strategy layer.
    Go NimblyYou run a Salesforce- or HubSpot-centered growth-stage SaaS environment and need revenue architecture, technical execution, AI readiness work, or RevOps coaching. Its positioning combines AI-enabled GTM strategy with Salesforce, HubSpot, Outreach, and Salesloft experience.Define how much hands-on Customer Success Operations coverage is included. Also identify the exact team composition because reported delivery pace can depend on scope and staffing.
    SkaledYou need a modular intervention rather than complete outsourced ownership. Available services span fractional CRO or VP leadership, CRM and automation support, revenue enablement, outbound performance, and an AI GTM system. A NoFraud case study reports a 126% pipeline increase and 95% MQL growth over eight months, but that result is case-specific rather than a forecast for another company.Ask who coordinates work when your scope crosses leadership, administration, enablement, and AI practices. Confirm which result from the relevant case work is transferable to your market, team, and funnel.
    RevPartnersYou are committed to HubSpot and want an ongoing RevOps-as-a-Service model, lifecycle measurement, GTM engineering, or Clay-powered outbound automation. Its Revenue Performance Model connects acquisition, conversion, retention, and expansion.Test the required depth outside HubSpot and Clay. Salesforce-primary companies and teams requiring extensive hands-on Customer Success Operations should define those needs explicitly before assuming they are covered.
    FullFunnelYou need broad B2B GTM strategy plus Sales Operations, Marketing Operations, or managed RevOps. Its listed platform footprint includes HubSpot, Salesforce, Clay, Apollo, and n8n.Ask which lifecycle stages the proposed team will own, which it will support, and which remain with you. Platform breadth should be converted into named deliverables and accountable operators.
    OperatusYour requirements center on Salesforce CPQ, MuleSoft, systems integration, or managed RevOps in a stack that may also include HubSpot, Apollo, Salesloft, LeanData, Outreach, or Marketo. Those platform and consulting specialties distinguish its systems-oriented offer.Verify whether your scope needs a technical implementation partner, a cross-functional operating leader, or both. Do not assume CPQ and integration expertise automatically includes deep marketing and post-sale ownership.
    Winning By DesignYou already have people who can execute and primarily need GTM methodology, the SPICED framework, revenue coaching, or certification. Its listed specialty is methodology training and advisory rather than comprehensive outsourced operations.Separate enablement deliverables from system-building deliverables. If you need CRM administration, integration work, data remediation, or ongoing workflow ownership, identify who will perform it.
    Think RevOpsYou want RevOps as a Service or stack optimization across HubSpot, Salesforce, and Gainsight. The inclusion of Gainsight makes it worth considering when customer-success tooling is part of the operating problem.Request direct evidence for any AI implementation requirement. AI or agentic capability was not listed for the firm in the 2026 fractional-agency comparison.
    RevOps AutomatedYou need GTM strategy, system integration, managed services, or AI-powered workflow automation in HubSpot and Salesforce. Its positioning emphasizes automation and AI-powered GTM workflows.Ask to see the architecture, controls, and operational results of a comparable workflow. Also define the required Customer Success Operations depth rather than inferring it from the managed-services label.
    Process Pro ConsultingYou have a focused HubSpot build, cleanup, or optimization requirement and prefer a specialist over a broad multi-platform firm. Its listed proficiency and specialty are centered on HubSpot.Inventory every system that must exchange data with HubSpot. If Salesforce, customer-success platforms, or agentic automation are material to the scope, determine whether another specialist will be needed.

    Your preferred order can change simply by changing the scoring weights. The fractional-agency methodology assigned 30% to platform proficiency and 30% to AI and agentic capability. The broader RevOps methodology assigned 30% to leadership, 25% to platforms, 20% to customer reviews, and 10% each to AI capability and lifecycle scope. A company prioritizing AI infrastructure could therefore reach a different answer from one prioritizing executive leadership or full-lifecycle operations.

    Rewrite those weights around your own risk. If your CRM is unstable, architecture and implementation depth should dominate. If functions disagree about stages, ownership, or forecasting, leadership and lifecycle scope matter more. If you already have strong operators and need a repeatable selling method, coaching quality should carry more weight than platform breadth.

    Do not let a logo wall override this work. Notable clients accounted for only 5% in the fractional-agency methodology and 5% in the broader company methodology. A famous client proves that some relationship existed; it does not establish that the agency handled your use case, systems, lifecycle stage, or engagement model.

    Use a buying process that exposes delivery risk

    Client and agency teams test a modular revenue workflow together while reviewing handoffs, system access, and contingency paths.

    Give every candidate the same written brief and ask for the same evidence. Otherwise, the most polished pitch will seem like the strongest capability even when candidates are solving different versions of your problem.

    Identify the operator who will actually own the work

    A senior leadership page does not tell you who will attend your operating meetings, make architecture decisions, configure systems, or resolve conflicts between marketing, sales, finance, and customer success. Ask the candidate to name the proposed operator and explain the delivery chain.

    • Who is accountable for the business outcome, and who performs the implementation?
    • Which proposed team members are employees, contractors, specialists, or executive sponsors?
    • How much concurrent client work does each assigned operator carry?
    • Who has authority to approve process, data-model, and automation decisions?
    • What happens when a requirement crosses practice areas or falls outside the original platform specialty?
    • Which responsibilities remain with your internal leaders, administrators, analysts, and front-line managers?

    Listen for clear ownership, not a large roster. A fractional executive who cannot direct implementation may leave you coordinating multiple delivery teams. An administrator without authority may complete tickets while the underlying operating disagreement remains untouched.

    Test platform depth with one of your real workflows

    Partner status and certifications are useful screening signals, but they do not prove that the proposed operator has solved your specific architecture problem. Bring a representative workflow to the evaluation: lead routing, account matching, opportunity-stage governance, CPQ approval, marketing attribution, closed-won handoff, renewal management, or expansion identification.

    Ask the candidate to map the systems of record, objects, fields, triggers, dependencies, permissions, exception paths, and reporting effects. Strong operators will surface ambiguities before proposing automation. Weak answers jump directly to a tool or produce a generic diagram that could apply to any company.

    Protect production data during implementation. Do not permit bulk CRM writes, object changes, routing changes, destructive merges, or new automations without an approved backup or export, a test environment where the platform supports one, defined validation checks, a release owner, and a rollback plan. A failed routing rule can hide demand; a poorly governed merge or overwrite can destroy history needed for attribution, forecasting, or account management.

    Trace ownership through the complete customer lifecycle

    Full-funnel language can describe measurement rather than hands-on ownership. Ask each candidate to walk through the lifecycle and identify who designs, implements, monitors, and improves every important handoff.

    • Acquisition to qualification: Who defines fit, intent, routing, response expectations, and rejection reasons?
    • Qualification to opportunity: Who governs stage entry, required fields, ownership changes, and pipeline reporting?
    • Closed-won to onboarding: Which data crosses the handoff, where is it stored, and who checks completeness?
    • Onboarding to adoption: How do product, service, or customer-success signals become visible to the revenue team?
    • Adoption to renewal: Who owns renewal dates, risk signals, commercial actions, forecasts, and escalation?
    • Renewal to expansion: How are expansion opportunities identified, assigned, measured, and separated from retention?

    If the answer becomes vague after closed-won, you are probably evaluating a sales-and-marketing operations firm rather than a complete lifecycle partner. That may be the right fit, but it should be an explicit decision rather than a discovery made after the engagement begins.

    Turn AI positioning into an auditable system design

    AI readiness, AI strategy, agent deployment, and agentic infrastructure are different deliverables. Domestique lists MCP server deployments, a deterministic harness framework, and Claude and Clay agents. Go Nimbly emphasizes AI-enabled architecture and readiness. Skaled combines maturity benchmarking, deployment, training, and certification. RevPartners focuses on Clay-powered allbound automation, while RevOps Automated emphasizes AI-powered GTM workflows. Put the exact capability you need into the scope instead of purchasing the broadest label.

    • Use case: What specific decision or task will the system assist, automate, or execute?
    • Inputs: Which CRM records, conversations, documents, enrichment data, or customer-success signals can it read?
    • Permissions: Can it only recommend an action, or can it create, update, route, message, or delete?
    • Control: Which actions require human approval, and who is accountable for that approval?
    • Evaluation: How will you test accuracy, completeness, consistency, and business usefulness before release?
    • Observability: What prompts, tool calls, outputs, errors, and record changes are logged?
    • Failure handling: What happens when the model is unavailable, uncertain, wrong, or given incomplete data?
    • Ownership: Who maintains instructions, integrations, permissions, evaluations, and vendor dependencies after launch?

    A working demo is more valuable than an AI strategy slide. Use representative but non-sensitive data and ask the candidate to show the complete path from input through reasoning or rules to the resulting CRM action. If the workflow can change customer records, routing, forecasts, or outbound messages, require approval boundaries and a recoverable path before production access is granted.

    Read reviews for engagement similarity, not just stars

    Review averages compress important differences. One 2026 methodology aggregated verified G2, Clutch, and Google ratings and rounded them to the nearest half star; the broader methodology weighted RevOps-specific engagements and rounded ratings to whole stars. Neither treatment tells you whether a positive review came from an embedded transformation, a migration, a small administration project, or executive coaching.

    Ask for references that match your company stage, primary platform, lifecycle problem, and engagement model. Questions about setbacks are more revealing than requests for general satisfaction: what slipped, which assumption proved wrong, how scope changed, who resolved cross-functional conflict, and what the client had to own internally.

    Scope the first engagement so you can judge real progress

    A strong statement of work turns RevOps language into operating commitments. It should make clear what will change, how you will accept it, who can decide, and how your team will run the result after the agency leaves.

    • Problem boundary: Name the lifecycle failure, affected teams, systems, records, and processes. Also state what is out of scope.
    • Baseline and outcome: Record the current operational and business measures that matter. Distinguish outputs such as workflows built from outcomes such as cleaner routing, more reliable stage data, better handoff completeness, or usable renewal visibility.
    • Target operating design: Define stages, ownership, systems of record, required data, decision rights, and escalation paths before automating them.
    • Deliverables: List the actual artifacts and system changes: architecture maps, data dictionaries, lifecycle definitions, configured workflows, dashboards, documentation, training, and governance procedures.
    • Acceptance criteria: State how each deliverable will be tested and who can approve it. Completion should not depend solely on the agency declaring a task done.
    • Change control: Specify test procedures, production permissions, release approval, backups, rollback, and incident ownership.
    • Internal participation: Name the executive sponsor, operational owner, system administrator, subject-matter experts, and front-line users whose decisions or feedback are required.
    • Handoff: Require accessible documentation, administrator training, unresolved-risk tracking, credential and integration ownership, and a prioritized backlog for work that remains.
    • Commercial boundaries: Clarify which work is included, what triggers additional fees or a change request, and how staffing changes affect delivery.

    If your problem is still poorly defined, make the first phase a diagnostic with implementation-ready outputs: a current-state map, target-state design, prioritized backlog, ownership model, dependencies, risks, and acceptance criteria. Do not accept a generic strategy presentation that forces the implementation team to rediscover the same requirements.

    Before your next agency call, write the one-sentence problem, list the systems involved, mark the affected lifecycle handoffs, and identify the proof you need to see. Send the same brief to each candidate. The safer choice is usually the firm that sharpens your scope, names tradeoffs, assigns an accountable operator, and makes its implementation testable.

    References


  • How to Design an AI-Assisted Content Workflow That Holds Up

    How to Design an AI-Assisted Content Workflow That Holds Up

    You probably do not need a better writing prompt. You need a production system that knows what can be published, which evidence it may use, and when a human must stop the run.

    If your current workflow produces fluent drafts followed by unpredictable rewrites, the model is not necessarily the bottleneck. The missing layer is usually an explicit definition of done. Build that first, then require every stage to prove that its output is ready for the next one.

    Begin with a publishable-content contract

    Start at the end. Work backward from the finished result and describe what an editor must see before approving it. This turns quality from a subjective reaction into a set of decisions your workflow can enforce.

    A publishable-content contract should cover at least six dimensions:

    • Reader value: The page resolves a defined question, problem, worry, or decision for a named audience. It does not merely cover a keyword.
    • Original contribution: The draft contains an insight, example, methodology, case study, internal finding, or point of view that is not interchangeable with every other result.
    • Factual integrity: Every material claim can be traced to approved evidence. Uncertainty is visible, and missing support stops publication.
    • Brand and product accuracy: Descriptions of your company, services, products, and methods match an approved source of truth.
    • Editorial fit: The language follows demonstrated voice patterns, structural rules, and publication standards.
    • Search and answer readiness: The page answers the central question early, uses descriptive headings, supports claims with nearby citations, and includes appropriate metadata and internal links.

    Write each requirement so that an editor can pass or return it. Useful criteria describe observable evidence: the opening answers the primary question; every number has a supporting link; the product description matches the approved product document; the page does not duplicate the intent of an existing URL. Vague criteria such as compelling, natural, authoritative, or optimized cannot control a workflow because two reviewers can interpret them differently.

    Your contract should also separate outputs from outcomes. A correct meta description is an output. A ranking is an outcome. A clearly supported answer passage is an output. Being cited by an AI system is an outcome. Your workflow can require the former and improve the potential for the latter, but it cannot guarantee rankings, traffic, or citations.

    Voice needs the same treatment. A list of adjectives is not enough. Instead of telling the model to sound friendly and expert, provide approved examples, counterexamples, and editing rules. Specify how quickly the writing reaches the answer, how technical terms are introduced, which claims require qualification, and which verbal habits should be removed. Examples of what to imitate and what to avoid give the system something concrete to compare.

    Separate permanent context from run-specific inputs

    An AI workflow becomes unreliable when every run begins with a different pile of documents. Divide your inputs into two groups: stable context that governs all work and a job packet that defines the current assignment.

    Permanent context

    Keep these assets under version control or in another clearly governed location. Give each one an owner and a review process so the workflow does not keep repeating outdated claims.

    • Brand explainer: Who you are, who you serve, the problems you address, and the boundaries of what you offer. For B2B content, include the relevant industries, roles, seniority levels, and pain points.
    • Voice guide: Approved passages, before-and-after edits, prohibited patterns, formatting preferences, and examples of language that sounds wrong for the brand.
    • Gold-standard work: Strong briefs, outlines, and published pages that demonstrate the expected depth and structure.
    • Product and methodology records: Approved descriptions, capabilities, limitations, terminology, and positioning. Sales collateral may help, but editorially sensitive claims still need verification.
    • Content inventory: Live URLs, titles, target topics, and summaries. A sitemap or crawl export can support internal-link suggestions and duplication checks.
    • Proprietary evidence: Internal research, case studies, approved customer evidence, and subject-matter expertise that can make the output distinct.
    • Publication rules: Requirements for citations, answer-forward passages, headings, paragraph structure, keyword use, metadata, URL slugs, internal links, and pre-publication review.

    Do not treat this library as one enormous prompt. The orchestrator should supply each stage with the context it needs. A research stage may need the audience definition and content inventory. A drafting stage needs the approved brief, evidence packet, voice examples, and product record. A metadata stage does not need every sales document your company has produced.

    Run-specific job packet

    Require the person starting a run to complete a small set of fields. If a field is essential and ambiguous, block the run instead of inviting the model to guess.

    • Content type and intended publication destination
    • Primary reader and the decision or task the page should support
    • Primary question, topic, or keyword
    • Angle, thesis, or intended distinction from existing content
    • Concepts that must be covered without forcing exact-match phrasing
    • Product, service, or methodology to mention, if any
    • Required internal evidence, examples, links, or subject-matter input
    • Constraints, reviewer, and final approver

    The angle deserves special attention. A keyword tells the system what territory to enter; it does not tell the system what useful contribution to make. If the angle is not known at kickoff, research should propose and test one before an outline is approved.

    Build a gated pipeline, not a chain of prompts

    An isometric five-stage pipeline moves source materials through drafting and verification chambers, with gates and revision trays between each stage.

    A sequence of prompts can produce text. A workflow produces controlled state changes. Each stage should have a defined input, task, output format, acceptance test, and failure route. An orchestrator should describe the full order of operations and the responsibility of every agent, then be updated whenever those responsibilities change.

    1. Kickoff: Validate the job packet. Confirm that the reader, question, content type, and angle are sufficiently specific. Return incomplete requests before they consume research or editing time.
    2. Research: Build an evidence packet, not a loose collection of links. Record the claim each reference can support, relevant qualifications, and any gaps that prevent the proposed angle from working. Review current site content so the new page has a distinct job.
    3. Brief: Define the search intent, reader outcome, central answer, differentiating contribution, required claims, evidence boundaries, internal-link opportunities, and optimization requirements. A researcher should be able to explain why the proposed page deserves to exist.
    4. Outline: Give every section one job. Put the answer before extended context, eliminate headings that merely restate the topic, and identify where evidence, examples, or proprietary material must appear.
    5. Draft: Write only from the approved brief and evidence packet. Preserve qualifications from the evidence. Mark unresolved claims for verification rather than filling gaps with plausible language.
    6. Factual review: Extract material claims from the draft and check each one against its supporting evidence. Return unsupported, overstated, time-sensitive, or internally contradictory claims.
    7. Editorial review: Check usefulness, structure, repetition, voice, product accuracy, and readability. This should be a distinct pass from factual review because a polished sentence can still be false, and a correct sentence can still be unhelpful.
    8. SEO, AEO, and GEO review: Verify that the page answers its main question clearly, uses descriptive headings, keeps citations close to supported claims, integrates concepts naturally, and does not sacrifice accuracy for phrasing. This pass may restructure existing information but should not introduce new facts.
    9. Publication preparation: Generate the meta description, proposed slug, internal links, and any other required CMS fields. If structured data is prepared, every represented claim must also be supported by the visible page.
    10. Human approval: Resolve remaining flags, verify consequential claims against the underlying evidence, and make the final publish-or-return decision.

    Make every handoff inspectable

    A stage should never report that it is done without showing what it produced and why it passed. The following contract makes failures easier to diagnose:

    StageRequired inputRequired outputReturn condition
    KickoffCompleted job packetValidated assignmentReader, question, or angle is missing
    ResearchAssignment and approved contextEvidence packet and gap listThe central answer lacks support or duplicates an existing page
    BriefEvidence packet and quality contractApproved content specificationThe proposed claims exceed the evidence
    DraftBrief, evidence, and voice examplesDraft and claim ledgerA required section is absent or a specific claim is unsupported
    Quality assuranceDraft and acceptance criteriaPass, return, or blocked reportAny publication-critical issue remains unresolved

    Use explicit statuses such as pass, return, and blocked. Pass sends the output forward. Return sends it to a named earlier stage with a reason code and requested correction. Blocked means the workflow cannot continue without new evidence or a human decision. This is more useful than letting an orchestrator silently rewrite failed work, because silent rewrites hide the stage that needs improvement.

    Keep the claim ledger attached to the job throughout the run. It should identify each material claim, its supporting reference, relevant qualification, and verification status. That record gives the factual reviewer a finite checklist and gives the human approver a direct path back to the evidence.

    Place human gates where errors become expensive

    A human editor compares a draft with source documents at an illuminated checkpoint before opening the final publication gate.

    Human review should not be one hurried read after the system has made every consequential decision. Put gates before expensive downstream work and before publication.

    • After research: A human confirms that the angle is worth pursuing, the evidence can support it, and the proposed page is sufficiently different from existing content. Stopping here is cheaper than rewriting a complete draft.
    • After the outline: A human checks whether the structure answers the reader’s actual question, whether each section earns its place, and whether proprietary material appears where it can change the value of the page.
    • Before publication: A human verifies unresolved claims, product statements, sensitive assertions, and any facts whose meaning depends on date, version, market, or audience. The approver also decides whether the page meets the quality contract as a whole.

    AI-assisted fact-checking can extract claims, compare wording with supplied evidence, and surface inconsistencies. It should not be allowed to convert missing support into confidence. Configure the check to return an unresolved claim when the evidence is absent, ambiguous, or narrower than the draft.

    Give factual review a precise set of questions:

    • What exact claim is being made?
    • Which approved evidence supports it?
    • Does that evidence support the whole claim or only part of it?
    • Has a qualification, limitation, or condition been removed?
    • Could the claim depend on a date, product version, geography, or audience?
    • Does the wording imply causation, certainty, consensus, or performance that the evidence does not establish?
    • Is the claim about your company or product consistent with the approved source of truth?

    Run the voice check separately. Asking a model to make a draft sound more human is too open-ended and can change meaning while polishing the prose. Instead, compare the draft with approved examples and enforce observable rules: opening length, sentence patterns, terminology, banned filler, level of explanation, use of first person, and how uncertainty is expressed.

    The optimization pass needs its own boundary as well. It may improve answer placement, heading clarity, internal linking, metadata, and concept coverage. It may not add a statistic, broaden a product claim, manufacture a consensus, or create structured data that says more than the visible content. When optimization changes meaning, the draft must return to factual review.

    Start narrow and improve the system from its failures

    Do not begin with a universal engine for blog posts, landing pages, social posts, newsletters, and external contributions. Get one content type working before adding conditional branches for others. Different formats have different definitions of done, so premature flexibility makes failures harder to locate.

    A sensible first implementation has one content type, one primary audience, one quality contract, one approved context library, and one accountable human owner. Run real assignments through it and record every intervention. The corrections tell you what to improve:

    • Repeated research gaps mean the kickoff fields, approved references, or research instructions are insufficient.
    • Repeated outline changes mean the brief does not define the reader outcome or differentiating angle clearly enough.
    • Repeated factual corrections mean the evidence packet, claim ledger, or factual-review rules need work.
    • Repeated voice edits mean the voice guide needs better examples and counterexamples.
    • Repeated internal-link errors mean the content inventory is incomplete, stale, or not being retrieved correctly.
    • Repeated optimization rewrites mean search requirements are arriving too late and should move into the brief or outline.

    Measure the workflow separately from published performance. For the workflow, track which gate returns work, why it returns, how often humans correct each error category, and which stage creates the delay. For published pages, track the business and search outcomes that matter to you. Do not let a later ranking obscure a broken factual process, and do not assume a correctly executed workflow guarantees a ranking.

    Not every team needs a coded, multi-agent system. A smaller prompt set and human checklist may be the better choice when volume is low, the offer changes frequently, source-of-truth documents do not exist, or no qualified reviewer is available. Building the pipeline is substantive work, and it can be assembled in stages. Automation should follow a stable editorial process, not substitute for one.

    Key takeaways

    • Define publishable quality before choosing models, agents, or prompts.
    • Separate permanent brand context from the job packet supplied on each run.
    • Give every stage a required input, output schema, acceptance test, and failure route.
    • Maintain a claim ledger so factual review can trace assertions to approved evidence.
    • Use humans to approve the angle, structure, consequential claims, and final publication decision.
    • Start with one content type and improve the workflow from recorded failure patterns.

    Your next move is not to add another agent. Choose one recently published page your team considers strong. Convert it into an acceptance checklist, trace every criterion back to the input needed to satisfy it, and run one real assignment through the stages manually.

    Automate only after the gates produce repeatable decisions. By then, you should be able to say why a run passed, where a failed run must return, and who owns the next decision. If any of those answers is unclear, keep that part of the workflow visible and manual for another cycle.

    References


  • Automated E-E-A-T Auditing: An Evidence-Led Workflow

    Automated E-E-A-T Auditing: An Evidence-Led Workflow

    Your crawler can find a missing byline in seconds. It cannot tell you, by itself, whether a reader should trust a consequential claim or whether Google will consider its creator authoritative. That distinction determines whether automated E-E-A-T auditing becomes a useful quality-control system or confidence theater.

    A reliable audit collects observable evidence, judges that evidence against the purpose of each page, and sends uncertain or consequential decisions to a person. It turns a broad quality framework into a repeatable editorial queue without pretending that E-E-A-T is a metric you can retrieve from Google.

    An automated audit finds evidence; it does not measure Google

    E-E-A-T stands for Experience, Expertise, Authoritativeness, and Trustworthiness. Google uses it as a framework for evaluating content quality and credibility, but its guidance is not exposed through a simple API endpoint. Your tool therefore cannot request an official E-E-A-T score. Any percentage, grade, or traffic-light rating it produces is a summary of your own rubric.

    That does not make automation useless. It changes what the tool should claim to do. A defensible auditor identifies evidence that a reviewer would use when making an E-E-A-T assessment:

    • For experience, it can locate descriptions of a process, first-hand observations, original methods, demonstrations, limitations, and outcomes. It cannot prove that the claimed experience happened.
    • For expertise, it can inspect bylines, biographies, qualifications, professional roles, explanatory depth, and support for factual claims. It cannot infer genuine expertise merely because the prose sounds confident.
    • For authoritativeness, it can connect a page to an identifiable creator or organization and find evidence of relevant work or recognition. An on-site crawl alone cannot establish the wider reputation of that entity.
    • For trustworthiness, it can check ownership, contact routes, dates, citations, disclosures, policies, corrections information, and consistency between visible content and structured data. It cannot verify every claim simply because the page contains references.

    The right verdict vocabulary reflects those limits. Use labels such as observed, missing, ambiguous, not applicable, and not assessed. A failed browser request must produce not assessed, not missing. A weakly relevant biography should be ambiguous, not automatically accepted as expertise.

    This distinction protects your editorial team from a common failure: treating a detector’s confidence as evidence of the underlying fact. The detector may be highly confident that it found a credential. Whether the credential is real, current, and relevant is a separate judgment.

    Build a page-type-aware rubric before choosing a model

    Three different page types are paired with distinct sets of evidence symbols and evaluation frameworks.

    A universal checklist will punish pages for failing to be something they were never meant to be. A contact page does not need an expert byline. An author profile should not be judged as though it were a commercial landing page. An editorial policy can describe a review process, but its existence does not prove that the process was followed on every URL.

    Start by classifying pages according to purpose. Then decide which evidence is applicable to each class. The following matrix is a practical starting point, not an official Google scoring model.

    Page typePrimary audit questionsMisreading to prevent
    Informational contentWho is responsible for the claims? Is relevant expertise or experience visible? Are factual assertions supported and limitations explained?Treating fluent, detailed prose as proof of expertise.
    Author or reviewer profileIs the person identifiable? Are qualifications, roles, experience, and published work relevant to the subjects they cover?Awarding expertise for a generic biography or an unrelated credential.
    Homepage or about pageWho owns the site? What does the organization do? Is its purpose, identity, and relevant competence clear?Counting promotional language as independent evidence of authority.
    Commercial or service pageIs the seller identifiable? Are important claims substantiated? Can a customer find material terms, support, and an accountable contact route?Assuming conversion copy is sufficient evidence of trust.
    Editorial, disclosure, or corrections pageAre review, correction, sourcing, and commercial-disclosure processes explained clearly enough to be followed?Assuming that a published policy proves consistent implementation.

    Write each rubric check as an operational rule. Name the page types to which it applies, the evidence the auditor may accept, evidence that is insufficient, the allowed verdicts, the reason the check matters, and the remediation that follows a failure. If two reviewers cannot apply a rule consistently, an AI model will not rescue it.

    For example, a rule called author expertise present is too loose. A better rule asks whether the page identifies its primary creator and whether the linked profile contains experience, qualifications, or work relevant to that page’s subject. The tool should return the creator’s name, the relevant evidence it found, the URL or element containing that evidence, and any ambiguity. It should not award expertise simply because an Author field exists in JSON-LD.

    Structured data is valuable evidence about how a site represents its entities. It is not a substitute for the underlying reality. Compare author names, organization names, publication dates, review dates, and canonical URLs in markup with what a visitor can see. Flag contradictions as trust issues. Do not award credibility merely because the markup is syntactically complete.

    Do not begin with a whole-site score. Begin with representative page types because one page cannot support a meaningful assessment of an entire website, while a complete crawl is often unnecessary during rubric development. Include the templates that publish important claims, the pages that establish creator and organization identity, and the governance pages those templates rely on. Expand only after the rules work on that sample.

    Run a browser-based evidence pipeline

    Abstract web pages move through an automated evidence pipeline while linked source items reach a human review station.

    The model should be one component of the auditor, not the entire auditor. Retrieval, rendering, classification, deterministic checks, language-model judgment, and reporting solve different problems. Keeping them separate makes failures visible and lets you improve one layer without rewriting everything.

    1. Define the audit unit. Record the site or section, locale, content types, excluded areas, and whether the run is a template sample or a broader crawl. This prevents results from unrelated markets or subdomains from being combined accidentally.
    2. Inventory and classify URLs. Group pages by purpose and template before sampling. Classification can begin with URL patterns, metadata, headings, structured-data types, and internal-link context, but uncertain classifications should remain reviewable.
    3. Select representative pages. Cover each important content purpose and template. Include identity and governance pages that provide context for individual URLs. A sample made only from high-traffic articles will miss the pages that establish who publishes the content and how it is controlled.
    4. Render the pages. Basic fetchers can be blocked or can miss client-rendered content. A headless Chromium browser driven through Python automation can acquire the page as a browser sees it. Chromium and Selenium are practical examples, not requirements.
    5. Extract evidence into a structured record. Capture the final URL, page title, headings, visible byline, linked profiles, visible dates, citations, policy links, contact details, relevant disclosures, internal and external links, and JSON-LD. Preserve where each item appeared rather than flattening the page into an unattributed text blob.
    6. Run deterministic checks first. Code is better than an LLM at confirming that an element exists, a link resolves, a byline points to a profile, or visible and structured names disagree. Use language-model judgment for questions that require interpreting relevance, specificity, or context.
    7. Apply the rubric with constrained outputs. Give the model the page class, the applicable criteria, the extracted evidence, and the allowed verdict labels. Require evidence for every observed or ambiguous result. Instruct it not to infer facts that are absent and not to penalize criteria marked not applicable.
    8. Aggregate only after page-level review. Keep template patterns, page-specific findings, acquisition failures, and site-level context separate. A footer link repeated across every URL is one site-wide element, not fresh evidence on every page.

    The acquisition status belongs in every result. Record successful rendering separately from blocked requests, authentication barriers, timeouts, parsing failures, unsupported files, and deliberate exclusions. Otherwise a crawler defect can generate a site-wide wave of false missing-evidence findings.

    Keep the AI’s task narrow. It can judge whether a biography appears relevant to a subject, whether a passage describes a specific method, or whether a citation plausibly supports the nearby assertion. A human should decide whether credentials are authentic, whether high-consequence claims are correct, whether claimed experience is genuine, and whether external reputation supports an authority judgment.

    Make every finding traceable and reviewable

    An editor should be able to challenge an audit result without rerunning the entire system or reverse-engineering a prompt. Each finding needs a compact evidence trail:

    • The criterion and the page type that made it applicable.
    • The audited URL and acquisition status.
    • The verdict and confidence in that verdict.
    • The exact evidence used, kept to the shortest useful fragment.
    • The evidence location, such as a heading, link target, structured-data property, or DOM selector.
    • The rule or model version that produced the result.
    • A plain-language explanation of why the evidence passed, failed, or remained ambiguous.
    • A specific next action and the person or team best placed to take it.

    Keep coverage separate from quality. If the auditor reached only part of the intended sample, report incomplete coverage prominently. Do not let the successfully audited pages create an apparently healthy site score while blocked or unclassified URLs disappear from the denominator.

    A single composite score usually hides the decision an editor needs to make. Prefer an evidence matrix that shows status by criterion and page type, plus severity based on the consequence of the issue. A missing optional biography detail should not cancel out an identity conflict or an unsupported consequential claim merely because both affect the same average.

    Controls for predictable failure modes

    • Retrieval failure looks like missing content. Gate all content judgments on successful acquisition and rendering.
    • Template elements inflate the result. Deduplicate repeated headers, footers, and policy links, then distinguish site-wide evidence from page-local evidence.
    • The model fills gaps with plausible assumptions. Require a captured evidence fragment and location for every positive verdict. Unsupported conclusions fail validation.
    • A generic checklist creates irrelevant failures. Mark applicability before scoring and retain not applicable as a real result.
    • Structured data earns unmerited credit. Treat markup as a claim about an entity, compare it with visible content, and flag mismatches instead of assuming truth.
    • An overall grade conceals serious findings. Report coverage, evidence status, ambiguity, and issue severity independently.
    • Prompt changes move the benchmark. Version the rubric, prompts, extraction logic, and result schema together. Re-run the validation set whenever one changes.
    • Stored page copies create avoidable content risk. Retain short evidence fragments, URLs, locations, and hashes where practical instead of archiving full third-party pages in the project repository.

    Validate the auditor before expanding the crawl

    Create a human-reviewed set of representative pages and record the expected applicability, evidence, verdict, and rationale for each check. Compare the automated output with those decisions. Inspect false positives and false negatives by criterion rather than celebrating agreement at the report level. A system that reliably finds bylines may still be poor at judging whether qualifications are relevant.

    Test uncomfortable cases deliberately: a credential that is impressive but unrelated, a methodology paragraph with no indication that the creator performed the work, a policy that exists but is not linked from relevant pages, conflicting author names in visible content and JSON-LD, and a browser failure that leaves the extracted body empty. These cases reveal whether the auditor follows evidence or merely rewards familiar patterns.

    Keep the rubric, prompts, test cases, and extraction code in version control. A project can begin inside an AI coding environment for flexible, multi-session iteration, or become a standalone application deployed outside that environment. The first shape suits a rubric that is still changing. The second becomes useful when you need repeatable runs, controlled access, scheduled processing, and a stable interface. Deployment does not make the judgments more valid; validation does.

    Human review should remain visible in the final report. Record whether a finding is machine-only, reviewer-confirmed, changed by a reviewer, or awaiting specialist verification. Those states let you measure where automation saves time and where it still creates work.

    Key takeaways

    • An automated E-E-A-T audit measures evidence against your rubric; it does not retrieve a Google score.
    • Classify pages by purpose before applying checks. Applicability is part of the judgment, not an afterthought.
    • Use browser rendering for acquisition, deterministic rules for objective checks, and an LLM only where interpretation is required.
    • Require every verdict to point to captured evidence and its location. Unsupported positive findings are as dangerous as false warnings.
    • Report acquisition coverage, ambiguity, and severity separately instead of compressing everything into one grade.
    • Validate on human-reviewed edge cases, version the whole system, and expand the crawl only when the findings lead to sound editorial decisions.

    Start with one important page template and the identity or policy pages that support it. Label a representative set by hand, define what acceptable evidence looks like, and make the auditor explain every verdict. If it cannot distinguish absent evidence from inaccessible evidence, or observation from inference, it is not ready to scale. Once reviewers can turn its findings into precise edits without redoing the audit themselves, add the next template.

    References


  • How to Audit and Automate Your AI Search Visibility

    How to Audit and Automate Your AI Search Visibility

    Someone asks an AI assistant which company can solve their problem. Your brand may be absent, described vaguely, or mentioned for the wrong reason, even when your website is technically sound and ranks for relevant searches.

    If you only audit rankings, crawl health, and individual pages, you will not see that failure clearly. An AI search visibility audit checks whether models can identify your business, explain its relevance, distinguish it from competitors, and support those conclusions with public evidence. The useful output is not a vanity score. It is a prioritized queue of problems you can fix and monitor.

    Audit the model’s understanding, not only your pages

    Traditional SEO audits examine assets: technical health, content, backlinks, structured data, business profiles, citations, and reviews. Those checks remain necessary, but they do not show whether the assets collectively create a coherent explanation of the business.

    AI search systems can summarize organizations, compare products, recommend businesses, and combine information from multiple public surfaces. That makes the entity, rather than an isolated page, the correct unit of analysis.

    Your AI entity footprint is the public body of evidence from which a system could form an understanding of your organization. It includes your website, but it can also include business profiles, reviews, social profiles, directories, press coverage, podcasts, videos, conference appearances, and association memberships. The audit asks whether those signals agree and whether they justify the conclusions you want a prospective customer to reach.

    Measure the footprint across separate dimensions. Do not compress them into one opaque visibility score:

    • Entity resolution: Does the system identify the correct organization, or does it confuse the brand with another company, product, or similarly named entity?
    • Factual accuracy: Are its statements about your services, products, audience, locations, and areas of specialization correct?
    • Specificity: Could the description apply only to your business, or is it generic enough to fit most competitors?
    • Evidence: Does the answer provide public support for its claims? Do the cited pages actually support the wording used?
    • Consideration: Does your business appear when someone asks about the category or problem without mentioning your brand?
    • Recommendation: Does the system merely know the brand, or does it present the brand as a suitable option for a defined need?
    • Consistency: Do different systems agree on the essential facts, or do they construct materially different versions of the company?

    Understanding and recommendation are different outcomes. A system may accurately explain what you sell while lacking enough evidence to say why someone should choose you. It may also cite your page without recommending the company, or mention the company without supplying a citation. Record those states separately.

    You cannot read a model’s internal confidence from polished prose. Treat hedging, contradictions, missing support, and generic language as observable warning signs rather than direct measurements of confidence. Preserve the complete answer so a reviewer can see the context instead of relying on an automated interpretation.

    Build a prompt matrix that represents real buying decisions

    Hands arrange translucent query tokens across a grid of tiles illustrated with symbols for different buying considerations.

    A single branded prompt is a useful diagnostic, but it is not a visibility audit. It tells you whether the system can discuss a company after being given its name. It does not show whether the company enters the conversation when a buyer describes a category, problem, location, requirement, or alternative.

    Create a fixed prompt registry around the decisions your audience actually makes. Give every prompt a stable identifier, keep its wording unchanged during baseline comparisons, and use placeholders for market, audience, category, and use case. Add this instruction where appropriate: Use publicly available information, do not guess, separate verified facts from inference, provide supporting URLs when available, and flag missing or contradictory information.

    TestPrompt patternFailure to notice
    Entity explanationWhat does [Brand] do, who does it serve, where does it operate, and what evidence supports that description?Name confusion, wrong offerings, missing locations, or a generic summary
    Category discoveryWhich providers help [Audience] solve [Problem] in [Market], and why might each fit?Your brand is absent from an important consideration set
    SpecializationWhich companies specialize in [Capability] for [Use Case]?The model knows the company but does not associate it with the intended expertise
    ComparisonCompare [Brand] and [Competitor] for [Use Case]. Use verifiable differences rather than general claims.Competitors own the differentiators you intended to establish
    Evidence challengeWhat public evidence supports [Brand Claim], and what remains uncertain?A marketing claim is repeated without corroboration
    Customer objectionWhat should a buyer verify before choosing [Brand] for [Use Case]?Outdated, contradictory, or missing information creates avoidable uncertainty

    Run the same registry across the AI systems that matter to your audience. ChatGPT, Gemini, Claude, and Perplexity can produce different representations, so cross-system comparison is part of the diagnosis, not an attempt to identify one universally correct answer.

    For every run, retain the prompt, complete response, system and model label, run date, market and language, account or session conditions, browsing mode when visible, cited URLs, brands mentioned, recommendation language, unsupported claims, and factual errors. Do not merge several outputs into a summary before storing them. The raw response is your audit evidence.

    Classify each result with explicit states rather than a vague pass or fail. Useful states include correct, incorrect, incomplete, generic, contradictory, unsupported, outdated, and unresolved. A response can occupy several states at once: it may correctly identify the company while giving an incomplete audience description and an unsupported explanation of its differentiation.

    Keep branded and non-branded prompts in separate views. Branded tests expose entity-understanding problems. Non-branded tests expose discovery and consideration problems. Mixing them can make a well-understood brand look highly visible even when it rarely appears in category answers.

    Turn every weak answer into an evidence diagnosis

    Do not respond to a bad AI answer by publishing more content at random. Start with the questionable statement and trace it backward. Your job is to find which public signals support it, which signals contradict it, and which necessary facts are absent.

    Create a claim register with one row for every buyer-relevant fact: legal or trading identity, primary offering, intended audience, operating area, product or service scope, specialization, differentiator, and evidence of that differentiator. For each claim, record the correct wording, the page or profile that should establish it, independent corroboration when available, conflicting wording, current audit state, and the person responsible for correction.

    The website is only one part of this map. AI systems may encounter evidence through reviews, Google Business Profiles, LinkedIn pages, press mentions, industry directories, podcasts, videos, presentations, and memberships. An accurate homepage cannot fully compensate for contradictory information distributed across the rest of the footprint.

    Match the remedy to the failure:

    • Wrong identity, location, or offering: Verify the correct fact internally, then correct the canonical website page and the business profiles you control. Maintain a record of third-party corrections you request.
    • Contradictory information: Choose one canonical formulation and align controllable surfaces around it. Do not add another variation in an attempt to outrank the older versions.
    • Generic representation: Replace broad adjectives with verifiable specificity. State the audience, problem, operating scope, specialization, and meaningful limits of the offering.
    • Unsupported differentiation: Give the claim public evidence. Relevant reviews, documented credentials, credible mentions, presentations, memberships, and other verifiable material are more useful than repeating the same slogan across owned pages.
    • Missing category relationship: Publish a clear explanation connecting the audience’s problem to the relevant offering and proof. A page that merely repeats a category phrase does not establish why the entity belongs in that category.
    • Outdated representation: Identify the obsolete public surfaces before changing current copy again. An old directory entry or profile can keep reintroducing a retired location, service, or description.
    • Unsupported AI claim: Do not adopt the claim because it sounds favorable. Mark it as an error, preserve the response, and correct any ambiguous material that may be encouraging the inference.

    Structured data belongs in this correction process, but give it the right job. Organization or LocalBusiness markup can express consistent machine-readable facts already supported by the visible page. It cannot turn an unproven superiority claim into independent evidence. Treat JSON-LD as a consistency layer, not a reputation layer, and keep its names, URLs, identifiers, locations, and relationships aligned with the content people can read.

    Prioritize issues by consequence. A wrong location, mistaken identity, discontinued service, or misleading qualification deserves attention before a mildly generic description. Next, resolve contradictions that prevent a stable entity profile. Then strengthen category relevance, differentiation, and supporting evidence. This order protects accuracy before you optimize visibility.

    Automate collection and comparison without automating truth

    An automated conveyor sorts abstract AI responses while a researcher inspects one result against several evidence artifacts.

    Automation is most valuable where the work is repetitive: running a controlled prompt set, preserving responses, extracting citations, comparing results, and routing changes for review. It is least trustworthy where context and factual judgment matter. Do not let an agent publish website copy, change structured data, or revise business facts merely because one model produced a surprising answer.

    A practical monitoring pipeline has these stages:

    1. Prompt registry: Store the approved prompt text, market, language, test type, business objective, and expected entity facts.
    2. Execution layer: Send the same tests to selected systems under documented conditions and preserve the model label exposed by each interface.
    3. Raw capture: Save the complete response, citations, run context, and retrieval or browsing status when the system makes it available.
    4. Structured extraction: Convert the response into fields for entities mentioned, facts asserted, recommendation state, differentiators, cited URLs, uncertainty language, and possible contradictions.
    5. Baseline comparison: Compare those fields with the approved claim register and the previous runs without discarding the underlying text.
    6. Evidence validation: Open cited pages and confirm that each page supports the specific claim attributed to it. A relevant URL is not automatically supporting evidence.
    7. Issue routing: Send material changes to a human reviewer with the prompt, response excerpt, citation, affected claim, proposed severity, and likely owner.

    MCP-connected workflows can already compare competitor pages with live citation data, retrieve category reports, and support specialized AI agents. Use those capabilities to shorten the distance between an observed output and the evidence behind it. The agent should assemble the case; a responsible owner should decide whether the public information or the model output is wrong.

    Alerts should correspond to decisions, not every wording change. Route an issue when a core business fact becomes wrong or contradictory, your brand leaves an important category response, a competitor begins receiving a relevant recommendation, a cited page disappears or changes materially, an unsupported claim emerges, or a corrected fact continues to be represented inaccurately.

    Model outputs can vary, so preserve enough context to distinguish fluctuation from a durable footprint problem. Rerun the controlled test and compare other systems before treating an isolated phrasing change as a new business issue. Escalate faster when the error affects identity, eligibility, location, availability, or another fact that could cause a buyer to make the wrong decision.

    Your dashboard should keep distinct views for brand accuracy, non-branded category inclusion, recommendation context, citation health, competitor presence, and unresolved evidence gaps. Avoid a single composite score that lets strong branded recognition conceal weak category discovery or lets frequent mentions conceal factual errors.

    The final guardrail is simple: no automated correction should enter a public system without verification against the approved claim register and the underlying evidence. Otherwise, the monitoring process can amplify the same ambiguity it was built to detect.

    Key takeaways

    • Audit the public understanding of the business as an entity, not only the performance of individual pages.
    • Measure identity, accuracy, specificity, evidence, category consideration, recommendation, and cross-system consistency separately.
    • Use a stable prompt matrix covering branded explanation, non-branded discovery, specialization, comparison, evidence, and buyer objections.
    • Trace every weak answer to a missing, contradictory, outdated, generic, or unsupported public claim before creating more content.
    • Automate prompt execution, response capture, citation extraction, comparison, and issue routing, but keep factual decisions and public corrections under human review.
    • Use structured data to align machine-readable facts with visible content, not as a substitute for public proof.

    Start with the category that matters most to your business and the facts that would cause the greatest harm if an AI system misstated them. Establish the baseline, correct the clearest evidence gap, and rerun the same tests. Automate the collection only after the workflow produces issues your team can verify and own.

    The goal is not to force an AI system to repeat your preferred slogan. It is to make the public evidence coherent enough that the system can explain who you are, where you fit, and why you may be relevant without having to guess.

    References

  • How to Build a Self-Improving AI Content Workflow

    How to Build a Self-Improving AI Content Workflow

    You keep correcting the same AI output: a vague heading, an unsupported claim, a generic opening, a conclusion that says nothing. The draft improves after you edit it, but the workflow that produced it stays exactly the same.

    A self-improving content workflow preserves those corrections, finds recurring patterns, and changes the next run under controlled conditions. The goal is not an agent that rewrites its own rules without supervision. It is a system that turns editorial judgment into reviewable improvements to briefs, evidence retrieval, writing instructions, quality gates, and routing.

    A workflow improves only when feedback changes the next run

    Generating a draft, editing it, and publishing it is a production process. It becomes a feedback loop only when the correction affects a reusable part of the process. Unless you persist that correction somewhere, a new model run has no reason to avoid the same failure.

    The reusable change does not have to be a prompt edit. Feedback can change the criteria used to approve an angle, the queries used to retrieve evidence, the material included in a writing packet, the rubric applied by an editorial agent, or the route taken when a check fails. This distinction matters because many apparent writing problems originate before the writer receives the task.

    Every useful loop needs the same basic components:

    • An observable failure, recorded in specific terms.
    • A classification that identifies where the failure entered the workflow.
    • A proposed change to a reusable instruction, criterion, example, query, or routing rule.
    • An evaluation that checks whether the change fixes the target problem without damaging other requirements.
    • A human-controlled decision to approve, reject, revise, or roll back the change.

    That last component is what makes the system governable. Production agents can record feedback and propose patches, but they should not silently promote every correction into permanent operating memory. A rushed edit, an individual preference, or an unusual brief can otherwise become a global rule.

    Key takeaways

    • Begin with a quality gate around existing drafts; it creates useful feedback without requiring you to rebuild the whole pipeline.
    • Cap revision at two rounds. A draft that still fails usually needs better evidence, a narrower claim, or a stronger angle.
    • Separate editorial review from citation checking so each agent has a clear job and an appropriate context packet.
    • Stop weak angles and evidence gaps before writing. Upstream failures become more expensive after a full draft exists.
    • Use recurring edits as evidence for an instruction change, but require a proposal, evaluation, version record, and human approval.

    Start with a quality gate and a firm revision cap

    Blank manuscript sheets move through a quality gate, with one approved, one sent through a limited revision loop, and one routed to a human editor.

    The smallest practical self-improving workflow places an independent reviewer after the writer. The reviewer does more than declare that a draft feels weak. It evaluates explicit acceptance criteria, identifies the class of failure, and returns a bounded revision request.

    Build that loop in this order:

    1. Write an acceptance contract for the content type. Define the intended reader, the decision or task the content must support, the required evidence standard, the voice constraints, and the structural requirements.
    2. Give the writer a bounded packet containing the approved brief, outline, evidence, brand instructions, and output format. Do not make the writer infer which requirements matter most from a large repository of loosely related material.
    3. Send the resulting draft to an editorial reviewer in a separate context window. The reviewer should receive the acceptance contract and the draft, not the writer’s internal deliberation.
    4. Send factual claims and cited evidence to a dedicated fact-checker. Its job is to verify that the evidence supports the wording in the draft, not merely that a cited link exists.
    5. Classify the result as pass, flag, or escalate. Attach a precise diagnosis to every flag.
    6. Return fixable defects to the writer. The revision request should name the affected passage, failed criterion, reason for failure, and required result.
    7. Stop after two revision rounds. Route the draft and its review history to a person who can change the angle, evidence plan, or brief.

    The three verdicts need operational definitions. Pass means the draft meets the acceptance contract and its factual claims survive checking. Flag means the defect can be corrected within the existing brief and evidence set. An undefined term, an indirect opening, or a poorly ordered section can usually be flagged. Escalate means rewriting alone cannot solve the problem. Missing evidence, an unworkable thesis, contradictory requirements, and an angle with no defensible point of view belong here.

    The revision cap prevents an agent pair from polishing around a structural defect. If specificity remains weak after two rewrites, the evidence packet may not contain the concrete material the writer needs. Another instruction to be more specific will not create that material. The correct route is back to research or strategy.

    Keep editorial review and fact-checking separate even if both happen after drafting. An editorial reviewer asks whether the structure serves the argument, the language fits the audience, and the answer is useful. A fact-checker compares each factual statement with the evidence attached to it. Combining those responsibilities makes it easier for fluent prose to distract from weak support, or for citation work to crowd out substantive editing.

    Add a direct entry point to the gate as well. A draft written by a colleague, contractor, or older system should be reviewable without rerunning ideation, retrieval, and drafting. This makes the gate useful across the content operation and gives you a more representative record of recurring failures.

    Catch weak angles and evidence gaps before drafting

    A downstream reviewer can detect an unsupported claim, but it cannot manufacture the missing proof. It can identify a generic thesis, but by then you have already paid for research, drafting, and review. Two upstream checks prevent those failures from entering the expensive part of the workflow.

    Filter the brief with pass, revise, and kill decisions

    Evaluate each proposed angle against criteria you define before generation. Useful criteria include audience fit, thesis strength, original point of view, distance from existing coverage, and whether the necessary proof appears obtainable. The evaluator must choose an action, not simply assign a vague confidence score.

    VerdictMeaningNext action
    PassThe angle has a defensible thesis, fits the intended audience, and can be supported.Release the brief to evidence retrieval and outlining.
    ReviseThe idea is viable, but its scope, audience, differentiation, or evidence requirement is wrong.Return a specific change request, then evaluate the revised brief again.
    KillThe angle lacks a meaningful point of view or depends on proof that is not available.Stop the run and record the reason. Do not ask the writer to rescue it with phrasing.

    The kill log is not a graveyard for ideas. It is training data for strategy rules. Record the intended audience, thesis, decision, reason code, missing requirement, evaluator, and rule version. You can then see whether the same pattern keeps failing: duplicate angles, claims that require unavailable data, topics aimed at the wrong buyer stage, or briefs too broad to support a useful answer.

    Keep revise and kill distinct. Revise means a known change can make the brief viable. Kill means the core proposition does not survive the criteria. If evaluators use kill merely to avoid difficult research, tighten the definition. If they send fundamentally empty ideas through repeated revisions, tighten it in the other direction.

    Map planned claims to evidence section by section

    Once the angle passes, place a checkpoint between retrieval and writing. For every planned section, record the claim it needs to establish, the evidence intended to support it, and the gap that would remain if the writer used only that material.

    A practical evidence map contains:

    • The section heading and its purpose in the argument.
    • The exact factual or analytical claim the section must support.
    • The relevant evidence URL or document identifier.
    • A support score on a 1-10 scale, using a definition that stays consistent across runs.
    • The unsupported part of the planned claim.
    • A follow-up query, narrower claim, or deletion recommendation.

    Choose the passing threshold before evaluating the packet. When a section falls below it, the mapping agent should not hand the gap to the writer. It should produce the follow-up query itself, narrow the planned statement to match the available evidence, recommend removing the section, or escalate the gap to a person.

    This checkpoint is especially useful for SEO, AEO, and GEO content. A fluent answer can still be unusable if its strongest sentence outruns its citation. Mapping claims before drafting gives the writer permission to be specific where the evidence is strong and forces a deliberate decision where it is not. It also gives the fact-checker a clean chain from planned claim to evidence to published wording.

    Turn repeated edits into controlled instruction updates

    An editor groups recurring changes from blank drafts, approves one pattern, and adjusts an instruction module for the next content cycle.

    Do not update a shared prompt every time someone changes a sentence. Many edits are local: a legal qualification for a particular market, a preference from one stakeholder, or an exception created by an unusual format. Promoting them immediately makes the workflow unstable.

    A useful operating rule is to wait until the same edit pattern appears across three separate content assets. That is not a universal law or proof that the proposed fix is correct. It is a practical trigger for asking whether a reusable instruction has failed. The system should propose a change at that point, not apply one automatically.

    Capture each meaningful edit as a structured event:

    • Asset type and workflow version.
    • Original passage and approved revision.
    • Defect category, such as weak specificity, unsupported claim, indirect answer, voice mismatch, repetition, or poor section order.
    • The workflow stage most likely to own the defect.
    • The requirement that the original output failed.
    • Whether the edit is local to the asset, specific to a channel, or potentially global.
    • The reviewer who approved the final correction.

    Classification is more important than raw edit distance. Replacing an entire paragraph may reflect a minor tone preference, while changing a short factual qualifier may correct a serious accuracy problem. The system needs to know why the edit happened before it can recommend where to intervene.

    Route the proposed fix to the earliest stage that can prevent recurrence. A repeated unsupported claim belongs in evidence mapping or fact-checking. A repeated mismatch between topic and audience belongs in the brief filter. A buried direct answer belongs in the outline or structural rubric. Only a failure that genuinely originates in drafting belongs in the writer instructions.

    Make every instruction proposal reviewable. It should contain the observed pattern, the affected assets, the proposed wording, the expected change, the evaluation criterion, the scope of application, and the current instruction version. Replace abstract directives such as improve clarity with testable behavior. For example: define a technical term when it first appears, then state the implementation consequence in the same section. A reviewer can inspect that requirement in an output; improve clarity cannot be evaluated consistently.

    Evaluate the patch on representative briefs before promoting it. Check the target defect and the rest of the acceptance contract. An instruction that produces sharper openings but removes necessary qualifications is not an improvement. Preserve the earlier version so you can roll back the change if a wider set of runs reveals a regression.

    Scope memory by format. The correction that improves a landing page may make a technical explainer too abrupt. A rule for a LinkedIn post may be inappropriate for a video script. Maintain shared brand requirements where they are genuinely universal, then place format-specific instructions closer to the relevant writer and reviewer.

    Use rubric scores to diagnose the system, not flatter it

    A pass-or-fail gate tells you whether content can move forward. A rubric tells you which capability is holding it back. Score each criterion separately and require a concrete diagnosis whenever a score falls below its threshold. A total score alone is dangerous because strong voice and clean structure can conceal weak evidence.

    Rubric dimensionQuestion to evaluateLikely route when it fails
    Audience and intent fitDoes the content resolve the decision or task named in the brief?Brief filter
    Original point of viewDoes the thesis make a defensible contribution rather than restating the topic?Angle evaluation
    SpecificityDo important recommendations include the mechanism and an actionable consequence?Evidence mapping or writer
    Claim supportDoes the evidence establish the claim at the strength used in the draft?Retrieval checkpoint
    Citation fidelityDoes each cited item support the exact sentence attached to it?Fact-checker
    StructureDoes each section advance the argument or help the reader complete the task?Outline or editorial reviewer
    VoiceDoes the wording follow the applicable brand and format rules?Writer instructions
    Answer usabilityAre core answers direct, self-contained, and explicit about the entities and conditions involved?Outline or writer

    A diagnosis must describe the gap, not merely repeat the criterion. Specificity is low is not useful feedback. The recommendation names actions but omits the condition that determines which action applies is useful. It tells the writer what to repair and gives the reviewer something concrete to check on the next pass.

    You can also apply the same rubric to competing briefs, outlines, or openings. Compare candidates criterion by criterion, preserve any hard acceptance requirements, and select the option that best serves the task. Do not let a high average compensate for a fatal weakness such as an unsupported central claim.

    Track workflow health alongside content scores. Useful operating measures include first-pass acceptance, flags by defect category, revision rounds per asset, escalation reasons, evidence gaps caught before drafting, instruction patches proposed and approved, and patches later rolled back. These measures show whether the system is preventing defects or merely moving them between agents.

    Post-publication outcomes can trigger investigation, but they should not rewrite instructions by themselves. Search visibility, AI citations, engagement, and conversion depend on more than wording. Associate each asset with its intended outcome, review performance within a predefined measurement window, and compare the result with the editorial record. Then decide whether the signal points to content quality, distribution, technical implementation, audience fit, or a changed search environment.

    Implement the system in layers. Put the capped reviewer and fact-checker around the draft currently waiting for approval. Log every verdict and escalation. When those logs expose upstream failures, add the angle and evidence checkpoints. When recurring edits become visible across separate assets, enable instruction proposals with approval and rollback. Your workflow will then improve from evidence of its own failures without giving up editorial control.

    References
  • Google Ads AI Automation: A Practical Control Framework

    Google Ads AI Automation: A Practical Control Framework

    Your Google Ads account can hit its conversion target while the business quietly loses ground. Spam leads, duplicate customers, weak inquiries, irrelevant searches, and unsuitable placements can all look like success to an automated system if your setup rewards them.

    The answer isn’t to switch off every automated feature. It is to give Google a business outcome it can learn from, define where it may explore, and detect drift before wasted spend becomes a new baseline. Here is the control framework we would use.

    Define the outcome before you automate the campaign

    Google Ads automation solves the objective represented by your data. It cannot independently decide that a qualified opportunity matters more than a form submission, that an approved applicant matters more than a completed application, or that a rental booking matters more than research about rental insurance.

    That makes conversion configuration a control, not merely a reporting choice. Your primary conversion tells the system what kind of outcome to reproduce. If that event includes low-quality or duplicated outcomes, automation can become very efficient at finding more of them.

    Start by finishing one sentence in business language: This campaign should produce more of what? The answer should be specific enough that sales, finance, operations, and marketing would classify the outcome the same way.

    1. Name the business outcome. Use a booking, qualified opportunity, approved applicant, completed sale, cross-sell opportunity, or another result the business genuinely values. Do not begin with the easiest event Google can observe.
    2. Map the observable steps. List the ad click, page visit, form submission, qualification, opportunity, approval, purchase, and any other stages that connect the ad to the outcome.
    3. Choose the bidding signal intentionally. Keep diagnostic events available for analysis, but make an event primary only when you actually want bidding to seek more of it.
    4. Remove false success. Look for spam, test records, duplicate submissions, existing customers counted as new acquisition, and leads that fall outside the serviceable market.
    5. Return downstream outcomes. Where the valuable event occurs outside the website, connect advertising data with CRM or operational data and return stronger signals through offline conversion imports, enhanced conversions, or appropriate first-party data.

    More conversion volume is not automatically better training data. If every lead is sent back as equally valuable, Google has no reason to distinguish a sales-ready prospect from a record that will never progress. A smaller set of outcomes that matches the business objective can be more useful than a larger but mixed pool.

    Audience inputs require the same discipline. A net-new acquisition campaign should not learn that repeat customers are ideal new prospects. A cross-sell campaign, by contrast, may intentionally use existing customers and their stage in the customer journey. In one B2B application, customer audiences aligned to complementary solutions helped create new CRM opportunities and cross-sell pipeline. The useful principle is not simply to upload more audience data; it is to supply the audience that fits the stated outcome.

    Put guardrails around reach, messaging, and destinations

    Abstract campaign routes pass through adjustable gates and exclusion barriers before reaching audience groups and destination portals.

    Once the outcome is sound, automation still needs boundaries. Google can recognize statistical relationships without understanding every commercial distinction behind them. Closely related searches may imply different intent, a relevant-looking page may be a poor conversion destination, and inexpensive inventory may produce leads the business cannot use.

    AI Max makes this especially important. The website is only one targeting input alongside existing keywords, ad copy, budget, and real-time intent signals. It can also use broad-match and keywordless technology to reach searches beyond narrower keyword matching. That creates discovery opportunities, but it also enlarges the area you must govern.

    Separate definite mismatches from ambiguous search intent

    Do not manage expanded search traffic as one undifferentiated pile. Use two decision lanes:

    • Definite mismatch: The query clearly represents a product, location, audience, or intent the campaign cannot serve. Exclude it under a documented rule.
    • Ambiguous intent: The wording could represent a valuable customer or an adjacent research task. Send it to human review with its volume, cost, conversions, and downstream quality.

    The distinction matters. A car-rental campaign, for example, repeatedly matched searches about car-rental insurance. The language was adjacent to the advertiser’s service, but the searcher was researching insurance rather than trying to book a vehicle. Business rules applied to recent search terms can automatically handle clear mismatches while surfacing uncertain terms for a person to decide.

    A practical search-term script or rules workflow should therefore do three jobs: exclude queries that unmistakably violate a business rule, queue borderline cases, and flag recurring high-volume modifiers that fail to convert so you can investigate them early. No conversions alone is not proof that a term is irrelevant, especially when volume is limited. Require an intent-based reason before an automated exclusion blocks future traffic.

    Control what AI says and where the click lands

    AI Max text customization can build headlines and descriptions from website copy, existing assets, and query context. Review the output as advertising copy, not as a harmless platform suggestion. Check product claims, offer terms, geography, tone, brand representation, and whether the message accurately describes the landing page.

    Text Guidelines, also described as guardrails, let you provide up to 25 search-term exclusions and 40 messaging restrictions for automatically created copy. Use those limited fields for restrictions that are precise and consequential. A vague instruction such as maintain our tone is hard to evaluate; a rule that forbids an unsupported product claim is concrete enough to audit.

    After enabling AI Max or upgrading a campaign, go to Ads > Assets > Performance and include the Added by column. That view identifies assets added by Google AI so you can inspect them separately from advertiser-supplied assets. Review more frequently immediately after a material change, then make the check part of recurring account governance.

    Final URL expansion needs its own review. Unlike a Dynamic Search Ads target that confines traffic to a defined part of the site, AI Max can route a searcher to another relevant page across the domain, subject to URL exclusions. A page can be topically relevant yet commercially wrong because it serves another region, describes an unavailable offering, targets existing customers, or lacks the path needed to complete the campaign’s intended action.

    1. List the page groups that are valid destinations for the campaign’s objective.
    2. Exclude sections that cannot serve that objective, rather than waiting for each individual URL to spend.
    3. Inspect the actual landing pages receiving traffic, not only the final URL entered in the ad setup.
    4. Confirm that the query, generated message, landing page, and conversion action describe one coherent journey.
    5. Check regional routing explicitly when campaigns or websites have location-specific pages.

    AI Max also provides brand inclusion and exclusion lists at the ad-group level and geographic intent controls. Treat them as explicit statements of campaign scope. They should reflect whether the campaign is meant to capture branded demand, exclude another brand relationship, or serve people expressing intent for a particular market.

    Evaluate placement patterns in aggregate

    Placement waste does not always arrive as one obvious offender. A large collection of individually inexpensive placements can create a costly pattern that remains hidden when each URL is reviewed alone.

    In one Demand Gen campaign, thousands of low-cost placements collectively generated expensive, weak quote requests. URL-based business rules excluded clearly unsuitable placements and escalated borderline ones. Within a month, the close rate for quote leads rose from below 1% to about 8%. That is one account outcome, not a universal benchmark, but it shows why downstream quality and aggregate placement patterns matter more than cheap inventory by itself.

    Build placement rules around suitability and business outcome. Automatically exclude only what clearly falls outside those rules. Review the uncertain group, preserve a change log, and keep a way to reverse exclusions if later evidence changes the decision.

    Protect the feedback loop from silent drift

    A circular automation feedback loop filters distorted signal fragments away from a central learning system while clean signals continue through.

    A good launch configuration can still decay. Tracking may stop firing, a conversion setting may change, CRM feedback may disappear, a campaign may point to the wrong regional page, or the customer mix may shift. Because these failures often accumulate gradually, the bidding system can keep learning while the meaning of its training data deteriorates.

    Your monitoring should cover the input pipeline as well as campaign performance. Automated quality assurance can validate tracking configurations, verify regional URLs, and flag significant daily, weekly, or monthly performance changes. Each check answers a different question:

    • Tracking integrity: Is the event still recorded and classified as intended?
    • Data delivery: Are offline and CRM outcomes still reaching the advertising system?
    • Destination integrity: Do campaigns still send each market to the correct page?
    • Traffic composition: Have search terms, placements, audiences, or landing pages shifted?
    • Business quality: Are the conversions becoming qualified opportunities, approvals, sales, bookings, or other intended outcomes?
    • Performance movement: Has a daily, weekly, or monthly measure changed enough to require investigation?

    An anomaly is an alert, not an explanation. When a metric moves sharply, investigate in a fixed order so you do not train the system around bad data:

    1. Verify that tracking, conversion configuration, and downstream data transfers are intact.
    2. Check whether the mix of queries, placements, audiences, generated assets, or landing pages changed.
    3. Compare platform conversions with the business outcomes recorded elsewhere.
    4. Correct broken inputs or scope violations before judging the bidding strategy.
    5. Evaluate budget or bidding changes only after you trust the feedback loop again.

    This sequence prevents a common mistake: reacting to a measurement failure as if it were a media-performance problem. Changing bids while CRM imports are missing does not repair the signal. It merely asks automation to make a new decision from incomplete evidence.

    Long sales cycles make the feedback gap more visible. If Google can observe the lead today but the business values a qualified pipeline event much later, document the handoff between the ad platform and the CRM. Assign ownership for the import, its validation, and its failure alerts. A sophisticated bidding setup cannot compensate for a feedback process that nobody owns.

    Move from DSA to AI Max on your own schedule

    If you use standalone Dynamic Search Ads campaigns, the transition to AI Max is a change in operating model, not a renamed campaign. Standalone DSA begins with the website and uses defined dynamic ad targets. AI Max sits within the existing Search campaign structure, combines more targeting signals, creates more ad text, and can expand landing-page selection across the domain.

    The current transition window gives you time to manage that change. Advertisers can continue creating DSA campaigns through January 2027, with automatic migrations beginning in February 2027. Waiting for automatic migration gives you less control over when new targeting, creative, and routing behavior enters the account.

    Before selecting the manual Upgrade campaign option in the Dynamic Search Ads settings, preserve the information DSA already gave you:

    1. Inventory the current structure. Record dynamic ad targets, negative keywords, URL exclusions, conversion configuration, budgets, and the pages allowed to receive traffic.
    2. Extract useful search-term history. Identify the themes that generated meaningful outcomes and the terms that revealed adjacent or unsuitable intent. DSA search-term performance can also show where explicit keyword coverage deserves attention.
    3. Write the new boundaries first. Prepare URL exclusions, brand controls, geographic intent settings, negative keywords, and text restrictions before exposing more traffic to expanded matching.
    4. Capture a business-quality baseline. Keep the downstream rates and outcomes you will need to judge the change, not just clicks and platform conversions.
    5. Upgrade deliberately. Start where you can observe the new behavior closely. Avoid combining the migration with unrelated measurement changes when possible, because simultaneous changes make the result harder to diagnose.
    6. Inspect from the first post-upgrade traffic. Review search terms, AI-created assets, actual landing pages, and downstream conversion quality as separate control surfaces.

    The first question after migration should not be whether AI Max produced more traffic. Ask whether it found more of the commercial intent you wanted, represented the offer correctly, chose viable destinations, and produced outcomes the business accepts. Volume without those checks can conceal a widening gap between platform performance and business performance.

    Key takeaways

    • Make the primary conversion represent the result you want automation to reproduce, not merely the easiest event to count.
    • Return qualified downstream outcomes through connected CRM, analytics, and first-party data processes where the valuable event happens after the lead.
    • Automatically block only clear search or placement mismatches; send ambiguous cases to human review.
    • Review AI-created assets through Ads > Assets > Performance with the Added by column visible.
    • Control Final URL expansion with page-group rules, exclusions, and checks of the actual destinations receiving traffic.
    • Verify measurement and data delivery before responding to a performance anomaly with bidding or budget changes.
    • Plan the DSA-to-AI Max transition before automatic migrations begin in February 2027.

    This week, choose one automated campaign and trace a real business outcome backward to its query, ad, landing page, conversion action, and CRM status. Wherever that chain becomes invisible or changes meaning, add a measurement check, a boundary, or a named owner. That is where control will produce more value than another round of bid adjustments.

    References

  • Why Marketing Automation Still Needs Human Oversight

    Why Marketing Automation Still Needs Human Oversight

    Marketing automation can react to campaign signals faster than a person, while marketing mix modeling can help explain performance across channels and longer time horizons. Neither capability removes the need for human oversight; each moves that oversight to decisions about goals, data quality, constraints, validation, and interpretation.

    The useful question is therefore not whether people or machines should control marketing. It is where human judgment has the greatest leverage in a system that combines rapid execution with slower, broader measurement.

    Automation and measurement address different decision gaps

    Campaign automation primarily shortens the gap between an observable signal and an action. The account described in the groas report used an automated system to adjust bids, budgets, keywords, match types, campaign activity, ad copy, and landing pages in response to Google Ads data. Its proposed advantage was continuous attention: a weak search term or drifting target could be addressed sooner than under a periodic manual review cycle.

    Marketing mix modeling (MMM) addresses a different problem. Rather than managing an individual auction, it estimates how channels and outside factors relate to business outcomes over time. the MMM report said a credible implementation may require two to three years of weekly data, consistent channel-level spending, offline activity, and external variables such as pricing, competitor activity, product launches, and macroeconomic conditions.

    These approaches operate at different speeds and levels of aggregation, but their dependencies converge. Both need a well-defined business outcome, trustworthy inputs, knowledge of exceptional events, and a person capable of challenging an apparently successful output. Faster optimization cannot repair a poorly chosen conversion goal, just as sophisticated modeling cannot compensate for missing or inconsistent historical data.

    DimensionCampaign automationMarketing mix modeling
    Primary purposeAct on account-level performance signalsEstimate contribution across channels and business conditions
    Reported data emphasisSearch terms, bids, budgets, devices, audiences, conversion tracking, and auction behaviorHistorical spend, outcomes, offline media, seasonality, pricing, launches, and external factors
    Main human responsibilitySet objectives, structure the account, establish guardrails, and review consequential changesSpecify the model, resolve data problems, test assumptions, calibrate estimates, and interpret uncertainty
    Failure riskRapidly optimizing toward the wrong signalProducing a plausible but misleading explanation of performance

    Human judgment matters before, during, and after automation

    Marketing specialists set campaign goals, monitor automated activity, and review outcomes across a continuous workspace.

    Before: define what the system should optimize

    The first oversight point is objective design. In the groas account, a human account manager reportedly audited campaign structure, keywords, bidding logic, budget allocation, conversion tracking, quality scores, search terms, and auction insights before automated optimization began. The report also acknowledged that people must communicate changes in products, pricing, and the relative importance of conversions. Those choices determine whether the system is improving a meaningful business result or merely making a platform metric look better.

    MMM has an equivalent setup problem. A modeler must decide which outcome to explain, how channels should be separated, which external variables belong in the model, and how unusual periods should be represented. The MMM source described the preliminary work as data archaeology because relevant records can be divided among finance, brand teams, agencies, and old spreadsheets. Human oversight begins with reconciling those records, not with selecting a modeling library.

    During: constrain action and investigate anomalies

    The reported groas rollout illustrates one way to limit early execution risk. It began with two weeks of observation, moved into calibration during weeks three and four, looked for traction in weeks five and six, and approached scaling in weeks seven and eight. This staged process is significant because automation should earn a larger operating range through observable behavior rather than receive unrestricted control on its first day.

    Oversight during MMM is more diagnostic than operational. According to the modeling source, practitioners still have to judge solutions along a Pareto frontier, assess whether an optimizer has converged, configure adstock behavior, and investigate implausible channel contributions. They may need to determine whether a suspicious result comes from an incorrect prior, a data error, or a variable that should be excluded. Code generation can reduce implementation effort without resolving any of those substantive choices.

    After: interpret evidence without overstating it

    Automated outputs still require a disciplined reading. The groas source reported a before-and-after comparison for a U.S. online mobile recharge account in which spend increased 18% to $164,000, ROAS rose from 1.02x to 1.32x, average CPC fell from $2.34 to $2, daily conversions increased from 571 to 739, conversion value grew 44%, and cost per conversion declined 14%. It also reported that active search campaigns were consolidated from 17 to 10.

    Those figures describe the source’s account snapshot, not an independently verified or universally transferable effect. A before-and-after account comparison can show that performance changed after an intervention, but by itself it does not isolate every possible cause. Seasonality, competitive conditions, demand, pricing, and concurrent business changes still need consideration. Human oversight includes distinguishing a promising operational result from a causal conclusion.

    Model sophistication does not neutralize weak inputs

    The MMM source compared three open-source options: Meta’s Robyn, Google’s Meridian, and PyMC-Marketing. It characterized Robyn as the most approachable of the three, Meridian as a more rigorous Bayesian option with uncertainty quantification and geo-level priors, and PyMC-Marketing as the most flexible but most demanding in statistical fluency. The availability of these libraries lowers the software and access barrier, but it does not make their results automatically reliable.

    This distinction also applies to campaign automation. A system may be technically capable of adjusting every available control while remaining unable to know that a tracking event is misconfigured, a temporary promotion has changed customer behavior, or a low-value conversion should no longer guide bidding. Greater execution coverage magnifies the value of clean signals, but it can also magnify the consequences of a bad specification.

    The common governance principle is proportional scrutiny. The more quickly a system can move money or the more strongly a model can influence allocation, the more clearly its inputs, permissions, assumptions, and escalation conditions should be documented. Transparency should cover not only what the technology changed or estimated, but also which human decisions framed the result.

    A supervised operating model connects action to learning

    A cross-functional team supervises a circular system of campaign actions, measurement signals, constraints, and revised decisions.

    A practical oversight structure separates responsibilities without separating the evidence. A strategy owner defines the business outcome and acceptable tradeoffs. A data owner protects conversion definitions, reconciles source systems, and records structural changes. A campaign operator monitors automated actions and intervenes when changes exceed agreed boundaries. A measurement specialist tests assumptions, communicates uncertainty, and uses experiments where possible to calibrate model estimates.

    These responsibilities should form a feedback loop. Campaign automation produces actions and fresh performance data. Broader measurement examines how channel activity relates to business outcomes. Incrementality experiments can help test selected assumptions, as the MMM source recommended. People then decide whether objectives, constraints, budgets, or measurement specifications need to change before the next cycle.

    Escalation should focus on changes that machines cannot interpret from performance data alone: broken or redefined tracking, a pricing shift, a product launch, an exceptional market disruption, an implausible channel estimate, or a budget move that conflicts with a strategic commitment. This allows routine optimization to proceed while reserving human attention for context-heavy and consequential decisions.

    Key takeaways

    • Campaign automation reduces response time, while MMM addresses cross-channel explanation; neither replaces the other.
    • Human oversight has three control points: defining objectives and inputs, governing execution and anomalies, and interpreting results.
    • Reported performance improvements should be evaluated in light of study design, business changes, and alternative explanations.
    • Open-source models and AI-assisted coding reduce technical barriers, but data reconciliation, assumption testing, and business context remain expert tasks.
    • The strongest operating model links automated action, measurement, experimentation, and human decisions in a documented feedback loop.

    As marketing systems gain more authority, oversight will need to become more explicit rather than more occasional. Organizations that define decision rights, preserve context, and test what their systems claim to learn will be better positioned to benefit from automation without surrendering accountability.

    References

  • Grok 4.5 Support in Profound: What It Means for Teams

    Grok 4.5 Support in Profound: What It Means for Teams

    Profound has added support for Grok 4.5, according to an announcement published on its blog. The integration gives users another model option for workflows involving research, strategy, automation, and other forms of knowledge work.

    The practical value will depend on more than model availability. Teams still need to determine where Grok 4.5 improves their work, how reliably it handles representative tasks, and whether it fits their operational requirements.

    What Profound announced

    Profound’s post says Grok 4.5 support is now available and describes the model as a new flagship designed for agentic workflows and knowledge work. It positions the integration as a way to use the model within a broader AI workflow rather than solely through isolated prompts.

    The announcement names research, strategy, automation, and everyday knowledge work as areas to explore. These are proposed applications, however, rather than reported results from comparative testing. The source does not provide benchmarks, customer outcomes, configuration details, or comparisons with other models.

    Key takeaways

    • Profound says Grok 4.5 support is available within its broader AI workflow environment.
    • The stated positioning emphasizes agentic workflows and knowledge-intensive tasks.
    • Research, strategy, automation, and routine knowledge work are the principal use cases identified in the announcement.
    • The announcement establishes integration availability, but it does not independently demonstrate performance, reliability, or superiority over alternative models.

    Where the integration could matter

    In general, an agentic workflow asks a model to help move a multi-step task toward completion. That can involve interpreting a goal, working through intermediate decisions, producing outputs, and responding to new context. Model support inside a workflow platform can therefore be more consequential than access to a standalone chat interface, provided the surrounding system can supply the context and controls the task requires.

    For research work, the relevant question is whether Grok 4.5 can consistently organize evidence, expose uncertainty, and produce outputs that remain easy to verify. For strategy work, teams should examine whether its reasoning stays connected to the supplied constraints rather than merely producing polished recommendations. Automation use cases add another requirement: predictable behavior when a task is repeated, interrupted, or handed between people and systems.

    These criteria are evaluation targets, not capabilities established by Profound’s announcement. The integration creates an opportunity to test them in context; it does not remove the need for that testing.

    How teams can evaluate Grok 4.5 in Profound

    A team evaluates an artificial intelligence system at parallel workstations using abstract result panels in a modern testing studio.
    1. Select representative tasks. Use real examples from research, planning, analysis, or automation rather than a small collection of showcase prompts.
    2. Define a baseline. Compare Grok 4.5 with the model or process already used for the same work, keeping instructions and source material as consistent as possible.
    3. Score the outputs. Assess factual accuracy, reasoning quality, adherence to constraints, completeness, and the amount of human correction required.
    4. Test repeatability. Run comparable tasks more than once and examine whether the workflow produces dependable results when inputs become ambiguous or incomplete.
    5. Review operational fit. Consider oversight, traceability, data-handling requirements, latency, and cost using the terms and controls actually available to the organization.

    A useful evaluation should separate model quality from workflow quality. A weak result may come from the model, the instructions, missing context, or the way the integration passes information between steps. Recording those failure modes makes comparisons more informative than selecting a model from a few preferred answers.

    What remains unconfirmed

    The supplied announcement does not specify access requirements, pricing, context limits, supported tools, routing behavior, governance controls, or technical implementation. It also does not report independent tests showing how Grok 4.5 performs inside Profound against other available approaches.

    Profound’s support is therefore best understood as expanded model choice and an invitation to evaluate new workflows. Documentation and task-level testing will determine whether that choice produces measurable gains for a particular team.

    References