Tag: AI Assistants

  • Yelp AI-Assisted Bookings: A Local Optimization Playbook

    Yelp AI-Assisted Bookings: A Local Optimization Playbook

    If your Yelp profile gets seen but still produces too few bookings, the problem may no longer be simple visibility. A customer can now ask a detailed question, compare the suggested businesses, and act without following the familiar path from search result to website.

    Your job is to make that compressed journey work. Yelp needs clear business facts, customers need credible evidence of fit, and the booking or ordering connection needs to survive the handoff. A weakness in any one of those layers can turn a recommendation into an abandoned transaction.

    Optimize the decision, not just the listing

    Traditional local SEO often treats discovery and conversion as separate stages. You rank or appear in a marketplace, earn a click, and then persuade the visitor on your own site. Yelp Assistant narrows that distance because it can answer complex questions, recommend businesses, explain why a business fits, refine the results conversationally, and continue into supported booking, ordering, or quote flows.

    That changes the optimization target. A conversational local request usually contains several constraints at once: the service, location, occasion, timing, preferences, and desired next step. A profile can be relevant to the broad category while failing to resolve one of those constraints. The customer may never reach your website to investigate further.

    Audit your Yelp presence against four questions:

    • What does the business actually provide? Categories, service names, menu items, and descriptive copy should agree about your core offer.
    • Who or what situation is it suitable for? Include meaningful distinctions customers use when choosing, but only where they are accurate and supported by your operation.
    • Why should the customer believe the fit? Reviews and photos should give the customer evidence, not merely repeat promotional claims.
    • What can the customer do next? The appropriate reservation, appointment, quote, or ordering action should be visible, current, and connected to a working destination.

    Build the audit from real customer language. Collect the questions that appear in calls, messages, quote requests, appointment notes, and reviews. Group them by intent, then check whether a person could answer each one from the information visible in Yelp. If the answer depends on an assumption or an old photo, you have found a content gap.

    Correct the underlying field wherever possible. Put hours in the hours field, services in the relevant service area, menu information in the menu, and the primary transaction in the appropriate action. Descriptive copy can clarify the offer, but it should not become a container for disconnected phrases. Treat this as an answerability audit, not as a claim that repeating keywords will influence Yelp’s selection logic.

    Your website still matters, including its LocalBusiness structured data. Keep the name, address, telephone number, URL, hours, and applicable business subtype aligned with the facts you publish elsewhere. Use a sameAs link when it accurately identifies your Yelp profile. That consistency helps search systems understand the same entity, but JSON-LD on your website cannot repair stale Yelp information or reconnect a broken booking calendar.

    Close every gap between recommendation and transaction

    A recommendation is not the conversion. The final action may depend on Yelp, your profile configuration, a scheduling or delivery partner, inventory or calendar data, and the confirmation experience. Every connection can look present while still sending the customer to the wrong service, location, or availability view.

    Yelp has expanded integrations involving Vagaro, Zocdoc, and Calendly across areas such as beauty, healthcare, and home services, alongside delivery support involving DoorDash. The practical implication is not that every business automatically receives every transaction type. It is that a connected marketplace profile and the external system behind it must be managed as one customer journey.

    Test the journey in the environment where customers encounter it:

    1. Open the Yelp profile on a supported mobile experience and identify the primary action presented to a customer.
    2. Confirm that the action matches the intent you want to win. A restaurant reservation, food order, healthcare appointment, service appointment, and home-service quote are not interchangeable conversions.
    3. Follow the action into the connected system. Verify the business name, location, selected service, availability, and contact information at each step.
    4. Continue to the final confirmation screen, but do not consume a real appointment or reservation unless your operation has a safe test procedure.
    5. Check the resulting confirmation or lead record. It should give both the customer and your staff enough information to fulfil the request without another round of clarification.

    Test more than the happy path. Try a service that has limited availability, a different location if you operate more than one, and a request that should become a quote rather than an instant booking. The purpose is to find mismatches between what the profile promises and what the connected system can actually accept.

    Assign ownership for each layer. The person updating the Yelp profile may not control the scheduling platform, menu, delivery availability, or service calendar. Record who owns each one and where changes originate. Otherwise, a corrected profile can be overwritten by old partner data, or the profile can continue advertising an option that operations no longer fulfils.

    The initial feature availability was described as mobile-first on iOS and Android, with broader category and desktop expansion planned. Rollout scope can differ by experience, so verify what customers can actually see instead of assuming that an announcement describes every account, category, or device.

    Give the assistant evidence it can explain
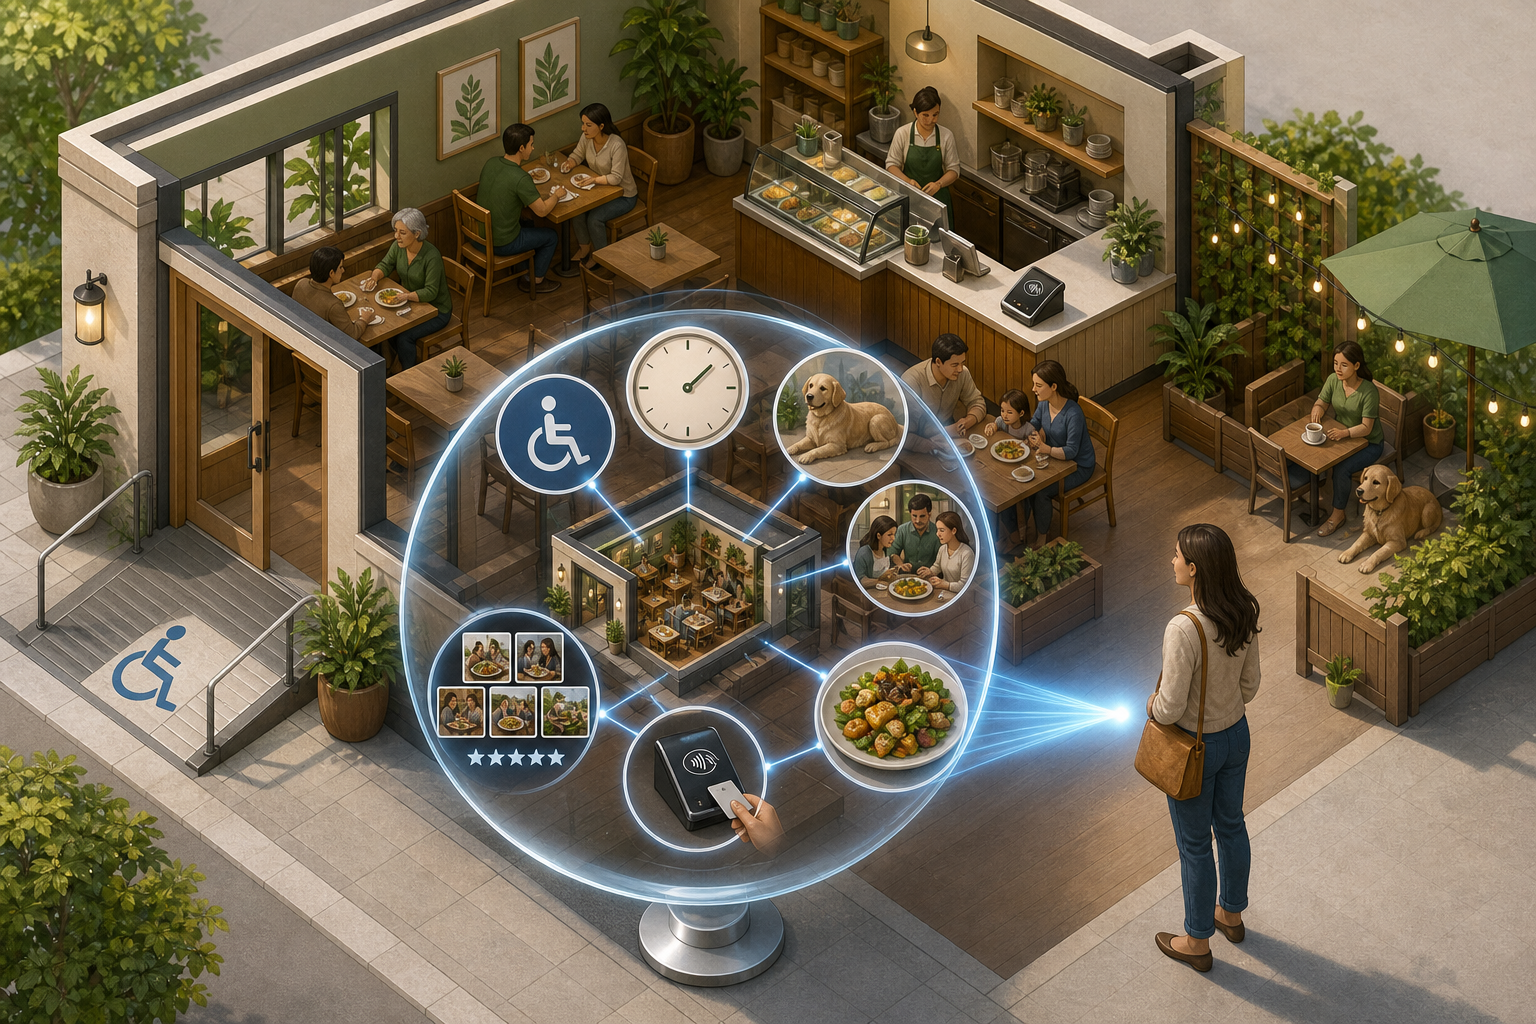
    An abstract AI lens gathers visual details about a restaurant's amenities, service, atmosphere, and customer evidence to guide a recommendation.

    Yelp Assistant draws on Yelp’s reviews and photos to tailor recommendations and explain why a business may be a good match. That makes customer-generated evidence part of the conversion surface. Your description can state that you provide a service; reviews and photos can show what receiving it is like.

    Do not translate that into a campaign for generic praise. Broad comments such as great service reveal little about the specific situations in which the business succeeds. Honest reviews are more useful when customers naturally mention the service received, the type of need, the location, and the experience. Any request for feedback should remain neutral and comply with the platform’s current policies.

    Use reviews as an operating dataset, not as copy you control:

    • Identify recurring service names and customer questions. Check whether your profile uses the same clear, accurate terminology.
    • Notice repeated misunderstandings. If customers arrive expecting an option you do not provide, correct the promise in your profile or connected flow.
    • Look for evidence gaps. A service may be listed but rarely described or photographed, leaving a customer with little basis for choosing it.
    • Respond to factual confusion calmly. Clarify the business detail that matters, then fix the underlying listing or operational issue when you control it.

    Photos need a similar job-based audit. Cover the decision points a new customer cannot infer: what the exterior looks like on arrival, what the relevant space or service looks like, what is actually delivered, and how distinct options differ. Accuracy matters more than decorative volume. An attractive image that no longer represents the current offer can create a stronger expectation mismatch than having no image at all.

    Restaurants have an additional surface to watch. Yelp’s revised Menu Vision can place dish information, reviews, and photos into visual overlays while a customer browses a menu. Menu item names, current availability, and corresponding images therefore need to describe the same dish. Remove or update obsolete material wherever your listing or connected system gives you control; do not let a retired item become the evidence for a current order.

    The same principle applies outside restaurants. A salon service name, healthcare appointment type, contractor quote category, and the evidence surrounding each one should remain consistent from recommendation through confirmation. The assistant can shorten the journey, but it cannot reconcile a profile, photograph, review pattern, and booking system that tell different stories.

    Measure the compressed funnel with transaction outcomes

    If a customer can complete more of the journey inside Yelp or a connected partner flow, website traffic alone becomes an incomplete scorecard. Flat website sessions do not prove that local visibility is stagnant, and more profile activity does not prove that qualified business increased.

    Choose the completed outcome that matches the action:

    • For restaurants, distinguish completed reservations or orders from action taps.
    • For appointment businesses, track booked appointments separately from completed appointments and cancellations.
    • For home services, separate raw quote requests from requests that fit the service area and become qualified opportunities.
    • For delivery, distinguish an ordering action from a completed order that the business successfully fulfils.

    Use the reporting fields available in Yelp and the connected platform, and keep definitions stable. If a partner exposes an origin label or channel field, preserve it through your export or customer-management workflow. If it does not, do not manufacture precise attribution from incomplete data. Record the limitation and compare only metrics that are defined consistently.

    Read funnel patterns as diagnostic clues, not proof of a single cause. If profile visibility rises while actions stay flat, start by checking whether the listing resolves fit and presents a clear next step. If actions rise while completed transactions do not, inspect the partner handoff, availability, eligibility rules, and confirmation flow. If transactions rise but cancellations, no-shows, or poor-fit requests also rise, compare the promise in Yelp with what the customer can actually book.

    Keep a change log alongside those measures. Record which profile fact, image set, menu item, service name, or transaction connection changed and when. Without that record, several simultaneous edits can make an improvement impossible to interpret and a regression hard to reverse.

    Key takeaways

    • Optimize for the customer’s complete decision, not for a broad category phrase in isolation.
    • Keep business facts, customer evidence, and the connected transaction system consistent.
    • Test booking, ordering, appointment, and quote paths from Yelp through confirmation.
    • Use reviews and photos to find unanswered questions and expectation mismatches; do not treat them as keyword containers.
    • Measure completed business outcomes because an in-platform transaction may never appear as a website visit.
    • Use website schema to reinforce accurate entity information, not as a substitute for maintaining the Yelp profile itself.

    Run the audit around one valuable customer intent
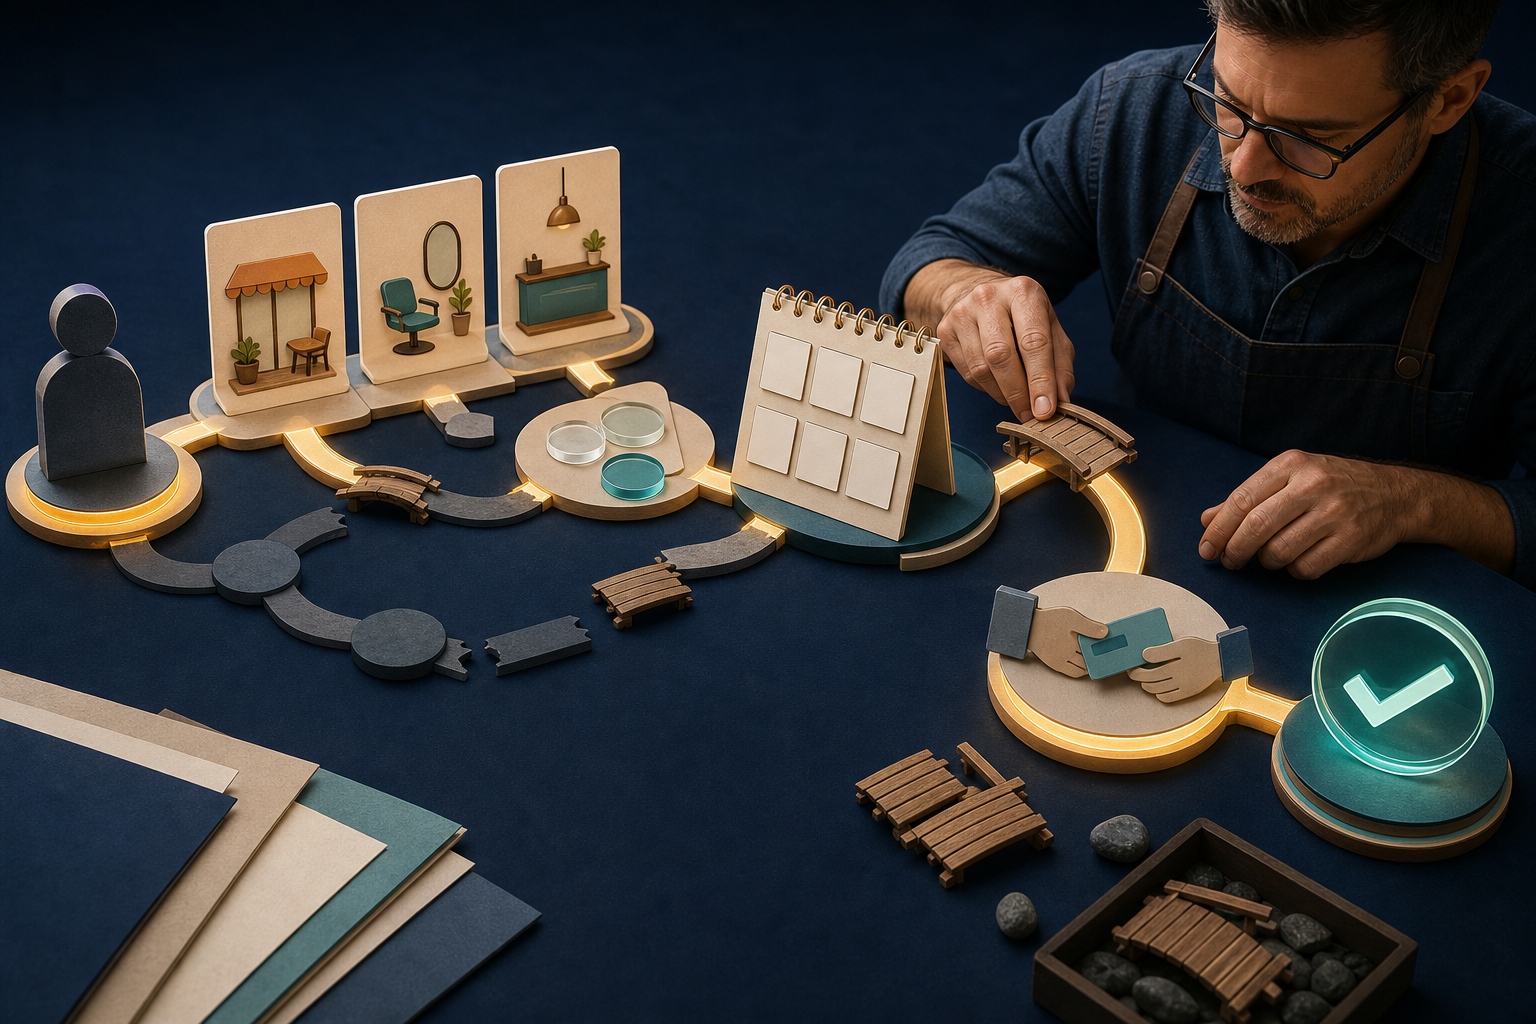
    A business owner examines a visual pathway from customer intent through recommendation, comparison, scheduling, payment, and booking confirmation.

    A full profile overhaul can hide the problem you need to solve. Start with one commercially meaningful intent: the reservation type, appointment, service request, or order you most need Yelp to support.

    1. Write the exact questions and constraints a suitable customer brings to that intent.
    2. Mark where each answer lives: profile field, service or menu information, review evidence, photo, booking system, or confirmation.
    3. Correct contradictions and remove unsupported promises before adding more copy.
    4. Test the transaction path on the customer-facing experience available to your category.
    5. Record the current funnel outcomes, the change made, and the operational owner responsible for keeping it accurate.
    6. Recheck the path whenever hours, services, locations, menus, calendars, or integration settings change.

    The businesses best prepared for AI-assisted local bookings will not necessarily be those with the longest descriptions. They will be the ones whose facts answer the question, whose evidence supports the choice, and whose transaction path does exactly what the recommendation promised. Pick the path tied most closely to revenue or qualified demand, and make that one dependable first.

    References


  • AI Search Foundations for an Assistant-Led Browser

    AI Search Foundations for an Assistant-Led Browser

    You can no longer judge a page only by whether it earns a traditional search listing. The same page may need to attract that listing, supply a direct answer, support a broader synthesis, and give a browser assistant enough clarity to help someone finish a task.

    If you are deciding what to fix first, do not start with AI-only copy tactics. Map the user’s task to the search experience likely to handle it, then make the underlying facts crawlable, consistent, extractable, and usable.

    The browser now routes tasks, not just queries

    The familiar model of search assumes a short sequence: someone enters a query, chooses a result, and visits a page. An assistant-led browser can keep that route, replace part of it with an answer, or continue beyond the page into research and task completion.

    Comet on iOS makes the split unusually clear. It uses Google Search by default for fast, local, and high-intent searches while providing an integrated Perplexity assistant for more involved knowledge work. This is not proof that every browser will make the same product choices. It is a useful operating model for content teams: traditional search and AI answers can serve different moments in the same journey.

    Classify each important page by the outcome its visitor needs:

    • Reach a destination: The user wants a site, location, product page, service page, or other known endpoint. Traditional search visibility and accurate navigational information remain central.
    • Resolve a focused question: The user needs a concise fact, definition, requirement, or procedure. Build a direct-answer module for AEO.
    • Understand a complicated decision: The user needs relationships, conditions, alternatives, or consequences explained together. Build enough connected material for GEO.
    • Complete an action: The user needs to submit, book, contact, select, or prepare something. The page and its interface must remain understandable to both the person and an assisting system.

    Do not assign a page to a category based only on keyword length. A short query can conceal a complicated decision, while a long query can still point to a specific destination. Write down the intended outcome, the facts required to reach it, and the step that should follow. Those three notes will tell you more than a generic label such as informational or transactional.

    Key takeaways

    • Plan for a hybrid search environment. Traditional results, direct answers, synthesized responses, and assistant-led actions can all matter within one journey.
    • Technical SEO, stable entity information, and verifiable facts are shared infrastructure. They are not optional work that begins only after an AI strategy is complete.
    • AEO and GEO solve different retrieval problems: AEO makes a focused answer easy to extract, while GEO makes relationships and context easy to synthesize.
    • Browser readiness extends beyond prose. Navigation, instructions, forms, labels, and completion states must be unambiguous.
    • Fix inaccessible pages, conflicting facts, and unclear task paths before expanding content. More copy cannot repair an unreliable foundation.

    Build the fact layer before optimizing the answer

    Organized layers of connected data tiles and document shapes form a foundation beneath a clear crystalline answer object.

    AI search did not appear without a technical lineage. Many mechanisms associated with modern search can be traced to patent blueprints filed between 2007 and 2016, including work concerned with entities and verification. The practical lesson is not that you need to read every patent. It is that durable search work still depends on machine-accessible information, recognizable entities, consistent relationships, and evidence.

    Create a single operational fact set

    Before rewriting pages, establish the facts every surface should agree on. For a business, product, service, or named expert, that set may include the canonical name, description, role, location, availability conditions, defining attributes, and relationships to other entities. Include only facts you can maintain.

    Then compare that set with the visible page, title and headings, internal links, structured data, profile pages, and any local or commercial landing pages you control. A disagreement is more important than a missing adjective. If one template calls an offering a product, another calls it a service, and the schema describes something else, a machine has to reconcile a conflict you created.

    Check the four controls every page depends on

    • Discovery: Confirm that the page can be reached through ordinary links and that its important content is available to the systems you expect to retrieve it. An orphaned or inaccessible answer is not an AI optimization opportunity.
    • Identity: Name the main entity consistently. Use clear relationships between the organization, people, products, services, locations, and topics represented on the page.
    • Information structure: Give each section a descriptive heading, place the answer near the question it resolves, and keep qualifications beside the claim they modify.
    • Evidence: Connect important claims to specific, trustworthy support. A link should help verify the claim beside it, not merely point to a generic homepage.

    Apply the same controls whether the site uses a traditional CMS or a headless architecture. A headless frontend can still hide essential content from retrieval, and a conventional CMS can still generate contradictory templates. Architecture changes where you inspect the problem; it does not remove the problem.

    JSON-LD belongs in this fact layer. Use it to express the same entities and relationships that a visitor can verify on the page. Do not use structured data as a second, invisible version of the business. Schema cannot make conflicting visible content trustworthy, and it should not introduce claims the page itself does not support.

    Give AEO and GEO different jobs on the same page

    Two illuminated paths lead from the same structured page, one to a single concise answer and the other to a multifaceted synthesis.

    AEO and GEO are often bundled together as AI optimization, but they require different content structures. AEO is built around direct answers, while GEO depends on synthesis and the relationships between concepts. Treating them as synonyms produces pages that are broad without being useful and concise without being complete.

    Build the AEO module around a bounded question

    An answer-engine module should let a reader isolate a question and still understand the response. Use this pattern:

    <!– wp:list {
  • How to Use AI-Powered Advertising Without Losing Control

    How to Use AI-Powered Advertising Without Losing Control

    Your ad platform can now reach beyond the audience you selected, produce analysis inside the campaign interface, and decide which entertainment title is most likely to interest a viewer. Those capabilities may all carry the AI label, but they do not create the same risk or require the same supervision.

    Your job is not to recover every manual lever. It is to decide what the system may optimize, which boundaries it must respect, and what evidence it must produce before you give it more budget. That requires a control system built for automation rather than a longer list of settings.

    The control surface has moved from audience settings to campaign inputs

    Manual advertising made control easy to see. You selected an audience, chose a similarity range, and expected delivery to remain within it. AI-led delivery weakens that visual connection. A setting can influence the model without defining the final audience.

    Google’s announced March 2026 change to Demand Gen Lookalike segments illustrates the shift. Narrow, balanced, and broad similarity tiers become optimization signals instead of rigid targeting limits. Google can reach beyond the selected segment when its system predicts that other users are likely to convert.

    That distinction changes how you should read the campaign setup. A Lookalike tier still communicates useful direction, but it no longer answers the eligibility question by itself. Optimized Targeting remains a separate feature, and layering it with Lookalike signals can give the system additional room to expand.

    Before you launch or diagnose an AI-powered campaign, classify every important input as one of four things:

    • Objective: the result the platform is being asked to maximize, such as a purchase, subscription, ticket sale, or another conversion.
    • Signal: information that helps the model search, such as a seed audience, similarity tier, genre preference, or observed price sensitivity. A signal provides direction; it does not necessarily restrict delivery.
    • Constraint: a boundary the campaign must not cross, such as a spend ceiling, eligible territory, product restriction, or contractual audience requirement.
    • Observation: a metric you use to understand behavior but have not asked the model to optimize, such as reach, conversion rate, or downstream customer quality.

    Do not call a signal a constraint unless the platform’s current behavior explicitly guarantees it. If a territory, age rule, customer exclusion, or other eligibility condition is commercially or legally important, confirm the setting that enforces it. An audience seed is not a safe substitute for a hard boundary.

    Keep a campaign change log with the date, campaign, previous setting, new setting, whether the change was automatic or manual, the expected effect, and the person responsible for reviewing it. This small record becomes essential when the platform changes its interpretation of a familiar control. Without it, a sudden increase in reach can look like creative success when it was actually caused by audience expansion.

    Write an optimization contract before you spend

    A human hand adjusts safety stops around a tabletop model containing audience figures, creative tiles, budget tokens, and an objective marker.

    An AI system can optimize only what you make legible to it. If the selected conversion event is a weak proxy for the business result, the platform can improve its own score while sending the campaign in the wrong direction. A system asked to find inexpensive page visits should not be expected to discover profitable customers by implication.

    Write a short optimization contract for each campaign. It does not need legal language or a new software tool. It needs six explicit decisions:

    1. Name the business outcome. State what has to happen outside the advertising interface: a paid subscription, completed ticket purchase, qualified opportunity, retained customer, or another result that matters to the business.
    2. Name the platform event. Record the event the platform can observe and optimize. If that event occurs earlier than the business outcome, describe the gap instead of pretending the two are equivalent.
    3. Choose one primary score. CPA, conversion rate, conversion volume, and reach answer different questions. Select the metric that decides whether the test passes, then use the others for diagnosis.
    4. Set economic and eligibility boundaries. Use your actual unit economics to define an acceptable acquisition cost and a campaign spend limit. Record territories, offers, audiences, and products that are not eligible for expansion.
    5. Define the quality check. Decide how you will notice low-value conversions. Depending on the campaign, that may be completed purchases, valid subscriptions, qualified leads, attendance, retention, or another downstream signal.
    6. Assign decision rights. State which changes AI may make automatically, which recommendations require human approval, and who can pause, expand, or revert the campaign.

    For an entertainment release, the contract might connect the ad platform’s purchase event to paid tickets, use CPA as the primary score, monitor conversion rate and reach for diagnosis, restrict delivery to eligible markets, and require a human review before a material budget increase. The exact thresholds should come from the release’s economics, not from a generic platform benchmark.

    Do not broaden the audience and increase the budget in the same test step. If performance changes, you will not know whether the cause was additional delivery freedom, additional spend, or an interaction between them. Change one source of freedom, observe the result through the normal conversion lag, and then decide whether the next increment is justified.

    Supervise each kind of advertising AI differently

    AI-powered advertising is not one operating mode. Some features help you analyze a campaign. Some change who receives an ad. Others personalize the content or format presented to a user. The amount and location of human review should follow the type of decision being automated.

    AI roleWhat it changesMain control questionHuman checkpoint
    Decision supportReports, summaries, and audience researchIs the analysis based on the right data and definitions?Verify filters, calculations, and causal claims before acting
    Audience expansionWho may receive the ad beyond the original seedWhich inputs are signals, and which are enforceable boundaries?Audit expansion settings, eligibility, and conversion quality
    Content and format selectionWhich title, card, or presentation a user seesDoes the selected format match the buying decision?Measure the business outcome by title, offer, and market

    Google Demand Gen: audit expansion before interpreting performance

    Start by finding out which targeting behavior actually applies to the campaign. Under Google’s announced transition, campaigns move to the signal-based Lookalike model unless the advertiser uses the dedicated opt-out route for traditional behavior. If restricted audience eligibility is important, verify the account’s current setting rather than relying on the familiar name of the segment.

    Record the selected Lookalike tier even though it is now a signal. It remains part of the model’s direction and therefore part of the test. Record the Optimized Targeting status separately because the two mechanisms are not interchangeable and can operate together.

    Then read the result as a sequence rather than a single KPI:

    • Did reach expand beyond the pattern you expected?
    • Did conversion volume rise with that expansion?
    • Did conversion rate and CPA remain commercially acceptable?
    • Did the additional conversions produce the same downstream quality as the original audience?

    More reach is evidence that the delivery system found more people. It is not evidence that it found better customers. A lower CPA is more promising, but it still needs a quality check if the platform conversion can include low-value or incomplete outcomes.

    Use the traditional targeting option when strict audience control is a real requirement or when you need a clean baseline. Do not opt out merely because expansion feels less familiar. Conversely, do not accept expansion merely because it is the default. The right choice depends on whether scale or controlled eligibility is the binding constraint for that campaign.

    Meta Ads Manager: treat Manus as an analyst, not an authority

    Meta has embedded Manus AI in Ads Manager, where it can assist with report creation and audience research. This is decision-support automation. It may shorten the route from raw campaign data to a usable analysis, but a faster report is not the same as better ad delivery.

    Give the assistant bounded analytical tasks. A useful request names the account or campaign, date range, metrics, comparison, segments, and desired output. Asking for a performance report without those details invites the system to choose definitions that may not match the decision in front of you.

    Review every AI-built report at three levels:

    • Data scope: confirm the campaigns, dates, markets, and filters included.
    • Metric meaning: confirm that conversions, CPA, reach, and other measures use the definitions required by your optimization contract.
    • Inference: separate what changed from why it changed. A report can identify a correlation without proving that an audience, creative, or platform action caused it.

    Audience research generated inside the workflow should become a testable hypothesis, not an immediate budget instruction. Translate the output into a specific question: which audience, which offer, which expected behavior, and which metric would disprove the idea? That keeps the assistant useful without allowing polished language to substitute for evidence.

    Measure Manus first by workflow outcomes: whether it reduced repetitive report building, made useful segments easier to inspect, or surfaced a hypothesis worth testing. Claim an advertising performance gain only when a controlled campaign decision produces one. The presence of AI inside Ads Manager does not establish that causal link by itself.

    TikTok entertainment ads: match the AI format to the buying decision

    TikTok’s European rollout separates two useful entertainment jobs. Streaming Ads can personalize a four-title video carousel or multi-title media card using user interaction, while New Title Launch is designed to find high-intent audiences using signals such as genre preference and price sensitivity.

    Choose between them by starting with the decision you need the viewer to make:

    • Use the streaming format for catalog discovery. Multiple titles make sense when the viewer can enter through more than one piece of content and the business outcome is a subscription, viewership action, or another catalog-level result.
    • Use the launch format for a concentrated release. High-intent signals are more relevant when one title, event, or cultural moment needs to produce tickets, subscriptions, or attendance.

    Do not let personalization blur the measurement unit. Tag and review results by title, offer, and eligible market. If a multi-title unit generates strong interaction but only one title produces the intended business outcome, the useful finding is not that the carousel worked equally well. It is that the AI found an effective entry point that deserves a title-level follow-up.

    TikTok says 80% of its users report that the platform influences their streaming decisions. Treat that vendor-supplied figure as context for why TikTok built the formats, not as a forecast for your campaign. It does not mean 80% of the people you reach will subscribe, buy, or attend. Your optimization contract and campaign evidence still determine whether the format earns more spend.

    Test automation without creating an uninterpretable result

    An analyst observes two isolated campaign-testing lanes, one stable and one containing a glowing automation module.

    The hardest failure to detect is not a campaign that performs badly. It is a campaign that changes in several ways, appears to improve, and leaves you unable to explain which change mattered. AI makes this easier to do because an apparently small setting can alter the system’s decision space.

    Use this sequence whenever a platform introduces a new AI feature or changes the meaning of an existing control:

    1. Write one test question. For example: does signal-based audience expansion increase valid conversion volume while keeping CPA and downstream quality within our limits?
    2. Capture the starting state. Save the objective, conversion event, audience inputs, similarity tier, expansion settings, budget, creative, geography, and any other condition that could affect delivery.
    3. Change one category of decision. Test audience freedom, analytical workflow, format selection, creative, or budget separately whenever the platform and campaign volume make that possible.
    4. Choose the evaluation window from the conversion process. Allow the normal conversion lag to pass before judging results. Do not declare a winner from an incomplete cohort simply because the interface is already showing activity.
    5. Use the strongest comparison available. Prefer a platform experiment when a valid one is available. Otherwise, keep surrounding inputs stable and label a before-and-after comparison as observational rather than causal proof.
    6. Inspect business quality as well as platform efficiency. Compare valid purchases, qualified leads, paid subscriptions, ticket completions, attendance, or the downstream outcome specified in the contract.
    7. Make an explicit decision. Scale, hold, narrow, opt out, or revert. Record the evidence and the unresolved uncertainty so the next review does not restart the argument from memory.

    Set a spend ceiling before the test begins. If the experiment can consume a meaningful amount of budget without producing interpretable evidence, reduce its exposure or improve the measurement design first. Automation does not suspend the campaign’s economics.

    Watch for four false wins. More reach without better outcomes is distribution, not success. A lower platform CPA with weaker downstream quality is metric substitution. A faster AI-generated report is a workflow gain, not a campaign lift. An improvement that appears after simultaneous audience, creative, budget, and format changes is a lead for another test, not a reliable conclusion.

    Key takeaways

    • AI advertising control now depends more on objectives, data, constraints, and review rules than on the number of manual audience settings.
    • A seed audience, similarity tier, or behavioral input may guide a model without restricting delivery. Verify hard eligibility boundaries separately.
    • Write an optimization contract that connects the platform event to a business outcome, an economic limit, a quality check, and a named decision owner.
    • Supervise decision-support AI, audience expansion, and content-selection AI differently. They automate different decisions and create different failure modes.
    • Do not award more budget for reach, reporting speed, or a vendor benchmark. Scale only when the campaign improves the predefined business result within its constraints.

    Before your next campaign review, take one active campaign and write down its objective, signal, hard constraints, primary score, quality check, and stop decision. If you cannot fill in all six, do not give the system more freedom yet. Once those answers are clear, you do not need every old manual lever. You have something more useful: accountable control.

    References

  • AI Assistant Advertising Models: A Practical Brand Guide

    If you are deciding whether to move media budget into AI assistants, the first question is not how much to spend. It is whether the assistant sells influence at all and, if it does, whether you can identify exactly what your money changes.

    That distinction matters because assistant advertising is not developing as one standardized channel. Claude has committed to an ad-free experience, while ChatGPT is opening a path toward advertising. Your plan therefore needs two lanes: paid distribution where inventory exists and organic AI visibility everywhere users may ask for recommendations.

    There is no single AI assistant advertising model

    Search advertising has familiar boundaries. A user enters a query, paid placements occupy identifiable positions, and organic results remain available alongside them. An AI assistant can collapse research, comparison, and recommendation into one generated response. That makes the commercial model more consequential: a paid element may sit much closer to the assistant’s advice than a conventional display or search ad does.

    Three relationships are especially important for planning. They are not mutually exclusive; one assistant can support user-initiated commerce while refusing advertiser-funded placements.

    ModelHow the brand participatesWhat the user experiencesYour planning priority
    Ad-supported conversationThe brand pays for eligibility in a sponsored message, link, product unit, or branded placement.Commercial content appears in or around the conversation.Verify disclosure, context controls, billing, and the separation between sponsorship and the assistant’s answer.
    Ad-free assistantThere is no sponsored-response inventory to purchase.The assistant answers without advertiser-funded placements.Invest in accurate, accessible, well-structured information that can qualify for unpaid discovery.
    User-initiated commerceThe brand can be considered when the user asks the assistant to research, compare, or help purchase something.Commercial help begins with the user’s request rather than an advertiser inserting a pitch.Make product facts, conditions, limitations, and supporting evidence easy to retrieve and verify.
    User-directed integrationA tool or service performs a function after the user chooses to invoke or connect it.The integration helps complete a task without necessarily creating sponsored exposure.Treat integration availability as product distribution or functionality, not as proof of advertising reach.

    The split is already commercially meaningful. Claude’s approximately 30 million users are outside its potential sponsored-placement market, while ChatGPT offers a possible advertising surface connected to an estimated 800 million weekly users. Those are estimates of platform audiences, not estimates of purchasable reach. They do not tell you how many people are eligible for an ad, which markets or accounts have access, how often ads appear, or whether a particular placement can reach your buyers.

    Do not put total assistant users into a media plan as though they were impressions. Ask for the addressable audience, eligible conversation contexts, available markets, delivery rules, and reporting definitions. If those details are unavailable, the audience number is market context rather than a forecast.

    The deeper difference is incentive design. Anthropic’s stated position is that advertising could undermine trust, encourage assistants to find monetizable moments, and create pressure to prolong engagement. That is Anthropic’s strategic argument for keeping Claude ad-free, not proof that every assistant ad will corrupt every answer. It does identify the right questions for a buyer to test:

    • Does sponsorship affect only the placement, or can it affect the substance, ordering, or framing of the assistant’s answer?
    • Can the user distinguish the sponsored element before interacting with it?
    • Does the disclosure remain visible when the response is expanded, copied, shared, or revisited?
    • Can you prevent placements from appearing in sensitive or unsuitable conversational contexts?
    • Is the system rewarded for resolving the user’s task, extending the conversation, or generating more commercial opportunities?
    • Can you retrieve a record of the creative, disclosure, destination, and context category that were served?

    If a platform cannot answer these questions clearly, you do not yet have enough information to evaluate brand risk. Novelty is not a substitute for placement transparency.

    Build paid distribution and organic AI visibility as separate lanes

    Assistant marketing becomes muddled when paid ads, organic citations, product recommendations, and tool integrations all appear under one AI visibility label. Separate them before assigning work, budget, or performance targets.

    Lane one: paid assistant distribution

    A paid program starts with the unit being purchased. Do not approve a line item called AI assistant ads unless the brief states whether you are buying a sponsored message, a branded module, a link, a product placement, or another clearly defined format.

    • Confirm access. Record the assistant, account type, market, language, device coverage, campaign objective, and inventory status. A platform announcement does not guarantee that your account can buy the format.
    • Define eligible context. Document what user intent or conversation category can trigger the placement. A broad audience label is not enough when the placement appears inside a highly specific exchange.
    • Capture the disclosure. Obtain an example showing the complete placement as the user sees it. Review the label, visual boundary, advertiser identity, and destination before launch.
    • Set exclusions. Identify contexts in which a commercial message would be inappropriate or risky for your brand. If the platform cannot support necessary exclusions, do not assume that careful creative will solve the placement problem.
    • Match the destination. The landing page should preserve the product, offer conditions, limitations, and expectations established by the placement. A conversational ad can feel unusually personal, so a mismatched handoff is especially conspicuous.
    • State one testable hypothesis. Decide whether the pilot is meant to generate qualified visits, purchases, leads, product consideration, or learning about a new format. Do not use platform audience size as the success metric.

    Lane two: unpaid assistant eligibility

    An ad-free policy does not make an assistant irrelevant to commerce. Claude can still help a user research, compare, or purchase products when the user requests that help; its distinction is that the commercial task is user-initiated rather than advertiser-driven. That means a brand can be discoverable without being able to buy its way into the conversation.

    This is where SEO, AEO, GEO, content quality, and structured data meet. Your objective is not to manufacture a recommendation. It is to make verifiable information available when an assistant needs to answer a relevant question.

    1. Map real decision questions. Start with the questions a buyer must resolve: what the product does, who it is for, what it works with, where it is available, what it costs, what is included, and when it is not a suitable choice.
    2. Create a canonical answer for each decision. Put the authoritative fact on a stable page instead of scattering conflicting versions across campaign pages, support documents, and old announcements.
    3. Make qualifiers explicit. Attach version, region, date, plan, compatibility, availability, and pricing conditions to the claim they qualify. An assistant cannot preserve a limitation that your page leaves implicit.
    4. Align JSON-LD with visible content. Use applicable structured-data types, such as Organization, Product, Offer, or SoftwareApplication, only for information that a reader can also verify on the page. Structured data can clarify entities and relationships; it does not make an unsupported marketing claim true or guarantee inclusion in an answer.
    5. Support important comparisons. Explain the basis of a compatibility, performance, feature, or suitability claim. Separate measured facts from editorial positioning and avoid presenting a slogan as evidence.
    6. Remove retrieval barriers. Check that public decision pages can be fetched, rendered, and understood without a login or a fragile interaction. Keep essential facts in readable page content rather than only in images or interactive widgets.
    7. Assign an owner. Product, policy, price, and availability pages need someone responsible for correcting stale facts. Display an updated date only when it reflects a genuine review.

    Paid placement may create exposure on one assistant. It will not repair contradictory specifications, inaccessible pages, vague entities, or unsupported claims. Organic readiness therefore remains infrastructure, not a fallback campaign.

    Use a six-part gate before approving an AI ad test

    A small pilot can be reasonable when the format is new, but small does not mean ungoverned. Require a written answer to each gate before money moves.

    1. Inventory gate: Is the placement available to your account in the intended market, language, device environment, and campaign period? If not, keep the item out of the committed budget.
    2. Influence gate: What exactly does payment buy? Separate eligibility for a labeled placement from influence over the assistant’s non-sponsored response. If the boundary is unclear, pause.
    3. Disclosure gate: Can a reasonable user tell what is sponsored, who paid for it, and where it leads? Review the complete rendered experience, not just the advertiser dashboard preview.
    4. Context gate: Can you target useful commercial intent and exclude contexts that would make the message intrusive, unsafe, or damaging? If context controls are weaker than your brand requirements, the inventory is not suitable.
    5. Measurement gate: Will reporting expose delivery, interaction, cost, and outcome definitions? A dashboard number without a denominator or documented event definition cannot support a scale decision.
    6. Economics gate: Is the test budget tied to a customer-value hypothesis and a stopping rule? Do not derive an acceptable price from the assistant’s total user count. Set it from the value of the outcome you can actually measure.

    Pass all six gates before treating the channel as performance media. If disclosure and context control pass but conversion measurement is weak, classify the activity as a learning or awareness test. If disclosure or answer independence fails, waiting is the clearer decision. If the assistant is ad-free, redirect the work to organic eligibility instead of searching for an unofficial shortcut.

    Include procurement, legal, privacy, and brand-safety reviewers when the placement uses personal data, operates in sensitive contexts, or creates claims with contractual consequences. The specific review depends on your market and use case; the novelty of the format does not remove existing obligations.

    Measure paid delivery, business outcomes, and organic visibility separately

    An assistant interaction can influence a decision without producing an immediate click. That does not justify vague attribution. It means you need a measurement structure that shows what is directly observed, what is attributed under your rules, and what remains unknown.

    Build the paid scorecard in layers:

    • Delivery: eligible conversation contexts, sponsored impressions, viewable placements, reach, and frequency, but only where the platform reports and defines them.
    • Interaction: placement opens, expansions, clicks, product-detail views, or other actions that can be tied to the sponsored unit.
    • Business outcome: qualified leads, purchases, subscriptions, booked meetings, or another outcome your existing analytics can validate.
    • Efficiency: cost per defined interaction and cost per defined business outcome. Preserve the event definition next to the number.
    • Quality: lead quality, cancellations, returns, or downstream customer value where those measures are relevant and available.
    • Trust and safety: complaints, unsuitable-context incidents, misleading renderings, disclosure failures, and brand-safety escalations.

    Tag paid destinations with campaign parameters and preserve the assistant, campaign, placement, creative, market, and date in your analytics records. Do not adopt a special attribution window merely because the channel uses AI. Apply your documented attribution rules, report direct and assisted outcomes separately where possible, and label modeled results as modeled.

    Incrementality deserves its own line. Use a randomized holdout when the platform supports one. Without a valid control, describe changes as observed or attributed rather than claiming the ads caused every conversion. A before-and-after increase can be useful evidence, but seasonality, other campaigns, and changes in demand can also move it.

    Organic AI visibility needs a different scorecard because no impression was purchased. Maintain a fixed set of decision prompts based on real buyer questions. For every check, record the assistant, model or product surface, market, date, account state, prompt, response, cited pages, brand inclusion, factual accuracy, and important omissions. Consistent conditions make changes interpretable; an isolated screenshot does not.

    • Track whether the brand is mentioned, but do not treat every mention as a recommendation.
    • Track whether a relevant page is cited, but inspect whether the citation actually supports the answer.
    • Track factual accuracy separately from visibility. A prominent but incorrect description is not a win.
    • Track referral traffic where it is observable, while acknowledging that some assisted journeys may not pass a usable referrer.
    • Keep paid appearances out of the organic visibility total. Sponsorship, citation, recommendation, and integration are different events.

    The final decision should be channel-specific. Scale a paid format only when delivery, business value, and placement integrity remain acceptable together. Improve organic content when assistants omit the brand, cite weak pages, or repeat stale facts. Escalate a platform issue when the disclosure, rendering, or context differs from what was approved.

    Key takeaways

    • AI assistant advertising is a platform policy, not a universal media category. Confirm that purchasable inventory exists before assigning budget.
    • Claude’s ad-free model still permits user-initiated research and commerce, so organic discoverability remains commercially relevant even where sponsored responses are unavailable.
    • A platform’s total users are not the same as addressable audience, eligible conversations, sponsored impressions, or conversions.
    • Before testing, require clear answers on paid influence, disclosure, context controls, measurement, and economics.
    • Build paid distribution and organic AI visibility as separate programs with separate metrics. Never report a sponsored appearance as an organic recommendation.
    • Accurate pages, explicit qualifiers, aligned JSON-LD, retrievable content, and maintained facts strengthen your eligibility across both ad-supported and ad-free assistants without guaranteeing selection.

    Your next move is practical: create a one-page inventory brief for every assistant ad opportunity, run it through the six gates, and establish an organic prompt-and-citation baseline before the campaign begins. You will then know whether you are buying measurable distribution, improving unpaid eligibility, or merely reacting to a large audience number.

    References

  • How to Plan Conversational AI and Social Ad Budgets

    How to Plan Conversational AI and Social Ad Budgets

    You have one experimental budget and three names in the room: Threads, ChatGPT, and Gemini. Calling all three emerging ad opportunities hides the decision that matters. What can you buy, what can you measure, and what job should each surface do?

    Start with the buying mechanics. Threads can enter Meta’s established campaign workflow. Early ChatGPT inventory is a controlled, impression-based buy. Gemini has no paid placement under Google’s announced stance. Once you separate those models, the budget decision becomes much easier.

    Separate the opportunity into three different ad markets

    Conversational AI and social feeds may compete for the same experimental budget, but they do not sell the same product. One sells feed distribution through a mature advertising system. Another is testing sponsored exposure beside a generated answer. The third is withholding ads while it develops the assistant.

    SurfaceWhat advertisers can accessWhat that means for your plan
    ThreadsGlobal advertiser access, a rollout to users worldwide, Advantage+ campaign expansion, and image, video, and carousel formats. Campaigns can be managed within the wider Meta environment used for Facebook, Instagram, and WhatsApp.Treat it as a paid-social placement test. Use familiar campaign objectives, but require placement-level reporting before claiming that Threads caused the result.
    ChatGPTSelected-advertiser testing with impression-based pricing, initial advertiser commitments below $1 million, and no self-service buying. Sponsored units are placed at the bottom of responses and separated from the organic answer.Treat it as controlled innovation inventory. It may support reach, learning, and brand objectives before it can support a conventional performance case.
    GeminiNo planned ad product under the stated 2026 position. Google is prioritizing assistant quality, usefulness, and trust before monetization.Do not put Gemini impressions in a paid-media forecast. Keep it in your organic AI visibility program and on a product-monitoring list.

    Availability is the first gate, not the final reason to spend. Threads has a reported user base of more than 400 million, but that figure describes platform scale rather than the reach available to your account. Meta also indicated that delivery would begin modestly. Your forecast should therefore come from the inventory and placement estimates available during campaign setup, not from the platform-wide audience number.

    ChatGPT presents the opposite planning problem. A conversation can reveal strong intent, but impression-based billing does not prove that the user noticed the sponsored unit, asked about it, visited the advertiser, or converted. Pricing tells you what triggers the charge. It does not tell you whether the exposure worked.

    Key takeaways

    • Classify each opportunity by buying model and reporting capability before comparing audience size.
    • Use Threads as an additional paid-social placement, not as a proxy for conversational intent.
    • Use early ChatGPT inventory for an impression-led learning objective unless the buying agreement supplies stronger outcome measurement.
    • Keep Gemini out of paid-media budgets until an actual ad product defines access, formats, billing, reporting, and controls.
    • Report paid conversational exposure separately from organic mentions and citations in AI answers.

    Give each surface one job before you fund it

    A new placement becomes expensive when it is asked to prove everything at once. If the same test is supposed to create awareness, generate leads, establish brand safety, and teach you how the format works, almost any result can be rationalized after the fact. Assign one decision question to each surface before approving spend.

    Threads: test incremental paid-social distribution

    Threads is the most operationally familiar option because Meta can streamline campaign expansion through Advantage+. That convenience can also obscure what happened. A blended Meta result cannot tell you whether Threads earned its share of the budget unless your reporting isolates delivery and outcomes for that placement.

    1. Write one hypothesis. For example, test whether a specific audience and creative concept can produce acceptable traffic or conversion quality on Threads. Do not use a vague objective such as learning the platform.
    2. Select one primary outcome. Choose reach, traffic, leads, sales, or another campaign objective supported by your setup. Keep secondary metrics diagnostic rather than treating every metric as a success condition.
    3. Confirm placement visibility. Before launch, verify that your reporting can show Threads delivery, spend, and the outcome tied to your objective. If it cannot, treat the campaign as a broader Meta test rather than a Threads test.
    4. Control the creative comparison. Carry one existing paid-social concept into the test and pair it with one Threads-specific variation. Hold the offer and audience as steady as your controls permit so that the creative difference remains interpretable.
    5. Predefine the decision rule. Set the acceptable result from your own paid-social benchmark before seeing the data. Record what would justify scaling, revising creative, or stopping.

    Modest early delivery may reflect limited inventory rather than a failed message. Do not judge creative after a handful of impressions, but do not wait indefinitely either. Evaluate once the placement has delivered enough exposure for the metric in your prewritten rule, and document underdelivery as a separate finding.

    ChatGPT: buy access only when the learning is worth the ambiguity

    Do not copy a paid-search brief into ChatGPT. The user may be expressing a need in the conversation, but the initial commercial model emphasizes impressions and offers limited conventional performance reporting. That makes the first tests better suited to advertisers that can value exposure and format learning without manufacturing a direct-response conclusion.

    Access is itself a qualification step. Initial testing involves selected advertisers, spending below $1 million per advertiser, without a self-service interface. The announced audience configuration places ads in free access and the $8-per-month ChatGPT Go tier, while Plus, Pro, and Enterprise remain ad-free for the time being. Your buying brief should identify the audience you can actually reach rather than referring to ChatGPT users as one undifferentiated group.

    Get written answers to these questions before approving an insertion order or equivalent commitment:

    • What event counts as a billable impression, and which impression fields appear in reporting?
    • Which account tiers, geographies, devices, and conversation contexts are eligible?
    • Can the unit link to a destination, and how are clicks or other interactions defined?
    • Are reach, frequency, and repeat exposure available, or will you receive only aggregate impressions?
    • Can follow-up questions about the sponsored product be measured, and are they reported in aggregate without exposing private conversation content?
    • Which category exclusions, adjacency controls, and remediation procedures apply?
    • Can campaign data be exported for reconciliation with your analytics and customer systems?

    If those answers do not support your normal acquisition model, label the spend correctly: a brand and product-learning test. Do not place a cost-per-acquisition target in the approval document and then excuse its absence because the format is new.

    Gemini: define the trigger for reconsideration

    A no-ad position is not the same as a permanent ban, but it is enough to make the current budget decision. Google leadership has ruled out Gemini ads for 2026 under the stated plan, citing the need to protect helpfulness and trust.

    Do not reserve speculative Gemini media money merely to appear prepared. Put the surface on a watchlist with five activation triggers: buyer access, eligible audience, ad format, billing method, and reporting controls. Until all five are defined, the paid-media row should remain unavailable rather than carrying an invented forecast. Your organic work for Gemini belongs in a different plan and can continue without waiting for an ad product.

    Build a measurement contract before the campaign

    Two analysts examine an abstract advertising journey that passes through a series of measurement checkpoints from impression to conversion.

    The measurement plan should be short enough to read in one meeting and strict enough to prevent a weak result from being renamed a success. For every test, record the business question, the primary metric, supporting diagnostics, disqualifying conditions, evaluation window, data owner, and decision owner.

    Use a four-level measurement ladder:

    1. Delivery: Record spend, billable impressions, placement share, and reach or frequency when provided. Reconcile the purchased amount with the platform report before interpreting response.
    2. Observable response: Track clicks, destination sessions, or another defined interaction only when the format supports it. State exactly what the platform counts rather than assuming that similarly named metrics are equivalent.
    3. Business outcome: Connect qualified leads, purchases, or other approved outcomes through your normal analytics process. Separate directly observed conversions from modeled or assisted attribution.
    4. Incrementality: When the buying system and budget permit, use a holdout or controlled split to test whether the advertising changed behavior. Without a control, label changes in branded demand or direct traffic as directional rather than causal.

    For Threads, the crucial diagnostic is placement-level delivery. A campaign that performed well across Meta does not establish that Threads worked if Facebook or Instagram delivered most of the impressions. Compare the Threads result with the benchmark chosen before launch, and keep differences in audience, creative, and optimization settings visible.

    For ChatGPT, the minimum evidence is verified delivery under the contracted impression definition. OpenAI has indicated that follow-up questions about sponsored products could become an engagement signal, but that possibility is not a current performance guarantee. Do not make a future field the cornerstone of today’s business case. If follow-up reporting becomes available, document its definition, privacy treatment, and relationship to downstream action before using it as a KPI.

    Do not compare raw click-through rates across a feed ad and a unit beneath an AI answer as if the interfaces were interchangeable. Position, user task, billing, and available actions all differ. Compare each surface with the goal and benchmark assigned to that surface. Then compare investment decisions using business value and confidence in the evidence.

    Make trust and brand safety part of campaign acceptance

    A transparent safety gateway filters a sponsored content tile before it enters a field of conversational speech bubbles.

    An ad beside a generated answer carries a different trust burden from an ad in a familiar feed. The assistant is responding directly to the user’s words, so commercial influence can be mistaken for neutral help unless the boundary is obvious. Google’s reluctance to monetize Gemini reflects concern that advertising could compromise unbiased recommendations and user trust. OpenAI’s initial design addresses the same tension by marking sponsored units and separating them at the bottom of responses.

    Turn that principle into acceptance criteria. Before launch:

    • Review the actual unit or a faithful preview and confirm that the sponsorship label is visible without extra interaction.
    • Reject creative that imitates the assistant’s voice or implies that the organic answer endorsed the advertiser.
    • Check that every factual claim in the ad is supported on the destination page and remains accurate when removed from the surrounding conversation.
    • Document prohibited adjacencies, sensitive categories, escalation contacts, and the remedy available after an unsuitable placement.
    • Capture a dated preview or screenshot with the approved copy, destination, disclosure, and platform version so later changes can be audited.
    • For regulated or high-consequence claims, route the complete placement context through the appropriate legal or compliance review rather than submitting isolated ad copy.

    Threads offers a more familiar control layer. Meta is extending third-party brand-safety verification used on Facebook and Instagram to Threads. Confirm which verification provider, report, market, and placement your campaign can use. The existence of a verification program does not prove that it covers every impression in your specific setup.

    A trust failure also damages measurement. If users cannot tell whether a recommendation is paid, engagement may reflect mistaken endorsement rather than persuasive advertising. A high interaction count under that ambiguity is not a clean signal to scale.

    Keep paid exposure separate from organic AI visibility

    Your reporting should have three lanes: paid social distribution, paid conversational exposure, and organic AI visibility. Combining them in one AI channel bucket makes every number harder to interpret.

    • Paid social distribution: Put Threads spend, impressions, placement delivery, response, and conversions here.
    • Paid conversational exposure: Put ChatGPT sponsored impressions and any defined ad interactions here. Keep the sponsorship label and placement type in the campaign record.
    • Organic AI visibility: Track whether assistants mention or cite the brand for a maintained set of relevant questions. Record the model, access tier, prompt, answer date, cited destination, and repeated observations because generated answers can vary.

    A sponsored unit beneath a ChatGPT response does not mean the brand appeared in the organic answer. An organic Gemini citation is not paid delivery. Threads reach does not establish visibility in an AI assistant. Preserve those distinctions in campaign names, analytics dimensions, dashboards, and executive reporting.

    The same boundary applies to technical optimization. JSON-LD, schema, clear entity information, and answer-focused content can be evaluated as parts of organic discovery, but the available ad plans do not establish them as levers for ChatGPT ad eligibility, Threads delivery, or a future Gemini auction. Give structured-data work its own validation and visibility objectives instead of attributing paid-media effects to it.

    At your next budget meeting, create one row for each surface and fill in four fields: whether it is buyable, the single question the spend will answer, the evidence the platform can return, and the event that would unlock more budget. Fund Threads when you have a paid-social question and placement-level measurement. Fund ChatGPT when impression-led learning is valuable enough to justify limited performance evidence. Leave Gemini out of the paid forecast until a real product changes the decision. The useful early move is not simply being first; it is knowing what the first test must prove before you buy the second.

    References

  • Apple’s Gemini-Powered Siri: An AI Search Action Plan

    Apple’s Gemini-Powered Siri: An AI Search Action Plan

    If you lead SEO or content discovery, Apple’s deal with Google changes what you should prepare for, but not what you can claim to measure. A more capable, personalized Siri could answer more questions inside Apple’s interface, leaving fewer searches that begin with a conventional results page.

    Your job now isn’t to chase a secret Siri ranking factor. It is to make your best information easy for an answer system to retrieve, understand, verify, and hand off, then preserve enough evidence to recognize when the upgraded Siri actually changes discovery.

    What Apple has confirmed, and what remains unknown

    Apple and Google have entered a multi-year collaboration covering Gemini models and cloud technology. Apple’s next generation of foundation models will be based on that technology and will help power future Apple Intelligence features, including a more personalized Siri expected later this year. Apple says Apple Intelligence will continue to run on its devices and through Private Cloud Compute.

    The architecture matters. Calling the upgrade “Gemini-powered Siri” is convenient shorthand, but it can create the wrong mental model. The confirmed relationship places Gemini beneath Apple’s next generation of foundation models. It does not establish that every Siri request will go directly to the public Gemini service, that Siri will become a reskinned Gemini app, or that Google will control the Siri experience.

    AreaConfirmedNot yet confirmed
    Model foundationApple’s next-generation foundation models will be based on Google’s Gemini models and cloud technology.The exact Gemini model, request-routing logic, and division of work between models.
    Siri upgradeA more personalized Siri is among the future Apple Intelligence features the collaboration will help power.An exact release date, supported-device list, language coverage, and regional availability.
    Privacy architectureApple says Apple Intelligence will continue to operate on Apple devices and Private Cloud Compute.How each category of Siri request will be partitioned across device, private cloud, and underlying model infrastructure.
    Content discoveryNo Siri-specific ranking, citation, or publisher-reporting mechanism has been disclosed.Which indexes Siri will use, how sources will be selected, when links will appear, and what referral data publishers will receive.

    Use that boundary in your roadmap. Put confirmed capabilities in the planning column and everything else in a testing backlog. If a proposed project depends on Siri supporting a particular schema type, exposing citations, or copying Google rankings, it is not ready to become a production requirement.

    Treat Siri as a distribution layer, not a Google ranking tab

    A smartphone routes an abstract question through connected information sources and produces a concise answer with several handoff paths.

    Gemini beneath Apple’s model stack does not mean Siri will inherit the Google Search index, ranking system, or citation behavior. A model can formulate an answer without owning the retrieval system that found the facts. Apple can also apply its own interfaces, policies, personalization, and privacy controls after a model generates or interprets information.

    That distinction changes the goal. A traditional search program often treats the ranked page and the resulting visit as the main units of success. An assistant can split that journey into three separate outcomes:

    • Selection: Your information helps form the answer, whether or not the page is shown.
    • Attribution: Siri names your organization, product, expert, or page as the source of a claim.
    • Action: The user visits, calls, navigates, subscribes, buys, books, or completes another useful next step.

    Do not collapse those outcomes into a vague idea of “ranking in Siri.” A page could influence an answer without receiving a visit. A brand could be named without a clickable citation. A linked page could earn traffic while contributing little to the generated wording. Each outcome needs its own observation and objective.

    Assign the objective by task. For an educational question, prioritize factual inclusion, accuracy, and attribution. For a commercial comparison, prioritize correct qualification and a useful destination page. For a local or service task, prioritize accurate entity data and a low-friction handoff. This keeps your strategy useful even if Apple’s final interface differs from current AI answer products.

    Build content Siri can extract, verify, and hand off

    Structured content cards pass through an illuminated verification system before reaching a smartphone and a webpage handoff.

    You do not need a speculative Siri optimization layer. You need pages whose important facts survive when separated from navigation, brand language, and surrounding prose. Audit the pages closest to a decision or action in this order:

    1. Start with assistant-shaped tasks. Collect the questions people ask before contacting support, choosing a product, visiting a location, or completing a purchase. Preserve the natural wording instead of converting every task into a short keyword. “Does this work with my current plan?” carries conditions that a generic phrase such as “plan compatibility” loses.
    2. Put the decisive answer before the sales argument. The first relevant subsection should identify the subject and answer the question directly. Follow it with conditions, exceptions, evidence, and the next step. Avoid introductions that require an answer system to infer the conclusion from several paragraphs of positioning.
    3. Scope every fact that can change. Name the product edition, software version, location, audience, availability condition, or effective date when it affects the answer. Replace floating statements such as “it is included” with language that identifies what is included, for whom, and under which plan or version.
    4. Align visible content with JSON-LD. Use structured data to label facts a visitor can verify on the page, not to insert claims that the page does not make. Names, descriptions, relationships, availability, authorship, locations, and other entity details should agree across markup and visible copy. More schema is not automatically better; accurate schema attached to a clear page is the useful target.
    5. Give important entities a stable home. Maintain a canonical page for the organization, product, service, location, or expert that matters to the query. Use consistent names and internal links so an answer system does not have to guess whether abbreviations, old product names, and near-duplicate pages describe the same entity.
    6. Make proof adjacent to the claim. Link consequential claims to the primary policy, specification, methodology, or other supporting material. Identify who owns the information and when it was last reviewed where freshness matters. A generic references page is less useful than evidence connected to the exact statement it supports.
    7. Remove retrieval barriers. Check that the intended page returns a successful response, is not accidentally excluded from indexing, declares the correct canonical URL, and exposes its main answer without requiring a login or an interaction. Do not place an essential fact only inside an image, video, downloadable file, or script-dependent interface when it can also appear as clear HTML text.
    8. Design the handoff. When a user needs to continue, provide a destination that matches the answer: the relevant booking screen, product configuration, support procedure, location page, or contact route. A generic homepage forces both the assistant and the user to reconstruct the journey.

    This work is not a guarantee of inclusion in Siri. It improves the properties that any retrieval-and-answer system needs: identifiable entities, explicit facts, credible support, accessible pages, and a coherent next action. It also strengthens your content before Apple reveals any Siri-specific controls.

    Measure Siri visibility without inventing a rank

    No query-level Siri reporting, citation rule, or referral format has been confirmed. A single “Siri rank” is therefore not a defensible key performance indicator. Build a repeatable observation system instead.

    Create a query ledger before the rollout

    Save the tasks that matter while your team still has a clean baseline. Record the exact prompt, not just its topic. Because Apple is promising a more personalized Siri, context will matter when you compare results. Keep test conditions consistent where possible and record meaningful differences rather than treating every response as universal.

    FieldWhat to record
    Business taskThe decision or action the user is trying to complete.
    Exact promptThe full wording, including follow-up questions in a multi-turn interaction.
    Test contextDate, device, operating-system version, language, region, and any relevant account state that can be documented safely.
    Observed answerThe material claims, recommendations, omissions, and errors in the response.
    AttributionWhether the brand, expert, page, or another source is named or linked.
    HandoffThe page, app, action, or service offered as the next step.
    OutcomeWhether the user could complete the intended task accurately and with reasonable effort.

    Classify each result rather than assigning an improvised position. Was your information included? Was the entity identified correctly? Was there visible attribution? Did the handoff reach the right destination? Was the task completed? Those questions reveal where the discovery chain works and where it breaks.

    Use web analytics conservatively. A recognizable referral can support attribution when one is exposed, but missing referral data does not prove that Siri had no influence. An unexplained increase in direct traffic does not prove Siri caused it either. Corroborate analytics with captured responses, destination-page changes, and repeated tests from your defined query set.

    Once the upgraded Siri reaches the devices, languages, and regions relevant to your audience, rerun the same tasks before changing your content strategy. Look for stable patterns across repeated observations. One surprising answer is a test case, not an algorithm update.

    FAQ for SEO and AI visibility teams

    Will strong Google rankings automatically produce Siri visibility?

    No automatic relationship has been confirmed. Gemini is part of the model foundation in Apple’s plan, but a model foundation is not the same thing as a search index or ranking pipeline. Keep improving conventional search performance, but measure Siri selection, attribution, and handoffs independently when the upgrade becomes available.

    Do you need special Siri schema markup?

    No Siri-specific schema requirement has been announced. Use the schema vocabulary that accurately describes the visible page and validate the resulting JSON-LD. Do not add irrelevant types, invented properties, or hidden claims merely to mention Apple, Siri, Gemini, or AI.

    Should you change traffic forecasts before Siri launches?

    No. Model the upgrade as a discovery scenario, not a booked traffic gain or loss. Fund improvements that help across search and answer systems now, such as entity cleanup, answer-focused editing, evidence mapping, technical accessibility, and baseline testing. Wait for observable Siri behavior before attaching a platform-specific forecast.

    In your next planning cycle, choose the assistant-shaped questions tied to real decisions, audit the pages responsible for answering them, and start the query ledger. When the upgraded Siri reaches your audience, test those same tasks first. Let observed selection, attribution, and action patterns determine the next investment, not the presence of the Gemini name.

    References

  • Google Ads API Optimization: A Safe AI-Assisted Workflow

    You have a Google Ads performance question, but answering it means choosing fields, writing GAQL, handling authentication, and turning the result into something the team can review. AI assistance can remove much of that technical friction. It cannot decide whether broader reach, a higher bid, or a new keyword strategy makes financial sense for your business.

    The useful approach is to separate observation from action. Use the Google Ads API Developer Assistant to investigate performance through read-only queries, validate what it returns, and save repeatable analysis. Put any change to budgets, bids, targeting, or keywords through a deliberate human approval process.

    Separate faster analysis from automated optimization

    Google Ads API Developer Assistant v1.0 is a Gemini CLI extension that can translate natural-language requests into GAQL, answers, and Python code built around the google-ads-python client library. This makes it useful when you understand the business question but do not want to reconstruct every query from memory.

    The assistant can also execute read-only API calls from the terminal, display results in formatted tables, export tabular data to CSV, and place generated code in a saved_code folder. Those capabilities shorten the path from a question to an inspectable result.

    That is analysis assistance, not an optimization strategy. A table can show which campaign recorded the most conversions. It cannot determine whether those conversions were valuable, whether lead quality deteriorated, or whether the campaign consumed more budget than the outcome justified. Those judgments depend on business definitions and constraints that sit outside a generic performance query.

    Keep the boundary explicit: the assistant retrieves and organizes evidence; an accountable person decides what the evidence means and whether the account should change.

    Key takeaways

    • Begin with reporting and diagnosis. Do not treat generated output as permission to change the account.
    • Include the account scope, date range, dimensions, metrics, filters, sort order, and desired output in every request.
    • Review generated GAQL and Python as untrusted code before running or reusing it.
    • Treat Google Ads Recommendations as hypotheses to investigate, not instructions to accept.
    • Keep changes to budgets, bids, targeting, and keywords behind human approval and a defined rollback path.

    Ask questions that lead to decisions, not just reports

    A vague request such as analyze my campaigns leaves too many choices to the assistant. It does not identify the problem, the period, the level of detail, or the decision you need to make. The result may be technically valid and still be operationally useless.

    Start with the decision. If you are deciding where to investigate a conversion decline, ask for a result that isolates campaign performance over a named period and includes the metrics needed to distinguish lower volume from higher cost. If you are checking a Google recommendation, request the evidence that would support or contradict its underlying claim.

    Use this prompt pattern: Within [account or campaign scope], for [date range], return [dimensions] and [metrics]. Apply [filters], sort by [metric], and provide [GAQL, Python, a terminal table, or CSV]. Explain the row grain, field choices, and assumptions before the result.

    Each part prevents a common analytical mistake:

    • Scope prevents a manager account, client account, campaign type, or status from being included unintentionally.
    • Date range makes the comparison reproducible. Relative periods are convenient for exploration, while explicit periods are easier to audit later.
    • Dimensions determine what one row represents. Adding a date, device, or other segment can change the grain and produce many rows for a campaign.
    • Metrics determine whether you can connect activity to a business outcome. A ranking by conversions alone does not show the cost or value behind those conversions.
    • Filters remove irrelevant entities, but an overly narrow filter can hide the reason performance changed.
    • Output determines whether you get an explanation, a reusable query, executable code, or an artifact another person can inspect.

    Prompts you can adapt

    • For the previous 30 days, rank campaigns by conversions. Return the GAQL first, explain the selected fields, and then produce a read-only Python script using google-ads-python.
    • Compare campaign cost and conversion performance across two explicitly named periods. Show the row grain and flag any filter that excludes paused or removed entities.
    • Generate a read-only query that provides evidence for or against a recommendation to expand keyword matching. Separate the requested output by campaign so the account owner can review exposure and outcomes.
    • Run this approved query, display a terminal table, and export the same rows to CSV. Include the account scope and date range in the output description.

    The first example closely matches a documented use case: a request for campaigns with the most conversions in the last 30 days can produce both a GAQL query and an optimized Python script. The important addition is the review instruction. You want to see what the assistant plans to ask the API before you rely on the answer.

    Inspect five things before execution: the customer being queried, the dates, the row grain, the filters, and the metric definitions. Then look for a sanity check. Compare a small part of the result with a familiar Google Ads view or an existing trusted report. A plausible table is not proof that the query answered the question you intended to ask.

    Configure Developer Assistant v1.0 for repeatable work

    The documented prerequisites for v1.0 include a Google Ads API developer token, a configured google-ads.yaml file, Python 3.10 or later, Gemini CLI, and a local clone of the google-ads-python library. A setup script handles the library cloning step.

    Do not stop once the assistant returns its first successful table. A useful setup makes the same request behave consistently for different operators and on different days.

    1. Validate the connection with a known read-only question. Choose a result you can verify in the Google Ads interface. This separates authentication or account-scope problems from query-design problems.
    2. Define project conventions in GEMINI.md. The assistant uses GEMINI.md and configuration files as project context when tailoring code. State the expected client library, output conventions, code location, naming rules, and read-only default.
    3. Require an explanation before execution. Ask for the GAQL, selected resources, filters, dates, and row grain in plain language. A reviewer should be able to understand the intended request without reverse-engineering the code.
    4. Keep credentials out of prompts and generated files. Use the supported configuration mechanism. Review saved files before sharing them or adding them to version control.
    5. Review generated Python before running it. Check imports, customer selection, request type, file paths, exception handling, and whether the code does anything beyond retrieval and export.
    6. Preserve a verified query as a smoke test. Run it after configuration or dependency changes. If its known output or shape changes unexpectedly, investigate the environment before trusting new analyses.

    Project context is leverage. Good instructions make repeated analysis more consistent; incorrect instructions make the same mistake repeatable. Keep GEMINI.md short enough to review, specific enough to guide the assistant, and under the same change-control discipline as other project configuration.

    The saved_code folder is most valuable when it becomes a reviewed library rather than a dumping ground. Give each retained script a clear purpose, record its account scope and required inputs, and distinguish experimental output from approved reporting code. Remove ambiguity before another person schedules or modifies it.

    Turn Recommendations into an evidence-backed test queue

    Google Ads Recommendations are prompts to evaluate. They are not proof that the proposed change fits your economics. A suggestion may be informed by patterns across accounts while missing a constraint that matters in yours. For example, an account using Exact and Phrase match keywords may receive a Broad Match suggestion even when its budget or niche requires tighter control.

    The Optimization Score is easy to misread as a performance grade. It reflects how recommendations are being handled, and dismissing a recommendation can affect the score in the same way as applying it. You do not need to accept an unsuitable change merely to clear the prompt or improve the displayed score.

    Use the API assistant to build an evidence packet for each recommendation:

    1. Restate the claimed problem. Is the recommendation trying to expand reach, improve efficiency, repair setup, or remove a limitation?
    2. Request the relevant account evidence. Define the entities, period, metrics, and filters that would show whether that problem exists.
    3. Write down the business constraint. Include budget limits, acceptable lead quality, geographic restrictions, inventory realities, or other rules that the platform cannot infer reliably.
    4. Set success and failure criteria before making a change. Decide what result would justify keeping the change and what result would trigger reversal.
    5. Choose a reversible test. Limit the blast radius and preserve the prior state so the account can be restored if performance or traffic quality deteriorates.
    6. Assign an owner. One person should approve the change, monitor the agreed evidence, and decide whether to keep or roll it back.

    Auto-apply deserves stricter treatment because it can remove that review gate. The documented control path is Recommendations, All Campaigns, and Auto-Apply Settings, where you can confirm that unwanted selections are unchecked. Check the setting at the account level instead of assuming that an earlier choice still reflects current policy.

    This is a financial control, not interface housekeeping. Automatically applied suggestions can affect reach, spending, bids, or keyword behavior. Enable a category only when you have defined who owns it, what changes it permits, how the effect will be monitored, and how the prior state can be recovered.

    Do not give every interface notice the same urgency. Blue or yellow notices can represent suggestions, while red or purple notices can indicate issues such as billing errors or disapproved ads. Investigate actual delivery or account-access problems before spending time on an optional optimization prompt.

    Run one controlled loop from question to verified change

    A reliable optimization process leaves a trail from the original question to the final decision. It should be possible for another person to see what was queried, what came back, why a change was approved, and whether the expected result appeared.

    1. Name the decision. Write the question in a form that could change an action: which campaigns need investigation, whether a recommendation deserves a test, or where a recurring report shows an exception.
    2. Specify the evidence. Add account scope, dates, dimensions, metrics, filters, and output format to the prompt.
    3. Generate before executing. Read the proposed GAQL and code. Correct ambiguous fields, unintended segments, and overly broad scope.
    4. Run read-only. Display the result in the terminal and export CSV when another reviewer or a longer audit trail is needed.
    5. Validate the result. Compare a small slice with a trusted interface view or established report. Confirm that each row represents what you think it represents.
    6. Form a testable explanation. State what appears to be happening, what evidence is still missing, and which reversible change could test the explanation.
    7. Approve and implement separately. Use your normal controlled account-management process for changes. Do not turn generated analysis code into mutation code simply because the first output looked correct.
    8. Run the same query again. Reuse the reviewed query so the before-and-after comparison is based on the same scope, fields, filters, and row grain.

    Label saved queries and exports with enough context to make them interpretable later. At minimum, preserve the account scope, analysis period, purpose, and important filters alongside the artifact. A file called campaign_report.csv creates less accountability than an export tied to a specific question and approved query.

    Automate stable retrieval only after the query has survived review and repeated validation. Keep recommendations and account mutations gated. The cost of manually approving a consequential change is small compared with the cost of allowing a misunderstood prompt, broad filter, or unsuitable recommendation to alter spend without supervision.

    Start with one recurring question your team currently answers by hand. Define it precisely, run it read-only, verify the output, and retain the approved query. Once that loop is dependable, add the next question. The real efficiency gain comes from reusing trusted analysis while keeping financial decisions under human control.

    References

  • Commercial Intent in AI Chats: Where Brands Should Focus

    Commercial Intent in AI Chats: Where Brands Should Focus

    If you are budgeting for AI visibility on the assumption that every product mention is close to a sale, stop and reclassify the opportunity. Commercial demand exists in AI chats, but much of it appears while people are framing a problem, weighing approaches, or trying to succeed with something they already bought.

    Your job is to recognize those moments without forcing a sales funnel onto every conversation. That changes which pages you prioritize, how you structure an answer, where you place the next action, and what you count as success.

    Commercial intent is a minority, but it is not one moment

    Across a corpus covering 4.4 billion characters, 613 million words, and 3.9 million conversation turns, people used AI heavily for tasks such as planning, brainstorming, analysis, learning, transformation, and creation. Those activities may happen at work or mention a product, but that does not automatically make them commercial.

    Within a categorized sample of 24,259 sessions spanning 42 intent categories, 64.6% did not fit a purchase funnel, while 35.4% showed some form of commercial intent. The useful correction is not that AI chats have no commercial value. It is that commercial value is distributed across several different jobs, most of which are not an immediate purchase request.

    Awareness accounted for 10% of the categorized sessions and consideration for 8.5%. Together, those early stages represented 18.5% of all sessions and the largest block of commercial activity. Discovery accounted for 4.1%, decision support for 2.8%, transactional support for 4.8%, and post-purchase needs for 5.1%.

    That distinction matters when you set priorities. If your AI strategy watches only prompts containing words such as buy, price, best, or demo, it will miss people who are still deciding what kind of solution they need. It will also miss existing customers asking how to configure, use, integrate, or repair what they own.

    Do not treat the percentages as a universal forecast for every market. They describe the analyzed corpus, not the exact intent mix for your category. Use them to challenge an overly transactional strategy, then classify the questions that appear in your own sales, support, search, and customer research.

    Classify the user’s job before choosing the content

    Four connected rooms show a user investigating a problem, exploring approaches, comparing products, and learning to use an owned device.

    A noun is not an intent signal. A user can mention your category while asking for writing help, summarization, technical instruction, product evaluation, or troubleshooting. Classify the job being done before deciding whether the conversation belongs in a commercial funnel.

    Intent classObserved shareWhat the user is trying to doWhat your content should accomplish
    Outside the purchase funnel64.6%Create, learn, analyze, plan, transform, or converse without making a product choiceComplete the requested task honestly; introduce a commercial path only when it is genuinely relevant
    Awareness10%Name a problem, understand its causes, or learn what kinds of solutions existDefine the problem, explain when it matters, and make the available approaches understandable
    Consideration8.5%Compare approaches, requirements, or tradeoffsProvide selection criteria, limitations, alternatives, and use-case fit
    Discovery4.1%Find products, providers, or options in a categoryHelp the user build a defensible shortlist without hiding eligibility criteria or constraints
    Decision support2.8%Choose among known optionsSupply verifiable details about fit, evidence, implementation, cost factors, and risk
    Transactional support4.8%Complete or manage a commercial actionRemove uncertainty about requirements, process, timing, and what happens next
    Post-purchase5.1%Set up, use, improve, or troubleshoot something already acquiredHelp the customer reach the intended result and recover from predictable failures

    The percentages in the table are rounded shares of the categorized sample. The user-job descriptions and content responses are practical applications of those intent classes.

    Context is decisive. Create a launch brief for this product is primarily a creation task. Which type of platform should our distributed team use to manage a launch? is consideration. Why did this feature stop working after setup? is post-purchase. The same category terms can appear in all three prompts, but only the latter two have an explicit relationship to choosing or owning a solution.

    Use a strict operational rule: label a conversation commercial only when the user is making an economic choice, evaluating a solution, completing a transaction, or seeking help with something already acquired. Do not inflate your opportunity estimate by treating every workplace task as latent demand.

    Build for exploration and ownership, not just selection

    Early-stage content should make the decision legible

    Awareness and consideration together accounted for 18.5% of all categorized sessions. This is where product-led content often arrives too early. A user who is still defining the problem does not need an unsupported claim that your product is the answer. They need enough structure to decide whether the category is relevant at all.

    A useful awareness or consideration page should do the following:

    • Answer the initiating question immediately. State the practical answer before company history, positioning, or a lead form.
    • Define the decision context. Identify who the advice applies to, the conditions that change it, and any prerequisites the user may not have mentioned.
    • Separate symptoms from causes. Help the user avoid buying a solution for the wrong problem.
    • Expose the criteria that change the choice. Explain requirements, constraints, tradeoffs, and cases in which a simpler approach is sufficient.
    • Include credible alternatives. A comparison is more useful when it covers different approaches, including doing nothing yet, rather than presenting a disguised product pitch.
    • Provide a natural next question. Link the problem explanation to criteria, the criteria to options, and the options to decision evidence.

    The first answer carries unusual weight. The median conversation in the corpus had two turns and 430 words, and more than 80% of chats stayed below 1,000 words. Many users therefore do not spend a long sequence teaching the assistant their context. Your page should state its audience, assumptions, constraints, and core answer clearly enough to survive a short exchange.

    This is also where answer-engine optimization and conversion writing need to part company for a moment. The strongest opening is the one that resolves the question accurately. The commercial handoff comes after the user can see why a category, method, or product deserves consideration.

    Post-purchase content belongs in the commercial strategy

    Post-purchase needs represented 5.1% of sessions, exceeding discovery at 4.1% and decision support at 2.8%. That is a clear reason not to limit AI optimization to comparison and product pages.

    Support content should be designed around the customer’s actual failure state, not your internal feature taxonomy. A page titled with the symptom a user can observe is more useful than one that assumes they already know which component caused it.

    • Name the symptom, task, or desired outcome in the title and opening.
    • State the applicable product state, configuration, prerequisites, and access requirements.
    • Put the resolution steps in the order the user must perform them.
    • Describe the expected result so the user can verify that each meaningful step worked.
    • Branch explicitly when different causes require different fixes.
    • Say when self-service should stop and what information support will need.
    • Connect the fix to related setup or usage guidance without turning the page into a sales pitch.

    Where security and account privacy allow it, publish general help in accessible, indexable page content. Keep account-specific data and privileged actions behind authentication. An AI visibility goal never justifies exposing information that should remain private.

    Audit AI demand by prompt, page, and outcome

    A strategist sorts abstract chat bubbles through webpage cards toward discovery, comparison, purchase, and customer-success outcomes.

    You do not need to guess whether your opportunity is mostly awareness, decision support, or ownership. Build an intent inventory from questions people already ask, then connect each question to a page and a measurable next step.

    1. Collect real questions. Pull wording from site search, sales conversations, support records, community discussions, product research, and known AI referrals. Preserve the original phrasing instead of rewriting everything as a target keyword.
    2. Assign one primary job. Label each question as non-funnel, awareness, consideration, discovery, decision, transactional support, or post-purchase. Record a secondary intent only when it changes the answer the user needs.
    3. Map the best existing page. Choose the page that should answer the question, not merely the page currently ranking for adjacent terms. A product page is not automatically the right destination.
    4. Find coverage and answer gaps. Mark questions with no page, pages that bury the answer, unsupported claims, missing limitations, stale instructions, or no sensible continuation.
    5. Repair the visible content first. Make the answer, scope, evidence, and next step explicit. Structured data should reflect what a user can actually see on the page; it cannot manufacture commercial intent or compensate for an evasive answer.
    6. Run repeatable prompt checks. Log the exact prompt, assistant, exposed model or version, date, language or market, answer, brand representation, and cited URLs. A single response is an observation, not a stable visibility benchmark.
    7. Measure the outcome appropriate to the stage. Evaluate awareness content by accurate inclusion and progression to deeper evaluation. Evaluate decision content by qualified actions. Evaluate post-purchase content by successful task completion and reduced escalation where those signals are available.

    Keep visibility and progression as separate measures. Visibility asks whether the assistant represents the right answer, entity, or page. Progression asks whether the user then reaches a useful next step. Combining them into one score hides whether you have a retrieval problem, an answer-quality problem, or a conversion-path problem.

    Referral traffic is also incomplete by definition. You can observe a visit only when a user follows a link; an interaction that ends inside the chat produces no referral session. Use AI referral data as evidence of visits and downstream behavior, not as a complete count of AI influence.

    Finally, compare like with like. Do not blend troubleshooting prompts and product-selection prompts into one visibility rate, then judge both by purchases. Segment the prompt set by intent, page type, market, and user state. The resulting report will tell you which content is failing and what kind of repair it needs.

    Key takeaways

    • Commercial intent appeared in 35.4% of the categorized AI chat sessions, while 64.6% did not fit a purchase funnel.
    • Awareness and consideration formed the largest commercial block, so problem framing and selection criteria deserve more attention than purchase language alone.
    • Post-purchase demand exceeded both discovery and decision support, making setup and troubleshooting content part of AI commerce strategy.
    • Classify the user’s job, not the presence of a product or business keyword.
    • Because the median chat was short, make the first answer self-contained, scoped, and useful before asking the user to take a commercial action.
    • Measure visibility, answer accuracy, progression, and business outcomes separately for each intent stage.

    Start with your own prompt inventory. Find an early-stage cluster and a post-purchase cluster with weak coverage, repair the answers and their handoffs, and retest them consistently. You will see where AI visibility can support demand and where usefulness should stand on its own.

    References

  • What ChatGPT’s Reliability Push Means for Your AI Workflow

    What ChatGPT’s Reliability Push Means for Your AI Workflow

    If ChatGPT stops responding halfway through a deadline-sensitive task, getting the service back is only part of the problem. You also need to know what was saved, what can be moved elsewhere, and whether the eventual answer is trustworthy enough to use.

    OpenAI’s reported push to improve ChatGPT is encouraging, but a product priority is not an operating guarantee. The practical response is to separate uptime from answer quality, then build controls for both.

    Reliability is four separate problems

    Four connected mechanisms on a workbench depict a connection beacon, saved files, transfer ports, and an inspection lens checking an output.

    Teams often use “reliability” to mean that ChatGPT loads and produces an answer. That definition is too narrow. During one widespread incident, many users received no answer or only a black dot while thousands reported an outage. That was an obvious availability failure. Less visible failures can occur even when the interface appears to work normally.

    • Availability: Can you access the service and receive a response at all?
    • Delivery performance: Does the response arrive fast enough, without an error or an incomplete generation?
    • Behavior consistency: Does ChatGPT follow the same instructions, constraints, tone, and output structure across comparable runs?
    • Answer quality: Are its claims correct, adequately supported, complete enough for the task, and safe to publish or act on?

    These failures require different responses. Refreshing or retrying may help with a temporary delivery error, but it cannot verify a factual claim. Rewriting a prompt may improve instruction-following, but it cannot restore an unavailable service. Treating every problem as “ChatGPT is unreliable” leaves you without a useful diagnosis.

    Create four labels in your AI incident log: unavailable, slow or incomplete, instruction failure, and factual or quality failure. For each incident, record the task, model or interface used, prompt version, visible symptom, and recovery action. That small distinction will show whether your real problem is infrastructure, prompt design, output verification, or an unsuitable use case.

    Product priorities are a signal, not an SLA

    OpenAI reportedly declared a “code red” that concentrated work on personalization, speed, reliability, and the ability to handle a wider range of questions, supported by frequent coordination and temporary team reassignments. The reprioritization also reportedly delayed advertising initiatives, health and shopping agents, and a personal assistant called Pulse.

    That is a meaningful resource-allocation signal. It indicates that the core ChatGPT experience was important enough to pull people and attention away from other initiatives. It does not establish an uptime commitment, an accuracy threshold, a release schedule, or a guarantee that the product will behave consistently for your particular workflow.

    The individual priorities also need to be interpreted separately. Faster output is not necessarily more accurate output. Better instruction-following can produce a neatly formatted wrong answer. Personalization can make responses more useful to an individual while making it harder for a team to reproduce the same result across accounts. Support for more kinds of questions says nothing by itself about the depth or evidentiary quality of each answer.

    Use the product direction as planning input, then measure what matters inside your own work:

    • Track successful completion separately from response speed. A quick response that requires a complete rewrite is not a successful run.
    • Measure instruction adherence separately from factual accuracy. Passing one check must not substitute for the other.
    • Re-run your representative test prompts after a noticeable behavior change. Do not assume that an improvement for general users preserves your preferred format or workflow.
    • Keep critical prompts, evidence, templates, and approved outputs outside ChatGPT. Product investment does not remove the risk of temporary access loss.

    We would treat a stated reliability priority as a reason to keep evaluating ChatGPT, not as permission to remove fallbacks. The evidence that matters most is whether your own failure rate and recovery burden improve.

    Build a workflow that survives an outage

    Three coworkers preserve files, move a task to a backup workstation, and review a draft while a central cloud service is inactive.

    An outage becomes a business interruption when ChatGPT is both the worker and the filing cabinet. If the only copy of a prompt, source packet, decision trail, or draft lives inside a conversation you cannot open, even a short access problem can stop the entire task.

    Assign every recurring ChatGPT task an operating mode before the next incident:

    • Wait: Low-urgency work such as optional ideation can pause until the service returns.
    • Continue manually: A documented template lets a person complete the work without a model. This is appropriate for repeatable briefs, checklists, metadata drafts, and routine formatting.
    • Move to an approved alternative: Another model or internal system may handle the task, but only if it is already approved for the same data and risk level.
    • Stop and escalate: Sensitive, regulated, financially consequential, or action-taking workflows should not be moved to an unapproved tool merely to meet a deadline.

    For each task, store a compact recovery package in your normal project system. It should contain the current prompt, required inputs, authoritative facts, output format, last approved result, and the name of the person who can accept or reject the output. This turns a conversation-dependent process into a portable specification.

    When ChatGPT becomes unavailable or repeatedly fails, use a fixed runbook:

    1. Confirm whether the problem is broad or local. Check the official service status and test whether the failure affects one conversation, one account, or the service generally.
    2. Preserve the task state. Copy any accessible prompt, input, partial output, and unresolved decision into the recovery package.
    3. Classify the task by its preassigned operating mode. Do not invent a fallback while the deadline is already slipping.
    4. Use the manual or approved alternative route. Do not paste confidential material into a consumer tool that has not passed your organization’s privacy and security review.
    5. Record what was completed during the interruption. If a connected workflow can publish, send, purchase, or modify data, check its state before retrying so that you do not duplicate an action.
    6. When service returns, start from the saved task state and review the new output against work completed during the outage. Do not silently replace an approved manual result with a fresh model response.

    The objective is not to eliminate every delay. It is to keep a provider interruption from erasing context, creating uncontrolled data movement, or forcing your team to reconstruct decisions from memory.

    Verify the answer after the service returns

    A successful response is not the same as a reliable answer. ChatGPT can satisfy the requested tone and structure while introducing an unsupported claim. Your quality controls therefore need to inspect the content, not merely confirm that the prompt was followed.

    Use a source-bound production process

    1. Prepare the evidence first. Give ChatGPT the approved facts, definitions, product details, and source material it is allowed to use.
    2. Define the boundary. Tell it not to add names, numbers, quotes, capabilities, or claims that are absent from the supplied evidence. Ask it to identify missing information rather than fill a gap.
    3. Specify the acceptance criteria. Include the audience, required sections, prohibited claims, output format, and what needs a citation or human decision.
    4. Inspect claims against the evidence. Check every changing fact, proper name, number, quotation, and product statement before publication.
    5. Retain a human approval record. Save the accepted version and the evidence used to approve it, rather than relying on conversation history as the audit trail.

    For SEO, AEO, and GEO work, apply an additional domain check. A model-generated keyword, question, or answer can help you explore phrasing, but it cannot prove search demand, customer intent, ranking potential, or the likelihood of being cited by an AI system. Confirm those decisions with actual query data, customer evidence, analytics, or another appropriate first-party source.

    JSON-LD needs two validations. First, parse the output and check that its types and properties are structurally valid. Second, compare every material value with the visible page and your authoritative business data. Syntactically valid schema can still be misleading when the model invents a rating, author, price, availability state, credential, or other property that the page does not support.

    Maintain a regression set for your real tasks

    Public model benchmarks do not tell you whether ChatGPT can produce your product brief, follow your editorial policy, or preserve your schema conventions. Maintain a fixed set of representative prompts drawn from work you actually perform. For each one, define the required elements and the failures that make the result unacceptable.

    • Completion: Did the system return a complete, usable response?
    • Instruction adherence: Did it follow the required scope, structure, and exclusions?
    • Factuality: Can every material claim be reconciled with the approved evidence?
    • Consistency: Do comparable runs preserve the elements your workflow depends on?
    • Recovery: Can another person or approved system continue from the saved artifacts when ChatGPT is unavailable?

    Run this set when your team notices a meaningful behavior change, when a critical prompt is revised, or before you expand ChatGPT into a more consequential process. Keep the dimensions separate. A faster completion time should not hide a decline in factuality, and better prose should not hide missing requirements.

    Key takeaways

    • ChatGPT reliability includes availability, delivery performance, behavior consistency, and answer quality. Diagnose the layer before choosing a response.
    • OpenAI’s reported focus on the core ChatGPT experience is a useful direction signal, but it is not an SLA or an accuracy guarantee.
    • Store prompts, evidence, accepted outputs, and decision ownership outside ChatGPT so an access problem does not become a context-loss problem.
    • Give each recurring task a predefined mode: wait, continue manually, use an approved alternative, or stop and escalate.
    • Validate factual content and JSON-LD independently, even when ChatGPT follows the requested format perfectly.
    • Judge product improvements with a regression set built from your own tasks, not with one general impression of whether the model feels better.

    Start with one workflow that would hurt if ChatGPT disappeared during a deadline. Export its prompt and evidence, choose its fallback mode, and write down the checks an answer must pass. Once that recovery package works, repeat the pattern for the next dependency. Future product improvements then become useful upside rather than your only protection against failure.

    References

  • Platform-Specific AEO: Optimize for Voice and AI Answers

    Platform-Specific AEO: Optimize for Voice and AI Answers

    You have a page that ranks, valid schema, and a concise answer, yet Bing surfaces it while Grok ignores it and a voice assistant names another business. The problem is not necessarily weak content. You may be asking one page to satisfy several different retrieval and delivery paths.

    The practical fix is to maintain one canonical answer, then adapt its discovery, evidence, structure, and testing for each platform. Platform-specific AEO should change how an answer is found and delivered, not create conflicting versions of the facts.

    Key takeaways

    • Keep one authoritative version of each answer. Adapt the surrounding format and distribution for each platform.
    • For Bing and Copilot, prioritize extractable answer blocks, structured data, indexability, and external authority.
    • For Gemini, connect direct answers to a coherent topic cluster, clear authorship, supporting evidence, and natural-language questions.
    • For Grok, cover context thoroughly, keep changing facts current, and use X to distribute accurate summaries that point back to the canonical page.
    • For Alexa and other voice experiences, optimize the spoken result as well as the page: natural wording, self-contained answers, accurate local data, and device-level testing.
    • Measure observed answers, citations, referrals, and recognition failures. A single AEO ranking cannot describe performance across these surfaces.

    Map the answer path before changing the content

    A branching pathway connects one source to search, evidence, content, and voice symbols before reaching several generic devices.

    A spoken search has more failure points than a typed search. Speech recognition converts audio into text, natural-language processing interprets the request, retrieval finds candidate information, and text-to-speech delivers a response. A poor result can therefore begin before your page is considered: the device may mishear the request, resolve the wrong intent, miss the user’s location, or retrieve inconsistent business information.

    This is why voice search and AEO are related but not interchangeable. Voice is an interface. The answer engine is the system that interprets, retrieves, selects, and sometimes synthesizes the response. A typed Gemini prompt and a spoken request can express the same intent while taking different routes to an answer.

    Separate the route into five layers so you can fix the layer that actually failed:

    • Recognition: Does the device convert the user’s words into the intended query? Write around phrases people naturally say, not only compressed keyword forms.
    • Intent: Does the page resolve the real task, location, audience, or constraint behind the question? State those conditions explicitly.
    • Retrieval: Can the relevant platform discover and understand the page, entity, listing, or X post that contains the answer?
    • Selection: Is there a self-contained answer that can be separated from the rest of the page without becoming misleading?
    • Delivery: Will the selected passage still make sense when spoken aloud without its heading, table, image, or surrounding context?

    If the assistant misunderstood the speech, rewriting your schema will not solve the problem. If it understood the query but selected a competitor, recognition is not the issue. This diagnostic distinction prevents a great deal of unfocused content editing.

    Change the selection strategy for each platform

    The shared foundation is straightforward: an indexable page, a direct answer, factual support, clear authorship, and markup that agrees with the visible content. The emphasis around that foundation changes by platform.

    SurfaceMain selection pressureWhat to changeHow to check it
    Bing and CopilotSearch extraction, rich-result understanding, relevance, and authorityPut a concise answer directly below a question heading, keep the opening response under 100 words when the subject permits, use lists or tables for genuinely structured information, add appropriate schema, and support the page with credible citations and links.Inspect the actual Bing result and Copilot response. Use Bing Webmaster Tools to review queries and click-through rates, then compare the wording selected with the answer block you intended to expose.
    GeminiConversational intent, topical coverage, understandable structure, and trust signalsOrganize related questions into a topic cluster, connect them with meaningful internal links, write in natural language, expose author credentials, cite reliable evidence, and keep time-sensitive information current. Use JSON-LD to clarify what the page contains.Ask the core question in several natural phrasings and note whether the page or brand appears. Check whether pages built around specific questions earn better engagement than broad pages that make readers hunt for an answer.
    GrokContextual relevance, factual accuracy, current discussion, and discoverability through the web and XCover the conditions and user scenarios surrounding the answer, cite factual claims, monitor the questions being discussed on X, and publish accurate summaries on X that link to the fuller canonical explanation. Do not let a short social post introduce claims the page cannot support.Query Grok directly with the main question and its contextual variations. Record mentions or citations, and separately monitor referrals from grok.com and X rather than treating them as ordinary search traffic.
    Voice assistants, including AlexaA single speakable response, conversational intent, and accurate local or task-specific informationUse full-sentence questions, front-load a concise answer, and make important qualifiers audible. For local requests, maintain accurate names, addresses, opening hours, and other listing details. Treat Alexa as a surface that must be tested directly rather than assuming every voice assistant uses the same route.Speak the query on the target device. Record what the assistant heard, which answer it delivered, whether the location was correct, and whether the response remained useful without a screen.

    These are optimization priorities, not guarantees or permanent ranking formulas. Answer systems evolve, and their complete selection logic is not exposed. The defensible approach is to make a clear hypothesis about the relevant layer, change one meaningful element, and test the resulting answer on the actual surface.

    Do not turn the table into four copies of every page. Keep facts, definitions, policies, prices, and instructions in one canonical location whenever possible. Adapt the question heading, supporting depth, internal links, structured data, social distribution, local records, and testing around that location.

    Build a canonical answer unit that survives extraction

    A modular capsule containing linked information is extracted from surrounding content into several different device frames.

    Write for a decision or task, not a keyword fragment

    An answer unit is the smallest passage that resolves a specific question accurately. It is not merely the first paragraph, and it should not try to summarize an entire subject. Build it in this order:

    1. Choose one real task. Include the user, situation, or constraint when it changes the answer. A broad best-product query usually hides several different decisions.
    2. Use the complete question as a heading. Match natural speech where it remains clear. Do not force awkward keyword repetition into the heading.
    3. Give the direct answer immediately. A 40- to 60-word opening is a useful authoring target for a compact snippet or spoken response, while an answer under 100 words can remain easy for Bing to extract. These are editing constraints, not eligibility rules. Use fewer or more words when accuracy requires it.
    4. Place the decisive condition next. If the answer changes by location, product version, audience, or scenario, say so before the reader acts.
    5. Expand in a predictable order. Explain the mechanism, steps, exceptions, evidence, and next action. Use a numbered list for a sequence and a table only when the reader genuinely needs to compare fields.
    6. Connect the answer to its topic cluster. Link to prerequisite explanations and closely related decisions. This gives an answer engine more context without bloating the direct response.

    The direct answer does not have to be identical everywhere it appears, but its claims must remain consistent. An X summary may be shorter and a spoken response may omit secondary detail. Neither should contradict the canonical page or remove a condition that changes the meaning.

    Use schema to label meaning, not manufacture it

    Structured data helps a machine classify information that already exists on the page. It does not supply a missing answer, establish expertise by itself, or guarantee that a platform will quote the marked passage.

    • Use Article markup for an article and expose accurate author and publication information.
    • Use FAQPage when the visible page genuinely contains questions with their answers.
    • Use HowTo for a real ordered process, not for a page that merely discusses a task.
    • Use a more specific type such as Recipe, Product, or Event when the visible content supports it. Specific schema can help Bing understand the fields available for rich results and direct answers.
    • Keep every marked fact aligned with the visible page. If the opening hours, steps, author, or answer change, update the markup in the same release.

    Validate the implementation with Bing’s Markup Validator when Bing is in scope. Then inspect the rendered page as a reader would. Error-free JSON-LD attached to vague, stale, or contradictory copy is still a weak answer.

    Make the opening answer work without a screen

    A passage can scan well on a page and fail when read aloud. Before publishing, read only the proposed answer block without its heading or surrounding paragraphs. Revise it if the listener would have to see the layout to understand it.

    • Name the subject instead of opening with an ambiguous pronoun such as it or they.
    • State the important condition before the recommendation, not several paragraphs later.
    • Put the conclusion into a sentence before a supporting table or chart.
    • Avoid directions such as see below, choose the option on the left, or compare the highlighted column.
    • Keep citations and evidence on the page, but do not let a long attribution interrupt the spoken core of the answer.
    • Use words a customer would say. Preserve the precise technical term where it changes the meaning, then explain it plainly.

    Local voice queries add an entity-resolution problem. Addresses, opening hours, reviews, mobile usability, and page speed can affect whether a nearby business is a credible and useful response. Reconcile the website and business listings before polishing an FAQ; a beautifully written answer cannot repair the wrong location or closed hours.

    Test observed answers instead of looking for one AEO rank

    Traditional rank tracking is not enough here. A generated answer may mention you without sending a click, a voice assistant may deliver a correct response without showing a URL, and two phrasings of the same intent may produce different selections. Build a repeatable observation log.

    1. Create a stable query set. Include the direct question, a natural paraphrase, a relevant follow-up, and a local or comparison modifier when the intent calls for one.
    2. Record the environment. Note the platform, typed or spoken input, device or interface, recognized query, location context when relevant, and the date of the check.
    3. Capture the output. Save the answer, named sources or citations, linked page, factual errors, missing qualifiers, and whether the assistant asked a follow-up question.
    4. Classify the failure layer. Decide whether the problem was recognition, intent, retrieval, selection, factual consistency, or spoken delivery.
    5. Change the smallest relevant layer. Edit the answer block for extraction problems, the topic cluster for missing context, structured data for classification problems, X distribution for Grok discovery, or local records for nearby voice requests.
    6. Run the same query set again. Recheck after a material content, schema, listing, or platform change so that the new result is comparable with the earlier observation.

    Match each failure to a specific correction

    • The page never appears: inspect crawlability, indexing, internal links, entity consistency, and platform-relevant distribution before rewriting every paragraph.
    • The correct page appears but the extracted answer is poor: tighten the question heading, opening answer, list structure, and nearby qualifiers.
    • The answer is stale or contradictory: reconcile the visible copy, structured data, citations, dates, listings, and distributed summaries.
    • A competitor is repeatedly selected: look for a real gap in evidence, topical coverage, author credibility, external authority, or scenario-specific usefulness.
    • The spoken query is misheard: test alternative natural wording and inspect the device, language, pronunciation, and location context. Content selection has not yet become the primary problem.
    • The answer is correct but no referral arrives: record the mention or citation separately. Referral traffic alone cannot show every voice or generated-answer appearance.

    Keep platform evidence separate

    Do not roll these observations into a single visibility score until you can still see the underlying platform results. A rising aggregate can conceal a broken local voice answer, while a falling click count can coexist with more unlinked mentions in generated responses.

    Start with one high-value question already connected to a customer action. Build its canonical answer unit, add truthful schema, reconcile any local records, and run the same intent across the platforms that matter to your audience. Once that answer survives extraction, contextual prompts, and spoken delivery, use the structure as a template for the next question. The scalable system is one reliable knowledge base with controlled platform adaptations, not a separate content calendar for every assistant.

    References