Tag: AI Adoption

  • How to Build an AI-Era Search Marketing Team and Career

    How to Build an AI-Era Search Marketing Team and Career

    If your search marketing role is described mainly as keyword lists, briefs, audits, drafts and reports, AI makes the job look easy to compress. That description leaves out the work a company still needs: choosing the right problem, setting an evidence standard, connecting search activity to customer outcomes and taking responsibility when automation is wrong.

    You do not need to predict what every model will do next. You need an operating model that can absorb changing capabilities without surrendering judgment. The framework below will help you redesign roles, decide which workflows deserve automation, protect the entry-level career ladder and show that your own value extends beyond producing deliverables.

    Move your value from production volume to controlled decisions

    AI can reduce routine production and create more room for strategy, creativity, testing and optimization. That does not automatically make a team more strategic. A team can use the time it saves to produce more low-value pages, reports and variants. The career advantage belongs to the marketer who can decide what should be produced, what should be rejected and what evidence would justify the next action.

    Start by auditing recurring work according to risk and judgment, not according to how impressive the tool demonstration looks. For each workflow, answer these questions:

    • Consequence: What happens if the output is wrong? A weak title suggestion and an incorrect crawl directive do not belong in the same risk class.
    • Detectability: Will a person or automated check catch the error before customers, search systems or advertising platforms encounter it?
    • Reversibility: Can the team undo the action cleanly, or could it affect indexing, tracking, customer trust or media spend?
    • Context dependence: Does success depend on unstated brand, product, legal or customer knowledge?
    • Accountability: Which named person owns the outcome after AI has contributed to it?

    Those answers lead to four useful classifications. Keep high-consequence decisions human-owned. Use AI to assist work that needs context but benefits from faster analysis or drafting. Delegate repetitive, reversible actions that have reliable checks. Stop work that exists only because an old process required it.

    The last category matters. Automating a report nobody uses does not create leverage; it preserves waste at a lower unit cost. Before automating anything, identify the decision the output is supposed to change. If no one can name that decision, remove or redesign the output.

    Your durable career assets are therefore problem framing, evidence evaluation, experimentation, technical judgment and cross-functional influence. Tool fluency still matters, but it should support those abilities. Knowing how to generate a draft is less valuable than knowing why the draft should exist, which claims it may make, how it will be checked and what result would cause you to revise the strategy.

    Give humans and AI explicit responsibilities at every handoff
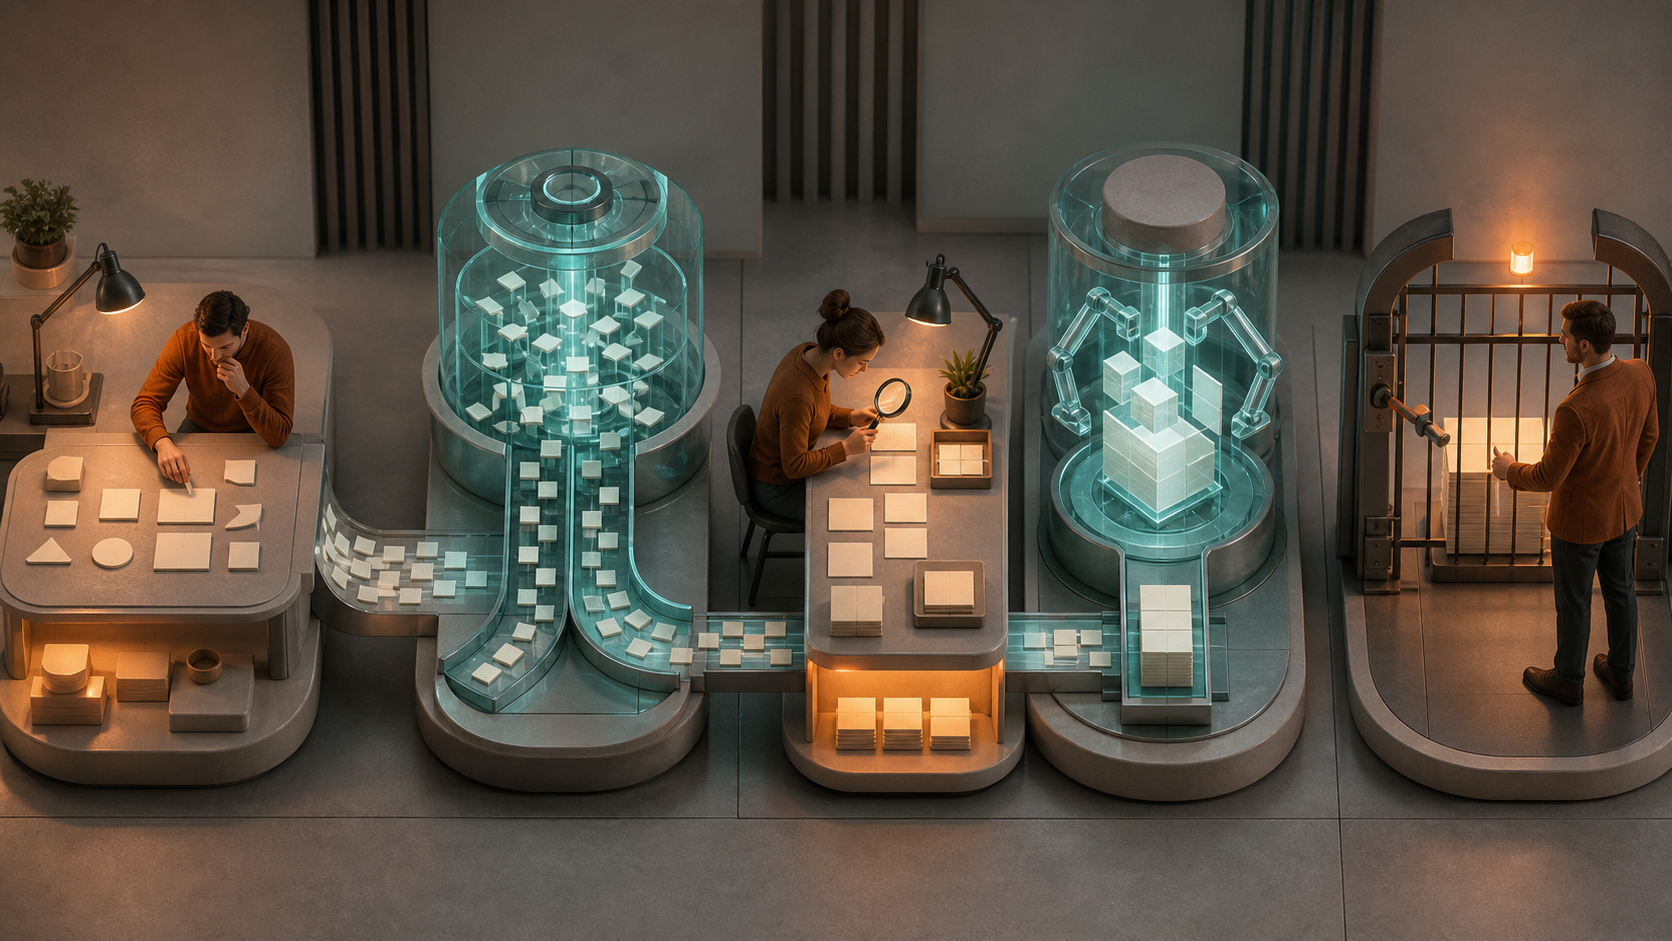
    Five connected workstations show people defining, checking, and approving work while translucent machines sort and assemble abstract components between them.

    Calling AI a teammate is only useful when the team defines its authority. AI can contribute to activities such as quality assurance, translation and performance alerts, but those capabilities do not answer who approves a claim, resolves conflicting signals or accepts business risk.

    Map the search workflow as a sequence of accountable handoffs. A practical division of work looks like this:

    Workflow stageHuman accountabilityUseful AI contributionRelease condition
    Opportunity selectionChoose the customer problem, business objective and acceptable trade-offsGroup inputs, identify patterns and surface gaps for reviewA named owner approves the objective and priority
    Brief developmentDefine intent, audience, required evidence, exclusions and success criteriaOrganize approved inputs and propose structures or variantsThe brief states what must be true, not merely what must be written
    ProductionOwn claims, brand meaning and final editorial judgmentDraft, transform, classify or adapt material within the briefEvery substantive claim can be checked against an approved input
    Search and schema validationDecide whether the page and markup accurately represent the visible subjectFlag omissions, inconsistencies, broken links or mismatched fieldsTechnical checks pass and a person reviews consequential changes
    PublicationAuthorize changes that affect users, indexing, tracking or spendExecute approved, logged and reversible stepsThe team has an owner, a record of the change and a rollback path
    MonitoringInterpret performance in business and market contextWatch defined signals, detect anomalies and prepare alertsAn alert identifies the expected response and the person responsible

    Then assign an autonomy level to each workflow. At the lowest level, AI proposes and a person executes. At the next level, AI can execute a pre-approved, reversible action after human review. At a higher level, an agent can complete a sequence of permitted actions inside defined boundaries, while logging its work and escalating exceptions.

    Do not promote a workflow to greater autonomy merely because it worked once. Require representative test cases, known failure categories, an approval boundary, an observable activity log and a tested recovery procedure. The accountable person must also be able to explain the system without relying on the person who originally configured it.

    This is where standard operating procedures become more important, not less. Record the trigger, required inputs, permitted actions, prohibited actions, expected output, evaluation method, escalation condition and rollback procedure. Also record which model, tool configuration and knowledge inputs were used. Without that context, the team cannot distinguish a genuine strategy change from a system change.

    Rebuild the junior career ladder around supervised judgment
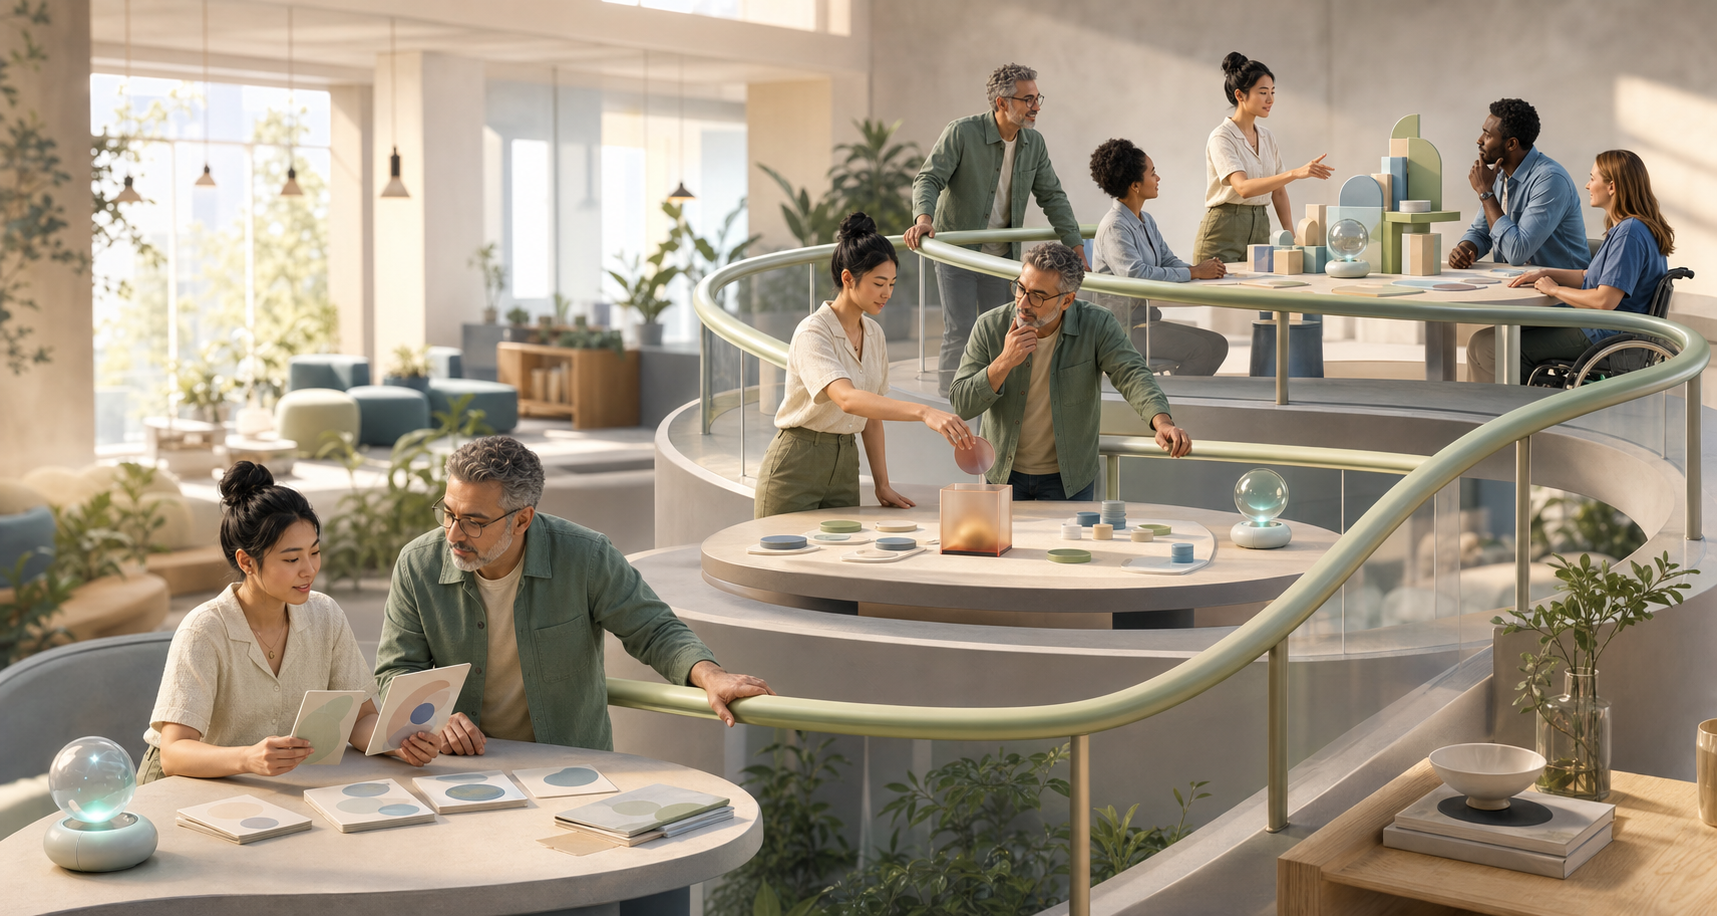
    A junior professional progresses through three supervised work platforms, reviewing generated cards, checking evidence pieces, and presenting a completed model to colleagues.

    Entry-level search marketers have traditionally learned through repetitive work: collecting queries, checking pages, preparing reports, writing first drafts and applying routine changes. Automating that work can free capacity, but removing it without a replacement also removes the practice through which people learn to notice errors.

    The answer is not to preserve repetitive work for its own sake. Redesign it as supervised judgment. A junior marketer should learn to inspect AI output, identify why it fails, correct it, improve the workflow and eventually own the result. That prepares them for a role in which early-career marketers may increasingly coordinate AI systems as part of their daily work.

    A useful development sequence is:

    • Observe: Compare an output with the brief and label defects rather than merely accepting or rejecting it.
    • Correct: Repair factual, editorial, technical and intent-related problems while documenting why the correction matters.
    • Control: Write the instructions, checks and escalation rules that prevent the same defect from recurring.
    • Own: Run the workflow, interpret its results and recommend whether it should be expanded, revised or retired.

    Managers need a common review rubric so feedback does not collapse into personal preference. Evaluate user-intent fit, factual support, entity clarity, technical validity, consistency with visible content and connection to the intended business decision. For structured data, for example, syntactically valid markup is not enough; the markup must describe what the page actually presents. For an AI-assisted content brief, fluent prose is not enough; the brief must preserve approved claims, constraints and audience needs.

    Give junior employees access to the reasoning behind senior decisions. A completed audit shows the answer, but an annotated audit shows why one issue was prioritized and another was deferred. A final content page shows the outcome, but a decision log exposes the trade-offs. This creates institutional memory that remains useful when team members, tools or models change.

    Promotion criteria should follow the same shift. Do not reward someone solely for producing more artifacts with AI. Reward the ability to reduce preventable defects, improve a repeatable process, explain uncertainty, escalate appropriately and connect work to a meaningful outcome. That is how you avoid creating a team of fast operators who cannot function when the system encounters an exception.

    Make remote AI operations legible instead of meeting-heavy

    Distributed search teams already depend on written context. AI increases that dependency because people now need to understand not only what colleagues decided, but also what an automated system saw, produced and changed.

    Begin with an honest distinction between remote-first and remote-friendly work. A remote-first team expects decisions and collaboration to work virtually. A remote-friendly employer permits remote work but may still place important conversations, access or advancement around an office. State which one you operate, along with location limits, expected overlap hours, response expectations and genuine offline boundaries.

    If you are hiring, test the behaviors the job requires. Give the candidate an imperfect AI-assisted deliverable and ask them to identify defects, missing context and risky assumptions. Ask which questions they would raise before acting. A candidate who can explain a cautious decision is showing more relevant ability than one who produces a polished answer without exposing its basis.

    If you are considering a role, ask where decisions are recorded, which working hours require overlap, who approves automated changes and how remote employees receive feedback. These questions reveal whether the company has an operating system or merely a collection of tools and meetings.

    Onboarding should cover the first week through 90 days, with access, training, supervised delivery and eventual workflow ownership made explicit. A new employee should know where to find:

    • Team responsibilities, escalation contacts and approval boundaries.
    • Workflow instructions, examples of acceptable output and known failure modes.
    • Approved tools, model configurations, data-handling rules and security practices.
    • Decision logs, experiment records and explanations of previous changes.
    • Definitions for business, search, content and quality metrics.
    • Feedback channels and the expected response when an automation fails.

    Keep credentials, private customer information and other sensitive data out of prompts and shared workflow documents unless an approved system and access policy explicitly permit their use. Convenience is not a substitute for data governance.

    Use meetings for disagreement, prioritization, coaching and decisions that need synchronous discussion. Put status, routine approvals and reusable explanations into shared systems. Every consequential meeting should leave behind a decision, an owner and the context needed by someone who was not present. That makes the team easier for both people and controlled automation to support.

    Use a 90-day transition to prove one workflow before scaling

    A team-wide AI transformation is too vague to manage. Use a 90-day horizon and choose a single recurring workflow with a limited blast radius, clear review criteria and a reversible outcome. Good candidates assist research organization, brief preparation, quality checks or anomaly detection. Poor first candidates automatically publish pages, alter crawl controls, change redirects or spend advertising budget; an error in those workflows can reach users or affect revenue before the team understands the failure.

    Run the transition in four parts:

    1. Inventory during the first week. Record the current trigger, inputs, handoffs, completion time, defect categories and decision the workflow supports. Separate necessary human judgment from repetitive handling.
    2. Pilot under supervision. Define approved inputs, prohibited actions, evaluation examples, review gates and stop conditions. Name the person who owns the business outcome, not merely the person configuring the tool.
    3. Harden the workflow. Add activity logging, exception handling, permission limits, version records, documentation and a recovery procedure. Train another team member to operate and challenge the workflow.
    4. Decide by day 90. Compare the result with the original process. Scale it only if quality is acceptable, failures are detectable, the saved effort is being redirected to higher-value work and the accountable owner can explain its operation. Otherwise revise or retire it.

    Update roles and performance reviews as part of that decision. The owner of the workflow should be evaluated on its outcome, quality and controls, not on the volume it generates. Managers should also track whether the system creates new capability across the team or concentrates knowledge in one operator.

    If you are building your own career, turn the pilot into a portfolio artifact without exposing proprietary information. Show the original problem, risk classification, human and AI responsibilities, evaluation rubric, failure discovered, control added and decision to scale or stop. On a resume, describe the business or workflow outcome and your accountable decision. Naming an AI tool without explaining what you governed proves very little.

    Key takeaways

    • Build your career around judgment, evidence, experimentation and accountability rather than the volume of assets you can produce.
    • Assign every AI-assisted workflow a human owner, an authority boundary, a release condition and a recovery path.
    • Replace repetitive junior work with structured practice in detecting, correcting and preventing defects.
    • Make remote operations explicit through written decisions, shared documentation, clear overlap expectations and visible feedback.
    • Prove a low-consequence, reversible workflow before granting AI greater autonomy or expanding it across the team.

    Your next move can be small. Map one recurring workflow, name the decision it supports and mark the point where human accountability must remain. That single map will tell you which work to automate, which skill to develop and which part of the team’s operating model needs attention first.
    References

  • AI Search Adoption, Referrals and Customer Journey Tracking

    AI Search Adoption, Referrals and Customer Journey Tracking

    Your analytics may show almost no traffic from AI assistants even when buyers are using them to define their problem, compare options and build a shortlist. The reverse can happen too: an AI referral can reach your site without becoming a qualified customer.

    If you are deciding whether AI search deserves time and budget, referral sessions alone will mislead you. You need an evidence chain that separates market adoption, answer visibility, identifiable visits, assisted influence and commercial outcomes.

    Adoption, visibility, referrals and revenue answer different questions

    AI search reporting becomes confusing when unlike metrics share one chart. Active-user growth and referral leadership are separate measures. A widely used platform may send little identifiable traffic to your site, while a smaller platform may produce a more noticeable referral stream.

    The same discipline applies to market reports. Use statistics about user behavior, LLM adoption and industry forecasts to form hypotheses about where discovery is moving. Do not treat them as evidence that your audience uses a particular platform or that its traffic will convert.

    Measurement layerQuestion it answersUseful evidenceWhat it cannot prove
    AdoptionAre people using this platform or search experience?Platform usage data, market reports and direct customer researchThat your brand is visible or that users will visit your site
    VisibilityDoes your brand appear for relevant questions?Mentions, citations and links across a controlled prompt setThat the appearance influenced a purchase
    ReferralDid a recognizable AI surface send a visit?Referrer data, landing pages and session-level eventsZero-click exposure or a later direct or branded visit
    Qualified outcomeDid the visit produce a meaningful action?Qualified leads, trials, purchases, bookings or other defined conversionsRevenue until the outcome has matured
    Commercial impactDid AI-related activity contribute to business value?Opportunities, pipeline, revenue, retention and closed-won outcomesThe precise contribution of AI when several touches shaped the decision

    Name the layer whenever you report a result. Say “recognized AI referral sessions,” not “AI performance.” Say “brand mentions in our tracked prompts,” not “AI market share.” This prevents a top-of-funnel signal from being mistaken for revenue.

    Every rate also needs a visible numerator and denominator. A referral conversion rate should mean qualified conversions divided by recognized AI referral sessions. Visibility coverage should mean prompts in which the brand appeared divided by prompts tested. If the underlying counts are small, show them beside the percentage; otherwise one visit or one deal can create a dramatic but fragile change.

    The AI-influenced journey rarely fits a last-click report

    A buyer is surrounded by connected AI, content, peer, website and sales touchpoints arranged in a looping journey.

    AI can shape discovery, decision-making and loyalty, not just the moment before a click. A useful journey map therefore starts before the website session and continues after the initial conversion.

    1. Problem recognition: The buyer asks what is causing a problem, whether it matters and what kind of solution exists.
    2. Category discovery: The buyer requests approaches, products, providers or a shortlist that fits stated constraints.
    3. Evaluation: Follow-up questions test features, tradeoffs, pricing logic, integrations, risks and suitability.
    4. Validation: The buyer visits websites, checks evidence, searches for the brand and verifies details supplied by the answer.
    5. Conversion: The buyer purchases, signs up, books, applies or starts a sales conversation.
    6. Experience and loyalty: The customer returns to AI or search for setup, support, troubleshooting, renewal and adjacent needs.

    A buyer can move through several of those stages inside one conversation. Clicks, search refinements and feedback can help AI systems adapt their results, so the follow-up question matters as much as the opening prompt. Content that answers only a broad category question may earn awareness but disappear when the buyer asks about implementation constraints.

    The surfaces also overlap. ChatGPT, Perplexity and Gemini can introduce or evaluate brands, while Google’s AI Mode brings an AI-mediated experience into Google search. A reporting model that defines everything from Google as traditional search and everything else as AI will miss that convergence.

    A recognizable referral is only one observable path. An AI answer may influence a buyer who later types your URL, searches your brand, responds to an ad or talks to a salesperson. Standard last-click reporting will credit that later touch. That does not justify relabeling every direct or branded visit as AI-assisted; it means you need another evidence layer.

    Add a short, optional discovery question to high-value forms and sales qualification: “Where did you first hear about us?” Include AI assistant as a distinct choice alongside search engine, social media, colleague, publication, event and other relevant channels. Follow it with an optional free-text question such as “What were you trying to find out?” Preserve the original response in your CRM. Use it as evidence of influence, not as a replacement for behavioral analytics.

    Build a measurement chain from prompt to closed outcome

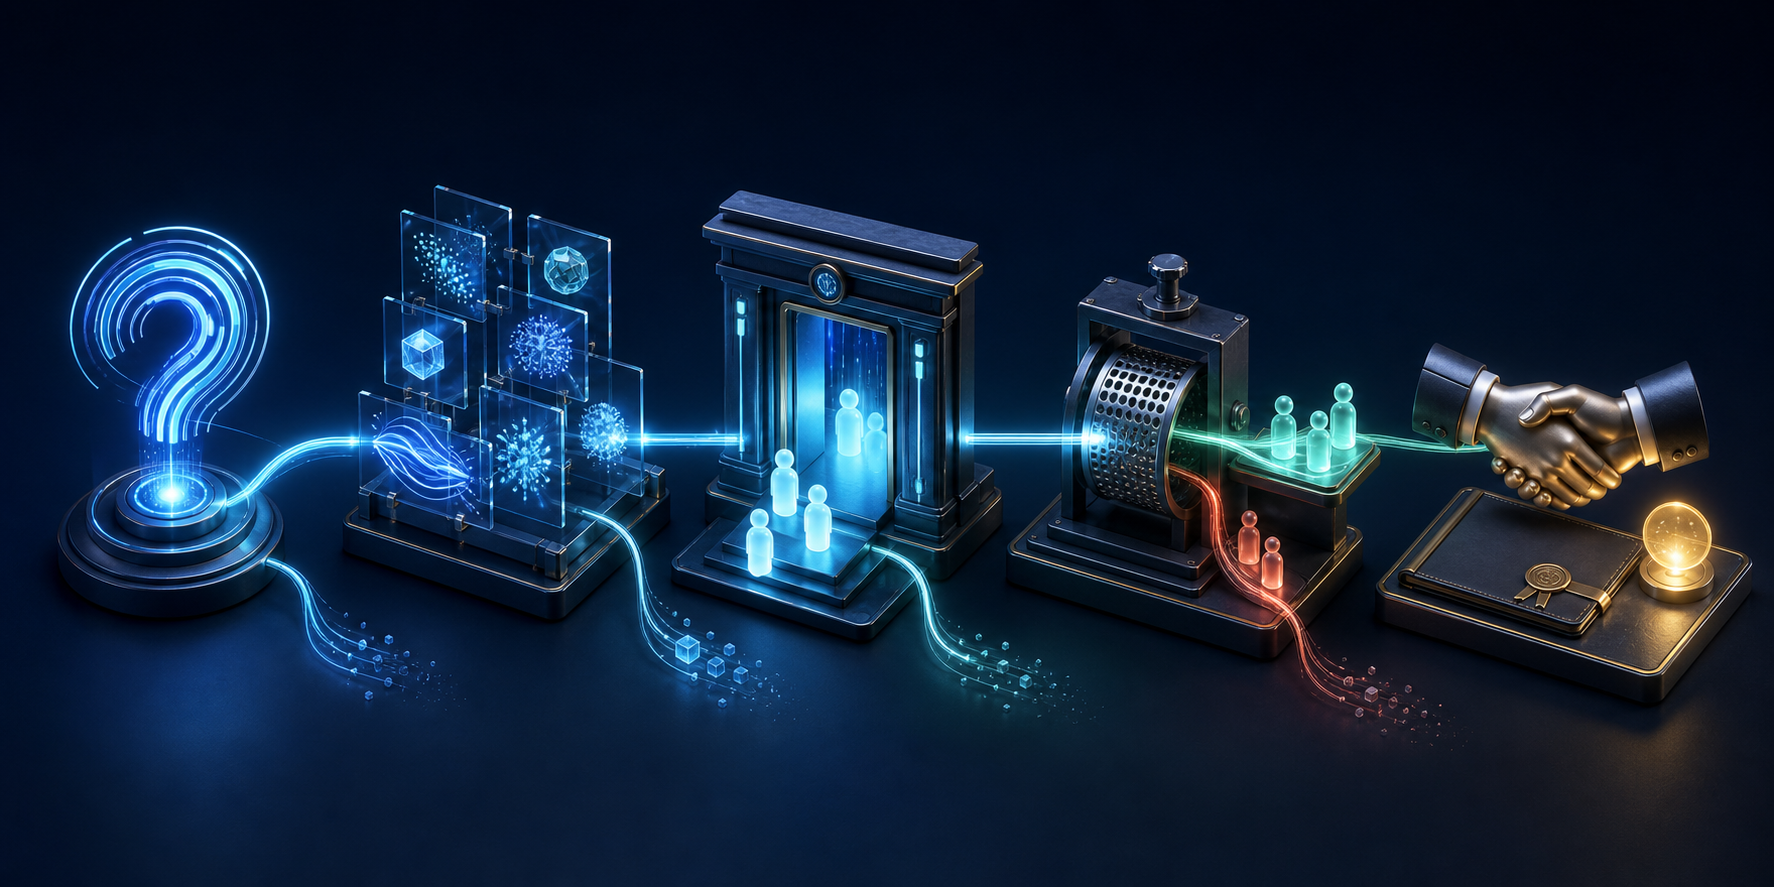
    A luminous thread connects an abstract AI question, answer panels, website visits, lead qualification and a completed business agreement.

    You do not need perfect attribution before you can make a better decision. You need consistent definitions and enough connection between discovery, visit and outcome to see where the chain breaks.

    1. Choose the business outcome first. Define the action that matters: a qualified lead, completed purchase, activated account, booked appointment or another outcome your team already recognizes. Do not create an easier AI-only conversion definition.
    2. Define the surfaces in scope. Name the assistants and AI-enabled search experiences you will monitor. ChatGPT, Perplexity, Gemini and Google AI Mode are valid starting points when they match your audience, but the list should come from customer behavior rather than platform publicity.
    3. Create a fixed prompt library. We’d start with 30 prompts split across problem recognition, category discovery, comparison, requirements and branded validation. Thirty is a manageable operating set, not a representative estimate of the entire market.
    4. Track recognizable referral traffic. Group known AI referrers in your analytics platform while preserving the raw source, landing page and conversion events. Keep this channel separate from organic search, direct and referral traffic so definitions do not drift between reports.
    5. Connect visits to downstream outcomes. Pass the relevant session or lead identifier into your CRM or commerce reporting. Measure qualification, opportunity creation, pipeline, purchases, revenue and closed outcomes with the same definitions and maturation windows used for other channels.
    6. Capture assisted influence. Combine voluntary discovery responses, sales notes and other documented customer evidence in a separate AI-influenced field. Never merge inferred influence into known referrals; report the two views side by side.

    Use a prompt log you can rerun

    For each prompt, record the exact wording, intended journey stage, audience, region, language, platform, date and any material session conditions. Then capture whether your brand appeared, whether it was linked or cited, which page was referenced, the surrounding claim, the competitors present and whether the answer represented your offer accurately.

    Do not quietly replace weak prompts with easier ones. Maintain a stable core set for trend comparison and a separate experimental set for newly discovered questions. If you change the platform, wording, geography or evaluation criteria, annotate the change so a methodology shift is not reported as a visibility gain.

    Keep one funnel, with clearly labeled AI signals

    • Prompt visibility coverage: tracked prompts with a brand appearance divided by prompts tested.
    • Linked visibility coverage: tracked prompts containing a link or citation to your domain divided by prompts tested.
    • Recognized AI referrals: sessions carrying a referrer that matches your documented AI channel rules.
    • AI referral qualification rate: qualified outcomes from those sessions divided by recognized AI referral sessions.
    • Known AI-sourced pipeline: opportunities and value attached to leads whose recorded source meets your AI referral definition.
    • Documented AI influence: outcomes with an explicit customer or sales signal showing that an AI tool contributed to discovery or evaluation.

    Lead volume is not the verdict. A comparison covering more than 117,000 leads examined pipeline quality and closed-won outcomes, which is the commercial layer your own analysis should reach. It does not give you permission to assume that AI referrals will outperform another channel in your business.

    Compare equivalent cohorts. A new AI referral cohort should not be judged on closed-won rate while an older organic cohort has had months to progress. Use the same qualification rules, sales stages and outcome windows. When counts remain low, inspect the individual journeys and report the uncertainty instead of declaring a winner.

    Match content to the next decision the buyer must make

    Measurement tells you where the gap is. Content should close that specific gap. Publishing more broad educational pages will not help if your brand appears during discovery but disappears when buyers ask who the product is for, what it integrates with or where its limits are.

    • For discovery: Give the problem and category a clear name. Answer the main question early, define necessary terms and explain the criteria a buyer should use to decide whether the category is relevant.
    • For evaluation: Publish concrete capabilities, requirements, tradeoffs, exclusions and implementation details. Organize comparisons around buyer criteria rather than unsupported claims of superiority.
    • For validation: Make authorship, evidence, update dates, policies, company identity and contact details easy to verify. Correct contradictions between product pages, documentation and third-party profiles.
    • For conversion: Align the landing page with the question that earned the visit. A buyer asking about compatibility should land on compatibility information with a relevant next step, not a generic homepage.
    • For retention: Keep setup instructions, troubleshooting, support policies and product facts current. AI-assisted customer journeys continue after acquisition, and inaccurate support information can damage trust as readily as an inaccurate recommendation.

    Use structured data to clarify content that already exists. Select the most specific applicable schema types, such as Organization, Product, Service, Article or FAQPage, and make sure the JSON-LD agrees with the visible page. Connect the correct entities and identifiers. Do not mark up claims, reviews, prices or FAQs that users cannot see, and do not treat valid markup as a guarantee that an AI system will mention or cite the page.

    Before publishing or refreshing a target page, ask five practical questions: Can a reader find the direct answer without decoding marketing language? Does the page say who the offer is and is not for? Are important claims supported on the page? Are names, attributes and relationships consistent across the site? Is the next action appropriate for the buyer’s current stage? A page that fails those checks is likely to create journey friction even if it earns a citation.

    Key takeaways: your first 12 weeks

    • Measure adoption, prompt visibility, referrals, qualified outcomes and commercial impact as separate layers.
    • Use external adoption data to choose where to investigate, then validate the choice with customer and first-party evidence.
    • Track a stable prompt set and a separate experimental set so methodology changes do not masquerade as performance changes.
    • Keep recognized AI referrals separate from documented AI influence throughout analytics and CRM reporting.
    • Judge traffic on qualification, pipeline and mature outcomes, not visits or lead counts alone.
    • Build or improve the page that answers the buyer’s next decision, then rerun the relevant prompts and inspect downstream behavior.

    We’d run the initial measurement system for 12 weeks. That is an operating window, not a universal performance benchmark. Establish definitions and a baseline in week zero, rerun the stable prompt set weekly, review referral and assisted-journey evidence every four weeks, and make the first allocation decision after week 12. If your sales cycle is longer, continue following the same cohorts until their outcomes are mature.

    Let the location of the break determine the next action. Low visibility calls for better question coverage and entity clarity. Visibility without visits calls for stronger citation-worthy detail, relevant landing pages and better influence capture. Visits without qualified outcomes call for a prompt-to-page alignment and conversion review. Qualified opportunities without mature revenue call for patience, not a premature channel verdict.

    Start by choosing one valuable journey, one defined outcome and one controlled prompt set. Once you can trace that chain honestly, you can expand the program without turning every unexplained customer touch into an AI success story.

    References