Tag: AI Adoption

  • Why I Stop Positioning AI as a People Replacement

    Why I Stop Positioning AI as a People Replacement

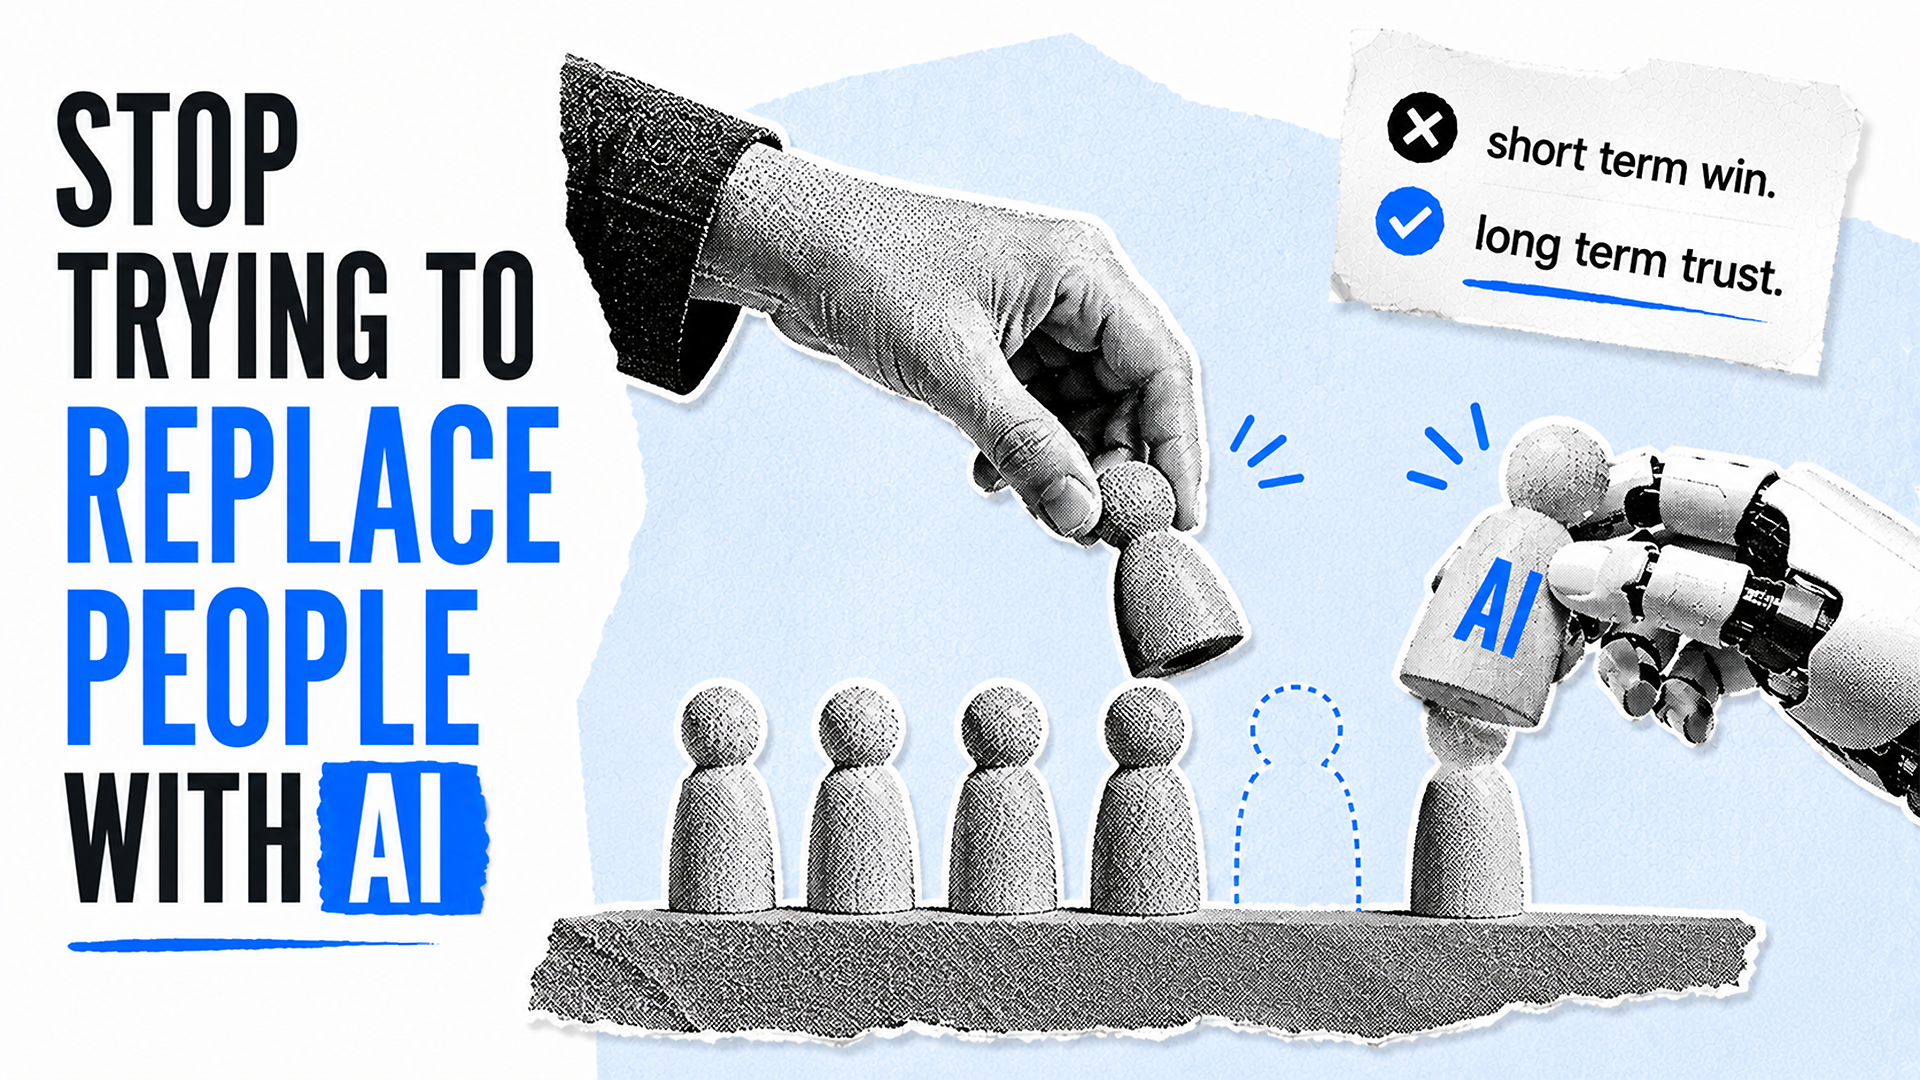
    I think one of the biggest mistakes in AI marketing is positioning a product as a replacement for people. That message can win attention in the short term, but I believe it quietly drains trust over time.

    This is a little different from what I usually write about, but it matters. The way we talk about AI shapes how customers, employees, executives, and markets respond to it.

    In this memo, I want to focus on three things: why “substitution positioning” feels powerful at first but weakens a brand later, what the data says about whether AI is actually replacing people, and how I think companies should position AI instead.
    Image

    The cardinal sin of positioning in the AI era is replacement. I call it substitution positioning. It is tempting because it sounds bold, efficient, and disruptive. But over time, it creates anxiety, skepticism, and credibility problems.

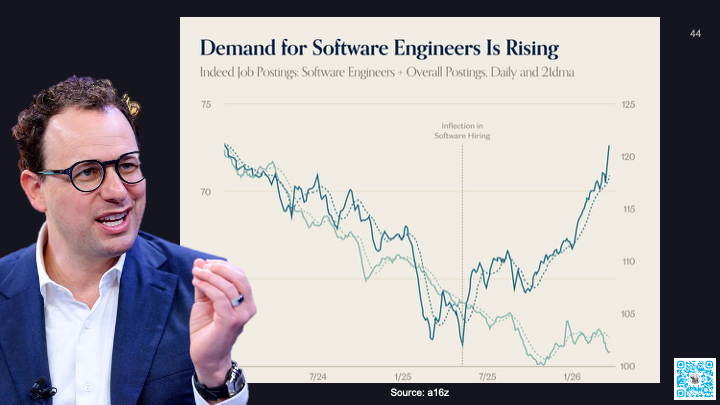
    We have seen this pattern already. Anthropic CEO Dario Amodei predicted that software engineering jobs could disappear within 6 to 12 months as models began doing most or all of what software engineers do end to end. Yet demand for software engineers has continued to look strong.
    Image

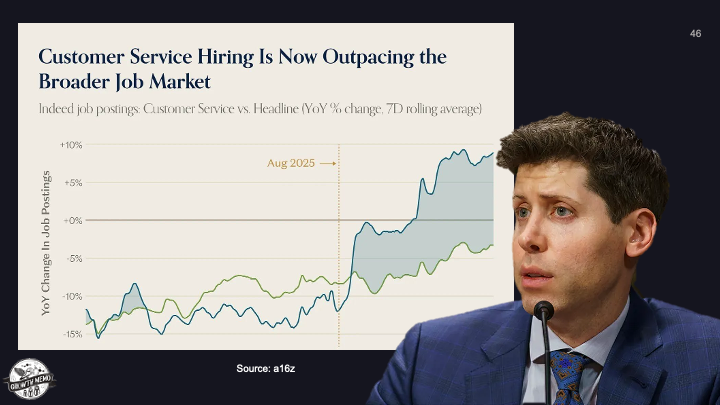
    OpenAI CEO Sam Altman also predicted that many customer support jobs would go away because AI could handle that work better. Soon after, customer service hiring began outpacing the broader job market.

    I understand why fear works as a marketing tool. The fear of being replaced gets attention fast. It got me, too. When powerful AI models gained traction, I worried about my own future. But when I still see AI companies hiring copywriters, SEOs, engineers, and support teams, I sleep better.
    Image

    Fear sells because it taps into fight-or-flight. Layoffs make that story even louder. They let companies frame cost-cutting as innovation and make the replacement narrative feel more real than it may actually be.

    But I do not think the facts support the clean replacement story. In New York, companies can indicate when mass layoffs are caused by technological innovation or automation. In one reported period, more than 160 companies filed mass layoffs affecting roughly 28,300 workers, and not one chose AI as the reason. That list included companies such as Amazon and Goldman Sachs.
    Image

    Researchers at Yale also studied employment data from the Current Population Survey over 33 months and found no evidence of job displacement from AI. To me, the pattern looks less like instant replacement and more like the earlier waves of computers and the internet changing how work gets done.

    That is why I keep coming back to this point: stop trying to make replacement happen. It is not happening in the simple, dramatic way many AI narratives suggest.
    Image

    AI is powerful, but it is also inconsistent. In its current form, it can do some tasks better than humans and fail badly at others. That paradox is often called the Jagged Frontier.

    The Jagged Frontier idea matters because it explains why some people see AI as transformative while others remain lukewarm. A BCG and Harvard study of 758 knowledge workers found that people get the most value from AI when they understand what it is good at and where it breaks down.
    Image

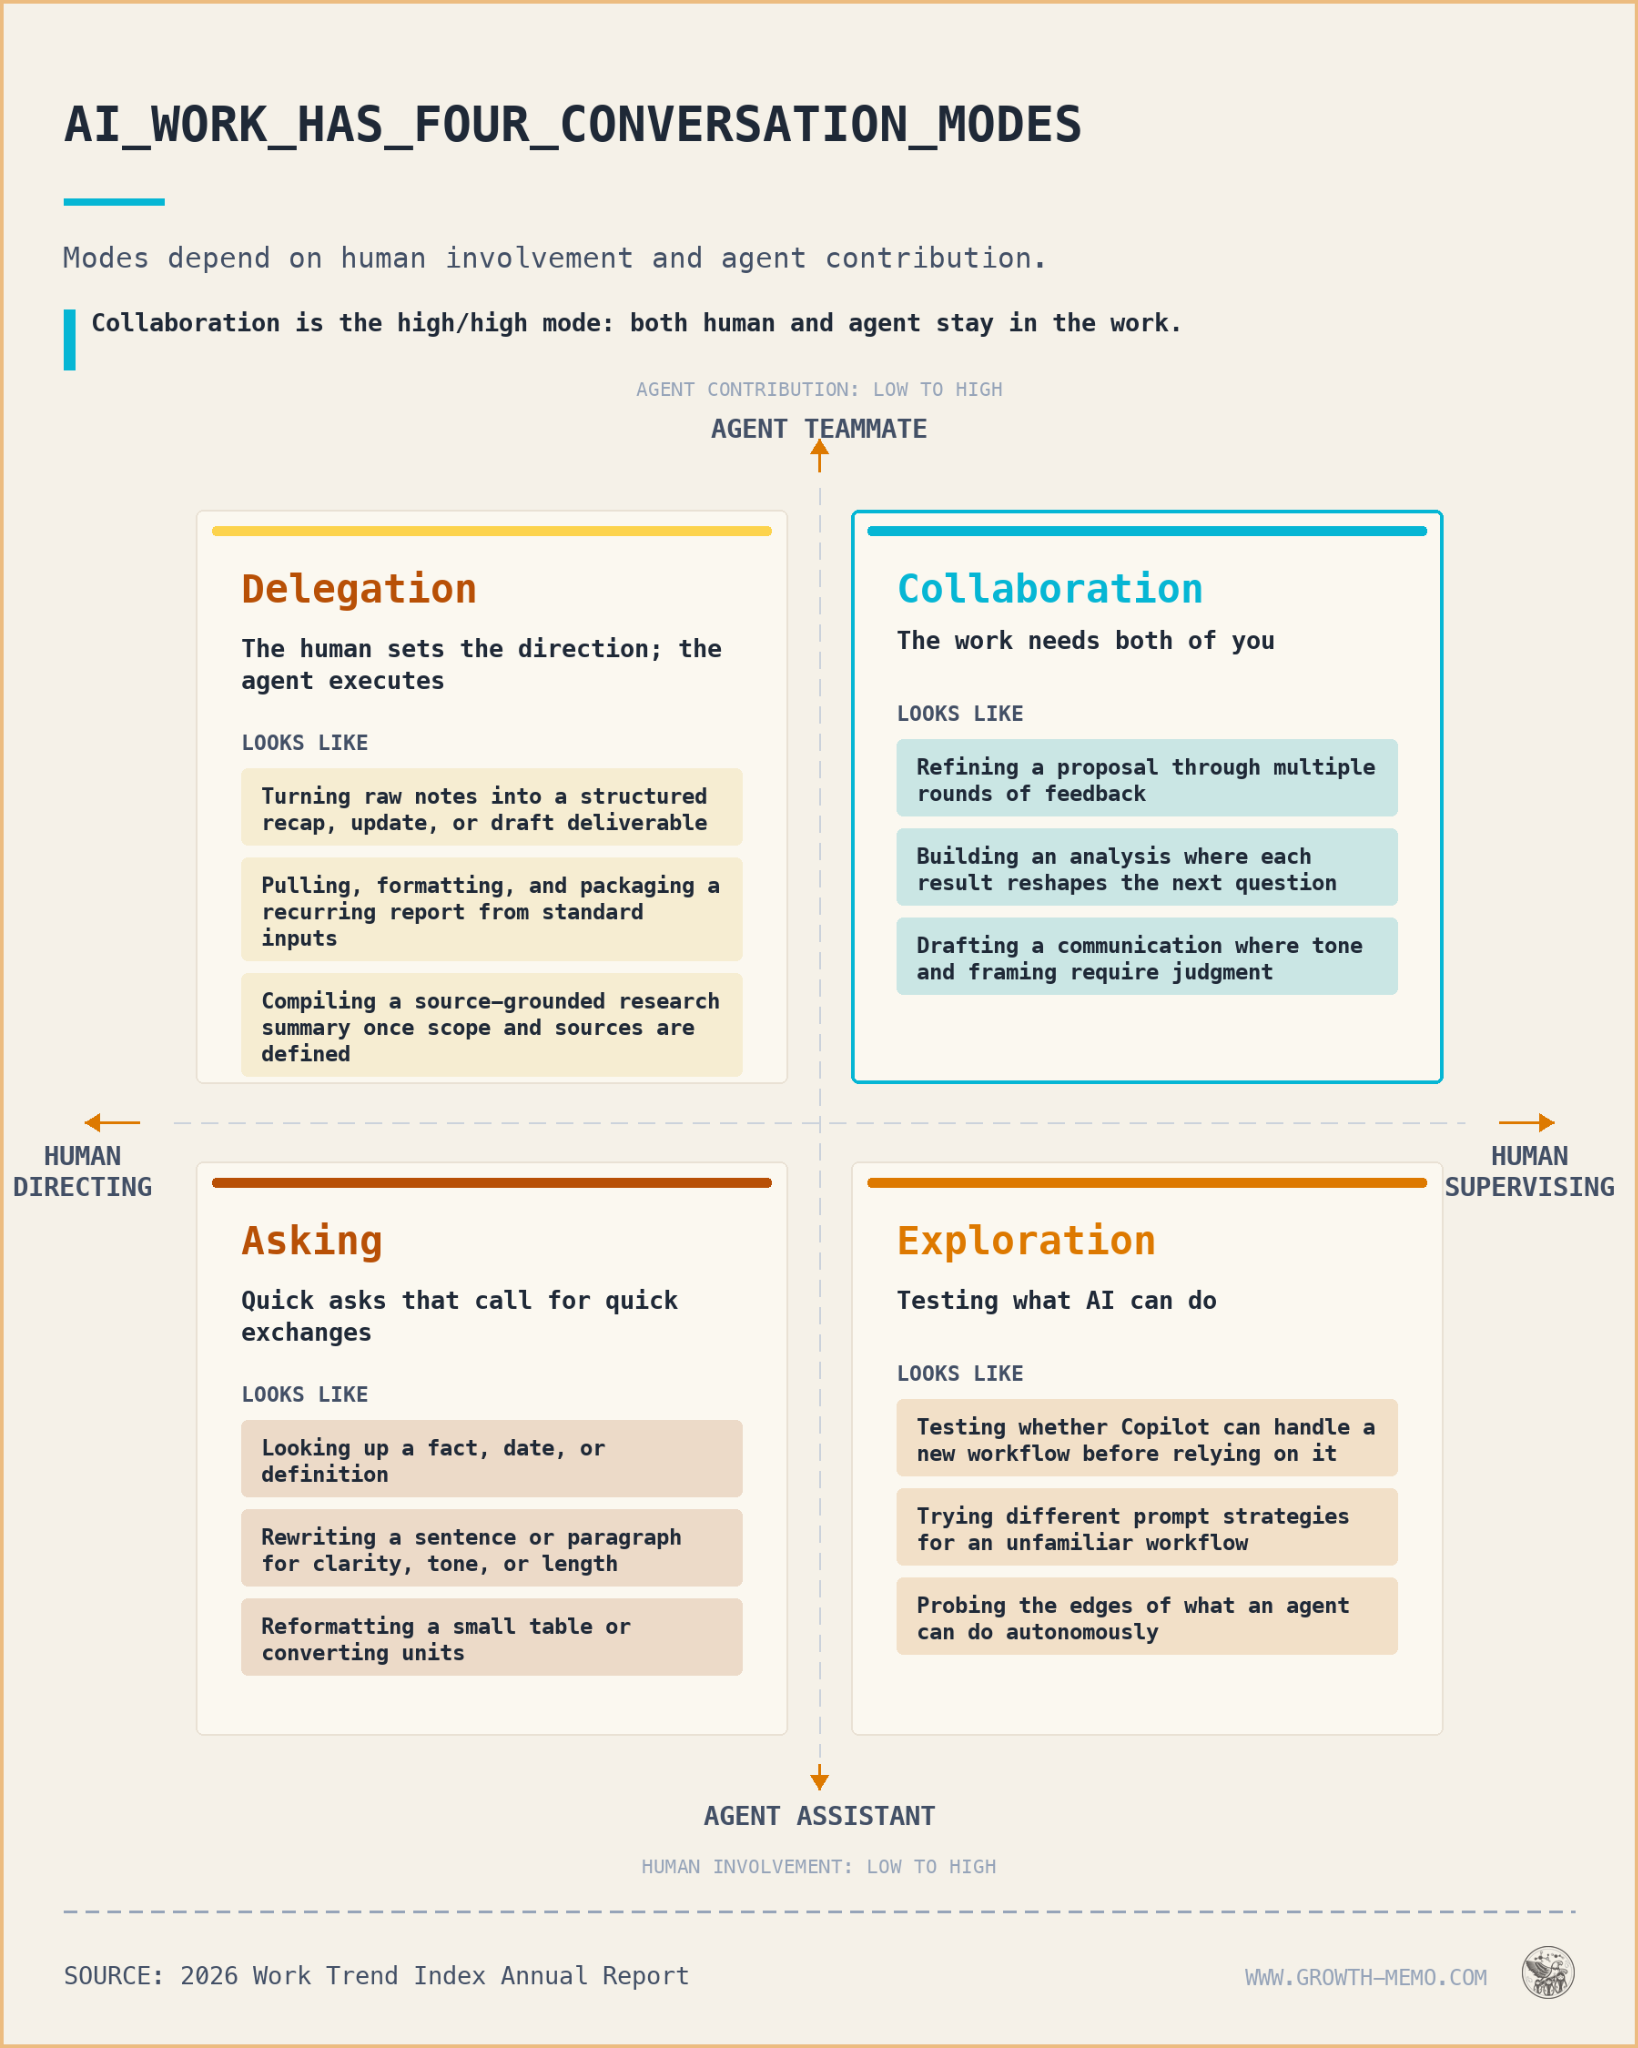
    Microsoft reached a similar conclusion in its 2026 Work Trend Index Annual Report. The company found that a small group of advanced AI users, described as Frontier Professionals, were not simply using AI more often. They also knew which mode of AI use fit each task.

    That distinction is important. The best AI users are not handing everything over blindly. They are applying judgment. They know when to use AI as a helper, when to use it as a collaborator, when to use agents for multi-step workflows, and when to keep a human firmly in control.
    Image

    I still do not trust most AI workflows enough to leave them running with no maintenance, review, or quality assurance. The question I ask is simple: would I bet my brand, customer experience, or revenue on a fully automated workflow with no human oversight?

    Klarna is a useful warning here. The company publicly promoted the idea that AI was doing the work of hundreds of agents and helping reduce headcount. Later, it reversed course and rehired humans after leadership acknowledged that aggressive cost-cutting had lowered quality and that customers still wanted a human option.
    Image

    That is the tradeoff I see with substitution positioning. It creates immediate attention, but it can damage long-term credibility. The words often do not match the operational reality.

    Replacement positioning could work if customers truly wanted full replacement and if the technology were consistently ready for it. I do not think either condition is true.
    Image

    Cost reduction is a strong AI argument because it shows up quickly on the P&L. Productivity gains usually take longer. They build inside companies over time and often take even longer to appear across the broader economy.

    But when replacement positioning goes beyond cost-cutting and becomes people-cutting, I believe it starts to antagonize the very people companies need to win over.
    Image

    We have already seen backlash. Duolingo’s AI-first memo drew heavy criticism before the company reframed AI as a tool to accelerate work rather than replace contractors. Surveys have found that some workers refuse to use AI tools because they fear job loss. Pew has reported that many U.S. adults are more concerned than excited about AI in daily life. Reuters/Ipsos polling has shown widespread fear that AI will permanently displace workers.

    There is also a quality problem. When employees believe the purpose of AI is to replace them, they may disengage or produce lower-quality work. In my view, that is not just an adoption issue. It is a positioning failure.

    Image

    Executives often feel more excited about AI than the employees asked to use it every day. That gap matters. If leadership talks about AI as a replacement engine, employees hear a threat. If leadership talks about AI as leverage, employees have a reason to learn.

    Token economics also complicate the replacement story. Some companies have bragged about massive AI usage, but token costs are still a real business variable. As those costs normalize, the math may make junior employees look interesting again, especially when human judgment, context, and accountability are part of the output.

    So what should replace replacement? I think the answer is enhancement. Instead of positioning AI as a way to remove people, I would position it as a way to make capable people more effective.

    AI can be used in two broad ways. A company can try to reduce the number of people, or it can grow output with the same number of people. The data I have seen suggests that productivity gains often create the stronger return.

    A National Bureau of Economic Research paper surveyed 750 executives about AI’s impact on productivity and labor markets. Larger firms showed more interest in replacing labor costs, but the highest ROI came from productivity growth.

    That is the lesson I take from the research: doing more with the talent you already have is often stronger than trying to remove the talent that knows what good work looks like.

    Building products has become easier, but distribution has not. When supply explodes, the scarce thing is not output. The scarce thing is being the product, brand, or service that actually gets chosen.

    That is why positioning matters more than ever. Product quality still matters, but the way I frame AI use can determine whether people see it as empowering or threatening.

    My takeaway is simple: I would stop selling AI as a people replacement. I would sell it as judgment leverage, workflow acceleration, and creative expansion. Fear can get attention, but empowerment is a better long-term strategy.

    This post first appeared on the author’s website and is republished here with permission.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • AI-Driven Marketing Transformation: A Practical Playbook

    AI-Driven Marketing Transformation: A Practical Playbook

    Your team may already have AI tools, prompt libraries, and a growing pile of experiments. Yet campaigns still wait for handoffs, content still gets trapped in review, and nobody can explain whether AI has improved a business outcome.

    That is the gap between adopting AI and transforming marketing with it. You close the gap by redesigning a small number of important workflows, preserving expert judgment, and measuring what becomes faster, better, or more visible.

    Key takeaways

    • Treat AI transformation as an operating-model change, not a software rollout.
    • Begin with a recurring workflow that has costly handoffs, usable inputs, and an outcome you already measure.
    • Assign AI the repetitive work while keeping named people responsible for claims, decisions, and publication.
    • For SEO, AEO, and GEO, improve the underlying content and entity signals before automating distribution.
    • Scale only after the workflow produces reliable gains under documented controls.

    Transform workflows before you transform job titles

    AI changes the economics of routine marketing work. A strategist can classify a large set of queries, a content lead can generate several structural options, and an analyst can turn raw results into a first-pass explanation without waiting for a specialist to complete every intermediate step.

    The useful idea behind positionless marketing is that work can move across traditional role boundaries when people have the right context and AI support. It does not mean expertise becomes unnecessary. It means specialists spend less time acting as queues for routine requests and more time setting standards, resolving ambiguity, and reviewing consequential decisions.

    Look at one current workflow and mark every place where work stops. For each stop, ask why it exists:

    • Missing information: Fix the intake form or data connection.
    • Routine transformation: Let AI summarize, classify, format, or generate a controlled draft.
    • Specialist judgment: Keep the decision with a qualified person and give that person better evidence.
    • Unclear ownership: Name one person who is accountable for the final outcome.
    • Habit: Remove the handoff if it no longer protects quality, compliance, or customer trust.

    This exercise prevents a common failure: inserting AI into an inefficient process and producing the same bottleneck at greater speed.

    Choose a first workflow with evidence, not enthusiasm

    A marketing operations lead compares several workflow paths and highlights one with repeated handoffs and approval bottlenecks.

    Your first use case should be important enough to matter and contained enough to inspect. Avoid choosing a task merely because a model can perform it in a demonstration. Choose a workflow where you can compare the new process with a credible baseline.

    Selection signalWhat a strong candidate looks likeReason to pause
    FrequencyThe team repeats the workflow often and follows a recognizable pattern.The task is rare, novel, or different every time.
    Input qualityThe necessary briefs, customer data, content, or performance records are accessible.Inputs are missing, contradictory, or prohibited from use.
    VerifiabilityA reviewer can check the output against defined requirements.Accuracy depends on hidden assumptions or unavailable evidence.
    Business connectionThe workflow influences a metric the team already monitors.The expected benefit is described only as producing more material.
    RiskMistakes can be caught before they affect customers or systems.An error could immediately create legal, financial, reputational, or security harm.

    A content-refresh workflow is often easier to evaluate than an autonomous campaign system. It has observable inputs, reviewable outputs, and a clear publication checkpoint. You can assess whether the revised page is more accurate, more complete, easier to extract answers from, and better aligned with real demand.

    Write a short pilot brief before configuring a tool. Name the workflow, its owner, the current baseline, the desired change, the allowed inputs, the approval requirement, and the condition that would stop the pilot. If you cannot fill in those fields, the use case is not ready.

    Build the workflow around human decisions

    A dependable AI workflow makes responsibility visible. A prompt alone is not a process, and a human somewhere in the loop is not a sufficient control. You need to specify what the system does, what a person decides, and what evidence the reviewer sees.

    1. Define the trigger. State what starts the workflow, such as a decline in qualified traffic, a new product release, or an approved campaign brief.
    2. Constrain the inputs. Identify the documents, datasets, brand rules, and page versions the system may use.
    3. Assign the machine task. Describe a bounded action such as clustering queries, finding unsupported claims, proposing headings, or drafting schema properties from approved page content.
    4. Name the human decision. Make one person responsible for validating intent, factual accuracy, positioning, and risk.
    5. Set the publication gate. Define what must be true before an output can reach a website, advertising account, customer, or external system.
    6. Capture the result. Record edits, rejected suggestions, performance changes, and failure patterns so the workflow can improve.

    For an SEO, AEO, or GEO refresh, the machine might collect relevant page material, map questions to existing passages, identify missing context, and draft clearer answers. The editor should confirm the search intent, verify every substantive claim, preserve the brand’s position, and decide whether the update deserves publication.

    Apply the same rule to JSON-LD. AI can help map visible facts into structured fields, but it should not invent awards, reviews, authorship, prices, availability, or other properties that the page and business records do not support. Structured data should describe the page accurately; it is not a place to add claims solely for machines.

    Measure transformation at the workflow and market levels

    Counting generated assets tells you how busy the system is. It does not tell you whether marketing improved. Use a scorecard that connects operational change to audience and business outcomes.

    • Workflow measures: Track elapsed time, rework, approval delays, cost, and the share of outputs that pass review.
    • Quality measures: Check factual accuracy, brand fit, completeness, originality, and compliance with the brief.
    • Search measures: Monitor whether important pages are crawlable, indexed where relevant, aligned with intended queries, and earning useful search visibility.
    • Answer-engine measures: Test whether priority questions receive accurate answers, whether your brand is represented correctly, and whether cited pages support the generated claims.
    • Business measures: Connect the workflow to qualified visits, leads, assisted conversions, retention, revenue, or another outcome your organization already trusts.

    Use a fixed evaluation set for AI visibility. Select questions that reflect actual customer needs across discovery, comparison, and decision stages. Run the same questions under consistent conditions, save the responses, and review representation as well as mentions. A brand citation is not useful if the surrounding answer is inaccurate or positions the company for the wrong problem.

    Do not promise that content, schema, or a particular publishing pattern will force inclusion in an AI-generated answer. These systems make their own retrieval and response decisions. Your controllable work is to publish accessible, specific, well-supported information; clarify entities and relationships; maintain consistency across owned properties; and measure how representation changes.

    Review the scorecard with the people who operate the workflow. If speed improves while corrections rise, narrow the machine’s task or strengthen the input. If quality improves but publication remains slow, inspect the approval path. If content output rises without a market result, stop rewarding volume and reconsider the use case.

    Scale only what you can govern and improve

    A marketing team oversees branching creative workflows controlled by review gates, guardrails, and feedback loops.

    Governance should live inside the workflow rather than in a policy document nobody consults. Give each production process an approved model or tool, data rules, an accountable owner, a review threshold, an audit trail, and a rollback path.

    • Separate public, internal, confidential, and restricted inputs before anyone sends data to a model.
    • Require stronger approval for customer-facing claims, regulated topics, pricing, legal language, and changes that execute automatically.
    • Store the prompt or instruction version, relevant inputs, output, reviewer, and final disposition when traceability matters.
    • Maintain examples of acceptable outputs and known failures so evaluation is based on shared standards.
    • Retest the workflow when the model, data connection, prompt, brand policy, or publishing system changes.
    • Keep a manual route available when the system is unavailable or its output cannot be verified.

    Then expand by capability, not by buying more tools. A reliable classification step can support content planning, lead routing, and feedback analysis, but each new workflow still needs its own inputs, reviewer, risk threshold, and outcome metric.

    Start with the workflow your team complains about most, provided its output can be checked before release. Map its delays, assign the decisions, and establish the scorecard before automating anything. When that process becomes measurably faster and more reliable, you will have an operating pattern worth extending.

    References

  • Enterprise AI Automation: A Practical Path to Production

    Enterprise AI Automation: A Practical Path to Production

    Your AI pilot probably does not need a smarter demo. It needs an accountable owner, a credible baseline, reliable data, permission boundaries, an escalation path, and a clear reason to exist after the demonstration ends.

    That is where many enterprise programs stall. In adoption data compiled through May 14, 2026, enterprises led at 25% adoption, but adoption covered everything from an initial trial to full-scale implementation. Among enterprise adopters, 62% remained in experimentation and only 13% had reached full deployment. If you are responsible for moving AI automation into production, the job is not to collect more use cases. It is to turn a carefully chosen workflow into a controlled, measurable operating process.

    Key takeaways

    • Fund a defined workflow with a business owner, not a broad AI capability looking for a problem.
    • Record the current cost, delay, error rate, conversion rate, or customer outcome before changing the process.
    • Favor workflows with stable triggers, accessible data, verifiable completion, bounded exceptions, and reversible actions.
    • Treat the model as one component. Production also requires permissions, deterministic rules, evaluations, monitoring, audit logs, human escalation, and rollback.
    • Set stage-gate criteria and stop conditions before the pilot begins. A project that cannot prove value should end without becoming permanent experimental infrastructure.

    Choose the first workflow by value and controllability

    Two operations leaders examine one illuminated, guardrailed process lane within a larger floor of branching workflows.

    Start below the level of a department. Customer service transformation is too broad. Qualifying an after-hours inquiry, answering approved questions, and offering an available appointment is a workflow. Supply chain optimization is too broad. Detecting a delayed shipment, checking an approved set of alternatives, and preparing a resolution for review is a workflow.

    This distinction matters because ordinary automation and agentic AI solve different parts of the process. A conventional automation follows predefined rules. Generative AI produces an output such as a summary or draft. An agentic system can plan, decide, and execute a multi-step task from beginning to end. More autonomy creates more ways to complete useful work, but it also expands the number of decisions, integrations, and failure modes you must control.

    A strong initial candidate has the following properties:

    • A visible operational leak: Work is being delayed, repeated, missed, or handled at an unnecessarily high cost.
    • A stable trigger: The workflow starts from a recognizable event such as an inbound request, completed meeting, status change, or new record.
    • Accessible inputs: The required data can be retrieved with appropriate permissions and has meanings the operating team agrees on.
    • A verifiable finish: You can tell whether the appointment was booked, case was resolved, package was sent, record was updated, or decision reached the right person.
    • Bounded exceptions: Unusual cases can be recognized and routed to a person instead of forcing the system to improvise.
    • Manageable consequences: A wrong draft can be reviewed or discarded. An unauthorized payment, deletion, price change, or legal commitment is much harder to reverse.
    • Enough recurring demand: The workflow occurs often enough for reduced handling time, faster response, or higher completion to matter.

    Score candidate workflows as high, medium, or low on each property. Do not average away a fatal weakness. Low data access, an undefined finish, or an unbounded consequence should block the candidate until the underlying process is redesigned.

    Structured processes tend to move first. Customer service and supply chain coordination show stronger agentic AI adoption, while finance faces more regulatory scrutiny. The practical lesson is not that every enterprise should begin in customer service. It is that repeatable inputs, explicit policies, and observable outcomes make automation easier to validate.

    A useful workflow can also be unglamorous. One documented PR automation locates a completed Zoom recording, creates a transcript, and prepares an email containing both for the journalist. It saves about 30 minutes per interview while shortening the handoff. The value comes from removing a specific delay, not from inventing a new communications platform.

    Apply the same discipline to the build-versus-buy decision. Existing software should handle commodity functions such as scheduling, transcription, telephony, CRM records, and routine orchestration when it meets your requirements. Custom development is easier to justify when the workflow depends on a proprietary process, distinctive formula, or exclusive data that is central to the business. Otherwise, concentrate engineering effort on integration, policy, evaluation, and observability rather than recreating a mature product category.

    Make the pilot prove a business case it cannot game

    Before selecting a model or vendor, write a testable operating hypothesis:

    By automating these defined steps for these eligible cases, we expect this business metric to move from its recorded baseline to an approved target, without worsening these guardrails, as measured in this system over this evaluation window.

    If the team cannot fill in each part, it is not ready to approve the pilot. A goal such as improve productivity leaves too much room to declare success after the fact. Reduce median handling time for eligible requests while maintaining resolution quality and escalation compliance can be measured.

    The measurement plan should separate five kinds of evidence:

    • Business outcome: Completed bookings, qualified opportunities, resolved cases, accepted deliverables, cycle time, recovered demand, or another result the operating owner already values.
    • Guardrail: Error severity, complaint rate, rework, policy violations, inappropriate messages, missed escalations, or another consequence that must not deteriorate.
    • Coverage: The share of incoming work that is actually eligible and processed. A system can perform well on a narrow subset without materially changing the operation.
    • Technical diagnostic: Extraction quality, classification quality, tool-call success, retrieval failures, latency, retries, and exception frequency. These explain performance but do not replace a business result.
    • Economics: Software, model usage, integration, monitoring, review labor, incident handling, and ongoing process ownership.

    Measure the baseline before the team sees pilot results. Otherwise, definitions tend to drift toward whatever the system can demonstrate. Specify which cases qualify, which are excluded, where each metric comes from, and who resolves disputed labels. When feasible, compare pilot cases with equivalent manually handled cases rather than assuming every change came from the automation.

    Do not count outputs as outcomes. Drafts generated, conversations handled, or tasks attempted are activity measures. They matter only when the workflow reaches a valid completion or produces verified capacity that the business can use. Time saved is not automatically a cash saving, either. State whether the capacity will absorb growth, reduce a queue, improve service, avoid new hiring, or be reassigned to higher-value work.

    Revenue automations need an additional capacity check. AI can help build targeted prospect lists, accelerate qualification, recover missed calls, and respond outside staffed hours, but increased demand can damage the customer experience when the business cannot fulfill it reliably. Map the next handoff before accelerating the top of the funnel. A faster response is not valuable if it creates an unstaffed queue downstream.

    Finally, define the stop rule while expectations are still neutral. Stop, narrow, or redesign the pilot if it cannot move the primary outcome, breaches an approved guardrail, depends on unsustainable review labor, or lacks a credible path to production economics. Unclear success criteria and weak data are recurring reasons AI projects fail to progress, while cost pressure is particularly important for smaller organizations. An enterprise budget may delay that reckoning, but it does not remove it.

    Build the operating system around the model

    A central AI computing unit is surrounded by data filters, permission gates, test chambers, monitoring equipment, audit storage, and human review stations.

    Separate deterministic rules from model judgment

    Map the workflow from trigger to completion before deciding what the model should do. For every step, record the input, rule or judgment, system of record, permitted action, expected output, exception path, and owner.

    Use ordinary code or workflow rules where the answer is deterministic. Required fields, account permissions, arithmetic, approved status transitions, duplicate checks, and routing tables should not become probabilistic merely because a language model is available. Use AI where interpretation is genuinely required, such as extracting intent from a message, summarizing an interaction, comparing unstructured evidence, or preparing a response under policy constraints.

    This separation makes failures easier to locate. It also reduces the chance that a persuasive output will bypass a rule the business intended to enforce.

    Increase authority only after the evidence supports it

    Autonomy should be an explicit permission level, not an accidental property of an integration. A practical authority ladder is:

    1. Read and recommend: The system analyzes data but cannot change a record or communicate externally.
    2. Prepare a draft: It creates a message, decision, or action package for a person to review.
    3. Execute after approval: A named reviewer authorizes the action with the relevant evidence visible.
    4. Execute within narrow limits: The system acts only for approved case types, values, destinations, and tools; exceptions are escalated.
    5. Execute the bounded workflow: The system completes eligible work autonomously while monitoring, audit, and shutdown controls remain active.

    Start at the lowest level that can test the business hypothesis. Advance only when the prior level meets predeclared quality and guardrail requirements. Full deployment does not require maximum autonomy. A stable draft-and-approval system can be the right production design when the action carries legal, financial, employment, security, reputational, or regulatory consequences.

    Use least-privilege credentials and separate test access from production access. Restrict the agent to the systems, records, fields, and actions required for the approved workflow. Payments, deletions, contractual commitments, price changes, sensitive employee decisions, and regulated communications should not become autonomous merely to remove a review step. If the business later approves that authority, it needs risk-specific testing, monitoring, and recovery controls.

    Make every handoff observable and recoverable

    A production trace should let an operator reconstruct what happened without relying on the model to explain itself. Capture the case identifier, input snapshot, relevant data version, workflow and prompt version, model and tool calls, retrieved evidence, proposed action, approval or override, external write, error, retry, elapsed time, unit cost, and final business outcome.

    Design retries so they do not duplicate a booking, order, message, refund, or record. Provide a clear shutdown control, queue failed work for recovery, and document how the operating team restores the last valid state. Alerts should identify an actionable condition and its owner; a dashboard that merely shows activity will not shorten an incident.

    Data readiness should be scoped to the workflow. You do not need to repair every enterprise dataset before beginning, but you do need a reliable contract for the fields this automation uses: canonical definitions, stable identifiers, permitted sources, freshness expectations, missing-value behavior, conflict resolution, and write-back ownership. Poor-quality and inconsistent data are common barriers to successful agent deployment. Giving an agent access to more systems does not solve disagreement between those systems.

    Build an evaluation set from representative normal cases, boundary cases, known exceptions, and costly failure modes. For each case, define an acceptable result, required escalation, and prohibited action. Run it before live access, compare the system with the existing process in shadow mode, and retain it as a regression suite whenever the prompt, model, tools, policy, or data mapping changes. Production monitoring then checks whether real traffic is drifting beyond what the evaluation set covered.

    Use stage gates to escape permanent pilot mode

    The large gap between experimentation and full deployment is a governance problem as much as a technical one. Teams can keep improving a demonstration indefinitely when nobody has defined the evidence required for the next decision. Gartner has projected that around 40% of agentic AI projects could be canceled by 2027. Cancellation is not necessarily the wrong outcome; discovering weak value or uncontrolled risk early is cheaper than scaling it.

    GateEvidence requiredDecision
    Workflow approvalNamed owner, process map, baseline, eligible cases, business hypothesis, risks, and stop ruleApprove a bounded test, redesign the workflow, or reject the use case
    Offline validationData contract, representative evaluation set, expected results, prohibited actions, permission design, and cost modelMove to shadow operation only if declared quality and safety requirements are met
    Shadow operationComparison with the existing process, exception analysis, reviewer feedback, diagnostic logs, and revised operating proceduresEnter limited production, narrow the scope, or return to offline work
    Limited productionVerified business outcome, guardrail performance, coverage, review burden, incident response, rollback, and actual unit costScale, maintain the bounded scope, redesign, or stop
    Operational scaleAccountable service owner, support model, change control, recurring evaluation, capacity plan, security review, and portfolio fundingExpand only while value and controls remain intact

    Set the thresholds for these gates according to the consequence of failure, and approve them before results arrive. A drafting assistant and a payment agent should not share the same tolerance. The important discipline is that the team cannot redefine success after seeing the output.

    At portfolio level, centralize the controls that should be consistent and decentralize ownership of the business outcome. A central AI function can provide identity, approved integrations, logging, evaluation tooling, security patterns, vendor review, and incident standards. The operating team should still own the process, metric, exceptions, staffing impact, and customer consequence. If ownership remains with an innovation lab after launch, the automation has not truly entered the business.

    Maintain a register of active automations showing the workflow owner, systems touched, data classification, permitted actions, risk level, deployment stage, model and vendor dependencies, current economics, and next gate. Use it to find duplicate experiments, unsupported integrations, and pilots that consume resources without approaching a decision.

    Before the next platform purchase, choose a specific queue or handoff that is already causing measurable loss. Name its owner, baseline, eligible cases, prohibited actions, escalation path, and stop rule. If those items cannot be written clearly, more AI will not make the process ready. If they can, you have the beginning of an automation that can earn its way into production.

    References

  • Professional vs. Consumer AI Adoption: What Marketers Should Do

    Professional vs. Consumer AI Adoption: What Marketers Should Do

    If AI seems unavoidable in your professional feed, it is easy to assume your customers have already moved their discovery and buying journeys into ChatGPT, Claude, or Gemini. That assumption can send budget toward the loudest channel rather than the audience you actually serve.

    The useful question is not whether AI is popular. It is which audience uses which assistant for which job, and whether that behavior affects discovery, evaluation, or purchase. Once you separate those questions, you can make a defensible AI search plan instead of reacting to general enthusiasm.

    Professional and consumer adoption are moving on different curves

    Broad reach and segment-level growth can move in opposite directions. At its measured high point, OpenAI or ChatGPT reached 37% of U.S. desktop users in September 2025, then slipped to 34% by March. That is a reach signal within a specific geography and device class. It does not mean 34% used the tool daily, preferred it over every alternative, or relied on it during a purchase.

    The professional pattern looks different. Claude usage among B2B professionals was 373% higher than the U.S. average, while Claude and Gemini continued to gain users as ChatGPT’s desktop growth slowed. The 373% figure describes relative overrepresentation. It is not a market-share percentage, and it does not prove that most professionals use Claude.

    Retail-shopping audiences provide the counterweight. People in that audience were 15% less likely to use ChatGPT than a typical U.S. consumer, and Claude did not rank among their top four AI tools. An AI-heavy professional network can therefore give you a distorted baseline for consumer behavior.

    This is not a clean split between people who use AI and people who do not. The same person can be a heavy assistant user at work and follow a conventional search, marketplace, or retailer journey when shopping. Adoption depends on context, task, and perceived value, not just demographics.

    Key takeaways

    • Do not apply one AI adoption rate to professional and consumer audiences.
    • Separate assistant reach, frequency of use, task relevance, brand visibility, and commercial impact. They are different measurements.
    • If you market to B2B professionals, include Claude alongside ChatGPT and Gemini in your visibility testing.
    • If you market to retail shoppers, keep search, category, product, marketplace, and on-site discovery paths strong while you test AI as an additional layer.
    • Increase investment only when audience use and a relevant business outcome appear in the same segment.

    Map adoption by audience and task before assigning budget

    A marketing team arranges audience, device, search, shopping, document, and AI symbols on an unlabeled strategy table connected by illuminated routes.

    A market-wide AI number cannot tell you where to publish, what to optimize, or which assistant deserves attention. Build an audience-by-task map instead. It should distinguish what has been observed from what still needs to be tested.

    AudienceObserved signalWhat it does not establishPlanning response
    Broad U.S. desktop usersOpenAI or ChatGPT moved from 37% reach in September 2025 to 34% by MarchFrequency, task, loyalty, mobile behavior, or purchase influenceMaintain a baseline presence, but do not forecast automatic growth from general awareness
    B2B professionalsClaude usage was 373% higher than the U.S. averageWhich roles, industries, or work tasks produced the differenceAdd Claude to role-specific discovery and evaluation tests
    Retail-shopping consumersChatGPT usage was 15% lower than among typical U.S. consumers; Claude was outside the top four AI toolsWhether AI influences an earlier research step or a later purchase decisionPreserve conventional shopping journeys and test assistants selectively

    Build the map before choosing a platform

    1. Define audiences by commercial context. Separate professional users, procurement participants, existing customers, retail shoppers, and other materially different groups. Do not merge them merely because they can buy the same product.
    2. Name the task. Record whether the person is trying to understand a problem, compare options, verify a claim, troubleshoot, create work, find a seller, or complete a purchase. A tool can be strong for one job and irrelevant to the next.
    3. Collect audience-level evidence. Combine AI referral analytics with customer interviews, sales and support language, on-site search terms, and a direct attribution question. Ask which tool was used and what the person was trying to accomplish; a yes-or-no question about AI is too broad.
    4. Label your confidence. Mark each audience-task-tool combination as observed, indicated, or unknown. A visible market trend can justify a test, but it should not be relabeled as proof about your customers.
    5. Assign an action. Scale combinations supported by audience and outcome evidence, test combinations with a plausible signal, and monitor combinations supported only by general market attention.

    The most common planning error is to start with a platform and look for reasons to fund it. Start with the audience and task instead. The platform should be the last column you fill in, not the first.

    Adjust SEO, AEO, and GEO priorities to match the pattern

    Adoption signals should change your priorities, not your technical standards. Pages still need to be crawlable, indexable, internally linked, consistent about named entities, and clear enough for a person to verify. Structured data must describe visible content accurately; it cannot compensate for a vague, unsupported, or inaccessible page.

    For professional audiences, optimize around decisions

    Where your audience resembles the measured B2B cohort, Claude belongs in the test set. That does not justify abandoning ChatGPT or Gemini. It means a ChatGPT-only visibility report can miss an assistant that is unusually prominent among professional users.

    • Give each important page a decision job. A page might explain compatibility, implementation requirements, operating constraints, use cases, or the difference between two approaches. Do not make one page answer every stage of the buying process.
    • Lead with a direct answer. Follow it with evidence, definitions, exceptions, and practical constraints. This gives human readers a fast answer while leaving enough context for an assistant to represent it accurately.
    • Keep entities unambiguous. Use consistent organization, product, feature, and category names in visible copy, titles, internal links, and applicable schema. If two names refer to the same thing, explain the relationship.
    • Test real professional questions. Run the questions your target roles ask through ChatGPT, Claude, and Gemini. Record whether your brand appears, whether the description is accurate, whether a citation is present, and which URL is surfaced.
    • Fix the underlying page before chasing mentions. If an assistant gives an incomplete answer, check whether your page actually states the missing fact clearly and supports it. Assistant-specific duplicate pages create more content to reconcile and can leave conflicting claims online.

    For consumer audiences, treat AI as an added path

    Lower ChatGPT incidence among retail shoppers and Claude’s absence from that audience’s top four do not make AI irrelevant. They do make an assistant-only discovery plan hard to defend. Keep the complete shopping journey usable without requiring an AI intermediary.

    • Protect category, product, marketplace, local, review, and on-site search paths that already help shoppers find and evaluate an offer.
    • Answer natural-language buying questions on the relevant category or product page instead of hiding useful details in promotional copy or disconnected FAQ pages.
    • Use applicable Product, Offer, or other structured data only when the corresponding information is visible, current, and internally consistent.
    • Test the assistants your audience actually mentions or sends traffic from. Do not give every platform equal budget merely because each one is growing somewhere.
    • Treat AI visibility as a supporting indicator until you can connect it to product discovery, qualified visits, assisted conversions, or purchases for that consumer segment.

    The useful distinction is not B2B equals AI and B2C equals conventional search. It is that professional adoption currently provides a stronger reason to test multiple assistants aggressively, while consumer planning needs more segment-specific proof before AI becomes the primary route.

    Measure adoption separately from visibility and revenue

    An analyst examines three separate transparent instruments containing usage tokens, discovery symbols, and purchase symbols connected by narrow pipes and valves.

    A single AI traffic chart cannot tell you whether customers are adopting assistants, whether assistants know your brand, or whether visibility changes business results. Track those questions in separate layers.

    • Audience use: Ask which assistants people use, for what tasks, and at which point in the journey. Preserve an open-text option so your questionnaire does not force respondents into your platform assumptions.
    • Referral behavior: Break AI-referred sessions down by assistant, landing page, audience, and outcome. Treat this as a floor rather than a complete adoption count: copied answers and manually entered URLs will not preserve an AI referrer.
    • Answer visibility: Maintain a fixed set of audience-specific questions. For each check, record the assistant, date, answer, brand inclusion, factual accuracy, cited URLs, and competitors mentioned. Prompt tracking samples outputs; it does not measure how many customers saw them.
    • Commercial outcomes: Connect identifiable AI visits and self-reported AI use to qualified leads, sign-ups, assisted conversions, purchases, or the outcome your organization already values. Do not label correlation as causation when several channels touched the journey.
    • Technical access: Use server logs and crawl diagnostics to confirm whether relevant bots can reach important pages. Bot activity shows technical access or crawler interest, not human demand.

    Use a simple decision rule. Scale when a defined audience uses an assistant for a relevant task, your visibility has a fixable gap, and improvement is associated with a qualified outcome. Run a contained test when audience and task are supported but commercial impact remains uncertain. Keep monitoring lightweight when the only evidence is broad market enthusiasm.

    For your next planning cycle, choose one high-value professional segment and one important consumer segment. Build separate audience-task maps, test the assistants indicated for each, and move the next content investment only where audience, task, and outcome align.

    References

  • How to Measure Realistic AI Productivity Gains at Work

    How to Measure Realistic AI Productivity Gains at Work

    An AI demo can collapse a visible task into a few prompts and still tell you almost nothing about productivity. The business question is whether the full workflow produces more accepted work, at the same or better quality, without quietly transferring effort to reviewers, managers, or downstream teams.

    If you need to set an AI target, evaluate a pilot, or defend an investment, measure the gain from the workflow boundary to the accepted result. That turns a promising time-saving claim into a decision you can trust.

    Key takeaways

    • A realistic AI productivity gain is net of preparation, prompting, review, correction, coordination, and failed outputs.
    • Measure labor per accepted output, not just generation time or the number of drafts produced.
    • Every percentage needs a named denominator, workflow boundary, baseline, and quality standard.
    • Released time becomes useful capacity only when the team can redirect it, remove a bottleneck, improve quality, or shorten delivery time.
    • Keep task efficiency, workflow efficiency, throughput, cost, and business value as separate claims.

    The usable gain is smaller than the visible time saving

    AI usually changes where work happens. Drafting may become quicker while context preparation, fact-checking, editing, escalation, and approval take more effort. A 25% efficiency gain can still matter, but its meaning depends on what became more efficient and whether the saved capacity survives the rest of the workflow.

    Separate the layers before you attach a productivity label:

    • Model speed: how quickly the system returns an output. This affects waiting time, but it is not a measure of human productivity by itself.
    • Task time: the active labor required for a bounded activity such as drafting metadata, classifying queries, or generating a first version of JSON-LD.
    • Workflow labor: all human effort from the request entering the process to the output passing its normal acceptance gate.
    • Accepted throughput: the amount of usable work completed within a defined period, after quality control and rework.
    • Business capacity: the additional work, faster delivery, lower operating burden, or higher quality the organization can actually use.

    Report the lowest layer you have genuinely measured. If your test covers only first-draft production, call the result a change in drafting time. Do not call it a change in content-team productivity. If you timed schema generation but excluded validation, page matching, deployment, and post-deployment checks, you measured generation rather than implementation.

    Use explicit calculations so hidden labor cannot disappear inside a headline:

    • Gross task saving equals baseline operator time minus AI-assisted operator time.
    • Net workflow saving equals gross task saving minus new preparation, review, correction, escalation, and coordination time.
    • Acceptance rate equals outputs passing the normal quality gate without material correction divided by outputs submitted for review.
    • Labor per accepted output equals total human labor across the workflow divided by the number of outputs that passed.
    • Cost per accepted output includes human labor, tooling, implementation, and rework rather than the AI subscription alone.

    The denominator matters as much as the result. Labor time per accepted brief, cost per validated schema deployment, and published pages per editor-hour are defined measures. AI productivity is not. It might refer to time, volume, cost, quality, or revenue, and those measures do not move in equal proportions.

    Measure the workflow, not the impressive task

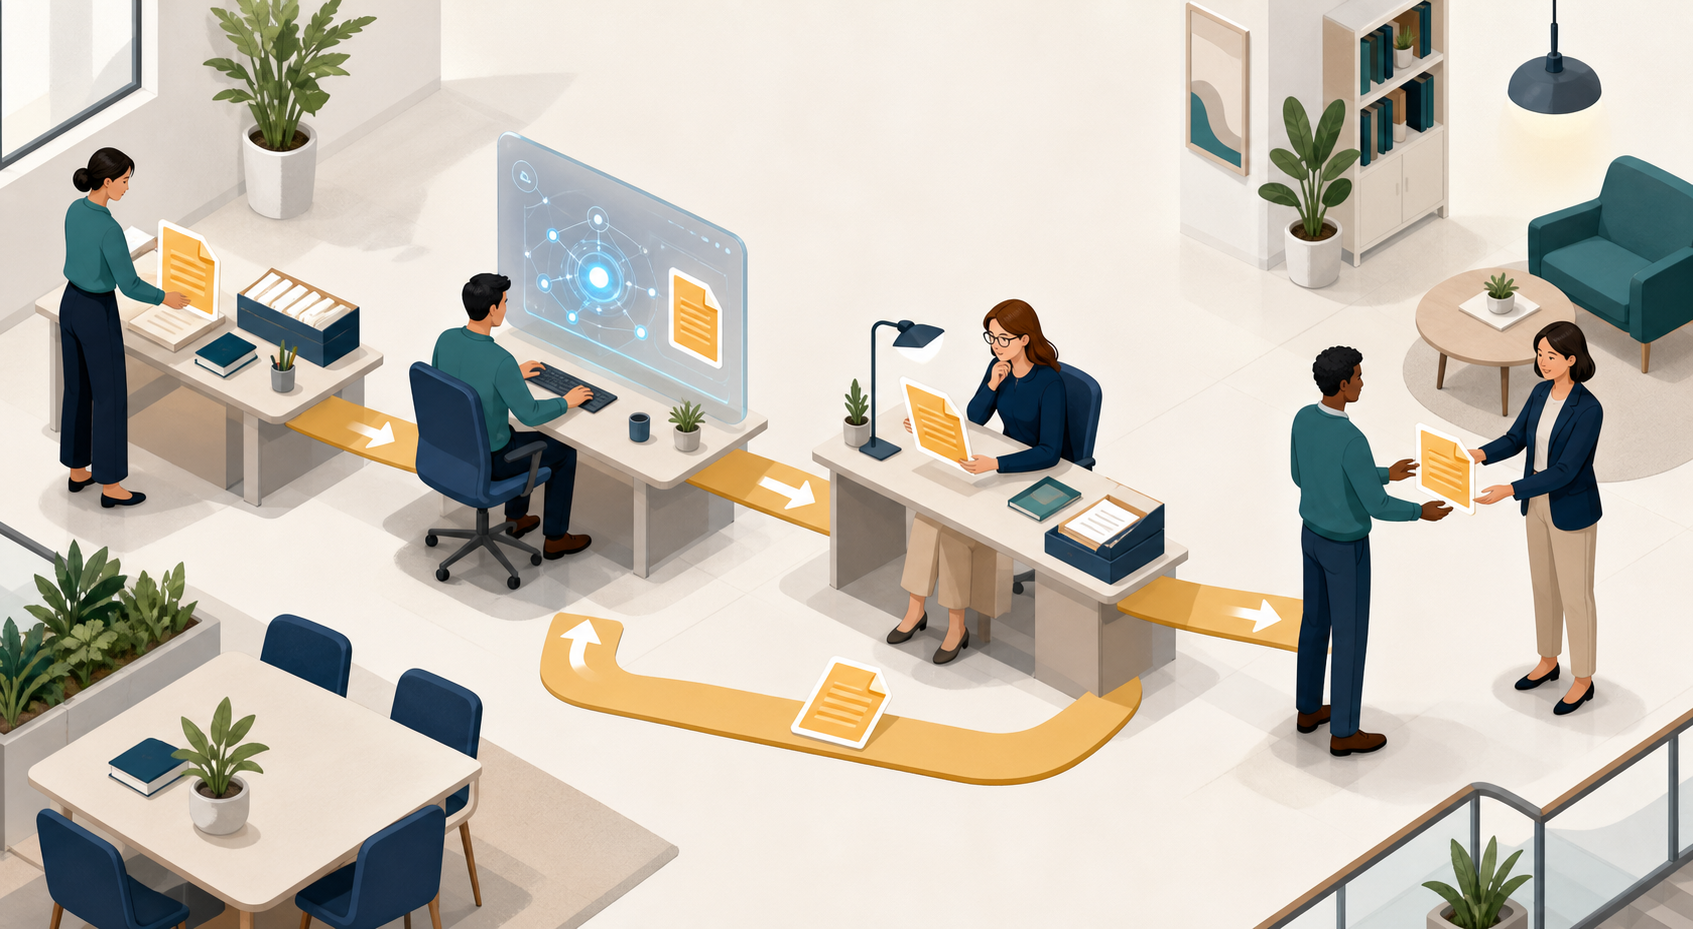
    Isometric illustration of one work item moving through preparation, AI assistance, review, revision, and final handoff.

    Start by drawing a boundary around a unit of work that has a recognizable finish. A generated asset is not finished merely because the model stopped responding. It is finished when the person or system that normally receives it would accept it.

    Define the workflow in this order:

    • Name the unit. Examples include an approved content brief, a published landing page, a validated schema deployment, or a completed technical recommendation.
    • Mark the start. Use an observable event such as a complete request entering the queue, not the moment an operator opens the AI tool.
    • Mark the finish. Tie completion to the existing acceptance or publication gate.
    • List every role that touches the unit, including reviewers and specialists who handle exceptions.
    • Separate active labor from elapsed time. Waiting for an approval is different from the labor required to perform that approval.
    • Define rejection, material rework, and minor correction before the pilot begins.

    For a content workflow, the boundary may include intake, research, briefing, drafting, factual review, search optimization, brand review, CMS entry, quality assurance, and publication. For structured data, it may include identifying the entity, selecting appropriate properties, grounding claims in page content, generating JSON-LD, validating syntax, checking vocabulary use, confirming consistency with the visible page, deploying, and monitoring.

    This map exposes displaced effort. If AI reduces drafting labor but creates an editing queue, the drafting task improved while the workflow bottleneck moved. If the approval stage already limits throughput, sending it more drafts can increase work in progress without increasing published output.

    Choose a pilot workflow with repeatable units, a stable quality gate, and enough ordinary volume to show variation. A one-off strategy project may be valuable, but it is a poor first benchmark because the work changes from case to case. Repeated briefs, metadata updates, query classification, internal-link candidates, schema drafts, and standardized audit checks are easier to compare without pretending every unit is identical.

    Run a quality-adjusted before-and-after test

    Overhead view of two matched work lanes being evaluated with input folders, completed outputs, review materials, and timers.

    A credible baseline comes from normal work completed before the AI-assisted process begins. Use a representative mix rather than selecting unusually easy or painful cases. Record complexity in advance so a change in task mix cannot masquerade as a productivity gain.

    Build the test around the following controls:

    • Use the same workflow boundary, output definition, and acceptance gate in the baseline and assisted conditions.
    • Keep task categories and complexity bands visible. Compare like with like before combining results.
    • Record active labor for preparation, prompting, reviewing, correcting, coordinating, and escalating.
    • Track elapsed lead time separately so a faster task is not confused with a faster delivery process.
    • Log whether each output passed on first submission, required minor edits, required material rework, or was rejected.
    • Record the tool, model, configuration, prompt or template version, and human role involved. A material process change creates a new test condition.
    • Separate rollout costs from ongoing operating costs. Training and workflow design matter to the investment decision even when they do not recur for every unit.

    Do not let faster production lower the acceptance standard. Define quality in terms the workflow already understands. For SEO and AI-optimized content, that may include factual accuracy, completeness, intent fit, source traceability, brand compliance, internal consistency, and technical correctness. For JSON-LD, a syntax pass is necessary but not sufficient; the markup must also describe the visible content accurately and use the intended vocabulary appropriately.

    Make rework categories operational. A minor correction is something the reviewer can fix without reconsidering the approach. Material rework changes the argument, evidence, structure, entity model, implementation choice, or substantial portions of the output. Write those definitions before reviewers see pilot results. Otherwise, enthusiasm for the tool can turn serious revisions into minor edits after the fact.

    Your measurement sheet should include the workflow, accepted unit, task category, complexity band, owner, baseline active labor, assisted active labor, preparation time, review time, correction time, escalation time, elapsed lead time, first-pass status, final acceptance status, error class, tooling cost, and workflow version. Keep the raw observations. A single average hides whether the result is reliable across routine and difficult work.

    Use the median to describe a typical case and show the spread or range to expose variability. Segment results when complex work behaves differently from routine work. An overall improvement can conceal a serious decline in the cases where accuracy matters most.

    Convert released time into capacity the organization can use

    Net time saved is an operational input, not automatically a business result. The next question is what happened to that time. If it remains scattered across tiny fragments, sits behind another bottleneck, or appears in a role with no additional demand, it may not create more output.

    Decide which outcome you are targeting before the rollout:

    • More accepted output with the existing team.
    • Shorter lead time for the same output volume.
    • Higher quality, deeper analysis, or broader coverage without extending delivery time.
    • Lower overtime, fewer backlogs, or more resilience during demand spikes.
    • Capacity redirected to work that had been deferred or neglected.
    • Lower cost per accepted output after tooling and operating costs are included.

    These outcomes are all legitimate, but they are not interchangeable. Reduced labor per unit does not prove payroll savings. Claim a cash saving only when paid hours, contractor spend, hiring requirements, or another real cost changes. Otherwise, describe the result as released capacity and identify where that capacity went.

    Apply a bottleneck test before forecasting additional throughput:

    • Was the improved stage actually limiting the workflow?
    • Can the next stage absorb more volume without adding a queue?
    • Is there enough demand for additional accepted output?
    • Does the saved time arrive in usable blocks that can be scheduled elsewhere?
    • Does the team have authority and a plan to reassign that capacity?
    • Will higher volume create new review, publishing, governance, or maintenance work?

    If the answer to those questions is no, do not discard the gain. Classify it correctly. It may reduce interruptions, create a buffer, shorten a stage, or make quality work possible. Those benefits can matter even when total output stays flat. What matters is reporting the observed outcome rather than converting every saved minute into hypothetical production.

    A defensible result can fit into a single reporting sentence: In the named workflow and task category, the AI-assisted process changed median active labor per accepted unit from the baseline to the measured assisted level after preparation, review, and rework; first-pass acceptance changed from the baseline rate to the assisted rate; the team redirected the resulting capacity to the stated use; and tooling plus rollout costs were recorded separately.

    Start with a single bounded workflow. Pull a representative batch of completed work, define its accepted unit, map every human touch, and capture the baseline before introducing AI. Then run the assisted process through the same gate. A modest gain that survives review and becomes usable capacity is worth more than a dramatic demo that disappears in production.

    References

  • Human Factors That Make Agentic AI Deployments Work

    Human Factors That Make Agentic AI Deployments Work

    Your agent can draft pages, change metadata, select audiences, trigger campaigns, and coordinate customer journeys. The hard question isn’t whether it can perform those actions. It’s whether it should be allowed to perform each one without stopping for a person.

    If you’re deciding how much autonomy to grant, treat the deployment as an operating-model decision rather than a software installation. Define who owns the outcome, which actions require approval, how people will detect a bad decision, and how they can stop or reverse it. Those human controls determine whether the agent produces useful leverage or merely executes mistakes faster.

    Start with a decision, not an AI agent

    Agentic AI projects often begin with a capability demonstration: the system can plan a campaign, create content, update a workflow, or act across several tools. A convincing demonstration doesn’t establish that the workflow is worth automating or safe to delegate.

    The warning is concrete. Gartner expects more than 40% of agentic AI projects to be canceled by the end of 2027. The projection, based on more than 3,400 organizations investing in the technology, points to unclear value, weak governance, and hype-led experimentation rather than a simple lack of technical capability. Treat that percentage as a forecast, not a settled outcome, but don’t miss the operational problem behind it.

    Before you select a product or build an agent, write a decision brief for one workflow. It should answer these questions:

    • What outcome changes? Name the business result, not the AI activity. “Reduce the time required to prepare a technically reviewed content brief” is an outcome. “Use an agent for briefs” is not.
    • What does the workflow look like now? Record its inputs, decisions, handoffs, failure points, review work, and final action. Otherwise, you won’t know whether the agent improved the process or merely moved effort into supervision and repair.
    • Which judgment is scarce? Separate repetitive coordination from decisions that depend on audience knowledge, brand context, ethics, or commercial priorities. Automating the former may create capacity. Hiding the latter inside a prompt creates unmanaged risk.
    • What evidence would justify continuation? Choose outcome, quality, intervention, and recovery measures before launch. A pilot without an exit rule tends to survive because it exists, not because it works.
    • Who can stop it? Assign a named operational owner with authority to pause actions, narrow scope, and require remediation.

    This brief also protects you from “agent washing.” A conventional chatbot or fixed automation shouldn’t be purchased as an autonomous agent simply because the label changed. Ask the vendor or internal team to demonstrate the operating loop: what the system observes, which choices it makes, what it can change, how it checks the result, when it stops, and when it escalates. If every meaningful path was predetermined, you may still have useful automation, but you don’t have the adaptive autonomy the name implies.

    For an SEO or GEO workflow, make the distinction visible. An agent that recommends schema corrections is materially different from one that edits production markup. An agent that identifies possible internal links is different from one that publishes them. An agent that proposes a redirect is different from one that changes routing. Evaluate the authority being granted, not just the sophistication of the output.

    Design human control before you grant autonomy

    Two operators oversee a modular automated workflow equipped with an approval gate, a pause lever, and a track that can reverse direction.

    “Human in the loop” is too vague to serve as a control. A person can technically appear in a workflow while lacking the context, time, authority, or evidence needed to catch a problem. Effective oversight specifies the decision rights on both sides of the human-agent boundary.

    Classify every action the agent may take using four practical questions:

    • Can it be reversed? Saving a draft is easy to undo. Sending a customer message, changing access, publishing an unsupported claim, or allowing a damaging URL change to propagate may not be.
    • How wide is the impact? A suggestion affecting one draft has a smaller blast radius than a template change affecting thousands of pages or an audience rule applied across campaigns.
    • How much context does the decision require? Stable rules are easier to delegate than choices involving brand nuance, conflicting evidence, unusual customer circumstances, or several acceptable outcomes.
    • Will failure be visible quickly? A malformed output may be obvious. A plausible but strategically wrong recommendation can remain unnoticed while it influences content, spend, or customer treatment.

    Use the answers to assign authority. Reversible, narrow, observable actions with clear rules are reasonable candidates for bounded autonomy. Irreversible, broad, ambiguous, or slow-to-detect actions should require approval or remain human-owned. Don’t use one autonomy setting for the entire workflow.

    ControlQuestion it must answerEvidence to retain
    Named ownerWho is accountable for the business outcome and failure response?Owner, backup, authority, and escalation route
    Scope boundaryWhich systems, records, audiences, and actions may the agent touch?Allowlist, denied actions, and permission configuration
    Approval gateWhich conditions force a person to decide?Trigger, reviewer, required context, and decision record
    Stop controlHow can a person halt new actions without waiting for the agent?Pause procedure, access owner, and confirmation that execution stopped
    Recovery pathHow will the team contain and reverse a bad action?Rollback method, affected-system inventory, and notification route
    Audit trailCan reviewers reconstruct what the agent knew, chose, and changed?Inputs, retrieved context, proposed action, approval, execution result, and exceptions

    The audit trail needs to capture more than generated text. Store the context used for the decision, the action requested, the tools called, the result returned, any human intervention, and the final system state. A polished explanation generated after the event isn’t a substitute for an execution record.

    Approval interfaces deserve the same care. Don’t ask a reviewer to click “approve” after showing only the agent’s preferred answer. Show the original input, relevant constraints, proposed change, affected assets, uncertainty or missing information, and available alternatives. Make rejection and escalation as easy as approval. Otherwise, the interface quietly trains people to accept.

    For content and search operations, require explicit review before actions such as publishing factual claims, changing canonical directives, modifying crawl controls, issuing broad redirects, altering product or business data, sending outreach, or communicating with customers. Your exact gates should reflect your systems and risk, but the rule is stable: the person must intervene before the consequential action, not after the impact appears in analytics.

    Increase autonomy only after the workflow becomes observable

    Analysts monitor tasks moving through a transparent automated system while an unusual task is diverted into a separate human review bay.

    A pilot should test the complete operating system around the agent. Testing only whether the model can produce a good answer leaves permissions, handoffs, monitoring, escalation, and recovery unexamined.

    Move through these modes in order:

    1. Shadow mode: Let the agent observe real inputs and record what it would do, but prevent external actions. Compare its proposed decisions with actual outcomes and inspect where its context is incomplete.
    2. Advisory mode: Let it recommend actions to a responsible operator. Record approvals, edits, rejections, escalation reasons, and the time required to review. Heavy correction is evidence that the workflow or context is not ready for autonomy.
    3. Bounded action mode: Allow a defined set of reversible actions within an allowlisted scope. Keep consequential actions behind approval gates and enforce a direct stop mechanism.
    4. Expanded autonomy: Broaden authority only when the existing scope produces acceptable outcomes, exceptions are understood, logs support investigation, and the team can demonstrate recovery.

    Promotion between modes should be an evidence decision. Don’t advance because the pilot deadline arrived or because a successful demonstration created executive enthusiasm. Review routine cases, edge cases, ambiguous requests, missing-data situations, conflicting instructions, permission failures, and attempts to push the agent beyond its assigned scope.

    Measure the deployment across four layers:

    • Outcome: Did the workflow improve the business result named in the decision brief?
    • Quality: Were outputs accurate, complete, on-brand, appropriately sourced, and suitable for the intended audience?
    • Control: How often did people edit, reject, stop, or escalate an action, and why?
    • Recovery: Could the team identify affected assets, contain the problem, restore the correct state, and learn from the failure?

    Don’t optimize the intervention rate toward zero. A falling rate can mean the system improved, but it can also mean reviewers stopped looking carefully. Read intervention data alongside sampled quality checks, downstream outcomes, and exception reports. The useful question is whether human attention is landing on the decisions where it changes the outcome.

    FOMO creates pressure to skip this progression and move directly from demo to production. That pressure is especially dangerous when an agent can act at campaign or site scale. Speed comes from making the safe path repeatable: clear permissions, reusable evaluation cases, reliable logs, tested rollback, and known escalation owners.

    Protect human judgment and customer trust as operating assets

    An agent’s output can look coherent even when its recommendation is unsuitable. That makes reviewer competence part of the control environment. If the person approving an action can’t recognize a strategic, factual, or ethical error, the approval step is ceremonial.

    One projection expects half of organizations to reassess their competencies as reliance on AI threatens critical thinking. You don’t need to reject automation to respond. You need to keep the relevant judgment active.

    • Require a reason for consequential approvals. The reviewer should identify why the action fits the goal and constraints, not merely confirm that the output reads well.
    • Keep people capable of performing the underlying task. Rotate qualified operators through manual cases and exception handling so the team retains a working model of what good looks like.
    • Separate creation from high-impact approval. The person who configured or champions the agent shouldn’t be the only person judging its production readiness.
    • Review disagreements, not just errors. Repeated edits and rejected recommendations reveal missing context, unclear policy, or a task that requires more human judgment than expected.
    • Run post-incident reviews around the system. Examine instructions, data, permissions, interface design, workload, escalation, and incentives. Telling reviewers to “be more careful” leaves the mechanism intact.

    Customer trust needs its own controls. A related forecast warns that poorly applied agentic AI could damage customer relationships by 2026. The risk isn’t limited to obviously nonsensical responses. An agent can send a polished message to the wrong person, apply a reasonable rule at the wrong moment, or take an authorized action that conflicts with the customer’s circumstances.

    Map each customer-facing action to an identity, authority, and escalation rule. The customer should be able to tell what happened, correct wrong information, reach a person when the automated path is unsuitable, and receive a clear resolution when an action causes harm. Internally, the team should be able to identify which agent acted, under whose authority, using what information.

    Brand alignment can’t live only in a long prompt. Translate it into reviewable policies: prohibited claims, evidence requirements, tone boundaries, audience exclusions, escalation topics, and actions the agent may never take. Give each policy an owner and a process for change. That turns “use good judgment” into controls a team can inspect.

    Key takeaways

    • Begin with one defined business decision and its current workflow, not a general mandate to deploy an agent.
    • Evaluate actual autonomy by inspecting what the system observes, decides, changes, verifies, and escalates.
    • Grant authority action by action. Reversibility, impact, ambiguity, and observability should determine where people intervene.
    • Test in shadow, advisory, bounded-action, and expanded-autonomy modes, with evidence required before each increase in authority.
    • Retain execution logs, explicit stop controls, and tested recovery paths before the agent touches consequential systems.
    • Treat reviewer competence and customer escalation as core infrastructure, not training tasks to add after launch.

    Before your next agent demo, produce a one-page deployment contract for the workflow: outcome, owner, allowed actions, prohibited actions, approval triggers, stop mechanism, recovery path, and evidence required for more autonomy. If the team can’t agree on that page, the agent isn’t ready for broader access. Resolving those human decisions first is the shortest route to a deployment you can trust.

    References

  • AI SEO Operations: A Practical System for Safe Automation

    AI SEO Operations: A Practical System for Safe Automation

    You probably do not need another AI SEO tool. You need to know which recurring job to automate, what evidence its output must meet, and who steps in when the system gets something wrong.

    That is the difference between scattered AI experiments and an AI-enabled SEO operation. The goal is not to generate more material. It is to move reliable work through content, analytics, technical SEO, brand and publishing with less friction, while keeping consequential decisions in human hands.

    Key takeaways for AI-enabled SEO operations

    • Start with a business outcome and an existing workflow, not a tool or prompt.
    • Automate stable, repeatable work only after you understand how it is completed manually.
    • Use reach, intent, scale and execution to reject AI ideas that will not produce a measurable result.
    • Give every automation an owner, acceptance criteria, a human escalation path and a manual fallback.
    • Measure quality and business impact alongside time saved. Faster output is not a win if it creates rework or publishes weak information.

    Start with an operating map, not another AI tool

    A team examines a tabletop workflow map connecting content, analytics, technical review, and publishing tasks.

    AI adoption often looks like a tooling problem because tools are the most visible part. The harder problem is that SEO work crosses several functions. A content lead may be generating briefs while an analyst builds a reporting assistant and a developer creates a schema workflow. Each project can be useful on its own, yet the combined system may duplicate effort, produce incompatible outputs or leave nobody accountable for the final result.

    The practical barrier is usually coordination and integration, not willingness to experiment with AI. Legal needs to understand exposure. Developers need defined requirements. Editors need to know what they must verify. Leadership needs to see how the work affects a business objective. A prompt library cannot resolve those dependencies.

    Begin by mapping one complete SEO workflow. Do not start with every task your team performs. Choose a recurring process with a visible beginning and end, such as refreshing declining pages, producing content briefs, reviewing internal links or explaining monthly performance.

    1. Name the outcome. State what should improve: faster refresh decisions, more consistent briefs, fewer unsupported brand claims, better internal-link coverage or less time spent preparing reports.
    2. Define the trigger. Specify what starts the workflow. It might be a scheduled audit, a page crossing a performance condition, an approved keyword cluster or a completed reporting period.
    3. Trace the inputs and handoffs. List the data, documents and approvals required at each stage. Mark where work waits, returns for correction or gets copied between systems.
    4. Assign one accountable owner. Several people may contribute, but one role must own the workflow’s health, approve changes and decide when automation should stop.
    5. Mark the decision points. Separate transformations a machine can perform from judgements a person must make. Summarizing rows is a transformation. Deciding whether a recommendation fits the brand and search intent is a judgement.
    6. Record the baseline. Capture how the workflow currently performs before changing it. Use the measures that already matter: completion time, revision volume, error rate, publishing delay or an associated SEO outcome.

    A small workflow register makes this map usable. It should show where AI assists and where responsibility remains human.

    WorkflowTrigger and inputAI roleHuman decisionOutcome
    Content refreshPerformance review and current pageSummarize changes, gaps and candidate updatesChoose whether to refresh, consolidate or leave the page aloneBetter update decisions with less audit preparation
    Internal linkingNew or updated URL plus site inventorySuggest relevant source pages and destinationsConfirm contextual relevance and approve placementMore consistent link coverage
    Monthly reportingValidated analytics and search dataSurface anomalies and draft observationsVerify causes, add business context and select actionsLess reporting busywork and clearer decisions
    Metadata or schemaApproved page facts and a defined templateGenerate a structured draftVerify factual support, syntax and suitability for publicationFaster production without surrendering control

    This register also exposes misplaced automation. If an AI step produces an outline before keyword selection is approved, for example, it may accelerate work that will later be discarded. Moving one task faster does not help when the actual delay sits at a different handoff.

    Build the automation backlog from work you already understand

    The strongest automation candidates are usually hiding inside work your team already performs repeatedly. They have known inputs, recognizable outputs and a reviewer who can explain what good looks like. That makes them easier to test than a new process invented around an AI feature.

    Observe a recently completed workflow from start to finish. Compare the actual work with onboarding documents and standard operating procedures. Ask the people doing it which steps they repeat, dislike or routinely postpone. This kind of workflow audit can reveal opportunities across data analysis, content gaps, editorial planning, briefs, metadata, schema and formatting.

    Use two tests to identify a candidate. First, ask whether you would confidently delegate the task to a new team member after giving them instructions and examples. Second, ask whether an experienced reviewer could detect a bad output without repeating the whole task. If both answers are yes, AI may be useful for the first pass.

    A 70% machine draft and 30% human refinement can be a useful starting heuristic for research and drafting work. It is not a staffing formula or a promise that every task divides neatly. It means the machine handles collection, classification, formatting or an initial draft, while a person supplies judgement, context and approval.

    Before putting a candidate in the backlog, pass it through an automation-readiness check:

    • The manual process is stable. Different team members follow substantially the same steps.
    • The input is available and trustworthy. The automation will not need to guess around missing page facts, incomplete analytics or inconsistent naming.
    • The output has a defined shape. A template, field structure or explicit deliverable makes validation possible.
    • Quality can be evaluated. Reviewers can distinguish an acceptable result from a plausible-looking failure.
    • Failures will be visible. A malformed output, missing input or unsupported statement will be flagged rather than silently published.
    • A person owns escalation. Someone knows what to do when the result falls outside the normal path.
    • The manual path still exists. The team can continue critical work if the model, integration or maintainer becomes unavailable.

    If the process is inconsistent, fix that first. Automation works best after the underlying workflow has been standardized and performed manually. Otherwise, AI does not remove the ambiguity. It executes the ambiguity faster and at a larger scale.

    Be especially cautious when the required asset does not exist. AI cannot reliably enforce brand rules that have never been documented, fill a content template whose fields are disputed or repair an analytics pipeline with incomplete data. Those are ownership and process problems. Treating them as prompt problems delays the real fix.

    Use RISE to reject weak automation ideas early

    An automation backlog will grow faster than your ability to implement it. The useful management skill is therefore rejection. A small number of well-integrated workflows will usually create more value than a large collection of clever demonstrations.

    The RISE framework tests an initiative through reach, intent, scale and execution. Use it before selecting a model, buying a tool or asking engineering for an integration.

    Reach: quantify the eligible work and the upside

    Reach is not a vague claim that a workflow affects SEO. Name the inventory, frequency and result. For a recurring task, you can model operational reach as eligible items multiplied by handling time and run frequency. For an SEO initiative, include the pages, query groups or customer questions it can materially affect.

    Write down the baseline and the expected movement before implementation. If you cannot identify a numerical business or operational upside, keep the idea in exploration rather than placing it on the production roadmap. This prevents novelty from being mistaken for impact.

    Intent: prove that the output serves a real decision

    Intent means more than classifying a keyword as informational or transactional. Ask who will use the output, what question it answers and what action follows. An automated content-gap report has little value if nobody has the authority or capacity to commission the missing work. A metadata generator is misplaced if weak positioning, not drafting time, is the constraint.

    For content operations, connect the workflow to a defined audience question and page purpose. AI can expand an outline, but a strategist still needs to decide whether the page deserves to exist and what distinct value it should provide.

    Scale: look for structural reuse

    A scalable workflow does not require someone to reconstruct the prompt, clean the inputs and explain the output every time it runs. It uses repeatable triggers, standardized fields, documented rules and a destination inside the team’s normal systems.

    Do not confuse a large batch with scale. Generating thousands of outputs once is volume. Scale exists when the operation can run again, under ownership, without rebuilding the process or accumulating hidden manual cleanup.

    Execution: define how the work reaches production

    Execution is where promising demonstrations tend to stall. Name the owner, required access, review stage, acceptance criteria and publishing destination. Identify the team that will maintain the workflow when prompts, templates, data fields or business rules change.

    A one-page initiative brief is enough to force clarity. It should contain the problem, baseline, eligible inventory, intended user, workflow owner, AI role, human decision, quality checks, expected outcome and stop condition. If those fields cannot be completed, the initiative is not ready for production.

    After an idea passes RISE, test it against previously completed work. Historical cases give you an expected result and let reviewers compare the automated output with decisions that have already been made. Only then move to a live pilot, with every output reviewed until the failure patterns are understood.

    Make control and measurement part of the workflow

    A controlled pipeline routes digital work through automated checks, human review, and a final release gate.

    Human review is necessary, but it is not a complete control system. A vague instruction to check the output leaves each reviewer to invent a different standard. Effective QA combines machine-readable checks, explicit editorial criteria and a named person who can approve exceptions.

    Design each production workflow as a controlled sequence:

    1. Validate the input. Confirm required fields, data freshness and allowed formats before sending anything to the model.
    2. Run the bounded AI task. Give the system a specific transformation, required output structure and the information it is allowed to use.
    3. Apply deterministic checks. Test syntax, missing fields, duplicates, prohibited terms, unsupported values or other conditions that do not require subjective judgement.
    4. Route the result for human review. Show the generated output with its input and any warnings. A reviewer should not have to hunt for the evidence needed to approve it.
    5. Publish through the normal system. Keep existing permissions and approval controls instead of creating a parallel route around the CMS or engineering workflow.
    6. Log the result and any correction. Record failures, overrides and substantive edits so the team can improve the process rather than correcting the same pattern indefinitely.

    The acceptance criteria should match the output. An internal-link recommendation needs a relevant context, a valid destination and an editorially sensible placement. A reporting narrative must reconcile with validated data and separate observation from explanation. Generated schema must be syntactically valid and contain only claims supported by the visible page. A content brief needs a defined intent, usable structure and enough evidence for a writer to proceed without guessing.

    Keep the final check personal where the output affects a public page, brand claim or strategic decision. Automating the first pass is useful precisely because it leaves more attention for quality assurance and consequential decision-making. Removing that review to maximize throughput defeats the purpose.

    Document the workflow well enough that it can survive a change of maintainer. Include its purpose, owner, trigger, input location, prompt or instruction version, output format, validation rules, reviewer, publishing path and failure response. This reduces the risk of losing both operational knowledge and a critical process when the person who built the automation is no longer available.

    Run governance at three different cadences. A weekly cross-functional checkpoint should handle exceptions, blocked handoffs and decisions that cannot wait. A monthly review should compare efficiency, quality and SEO or business outcomes with the baseline. A quarterly roadmap session should decide which workflows to expand, repair, retire or leave manual. Weekly coordination, monthly performance reviews and quarterly roadmap alignment keep ownership active after launch.

    Measure the operation in three layers:

    • Efficiency: completion time, queue age, manual touches and work returned for correction.
    • Quality: acceptance rate, substantive edit rate, validation failures, false positives and published corrections.
    • Outcome: the business or SEO measure named when the initiative was approved, such as refresh completion, useful internal-link coverage, reporting decisions or performance of the affected page group.

    Do not report time saved without showing what happened to quality and outcomes. An automation that halves drafting effort but doubles review work has shifted the cost, not removed it. Likewise, a workflow can be accurate and still be unnecessary if nobody acts on its output.

    Recovered capacity should have an explicit destination. Use it for work AI cannot own: coordinating priorities across teams, investigating why performance changed, improving the customer search journey and deciding which emerging search behaviors deserve attention. Otherwise, the saved time tends to be absorbed by a larger volume of low-value production.

    Your next move can be small. Select one recurring workflow, write its one-page operating brief, record the current baseline and test the proposed automation on completed work. If you cannot name the owner, acceptance criteria and failure path, do not automate it yet. Fix those three gaps first, then let AI accelerate a process you can actually control.

    References


  • AI Search Adoption Is Unequal: How Brands Should Respond

    AI Search Adoption Is Unequal: How Brands Should Respond

    If your search strategy begins with the assumption that everyone is moving from Google to ChatGPT at roughly the same pace, stop before you move the budget. The shift is real, but the average adoption figure hides the people, circumstances, and confidence levels driving it.

    You need a strategy that serves confident AI-search users without making conventional search worse for everyone else. That means maintaining two discovery paths, designing AI features as optional assistance, and measuring who benefits rather than treating every AI interaction as progress.

    The average adoption number hides different search realities

    In UK monitoring that began in early 2025, 27% of users said they regularly used ChatGPT. That topline becomes much less useful once household income enters the picture: higher-income households were substantially more likely to use generative AI tools.

    Treat that result as a segmentation signal, not a universal market adoption rate. It tells you that AI use can cluster around particular audiences. It does not tell you that every high-income person uses AI, that lower-income users lack interest, or that the same distribution applies in every country and category.

    Income matters partly because it sits alongside several mechanisms that affect whether someone makes AI part of a normal search journey:

    • Access: Can the person readily use the relevant tool in the context where the question arises?
    • Exposure: Do their workplace, peers, or professional routines encourage them to use AI? People in digital and corporate environments may encounter more prompts to incorporate it into daily work.
    • Capability: Can they frame a useful request, add context, refine a weak response, and inspect the supporting material?
    • Confidence: Do they trust themselves to use the interface and know when an answer needs checking?

    These factors reinforce one another. Frequent exposure builds skill. Skill can improve results. Better results can increase confidence and make the tool feel like the natural place to begin the next task. Someone without that loop may try the same interface once, receive an unhelpful answer, and return to a familiar search box.

    Trust also needs context. Perplexity users have reported high trust while the platform remains comparatively niche. Strong confidence inside a self-selecting user group is not proof of broad public confidence. It may simply describe the people who chose that tool and stayed.

    This is where an average can misdirect strategy. A revenue-weighted customer view may make AI search appear nearly universal if affluent decision-makers are overrepresented among early adopters. A traffic-weighted view may make it look marginal if the larger audience still relies on conventional results. Neither view is sufficient by itself.

    Before reallocating search investment, audit four questions for each important audience:

    1. Where does this audience normally encounter the problem: at work, at home, during a purchase, or while learning?
    2. Which interface do they use to begin, and which interface do they use to verify?
    3. What capability does the journey assume, such as prompting, comparing options, or checking citations?
    4. What happens when confidence fails: do they reformulate, open a conventional result, ask another person, or abandon the task?

    Do not use household income as a shortcut for individual behavior. Use it, when legitimately available and appropriately governed, as one possible research variable. Behavioral evidence such as entry path, repeated feature use, verification actions, and successful task completion is more useful for designing an experience.

    Build one evidence base for two discovery paths

    A shared foundation of connected content and evidence supports both an abstract conventional search interface and an abstract conversational AI interface.

    You do not need an AI site and a non-AI site. You need one dependable body of content that can support two ways of exploring it.

    Journey stageConventional search behaviorAI-search behaviorWhat your content must provide
    Frame the problemEnters a short query and scans resultsDescribes a situation and refines it through follow-up promptsA direct statement of the problem, audience, scope, and relevant terminology
    Compare optionsOpens several pages and compares claims manuallyRequests a synthesis, shortlist, or side-by-side explanationConsistent attributes, explicit differences, limitations, and decision criteria
    VerifyChecks the page, publisher, evidence, and supporting materialInspects citations or leaves the answer to check the underlying pageVisible evidence, clear authorship, dates where relevant, and traceable claims
    ActNavigates to a product, form, store, or next-step pageActs on a shortlist and may enter the site late in the journeyAccurate facts and an obvious next action that does not depend on AI

    The shared content layer matters because optimization for AI discovery cannot rescue weak information. A machine-readable page that never gives a clear answer is still unclear. A polished conversational response built from unsupported claims is still unsupported.

    For every high-value page, make the evidence layer usable in both paths:

    • Lead with the decision-relevant answer. State who the page is for, what question it resolves, and where the answer changes by circumstance.
    • Name entities consistently. Use the same product, organization, service, location, and category names throughout the visible content and metadata.
    • Expose comparison attributes. If a buyer must compare eligibility, compatibility, availability, process, or limitations, place those facts in plainly labelled sections rather than implying them through promotional copy.
    • Separate fact from judgement. Make it obvious which statements describe a documented feature and which represent your recommendation or interpretation.
    • Show evidence near the claim. A reader should not have to hunt through a generic resources page to discover what supports an important assertion.
    • Keep structured data aligned with visible content. JSON-LD should clarify the entities and relationships already present on the page, not introduce claims that visitors cannot verify.
    • Preserve a complete human-readable route. Do not require an AI assistant to reveal essential instructions, terms, limitations, or next steps.

    This approach lets conventional SEO, answer engine optimization, and generative engine optimization share the expensive part of the work: producing content precise enough to retrieve, interpret, compare, and verify. The delivery layer can vary without creating competing versions of the truth.

    Prioritization should reflect audience value without turning early adopters into a stand-in for the market. Fast adopters often include decision-makers and higher-income consumers, so AI visibility may deserve early investment even when total usage remains limited. The correct conclusion is to add coverage for an influential segment, not to remove coverage from everyone else.

    Add AI interfaces as assistance, not as a gate

    People choose between a conventional search panel and an optional conversational assistant while using a range of devices and accessibility methods.

    An on-page AI button can shorten a difficult task. It can also add ambiguity, expose visitors to weak generated output, or hide information behind an interface they do not want to use. The debate around AI buttons spans usability benefits, SEO risk, and fears of AI poisoning, so the useful question is not whether a button looks innovative. It is whether it helps a defined user complete a defined job safely.

    Start with the verb. Labels such as Summarize this policy, Compare these plans, or Ask about eligibility tell the visitor what the feature will do. A vague AI button asks the visitor to understand the technology before understanding the benefit, which creates exactly the kind of confidence barrier you are trying to reduce.

    Use six release gates before putting an AI interface into a search or content journey:

    1. Defined task: Write down the user job in one sentence. If the feature is meant to summarize, compare, explain, or route, choose one primary job and design for it.
    2. Optional path: Confirm that a visitor can reach the same essential information and next action without opening the AI experience.
    3. Clear boundary: Tell users what information the assistant uses and what it cannot determine. Do not invite sensitive or consequential input merely because a free-text box makes that possible.
    4. Grounded output: Make the response traceable to the approved page content or other clearly identified material. AI poisoning, in this context, is the risk that manipulated content or instructions distort what the system produces; limiting and validating the material available to the feature reduces the opportunity for that distortion.
    5. Recovery route: Provide a visible way to open the relevant page section, inspect supporting details, start over, or continue through the standard journey when the response is unhelpful.
    6. Success measure: Define success as task completion or a meaningful next step, not the number of times the button is clicked.

    Progressive enhancement is the right operating principle. Publish the essential content in stable, accessible HTML. Keep navigation, forms, and core actions usable without generated assistance. Then add the AI layer where summarization, comparison, or conversational clarification removes genuine work.

    This also protects the conventional search journey. If important information exists only inside a generated interaction, users cannot reliably scan it before opting in, and the standard page no longer carries the complete answer. The feature has stopped being assistance and become a gate.

    Test the full experience, not just whether the button opens. Check keyboard operation, focus order, labels, loading and error states, generated links, narrow screens, and the non-AI fallback. Review sample outputs for unsupported claims, missing qualifications, inconsistent names, and recommendations that exceed the page’s evidence.

    Measure adoption without averaging away inequality

    A single AI engagement rate cannot tell you whether the feature broadens access or merely serves the people who were already confident enough to try it. Build reporting around exposure, use, usefulness, recovery, and outcome.

    • Eligible exposures: How many visits actually encountered the feature on a relevant page?
    • Activation rate: Of those eligible visits, how many initiated the feature?
    • Task completion: How many users reached the intended next step after using it?
    • Fallback rate: How often did users leave the AI flow for the standard page, search, navigation, or support route?
    • Correction signals: How often did users regenerate, reformulate, dispute, or abandon the response?
    • Downstream outcome: Did the interaction support the real goal, such as finding the right page, understanding a requirement, completing a form, or making an informed selection?

    Break these measures down by relevant, ethically collected context. Useful views may include entry channel, task, first-time versus returning visit, exposure to the AI feature, prior feature use, and voluntarily reported confidence. If your organization has a legitimate basis for audience or income research, keep that analysis aggregated and governed rather than turning a population-level pattern into an assumption about an individual.

    Read the combinations, not just the totals:

    • Low activation and high completion can mean the feature is useful once discovered, but its label, placement, or trust cues are weak.
    • High activation and high fallback can mean curiosity is strong while output quality, task fit, or confidence is poor.
    • Strong outcomes concentrated among experienced users can mean the interface rewards existing AI literacy rather than reducing the skill barrier.
    • Rising AI engagement alongside falling conventional completion can mean the new interface is disrupting the baseline journey instead of improving it.
    • High commercial value from a small AI-search cohort can justify targeted investment, but it does not justify treating that cohort’s behavior as universal.

    Keep external AI discovery separate from on-site AI usage. Mentions, citations, referrals, assisted visits, and landing-page behavior describe visibility outside your site. Button activations, response quality, fallback, and completion describe the experience you control. Combining them into one AI score makes it harder to identify whether the problem is discoverability, content quality, interface design, or audience readiness.

    Your investment decision should follow the constraint. If the right audience cannot find you in AI-generated results, improve retrievability, entity clarity, and evidence. If people arrive but cannot verify the answer, strengthen the page. If an AI feature attracts clicks but blocks completion, fix or remove the feature. If conventional search still carries most successful journeys for an important audience, maintain it.

    Key takeaways

    • Do not use an average AI-adoption rate as your audience model; segment by behavior, context, exposure, capability, and confidence.
    • Treat income-linked adoption as a planning signal, not as a rule about any individual user.
    • Build one verifiable content base that supports both conventional search and conversational discovery.
    • Keep AI buttons optional, label them by the job they perform, and preserve the complete non-AI route.
    • Measure task completion, fallback, correction, and downstream outcomes by cohort; a click on an AI feature is not success.
    • Invest early where AI-search users are commercially important, but do not weaken the search paths used by the rest of your audience.

    Your next move is not to choose between SEO and AI search. Take one high-value customer journey, draw its conventional and conversational paths, inspect the shared evidence beneath both, and define the cohort-level measures before adding another AI feature. If you cannot see who gains, who struggles, and how either group recovers, the experience is not ready to scale.

    References


  • AI Advances in Healthcare: A Practical Evaluation Guide

    AI Advances in Healthcare: A Practical Evaluation Guide

    You’ve got a healthcare AI announcement in front of you and a decision to make: is this a meaningful advance, a promising demonstration, or a polished claim that has outrun its evidence? The model’s reputation won’t answer that question.

    You need to connect the technology to a care task, the care task to evidence, and the evidence to a controlled workflow. That framework works whether you’re evaluating a product, planning adoption, writing clinical content, or deciding which claims deserve visibility in search and AI-generated answers.

    The useful unit of progress is the care task

    The potential of healthcare AI extends from diagnostics to patient care. That range is also why broad statements about AI transforming healthcare tell you so little. Diagnostics, documentation, scheduling, patient education, and clinical decision support are different jobs with different users, failure modes, and consequences.

    Start by reducing every claimed advance to one task statement. It should identify five things:

    1. User: Who receives or acts on the output: a patient, clinician, administrator, researcher, or another system?
    2. Input: What information does the system receive, and where did that information come from?
    3. Output: Does it draft text, summarize a record, flag a case, rank options, predict an event, or initiate an action?
    4. Decision: What real decision could change because of the output?
    5. Failure consequence: What happens if the output is incomplete, late, biased, misleading, or wrong?

    For example, AI that summarizes clinician-authored encounter notes for clinician review is an assessable use case. AI that improves patient care is not. The first statement identifies a user, input, output, and review step. The second jumps directly to an outcome without showing the mechanism.

    Once the task is clear, ask what actually improved. An advance might reduce the time required for a task, make documentation more consistent, identify relevant cases, expand access, or reduce avoidable administrative work. Those are separate claims. Evidence for faster drafting does not establish better diagnosis, and stronger performance on a technical evaluation does not automatically establish better patient outcomes.

    This distinction should shape your language. If a system generates possibilities for a qualified professional to consider, say that. Don’t say it diagnoses. If it drafts an explanation that must be reviewed, call it a draft. Don’t describe it as patient guidance delivered independently. Precise verbs prevent a capability claim from quietly becoming a clinical claim.

    Separate assistance, recommendation, and action

    A three-part clinical scene shows AI organizing information, presenting a recommendation, and operating supervised medication equipment.

    Healthcare AI systems can occupy very different positions in a workflow. A useful first classification is whether the system assists, recommends, or acts. This is an evaluation framework, not a regulatory classification, but it quickly exposes how much control the workflow needs.

    ModeWhat the AI doesHuman control to verifyClaim discipline
    AssistsDrafts, organizes, retrieves, or summarizes informationA person can inspect, edit, reject, and replace the outputDescribe the task support, not an unmeasured care outcome
    RecommendsFlags cases, ranks options, or proposes a next stepA qualified person evaluates the recommendation before it affects careName the intended user, decision, evaluation context, and known limits
    ActsTriggers, routes, schedules, or changes something in the workflowThe system has defined boundaries, escalation paths, and a way to stop or reverse inappropriate actionExplain exactly what is automated and where human oversight remains

    Risk does not begin only when AI acts autonomously. An incorrect summary can carry an old fact forward. A fluent explanation can make uncertain information sound settled. A recommendation can attract more trust than its evidence deserves. Human review is not a meaningful safeguard unless the reviewer has the information, authority, time, and interface needed to catch a problem.

    Inspect the control itself. A reviewable workflow should make the AI-generated material identifiable, preserve relevant input context, let the reviewer edit or reject the output, provide an escalation route, and record what was accepted or changed. A button labeled approve is not sufficient if the reviewer cannot see how the output was produced or cannot safely disagree with it.

    The closer an output gets to diagnosis, medication, treatment, or urgent-care decisions, the more explicit these boundaries must become. Patient-facing AI must not be presented as a substitute for a qualified healthcare professional. If an output conflicts with a clinician’s instructions or a medication label, the safe next step is to contact the appropriate clinician or pharmacist rather than act on the AI response. Situations involving possible immediate harm require established local emergency channels, not another chatbot prompt.

    Match every claim to its actual level of evidence

    A compelling output proves that the system produced a compelling output once. It does not establish reliability, clinical usefulness, or patient benefit. To avoid that leap, place evidence on a ladder and stop at the highest rung the evaluation genuinely supports.

    1. Capability evidence: The system can produce the intended kind of output in selected examples.
    2. Task validation: Its outputs have been evaluated against a predefined reference, process, or reviewer judgment for the stated task.
    3. Workflow validation: Intended users have used it under conditions that resemble the intended setting, including realistic inputs and handoffs.
    4. Outcome evidence: The evaluation measured the patient, clinical, or operational outcome named in the claim rather than using a technical metric as a substitute.
    5. Post-deployment evidence: Performance, failures, overrides, and changes continue to be monitored in actual use.

    Each rung answers a different question. Task validation may show that a system performs a bounded function well. Workflow validation asks whether people can use that function safely and effectively. Outcome evidence asks whether the claimed real-world result occurred. Post-deployment monitoring matters because users, data, interfaces, prompts, retrieval material, and models can change after an initial evaluation.

    When you inspect an evaluation, ask questions that reveal what the headline leaves out:

    • Which population, language, care setting, and task were represented?
    • What counted as success, and was that definition chosen before the results were reviewed?
    • What was the comparison: no tool, the existing workflow, another system, or an expert judgment?
    • Which failures occurred, who was affected, and which failures carried the greatest clinical consequence?
    • Were intended users evaluating the output, or was the system assessed only outside the care workflow?
    • What happens when information is missing, contradictory, unusually phrased, or outside the intended scope?
    • Which model, configuration, retrieval material, interface, and review process produced the result?

    If those details are unavailable, treat that absence as an evidence limit. Don’t fill the gap with a stronger adjective. Promising can be appropriate for an early capability. Validated needs a stated task and context. Effective should identify the outcome that improved. Safe is usually too broad to stand alone because safety depends on the user, setting, controls, and type of failure being considered.

    Keep the evaluated system distinct from the underlying model. A healthcare AI implementation may include a model, prompts, retrieval sources, interface rules, access controls, escalation policies, and human review. Changing any of those elements can change the behavior that users experience. Record them together, and retest material changes instead of assuming that an earlier result transfers automatically.

    Test the workflow around the model, not just the model

    A nurse, physician, informaticist, and human-factors specialist test an AI-supported process with a training mannequin in a clinical simulation room.

    A technically capable model can still fail as a healthcare system. The failure often appears at the handoff: the wrong information enters, the output reaches the wrong person, a warning arrives too late, or nobody owns the exception. Evaluate the full route from input to consequence.

    Use these six gates before treating a capability as deployment-ready:

    1. Context match: Confirm that the intended users, population, language, setting, and task resemble those represented in the evaluation.
    2. Input control: Define which data the system may receive, how missing or conflicting information is handled, and who is responsible for input quality. Never place identifiable patient information into an AI tool that your organization has not approved for that use.
    3. Output routing: Specify who sees the result, when they see it, what supporting context accompanies it, and whether it can alter a decision before review.
    4. Human factors: Verify that users can understand the output’s role, identify uncertainty, disagree with it, and complete the task without becoming dependent on it.
    5. Failure response: Decide in advance how the workflow handles false alarms, missed cases, unsupported statements, system outages, and outputs outside the intended scope.
    6. Change monitoring: Assign an owner to watch failures, overrides, complaints, model or configuration changes, and performance drift after launch.

    Run the workflow with difficult cases before routine ones create false confidence. Test missing context, ambiguous requests, contradictory records, out-of-scope questions, and attempts to bypass the intended process. The goal is not to prove that the system never fails. It is to learn whether failures are visible, containable, recoverable, and routed to someone able to respond.

    Define a stop condition as well as a success condition. A responsible deployment plan says who can pause the system, which events trigger review, what work continues without it, and how affected users are notified or corrected. If nobody has authority to stop an unsafe workflow, the oversight plan is incomplete.

    Publish healthcare AI claims that can survive scrutiny

    Healthcare AI content has to work for a person assessing risk and for search or answer systems extracting a concise statement. Both benefit from the same thing: explicit claims with their qualifications attached. A vague page cannot become trustworthy through optimization, and structured data cannot turn unsupported language into evidence.

    Put the central claim in a form that can stand on its own: the system, intended user, task, setting, oversight, and demonstrated evidence level should appear together. Put an important limitation in the same sentence or adjacent paragraph, not in a distant disclaimer that disappears when the sentence is quoted.

    A useful claim pattern is: [System] helps [intended user] perform [task] in [setting]. [Reviewer or control] checks [output] before [decision or action]. Current evidence establishes [capability, task performance, workflow performance, or outcome], while [important limitation] remains unresolved.

    Before publication, apply these editorial thresholds:

    • Can generate or summarize: Show that the capability was tested with the stated input and output. Don’t convert generation into an accuracy or outcome claim.
    • Supports review or decision-making: Identify the qualified user, the decision being supported, the review step, and the context in which the support was evaluated.
    • Improves a workflow: Name the measured operational result and the workflow used for comparison. Don’t use an isolated model score as proof of workflow improvement.
    • Improves diagnosis or patient outcomes: Reserve this language for evidence that measured the named diagnostic or patient outcome in the defined population and setting.
    • Is safe: Replace the blanket claim with the risks evaluated, controls used, limitations found, and context covered. No system is safe independently of its use.

    Keep vendor, model, product, and care provider roles separate. OpenAI, Google, and Anthropic may be relevant to the underlying AI landscape, but a familiar model developer’s name does not establish that a particular healthcare implementation is clinically validated. State who built the model, who configured the system, who operates the workflow, and who is responsible for clinical review whenever those roles differ.

    Your maintenance process matters as much as the launch page. Keep a claim inventory linking each public statement to its evidence, evaluated configuration, owner, review date, limitations, and correction route. When a model, prompt, retrieval source, interface, intended use, or oversight process changes, review the dependent claims. Otherwise, accurate content can become misleading while its publication date and search visibility remain unchanged.

    Use schema and other machine-readable markup to describe what the visible page actually says. Keep the evidence level, intended use, limitations, author or reviewer responsibility, and update history readable on the page itself. Machines may extract the markup, but people still need enough context to judge the claim.

    Key takeaways

    • Judge healthcare AI at the level of a defined care task, not the reputation of a model or developer.
    • Separate systems that assist, recommend, and act; each position requires a different degree of control and claim restraint.
    • Don’t treat a demonstration, task evaluation, workflow evaluation, outcome evaluation, and monitored deployment as interchangeable evidence.
    • Evaluate inputs, handoffs, human review, failure response, and change control alongside model performance.
    • Keep qualifications beside the claim so readers and AI answer systems do not receive a stronger statement than the evidence supports.
    • Do not present patient-facing AI as a replacement for qualified medical care, especially where diagnosis, medication, treatment, or urgent decisions are involved.

    For the next healthcare AI claim you encounter, write the five-part task statement before you draft a headline, approve a tool, or publish a page. Then label the highest evidence rung it has reached. If you cannot complete either step, hold the claim at capability level until the missing context is available.

    References

  • How to Evaluate Leading AI Software Companies in 2026

    How to Evaluate Leading AI Software Companies in 2026

    If you are shortlisting AI software companies, a generic ranking answers the wrong question. A company can lead at the model layer and still be a poor choice for deploying a governed workflow inside your business.

    Your real task is to identify the kind of company you need, define what leadership means for your use case, and make each candidate prove it with your workflow and representative data. That turns a crowded market into a decision you can defend.

    Start with the job, not the company ranking

    There is no useful universal winner. A packaged AI application, a model provider, a cloud platform, and a custom development company solve different parts of the problem. Ranking them together is like ranking an engine, a delivery van, and a logistics contractor on the same scale.

    Before you collect vendor names, write a short procurement brief. It should be specific enough that another person could recognize a successful deployment without hearing the sales pitch.

    • Workflow: Name the task or decision the software will support. Avoid broad goals such as “use AI for marketing.” A workable definition is closer to “produce a cited first draft from approved product documentation for an editor to review.”
    • Owner: Identify the person accountable for the workflow after launch. A sponsor can approve a purchase, but an operational owner has to manage errors, updates, and user adoption.
    • Inputs: List the documents, databases, messages, images, or application events the system may use. Record where that data lives and who has permission to expose it.
    • Output and action: State what the system produces and what happens next. Distinguish a suggestion shown to a person from an action executed in another system.
    • Failure boundary: Describe acceptable mistakes, unacceptable mistakes, and the point at which a human must intervene. A formatting error and an invented compliance claim cannot share the same severity.
    • Environment: Name the identity system, content repository, analytics stack, customer platform, or other software the product must work with.
    • Evidence: Define what a candidate must demonstrate using representative cases. A polished demonstration using vendor-selected examples is not evidence of fit.
    • Exit conditions: Decide what data, configurations, prompts, evaluation cases, logs, and code you must be able to recover if you change providers.

    If you cannot complete this brief, pause the vendor search. When the outcome is vague, almost any demonstration can look successful, and disagreements about quality appear only after money and integration work have been committed.

    Compare companies that perform the same role

    Four distinct AI software workstations connect to the same central business task for a role-based comparison.

    The label leading AI software development companies can cover businesses with very different products and delivery models. Put each candidate into a functional category before you compare features, pricing, or market visibility.

    Company typeChoose it whenEvidence to requestCommon mismatch
    Model or API providerYour team is building its own application and needs model capabilities as a component.Results on your evaluation cases, usage controls, model-change procedures, latency behavior, and data-handling terms.Buying raw capability when you do not have the engineering or operational team to turn it into a reliable workflow.
    Cloud or data platformYour priority is connecting AI to governed data, existing infrastructure, and enterprise controls.Architecture fit, identity integration, data boundaries, deployment options, monitoring, and portability.Assuming platform breadth means the desired business application is already complete.
    Packaged AI applicationYou need a defined outcome in a familiar function such as content operations, support, analytics, or sales workflow.Workflow coverage, administrator controls, export options, user permissions, integration depth, and evidence from representative tasks.Paying for a broad feature set while the product remains weak at the narrow task that matters.
    Workflow or agent platformYou need AI to coordinate steps, tools, and approvals across systems.Action permissions, state handling, retries, approval gates, audit logs, failure recovery, and limits on autonomous behavior.Treating an impressive prototype as a dependable operational process.
    Custom AI development companyNo packaged product fits the workflow, or your process and data create meaningful differentiation.Proposed architecture, delivery ownership, evaluation method, repository access, documentation, deployment plan, support model, and intellectual-property terms.Commissioning custom software before confirming that the workflow is stable enough to specify and maintain.
    AI operations or governance providerYou already have AI systems and need evaluation, observability, policy enforcement, or control across them.Coverage of your actual stack, alert quality, policy implementation, evidence retention, and response procedures.Expecting a control layer to repair poor application design or unsuitable source data.

    A candidate can belong to more than one category, but you should still name the role you are buying from it. Otherwise, a vendor’s strength in one layer can distract you from a gap in another. If you need a finished application, model quality alone does not settle the decision. If you need a model component, a large catalogue of packaged features may be irrelevant.

    Turn “leading” into pass-or-fail requirements

    Feature counts reward breadth, and weighted scorecards can hide a fatal weakness behind a high total. Use non-negotiable gates first. Score or rank only the companies that pass every gate that protects the workflow.

    • Task performance: The product must produce usable results on ordinary cases, difficult edge cases, and inputs that should trigger refusal or escalation. Define “usable” in terms of the next step in the workflow, not whether the output sounds polished.
    • Evaluation discipline: Ask how the company detects regressions and separates different error types. For generated answers, completeness, factual support, citation quality, format compliance, and harmful fabrication are different dimensions. A blended quality claim can conceal the failure that matters most to you.
    • Data governance: Get written answers about retention, use of customer data for training, storage location, deletion, subprocessors, tenant separation, and access by vendor personnel. Product controls and contract language should agree.
    • Security and human control: Confirm authentication, role-based access, approval steps, auditability, and the ability to stop or override automated actions. The more consequential the action, the less acceptable an invisible decision path becomes.
    • Integration depth: Distinguish a live, supported integration from a demonstration, roadmap item, or generic API. Verify the exact records the system can read, create, update, and export.
    • Operational resilience: Ask what happens when a model, connector, data source, or downstream system fails. A production workflow needs observable errors, safe fallbacks, ownership, and a recovery procedure.
    • Commercial fit: Calculate the cost of the working process, including usage, integration, human review, monitoring, support, and ongoing evaluation. A low software price can still produce an expensive workflow if reviewers must repair most outputs.
    • Exit viability: Confirm that you can retrieve business data and the operational assets needed to continue elsewhere. For custom development, define ownership of code, prompts, configurations, documentation, and deployment materials before work begins.

    Treat unsupported roadmap promises as unavailable. Record each capability as proven, contractually committed, or absent. Those labels keep a persuasive demonstration from turning future intent into present functionality.

    References and customer logos can help you understand where to investigate, but they do not replace workflow evidence. Ask references about deployment effort, failure handling, support after the sale, and what their internal team still has to operate. A similar industry is useful; a similar data shape, risk level, and workflow is better.

    Run a production-shaped proof before you commit

    A business and engineering team observes an AI proof-of-concept moving through security, human review, monitoring, and final delivery stages.

    A proof should test the operating system around the AI, not just the most attractive output. Keep the workflow narrow enough to inspect closely, but preserve the data conditions, permissions, integrations, and review steps that will exist in production.

    1. Freeze the use case. Give every candidate the same workflow definition, input boundaries, expected output, and failure rules. Do not let each vendor redefine success around its strongest feature.
    2. Build the evaluation set. Include routine examples, ambiguous inputs, incomplete information, edge cases, and requests the system should decline or escalate. Keep a portion of the cases out of vendor-led configuration so you can see how the system handles unfamiliar inputs.
    3. Protect sensitive information. Use de-identified or synthetic material until contractual, security, and internal approvals permit representative production data. When real data becomes necessary, expose only what the approved test requires.
    4. Record configuration work. Track the prompts, rules, connectors, data cleanup, and human assistance required to achieve the result. A system that performs well only after extensive hidden preparation may carry a much higher operating cost than the demonstration implies.
    5. Test the whole handoff. Measure whether users can review, correct, approve, reject, and trace the output inside the intended workflow. A strong answer copied manually between applications may still be a weak production solution.
    6. Force recoverable failures. Remove a source, deny a permission, provide conflicting information, or interrupt a downstream service in a controlled test. Check whether the system fails visibly, preserves state, avoids unsafe actions, and gives an operator a clear recovery path.
    7. Review the evidence by error type. Keep a failure log that identifies what went wrong, its consequence, whether a person detected it, and whether the proposed fix is repeatable. Do not average a severe failure into a reassuring overall score.
    8. Price the observed workflow. Use the actual configuration, workload shape, review effort, support requirement, and integration pattern from the proof. Model an increase and decrease in usage so you can see which charges are fixed and which scale with activity.
    9. Test the exit. Export representative data and configuration, inspect its format, and identify what cannot move. For a custom system, verify access to the repository, build instructions, environment configuration, and operating documentation.

    The proof should leave you with artifacts you can inspect later: the frozen evaluation set, result sheet, failure log, data-flow map, architecture diagram, cost model, operating runbook, and exit plan. If the only durable artifact is a presentation, you have evaluated a sales process rather than a production system.

    Reject any company that fails a non-negotiable gate, even if it has the highest total score. Among the survivors, prefer the option that reaches the required outcome with the clearest controls, lowest operational burden, and most credible path out. That is a more useful definition of leadership than size, visibility, or the longest feature list.

    Key takeaways for your shortlist

    • Define the workflow, owner, data, action, failure boundary, evidence, and exit conditions before collecting vendor names.
    • Compare model providers with model providers, applications with applications, and development companies with development companies.
    • Make task performance, data governance, security, operational resilience, economics, and exit viability pass-or-fail gates.
    • Use the same production-shaped evaluation cases for every candidate, and keep severe errors visible instead of burying them in an average.
    • Count configuration, integration, review, monitoring, and support when calculating cost.
    • Choose the company that can prove the required outcome and remain operable when inputs, systems, or providers change.

    Take your current list and write each company’s intended role beside its name. Remove candidates that solve a different layer, send the survivors the same procurement brief, and do not declare a leader until the proof produces evidence your operational owner is willing to accept.

    References