Tag: Agentic Search Optimization

  • SEO After the Click: Winning AI Search and Agent Traffic

    SEO After the Click: Winning AI Search and Agent Traffic

    You can rank first and still lose the recommendation. A buyer asks an AI assistant for a shortlist, gets a synthesized answer, and never reaches the search result where you lead. Your competitor appears because its name, category, capabilities, and reputation are easier to retrieve and corroborate across the web.

    That does not make SEO obsolete. It changes the job. You still need pages that rank, but you also need a brand that AI systems can identify, trust, describe accurately, and use when helping someone make a decision.

    Key takeaways for AI search and agent traffic

    • Keep investing in technical SEO, content quality, and organic rankings. They support retrieval even when the final answer appears somewhere other than a conventional results page.
    • Give every important product, service, person, and claim one clear source of truth on your site. Make your schema markup and JSON-LD agree with the visible page.
    • Build independent corroboration. Repeated claims on your own domain are messaging; consistent mentions across credible publishers and communities create consensus.
    • Audit ChatGPT, Perplexity, Gemini, and Google AI Overviews with the questions customers actually ask. Record accuracy, citations, competitors, and whether your brand appears at all.
    • Separate AI referrals, brand mentions, and agent requests in your reporting. A crawler request is infrastructure activity, not proof of attention or revenue.

    The optimization target has split into three outcomes
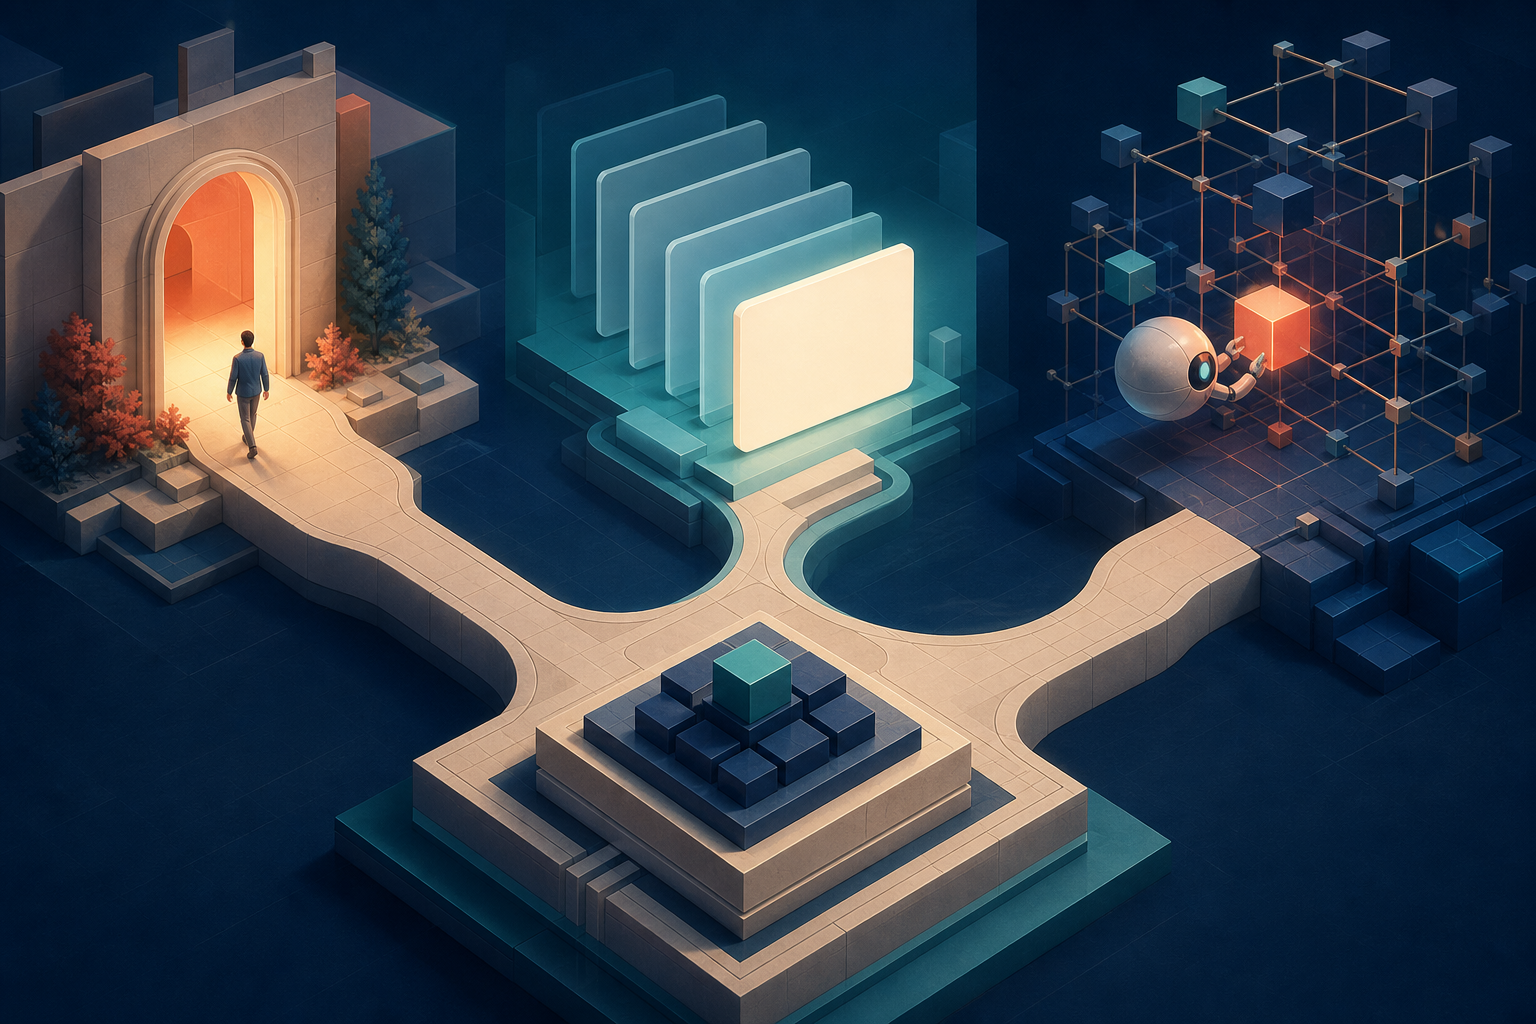
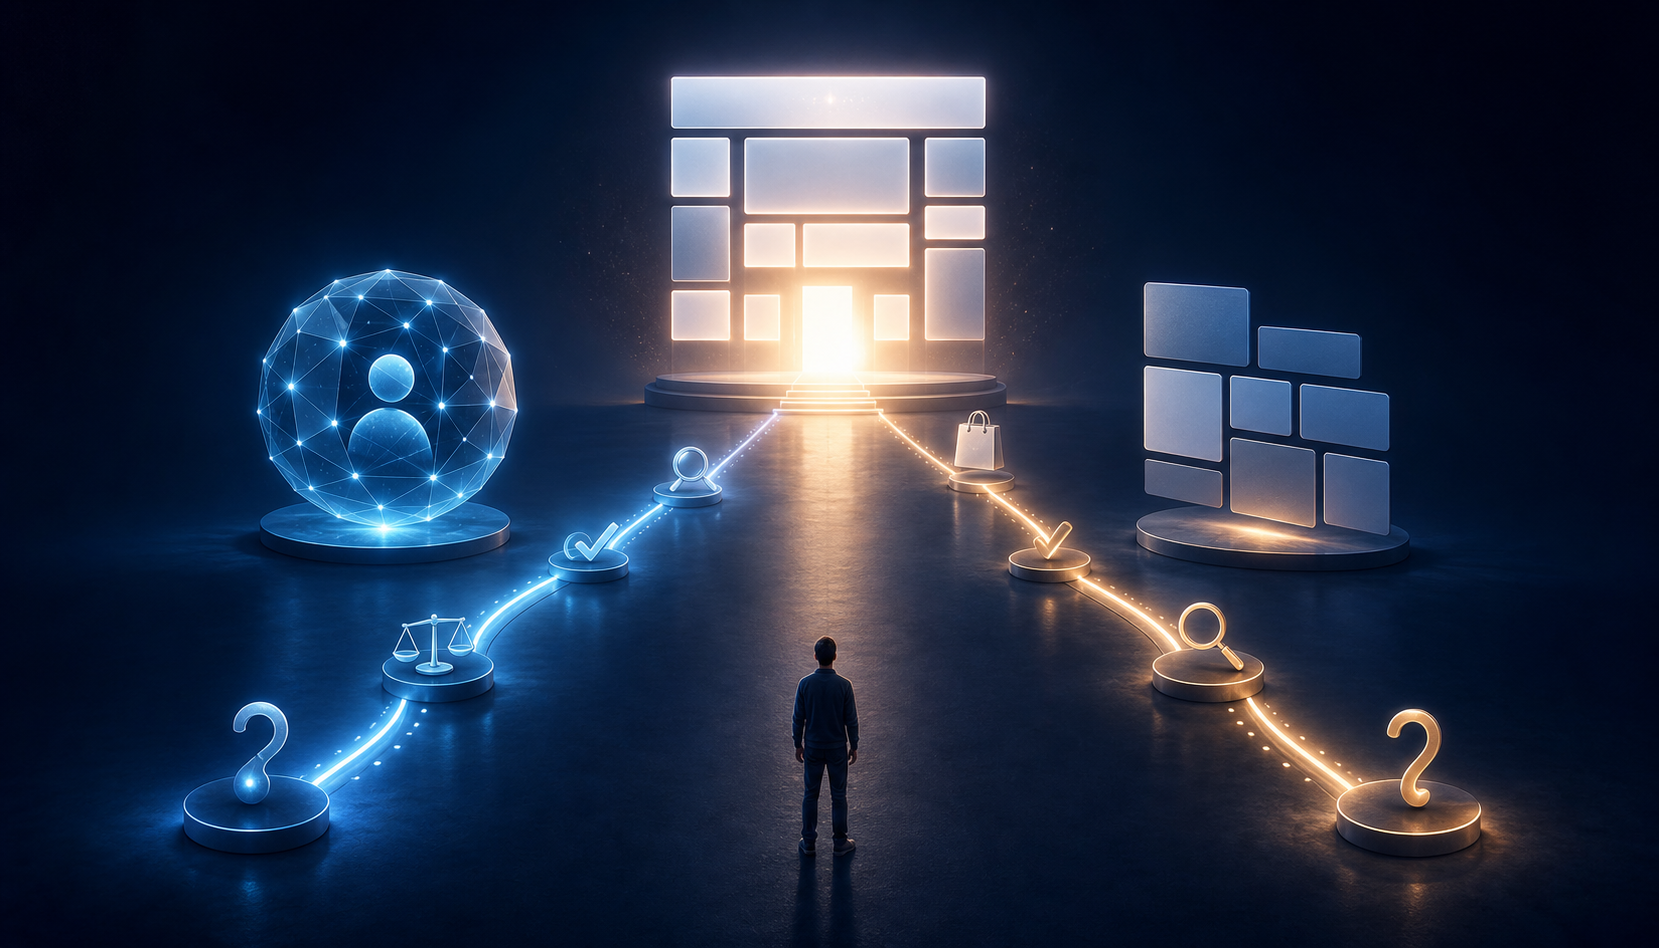
    Three paths from one digital foundation lead toward a human visitor, an abstract search result, and an autonomous agent retrieving information.

    Traditional search optimization concentrated on discoverability, ranking, and the click. AI-mediated discovery adds two more requirements: corroboration and actionability. A useful strategy addresses all three instead of renaming ordinary SEO as GEO and leaving the workflow unchanged.

    AI can make structured technical work faster, but automation still depends on clean data, precise instructions, expert review, and strategic judgment. Your advantage will not come from producing more machine-written pages than everyone else. It will come from making better decisions about which facts deserve to be published, how they should be represented, and where they need independent support.

    Retrieval: can the system find and understand the right page?

    Create one authoritative page for each decision-critical subject. A service page should state what the service is, who it is for, what problem it addresses, where it is available, and what its important limitations are. An expert profile should use the same name, role, and area of expertise that appear on the content attributed to that person.

    Use stable language for your category. If the homepage calls you an AI visibility platform, a product page calls you an answer marketing suite, and an external profile calls you an SEO automation tool, a machine has to decide whether those descriptions refer to the same thing. Choose a primary category, explain adjacent terms, and use that relationship consistently.

    Treat schema markup and JSON-LD as a map of facts that a visitor can verify on the page. Markup should reinforce identity, relationships, authorship, and the subject of the page. It should not contain a more flattering or more complete version of the business than the visible content does. Structured data can reduce ambiguity, but it cannot manufacture third-party trust or guarantee inclusion in an AI answer.

    Do not confuse a carefully written title with control over the final interface. Google has tested AI-driven headline rewrites in search, so your title and headings must communicate the subject clearly even when the displayed wording changes. Optimize the underlying meaning, not only the snippet you hope to see.

    Corroboration: can the system verify the claim elsewhere?

    Your website can establish what you say about yourself. It cannot independently prove that customers, specialists, publishers, and communities recognize you in the same category. AI systems that synthesize answers can compare multiple sources, so a claim supported across independent domains is more defensible than a claim repeated across several pages you control.

    This is why rankings and AI visibility can diverge. A page may perform well in a conventional result while the brand behind it remains absent from synthesized recommendations. The missing ingredient is often not another keyword variation. It is distributed evidence.

    Actionability: can an assistant help the user decide what to do?

    An agent may need more than a persuasive description. It may be comparing price, quality, suitability, availability, prerequisites, or efficiency. Those decision facts should be explicit, current, and easy to distinguish from promotional claims.

    • State what the offering does and what it does not do.
    • Name the customer, use case, geography, or prerequisite that determines fit.
    • Publish current pricing when it is genuinely public. If pricing requires a quote, explain the pricing model and the information needed to obtain one.
    • Use consistent labels and units when presenting plans, features, limits, or performance evidence.
    • Give the user a clear next step on the same page: buy, book, apply, request a quote, check availability, or read the relevant documentation.

    These details help humans as much as machines. The difference is that an agent may discard a vague brand claim before a person ever sees it. As automated comparison grows, brand familiarity alone may be a weaker shortcut than a clear match on price, quality, and suitability.

    Build consensus beyond your own domain

    Retrieval-augmented systems assemble context from material they can find and then generate an answer from that context. When multiple credible sources associate the same entity with the same category or capability, the repeated relationship becomes easier to use. When your site is the only place making the connection, your brand looks like an unsupported outlier.

    The gap between rankings and citations can be substantial. One reported estimate places approximately nine out of ten pages cited by ChatGPT outside the top 20 organic results. Treat that figure as a directional warning rather than a universal rule: a first-page position does not automatically confer visibility in every AI system, and an AI citation does not require a top-20 ranking in every case.

    Start with a claim inventory. For every claim that could affect selection, write down the exact proposition you need the market to understand:

    • Identity: the brand, product, person, or organization being discussed.
    • Category: the primary market or problem to which the entity belongs.
    • Fit: the customer, situation, or constraint for which it is appropriate.
    • Capability: the outcome it can produce, with material limits attached.
    • Evidence: the data, method, example, credential, or customer experience that supports the capability.
    • Currency: the date, edition, plan, location, or version to which a changeable fact applies.

    For each proposition, mark where it appears on your site and where an independent source supports it. A capability mentioned on six owned pages still has only owned support. A trade publication, podcast, customer discussion, expert quotation, industry directory, or community recommendation adds a different kind of evidence.

    Links remain useful, but they are not the only signal worth pursuing. Unlinked brand mentions and diverse publisher coverage can also strengthen entity recognition. The practical implication is that digital PR, expert participation, and reputation work now belong inside the search strategy rather than beside it.

    The strongest consensus assets give other people a reason to refer to you. Original data, a proprietary survey, a transparent methodology, a useful public tool, or a genuinely qualified expert can earn citations without requiring every mention to repeat a marketing line. Make the underlying evidence easy to inspect and the responsible person easy to identify.

    Communities require a different approach. Answer the actual question, disclose your relationship to the brand, and accept that the product may not be the right recommendation. Planted praise and repetitive link drops can create reputation problems rather than consensus. A natural recommendation from an established participant is valuable precisely because you cannot manufacture it on demand.

    Consistency does not mean forcing every publisher to copy your wording. It means that independently written descriptions resolve to the same underlying facts. If credible sources disagree about your category, current features, leadership, or availability, repair the source-of-truth page first and then correct the most consequential external records.

    Audit AI visibility by failure mode

    Do not begin with another content calendar. Begin with the answers your prospects already receive. An AI visibility audit should tell you whether the problem is retrieval, entity clarity, corroboration, positioning, factual accuracy, or attribution.

    1. Build prompts from real decisions. Include category discovery, problem-to-solution questions, comparisons, use-case constraints, reputation questions, and branded fact checks. Examples include: What are the leading providers in this category? Which option fits this constraint? What do people say about this brand? Is this product suitable for this use case?
    2. Use the same prompt set across relevant surfaces. Check ChatGPT, Perplexity, Gemini, and Google AI Overviews where an overview appears. Keep the wording stable so you are comparing the answer, not your own prompt variations.
    3. Capture evidence, not impressions. Record the date, surface, prompt, whether the brand appeared, the exact category and attributes assigned to it, competing brands, cited domains, factual errors, and the action offered to the user.
    4. Classify the failure. Map each weak answer to a specific cause before creating or editing content.
    5. Fix the smallest responsible layer. Correct dangerous or commercially significant errors first. Then repair the owned source of truth, clarify entity relationships, and pursue external corroboration for claims that remain unsupported.
    Observed patternLikely gapFirst move
    Your brand is absent and the relevant owned page is unclear or incompleteRetrieval or entity clarityCreate or revise the authoritative page; align visible facts, headings, internal references, schema markup, and JSON-LD
    Competitors appear through several independent domains while your claims exist only on your siteConsensusDevelop evidence worth citing and earn coverage, expert mentions, customer discussion, or community recognition
    Your brand appears with an outdated feature, category, person, or locationConflicting or stale factsCorrect the owned source of truth and then prioritize the external pages that repeat the error
    Your brand appears for branded prompts but not for category or use-case promptsWeak category associationClarify the primary category and publish decision-focused content that connects your entity to the relevant problem
    Your brand is described accurately but sessions do not riseZero-click behavior or attributionMeasure mentions, branded demand, direct visits, and self-reported discovery before declaring the work ineffective

    A single favorable response is not a durable ranking. Generated answers can vary by system, context, and timing. Preserve your prompt set and evidence so the next audit can show whether a correction persisted, whether citations diversified, and whether competitors displaced you.

    Do not reduce the audit to a brand mention count. A recommendation in the wrong category can be worse than an omission, and an accurate mention supported by an irrelevant page may be fragile. Read the claim, the context, and the cited evidence together.

    Measure human demand and machine activity separately
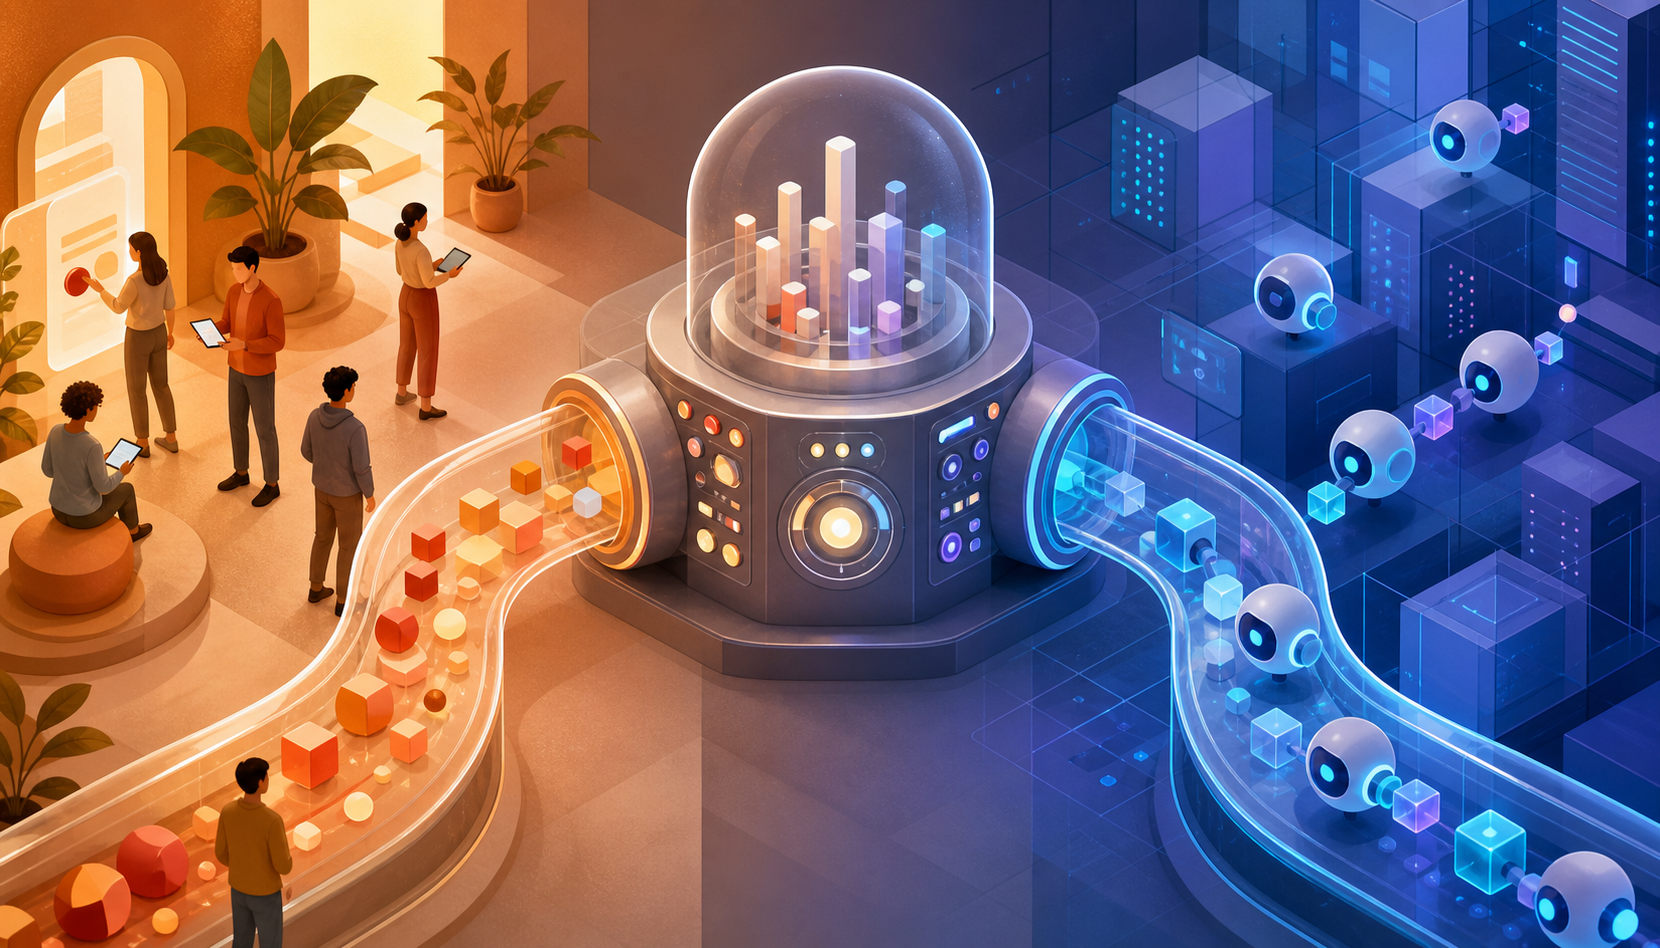
    People and abstract software agents move through separate warm- and cool-colored channels toward an unlabeled measurement console.

    Clicks remain commercially important, but they no longer describe the entire discovery path. Organic click-through rates have declined in reported data for queries displaying AI Overviews since mid-2024, with declines also reported for some queries without AI answers. That is not a reason to abandon search performance reporting. It is a reason to stop using sessions as the sole measure of visibility.

    Agent traffic creates a separate measurement problem. Cloudflare CEO Matthew Prince has said bots represented roughly 20% of web traffic for a long period and projected that bot activity could exceed human activity by 2027. The date is a forecast, not a settled timetable. The operational point is more durable: an agent can retrieve far more pages than a person considering the same decision, so request volume may grow without an equivalent rise in human sessions.

    Use four reporting layers and resist combining them into one traffic number:

    • Search performance: rankings, impressions, click-through rate, organic sessions, and conversions. Keep these metrics because search engines remain a retrieval and demand channel.
    • Answer visibility: the share of your tracked prompts that mention the brand, the share that cite a useful owned or earned page, descriptor accuracy, competitor share of voice, and the diversity of domains supporting decision-critical claims.
    • Agent access: identifiable automated requests, requested URLs, response status, response volume, and infrastructure cost. Separate useful retrieval from errors, loops, and repeated fetching.
    • Business outcomes: qualified leads, sales, branded search, direct visits, AI referral sessions when a referrer is exposed, and self-reported discovery from forms or sales conversations.

    Give each visibility metric a stable denominator. Mention coverage can be calculated as tracked prompts in which the brand appears divided by all prompts checked. Descriptor accuracy can be calculated as correct brand appearances divided by all brand appearances reviewed. Citation coverage can track how often a relevant owned or earned page supports the answer. Keep the prompt set stable between reporting periods, and document additions instead of quietly changing the test.

    Agent requests should never be reported as visits, engagement, or purchase intent. If automated requests rise while answer visibility, branded demand, and qualified outcomes remain flat, you may have a cost increase rather than a marketing gain. If mentions improve while referral sessions decline, inspect branded search, direct demand, and lead-source responses before concluding that AI visibility has no value.

    The economic response also depends on your business model. Publishers supported by advertising face a direct problem because bots do not consume ads like people do. Unique reporting, original data, access controls, and possible licensing arrangements may become more important, although licensing is not a guaranteed substitute for audience revenue. Lead-generation and commerce sites have a different priority: publish accurate selection facts and make the next human action unmistakable.

    Before changing crawler permissions or rate limits, identify which automated systems request which pages, what those requests cost, and whether they contribute to discovery. Blocking broadly can reduce infrastructure load but may also reduce retrieval. Allowing unrestricted access may raise server costs or content-rights concerns. Treat access as a joint technical, commercial, and legal policy rather than a reflexive SEO setting.

    Your next move should happen before you approve another batch of content. Choose one revenue-critical topic, run the same decision prompts across the major AI surfaces, and classify the first failure you find. Fix the source-of-truth page if the facts are unclear; build independent evidence if the facts are clear but unsupported; improve the decision path if the recommendation is accurate but unusable.

    The durable SEO plan is not a choice between rankings and AI visibility. Rankings support retrieval, distributed evidence supports inclusion, and clear decision facts support action. Build those layers deliberately, and you will be prepared whether the next visitor arrives as a person, through an AI answer, or behind an agent.
    References

  • AI Search Foundations for an Assistant-Led Browser

    AI Search Foundations for an Assistant-Led Browser

    You can no longer judge a page only by whether it earns a traditional search listing. The same page may need to attract that listing, supply a direct answer, support a broader synthesis, and give a browser assistant enough clarity to help someone finish a task.

    If you are deciding what to fix first, do not start with AI-only copy tactics. Map the user’s task to the search experience likely to handle it, then make the underlying facts crawlable, consistent, extractable, and usable.

    The browser now routes tasks, not just queries

    The familiar model of search assumes a short sequence: someone enters a query, chooses a result, and visits a page. An assistant-led browser can keep that route, replace part of it with an answer, or continue beyond the page into research and task completion.

    Comet on iOS makes the split unusually clear. It uses Google Search by default for fast, local, and high-intent searches while providing an integrated Perplexity assistant for more involved knowledge work. This is not proof that every browser will make the same product choices. It is a useful operating model for content teams: traditional search and AI answers can serve different moments in the same journey.

    Classify each important page by the outcome its visitor needs:

    • Reach a destination: The user wants a site, location, product page, service page, or other known endpoint. Traditional search visibility and accurate navigational information remain central.
    • Resolve a focused question: The user needs a concise fact, definition, requirement, or procedure. Build a direct-answer module for AEO.
    • Understand a complicated decision: The user needs relationships, conditions, alternatives, or consequences explained together. Build enough connected material for GEO.
    • Complete an action: The user needs to submit, book, contact, select, or prepare something. The page and its interface must remain understandable to both the person and an assisting system.

    Do not assign a page to a category based only on keyword length. A short query can conceal a complicated decision, while a long query can still point to a specific destination. Write down the intended outcome, the facts required to reach it, and the step that should follow. Those three notes will tell you more than a generic label such as informational or transactional.

    Key takeaways

    • Plan for a hybrid search environment. Traditional results, direct answers, synthesized responses, and assistant-led actions can all matter within one journey.
    • Technical SEO, stable entity information, and verifiable facts are shared infrastructure. They are not optional work that begins only after an AI strategy is complete.
    • AEO and GEO solve different retrieval problems: AEO makes a focused answer easy to extract, while GEO makes relationships and context easy to synthesize.
    • Browser readiness extends beyond prose. Navigation, instructions, forms, labels, and completion states must be unambiguous.
    • Fix inaccessible pages, conflicting facts, and unclear task paths before expanding content. More copy cannot repair an unreliable foundation.

    Build the fact layer before optimizing the answer

    Organized layers of connected data tiles and document shapes form a foundation beneath a clear crystalline answer object.

    AI search did not appear without a technical lineage. Many mechanisms associated with modern search can be traced to patent blueprints filed between 2007 and 2016, including work concerned with entities and verification. The practical lesson is not that you need to read every patent. It is that durable search work still depends on machine-accessible information, recognizable entities, consistent relationships, and evidence.

    Create a single operational fact set

    Before rewriting pages, establish the facts every surface should agree on. For a business, product, service, or named expert, that set may include the canonical name, description, role, location, availability conditions, defining attributes, and relationships to other entities. Include only facts you can maintain.

    Then compare that set with the visible page, title and headings, internal links, structured data, profile pages, and any local or commercial landing pages you control. A disagreement is more important than a missing adjective. If one template calls an offering a product, another calls it a service, and the schema describes something else, a machine has to reconcile a conflict you created.

    Check the four controls every page depends on

    • Discovery: Confirm that the page can be reached through ordinary links and that its important content is available to the systems you expect to retrieve it. An orphaned or inaccessible answer is not an AI optimization opportunity.
    • Identity: Name the main entity consistently. Use clear relationships between the organization, people, products, services, locations, and topics represented on the page.
    • Information structure: Give each section a descriptive heading, place the answer near the question it resolves, and keep qualifications beside the claim they modify.
    • Evidence: Connect important claims to specific, trustworthy support. A link should help verify the claim beside it, not merely point to a generic homepage.

    Apply the same controls whether the site uses a traditional CMS or a headless architecture. A headless frontend can still hide essential content from retrieval, and a conventional CMS can still generate contradictory templates. Architecture changes where you inspect the problem; it does not remove the problem.

    JSON-LD belongs in this fact layer. Use it to express the same entities and relationships that a visitor can verify on the page. Do not use structured data as a second, invisible version of the business. Schema cannot make conflicting visible content trustworthy, and it should not introduce claims the page itself does not support.

    Give AEO and GEO different jobs on the same page

    Two illuminated paths lead from the same structured page, one to a single concise answer and the other to a multifaceted synthesis.

    AEO and GEO are often bundled together as AI optimization, but they require different content structures. AEO is built around direct answers, while GEO depends on synthesis and the relationships between concepts. Treating them as synonyms produces pages that are broad without being useful and concise without being complete.

    Build the AEO module around a bounded question

    An answer-engine module should let a reader isolate a question and still understand the response. Use this pattern:

    <!– wp:list {
  • AI-Powered Commerce in Google Search: A UCP Readiness Plan

    AI-Powered Commerce in Google Search: A UCP Readiness Plan

    Your product can be visible in Google and still lose an AI-led sale. The failure may have nothing to do with rankings. An AI system might be unable to confirm the right variant, reconcile two prices, understand a shipping condition, or complete the transaction without handing the shopper back to a conventional store journey.

    Google’s Universal Commerce Protocol, or UCP, gives commerce teams a framework for closing that gap. It is still in beta and intended to support purchases within Gemini and AI search environments, so this is a readiness project rather than a reason to replace your working checkout. The practical goal is to make your catalog understandable, your offer trustworthy, and your transaction systems ready for controlled participation.

    AI search is compressing discovery and checkout

    A conventional ecommerce search journey contains several opportunities for the shopper to fill in missing information. They can open a product page, inspect variants, read the returns page, compare prices, add an item to the cart, and correct a mistake before paying.

    An AI-mediated journey can compress those decisions into one request: find a highly rated waterproof hiking boot in size 10 for less than $200, then buy it. In that flow, the system has to identify a suitable product, select the correct variant, verify the price and terms, and connect the choice to checkout. UCP is designed to standardize communication between consumer AI interfaces and merchant checkout systems.

    That changes the unit of optimization. You are no longer optimizing only a page that persuades a person to click. You are also maintaining a set of facts that an AI system can use to decide whether your offer satisfies a constrained request.

    Do not treat UCP as a new ranking shortcut. A transaction protocol cannot repair an ambiguous product record, an unavailable variant, or a policy that conflicts with checkout. Keep three questions separate:

    • Discovery: Can Google understand when the product is relevant to the shopper’s request?
    • Selection: Can the system confirm that a specific product and variant meet every important constraint?
    • Execution: Can the selected offer move through checkout with the correct price, terms, and merchant relationship intact?

    Map one representative product through all three stages before discussing a broad rollout. If your team cannot identify the system that supplies each important fact, you have found a readiness problem.

    Separate product understanding from transaction plumbing

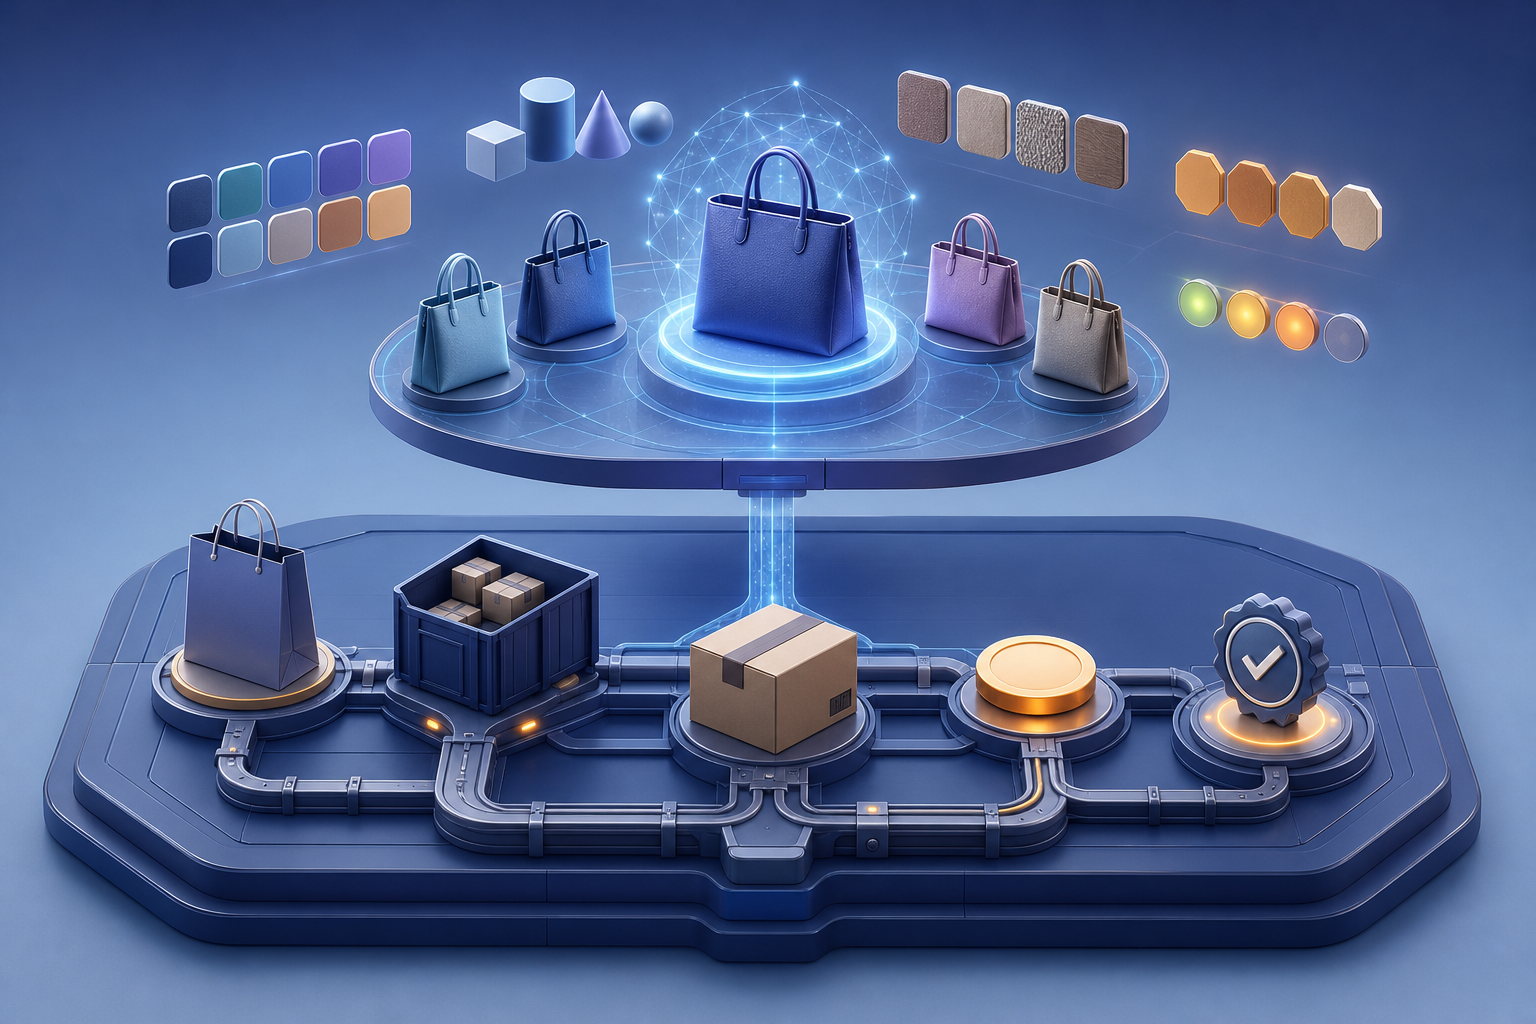
    Cutaway illustration with an upper layer interpreting product variants and a lower layer connecting inventory, payment, delivery, and order confirmation.

    Commerce teams often distribute ownership across SEO, merchandising, feed operations, ecommerce engineering, payments, analytics, and customer service. UCP crosses those boundaries. Someone therefore needs to connect the systems without pretending that one feed or protocol owns the entire customer experience.

    Use this model to define what each layer must provide:

    LayerQuestion it must answerMerchant-controlled inputs
    DiscoveryWhat is this product, and which requests is it relevant to?Product identity, descriptions, category context, and distinguishing attributes
    QualificationDoes the exact offer meet the shopper’s constraints?Variant details, size or other options, price, availability, and product attributes
    TrustAre the commercial terms clear enough to support a decision?Shipping terms, return policy, reliable pricing, and consistent offer information
    TransactionCan the chosen product and variant move through checkout correctly?Checkout integration, selected offer, payment flow, and order handling
    RelationshipWho sells the product and owns the customer relationship?Merchant-of-record status, customer communication, fulfillment, and support

    UCP can build on existing Google Merchant Center shopping feeds. That makes feed quality a sensible starting point, but it does not make the feed your only source of truth. Your product page, catalog platform, policy pages, checkout, and Merchant Center data still need to agree.

    Create a simple ownership register for the fields that affect a purchase. For each field, record its canonical system, business owner, update path, and downstream destinations. Start with product identity, variant identity, price, availability, shipping terms, and returns. When two systems disagree, the register tells the team where the correction belongs.

    This avoids a common operational trap: manually repairing the visible feed while leaving the underlying catalog or policy system unchanged. The temporary correction disappears during the next synchronization, and the contradiction returns. Repair the canonical value first, then verify every downstream representation.

    Build product records that can answer constrained requests

    The fastest way to audit AI-commerce readiness is to turn a buying request into a fact checklist. Consider the request to find a highly rated, waterproof hiking boot in size 10 for less than $200. The candidate record must support several independent decisions: product type, intended use, waterproof status, size availability, price, and rating evidence.

    A page can look complete to a shopper while still leaving one of those decisions unresolved. A lifestyle image might imply outdoor use without confirming waterproof construction. A size selector might show size 10 on the page even though that variant is unavailable. A promotional headline might promise a lower price that is not reflected in the feed or checkout.

    Run a query-to-record audit in this order:

    1. Choose a commercially important product. Use an item with real variants, attributes, and policy conditions. A product with no options will not expose the difficult gaps.
    2. Write realistic constrained requests. Include only requirements your catalog can honestly prove. Do not manufacture a rating, certification, feature, or use case to make the test easier.
    3. Break each request into atomic facts. One fact should answer one decision: product type, attribute, variant, price, availability, shipping condition, or return term.
    4. Locate the canonical value. Identify where each fact originates and where it is transformed before appearing in Merchant Center, on the product page, or at checkout.
    5. Compare every representation. Check the same product and variant across the catalog, feed export, live page, policy content, cart, and checkout.
    6. Classify each failure. Mark a fact as missing, vague, contradictory, stale, or unsupported. Those labels make the remediation clear.
    7. Repair the source and retest. Confirm that the corrected value reaches every surface instead of checking only the system you edited.

    Prioritize facts that can change the purchase decision or the order itself. Product identity and variants come first because the wrong selection creates the wrong order. Price, availability, shipping, and returns come next because they determine whether the offer remains valid at checkout. Rich descriptive copy matters, but it should not conceal a missing operational fact.

    Write product information so that important attributes stand on their own. If waterproof construction affects eligibility, state it as a supported product fact rather than asking a model to infer it from words such as “trail-ready.” If a feature applies only to certain variants, attach it to those variants rather than the entire product family. If the evidence is unavailable, leave the claim out until the business can support it.

    Use the same discipline for product descriptions. Google-oriented copy still needs to help a person, but completeness matters more in an agentic decision. A useful record answers what the item is, which option is being offered, which constraints it satisfies, what it costs, and which conditions apply. Repetition and promotional adjectives do not compensate for a missing fact.

    Treat trust signals as transaction data

    A product package surrounded by linked security, inventory, delivery, returns, payment, and verification symbols, with two visibly inconsistent signals disrupting the network.

    When a shopper browses your store, design, reviews, support content, and policy pages can gradually build confidence. A compressed AI journey gives those cues less room to work. The commercial terms themselves have to carry more of the trust burden.

    That is why free-shipping information, return policies, and reliable pricing belong in the core commerce-data audit. They are not supporting copy to update after the integration. They can determine whether an offer is suitable before checkout begins.

    Check each trust signal for three qualities:

    • Present: The relevant term is available where the product or transaction system needs it.
    • Precise: Conditions, exclusions, applicable regions, variants, or order requirements are stated instead of hidden behind a broad promise.
    • Consistent: The feed, product page, cart, checkout, confirmation, and policy page do not tell different stories.

    Review terms from the perspective of one exact order. Do not ask whether your site “has a returns policy.” Ask which return terms apply to this product, in this condition, for this customer and destination. Do not ask whether you advertise free shipping. Ask whether the selected order actually qualifies and whether checkout produces the same result.

    Use plain operational wording. “Easy returns” is a marketing description, not a usable rule. The real policy should explain the applicable period, product conditions, exclusions, costs, and initiation process as they actually operate. Likewise, a price is useful only when it refers to the selected variant and remains true when the order reaches checkout.

    Contradictions carry a direct commercial cost. A shopper can authorize a purchase based on a term that your checkout, fulfillment team, or support policy cannot honor. That can lead to abandoned transactions, cancellations, returns, support work, and damaged trust. If a condition cannot be represented reliably, keep that offer out of an automated buying path until the systems agree.

    UCP is also designed so that the seller remains the merchant of record and preserves its customer relationship and data. Treat that as an operating responsibility, not just a benefit. Decide who sends confirmations, handles fulfillment questions, processes returns, manages consent, and resolves disputes before accepting an AI-originated order.

    Roll out UCP as a controlled commerce capability

    A beta protocol should not become a hidden dependency for your entire revenue path. Keep your current store and checkout working while you develop the data, governance, and integration needed for AI-assisted transactions. The aim is to learn which parts of your commerce stack are ready without turning early access into a full migration gamble.

    A practical rollout sequence looks like this:

    1. Name one accountable owner. Give that person authority to coordinate SEO, feed operations, merchandising, engineering, payments, analytics, fulfillment, and support.
    2. Define the canonical commerce record. Document where product, variant, price, availability, shipping, and return facts originate.
    3. Audit a narrow product set. Select products that expose meaningful attributes and variants, then complete the query-to-record and trust-signal checks.
    4. Preserve the existing purchase path. Do not remove a proven checkout merely because an AI-native path is being evaluated.
    5. Set release gates. Require accurate product data, consistent policies, correct variant transfer, valid checkout behavior, order confirmation, and clear operational ownership before expanding scope.
    6. Explore the available programs. Google points merchants toward pilot opportunities and related capabilities such as Business Agents and Direct Offers. Evaluate each against the problem it solves rather than enabling every feature at once.
    7. Expand by evidence. Add products only after the previous group can move from request to fulfilled order without unresolved data or policy conflicts.

    Measure the rollout as a funnel with operational checks, not as a single conversion-rate experiment. Your dashboard should distinguish data health, product selection, checkout execution, and post-purchase outcomes. Useful measures include missing or rejected product data, stale offer information, selected products and variants, checkout starts, completed orders, cancellations, returns, and support issues tied to AI-originated transactions. Use only the signals your systems and pilot access can identify reliably.

    Do not combine all failures under “AI traffic.” A product that was never considered has a discovery or qualification problem. A selected product that arrives at checkout with the wrong variant has an integration problem. A completed order that is later canceled because a shipping promise was wrong has a policy or operations problem. The remedy depends on the stage.

    Keep a decision log during the beta. Record which products were included, which systems supplied their facts, which assumptions were made, and why an offer was removed or expanded. That record becomes the foundation for governance when access, interfaces, or program requirements change.

    Key takeaways

    • UCP connects AI consumer interfaces with merchant checkout systems; it does not substitute for accurate product data.
    • Optimize for a purchasable answer: a specific product and variant with enough evidence to satisfy the shopper’s constraints.
    • Assign a canonical source and owner to every fact that can change product selection, price, shipping, returns, or fulfillment.
    • Treat pricing, shipping, and return terms as decision data, then verify that they remain consistent through checkout.
    • Preserve your existing checkout while UCP remains in beta, and start with a narrow, representative product set.
    • Diagnose discovery, qualification, transaction, and post-purchase failures separately so each team fixes the right system.

    Start with one product that has real variants and meaningful policy conditions. Write the request an informed shopper would give an assistant, trace every required fact to its source, and follow the selected offer through checkout. The gaps you find will tell you what to repair before AI-powered commerce becomes a larger part of your Google strategy.

    References

  • How to Optimize Content for Search, Answers, and AI Agents

    How to Optimize Content for Search, Answers, and AI Agents

    You can publish accurate, polished, keyword-relevant content and still struggle for visibility. As AI makes publishing easier, the competitive problem is increasingly sameness across otherwise competent pages. A page that merely restates the standard advice gives a searcher, answer engine, or agent little reason to prefer it.

    You do not need to abandon SEO or start separate programs for every new acronym. You need one operating model that makes each important page discoverable, easy to extract, connected to a clearly defined entity, credible enough to recommend, and complete enough to support a decision.

    Key takeaways

    • Keep the SEO foundation. Clear titles, headings, descriptive language, crawlable content, and intent alignment still determine whether a page gets found and understood.
    • Optimize for four nested outcomes: be found, become the answer, earn the recommendation, and supply enough verified information to be chosen.
    • Design for three kinds of processing: traditional search retrieval, language-model extraction, and entity or knowledge-graph understanding.
    • Refresh useful pages before creating more of the same. Fix the promise, answer order, specificity, entity facts, and technical accessibility.
    • Use structured data to reinforce visible, consistent facts. It cannot repair vague positioning or contradictory information.
    • Let AI accelerate inventory, variation, and formatting work. Keep intent, factual verification, differentiation, and final editorial judgment with a person.

    Optimize for four outcomes, not four disconnected channels

    The language around AI search is unsettled. SEO, AEO, AIEO, GEO, entity SEO, LLM optimization, and assistive agent optimization describe overlapping parts of the same environment. Building a separate workflow around every label creates duplicated briefs, conflicting measurements, and pages that optimize one layer while neglecting the others.

    A more useful approach is to treat optimization as a sequence of outcomes. Each later outcome depends on the earlier ones, so the work compounds instead of restarting whenever the terminology changes.

    LayerRequired outcomeThe question your page must answer
    SEOBe foundCan a system discover, interpret, and match this page to the searcher’s actual need?
    AEOBe the answerCan an answer engine extract a direct, accurate response without reconstructing it from several vague sections?
    AIEOBe recommendedAre the offering, audience, constraints, and evidence clear enough to support a comparison?
    AAOBe chosenCan an assistive agent verify the decisive facts and identify the correct next action?

    This does not mean every informational page must close a transaction. It means the page should completely perform its assigned job. A definition page may need to resolve a concept and point to the next relevant question. A service page may need to establish fit, exclusions, evidence, and a contact path. A product page may need to expose the attributes on which selection depends.

    Use one brief with four acceptance criteria:

    • Discovery: State the problem in the language a person would recognize, then reflect it in the title, primary heading, description, and opening.
    • Extraction: Put the core answer in a self-contained passage. Do not make a system combine an introduction, a definition, and a conclusion to infer your position.
    • Recommendation: Name who the advice or offering is for, when it applies, what constraints matter, and what makes it preferable in that situation.
    • Selection: Supply the facts, corroboration, and next step required to move from consideration to action.

    If a page cannot pass the first layer, work on crawlability and intent before debating agent optimization. If it is discoverable but never mentioned, improve answer clarity and entity definition. If it is mentioned but not recommended, the missing layer is usually decision-grade detail rather than another block of general background.

    Design pages for search, language models, and knowledge graphs

    An isometric web page structure is examined by a search lens, an abstract language model, and a network of linked entity nodes.

    A practical model for AI-era retrieval has three components: traditional search, large language models, and knowledge graphs. Their relative influence can vary by platform and task, but the model prevents you from optimizing only the visible prose or only the technical markup. Think of it as three different readings of the same page.

    Traditional search needs a clear promise and accessible content

    The title, primary heading, description, internal organization, and crawlable copy tell a search system what the page is about. They also tell a person whether the result is worth opening. That second role matters: titles and descriptions are not administrative metadata. They are decision copy.

    Write the title after you can complete this sentence: “This page helps [specific audience] do or decide [specific thing] under [relevant condition].” You do not have to use that entire sentence as the title. Its purpose is to expose a vague brief before the vagueness reaches the page.

    Compare these title shapes:

    • Broad: AI Content Optimization
    • Intent-aligned: How to Optimize Service Pages for AI Recommendations
    • Constraint-aware: How to Optimize Service Pages for AI Recommendations Without Rebuilding the Site

    The sharper version identifies the object, desired outcome, and practical constraint. It helps the right reader recognize the page and gives the page a more precise assignment. A single-site title experiment found a substantial increase in click-through rate after titles were aligned more closely with intent, even though the underlying content was unchanged. That result does not establish a universal lift, but it is a good reason to test packaging before commissioning a replacement page.

    Language models need extractable passages

    A language model can summarize long prose, but making it perform avoidable interpretation introduces ambiguity. Give each important question a direct answer, then support it with reasoning, conditions, and examples.

    • Use a descriptive heading that states the question, decision, or problem covered by the section.
    • Answer that heading in the opening sentence or paragraph of the section.
    • Name the subject instead of relying on a chain of pronouns whose meaning depends on earlier paragraphs.
    • Keep qualifications beside the claim they qualify. Do not hide the limitation several screens later.
    • Separate definitions, procedures, tradeoffs, and examples so each passage can stand on its own.
    • Use lists when the reader needs steps or criteria, not merely to break prose into fragments.

    Extractability is not the same as writing robotic copy. It is the discipline of making the relationship between the question, answer, evidence, and limitation unmistakable.

    Knowledge graphs need stable entity facts

    An agent evaluating organizations, products, or experts needs to understand what each entity is, what it offers, whom it serves, and whether the relevant facts are dependable. Create an entity home: a page you control that states the canonical facts about the entity in clear language.

    For a business, that page should make the following information unambiguous:

    • The canonical name and any commonly used alternate form.
    • A plain description of what the business provides.
    • The audiences, use cases, or markets it serves.
    • The relevant operating area, eligibility conditions, or service constraints.
    • The products, services, people, and locations connected to the business.
    • The evidence a reader can use to assess reliability.
    • The authoritative destination for contact, purchase, booking, or another next action.

    Structured data should reinforce those visible facts, not introduce a second version of them. If the page describes one audience while the markup, profiles, and feeds imply another, more markup increases the contradiction. Resolve the entity definition first, then make the structured representation match it.

    Rendering also matters. Critical copy that appears only after client-side execution is vulnerable because many AI-agent crawlers do not process JavaScript. Inspect the raw HTML of an important page. If its main answer, entity name, decisive attributes, or action path is absent, make that information available in the initial HTML through an appropriate server-rendered or pre-rendered implementation. Treat anything injected only after interaction as potentially unavailable to a crawler that does not execute the page like a full browser.

    Refresh intent, packaging, and specificity before adding pages

    Freshness is not a newer publication date attached to an unchanged answer. In an AI-saturated market, useful freshness comes from restoring alignment between the reader’s current problem, the page’s promise, and the information required to act. That is why refreshing an established page can be more valuable than publishing another broad treatment of the same subject.

    Use this sequence when a page has relevant subject matter but underperforms:

    1. Write the intent in one sentence. State what the reader should be able to do or decide after reading, including the constraint that makes the question difficult.
    2. Compare the promise with the answer. Check whether the title and description promise the same outcome the body actually delivers. If not, change the packaging, the body, or both.
    3. Move the useful answer forward. Remove the generic setup that delays the response. Put the direct answer where the reader can encounter it before the supporting detail.
    4. Replace interchangeable passages. Add boundaries, decision rules, tradeoffs, relevant evidence, and corrections to common misreadings.
    5. Reconcile entity facts. Confirm that names, descriptions, relationships, service details, and next steps agree across the page and the other representations you control.
    6. Validate machine access. Check the initial HTML, heading structure, links, and structured data. The content a person sees and the facts a machine receives should describe the same reality.
    7. Measure the changed behavior. Watch click-through rate to assess the search promise, then use time on page and scroll depth to see whether visitors engage with the answer. Change a limited set of elements when you need to understand what affected the result.

    The pattern of behavior helps you choose the next edit. Visibility without clicks often points to weak or mismatched packaging. Clicks followed by shallow reading often point to a promise-answer mismatch, excessive setup, or the wrong audience. Sustained reading without the intended next action can indicate that the page explains the subject but omits the criteria needed to decide.

    Replace generic competence with decision-grade specificity

    The competitive weakness of AI-assisted copy is often sameness, even when the draft is readable and factually acceptable. A useful editorial test is simple: could an unrelated organization publish this passage unchanged? If so, it probably does not contain enough judgment or context to influence a decision.

    Strengthen the passage by adding at least one of these elements:

    • A boundary: who the advice is not for or when it stops applying.
    • A constraint: the platform, workflow, audience, resources, or operating condition that changes the answer.
    • A tradeoff: what improves, what becomes harder, and which priority should decide between them.
    • A decision rule: the condition under which the reader should choose one path rather than another.
    • A correction: a common interpretation that sounds plausible but leads to the wrong action.
    • Relevant evidence: a fact that substantiates the claim being made, placed beside that claim.

    Specificity does not mean adding decorative detail. A longer page full of definitions can remain generic. The right detail reduces uncertainty at the exact point where the reader or agent must distinguish between options.

    Give AI the work that does not require final judgment

    AI can accelerate content operations without becoming the editor. Use it to inventory recurring topics, group similar pages for review, produce alternative title shapes, identify repeated passages, restructure already verified material, or turn an approved process into a draft checklist.

    Keep the consequential decisions with a person:

    • Choosing the reader and the intent worth serving.
    • Deciding which facts are true, current, relevant, and sufficiently supported.
    • Setting the boundaries and tradeoffs that make the answer useful.
    • Resolving contradictions between page copy, structured data, profiles, and operational systems.
    • Approving the final claims, recommendations, and next action.

    This division of labor preserves the speed advantage while preventing a plausible draft from becoming another indistinguishable page.

    Turn brand facts into a verifiable decision path

    Product, service, document, and location evidence connects through a visible path to an AI assistant making a final choice.

    Traditional search often sent a person through separate awareness, comparison, and decision visits. An assistive interface can perform much of that evaluation internally and present a narrow recommendation. Your page is therefore competing to become an input to the decision, not merely a blue link near the beginning of the journey.

    That changes the role of brand information. A clever positioning line may attract attention, but an agent still needs explicit facts about the entity, offering, audience, suitability, and reliability. If those facts are unclear or inconsistent, a better-understood alternative is easier to choose.

    Build a corroboration chain around the entity home

    Start with the entity home, then trace every decisive fact outward. The goal is not to repeat promotional copy everywhere. It is to prevent the systems involved in research from encountering incompatible identities.

    1. Define the canonical fact. Decide the exact name, description, relationship, service condition, or destination that should be treated as authoritative.
    2. State it visibly. Put the fact in clear, crawlable language on the relevant owned page.
    3. Represent it structurally. Make the structured data describe the same fact and relationship that the visitor can see.
    4. Align controlled profiles and feeds. Correct outdated names, descriptions, destinations, and eligibility details wherever you can manage them.
    5. Check operational data. When availability or selection depends on an API, booking system, inventory system, or internal database, make sure the decision-critical values agree with the public representation.
    6. Preserve a valid action path. The recommended entity must lead to the right contact, booking, purchase, or information destination.

    This broader check matters because the public web index is no longer the only information layer available to assistive systems. Proprietary datasets, APIs, booking platforms, and internal databases can contribute information that is not obtained from an ordinary crawl. Optimizing the page while neglecting the operational record can leave the decision system with conflicting answers.

    Treat push mechanisms as delivery, not authority

    Proactive mechanisms such as IndexNow, structured data feeds, and emerging agent connections can reduce reliance on waiting for a crawler. They do not make a claim trustworthy merely because it arrived faster. Use a supported push method when it fits the platform, but send information that is already accurate, consistent, and attached to a well-defined entity.

    Before releasing or refreshing an important page, run this five-question check:

    1. Can it be found? The title matches a real intent, and the essential content is available to the crawler.
    2. Can it be answered from? A self-contained passage resolves the main question with its necessary qualification.
    3. Can it be understood? The people, organization, offering, and relationships are explicitly named.
    4. Can it be verified? Visible facts, structured data, controlled profiles, and relevant operational records do not contradict one another.
    5. Can it be chosen? The page supplies the fit criteria, constraints, evidence, and correct next action required for its role.

    Start with one commercially or strategically important page rather than rewriting the entire site. Clarify its title, place the answer earlier, add the missing decision criteria, establish the entity facts, inspect the raw HTML, and reconcile the structured and operational representations. Measure how people respond, then carry the successful pattern into the next group of pages.

    The durable advantage in AI-era search is not publishing faster than every competitor. It is reducing uncertainty more completely – for the person asking the question and for every system deciding whether your answer or brand deserves to move forward.

    References

  • How to Make Ecommerce Sites Ready for AI Shopping Agents

    How to Make Ecommerce Sites Ready for AI Shopping Agents

    Your product page can be perfectly usable by a person and still be unreliable for an AI shopping agent. A shopper can interpret layout, infer which option is selected, notice a warning, and back out of a mistake. An agent needs explicit facts, unambiguous choices, and a safe path from finding an item to taking an action.

    If you run an ecommerce or transactional site, the question is no longer just whether an AI system can mention your brand. You also need to know whether an agent can identify the right product, resolve its options, understand the commercial constraints, and complete the next permitted step without guessing. You can prepare for that shift now without treating an experimental protocol as a finished standard.

    The agent journey has four separate failure points

    AI-driven shopping discovery changes the job of a product page. It still has to persuade a person, but it increasingly has to help a machine determine whether a particular product satisfies a particular set of constraints.

    That journey has four layers: discovery, decision, action, and confirmation. Traditional search optimization concentrates heavily on the first. An agent-driven experience can fail at any of the other three even when the page ranks, gets cited, or receives a visit.

    Journey stageWhat the agent must establishTypical site-level failureWhat to fix
    DiscoverWhether the page and product match the user’s needImportant facts exist only in images, interface states, or vague promotional copyPut essential product facts in clear HTML and consistent structured data
    DecideWhich exact product and variant satisfy the constraintsSizes, units, compatibility, availability, or variant relationships are ambiguousTie every choice to a stable product or variant identifier and its current commercial facts
    ActWhich operation is allowed and which inputs it requiresThe agent must guess what buttons do or manipulate a changing document structureExpose narrow, named actions with explicit inputs, outputs, and errors
    ConfirmWhat changed, what it will cost, and whether further approval is requiredA side effect occurs without a review step or a clear resultReturn the resolved item, quantity, price, status, and next required decision

    Use those four stages as separate audit columns. If an agent finds the page but selects the wrong size, you have a decision-layer problem. If it selects the correct variant but cannot add it to a cart reliably, you have an action-layer problem. If it can place the same order twice, you have a confirmation and transaction-safety problem. Calling all three problems “AI visibility” hides the work that actually needs to be done.

    Build a reliable product truth layer before adding agent actions

    An unbranded sneaker and its color, size, material, inventory, price, shipping, and return details connect to a transparent structured foundation.

    An action contract cannot repair an unclear catalog. Before you expose callable tools, make sure an agent can resolve one user request to one exact purchasable item. That requires more than a polished product name and a paragraph of sales copy.

    Create a product record an agent can resolve

    • Give the product, offer, and purchasable variant stable identifiers. Do not make an agent rely on a position in a product grid or a temporary interface label.
    • State concrete attributes with their units and scope. “Lightweight” may help a person scan the page; an actual weight and unit let an agent test a constraint.
    • Connect every option combination to the correct availability, price, image, identifier, and purchasing state. A parent product being available does not establish that the requested variant is available.
    • Make compatibility and exclusions explicit. If a part fits only certain models, regions, account types, or configurations, put that boundary next to the applicable item.
    • State fulfilment and return constraints in language that can be applied to a decision. Avoid scattering a decisive restriction across a tooltip, an image, and a generic policy page.
    • Distinguish a one-time purchase, subscription, reservation, quote request, and other commercial models. An agent should not have to infer the commitment from button copy.

    The same facts may appear in rendered HTML, Product and Offer structured data, a catalog feed, an internal API, a form, and an agent tool response. They should resolve to the same item and current state. If JSON-LD presents one price, visible copy presents another, and the cart calculates a third, an agent has no unambiguous value on which to act.

    Keep description and execution separate

    Schema markup and an agent tool contract solve related but different problems. Product structured data can describe an item, its offer, and its availability. It does not, by itself, grant an agent a reliable function for configuring the item or changing a cart. A tool contract describes an operation the site is prepared to accept.

    A useful shorthand is: schema explains what something is; a tool contract explains what can be done with it. You need both layers to agree, but you should not treat one as a substitute for the other. Keep the human-readable page as the visible source of context, terms, and control as well.

    If you can only fix one layer first, fix product truth. A fast agent action that operates on an ambiguous variant is worse than a slower path that asks the user to choose.

    Expose narrow tools instead of making agents operate your interface

    Google’s early WebMCP preview proposes a structured way for websites to expose tools to browser agents. A site can publish a Tool Contract through the navigator.modelContext browser API so an agent receives named functions instead of having to infer the meaning of links and buttons from the document structure.

    That distinction matters. Raw interface operation is fragile because labels, layouts, overlays, and component states change. A named action can state its purpose, required inputs, expected result, and failure conditions directly. The agent still has to reason about the user’s request, but it should not have to reverse-engineer your checkout interface.

    Choose the API style that matches the interaction

    WebMCP describes two approaches. The declarative API is intended for standard actions that can be defined through HTML forms. The imperative API supports more complex or dynamic interactions that require JavaScript execution.

    • Use a declarative action when the operation already maps cleanly to a form with explicit fields, constraints, and submission behavior.
    • Use an imperative action when the workflow depends on changing state, a multi-part configuration, asynchronous validation, or other logic that a normal form cannot express clearly.
    • Keep the ordinary page and form working as a fallback. An experimental agent layer should enhance the purchasing path, not become its only usable route.

    WebMCP is an early preview, so its details may change. Do not rebuild your checkout around it or assume that implementing it creates a search-ranking advantage. Treat the protocol as an experimental delivery mechanism for an interaction model you should design carefully regardless of which standard eventually carries it.

    Write each tool contract like a small public promise

    1. Name the action after the user’s intent. Search products, retrieve a product, select a variant, add an item to a cart, and begin checkout are clearer responsibilities than click button or process page.
    2. Request only the inputs needed for that action. Define allowable values and identify which fields are required instead of accepting an undifferentiated text payload.
    3. Separate read-only operations from operations that change state. Searching a catalog and submitting an order should not share the same permission or confirmation behavior.
    4. Return stable identifiers and the resolved current state. An add-to-cart result should identify the exact variant, quantity, current price, cart state, and any remaining decision.
    5. Return structured failures. Unavailable variant, unsupported destination, authentication required, invalid quantity, and price changed are outcomes an agent can handle; a generic failure message is not.
    6. Make consequential actions explicit. The contract should reveal when an operation reserves inventory, starts a subscription, submits payment, or creates an order.

    An illustrative shopping sequence might expose searchProducts, getProduct, selectVariant, addToCart, and beginCheckout as separate operations. A submitOrder action would sit behind an explicit review and approval step. Those names illustrate separation of responsibility; they are not prescribed WebMCP syntax.

    Resist the urge to publish one general-purpose function that accepts a natural-language instruction and performs an entire purchase. It may look flexible, but it conceals intermediate decisions, makes permissions harder to enforce, and leaves fewer points where the user can inspect or correct the result.

    Design checkout around permission, reversibility, and proof

    A geometric shopping agent presents a basket as a human hand authorizes checkout through a shield checkpoint, with a parcel, proof token, and return path beyond it.

    An agent acting on behalf of a shopper can create financial consequences. The site therefore needs a permission model based on what an action changes, not merely on whether the agent knows how to call it.

    Use a simple action-risk ladder

    • Read-only actions: searching, filtering, comparing, and retrieving current details can normally run without transactional confirmation.
    • Reversible state changes: adding an item to a cart, removing it, or changing a quantity can proceed when the result is reported clearly and the user can undo it.
    • Commitment actions: placing an order, accepting changed terms, starting a paid subscription, or making a non-refundable booking should require the user to review the resolved details and confirm the commitment.

    Do not let an agent infer a missing variant, quantity, shipping destination, or commitment period when the choice affects the transaction. Return the missing field as a required decision. A short clarification is safer than a confidently completed wrong order.

    Make repeated requests safe

    Agents, browsers, and networks can retry an operation after an interrupted response. Your transaction design should ensure that repeating the same confirmed request does not silently create duplicate orders or charges. In engineering terms, the consequential operation should be idempotent or protected by an equivalent duplicate-prevention mechanism.

    • Assign the attempted transaction a stable request or confirmation identifier.
    • Return a definite status such as pending, completed, rejected, or requiring confirmation rather than an ambiguous success message.
    • If the price or selected item changes before commitment, return the new state and require confirmation again.
    • If the requested variant becomes unavailable, stop and offer alternatives as new choices. Do not substitute a different variant automatically.
    • Record the action invoked, resolved item, result, confirmation event, and safe request identifier so a failed workflow can be investigated.

    Keep payment credentials, authentication secrets, and unnecessary prompt content out of general agent analytics. Operational visibility is useful, but it does not justify collecting sensitive data that the team does not need for diagnosis.

    Preserve a visible human handoff

    The shopper should be able to inspect what the agent selected, edit it in the ordinary interface, and continue without starting over. Before a commitment, show the exact line items and variants, quantities, current charges, applicable fulfilment details, and the action that confirmation will trigger.

    A handoff is not necessarily an agent failure. It is the correct result when authentication, policy, missing information, or financial approval requires the person. Design it as an intentional state with preserved context, not as an error page.

    Test complete shopping tasks, including safe failures

    Testing whether an agent can call a function is not enough. The real unit of quality is a complete user task: the right item is found, the right option is selected, the allowed action succeeds, and the shopper receives an accurate result. A safe stop also counts as correct behavior when required information or permission is missing.

    1. Start with a constrained search, such as a product that must satisfy a compatibility requirement and a specific option.
    2. Test a parent product whose requested variant is unavailable even though another variant remains purchasable.
    3. Change a price or availability state between selection and checkout, then verify that the agent presents the change instead of continuing on stale information.
    4. Attempt a state-changing action without authentication or a required field and verify that the response identifies the next necessary step.
    5. Repeat the same transactional request and verify that it cannot produce a duplicate commitment.
    6. Move from the agent flow to the visible interface and confirm that the exact cart or configuration survives the handoff.

    Track outcomes by journey stage. Useful measures include product-resolution accuracy, completed-task rate, clarification rate, invalid-action rate, duplicate-attempt handling, safe-stop rate, recovery after a structured error, and successful human handoff. Keep discovery events separate from tool invocations and completed actions. Otherwise, an increase in AI-originated visits can conceal a broken decision or checkout path.

    Review failures by cause, not only by agent or channel. If several agents choose the wrong variant, inspect the catalog relationships and labels before tuning prompts. If they choose correctly but fail at cart mutation, inspect the action contract and transaction state. That diagnosis tells you whether the next fix belongs in content, schema, product data, interface logic, or the agent tool layer.

    Key takeaways

    • Treat agent readiness as four connected capabilities: discovery, decision, action, and confirmation.
    • Fix product identity, variant relationships, commercial facts, and policy constraints before exposing purchase tools.
    • Use structured data to describe products and a narrow tool contract to expose permitted actions.
    • Separate read-only, reversible, and commitment actions so confirmation matches the consequence.
    • Make consequential requests duplicate-safe, return structured errors, and preserve a visible human handoff.
    • Treat WebMCP as an early experimental layer and measure complete task outcomes rather than assuming an SEO benefit.

    Choose one high-value journey this week: product search, variant selection, and add to cart is a sensible starting boundary. Resolve every ambiguity in that path, document its allowed actions and failures, and leave order submission behind an explicit user confirmation. Once that narrow journey works reliably, expand one consequential step at a time.

    References

  • Agentic AI for E-commerce: A Leadership Operating Plan

    Agentic AI for E-commerce: A Leadership Operating Plan

    If your leadership team is asking whether agentic AI will make product pages, search traffic, or brand marketing obsolete, the useful answer is no. That is not a reason to wait. The practical change is that more discovery, comparison, filtering, and execution can move into software acting for the shopper.

    You need an operating plan that makes your products easy for both people and machines to understand, verify, and select. You also need measurement that remains honest when part of the buying journey happens beyond your analytics. Here is how to build both without reorganizing the company around an adoption curve nobody can forecast precisely.

    Key takeaways

    • Agentic commerce adds a software decision layer between customer intent and commercial execution. It does not remove the customer or the need to earn trust.
    • Your central readiness question is no longer only whether a product can rank. It is whether the product is eligible to survive a constraint-based selection process.
    • Eligibility depends on complete, consistent product facts, dependable price and availability data, clear policies, technical accessibility, and a transaction path that works.
    • JSON-LD and other machine-readable formats should publish canonical business facts, not compensate for contradictions between your systems.
    • SEO, merchandising, engineering, operations, customer experience, and analytics need named ownership. Agent readiness cannot sit entirely inside the marketing team.
    • Exact attribution will become less reliable as more evaluation happens inside AI systems. Measure readiness directly and interpret commercial outcomes directionally.

    Reframe the agent as a customer proxy

    In this context, agentic AI means software can carry part of a task forward from a person’s intention. The shopper still supplies the need, preferences, budget, and acceptable trade-offs. The software interprets those constraints, investigates options, narrows the field, and may take an action on the shopper’s behalf.

    Consider the difference between a shopper searching for running shoes and a shopper asking for a pair that fits a particular use, budget, size, delivery requirement, and material preference. A traditional search journey requires the person to open results and resolve those constraints manually. An agent can turn the same request into a filtering job before the shopper reaches a product page.

    A useful leadership model separates the journey into distinct decisions:

    • The person defines the desired outcome and acceptable constraints.
    • The agent interprets those constraints and identifies possible candidates.
    • Your published product and business data determine whether your offer can be understood and qualified.
    • Trust signals, policies, and commercial reliability help the agent distinguish between otherwise suitable candidates.
    • Your commerce systems determine whether the selected action can be completed successfully.

    This model changes the executive question. Instead of asking, ‘Will agents replace our customers?’, ask, ‘At which decision could incomplete or unreliable information remove us from consideration?’

    Rankings still matter because agents need candidates to evaluate. They are no longer a sufficient definition of success. A highly visible offer can still be filtered out if its suitability is unclear, its current price cannot be trusted, or its policies create unresolved risk. A lower-profile offer may remain eligible because it answers the request more precisely.

    The transition will not move at the same speed in every market. Categories with standardized products and organized data are easier for software to evaluate. Complex purchases and categories with regulatory constraints introduce more ambiguity. Treat adoption as gradual and category-dependent, then set investment levels for your own selection conditions rather than following a general hype cycle.

    The earliest pressure is likely to appear in discovery and consideration. Natural-language requests can carry far more context than short category queries, while software can perform the initial comparison without exposing every intermediate step. That weakens the assumption that owning a broad head term guarantees access to the consideration set.

    It also changes the job of content. A page should not merely attract a click or repeat a category phrase. It should resolve the variables that determine fit: what the product is, whom it serves, where it does not fit, what it costs, whether it is available, what conditions apply, and why the claims are credible.

    Audit the selection chain, not just the search result

    A glowing software agent passes generic products through several visual filtering and verification stages before making a final selection.

    Eligibility is not an official score supplied by an AI platform. It is a management lens for identifying the facts and systems that must work before an offer can be selected confidently. That makes it more useful than a vague goal such as ‘be ready for agents.’

    Selection stageQuestion the system must resolveEvidence to inspect
    IdentityWhat exactly is being offered?Canonical product name, identifiers, category, variant relationships, and consistent descriptions.
    SuitabilityDoes the offer satisfy the shopper’s constraints?Category-specific attributes, compatibility, dimensions, use conditions, exclusions, and variant-level facts.
    Commercial truthWhat will the shopper pay, and can the item be obtained?Current price, availability, offer conditions, and agreement between public surfaces and commerce systems.
    Trust and riskWhat uncertainty comes with choosing the offer?Clear return terms, restrictions, warranties where relevant, evidence for claims, and consistent policy language.
    ExecutionCan the intended action be completed reliably?Working product and checkout paths, accurate inventory state, dependable payment handling, and technical availability.

    Do not begin this audit with a new AI tool. Begin with a representative product family and a realistic, constraint-rich shopping request. The request should contain the kinds of conditions that would change the answer, not merely the category name.

    1. Write down the product facts, offer conditions, and policies required to answer the request without guessing.
    2. Identify the authoritative system and accountable owner for each fact.
    3. Trace the fact through every surface that publishes it, including the product page, product feeds, structured data, inventory displays, policy pages, and checkout where relevant.
    4. Mark each fact as present and consistent, absent, contradictory, stale, or technically inaccessible.
    5. Repair the authoritative value or propagation path rather than editing one visible symptom.
    6. Republish the affected surfaces and repeat the same shopping request to confirm that the ambiguity has actually disappeared.

    Prioritize contradictions before polishing optional copy. A missing secondary detail may narrow your eligibility for a particular request. Conflicting price, availability, variant, or policy information can undermine confidence in the entire offer. Dynamic facts deserve particular attention because a value that was correct when published can become wrong when updates fail to propagate.

    JSON-LD belongs in this chain, but it is a publication layer rather than a separate version of reality. If your visible page, feed, structured data, and backend expose different values, adding more markup gives the system another conflicting claimant. Define the canonical fact, define which system owns it, and make every machine-readable representation inherit from that source wherever your architecture allows.

    Your audit record should preserve the shopping request, required constraints, expected eligible products, retrieved facts, contradictions, remediation owner, and retest result. That turns agent readiness into a repeatable quality process instead of a collection of screenshots from impressive demonstrations.

    Build agent readiness into normal commerce ownership

    A cross-functional commerce team coordinates product information, inventory, fulfillment, analytics, and customer experience around a shared digital product model.

    Agentic selection crosses organizational boundaries because the deciding signals do. Marketing can improve discovery, but it cannot independently correct an inventory state, repair checkout, define a returns policy, or decide which product database is authoritative. Machine-readable trust depends on technical and operational integrity as much as promotional visibility.

    Assign the fact, the path, and the control

    Team names will vary, but the accountability cannot remain vague. Use the following division as a starting point:

    WorkstreamQuestion it should ownEvidence leadership should request
    Merchandising or product dataWhich attributes and variant relationships are authoritative?A documented source for selection-critical product facts and a queue of unresolved data defects.
    Commerce operationsAre price, availability, and offer conditions current?Exception reporting for mismatches and a defined response when updates fail.
    EngineeringCan machines reliably retrieve the same facts customers see?Healthy publication paths for pages, feeds, structured data, inventory, payment, and checkout.
    SEO, AEO, and GEOWhich intents and constraints determine eligibility, and where is ambiguity visible?Constraint maps, crawl and rendering findings, content gaps, and cross-surface consistency checks.
    Customer experience and policy ownersCan a buyer resolve risk without interpretation or conflicting language?Explicit policy terms, known ambiguity cases, and a path for correcting recurring questions.
    AnalyticsWhat can be observed directly, and what can only be inferred?Metric definitions that separate readiness, observable behavior, commercial outcomes, and unknowns.
    Executive sponsorWho resolves ownership conflicts and approves contingent investment?A prioritized defect register, decision gates, and accepted limits on attribution.

    Attach this work to an existing digital commerce, merchandising, or operational review. A separate agentic AI committee will not help if it lacks authority over product truth and commerce systems. The standing agenda can remain short: which selection-critical defects appeared, which source owns them, which customers or products are exposed, and whether the repair survived retesting.

    Change the content brief from attention to resolution

    Traditional consideration content often accumulates reviews, comparisons, benefit claims, and reassurance. Those assets still have value, but an agent can turn consideration into a strict filtering exercise. Content must therefore make fit and evidence easy to extract, not merely make the page persuasive.

    • State who and what the product is for, including meaningful limitations and exclusions.
    • Use stable terminology for the same attribute across product copy, specifications, feeds, structured data, and policies.
    • Keep claims close to their supporting evidence. Avoid vague superiority language that cannot help resolve a constraint.
    • Put selection-critical facts on the canonical page where they belong instead of scattering answers across thin supporting pages.
    • Make comparisons explicit about the condition that changes the recommendation. Not every product should appear to be the best option for every buyer.
    • Review policy language as decision data. A policy that requires interpretation leaves a risk variable unresolved.

    This favors content quality over page volume. If the answer already belongs on a product or category page, repair that page rather than publishing another near-duplicate merely to target a longer query. The goal is a coherent representation of the offer across every surface an agent may use.

    There is also a brand consequence. Software may filter and select products before a shopper becomes familiar with every candidate. That can improve conversion while weakening brand recognition. Preserve clear brand identity in the product facts and trust signals likely to travel with the offer, and continue building familiarity beyond search. A trusted brand gives both the shopper and the software fewer unresolved reasons to reject the choice.

    Measure readiness honestly and stage your investment

    Agentic journeys make precise attribution harder because more evaluation can happen inside an external AI system. Fewer visible page interactions do not automatically mean your optimization failed, just as a conversion cannot automatically prove that an agent caused the outcome. Leadership should expect directional indicators and blended performance to carry more weight than a perfectly reconstructed path.

    Use a layered scorecard

    Start with measures your business can observe and control:

    • Critical-fact completeness: the share of in-scope products with every attribute required for the tested shopping requests.
    • Cross-surface agreement: whether product pages, feeds, structured data, inventory displays, policies, and checkout expose the same current facts.
    • Update propagation: how reliably a canonical change reaches each public surface, and where stale values persist.
    • Technical availability: whether the relevant content and transaction paths can be retrieved and completed without an avoidable failure.
    • Policy ambiguity: unresolved cases in which offer conditions or customer protections conflict or require interpretation.

    Then place behavioral and commercial indicators beside those readiness measures:

    Leadership questionUseful indicatorWhat it cannot prove
    Are our offers becoming easier to qualify?Improved completeness, consistency, accessibility, and retest results for priority product families.That a specific AI system selected the offer.
    Can we see agent-associated visits?Identifiable referral or journey evidence where analytics exposes it.The total volume of agent influence, because many intermediate decisions may remain hidden.
    Are repaired journeys performing better?Product-family conversion, completion, cancellation, and other relevant outcome trends interpreted with the defect history.That the repair alone caused the change.
    Is the business gaining selection without losing recognition?Blended commercial performance considered alongside branded demand and returning-customer behavior.Exact credit for any single search, content, brand, or agent interaction.

    Report observation, inference, and unknowns separately. ‘The price mismatch was removed and the affected family improved’ is an observation followed by a correlation. ‘Agents generated the improvement’ is a causal claim that requires evidence you may not possess. This distinction protects the budget conversation from false precision.

    Separate foundation work from contingent bets

    The most defensible investments help current customers and current commerce operations even if agent adoption is slower than expected. Approve work that improves product information, removes contradictions, clarifies policies, strengthens technical reliability, or fixes price, inventory, payment, and checkout defects. These changes reduce uncertainty regardless of which interface initiates the purchase.

    Run controlled experiments for questions your analytics cannot answer yet. Reuse realistic shopping requests, record the expected eligibility conditions before testing, and preserve failures as well as successes. A demonstration is useful for discovering defects; it is not enough evidence for a large strategy change.

    Keep bespoke integrations, major budget reallocations, and platform-dependent builds behind explicit decision gates. Before approving one, ask whether the business controls the required data, whether a recurring failure or opportunity has been observed, whether the dependency is stable enough to support the investment, and whether the work remains valuable if adoption develops differently.

    This avoids the two expensive extremes: making sweeping changes because a demonstration looks inevitable, or ignoring agentic behavior until commercial performance forces a rushed response. The practical middle is to repair known eligibility weaknesses now and reserve harder-to-reverse bets for evidence that justifies them.

    At your next operating review, put a real product family and a real constraint-rich shopping request on screen. Trace every fact a shopper’s proxy would need, name the owner of each contradiction, repair the problem at its source, and retest the same request. You will make the business easier to select now without pretending anyone knows the final shape or pace of agentic commerce.

    References

  • Publisher Strategy for Content Markets on the Agentic Web

    Publisher Strategy for Content Markets on the Agentic Web

    An AI agent can use your reporting to answer a question, recommend a product, and help complete a task without sending the user to your page. If your publishing model treats every machine interaction as a future click, you may be assigning value to an event that never happens.

    You do not have to choose between unlimited reuse and disappearing from AI discovery. The practical job is to separate access, interpretation, permission, attribution, and payment. Once those decisions are explicit, you can pursue visibility without quietly giving every commercial use the same terms.

    When the answer performs the task, the traffic bargain weakens

    The agentic web is more than a search box with longer answers. An agent can interpret a person’s intended outcome, gather information, coordinate with other systems, request consent where needed, and take an action. That progression from expressed intent to an outcome changes where publisher content creates value.

    QuestionSearch-led webAgentic webPublisher implication
    What does the user provide?A query to investigateA goal the agent can interpretContent must support decisions, not merely match keywords
    How is information gathered?The user opens and compares pagesThe agent can retrieve and combine relevant materialA page may contribute value without receiving a visit
    Where does the decision happen?Mostly on publisher, merchant, or service pagesPartly inside the agent’s reasoning and recommendation layerQualifications and provenance must survive extraction
    How can an action follow?The user moves between sites and completes each stepThe agent can coordinate systems with the user’s permissionAccurate operational details become as important as persuasive copy
    How can the publisher benefit?Referrals, advertising, subscriptions, leads, or salesThose outcomes may remain, but licensing, attribution, and measured usage can also matterTraffic alone is no longer a complete value model

    The old exchange was easy to understand: a platform discovered a page, displayed a link, and sent some users to it. AI answers can compress that journey. They may rely on a publisher’s work while satisfying the user before a click occurs. That does not make traffic irrelevant. It means traffic, content use, and commercial value can separate.

    Keep these layers distinct in your strategy:

    • Access: Can an agent retrieve the content through a public page, authenticated archive, feed, API, or licensed system?
    • Interpretation: Can it reliably identify the entities, claims, dates, qualifications, and relationships on the page?
    • Permission: What may the operator do with the content, in which products, for which purposes, and for how long?
    • Attribution: Will the output identify the publisher, author, and canonical page in a form the user can follow?
    • Compensation: What event creates payment, how is that event measured, and what reporting lets you verify it?

    A crawl directive addresses access. JSON-LD can improve interpretation. Neither one, by itself, grants a commercial license or establishes a price. A licensing agreement cannot rescue content that is too ambiguous or stale for an agent to use safely. Treating these controls as interchangeable is how publishers either expose too much or block more than they intended.

    The distinction becomes more consequential when agents influence purchases, finance, or healthcare. In those settings, trusted inputs can shape decisions rather than merely inform browsing. If you publish high-stakes material, keep eligibility conditions, uncertainty, audience limits, and safety qualifications adjacent to the claim they modify. A caveat placed several paragraphs away may disappear when an answer system extracts only the central sentence.

    Turn your archive into rights-aware content inventory

    Hands organize articles, photographs, audio, video, and research files into an archive with distinct visual markers for permissions and provenance.

    Do not begin marketplace evaluation with a sitewide yes or no. Begin with an inventory. Most publishing archives contain a mixture of original work, syndicated material, commissioned assets, contributor content, licensed data, outdated pages, and material governed by different agreements. A single technical switch cannot represent those differences.

    Create a rights and readiness ledger at the page or collection level. Record:

    • The canonical URL, content identifier, current version, publication date, and latest substantive update.
    • The publisher, author, contributor, data provider, photographer, illustrator, and any other party whose rights may be involved.
    • Whether the text, images, tables, audio, video, and underlying data can be licensed for the contemplated use.
    • The topic, named entities, geography, audience, and decision context the content supports.
    • The editorial method, evidence trail, and qualifications an agent would need to preserve.
    • The person or team responsible for corrections, expiry decisions, and future updates.
    • The permitted products and uses, prohibited uses, attribution requirements, and withdrawal process.
    • The commercial role of the content: audience acquisition, advertising, subscription retention, lead generation, direct sales, or licensing.

    If a contributor agreement or third-party license does not clearly cover the proposed AI use, stop at that item and get qualified legal review. Marketplace enrollment should not become the event that silently resolves an ambiguous right. The downside can include licensing material you do not control or accepting obligations that conflict with an existing agreement.

    Once the ledger exists, place content into practical access classes:

    • Open for discovery: Public material you want search engines and answer systems to find, summarize within acceptable limits, and cite back to you.
    • Eligible for commercial licensing: Material you control and are willing to provide for defined products, use cases, reporting, attribution, and payment terms.
    • Restricted or excluded: Content with unclear rights, private information, contractual limits, unacceptable substitution risk, unresolved accuracy issues, or no reliable update owner.

    This segmentation lets you test a controlled collection without packaging the entire archive. It also improves negotiation. You can describe what makes a collection distinctive, how it is maintained, which decisions it supports, and what a licensee must do when it changes.

    Length is not a useful proxy for licensing value. A long generic explainer may add little to an agent that already has abundant coverage. A concise specialist archive, original reporting stream, maintained reference set, or decision-grade dataset may be harder to replace. Ask what the content contributes that a model cannot safely infer from generic material.

    Paywalled and secured archives deserve separate attention. High-quality material in those systems may be unavailable to open-web retrieval, which is part of the rationale for licensed access to premium publisher content. That does not mean every paywalled page should be licensed. Compare the potential licensing return with the subscription, exclusivity, and audience value the same material already creates.

    Use a simple value test for each candidate collection. Can you establish the rights? Is the information meaningfully differentiated? Can an agent preserve its important qualifications? Can you keep it current? Would agent use create incremental value, or mainly replace a paid interaction you already own? If you cannot answer those questions, the collection is not ready for pricing.

    Evaluate a content marketplace by its terms and evidence

    Three transparent marketplace mechanisms are inspected side by side for content tracking, attribution, payment, and audit trails.

    Microsoft’s Publisher Content Marketplace offers an early model for a more direct exchange. Its stated design lets publishers set licensing and usage terms, lets AI developers discover content for grounding, and provides usage reporting intended to show how licensed material contributes. The marketplace is also designed to reduce reliance on separate one-off deals.

    Those are useful design principles, but a marketplace description is not the contract you will sign. Participation is presented as voluntary, with publishers retaining ownership and editorial independence. Confirm how each promise appears in the actual agreement, technical controls, reporting fields, and withdrawal procedure.

    Define the licensed use precisely

    The label AI licensing is too broad for a commercial decision. Ask:

    • Does the license cover run-time retrieval and grounding, model training, fine-tuning, evaluation, embeddings, caching, synthetic outputs, or only a defined subset?
    • Can the system use full text, excerpts, facts, media assets, metadata, or structured data? Do different asset types receive different treatment?
    • Which named products, developers, customers, affiliates, or subcontractors can use the material?
    • What territories, languages, audiences, and use cases are included?
    • How long may content and derived representations be retained after an update, withdrawal, or termination?
    • Can rights be sublicensed, bundled, transferred, or used in a product category you would not approve directly?

    Have counsel review the language against your contributor, syndication, data, image, and customer agreements. A marketplace can reduce transaction overhead; it cannot make an overly broad license safe.

    Make attribution and correction operational

    Attribution should be testable, not ceremonial. Specify whether an output displays the publisher name, author where relevant, content date, and a clickable canonical URL. Ask where attribution appears when several publishers contribute to one answer and whether it remains visible when the agent completes a task rather than showing a research-style response.

    Then test the correction path. Who receives a publisher correction? How quickly can an updated version replace the prior one? Are cached passages and generated summaries refreshed? Can the publisher flag a dangerous misrepresentation? What evidence shows that withdrawal reached participating products? These controls matter most for content whose advice changes, expires, or carries material qualifications.

    Interrogate the unit called usage

    A promise of usage-based revenue is incomplete until usage has a definition. It could refer to content retrieval, inclusion in a grounding set, contribution to an answer, a displayed citation, an agent-assisted transaction, or another event. Each unit values the publisher differently.

    Request the reporting schema and a representative record before agreeing to pricing. Determine whether reports identify the content item, version, product, use type, time, geography, citation outcome, and payment calculation. Ask how value is assigned when several items or publishers contribute to the same output. Establish how disputed records, invalid activity, reporting errors, and delayed data are handled.

    Detailed reporting is part of the proposed content-marketplace value exchange. Its usefulness depends on whether you can reconcile the report with your catalog and commercial terms. A total usage number without content-level identity will not tell you which collection deserves more investment, which page needs an update, or whether the payment is correct.

    Protect your ability to change course

    Confirm that you can exclude individual assets or collections, reject sensitive use cases, update prices and terms, correct content, and withdraw future access. Examine exclusivity, renewal, termination, post-termination retention, confidentiality, and conflicts with direct licensing deals. If editorial independence matters, identify the specific contractual and product controls that protect it.

    Early PCM activity included co-design work with Business Insider, Conde Nast, and Hearst, pilots that grounded Microsoft Copilot responses in licensed content, and Yahoo as an early adopter. That demonstrates real industry experimentation. It does not yet establish a universal price, reporting standard, publisher return, or optimal deal structure.

    Use a decision model rather than the size of the marketplace logo. Consider net expected value as licensing revenue, retained audience value, useful market intelligence, and strategic access, minus substitution risk, rights exposure, operational cost, and any value lost from conflicting deals. The expression is an agenda for due diligence, not a precise forecast. If a proposed agreement cannot provide the inputs, that uncertainty belongs in the decision.

    Make content agent-ready without flattening it for machines

    Licensable content can still be difficult to use. An agent needs to determine what a passage claims, which entity it concerns, when it was valid, who stands behind it, and which qualification changes its meaning. Your AEO and GEO work should make those elements easier to identify while preserving the page’s value for a human reader.

    Use this editorial and technical checklist:

    • State the decision-grade answer early. Give the reader the direct answer, rule, or distinction before expanding the reasoning.
    • Attach scope to the claim. Keep audience, geography, version, date, eligibility, and uncertainty in the same sentence or adjacent sentence. Do not strand a critical exception in a distant footnote.
    • Use descriptive headings. A heading should identify the question being resolved, not merely label a broad theme.
    • Expose provenance. Show authorship, editorial ownership, source or methodology information, publication date, substantive update date, and a correction route where appropriate.
    • Name entities consistently. Stable names and identifiers reduce the risk that an agent merges different people, products, organizations, places, or versions.
    • Maintain a canonical identity. Syndicated, translated, updated, and feed versions should point back to a stable record your internal catalog can also recognize.
    • Keep structured data truthful. JSON-LD should describe what is visibly present and should use the most specific accurate type. It should not convert an editorial judgment into a fact or imply an offer the page does not make.
    • Publish corrections as data, not only prose. Update the visible page, version record, feed, API, and licensing catalog so downstream systems do not continue receiving the superseded material.
    • Separate volatile facts from durable analysis. Prices, availability, eligibility, and similar operational facts need a clear update owner; the surrounding explanation can remain stable.
    • Preserve a human reading path. Concise answer blocks are useful, but they should lead into evidence and judgment rather than turn the page into disconnected fragments.

    Apply an extraction test to every important passage. Read the sentence by itself. Can you tell what is being claimed, whom it applies to, when it applies, and what would make it false or unsafe to act on? If the answer changes when the surrounding paragraph disappears, move the necessary qualifier closer.

    Schema helps with interpretation, not truth, authority, access, or permission. A technically valid graph cannot establish that your evidence is sound, that you own every asset, or that an agent has accepted your license. Keep editorial review, rights management, delivery controls, and structured data connected, but do not collapse them into one SEO task.

    Feeds and APIs can give licensed systems a cleaner way to receive content, identifiers, versions, and updates. APIs are also important connective tissue in the agentic environment, where separate systems must coordinate. If you offer a machine-readable delivery surface, document its fields, version behavior, correction process, authentication, permitted uses, and relationship to the canonical page. Delivery access should enforce the agreement rather than leave its boundaries to guesswork.

    Commerce publishers should also distinguish exploration from execution. The Agentic Commerce Protocol focuses on actions arising from express user intent, while the Universal Commerce Protocol addresses the wider shopping experience across platforms and payment systems. They support different stages of the journey rather than serving as simple substitutes. Product content therefore needs to support both evaluation and action: editorial recommendations require evidence and scope, while transactional facts require current, unambiguous fields.

    A brand-owned assistant can provide another route to the same material. It can operate with first-party information, a controlled editorial voice, and a clear point of accountability. That will not eliminate the need to appear in external agents, but it gives loyal users a place to ask questions within an environment you govern. Treat it as owned distribution, not merely a chatbot feature.

    The design tension is real: publishers need content that AI systems can understand without making the human page feel as if it was written for a parser. The answer is not machine-first prose. It is precise prose with visible evidence, stable entities, useful structure, and qualifications that survive reuse.

    Key takeaways for your next licensing decision

    • Separate retrieval, interpretation, permission, attribution, and compensation. Each requires a different control.
    • Inventory rights and update responsibilities before offering an archive. Exclude anything you cannot confidently license or maintain.
    • Segment public discovery content, commercially licensable collections, and restricted material instead of applying one policy to the whole site.
    • Define whether a deal covers grounding, training, caching, generated outputs, or other uses. Do not accept AI use as a sufficient definition.
    • Require content-level reporting that connects a use event to the licensed item, version, product, attribution outcome, and payment calculation.
    • Optimize pages for clear extraction, provenance, freshness, stable identity, and attached qualifications. Do not expect JSON-LD to manufacture authority or grant rights.
    • Preserve correction, exclusion, and withdrawal controls, especially for changing or high-stakes information.
    • Measure licensing revenue alongside referrals, subscriptions, leads, sales, citations, and substitution effects. A single visibility score cannot represent the whole exchange.

    Establish a baseline before making a collection available. Record the referrals, subscriber starts, leads, commerce outcomes, citations, and direct revenue the eligible material already supports. After licensing begins, compare those outcomes with licensed retrieval or grounding activity, attributed mentions, payments, correction latency, and operational cost. Usage reports can help reveal where content contributes value, but only if you can join them to your own content identifiers and business data.

    Do not interpret every decline in referrals as failure if a measured licensing return or higher-value action replaces it. Do not call licensing revenue incremental when the same use displaces subscriptions, direct deals, or profitable visits. Review the collection as a portfolio, then inspect individual items when aggregate results hide winners, stale assets, or damaging substitution.

    Your next move should be a controlled commercial decision, not a sitewide reaction. Choose a collection whose rights, quality, and update process you understand. Define acceptable use, attribution, reporting, correction, payment, and withdrawal before comparing marketplace terms. If a proposal cannot tell you what use occurred, how value was calculated, and how an error can be removed, it is not ready to govern your best content.

    References

  • How AI Search Is Changing Visibility and What to Measure

    How AI Search Is Changing Visibility and What to Measure

    If your average positions look steady while organic growth feels weaker, you may be measuring a journey that no longer happens in the same number of steps. A person can express a fuller need in one query, receive a synthesized answer, and skip follow-up searches that once gave you several chances to earn a click.

    That changes visibility in two ways. Search sessions are becoming more compressed, and AI recommendations are less stable than conventional rankings. Your response should be an intent-based system that measures repeated presence, gives machines unambiguous evidence, and still helps a person make the decision in front of them.

    Search demand can persist while the journey loses steps

    Datos/SparkToro behavioral data from millions of users found that desktop Google searches per U.S. user fell by nearly 20% year over year. The decline in the EU and U.K. was much smaller, at roughly 2% to 3%. This is a per-user change, not proof that Google suddenly lost its audience.

    The surrounding numbers make that distinction important. Traditional search remained about 10% of U.S. desktop activity through 2025. Dedicated AI tools accounted for only 0.77%, while Google AI Mode represented about 0.06% of U.S. desktop events by December. AI adoption is growing, but those shares are too small to support a simple story in which everyone abandoned Google for a chatbot.

    These figures do not prove that AI caused every missing search. They are consistent with a more practical mechanism: AI answers and instant results can resolve part of a need before a person performs a second, third, or fourth query. Search remains central, but each session may generate fewer opportunities for publishers.

    Query shape is changing at the same time. Six-to-nine-word searches are increasing rapidly in the U.S. Very long queries of 15 words or more remain uncommon and volatile, but they show that people are experimenting with more complete descriptions of what they need. You should therefore plan around the decision contained in a query, not just the keyword string that introduces it.

    1. Choose one commercially meaningful decision. Examples include selecting a product for a constrained use case, deciding whether a service fits a particular situation, or comparing two approaches.
    2. List the modifiers that change the answer. Audience, budget, compatibility, location, urgency, skill level, risk tolerance, and intended use can turn superficially similar prompts into different decisions.
    3. Write down the facts required to answer each version. Include suitability, exclusions, specifications, limitations, evidence, availability, and the next action.
    4. Map every important fact to a crawlable location. A claim should have a clear home on a page, not exist only in an image, sales call, private document, or advertising campaign.
    5. Consolidate wording variants, but split genuinely different intents. If ten phrasings lead to the same criteria and answer, one strong resource can serve them. If the criteria change, create a distinct section or page rather than forcing every audience into generic copy.

    This exercise gives you an intent map rather than another keyword list. It also exposes a common visibility gap: the page may mention the right topic while failing to provide the specific facts a search engine or AI system needs to answer the actual decision.

    Measure AI visibility as repeated presence, not a fixed rank

    Several translucent answer surfaces contain changing source arrangements, with the same blue and amber source object recurring in different positions.

    An AI recommendation is generated for a particular request and context. It is not a stored, universally ordered result. Across nearly 3,000 executions of 12 identical prompts by more than 600 volunteers, an identical recommendation list appeared fewer than once in 100 responses. Getting the same list in the same order was rarer still, at fewer than once in 1,000.

    A single screenshot therefore cannot tell you that your brand ranks third in AI search. It tells you that your brand appeared third in one response. Running the same prompt once more and reporting the better result is no more defensible; it replaces one anecdote with another.

    The more useful signal is visibility percentage: how often your brand appears across a defined set of valid responses. Presence proved more stable than exact order, even when the lists themselves changed. Smaller niche categories tended to produce more consistent answers than large markets, so you should not compare percentages across unrelated categories as though they shared the same competitive conditions.

    1. Define the prompt universe before collecting results. Select the audience, decision, market, language, and meaningful constraints. Do not add favorable prompts after seeing the outcome.
    2. Create wording variants that preserve intent. Natural prompts can differ substantially in phrasing while expressing the same underlying need. Keep these in one family.
    3. Separate prompts when the purpose changes. A general product recommendation and a recommendation for gaming, accessibility, enterprise security, or noise cancellation are different intent families if their selection criteria differ.
    4. Repeat tests under documented conditions. Record the product or model, interface, date, locale, login or personalization state when known, exact prompt, and complete response.
    5. Classify the outcome before calculating a rate. A passing mention, a direct recommendation, a citation, and an accurate description are not interchangeable forms of visibility.
    6. Aggregate by intent family. Calculate repeated presence within each decision context before combining anything into an overall number.

    There is not yet a validated universal minimum number of runs, and API output may not reproduce what a person sees in a consumer interface. Treat a small sample as directional. Keep the protocol consistent, retain the underlying responses, and widen the sample before making an expensive content or positioning decision.

    You can still record list order for diagnosis. A persistent pattern may lead you to inspect what distinguishes frequently preferred brands. But exact position should not become the executive KPI, agency guarantee, or performance bonus when the output is inherently variable.

    Make every important claim retrievable, specific, and verifiable

    An illuminated knowledge cabinet organizes documents, a product part, a measuring tool, a video frame, and a sample while a search beam selects one evidence module.

    The next visibility problem is eligibility: can a system identify your entity, retrieve the relevant facts, and determine whether your offer fits the user’s constraints? A page can be persuasive to a person while remaining ambiguous to a machine because the product name changes between sections, limitations are missing, specifications live in images, or structured data conflicts with visible copy.

    Moving from discovery to transaction inside one AI conversation is still a forecast rather than established behavior at scale. It is nevertheless sensible to make product and service information machine-readable now. The same cleanup also helps conventional search, feeds, internal search, accessibility, and human comparison.

    Use this content pattern for each important decision page:

    • Entity: State the exact product, service, organization, person, or location being described. Use the same canonical naming across headings, copy, metadata, and structured data.
    • Direct answer: Address the central decision early. Say who or what the option is for, rather than making the reader assemble an answer from feature copy.
    • Qualifiers: State compatibility requirements, exclusions, prerequisites, geographic limits, and material tradeoffs. Missing limits invite incorrect assumptions.
    • Comparable facts: Present specifications, capabilities, availability, and policies in labeled text or tables where a comparison genuinely helps.
    • Evidence: Add original measurements, first-party data, expert explanation, examples, or a documented method. Include enough context for someone to judge what the evidence does and does not establish.
    • Freshness: Show when time-sensitive facts were reviewed, and correct outdated pages instead of allowing contradictory versions to coexist.
    • Structured data: Apply the most specific relevant schema types and properties, using the same facts shown to the reader. Markup labels evidence; it does not replace evidence or make an unsupported claim true.

    Generic summaries are easy to reproduce and hard to distinguish. Proprietary data and distinctive first-party content give other sites and AI systems information they cannot obtain from another lightly rewritten overview. The useful part is not merely owning data. You need to publish the method, scope, date, definitions, and limitations that make the result interpretable.

    Specificity also protects brand accuracy. When your trial policy, service boundary, compatibility, or availability is unclear, a generative system may fill the gap with a category-level pattern that applies to competitors but not to you. Put the correction on the canonical page, align related pages and schema, and make the wording explicit enough to quote without reconstruction.

    Do not create a separate thin page for every prompt variation. Build around meaning. A strong resource can answer several phrasings when the intended decision is the same, while modular sections can address the qualifiers that materially change the answer.

    Treat video as visual, audio, text, and metadata

    Video can supply evidence that prose struggles to carry: a product in use, a software workflow, a physical dimension, an expert’s explanation, or the exact state of an interface. AI systems can process visual frames, speech, on-screen text, and relationships between them. Some handle these streams together; others depend on separate recognition and transcription components. Either way, clarity determines how much useful information survives.

    Optimize all four layers rather than uploading a polished file and relying on its title:

    • Visual layer: Publish crisp 1080p video where practical. OCR can struggle with footage below 360p, and enhancement cannot reliably restore text that was never captured clearly. Use high contrast, bold readable type, and close enough framing for labels and interface states to be legible.
    • Temporal layer: Keep a key object, label, or action on screen long enough to appear in sampled frames. Rapid cuts may look energetic to a person while causing an automated system to miss the one frame that establishes the fact.
    • Audio layer: Use clear speech, identify speakers, reduce competing noise, and align narration with the action on screen. Deliberate pauses can separate important statements and reduce ambiguity.
    • Text layer: Provide human-verified captions and a transcript. A transcript gives text-dependent systems access to the substance and reduces errors introduced by automatic speech recognition.
    • Metadata layer: Use accurate titles and descriptions, then add applicable VideoObject markup. Properties such as hasPart, transcript, and interactionStatistic should describe real, visible content and verified data.

    Review the finished video without sound, then review only the audio and transcript. If either version loses the core claim, the layers are not reinforcing one another. Fix the asset itself before adding schema; metadata cannot rescue an unreadable demonstration, an incorrect caption, or a missing limitation.

    Use a scorecard that separates exposure, accuracy, and value

    Traffic remains useful, but it no longer describes the whole journey. An answer can mention your brand without linking to it, cite you without recommending you, recommend you inaccurately, or send a visitor who converts. Those are different outcomes and should occupy different rows in your reporting.

    Key takeaways

    • Fewer searches per person do not mean Google has become irrelevant; they mean each journey may contain fewer opportunities.
    • An AI list position is an observation from one response, not a durable rank.
    • Measure repeated brand presence across defined intent families and documented conditions.
    • Separate mentions, recommendations, citations, accuracy, and business outcomes.
    • Improve visibility eligibility with explicit facts, distinctive evidence, consistent structured data, and machine-readable media.

    A practical scorecard can use the following definitions. Set the inclusion rules before testing, and keep the denominator visible beside every percentage.

    MetricHow to calculate itWhat it helps you decide
    AI visibility rateValid responses that mention your brand divided by all valid responses in the defined prompt setWhether you enter the answer set for that intent
    Recommendation rateValid responses that present your brand as a suitable option divided by all valid responsesWhether appearances are incidental or decision-relevant
    First-party citation rateResponses that cite a page you control divided by valid responses on citation-capable surfacesWhether your own evidence is being used, rather than only third-party descriptions
    Accuracy rateReviewed appearances with all predefined material claims correct divided by appearances reviewedWhether greater exposure is reinforcing the right brand facts
    Intent coverageIntent families in which the brand appears divided by all intent families testedWhich audiences or use cases have evidence gaps
    Human search performanceImpressions, clicks, landing-page behavior, and conversions reported by page and intent groupWhether conventional discovery and on-site usefulness are improving
    Business outcomeQualified actions, leads, sales, or other agreed outcomes from attributable journeysWhether visibility work is connected to value rather than exposure alone

    Store the prompt and complete response behind every AI observation. Also retain the model or product, interface, collection date, locale, and personalization state when known. Compare like with like. If a platform changes, preserve the old series and label a new baseline instead of hiding the discontinuity inside a blended average.

    Do not force no-click visibility into a revenue number you cannot defend. Report correlation as correlation, keep attributable conversions separate, and use brand visibility trends to decide where to investigate. The purpose of the scorecard is to improve decisions, not manufacture certainty from a probabilistic system.

    On your next reporting cycle, start with one high-value customer decision. Build its prompt family, collect a documented baseline, identify the most obvious evidence or accuracy gap, and correct that gap on the canonical page. Then rerun the same protocol. That gives you a repeatable visibility practice while the interfaces, models, and search journeys continue to change.

    References

  • Agentic Commerce Protocols: A Practical Readiness Plan

    Agentic Commerce Protocols: A Practical Readiness Plan

    You may already have product schema, shopping feeds, and commerce APIs, yet still not know whether your store is ready for an AI agent to recommend an item, verify the offer, and help complete a purchase. That uncertainty is the real protocol problem. The question is not simply which acronym to support, but whether your product facts and transaction controls survive a machine-to-machine buying journey.

    The safest approach is to separate protocol compatibility from commerce readiness. Build one reliable commerce core, then connect protocols to it through controlled adapters. That gives you a practical path into Google UCP and OpenAI ACP without duplicating pricing, inventory, checkout, or policy logic for every new interface.

    Choose the commerce job before you choose the protocol

    An agentic commerce protocol is an interoperability contract. It defines how participating systems exchange commerce information or request actions. That contract matters, but it does not replace your catalog, pricing engine, order system, payment flow, or fulfillment operation.

    Start by naming the buyer journey you want an agent to support. “We support agentic commerce” is too vague to test. “An agent can identify the correct variant, verify the current offer, create a cart, and return a checkout handoff” is specific enough to build and audit.

    Commerce jobRequired source of truthFailure to prevent
    Discover and compareCatalog, product identity, variants, attributes, and relationshipsThe agent selects the wrong product or compares unlike variants
    Verify an offerCurrent price, currency, availability, eligibility, and fulfillment conditionsThe agent presents an expired, unavailable, or inapplicable offer
    Create a cart or checkout handoffCart, promotion, customer, and checkout servicesA discount is misapplied, a cart is corrupted, or the buyer loses context
    Complete a bounded actionAuthentication, authorization, payment, and order servicesAn unauthorized or duplicate transaction is created
    Confirm and support an orderOrder status, fulfillment, cancellation, and return systemsThe agent promises an action that the merchant cannot honor

    A protocol may cover all, some, or none of those jobs. Build a requirements matrix from the actual specification and label each capability as supported, externally handled, unsupported, or subject to approval. Do not turn partial support into a blanket compatibility claim.

    This also prevents a common architecture mistake: wiring business rules directly into a protocol integration. Protocol-specific code should translate requests and responses. Your existing commerce services should continue deciding what an item costs, whether it can be sold, which promotion applies, and what happens after the order.

    Make product and offer data internally consistent

    A product is surrounded by synchronized catalog, inventory, price, variant, shipping, and availability objects while mismatched duplicates are corrected.

    An AI agent cannot resolve contradictions by calling them “close enough.” If a product page says an item is available, a feed carries yesterday’s price, and the transaction API rejects the variant, the agent has no trustworthy offer to present. More interfaces amplify that inconsistency rather than repairing it.

    Build a field-level inventory before adding endpoints. For every fact exposed to an agent, record its format, owner, update path, and authoritative system.

    1. Stabilize identity. Give each sellable product and variant a durable internal identifier. Use the same identifier wherever your catalog, feed, structured data, cart, and order systems can carry it.
    2. Separate products from offers. Descriptive attributes such as material or compatibility do not change on the same schedule as price, availability, delivery options, or promotion eligibility. Model them separately so mutable offer data can be refreshed without rebuilding the whole product record.
    3. Represent variants explicitly. Size, color, capacity, pack quantity, and other purchase-defining options should resolve to an exact sellable item. Do not make an agent infer the variant from an image filename or a paragraph of marketing copy.
    4. State conditions alongside claims. A price or delivery promise without its currency, region, eligibility, or other applicable condition is incomplete. Return the condition with the value rather than expecting the agent to recover it elsewhere.
    5. Connect policies to the affected offer. Return, cancellation, warranty, subscription, and fulfillment terms should be retrievable in the context where they apply. A generic policy page is useful to people, but it may not resolve an exception attached to one product or offer.
    6. Define conflict precedence. Decide which system wins when the page, JSON-LD, feed, cache, and transaction service disagree. Mutable facts should normally be revalidated against the system that can actually accept the transaction.

    JSON-LD remains useful, but it serves a different role from a transaction API. Structured data helps machines interpret what a public page describes. It does not reserve inventory, authorize a discount, create an order, or prove that a cached offer is still valid. Keep page content, markup, feeds, and APIs aligned, then revalidate consequential facts when the buyer moves from discovery to action.

    Give each response an unambiguous outcome. If current availability cannot be confirmed, return an unavailable or indeterminate state and a safe next step. Do not substitute an old value, invent a delivery promise, or turn missing data into a confident answer.

    Put explicit controls around every agent action

    A discovery request is mostly informational. Creating a cart changes state. Placing an order, cancelling one, or requesting a refund can affect money and customer rights. Your controls should become stricter as the consequence increases.

    Put a protocol adapter between the external agent interface and your internal commerce services. The adapter should translate fields, enforce the supported capability set, reject malformed requests, and produce protocol-compatible errors. It should not become a second pricing engine or an alternative order-management system.

    • Authenticate the caller. Establish which agent, platform, account, or delegated identity is making the request.
    • Authorize the exact action. Knowing who called is not enough. Check whether that identity may read an offer, create a cart, place an order, cancel an order, or request another state change.
    • Revalidate server-side. Price, availability, promotion eligibility, shipping conditions, and order totals must be checked by the commerce system before commitment. Values repeated by the agent are inputs to verify, not facts to trust.
    • Make retries safe. State-changing requests need a stable operation identifier or equivalent idempotency control. A timeout followed by a retry must not create a second order or duplicate another irreversible action.
    • Bound delegated authority. Limit what the agent can buy, change, cancel, or approve. When the requested action exceeds that authority, require an explicit user decision rather than stretching the scope silently.
    • Preserve an audit trail. Record the caller, requested action, authorization result, validated commercial state, resulting transaction, and error outcome. Keep sensitive information out of prompts and general-purpose traces.
    • Return recoverable errors. Tell the agent whether it should refresh an offer, request a missing selection, ask the buyer for confirmation, hand off to checkout, or stop. Do not expose credentials or sensitive internal details in the explanation.

    Route payment credentials and personal data through your approved payment, identity, consent, and privacy flows. An agent conversation or model trace is not a safe substitute for those systems. If the agent only needs to hand the buyer into checkout, give it a constrained handoff mechanism rather than unnecessary access to the full payment process.

    Confirmation also needs state awareness. If the price, item, quantity, delivery terms, or another material condition changes after the buyer’s instruction, stop and present the changed state before committing. Agreement to one offer is not blanket permission to accept a different one.

    Optimize discovery and transaction readiness separately

    Protocol support is not a ranking switch. An agent still needs to discover your products, understand them, decide whether they fit the request, and obtain a valid path to action. A working checkout endpoint does not compensate for vague product information, just as excellent content cannot complete a transaction when the offer cannot be verified.

    Treat the journey as four connected layers:

    • Discovery: Can the system find a canonical product page or catalog record for the buyer’s need?
    • Understanding: Can it identify the product, variant, attributes, compatibility, constraints, and applicable policies without guessing?
    • Decision support: Does your content answer the questions that distinguish this option from alternatives?
    • Action: Can the agent verify the live offer and move into a controlled cart, checkout, or order flow?

    Your public content should do more than repeat a product name and a promotional claim. State concrete specifications, intended use, compatibility, included components, variant differences, purchase conditions, and limitations where they matter. Use consistent terminology across prose, tables, structured data, feeds, and APIs. If one surface calls an option a “starter pack” while another exposes only an unexplained internal code, automated matching becomes less reliable.

    Keep canonical pages useful to people even when machines consume their data. Clear explanations help a buyer verify the recommendation and give answer engines grounded material to cite or summarize. The protocol should extend that experience into live commerce operations, not turn the website into a thin wrapper around an endpoint.

    Measure these layers independently. If products are rarely selected, investigate discoverability, identity, attributes, and decision content. If products are selected but transactions fail, investigate offer freshness, authorization, validation, handoff, and error recovery. Combining both failures into one “AI traffic” metric hides the part you need to fix.

    Roll out one bounded journey and test the failure paths

    An abstract shopping agent travels through a guarded test corridor while unavailable inventory, price changes, payment failure, delivery problems, and permission blocks are contained on side paths.

    Do not begin by exposing every catalog action to every agent. Choose one journey with a clear owner, a known source of truth, and a reversible handoff where possible. A narrow implementation reveals data and control problems before they spread across the whole store.

    1. Define the journey. Write the starting request, required product decisions, supported actions, handoff point, completion signal, and responsible internal team.
    2. Write the field contract. List required and optional fields, identifiers, formats, authority, freshness expectations, and what happens when a value is absent.
    3. Write the action contract. For every state change, define authentication, authorization, validation, confirmation, retry handling, audit output, and safe failure response.
    4. Validate read-only behavior first. Confirm that product identity, variants, current offers, and policies resolve consistently before allowing the integration to alter carts or orders.
    5. Simulate state changes. Exercise order creation, retries, timeouts, revocation, changing prices, unavailable variants, expired promotions, and partial service failures without risking a real buyer’s money.
    6. Restrict the first live scope. Limit the supported catalog, actions, regions, accounts, or other meaningful dimensions until the operational signals are stable.
    7. Expand by evidence. Add capabilities only when the previous scope has reliable data, safe authorization, understandable errors, and an owner who can respond to exceptions.

    Test cases that expose weak integrations

    • The chosen variant goes out of stock after discovery but before checkout.
    • The price or promotion changes between recommendation and commitment.
    • A request times out after the order service succeeds, then the agent retries it.
    • The buyer omits a purchase-defining option such as size, quantity, or configuration.
    • The caller’s authorization is revoked during the session.
    • An internal service succeeds while the protocol adapter fails to return the response.
    • The requested shipping, cancellation, or return condition is not available for that offer.
    • The agent requests an action outside its delegated scope.

    A pass is not merely “the endpoint returned a response.” The response must preserve the correct commercial state, avoid duplicate effects, explain what the agent can do next, and leave an auditable record.

    Measure the agent funnel, not just agent traffic

    Give every metric a numerator, denominator, and operational owner. Useful measures include exact product-resolution rate, successful offer-verification rate, cart or handoff success, authorized action success, duplicate requests safely suppressed, policy exceptions, and completed orders associated with an agent-assisted journey. Track stale-data failures separately from authorization and checkout failures because they require different fixes.

    Preserve the boundary between influence and completion. An agent referral, a protocol request, a cart creation, a checkout handoff, and a paid order are different events. Calling all of them conversions will overstate performance and make protocol decisions harder to defend.

    Key takeaways

    • Define the exact discovery or transaction journey before evaluating a protocol.
    • Keep pricing, inventory, policy, checkout, and order rules in your core commerce systems.
    • Use adapters to connect protocols rather than rebuilding business logic for each interface.
    • Align product pages, JSON-LD, feeds, and APIs, but revalidate mutable facts before consequential actions.
    • Require explicit authentication, action-level authorization, safe retries, bounded delegation, and audit records.
    • Launch with a restricted journey, test failure states, and expand only when each stage has measurable reliability.

    Your next move is to pick one sellable journey and document its fields, actions, authorities, and errors on a single implementation map. That map will show whether your immediate constraint is visibility, catalog quality, transaction safety, or protocol translation. Fix that constraint first, then add the interface that gives the journey a useful route into agentic commerce.

    References

  • How to Adapt Search Visibility and Customer Journeys for AI

    How to Adapt Search Visibility and Customer Journeys for AI

    Your rankings can look stable while part of your customer journey quietly moves elsewhere. A prospect can ask an AI assistant to define the problem, build a shortlist and challenge each option before visiting a website. They may then use Google to verify a detail, arrive through a branded search and convert on a page that receives all the credit.

    If your pages are inconsistent, duplicated or vague, the assistant may omit you, describe you incorrectly or send the prospect to an outdated URL. The answer is not a separate factory for AI content. You need one dependable set of business facts that search engines, AI systems, people and agents acting on their behalf can retrieve, evaluate and carry into a clear next step.

    Plan around the customer’s task, not the search platform

    Do not treat Google and AI assistants as interchangeable traffic sources. They often serve different parts of the same decision.

    One modeled estimate for Q4 2025 placed Google at 77.9% of global digital queries and ChatGPT at 17.1%. The intent split was more revealing: Google held an estimated 90% share of transactional queries, compared with 5% for ChatGPT, while ChatGPT had a much stronger position in generative and creative work. These are directional figures from a model combining client analytics, third-party data and anonymized logs, not a universal census of every query.

    The practical implication is straightforward. Do not dismantle the Google pages that capture high-intent demand. Strengthen the earlier stages where a person is framing a problem, learning terminology, comparing approaches or testing a recommendation. AI can influence the shortlist even when Google, direct traffic or a branded query produces the final visit.

    Start by sorting the questions around one commercially important journey into four jobs:

    • Discover: What kind of solution exists for this problem?
    • Compare: Which options fit my budget, use case, location or constraints?
    • Verify: Is this claim current, supported and applicable to me?
    • Act: What do I need to do next, and what will happen when I do it?

    For every job, name the page you want an AI system or search engine to select. If your team cannot agree on that URL, a retrieval system is unlikely to infer the right one consistently. That gap is more urgent than producing another loosely related blog post.

    Device behavior also affects the handoff. The same 2025 model put 62% of ChatGPT usage on desktop and 63% of Google usage on mobile. That does not establish a conversion pattern, but it is a useful warning: someone may research with AI at a desk and resume through search on a phone. Use stable names, URLs and claims across devices so that the second session confirms what the first one established.

    Map the human and AI journeys to the same pages

    A human and an abstract AI system follow connected paths through the same modular information hub.

    A conventional funnel describes what a person does. An AI-ready journey must also describe what a machine needs to retrieve and explain at each stage. Those are not separate funnels. They are two views of the same handoffs.

    Journey stageWhat the person needsWhat the AI system must resolveWhat the page should provide
    Problem framingLanguage for the problem and its possible causesWhether your entity and content are relevant to the questionA direct explanation, clear scope and links to the next decision
    Option discoveryA credible set of approaches or providersWhat you offer, who it is for and how it differsConsistent product or service names, use cases and qualification criteria
    EvaluationComparable facts, limitations and proofWhich claims apply under which conditionsExplicit criteria, evidence, exclusions, dates and current commercial details
    ActionA low-ambiguity next stepWhere to send the person or how to relay the taskA stable destination, visible prerequisites, a specific call to action and a confirmation path

    This map exposes two common failures. The first is an orphaned educational page that answers the question but never leads to a decision. The second is a conversion page that asks for a booking, trial or purchase without publishing enough information for the prospect to evaluate it. AI can compress several stages into one conversation, so both failures can remove you before a visit occurs.

    Key takeaways

    • Keep strong transactional SEO pages, but connect them to the informational and comparison questions AI assistants handle upstream.
    • Assign one preferred URL to every material intent. If several URLs appear equally valid, consolidate or differentiate them.
    • Put decision-critical facts in visible page content. Do not hide them only in images, downloads, scripts or structured data.
    • Use JSON-LD to mirror the page’s visible facts, not to introduce a second version of those facts.
    • Measure whether AI selects the correct page and represents it accurately, not just whether an identifiable referral arrives.

    Consolidate duplicate pages before expanding your coverage

    AI visibility becomes harder when several URLs compete to answer the same question. Repeated or near-identical pages weaken intent signals, and large language models may cluster the variants and select an outdated one. Publishing more versions can therefore reduce your control over the answer rather than expand your reach.

    Audit duplicates by intent, not just by matching text. Two pages can use different wording and still compete for the same customer task. Conversely, pages built from the same template may deserve to remain separate when they contain genuinely different local rules, prices, eligibility conditions or offers.

    Create a working sheet with one row per indexable URL and these columns: primary question, audience, product or service, location or language, preferred URL, canonical target, last meaningful update and intended next action. Then classify each overlapping page:

    1. Keep: It is the strongest, current page for a distinct intent. Make it the preferred destination and link to it consistently.
    2. Differentiate: It serves a real audience or intent that the primary page does not. Add meaningful differences in examples, terminology, regulations, eligibility, availability or pricing. A swapped place name is not a local strategy.
    3. Consolidate: It no longer deserves a separate destination. Move useful information into the preferred page and use a permanent redirect when the old URL is being retired.
    4. Canonicalize: The variant must remain accessible, but search systems should select another version. Point the canonical tag to the preferred page and keep internal linking consistent with that choice.
    5. Exclude: The page should not participate in discovery. This can apply to staging, archives and republished copies that exist for another operational purpose.

    Campaign pages need the same discipline. Keep a separate landing page when the campaign changes the offer, audience, season, location or other decision context. If only the tracking code and headline change, use one primary interaction page rather than creating a cluster of weak alternatives.

    Localization also requires more than duplicate translation or regional labels. Publish separate regional pages when the content answers a materially different need, use accurate language and regional targeting, and include the local facts a buyer must know. Otherwise, prefer a single strong page over multiple same-language pages serving an identical purpose.

    Syndication can create the same ambiguity across domains. Ask republishing partners to canonicalize to the original, publish a meaningfully reworked version or exclude the copy from indexing. A byline or backlink alone does not tell every retrieval system which full-text version should represent the claim.

    Do not apply redirects or canonical changes to a large group of valuable pages without checking what each URL currently serves. A page that looks repetitive in a crawl may still satisfy a distinct query, campaign or local need. Test the classification on a small group, verify indexing and landing behavior, and then expand the cleanup.

    Make the decision and action layers legible

    An AI guide organizes evidence for a customer beside a clear illuminated path from evaluation to action.

    Give every important page a decision block

    An AI system should not have to assemble your position from a slogan, an old comparison page and a footnote in a downloadable file. Put the minimum complete decision near the top of the preferred page. This is not a demand for simplistic writing. It is a demand for explicit relationships between the question, answer, conditions and evidence.

    A useful decision block contains:

    • Direct answer: State what the product, service or recommendation does in the language of the customer’s question.
    • Best-fit conditions: Name the use cases, audience or constraints under which the answer applies.
    • Exclusions: State when the offer is unavailable or when another approach would be more appropriate.
    • Decision facts: Show the specifications, coverage, requirements, pricing basis or process details needed to compare options.
    • Evidence: Connect important claims to visible support rather than relying on adjectives such as leading, advanced or seamless.
    • Freshness: Display a meaningful update date and revise dependent pages when the underlying fact changes.
    • Next action: Link to the exact place where the visitor can check, calculate, contact, book, buy or continue.

    Write headings that identify the decision being resolved. A heading such as “Eligibility and exclusions” gives both a hurried reader and a retrieval system more information than “What you need to know.” Use tables only for real comparisons, and keep each row based on the same criterion. A table that mixes pricing, brand claims and feature descriptions looks structured while remaining difficult to evaluate.

    JSON-LD belongs behind this visible decision layer. Use it to identify the entities and properties already stated on the page, with the same names, URLs and current values. Do not put an offer, rating, date or availability status in structured data if the visitor sees something different. Machine-readable markup can reduce ambiguity, but it cannot repair contradictory content or guarantee selection in an AI answer.

    Let agents relay or complete a task without guessing

    The machine visitor is usually an intermediary, not the person whose money, data or consent is at stake. Design the action path so an assistant can explain it clearly and an authorized agent can proceed only within the user’s intent.

    • Use stable action destinations. Send booking, checkout, application and contact traffic to durable URLs rather than temporary campaign variants.
    • Expose prerequisites before the action. State location limits, required documents, eligibility, fees, account requirements and expected next steps before asking for information.
    • Label controls by outcome. “Check availability” or “Request an assessment” is clearer than “Continue” because it describes what will happen.
    • Separate explanation from authorization. Public pages can make an offer understandable, while authenticated or consequential actions still require appropriate identity, consent and confirmation.
    • Return useful errors. If an option is unavailable, explain the failed condition and provide a valid alternative instead of sending the visitor back to a generic page.
    • Preserve a human route. Provide a clear support or contact path when the request is ambiguous, exceptional or too consequential to automate safely.

    This work also improves the human journey. Clear prerequisites reduce abandoned forms. Specific controls reduce misclicks. Visible constraints prevent a sales conversation from beginning with a misunderstanding. Agent readiness is largely the discipline of removing guesswork without removing safeguards.

    Measure selection, accuracy, handoff and outcome

    Referral traffic is useful but incomplete. Analytics can identify a source only when a visit arrives with recognizable referral information. It cannot see a recommendation that was copied, remembered or followed later through a branded search. Last-click reporting can therefore reward the final route while hiding the system that shaped the shortlist.

    Build a scorecard around four questions:

    LayerQuestionWhat to recordWhat a failure means
    SelectionDoes the brand appear for an eligible question?Prompt, platform, locale, date, brand inclusion and cited competitorsThe topic, entity or evidence may not be sufficiently clear or available
    AccuracyIs the answer current and supported?Correct claims, outdated claims, unsupported claims and missing conditionsImportant facts may be ambiguous, duplicated or stale
    HandoffDoes the answer lead to the preferred page?Cited URL, canonical status, landing experience and next actionThe system may be selecting a duplicate, weak or outdated destination
    OutcomeDoes the journey produce useful business activity?Identifiable AI referrals, qualified actions, conversions and self-reported discoveryVisibility may not align with intent, or the page may fail after retrieval

    Use a fixed, representative question set rather than collecting only flattering examples. Include discovery, comparison, verification and action questions. For each observation, preserve the exact wording and testing conditions so that later changes are interpretable. Separate questions for which your brand is genuinely eligible from questions where inclusion would be irrelevant.

    When an answer is wrong, diagnose the failure at the right layer:

    • If the correct page is absent, inspect crawlability, indexing, internal links, duplication and canonical signals.
    • If the page is selected but the claim is wrong, make the fact and its conditions explicit in visible content, then align structured data and dependent pages.
    • If the answer is accurate but cites an old URL, consolidate the old version and update internal destinations.
    • If the handoff is correct but nobody acts, inspect whether the page answers the comparison and qualification questions that precede the call to action.
    • If conversions appear without identifiable AI referrals, add a concise discovery question to sales or checkout research and treat the result as supporting evidence, not perfect attribution.

    Start with one high-value journey rather than rewriting the entire site. Choose a decision that already matters to the business, assign its preferred pages, consolidate competing versions, add the decision and action layers, and baseline the four-part scorecard. Expand only after an assistant can find the current page, describe its limits accurately and hand the person to a next step that requires no guesswork.

    References