Tag: Agentic Commerce

  • Google Commerce and Checkout Updates: A Merchant Playbook

    Google Commerce and Checkout Updates: A Merchant Playbook

    If your commerce strategy ends when a shopper clicks through to a product page, Google’s transaction layer creates a new gap. Products may now be discovered, evaluated and purchased within a Google experience, but only when your catalog data, payment processing and offer terms can support the same transaction.

    Your immediate decision isn’t simply whether to adopt AI shopping. You need to determine which offers are eligible, whether Merchant Center can express them accurately, whether your processor can complete the payment and whether the customer sees consistent terms from discovery through purchase.

    Google is turning some discovery journeys into checkout journeys

    Google’s Universal Commerce Protocol, or UCP, supports a native Buy button that can keep checkout on Google while the merchant remains the seller of record. The transaction can use credentials stored in Google Wallet, and the payment processor must support Google Pay tokens. Merchants implement the associated Merchant Center signal through the native_commerce attribute.

    This changes what commerce readiness means. In a conventional search journey, Google primarily needs enough reliable information to match a product with a query and send the shopper to the merchant. In a native checkout journey, the offer must also be executable. A discoverable product with an unsupported payment path, incomplete transaction data or conflicting terms isn’t transaction-ready.

    That distinction matters for SEO, AEO and GEO teams. Product schema and clear page content can help systems understand an offer, but they don’t replace a required Merchant Center attribute or payment integration. Treat page markup, catalog feeds and transaction infrastructure as connected layers with different jobs.

    A shorter path to payment may reduce friction in experiences such as Gemini and AI Mode, but conversion improvement is a possibility, not a guaranteed result. Merchant eligibility, offer quality, payment reliability and customer confidence still determine whether the shorter journey performs better.

    Separate transaction readiness from policy eligibility
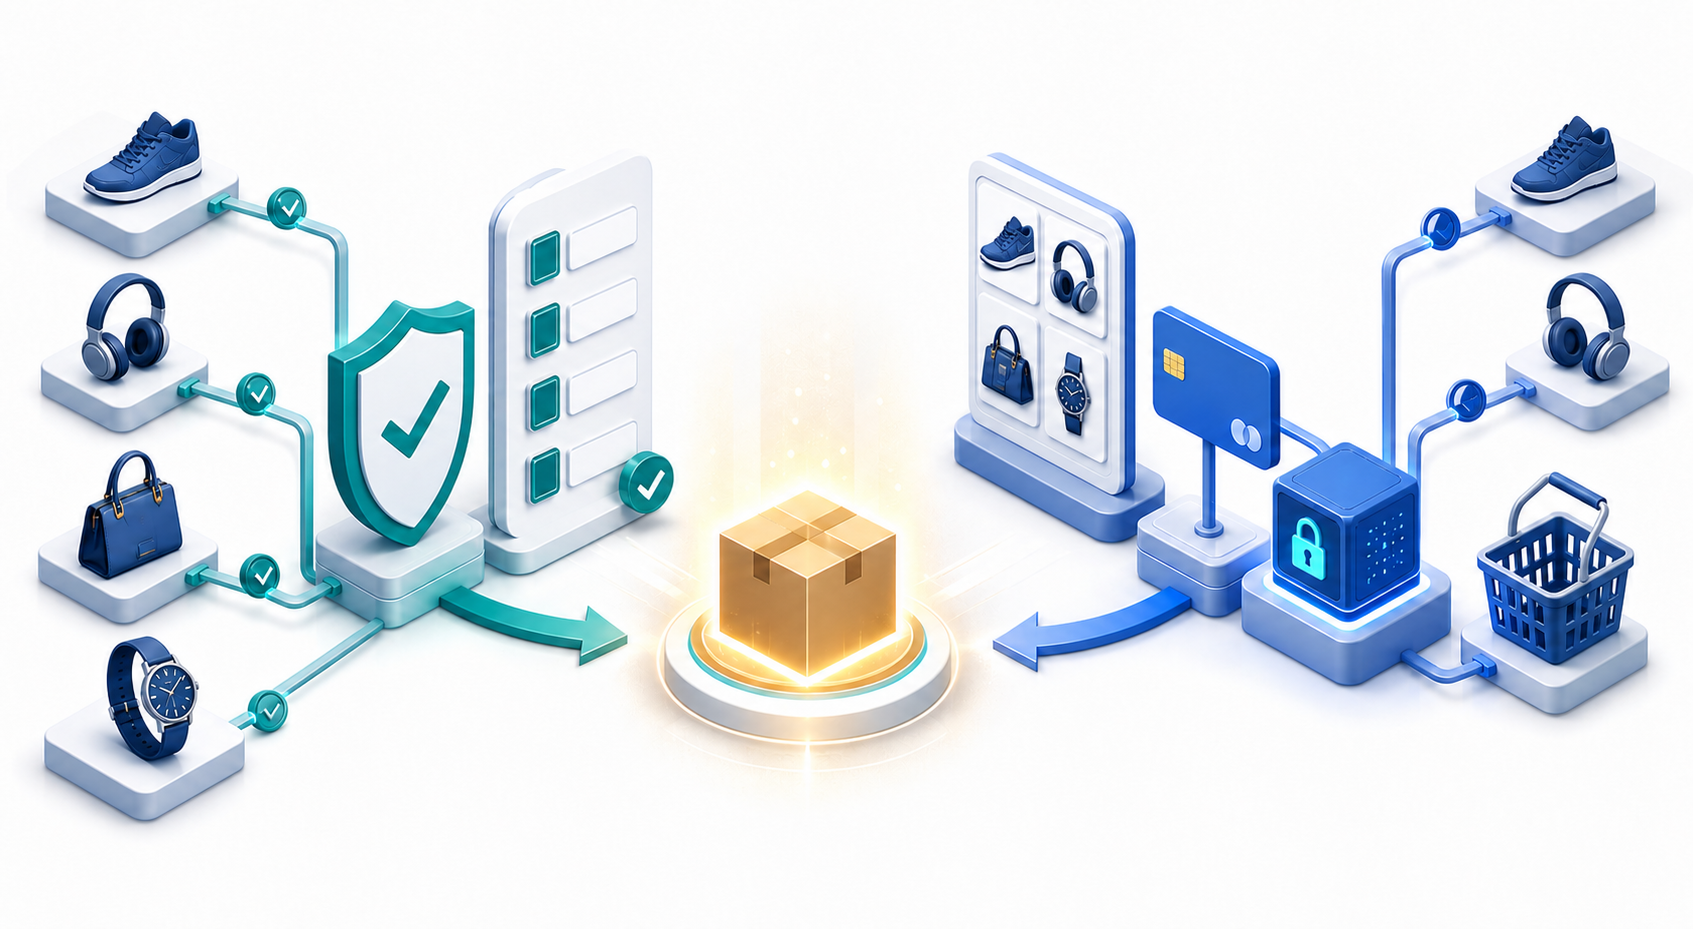
    Generic products pass through separate compliance and transaction checkpoints before converging on a completed order package.

    Google’s broader checkout capability and its recurring prescription billing expansion affect different parts of the commerce stack. UCP is a transaction mechanism. The pharmacy change is a category-specific policy expansion for certified online pharmacies in the United States. Combining them into one implementation project can hide the gate that is actually blocking an offer.

    Commerce changeWhen it mattersRequired elementsWhat it changes
    UCP-powered checkoutWhen a merchant is preparing an on-Google purchase flownative_commerce in Merchant Center and a processor that supports Google Pay tokensThe shopper can use stored Google Wallet credentials while the merchant remains the seller of record
    Recurring prescription billingWhen a certified U.S. online pharmacy promotes an eligible subscription, bundle or consultationMerchant certification, an accurate subscription_cost value, transparent landing-page terms and fees, and continued Healthcare & Medicine policy complianceEligible prescription offers can use recurring billing, subject to Google’s category requirements

    For certified U.S. online pharmacies, the expanded policy covers recurring prescription purchases, qualifying bundles and recurring prescription-eligibility consultations. A bundle may combine medication with services such as coaching or a treatment program, but the medication must remain the primary product. A consultation may be offered on its own or alongside medication when its purpose is to assess prescription eligibility.

    The expansion doesn’t remove the existing certification or Healthcare & Medicine requirements. It also doesn’t turn an eligibility assessment into guaranteed access to a prescription. Describe the consultation as an assessment, make the recurring arrangement explicit and ensure the promoted offer matches what the customer can actually purchase.

    This gives you two independent questions to answer. First, is the offer allowed? Second, can your systems execute it through the intended Google experience? A policy-approved offer can still fail the technical test, while a technically complete transaction can still be ineligible for promotion.

    Build the commerce stack in the right order
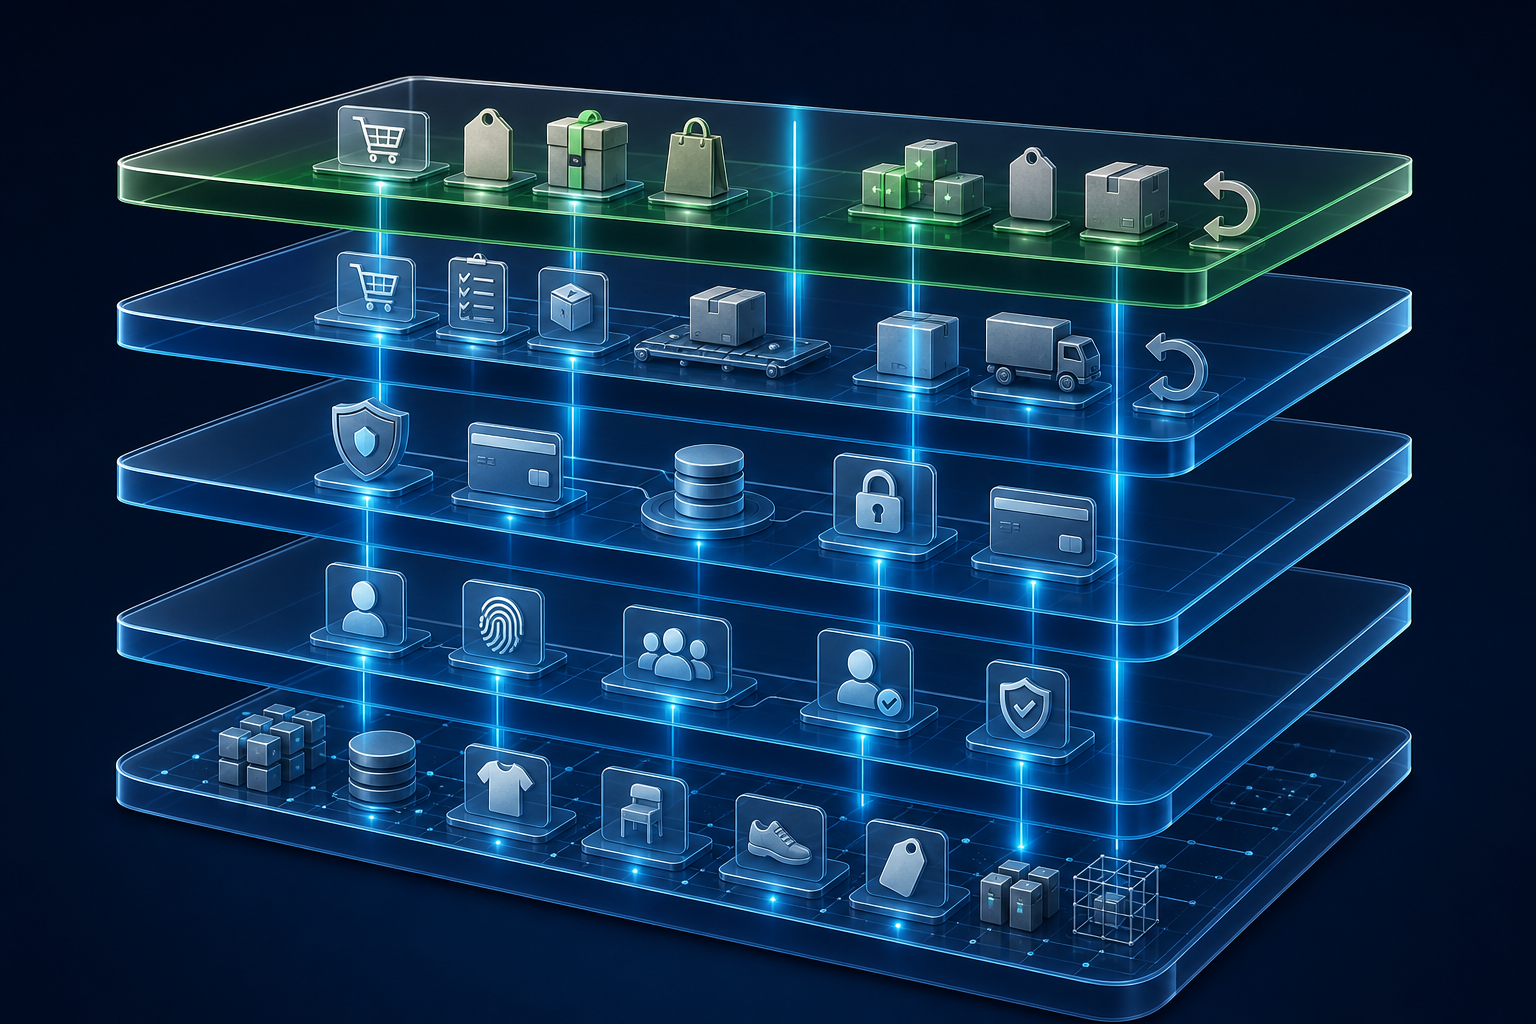
    A layered digital commerce stack links catalog objects, account controls, payment processing, order management, and customer offers.

    Don’t begin by adding an attribute across the catalog. Start with one clearly defined offer and trace it from Merchant Center to the confirmed order. That limits the number of variables when something doesn’t match.

    1. Define the offer as a customer would understand it. Record the product being purchased, whether billing recurs, what the subscription costs, what a bundle contains, which item is primary, and which terms or fees apply. If the team cannot describe the offer consistently in one internal record, the feed and landing page are unlikely to agree.
    2. Create an offer-level eligibility matrix. Use one row per offer, not one row per business. Track the applicable market, certification status, policy eligibility, required Merchant Center attribute, processor status, landing-page match and review status. This prevents approval for one product from being treated as approval for an entire catalog.
    3. Confirm the payment path before activating native commerce. Ask the payment team or processor to verify support for Google Pay tokens in the intended flow. General support for a familiar wallet experience isn’t specific enough; the requirement concerns the tokens used to execute the UCP-powered transaction.
    4. Submit only the attributes that apply. Use native_commerce for the UCP checkout implementation. For an eligible recurring prescription offer, submit the subscription cost accurately through subscription_cost. Don’t copy a recurring-billing value to one-time products or enable a transaction signal before its corresponding payment path is ready.
    5. Make the landing page agree with the feed. A shopper should see the same product, recurring cost, bundle composition, fees and material terms represented in Merchant Center. For pharmacy bundles, the page must also make it clear that medication is the primary product rather than presenting the service as the main purchase.
    6. Test the seller-of-record handoff. Google may host the checkout interface, but the merchant retains the seller-of-record role. Confirm that your order system receives what it needs to identify, fulfill and support the purchase. A successful payment that produces an incomplete or unusable order isn’t a successful implementation.
    7. Reconcile measurement across systems. Establish a baseline for checkout starts, completed payments, failed payments and confirmed orders before rollout. Because an on-Google checkout can remove parts of the usual website journey, pageview-only reporting may not describe the full funnel. Reconcile Merchant Center activity, processor outcomes and order records instead of relying on a single web session.
    8. Request a review only after correcting the underlying issue. A previously disapproved pharmacy account can seek another review once it meets the expanded requirements. Preserve the corrected feed values, visible landing-page terms, certification status and payment confirmation so the team can verify that the reviewed configuration is the one actually in production.

    This sequence also clarifies ownership. SEO and content teams can define the offer and maintain page clarity. Feed specialists can implement Merchant Center attributes. Payments teams can validate token support. Compliance teams can determine whether a regulated offer is eligible. Analytics and commerce operations can verify that a paid transaction becomes a usable order. No single discipline can safely infer that the other layers are ready.

    Offer consistency is now part of transaction architecture

    Merchants often treat feed discrepancies as catalog housekeeping. Native checkout raises the consequence. Google isn’t only using the offer to decide whether and where it should appear; the offer data can help shape a transaction. A mismatch can therefore affect customer understanding, policy eligibility or the ability to complete the purchase.

    • The page describes recurring billing, but the subscription cost is missing or inaccurate. Correct the Merchant Center value and verify it against the live offer before requesting review.
    • The feed contains a native-commerce signal, but processor support hasn’t been confirmed. Hold activation until the payment path can accept the required Google Pay tokens.
    • A prescription bundle visually leads with coaching or a treatment program. Rework the offer so the medication is unmistakably the primary product, as the category policy requires.
    • A consultation is presented as if it guarantees medication. State its actual role: assessing prescription eligibility. Keep the assessment distinct from the outcome.
    • Terms or fees are technically present but difficult to find. Put them where the customer can understand the recurring commitment before proceeding. Mere presence isn’t the same as transparency.
    • A prior disapproval is treated as permanent. If a certified U.S. pharmacy now meets the expanded requirements, correct the offer and account configuration, then use the available review process.

    For regulated health offers, this isn’t only a conversion concern. Ambiguous billing, unclear eligibility language or a service-led bundle can misrepresent what a patient is buying. Keep medical and policy review in the launch path, and don’t use optimization work to soften or obscure a condition that determines access, cost or recurring payment.

    The same consistency principle applies outside healthcare. Use one governed offer record as the reference for feed data, landing-page copy, checkout configuration and internal review. When a price, fee, bundle or term changes, update each layer as one release rather than as separate content and engineering tasks.

    Key takeaways

    • UCP can place a native Buy action on Google, but the merchant remains the seller of record.
    • Merchant Center’s native_commerce attribute and processor support for Google Pay tokens solve different parts of the same checkout flow.
    • Certified U.S. online pharmacies can promote qualifying recurring prescriptions, bundles and consultations when they meet the expanded requirements.
    • Eligible pharmacy offers need accurate subscription_cost data, transparent terms and fees, continued certification, and compliance with existing Healthcare & Medicine policies.
    • Schema and page optimization support offer understanding; they don’t substitute for Merchant Center configuration, payment readiness or policy approval.
    • Measure confirmed orders and payment outcomes across systems because an on-Google transaction may not follow the website funnel your current reports expect.

    Choose one eligible offer and run it through the matrix before expanding the rollout. If its policy status, Merchant Center data, landing page, processor response and confirmed order all agree, you have a repeatable commerce path. If they don’t, the failed checkpoint tells you exactly which team should fix the next problem.
    References

  • Google AI Commerce: How Ecommerce Brands Stay Visible

    Google AI Commerce: How Ecommerce Brands Stay Visible

    Your product can hold a respectable search position and still lose the sale before a shopper reaches your site. When an AI system interprets the need, compares the options, chooses an offer and potentially handles checkout, the decisive visibility event happens upstream of the click.

    You now need to make each product easy for an agent to find, understand, select and transact. That means treating product truth, recommendation fit and operational readiness as parts of SEO rather than leaving them to separate catalog, merchandising and checkout teams.

    The sale can now be won before a site visit happens

    The familiar ecommerce journey starts with a query, moves through a search result and ends on a merchant-controlled product page or checkout. Google’s AI commerce direction compresses that journey. Its Universal Commerce Protocol enables AI agents to discover, evaluate, recommend and purchase products across the web within Google’s AI experiences.

    UCP matters because it is not an isolated shopping widget. Its launch collaboration included Shopify, Etsy, Wayfair, Target and Walmart, with existing payment networks incorporated. Google also introduced three related commerce surfaces: Business Agent for brand-specific conversations in Search and Gemini, Direct Offers for promotions inside AI Mode, and Checkout in AI Mode for purchases completed within Google’s interface.

    For you, the important shift is from ranking alone to selection. A conventional ranking report asks whether a URL appeared and received a click. AI commerce requires four different questions:

    Visibility stageQuestion to answerTypical failure to investigate
    EligibilityCan the system find and use the product record?The item, variant or offer is absent, inaccessible or unsupported.
    InterpretationCan it identify exactly what the product is?Names, identifiers, attributes, prices or availability conflict.
    SelectionCan it explain why this product fits the shopper’s need?The catalog describes the item but not its use, constraints or differences.
    TransactionCan the selected offer be purchased successfully?The offer is stale, the variant is unavailable or the handoff fails.

    Your website remains important. It may still be the clearest public expression of your product facts, policies and brand expertise. But a polished page cannot compensate for exclusion at the eligibility stage, contradictory data at the interpretation stage or weak product fit at the selection stage. Diagnose the stage that failed before rewriting copy or increasing media spend.

    Build a product truth layer before optimizing recommendations

    A running shoe is connected to organized product details, inventory, shipping and verification symbols above a foundation of data blocks.

    The first job is agreement, not persuasion. Your page, structured data, catalog feed, commerce platform, inventory system and checkout should describe the same purchasable item. If they disagree, an agent has to decide which representation to trust while the shopper sees only the result.

    Create a field-level catalog audit. For each commercially important product and variant, record the canonical system, the surfaces that publish the field, the event that refreshes it and the person responsible when synchronization fails. Inspect at least these groups of information:

    • Identity: product name, brand, internal identifier, SKU and any supported external identifier.
    • Variant definition: the attributes that distinguish one purchasable option from another, such as size, color, configuration or quantity.
    • Offer state: current price, currency, discount terms, availability and the exact variant to which each value applies.
    • Product facts: materials, dimensions, included components, compatibility, care requirements and other attributes the shopper may use to rule an option in or out.
    • Fulfillment facts: the shipping, pickup or delivery conditions your operation can actually honor.
    • Policy facts: the conditions that affect the decision or the completed order, including relevant return, cancellation and warranty terms.

    This is not a claim that every field is a UCP requirement. It is a practical inventory of the commercial truths that discovery, comparison and checkout systems must keep straight. Match the audit to the fields, integrations and eligibility rules that apply to your own platform setup.

    Keep identifiers and variants stable

    Variant ambiguity is particularly costly. A parent product may be available while the size or configuration the shopper wants is not. If the parent page, structured data and feed collapse those states into one generic record, the system can recommend an option that cannot be purchased.

    Use stable identifiers for the same item everywhere. Do not casually recycle an identifier after replacing a product, merge materially different variants into a single offer or use different names for the same attribute across systems. When a product changes enough that compatibility or customer expectations change, treat identity as a catalog decision rather than a copy edit.

    Make freshness an operating rule

    Price and availability are state, not static content. Document what event updates each downstream representation: an inventory change, a promotion activation, a price revision or a product withdrawal. Then define what happens when the update does not arrive. A safe failure may mean suppressing an uncertain offer until it is reconciled instead of continuing to advertise a price or item you cannot honor.

    Test a real purchasable variant from end to end. Compare its visible page, Product and Offer structured data where used, feed record, API response, cart and checkout. Search for disagreement in identifiers, price, currency, availability and variant labels. A valid schema block does not make a stale price true; structured data is a machine-readable representation of your commerce record, not a substitute for one.

    Give the recommendation system reasons to choose you

    Traditional product copy often assumes that the shopper already knows the category and is comparing familiar options. Conversational shopping starts earlier. Gemini can turn requests such as planning a camping trip or removing wine from a couch into product discovery based on inventory, price and availability. The initial language may describe a problem or outcome without naming a product category.

    A catalog full of short, near-duplicate descriptions gives an agent little basis for matching those needs. Add decision information that helps it distinguish fit. For each priority product, make the following explicit in visible, accurate language:

    • What the product is, without relying on a clever product name to carry the definition.
    • Which use cases it is designed for and which product attributes support those uses.
    • Which shopper, environment or constraint it suits.
    • What it requires to work, including compatibility, installation or complementary components where relevant.
    • How it differs from nearby options in your own range.
    • When another option is a better fit.
    • Which claims are factual and where the supporting evidence appears.

    The last two points deserve attention. If every item is described as the best choice for every buyer, none of the descriptions provides a useful selection boundary. A clear exclusion such as an incompatible device, unsuitable environment or missing feature can improve recommendation fit by preventing the wrong product from being chosen.

    Do not turn this into an exercise in manufacturing question-and-answer text or repeating likely prompts. Write complete product facts and decision criteria in the language customers use. The goal is not to imitate a chatbot. It is to remove the inference a chatbot would otherwise have to make.

    Make category pages do comparison work

    A product page can explain one item well while the category still fails to explain choice. Build category content around meaningful differences: intended use, decisive attributes, compatibility, level of capability and tradeoffs. If two products differ only in internal merchandising language, rewrite the distinction so a customer can tell why both exist.

    Use comparison tables only when the attributes are genuinely comparable. Keep values normalized, name units and avoid leaving a blank cell when the real meaning is unknown, not applicable or not included. Those states lead to different decisions and should not be collapsed into the same empty space.

    Prepare each AI commerce surface as a separate operation

    A travel bottle on a central operations hub connects to conversational, comparison, visual discovery and checkout surfaces through separate readiness gates.

    Business Agent, Direct Offers and Checkout in AI Mode affect different parts of the buying journey. Do not assume that connecting one surface makes the others accurate or operational. Give each capability an owner, a source of truth, an approval boundary and a failure procedure.

    Business Agent needs governed brand knowledge

    Business Agent acts as an AI-powered brand representative in Search and Gemini, where shoppers can ask about products, compare choices and receive brand-specific guidance without opening a separate site. That makes answer quality part of merchandising and reputation management, not merely customer support.

    Start by identifying the questions that materially change a purchase: suitability, compatibility, differences between models, included components, availability and relevant policies. Map each answer to an approved source. Decide which claims can be stated directly, which require conditions and which should not be made. When an answer depends on information the agent cannot reliably access, provide a safe path to verification rather than filling the gap with promotional language.

    Audit the agent as a buyer would use it. Ask underspecified questions, add a constraint, change a variant and challenge a recommendation. Check whether the answer preserves the constraint, cites the correct product facts and avoids promising unavailable stock or unsupported capabilities.

    Direct Offers need commercial controls

    Direct Offers allow merchants to put exclusive discounts into AI Mode, placing the promotion inside the recommendation environment. That can make offer quality part of selection, but it also introduces margin and customer-expectation risk.

    Every offer should have an unambiguous product or variant scope, eligibility rule, valid period, discount definition and fallback state. Confirm that the same terms reach the agent, cart and order system. If the promotion cannot be honored at checkout, suppress or correct it rather than relying on fine print after selection. An expired or mis-scoped offer can turn added visibility into support costs, cancellations and lost trust.

    Checkout in AI Mode needs order-level testing

    Checkout in AI Mode moves purchase completion into Google’s interface. Your storefront may no longer control every step or observe a conventional browsing session before the order. Test the transaction as an operational flow: selected variant, current price, inventory reservation, payment status, tax and delivery handling, order creation, confirmation, cancellation and returns.

    Do not begin with your entire catalog merely because the integration permits broad coverage. A bounded set of products with clean data, dependable inventory and understood margins gives you a safer place to verify order routing and exception handling. Commerce automation can create real financial exposure when a discount, stock state or fulfillment promise is wrong, so expand only after the failure path works as well as the happy path.

    Measure AI visibility as a decision journey

    Rankings, clicks and onsite conversion rate still describe part of ecommerce performance. They do not tell you whether an agent found the product, interpreted it correctly, recommended it for the right need or completed the purchase without a traditional visit. Keep the established metrics, but add observations for the stages you can now lose before the click.

    • Catalog coverage: which priority products and variants are eligible for the commerce surfaces you use.
    • Data consistency: whether identity, price, availability and offer terms agree across exposed systems.
    • Recommendation presence: whether your product appears for a controlled set of relevant buyer needs.
    • Recommendation accuracy: whether the explanation, constraints and selected variant match the underlying product facts.
    • Offer integrity: whether the displayed promotion remains valid through checkout.
    • Transaction quality: whether the order is created correctly and can be fulfilled without avoidable correction, cancellation or support intervention.
    • Commercial quality: whether the resulting order remains worthwhile after discounts, fulfillment costs, returns and service demands.

    Use the telemetry your platforms actually expose, and do not manufacture precision where reporting is incomplete. A repeatable observation log can still reveal problems. Record the shopper need, constraints, region or language, date, products surfaced, recommendation wording, displayed offer and any incorrect claim. Run the same scenario after a meaningful catalog or content change. A single conversation is an example, not proof of sustained visibility.

    Prioritize changes by stage. If the product is absent, investigate eligibility and data delivery. If it appears with wrong facts, fix the truth layer. If the facts are right but the fit is unclear, improve decision content. If selection succeeds but the order fails, stop rewriting pages and repair the transaction path.

    Key takeaways

    • Google AI commerce visibility spans eligibility, interpretation, selection and transaction, not only rankings and clicks.
    • Product pages, structured data, feeds, inventory systems and checkout must agree on the identity and current state of each variant.
    • Useful product content states use cases, constraints, compatibility, differences and exclusions so an agent has a defensible reason to recommend the item.
    • Business Agent, Direct Offers and Checkout in AI Mode need separate ownership, controls and failure procedures.
    • Measurement should connect recommendation presence and accuracy to valid offers, successful orders and commercial outcomes.

    Choose a commercially important category and trace a real variant from product record to recommendation and completed order. Log every contradiction, missing decision fact and broken handoff. Fix that path before expanding coverage. The brands that become easier for AI to choose will be the ones that make product truth operational, not merely publish more content.

    References

  • How to Make Ecommerce Sites Ready for AI Shopping Agents

    How to Make Ecommerce Sites Ready for AI Shopping Agents

    Your product page can be perfectly usable by a person and still be unreliable for an AI shopping agent. A shopper can interpret layout, infer which option is selected, notice a warning, and back out of a mistake. An agent needs explicit facts, unambiguous choices, and a safe path from finding an item to taking an action.

    If you run an ecommerce or transactional site, the question is no longer just whether an AI system can mention your brand. You also need to know whether an agent can identify the right product, resolve its options, understand the commercial constraints, and complete the next permitted step without guessing. You can prepare for that shift now without treating an experimental protocol as a finished standard.

    The agent journey has four separate failure points

    AI-driven shopping discovery changes the job of a product page. It still has to persuade a person, but it increasingly has to help a machine determine whether a particular product satisfies a particular set of constraints.

    That journey has four layers: discovery, decision, action, and confirmation. Traditional search optimization concentrates heavily on the first. An agent-driven experience can fail at any of the other three even when the page ranks, gets cited, or receives a visit.

    Journey stageWhat the agent must establishTypical site-level failureWhat to fix
    DiscoverWhether the page and product match the user’s needImportant facts exist only in images, interface states, or vague promotional copyPut essential product facts in clear HTML and consistent structured data
    DecideWhich exact product and variant satisfy the constraintsSizes, units, compatibility, availability, or variant relationships are ambiguousTie every choice to a stable product or variant identifier and its current commercial facts
    ActWhich operation is allowed and which inputs it requiresThe agent must guess what buttons do or manipulate a changing document structureExpose narrow, named actions with explicit inputs, outputs, and errors
    ConfirmWhat changed, what it will cost, and whether further approval is requiredA side effect occurs without a review step or a clear resultReturn the resolved item, quantity, price, status, and next required decision

    Use those four stages as separate audit columns. If an agent finds the page but selects the wrong size, you have a decision-layer problem. If it selects the correct variant but cannot add it to a cart reliably, you have an action-layer problem. If it can place the same order twice, you have a confirmation and transaction-safety problem. Calling all three problems “AI visibility” hides the work that actually needs to be done.

    Build a reliable product truth layer before adding agent actions

    An unbranded sneaker and its color, size, material, inventory, price, shipping, and return details connect to a transparent structured foundation.

    An action contract cannot repair an unclear catalog. Before you expose callable tools, make sure an agent can resolve one user request to one exact purchasable item. That requires more than a polished product name and a paragraph of sales copy.

    Create a product record an agent can resolve

    • Give the product, offer, and purchasable variant stable identifiers. Do not make an agent rely on a position in a product grid or a temporary interface label.
    • State concrete attributes with their units and scope. “Lightweight” may help a person scan the page; an actual weight and unit let an agent test a constraint.
    • Connect every option combination to the correct availability, price, image, identifier, and purchasing state. A parent product being available does not establish that the requested variant is available.
    • Make compatibility and exclusions explicit. If a part fits only certain models, regions, account types, or configurations, put that boundary next to the applicable item.
    • State fulfilment and return constraints in language that can be applied to a decision. Avoid scattering a decisive restriction across a tooltip, an image, and a generic policy page.
    • Distinguish a one-time purchase, subscription, reservation, quote request, and other commercial models. An agent should not have to infer the commitment from button copy.

    The same facts may appear in rendered HTML, Product and Offer structured data, a catalog feed, an internal API, a form, and an agent tool response. They should resolve to the same item and current state. If JSON-LD presents one price, visible copy presents another, and the cart calculates a third, an agent has no unambiguous value on which to act.

    Keep description and execution separate

    Schema markup and an agent tool contract solve related but different problems. Product structured data can describe an item, its offer, and its availability. It does not, by itself, grant an agent a reliable function for configuring the item or changing a cart. A tool contract describes an operation the site is prepared to accept.

    A useful shorthand is: schema explains what something is; a tool contract explains what can be done with it. You need both layers to agree, but you should not treat one as a substitute for the other. Keep the human-readable page as the visible source of context, terms, and control as well.

    If you can only fix one layer first, fix product truth. A fast agent action that operates on an ambiguous variant is worse than a slower path that asks the user to choose.

    Expose narrow tools instead of making agents operate your interface

    Google’s early WebMCP preview proposes a structured way for websites to expose tools to browser agents. A site can publish a Tool Contract through the navigator.modelContext browser API so an agent receives named functions instead of having to infer the meaning of links and buttons from the document structure.

    That distinction matters. Raw interface operation is fragile because labels, layouts, overlays, and component states change. A named action can state its purpose, required inputs, expected result, and failure conditions directly. The agent still has to reason about the user’s request, but it should not have to reverse-engineer your checkout interface.

    Choose the API style that matches the interaction

    WebMCP describes two approaches. The declarative API is intended for standard actions that can be defined through HTML forms. The imperative API supports more complex or dynamic interactions that require JavaScript execution.

    • Use a declarative action when the operation already maps cleanly to a form with explicit fields, constraints, and submission behavior.
    • Use an imperative action when the workflow depends on changing state, a multi-part configuration, asynchronous validation, or other logic that a normal form cannot express clearly.
    • Keep the ordinary page and form working as a fallback. An experimental agent layer should enhance the purchasing path, not become its only usable route.

    WebMCP is an early preview, so its details may change. Do not rebuild your checkout around it or assume that implementing it creates a search-ranking advantage. Treat the protocol as an experimental delivery mechanism for an interaction model you should design carefully regardless of which standard eventually carries it.

    Write each tool contract like a small public promise

    1. Name the action after the user’s intent. Search products, retrieve a product, select a variant, add an item to a cart, and begin checkout are clearer responsibilities than click button or process page.
    2. Request only the inputs needed for that action. Define allowable values and identify which fields are required instead of accepting an undifferentiated text payload.
    3. Separate read-only operations from operations that change state. Searching a catalog and submitting an order should not share the same permission or confirmation behavior.
    4. Return stable identifiers and the resolved current state. An add-to-cart result should identify the exact variant, quantity, current price, cart state, and any remaining decision.
    5. Return structured failures. Unavailable variant, unsupported destination, authentication required, invalid quantity, and price changed are outcomes an agent can handle; a generic failure message is not.
    6. Make consequential actions explicit. The contract should reveal when an operation reserves inventory, starts a subscription, submits payment, or creates an order.

    An illustrative shopping sequence might expose searchProducts, getProduct, selectVariant, addToCart, and beginCheckout as separate operations. A submitOrder action would sit behind an explicit review and approval step. Those names illustrate separation of responsibility; they are not prescribed WebMCP syntax.

    Resist the urge to publish one general-purpose function that accepts a natural-language instruction and performs an entire purchase. It may look flexible, but it conceals intermediate decisions, makes permissions harder to enforce, and leaves fewer points where the user can inspect or correct the result.

    Design checkout around permission, reversibility, and proof

    A geometric shopping agent presents a basket as a human hand authorizes checkout through a shield checkpoint, with a parcel, proof token, and return path beyond it.

    An agent acting on behalf of a shopper can create financial consequences. The site therefore needs a permission model based on what an action changes, not merely on whether the agent knows how to call it.

    Use a simple action-risk ladder

    • Read-only actions: searching, filtering, comparing, and retrieving current details can normally run without transactional confirmation.
    • Reversible state changes: adding an item to a cart, removing it, or changing a quantity can proceed when the result is reported clearly and the user can undo it.
    • Commitment actions: placing an order, accepting changed terms, starting a paid subscription, or making a non-refundable booking should require the user to review the resolved details and confirm the commitment.

    Do not let an agent infer a missing variant, quantity, shipping destination, or commitment period when the choice affects the transaction. Return the missing field as a required decision. A short clarification is safer than a confidently completed wrong order.

    Make repeated requests safe

    Agents, browsers, and networks can retry an operation after an interrupted response. Your transaction design should ensure that repeating the same confirmed request does not silently create duplicate orders or charges. In engineering terms, the consequential operation should be idempotent or protected by an equivalent duplicate-prevention mechanism.

    • Assign the attempted transaction a stable request or confirmation identifier.
    • Return a definite status such as pending, completed, rejected, or requiring confirmation rather than an ambiguous success message.
    • If the price or selected item changes before commitment, return the new state and require confirmation again.
    • If the requested variant becomes unavailable, stop and offer alternatives as new choices. Do not substitute a different variant automatically.
    • Record the action invoked, resolved item, result, confirmation event, and safe request identifier so a failed workflow can be investigated.

    Keep payment credentials, authentication secrets, and unnecessary prompt content out of general agent analytics. Operational visibility is useful, but it does not justify collecting sensitive data that the team does not need for diagnosis.

    Preserve a visible human handoff

    The shopper should be able to inspect what the agent selected, edit it in the ordinary interface, and continue without starting over. Before a commitment, show the exact line items and variants, quantities, current charges, applicable fulfilment details, and the action that confirmation will trigger.

    A handoff is not necessarily an agent failure. It is the correct result when authentication, policy, missing information, or financial approval requires the person. Design it as an intentional state with preserved context, not as an error page.

    Test complete shopping tasks, including safe failures

    Testing whether an agent can call a function is not enough. The real unit of quality is a complete user task: the right item is found, the right option is selected, the allowed action succeeds, and the shopper receives an accurate result. A safe stop also counts as correct behavior when required information or permission is missing.

    1. Start with a constrained search, such as a product that must satisfy a compatibility requirement and a specific option.
    2. Test a parent product whose requested variant is unavailable even though another variant remains purchasable.
    3. Change a price or availability state between selection and checkout, then verify that the agent presents the change instead of continuing on stale information.
    4. Attempt a state-changing action without authentication or a required field and verify that the response identifies the next necessary step.
    5. Repeat the same transactional request and verify that it cannot produce a duplicate commitment.
    6. Move from the agent flow to the visible interface and confirm that the exact cart or configuration survives the handoff.

    Track outcomes by journey stage. Useful measures include product-resolution accuracy, completed-task rate, clarification rate, invalid-action rate, duplicate-attempt handling, safe-stop rate, recovery after a structured error, and successful human handoff. Keep discovery events separate from tool invocations and completed actions. Otherwise, an increase in AI-originated visits can conceal a broken decision or checkout path.

    Review failures by cause, not only by agent or channel. If several agents choose the wrong variant, inspect the catalog relationships and labels before tuning prompts. If they choose correctly but fail at cart mutation, inspect the action contract and transaction state. That diagnosis tells you whether the next fix belongs in content, schema, product data, interface logic, or the agent tool layer.

    Key takeaways

    • Treat agent readiness as four connected capabilities: discovery, decision, action, and confirmation.
    • Fix product identity, variant relationships, commercial facts, and policy constraints before exposing purchase tools.
    • Use structured data to describe products and a narrow tool contract to expose permitted actions.
    • Separate read-only, reversible, and commitment actions so confirmation matches the consequence.
    • Make consequential requests duplicate-safe, return structured errors, and preserve a visible human handoff.
    • Treat WebMCP as an early experimental layer and measure complete task outcomes rather than assuming an SEO benefit.

    Choose one high-value journey this week: product search, variant selection, and add to cart is a sensible starting boundary. Resolve every ambiguity in that path, document its allowed actions and failures, and leave order submission behind an explicit user confirmation. Once that narrow journey works reliably, expand one consequential step at a time.

    References

  • Advertising in AI Experiences: A Practical Readiness Plan

    Advertising in AI Experiences: A Practical Readiness Plan

    If you’re being asked for an “AI ads strategy,” don’t start by moving a search campaign into a new interface. An AI experience may be answering a question, narrowing a comparison, selecting an offer, or helping complete a purchase. Your ad has to help with that task without pretending to be the answer.

    The practical job is to make four things line up: the user’s decision, the claim the system can verify, the offer you can honor, and the next action you can measure. When one breaks, more targeting or more generated creative won’t rescue the experience.

    AI ads compete for the next useful action

    A conventional search ad usually occupies a known slot between a query and a landing page. An ad inside an AI experience enters a more fluid sequence. The user may have already described constraints, rejected alternatives, requested a comparison, or asked the system to help complete a task.

    That does not mean advertisers automatically receive the conversation or control the answer. In the initial ChatGPT design, ads are limited to the Free and Go tiers, kept separate visually and technically from model answers, and hidden from Plus, Pro, and Enterprise users. The model is not informed that an ad is present and does not refer to it unless the user asks. Treat that separation as a real product boundary, not a temporary obstacle to work around.

    Google is pursuing a different but related path. Conversational and visual discovery in AI Mode can include sponsored retail listings and Direct Offers intended to help a user continue a shopping journey. The useful planning unit is therefore not merely the keyword, placement, or audience. It is the decision the user is trying to make.

    Rewrite each campaign brief as a decision task. “Reach operations leaders” is an audience description. “Help an operations leader compare tools that meet a stated integration requirement” is a task. The second version tells your team what facts, offer, destination, and measurement the experience needs.

    • User state: What has the person probably established before a sponsored option becomes useful?
    • Decision constraint: Which requirement, location, budget condition, compatibility need, or availability question narrows the choice?
    • Verifiable claim: What can your site, feed, structured data, or product record support without interpretation?
    • Useful next action: Should the user inspect an offer, compare configurations, check availability, request qualification, or complete a purchase?
    • No-ad condition: In which contexts would promotion be irrelevant, sensitive, misleading, or unsafe?

    The same principle applies outside chat. AI can help connect brands with YouTube creators and turn creator-led discovery into commerce. Define creator fit through the audience problem, acceptable claims, and commercial handoff – not reach alone. A highly visible creator cannot repair a mismatched offer or an unsupported product promise.

    Build answer, offer, and transaction readiness in that order

    Three connected stations depict product answers and evidence, an available offer, and a secure transaction in sequence.

    AI advertising readiness is not a media-only project. The system may need to understand your business, retrieve a current offer, and pass the user into a reliable transaction. Those are separate layers, and each can fail independently.

    Answer readiness: make the commercial facts unambiguous

    Your organic AI visibility and your paid eligibility are different, but they depend on a shared factual foundation. A discovery system should be able to identify what you sell, who it is for, where it is available, what conditions apply, and which page is authoritative.

    • Give every important product, service, location, and offer a stable name and a canonical destination.
    • State the qualifying details in visible page copy. Do not leave essential limitations inside an image, sales deck, or support conversation.
    • Keep names, identifiers, prices, service areas, availability, and eligibility language consistent across pages.
    • Use relevant Schema.org types such as Organization, Product, Service, Offer, and LocalBusiness where they accurately describe visible content.
    • Make JSON-LD match the page. Structured data that promises more than the user can see creates ambiguity rather than authority.
    • Separate factual descriptions from promotional language so a system can retrieve a supportable claim without inheriting the slogan around it.

    No schema type guarantees inclusion in an AI answer or an ad placement. The point of structured data is to reduce ambiguity and connect entities, properties, and offers. It cannot compensate for missing content or contradictory records.

    Offer readiness: synchronize what the user can actually receive

    An AI-matched ad becomes unhelpful the moment its offer is stale. This matters more when a sponsored option is presented after the user has already supplied detailed constraints. The apparent relevance raises the cost of a mismatch.

    For retail, reconcile the identifier, title, destination URL, price, currency, availability, variant, shipping terms, return terms, and promotion conditions across the feed, landing page, structured data, and checkout. For services, do the equivalent with the service area, qualification rules, deliverable, capacity, expected handoff, and any condition that can disqualify the lead.

    Assign an owner to every field that can change. Then define which system is authoritative when two records disagree. “The feed team owns price” is incomplete if checkout can display something else. The useful rule is operational: when the source of record changes, every consumer of that field must receive the update, and the affected offer should stop serving if synchronization fails.

    Transaction readiness: design for safe completion and failure

    Agentic commerce shortens the distance between recommendation and purchase. Google’s Universal Commerce Protocol is intended to standardize AI-assisted browsing, purchasing, and transaction completion. That makes checkout reliability, inventory state, and exception handling part of advertising quality.

    • Require clear authorization before a charge, booking, subscription, or binding order.
    • Make order creation idempotent so a retry does not create a duplicate transaction.
    • Validate price, inventory, tax, shipping, eligibility, and promotion status at the point of commitment.
    • Return an unambiguous confirmation with the item or service, amount, status, and next step.
    • Provide a usable path for cancellation, correction, refund, and human escalation.
    • Preserve enough event history to determine whether an error began in the ad, offer record, handoff, or transaction system.

    Do not enable an automated purchase path while duplicate-order protection, cancellation, or exception handling remains untested. The downside is not a weak engagement metric; it is an incorrect charge, unavailable order, or commitment the user did not understand. Keep a confirmation step and a conventional checkout alternative until the failure paths are reliable.

    Make trust part of delivery, not a policy page

    Relevance does not excuse hidden influence. An AI answer carries a different kind of perceived authority from a familiar ad slot, so sponsorship has to remain legible at the moment the user evaluates the recommendation.

    ChatGPT’s initial guardrails include not sharing conversations with advertisers, excluding ads from health, politics, and other sensitive discussions, and giving users personalization controls. These are platform-specific commitments, not universal rules for every AI ad product. Verify the controls and exclusions of each channel before you approve a campaign.

    Your own delivery specification should cover the following:

    • Sponsorship: Do not write creative that could be mistaken for the assistant’s independent conclusion or an organic citation.
    • Context exclusions: Document the tasks and sensitive situations in which your offer should not appear, even if the platform allows the placement.
    • Data boundary: Record which contextual signals the platform exposes and which user data reaches your systems. Do not reconstruct a private conversation from unrelated identifiers.
    • Claim control: Link every material claim to an approved fact, product record, policy, or landing-page statement.
    • Personalization control: Make consent, preference changes, and opt-out behavior understandable wherever your own data collection begins.
    • Correction path: Give users and internal reviewers a direct way to report an inaccurate offer, misleading claim, or broken handoff.

    Keep paid visibility and AI visibility on separate scorecards

    Do not report a sponsored appearance as proof that a model independently recommends your brand. Do not report an organic mention as paid campaign delivery. They answer different questions.

    • Organic AI visibility: Can the system identify the brand, retrieve accurate facts, answer the relevant question, and cite or mention the right entity?
    • Paid AI delivery: Was the sponsored option eligible, shown in an appropriate context, acted on by a qualified user, and connected to a valid offer?
    • Shared quality: Did the destination substantiate the claim, preserve context, and produce an acceptable customer outcome?

    This separation protects your reporting and your optimization. A bid or budget cannot make weak facts more authoritative. Better organic answer coverage does not guarantee sponsored distribution. Both programs can improve the same landing pages and entity records without pretending to be the same channel.

    Put generated creative behind a claim gate

    Generative tools can make asset production much faster. Google’s advertising direction includes Gemini 3, Nano Banana, Veo 3, and AI Max for creative production, reach, and campaign optimization. Faster production increases the need for tighter review because one outdated input can be repeated across many polished variations.

    Start creative generation from an approved claim set, not an open-ended prompt. Require each variation to retain the qualifying language, destination, and current offer. Store the asset with its source claim and offer identifier. When the underlying fact changes, you can then find and retire every affected version instead of searching campaigns by eye.

    Run the first pilot around one decision, not a whole funnel

    A shopper compares three products with help from verified evidence and a distinct promotional offer while a small team observes the decision.

    A broad launch makes diagnosis difficult. If performance disappoints, you will not know whether the problem was matching, creative, answer readiness, offer accuracy, the landing-page handoff, or transaction friction. A narrow pilot gives each failure somewhere specific to land.

    1. Choose a bounded decision task. Define what the user is trying to decide and the conditions that make your offer relevant or irrelevant.
    2. Create a truth set. Record approved claims, prohibited claims, current offers, exclusions, systems of record, and field owners.
    3. Build the complete path. Review the sponsored message, destination, structured data, offer record, form or checkout, confirmation, and exception route as one experience.
    4. Instrument the handoff. Capture the channel, placement type, campaign, asset, offer identifier, destination, qualified action, completed outcome, and any reversal without collecting private conversational content.
    5. Establish a counterfactual. Use a platform experiment or holdout when available. If neither is available, document a stable baseline and state clearly that the result is directional rather than incremental.
    6. Expand only after quality holds. Increase the range of tasks, offers, or creative after the pilot produces accurate offers, acceptable outcomes, and no recurring trust failure.

    Click-through rate can diagnose whether a sponsored option attracts attention, but it cannot tell you whether the AI-assisted decision was good. Define qualification and completion before launch, then measure the handoff with metrics that expose both performance and failure.

    MetricHow to calculate itWhat it helps you decide
    Qualified action rateQualified actions divided by attributed AI ad visitsWhether matching and creative are producing commercially relevant responses
    Offer consistency rateAudited offers whose ad, destination, structured data, and transaction terms agree divided by all audited offersWhether the commercial data is dependable enough to scale
    Decision completion rateConfirmed target outcomes divided by eligible initiated pathsWhether the handoff helps the user finish the intended task
    Outcome quality rateAccepted, retained, or otherwise qualified outcomes divided by completed outcomesWhether apparent conversions remain valuable after validation
    Mismatch or complaint rateRecorded relevance, sponsorship, offer, or transaction complaints divided by attributable interactionsWhether utility is being purchased at the cost of trust
    Incremental outcomeDifference between exposed and valid comparison groupsWhether the channel created value beyond outcomes that would have happened anyway

    Set the definitions, data owner, and decision rule for each metric before anyone sees campaign results. Otherwise, teams tend to relax the meaning of “qualified” or emphasize whichever event improved.

    Pause the affected offer or path when the ad claim is absent from the destination, displayed terms disagree with checkout, inventory cannot be confirmed, users mistake sponsorship for an independent answer, or additional conversions arrive with a corresponding rise in reversals, refunds, or disqualified leads. These are not creative-learning signals. They indicate that the experience is making a promise the operating system cannot reliably keep.

    Key takeaways

    • Plan AI advertising around a user’s decision task, not merely a keyword, audience, or placement.
    • Treat answer readiness, offer accuracy, and transaction reliability as separate layers with named owners.
    • Keep sponsored delivery visibly separate from model answers and report paid exposure separately from organic AI visibility.
    • Use structured data to clarify visible facts, never to introduce claims or terms that the page does not support.
    • Measure qualified outcomes, offer consistency, completion, and trust failures alongside attention metrics.
    • Scale only after the entire path can preserve context, honor the offer, and handle exceptions safely.

    Your first move does not need to be a large media commitment. Choose a commercially important decision, make its facts and offer machine-readable, connect it to a dependable action, and define the conditions that will stop the campaign. That foundation will remain useful as AI ad formats, matching systems, and agentic purchase paths continue to change.

    References

  • Agentic AI for E-commerce: A Leadership Operating Plan

    Agentic AI for E-commerce: A Leadership Operating Plan

    If your leadership team is asking whether agentic AI will make product pages, search traffic, or brand marketing obsolete, the useful answer is no. That is not a reason to wait. The practical change is that more discovery, comparison, filtering, and execution can move into software acting for the shopper.

    You need an operating plan that makes your products easy for both people and machines to understand, verify, and select. You also need measurement that remains honest when part of the buying journey happens beyond your analytics. Here is how to build both without reorganizing the company around an adoption curve nobody can forecast precisely.

    Key takeaways

    • Agentic commerce adds a software decision layer between customer intent and commercial execution. It does not remove the customer or the need to earn trust.
    • Your central readiness question is no longer only whether a product can rank. It is whether the product is eligible to survive a constraint-based selection process.
    • Eligibility depends on complete, consistent product facts, dependable price and availability data, clear policies, technical accessibility, and a transaction path that works.
    • JSON-LD and other machine-readable formats should publish canonical business facts, not compensate for contradictions between your systems.
    • SEO, merchandising, engineering, operations, customer experience, and analytics need named ownership. Agent readiness cannot sit entirely inside the marketing team.
    • Exact attribution will become less reliable as more evaluation happens inside AI systems. Measure readiness directly and interpret commercial outcomes directionally.

    Reframe the agent as a customer proxy

    In this context, agentic AI means software can carry part of a task forward from a person’s intention. The shopper still supplies the need, preferences, budget, and acceptable trade-offs. The software interprets those constraints, investigates options, narrows the field, and may take an action on the shopper’s behalf.

    Consider the difference between a shopper searching for running shoes and a shopper asking for a pair that fits a particular use, budget, size, delivery requirement, and material preference. A traditional search journey requires the person to open results and resolve those constraints manually. An agent can turn the same request into a filtering job before the shopper reaches a product page.

    A useful leadership model separates the journey into distinct decisions:

    • The person defines the desired outcome and acceptable constraints.
    • The agent interprets those constraints and identifies possible candidates.
    • Your published product and business data determine whether your offer can be understood and qualified.
    • Trust signals, policies, and commercial reliability help the agent distinguish between otherwise suitable candidates.
    • Your commerce systems determine whether the selected action can be completed successfully.

    This model changes the executive question. Instead of asking, ‘Will agents replace our customers?’, ask, ‘At which decision could incomplete or unreliable information remove us from consideration?’

    Rankings still matter because agents need candidates to evaluate. They are no longer a sufficient definition of success. A highly visible offer can still be filtered out if its suitability is unclear, its current price cannot be trusted, or its policies create unresolved risk. A lower-profile offer may remain eligible because it answers the request more precisely.

    The transition will not move at the same speed in every market. Categories with standardized products and organized data are easier for software to evaluate. Complex purchases and categories with regulatory constraints introduce more ambiguity. Treat adoption as gradual and category-dependent, then set investment levels for your own selection conditions rather than following a general hype cycle.

    The earliest pressure is likely to appear in discovery and consideration. Natural-language requests can carry far more context than short category queries, while software can perform the initial comparison without exposing every intermediate step. That weakens the assumption that owning a broad head term guarantees access to the consideration set.

    It also changes the job of content. A page should not merely attract a click or repeat a category phrase. It should resolve the variables that determine fit: what the product is, whom it serves, where it does not fit, what it costs, whether it is available, what conditions apply, and why the claims are credible.

    Audit the selection chain, not just the search result

    A glowing software agent passes generic products through several visual filtering and verification stages before making a final selection.

    Eligibility is not an official score supplied by an AI platform. It is a management lens for identifying the facts and systems that must work before an offer can be selected confidently. That makes it more useful than a vague goal such as ‘be ready for agents.’

    Selection stageQuestion the system must resolveEvidence to inspect
    IdentityWhat exactly is being offered?Canonical product name, identifiers, category, variant relationships, and consistent descriptions.
    SuitabilityDoes the offer satisfy the shopper’s constraints?Category-specific attributes, compatibility, dimensions, use conditions, exclusions, and variant-level facts.
    Commercial truthWhat will the shopper pay, and can the item be obtained?Current price, availability, offer conditions, and agreement between public surfaces and commerce systems.
    Trust and riskWhat uncertainty comes with choosing the offer?Clear return terms, restrictions, warranties where relevant, evidence for claims, and consistent policy language.
    ExecutionCan the intended action be completed reliably?Working product and checkout paths, accurate inventory state, dependable payment handling, and technical availability.

    Do not begin this audit with a new AI tool. Begin with a representative product family and a realistic, constraint-rich shopping request. The request should contain the kinds of conditions that would change the answer, not merely the category name.

    1. Write down the product facts, offer conditions, and policies required to answer the request without guessing.
    2. Identify the authoritative system and accountable owner for each fact.
    3. Trace the fact through every surface that publishes it, including the product page, product feeds, structured data, inventory displays, policy pages, and checkout where relevant.
    4. Mark each fact as present and consistent, absent, contradictory, stale, or technically inaccessible.
    5. Repair the authoritative value or propagation path rather than editing one visible symptom.
    6. Republish the affected surfaces and repeat the same shopping request to confirm that the ambiguity has actually disappeared.

    Prioritize contradictions before polishing optional copy. A missing secondary detail may narrow your eligibility for a particular request. Conflicting price, availability, variant, or policy information can undermine confidence in the entire offer. Dynamic facts deserve particular attention because a value that was correct when published can become wrong when updates fail to propagate.

    JSON-LD belongs in this chain, but it is a publication layer rather than a separate version of reality. If your visible page, feed, structured data, and backend expose different values, adding more markup gives the system another conflicting claimant. Define the canonical fact, define which system owns it, and make every machine-readable representation inherit from that source wherever your architecture allows.

    Your audit record should preserve the shopping request, required constraints, expected eligible products, retrieved facts, contradictions, remediation owner, and retest result. That turns agent readiness into a repeatable quality process instead of a collection of screenshots from impressive demonstrations.

    Build agent readiness into normal commerce ownership

    A cross-functional commerce team coordinates product information, inventory, fulfillment, analytics, and customer experience around a shared digital product model.

    Agentic selection crosses organizational boundaries because the deciding signals do. Marketing can improve discovery, but it cannot independently correct an inventory state, repair checkout, define a returns policy, or decide which product database is authoritative. Machine-readable trust depends on technical and operational integrity as much as promotional visibility.

    Assign the fact, the path, and the control

    Team names will vary, but the accountability cannot remain vague. Use the following division as a starting point:

    WorkstreamQuestion it should ownEvidence leadership should request
    Merchandising or product dataWhich attributes and variant relationships are authoritative?A documented source for selection-critical product facts and a queue of unresolved data defects.
    Commerce operationsAre price, availability, and offer conditions current?Exception reporting for mismatches and a defined response when updates fail.
    EngineeringCan machines reliably retrieve the same facts customers see?Healthy publication paths for pages, feeds, structured data, inventory, payment, and checkout.
    SEO, AEO, and GEOWhich intents and constraints determine eligibility, and where is ambiguity visible?Constraint maps, crawl and rendering findings, content gaps, and cross-surface consistency checks.
    Customer experience and policy ownersCan a buyer resolve risk without interpretation or conflicting language?Explicit policy terms, known ambiguity cases, and a path for correcting recurring questions.
    AnalyticsWhat can be observed directly, and what can only be inferred?Metric definitions that separate readiness, observable behavior, commercial outcomes, and unknowns.
    Executive sponsorWho resolves ownership conflicts and approves contingent investment?A prioritized defect register, decision gates, and accepted limits on attribution.

    Attach this work to an existing digital commerce, merchandising, or operational review. A separate agentic AI committee will not help if it lacks authority over product truth and commerce systems. The standing agenda can remain short: which selection-critical defects appeared, which source owns them, which customers or products are exposed, and whether the repair survived retesting.

    Change the content brief from attention to resolution

    Traditional consideration content often accumulates reviews, comparisons, benefit claims, and reassurance. Those assets still have value, but an agent can turn consideration into a strict filtering exercise. Content must therefore make fit and evidence easy to extract, not merely make the page persuasive.

    • State who and what the product is for, including meaningful limitations and exclusions.
    • Use stable terminology for the same attribute across product copy, specifications, feeds, structured data, and policies.
    • Keep claims close to their supporting evidence. Avoid vague superiority language that cannot help resolve a constraint.
    • Put selection-critical facts on the canonical page where they belong instead of scattering answers across thin supporting pages.
    • Make comparisons explicit about the condition that changes the recommendation. Not every product should appear to be the best option for every buyer.
    • Review policy language as decision data. A policy that requires interpretation leaves a risk variable unresolved.

    This favors content quality over page volume. If the answer already belongs on a product or category page, repair that page rather than publishing another near-duplicate merely to target a longer query. The goal is a coherent representation of the offer across every surface an agent may use.

    There is also a brand consequence. Software may filter and select products before a shopper becomes familiar with every candidate. That can improve conversion while weakening brand recognition. Preserve clear brand identity in the product facts and trust signals likely to travel with the offer, and continue building familiarity beyond search. A trusted brand gives both the shopper and the software fewer unresolved reasons to reject the choice.

    Measure readiness honestly and stage your investment

    Agentic journeys make precise attribution harder because more evaluation can happen inside an external AI system. Fewer visible page interactions do not automatically mean your optimization failed, just as a conversion cannot automatically prove that an agent caused the outcome. Leadership should expect directional indicators and blended performance to carry more weight than a perfectly reconstructed path.

    Use a layered scorecard

    Start with measures your business can observe and control:

    • Critical-fact completeness: the share of in-scope products with every attribute required for the tested shopping requests.
    • Cross-surface agreement: whether product pages, feeds, structured data, inventory displays, policies, and checkout expose the same current facts.
    • Update propagation: how reliably a canonical change reaches each public surface, and where stale values persist.
    • Technical availability: whether the relevant content and transaction paths can be retrieved and completed without an avoidable failure.
    • Policy ambiguity: unresolved cases in which offer conditions or customer protections conflict or require interpretation.

    Then place behavioral and commercial indicators beside those readiness measures:

    Leadership questionUseful indicatorWhat it cannot prove
    Are our offers becoming easier to qualify?Improved completeness, consistency, accessibility, and retest results for priority product families.That a specific AI system selected the offer.
    Can we see agent-associated visits?Identifiable referral or journey evidence where analytics exposes it.The total volume of agent influence, because many intermediate decisions may remain hidden.
    Are repaired journeys performing better?Product-family conversion, completion, cancellation, and other relevant outcome trends interpreted with the defect history.That the repair alone caused the change.
    Is the business gaining selection without losing recognition?Blended commercial performance considered alongside branded demand and returning-customer behavior.Exact credit for any single search, content, brand, or agent interaction.

    Report observation, inference, and unknowns separately. ‘The price mismatch was removed and the affected family improved’ is an observation followed by a correlation. ‘Agents generated the improvement’ is a causal claim that requires evidence you may not possess. This distinction protects the budget conversation from false precision.

    Separate foundation work from contingent bets

    The most defensible investments help current customers and current commerce operations even if agent adoption is slower than expected. Approve work that improves product information, removes contradictions, clarifies policies, strengthens technical reliability, or fixes price, inventory, payment, and checkout defects. These changes reduce uncertainty regardless of which interface initiates the purchase.

    Run controlled experiments for questions your analytics cannot answer yet. Reuse realistic shopping requests, record the expected eligibility conditions before testing, and preserve failures as well as successes. A demonstration is useful for discovering defects; it is not enough evidence for a large strategy change.

    Keep bespoke integrations, major budget reallocations, and platform-dependent builds behind explicit decision gates. Before approving one, ask whether the business controls the required data, whether a recurring failure or opportunity has been observed, whether the dependency is stable enough to support the investment, and whether the work remains valuable if adoption develops differently.

    This avoids the two expensive extremes: making sweeping changes because a demonstration looks inevitable, or ignoring agentic behavior until commercial performance forces a rushed response. The practical middle is to repair known eligibility weaknesses now and reserve harder-to-reverse bets for evidence that justifies them.

    At your next operating review, put a real product family and a real constraint-rich shopping request on screen. Trace every fact a shopper’s proxy would need, name the owner of each contradiction, repair the problem at its source, and retest the same request. You will make the business easier to select now without pretending anyone knows the final shape or pace of agentic commerce.

    References

  • AI Assistant Advertising Models: A Practical Brand Guide

    If you are deciding whether to move media budget into AI assistants, the first question is not how much to spend. It is whether the assistant sells influence at all and, if it does, whether you can identify exactly what your money changes.

    That distinction matters because assistant advertising is not developing as one standardized channel. Claude has committed to an ad-free experience, while ChatGPT is opening a path toward advertising. Your plan therefore needs two lanes: paid distribution where inventory exists and organic AI visibility everywhere users may ask for recommendations.

    There is no single AI assistant advertising model

    Search advertising has familiar boundaries. A user enters a query, paid placements occupy identifiable positions, and organic results remain available alongside them. An AI assistant can collapse research, comparison, and recommendation into one generated response. That makes the commercial model more consequential: a paid element may sit much closer to the assistant’s advice than a conventional display or search ad does.

    Three relationships are especially important for planning. They are not mutually exclusive; one assistant can support user-initiated commerce while refusing advertiser-funded placements.

    ModelHow the brand participatesWhat the user experiencesYour planning priority
    Ad-supported conversationThe brand pays for eligibility in a sponsored message, link, product unit, or branded placement.Commercial content appears in or around the conversation.Verify disclosure, context controls, billing, and the separation between sponsorship and the assistant’s answer.
    Ad-free assistantThere is no sponsored-response inventory to purchase.The assistant answers without advertiser-funded placements.Invest in accurate, accessible, well-structured information that can qualify for unpaid discovery.
    User-initiated commerceThe brand can be considered when the user asks the assistant to research, compare, or help purchase something.Commercial help begins with the user’s request rather than an advertiser inserting a pitch.Make product facts, conditions, limitations, and supporting evidence easy to retrieve and verify.
    User-directed integrationA tool or service performs a function after the user chooses to invoke or connect it.The integration helps complete a task without necessarily creating sponsored exposure.Treat integration availability as product distribution or functionality, not as proof of advertising reach.

    The split is already commercially meaningful. Claude’s approximately 30 million users are outside its potential sponsored-placement market, while ChatGPT offers a possible advertising surface connected to an estimated 800 million weekly users. Those are estimates of platform audiences, not estimates of purchasable reach. They do not tell you how many people are eligible for an ad, which markets or accounts have access, how often ads appear, or whether a particular placement can reach your buyers.

    Do not put total assistant users into a media plan as though they were impressions. Ask for the addressable audience, eligible conversation contexts, available markets, delivery rules, and reporting definitions. If those details are unavailable, the audience number is market context rather than a forecast.

    The deeper difference is incentive design. Anthropic’s stated position is that advertising could undermine trust, encourage assistants to find monetizable moments, and create pressure to prolong engagement. That is Anthropic’s strategic argument for keeping Claude ad-free, not proof that every assistant ad will corrupt every answer. It does identify the right questions for a buyer to test:

    • Does sponsorship affect only the placement, or can it affect the substance, ordering, or framing of the assistant’s answer?
    • Can the user distinguish the sponsored element before interacting with it?
    • Does the disclosure remain visible when the response is expanded, copied, shared, or revisited?
    • Can you prevent placements from appearing in sensitive or unsuitable conversational contexts?
    • Is the system rewarded for resolving the user’s task, extending the conversation, or generating more commercial opportunities?
    • Can you retrieve a record of the creative, disclosure, destination, and context category that were served?

    If a platform cannot answer these questions clearly, you do not yet have enough information to evaluate brand risk. Novelty is not a substitute for placement transparency.

    Build paid distribution and organic AI visibility as separate lanes

    Assistant marketing becomes muddled when paid ads, organic citations, product recommendations, and tool integrations all appear under one AI visibility label. Separate them before assigning work, budget, or performance targets.

    Lane one: paid assistant distribution

    A paid program starts with the unit being purchased. Do not approve a line item called AI assistant ads unless the brief states whether you are buying a sponsored message, a branded module, a link, a product placement, or another clearly defined format.

    • Confirm access. Record the assistant, account type, market, language, device coverage, campaign objective, and inventory status. A platform announcement does not guarantee that your account can buy the format.
    • Define eligible context. Document what user intent or conversation category can trigger the placement. A broad audience label is not enough when the placement appears inside a highly specific exchange.
    • Capture the disclosure. Obtain an example showing the complete placement as the user sees it. Review the label, visual boundary, advertiser identity, and destination before launch.
    • Set exclusions. Identify contexts in which a commercial message would be inappropriate or risky for your brand. If the platform cannot support necessary exclusions, do not assume that careful creative will solve the placement problem.
    • Match the destination. The landing page should preserve the product, offer conditions, limitations, and expectations established by the placement. A conversational ad can feel unusually personal, so a mismatched handoff is especially conspicuous.
    • State one testable hypothesis. Decide whether the pilot is meant to generate qualified visits, purchases, leads, product consideration, or learning about a new format. Do not use platform audience size as the success metric.

    Lane two: unpaid assistant eligibility

    An ad-free policy does not make an assistant irrelevant to commerce. Claude can still help a user research, compare, or purchase products when the user requests that help; its distinction is that the commercial task is user-initiated rather than advertiser-driven. That means a brand can be discoverable without being able to buy its way into the conversation.

    This is where SEO, AEO, GEO, content quality, and structured data meet. Your objective is not to manufacture a recommendation. It is to make verifiable information available when an assistant needs to answer a relevant question.

    1. Map real decision questions. Start with the questions a buyer must resolve: what the product does, who it is for, what it works with, where it is available, what it costs, what is included, and when it is not a suitable choice.
    2. Create a canonical answer for each decision. Put the authoritative fact on a stable page instead of scattering conflicting versions across campaign pages, support documents, and old announcements.
    3. Make qualifiers explicit. Attach version, region, date, plan, compatibility, availability, and pricing conditions to the claim they qualify. An assistant cannot preserve a limitation that your page leaves implicit.
    4. Align JSON-LD with visible content. Use applicable structured-data types, such as Organization, Product, Offer, or SoftwareApplication, only for information that a reader can also verify on the page. Structured data can clarify entities and relationships; it does not make an unsupported marketing claim true or guarantee inclusion in an answer.
    5. Support important comparisons. Explain the basis of a compatibility, performance, feature, or suitability claim. Separate measured facts from editorial positioning and avoid presenting a slogan as evidence.
    6. Remove retrieval barriers. Check that public decision pages can be fetched, rendered, and understood without a login or a fragile interaction. Keep essential facts in readable page content rather than only in images or interactive widgets.
    7. Assign an owner. Product, policy, price, and availability pages need someone responsible for correcting stale facts. Display an updated date only when it reflects a genuine review.

    Paid placement may create exposure on one assistant. It will not repair contradictory specifications, inaccessible pages, vague entities, or unsupported claims. Organic readiness therefore remains infrastructure, not a fallback campaign.

    Use a six-part gate before approving an AI ad test

    A small pilot can be reasonable when the format is new, but small does not mean ungoverned. Require a written answer to each gate before money moves.

    1. Inventory gate: Is the placement available to your account in the intended market, language, device environment, and campaign period? If not, keep the item out of the committed budget.
    2. Influence gate: What exactly does payment buy? Separate eligibility for a labeled placement from influence over the assistant’s non-sponsored response. If the boundary is unclear, pause.
    3. Disclosure gate: Can a reasonable user tell what is sponsored, who paid for it, and where it leads? Review the complete rendered experience, not just the advertiser dashboard preview.
    4. Context gate: Can you target useful commercial intent and exclude contexts that would make the message intrusive, unsafe, or damaging? If context controls are weaker than your brand requirements, the inventory is not suitable.
    5. Measurement gate: Will reporting expose delivery, interaction, cost, and outcome definitions? A dashboard number without a denominator or documented event definition cannot support a scale decision.
    6. Economics gate: Is the test budget tied to a customer-value hypothesis and a stopping rule? Do not derive an acceptable price from the assistant’s total user count. Set it from the value of the outcome you can actually measure.

    Pass all six gates before treating the channel as performance media. If disclosure and context control pass but conversion measurement is weak, classify the activity as a learning or awareness test. If disclosure or answer independence fails, waiting is the clearer decision. If the assistant is ad-free, redirect the work to organic eligibility instead of searching for an unofficial shortcut.

    Include procurement, legal, privacy, and brand-safety reviewers when the placement uses personal data, operates in sensitive contexts, or creates claims with contractual consequences. The specific review depends on your market and use case; the novelty of the format does not remove existing obligations.

    Measure paid delivery, business outcomes, and organic visibility separately

    An assistant interaction can influence a decision without producing an immediate click. That does not justify vague attribution. It means you need a measurement structure that shows what is directly observed, what is attributed under your rules, and what remains unknown.

    Build the paid scorecard in layers:

    • Delivery: eligible conversation contexts, sponsored impressions, viewable placements, reach, and frequency, but only where the platform reports and defines them.
    • Interaction: placement opens, expansions, clicks, product-detail views, or other actions that can be tied to the sponsored unit.
    • Business outcome: qualified leads, purchases, subscriptions, booked meetings, or another outcome your existing analytics can validate.
    • Efficiency: cost per defined interaction and cost per defined business outcome. Preserve the event definition next to the number.
    • Quality: lead quality, cancellations, returns, or downstream customer value where those measures are relevant and available.
    • Trust and safety: complaints, unsuitable-context incidents, misleading renderings, disclosure failures, and brand-safety escalations.

    Tag paid destinations with campaign parameters and preserve the assistant, campaign, placement, creative, market, and date in your analytics records. Do not adopt a special attribution window merely because the channel uses AI. Apply your documented attribution rules, report direct and assisted outcomes separately where possible, and label modeled results as modeled.

    Incrementality deserves its own line. Use a randomized holdout when the platform supports one. Without a valid control, describe changes as observed or attributed rather than claiming the ads caused every conversion. A before-and-after increase can be useful evidence, but seasonality, other campaigns, and changes in demand can also move it.

    Organic AI visibility needs a different scorecard because no impression was purchased. Maintain a fixed set of decision prompts based on real buyer questions. For every check, record the assistant, model or product surface, market, date, account state, prompt, response, cited pages, brand inclusion, factual accuracy, and important omissions. Consistent conditions make changes interpretable; an isolated screenshot does not.

    • Track whether the brand is mentioned, but do not treat every mention as a recommendation.
    • Track whether a relevant page is cited, but inspect whether the citation actually supports the answer.
    • Track factual accuracy separately from visibility. A prominent but incorrect description is not a win.
    • Track referral traffic where it is observable, while acknowledging that some assisted journeys may not pass a usable referrer.
    • Keep paid appearances out of the organic visibility total. Sponsorship, citation, recommendation, and integration are different events.

    The final decision should be channel-specific. Scale a paid format only when delivery, business value, and placement integrity remain acceptable together. Improve organic content when assistants omit the brand, cite weak pages, or repeat stale facts. Escalate a platform issue when the disclosure, rendering, or context differs from what was approved.

    Key takeaways

    • AI assistant advertising is a platform policy, not a universal media category. Confirm that purchasable inventory exists before assigning budget.
    • Claude’s ad-free model still permits user-initiated research and commerce, so organic discoverability remains commercially relevant even where sponsored responses are unavailable.
    • A platform’s total users are not the same as addressable audience, eligible conversations, sponsored impressions, or conversions.
    • Before testing, require clear answers on paid influence, disclosure, context controls, measurement, and economics.
    • Build paid distribution and organic AI visibility as separate programs with separate metrics. Never report a sponsored appearance as an organic recommendation.
    • Accurate pages, explicit qualifiers, aligned JSON-LD, retrievable content, and maintained facts strengthen your eligibility across both ad-supported and ad-free assistants without guaranteeing selection.

    Your next move is practical: create a one-page inventory brief for every assistant ad opportunity, run it through the six gates, and establish an organic prompt-and-citation baseline before the campaign begins. You will then know whether you are buying measurable distribution, improving unpaid eligibility, or merely reacting to a large audience number.

    References

  • Agentic Commerce Protocols: A Practical Readiness Plan

    Agentic Commerce Protocols: A Practical Readiness Plan

    You may already have product schema, shopping feeds, and commerce APIs, yet still not know whether your store is ready for an AI agent to recommend an item, verify the offer, and help complete a purchase. That uncertainty is the real protocol problem. The question is not simply which acronym to support, but whether your product facts and transaction controls survive a machine-to-machine buying journey.

    The safest approach is to separate protocol compatibility from commerce readiness. Build one reliable commerce core, then connect protocols to it through controlled adapters. That gives you a practical path into Google UCP and OpenAI ACP without duplicating pricing, inventory, checkout, or policy logic for every new interface.

    Choose the commerce job before you choose the protocol

    An agentic commerce protocol is an interoperability contract. It defines how participating systems exchange commerce information or request actions. That contract matters, but it does not replace your catalog, pricing engine, order system, payment flow, or fulfillment operation.

    Start by naming the buyer journey you want an agent to support. “We support agentic commerce” is too vague to test. “An agent can identify the correct variant, verify the current offer, create a cart, and return a checkout handoff” is specific enough to build and audit.

    Commerce jobRequired source of truthFailure to prevent
    Discover and compareCatalog, product identity, variants, attributes, and relationshipsThe agent selects the wrong product or compares unlike variants
    Verify an offerCurrent price, currency, availability, eligibility, and fulfillment conditionsThe agent presents an expired, unavailable, or inapplicable offer
    Create a cart or checkout handoffCart, promotion, customer, and checkout servicesA discount is misapplied, a cart is corrupted, or the buyer loses context
    Complete a bounded actionAuthentication, authorization, payment, and order servicesAn unauthorized or duplicate transaction is created
    Confirm and support an orderOrder status, fulfillment, cancellation, and return systemsThe agent promises an action that the merchant cannot honor

    A protocol may cover all, some, or none of those jobs. Build a requirements matrix from the actual specification and label each capability as supported, externally handled, unsupported, or subject to approval. Do not turn partial support into a blanket compatibility claim.

    This also prevents a common architecture mistake: wiring business rules directly into a protocol integration. Protocol-specific code should translate requests and responses. Your existing commerce services should continue deciding what an item costs, whether it can be sold, which promotion applies, and what happens after the order.

    Make product and offer data internally consistent

    A product is surrounded by synchronized catalog, inventory, price, variant, shipping, and availability objects while mismatched duplicates are corrected.

    An AI agent cannot resolve contradictions by calling them “close enough.” If a product page says an item is available, a feed carries yesterday’s price, and the transaction API rejects the variant, the agent has no trustworthy offer to present. More interfaces amplify that inconsistency rather than repairing it.

    Build a field-level inventory before adding endpoints. For every fact exposed to an agent, record its format, owner, update path, and authoritative system.

    1. Stabilize identity. Give each sellable product and variant a durable internal identifier. Use the same identifier wherever your catalog, feed, structured data, cart, and order systems can carry it.
    2. Separate products from offers. Descriptive attributes such as material or compatibility do not change on the same schedule as price, availability, delivery options, or promotion eligibility. Model them separately so mutable offer data can be refreshed without rebuilding the whole product record.
    3. Represent variants explicitly. Size, color, capacity, pack quantity, and other purchase-defining options should resolve to an exact sellable item. Do not make an agent infer the variant from an image filename or a paragraph of marketing copy.
    4. State conditions alongside claims. A price or delivery promise without its currency, region, eligibility, or other applicable condition is incomplete. Return the condition with the value rather than expecting the agent to recover it elsewhere.
    5. Connect policies to the affected offer. Return, cancellation, warranty, subscription, and fulfillment terms should be retrievable in the context where they apply. A generic policy page is useful to people, but it may not resolve an exception attached to one product or offer.
    6. Define conflict precedence. Decide which system wins when the page, JSON-LD, feed, cache, and transaction service disagree. Mutable facts should normally be revalidated against the system that can actually accept the transaction.

    JSON-LD remains useful, but it serves a different role from a transaction API. Structured data helps machines interpret what a public page describes. It does not reserve inventory, authorize a discount, create an order, or prove that a cached offer is still valid. Keep page content, markup, feeds, and APIs aligned, then revalidate consequential facts when the buyer moves from discovery to action.

    Give each response an unambiguous outcome. If current availability cannot be confirmed, return an unavailable or indeterminate state and a safe next step. Do not substitute an old value, invent a delivery promise, or turn missing data into a confident answer.

    Put explicit controls around every agent action

    A discovery request is mostly informational. Creating a cart changes state. Placing an order, cancelling one, or requesting a refund can affect money and customer rights. Your controls should become stricter as the consequence increases.

    Put a protocol adapter between the external agent interface and your internal commerce services. The adapter should translate fields, enforce the supported capability set, reject malformed requests, and produce protocol-compatible errors. It should not become a second pricing engine or an alternative order-management system.

    • Authenticate the caller. Establish which agent, platform, account, or delegated identity is making the request.
    • Authorize the exact action. Knowing who called is not enough. Check whether that identity may read an offer, create a cart, place an order, cancel an order, or request another state change.
    • Revalidate server-side. Price, availability, promotion eligibility, shipping conditions, and order totals must be checked by the commerce system before commitment. Values repeated by the agent are inputs to verify, not facts to trust.
    • Make retries safe. State-changing requests need a stable operation identifier or equivalent idempotency control. A timeout followed by a retry must not create a second order or duplicate another irreversible action.
    • Bound delegated authority. Limit what the agent can buy, change, cancel, or approve. When the requested action exceeds that authority, require an explicit user decision rather than stretching the scope silently.
    • Preserve an audit trail. Record the caller, requested action, authorization result, validated commercial state, resulting transaction, and error outcome. Keep sensitive information out of prompts and general-purpose traces.
    • Return recoverable errors. Tell the agent whether it should refresh an offer, request a missing selection, ask the buyer for confirmation, hand off to checkout, or stop. Do not expose credentials or sensitive internal details in the explanation.

    Route payment credentials and personal data through your approved payment, identity, consent, and privacy flows. An agent conversation or model trace is not a safe substitute for those systems. If the agent only needs to hand the buyer into checkout, give it a constrained handoff mechanism rather than unnecessary access to the full payment process.

    Confirmation also needs state awareness. If the price, item, quantity, delivery terms, or another material condition changes after the buyer’s instruction, stop and present the changed state before committing. Agreement to one offer is not blanket permission to accept a different one.

    Optimize discovery and transaction readiness separately

    Protocol support is not a ranking switch. An agent still needs to discover your products, understand them, decide whether they fit the request, and obtain a valid path to action. A working checkout endpoint does not compensate for vague product information, just as excellent content cannot complete a transaction when the offer cannot be verified.

    Treat the journey as four connected layers:

    • Discovery: Can the system find a canonical product page or catalog record for the buyer’s need?
    • Understanding: Can it identify the product, variant, attributes, compatibility, constraints, and applicable policies without guessing?
    • Decision support: Does your content answer the questions that distinguish this option from alternatives?
    • Action: Can the agent verify the live offer and move into a controlled cart, checkout, or order flow?

    Your public content should do more than repeat a product name and a promotional claim. State concrete specifications, intended use, compatibility, included components, variant differences, purchase conditions, and limitations where they matter. Use consistent terminology across prose, tables, structured data, feeds, and APIs. If one surface calls an option a “starter pack” while another exposes only an unexplained internal code, automated matching becomes less reliable.

    Keep canonical pages useful to people even when machines consume their data. Clear explanations help a buyer verify the recommendation and give answer engines grounded material to cite or summarize. The protocol should extend that experience into live commerce operations, not turn the website into a thin wrapper around an endpoint.

    Measure these layers independently. If products are rarely selected, investigate discoverability, identity, attributes, and decision content. If products are selected but transactions fail, investigate offer freshness, authorization, validation, handoff, and error recovery. Combining both failures into one “AI traffic” metric hides the part you need to fix.

    Roll out one bounded journey and test the failure paths

    An abstract shopping agent travels through a guarded test corridor while unavailable inventory, price changes, payment failure, delivery problems, and permission blocks are contained on side paths.

    Do not begin by exposing every catalog action to every agent. Choose one journey with a clear owner, a known source of truth, and a reversible handoff where possible. A narrow implementation reveals data and control problems before they spread across the whole store.

    1. Define the journey. Write the starting request, required product decisions, supported actions, handoff point, completion signal, and responsible internal team.
    2. Write the field contract. List required and optional fields, identifiers, formats, authority, freshness expectations, and what happens when a value is absent.
    3. Write the action contract. For every state change, define authentication, authorization, validation, confirmation, retry handling, audit output, and safe failure response.
    4. Validate read-only behavior first. Confirm that product identity, variants, current offers, and policies resolve consistently before allowing the integration to alter carts or orders.
    5. Simulate state changes. Exercise order creation, retries, timeouts, revocation, changing prices, unavailable variants, expired promotions, and partial service failures without risking a real buyer’s money.
    6. Restrict the first live scope. Limit the supported catalog, actions, regions, accounts, or other meaningful dimensions until the operational signals are stable.
    7. Expand by evidence. Add capabilities only when the previous scope has reliable data, safe authorization, understandable errors, and an owner who can respond to exceptions.

    Test cases that expose weak integrations

    • The chosen variant goes out of stock after discovery but before checkout.
    • The price or promotion changes between recommendation and commitment.
    • A request times out after the order service succeeds, then the agent retries it.
    • The buyer omits a purchase-defining option such as size, quantity, or configuration.
    • The caller’s authorization is revoked during the session.
    • An internal service succeeds while the protocol adapter fails to return the response.
    • The requested shipping, cancellation, or return condition is not available for that offer.
    • The agent requests an action outside its delegated scope.

    A pass is not merely “the endpoint returned a response.” The response must preserve the correct commercial state, avoid duplicate effects, explain what the agent can do next, and leave an auditable record.

    Measure the agent funnel, not just agent traffic

    Give every metric a numerator, denominator, and operational owner. Useful measures include exact product-resolution rate, successful offer-verification rate, cart or handoff success, authorized action success, duplicate requests safely suppressed, policy exceptions, and completed orders associated with an agent-assisted journey. Track stale-data failures separately from authorization and checkout failures because they require different fixes.

    Preserve the boundary between influence and completion. An agent referral, a protocol request, a cart creation, a checkout handoff, and a paid order are different events. Calling all of them conversions will overstate performance and make protocol decisions harder to defend.

    Key takeaways

    • Define the exact discovery or transaction journey before evaluating a protocol.
    • Keep pricing, inventory, policy, checkout, and order rules in your core commerce systems.
    • Use adapters to connect protocols rather than rebuilding business logic for each interface.
    • Align product pages, JSON-LD, feeds, and APIs, but revalidate mutable facts before consequential actions.
    • Require explicit authentication, action-level authorization, safe retries, bounded delegation, and audit records.
    • Launch with a restricted journey, test failure states, and expand only when each stage has measurable reliability.

    Your next move is to pick one sellable journey and document its fields, actions, authorities, and errors on a single implementation map. That map will show whether your immediate constraint is visibility, catalog quality, transaction safety, or protocol translation. Fix that constraint first, then add the interface that gives the journey a useful route into agentic commerce.

    References

  • Microsoft Copilot Conversational Commerce: Merchant Guide

    Microsoft Copilot Conversational Commerce: Merchant Guide

    If your products already rank in search, that does not mean they are ready to sell inside Microsoft Copilot. Conversational commerce adds two points of failure: the assistant must answer a buyer’s exact question from reliable product data, and the purchase path must preserve the right product, variant, terms and price through checkout.

    Microsoft’s rollout gives merchants two related but distinct surfaces to prepare for: Copilot Checkout inside Copilot.com and Brand Agents on Shopify stores. You need a different operating plan for each one, followed by a shared catalog audit, conversation test and measurement framework.

    Treat Copilot Checkout and Brand Agents as separate surfaces

    It is easy to collapse both products into a single AI shopping feature. That creates muddled ownership and incomplete testing. Copilot Checkout handles a transaction within a Copilot conversation; a Brand Agent answers and guides shoppers on a merchant’s own Shopify site. One changes an off-site buying path. The other changes an on-site decision path.

    Copilot Checkout shortens the path from answer to purchase

    Copilot Checkout began its U.S. rollout on Copilot.com, allowing a buyer to complete a purchase without leaving the current conversation. PayPal, Shopify, Stripe and Etsy were named as integration partners.

    That changes what it means to be visible. A product mention is no longer the final objective; the product also has to remain purchasable when the buyer acts. Ask your commerce owner to verify which catalog, inventory, price, variant and policy records feed the transaction. The presence of a payment partner does not tell you which system supplies each product fact.

    Shopify merchants are automatically enrolled and can opt out. Treat that as a reason to check your status, not as proof that your store is ready or that a particular product is already appearing. Non-Shopify merchants have an application route, so eligibility work and content optimization should be managed as separate tasks.

    Brand Agents influence the decision on your own site

    Brand Agents are available to Shopify merchants. They use the merchant’s product catalog to answer product-specific questions, adopt the brand’s voice and guide shoppers from browsing toward purchase. Microsoft says they can be set up in a few hours.

    Fast setup is not the same as production readiness. A quick installation cannot resolve contradictory variant names, incomplete compatibility details, buried exclusions or a returns rule that differs between the catalog and the storefront. Put catalog and policy owners in the launch workflow before asking the marketing team to tune the agent’s tone.

    The practical ownership split is simple: your ecommerce team should own transaction integrity, your product-data team should own factual answers, and your brand team should own voice. Give one person authority to stop the rollout when those layers disagree.

    Build an answer-ready catalog, not just an indexable page

    Structured product records connect colors, sizes, inventory, delivery, returns, and pricing to an AI-assisted recommendation.

    Traditional product-page optimization often concentrates on discoverable titles, category copy and commercial keywords. A conversational agent also needs enough explicit information to resolve follow-up questions. The difference matters because shoppers rarely ask for a keyword in isolation. They add a use case, compare options, introduce a constraint and then ask whether a particular variant will work.

    For every product family you expect an agent to recommend, review these elements:

    • Identity: Use one canonical product name and a plain description of what the product is. Keep abbreviations, model names and bundles distinguishable.
    • Variants: Make size, color, capacity, configuration and other selectable attributes unambiguous. A buyer should not have to infer whether two labels describe the same option.
    • Fit and compatibility: State who or what the product works with, along with material exclusions. Do not hide a decisive limitation in an image or an unrelated help page.
    • Included items: Say what arrives in the package and what must be purchased separately. This prevents a recommendation from creating the wrong expectation.
    • Commercial facts: Keep price, availability, shipping conditions, returns and warranty language aligned with the systems that govern the transaction.
    • Comparison logic: Explain the decision-relevant difference between adjacent products. A list of specifications is less useful than a clear statement of when a buyer should choose one option over another.
    • Claim boundaries: Mark subjective language as positioning and reserve factual claims for statements you can support. Brand voice must not turn a qualified benefit into a guarantee.

    Your structured data should reflect the same facts. Keep Product and Offer markup synchronized with visible copy and store data, but do not present schema as a magic switch for Copilot eligibility. The announced merchant routes are Shopify enrollment or a non-Shopify application; adding markup alone does not complete either route.

    When the page, JSON-LD, catalog and checkout disagree, choose a system of record for each field and repair the downstream copies. Do not solve the conflict by giving the agent a more persuasive answer. The correct response to uncertain availability or compatibility is a qualified answer, a request for clarification or a refusal to claim more than the data supports.

    Turn the catalog audit into an answer audit. Write representative questions in the language a shopper would use, then attach each approved answer to the exact field, policy or page statement that supports it:

    • What is this product, and what problem is it meant to solve?
    • Will it work with the model, space, use case or constraint I described?
    • What is the meaningful difference between these two options?
    • Which variant should I choose, and why?
    • What is included, and what would I still need?
    • What happens if the item is unavailable or the stated condition is not met?
    • Which shipping, return or warranty qualification applies to this purchase?

    If an approved answer has no supporting location, you have found a data gap. Repair that gap before expanding the agent’s vocabulary. This is also the most useful place for SEO, AEO and ecommerce teams to collaborate: the question set reveals what buyers need, while the evidence map shows whether your content and structured data can answer them consistently.

    Test the complete buying conversation before launch

    A merchant team checks each stage of an AI-guided purchase, from a shopper's question through product selection, variant validation, checkout, and delivery.

    A polished demonstration usually follows a clean prompt and a known product. Real buyers are less orderly. They misspell model names, change constraints, compare products that are not equivalent and revise a variant near the end. Your test should reproduce that behavior instead of asking only whether the agent can recite a product description.

    1. Begin without a product name. Describe a need and see whether the agent asks a useful clarifying question or jumps to an unsupported recommendation.
    2. Add a material constraint. Introduce compatibility, size, intended use or another condition that should narrow the answer. Check whether the recommendation changes appropriately.
    3. Request a comparison. Ask why one product or variant is a better fit than another. Confirm that every claimed difference exists in the catalog or visible product information.
    4. Probe an exception. Ask about an unavailable option, an ambiguous model, an excluded use or a policy edge case. A safe agent should expose uncertainty instead of smoothing it over.
    5. Continue toward purchase. Verify that the selected product, variant, quantity, price and applicable terms survive the handoff to checkout. Use the approved test method for your commerce stack rather than real customer payment details.
    6. Change your mind late. Switch a variant, revise a constraint or return to the comparison. Confirm that the final checkout state reflects the latest instruction rather than an earlier choice.

    Record the expected answer, observed answer, supporting evidence, severity and owner for every test. Use a severity model that reflects actual commercial risk:

    • Blocker: wrong product, price or variant; an unsupported policy statement; a payment problem; or a claim that could materially mislead the buyer.
    • Major: the agent cannot answer a common high-intent question, loses an important constraint or recommends an option without evidence.
    • Minor: awkward wording, unnecessary repetition or a tone mismatch that does not change the factual meaning.

    Do not approve a production launch with unresolved blockers. Correctness belongs ahead of personality because a charming wrong answer still creates the wrong order. Tune brand voice after the agent can identify uncertainty, retain constraints and carry the correct selection into the transaction.

    Measure assisted commerce without mistaking correlation for lift

    Microsoft Clarity provides Brand Agent conversation insights and lets merchants compare agent-assisted sessions with organic traffic. That gives you a useful diagnostic view, but the two groups are not automatically equivalent. People who open a shopping conversation may already have different intent from visitors who do not.

    Microsoft says Brand Agent-assisted sessions show higher engagement and conversion. Treat that vendor claim as a hypothesis for your store, not a forecast. No percentage is supplied, and more interaction can be a mechanical result of adding a chat experience. Engagement is useful only when it helps explain a commercial outcome or reveals a problem.

    Build your measurement plan around questions that lead to a decision:

    • Did the agent attract use? Measure eligible sessions, agent starts and meaningful exchanges. Define a meaningful exchange before reviewing results so a greeting is not counted as successful assistance.
    • Did it improve buying progress? Compare product views, checkout starts and completed orders for relevant segments. Use your store or analytics platform for commerce outcomes that Clarity does not provide.
    • Did it improve order quality? Watch cancellations, returns, support contacts and variant corrections associated with agent-assisted purchases. A higher conversion rate can conceal a recommendation problem if downstream friction rises.
    • Which questions failed? Group unsuccessful conversations by missing product fact, ambiguous variant, policy gap, unsupported comparison, technical handoff or tone. Send each category to the team that can repair the underlying system.
    • What changed during the period? Annotate catalog updates, promotions, traffic shifts and agent revisions. Without that change log, a conversion movement is easy to credit to the wrong cause.

    Use the Clarity comparison directionally unless you have a controlled test with comparable audiences. When a controlled test is not practical, compare matched time periods and similar acquisition segments, then look for the same pattern across commerce outcomes and conversation quality. Do not call a result incremental lift merely because assisted sessions converted differently.

    Keep Copilot Checkout and Brand Agent reporting separate. The first can influence a purchase completed inside an off-site conversation; the second assists a shopper on your Shopify site. Before reporting AI-commerce revenue, document how each path appears in analytics, payment records and order data. Otherwise, a change in attribution can look like a change in demand.

    Key takeaways

    • Copilot Checkout and Brand Agents solve different parts of the journey, so assign separate owners and tests.
    • Shopify merchants should verify their Copilot Checkout enrollment status and readiness rather than assuming automatic enrollment means every product is transaction-ready.
    • A conversational agent needs explicit product identity, variants, compatibility, comparisons, commercial terms and claim boundaries.
    • Keep storefront copy, catalog data, JSON-LD and checkout records consistent; schema cannot compensate for contradictory commerce data.
    • Test discovery, clarification, comparison, exceptions, late changes and checkout state before tuning the agent’s personality.
    • Use Clarity insights to find behavior and answer gaps, but verify commercial outcomes in store analytics and avoid treating an observational comparison as causal lift.

    Your next move is a catalog-and-conversation audit on the product family where a wrong recommendation would create the most customer friction. Run discovery, fit, comparison, exception and checkout prompts against it. Repair every unsupported answer at the data or policy layer, then decide whether the experience is ready to scale.

    The first win is not making the agent sound clever. It is making sure the buyer receives the same accurate answer from the catalog, product page, agent and checkout.

    References

  • A Practical Guide to Product Visibility in AI Commerce

    A Practical Guide to Product Visibility in AI Commerce

    If your product performs well in conventional search but vanishes when a shopper asks an AI assistant what to buy, adding more keywords is unlikely to solve the whole problem. The assistant still has to identify the item, connect it to the request, evaluate the available claims, and give the shopper a viable next step.

    Your goal is durable AI shelf presence: making the product easy for shopping systems such as ChatGPT, Perplexity, and Rufus to evaluate and choose when the buyer’s request fits. That requires clearer product facts, better decision support, and repeatable testing.

    Treat visibility as a chain, not a single ranking

    Think of product visibility as a chain with five gates. This is a practical audit model, not a reverse-engineered description of any platform’s algorithm:

    • Availability: A usable product page, listing, or product record exists for the relevant market, and the offer is still available.
    • Identity: The product, brand, model, and variant can be distinguished from similar items.
    • Relevance: The product’s attributes and intended uses answer the shopper’s stated need and constraints.
    • Confidence: Important claims are specific, consistent, qualified where necessary, and supported by information a buyer can inspect.
    • Actionability: The shopper can determine what is being sold, by whom, under which terms, and what to do next.

    A weakness early in the chain can make later optimization irrelevant. Strong comparison copy cannot repair an unavailable offer. Detailed specifications cannot help if two variants share an ambiguous identity. A recommendation is also less useful when the destination page shows a different price, configuration, or compatibility statement.

    Use the pattern of failure to decide where to investigate. If the product rarely appears for broad category requests, begin with availability and identity. If it appears for broad requests but disappears when a buyer adds a use case or constraint, inspect the decision facts that establish relevance. If the name is correct but the details are wrong, look for conflicting or stale representations. If the assistant describes the product accurately but cannot lead the shopper to a current offer, focus on actionability.

    These are clues, not proof of a particular ranking factor. They keep your audit tied to an observable failure instead of sending the team into a general rewrite.

    Build one canonical product record before creating more content

    A central unbranded product and layered digital record connect to matching product representations across several shopping channels.

    Before editing product copy, decide what must be true everywhere the product appears. Create an internal canonical record that separates stable identity, variant-specific information, buying criteria, and commercial terms.

    • Stable identity: Brand, exact product name, model identifier, product category, and any identifier used consistently across your catalog.
    • Variant identity: The attributes that make one configuration different from another, such as size, capacity, material, color, bundle contents, or compatibility.
    • Decision facts: The specifications that materially affect whether the product fits the intended use.
    • Fit and limits: The buyer, task, environment, or use case the product is designed for, plus important situations where it is not a fit.
    • Commercial facts: Current price, currency, availability, seller, included items, delivery conditions, and applicable return terms.
    • Claim support: The basis, scope, qualifier, and approved wording for each consequential performance or compatibility claim.

    The exact decision facts will differ by category. Do not add attributes merely because a generic template contains them. Start with the questions that would change a buyer’s choice, then make the answers explicit.

    Pay particular attention to the boundary between a product family and its variants. A family page should not imply that every configuration has the same dimensions, contents, compatibility, price, or availability. Give each purchasable choice an unambiguous label, and place variant-specific facts beside the choice they describe.

    Keep visible copy and structured data synchronized

    If you publish product and offer information through JSON-LD or another machine-readable format, treat it as a representation of the same canonical record. It should not become a correction layer for an incomplete product page or a hiding place for facts a shopper cannot verify.

    • Use the same exact product and variant names in the page heading, selection controls, structured data, feeds, and merchant listings.
    • Make sure visible price, currency, seller, and availability agree with the corresponding machine-readable values.
    • Connect each offer to the correct configuration instead of attaching a family-level offer to every variant.
    • Remove expired promotional language and discontinued configurations from every representation, not only from the visible page.
    • Give commercial facts an owner and an update trigger so a stock, price, policy, or bundle change does not leave old values behind.

    Structured data can reduce ambiguity, but markup alone does not make a product relevant or credible. The visible page still needs to help a person understand the choice.

    Use a claim ledger to prevent confident contradictions

    Create a claim ledger for statements that could influence a purchase. Record the claim, its classification, supporting material, necessary qualifier, approved wording, every place it appears, and the person responsible for keeping it current.

    Classify claims before approving them. An objective attribute is different from a compatibility statement, a seller policy, a marketing claim, or a customer’s opinion. Do not turn a reviewer’s experience into a universal product fact. Do not publish phrases such as works with everything, best for everyone, or free returns without the conditions that make the statement accurate.

    When a claim depends on a variant, region, accessory, operating condition, subscription, or seller, carry that qualifier everywhere the claim appears. Clear limitations improve the buyer’s decision and reduce the chance that an assistant has to reconcile incompatible descriptions.

    Answer the decision prompts buyers give shopping assistants

    Traditional product copy often describes what an item is. AI shopping prompts frequently ask whether it is right for a particular person, task, constraint, comparison, or purchase situation. Your content has to bridge that gap without manufacturing a separate thin page for every possible wording.

    Buyer questionWhat your content must make clear
    Who or what is this product for?The intended user, task, environment, and important exclusions.
    Does it meet this constraint?The exact relevant attribute, applicable variant, and any condition or threshold the buyer must check.
    Will it work with something I already own?A direct compatibility answer, supported models or systems, required accessories, and exceptions.
    How does it differ from another option?Meaningful trade-offs, not a list that portrays every attribute as a win.
    Can I buy the right version now?The current configuration, seller, price, availability, included items, and applicable purchase terms.

    Build a prompt-to-evidence map for each commercially important product. Gather real buyer language from the customer-facing material you already have, such as internal search terms, support questions, reviews, sales notes, and product-page queries. Group the language by need, constraint, compatibility, comparison, and transaction intent. Then connect each group to the page section and product facts that answer it.

    For a direct question, use an answer-first structure:

    1. Give the direct answer: yes, no, or it depends.
    2. State the decisive reason in plain language.
    3. Name the relevant condition, exception, or configuration.
    4. Provide the specification or evidence that supports the answer.
    5. Point the shopper to the correct variant, comparison, or purchase step.

    Comparison content deserves particular care. A useful comparison names the dimensions that matter, explains who benefits from each trade-off, and acknowledges where the competing choice is stronger. If your product is easier to carry but has less capacity, both facts belong in the decision. A comparison that declares your product the winner in every situation gives the buyer less usable information.

    Do not confuse natural language with vagueness. A sentence can be easy to read and still carry an exact model name, material, dimension, compatibility condition, or policy scope. That combination gives assistants useful language while preserving the facts a shopper needs to verify.

    Measure scenario coverage instead of chasing one answer

    Anonymous shoppers surround an AI assistant display where different unbranded products are highlighted for varied shopping needs.

    One favorable response to one prompt is not a visibility strategy. A mention is not necessarily a recommendation, and a recommendation is not necessarily accurate. Build a repeatable test that shows where the product enters, survives, or falls out of the shopping decision.

    1. Define the eligible offer. Choose the exact product and variant, the market where it can be purchased, and the facts that must be current for the test to be valid.
    2. Create a fixed prompt set. Cover category discovery, use-case fit, constraints, compatibility, comparison, objections, and purchase intent. Preserve the exact wording.
    3. Run prompts in the relevant environments. Test ChatGPT, Perplexity, Rufus, or another assistant only when it is part of the audience’s plausible shopping journey. Record language, market, sign-in state, and conversation context.
    4. Capture the whole response. Log whether the product appears, the role it receives, the reasons given, the stated facts, the linked destination, and whether a valid offer can be reached.
    5. Classify the failure. Map the result to availability, identity, relevance, confidence, or actionability before deciding what to edit.
    6. Change one meaningful layer. Correct a data conflict, improve a decision answer, clarify a variant, or repair an offer. Once the updated information is available to the tested environment, repeat the same prompt set.

    Track separate measures rather than hiding everything inside a composite visibility score:

    • Inclusion coverage: How often the product appears in test scenarios where it is genuinely eligible.
    • Consideration coverage: How often it appears as a serious option rather than an incidental mention.
    • Recommendation coverage: How often the product is selected for scenarios it actually fits.
    • Factual accuracy: How many checked product and offer facts are represented correctly.
    • Citation alignment: Whether the linked destination supports the claims made in the answer.
    • Transaction readiness: Whether the shopper can reach the correct, current, purchasable configuration.

    The combination of measures tells you what to do next. Low inclusion points you toward availability and identity. Reasonable inclusion with weak recommendation coverage points toward fit, differentiation, or decision evidence. Strong inclusion with poor factual accuracy points toward inconsistent or outdated product representations. Accurate recommendations with weak transaction readiness point toward the offer and purchase path.

    AI answers can vary with wording, context, and system changes, so testing is directional rather than a permanent certification. Keep the prompt set and evaluation rules stable enough to distinguish a recurring pattern from an isolated response.

    Key takeaways

    • Diagnose AI commerce visibility across availability, identity, relevance, confidence, and actionability instead of treating it as one ranking problem.
    • Maintain one canonical product record, with a clear boundary between family-level facts and variant-specific facts.
    • Keep visible content, JSON-LD, feeds, listings, and commercial terms synchronized.
    • Write for buyer decisions: fit, constraints, compatibility, trade-offs, and the path to the correct offer.
    • Measure inclusion, recommendation, accuracy, citation alignment, and transaction readiness separately.
    • Treat every test result as evidence about a failure class, not proof that you have discovered a platform’s algorithm.

    Start with one commercially important product. Build its canonical record, repair the most consequential conflict, map the buyer’s decision prompts, and run a fixed test set. Once that product can be identified, evaluated, described accurately, and purchased without ambiguity, turn the process into a catalog template.

    References

  • AI-Driven Commerce: Build for Search, Answers and Agents

    AI-Driven Commerce: Build for Search, Answers and Agents

    If a shopper needs six tabs and a set of notes to understand the differences between your products, your catalog has a data problem disguised as a user-experience problem. AI can now perform much of that comparison before the shopper reaches your site, so a polished product page is no longer your whole sales surface.

    Your job is not to choose between Google and ChatGPT. It is to give search engines, answer engines, and emerging shopping agents the same accurate, decision-ready facts, then measure how each channel moves the buyer toward a transaction.

    The commerce journey has expanded, not moved

    AI search is adding another discovery and evaluation layer. It is not yet a reason to abandon conventional search. Search engines still account for about 88% of search traffic, while AI usage is growing alongside it. For ecommerce specifically, Google organic search reportedly supplies 43% of traffic and supports 23.6% of sales. Those figures are directional rather than a forecast for your store, but they make the strategic choice clear: protect traditional search visibility while building AI visibility.

    A buyer may ask an AI assistant to shortlist products, use Google to verify a feature, open your product page to check availability, return to the assistant with a compatibility question, and later make a branded search before purchasing. If you measure only the final click, you can mistake a multi-channel decision for a single-channel conversion.

    SurfaceWhat the buyer needs thereWhat you should provide
    Traditional searchDiscovery, navigation, and verificationIndexable product, category, comparison, and supporting pages
    AI answerA concise explanation or recommendationDirect answers, complete context, explicit differences, and verifiable claims
    Shopping agentFacts it can retrieve and evaluate consistentlyStructured product, offer, variant, compatibility, and policy data
    Your websiteConfidence and a path to purchaseClear evidence, current commercial details, usable navigation, and checkout

    Do not run these as four disconnected strategies. They are four presentations of the same catalog. A processor name, supported device, price, included accessory, or return condition should not change depending on whether it appears in page copy, JSON-LD, a merchant feed, or an internal API.

    This changes the meaning of search optimization. You are no longer optimizing only for a ranking and a click. You are optimizing the information chain that lets a machine discover a product, distinguish it from alternatives, explain the distinction, and hand the buyer an accurate next step.

    Build product content around decisions, not descriptions

    Most product pages describe one item at a time because that is how a seller organizes a catalog. Buyers usually think in differences: what changes between the base and premium versions, which missing feature matters, whether two names describe the same capability, and whether the extra cost solves their actual problem. That gap is why even a built-in comparison tool can leave a shopper with more questions than answers.

    Start with the product families that generate repeated comparison questions, not necessarily the products with the most visits. A product with modest traffic but high consideration can benefit more from better decision content than a familiar commodity with substantially more visits.

    1. Define the real choice set. Group models, plans, sizes, generations, or substitutes that a reasonable buyer would compare. Your internal category structure may not reflect that choice set.
    2. Normalize the attributes. Use the same name, unit, and value format for the same characteristic. Do not call a field “battery duration” on one page and “typical runtime” on another unless they measure different things.
    3. State absence explicitly. A blank cell is ambiguous. Use language such as “not included,” “not supported,” “optional,” or “information not provided,” whichever is accurate.
    4. Translate specifications into consequences. Give the factual specification first, then explain why it could matter. If you cannot verify a practical consequence, do not manufacture one from a marketing adjective.
    5. Separate fact from recommendation. “Includes 256 GB” is a product fact. “Better for frequent offline video” is guidance that needs a visible rationale.
    6. Surface checks before the purchase. Put compatibility, required accessories, regional limitations, account requirements, and other decision-changing conditions beside the relevant claim instead of burying them in a general FAQ.
    7. Assign maintenance ownership. Every comparison needs an owner and a review trigger when a model, offer, specification, or policy changes.

    The opening of a comparison page should answer the decision before expanding on it. A practical template is: “Choose [product] when [need] because [verified differences]. Choose [alternative] when [different need]. Before buying, verify [important condition].” This gives a person a usable answer and gives an answer engine a compact passage it can interpret without reconstructing your position from scattered sections.

    Then support that answer with a complete comparison. Cover the questions that change the purchase:

    • Which capabilities are shared, and which are genuinely different?
    • What does the higher-priced option add?
    • What does each option leave out?
    • Which differences affect a defined use case?
    • Which accessories, subscriptions, or compatible devices are required?
    • What should the buyer verify before ordering?
    • When were the facts last checked?

    Do not turn this into keyword stuffing. AI systems interpret topics through connected concepts, so useful coverage means answering the related questions needed to understand the decision. Content about an eco-friendly product, for example, may need to explain its materials, relevant trade-offs, maintenance, and disposal. It does not need twenty variations of the phrase “sustainable product.” Clear topical relationships support both conventional and AI search performance.

    Keep each claim close to its proof. If you say a model works with a particular device family, identify the supported versions or link to the maintained compatibility information. If you say an option is better for a use case, show the differences that lead to that recommendation. A machine can repeat an unsupported conclusion as easily as a supported one; the structure of your page should make the distinction visible.

    Turn the catalog into a machine-readable product record

    A product floats above connected tiles representing its materials, dimensions, compatibility, availability, and shipping details.

    A webpage can make a price, specification, or model relationship obvious to a person without expressing its meaning explicitly to a machine. HTML is excellent for presentation, but visual proximity alone does not guarantee semantic clarity. Structured data exists to reduce that ambiguity, yet its implementation remains uneven.

    JSON-LD is not a replacement for a useful product page. Treat it as a translation layer between your governed catalog record and systems that need an explicit description of the entity. For a commerce implementation, inspect six groups of information:

    • Identity: the canonical product name, brand, internal SKU, and legitimate global identifier where one exists.
    • Variant relationships: the attributes that create distinct variants, such as size, color, capacity, model, or configuration, plus the relationship between each variant and its product family.
    • Commercial state: price, currency, availability, condition, seller, and the offer or variant to which each value applies.
    • Decision attributes: the measurable specifications, compatibility statements, included items, requirements, and exclusions that buyers use to compare options.
    • Policies and evidence: the maintained pages or records behind shipping, returns, warranties, ratings, and other claims you choose to expose.
    • Freshness controls: the system responsible for each field, its update trigger, and a way to detect disagreement between surfaces.

    Use the Schema.org Product vocabulary for an individual product representation and connect its Offer data where appropriate. The exact markup should follow the product and offer you actually display. Do not add a field because it looks advantageous in a validator. Do not mark up a family-level price as if it applied to every variant. Do not publish review or rating data in JSON-LD if a user cannot find the corresponding information on the page.

    Five implementation rules prevent most damaging inconsistencies:

    1. Match visible content. The machine-readable value and the customer-facing value should describe the same product, offer, and condition.
    2. Preserve identifiers. Do not reuse an SKU or global identifier across unrelated products. Stable identifiers help systems reconcile records from multiple surfaces.
    3. Include units and qualifiers. A number without its unit, measurement condition, region, or variant can create a confidently wrong comparison.
    4. Update dynamic fields from the catalog system. Manually copied price and availability values become stale. Generate them from the same maintained record used by the page whenever your stack permits it.
    5. Validate meaning as well as syntax. Passing a structured-data test proves that the markup parses. It does not prove that the claims are current, complete, assigned to the right variant, or useful for a purchasing decision.

    The proposed idea of an AI data interface, or AIDI, imagines a future in which personal agents retrieve structured information more directly instead of interpreting every business through a traditional page. The label and adoption path are uncertain. The durable requirement underneath it is not: reusable, well-defined product data will be easier to publish into pages, JSON-LD, feeds, and future interfaces than facts trapped in layout-specific copy.

    That is the sensible way to prepare for agents. Do not rebuild your commerce stack around a prediction that HTML will disappear. Move decision-critical facts into a governed catalog record, make each output consistent, and keep the human page strong. This improves the current experience while preserving options for whatever interface gains adoption.

    Measure discovery, influence, and revenue separately

    Three connected visual zones show signals being discovered, product options influencing a shopper, and a final path ending in a purchase.

    A dashboard that reports only organic clicks cannot tell you whether an AI assistant introduced the product and Google completed the journey. A dashboard that reports only AI referrals has the opposite problem: a shopper can read an answer, remember the brand, and return through branded search or direct navigation.

    Build measurement in three layers. The layers answer different questions and should not be collapsed into one visibility score.

    • Answer visibility: Is your brand or product named for the questions that matter? Is your site cited? Is the description accurate? Which competing products appear?
    • On-site behavior: Which AI referrals reach the site? What landing pages do they use? Do they view products, use comparisons, start checkout, or leave after encountering a mismatch?
    • Commercial outcome: Which journeys produce orders, revenue, qualified leads, or assisted conversions? How does that performance differ by landing page and intent?

    Keep a fixed prompt set for monitoring. Include category discovery, named product comparisons, use-case recommendations, compatibility questions, and pre-purchase checks. Record the exact prompt, platform, model or mode when visible, date, products mentioned, citations returned, and factual errors. A single answer is an observation, not a stable ranking. Repeating the same controlled set gives you a more useful view of change.

    In analytics, create a distinct channel group for identifiable AI referrals instead of silently mixing them with ordinary organic search. Preserve the landing URL and conversion path. Add a post-purchase or lead-form question about where the customer first researched the purchase; referral data alone cannot reveal every AI-influenced journey. Compare revenue and assisted outcomes, not just visits.

    Use the combination of metrics to diagnose the next change:

    • If your products are mentioned but described incorrectly, fix catalog consistency and claim clarity before creating more content.
    • If relevant pages rank in conventional search but rarely appear in AI answers, strengthen the direct answer, comparison structure, supporting context, and entity relationships.
    • If AI citations increase but qualified visits or conversions do not, inspect whether the cited passage promises something the landing page does not make easy to verify.
    • If visits convert but visibility remains narrow, expand the proven content and data pattern to adjacent product families.
    • If price or availability differs across surfaces, stop scaling and repair the update path. More visibility would only distribute the error further.

    You can put this into operation with a four-week pilot:

    1. Week 1: Establish the baseline. Select up to ten high-value product families with meaningful comparison friction. Inventory their visible facts, JSON-LD, feed values, AI answers, organic landing pages, and conversion paths. Record every contradiction.
    2. Week 2: Publish the decision layer. Create or revise one comparison experience per family. Lead with the choice, normalize attributes, state missing features, explain practical consequences, and add the checks that could change the purchase.
    3. Week 3: Align the data layer. Map identity, variants, offers, and decision attributes back to the maintained catalog. Correct structured data and feed discrepancies. Add validation to the publishing workflow.
    4. Week 4: Retest and connect outcomes. Run the same prompt set, review search visibility, verify cited claims, inspect landing behavior, and connect conversions to identifiable search and AI touchpoints. Use the defects you find to define the next product group.

    The pilot is successful when it creates a repeatable publishing and measurement loop, not merely when one prompt mentions your brand. The operational asset is a product record that stays accurate across channels and a content pattern that helps buyers make a decision.

    Key takeaways

    • Do not replace SEO with AI optimization. Buyers can use both channels during one purchase, and organic search still carries substantial ecommerce demand.
    • Organize product content around the differences buyers need to evaluate, not the order in which your catalog happens to store products.
    • Give direct recommendations a visible factual basis, including exclusions, compatibility conditions, and pre-purchase checks.
    • Keep page content, JSON-LD, feeds, and interfaces aligned to one governed catalog record.
    • Measure answer visibility, factual accuracy, on-site behavior, and commercial outcomes as separate layers.
    • Prepare for agents by improving reusable product data now, without betting your business on a specific interface or a predicted end of HTML.

    Start with one product family your customers routinely struggle to compare. Build its fact matrix, publish the decision clearly, map the same facts into structured data, and track the path through Google and AI answers. Once that loop stays accurate, scale it across the catalog. You will gain a better shopping experience now and a cleaner route into agent-driven commerce later.

    References