Tag: Ad Positioning

  • How to Control Paid Search Placement and Ad Presentation

    How to Control Paid Search Placement and Ad Presentation

    You may have approved the targeting, copy and landing pages, yet still feel that part of your paid search campaign is outside your control. Automation can decide where an ad appears, while the search interface can change how the same assets look to users.

    The practical answer is to manage placement safety and ad presentation as separate control systems. One governs the contexts your brand will accept. The other makes your assets resilient when a platform changes their visual treatment.

    Treat placement and presentation as separate control planes

    Placement control answers: “Which content should never sit beside this campaign?” Presentation control answers: “If the platform rearranges or emphasizes our assets, will the ad still communicate clearly?”

    Those questions require different actions:

    • Placement safety: define prohibited contexts, choose the right exclusion scope, document why each restriction exists and verify that the setting was applied where intended.
    • Presentation resilience: write assets that work independently, send each link to a matching destination and measure whether interface changes redistribute attention among those links.

    Do not use one as a substitute for the other. Strong sitelinks cannot protect a brand from unsuitable content adjacency. A detailed exclusion list cannot prevent a weak or ambiguous sitelink from attracting the wrong click.

    This distinction also makes troubleshooting faster. When impressions or eligible reach change after a placement update, inspect exclusions first. When mobile users start choosing different destinations from the same ad, inspect presentation and asset clarity before changing bids or audiences.

    Turn content exclusions into an enforceable brand policy
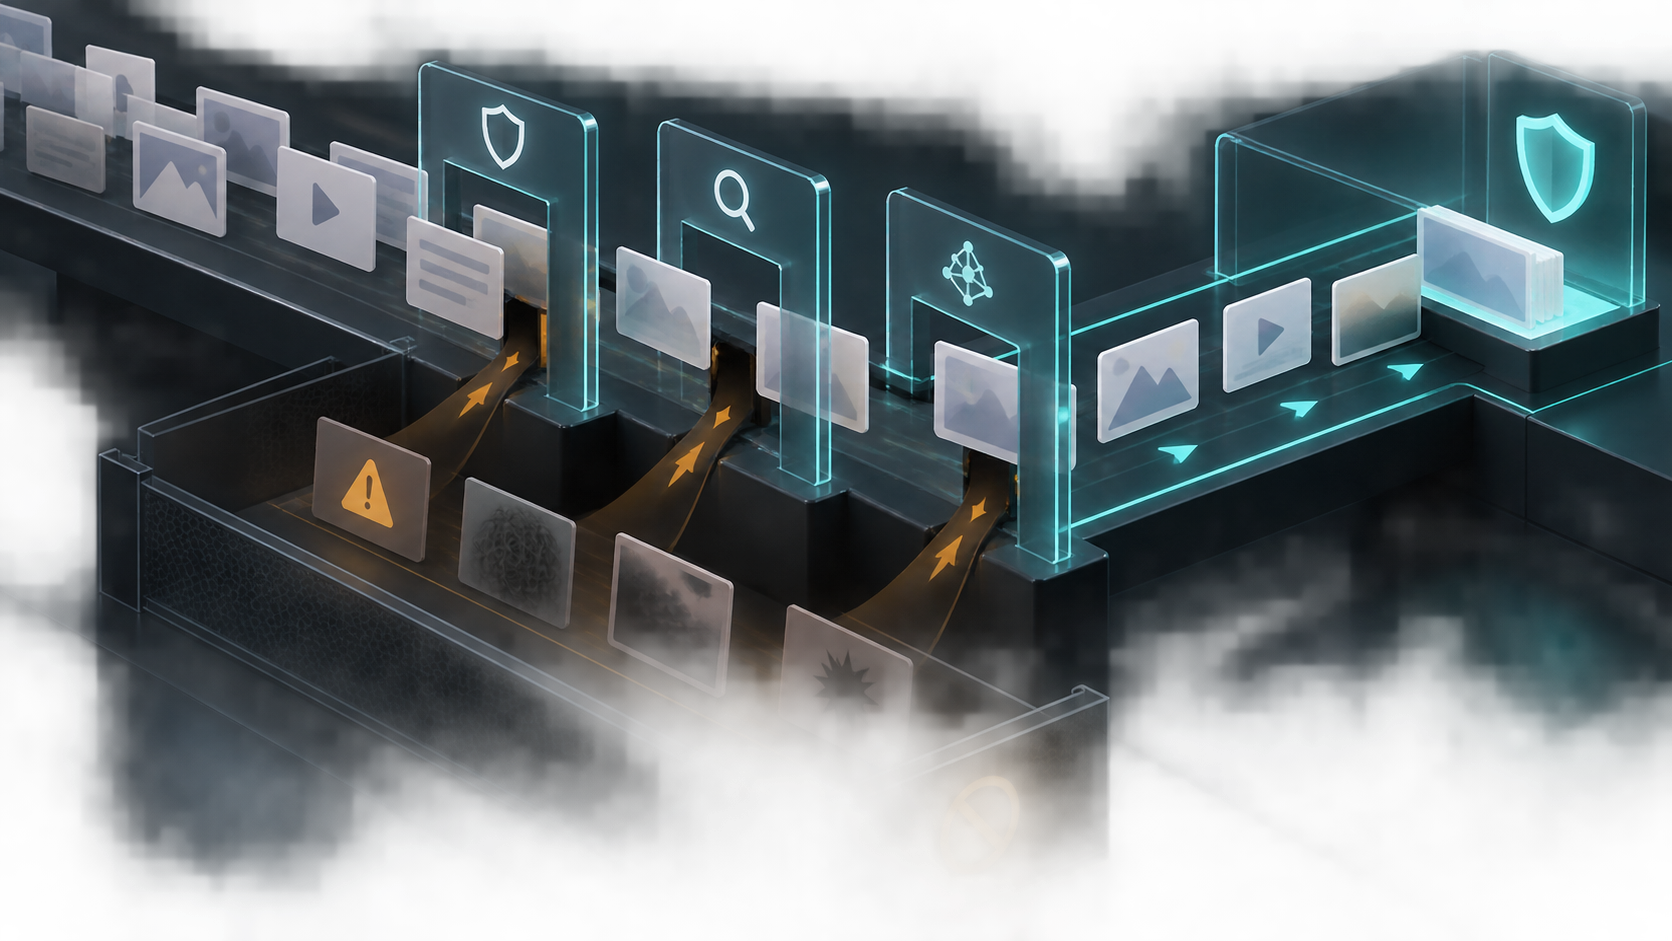
    A layered filtering system diverts risky content cards away from a protected advertising area while neutral cards pass through.

    Microsoft Advertising gives advertisers a direct way to define unsuitable content topics. Its Excluded Content Terms control accepts up to 1,000 terms based on page titles. The control can be applied across an account or scoped to an individual campaign.

    That scope decision matters more than the length of the list. An account-level exclusion is appropriate when association with a topic would be unacceptable for the brand under any campaign. A campaign-level exclusion is better when suitability depends on the product, audience or message being advertised.

    For example, a company-wide reputational restriction belongs at account level because a campaign manager should not be able to bypass it accidentally. A topic that conflicts with one product campaign but remains relevant to another belongs at campaign level. Applying every concern globally may restrict suitable opportunities; keeping every concern local can leave avoidable gaps.

    Build the exclusion list in six steps

    1. Start with policy, not keywords. Write down the topics that create a real reputational, contractual or internal-policy conflict. This prevents the list from becoming a collection of vague dislikes.
    2. Assign a scope to each topic. Mark every restriction as account-wide or campaign-specific before anyone enters it into the platform.
    3. Translate the topic into page-title language. The mechanism evaluates terms associated with page titles, so use wording that is likely to identify the unwanted subject clearly. Do not assume that a broad concept and the words appearing in a title are always the same thing.
    4. Review ambiguous terms. A word can appear in both unsuitable and harmless contexts. Check whether the term expresses the prohibited topic precisely enough before applying it across the account.
    5. Record an owner and rationale. Keep the term, scope, reason, approving stakeholder and implementation status in a shared change log. When delivery changes later, you will know whether the restriction was intentional.
    6. Verify the deployed setting. Confirm that account-level terms appear at account level and campaign-specific terms appear only in the intended campaigns. A correct policy in a worksheet provides no protection if it was entered in the wrong place.

    The 1,000-term allowance is capacity, not a target. More exclusions do not automatically create better protection. Prioritize terms with a clear connection to a documented concern, then review the list when brand policy, products or campaign scope changes.

    Also be precise about what this control can establish. Because the terms are based on page titles, they are a useful boundary for identifiable topics, not a complete interpretation of every page’s meaning. Keep the platform’s built-in safeguards in place and treat your custom list as an additional layer shaped by your own requirements.

    Build sitelinks that survive changes in visual treatment
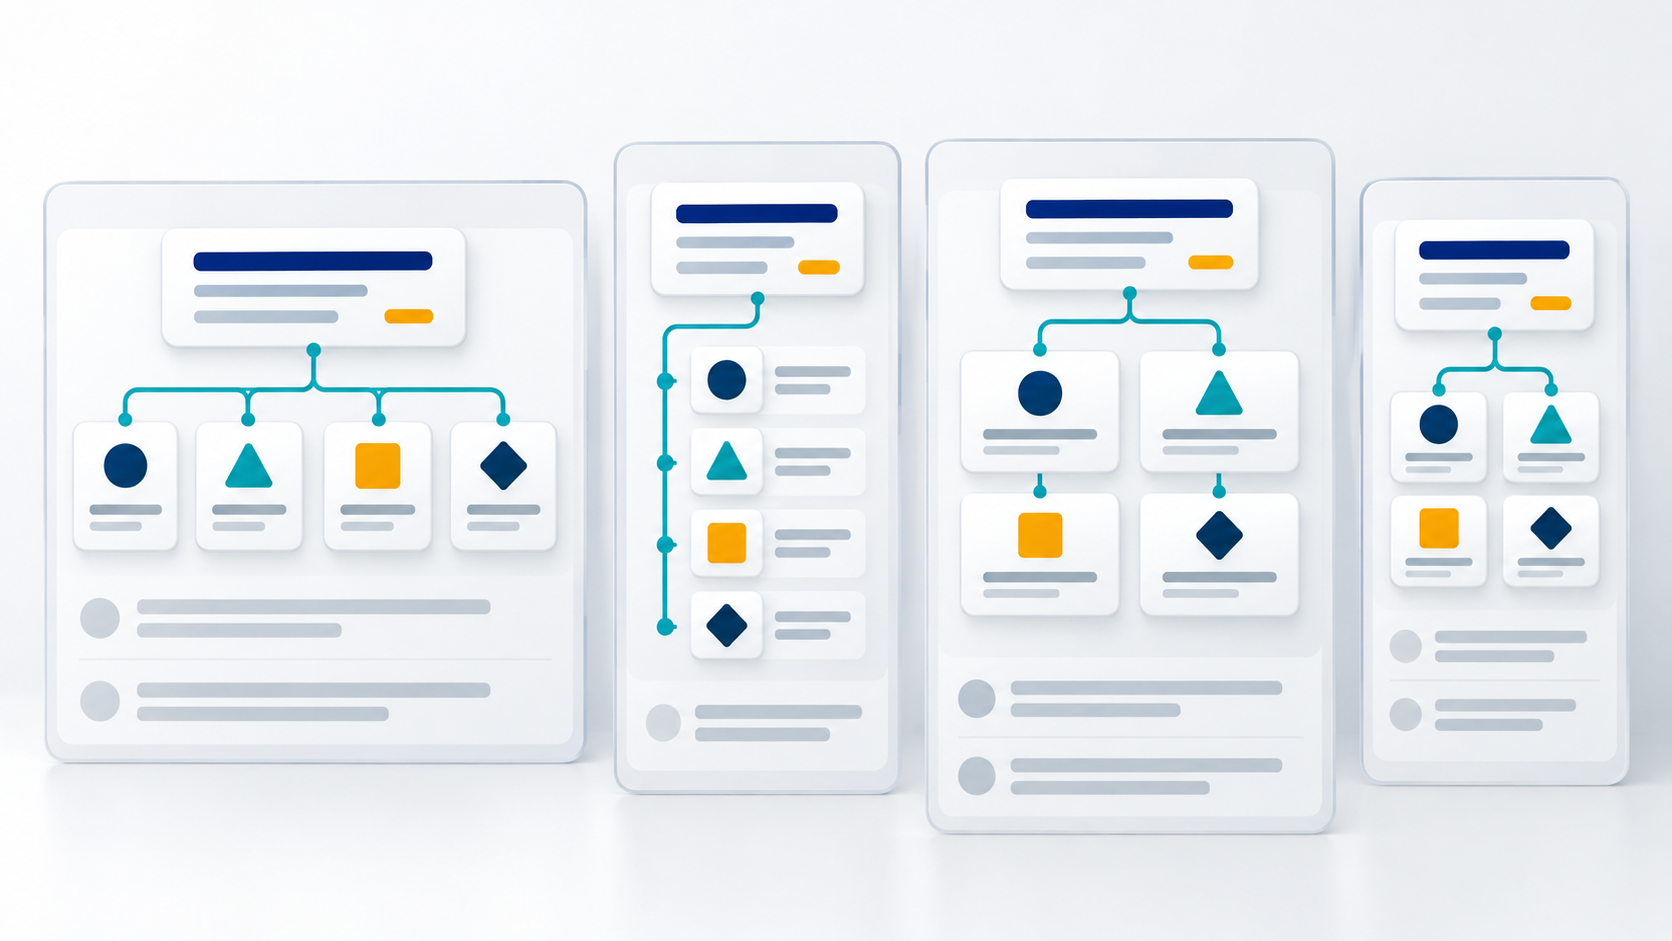
    Four modular destination tiles connect to a search ad component and reflow into horizontal, stacked, expanded, and compact layouts.

    You control the sitelink assets you submit, but not every detail of how Google displays them. Google has tested a mobile layout that places sitelinks on separate lines, adds a vertical treatment on the left and uses darker link text. That could make secondary routes more noticeable even though the advertiser has not edited the assets.

    A test is not a promise of broad rollout. It is still an operational warning: an asset that feels secondary in one layout may become visually prominent in another. Write every sitelink as though it could receive focused attention.

    Make every sitelink understandable on its own

    • Name the destination. “Pricing,” “Enterprise plans” or “Book a demo” tells the user what lies behind the click. Generic labels such as “Learn more” depend too heavily on surrounding copy.
    • Give each route a distinct job. If several sitelinks promise nearly the same thing, a more prominent layout creates apparent choice without meaningful choice.
    • Match the landing page to the label. A user who selects a specific secondary link should arrive at that destination, not a general page that requires another search.
    • Avoid sequence-dependent wording. Sitelinks may be scanned individually. Do not make the meaning of one link depend on the user reading the link before it.
    • Check the set for internal competition. Your most visually attractive sitelink should not divert high-intent users toward a lower-value or poorly matched route.

    Reviewing the text in an asset manager is not enough. Inspect the rendered mobile result whenever you can observe it, and compare the visual hierarchy with the campaign’s intended decision path. Ask which element attracts the eye first, which links now resemble primary choices and whether those destinations deserve the additional attention.

    This is also why approval should cover the complete asset set. A sitelink is not merely an optional accessory beneath the main ad. It is a possible entrance to your site whose prominence can change without a new copy review.

    Diagnose performance shifts before changing the campaign

    Placement changes and presentation changes can both alter performance, but they leave different clues. Use the following as first hypotheses, not proof of causation.

    Observed changeQuestion to investigate firstUseful next action
    Delivery changes after exclusions are addedWas a restriction applied at account level when it was intended for one campaign?Compare the deployed account and campaign lists with the approved scope log.
    Mobile users begin choosing different sitelink destinationsHas the visual hierarchy changed even though the assets have not?Inspect live mobile presentation and destination-level analytics before rewriting the ads.
    Click-through behavior changes but downstream results do not improveIs a newly prominent route attracting attention without matching intent?Compare the promise of each sitelink with its landing page and desired action.
    Performance moves across devices and asset routes at onceIs the cause broader than a mobile presentation variation?Review targeting, bids, budgets, demand and other campaign changes before attributing the shift to layout.

    Keep an annotation for each exclusion deployment, asset edit and observed interface change. Without that timeline, a platform presentation test can be mistaken for the effect of your copy revision, or an account-level exclusion can be mistaken for a demand problem.

    Do not call a platform-run interface experiment your A/B test unless you have reliable assignment and reporting for the variants. If you cannot identify which users saw which treatment, you can document the correlation and investigate it, but you cannot cleanly credit the layout for the outcome.

    A useful review separates three layers: eligibility and distribution, user interaction with the rendered ad, and behavior after the click. That sequence keeps you from “fixing” the landing page when an exclusion changed delivery, or loosening brand-safety rules because a sitelink destination underperformed.

    Key takeaways

    • Manage content adjacency and visual presentation as separate risks with separate owners, controls and diagnostics.
    • Use account-level exclusions for non-negotiable brand restrictions and campaign-level exclusions for context-specific concerns.
    • Microsoft’s Excluded Content Terms can use as many as 1,000 page-title terms, but relevance and scope matter more than filling the allowance.
    • Write each sitelink as a self-contained route because Google can change its prominence without requiring an asset edit.
    • When performance moves, check distribution, rendered interaction and post-click behavior in that order before changing the campaign.

    Your next step is concrete: audit one account’s exclusion scopes and one mobile campaign’s complete sitelink set. Correct the first mismatch you find, log the change and establish the baseline you will use to judge what happens next.

    References


  • Chrome Ad Metrics: How to Audit an Ad-Heavy Website

    Chrome Ad Metrics: How to Audit an Ad-Heavy Website

    If increasing ad revenue has made your pages feel crowded or slow, you no longer have to settle the argument with screenshots and opinions. Chrome can now expose four separate dimensions of ad load through real-user data: how many ads people see, how much space those ads occupy, how many bytes they consume, and how much processing time they require.

    The useful move is not to chase the lowest possible number. It is to find the page patterns where advertising consumes more attention or resources than the commercial return justifies, then reduce the specific cost without weakening the rest of the business.

    The four metrics reveal different kinds of ad load

    Chrome has added four experimental advertising metrics to the Chrome User Experience Report, commonly called CrUX. Treat them as four diagnostic signals, not as interchangeable measures of whether a page has too much advertising.

    MetricWhat Chrome measuresWhat it helps you notice
    Ad CountThe average number of ads visible in the viewportHow many detected ads compete for the user’s visible attention at the same time
    Ad DensityThe average percentage of the viewport occupied by adsHow much of the visible screen advertising takes over, regardless of the number of placements
    Ad Weight – NetworkThe bytes consumed by advertisingThe data cost of the detected ad experience
    Ad Weight – CPUThe processing time consumed by ads, measured in millisecondsThe execution cost imposed by ad-related resources and scripts

    The distinction matters because a single large placement can create high density without a high count. A collection of small placements can raise count while occupying less space. A visually restrained layout can still transfer substantial data or consume considerable processing time.

    Read the metrics in combination:

    • Count and density rise together: Start with the layout. Too many placements may be visible concurrently, and they collectively occupy more of the screen.
    • Density rises while count stays near your cleaner-page baseline: Investigate placement size and persistence before removing every slot. One dominant unit may be the main difference.
    • Network weight rises while count and density remain stable: The visible layout is not telling the whole story. Inspect the advertising payload and repeated resource requests.
    • CPU weight rises by itself: Concentrate on execution. Reducing visible ad space will not necessarily address script-related processing cost.
    • The four signals stay near your baseline but commercial results remain weak: Do not assume ad load is the cause. Creative relevance, audience fit, placement quality, or another factor may deserve attention first.

    This gives you a better decision model than a blanket instruction to run fewer ads. You can identify whether the problem is competition for space, data transfer, processing, or a combination of them.

    Understand what Chrome is actually observing

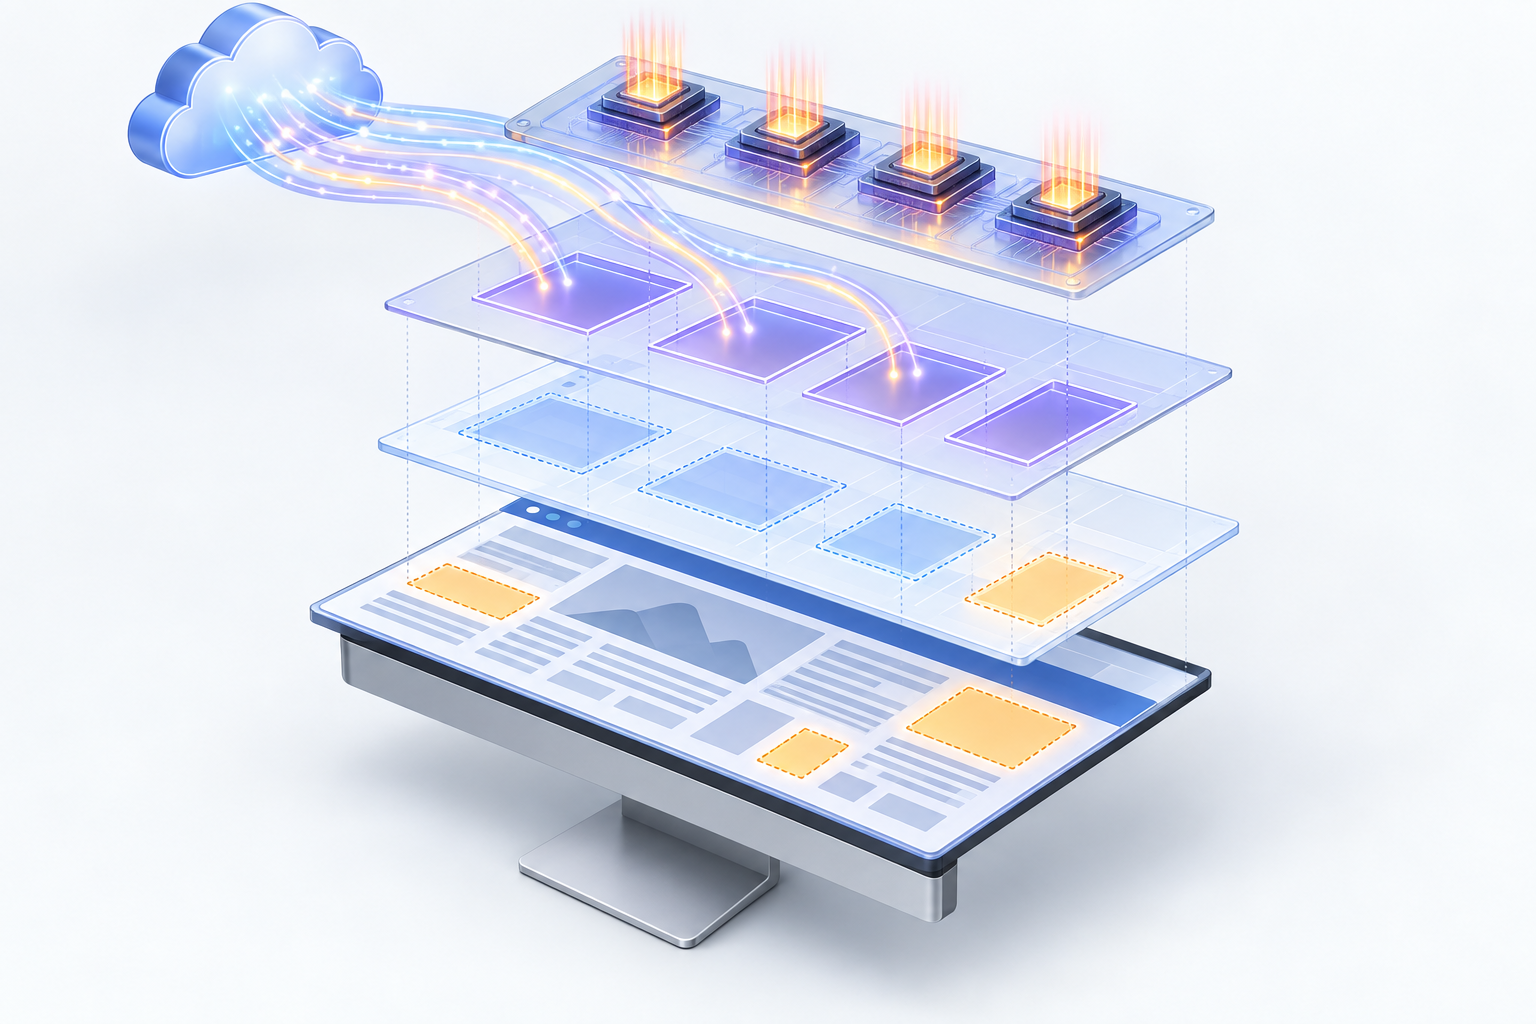
    Four floating webpage layers depict visible ad placements, their occupied area, incoming data, and processor activity above a computer monitor.

    Your ad server, content management system, and Chrome do not necessarily count the same thing. Your systems know which slots, campaigns, or line items you configured. Chrome detects advertising from the browser side.

    Chrome uses network-level filtering and script-execution analysis to identify ads. It can classify a URL as advertising when that URL matches its ad filter list. It can also recognize resources or frames created by scripts that have already been identified as ad-related.

    Ad Count should therefore be read as a count of ads Chrome detected in the visible viewport, not as a count of the placements declared in your page template. When an internal slot report and the Chrome metric differ, first check whether the two systems are measuring the same object. Do not label either figure incorrect merely because it does not match the other.

    Timing changes the interpretation too. Chrome samples the visible viewport once per second for Ad Count and Ad Density. Network and CPU usage accumulate through the user’s session. CrUX then reports the results at the 75th percentile.

    • A screenshot is not a session. A page may begin with a restrained layout and become denser as advertising appears or remains visible during use. Inspect the experience over time.
    • An initial transfer is not total network weight. Resources loaded later in a session still contribute to the accumulated advertising cost.
    • A quick lab run is not field data. CrUX reflects real Chrome usage, so device capability, network conditions, page behavior, and actual user journeys can produce a different result from a controlled check.
    • The 75th percentile is not the arithmetic mean. It marks a value at or below which three-quarters of measured experiences fall. The remaining quarter is heavier, so do not describe the number as the experience of an average user.

    That measurement model should shape your quality assurance. Reproduce an ordinary journey rather than loading the page, taking one screenshot, and declaring the layout acceptable. Let advertising appear, scroll through the content, and continue long enough to expose resources that arrive after the first view.

    Build an audit around contrasts, not invented thresholds

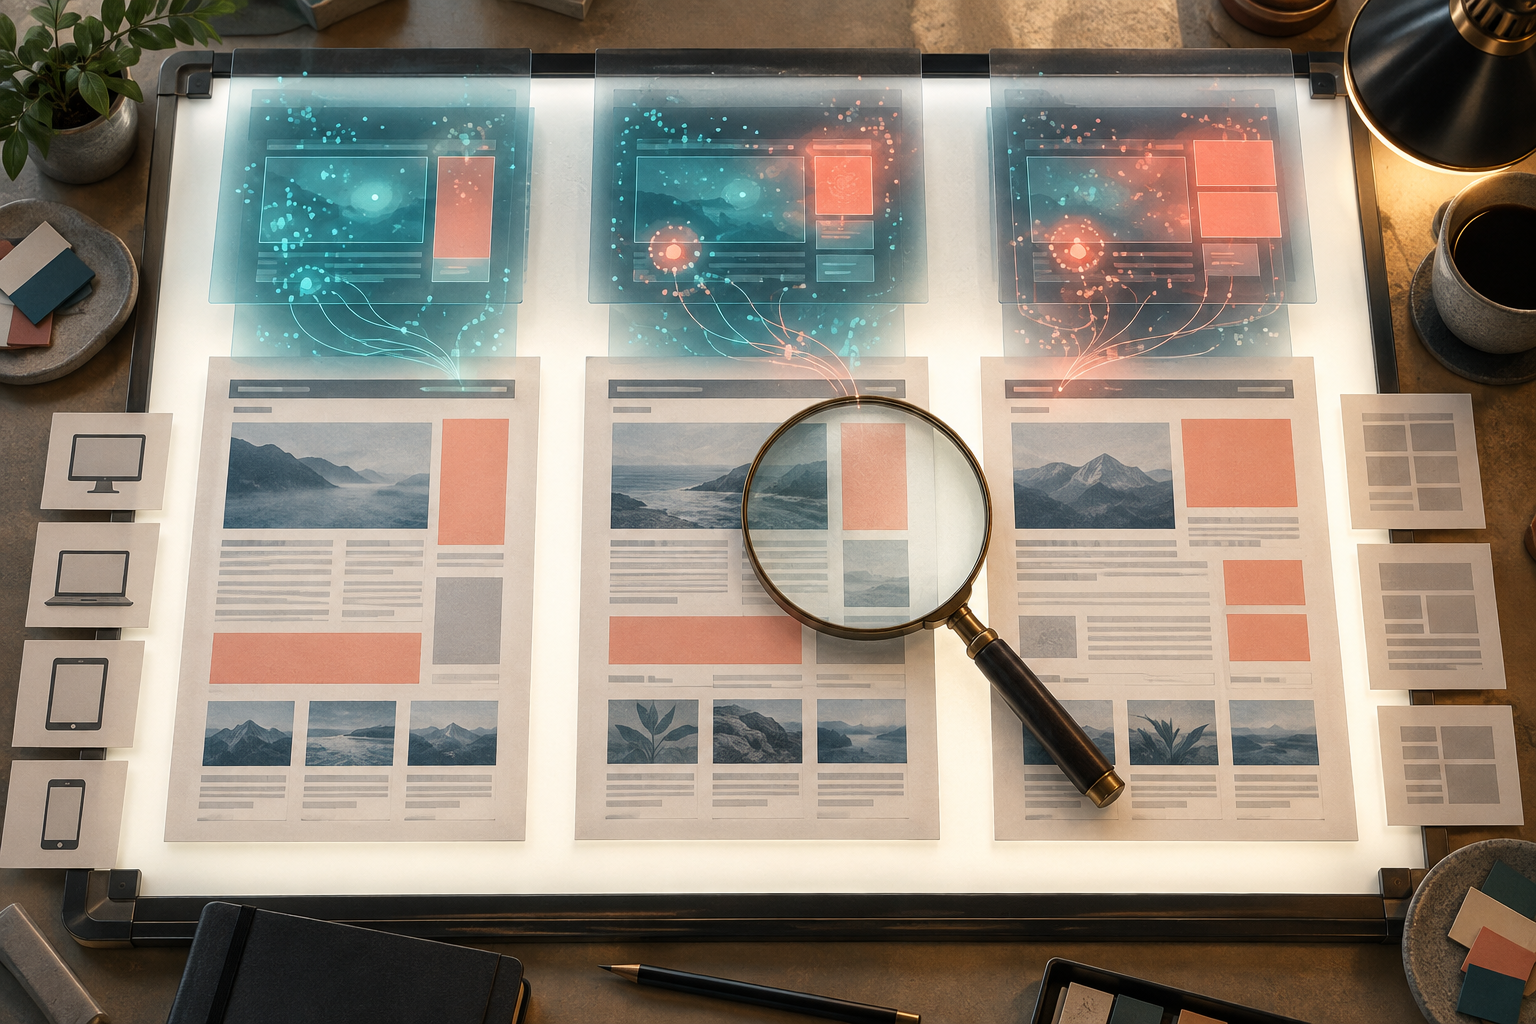
    Three similar webpage layouts with different ad patterns are compared on a light table using a magnifying lens and abstract resource signals.

    Chrome has not established a recommended pass or fail threshold for any of the four metrics. They are experimental, and they are not Core Web Vitals. A universal scorecard that labels a page good or bad would therefore create precision that the current program does not provide.

    You can still run a disciplined audit. Use your own comparable page patterns to establish context:

    1. Define comparable groups. Separate page patterns that have materially different jobs or layouts. An article template, a gallery, and a short reference page should not automatically share one baseline.
    2. Record all four ad metrics together. Do not report density without network and CPU weight, or combine the four into an unsupported composite score. Keeping the raw dimensions visible prevents one improvement from hiding a regression elsewhere.
    3. Keep Core Web Vitals in a separate column. The advertising metrics can sit beside established performance reporting, but they should not be relabeled as Core Web Vitals or folded into a made-up Google score.
    4. Find useful contrasts. Compare cleaner and more heavily monetized experiences within a relevant group. Look for the metric that changes most clearly rather than assuming every ad-heavy page has the same defect.
    5. Reproduce the suspected behavior. Review the page across a realistic session, paying attention to what is visible and what continues loading or executing. The goal is to connect a field signal to an observable mechanism.
    6. Change one cost dimension first. Reduce concurrent visible placements for count, occupied screen area for density, advertising payload for network weight, or unnecessary execution for CPU weight. A focused change makes the result easier to interpret.
    7. Judge the tradeoff with business outcomes. Put the ad metrics beside the revenue and campaign measures your team already trusts. Keep changes that improve the experience at an acceptable commercial cost; investigate further when a lower ad metric merely moves the problem elsewhere.
    8. Create internal guardrails only after you have a baseline. Express them as limits for comparable page patterns and document why they exist. Do not present them as official Chrome thresholds.

    A practical internal rule might require a redesigned template not to materially worsen density or CPU weight against the template it replaces while maintaining an acceptable monetization result. Your team still has to define what materially and acceptable mean, but the rule identifies the comparison, the protected outcomes, and the owner of the decision.

    When possible, test changes in isolation. Removing a placement while simultaneously changing the ad vendor, page layout, and loading behavior may improve the numbers, but it will not tell you which intervention mattered. That leaves you unable to repeat the result elsewhere.

    Avoid five costly interpretation errors

    The new metrics are useful precisely because they separate layout pressure from resource pressure. That value disappears when a team compresses them into a simplistic verdict.

    • Do not optimize only for fewer ads. A lower count can coexist with high density, network weight, or CPU weight. Verify which cost actually fell.
    • Do not treat density as a performance metric. Density describes visible space. Network and CPU weight describe resource consumption. One cannot stand in for the others.
    • Do not claim an SEO ranking effect. Nothing in the current rollout establishes these experimental measurements as ranking signals. Track them beside SEO and performance data when useful, but keep the labels honest.
    • Do not promise a media-value or bidding uplift. Better transparency could affect how buyers assess inventory, but Google has not said whether Display & Video 360 is testing these signals for bidding, valuation, or reporting.
    • Do not wait for an official cutoff before measuring. The absence of a universal threshold prevents a pass or fail verdict; it does not prevent you from detecting regressions, comparing relevant experiences, or correcting an obvious outlier.

    Publishers with cleaner experiences may eventually use the metrics to distinguish their inventory. Advertisers and agencies may use them to identify placements where clutter or resource consumption threatens attention and campaign performance. Independent advertising platforms are expected to receive the CrUX data at the same time as Google’s advertising businesses, which makes it sensible to preserve the raw metrics now rather than build a process around a proprietary composite score.

    For buyers, the right first use is comparison and investigation, not automatic exclusion. A high reading identifies a question to ask about the experience. Without an established threshold or evidence connecting that reading to your own campaign outcome, it is not yet a sufficient reason to reject inventory by itself.

    Key takeaways

    • Ad Count measures how many detected ads are visible; Ad Density measures how much of the viewport they occupy.
    • Ad Weight – Network measures advertising bytes, while Ad Weight – CPU measures advertising processing time in milliseconds.
    • Chrome samples the viewport once per second, accumulates network and CPU use through the session, and reports CrUX results at the 75th percentile.
    • The four measurements are experimental, are not Core Web Vitals, and do not have official recommended thresholds.
    • Use the metrics as separate diagnostic signals, compare relevant page patterns, and evaluate every change against both user-experience and commercial outcomes.

    Choose one commercially important page pattern this week and capture all four dimensions before changing it. That baseline will give your ad, performance, analytics, and editorial teams something concrete to improve – and it will keep future decisions grounded if buyers begin using the same signals to value inventory.

    References


  • Google’s Mobile Search Ad Test: A Practical Response Plan

    Google’s Mobile Search Ad Test: A Practical Response Plan

    If you manage paid search, Google’s mobile ad presentation test creates an awkward question: should you change campaigns now, or wait until the format becomes more than an isolated experiment? The right answer is to prepare the brand elements the layout exposes, preserve your measurement baseline, and avoid auction-level changes that the available evidence cannot justify.

    The test changes what a mobile searcher may notice first. That could matter for recognition and trust, but it does not yet establish a new campaign rule. Your immediate job is to separate the visible interface change from the performance effects you can actually demonstrate.

    The test adds an identity layer before the ad copy

    In the observed mobile layout, Google places a list of advertisers, including their favicons and domain names, at the top of a sponsored-results block. The individual ads appear below that list. A searcher therefore encounters the participating companies before reaching the first complete ad.

    That is more than a cosmetic rearrangement. The standard ad-reading sequence starts with a specific advertiser’s message. This test inserts a preliminary identity check: which companies are present, which ones look familiar, and which domains appear credible enough to consider.

    Three practical implications follow, although none has been proven as a performance outcome:

    • Recognition may arrive before relevance. A familiar favicon or domain could attract attention before the searcher compares headlines and descriptions.
    • Unfamiliar advertisers may face a sharper trust test. If your domain does not clearly map to your brand, the user may have little reason to remember you when the full ad appears.
    • Ad copy remains important, but it may no longer make the first impression. The advertiser list can frame the choice set before any individual value proposition is read.

    Do not turn those possibilities into conclusions. The test does not show that recognized brands will necessarily gain clicks, that unfamiliar brands will lose them, or that inclusion in the list conveys an endorsement. It only gives you a credible set of hypotheses to examine.

    Treat this as a presentation test, not a new campaign rule

    Google has not publicly explained the experiment, and it remains unclear whether the layout will move beyond limited testing. That uncertainty should govern your response. A screenshot is evidence that a format exists; it is not evidence that your account is consistently exposed to it or that the format changed your results.

    Use this response sequence if someone on your team encounters the layout:

    1. Capture the entire mobile results block. A cropped advertiser row is not enough to understand its position relative to the Sponsored results label, individual ads, and nearby organic results.
    2. Record the observation context. Save the query, date and time, market, device type, browser, and whether the search was performed while signed in. These details will not reveal Google’s test assignment, but they make repeated observations comparable.
    3. Check whether the layout appears again under controlled conditions. Look for a pattern across relevant queries and devices. Do not treat one person’s result as universal.
    4. Annotate the observation in your reporting. Keep it separate from campaign launches, budget changes, promotional periods, landing-page releases, and other events that could affect performance.
    5. Delay structural campaign changes. Bids, budgets, match types, targeting, and creative rotation all introduce new variables. Changing them in response to an unconfirmed interface test makes later diagnosis harder.

    The distinction is simple: prepare for the format where preparation is low-risk, but require performance evidence before altering how you buy traffic.

    Audit the two brand assets users may see first

    A specialist compares a circular identity mark and a rectangular brand image in small mobile interface previews.

    The observed advertiser list emphasizes two compact identity cues: the favicon and the domain. You can review both without rebuilding a campaign or assuming the experiment will become permanent.

    • Inspect the favicon at a genuinely small size. A detailed logo can become an indistinct shape when reduced. Look for strong contrast, a recognizable silhouette, and freedom from tiny text that disappears on a phone.
    • Check the domain as a brand signal. Read the domain without the surrounding ad. It should be easy to associate with the company a user expects to find. Document confusing abbreviations, legacy names, unexpected subdomains, or other mismatches before deciding whether any change is warranted.
    • Compare identity across the journey. The favicon, domain, ad language, and landing-page branding should feel like parts of the same company. A mismatch can be especially costly when a compact advertiser list prompts users to evaluate identity before the offer.
    • Review ad differentiation after the identity check. Once the user reaches the full ads, your message still needs to explain why your option fits the query. Brand recognition cannot substitute for a relevant proposition.
    • Make landing-page verification immediate. An unfamiliar advertiser should not force visitors to hunt for the company name, product relationship, or reason to trust that they reached the intended destination.

    Keep this audit within its proper scope. Nothing disclosed about the experiment establishes that JSON-LD, organic structured data, or an SEO schema change controls the advertiser list. Do not modify markup merely because the interface displays a favicon and domain. That would connect two systems without supporting evidence.

    Measure the effect without confusing visibility with causality

    Two identical smartphones display generic ad layouts with and without an identity layer, separated for controlled comparison.

    The central measurement problem is exposure. Unless Google identifies test participation in reporting, you may know that the layout was observed without knowing which impressions used it. Any account-level analysis is therefore directional, not a clean experiment.

    Build the analysis around the part of the journey the layout can plausibly influence:

    1. Preserve a baseline. Retain mobile performance from a comparable period before the first confirmed observation. Use a window long enough to reflect your normal buying cycle rather than selecting dates because they produce a convenient result.
    2. Separate mobile from desktop. The observed format is a mobile Search test. A blended device report can hide a mobile movement or incorrectly attribute an account-wide change to the layout.
    3. Split branded and non-branded intent. Brand recognition is one of the clearest hypotheses created by the advertiser-first presentation. If branded and non-branded queries move differently, that difference deserves investigation.
    4. Start with click-through rate, then follow the click. Presentation acts before the visit, so CTR is the nearest directional signal. Conversion rate, cost per acquisition, return on ad spend, and lead quality tell you whether any additional clicks were commercially useful.
    5. Use stable comparisons where possible. Compare query groups, markets, or campaigns with similar conditions rather than placing all traffic in one before-and-after total. A comparison is useful only if it was not changed by a different promotion, bid strategy adjustment, budget constraint, or creative release.
    6. Keep a confounder log. Record every material account and site change during the observation period. Without that log, a mobile CTR shift can easily be credited to the interface when a new ad, offer, competitor, or landing page changed at the same time.

    Interpret patterns conservatively. A mobile CTR increase while desktop remains stable would be consistent with a mobile presentation effect, but it would not prove one. A larger branded than non-branded shift would fit the recognition hypothesis, but other brand activity could produce the same pattern. If clicks rise while conversion quality weakens, the format may be attracting attention without improving intent. If nothing meaningful changes, the correct action may be no action at all.

    Only consider campaign changes after you can state the decision rule in advance. For example: if a repeatable mobile-only movement persists while comparable traffic remains stable, review creative or budget allocation in the affected segment. Defining the rule first prevents ordinary volatility from becoming a story after the fact.

    Key takeaways for paid search teams

    • Google’s test places advertiser favicons and domains before the individual mobile Search ads, potentially changing the first cue a user evaluates.
    • The format remains a limited experiment with no confirmed broad rollout, so one sighting should not trigger changes to bids, budgets, targeting, or campaign structure.
    • Audit favicon legibility, domain recognition, ad-to-landing-page consistency, and message differentiation now because those checks are useful even if the test ends.
    • Measure mobile separately, preserve branded and non-branded segments, and treat CTR as an early signal rather than the final business result.
    • Do not assume structured data or schema markup controls the paid advertiser list; no such connection has been established.
    • Without impression-level test identification, performance analysis can support a hypothesis but cannot cleanly prove causation.

    Your next move should be small and reversible: document any sightings, complete the favicon-and-domain audit, and protect a clean performance baseline. If the presentation expands, you will be ready to measure it. If it disappears, you will not have disrupted a working account in pursuit of a temporary interface.

    References


  • Uncovering the Hidden Flaw in a ‘Perfect’ PPC Campaign

    Uncovering the Hidden Flaw in a ‘Perfect’ PPC Campaign

    I recently sat down with Veronika Höller for an enlightening discussion on PPC campaigns in an episode of PPC Live The Podcast. We delved into a scenario where a seemingly flawless campaign was secretly underperforming, uncovering the real issue beneath the surface.

    From “perfect” campaigns to zero revenue

    Initially, Veronika encountered an impeccably organized account. It had all the right elements: a clean structure, compelling creatives, and well-allocated budgets with conversions rolling in. But there was one glaring omission—it wasn’t generating any revenue.

    This discrepancy prompted us to investigate further, revealing that while surface metrics such as impressions, clicks, and conversions appeared promising, the true business impact was lacking. The unraveling began here.

    The real issue: nothing stood out

    The breakthrough came not from within the account but by stepping outside it. During competitor research, Veronika noticed that the brand’s messaging was indistinguishable from its competitors. There was no compelling reason for users to choose their products over others.

    From a user’s perspective, the ads weren’t incorrect; they were simply forgettable. In a saturated market, being simply “good” wasn’t enough. The revelation was not about performance but positioning.

    Starting again — from scratch

    Veronika boldly decided to reconstruct everything from the ground up. This involved crafting new messaging, developing fresh creatives, and establishing a comprehensive strategic blueprint. A pivotal change was identifying not only the ideal customer but also defining who they were not targeting, utilizing anti-ICPs to refine the messaging.

    This reset also incorporated enhanced localization, creating tailored landing pages for different markets, and formulating platform-specific strategies instead of simply recycling campaigns across channels. It was much more than optimization—it was a complete overhaul, and it succeeded.

    The mistake that nearly broke everything

    Looking back at earlier times in her career, Veronika recalled a major misstep that will resonate with many PPC professionals. She had implemented a recommended target CPA but failed to adjust the budget accordingly.

    This oversight led to a halt in campaign delivery and a significant drop in performance, all of which went unnoticed over the weekend. By Monday, the damage was done, and the client was understandably upset.

    Owning the mistake — and fixing it fast

    Veronika didn’t shy away from the situation. She promptly admitted her mistake, provided an explanation, and took full responsibility. This transparency shifted the client’s initial frustration into collaboration, as there was no defensiveness, only a structured plan for resolution.

    The takeaway was invaluable: one must never apply recommendations blindly and should always consider the entire context before implementing changes.

    Why failure is part of getting good

    For Veronika, mistakes aren’t something to avoid—they’re a stepping stone to mastery. “You can only be good if you fail,” she asserted.

    This philosophy now influences her work approach and mentorship style. Mistakes signal progress, experimentation, and improvement.

    Furthermore, sharing these experiences helps others steer clear of similar pitfalls.

    The biggest issue she still sees today

    Despite evolving PPC landscapes, tracking remains a persistent issue. Many setups suffer from flawed implementations, reliance on micro conversions, and misconfigurations in tools like Google Tag Manager.

    In a world dominated by smart bidding and automation, inaccurate data not only constrains performance but leads it astray. Even the most stellar campaigns can falter without precise tracking.

    AI won’t fix average marketing

    Veronika emphasized that AI isn’t a magic bullet for improving outcomes. Feeding it mediocre data yields mediocre results.

    Many marketers erroneously rely on AI tools for account analysis without a proper understanding of the necessary enhancements. AI can’t create uniqueness; it can only optimize existing inputs. Distinctive strategies still demand human ingenuity.

    The mindset that matters now

    The most significant takeaway isn’t about tactics; it’s about mentality.

    Perfection isn’t the goal. Avoid following recommendations blindly, and don’t assume tools will think for you. Instead, rely on your instincts, experiment, and accept that mistakes are a valuable part of the journey.

    In performance marketing, the real hazard isn’t failure but becoming invisible by playing it safe.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • ChatGPT Advertising: A Practical Readiness Plan for Brands

    ChatGPT Advertising: A Practical Readiness Plan for Brands

    If ChatGPT advertising has reached your planning meeting, the immediate question isn’t whether to move budget. It is whether you can run a test that teaches you something without weakening trust. ChatGPT ads have entered the marketing landscape, but an emerging ad surface should be treated as an experiment, not a finished channel.

    You don’t need a confident prediction about every format, targeting option, or pricing model. You need a campaign brief that survives uncertainty: a defined user decision, a verifiable claim, a useful destination, independent measurement, and rules for stopping or scaling. Build those pieces now and you can evaluate actual inventory on its merits when it is available to you.

    Do not treat ChatGPT advertising as another search campaign

    A conventional search campaign often starts with a query, a keyword set, and a landing page. A conversational environment starts with a person trying to resolve something. They may be defining a problem, comparing options, checking a claim, or looking for the next step. Your planning should begin with that decision state, even if the advertising product does not offer conversation-level targeting.

    That distinction matters. Copying an existing search ad into ChatGPT may preserve the slogan while losing the reason the person would care. The better question is not, “What can we promote here?” It is, “What unresolved decision can we help the right person make?”

    Give each campaign one primary job:

    • Introduce an option the person may not know exists.
    • Clarify a point that commonly blocks evaluation.
    • Support a comparison with evidence the person can inspect.
    • Offer a practical next step after the person understands the issue.

    An ad that tries to do all of these at once will be difficult to understand and even harder to evaluate. Use a decision brief before anyone writes copy:

    • User state: What is the person deciding, and what do they probably understand already?
    • Question: What would they need answered before taking another step?
    • Claim: What useful, narrow statement can your brand make?
    • Proof: Where can the person verify that statement?
    • Disqualifier: Who should not click, sign up, or buy?
    • Next step: What is the smallest useful action after the ad?
    • Success event: What behavior would show meaningful progress rather than curiosity?

    A compact objective can follow this pattern: when a person is in a defined decision state, present a verifiable claim, send them to the page that resolves the next question, and judge the test by a qualified action. If you cannot fill in every part, the campaign is not ready for budget.

    Keep paid placement separate from AI answer visibility

    An abstract conversational interface shows a promotional tile separated by a glass gap from a background layer of connected answer bubbles.

    Paid placement, an AI-generated response, and your destination page can appear within the same journey, but they do different jobs. Treating them as one system leads to two costly assumptions: that buying an ad will change what the AI says, or that an organic brand mention means the advertising worked.

    SurfacePrimary jobWhat you can prepareCommon mistake
    Paid placementEarn attention and invite a relevant next stepA narrow claim, suitable creative, budget limits, and explicit targeting assumptionsPresenting the ad as if the assistant independently recommended the brand
    AI-generated responseHelp the person understand or resolve the questionClear content, consistent entity facts, current evidence, and valid structured dataAssuming media spend controls or improves the generated answer
    Destination pageProve the claim and move the decision forwardA direct answer, supporting evidence, relevant limitations, a clear action, and measurementRepeating the ad without resolving the person’s next question

    This separation is especially important for SEO, AEO, and GEO teams. Advertising can purchase an opportunity to be seen where inventory is offered. Organic AI visibility depends on whether systems can find, interpret, and use information about your brand. Neither outcome guarantees the other.

    Run a message-parity audit before launch. Compare the proposed ad with the landing page, product documentation, policies, sales materials, and structured data. The same factual claim should have the same scope everywhere. If the ad says a capability is available, the destination should state what it does, who can use it, what conditions apply, and when the information was last reviewed.

    Create a claim register with these fields:

    • The exact claim in plain language.
    • The page or record that substantiates it.
    • The owner responsible for keeping it current.
    • The markets, products, plans, or users to which it applies.
    • The event that should trigger another review, such as a pricing, policy, or feature change.

    Use JSON-LD to describe facts that are also supported by the visible page. Choose schema types and properties that match the page’s real subject. Do not create markup that broadens a claim, hides an important limitation, or describes an offer the visitor cannot verify. Structured data can improve clarity and consistency; it does not turn an unsupported statement into truth or guarantee inclusion in an AI response.

    Build a launch-ready test before you buy media

    Emerging advertising products can change while teams are still planning around them. Keep the stable parts of your strategy separate from platform-dependent details. Your audience problem, evidence, landing experience, economics, and business outcome belong in the stable layer. Inventory, placement, targeting controls, reporting fields, and billing belong in the platform layer and must be verified at activation.

    1. Write a falsifiable test thesis. Use the form: if a defined user state receives a defined claim and next step, a named qualified outcome should improve relative to a documented baseline. Avoid objectives such as creating buzz or seeing what happens.
    2. Record what is known and unknown about the ad product. Verify available placements, sponsorship labels, audience or contextual controls, geographic and language coverage, exclusions, billing, reporting, data use, and content restrictions in the actual buying materials. Do not turn a screenshot, announcement, or assumption into a media plan.
    3. Build the destination around the next question. Its opening should confirm that the visitor is in the right place. Put evidence close to the claim, state relevant constraints, and offer an action proportionate to the person’s readiness. A comparison visitor may need specifications or documentation before a sales form.
    4. Create variants that test one meaningful difference at a time. You might test the framing of the problem, the supporting proof, or the proposed next step. If the claim, audience, destination, and call to action all change together, the result will not tell you what caused the difference.
    5. Instrument the full journey. Use a dedicated landing URL or consistent campaign parameters where supported. Confirm that analytics records the intended onsite action and that your CRM or commerce system retains the acquisition source. Test the path yourself from landing visit to recorded outcome before approving spend.
    6. Set decision rules in advance. Name the metric that permits scaling, the spend ceiling, the conditions that require a pause, and the person authorized to make each decision. This prevents a novelty-driven campaign from continuing merely because it produced traffic.
    7. Run an adversarial review. Ask someone outside the campaign team to read the ad and destination as a skeptical prospect. They should be able to identify who the offer is for, what is being claimed, where the evidence sits, what happens next, and what important limitation applies.

    Keep this material in a reusable launch packet. If the available ChatGPT inventory does not fit your decision state, measurement needs, risk limits, or economics, you can decline the test without discarding the strategic work. The same brief can guide organic content, another paid channel, or a later campaign when the product is a better fit.

    Set trust guardrails and measurement rules together

    An unbranded product moves through checkpoints represented by a magnifying lens, a balanced scale, and an independent sensor before reaching an abstract conversational screen.

    Protect the boundary between assistance and promotion

    A conversational interface can feel advisory. When a paid message appears close to a generated response, a person may infer a relationship between them even when the placement is separate. Your creative should not intensify that ambiguity.

    • Do not imitate the assistant’s voice in a way that hides the commercial role of the message.
    • Do not imply that ChatGPT independently selected, verified, ranked, or endorsed the product unless that precise claim is demonstrably true and permitted.
    • Make the sponsor identity and destination clear within the controls available to the advertiser.
    • Use claim language that remains accurate outside an ideal context. Avoid an unqualified best, guaranteed, safe, or suitable claim when the destination cannot substantiate it.
    • Do not assume that private conversational details are available for targeting. Treat every claim about contextual signals, audience creation, retention, and advertiser access as unverified until the platform documents it.
    • Route campaigns involving regulated or sensitive decisions through qualified legal, privacy, and compliance review before targeting or creative goes live.

    Add an adjacency plan as well. Decide what your team will do if the ad appears near an unsuitable response, if a user interprets the placement as an endorsement, or if a product change makes the claim stale. The plan should identify who can pause the campaign, who captures evidence, who contacts the platform, and who corrects the destination or structured data. Waiting for an incident to establish ownership turns a manageable problem into a prolonged one.

    Measure qualified decisions, not the novelty of the click

    Early curiosity can produce visits without producing durable demand. A click therefore tells you that the placement earned attention, not that it reached the right person or changed a business outcome. Build a measurement ladder that distinguishes those stages:

    • Delivery: Did the platform serve the campaign as configured?
    • Qualified visit: Did the visitor reach the intended page and meet your predefined relevance conditions?
    • Decision behavior: Did the visitor inspect documentation, compare an option, check compatibility, begin a suitable workflow, or complete another meaningful step?
    • Business outcome: Did the journey produce a qualified lead, purchase, activation, or other result that the organization already recognizes?
    • Outcome quality: Did those results remain useful after the initial conversion, or did they produce avoidable cancellations, disqualification, support burden, or low-value activity?

    Use platform reporting to understand delivery, your first-party analytics to understand onsite behavior, and your CRM or commerce records to understand downstream outcomes. If those systems disagree, investigate the definition and handoff before changing the campaign. A dashboard that blends incompatible events can look precise while answering the wrong question.

    Where a credible comparison is possible, evaluate exposed and unexposed groups or use another controlled design. If the platform does not support that design, run a bounded pilot, compare it with a relevant baseline, document competing explanations, and label the conclusion as directional. Do not present last-click attribution as proof that the ad caused the result.

    Scale only when business outcome and outcome quality move in the same direction. If clicks rise while qualified actions stay flat, the answer is not automatically more spend. Revisit the user state, message, placement, and destination. If conversions rise but quality declines, tighten qualification before expanding reach.

    Key takeaways

    • Treat ChatGPT advertising as a bounded experiment until its available formats, controls, economics, and reporting fit your use case.
    • Plan around the person’s unresolved decision, not around a recycled search ad or a broad desire for awareness.
    • Keep paid placement, organic AI visibility, and landing-page conversion separate in your strategy and measurement.
    • Maintain message parity across ad copy, visible content, product documentation, policies, and JSON-LD.
    • Verify platform capabilities in the real buying materials instead of assuming conversational context is targetable or visible to advertisers.
    • Predefine evidence, spend limits, stop conditions, trust guardrails, and qualified outcomes before launch.

    Your next move is a readiness review, not a forecast. Put the decision brief, claim register, destination, tracking map, and risk rules into a shared launch packet. When suitable inventory is available to your team, you will be able to run a controlled test, learn from it, and scale only when the result survives both a trust check and a business check.

    References

  • Elevate Your LinkedIn Ads: Reserved Slots Now Available

    Elevate Your LinkedIn Ads: Reserved Slots Now Available

    Recently, I’ve been exploring LinkedIn’s Reserved Ads feature, which is now open to all managed advertisers. This exciting update lets me secure the prized top-of-feed placement, fundamentally boosting visibility and engagement for my B2B campaigns.

    LinkedIn has now made Reserved Ads accessible to all managed accounts, allowing me to grab the first ad slot in the feed. This prime location guarantees premium visibility for my advertising efforts.

    What’s new. With Reserved Ads, I can secure top-of-feed placement at a consistent rate, ensuring predictable delivery and enhanced reach. According to LinkedIn, this format drives up to 75% higher dwell time, 88% higher view-through rates, and achieves 99% of forecasted impressions, making it a powerful choice for my marketing strategy.

    How it works. These ads appear in the most visible ad slot on LinkedIn’s feed and support a variety of Sponsored Content formats like Video, Single Image, and Carousel Ads. My LinkedIn account representative assists me in reserving this valuable inventory and setting the pricing strategy.

    Why we care. For me, LinkedIn Reserved Ads are a game-changer, providing guaranteed top-of-feed placement. This increases my campaign’s visibility and engagement, helping me stand out in the competitive B2B space. The premium positioning enhances brand recall and influences potential leads early in the funnel.

    LinkedIn feed showing a digital advertisement for a payment system called Oustia, with a visual of a card reader.
    Explore the future of payments with Oustia's sleek new card reader! Secure, stylish, and efficient — the perfect tool for modern businesses.

    The predictable delivery and fixed pricing models mean I can plan my campaigns with more certainty, while also building high-quality retargeting audiences for future conversions.

    The big picture. By utilizing Reserved Ads, I’m effectively bridging brand awareness and demand generation. Anchoring my campaigns at the top of LinkedIn’s feed enables me to create higher-quality retargeting pools, with LinkedIn reporting up to a 101% increase in mid-funnel engagement as a result.

    The bottom line. LinkedIn’s Reserved Ads provide me, as a B2B marketer, with a predictable way to command attention and transform it into significant demand.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • AI-Driven Paid Media Strategy: Budgets, Bids and Visibility

    AI-Driven Paid Media Strategy: Budgets, Bids and Visibility

    You’ve probably been handed a familiar contradiction: let the ad platforms automate more decisions, but remain accountable for every dollar they spend. The answer isn’t to micromanage every bid, and it isn’t to treat an automated campaign as self-driving.

    Your job is to design the system around the automation. That means concentrating the budget, assigning each campaign a clear role, measuring channels as a portfolio and checking whether AI-generated search results are changing the visibility you thought you had.

    Allocate the budget before you configure the campaigns

    Metallic budget tokens are divided among three transparent channels before reaching smaller campaign controls.

    AI can optimize toward a target, but it can’t decide which business constraint matters most. Before opening a platform, write a one-page constraint sheet that answers five questions:

    • What business outcome are you buying? Name the sale, qualified lead, subscription, store visit or other outcome that ultimately matters.
    • What economics must the outcome meet? Use the maximum acceptable acquisition cost, minimum return or other threshold your business has approved. Don’t substitute a platform metric merely because it is available.
    • How much spending is committed? Separate the budget you expect to deploy from money that is optional, experimental or contingent on performance.
    • When is demand likely to change? Mark peak buying periods, expected slumps, launches and deadlines. Historical performance and Google Trends can help shape the monthly curve because an annual budget rarely deserves twelve equal allocations.
    • Which campaigns can you actually support? A channel that needs a steady supply of approved video or social creative is not a realistic allocation if that production process is blocked.

    Then divide the available money by purpose, not by platform. A useful portfolio has three conceptual pools:

    • Core delivery funds campaigns with an established job and credible performance evidence.
    • Growth funds additional reach, audience building or expansion beyond the demand you already capture.
    • Exploration funds a specific, bounded test of a channel, format, audience or message.

    There is no defensible universal percentage for these pools. The correct split depends on budget size, demand, business maturity, creative capacity and confidence in your measurement. What does generalize is the need for concentration. Spreading a modest budget across too many campaigns limits the data each campaign can collect, leaving the platform with too little signal and you with too many inconclusive results.

    Fund the smallest coherent campaign structure first. Add another campaign only when you can state its distinct job, give it enough budget to perform that job and explain how you will judge it. A new campaign created merely to use an available targeting option is fragmentation, not strategy.

    When more money becomes available, look first for campaigns that are both efficient and budget-constrained. That is a better starting point than dividing the increase evenly. Still, don’t assume that historical efficiency will survive unlimited scale. Increase spending in stages and inspect the economics of the additional volume. A higher budget creates financial exposure; if you don’t know the acceptable marginal acquisition cost, don’t scale solely because the platform forecasts more conversions.

    Give every channel a job in the portfolio

    Four color-coded media modules perform different functions while connecting to a shared central objective.

    A channel-by-channel return table often rewards the campaign that collects the conversion and punishes the campaign that created the demand. That can produce a tidy report and a weaker media plan.

    Portfolio roleTypical campaign useReason to fund itEvidence to inspect
    Demand capturePaid search against relevant queriesReach people already expressing intentQuery quality, conversion economics, impression availability and budget constraints
    Demand creationYouTube or social prospectingBuild awareness and qualified audiences before the final searchReach, audience growth, later search behavior and change in portfolio-level efficiency
    Re-engagementViewer or visitor remarketingContinue the journey with people who have already encountered the brandIncremental outcomes, frequency and overlap with other campaigns
    ExplorationDemand Gen, a new social channel or an unproven formatTest a defined path to additional demandThe stated hypothesis, spend boundary, delivery quality and downstream business outcome

    These roles prevent two common mistakes. The first is expecting every campaign to close the sale directly. The second is excusing weak performance with a vague claim that a campaign is building awareness. A demand-creation campaign still needs a measurable theory of change.

    For example, a YouTube campaign may produce few attributed conversions while search conversion rates improve and video-viewer remarketing audiences perform well. That pattern can justify continued investigation because campaigns can affect the efficiency of other channels. It does not, by itself, prove that video caused the improvement. Seasonality, promotions, competitive changes or measurement differences may also be involved.

    Use three levels of evidence so you don’t confuse a plausible contribution with a demonstrated one:

    <!– wp:list {