Tag: Ad Optimization

  • Curiosity-Driven Social Ads: A Practical Creative System

    Curiosity-Driven Social Ads: A Practical Creative System

    Your ad stops the thumb, but viewers leave as soon as the opening gives way to a familiar product pitch. The hook worked. The rest of the ad did not give them a reason to stay.

    The fix is not a louder opening or more frantic editing. You need a controlled sequence of questions, partial answers, proof, and payoff. That sequence turns a moment of attention into enough interest for someone to understand the offer and decide whether it is relevant.

    Key takeaways

    • A hook earns a pause. Curiosity earns the next few seconds by creating a question the viewer genuinely wants answered.
    • Build one primary information gap, then close it through a sequence of useful revelations rather than withholding the answer until the final frame.
    • Give creators a planned beat sheet but room to choose their own words. Natural delivery and deliberate structure can coexist.
    • Judge creative with retention, completion, replay, save, share, click, and conversion signals. No single metric tells you whether the ad is commercially effective.
    • Test the opening, revelation sequence, demonstration, and product transition separately so you can identify the part that changed performance.
    • Curiosity must repay attention. If the resolution is vague, irrelevant, or weaker than the promise, the ad becomes clickbait and trust falls with it.

    Build a curiosity chain, not a single hook
    Four connected tabletop scenes progressively reveal, demonstrate, and show the use of an unbranded product.

    Attention is an event: someone notices an unusual visual, a sharp line, or an unexpected result. Curiosity is a continuing state: the viewer notices that something remains unresolved and chooses to follow it.

    That distinction matters because Meta and TikTok increasingly use AI-powered delivery systems that respond to engagement, watch time, and downstream conversion behavior. An opening that produces a brief pause but immediate abandonment gives those systems less evidence of sustained interest than an ad people actively choose to finish, replay, save, share, or click.

    A curiosity gap is the distance between what the viewer knows and what they now want to know. It might be the cause of an unexpected result, the missing step in a demonstration, or whether a solution worked under a condition that resembles their own. It should not be a random mystery pasted onto an unrelated offer.

    Write the curiosity brief before the script

    Before anyone records, answer the following in plain language:

    1. What should the viewer understand by the end? Write the commercial conclusion without slogans. If you cannot state it clearly, the creative will wander.
    2. What question will carry the ad? Choose one primary question, such as why a familiar approach failed, what caused a surprising outcome, or whether a particular method can solve the viewer’s problem.
    3. Why does that question matter to this audience? Connect it to a recognizable frustration, risk, desire, or decision. Curiosity without relevance produces empty viewing.
    4. What evidence will resolve it? Select the demonstration, observation, comparison, explanation, or experience that makes the answer credible.
    5. Where does the product belong? Introduce it when the viewer can understand its role, not merely because the logo is due to appear.
    6. What is the complete payoff? State the answer you owe the viewer. The ending must satisfy the question created at the beginning.
    7. What should happen next? Match the call to action to the level of intent the ad has earned.

    This brief prevents a common mistake: opening with a compelling problem and then abandoning it for a feature list. Every beat should either advance the answer, provide proof, or help the viewer decide whether the answer applies to them.

    Use a question-and-answer ladder

    Do not keep one answer locked away while padding the middle. Give the viewer useful progress. Each beat can close a small question while opening the next logical one:

    • Opening tension: What happened, and why is it unexpected?
    • Relevant context: Why was the outcome a problem worth solving?
    • First revelation: What obvious explanation turned out to be incomplete?
    • Mechanism or demonstration: What was actually happening?
    • Product connection: How did the product change the process or result?
    • Resolution: What should the viewer conclude from what they have seen?
    • Next step: What can an interested viewer do now?

    The sequence should feel inevitable. If you remove the product and the opening story still reaches the same conclusion, the connection is probably too weak. If the product appears before the problem has meaning, the ad will feel like a disguised sales pitch.

    Make creator ads sound natural without leaving them to chance

    Conversational creator ads work differently from compressed brand spots. Longer, less polished creator videos are sometimes called yapper ads. They may move through a personal experience, an explanation, or a demonstration before naming the product. Their apparent looseness can make them feel like content someone chose to share rather than a commercial recited at them.

    That does not mean you should ask a creator to improvise the strategy. Most people will either disclose the conclusion too early, drift away from the main question, or remember the selling points and forget the promised payoff.

    Give the creator a beat sheet rather than a word-for-word script. Specify what each beat must accomplish, the evidence that must appear, any claim boundaries, and the final action. Let the creator choose the connective language, pauses, examples, and conversational rhythm.

    A reusable creator beat sheet

    1. Start inside the problem. Open with the moment the creator noticed something was wrong, surprising, or inconsistent with what they expected.
    2. Make the consequence concrete. Explain why the situation mattered without inflating the stakes.
    3. Show the first attempt. A failed assumption or incomplete fix gives the eventual answer context.
    4. Reveal the missing mechanism. Explain what changed the creator’s understanding of the problem.
    5. Demonstrate the product’s role. Show the action, process, or result instead of substituting adjectives for evidence.
    6. Close the original question. Return to the tension from the opening and provide a definite resolution.
    7. Invite the next step. Use a call to action that follows naturally from the resolved problem.

    A useful opening pattern is: I thought the obvious fix would solve this problem, but it made this specific symptom worse. The next beat must explain what happened. It cannot jump directly to a product name and leave the contradiction unresolved.

    Another workable pattern begins with a visible result, then asks what produced it. The demonstration supplies the answer in stages. This is especially useful when the product has a behavior viewers can see, because the proof becomes part of the story rather than a claim delivered over unrelated footage.

    During recording, capture complete thoughts and natural pauses. In editing, remove repetition but preserve the cause-and-effect chain. A jump cut should move the explanation forward, not create artificial urgency. The goal is not to make a conversational ad slow; it is to give each second a clear job.

    Protect the line between curiosity and clickbait

    Every open loop creates a debt. The viewer gives you time because the ad implies that an answer is coming. Honest curiosity repays that debt with an explanation, result, or demonstration that is useful even if the viewer does not buy.

    Clickbait uses the same surface mechanics but breaks the exchange. It exaggerates the opening, delays a simple answer without adding value, or resolves the story with information that has little to do with the promise. The problem is not merely tone. A disappointed viewer can abandon the video, ignore the call to action, or carry their distrust to the brand.

    Run a promise-payoff check

    Review the finished ad without sound first, then read its transcript without the visuals. In both passes, ask:

    • Can you state the opening promise in one sentence?
    • Does the middle provide meaningful progress, or does it merely postpone the answer?
    • Is the final answer specific enough to satisfy the opening?
    • Does the proof support the conclusion the viewer is asked to draw?
    • Is the product essential to the resolution, or has it been attached to an unrelated story?
    • Would a reasonable viewer feel that the time spent watching was respected?
    • Does the call to action follow from the evidence, or does it demand more confidence than the ad earned?

    Also inspect every transition. A strong transition answers one question and introduces the next. A weak transition changes the subject. When the ad jumps from a personal problem to a generic feature montage, curiosity collapses because the viewer can already predict the rest.

    Do not manufacture uncertainty around information the audience needs to evaluate the offer. The mystery should concern the story or mechanism, not whether the ad will eventually disclose a meaningful condition. The more consequential a fact is to the buying decision, the less useful it is as a tease.

    Measure the whole attention-to-action sequence
    A smartphone projects a path of glowing steps through a lens and doorway toward a hand reaching for a product.

    The traditional focus on the first three seconds is still useful, but it answers only whether the opening earned a chance. It does not tell you whether the story sustained interest, the proof created confidence, or the offer produced action.

    Read performance as a sequence of signals:

    • Initial attention: Did viewers stay beyond the opening instead of leaving immediately?
    • Sustained interest: Did watch time and completion behavior indicate that the middle held attention?
    • Active value: Did viewers replay, save, or share the video, including sharing it through direct messages?
    • Commercial interest: Did clicks occur after viewers had enough context to understand the offer?
    • Business outcome: Did the resulting visits produce the downstream conversion the campaign was built to generate?

    Watch time, completion, replays, saves, shares, post-view clicks, and conversions provide different evidence of chosen attention. Read them together. A long watch with no commercial response may mean the story entertained but did not qualify the viewer. A strong opening followed by weak completion points toward a middle that became predictable, repetitive, or disconnected from the hook. Completed views without clicks can indicate that the payoff was satisfying but the product transition or call to action was not persuasive.

    These patterns are diagnostic prompts, not automatic verdicts. Placement, audience delivery, offer, landing experience, and campaign objective can also shape the result. Use the creative signals to identify the next question, then isolate that question in the next test.

    Test one part of the curiosity system at a time

    Begin with a control ad and create variants around a single creative decision. Keep the offer, core message, and other controllable campaign conditions stable where possible.

    1. Test the opening. Keep the body and payoff unchanged while changing the initial tension, visual, or question. This tells you which version earns the strongest entry into the same story.
    2. Test the revelation sequence. Keep the opening constant while changing how the explanation unfolds. Compare direct explanation with demonstration, personal experience, or a problem-and-discovery progression.
    3. Test the proof. Preserve the promise and product role while changing the evidence used to resolve the question.
    4. Test product timing. Introduce the product at different logical points, but do not change the ending. Look for the point at which its appearance feels informative rather than interruptive.
    5. Test the payoff and call to action. Keep the preceding story stable while changing how explicitly the conclusion connects the result to the next step.

    Do not select a winner from the opening signal alone. The variant that stops more people can still attract poorly matched attention or fail to hold it. Compare retention behavior with clicks and downstream conversions, then choose the creative that advances the campaign’s actual objective.

    Keep a simple test record containing the hypothesis, the element changed, the control, the observed retention pattern, and the business outcome. This turns individual ads into reusable knowledge. Without that record, teams often repeat the same hook test while the real weakness sits in the middle of the story.

    Start with one active ad. Print its transcript, underline the question created in the opening, and label the exact line that resolves it. Then mark what new reason to continue appears between those points. If the middle contains no useful progress, rewrite that sequence before producing another hook.

    Automated delivery can decide who receives the next impression. Your controllable advantage is making that impression worth following. Build an honest question, reward each additional second, and let the sale follow from a conclusion the viewer was given enough evidence to reach.
    References

  • ChatGPT Ad Generation Puts Review Ahead of Automation

    ChatGPT Ad Generation Puts Review Ahead of Automation

    A reported ad-generation feature inside ChatGPT Ads could shorten the path from campaign setup to a usable creative variation. The important distinction is that the interface appears to generate a draft for approval, not a finished ad that bypasses advertiser judgment.

    For marketers, the practical value lies in faster iteration. The corresponding risk is treating generated copy as campaign strategy rather than as a starting point that still needs brand, accuracy, and performance review.

    What the reported workflow actually automates

    A visual workflow turns campaign inputs into several advertising drafts that await human selection.

    CrushPress.AI reported that an option to generate ads appears under the ChatGPT Ads platform’s ad-creation controls. According to the report, the system produces an ad variation using the advertiser’s website and campaign settings, then presents it for review, editing, and activation.

    That sequence matters. The reported interface positions artificial intelligence as a drafting layer within a conventional approval workflow. The marketer remains responsible for deciding whether the variation accurately reflects the offer, fits the campaign, and is ready to run.

    The report also describes a quick duplication option. Used carefully, that could support faster variation building: an advertiser could copy an existing ad, adjust one meaningful element, and compare the result with the original. The screenshot evidence does not, however, establish how widely the generation feature is available or how its output performs.

    Key takeaways

    • The reported tool uses website information and campaign settings to produce an ad variation.
    • Its workflow retains a human checkpoint before an ad is activated.
    • A duplication control could make structured creative variation easier, although speed alone does not create a sound experiment.
    • Generated copy still requires checks for factual accuracy, brand fit, campaign intent, and expected business value.
    • The available report shows an interface preview, not evidence of reach, output quality, or return on investment.

    Where generation can help and where it cannot

    Ad generation is most useful when the strategic inputs are already clear. A defined audience, offer, objective, and brand position give the system boundaries within which to draft. If those inputs are weak or inconsistent, quicker copy production can simply multiply the ambiguity.

    The feature may reduce mechanical work involved in producing a first variation. It cannot determine by itself whether a claim is sufficiently supported, whether the message creates the right expectation after the click, or whether a variation addresses the campaign’s actual constraint. Those are business and editorial judgments.

    The reported reliance on a website also introduces a source-quality issue. A generated ad may inherit unclear positioning, stale language, or overly broad claims from the page it uses. The output should therefore be checked against the current offer and campaign brief rather than assumed to be reliable because it originated inside the advertising platform.

    A review standard for AI-generated ads

    A marketing team checks an AI-generated ad mockup for imagery, layout, and approval criteria.

    A useful approval process begins with fidelity: the ad should describe the offer accurately and avoid introducing promises that the destination page cannot support. Reviewers should then assess whether the message reflects the intended audience and campaign objective instead of merely sounding polished.

    Brand review should cover voice, terminology, and the impression created by the ad as a whole. A grammatically clean variation can still be wrong for a brand if it exaggerates urgency, flattens an important distinction, or uses language the organization would not otherwise publish.

    Performance review requires discipline as well. The duplication control described in the report could encourage a large volume of near-identical ads. Marketers can preserve learning value by changing a deliberate variable, recording the hypothesis behind it, and judging results against the campaign’s established success measure. Generation increases the supply of options; it does not replace experimental design.

    The larger implication for campaign operations

    Embedding generation directly in an ad manager reduces the distance between source material, campaign configuration, and creative production. That convenience could lead to more variations being drafted and submitted, a commercial benefit that CrushPress.AI identified as potentially helpful to OpenAI’s advertising revenue.

    For advertisers, the more consequential change may be operational. As drafting becomes easier, quality control becomes the scarce capability. Teams will need clear ownership for approving claims, protecting brand standards, and deciding which variations deserve budget.

    The feature should therefore be evaluated less as an autonomous creative system and more as a workflow accelerator. Its long-term usefulness will depend on whether advertisers can turn faster production into better-controlled learning rather than simply a larger inventory of ads.

    References

  • Paid Search Relevance and Compliance: A Practical Framework

    Paid Search Relevance and Compliance: A Practical Framework

    Paid search relevance is no longer just a matter of matching a keyword to an ad. It spans the searcher’s intent, the platform’s quality signals, the promise made in the ad, the information on the landing page and, in regulated sectors, the boundaries imposed by advertising and privacy policies.

    Taken together, the source reports point to a practical model: use query analysis to understand demand, translate that demand into accurate ads and pages, apply compliance checks before launch, and measure whether the resulting leads are genuinely useful. Each layer constrains the others, so optimizing one in isolation can produce misleading gains.

    Relevance is becoming visible to searchers

    Google’s reported test of “Strongest match” and “Strong match” labels could make an internal assessment of relevance more noticeable in the search results. According to the source report, Google Ads Liaison Ginny Marvin confirmed that the experiment was intended to help people identify ads closely aligned with their queries. The test was described as limited to a small percentage of users in the United States, with no indication that the labels would become permanent.

    The report also said the labels relied on existing ad-quality and relevance signals rather than a new ranking factor. That distinction matters. Advertisers should not treat an experimental badge as a separate optimization target; the durable work remains the alignment among query, ad and destination. What may change is the visibility of that alignment. If a platform explicitly identifies some ads as stronger matches, relevance can influence attention before a searcher has evaluated the copy or brand.

    This creates a useful distinction between auction relevance and experienced relevance. A platform can judge an ad to be a close match, but the searcher still encounters a complete journey. A prominent label cannot compensate for an ambiguous offer, an inaccurate claim or a landing page that fails to answer the query. In sensitive categories, a message can also be highly specific yet unsuitable under advertising policy. Relevance therefore has to be assessed as an end-to-end quality, not merely a platform score.

    Semantic analysis turns search terms into intent evidence

    Colored signal paths pass through a translucent prism and form clusters around simple intent symbols.

    The semantic PPC report describes a set of methods for finding useful patterns in large, noisy search-term datasets. N-gram analysis separates queries into one-word, two-word and three-word units, then aggregates performance around those recurring components. In the source’s example, “private caregiver nearby” can be examined as individual words, adjacent pairs and the complete three-word phrase.

    This approach connects relevance decisions to observed behavior. A recurring term associated with spend but no conversions may warrant exclusion, while a component associated with strong performance may justify its own messaging, budget treatment or landing-page experience. The source specifically described using measures such as cost, impressions, clicks, conversions and conversion value to calculate performance for each n-gram. It also cautioned that the technique needs substantial search-term volume and becomes less manageable as the size of the word combinations increases.

    Two additional techniques address different forms of similarity. Levenshtein distance counts the edits needed to turn one string into another, making it useful for misspellings and near-duplicate wording. Jaccard similarity measures the overlap between sets of terms, so it can recognize queries containing the same words in a different order. The semantic PPC report presented thresholds of three and six as examples for tighter or broader grouping with Levenshtein distance, but those examples should not be treated as universal account rules.

    These techniques organize evidence; they do not settle meaning by themselves. As the source notes, Jaccard similarity does not inherently understand that “New York” and “NYC” refer to the same place. Edit distance likewise measures textual change, not whether two searches express the same need. Human review and business context remain necessary, especially when similar wording can refer to different services, professional roles or levels of urgency.

    Healthcare shows where relevance and compliance diverge

    A campaign specialist reviews blank healthcare advertising screens beside a magnifying glass, shield, padlock, and balance scale.

    The medical and mental-health PPC guide illustrates why closer query matching is not sufficient on its own. It groups patient searches into symptom or treatment research, informal descriptions of a service, and correct professional or service terms. The report recommends concentrating most budget on the latter two groups, where people are generally closer to taking action, while testing broader informational demand when resources allow.

    That search behavior creates a translation problem. A prospective patient may use an imprecise phrase that still communicates a legitimate need. Semantic analysis can identify recurring language and cluster variants, but the advertiser must decide whether the service actually fits the need and how to describe it accurately. Negative keywords are therefore not merely a cost-control device in this context; they also help prevent ads from appearing for services the practice does not provide.

    Ad copy introduces another boundary. The medical PPC source advises against guaranteed outcomes and blunt language, including terms such as “cure,” while emphasizing practical information such as accepted insurance, payment arrangements, specializations and professional credentials. It reports that Google and Meta restrict the promotion of medical, mental-health and wellness services, and that some providers may face additional requirements. Addiction-treatment advertisers, for example, may need a LegitScript listing depending on the practice and applicable Google Ads requirements.

    The implication is that the most direct wording is not always the most appropriate wording. Strong paid-search communication should recognize intent without making unsupported promises or addressing a person in an intrusive way. When an ad is rejected, the source recommends revising the language or seeking manual review where appropriate; it does not characterize every isolated rejection as evidence of an account-level problem.

    An operating model for relevant, defensible campaigns

    A sound workflow begins with the actual search-term record rather than an AI-generated keyword list alone. N-grams can reveal recurring modifiers, edit distance can consolidate close variants, and set overlap can expose duplicated themes. Those outputs should then be labeled by business meaning: the service requested, the searcher’s apparent stage, location or urgency, and whether the advertiser can truthfully meet the need.

    Campaign structure should follow meaningful differences, not every textual variation. The semantic PPC source warns that excessive granularity can complicate reporting, bidding and account management. Consolidation is appropriate when terms share an offer and intent; separation is warranted when they require different budgets, messages, destinations or compliance treatment. This keeps semantic analysis tied to decisions rather than turning clustering into an end in itself.

    Each resulting theme then needs a message-and-page review. The ad should accurately state what is available, while the landing page should resolve the questions raised by the query and explain the next action. For healthcare, the source recommends drawing on common intake questions and clearly covering matters such as eligibility, insurance, payment, treatment availability and the appointment process. Clear calls to book, call, request a consultation or submit an inquiry reduce uncertainty without requiring exaggerated claims.

    Measurement completes the relevance test. The medical PPC guide argues that form submissions alone are insufficient and that inbound calls should also be tracked because they can represent high-intent inquiries. It further recommends connecting campaign data with a CRM so the practice can distinguish raw leads from people who become patients or clients. This feedback can reveal a crucial failure mode: a query may generate clicks and conversions while repeatedly producing unsuitable inquiries.

    Compliance should be a recurring review rather than a launch gate that is never revisited. Search terms change, landing pages accumulate edits, platform policies evolve and automated matching can expose campaigns to unexpected queries. A defensible account keeps a record of exclusions, copy revisions, landing-page claims, approval outcomes and lead-quality findings so that optimization decisions can be explained and reassessed.

    Key takeaways

    • Google’s limited match-label experiment, as reported, makes existing relevance judgments more visible but does not introduce a separate ranking factor for advertisers to chase.
    • N-grams, Levenshtein distance and Jaccard similarity can reduce search-term noise, but textual similarity must still be interpreted through service, intent and policy context.
    • Negative keywords protect both budget and promise accuracy by filtering demand the advertiser cannot appropriately serve.
    • In regulated categories, a close query match does not authorize aggressive personalization, guaranteed outcomes or claims unsupported by the destination.
    • Lead quality, including qualified calls and downstream outcomes, is the strongest practical check on whether apparent relevance produced useful demand.

    If relevance indicators become more prominent, advertisers with coherent query, copy, page and measurement systems will be better positioned than those optimizing only for a visible platform label. The next competitive advantage is likely to come from making that coherence auditable as well as persuasive.

    References

  • Why Better PPC Bidding Still Depends on Conversion Quality

    Why Better PPC Bidding Still Depends on Conversion Quality

    PPC bidding can determine which auctions an advertiser enters and how aggressively a campaign pursues demand. It cannot, by itself, determine whether a click becomes a qualified lead, a signed client, or profitable revenue.

    Taken together, the two source reports point to a more useful way to evaluate bidding: connect auction-time optimization with search intent, landing-page relevance, operational follow-up, and closed-loop measurement. That makes it possible to distinguish genuine growth from a larger volume of inexpensive but low-value conversions.

    Key takeaways

    • Automated bidding can explore additional demand, but its value depends on whether the campaign optimizes toward conversions that reflect business outcomes.
    • CPA and ROAS targets are operating controls, not complete measures of performance; qualified leads, signed cases, and revenue provide essential context.
    • Temporary bidding and budget changes can help capture peak demand when they are paired with sufficient fulfillment or intake capacity.
    • Search-term reviews, intent-specific landing pages, CRM outcomes, and offline conversion data give bidding systems more meaningful signals.
    • Budget allocation should follow marginal business value rather than lead volume alone.

    Why efficient bidding can still produce weak business results

    A platform can lower the reported cost per conversion while the underlying economics deteriorate. This happens when the conversion being optimized is too far removed from the outcome the advertiser actually values. A form submission, for example, may be easy to generate but may say little about qualification, purchase intent, or eventual revenue.

    The law-firm PPC source illustrates the problem through the difference between leads and signed retainers. It argues that cost per lead alone leaves out the intake process, response speed, qualification, and the rate at which qualified prospects become clients. Its recommended reporting chain extends from ad spend and leads through qualified leads, signed cases, CPL, and CPA, segmented by channel and practice area.

    That distinction also changes how an advertiser should interpret automated bidding. Google’s Smart Bidding Exploration update, as described in the other source, lets advertisers specify a ROAS tolerance so campaigns can pursue conversion opportunities beyond queries they might otherwise reach. The source reports that campaigns using the capability saw about an 18% increase in unique converting search-query categories and a 19% increase in conversions. Those are platform-reported expansion indicators; they do not establish that every additional conversion carried the same downstream value.

    The practical question is therefore not simply whether bidding found more conversions. It is whether the incremental conversions remained qualified and profitable after the full customer journey was considered.

    Conversion quality is built before and after the auction

    An auction gateway connects search-intent pathways on one side with a landing experience, human follow-up, and a business handshake on the other.

    Better outcome data begins with the query. The law-firm source recommends reverse-engineering keyword strategy from call transcripts and CRM records rather than beginning with broad, generic terms. It also advocates segmenting keywords and campaigns by intent, funnel stage, budget, and conversion objective, with weekly search-term reviews used to identify valuable language and exclude irrelevant demand.

    This creates an important complement to bidding automation. The algorithm decides among available opportunities, while campaign structure defines which opportunities are grouped together and which outcome signals they share. If high-intent and exploratory traffic are mixed under one target, an aggregate CPA can conceal substantial differences in lead quality.

    Landing pages provide the next quality filter. The law-firm report calls for alignment between the searcher’s intent and the page headline, supporting proof, fast mobile performance, and immediate contact options. It reports that replacing a generic page with intent-specific pages, recent reviews and results, and fewer form fields doubled one client’s conversion rate without additional ad spend. Because this is a single account example reported by the source, it should be treated as illustrative rather than a universal expectation.

    Post-contact operations complete the chain. The same source recommends a response time below 60 seconds, an answer rate above 90%, and a signed rate of 25% to 40% among qualified leads for the law-firm context. These are the source’s operational targets, not general benchmarks for every industry. Their broader significance is that slow or inconsistent follow-up can erase gains produced by bidding and landing-page optimization.

    Use automated expansion and peak bidding with guardrails

    Google’s reported updates introduce two distinct bidding use cases. Smart Bidding Exploration is intended to uncover incremental demand while allowing a degree of ROAS flexibility. Promotion Mode, described as a beta in the source, is designed for temporary changes to ROAS targets and daily budgets around seasonal events, product launches, and flash sales. The source also says Exploration was extended to Performance Max campaigns without product feeds and was being tested for Shopping ads in Performance Max and Standard Shopping campaigns.

    Exploration should be judged as a controlled expansion test. Advertisers need to compare the new query categories with established traffic on qualified-conversion rate, acquisition cost at the final outcome, and revenue contribution. Search-term analysis remains relevant even when automation broadens reach because it can reveal whether incremental volume represents new high-intent demand or merely looser matching.

    Promotion-oriented bidding requires a different guardrail: operational readiness. Raising a daily budget and relaxing a ROAS target may generate more opportunities during a short demand window, but the extra volume only has value if inventory, sales, intake, and customer service can process it. Temporary settings should also have a defined end point so an exceptional trading period does not quietly become the campaign’s permanent efficiency standard.

    For campaigns constrained by budget, the Smart Bidding source also reports a change intended to produce more consistent performance against CPA and ROAS targets. Consistency can make planning easier, but a target should not be treated as proof of profitability. Budget decisions still need to account for the quality and economic value of the outcomes being purchased.

    Build a measurement loop that bidding can learn from

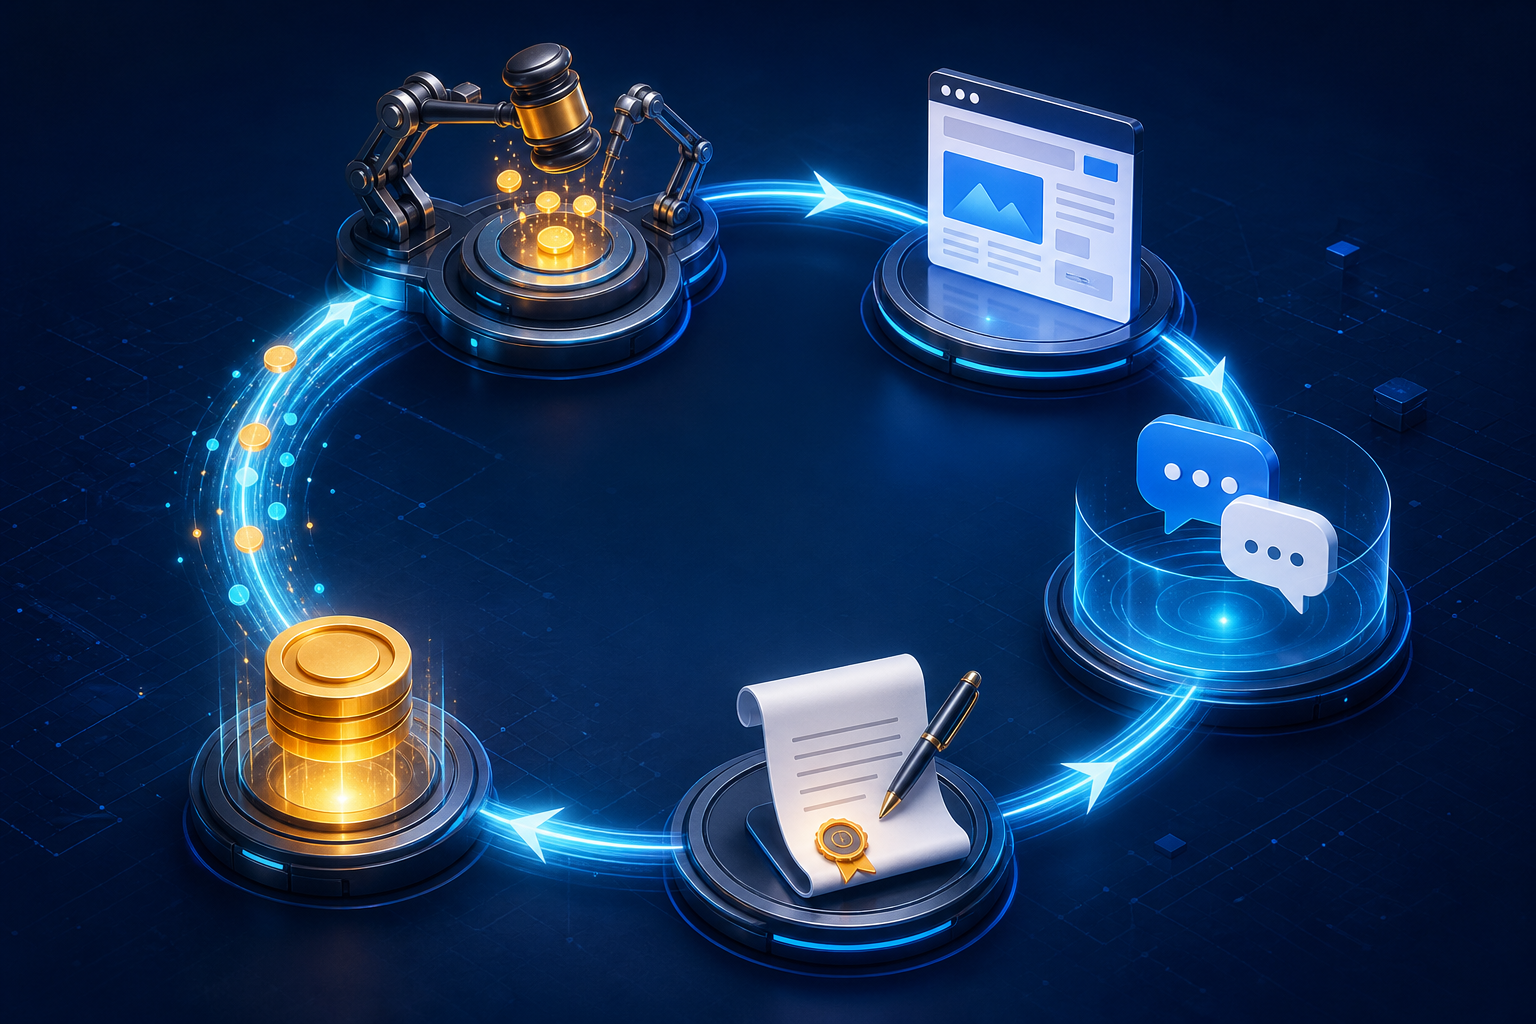
    A circular system links an ad auction, webpage, customer conversation, agreement, and revenue, with outcome signals flowing back to the auction.

    A reliable PPC system connects UTMs, call tracking, website analytics, CRM stages, and final outcomes. The law-firm source specifically points to Google Analytics and CRMs such as Lawmatics or Clio as parts of that chain. Its emphasis is not the choice of software, but the ability to trace a click through qualification and retention rather than ending reporting at the ad platform.

    That closed loop supports better decisions at three levels. Search terms and landing pages can be evaluated by the quality they produce. Campaign targets can be based on downstream value instead of superficial conversion volume. Budgets can then move toward the channels, practice areas, or intent groups that contribute the strongest business outcomes.

    The law-firm source also recommends Marketing Efficiency Ratio as an ecosystem-level measure rather than evaluating every channel in isolation. Used alongside channel-level CPL, CPA, qualified-lead rates, and signed outcomes, it can help distinguish the contribution of the overall marketing mix from the performance reported inside a single platform.

    The next stage of PPC optimization is therefore less about choosing between automation and manual control than about improving the feedback connecting them. Advertisers that define valuable conversions, preserve intent distinctions, and return verified outcomes to the campaign will be better positioned to use bidding expansion without losing sight of profitability.

    References

  • Paid Media Diagnostics: From Clean Data to Catalog Health

    Paid Media Diagnostics: From Clean Data to Catalog Health

    A weak paid media result can originate in several places: the reporting may be misleading, an advertised item may be unable to serve, or eligible inventory may simply be underperforming. Treating every symptom as an optimization problem risks changing bids, budgets, or creative before the underlying fault is known.

    Recent reporting on Google Analytics source controls and Microsoft Ads catalog diagnostics points to a more disciplined approach. Measurement integrity should be checked first, delivery eligibility second, and performance efficiency only after both foundations are credible.

    A diagnostic sequence for separating symptoms from causes

    The two source reports address different parts of the paid media system. The Google Analytics changes concern how traffic is classified and which domains contribute events to reporting. Microsoft Ads Product Explorer concerns whether catalog items are eligible, sufficiently described, and producing results. Together, they support a layered diagnostic model rather than a single dashboard verdict.

    Diagnostic questionLayer under reviewRelevant evidenceDecision it informs
    Can the reported traffic be trusted?Measurement integritySource classification and hostname provenanceWhether channel comparisons are reliable enough to guide budget decisions
    Could the advertised products serve?Delivery eligibilityCatalog status, required metadata, and identified feed issuesWhether reach is constrained before bidding or creative can have an effect
    How did eligible inventory perform?Performance efficiencyProduct-level results and consistently classified conversion trafficWhich items or channels warrant optimization, expansion, or closer investigation

    This sequence matters because similar symptoms can have unrelated causes. A channel can appear fragmented when one platform is recorded under several source names. A product can show no meaningful activity because it is not eligible to serve. Only after those possibilities are addressed does an efficiency diagnosis become well grounded.

    Clean attribution before comparing channel performance

    Tangled digital signals pass through a transparent filter and emerge as clean, distinct data streams.

    The Google Analytics source reported that a new Source Group reporting dimension consolidates variations of the same traffic source. Its example groups labels such as “facebook” and “fb” into one recognizable value. It also reported improvements to the Source Platform field intended to make classifications more consistent across advertising channels.

    For paid media diagnostics, that standardization reduces a common analytical distortion: one platform appearing as several small sources while another appears as a single consolidated source. The report said the structure extends beyond Google properties to platforms including TikTok, Pinterest, and Amazon, while also accounting for AI-originated traffic such as ChatGPT and Perplexity. It further said source-group information is available retroactively for historical analysis.

    Source consolidation does not resolve every attribution limitation. It makes labels more coherent, but a consistently named source is not automatically proof that the source caused a conversion. Analysts still need to distinguish reporting consistency from causal measurement and apply the same attribution interpretation when comparing channels.

    The reported hostname filters address a separate trust issue. According to the Google Analytics source, administrators can exclude events from unapproved domains before those events enter reporting. This can help prevent traffic associated with unexpected hosts from influencing campaign analysis. The practical control is to document which domains are legitimate before filtering; otherwise, an overly narrow approval set could remove activity that should have remained visible.

    Check catalog eligibility before optimizing retail campaigns

    Generic retail products move through eligibility checkpoints while a few incomplete or unavailable items are diverted for inspection.

    Microsoft Ads Product Explorer moves the investigation from attribution to inventory readiness. The Microsoft-focused source described a searchable catalog interface with filters for SKU, title, GTIN, and product ID. It reportedly surfaces eligibility problems, metadata gaps, and other conditions that may stop products from serving, while providing recommended actions and exportable filtered product lists.

    This changes how low delivery should be interpreted. If a product is ineligible or lacks necessary feed information, adjusting campaign-level settings does not address the immediate constraint. Catalog remediation comes first. Once an item is active and capable of serving, its advertising results can be evaluated as a performance issue rather than confused with a feed-health issue.

    The source also reported product-level performance visibility covering the previous 30 days. That window can connect operational diagnostics with observed activity: advertisers can distinguish products blocked by catalog problems from active items receiving exposure or producing results. The report stated that Product Explorer was live in advertiser accounts, although the source did not independently test its coverage or recommendations.

    Turn cleaner evidence into better optimization decisions

    The strongest synthesis is not a new all-in-one metric. It is a division of diagnostic responsibilities. Analytics source controls help establish whether cross-channel reports are internally coherent. Catalog tools help establish whether retail inventory can participate in the auction. Performance analysis then assesses what happened among the traffic and products that survived those checks.

    That separation also clarifies ownership. Measurement anomalies belong with analytics governance; product eligibility and metadata gaps belong with feed operations; efficiency questions belong with campaign management. Teams can still investigate collaboratively, but each finding should be routed to the layer capable of correcting it.

    A defensible performance review should therefore record both the result and the conditions under which it was observed. Channel comparisons should note whether source grouping and hostname controls were reviewed. Retail conclusions should note whether the relevant products were eligible and whether catalog issues were present. This creates an audit trail that makes later changes in reported performance easier to interpret.

    Key takeaways

    • Validate source classification and domain provenance before moving budget based on cross-channel reports.
    • Treat source standardization as a reporting improvement, not as proof of causal attribution.
    • For retail advertising, resolve eligibility and metadata problems before diagnosing low delivery as a bidding or creative failure.
    • Evaluate product and campaign efficiency only after measurement integrity and serving readiness have been checked.

    As advertising platforms automate more campaign execution, diagnostic discipline becomes more important, not less. The next useful advance will be a repeatable review process that connects trustworthy measurement, servable inventory, and performance decisions without collapsing them into the same signal.

    References

  • Google Ads Updates Link Trust Rules With Creative Testing

    Google Ads Updates Link Trust Rules With Creative Testing

    Two Google advertising updates point to a broader operating model for advertisers: eligibility must be maintained through clearer requirements, while campaign improvements should be validated through controlled experiments. The changes affect different products, but together they show how governance and optimization are becoming more structured.

    For Local Services Ads, the reported emphasis is on clearer terminology and alignment with Google’s revised badge framework. For Performance Max, the emphasis is on testing creative decisions before applying them more broadly. Advertisers therefore need both reliable compliance processes and a repeatable approach to experimentation.

    Two updates address different kinds of advertising risk

    A metallic link symbol and verification shield passing through a security checkpoint toward generic local storefront icons.

    CrushPress.AI’s Local Services Ads coverage reported that Google plans to rename its “Local Services platform policies” as “Local Services Ads requirements” on July 6. The report characterized the change as a clarification and modernization of guidance rather than a major enforcement crackdown. It also connected the revised language to Google’s recent restructuring of its badge system and verification standards.

    That update concerns participation risk: whether a business understands and satisfies the conditions associated with advertising and badge eligibility. Clearer requirements may reduce ambiguity, but a new label does not eliminate the need to keep credentials, verification information and operating standards current.

    The separate Performance Max report focused on decision risk. Because creative changes can affect results, advertisers need evidence before committing budget across campaigns. The newly reported experiment capabilities are intended to provide a more controlled way to assess assets instead of treating every creative revision as an immediate full rollout.

    Performance Max testing adds more useful creative comparisons

    Two different generic ad creatives moving through matching glass test modules before reaching a network of blank device displays.

    According to CrushPress.AI’s coverage, Performance Max advertisers can test entirely new asset groups, evaluate the effect of adding individual assets, and compare seasonal material with evergreen creative. The report also said that assets produced through Google’s Asset Studio can be included, allowing generated creative and other asset approaches to be assessed within the same experimentation framework.

    The practical value is not simply the ability to declare one asset a winner. The report described an additional success metric that can help advertisers evaluate more than one objective, such as conversion volume alongside efficiency. This matters because a creative change can improve one measure while weakening another; a broader evaluation can expose that trade-off before the change is expanded.

    The coverage also reported that experiments, including conversion lift studies, are being centralized on one Experiments page. Support for manager accounts and the Google Ads API was described as beginning to roll out soon, while further experiment and measurement capabilities were said to be forthcoming. Those rollout statements should be treated as reported product direction rather than proof that every account already has access.

    Key takeaways

    • Local Services Ads guidance is reportedly being reframed as explicit requirements and aligned with Google’s revised badge and verification framework.
    • The Local Services Ads change was presented as a clarity initiative, but businesses still need dependable processes for maintaining eligibility information.
    • Performance Max experiments reportedly support tests of asset groups, individual additions, seasonal versus evergreen creative, and assets created with Asset Studio.
    • An additional success metric can help teams judge creative against multiple campaign objectives rather than a single headline result.
    • Centralized experiment management may simplify oversight, although manager-account and API support were reported as rolling out rather than universally available.

    Advertisers need separate controls for eligibility and performance

    The two updates should not be collapsed into a single workflow. Local Services Ads requirements concern whether an advertiser can participate and qualify under the relevant framework. Performance Max experiments concern whether a proposed creative change produces a desirable outcome. Passing a verification check says nothing about asset effectiveness, while a successful creative test says nothing about compliance or badge eligibility.

    A practical response is to assign each issue to the appropriate review process. Local advertisers and their agencies can track requirement changes, verification materials and badge-related dependencies as governance work. Performance teams can document the hypothesis behind each asset experiment, the primary and secondary measures used to judge it, and the scope of any subsequent rollout.

    This separation also makes accountability clearer. Eligibility reviews should answer whether the business remains qualified and whether its information is current. Experiment reviews should answer what changed, what comparison was made, which measures moved and whether the evidence supports broader deployment. Both disciplines reduce avoidable risk, but they do so in different ways.

    Questions remain about access, enforcement and interpretation

    The source material does not establish how the renamed Local Services Ads requirements will affect individual advertisers, whether enforcement practices will change, or exactly how compliance will determine badge status in every case. The reported alignment suggests that eligibility and trust signals should be reviewed together, but it does not justify assuming a new penalty or automatic badge outcome.

    Likewise, the Performance Max report does not provide universal availability dates, account-level eligibility details or a guarantee that every experiment will produce a conclusive result. Advertisers should confirm which capabilities appear in their own accounts and avoid treating an announced rollout as completed access.

    As Google develops both frameworks, the durable advantage will come from operational readiness: maintaining evidence for eligibility decisions and using experiments to support creative decisions. Teams that establish those routines can adapt to additional requirements and measurement features without rebuilding their processes around every product update.

    References

  • AI-Driven PPC Optimization: A Practical Signal Strategy

    AI-Driven PPC Optimization: A Practical Signal Strategy

    Your automated PPC campaign can hit its platform target and still be bad for the business. If accidental clicks, weak leads or low-margin sales count as success, the system will pursue more of them with impressive efficiency.

    The fix isn’t constant bid tinkering. You need to improve the signals, values and boundaries that shape each decision. Use the framework below to diagnose an underperforming campaign and give its automation a better problem to solve.

    Start with the question the bidding system must answer

    AI-driven PPC changes your job from controlling every keyword and bid to designing the inputs that guide the system. That starts with a clear business objective. “Get more conversions” is not clear enough when a form submission, qualified opportunity and completed sale have very different value.

    Write the campaign objective as a decision the system can repeatedly make: find additional qualified demo requests within an acceptable acquisition cost, sell available products while protecting margin, or reach relevant prospects without allowing low-quality inventory to consume the budget.

    1. Name one primary outcome. Choose the action that best represents business success, not merely the event that is easiest to track.
    2. Define what counts. State the conditions that distinguish a useful lead, order or visit from an irrelevant one.
    3. Assign value where outcomes differ. Reflect meaningful differences in revenue, margin, lead quality or customer value instead of treating every conversion as equal.
    4. Select the matching bidding objective. Target CPA makes sense when qualifying outcomes have comparable value. Target ROAS needs values that reliably represent what the business gains.
    5. Record the guardrails. Note brand restrictions, excluded inventory, geographic limits, inventory constraints and any claims the ads must not make.

    Then apply a blunt test: if the campaign doubled the primary conversion tomorrow, would the business be pleased with every additional result? If the answer is no, repair the definition before asking automation to scale it.

    Make conversion data harder to fool

    A translucent sorting system separates strong customer and purchase signals from weak click data while an analyst observes.

    Smart Bidding can only learn from the events you send back. A thank-you page that fires twice, a spam form submission or a low-intent micro-conversion can teach the system that poor traffic is desirable. More data does not compensate for the wrong data.

    Audit every conversion action included in bidding. For each one, answer these questions:

    • Does this event represent a business outcome or only progress toward one?
    • Can duplicate, accidental, internal or fraudulent activity trigger it?
    • Does the platform receive any later signal about lead qualification, completed purchases or cancellations?
    • Does its assigned value reflect revenue alone, or the economic measure the campaign is meant to improve?
    • Would you intentionally buy more of this exact action at the target cost?

    Keep primary and diagnostic signals distinct. A brochure view or form start can help you understand the journey without carrying the same bidding weight as a qualified lead. When the buying cycle continues beyond the website, connect later outcomes back to the original ad interaction where your measurement setup permits it. That gives the system evidence about customer quality rather than just form completion.

    Value design matters just as much. If two products generate the same revenue but have very different margins, revenue-only values can push spend toward the less profitable sale. The same problem appears in lead generation when every inquiry receives equal credit even though only some become viable opportunities.

    Do not start by changing the bid target when reported performance and commercial results disagree. First verify the event, its deduplication, its value and the feedback coming from downstream systems. A bidding adjustment cannot correct a broken definition of success.

    Use exclusions as signal control, not just brand protection

    Placement exclusions still protect your brand, but they also protect the learning process. Display inventory that produces cheap clicks, accidental taps or automated traffic can create attractive engagement metrics without producing useful outcomes. Strategic exclusions help prevent those interactions from distorting the signals used for optimization.

    Review placements by business result, not click-through rate alone. Start with the inventory consuming meaningful spend, then inspect conversion quality, downstream lead status and the context in which the ad appeared.

    1. Remove clear contamination. Exclude malicious, bot-heavy or obviously irrelevant placements as soon as you can identify them.
    2. Question high-click, low-outcome inventory. A placement producing many interactions but no useful commercial result may be training the campaign toward cheap activity.
    3. Treat mobile apps intentionally. If app inventory is not part of the campaign strategy, exclude it rather than allowing accidental taps to become a hidden acquisition channel.
    4. Match exclusions to the objective. A reputable broad-reach placement may suit awareness while being too expensive or unfocused for direct response.
    5. Keep an audit trail. Record why each exclusion was added so that a temporary performance decision does not become an unexplained permanent rule.

    Avoid building a blocklist simply because a placement has not converted yet. Sparse data can make normal variation look conclusive, and indiscriminate exclusions can remove useful reach. Look for a defensible reason: irrelevant context, suspicious interaction patterns, poor downstream quality or economics that conflict with the campaign objective.

    Apply obvious safety and quality exclusions before launch when possible. During the learning phase, early low-quality traffic does more than spend money; it gives the system examples of the behavior it should seek. Clean boundaries let automation explore without making every corner of the network equally eligible.

    Operate automation through inputs, budgets and diagnosis

    A marketer manages input channels, budget reservoirs, diagnostic tools, and exclusion gates around an automated advertising system.

    Give audience and query expansion a useful starting point

    Broad match, keywordless targeting, URL expansion and audience signals can uncover demand that a fixed keyword list misses. They are discovery tools, not substitutes for positioning. Supply accurate first-party audience data where available, keep landing pages tightly aligned with the offer, and review the new queries and destinations the system finds.

    Judge expansion by the quality of the resulting customers. If volume rises while lead quality falls, inspect the newly reached queries, audiences, placements and pages before constraining the entire campaign. You are trying to locate the weak input, not eliminate discovery.

    Write a brief that automation can use

    When AI assembles or adapts ads, your brief becomes part of campaign control. Include the intended audience, the problem being solved, the offer, approved proof points, brand tone, required qualifications and prohibited claims. Specify which landing page supports each promise.

    Product campaigns also depend on feed quality. Make sure product names, attributes, availability and other business data describe what can actually be bought. A bidding system cannot recover from an ambiguous feed or an ad promise that the destination page fails to support.

    Build budgets around business constraints

    Set budget architecture with margin, inventory, lifetime value, cash flow and growth priorities in view. Daily spend is an output of that structure, not the strategy itself. Use missed-opportunity reporting to distinguish a campaign constrained by budget from one constrained by demand, eligibility or weak inputs.

    Before increasing budget, ask whether the next unit of spend is likely to produce an outcome the business wants. Before reducing it, ask whether the campaign is genuinely inefficient or simply being judged against incomplete conversion data. Budget changes amplify whatever signal architecture is already in place.

    Diagnose the symptom before changing the target

    • Conversion volume rises but quality falls: inspect spam, placement mix, query expansion and the definition of the primary conversion.
    • CPA looks healthy but profit falls: check conversion values, product margin, cancellations and which outcomes receive bidding credit.
    • Traffic grows but conversions do not: compare the ad promise with the landing page, then review newly reached queries, audiences and placements.
    • Volume remains limited: verify tracking first, then examine eligibility, exclusions, budget constraints and available demand.
    • Brand representation drifts: strengthen the creative brief, approved claims and destination mapping before broadly restricting delivery.

    Change the input closest to the diagnosed problem. If you alter the conversion setup, exclusions, creative, budget and bid target at once, you lose the ability to tell which intervention helped. Keep a decision log that records the symptom, evidence, change and expected business effect.

    Key takeaways

    • AI-driven PPC improves when you define a valuable outcome clearly enough for the system to recognize and pursue it.
    • Clean conversion events and realistic values matter more than feeding the platform the largest possible volume of signals.
    • Placement exclusions can protect both brand safety and the quality of campaign learning.
    • Audience expansion, feeds and AI-generated creative need accurate starting inputs plus human review of the results.
    • Diagnose tracking, traffic quality and economics before responding to weak performance with a bid or budget change.

    For your next optimization session, choose one campaign and audit its primary conversion, assigned value and highest-spend placements. Fix the clearest signal problem first, document the change, and let the next decision follow from business results rather than platform activity alone.

    References

  • How to Scale a High-ROAS Campaign Without Wasting Budget

    How to Scale a High-ROAS Campaign Without Wasting Budget

    Your campaign is profitable, lead quality looks good, and someone wants to double the budget. The tempting assumption is that twice the spend will produce twice the revenue.

    That only works when the campaign has profitable demand left to capture. Before you raise the budget, verify the business value behind the reported ROAS, confirm that budget is the real constraint, and decide how much efficiency you are prepared to trade for additional volume.

    High average ROAS does not prove the next dollar will perform

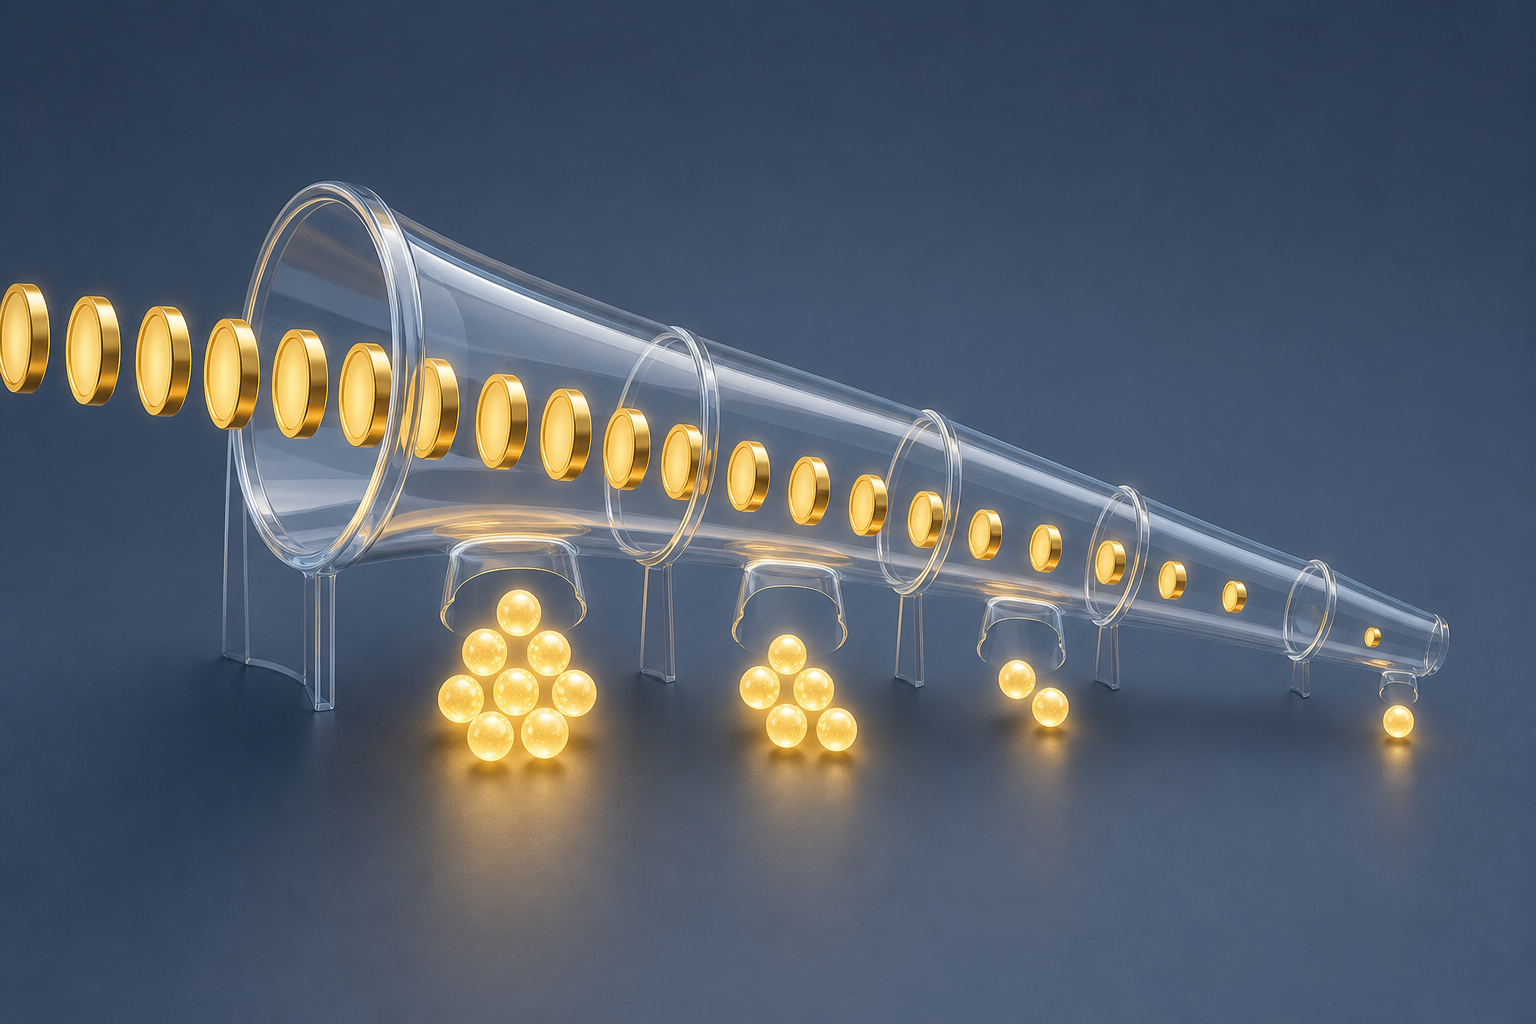
    A curved transparent funnel converts successive gold tokens into progressively fewer glowing spheres.

    The ROAS in your dashboard describes the spend you have already made. It does not tell you what the next dollar will return. A tightly constrained campaign may be collecting the easiest conversions: high-intent searches, familiar audiences, strong locations, or the most responsive hours. More budget can push delivery into less efficient opportunities.

    That is why budget scaling should be judged on marginal performance. Calculate incremental ROAS as additional revenue divided by additional spend. If spend rises but qualified revenue barely moves, the campaign has not scaled successfully, even if its blended ROAS still looks respectable.

    You also need an economic floor. Your target should reflect gross margin, fulfillment costs, returns, sales costs, and any other expense that changes when you acquire another customer. A campaign can exceed a platform ROAS target and still produce weak profit.

    Key takeaways

    • Scale only when the campaign is constrained by budget and still has qualified demand available.
    • Validate conversion tracking, lead quality, order value, and profitability before trusting a high ROAS.
    • Increase budget in controlled steps and avoid changing bids, targeting, creative, and budget at the same time.
    • Judge the test by incremental qualified revenue and profit, not spend growth alone.

    Validate the business result before funding it

    A scaling decision is only as reliable as the conversion signal behind it. Run this audit before approving more spend:

    1. Check conversion tracking. Confirm that each important action fires once, carries the correct value, and represents a result the business actually wants. Remove duplicate, test, or low-value actions from the primary optimization signal.
    2. Trace leads to outcomes. Compare campaigns using qualified opportunities, closed sales, or another downstream milestone. A form submission is not equivalent to revenue when lead quality varies.
    3. Reconcile order value. Check whether the value sent to the ad platform reflects cancellations, refunds, discounts, and unusually large purchases that can distort the average.
    4. Compare revenue with profit. Establish the lowest acceptable return before scaling. This gives you a stopping rule if marginal efficiency declines.
    5. Confirm operational capacity. Make sure sales, inventory, fulfillment, and customer support can absorb more volume. Paying for demand that the business cannot serve is not productive growth.

    If any of these checks fails, fix the measurement or business constraint first. Increasing the budget would amplify the uncertainty rather than resolve it.

    Prove that budget is the constraint

    A strong campaign can have limited scale for reasons that money cannot fix. Search demand may be finite. Targeting may be narrow. Inventory may be unavailable. The sales team may reject additional leads. Budget should rise only when the evidence points to a spend constraint.

    What you observeLikely interpretationWhat to do next
    The campaign regularly reaches its budget while qualified conversions remain profitableBudget may be limiting useful demandRun a controlled budget increase
    The campaign does not consistently spend its current budgetBudget is probably not the immediate constraintInvestigate demand, bids, eligibility, targeting, and creative
    Platform ROAS is high but downstream lead quality is weakThe optimization signal does not match business valueRepair tracking and feed stronger outcomes back into optimization
    Spend rises but qualified revenue stays nearly flatMarginal demand is weak or already exhaustedStop increasing budget and diagnose the expansion
    More orders create stock or service problemsThe constraint sits outside advertisingResolve operational capacity before buying more demand

    Do not treat a platform recommendation to spend more as sufficient evidence. It can identify delivery capacity, but your business data must determine whether that capacity is worth buying.

    Scale in stages with a written stopping rule

    Gold budget blocks move up three platforms with checkpoint gates, while a stop lever and reserve blocks sit nearby.

    Large budget changes can disturb a stable campaign and make the result harder to interpret. In Microsoft Advertising, changes beyond 15% may introduce volatility or a renewed learning period. Other platforms have their own behavior, so check the system you use and favor measured adjustments.

    1. Save the baseline. Record spend, qualified conversions, qualified revenue, profit, cost per acquisition, ROAS, and conversion volume before the change.
    2. Name the hypothesis. Write down why more budget should capture additional profitable demand. For example, the campaign is repeatedly constrained while downstream conversion quality remains stable.
    3. Set the guardrails. Define the minimum acceptable marginal ROAS or maximum acceptable acquisition cost. Include lead-quality or profit requirements where platform revenue is incomplete.
    4. Change the budget only. Keep bidding strategy, targeting, ads, landing pages, and conversion definitions stable. Otherwise, you will not know what caused the result.
    5. Allow the campaign to settle. Avoid reacting to an isolated day. Wait until you have enough conversion volume to compare the new period with the baseline while accounting for normal business conditions.
    6. Choose the next action. Increase again only if incremental volume meets the guardrails. Hold when the result is promising but uncertain. Reduce the budget when additional spend fails the profitability test.

    Document each change with its date, amount, rationale, and result. This creates a usable scaling history and prevents a sequence of undocumented increases from turning into a permanent efficiency loss.

    Read the result as a business decision

    A lower blended ROAS after scaling is not automatically a failure. Additional volume can justify some efficiency loss if the new customers or leads remain profitable. The decision depends on what happened at the margin.

    • Spend and qualified profit both rise: the campaign has demonstrated headroom. Consider another controlled increase.
    • Spend rises, revenue rises, but profit does not: you have crossed the economic limit. Return to the last profitable level or improve margins and conversion quality before testing again.
    • Spend rises but qualified volume barely changes: more budget is not solving the active constraint. Examine demand, auction eligibility, targeting, the offer, and the landing experience.
    • Platform conversions rise while sales outcomes weaken: the campaign is optimizing toward the wrong signal. Pause scaling and reconnect optimization to verified business outcomes.

    Your next budget increase should be earned by evidence. Establish the profit floor, verify headroom, make one controlled change, and fund the next step only when the additional spend produces business value.

    References