Tag: Ad Optimization

  • Google Ads Smart Bidding: The 50-Conversion Benchmark

    Google Ads Smart Bidding: The 50-Conversion Benchmark

    You changed a Smart Bidding strategy, performance moved, and Google Ads now shows a Learning status. The difficult decision is whether to wait, reverse the change, or treat the movement as evidence that something is wrong.

    The short answer is that 50 conversions is not a minimum requirement or a guaranteed turning point. Google says calibration can take up to roughly 50 conversion events or three conversion cycles, with faster learning possible when useful historical data already exists. Treat those figures as planning boundaries for diagnosis, not as a finish line the campaign must cross before it can work.

    The 50-conversion figure is a benchmark, not an entry fee

    A Smart Bidding strategy does not sit idle until conversion number 50. It bids while it is learning. The approximate 50-event figure describes how much feedback calibration may require after a qualifying change; it does not mean every campaign needs 50 conversions before automation becomes usable.

    It is also not a 50-conversions-per-month rule. Calendar months are arbitrary boundaries to a bidding system. What matters is the stream of conversion feedback available after the change and how quickly that feedback arrives.

    The second part of the benchmark matters just as much: three conversion cycles. A conversion cycle is the time between the traffic being generated and the resulting conversion feedback arriving. If customers tend to convert after a delay, the bidder cannot immediately observe the eventual outcome of recent auctions. A week of elapsed time can therefore contain plenty of traffic but little mature conversion evidence.

    That distinction corrects four common misreadings:

    • You do not have to accumulate 50 conversions before enabling Smart Bidding.
    • The 50th event does not guarantee that performance will suddenly stabilize or meet your business target.
    • Fifty clicks, leads in a separate system, or other uncounted actions are not substitutes for the conversion events available to the bidding strategy.
    • A campaign with strong relevant history may calibrate before it reaches the approximate upper benchmark.

    Use the benchmark to answer a narrow question: has the bidder had a reasonable opportunity to observe outcomes since the material change? Keep that separate from the larger question of whether the campaign is profitable.

    Estimate learning time with two clocks
    Two numeral-free clocks connected to a learning system, one surrounded by event signals and the other by three broad cycle rings.

    Asking how many days Smart Bidding needs is usually too imprecise. Two campaigns can be the same age while giving the bidder very different amounts of usable information. Track a volume clock and a feedback-latency clock instead.

    Planning signalQuestion to answerHow to use it
    Conversion-event volumeHow many relevant conversion events have arrived since the change?Compare the observed count with the approximate 50-event calibration benchmark. Do not treat 50 as a required quota.
    Conversion-cycle lengthHow long does it normally take conversion feedback to arrive after traffic occurs?Use up to three cycles as the alternative time frame. Recent traffic may still be too immature to judge.
    Historical conversion dataDoes the strategy already have useful evidence from before the change?Expect that relevant history may shorten calibration, but do not assume that unrelated or obsolete history will settle the current decision.
    Change historyDid another material edit happen during the observation period?Separate the periods in your change log. Otherwise, you may attribute one change’s effect to another.

    For rough capacity planning, you can calculate a volume-only estimate as follows: subtract the conversion events already observed from 50, then divide the remainder by the campaign’s recent average conversion events per day. This is not an official completion forecast. Conversion rates fluctuate, historical data can accelerate calibration, and delayed outcomes can make the most recent days look artificially weak.

    The practical lesson for a low-volume campaign is simple: the same amount of algorithmic feedback can require much more calendar time. If conversion events arrive slowly, checking the campaign every few days does not create new evidence. It only creates more opportunities to interrupt learning with another edit.

    Do not manufacture apparent volume by redefining a shallow action as a primary conversion merely to approach 50. That changes what the bidder is being asked to optimize. More signals are not better when they represent the wrong business outcome.

    Performance Max needs an additional expectation check. It can take longer to reach performance goals when most traffic comes from channels outside Search or Shopping. If that describes your campaign, avoid transferring a Search campaign’s calendar expectations directly onto Performance Max.

    Protect the learning period from overlapping changes
    A glowing network develops inside a protective dome while hands pause above several surrounding control levers and dials.

    A campaign can enter Learning when you create or reactivate a bidding strategy, change its settings, or make certain changes to campaign composition. Changes to conversion goals are also relevant for Search, Shopping, and Performance Max campaigns.

    This creates a change-control problem. If you edit the bidding strategy, alter the goal, adjust the campaign again, and then judge the combined result, there is no clean observation window. You will know that performance changed, but not which intervention deserves credit or blame.

    Before making a material change, create a short learning record with:

    • The exact time and date of the change.
    • The campaign and bidding strategy affected.
    • The setting, campaign composition, status, or conversion goal that changed.
    • The conversion events the strategy is intended to optimize.
    • The typical conversion-cycle length used for planning.
    • The accumulated conversion-event count you will review after the change.
    • The business guardrails that would justify intervening before calibration is complete.

    Then give the change a clean observation period when business risk allows it. This is particularly important during the initial Performance Max learning period, when frequent budget, bidding-strategy, and campaign-status changes can be counterproductive.

    A clean observation period does not mean ignoring the account. Monitor measurement, spend, and lead or transaction quality throughout. The restraint applies to unnecessary optimization edits, not to detecting broken tracking or containing unacceptable cost.

    Know when to wait and when to intervene

    The Learning label is not a command to leave a campaign untouched at any cost. Advertising spend is real exposure. Your decision should combine calibration evidence with measurement integrity and business limits.

    1. Check measurement first. Confirm that the intended conversion events are still being recorded and that the bidder is optimizing toward the outcome you actually value. If tracking is broken or the wrong goal is active, waiting for more data only gives the system more bad information.
    2. Identify the most recent material change. Use that point as the start of the current observation period. If several changes overlap, document each one before drawing a causal conclusion.
    3. Read both learning clocks. Count relevant conversion events and assess how many conversion cycles have had time to mature. Do not substitute impressions, clicks, or elapsed days for conversion feedback.
    4. Apply business guardrails. Continue observing when measurement is sound, the campaign remains within tolerable cost boundaries, and it is still inside the approximate calibration window. If spend is creating unacceptable exposure, protect the budget even though another change may lengthen learning.
    5. Escalate the diagnosis after a fair opportunity. Once the strategy has seen roughly the benchmark amount of evidence or enough conversion cycles, continuing volatility does not automatically prove that Smart Bidding failed. It does mean that learning alone is no longer a sufficient explanation.

    When that last condition applies, inspect the inputs and constraints rather than repeatedly toggling the strategy. Check whether the selected conversion goal represents the desired outcome, whether recent changes altered campaign composition, whether traffic quality shifted, and whether the business target is compatible with the campaign’s available opportunities. These are different problems, and none is solved merely by waiting for a Learning status to disappear.

    The most useful decision rule is therefore conditional:

    • Wait when measurement is valid, the change is understood, the campaign is still accumulating meaningful evidence, and spend remains within your limits.
    • Investigate now when conversion tracking appears broken, the wrong goal is active, or another change has contaminated the observation period.
    • Intervene when the financial exposure is unacceptable. Learning is not a reason to ignore a budget or cost boundary.
    • Broaden the diagnosis when sufficient event volume or conversion-cycle time has passed but the campaign still misses the outcome that matters.

    This framework prevents opposite mistakes: aborting a sound strategy before delayed outcomes arrive, and excusing persistent underperformance indefinitely because automation is supposedly still learning.

    Key takeaways

    • Roughly 50 conversion events is an approximate upper calibration benchmark, not a universal eligibility requirement.
    • Three conversion cycles account for delayed feedback that a simple day count misses.
    • Conversion volume, conversion-cycle length, bidding strategy, and available history can all affect calibration time.
    • Low-volume campaigns may need more calendar time because they accumulate conversion evidence slowly.
    • Frequent changes make the learning period harder to interpret and can prolong the path to a useful decision.
    • Broken measurement, an incorrect conversion goal, or unacceptable spend warrants action before any numerical benchmark is reached.

    For your next Smart Bidding change, record the event count, conversion-cycle expectation, and acceptable spend boundary before you edit the campaign. When performance moves, you will have a defined basis for waiting, investigating, or acting instead of treating day 50 or conversion 50 as a magic answer.

    References


  • Search Marketing Performance Intelligence: A Decision System

    Search Marketing Performance Intelligence: A Decision System

    Your CPA jumps, organic clicks soften, and visibility across AI search looks uneven. Your dashboard confirms that something moved. It does not tell you whether demand changed, a competitor became more aggressive, your ads lost relevance, or the conversion path broke.

    You need more than a cleaner report. You need a repeatable way to connect business outcomes, funnel metrics, account changes, market behavior, and search-surface coverage – then turn that evidence into one defensible action. That is the practical job of search marketing performance intelligence.

    Replace the reporting question with a decision question

    Reporting asks what happened. Performance intelligence asks what you should change, why that change is justified, and what evidence would prove it worked.

    That difference sounds small, but it changes how you build the entire analysis. If you start with all available data, you tend to produce a dashboard full of metrics. If you start with a pending decision, you can select only the evidence needed to make that decision safely.

    Write a one-sentence decision question before opening your reporting tools. It should name the affected scope, the observed change, and the choice in front of you. For example: Should we restore non-brand bids, revise the ads, or repair the landing-page experience after conversion volume fell in these campaigns?

    A useful decision question has five parts:

    • Scope: The channel, market, campaign, topic, device, audience, or landing page affected.
    • Outcome: The business metric that moved, such as conversions, revenue, CPA, return on ad spend, or average order value.
    • Timing: When the movement began and which comparison period is genuinely comparable.
    • Competing explanations: At least one internal cause and one external cause worth testing.
    • Decision: The bid, budget, targeting, creative, content, landing-page, or measurement change you might make.

    This prevents a familiar failure: treating a falling line as a diagnosis. A traffic decline only becomes actionable after you identify where it began, what drove it, and what decision follows. Until then, it is an alert.

    Separate outcome metrics from diagnostic metrics as well. Revenue and qualified conversions are outcomes. Impressions, click-through rate, CPC, Quality Score, ranking coverage, and AI Overview presence can help explain those outcomes, but none is a business result by itself. A Quality Score decline, for example, may surface before a later increase in click costs becomes obvious. Treat it as an early clue to investigate, not a target to optimize in isolation.

    Trace every performance shift through five evidence layers

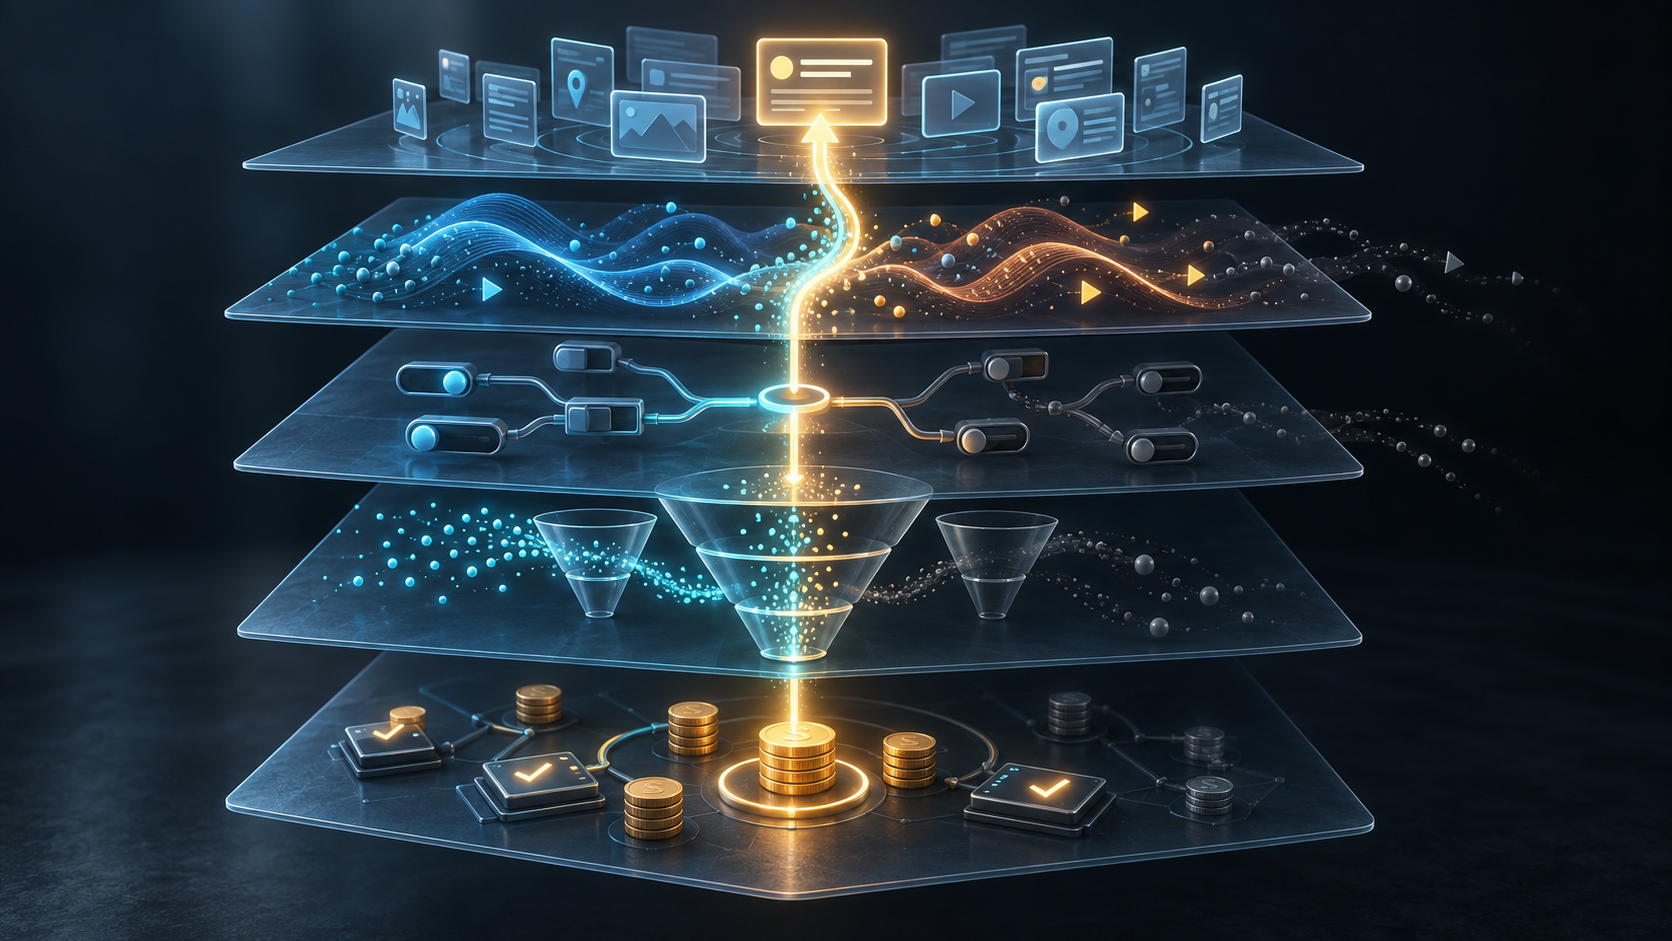
    Five translucent evidence layers show business outcomes, a conversion funnel, campaign controls, market activity, and search surfaces connected by one glowing signal.

    A strong diagnosis moves from the business result toward its possible causes. Do not begin with the most interesting chart or the most accessible data set. Work through the same evidence layers in the same order so that a plausible story does not outrun the facts.

    1. Confirm the business outcome. Compare equivalent conversion definitions and comparable periods. Determine whether the change sits in conversions, revenue, CPA, return on ad spend, or average order value. Check whether it is account-wide or concentrated in a particular campaign, topic, product, market, device, or landing page.
    2. Decompose the funnel. Inspect impressions, click-through rate, clicks, average CPC, conversion rate, and average order value. The arithmetic keeps the analysis honest: clicks are driven by impressions and click-through rate; conversions are driven by clicks and conversion rate; for commerce, revenue is driven by orders and average order value. Find the first meaningful component that changed.
    3. Inspect internal account state. Review budgets, bids, targeting, search terms, negatives, ads, Quality Scores, landing pages, tracking, and account change history. Match each change to the affected segment and date. A coincidental account edit is not automatically the cause, but it is a testable lead.
    4. Add market context. Look at competitor participation, competitor messaging, auction conditions, generic demand, and relevant market events. Joining account behavior with market behavior helps distinguish an internal failure from a broader shift. Timing can narrow the explanation, although it does not prove causation on its own.
    5. Check visibility across surfaces. For the same high-value topics, inspect paid coverage, organic rankings, and AI Overview presence. A paid keyword gap has a different priority when you already hold strong organic or AI visibility than when competitors occupy every visible surface.

    Keep the comparison grain consistent. If the outcome is measured weekly by market and campaign, do not explain it with a monthly global competitor trend. Align time zones, currencies, conversion definitions, attribution settings, and segment boundaries before drawing a conclusion. Otherwise, the data join can manufacture a shift that did not occur.

    The table below is a diagnostic starting point, not a set of automatic conclusions. Each pattern should produce a hypothesis and a verification step.

    Observed patternLeading hypothesesNext check or action
    Impressions fall while downstream rates remain steadyDemand, eligibility, budget coverage, or competitive participation changedSplit brand from non-brand, inspect budget and targeting status, then compare market demand and competitor presence
    Impressions hold but click-through rate fallsThe message no longer fits the query, a competitor has a stronger proposition, or the results page changedCompare creative by placement and query theme; inspect competitor messaging and AI Overview presence
    CPC rises while Quality Scores weakenAd or landing-page relevance may be deteriorating; competitive pressure may also have increasedLocate the affected campaigns, ads, queries, and pages before changing bids; add auction and competitor context
    Clicks remain steady but conversion rate fallsTraffic mix, landing-page behavior, offer fit, site function, or conversion measurement changedSegment by search term and landing page, verify tracking, and test the on-site path before buying more traffic
    Conversion rate holds but average order value fallsProduct, offer, customer, or order mix changedFind the affected commercial segment before altering acquisition settings
    Search terms spend without recorded conversionsThe traffic may be irrelevant, but conversion lag, low volume, or measurement gaps may be hiding valueValidate the window, tracking, query intent, and assisted value; add negatives only where exclusion is justified
    Generic market demand exists but non-brand coverage is thinBudget may be concentrated on branded demand while competitors capture discovery trafficRank the gaps by commercial relevance and plausible return, then account for existing organic and AI visibility

    This sequence also prevents channel teams from optimizing against each other. A PPC team can see a missing keyword and increase bids while the SEO team already owns the result. An SEO team can celebrate stable rankings while an AI Overview changes the visible path to the site. Performance intelligence treats those as parts of one demand landscape rather than separate scorecards.

    Make every visualization perform a diagnostic job

    A visual earns its place when it answers a defined question, eliminates an explanation, or supports a decision. A graph that merely makes a metric easier to look at is still reporting.

    Build your diagnostic sequence as a short evidence story:

    1. Establish the baseline. Use a trend view to show when the outcome changed. Split the line by the segment that matters, such as brand versus non-brand, market, campaign, topic, or landing page.
    2. Expose the mechanism. Decompose the movement into impressions, click-through rate, CPC, conversion rate, and average order value. Show which component moved first and where the change is concentrated.
    3. Test the cause. Add account changes, competitor participation, auction information, campaign launches, promotions, and relevant external events. Use them to compare explanations, not to decorate the timeline.
    4. Mark the intervention. Annotate the date and scope of the bid, budget, creative, targeting, content, landing-page, or measurement change.
    5. Show the resolution. Extend the same view beyond the intervention. State whether the expected signal appeared and whether the business outcome followed.

    This setup-conflict-intervention-resolution structure is useful because one chart rarely provides enough context to explain both a performance change and its cause. The sequence lets each view carry one part of the reasoning.

    Choose the format according to the question:

    • Line chart: Locate when a change began and whether an intervention coincided with recovery. Segment the line rather than relying on an account-wide average.
    • Metric heatmap: Find combinations that behave unexpectedly, such as strong placement paired with weak click-through rate. This is useful for creative triage because the contrast becomes visible immediately.
    • Calendar heatmap: Expose day- or week-level patterns around seasonality, launches, promotions, and operational events. Use it to generate a timing hypothesis, then verify the mechanism in the underlying metrics.
    • Word cloud: Scan dominant query or content themes, overlap, gaps, and possible cannibalization. Frequency is not commercial value, so validate promising themes against conversions, revenue, or another business outcome.
    • Exception table: Hand the team a finite work queue. Include only the affected entity, evidence, recommended action, expected effect, risk, and owner.

    Write chart titles as questions or findings. Traffic Trend forces the reader to interpret the graph. Non-brand traffic fell after eligible impressions declined tells them what to inspect. If the evidence cannot support that stronger title, use the question you are testing: Did competitor participation coincide with the CPC increase?

    Every visual should end with a short decision caption: what changed, the leading explanation, which alternatives were checked, what action is proposed, and what evidence is still missing. If no action is justified, name the next investigation and its owner. Uncertainty is acceptable; an ownerless ambiguity is not.

    Turn the diagnosis into a controlled action queue

    Tangled performance signals pass through a diagnostic prism and become an orderly queue of controlled actions, with one action highlighted.

    The deliverable is not the dashboard. It is a prioritized queue of changes that someone can review, execute, and measure.

    Each queue item should contain:

    • Problem: The business outcome and affected scope.
    • Evidence: The internal metric, account state, market context, and cross-surface coverage supporting the diagnosis.
    • Proposed action: The exact campaign, query set, creative, budget, landing page, or content area to change.
    • Expected signal: The first diagnostic metric that should respond and the business outcome expected to follow.
    • Confidence and gap: How strong the explanation is and what remains unknown.
    • Risk and rollback: What valuable traffic, data, or revenue the change could disrupt and how to reverse it.
    • Ownership: Who approves, who implements, and when the result will be reviewed.

    Prioritize with judgment rather than a single opaque score. Start with financial exposure, confidence in the diagnosis, urgency, reversibility, and learning value. A broken landing page or measurement failure deserves attention before a speculative keyword expansion. A reversible creative test can move ahead with less evidence than a large budget reallocation. A negative-keyword upload needs careful review because an incorrect exclusion can remove useful reach across Search, Shopping, or Performance Max.

    A practical order of work is to stop compounding loss, repair leading indicators, reallocate proven resources, and then test growth gaps. That usually means checking broken or outdated pages, tracking failures, and clearly irrelevant spend first; then addressing weak relevance or creative; then moving budget toward supported opportunities; and only then expanding into uncovered demand.

    Automation should follow the same progression. Begin with observation, move to evidence-linked recommendations, then generate an editable implementation file, and require approval before changes are applied. Limited automatic execution should come only after you have reliable inputs, explicit guardrails, monitoring, and a tested rollback path.

    Adthena describes a commercial version of this approach that joins advertiser account data with its market view and returns actions such as negative terms, copy changes, and budget moves. Its vendor-provided examples currently produce editable reports or upload-ready files, and the product is identified as Alpha. Treat that as a useful model for workflow design, not independent proof that every generated recommendation is correct.

    Before approving any machine-generated action, confirm that it exposes the evidence it used, the campaigns affected, the expected result, and the reversal method. Also verify account scope, time zone, currency, attribution settings, conversion definitions, and data freshness. A recommendation that cannot show its inputs is not performance intelligence. It is an instruction without an audit trail.

    Keep market context in the same evidentiary role. A competitor change that aligns with your decline is a serious lead, but timing alone does not prove the competitor caused it. Compare affected and unaffected segments, inspect the internal funnel, and use a reversible intervention where possible. The goal is not a confident story. It is a decision that can survive review.

    Key takeaways

    • Start with a pending decision, not a collection of metrics.
    • Trace the shift from business outcome to funnel mechanism, internal account state, market context, and cross-surface visibility.
    • Treat charts as diagnostic steps: establish the baseline, expose the mechanism, test causes, mark the intervention, and verify the result.
    • Turn every supported finding into an owned action with an expected signal, risk, rollback method, and review point.
    • Use paid, organic, and AI visibility together when evaluating gaps so one channel does not buy coverage another already provides.
    • Keep automated recommendations editable and auditable until their inputs, guardrails, and rollback process have earned greater authority.

    At your next performance review, choose one material shift and run it through the five evidence layers. Publish only the top supported action, its risk, and the signal you will remeasure. If the meeting ends with an observation but no decision or owned evidence gap, you still have a report – not performance intelligence.

    References


  • How to Use AI Dubbing for Localized Google Ads Videos

    How to Use AI Dubbing for Localized Google Ads Videos

    You have a video ad that already works, and the next market looks promising. The tempting move is to dub the audio, duplicate the campaign, and switch it on. That is also how you end up with a polished local voice describing an offer, screen, or landing page that still feels foreign.

    Google Ads is rolling out Video Ads Dubbing in Asset Studio for 33 languages and locales. It can remove a large production barrier, but it only solves the spoken-audio layer. You still need to localize the promise around that voice, verify what the model produced, and test whether the complete journey works in the market.

    Treat AI dubbing as a production shortcut, not complete localization

    A laptop video ad is surrounded by separate layers for dubbed audio, localized visuals, a mobile page, and checkout elements.

    Dubbing changes what the audience hears. Localization changes whether the ad makes sense to that audience. Those jobs overlap, but they are not interchangeable.

    Localization layerWhat AI dubbing can handleWhat you still need to check
    Spoken messageTranslate the dialogue and generate localized speechMeaning, pronunciation, tone, pacing, emphasis, and call to action
    Visible creativeDo not assume dubbing changes itOn-screen copy, captions, product screens, prices, dates, and disclaimers
    Offer and destinationOutside the dubbing taskLanding-page language, offer availability, form fields, support information, and confirmation messages
    Market contextCannot approve commercial fit on its ownLocal expectations, brand terminology, audience relevance, and claim compliance

    This distinction should shape your budget. AI dubbing may reduce the cost of producing a usable first version, but it does not eliminate creative editing, market review, or campaign validation. If your video contains substantial on-screen copy, the audio may be the easy part.

    Access also needs to be confirmed before you plan a rollout. The feature has been free for select users, with limited availability. Check the Asset Studio options in the account that will actually run the ads. Translation, voice, and version controls may also vary as the product develops, so treat the controls visible in your account as authoritative for your workflow.

    Choose source ads and markets with a readiness scorecard

    The fastest way to waste the production savings is to dub every existing video at once. Start with an ad-market pair that can answer a useful business question.

    Score each candidate against these criteria:

    • The source ad has produced a meaningful downstream result, not merely views or clicks.
    • The spoken explanation carries an important part of the value proposition, so dubbing adds more than cosmetic polish.
    • The product, offer, and destination page are available to the intended audience.
    • The visible scenes, gestures, examples, and on-screen claims remain understandable in that market.
    • A fluent market reviewer is available to evaluate both meaning and delivery.
    • Any price, eligibility condition, guarantee, or regulated claim has an accountable owner who can approve the localized wording.

    Treat the landing page and the fluent reviewer as hard gates. If either is missing, you do not yet have a launchable localization. You have an audio file.

    Plan by market and locale, not by language alone. A shared language does not guarantee a shared offer, vocabulary, pronunciation, or destination experience. Your working sheet should identify the market, intended locale, campaign, source-video version, landing-page URL, offer owner, language reviewer, approval status, and date of the last review. That simple structure prevents a later source edit from leaving several dubbed versions silently out of date.

    Prepare a localization brief before generating anything. Include the approved source transcript, the intended meaning of each line, brand and product names that must not be translated, required pronunciations, the exact call to action, and wording that must not be introduced. If a sentence depends on a visual action, note that timing relationship explicitly.

    A clean brief does more than help the reviewer. It gives you a stable reference when the generated speech sounds plausible but changes the commercial meaning. Fluency is not proof of accuracy.

    Run every dubbed asset through a four-pass review

    Four specialists review a dubbed video for language accuracy, audio quality, cultural fit, and the final mobile experience.

    Do not approve a localized video from an English back-translation or transcript alone. The final artifact is audiovisual, so the review must be audiovisual too.

    1. Review meaning. Compare the dubbed dialogue with the approved intent line by line. Check product names, quantities, negation, conditions, calls to action, and the strength of every claim. A translation can be linguistically correct while making a promise broader or narrower than the original.
    2. Review the voice. Listen without reading the transcript. Check pronunciation, natural stress, emotional register, pace, abrupt pauses, and clipped endings. The voice should fit the scene and brand; it does not need to imitate the original speaker.
    3. Review the visual relationship. Watch the complete video with sound. Confirm that spoken references still line up with demonstrations, product screens, gestures, captions, and end cards. Flag any line that finishes too late for the scene or contradicts visible copy.
    4. Review the destination journey. Click through exactly as the audience will. The landing page should continue in the expected language, present the same offer, repeat the same qualification conditions, and use a call to action consistent with the ad. Complete the form, purchase path, or other primary action far enough to catch language reversions and conflicting details.

    Back-translation can help expose meaning drift, but it cannot tell you whether the performance sounds awkward, patronizing, overly formal, or unintentionally comic. That judgment belongs to someone who understands how the target audience actually speaks.

    Separate language approval from commercial approval. A fluent reviewer can confirm that a sentence sounds natural. The offer owner must confirm that it is accurate. If the ad makes regulated, contractual, financial, or health-related claims, send the localized wording through the appropriate compliance review before publishing. AI-generated language does not transfer responsibility for the claim to the tool.

    Record approvals against a specific source-video version. When the source script, offer, disclaimer, or destination changes, reopen every affected localization. Otherwise, a small edit to the original can create a portfolio of obsolete ads that still look approved.

    Test the localized message, not just the synthetic voice

    Your experiment should answer whether the localized ad creates better business results for that market. It should not merely ask whether the generated voice sounds convincing.

    Choose the control that matches the decision. If you want to know whether dubbing beats your current approach, compare it with the existing asset shown to a comparable audience. If you want to evaluate AI production against a locally produced version, keep the offer, landing page, audience, and campaign objective aligned as closely as the setup permits. Do not compare raw results across countries and attribute every difference to dubbing; market demand, auctions, targeting, and offers can all differ.

    Use a naming convention that exposes what changed. A practical asset label includes the market, locale, source-video identifier, localization method, and version. Keep dubbed assets separate in reporting rather than combining them under a generic localized-video label.

    Read performance as a funnel:

    • Delivery tells you whether the asset entered the intended auctions and spent enough to be evaluated.
    • Available viewing and engagement metrics tell you whether the opening and delivery retained attention.
    • Click-through rate tells you whether the ad generated a response, not whether it generated a good customer.
    • Landing-page conversion rate helps expose a mismatch between the localized promise and the destination.
    • Cost per qualified conversion, revenue, or another downstream business outcome tells you whether the localization is commercially useful.

    When click-through rate rises but conversion quality falls, inspect the translated promise, call to action, audience expectations, and landing-page continuity before declaring a win. When viewing weakens but people who click still convert, inspect the voice, opening, pacing, and first visual-audio handoff. When both creative versions change similarly, check campaign conditions before blaming or crediting the dub.

    Google promotional material has highlighted examples of an 86% increase in click-through rate and a 75% reduction in cost per click. Those are Google-provided examples, not expected results or guarantees. Do not use them as your forecast, target, or stopping rule. Your own undubbed or previously localized performance is the relevant baseline.

    Scale only after you know why a version worked. Lock the approved transcript, glossary, voice choice, destination, and source-video version. Then expand in reviewable waves, retaining separate reporting for each market. This keeps a successful test from becoming an uncontrolled batch of superficially similar assets.

    Key takeaways

    • Google Ads Video Ads Dubbing can accelerate spoken-language production across supported languages and locales, but availability remains limited.
    • A dubbed voice is only one localization layer; visible copy, offers, landing pages, and market context still need separate work.
    • Do not launch without a fluent market reviewer and a destination experience that continues the localized promise.
    • Review meaning, voice, visual timing, and the full conversion journey before approving an asset.
    • Measure downstream business outcomes against a relevant control rather than treating higher click-through rate as proof of success.
    • Keep every localized asset tied to a specific source version so later edits trigger a new review.

    Start with one proven source ad and one market where the destination and reviewer are already in place. Build the brief before opening Asset Studio, run the finished video through the complete review, and launch it as a controlled test. The real advantage is not producing dozens of voices at once. It is learning which localized message deserves to be scaled before production complexity returns.

    References


  • Competitive Intelligence for PPC: A Decision-First Playbook

    Competitive Intelligence for PPC: A Decision-First Playbook

    You have a competitor spreadsheet full of keywords, screenshots and offers. The harder question is what any of it should change. Copying a rival’s message can make your ads less distinctive, while chasing its apparent spend can move money into traffic that does not fit your economics.

    Useful competitive intelligence narrows a decision. It shows you which customer concern may be underserved, whether you can credibly address it and how to test that advantage without confusing competitor activity with proof of profitability.

    Start with the PPC decision, not the competitor

    Before collecting more data, write down the decision in front of you. Are you deciding whether to raise a budget, change an ad promise, rebuild a landing page, enter a query category or defend a profitable campaign? Each decision requires different evidence.

    A budget decision needs your marginal acquisition economics. A messaging decision needs evidence of an unmet customer expectation and proof that your business can meet it. A landing-page decision needs a visible break between the ad promise and the information a visitor finds after clicking. Without that distinction, a competitor audit becomes an attractive archive with no operating value.

    Set your internal guardrails before looking outward. Record the acceptable acquisition cost or return target, the conversion that actually matters, your capacity to serve additional demand and the business objective of the campaign. Base a break-even acquisition cost on contribution rather than top-line revenue. If customer lifetime value affects the calculation, use retention and margin evidence you can defend rather than an optimistic projection.

    This step matters because businesses that appear similar can have very different margins, average order values, conversion rates, customer lifetime values and growth priorities. A competitor can rationally spend more than you, or less than you, without either account being mismanaged. Even Google’s peer comparisons cannot see enough of those differences to set your budget for you. Industry and advertised location help define a peer group, but they do not make the underlying businesses economically equivalent.

    Use a short decision brief for every competitive-intelligence task:

    1. Decision: State the one campaign choice the work must inform.
    2. Scope: Name the offer, search intent, audience and market involved.
    3. Success measure: Choose the closest reliable business outcome, such as qualified leads, booked work or completed sales.
    4. Guardrails: Record the limits on cost, lead quality, margin and operating capacity.
    5. Possible actions: Limit the outcome to test, investigate, leave unchanged or stop.

    If a finding cannot affect one of those actions, it may be interesting, but it is not yet actionable intelligence.

    Build an evidence stack instead of a swipe file

    Layered translucent evidence cards converge on one highlighted token beside a blurred pile of disconnected screenshots.

    No single competitive signal answers the whole question. An ad shows what a competitor chose to say at one captured moment. A landing page shows how that promise was supported. Reviews expose recurring expectations and disappointments. Your own campaign and commercial data determine whether an opportunity is worth pursuing.

    EvidenceWhat it can tell youWhat it cannot establishUseful decision
    Competitor adThe promise, framing and call to action visible for a particular query at capture timeHow often the ad runs, whether it converts or whether it is profitableWhich message deserves closer inspection
    Competitor landing pageHow the promise is explained, proven and connected to the conversion pathThe page’s conversion rate, lead quality or commercial returnWhich uncertainty your own page may need to resolve
    Low-rated customer reviewsRepeated frustrations, failed expectations and language customers useThe prevalence of a problem across the whole customer baseWhich customer outcome may be underserved
    Your reviews and operating recordsStrengths customers recognize and promises your team can consistently deliverWhether featuring a strength in an ad will improve performanceWhich competitive message is eligible for testing
    Google Ads peer benchmarkHow weekly spend and clicks compare with a platform-defined peer groupPeer profitability, margins, conversion quality or your optimal budgetWhich difference deserves diagnosis

    Capture observations in a consistent worksheet. For an ad or page, include the date, query theme, market, visible promise, proof offered, call to action and continuity between the ad and destination. For a review theme, include the complaint, desired outcome, frequency in your sample, whether it appears across competitors and whether your business has verified evidence of doing better.

    Keep three columns separate: observation, interpretation and proposed test. A statement such as a competitor emphasizes rapid service is an observation. Customers may value time certainty is an interpretation. Showing a verified response commitment will improve qualified conversion is a hypothesis. Blending those three statements makes a plausible idea look like a fact.

    Weight competitors by relevance. A direct alternative serving the same intent, geography and buyer deserves more attention than a famous brand with a different offer or economic model. Preserve the capture date as well. Ads, pages and offers change, so an undated screenshot quickly becomes unreliable.

    Mine negative reviews for unmet expectations

    Keywords show what people request. Negative and mixed reviews often show what they feared, expected or regretted after choosing a provider. That makes them especially useful for finding a message competitors cannot easily copy unless their operations support it.

    Start with roughly 30 to 50 negative or mixed reviews from two or three direct competitors, concentrating on one-, two- and three-star feedback. Use relevant public review platforms for the market. Remove obvious duplicates, preserve enough context to understand each complaint and do not treat a complaint about one location or service as evidence about an entire brand.

    AI is useful here as a clustering assistant. Give it the raw review text and ask it to group recurring complaints, count mentions, calculate each theme’s share of the collected sample, paraphrase a representative example and identify the outcome the customer appeared to want. Require it to flag ambiguous reviews and avoid adding facts that are not in the text.

    Keep an important limitation attached to the output: the percentage describes your selected review sample, not the market. Low-rated reviewers are self-selected, competitor review volumes differ and platform audiences are not interchangeable. Use the count to prioritize investigation, not to announce that a given percentage of all customers has the problem.

    Translate complaints into desired outcomes before writing copy:

    • Unexpected charges point toward a need for price certainty and a clear approval process.
    • Slow replies point toward a need for acknowledgement and time certainty.
    • Poor communication points toward a need to understand status and next steps.
    • A complicated booking process points toward a need for lower effort and clearer instructions.
    • Limited availability points toward a need to know when service can actually be provided.

    A repeated theme across several direct competitors is more useful than an isolated complaint. It may identify a category-level expectation that is not being met consistently. It still does not prove that your company meets it.

    Now compare those themes with your own reviews and operating evidence. Ask AI to identify strengths customers repeatedly praise in your reviews when competitors receive complaints about the same issue. Then verify the result with the people responsible for delivery. Review language can identify a candidate advantage; service records, policies and operational owners determine whether you are entitled to advertise it.

    Create a claim ledger before any candidate promise enters an ad. For each claim, record the exact wording, responsible owner, supporting evidence, conditions or exclusions, landing-page proof and the action to take if performance slips. A response-time promise, for example, needs a defined starting event, covered hours and a reliable measurement method. A fixed-price promise needs a documented pricing process and clear boundaries.

    Do not turn a rival’s review problem into an accusation. State the positive outcome your business can prove. Customers care about avoiding surprise costs; they do not need an ad that says another company hides fees. This keeps the message focused on the buyer and prevents an unverified competitor claim from becoming the center of your campaign.

    Turn a validated gap into one matched PPC test

    Two matched campaign pathways use equal budget tokens and funnels, with one colored message tile distinguishing the test version.

    The unit of action is not a clever headline. It is a matched chain from customer concern to operational proof:

    1. Signal: A concern repeats in relevant competitor reviews or appears unresolved in visible competitor messaging.
    2. Need: You translate the complaint into the outcome the searcher wants.
    3. Validated strength: Your business can deliver and document that outcome consistently.
    4. Ad promise: The message makes the strength concrete without overstating it.
    5. Landing-page proof: The destination explains how the promise works and what happens next.
    6. Business measure: The test is judged by qualified conversion or a deeper outcome, with cost and quality guardrails.

    The following examples show the translation. They are candidate directions, not claims you can adopt without verification.

    Complaint themeDesired outcomeCandidate headlineLanding-page proof
    Unexpected costsPrice certaintyPrice Set Before WorkExplain when the quote is issued, what it includes and how changes are approved
    Slow responseTime certaintyResponse Time Made ClearState the verified response process, covered hours and next contact
    Poor communicationProcess visibilityKnow What Happens NextShow the stages after submission and how status updates are delivered
    Complicated bookingLow-friction actionSimple Online BookingShow the actual booking steps, required information and confirmation process

    Each sample headline stays within the 30-character limit used for Responsive Search Ad headlines. Character compliance is only the mechanical requirement. A useful asset set also needs query relevance, the verified competitive message and a clear action or form of certainty. Filling every headline slot with slight keyword variations wastes the opportunity to answer a real concern.

    The landing page must finish the thought. If an ad promises pricing clarity, explain the pricing and approval process near the relevant conversion action. If it promises a response commitment, define when the clock starts and what the visitor will receive. If the value is better communication, show the next steps after form submission. A claim that disappears after the click creates a new uncertainty at the moment the visitor is deciding whether to trust you.

    Write a test card before launch. Include the audience and intent, hypothesis, isolated change, operational evidence, destination-page change, primary business outcome, quality guardrails and stopping rule. Keep the comparison as controlled as the account allows. Do not compare click-through rates from campaigns with different query mixes and call the result proof of a better message.

    Choose the closest dependable downstream measure. Click-through rate can show that wording attracted attention, but a complaint-based message may also attract people who are unusually sensitive to price, urgency or service conditions. Watch qualified conversion, sales acceptance, cancellations, refunds or contribution where those signals are available. A test that wins clicks while reducing lead quality has not established a competitive advantage.

    Use peer benchmarks as a question, never a budget target

    Google Ads may display a Spend Benchmarks report in the account Overview. It compares weekly spend and clicks with a peer group informed by industry and where the advertiser runs ads. That can add useful context, but context is the correct limit of the feature.

    Being below the peer spend does not establish underinvestment. Being above it does not establish waste. A lower-spend account may have a narrower market, stricter profit requirements, limited operating capacity or a different growth objective. A higher-click account may be buying cheaper traffic, not better customers. Neither comparison reveals conversion quality or incremental profit.

    Treat an unexpected benchmark as a diagnostic prompt:

    • Is the campaign currently acquiring the right conversion at an acceptable marginal cost?
    • Would additional spend reach more of the same valuable demand, or force the account into weaker traffic?
    • Can sales and operations serve more volume without slower response or lower quality?
    • Does the budget difference reflect a deliberate scope choice, such as a narrower offer or market?
    • Would the additional spend advance the current business objective rather than merely increase clicks?

    Pay particular attention to marginal returns. An account’s average acquisition cost describes the spend already deployed; it does not guarantee that the next block of budget will perform at that average. Increase spend only when your own demand, capacity and profit evidence supports the next increment.

    The benchmark may also appear beside recommendations to spend more for additional results. Keep those two messages separate. A comparison can reveal a difference. It cannot decide whether closing that difference is economically sensible for your business.

    Key takeaways

    • Begin with a defined PPC decision, success measure and economic guardrails.
    • Separate observations from interpretations and testable hypotheses.
    • Use competitor reviews to identify desired customer outcomes, not to write attacks on competitors.
    • Advertise a market gap only after your operations can prove the corresponding promise.
    • Carry the same promise from the ad into the landing page and service process.
    • Use peer spending as context for investigation, not as a target or permission to raise the budget.

    Choose the next material campaign decision and create one evidence row for each part of it: a visible competitor message, a recurring customer concern and a verified strength inside your business. If those signals align, build one matched ad-and-page test. If they do not, leave the budget and promise unchanged. Declining to act on weak evidence is part of good competitive intelligence.

    References


  • Chrome Ad Metrics: How to Audit an Ad-Heavy Website

    Chrome Ad Metrics: How to Audit an Ad-Heavy Website

    If increasing ad revenue has made your pages feel crowded or slow, you no longer have to settle the argument with screenshots and opinions. Chrome can now expose four separate dimensions of ad load through real-user data: how many ads people see, how much space those ads occupy, how many bytes they consume, and how much processing time they require.

    The useful move is not to chase the lowest possible number. It is to find the page patterns where advertising consumes more attention or resources than the commercial return justifies, then reduce the specific cost without weakening the rest of the business.

    The four metrics reveal different kinds of ad load

    Chrome has added four experimental advertising metrics to the Chrome User Experience Report, commonly called CrUX. Treat them as four diagnostic signals, not as interchangeable measures of whether a page has too much advertising.

    MetricWhat Chrome measuresWhat it helps you notice
    Ad CountThe average number of ads visible in the viewportHow many detected ads compete for the user’s visible attention at the same time
    Ad DensityThe average percentage of the viewport occupied by adsHow much of the visible screen advertising takes over, regardless of the number of placements
    Ad Weight – NetworkThe bytes consumed by advertisingThe data cost of the detected ad experience
    Ad Weight – CPUThe processing time consumed by ads, measured in millisecondsThe execution cost imposed by ad-related resources and scripts

    The distinction matters because a single large placement can create high density without a high count. A collection of small placements can raise count while occupying less space. A visually restrained layout can still transfer substantial data or consume considerable processing time.

    Read the metrics in combination:

    • Count and density rise together: Start with the layout. Too many placements may be visible concurrently, and they collectively occupy more of the screen.
    • Density rises while count stays near your cleaner-page baseline: Investigate placement size and persistence before removing every slot. One dominant unit may be the main difference.
    • Network weight rises while count and density remain stable: The visible layout is not telling the whole story. Inspect the advertising payload and repeated resource requests.
    • CPU weight rises by itself: Concentrate on execution. Reducing visible ad space will not necessarily address script-related processing cost.
    • The four signals stay near your baseline but commercial results remain weak: Do not assume ad load is the cause. Creative relevance, audience fit, placement quality, or another factor may deserve attention first.

    This gives you a better decision model than a blanket instruction to run fewer ads. You can identify whether the problem is competition for space, data transfer, processing, or a combination of them.

    Understand what Chrome is actually observing

    Four floating webpage layers depict visible ad placements, their occupied area, incoming data, and processor activity above a computer monitor.

    Your ad server, content management system, and Chrome do not necessarily count the same thing. Your systems know which slots, campaigns, or line items you configured. Chrome detects advertising from the browser side.

    Chrome uses network-level filtering and script-execution analysis to identify ads. It can classify a URL as advertising when that URL matches its ad filter list. It can also recognize resources or frames created by scripts that have already been identified as ad-related.

    Ad Count should therefore be read as a count of ads Chrome detected in the visible viewport, not as a count of the placements declared in your page template. When an internal slot report and the Chrome metric differ, first check whether the two systems are measuring the same object. Do not label either figure incorrect merely because it does not match the other.

    Timing changes the interpretation too. Chrome samples the visible viewport once per second for Ad Count and Ad Density. Network and CPU usage accumulate through the user’s session. CrUX then reports the results at the 75th percentile.

    • A screenshot is not a session. A page may begin with a restrained layout and become denser as advertising appears or remains visible during use. Inspect the experience over time.
    • An initial transfer is not total network weight. Resources loaded later in a session still contribute to the accumulated advertising cost.
    • A quick lab run is not field data. CrUX reflects real Chrome usage, so device capability, network conditions, page behavior, and actual user journeys can produce a different result from a controlled check.
    • The 75th percentile is not the arithmetic mean. It marks a value at or below which three-quarters of measured experiences fall. The remaining quarter is heavier, so do not describe the number as the experience of an average user.

    That measurement model should shape your quality assurance. Reproduce an ordinary journey rather than loading the page, taking one screenshot, and declaring the layout acceptable. Let advertising appear, scroll through the content, and continue long enough to expose resources that arrive after the first view.

    Build an audit around contrasts, not invented thresholds

    Three similar webpage layouts with different ad patterns are compared on a light table using a magnifying lens and abstract resource signals.

    Chrome has not established a recommended pass or fail threshold for any of the four metrics. They are experimental, and they are not Core Web Vitals. A universal scorecard that labels a page good or bad would therefore create precision that the current program does not provide.

    You can still run a disciplined audit. Use your own comparable page patterns to establish context:

    1. Define comparable groups. Separate page patterns that have materially different jobs or layouts. An article template, a gallery, and a short reference page should not automatically share one baseline.
    2. Record all four ad metrics together. Do not report density without network and CPU weight, or combine the four into an unsupported composite score. Keeping the raw dimensions visible prevents one improvement from hiding a regression elsewhere.
    3. Keep Core Web Vitals in a separate column. The advertising metrics can sit beside established performance reporting, but they should not be relabeled as Core Web Vitals or folded into a made-up Google score.
    4. Find useful contrasts. Compare cleaner and more heavily monetized experiences within a relevant group. Look for the metric that changes most clearly rather than assuming every ad-heavy page has the same defect.
    5. Reproduce the suspected behavior. Review the page across a realistic session, paying attention to what is visible and what continues loading or executing. The goal is to connect a field signal to an observable mechanism.
    6. Change one cost dimension first. Reduce concurrent visible placements for count, occupied screen area for density, advertising payload for network weight, or unnecessary execution for CPU weight. A focused change makes the result easier to interpret.
    7. Judge the tradeoff with business outcomes. Put the ad metrics beside the revenue and campaign measures your team already trusts. Keep changes that improve the experience at an acceptable commercial cost; investigate further when a lower ad metric merely moves the problem elsewhere.
    8. Create internal guardrails only after you have a baseline. Express them as limits for comparable page patterns and document why they exist. Do not present them as official Chrome thresholds.

    A practical internal rule might require a redesigned template not to materially worsen density or CPU weight against the template it replaces while maintaining an acceptable monetization result. Your team still has to define what materially and acceptable mean, but the rule identifies the comparison, the protected outcomes, and the owner of the decision.

    When possible, test changes in isolation. Removing a placement while simultaneously changing the ad vendor, page layout, and loading behavior may improve the numbers, but it will not tell you which intervention mattered. That leaves you unable to repeat the result elsewhere.

    Avoid five costly interpretation errors

    The new metrics are useful precisely because they separate layout pressure from resource pressure. That value disappears when a team compresses them into a simplistic verdict.

    • Do not optimize only for fewer ads. A lower count can coexist with high density, network weight, or CPU weight. Verify which cost actually fell.
    • Do not treat density as a performance metric. Density describes visible space. Network and CPU weight describe resource consumption. One cannot stand in for the others.
    • Do not claim an SEO ranking effect. Nothing in the current rollout establishes these experimental measurements as ranking signals. Track them beside SEO and performance data when useful, but keep the labels honest.
    • Do not promise a media-value or bidding uplift. Better transparency could affect how buyers assess inventory, but Google has not said whether Display & Video 360 is testing these signals for bidding, valuation, or reporting.
    • Do not wait for an official cutoff before measuring. The absence of a universal threshold prevents a pass or fail verdict; it does not prevent you from detecting regressions, comparing relevant experiences, or correcting an obvious outlier.

    Publishers with cleaner experiences may eventually use the metrics to distinguish their inventory. Advertisers and agencies may use them to identify placements where clutter or resource consumption threatens attention and campaign performance. Independent advertising platforms are expected to receive the CrUX data at the same time as Google’s advertising businesses, which makes it sensible to preserve the raw metrics now rather than build a process around a proprietary composite score.

    For buyers, the right first use is comparison and investigation, not automatic exclusion. A high reading identifies a question to ask about the experience. Without an established threshold or evidence connecting that reading to your own campaign outcome, it is not yet a sufficient reason to reject inventory by itself.

    Key takeaways

    • Ad Count measures how many detected ads are visible; Ad Density measures how much of the viewport they occupy.
    • Ad Weight – Network measures advertising bytes, while Ad Weight – CPU measures advertising processing time in milliseconds.
    • Chrome samples the viewport once per second, accumulates network and CPU use through the session, and reports CrUX results at the 75th percentile.
    • The four measurements are experimental, are not Core Web Vitals, and do not have official recommended thresholds.
    • Use the metrics as separate diagnostic signals, compare relevant page patterns, and evaluate every change against both user-experience and commercial outcomes.

    Choose one commercially important page pattern this week and capture all four dimensions before changing it. That baseline will give your ad, performance, analytics, and editorial teams something concrete to improve – and it will keep future decisions grounded if buyers begin using the same signals to value inventory.

    References


  • Facebook Ad Costs in 2026: What Better Clicks Really Mean

    Facebook Ad Costs in 2026: What Better Clicks Really Mean

    If your Facebook dashboard is showing cheaper clicks, the tempting response is to open the budget. The 2026 numbers support cautious optimism: traffic campaigns are attracting more clicks at a lower price, and lead campaigns are also paying less per click. But the metric that determines whether many advertisers can afford to scale—cost per lead—has barely changed.

    That gap is where your decision lives. A cheaper click is useful only when its value survives the rest of the funnel. Before you increase spend, find out whether Facebook has lowered your acquisition cost or merely made the first step less expensive.

    What actually changed in the 2026 Facebook benchmarks

    In 2026, nearly 1,800 Facebook ad campaigns across multiple industries were measured using click-through rate, cost per click, conversion rate and cost per lead. Traffic and lead campaigns both became more efficient at generating clicks, but the improvement was much smaller at the completed-lead stage.

    Campaign objectiveAverage CTRAverage CPCAverage CVRAverage CPL
    Traffic1.93%, up 12.87% year over year$0.60, down 14.29%Not includedNot included
    Leads2.70%, up 4.25% year over year$1.80, down 6.25%8.54%$27.39, down 0.98%

    CTR measures how often an impression becomes a click. CPC measures the amount spent for each click. CVR tracks how often a click becomes a conversion, while CPL divides campaign spend by the number of leads generated.

    For traffic campaigns, the direction is unambiguously favorable at the click stage: CTR increased by 12.87% while CPC fell by 14.29%. Advertisers received stronger engagement and cheaper visits at the same time.

    Lead campaigns tell a more restrained story. Their CPC fell by 6.25%, but CPL declined by only 0.98%. In aggregate, most of the click-cost improvement did not appear as an equivalent reduction in lead cost. That does not prove where the difference was absorbed. It tells you where to investigate: between the click and the completed lead.

    Better bidding and campaign optimization may be contributing to the stronger performance, but these aggregate outcomes do not establish a single cause. Your own campaign history remains the evidence that should determine your next budget move.

    Key takeaways for your next Facebook budget decision

    • Cheaper Facebook traffic is a real top-of-funnel gain, but it is not automatically a lower customer-acquisition cost.
    • Judge traffic and lead campaigns against their intended jobs. A traffic CPC and a lead CPL answer different business questions.
    • If CTR rises and CPC falls while CPL stays flat, examine the audience-to-offer match, landing experience and lead process before buying more clicks.
    • Use the $27.39 overall CPL as context, not as a universal target. Industry averages range from $12.30 to $61.56 among the reported verticals.
    • Do not move money from search to Facebook based on CPC alone. The channels often reach people at different stages of intent.

    Follow cheaper clicks through the whole lead funnel

    A transparent three-stage funnel carries many blue cursor symbols through visitor and lead stages, with some markers dropping out along the way.

    One metric cannot tell you whether a campaign is improving. CPC is an input cost. CPL is an acquisition outcome. Lead quality and eventual revenue sit farther downstream. If you stop at the cheapest visible metric, you can scale a campaign that looks efficient while its business value deteriorates.

    Use the same reporting period, spend base and lead definition for each stage of your account-level calculation:

    • CTR = clicks divided by impressions.
    • CPC = spend divided by clicks.
    • Click-to-lead CVR = leads divided by clicks.
    • CPL = spend divided by leads.
    • Qualified-lead rate = leads that meet your qualification criteria divided by total leads.
    • Customer conversion rate = acquired customers divided by the relevant lead group.

    The last two measures are specific to your business, which makes them more valuable than a broad platform average. A low CPL can be a false economy if the form is attracting people who cannot buy, are outside your service area or do not match the offer. Conversely, a CPC increase can be acceptable when the resulting visitors convert into qualified leads at a higher rate.

    Pattern in your accountWhat it can meanWhat to inspect next
    CTR up, CPC down, CVR stable or up, CPL downThe media-efficiency gain is reaching lead acquisitionLead quality and performance as spend increases
    CTR up, CPC down, CVR down, CPL flat or upAttention is cheaper, but more clicks are failing to become leadsAudience intent, message continuity, landing page, form and offer
    CPC up, CPL downMore expensive clicks may be converting efficientlyDo not cut the campaign on CPC alone; verify lead quality
    CPL down, qualified-lead rate downThe apparent acquisition gain may come from lower-value leadsQualification rules, geographic fit, duplicate or invalid leads and sales outcomes
    Traffic CPC down, but valuable site actions unchangedThe campaign is buying visits without improving useful behaviorPost-click intent, page relevance and the action chosen as the next success signal

    Read the sequence from left to right. If CTR improves, the ad is earning more clicks per impression. If CPC also falls, those clicks are becoming less expensive. If CVR then falls, however, the added traffic may not match the promise, destination or conversion request. That is a handoff problem, not a reason to celebrate the click metric.

    For a lead campaign, compare the language and expectation across the ad, landing page or instant form, and follow-up. The person who clicks should encounter the same offer, audience fit and next step throughout. If the ad attracts broad curiosity but the form asks for a serious commitment, Facebook can deliver an attractive CTR without delivering an attractive CPL.

    Industry averages can reverse the headline

    The overall decline in Facebook CPC hides substantial differences between industries. For traffic campaigns, only two reported verticals paid more per click year over year: Shopping, Collectibles and Gifts rose 73.53%, while Sports and Recreation rose 43.90%. At the other end, Real Estate fell 39.56%, Restaurants and Food fell 37.50%, and Industrial and Commercial fell 37.21%.

    Lead-campaign CPC also fell in most verticals. Automotive – For Sale dropped 44.17%, Dentists and Dental Services dropped 41.72%, and Health and Fitness dropped 30.30%. Education and Instruction, up 4.24%, and Sports and Recreation, up 0.93%, were the only reported industries with higher lead-campaign CPC.

    Those click-cost movements still do not reveal what a lead should cost in your market. Average CPL varied sharply:

    IndustryAverage CPLPosition among reported industries
    Career and Employment$12.30Lowest
    Real Estate$13.74Lower end
    Arts and Entertainment$14.59Lower end
    Home and Home Improvement$42.95Higher end
    Beauty and Personal Care$50.91Higher end
    Dentists and Dental Services$61.56Highest

    Dentistry exposes the danger of treating click cost as the result. The vertical recorded a 41.72% reduction in lead-campaign CPC while still carrying the highest reported CPL at $61.56. Access to attention became much cheaper, yet a completed lead remained expensive relative to the other listed industries.

    Use benchmarks in the right order. Start with your own comparable historical period, because it reflects your offer, geography, audience and lead definition. Next, compare campaigns and segments inside the account. Only then use the industry figure to judge whether your experience is directionally unusual. The overall $27.39 average should not become a target imposed on a dentist, recruiter or real estate advertiser as though their economics were interchangeable.

    Turn the trend into a controlled budget decision

    A branching pipeline sends blue traffic particles through two small test chambers while most gold budget tokens remain behind a partially closed gate.

    The 2026 trend gives you a reason to test for additional efficiency, not a reason to approve an unrestricted increase. A broad budget shift can turn an attractive average into expensive marginal volume. Make the decision with a sequence you can audit.

    1. Name the outcome before reading the dashboard. For a traffic campaign, define the valuable behavior expected after the visit. For a lead campaign, define both the counted lead and the criteria for a qualified one.
    2. Build a comparable baseline. Keep the reporting period, conversion event and lead definition consistent. If any of those changed, label the break rather than presenting the before-and-after figures as a clean trend.
    3. Separate campaigns by objective. Do not blend a $0.60 traffic CPC with a $1.80 lead CPC and call the result an account benchmark. The systems are optimizing toward different actions.
    4. Locate the first metric that failed to improve. Read CTR, CPC, CVR and CPL in order, then continue into qualified-lead rate and customer outcomes. The first break identifies the part of the funnel that needs attention.
    5. Test a limited, reversible budget increase in the segments where lower CPL and acceptable lead quality appear together. Keep unrelated variables stable enough to distinguish a budget effect from a simultaneous creative, audience or offer change.
    6. Judge marginal performance, not only the old average. If the extra spend raises CPL or reduces qualification quality beyond what your unit economics support, stop expanding that segment even if its blended CPC still looks inexpensive.
    7. Compare channels by their role in the buyer journey. Within the benchmark context, Google Ads CPC is more than twice Meta’s average CPC, but Google Search typically captures stronger purchase intent. Paying less for a Facebook click does not make it a direct substitute for a high-intent search click.

    If your primary goal is traffic, the lower 2026 CPC gives you room to test whether additional visits produce meaningful on-site behavior. If your goal is leads, the nearly flat CPL calls for more discipline: isolate where cheaper clicks stop translating into cheaper acquisition before you scale.

    Start with the campaigns where CTR improved and CPC declined but CPL or lead quality did not. Put those campaigns at the top of your diagnostic queue. Repair the audience-to-conversion handoff first, then increase spend only where the efficiency survives into qualified outcomes. Facebook may be offering cheaper access to attention in 2026; your account still has to prove that the savings reach the business.

    References


  • Human Judgment Is the Control Layer for Automated Ads

    Human Judgment Is the Control Layer for Automated Ads

    You have an hour-of-day row with spend and no conversions, an automated campaign that feels opaque, and someone asking you to "fix the waste." Excluding the hour looks decisive. It is also exactly where human judgment matters: not because a person can outbid a system one auction at a time, but because only a person can decide whether that row is mature, meaningful, and worth turning into an eligibility rule.

    Your job in automated advertising is no longer to touch every lever. It is to define the right outcome, protect the quality of the inputs, challenge weak evidence, and own changes that remove opportunities. The practical goal is not more manual control. It is better control over what the automation is allowed to decide.

    Put human judgment at the decision boundary

    Automated systems are strongest when they make frequent decisions inside a clearly defined objective. A bidding system can evaluate an auction, combine contextual signals, and adjust its bid faster than a campaign manager could. It cannot decide whether the objective itself represents a profitable customer, whether an overnight lead will receive an acceptable response, or whether the business should trade margin for growth.

    That distinction gives you a usable division of responsibility:

    DecisionWhat automation should doWhat a person must own
    Auction executionEvaluate eligible auctions and adjust bids within the chosen strategy.Choose the business objective, budget, constraints, and acceptable tradeoffs.
    Data preparationGroup records, calculate fields, identify anomalies, and assemble recurring reports.Verify definitions, attribution, data maturity, and whether the records represent real business outcomes.
    Campaign eligibilityRespect targeting, schedules, exclusions, and other account settings.Decide which opportunities the campaign should never be allowed to enter.
    Performance diagnosisSurface patterns and produce candidate explanations.Determine which explanation is credible and what evidence would disprove it.
    Final approvalPrepare a recommendation or execute an approved, bounded workflow.Accept accountability for the consequences and authorize the change.

    A simple boundary works well: let automation make high-frequency, reversible choices within an approved objective. Require human review when a decision changes the objective, conversion definition, customer promise, account eligibility, or exposure to wasted spend.

    Before approving an automated recommendation, ask four questions:

    • What outcome is the system actually optimizing?
    • Which business facts cannot be seen in the platform data?
    • Does this recommendation tune execution, or does it remove an audience, location, device, query, or time period from consideration?
    • Who will decide whether the result was acceptable after conversion lag and downstream sales are visible?

    If nobody can answer those questions, the problem is not insufficient automation. It is an undefined decision boundary.

    An ad schedule is an eligibility rule, not a cleanup tool

    Hour-of-day reports invite a common mistake. You see a weak average, label the period inefficient, and remove it. That reasoning treats every auction in an hour as if it had the same probability and value.

    Google Ads Smart Bidding works at a different level. Target CPA, Target ROAS, Maximize Conversions, and Maximize Conversion Value use auction-time bidding, with time of day and day of week among the contextual signals that can inform an individual bid. Device, location, and audience characteristics can also change the assessment. The system is not deciding that an entire hour is universally good or bad. It is evaluating the eligible auctions that occur during that hour.

    This makes the effect of scheduling easy to misread. Manual ad-schedule bid adjustments are not used by Smart Bidding, but the schedule itself is respected. Removing Tuesday morning does not tell the bidding system to be more selective on Tuesday morning. It makes every Tuesday-morning auction ineligible, including any valuable ones the hourly average concealed.

    A row with four clicks and no conversions proves only that those four recorded clicks did not yet show a conversion. It does not establish that the hour is intrinsically unprofitable. Nor does it estimate what would have happened in future auctions if the campaign had remained eligible.

    Scheduling can still be the correct decision when the restriction represents a real business constraint:

    • Home services and call-driven lead generation: Restricting delivery may be justified if an overnight inquiry cannot be answered promptly and the delayed response materially reduces its value. If those leads perform well when contacted later, the schedule would remove opportunity without fixing a business problem.
    • Appointment-based businesses: Capacity can be the binding constraint. Acquiring more demand may stop being useful once the available appointments are full.
    • Ecommerce: Customers can buy outside office hours. Operating hours alone therefore provide little basis for an exclusion; look for persistent differences in conversion value and profitability.
    • Restaurants: Opening hours, ordering hours, and reservation-search hours are not the same. Someone can make a valuable reservation before the doors open or after service ends.
    • B2B: Research does not stop at the office door. A nighttime search can produce a qualified inquiry that the sales team handles the following day.
    • News and publishing: Breaking events, elections, sports, and entertainment can move demand into hours that looked weak historically. A rigid schedule cannot anticipate every shift in attention.

    The rule is straightforward: use a schedule when you intend to prohibit participation, not merely because you want the bidding system to be cautious. If you would still want the right customer during that period, an absolute exclusion is a blunt response.

    Use a five-part evidence gate before restricting automation

    An analyst examines five visual checkpoints leading to a gated automation system.

    An automated account can generate more segmented data than a person can sensibly act on. There are 168 hours in a week before you add device, location, audience, campaign, or conversion type. Some rows will look unusually strong or weak by chance. Human judgment begins with refusing to confuse a visible pattern with a reliable decision.

    1. Wait for enough observations. Expand the date range until the pattern has had a reasonable chance to repeat. In many accounts, 60 to 90 days is a more useful starting window than a few recent days, but it is not a universal threshold. A high-volume account may mature sooner; a low-volume account or long sales cycle may need more time. The test is repeated evidence, not compliance with an arbitrary number of days.
    2. Let conversions mature. A click can convert hours or days later. Google Ads generally assigns the conversion to the date of the ad interaction, so a recent period may temporarily show its spend before all associated conversions have arrived. Check the account’s typical conversion delay before declaring yesterday evening inefficient. If the outcome data is still arriving, the conclusion is still changing.
    3. Inspect value below the average. Conversion count and average CPA may omit the result that matters. Review conversion value, lead quality, downstream sales, and customer value where those signals are available. A period with fewer conversions may still acquire better customers. Conversely, a superficially efficient period may be producing low-quality actions that never become revenue.
    4. Identify the business mechanism. Ask why the time period would be less valuable. A credible explanation might involve response time, fulfillment, inventory, staffing, or appointment capacity. If you cannot name a mechanism, treat the pattern as a question to investigate rather than a rule to implement. If the mechanism is operational, consider fixing the operation before suppressing demand.
    5. Test the restriction against broader eligibility. When traffic volume supports a meaningful comparison, test the scheduled version against a version that remains eligible for more hours. Use the business KPI that motivated the decision, allow for conversion lag, and change one major eligibility dimension at a time. One documented restaurant test found that unrestricted delivery produced 12% more conversions while reducing CPA by 3%. That is a single account result, not a universal benchmark; its value is showing why the counterfactual must be measured rather than assumed.

    This gate separates two different questions. The report asks, "What performance was recorded during the auctions that occurred?" The decision asks, "Will prohibiting future auctions improve the business result?" You cannot answer the second merely by sorting the first from worst to best.

    Document the decision before launch. Record the proposed restriction, the evidence window, known conversion delay, primary KPI, downstream quality check, operational rationale, test design, owner, and review point. That short record prevents a temporary anomaly from becoming permanent account folklore.

    Build an operating loop that removes labor, not accountability

    Two advertising professionals oversee a circular automated workflow while mechanical arms handle routine tasks.

    There are usually two kinds of automation in the same advertising workflow. The ad platform automates delivery and bidding. Analyst-facing AI can summarize meetings, organize exports, flag anomalies, draft formulas, generate basic scripts, and turn findings into review-ready formats. Both can save time, but neither should silently expand its own authority.

    Use this operating loop for consequential campaign changes:

    1. Frame the decision. Write one sentence naming the action under consideration and the business result it is meant to improve. "Reduce wasted spend" is too vague. "Determine whether overnight eligibility lowers qualified-lead profitability after leads have matured" can be tested.
    2. Assemble the evidence. Let approved tools merge exports, label time periods, calculate recurring fields, and flag unusual movement. AI is well suited to categorizing large datasets and surfacing changes that require investigation. Keep sensitive data inside approved systems and verify calculated fields before relying on them.
    3. Expose what the platform cannot see. Add sales acceptance, revenue, lead disposition, staffing constraints, inventory conditions, and other business context that is absent from the advertising interface. If the optimization signal rewards form submissions while the business needs completed sales, fix or supplement the signal before asking the algorithm to optimize harder.
    4. Generate challenges, not verdicts. Ask AI to find missing information, contradictory evidence, immature periods, unusually small samples, and alternative explanations. Do not ask it to make a final pause-or-expand decision from a summary table. AI can identify where something changed; the causal explanation still needs validation.
    5. Approve a bounded test. A person chooses the hypothesis, success measure, duration appropriate to the conversion cycle, and rollback condition. The system can then execute within those limits. Eligibility changes deserve particular care because the excluded auctions stop producing evidence once they disappear.
    6. Review and record the outcome. Wait for the agreed data to mature, compare the result with the predeclared KPI, check downstream quality, and record what changed. Meeting transcription and task extraction can remove administrative work by capturing decisions, owners, deadlines, and unresolved debates, but the meeting owner should review the output before it becomes the record.

    Prompt design should reinforce that boundary. Instead of asking, "Which hours should we turn off?" ask:

    • List time periods with persistent performance differences and show the observation count, date range, and conversion maturity for each.
    • Separate facts in the export from possible explanations that require validation.
    • Flag periods where conversion count, conversion value, and downstream lead quality point in different directions.
    • Identify which proposed actions tune execution and which actions remove campaign eligibility.
    • Draft a test plan and a list of missing inputs, without making the final approval decision.

    The same principle applies to technical work. AI can draft spreadsheet formulas, SQL, regex, account scripts, or reporting logic. Those outputs are useful because you can test whether they work. Review generated code, run it in a safe and limited context, and verify its output before it can change a production account. Fluent text is not proof of correct logic.

    Measure automation by the labor it removes and the errors it helps catch: rows reviewed, analysis time saved, anomalies surfaced, manual steps eliminated, revision cycles, and error rate. Measure the human control layer by decision quality: valid conversion signals, explicit ownership, mature evidence, reversible tests, and fewer unexplained account restrictions. Faster execution is valuable only when it carries a sound decision forward.

    Key takeaways

    • Let automated bidding make auction-level choices within a business objective that a person has defined and can defend.
    • Treat schedules, exclusions, and targeting limits as eligibility decisions. They remove opportunities rather than instructing Smart Bidding to bid more carefully.
    • Do not act on a weak hourly row until you have enough observations, mature conversions, business-value data, and a plausible mechanism.
    • Test restrictions against broader eligibility when volume permits. Historical averages do not reveal the outcome of auctions you choose not to enter.
    • Use AI to prepare evidence, find gaps, document decisions, and produce testable technical work. Keep strategy, prioritization, approval, and accountability with people.

    At your next account review, take one proposed automation change and label it either an execution aid or an eligibility decision. Automate the labor around the first. Put the second through the evidence gate before approving it. That small distinction is where responsible automated advertising starts.

    References


  • Google AdSense Begin-to-Render: A Publisher Action Plan

    Google AdSense Begin-to-Render: A Publisher Action Plan

    If AdSense revenue helps you judge whether your content strategy is working, February 2027 could produce a misleading signal. Your reported display impressions may fall even when traffic and reader behavior have not materially changed.

    The right response is to establish a clean baseline, mark the measurement break, and compare impressions with traffic, clicks, and earnings before changing your site. That lets you separate a new counting rule from a real monetization or SEO problem.

    Key takeaways

    • Beginning February 17, 2027, an AdSense display impression will be counted after the ad has successfully loaded and started to render, not when it merely starts downloading.
    • Downloads that never reach rendering will disappear from the impression total. An early page exit is one example of how that gap can occur.
    • A lower impression count does not, by itself, prove that traffic, ad demand, viewability, engagement, or revenue declined.
    • Click-through rate and other per-impression ratios may change mechanically because their denominator has changed.
    • Preserve pre-change data now, separate display inventory from inventory already using Begin-to-Render, and evaluate post-change results by page type, device, and placement where your reporting supports those dimensions.

    What Begin-to-Render changes in AdSense

    Three generic browser panels show an empty ad space, the first visible pixels appearing with an indicator light, and the completed ad rendering.

    On February 17, 2027, Google will change the counting trigger for AdSense display impressions. Under the current method, the impression is recorded when an ad starts downloading to the user’s device. Under Begin-to-Render, or BTR, the ad must successfully load and start rendering on that device.

    Measurement pointCurrent display methodBegin-to-Render method
    Counting triggerThe ad starts downloadingThe ad successfully loads and starts rendering
    User leaves after download starts but before renderingThe impression can be countedThe impression is not counted
    Inventory affected by the transitionAdSense display adsDisplay joins the unified BTR approach
    Other inventoryNative, app, and video inventory already uses or complies with Begin-to-Render counting

    The important difference is the interval between download and render. If an ad crosses both points, it qualifies under either method. If it begins downloading but never reaches rendering, it can contribute to the old total but not the new one.

    Begin-to-Render should not be treated as another name for viewability, attention, or engagement. It confirms that rendering began after a successful load. It does not tell you how much of the ad the person saw, how long it remained available, or whether the person interacted with it. Avoid relabeling the new count as a viewable impression in internal reports unless the metric you are using separately establishes viewability.

    The transition also is not a directive to move every placement higher on the page. It is a measurement change. First identify where download-to-render failures actually occur; otherwise, a layout overhaul may damage the reading experience without addressing the cause.

    Why the dashboard can look better and worse at once

    Google has warned that publishers may see a change in total impressions because downloads that never render will no longer count. No universal percentage change has been specified. Your result will depend on how often your display ads currently enter that unfinished state.

    That creates a break in the time series. A chart that places pre-February 17 impressions beside post-February 17 impressions without an annotation makes the two periods look directly comparable when they are not. Treat the date as a measurement boundary in dashboards, forecasts, stakeholder reports, and automated alerts.

    Derived rates require even more care. Click-through rate divides clicks by impressions. If clicks remain unchanged while the newly defined impression total falls, the reported rate rises automatically. That increase does not prove that people became more interested in the ads. Part of it may be denominator removal.

    The same arithmetic applies to any earnings-per-impression calculation. If earnings remain stable while counted impressions decline, earnings per thousand impressions can rise without any improvement in total revenue. If earnings and impressions fall together, the rate may remain similar even though the site earns less. A rate by itself cannot tell you which situation occurred.

    This is why neither conclusion is safe on impression data alone. Fewer impressions do not automatically mean your SEO traffic weakened, and a higher per-impression rate does not automatically mean monetization improved. Keep the numerator and denominator visible: traffic, display impressions, clicks, and earnings should be reviewed as separate values before you interpret their ratios.

    Build a baseline that survives the February change

    The useful work happens before the switch. You need enough context to answer one practical question afterward: did the business change, or did only the definition change?

    1. Map the inventory in scope. Identify the reports and dashboards that contain AdSense display impressions. Keep native, app, and video inventory distinct where possible because those formats already use or comply with BTR counting.
    2. Save a stable pre-change baseline. Export the reports you routinely use before February 17, including their exact date range and filters. Preserve raw impressions, clicks, and earnings rather than saving only calculated rates.
    3. Add independent traffic context. Retain pageviews, landing-page visits, sessions, or the equivalent traffic measures your analytics setup uses. Align site scope and reporting dates so that an AdSense property is not accidentally compared with traffic from a different set of pages.
    4. Record operational changes. Note ad-placement edits, template releases, consent-flow changes, performance work, major campaigns, and content migrations near the transition. Any of these can complicate the comparison even though they are separate from the counting rule.
    5. Choose meaningful cohorts in advance. Where your existing reports support them, prepare comparisons by device, page template, content section, and ad placement. A site-wide total can hide a problem concentrated in one implementation.
    6. Annotate February 17, 2027 everywhere. Put the date in reporting calendars, dashboard notes, forecast assumptions, and recurring stakeholder reports. Future analysts should not have to rediscover why the series changed.

    Four paired calculations are especially helpful: display impressions per pageview, clicks per display impression, earnings per display impression, and earnings per pageview. Use the same definitions and scope on both sides of the change.

    The per-impression measures show what happened inside the newly counted population. The per-pageview measures show whether the economic result changed for the traffic you actually received. If earnings per impression rises while earnings per pageview stays flat, you may be looking mainly at a denominator effect. If earnings per pageview declines as well, there is a business outcome to investigate rather than merely relabel.

    Do not force a comparison between periods with visibly different traffic composition. A major campaign, seasonal event, ranking change, or shift in device mix can move ad behavior independently of BTR. Use comparable traffic cohorts and keep those differences explicit.

    Turn the post-change gap into a defensible decision

    An analyst compares four abstract measurement streams across a divider, with only the impression tiles dropping while traffic, clicks, and earnings remain steady.

    Read the pattern before changing the site

    Start with the shape of the change, not a theory about its cause. The following patterns point to different next steps:

    • Traffic is stable, display impressions fall at the transition, and clicks and earnings are broadly stable: a counting-definition effect is plausible. Document the break before treating it as an optimization problem.
    • Traffic and display impressions decline together: investigate acquisition and audience changes as well as ad measurement. BTR alone cannot establish why fewer people reached the site.
    • Display impressions fall mainly on one template, device group, or placement: inspect that implementation. A concentrated gap deserves more attention than a uniform site-wide adjustment.
    • Click-through rate rises while clicks are flat: treat the increase as denominator-sensitive. Do not claim stronger engagement without additional evidence.
    • Earnings per pageview declines: the economic result changed for the traffic received. Review earnings, traffic mix, placement behavior, and render failures together rather than assuming the counting rule explains the entire loss.

    For an SEO-led publisher, compare organic landing traffic with display impressions separately. Stable organic visits alongside a lower ad-impression total are not evidence of a ranking loss. Falling organic visits and falling impressions, by contrast, require an SEO investigation that is independent of the AdSense definition change.

    Inspect the download-to-render interval

    Once you find a cohort with an unusual gap, test representative pages on the affected device type. Observe whether the ad begins loading, whether the creative starts rendering, and whether navigation or another page event occurs first. Browser developer tools, the visible page state, and the diagnostics already available in your ad implementation can help you distinguish an initiated request from an actual render.

    Treat possible causes as hypotheses. A user may leave before rendering, which is the explicit example behind the change. A slow page, late ad initialization, template-specific integration, consent sequence, or navigation behavior may also deserve inspection when the evidence points there. Do not declare one of these the cause merely because it sounds plausible.

    Change one relevant variable at a time and review the same cohort again. If several layout, performance, consent, and placement changes launch together, you will not know which one affected rendering or revenue.

    Optimize the outcome, not the retired counter

    The old metric gave credit at an earlier technical milestone. Trying to recover every disappearing impression can push you toward the wrong goal. A download that repeatedly begins but never produces a rendered ad is not a number you should preserve merely for continuity.

    Prioritize genuine implementation failures, avoidable delays, and placements that fail to render despite meaningful reader activity. Avoid disruptive layout changes whose only justification is restoring the old impression total. The decision should improve rendered ad delivery, earnings per visit, or the reader experience under the new definition.

    Put February 17, 2027 on your reporting calendar now and preserve the unaggregated values behind your ratios. When the switch arrives, make the first review a measurement audit. Redesign a placement only after the traffic, cohort, and earnings evidence shows that you have a delivery problem rather than a cleaner count.

    References


  • PPC Automation for Better Leads: A Practical Framework

    PPC Automation for Better Leads: A Practical Framework

    Your PPC account can hit its cost-per-lead target and still leave sales with little usable pipeline. When the bidding system is rewarded for a form fill, it will find people who are likely to fill forms. It cannot prefer future customers unless you return that distinction as data.

    The fix does not begin with another bid adjustment or a tighter keyword list. You need to identify the business constraint, choose a conversion event that represents progress toward revenue, and then give automation enough room to find more of that outcome. This framework shows you how to do that without treating every unusual query or expensive lead as a failure.

    Key takeaways

    • Decide whether the immediate constraint is insufficient lead volume or insufficient lead quality. They require different optimization signals and campaign levers.
    • Use the deepest conversion event that occurs often and consistently enough to guide bidding. That may be a qualified lead or opportunity rather than a closed customer.
    • Connect CRM outcomes to your advertising platforms. Form submissions alone do not tell an algorithm which people became valuable.
    • Broad match, automated audiences, and Smart Bidding need reliable conversion data, explicit exclusions, and clear landing pages.
    • Judge performance with cost per qualified lead, cost per opportunity, customer acquisition cost, and revenue. CPL is only an early-funnel diagnostic.

    Pick the business constraint before the campaign metric

    The useful question is not whether you want more leads or better leads. Every business wants both. The question is which constraint is preventing growth right now. Lead quantity and lead quality are different growth objectives with different inputs, not opposing philosophies.

    Business conditionPrimary objectiveFirst PPC leverMain risk
    Sales has unused capacity and too few leadsVolumeExpand eligible demand and remove unnecessary conversion frictionCheap form fills can crowd out valuable prospects if every submission is treated equally
    Sales is overwhelmed by poor-fit inquiriesQualityOptimize toward a qualified lead or opportunityLead count may fall and CPL may rise even while pipeline economics improve
    A new market or offer has little outcome dataVolume and learningBroaden reach while building consistent CRM classificationsA sparse customer signal may give automation too little information
    Lead volume is healthy but revenue is weakQuality and valueReturn deeper outcomes and, where defensible, their business valuesThe problem may sit in qualification, the offer, or the sales handoff rather than targeting

    CPL should not make this decision for you. A $30 lead that never becomes a customer is not inherently better than a $100 lead that regularly closes. The useful denominator is the business outcome you are trying to produce.

    • Cost per qualified lead equals media spend divided by qualified leads.
    • Cost per opportunity equals media spend divided by accepted opportunities.
    • Customer acquisition cost becomes useful when customer records can be matched reliably to acquisition.
    • ROAS is meaningful only when the revenue or conversion values sent back to the platform reflect real economics.

    Write the objective as an operating sentence: “Paid media will optimize for [lifecycle event] because [business constraint], while [downstream metric] remains the guardrail.” That forces marketing, sales, and finance to agree on the event and the trade-off before the algorithm starts making it for them.

    Also separate a media-quality problem from a sales-process problem. If leads meet documented fit criteria but fail to become opportunities, inspect routing, follow-up, sales acceptance, and the offer before narrowing targeting. Automation cannot correct a broken handoff by finding fewer people.

    Feed CRM outcomes back into the bidding system

    A circular flow connects an advertising engine, a qualification funnel, and a customer database, with glowing outcome signals returning to the advertising system.

    Imagine that an ad platform records 1,000 form submissions while the CRM shows 300 qualified leads, 75 opportunities, and 20 customers. If only the form event returns to the ad platform, the system cannot distinguish those 20 customers from everyone else. It learns to reproduce the easiest visible action instead.

    Your feedback loop should give each important lifecycle stage an unambiguous meaning:

    Conversion eventWhat it provesWhen it can guide bidding
    Form submissionA person completed the initial actionWhen volume is the immediate goal or deeper outcomes are not yet recorded consistently
    Qualified leadThe record meets written fit or eligibility rulesWhen opportunities and customers are too sparse but lead quality can be classified reliably
    OpportunitySales accepted the lead into an active commercial processWhen opportunity creation occurs often enough and follows a consistent definition
    Customer or revenueThe acquisition produced a closed outcome and, where available, economic valueWhen the event is frequent, timely, and matched accurately enough for optimization

    Build the connection in this order:

    1. Define the stages. A qualified lead cannot mean “sales liked it.” Write the fit and eligibility rules, who owns the classification, and what causes a record to leave that stage.
    2. Preserve the acquisition link. Carry the identifiers needed to connect the ad interaction, form submission, and CRM record under your consent and privacy requirements. A lifecycle event that cannot be tied back to acquisition is useful for reporting but not for campaign learning.
    3. Clean the event stream. Deduplicate records, keep test submissions and spam out of optimization, and distinguish hard disqualification from an unsuccessful contact attempt.
    4. Return downstream events. Send the selected lifecycle milestones to the relevant advertising platform with consistent names, timestamps, and values where those values are economically defensible.
    5. Choose one primary optimization event. Keep shallower stages available for diagnosis, but do not reward every stage as though it represents the same result.
    6. Reconcile platform and CRM reporting. Investigate missing matches, duplicate events, status reversals, and unexplained shifts before changing bids or targeting.

    Google Ads supports qualified-lead and converted-lead goals, while Meta can receive down-funnel CRM outcomes through the Conversions API. These mechanisms close the visibility gap, but neither can repair a vague qualification rule. If sales changes the meaning of “qualified” from person to person, the machine receives inconsistent training data.

    Choose the deepest event that still supplies a recurring, timely signal. If you generate only a handful of customers in a typical month, customer-only optimization may not provide enough learning data. Move one meaningful stage higher, such as opportunity or qualified lead. Do not retreat all the way to form submissions unless that is the only dependable event.

    Conversion values deserve the same discipline. Use value-based bidding only when the values reflect expected revenue, margin, or another agreed business measure. Arbitrary points can look sophisticated while teaching the system to favor the wrong outcome.

    Give automation room, but keep business guardrails

    Keyword precision is no longer the control system it once was. Google required close variants for exact match in 2014, and automated products such as Performance Max and AI Max can expose advertisers to auctions they did not deliberately choose one by one. Trying to recreate perfect query-level control leaves you fighting the platform instead of shaping its objective.

    Modern broad match can use context beyond the literal keyword, including previous searches and landing-page context. That makes it more capable of finding intent, but also more dependent on the accuracy of your conversion data and the clarity of your site.

    Use an expansion sequence that protects the signal:

    1. Confirm that the chosen conversion event reaches the platform accurately and excludes invalid records.
    2. Expand keyword coverage or test broad match with automated bidding while maintaining negatives for clearly irrelevant or impossible intent.
    3. Broaden geography or paid-social audiences only where the business can actually serve the resulting demand.
    4. Add inventory such as Display, Demand Gen, YouTube, or other video placements when incremental reach is part of the objective.
    5. Evaluate each expansion through qualified leads, opportunities, and customers rather than form volume alone.

    The guardrails should encode business facts, not personal discomfort with an unusual search term:

    • Negative keywords and exclusions: Block structurally irrelevant demand, prohibited locations, services you do not sell, and patterns that repeatedly produce invalid records. Do not exclude a query solely because its wording looks odd if it contributes profitable downstream outcomes.
    • Clear conversion configuration: Make sure the bidding strategy is optimizing for the intended lifecycle event rather than an easier secondary action.
    • Landing-page specificity: Give people and matching systems a precise description of the offer, audience, service area, and next step.
    • Separate brand reporting: Keep branded demand distinct from prospecting. Automated campaign types and competitive bidding can blur that boundary, and revenue attributed to your own brand searches does not by itself show how much new demand the campaign created.
    • Downstream segmentation: Compare campaign, network, geography, audience, and query themes using qualified and opportunity outcomes. A segment with a low CPL can still be your most expensive source of pipeline.

    Smart Bidding replaces thousands of manual bid decisions with auction-level choices guided by a target such as CPA or ROAS. That is useful operational leverage, not strategic judgment. A system can efficiently minimize the cost of the wrong conversion just as easily as the right one.

    Review strange queries as patterns, not isolated screenshots. One unconventional search term that produces qualified opportunities may reflect context you cannot see in the term itself. A recurring cluster of irrelevant searches with no downstream value is evidence for a negative, a message change, or a tighter business boundary.

    Make your ads, forms, and landing pages qualify together

    Three connected panels representing an ad, a landing page, and a form progressively filter prospect tokens before they reach a sales representative.

    When lead quality falls, adding form fields is an easy reaction. It also confuses friction with qualification. A longer form can reduce submissions without making the remaining people a better fit.

    Your ad should help the right person recognize the offer and the wrong person opt out. A generic message such as “Get started today” does almost no filtering. Stronger qualification comes from saying what the offer is, who it serves, which real boundaries apply, and what happens after the click.

    • Name the use case. Do not make a buyer infer whether the offer concerns a product demo, a quote, an application, a consultation, or an informational download.
    • State genuine boundaries. If location, business type, eligibility, or service scope determines fit, make that information visible before the form.
    • Explain the next step. A person expecting instant access behaves differently from someone knowingly requesting contact from sales.
    • Reflect rejection data. If a recurring poor-fit group responds to the ad, revise the message that is inviting it rather than relying on sales to filter it later.

    Apply the same standard to the form. Every question should support routing, qualification, follow-up, or measurement. If nobody uses an answer, remove the question. Keep discovery questions that sales can ask later out of the acquisition gate unless the answer is genuinely required to determine fit.

    Do not label every unreachable lead as low quality. “Could not contact,” “not eligible,” “wrong service,” “outside service area,” “duplicate,” and “spam” describe different failures. Combining them into one bad-lead bucket hides the corrective action and corrupts the optimization signal.

    Map each rejection reason to the lever that can plausibly fix it:

    • Wrong service or product: Clarify the ad and landing page, separate offers, and exclude consistently irrelevant search themes.
    • Outside the service area: Correct location settings and state the coverage area plainly.
    • Wrong buyer type: Use audience-specific language and route distinct buyer groups through appropriate paths.
    • Spam or duplicates: Repair validation and deduplication. Narrower audience targeting is not a substitute for data hygiene.
    • Qualified but never accepted as an opportunity: Inspect the qualification definition, sales handoff, offer, and follow-up process before blaming media.

    The landing page completes the loop. It must confirm the promise in the ad, describe the intended customer, and make the conversion’s meaning unmistakable. This improves human self-selection and supplies the contextual information that modern matching can use.

    For a volume objective, shorter forms, broader audiences, more creative variations, and additional conversion opportunities can remove unnecessary barriers. For a quality objective, start with better outcome data and clearer positioning. Making the form harder to complete should not be your proxy for teaching the platform what a valuable lead looks like.

    Judge automation with mature, downstream cohorts

    The funnel does not end at the thank-you page. Track the full progression from impression to click, lead, qualified lead, opportunity, and customer. Each transition tells you where performance changed and which team can act on it.

    Your working dashboard should include:

    • Spend, clicks, form submissions, and CPL for acquisition diagnostics.
    • Qualified leads, lead-to-qualified rate, and cost per qualified lead.
    • Opportunities, qualified-to-opportunity rate, and cost per opportunity.
    • Customers, opportunity-to-customer rate, and customer acquisition cost.
    • Revenue or another defensible value measure, plus ROAS where attribution is reliable.
    • Rejection reasons by campaign, audience, location, query theme, creative, and landing page.

    Read these metrics by acquisition cohort after that cohort has had enough time to move through your normal sales cycle. Recent leads will naturally have fewer opportunities and customers than mature leads. Comparing them without accounting for that delay can make a healthy campaign look weak or a deteriorating campaign look temporarily efficient.

    Use the pattern in the funnel to choose the next action:

    • Lead volume rises, qualification rate falls, and cost per qualified lead worsens: Automation is probably scaling the easy signal. Move the optimization event deeper, correct exclusions, or strengthen qualification messaging.
    • CPL rises while qualification rate improves and cost per opportunity falls: The campaign may be working better. Do not reverse it merely to restore a cheaper form fill.
    • Qualified-lead volume holds but opportunity creation falls: Revisit the qualification definition and sales-acceptance process. The label may no longer predict commercial value.
    • Opportunities remain healthy but customer or revenue performance weakens: Inspect value assumptions, offer fit, close rates, and the sales process. Targeting may not be the root cause.
    • The deepest event appears only sporadically: Step up to a more frequent meaningful stage while keeping the final outcome in reporting.
    • Platform metrics look strong while sales reports poor quality: Require structured rejection reasons and reconcile the records. Anecdotes can flag a problem, but they cannot train an algorithm or locate the failure.

    Your next move should be concrete: take a mature group of paid leads, assign consistent lifecycle stages and rejection reasons, then calculate cost per qualified lead and cost per opportunity. Select the deepest dependable event as the bidding goal before expanding match types, audiences, or inventory. Once the platform can see the same definition of success as the business, automation has something useful to optimize.

    References


  • YouTube Ad Creative and DV360 Changes to Make by October

    YouTube Ad Creative and DV360 Changes to Make by October

    Your YouTube campaign can have a sound bid strategy and still underperform because the ad was built for another surface. At the same time, a promising creative refresh can stall before delivery if the Display & Video 360 integration behind it is not ready for October’s unversioned platform changes.

    Treat this as one operating problem with two workstreams. Improve the message people see and hear, then verify that your API and Structured Data File workflows can still create, update and protect the campaign. Here is the sequence we would use.

    Key takeaways

    • For Demand Gen in-stream skippable ads in the United States, July 2026 data associated human voice with 12% higher conversions on average, text overlays with 3% higher conversions and visible branding in the first five seconds with 4% higher conversions. These are test priorities, not guaranteed lifts.
    • Build image ads for the YouTube feed: use high-resolution, full-bleed imagery, include people when appropriate and remove black bars, excessive empty space and oversized logos.
    • Do not bake fake buttons or arrows into an image. They compete with YouTube’s functional call to action and can leave the viewer unsure about what is actually clickable.
    • On Oct. 1, DV360 API and Line Item Structured Data File workflows lose specified digital-content-label exclusions and most sensitive-category exclusion options.
    • On Oct. 12, YouTube responsive ad creation and updates require a business name and logo when those defaults are not already assigned to the parent advertiser.

    Start with voice, early branding and useful on-screen text

    A presenter speaks into a microphone while being recorded on a smartphone, surrounded by an abstract audio waveform and blank graphic overlays.

    Creative is not the decorative layer that you address after bidding and targeting. Nielsen attributed 49% of campaign ROI to creative, while Ekimetrics found that improving creative could more than double YouTube ROI. Those aggregate findings do not forecast what your account will gain, but they do justify giving creative testing the same operational attention as media settings.

    The most actionable benchmarks are narrower. They apply to Demand Gen in-stream skippable ads, use U.S. data from July 2026 and describe associations rather than proof that an isolated element caused the result. That scope matters when you decide what to test and how confidently to interpret it.

    Creative elementObserved conversion associationFirst controlled test
    Human voice12% higher on averageCompare a voiced cut with a closely matched cut that has no human voice.
    Supers or text overlay3% higher on averageAdd concise on-screen wording to the same core edit and keep the offer and call to action unchanged.
    Brand visible in the first five seconds4% higher on averageCompare immediate visual brand identification with a later brand reveal.

    Do not add those percentages together and turn the result into a forecast. The elements can interact, and campaigns that use them may differ in other important ways. Use the figures to determine test order: if you have enough traffic for only one new comparison, human voice is the most defensible place to start because it had the largest reported association.

    Give the voice a real job. It can state the viewer’s problem, establish the offer or make the next action clear. A voice that merely reads every word on screen adds sound without improving the message. Keep supers equally disciplined: reinforce the key point rather than turning the frame into a transcript.

    Early branding also needs restraint. The goal is to make the advertiser identifiable within five seconds, not to cover the opening with a logo that delays the reason to keep watching. Put the brand into the story while the viewer is still deciding whether to skip.

    For a useful test, hold the audience, offer, bid strategy, call to action and landing page as steady as your campaign setup permits. Change one creative factor at a time. If your conversion volume cannot support several cells at once, run the comparisons sequentially instead of launching a test that never produces a clear decision.

    Judge the result against the conversion action that matters to the campaign. A click-through improvement is not automatically a conversion improvement. Also, do not assume that benchmarks from U.S. Demand Gen in-stream skippable inventory transfer unchanged to Shorts, other formats or other markets. Those are separate questions for your account to answer.

    Make image assets belong in the YouTube feed

    An image can be polished in a design file and still look broken when placed in a YouTube feed. The common failure is not low production value. It is a layout that carries the visual habits of a banner, presentation slide or another ad platform into a surface where people expect immersive imagery.

    For YouTube image ads, visible people and people interacting with products tend to outperform assets without human presence in Google’s platform observations. Human presence should still make sense for the product and message; inserting an unrelated face is not a substitute for a coherent concept.

    • Fill the available frame. Start with high-resolution, full-bleed photography or lifestyle imagery rather than an image floating inside a large solid canvas.
    • Show use, not just inventory. When appropriate, let a person hold, wear, operate or otherwise interact with the product so the viewer can understand its role quickly.
    • Keep the logo proportional. The brand should be identifiable without making an oversized logo the main visual event.
    • Remove structural clutter. Black bars and large empty solid areas can make the asset feel fragmented or incorrectly formatted.
    • Delete fake interface elements. A button, play control or arrow drawn into the image is not functional. Let YouTube’s actual call-to-action control handle the interaction.

    Fake controls create two competing instruction systems. The platform presents a real action, while the picture implies another one that does nothing. That forces the viewer to determine which visual element is interactive instead of understanding the offer. If an arrow is necessary to make the call to action discoverable, the composition or message probably needs another pass.

    Review the rendered asset in its intended placement, not only at full size on a designer’s canvas. Ask whether it reads as one complete image, whether the important person or product survives the crop, whether the brand remains recognizable and whether there is exactly one obvious functional path forward. This preview is also where black bars, oversized marks and deceptive button shapes become easiest to catch.

    Native fit does not mean disguising an advertisement. It means using the visual language of the surface while keeping the advertiser and offer clear. A feed-compatible image earns attention through relevance and composition, not through an imitation of YouTube’s controls.

    Prepare DV360 automation for the October deadlines

    An abstract automation pipeline moves file cards through validation gates, version branches and safeguards beside a blank calendar.

    A better asset cannot improve results if the integration that manages it stops working. The October rollout contains three unversioned changes across the Display & Video 360 API and Structured Data Files. Do not assume an older client or a delayed API-version migration will preserve the previous behavior.

    Oct. 1: specified exclusion controls are removed

    Starting Oct. 1, advertisers will no longer be able to use API targeting to exclude specific digital content labels. The change affects available TARGETING_TYPE_DIGITAL_CONTENT_LABEL_EXCLUSION options and valid values in the Digital Content Labels - Exclude column of Line Item Structured Data Files.

    Most sensitive-category exclusions are also being removed from targeting on that date. Audit any workflow that uses TARGETING_TYPE_SENSITIVE_CATEGORY_EXCLUSION, as well as the Brand Safety Sensitivity Setting and Brand Safety Custom Settings columns in Line Item Structured Data Files.

    This is a change to available controls, not a reason to quietly weaken your brand-safety policy. Do not simply delete fields until an error disappears. First identify which business rule each field was implementing, who owns that rule and what the approved workflow should be once that targeting option is unavailable.

    Do not guess how every existing line item will display or behave after the change. Inventory the affected line items and validate the actual transition in a controlled workflow. The important distinction is between authoring a new setting, updating an existing line item and observing a previously configured value; each path deserves an explicit check.

    Oct. 12: responsive ads need business identity assets

    Starting Oct. 12, developers creating or updating YouTube responsive ads must provide a business name and logo when default values are not already assigned to the parent advertiser. The requirement also applies to ads uploaded through Ad Structured Data Files.

    That parent-advertiser condition gives you a clean preflight decision. If approved defaults exist, verify that every relevant workflow can use them. If they do not, make the business name and logo required inputs before an ad reaches the create, update or upload step. Do not wait for a production job to discover that the identity assets are missing.

    Your technical audit should cover these exact paths:

    1. Search code, configuration files and Line Item Structured Data File templates for TARGETING_TYPE_DIGITAL_CONTENT_LABEL_EXCLUSION, TARGETING_TYPE_SENSITIVE_CATEGORY_EXCLUSION and the affected column names.
    2. List every scheduled job, internal tool and third-party workflow that creates or updates YouTube responsive ads through the API.
    3. List every process that uploads Line Item or Ad Structured Data Files. Treat the two file types separately because the exclusion and identity changes affect different operations.
    4. Inspect each parent advertiser used by those workflows and record whether an approved default business name and logo are already assigned.
    5. Add a preflight check that blocks responsive-ad submission when neither advertiser defaults nor required identity inputs are available.
    6. Have the brand-safety owner approve any operational change caused by the lost exclusion options, then test create, update and file-upload paths before their respective deadlines.

    Record which test covers which deadline. A successful responsive-ad creation test does not prove that an exclusion workflow is ready, and a clean Line Item Structured Data File does not prove that an Ad Structured Data File contains the required identity. Separating those assertions will make a failure much easier to locate.

    Run one joined creative-and-delivery sprint

    Creative production and delivery engineering often sit in different queues, but the campaign depends on both. A new ad trapped behind a failed update request creates no learning. A perfectly updated integration serving weak recycled assets only automates the wrong input.

    Use this order to turn the work into a test you can trust:

    1. Clear the deadline risk. Open technical tickets for the Oct. 1 exclusion changes and the Oct. 12 identity requirement. Assign owners before asking the creative team to produce a large new batch.
    2. Freeze a useful control. Preserve the current offer, landing page, audience and conversion action so the next result can be interpreted as a creative comparison.
    3. Create focused video variants. Build a human-voice version, an early-brand version and a concise-text-overlay version. Keep the underlying proposition as consistent as possible.
    4. Rebuild image assets for the feed. Use full-bleed imagery, meaningful human presence and one clear composition. Remove fake buttons, arrows, black bars and excess empty space.
    5. Validate delivery before launch. Exercise the API create and update paths, the relevant Structured Data File uploads and the business-identity fallback. Do not mix a delivery defect into a creative performance test.
    6. Label the change in reporting. Use variant names that identify the factor being tested. When conversions move, you should be able to connect the result to voice, branding, text or image treatment without reopening the design files.

    If capacity is tight, prioritize the integration work first because its dates are fixed. Then test human voice, which had the largest reported conversion association, followed by early branding and text overlays. Feed-image cleanup can run alongside those video edits because it addresses a different asset type.

    Open your highest-spend YouTube ad and its parent advertiser record side by side. Check whether the ad uses a human voice, identifies the brand within five seconds and gives on-screen text a clear purpose. Then confirm the advertiser’s default business name and logo and search your automation for the affected exclusion identifiers. You will leave that session with one defined creative experiment and one concrete technical readiness list, both in time for October.

    References