Tag: Accessibility

  • How to Optimize Content for Humans and AI Discovery

    How to Optimize Content for Humans and AI Discovery

    Your page has two jobs before it can earn a business result. A person must understand why it matters, and a search or AI system must be able to identify what it says without guessing. Treat those as separate writing assignments and you usually get a stiff “AI version” alongside a more expressive page whose meaning remains implicit.

    Use one clarity-first page instead. Make its meaning explicit, its value hard to substitute and its next action easy to complete. That approach matters because generic informational content now competes with direct AI answers while visibility becomes scarcer. Publishing more is not enough. Each page must be understandable, retrievable, memorable and useful.

    Optimize the shared information, not two separate audiences

    People and AI systems process a page differently, but they tend to struggle at the same points: an unclear subject, an unsupported claim, an unexplained term, a buried qualification or an ambiguous next step. That is why clear messaging, usable experiences and technical precision form a shared foundation for people and automated systems.

    A person can sometimes infer meaning from visual position, tone or previous experience. An automated system may depend more heavily on labels, surrounding text and explicit relationships. The answer is not to flatten your writing into robotic prose. Keep the voice, examples and visual hierarchy that help people, but state the essential facts in text that can stand on its own.

    Page elementWhat a person needsWhat an AI system needs to identifyShared treatment
    OpeningWhether the page is relevantThe primary subject, audience and outcomeGive a direct answer or promise before background
    HeadingsA fast route to the right detailClear boundaries between subtopicsUse descriptive headings that name the question or decision
    EvidenceA reason to believe the claimThe relationship between a claim, its support and its limitsPlace support and qualifications beside the claim
    Call to actionConfidence about what happens nextThe action available and its destinationUse a specific label and a working, direct path

    Key takeaways

    • Optimize one canonical page for shared clarity instead of creating separate human and AI versions.
    • Put the main answer, offer or decision near the beginning, then add the context needed to evaluate it.
    • Use descriptive headings and self-contained sections so readers and systems can locate the right passage.
    • Keep evidence, definitions and limitations close to the claims they support.
    • Make the primary next action explicit in both its wording and its destination.
    • Plan how the page will reach its audience before committing resources to its production.

    Build every page as a question-to-action path
    A person follows a connected path of blank content cards from an initial question to a final action control.

    Optimization starts before the draft. Write a three-line page contract that prevents the page from drifting into a broad topic summary:

    • Audience: Who is making a decision or trying to complete a task?
    • Promise: What will this page help that person understand, choose or do?
    • Action: What should become possible after the promise has been fulfilled?

    Be specific enough that an editor could reject material that does not belong. “People interested in AI SEO” is too broad. “A content lead deciding how to revise service pages for human visitors and AI discovery” establishes a reader, a page type and a decision.

    1. Choose one dominant job. Decide whether the page primarily helps someone learn, compare, evaluate, buy or complete an action. A page may support secondary needs, but it should not give all of them equal weight.
    2. Answer before explaining. State the conclusion, offer or recommended direction early. Background belongs after the reader knows why it matters.
    3. Develop a visible reasoning chain. Move from the answer to the mechanism, supporting evidence or criteria, important limitations and the appropriate next step.
    4. Name important entities consistently. If you alternate among a product name, category name and vague phrases such as “the solution,” neither the reader nor a downstream system should have to infer whether they refer to the same thing.
    5. Close the loop. The call to action should follow from the page’s promise. A comparison page might lead to a specification, consultation or purchase path. An instructional page should let the reader perform or verify the task it explained.

    Then perform a sentence-level clarity audit. Replace pronouns whose antecedents are uncertain. Define an acronym at first use. Remove adjectives such as “advanced,” “leading” or “seamless” unless the page supplies a basis for them. Put exceptions beside the rule instead of hiding them in a closing note. Replace generic links such as “click here” and “learn more” with labels that identify the destination or action.

    A useful stress test is whether a 10-year-old could roughly explain what you offer, why it matters and how someone engages with it. That clarity test is meant to expose unnecessary complexity, not to make a technical subject childish. Keep the precise terms your audience needs, but define them in the same section where they become relevant.

    Write modules that survive scanning, extraction and reuse
    Blank visual content modules move from a central page into a mobile screen, an AI extraction frame, and a reader's reference card.

    There is no universally correct amount of text for a page. The right length is the amount required to explain the offer or answer, establish why it is credible, distinguish it from alternatives and support the intended action. A long page can be easy to use when it is modular. A short page can still fail when it omits the facts needed to decide.

    Give each section a repeatable internal shape:

    1. Descriptive heading: Name the subquestion, criterion or decision addressed by the section.
    2. Direct opening: Answer that subquestion in the first sentence or paragraph.
    3. Support: Add the mechanism, evidence, definition, example or comparison needed to evaluate the answer.
    4. Boundary: State any condition under which the answer changes or does not apply.
    5. Implication: Tell the reader what to notice, decide or do with the information.

    This structure makes a section useful when someone scans directly to it. It also reduces the risk that a sentence will be extracted without the qualifier that changes its meaning. Do not repeat the same conclusion in every module. Each section should advance the decision.

    Match formatting to the relationship in the information. Use bullets for criteria of the same kind, numbered lists when sequence matters and tables only when readers need to compare the same attributes across multiple options. Use images when they explain something the text cannot show as efficiently. Relevant alt text should communicate the image’s purpose or information, while decorative imagery should not be forced to carry a claim. Readable typography, adequate contrast and meaningful image descriptions support accessibility as well as comprehension.

    Once the visible copy is stable, align the structured layer. Treat JSON-LD as a machine-readable restatement of facts on the page, not as a second marketing message. Entity names, descriptions, relationships and available actions should agree with what a visitor can see. Do not add a claim to structured data that the page does not substantiate, and do not expect schema to rescue copy whose subject or purpose is unclear.

    • Use the same preferred name for the organization, product, service or person in the copy and structured data.
    • Make each marked-up type match the thing the page actually describes.
    • Keep dates, status information and other changeable facts synchronized wherever they appear.
    • Ensure an action described in structured data resolves to a real, functioning destination.
    • Remove obsolete markup when the corresponding visible content or capability is removed.

    When an AI agent must interact with tools or shared information rather than merely read a page, connection standards such as Model Context Protocol can help systems reach those resources. But clean, well-structured and actionable information is still required downstream. Connectivity does not correct an ambiguous offer, an unsupported statement or a broken workflow.

    Add value that cannot be replaced by a generic summary

    A generic explanation can be accurate and still be strategically weak. If a capable system can reproduce the page’s entire value from common knowledge, the reader has little reason to remember your brand or visit for the next step. As content production becomes easier, originality, distinctiveness and deliberate distribution carry more of the visibility burden.

    Do not confuse originality with novelty for its own sake. A useful page becomes harder to substitute when it contributes at least one defensible unit of value:

    • A decision rule: A clear way to choose between options, including the condition that changes the choice.
    • A bounded position: A recommendation that states where it applies, where it does not and why.
    • Owned evidence: Substantiated data, examples, observations or methods that your organization is entitled to publish.
    • An operational method: A checklist, sequence, template or diagnostic that lets the reader perform the work.
    • A revealing limitation: A tradeoff or failure mode that generic descriptions tend to omit.
    • A distinctive asset: A useful visual, framework or recurring editorial device that people can recognize and share.

    Use only material you can support. Invented data, anonymous anecdotes and manufactured certainty may make a page look specific, but they weaken trust and make its claims unsafe to reuse. Precision includes saying when evidence is limited or a recommendation depends on context.

    Apply a substitution test before publication. Could a competitor replace the logo and publish the page unchanged? Does the page contain a rule someone can use, or only a summary of the topic? Is there a sentence that expresses a recognizable point of view? Would a partner have a concrete reason to share it? If every answer points to interchangeability, revise the value proposition before polishing metadata.

    Distinctive content still needs a route to attention. Reverse the volume-era workflow that publishes first and asks about promotion later. Media, partnerships and events can push useful work toward an audience instead of leaving discovery entirely to search. Complete a distribution brief before approving the draft:

    • Audience: Name the specific group that will use the page and the decision it helps them make.
    • Carrier: Identify the newsletter, partner, community, media relationship, event, paid placement or owned channel capable of reaching that group.
    • Reason to share: State the practical value the carrier can offer its audience by distributing the work.
    • Portable asset: Choose the checklist, chart, decision rule, example or excerpt that can travel without stripping away the meaning.
    • Destination: Decide where interested people should land and what they should be able to do there.

    If you cannot identify a credible carrier or reason to share, that is useful information. Narrow the audience, strengthen the original contribution or reconsider whether the page deserves production. Distribution should shape the content brief, not become a rescue operation after publication.

    Use a publish gate for clarity, action and delivery

    Technical optimization belongs after the message and user path are coherent. It can expose and remove friction, but it cannot manufacture relevance. A fast, marked-up page with a vague offer remains vague. The final review should test meaning, task completion, rendering, discovery and distribution as one system.

    Run the same comprehension test with a person and an AI assistant

    Give the page to a colleague who was not involved in writing it. Ask that person to identify the intended audience, main answer or offer, supporting evidence, important limitation and primary next action. Do not explain the page before the test.

    Then give an AI assistant only the visible page copy and use this prompt: “Identify the intended audience, main claim or offer, supporting evidence, limitations and primary next action. Quote the text that supports each answer. If an answer is unsupported, write ‘not stated.’” Compare both responses with the page contract.

    A correct AI response does not prove that the page will rank, appear in an answer or receive a citation. Treat the exercise as an ambiguity detector, not a visibility score. When the assistant invents a benefit, misses a limitation or chooses the wrong action, find the wording or structure that allowed the misreading. The same ambiguity may also be costing human comprehension.

    Complete the action yourself

    • Follow the primary call to action and confirm that its destination matches its label.
    • Test phone numbers, email links, forms, validation messages and confirmation states where they are part of the path.
    • Remove form fields and separate steps that are not required to complete or qualify the action.
    • Check that a user can recover from an error without re-entering unrelated information.
    • Confirm that transactional or lead-generation intent is stated in visible language instead of being implied only by a button or form.

    Clear calls to action and simple task paths matter because unclear checkout and lead-generation flows obstruct people and automated agents alike. A button labeled “Submit” identifies an interface event. A label such as “Request the estimate” identifies the user’s action and expected outcome.

    Inspect the experience that carries the content

    • Load the page at common desktop and mobile widths and check whether text, controls or media move after they first appear.
    • Remove intrusive overlays, excessive advertising and visual elements that compete with the page’s primary purpose.
    • Check contrast, text readability, keyboard access, control labels and meaningful alternative text.
    • Verify that the complete page renders, internal resources load and security warnings are absent.
    • Review the visible copy and structured data after deployment rather than assuming the content management system published both correctly.

    Large layout shifts, incomplete rendering, weak contrast, malware warnings and disruptive pop-ups undermine usability and trust. Fix those problems because they interfere with the experience, not because a technical score can replace a clear answer.

    Measure the page by the job it was built to do

    Traffic remains useful context, but it is not a complete outcome. Informational visits have always been a proxy for business progress, and direct answers make that proxy less dependable on its own. Keep a small scorecard tied to the page contract:

    • Comprehension: Record which parts people or AI extraction tests misinterpret, omit or overstate.
    • Action: Track starts, completions, abandonment and errors for the page’s intended task.
    • Discovery: Monitor the relevant queries, impressions, brand mentions and AI-answer appearances that matter to the defined audience.
    • Demand and memory: Watch branded search, direct or returning visits and voluntary brand engagement without treating any one measure as conclusive.
    • Distribution: Record placements, partner participation, qualified referral activity and reuse of the portable asset.

    Tools can make individual checks easier. IndexNow can notify participating search engines about a changed URL more quickly, though notification is not a promise of indexing or visibility. Microsoft Clarity can reveal behavioral friction, including problems in chatbot experiences. Both are diagnostic aids for updates and user behavior, not substitutes for editorial judgment.

    Start with the page closest to a meaningful customer decision. Make its promise and action unmistakable, align its structured data, run the paired comprehension test and give it a real distribution path. Once that page passes, turn the same publish gate into the default for every high-value page you create or revise.
    References

  • When a Dark B2B Landing Page Can Outperform a Light One

    When a Dark B2B Landing Page Can Outperform a Light One

    You chose a light B2B landing page because it looks clean, credible and safe. Now a darker concept feels more natural for your audience, but changing the visual system without evidence could put paid traffic and lead flow at risk.

    Don’t settle the decision through taste or a generic benchmark. A dark design can outperform when it reflects the buyer’s working world, supports the right brand associations and makes the conversion path unmistakable. It can also lose when it weakens readability or merely follows a design trend. The useful question is not whether dark pages convert better. It is whether a dark page communicates your particular offer better to your particular buyer.

    A dark theme is a hypothesis, not a best practice

    One industrial fleet-repair SaaS experiment sent paid traffic evenly to dark and light landing pages with identical copy. During a three-to-four-week Google Ads search run, the campaigns spent $8,205.97 and produced 767 clicks and 30 conversions. The light variant recorded a 16.62% higher click-through rate, yet it generated 42% fewer conversions. Meta testing also favored the dark direction.

    That is meaningful evidence that audience context can overturn a common design default. It is not evidence that dark backgrounds are universally better for B2B. The result belongs to a specific market, offer, traffic mix and page treatment. A finance buyer working in spreadsheets, a healthcare administrator reviewing compliance software and a commercial shop operator surrounded by equipment do not necessarily interpret the same visual language in the same way.

    The industrial audience provides a plausible explanation for the result. Dark and metallic tones were familiar within the buyers’ operating environment. The visual treatment could communicate durability, seriousness and functional value, while white form fields against the dark background created an obvious destination for attention. Those explanations are useful mechanisms to test, but they are not independently proven causes.

    Consider a dark concept when it has a defensible connection to the buyer’s environment or expectations. Do not choose it because your design team prefers it, because a competitor uses it or because dark interfaces currently look modern. If you cannot complete the sentence, “This treatment should work for this audience because…”, you do not yet have a testable rationale.

    Translate audience context into a design hypothesis

    A professional works in a dim operations room while a laptop displays an abstract dark landing-page interface.

    A buyer persona containing a job title and company size will not tell you whether to use a black background. You need to examine the context in which the buyer works, the visual conventions of the category and the meaning your page must convey at the moment of decision.

    • Inspect the working environment. Look at the equipment, materials, interfaces, documents and spaces your buyer encounters every day. Record recurring colors, textures and levels of visual density.
    • Identify category signals. Decide which visual cues already mean dependable, technical, premium, efficient or familiar to this audience. Separate useful conventions from competitors’ arbitrary styling.
    • Define the decision state. A buyer urgently trying to restore an operation may need a forceful, obvious path to action. A committee comparing a complex platform may need more reading comfort and visible evidence.
    • Name the conversion target. Decide whether the design must direct attention to a form, demo request, pricing path or another action. Contrast should support that target rather than decorate the page evenly.
    • Document the risk. Write down what the treatment might accidentally communicate, such as low readability, consumer entertainment, excessive luxury or a lack of transparency.

    Turn those observations into one sentence before anyone opens a design tool: “For this audience in this context, this visual system will make the offer feel more familiar and the action easier to locate, increasing completed lead forms.” That statement gives you an audience, a proposed mechanism and a measurable outcome.

    For commercial shop operators, the hypothesis might connect an industrial palette with familiarity and seriousness, then connect high-contrast fields with easier form discovery. For another audience, the same palette could create distance or make a text-heavy evaluation harder. Design psychology should generate the hypothesis; observed behavior should decide whether you keep it.

    Dark is not the same as accessible

    White text on a dark background does not make a page accessible by itself. Check body copy, headings, links, field labels, entered text, borders, keyboard focus, validation errors and disabled states. A form can appear high-contrast at a glance while still hiding field boundaries or error messages from someone trying to complete it.

    Run the same checks on the light version. Accessibility is not a reason to assume one theme will win; it is a requirement both variants must satisfy before their conversion results are worth comparing. If one treatment is difficult to read or operate, you are testing usability failure against a functional page, not audience preference.

    Decide whether you are testing a theme or a design system

    The most important methodological distinction is easy to miss. A broad concept test tells you which complete experience performs better. An isolation test tells you whether one component caused a difference. Both are legitimate, but they answer different questions.

    In the industrial SaaS experiment, the copy stayed constant, but several visual elements changed together. The dark version used a black background, white text, prominent white form fields, a subtly outlined black call-to-action button and no header logo. The light version used white and gray surfaces, dark text, a blue button and a prominent header logo. The experiment therefore showed that one complete design treatment beat the other. It did not establish that the background color alone produced the conversion difference.

    Use a concept test to choose a direction

    A concept test is appropriate when you need to choose between substantially different visual systems. Make the alternatives different enough to express distinct hypotheses, but preserve the underlying commercial proposition.

    1. Keep the offer, copy, form fields, call-to-action wording and post-submit experience unchanged.
    2. Define each visual system in advance, including its background, typography, field treatment, button styling, imagery and brand presence.
    3. Send the same audience and advertising promise into a stable random assignment. An even split is useful when traffic permits it.
    4. Record the assigned variant, landing-page visit, form completion and any downstream lead-quality outcome.
    5. Name the primary success metric before launch. Do not promote whichever metric looks favorable after results arrive.
    6. Plan the required sample using your normal test method and expected conversion rate. Do not borrow the three-to-four-week duration from another campaign as a universal stopping rule.
    7. Review the overall result first. Treat source, device or audience-segment differences as follow-up hypotheses unless the original test was designed to evaluate them.

    This approach answers a practical production question: which page should receive traffic? It does not tell you which ingredient inside the winner mattered most.

    Use isolation tests to find the cause

    Once a concept wins, clone it and test its components deliberately. You might compare logo presence, form-field contrast or button treatment in separate experiments. If your claim is specifically about dark versus light, keep the logo, layout, field count, copy, button wording and promotional promise the same. Treat the foreground and background palette as the variable, while ensuring both versions remain readable and operable.

    This two-stage sequence prevents an attractive but unsupported conclusion. A dark concept may win because of its field contrast, its reduced header distraction, its overall tone or an interaction among those elements. Selecting the winning bundle is still valuable. Naming the cause requires another test.

    Do not let click-through rate choose the landing page

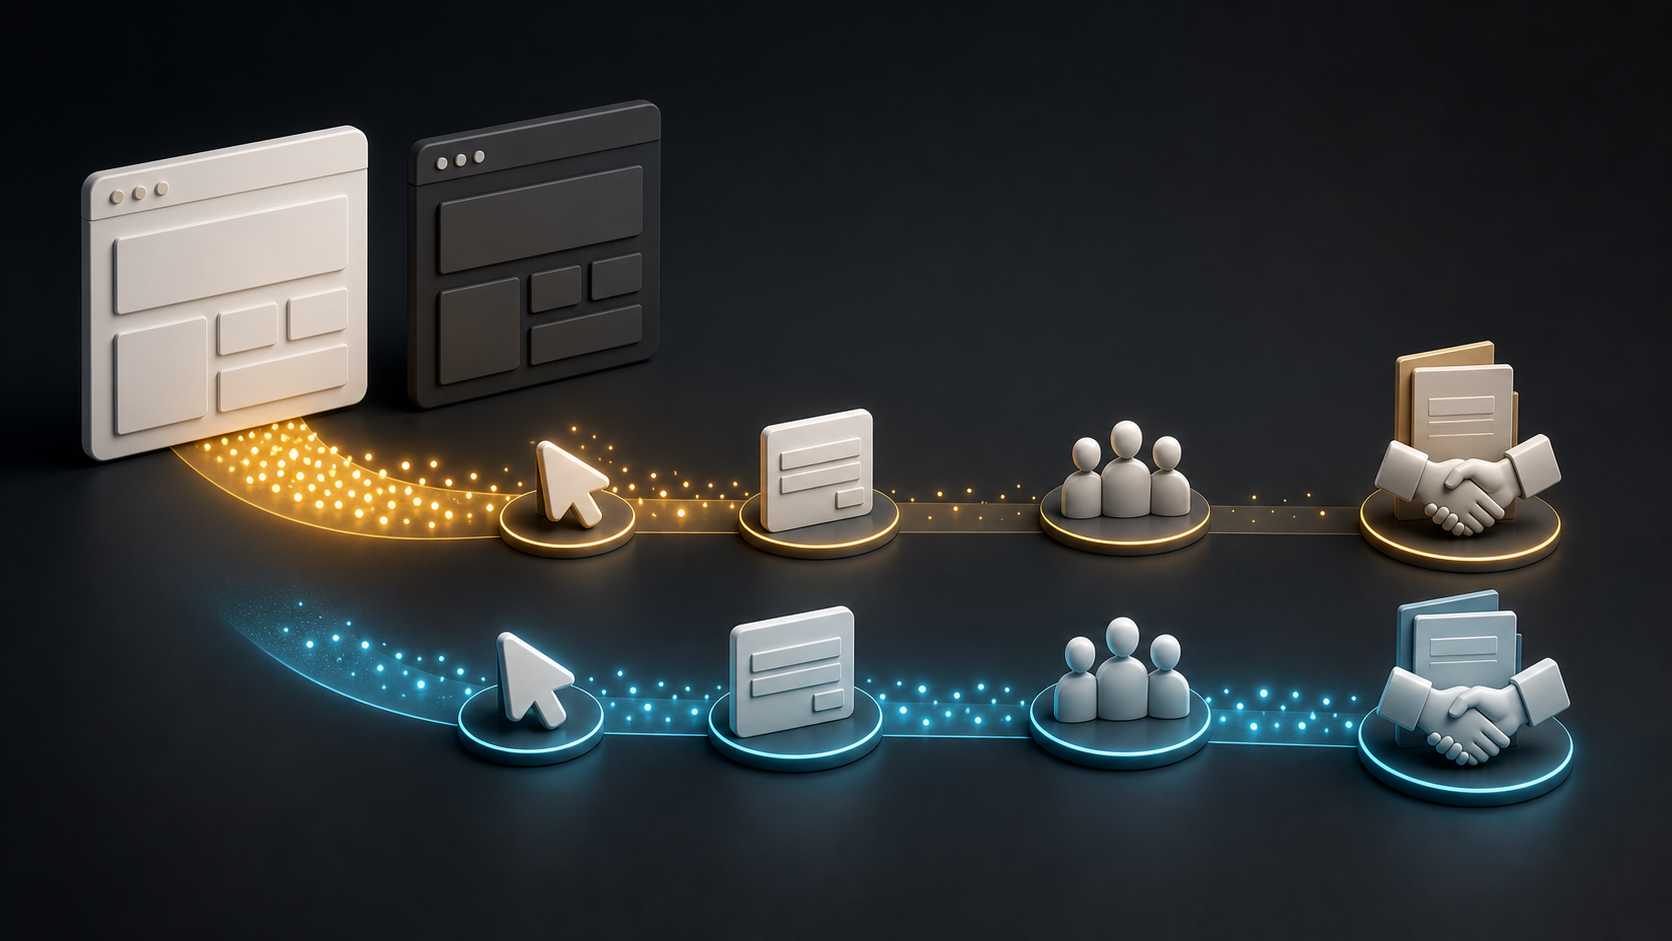
    Two abstract landing-page paths lead from clicks through forms and qualified prospects to a business handshake, with different numbers reaching the final outcome.

    Click-through rate measures behavior before the visitor experiences the landing page. Unless the page design is visible in the ad creative, a user cannot react to its theme before clicking. A variant-level CTR difference should therefore trigger a review of traffic assignment, campaign delivery and tracking. It should not automatically be credited to the landing-page palette.

    The industrial SaaS result makes the practical danger clear: the light treatment’s CTR was 16.62% higher while its conversion count was 42% lower. Choosing the page on CTR alone would have favored the upstream metric and ignored the action the landing page existed to produce.

    MetricWhat it answersHow to use it
    Ad click-through rateDid the ad and its targeting earn a click?Use it to diagnose traffic acquisition, not to declare a landing-page theme the winner.
    Landing-page conversion rateWhat proportion of landing-page visitors completed the intended action?Use it as the primary page metric when a form completion is the immediate objective.
    Qualified lead rateWhat proportion of visitors became leads your business considers usable?Use it to catch variants that generate more forms but poorer-fit prospects.
    Cost per qualified leadHow much media spend produced each usable lead?Use it when deciding which experience should receive budget.

    Also distinguish conversion volume from conversion rate. If variants receive different numbers of visitors, raw form totals cannot make a fair comparison on their own. Use the actual visitor count assigned to each experience. And do not describe one page’s leads as better qualified merely because it generated fewer clicks and more forms; lead quality requires downstream evidence such as acceptance, sales progression or another definition your team applies consistently.

    Key takeaways

    • Do not adopt dark mode as a general conversion rule. Use it when you can connect the treatment to a specific audience context and buying task.
    • Write the proposed mechanism before designing: identify what the theme should communicate, where it should direct attention and which outcome should change.
    • Choose between a broad concept test and an isolated variable test. A bundle can select a production winner, but it cannot prove which component caused the result.
    • Keep the offer, copy, form requirements and traffic assignment controlled. Make both variants accessible enough that usability failure does not decide the experiment.
    • Treat ad CTR as an acquisition diagnostic. Judge the landing page by visitor conversion and, where available, qualified lead or business outcomes.
    • Use a winning concept as the start of component testing, not as permission to declare that all B2B audiences prefer the same theme.

    Your next move is simple: create two annotated mockups and label the audience signal each important choice is meant to send. Decide whether you need a concept winner or an explanation of one component, then write down the primary metric before traffic begins. If dark wins, isolate the elements that may have produced the lift. If light wins, revise the audience hypothesis rather than forcing the aesthetic. Either outcome replaces an assumption with something you can use on the next campaign.

    References

  • Profound Multilingual Access: A Rollout Guide for Teams

    Profound Multilingual Access: A Rollout Guide for Teams

    If your regional specialists must navigate every dashboard and workflow in a second language, translation becomes part of every task. Labels take longer to interpret, handoffs require extra explanation, and a small misunderstanding can follow an insight all the way into content planning.

    Profound is rolling out a beta App Language Selector with support for more than 30 languages. That can remove a meaningful layer of friction for international teams. To use it well, however, you need to distinguish the language of the application from the language of your prompts, measurement, analysis, and published content.

    Start with the right model of what language access changes

    A language selector changes how a person interacts with an application. It should not be treated as proof that every other language-dependent part of the workflow changed with it.

    Before enabling the feature across your team, separate four layers:

    • Interface language: The language used for navigation, labels, instructions, messages, and other application text.
    • Research language: The original wording of the question, query, prompt, topic, product, or entity being investigated.
    • Measurement context: The market, audience, platform, model, location, and other settings that define what your team is examining.
    • Publication language: The language and locale of the content your audience will ultimately read.

    Changing the first layer does not, by itself, change the other three. A French interface does not automatically make an English-language research set representative of France. A Spanish label on a report does not prove that the underlying prompts were run in Spanish. A German dashboard does not localize the pages your team plans to publish.

    This distinction matters in AI search because language carries intent, not just vocabulary. A literal translation can change the specificity of a question, the entity it appears to reference, or the way a local audience describes a need. Keep the original wording visible throughout the workflow, even when the interface and the team’s shared working language are different.

    Pilot one complete workflow before enabling every language

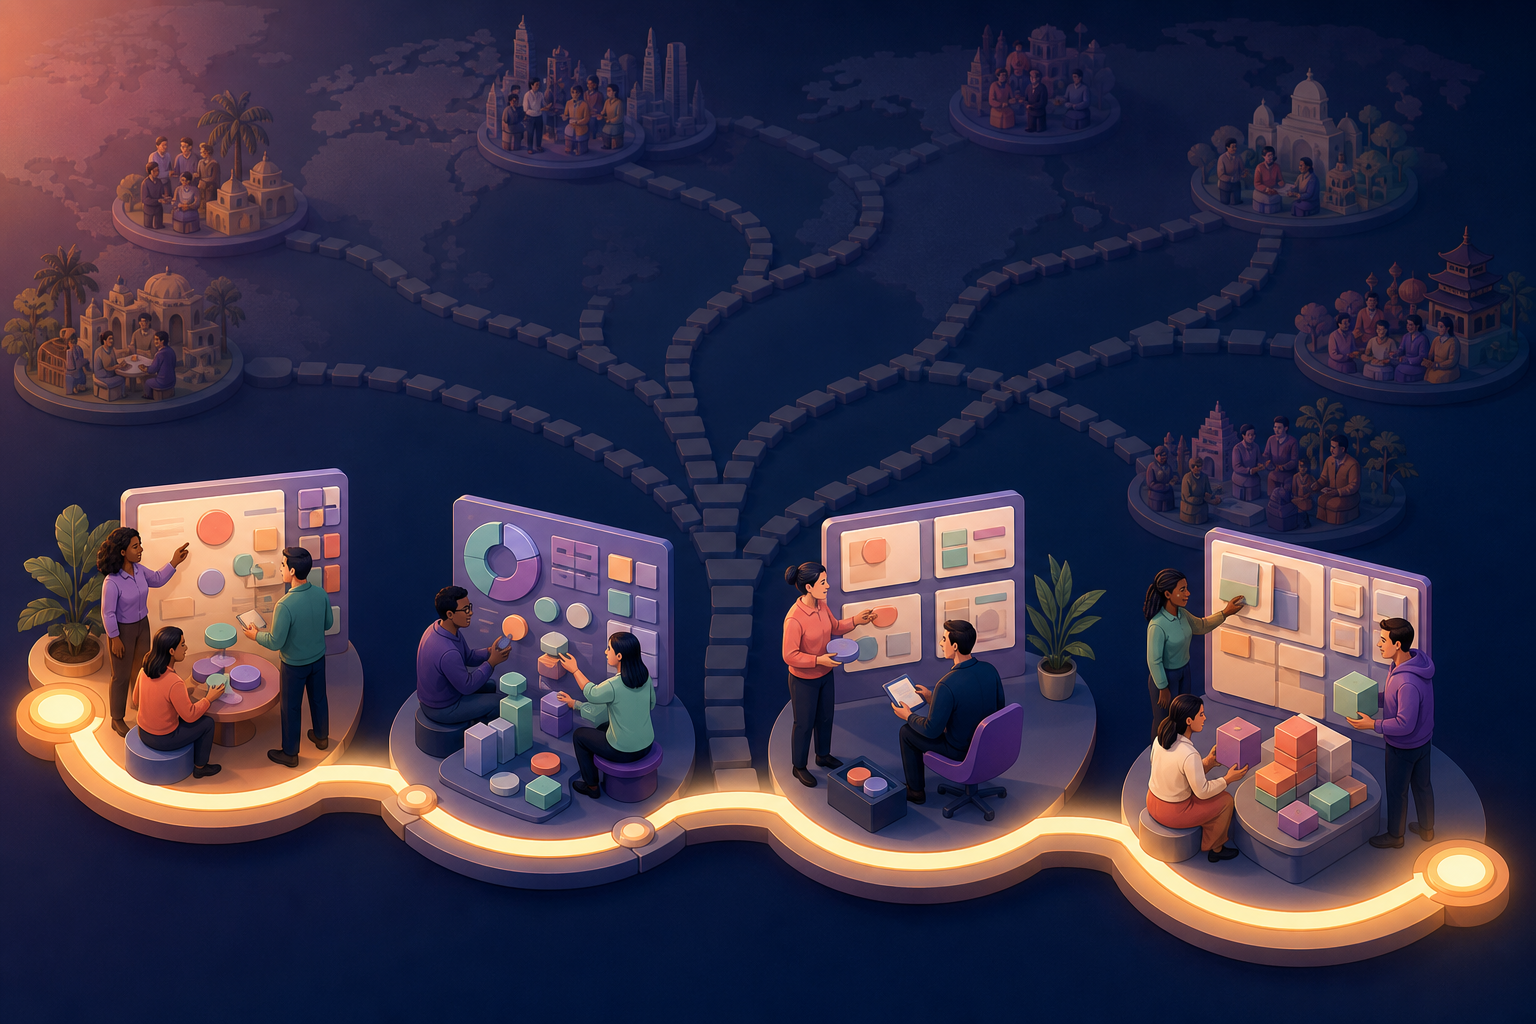
    A small team completes one illuminated four-stage workflow while unopened paths extend toward additional regions.

    A broad launch can hide where confusion begins. Run a limited pilot around one recurring task that already causes translation friction. The task should have a clear start, a clear decision, and a handoff to another person.

    1. Define the result in one sentence. For example: a regional analyst can review an existing visibility finding, explain what it means, and pass an unambiguous recommendation to the content owner without reverting to the team’s fallback language.
    2. Record the current path. List the screens, decisions, terminology, and handoff involved in the task. Capture screenshots only where they clarify a critical state, and avoid placing sensitive information in the test record.
    3. Repeat the task in the preferred interface language. Use the same workspace and the same underlying item so the interface language is the main variable.
    4. Review with two perspectives. A fluent user should judge whether the language is natural and understandable. A system owner should verify that the user interpreted the controls, states, and resulting action correctly.
    5. Test the return path. Confirm that the user knows how to switch back to an agreed fallback language if a translated label, message, or support step becomes unclear.
    6. Decide from observed blockers. Expand only when the person can complete the task and hand off the result without guessing at terminology or meaning.

    Keep an issue log during the pilot. For each problem, record the selected interface language, location in the application, displayed wording, intended meaning, screenshot, operational impact, workaround, owner, and status. A note such as “translation seems odd” is difficult to act on. A note that identifies the exact label and the decision it disrupted is useful.

    Do not grade the pilot on whether every phrase sounds elegant. Grade it on whether the user can understand the state of the work, choose the intended action, recognize errors, and communicate the result accurately. Those are the conditions that determine whether multilingual access improves operations.

    Keep interface, measurement, interpretation, and content separate

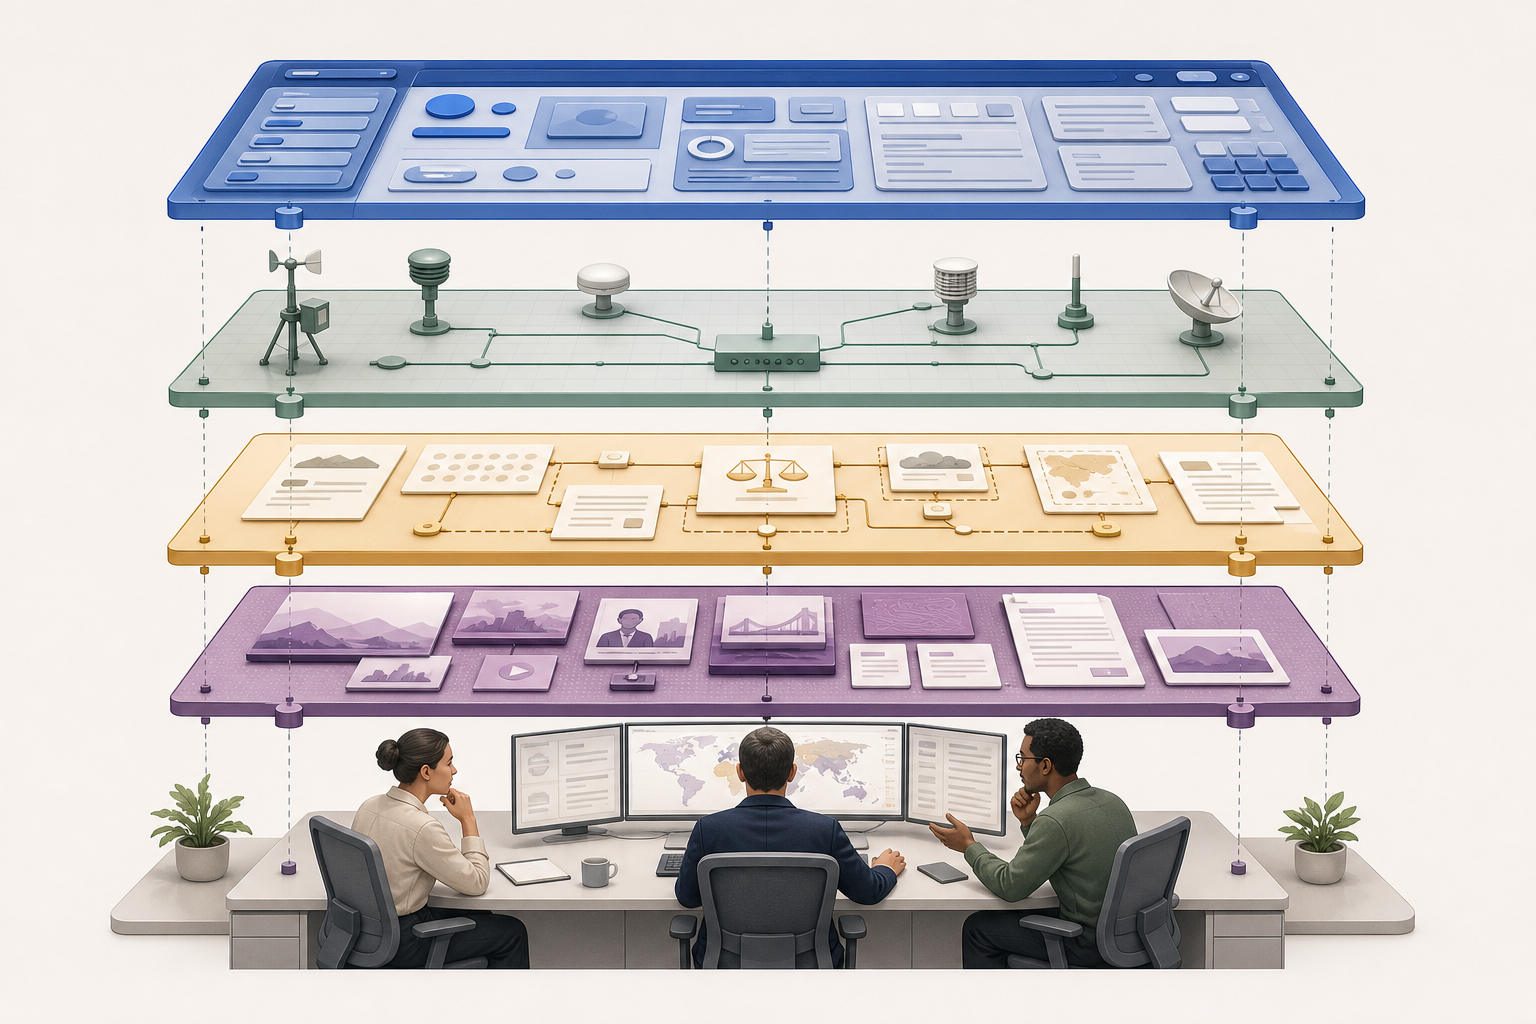
    An analyst and two colleagues examine four separated layers representing interface, measurement, interpretation, and content.

    A lightweight record prevents a translated interface from creating false confidence about the rest of the analysis. Attach the following information to any multilingual AI visibility finding that could influence strategy or publication.

    LayerWhat to recordWhat can go wrong if it is omitted
    InterfaceThe language selected when the work was completed and the date it was checkedA later reviewer may mistake translated labels for a change in the underlying research context
    Research inputThe exact original-language query, prompt, topic, or entity nameA translation can hide a change in intent, phrasing, or entity meaning
    Measurement contextThe market, audience, AI surface, model, and other settings relevant to the findingResults from different contexts may be compared as though language were the only difference
    InterpretationThe native-language conclusion plus a short shared-language explanation where neededThe regional nuance can disappear during the handoff
    Content actionThe target locale, page or asset, decision owner, and intended changeA useful finding may turn into generic translation instead of a market-specific improvement

    Preserve original-language research inputs as immutable evidence. Add translations beside them; do not replace them. If a phrase has no clean equivalent, annotate the intended meaning and the uncertainty instead of forcing a polished translation. This gives reviewers enough context to distinguish a real market difference from a wording difference.

    Apply the same discipline to comparisons. Two prompts written in different languages should remain separate rows unless someone qualified in both languages has confirmed that they express the same intent. Even then, label the relationship as an analytical judgment rather than treating one prompt as a mechanical copy of the other.

    Turn native-language access into a better decision process

    The practical benefit does not come from translated menus alone. It comes from giving the person closest to a market a cleaner route into the analysis and a defined role in the resulting decision.

    A reliable handoff can follow this sequence:

    1. The regional reviewer interprets the finding. They work in their preferred interface language and write the conclusion in the language that preserves the market’s meaning most accurately.
    2. The original evidence stays attached. Exact prompts, queries, entity names, and relevant context travel with the conclusion.
    3. A shared-language explanation supports coordination. This should explain the decision, not replace the original evidence. Terms with no direct equivalent should be flagged.
    4. The measurement owner checks definitions. They verify that the team is using the same metric definitions and comparing compatible contexts.
    5. The content owner assigns an action. The handoff names the target locale, asset, owner, and intended outcome rather than ending with a general observation.

    Build a small operational glossary alongside this workflow. Include only terms that can change a decision: product states, measurement labels, workflow statuses, recurring market concepts, and action verbs. For each entry, record the approved translation, a plain-language definition, terms that must remain untranslated, the owner, and the last review date.

    Do not try to standardize every sentence a team might write. Standardize the words that affect interpretation and action. If two specialists disagree, divide authority clearly: the regional owner decides local meaning, the system owner explains platform mechanics, and the content owner governs publication style. Record unresolved ambiguity instead of letting the loudest translation become the default.

    Govern the beta as a working dependency

    Because the selector is in beta, build a workflow that can tolerate wording or behavior changing. Permanent training material based only on screenshots will age quickly. Document the purpose of each step in text, then use screenshots as supporting context rather than as the procedure itself.

    Use event-based revalidation instead of choosing an arbitrary review schedule. Recheck a workflow when a new language is introduced to your team, when the application changes a critical screen, when the team changes its process, or when multiple users report confusion around the same term. That focuses effort where the risk has actually changed.

    Your operating guardrails should include an agreed fallback language, an owner who consolidates translation issues, a glossary for decision-critical terminology, and a route for escalating problems that stop work. Keep local workarounds in the shared issue log. Otherwise, each region may quietly invent a different meaning for the same control or status.

    Key takeaways

    • Profound’s App Language Selector is a beta feature that makes the platform available in more than 30 languages.
    • Interface language, research language, measurement context, and publication language are separate layers.
    • Pilot one complete workflow with both a fluent reviewer and a system owner before expanding access.
    • Preserve original-language prompts and queries; add translations beside them instead of overwriting them.
    • Manage terminology, handoffs, fallback access, and beta issues as operational assets rather than informal knowledge.

    Choose one regional workflow that creates repeated translation work and write its expected outcome in a single sentence. Test it end to end in the user’s preferred language. If the finding can move from review to action without ambiguity, expand deliberately. If it cannot, classify the blocker as interface, measurement, interpretation, or content. Each category has a different fix, and identifying the right one is the fastest way forward.

    References