Your team can probably make more content with AI. That doesn’t mean your marketing operation has become more intelligent. If briefs, data, approvals, assets, distribution, and measurement still live in separate workflows, AI simply helps the fragments move faster.
AI-driven marketing engineering solves a different problem: how to turn customer signals into controlled decisions, useful experiences, and measurable learning. The goal is a marketing system that can adapt without surrendering brand judgment, factual accuracy, or human accountability.
The real shift is from campaigns to closed-loop systems
A conventional campaign follows a line: write the brief, produce the assets, launch them, measure the result, and start again. That structure works when the environment remains stable long enough for the entire cycle to finish. It becomes restrictive when customer behavior changes while the campaign is still running.
Marketing engineering replaces that line with a loop. Signals enter the system, a rule or model interprets them, an approved response is activated, the outcome is observed, and the next decision incorporates what was learned. This is the practical meaning of moving from finite campaigns to continuously adapting marketing systems.
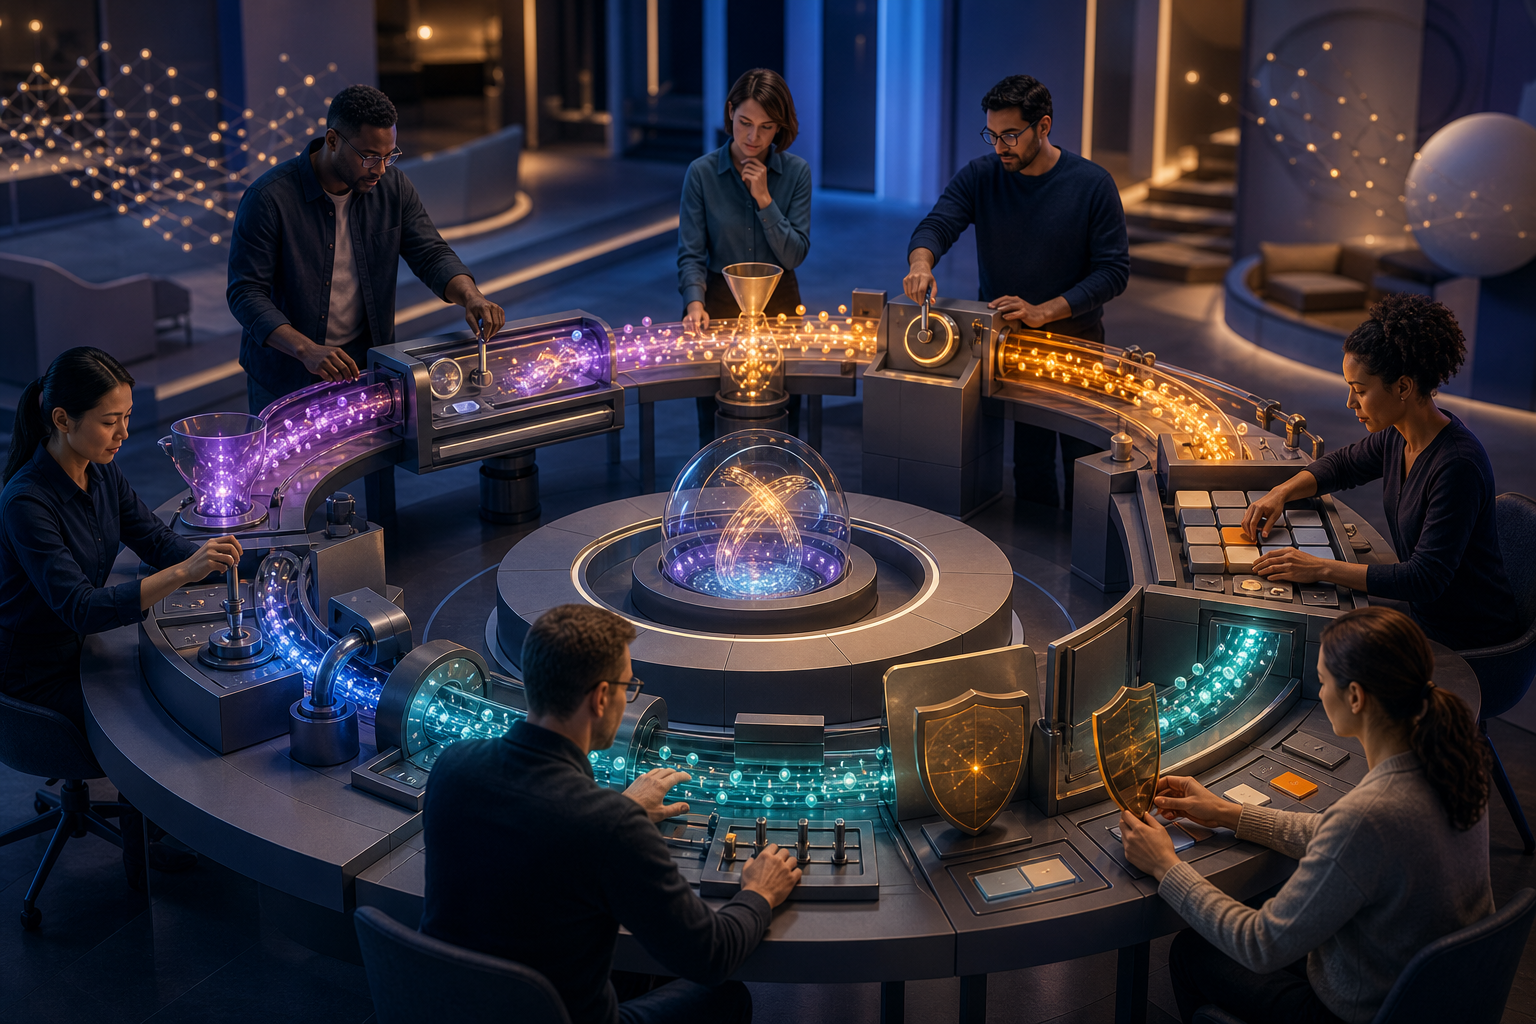
A workable system has five connected layers:
- Signal layer: Collect the events that matter to the decision, such as a search, click, content interaction, form submission, purchase, or support question. Record where each signal came from, what it means, and whether it is fresh enough to use.
- Decision layer: Translate a signal into an eligible action. The mechanism might be a fixed rule, a scoring model, an AI classifier, or a person reviewing a recommendation. Give every decision a defined input, output, owner, and fallback.
- Asset layer: Maintain approved content components, offers, claims, evidence, calls to action, and brand constraints. AI should select from or work within this governed inventory instead of improvising from an empty prompt.
- Activation layer: Deliver the selected response through a page, email, ad, chatbot, sales workflow, or another customer-facing surface. Preserve the decision and asset version that produced each experience.
- Learning layer: Observe whether the intended action occurred, check for unwanted effects, and route the result back to the owner of the decision. A dashboard without a path to a changed rule, asset, or experience is reporting, not learning.
Draw these layers for one current workflow. For every handoff, write down the input, output, system of record, responsible owner, and failure behavior. Missing ownership and undefined fallbacks will usually cause more trouble than the model itself.
Do not wait for a perfect panoramic customer profile before you begin. Build the smallest decision-specific view that can support the use case. A system choosing an answer for a product page may need the visitor’s expressed question and the page context; it does not automatically need every historical interaction your company has stored.
Design the smallest useful feedback loop first
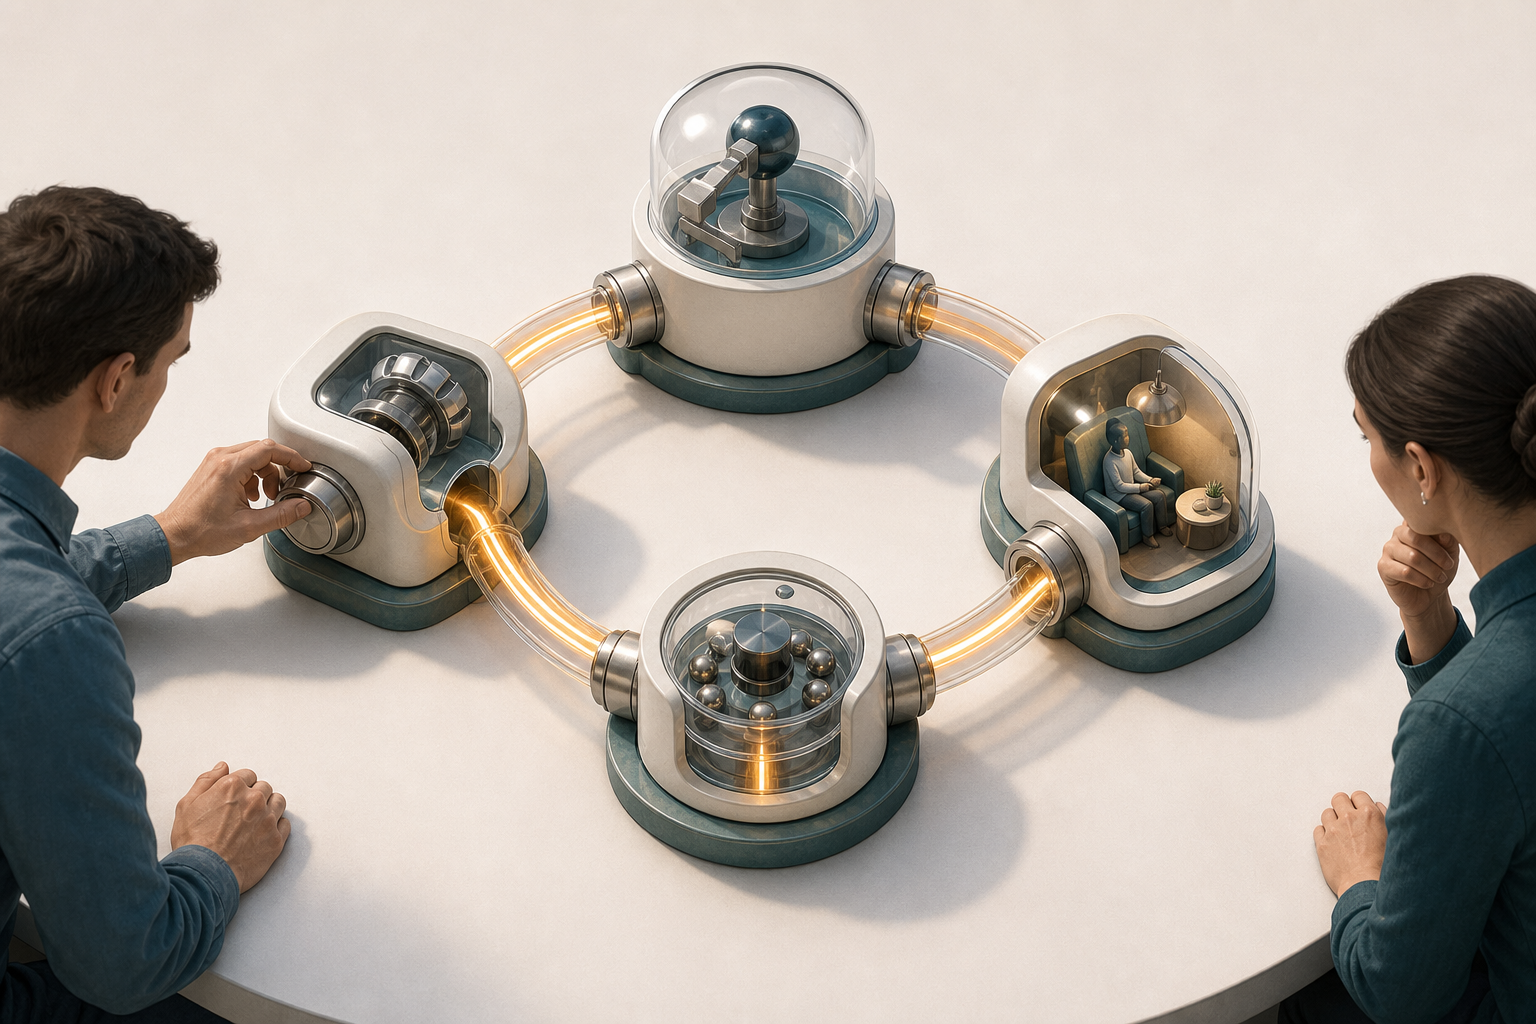
The safest first use case has a narrow input, a bounded decision, an approved set of outputs, and an observable result. That boundary makes the workflow easier to inspect and gives you somewhere to intervene when the AI is wrong.
Suppose a B2B product page attracts several kinds of questions. Your first loop could classify the question being expressed, select one approved answer module, expose the relevant next action, and record whether the visitor continues to the supporting material or conversion step. It should not rewrite the entire page, invent product claims, choose an offer, and alter audience targeting in the same run. Too many simultaneous decisions make both the risk and the result difficult to interpret.
Use this sequence to define a closed loop:
- Name the business decision. Write it as a choice the system must make, not as a vague goal. For example: choose the most relevant approved answer module for the question expressed on this page.
- Define the eligible audience and context. State where the decision may run and where it must not run. Include consent, geography, account status, page type, and other constraints that genuinely affect eligibility.
- Select the minimum necessary signals. Document the meaning and origin of each field. Do not feed every available attribute into the model merely because it exists.
- Constrain the possible outputs. Specify approved content, actions, claims, and formats. Provide a neutral default for cases the system cannot classify safely.
- Choose the activation point. Start with one surface so you can identify which experience produced the response. Expanding across channels before the first loop is observable creates an attribution problem.
- Define the outcome and countermetric. Pair the intended result with a signal that can reveal damage. A higher click rate, for example, should not be accepted blindly if corrections, complaints, unsubscribes, or low-quality conversions also rise.
- Assign review and rollback ownership. Name the person who can pause the workflow, restore the previous version, and decide whether a failure came from the data, decision logic, content, or activation.
Make every AI workflow pass acceptance criteria
An AI workflow is not ready merely because it produces a plausible output. Test it against operational acceptance criteria:
- Traceable: You can identify the input data, decision rule or prompt, model configuration, asset version, and resulting action.
- Bounded: The system can act only within its declared audience, channels, claims, and permissions.
- Reversible: An owner can disable the automation and restore a known safe version without rebuilding the workflow.
- Observable: Failures, fallbacks, constraint violations, and missing data are visible instead of silently discarded.
- Reviewable: High-impact, unsupported, unusual, or low-confidence outputs can be routed to a person before publication or activation.
- Comparable: The changed experience can be evaluated against a baseline, holdout, or controlled alternative appropriate to the use case.
Change one major part of the loop at a time when you need to understand causality. If you replace the model, prompt, audience logic, offer, and landing page in one release, the resulting movement may be real, but it will not tell you which decision to keep.
Turn content into governed, reusable components
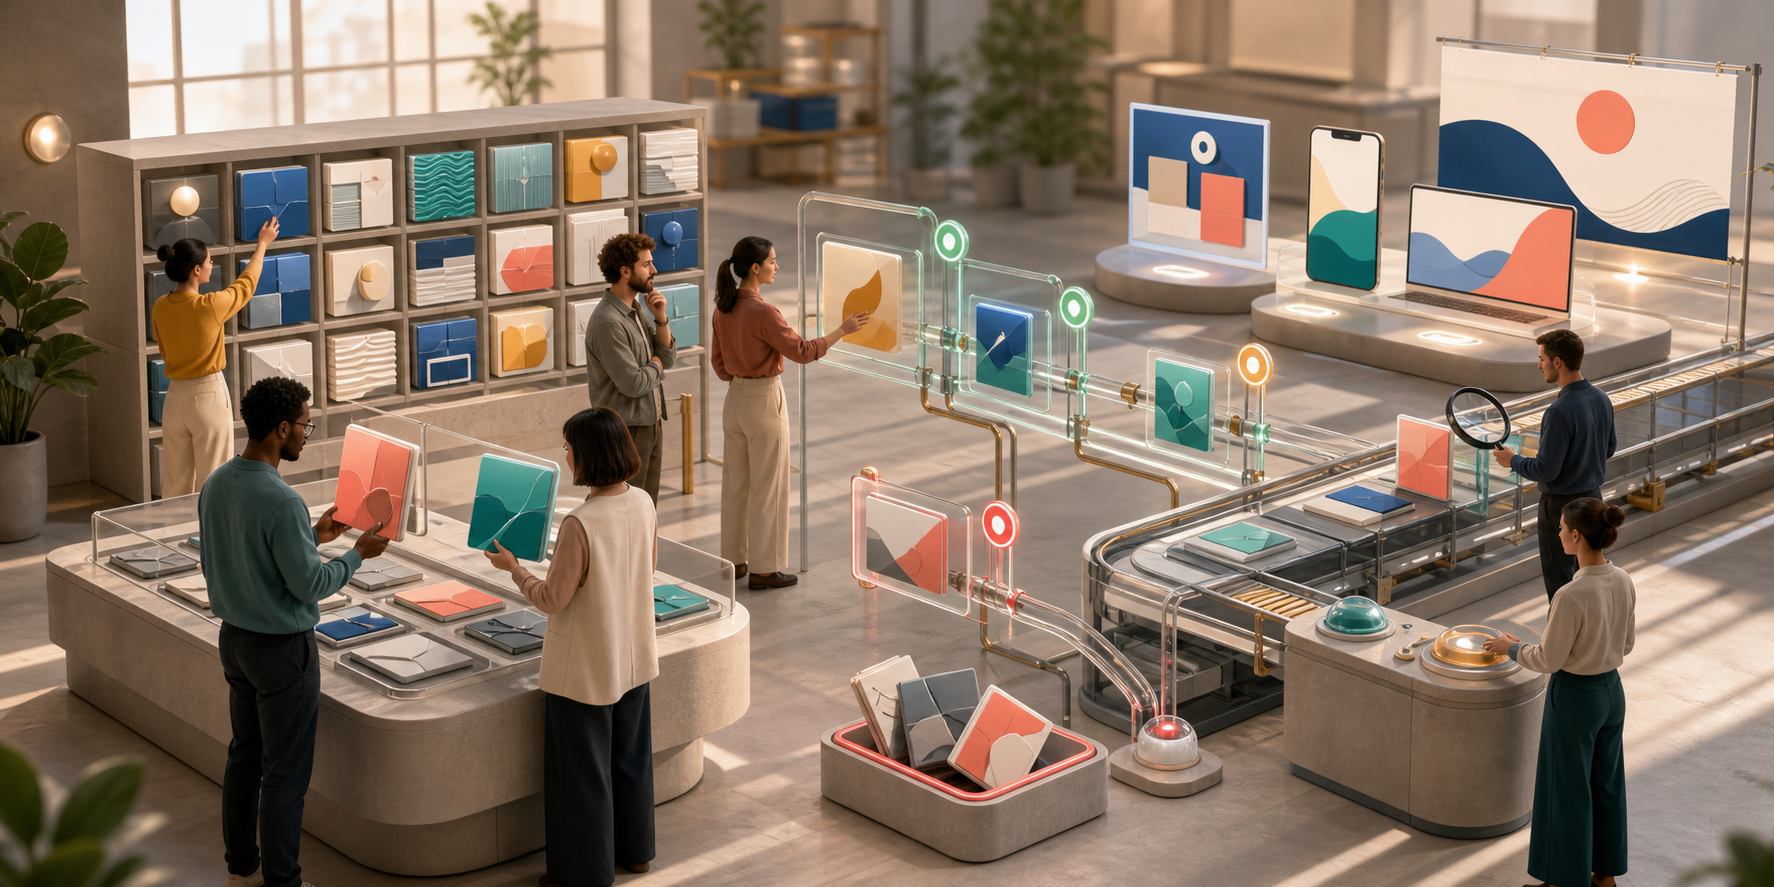
AI cannot reliably assemble a coherent customer experience when its raw material is a collection of unrelated documents. It needs content that is structured around meaning, permissions, and reuse.
Instead of treating a finished page as the smallest manageable asset, define content objects that can travel across pages, answer experiences, email, advertising, sales material, and structured data. This applies the same principles of modularity, reuse, and version control that make software systems maintainable.
A useful content object should carry more than copy. Give it fields for:
- the customer question or task it addresses;
- the approved answer, claim, or narrative;
- the evidence or internal source supporting that claim;
- the applicable product, audience, market, and journey state;
- required qualifications and prohibited interpretations;
- the owner and approval status;
- the last review point and conditions that require another review;
- eligible formats and channels;
- the intended next action;
- the identifier used to connect the object to analytics and structured data.
This model separates truth from presentation. A verified product fact can support a concise answer, a comparison module, an email paragraph, and a JSON-LD property without being copied into four disconnected files. When the fact changes, you can identify every dependent surface instead of hoping each channel owner notices.
For SEO, AEO, and GEO work, generate structured representations from the same governed facts used in visible content. JSON-LD should describe what the page actually establishes; it should not become a parallel database containing stronger or different claims. Using one verified record for both human-readable and machine-readable output reduces contradiction and makes corrections easier to propagate.
Model journeys as states, not a rigid funnel
A funnel assigns people to broad stages. A living journey architecture defines the state the customer appears to be in, the evidence supporting that state, the actions eligible from it, and the event that moves the customer elsewhere.
For each journey state, document three things:
- Entry evidence: the observable behavior or declared need that makes the state reasonable;
- Eligible next experiences: approved content and actions that help the person progress without forcing an irrelevant conversion;
- Exit conditions: the event that changes the state, ends the workflow, or suppresses further activation.
This creates a safer form of personalization. The system responds to an expressed need and known context rather than constructing an unnecessarily intimate profile. It also prevents common contradictions, such as continuing an acquisition sequence after a purchase or sending an introductory explanation after someone has requested technical detail.
Build an operating model that can govern continuous change
A continuous system changes the work of the marketing team. The unit of delivery is no longer only a finished campaign. It is a versioned improvement to a signal, rule, asset, experience, or measurement path.
Put proposed improvements into one backlog. Each work item should contain:
- the customer or business problem visible in the signals;
- the hypothesis about what should change;
- the affected audience and journey state;
- the signal, decision, asset, and activation components involved;
- the primary outcome and countermetric;
- the human owner of the result;
- the previous safe version and rollback method;
- the evidence required to expand, revise, or stop the change.
Short delivery cycles are useful because customer preferences and performance signals can move before a long planning process finishes. But adopting the language of sprints is not enough. Agile marketing depends on testing, iteration, and ongoing optimization, so every cycle must end with a decision: keep the change, revise it, widen it, or roll it back.
Ownership should cross functional boundaries without becoming vague. A marketing owner defines the customer and business decision. Content and brand owners govern allowable meaning. Data or engineering owners maintain signals, integrations, and reliability. The person accountable for the use case remains responsible for the final behavior even when AI makes an intermediate recommendation.
Put controls around AI before increasing its autonomy
Automation increases the reach and speed of whatever system you already have. If the content is contradictory, the signals are poorly defined, or no one owns the outcome, AI scales those defects along with the output.
Before allowing a workflow to publish or activate without review, require:
- an approved set of information the model may use;
- explicit prohibited claims, actions, audiences, and channels;
- version records for prompts, rules, models, and content components;
- a deterministic fallback when the required data is absent or the result is unsuitable;
- a log connecting the input, decision, output, and customer-facing action;
- a pause control and a tested route back to the previous safe behavior;
- a named owner who reviews exceptions and decides whether autonomy should expand.
Increase autonomy by decision type, not by declaring an entire channel automated. A system may be ready to classify a question while still requiring approval to create a new product claim. It may safely select an existing module but not set a price or make an eligibility decision. Those boundaries should remain visible in the workflow design.
Measure the loop at three levels
A single performance score hides too much. Separate your measurement into three levels:
- System health: missing or stale data, failed jobs, fallback frequency, broken activations, and untraceable outputs;
- Decision quality: correct matches, human accept-edit-reject patterns, constraint violations, and cases routed to the wrong state;
- Customer and business response: progress to the intended next action, qualified conversion, retention, revenue, or another outcome appropriate to the decision, paired with relevant countermetrics.
These levels tell you where to intervene. Weak business performance with healthy infrastructure may point to the decision or offer. Strong response accompanied by frequent corrections may indicate that the workflow is creating hidden operational or brand costs. A model-level metric cannot answer either question on its own.
Key takeaways
- AI-driven marketing engineering connects signals, decisions, governed assets, activation, and feedback in a closed loop.
- Start with one bounded decision whose inputs, outputs, result, fallback, and owner can be clearly observed.
- Structure content as reusable, versioned objects with evidence, permissions, applicability, and review ownership.
- Use the same verified facts for visible content and JSON-LD so human-facing and machine-readable claims stay aligned.
- Expand AI autonomy by decision type only after the workflow is traceable, bounded, reversible, observable, and reviewable.
- Measure system health, decision quality, and business response separately so you know what actually needs to change.
Choose one live marketing decision this week and map its five layers. If you cannot point to the signal, rule, approved asset, activation record, outcome, and owner, fix that chain before adding another AI tool. Once the loop is visible and governed, automation can make the marketing system more responsive without making it less accountable.