Category: Workflows

  • How to Build Reliable AI-Powered Content Operations

    How to Build Reliable AI-Powered Content Operations

    Your content backlog probably isn’t blocked by typing. It is blocked by everything around the typing: choosing what deserves attention, finding approved evidence, routing reviews, resolving exceptions, recording decisions, and knowing when a published page needs another pass. Add AI without fixing that system and you can create more drafts while making the operation harder to control.

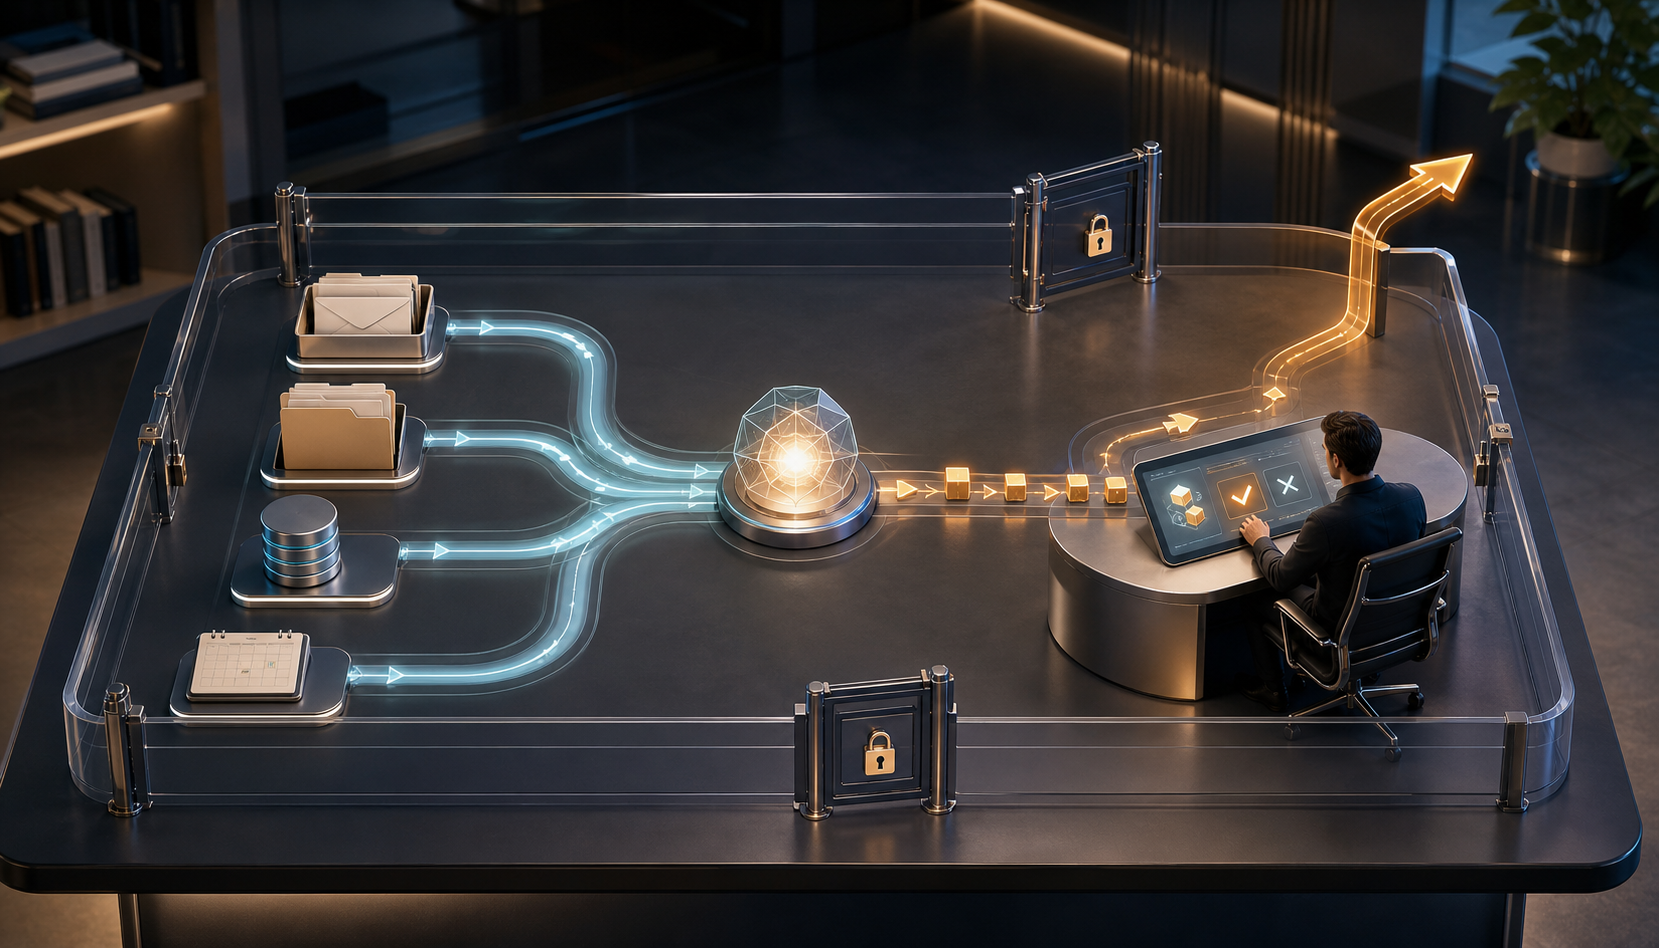
    AI-powered content operations works when models move structured tasks through a governed lifecycle. The goal is not maximum output. It is a faster, more observable path from a real audience need to accurate, useful, discoverable content.

    Decide what AI can own before choosing a tool

    The commercial appeal is easy to understand. Automation layers are being positioned to audit, analyze, and optimize content at scale, reducing the manual work wrapped around each asset. Treat that as a capability to validate against your own content, not as proof that every editorial decision should be automated.

    The useful dividing line is not creative work versus administrative work. It is controlled work versus judgment-heavy work. Before assigning a task to AI, ask whether you can name the correct inputs, express an acceptable output as observable conditions, detect a bad result before it causes damage, and reverse the action cleanly.

    Use those questions to place work into three operating lanes:

    • Execute automatically: low-risk tasks with explicit rules, such as applying an approved classification, checking whether required fields are present, comparing a page against a defined checklist, or routing a completed record to its next owner.
    • Recommend for review: tasks where AI can narrow the work but should not make the final call, such as identifying possible content gaps, grouping overlapping URLs, proposing internal links, drafting a brief, suggesting a passage-level revision, or flagging claims that may need evidence.
    • Reserve for accountable owners: decisions involving business priority, original positioning, disputed evidence, sensitive claims, final approval, publication, consolidation, deletion, redirects, or canonical changes.

    This classification prevents a common operating mistake: treating every AI-assisted task as if it has the same risk. A missing topic label and an unsupported product claim should not share an approval path. Neither should a metadata suggestion and a page retirement.

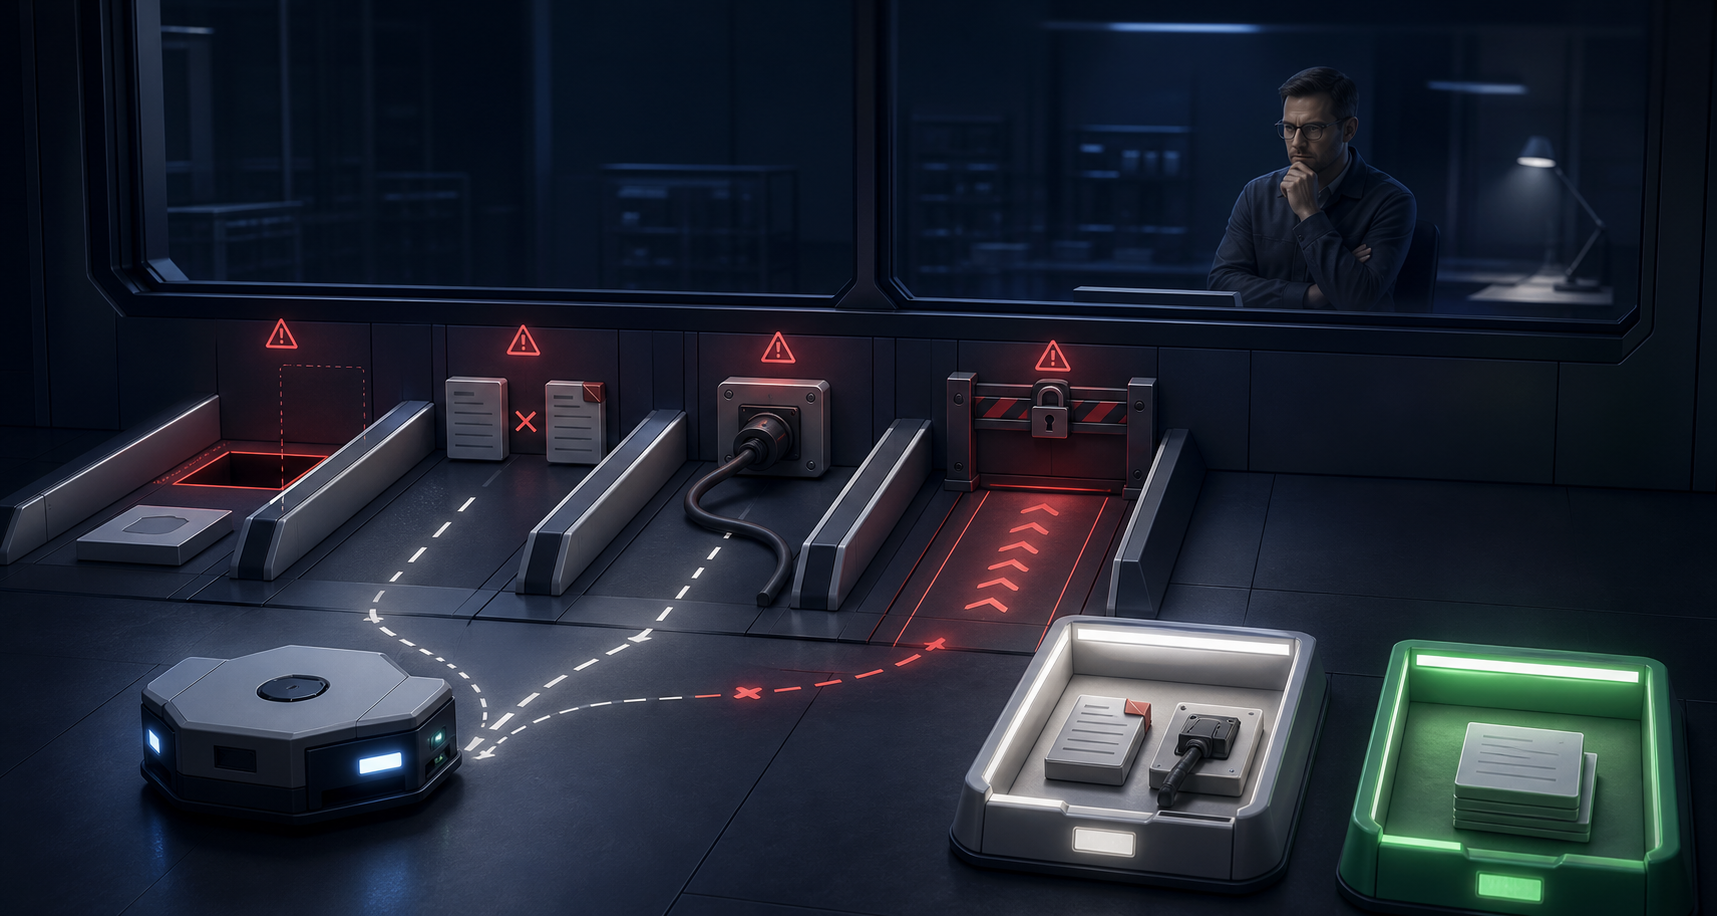
    Automation should also have a no-action outcome. If the available evidence is incomplete, the instructions conflict, or the requested change falls outside the approved scope, the correct result is an exception record. Forcing the model to produce an answer turns uncertainty into hidden editorial debt.

    Give every task a durable content record
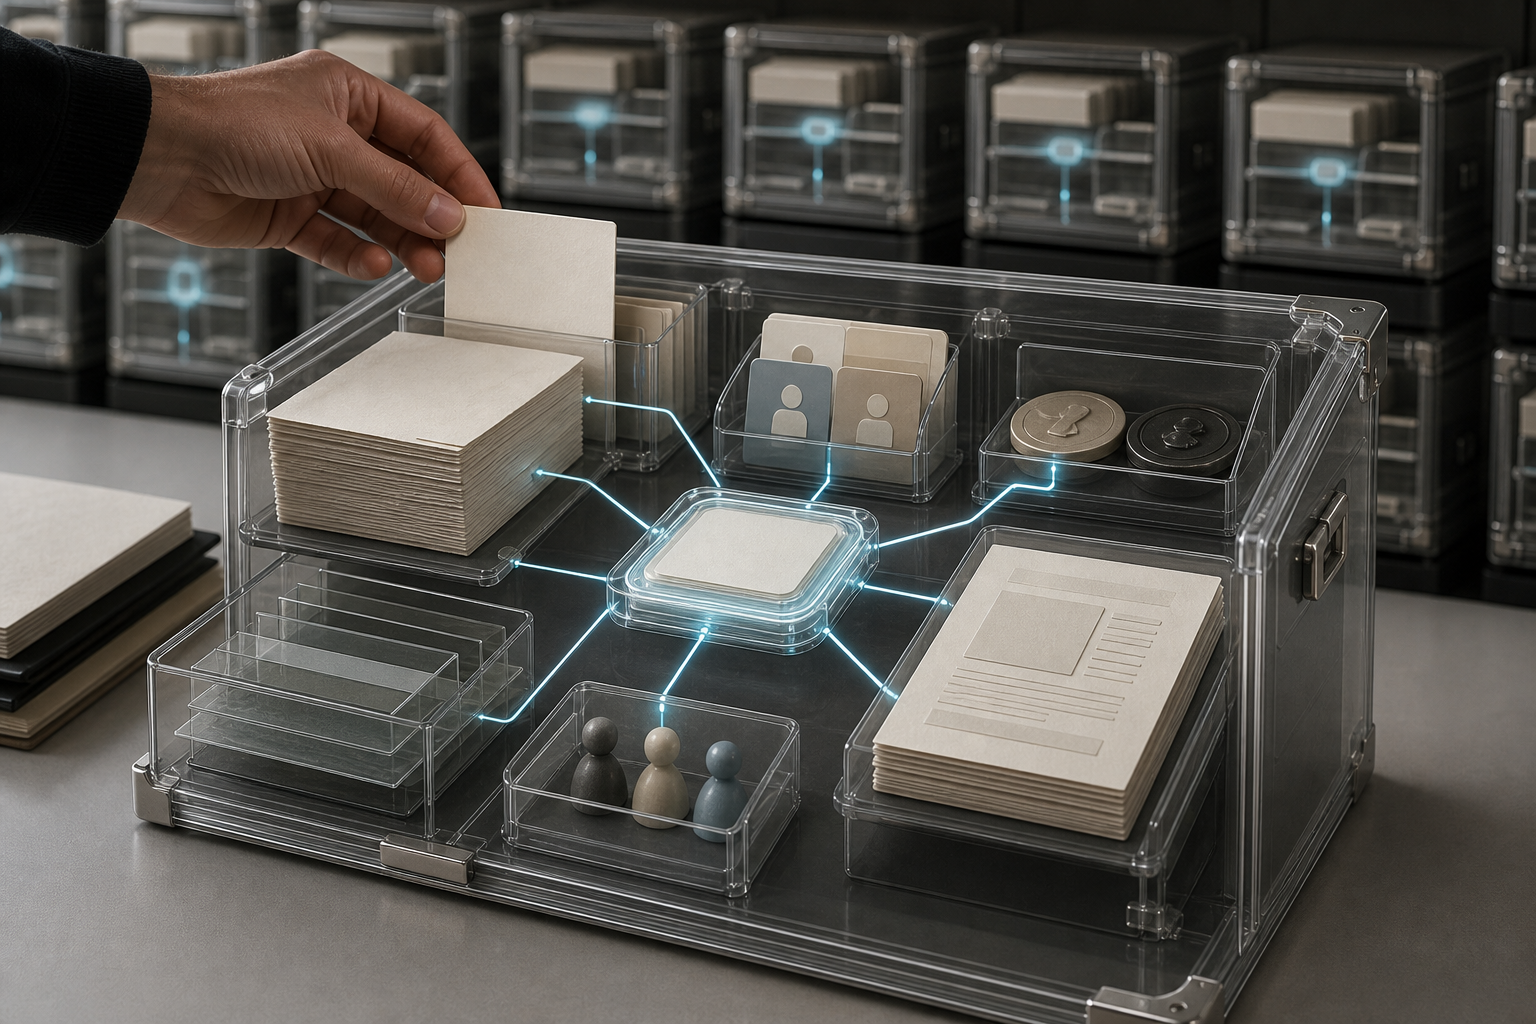
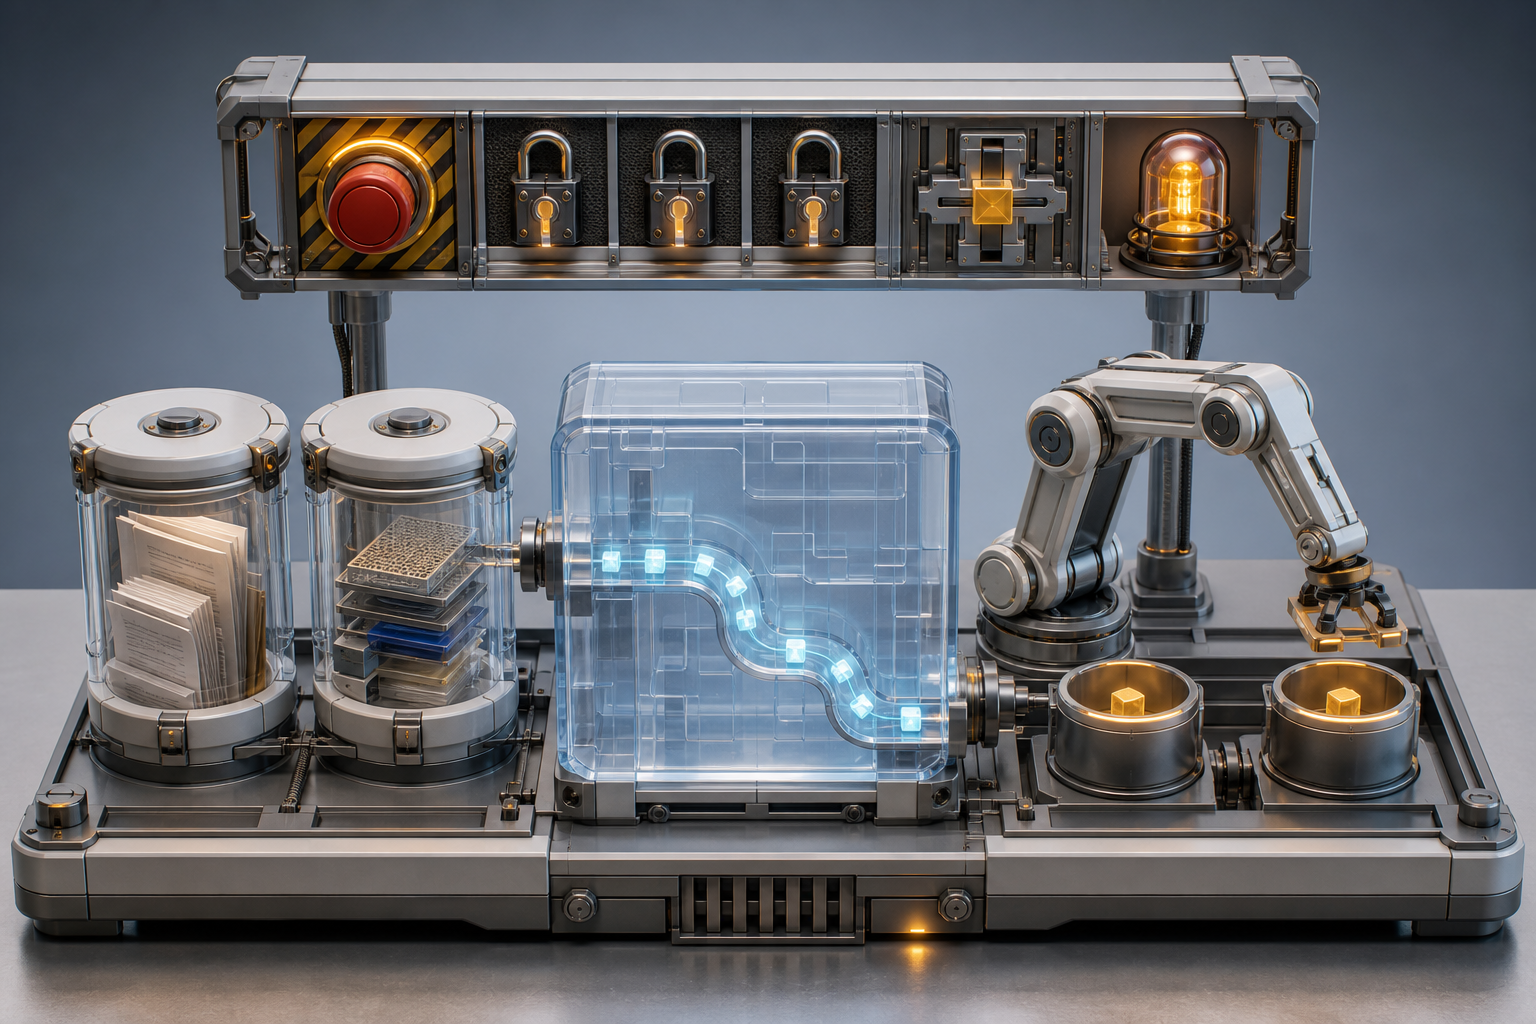
    A transparent modular case holds source documents, evidence cards, approvals, version layers, and a finished content page, with a hand adding a verified source card.

    A prompt is not an operating system. It describes what you want at a moment in time, but it does not reliably preserve why the work exists, which evidence is allowed, who owns the decision, what changed, or what should happen next.

    Build the workflow around a durable record for each content asset. That record can live in your CMS, project system, database, or orchestration platform, but it should expose the same core fields wherever the work runs:

    • Identity: asset ID, current URL or planned destination, content type, market, language, and related assets.
    • Purpose: intended audience, primary question or task, search intent, business purpose, and the action the page should help the reader take.
    • Evidence: approved references, source owner, claim-level notes, known uncertainties, and material that must not be used.
    • Ownership: content owner, subject reviewer, SEO owner, technical owner, and final approver where those roles apply.
    • State: lifecycle status, current workflow stage, blocking reason, next action, and the person or system responsible for that action.
    • Constraints: brand rules, regulatory or legal review requirements, format limits, localization needs, and protected language that must remain unchanged.
    • Change history: requested change, accepted change, rejected recommendation, approval record, publication event, and rollback information.
    • Measurement: target query set, baseline observations, relevant search and business outcomes, and the condition that should trigger another review.

    Without this record, each model run reconstructs context from whatever happens to be in its prompt. That creates inconsistent decisions and makes failures difficult to diagnose. With it, you can tell whether the problem came from missing evidence, an unclear instruction, an invalid output, a routing failure, or a human decision.

    Turn prompts into task contracts

    Once the content record exists, write a task contract for each automated step. A usable contract names the input fields, allowed context, requested operation, prohibited actions, required output fields, validation rules, no-change condition, and next route.

    For an audit task, do not ask the model to improve a page. Ask it to return an issue type, the affected passage or page element, the reason it failed a named rule, the evidence needed to resolve it, a proposed action, and a routing status. If approved evidence is missing, require an evidence-needed status and prohibit a factual rewrite.

    For an optimization task, define what optimization means. It might mean answering the primary question more directly, clarifying an entity, removing duplication, repairing a claim-source mismatch, aligning structured data with visible content, or improving an internal link path. If those outcomes are not named, the model is likely to equate optimization with rewriting, which creates unnecessary review work.

    Run a closed loop from audit to refresh

    A useful content workflow does not end when a draft appears. It carries an asset from detection through prioritization, evidence, revision, verification, publication, observation, and the next decision. You can use the following sequence as a practical starting point.

    1. Normalize the inventory. Give each asset a stable identity and map obvious relationships between canonical pages, localized versions, campaign variants, supporting pages, and structured data. Do not let the same URL enter multiple queues without a visible dependency.
    2. Audit against a fixed issue taxonomy. Separate accuracy risk, unsupported claims, intent mismatch, answer gaps, duplication, structural problems, internal link gaps, metadata defects, schema inconsistencies, and stale evidence. A fixed taxonomy makes findings routable and measurable.
    3. Triage before generating. Place work into operational buckets such as protect, improve, expand, consolidate, or retire. A valuable page with a material accuracy issue should not wait behind a speculative expansion. A weak page should not receive a full rewrite until you decide whether another asset should own the topic.
    4. Create an evidence-bound brief. State the audience problem, primary question, required subquestions, approved claims, named entities, allowed references, desired reader action, search role, and boundaries. Record unresolved questions instead of allowing the draft to conceal them.
    5. Make the smallest sufficient change. If a passage, heading, citation, internal link, or schema property can resolve the problem, do that before commissioning a full rewrite. Smaller changes are easier to verify, approve, attribute, and reverse.
    6. Verify the output against the brief and the original defect. Check whether the named problem was actually fixed, whether protected meaning changed, whether every material claim remains supported, and whether the revision introduced new duplication or ambiguity.
    7. Publish with a decision log. Store what changed, why it changed, who approved it, which workflow produced it, and how to reverse it. Update connected assets when the change affects internal links, canonical relationships, metadata, or structured data.
    8. Observe and route again. Compare the result with the intended search and business outcome. Keep it, revise it, escalate it, or return it to monitoring. The workflow is complete only when the next state is explicit.

    This closed loop matters for AI search as much as traditional search. A page needs a clear answer, unambiguous entities, support for consequential claims, descriptive structure, and visible content that agrees with its metadata and JSON-LD. Structured data cannot repair a vague answer, and a polished answer cannot make unsupported schema accurate.

    Keep content and schema in the same change set when one describes the other. If a workflow updates a product attribute, author identity, FAQ answer, date, organization detail, or other structured fact, route the visible page and its markup through the same verification gate. Otherwise, your automation can create two competing versions of the page.

    Put executable gates between generation and publishing
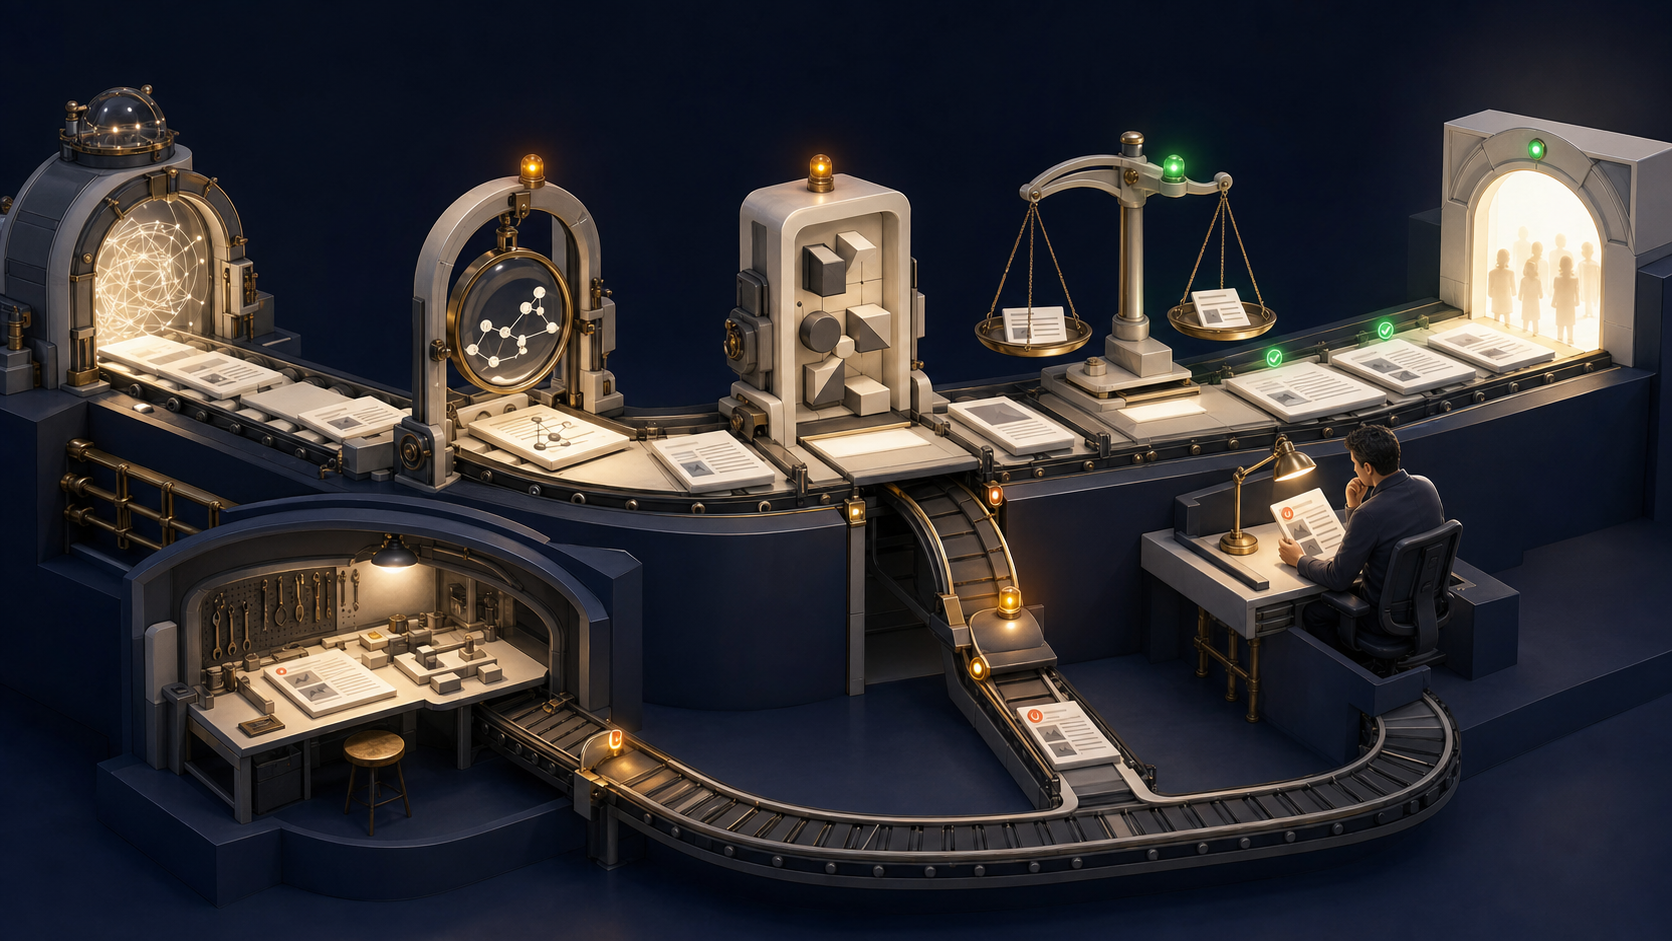
    Content page artifacts move through evidence, structure, policy, and human-review gates, while a failed item loops back for correction before publishing.

    A quality gate needs observable pass conditions. Instructions such as make it authoritative, improve the SEO, or ensure it is high quality are editorial ambitions, not tests. Replace them with checks that produce a pass, fail, or exception and identify who owns the next decision.

    GateMachine-checkable conditionHuman decisionFailure route
    IntakeRequired identity, purpose, owner, state, and constraint fields are present.The request belongs in this workflow and is worth doing.Return to the requester with the missing field or scope conflict.
    EvidenceMaterial claims map to approved evidence, and unknown or conflicting claims are flagged.The evidence supports the intended meaning and is appropriate for the audience.Send missing evidence to its owner; send conflicts to the subject reviewer.
    AnswerThe primary question has an identifiable answer passage, required subquestions are covered, and the requested action is present.The answer is accurate, useful, appropriately qualified, and not merely keyword-aligned.Return the named gap to revision without reopening unrelated sections.
    Search and AI readinessHeadings describe their sections, entities use consistent names, important references are linked, and structured data agrees with visible content.The page deserves to represent the organization in search results and generated answers.Route content defects to editorial and markup defects to the technical owner.
    PublicationRequired approvals, destination, metadata, internal links, change log, and rollback information are present.The residual risk is acceptable and the release timing makes sense.Block publication and assign the unresolved condition to an accountable owner.

    Treat model confidence as routing metadata, not evidence. A confident output can still rely on the wrong context, miss a qualification, or satisfy the requested format while failing the reader. Evidence, deterministic validation, and accountable review are separate controls.

    Your exception queue is part of the product, not a bin for failed automation. Every exception should carry the asset, failed rule, blocking reason, evidence captured, attempted action, next owner, and resolution status. Group the queue by reason so you can see whether the recurring problem is missing source material, vague briefs, conflicting policies, technical validation, or an overloaded reviewer.

    If you permit automatic publishing, confine it to transformations with approved inputs, mechanical validation, a recorded change, and a tested reversal path. Deletions, redirects, canonical changes, unsupported factual edits, and sensitive claims need accountable approval because a technically reversible change can still damage discoverability, trust, or compliance before anyone notices.

    Measure the operation, not the volume of output

    Draft count is easy to increase and easy to misread. It says nothing about whether the queue is moving, whether reviewers trust the output, whether published pages answer better questions, or whether AI is creating rework somewhere else.

    Build the dashboard around three layers:

    • Flow: queue age, active cycle time, blocked time by reason, handoffs, work returned to an earlier stage, and items waiting on each owner. These measures reveal where automation moved effort rather than removed it.
    • Quality: first-pass gate failures, unsupported-claim findings, post-publication corrections, exceptions by type, content-to-schema mismatches, and recommendations rejected by reviewers. Segment these by workflow, content type, and risk class.
    • Outcome: coverage of approved audience questions, search discovery for the intended queries, qualified actions after landing, citation or inclusion in relevant AI answers, and whether refreshed assets hold their intended role over time.

    Always pair a count with its denominator. A failure total is hard to interpret without the number of items reviewed. A fast cycle time can hide poor quality if corrections rise. A high acceptance rate can be meaningless if reviewers approve cosmetic edits while rejecting the consequential ones.

    AI-search observations also need a controlled record. Preserve the exact query, engine or model surface, market and language, account or personalization state where relevant, observation time, returned answer, cited pages, brand inclusion, and landing destination. Compare like with like. Otherwise, normal variation in the testing context can be mistaken for a content result.

    Use the measurements to change the workflow itself. Repeated evidence failures mean the intake or source library needs work. Repeated brand corrections point to an incomplete constraint set. Long blocked time identifies an ownership problem. High rework on full-page drafts is a reason to narrow the unit of change. The dashboard should tell you what to redesign, not merely what happened.

    Key takeaways

    • Automate a task only when its inputs, pass conditions, failure detection, and reversal path are explicit.
    • Keep purpose, evidence, ownership, lifecycle state, constraints, changes, and measurements in a durable content record.
    • Require every AI task to support no-change and exception outcomes instead of forcing a draft.
    • Use the smallest sufficient edit, then verify it against the original defect and the approved evidence.
    • Gate visible content, metadata, internal links, and JSON-LD as one connected publishing system.
    • Measure flow, quality, and reader or search outcomes together so faster production cannot hide greater rework.

    Start with the narrowest recurring queue that currently consumes useful editorial time: a stale-page audit, an evidence-backed refresh, an internal-link review, or a content-to-schema consistency check. Define its record, task contract, gates, exception routes, and measurements before widening the scope. When that workflow can move predictably without hiding uncertainty, you have a foundation worth scaling.
    References

  • AI Marketing Operations: Move Faster Without Losing Brand Control

    AI Marketing Operations: Move Faster Without Losing Brand Control

    Your team can now generate campaign concepts, creative variants, audience-specific copy and performance summaries faster than a traditional request can move between departments. That speed is useful, but it also exposes every weak approval rule, scattered brand document and unreliable data handoff in your operation.

    The answer is not another collection of AI tools. You need an operating system that tells AI what it may do, gives it reliable brand context, checks the consequences and feeds results back into the next decision. Build that system well and you can move faster without turning brand management into a permanent cleanup exercise.

    Give AI a clear operating envelope

    AI-enabled marketing operations should begin with a workflow, not a product. AI can support personalization, predictive insight, content production, customer experience and digital presence, but those capabilities do not tell you where automation belongs in your business.

    Choose a recurring marketing job and map how it works before adding AI. If nobody can explain where the input comes from, who owns the decision or what happens when the output is wrong, automation will only make the ambiguity run faster.

    Map the complete decision path

    Document the workflow in operational terms:

    1. Trigger: Define the event that starts the work, such as a new lead, an approved campaign concept, a reporting deadline or a change in performance.
    2. Inputs: Identify the customer data, campaign data, approved claims, brand rules and channel constraints needed to make the decision.
    3. Transformation: State exactly what AI should classify, generate, summarize, predict or recommend.
    4. Decision: Name the person or rule that determines whether the output proceeds, returns for revision or stops.
    5. Action: Specify which system may be changed, which audience may receive the output and which permissions are required.
    6. Evidence: Record what was produced, what was approved, what changed and what business or brand outcome followed.

    This map separates useful automation from vague ambition. Generate variants is not a workflow. Generate channel-specific variants from an approved concept, verify every claim, send them to a named reviewer and retain the final edits is a workflow.

    Grant autonomy according to consequence

    A positionless marketing model can bring data, creativity and optimization into the same working loop. It does not mean every marketer should receive unrestricted access to customer records, publishing systems or campaign budgets. Faster execution still needs explicit decision rights.

    • Draft: AI creates an internal brief, summary or variation. Nothing reaches a customer or changes a live system.
    • Recommend: AI proposes a segment, route, response or optimization. A named person accepts or rejects it.
    • Execute within rules: The workflow performs a reversible action inside approved conditions, such as normalizing a tracking value or sending an exception into the correct queue.
    • Escalate: The workflow stops when data is missing, a claim lacks support, a request falls outside policy or an action could create material cost, legal exposure or reputational damage.

    Attach an owner to every level. The owner is accountable for the live workflow even if a vendor model, automation platform or specialist built part of it. AI can propose a budget change, for example, but it should not receive permission to spend beyond an approved rule merely because its recommendation sounds confident. Keep consequential actions behind human approval until you have reliable evidence that the narrower automation behaves as intended.

    This approach removes unnecessary handoffs while preserving specialist judgment. A marketer may be able to retrieve data, create assets and orchestrate a journey independently, while security, legal, analytics and brand specialists still define the boundaries that protect the business.

    Turn brand standards into system inputs

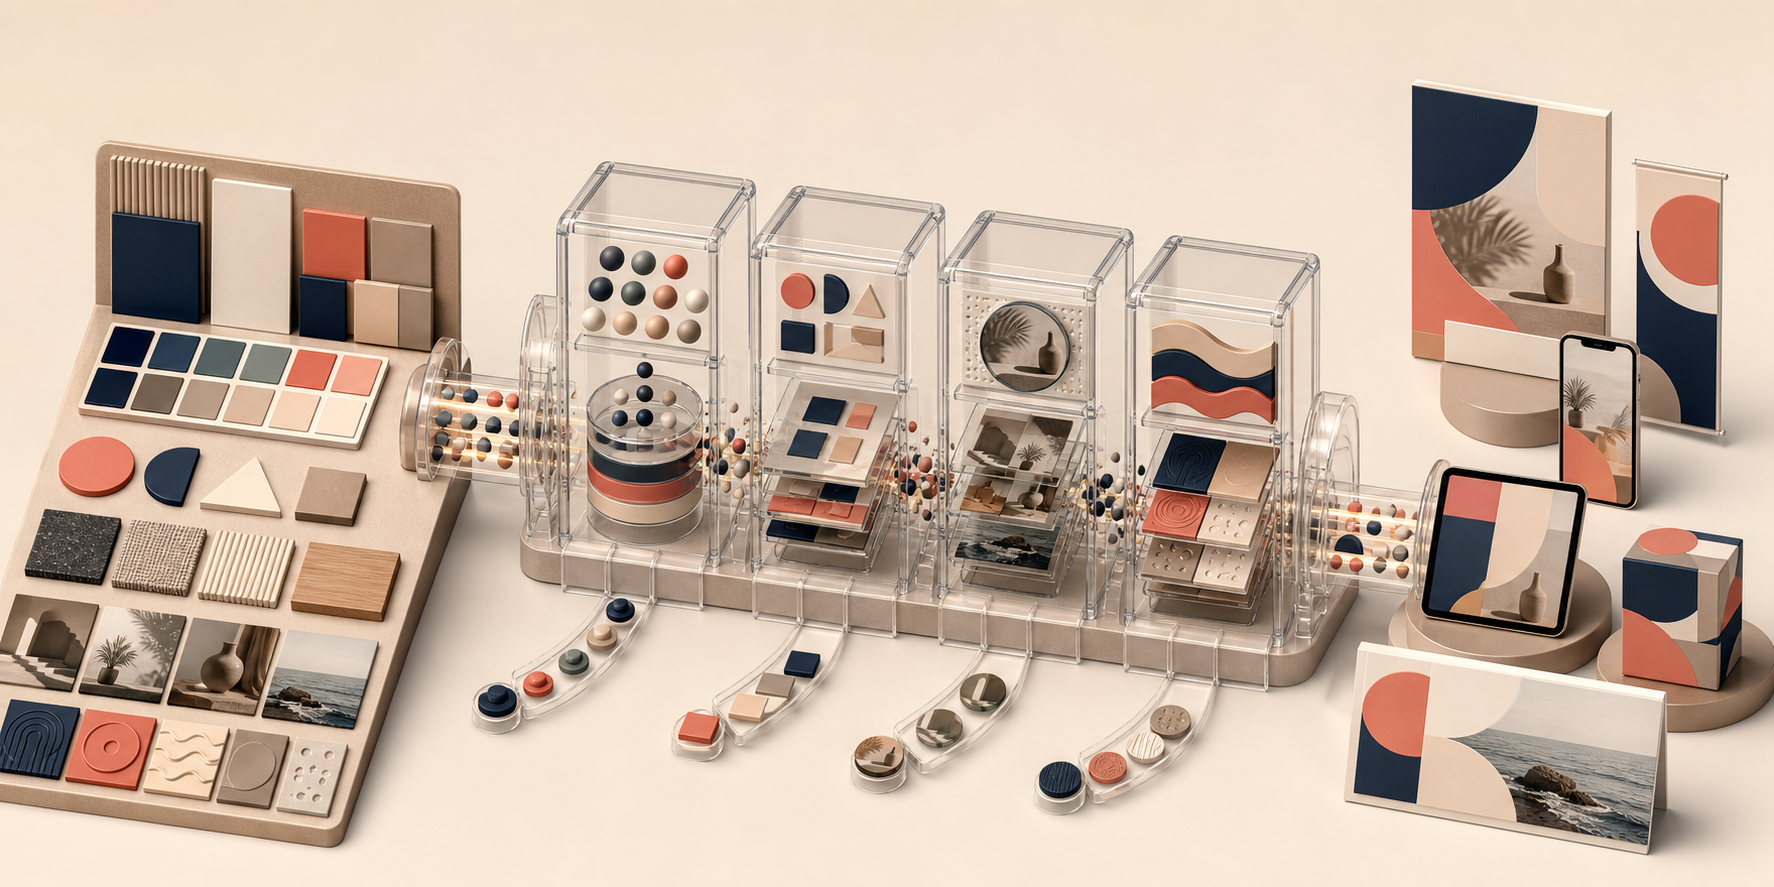
    Color swatches, textures and image samples pass through modular sorting chambers and emerge as a consistent family of campaign designs.

    A conventional brand guide is usually written for a person who can interpret context. An AI workflow needs more explicit instructions. Telling a model to sound clear, premium or human leaves too much room for interpretation, especially when different teams use different prompts and different versions of the brand rules.

    Create a machine-usable brand control pack. It should be short enough to retrieve for each task, structured enough to validate and owned by someone who can resolve conflicts.

    • Brand identity: Approved name, description, product names, product relationships and the URLs that represent the business.
    • Audience definitions: Who each message is for, what that person is trying to accomplish and which assumptions the copy must not make.
    • Message hierarchy: The primary promise, supporting themes and the distinction between an approved message and a claim that requires evidence.
    • Claim ledger: Approved wording, supporting evidence, permitted channels, restrictions, owner and review status. If a claim is absent or out of date, the workflow should flag it instead of improvising.
    • Voice rules: Concrete instructions for sentence length, terminology, point of view, tone and calls to action, supported by accepted and rejected examples.
    • Visual rules: Approved assets, treatments, layouts, accessibility requirements and prohibited combinations.
    • Channel constraints: What may change across ads, social posts, landing pages, email, search content and AI-facing brand descriptions.
    • Escalation rules: Topics, audiences, claims or actions that always require review by brand, legal, compliance, security or another accountable specialist.

    Do not hide this information in one large prompt that nobody owns. Store the control pack as versioned, reusable components. A creative workflow may need voice, visual and claim rules. A reporting workflow may need metric definitions and approved interpretations instead. Supplying only the relevant context makes conflicts easier to detect and revisions easier to govern.

    Record the version used for every externally visible output. When brand guidance changes, you can then identify which campaigns used the old rule and decide whether they require correction. Without that record, a policy update changes future prompts but leaves you unable to trace earlier decisions.

    Test the rules with adversarial examples

    Before connecting the workflow to a live channel, give it difficult examples from the work it will actually encounter:

    • A request that contains an unsupported performance claim.
    • A source asset that uses an obsolete product name.
    • Two brand instructions that point toward different tones.
    • An audience request that would require unavailable personal data.
    • A prompt asking the model to ignore the review process.
    • An input with missing campaign, market or channel context.

    The correct result is not always polished copy. Sometimes it is a refusal, a clarification request or an exception ticket. Treat those outcomes as signs that the control system is working.

    Build workflows around failure-safe boundaries

    Abstract campaign assets move through automated checks, a human review bay and a quarantine chamber in a branching workflow system.

    The best first workflow is frequent, bounded and reversible. Practical candidates already include lead enrichment and routing, UTM normalization, performance reporting and creative variation. Each has a visible input and output, but each needs a different automation boundary.

    WorkflowSafe starting boundaryMandatory checkUseful signal
    Creative variationGenerate variants only from an approved concept, asset set and claim ledger.Review factual accuracy, brand voice, visual treatment and channel suitability before publication.Approval without revision, reasons for rejection and performance by approved variation.
    Lead enrichment and routingRecommend or perform routing inside documented segments; send uncertain records to an exception queue.Check data permission, route quality, duplicate handling and whether the receiving team can act on the record.Reroutes, unresolved exceptions and downstream lead quality.
    UTM normalizationApply deterministic mappings to known values; quarantine unknown or conflicting values.Confirm that raw parameters are preserved and that normalized values match the analytics taxonomy.Invalid values, quarantined records and attribution completeness.
    Performance reportingRetrieve and structure platform metrics, then draft a summary without changing campaigns.Reconcile the underlying data and separate observed changes from AI-generated explanations.Data discrepancies, corrected interpretations and decisions produced by the report.
    AI search visibility monitoringTrack a stable set of relevant questions, audiences and competitors before recommending content changes.Inspect the underlying answers and distinguish a missing mention from an inaccurate or unfavorable brand narrative.Relevant mentions, description consistency, competitor gaps and recurring factual errors.

    Place human review where an error becomes consequential

    A generic human-in-the-loop requirement is too vague to govern anything. Name the reviewer, the exact evidence they see and the decision they are expected to make. A brand reviewer should not be asked to verify data extraction they cannot inspect. An analyst should not become the final authority on a legal claim simply because the claim appeared in a report.

    Separate the checks so failures have an owner:

    • Input validity: Are required fields present, current and permitted for this use?
    • Factual validity: Does every material claim trace to approved evidence?
    • Brand validity: Does the output use the correct identity, message, voice and visual rules?
    • Operational validity: Is the destination correct, is the action permitted and can it be reversed?
    • Measurement validity: Can the result be attributed to this workflow without confusing correlation with causation?

    Do not let the same AI output serve as both the work and its only approval. Automated checks can catch missing fields, prohibited terms, malformed links and taxonomy mismatches. A model can also highlight possible inconsistencies. Neither is a substitute for an accountable reviewer when an error could affect customers, public claims, regulated content or material spend.

    Design the failure path before the happy path

    Workflow automation often depends on APIs, JSON payloads, authentication and platform-specific integrations. That flexibility introduces real implementation and security work, and a misconfigured system can expose data or behave differently when an integration is incomplete.

    • Give each connector only the permissions required for its task.
    • Preserve the original input before normalizing or enriching it.
    • Prevent the same event from creating duplicate sends, records or campaign changes.
    • Route malformed, ambiguous and policy-breaking inputs into an exception queue.
    • Alert a named owner when a dependency fails or an error repeats.
    • Keep a readable log of the trigger, data version, brand-rule version, model or tool used, output, approval and final action.
    • Provide a kill switch and a documented rollback path before enabling live execution.

    These controls are not administrative decoration. They determine whether a problem remains one rejected draft or becomes a large batch of off-brand assets, incorrectly routed leads or corrupted attribution data.

    Measure the operation, not the volume of AI output

    Counting prompts, generated assets or automated tasks rewards activity. It does not show whether marketing improved. Your scorecard needs to connect operational speed with quality, business performance and brand representation.

    • Flow health: Track cycle time, queue time, failed runs, repeated attempts, manual interventions and unresolved exceptions.
    • Output quality: Track approval without revision, edit reasons, unsupported claims, data corrections and brand-rule violations.
    • Business outcome: Use the outcome the workflow is meant to affect, such as qualified demand, campaign efficiency, completed journeys or another metric your business already owns.
    • Brand outcome: Monitor whether approved identity, positioning and claims remain consistent across channels.
    • AI visibility: Examine whether relevant AI answers mention the brand accurately, represent its solution consistently and expose recurring competitor or messaging gaps.

    Specialized AI visibility platforms can provide persona-level, competitor-level and brand-narrative views. Treat those outputs as diagnostic evidence, not proof that one content change caused an AI model to respond differently. Keep the question set and evaluation method stable enough to distinguish a real pattern from ordinary answer variation.

    Capture a baseline before automation. When an A/B test is appropriate, define the primary outcome, guardrail metric, assignment method and stopping rule before launch. When controlled testing is not practical, compare like-for-like work and document other changes that could explain the result. A faster workflow that produces more corrections or weaker campaign outcomes is not an improvement.

    Buy tools for replaceability

    AI products and features change quickly, so avoid making the operating model depend on one vendor’s interface or a long commitment before the workflow is proven. Caution around long-term contracts is especially sensible while the toolset continues to evolve.

    Evaluate a tool against the system you need, not the most impressive demonstration:

    • Can you export prompts, templates, outputs, evaluations and logs in usable formats?
    • Can you replace the underlying model without rebuilding the entire workflow?
    • Does it support the authentication, access controls and data handling your systems require?
    • Can reviewers see the input, evidence and transformation behind an output?
    • Can failed actions retry safely without duplicating work?
    • Does it integrate with the systems that hold your actual campaign, customer and brand data?
    • How does cost change when usage moves from evaluation to routine production?
    • Can you disable it and return to a documented manual process?

    Use the same evaluation set when testing alternatives: representative inputs, edge cases, prohibited requests and previously rejected outputs. Score correctness, brand fit, required editing, operational reliability and total workflow cost. This makes a tool change an evidence-based decision rather than a reaction to a new feature announcement.

    Keep a shared workflow library and changelog as well. Record changes to prompts, brand rules, models, integrations, permissions and review steps. Regular knowledge-sharing matters because an improvement discovered by one campaign team should not remain trapped in that team’s private prompt history.

    Key takeaways

    • Start with a recurring workflow and define its trigger, inputs, decision owner, action and evidence before selecting an AI tool.
    • Grant AI more autonomy only when the action is bounded, reversible and covered by explicit escalation rules.
    • Convert brand guidance into versioned identity, audience, message, claim, voice, visual and channel controls that workflows can retrieve and validate.
    • Place named reviewers at the point where an error would affect a customer, public claim, regulated message, live system or material spend.
    • Measure cycle time and automation reliability alongside factual accuracy, brand consistency and the business outcome the workflow exists to improve.
    • Favor portable workflows, exportable records and reversible vendor commitments so the operation survives changes in models and tools.

    If your governance is still new, begin with a workflow whose mistakes are easy to detect and reverse, such as UTM normalization or a draft-only reporting summary. Define the baseline, brand context, exception path and owner, then run it on representative work before allowing a live action. The goal is not maximum autonomy. It is the smallest reliable loop that helps your team learn safely and earn the next level of autonomy.

    References

  • How to Build a B2B Go-to-Market Operating Model

    How to Build a B2B Go-to-Market Operating Model

    Your go-to-market strategy can be sound while execution still feels improvised. Marketing generates demand, sales qualifies it, enablement creates materials, and customer teams hear the objections, but each function uses a different definition of progress. That is an operating-model gap.

    You close that gap by specifying how buyer evidence becomes a decision, how work crosses team boundaries, where the official record lives, and how feedback changes the system. The goal is not a larger process manual. It is a small set of rules that helps your teams make the same good decision without rebuilding the process around every campaign or deal.

    Separate your strategy from the system that runs it

    A GTM strategy defines where you intend to compete and how you expect to win. A GTM operating model defines how people, workflows, systems, and decision rights turn those choices into coordinated action. An execution plan covers the work currently in motion.

    LayerQuestion it answersRequired output
    GTM strategyWhere will we play, for whom, and why should they choose us?Target market, buyer problem, value proposition, commercial motion, and strategic constraints
    GTM operating modelHow will teams repeatedly turn those choices into revenue work?Buyer stages, decision rights, handoffs, workflows, systems of record, controls, and feedback loops
    Execution planWhat are we doing now?Active accounts, campaigns, opportunities, experiments, deliverables, owners, and commitments

    The distinction matters because changing tools does not repair an undefined decision. Adding an AI assistant does not repair a weak handoff. Hiring another specialist does not repair incompatible stage definitions. Start with the outcome the system must produce, then decide which roles and technology support it. That follows an outcome-first Service as Software principle: the useful unit of design is the result, not the tool itself.

    Use the following questions as a completeness test. If the answers depend on whom you ask, the operating model is still implicit:

    • Which buyer and buying situation does this revenue motion serve?
    • What observable evidence moves an account from one stage to the next?
    • Who decides whether that evidence is sufficient?
    • What information must accompany a handoff?
    • Where is acceptance, rejection, or rework recorded?
    • Which signal causes the team to change targeting, messaging, channel use, or process?
    • Which decisions may AI support, and which still require human approval?

    Do not begin with the organization chart. Roles will change, and the same role name can carry different authority in different companies. Begin with a bounded revenue motion: a defined audience, problem, offer, route to market, and desired customer outcome. Build the operating model around that flow of value.

    Use buyer progression as the spine of the model

    A central illuminated path connects successive buyer situations while several business teams contribute evidence at different stages.

    Internal funnel labels are useful only when they correspond to something that has changed for the buyer. A label such as MQL describes an internal classification. It does not, by itself, tell sales what the buyer understands, what evidence exists, or what should happen next.

    Define stages as buyer states that your team can recognize from evidence. Starter language might include exploring a problem, validating an approach, resolving risk, committing to a decision, and beginning adoption. Those names are not universal. The important part is that each state has an observable entry condition and an observable exit condition.

    1. Write the audience, buying situation, problem, offer, and route to market on a shared brief. If those choices vary materially, you may be dealing with separate revenue motions that need separate rules.
    2. Name each buyer state in plain language. Avoid stage names that merely identify the department currently holding the record.
    3. Define entry evidence. Specify what must be known or confirmed before an account belongs in that state.
    4. Define exit evidence. Use a change in buyer commitment, understanding, access, or risk resolution rather than a seller activity such as sending an email.
    5. Assign an accountable owner, the required system fields, and the next commitment that advances the buyer.
    6. Define what happens when evidence is missing, the buyer pauses, or the account no longer fits. Recycling and disqualification are operating paths, not miscellaneous exceptions.

    A stage specification should be usable during live work, not only during training. Give each stage the following fields:

    FieldQuestion to answerExample of useful evidence
    Buyer stateWhat is now true for the buyer?The problem has been confirmed in the buyer’s own terms
    Entry conditionWhat evidence allows the record to enter?A relevant stakeholder has confirmed the operational consequence
    Exit conditionWhat must change before the record advances?The buyer has agreed to evaluate a defined approach
    Accountable ownerWho decides whether the condition is met?The role with the authority and context to accept the stage
    Required recordWhere can another team verify the evidence?A structured field plus a concise evidence note in the system of record
    Next commitmentWhat mutually understood action advances the buyer?An agreed review with the relevant participants and purpose
    Return pathWhat happens if the evidence is incomplete?Return to the prior owner with a recorded reason and required correction

    Test the definitions against active accounts. Give independent teammates the same evidence and ask them to classify the buyer state and identify the next action. If they reach different answers, do not add more dashboard fields yet. Tighten the stage language, evidence standard, or decision owner.

    This buyer-centered spine also keeps content connected to revenue work. Every important asset should support a specific buyer question, evidence requirement, risk, or next commitment. If nobody can name the buyer state and decision the asset supports, its place in the operating model is unclear.

    Give decisions and handoffs explicit owners

    Cross-functional collaboration does not mean collective accountability. A decision can have many contributors, but it needs a clearly identified owner with enough authority, information, and capacity to make the call. Otherwise, teams keep revisiting the same issue while execution moves ahead on incompatible assumptions.

    Keep a lightweight decision record

    Record recurring or consequential GTM decisions in a shared location. This is not a transcript of the discussion. It is the minimum context someone needs to execute the decision and know when it may be reopened.

    • Decision: State the choice in terms that can be acted on.
    • Owner: Name the role responsible for making and maintaining the decision.
    • Required inputs: Identify the buyer, market, operational, financial, or risk evidence needed.
    • Decision rule: Explain what would make one option preferable to another.
    • Contributors: List the roles that supply expertise without transferring ownership.
    • Record: Link the approved definition, workflow, message, or configuration affected.
    • Revisit condition: Name the new evidence or material change that would justify reopening the choice.

    Apply this structure to decisions such as target-account eligibility, stage acceptance, message approval, channel allocation, proof requirements, process exceptions, and permitted AI use. The owner may differ by decision. What should not change is the visibility of the ownership.

    Treat every handoff as a contract

    A handoff is not complete when the sending team changes a status field. It is complete when the receiving team can accept the work, understand why it matters, and take the next action without reconstructing the missing context.

    For each important boundary, document:

    • Trigger: The buyer evidence or operational event that starts the handoff.
    • Payload: The fields, notes, assets, permissions, and context that must travel with it.
    • Receiver response: The available outcomes, such as accept, reject, or return for correction.
    • Reason codes: A short, controlled set of explanations that can reveal repeated failure patterns.
    • Response expectation: The agreed service window and the event that starts it.
    • System of record: The place where status, evidence, ownership, and response are authoritative.
    • Escalation path: The owner who resolves a disputed definition or stalled boundary.

    Track acceptance and rework, not just handoff volume. High volume can look productive while the receiving team quietly discards weak records. Repeated rejection for the same reason usually points to a targeting problem, an evidence problem, an unclear definition, or a missing field. Fix that boundary instead of asking the sender to produce more volume.

    The same contract should cover the transition from sales to onboarding and from customer feedback back to marketing, product, and enablement. A GTM model is incomplete if it ends when a deal is marked won. The promises made during acquisition need to remain visible to the team responsible for delivering and expanding the relationship.

    Run feedback loops that change the work

    Four connected teams collect customer signals, identify patterns, update modular processes, and return the revised system to frontline work.

    A full meeting calendar is not a feedback system. Every operating ritual needs a defined question, required inputs, a decision it can produce, an owner, and a place where the result changes the workflow.

    • Flow review: Identify where buyer progress is blocked, where records wait, and where work returns for correction. The output is an owner and a change to the blocked path.
    • Market-signal review: Examine recurring objections, failed assumptions, competitive pressure, search behavior, and language used by buyers. The output may change targeting, positioning, content, or qualification.
    • Experiment review: Compare the original hypothesis, execution, observed signal, and decision. The output is to continue, change, stop, or design a better test.
    • Adoption review: Determine whether the intended users can perform the process inside their normal tools. The output is a workflow, training, field, or artifact change.
    • Promise-delivery review: Compare what acquisition teams promised with what onboarding and customer teams can deliver. The output is a corrected promise, delivery change, or escalation.

    Match the cadence to the rate at which useful evidence appears. Routing problems need an execution cadence because they obstruct current work. Positioning changes need enough accumulated market evidence to distinguish a pattern from an isolated comment. Do not use the same meeting rhythm for every decision merely because the calendar makes that convenient.

    Use a metric stack that exposes both business results and the mechanism producing them:

    • Outcome measures show commercial progress, customer value, and retention.
    • Flow measures show movement, waiting, conversion, and backlog across buyer stages.
    • Quality measures show acceptance, completeness, correction, and avoidable rework.
    • Adoption measures show whether the intended workflow and assets are actually being used.
    • Learning measures show which assumptions were tested and which decisions changed as a result.

    For every metric, document its definition, data source, owner, review context, and the decision it can trigger. A dashboard that cannot change a decision is reporting overhead. A dashboard whose definitions vary by function is a visual version of the operating-model problem.

    Put AI inside a controlled workflow

    AI should have the same operational discipline as any other part of the GTM model. Do not make adoption of an AI tool the outcome. Define the work it supports, the evidence it may use, the quality standard it must meet, and the accountable human decision.

    • Permitted input: Specify which customer, market, performance, and internal data may enter the workflow.
    • Bounded task: Define whether AI is classifying, drafting, retrieving, summarizing, recommending, or executing.
    • Acceptance criteria: State what makes the output accurate, relevant, complete, brand-safe, and usable.
    • Approval boundary: Identify what a person must verify before publication, customer contact, data change, or commercial action.
    • Audit record: Preserve the input context, output, reviewer, disposition, and downstream action where the risk warrants it.
    • Fallback: Define how work continues when the model, integration, or output is unavailable or unsuitable.

    For SEO, AEO, and GEO content workflows, acceptance may include traceable claims, a defined search or buyer intent, approved product language, clear ownership of structured data, and editorial review before publication. That connects AI-assisted content to the GTM system instead of allowing generated assets to accumulate without a buyer decision or distribution path.

    Earn sophistication through adoption

    A new operating model usually fails at the point of use, not at the level of the diagram. If a seller must leave the CRM, find a separate document, reinterpret a stage, and duplicate the evidence in another system, the designed workflow is competing with the actual job.

    Behavior change depends on fitting enablement into daily work. A polished deck cannot compensate for a process that requires extra steps at every deal. Put definitions, prompts, assets, approvals, and feedback controls where the relevant decision occurs. Train with live work, and observe where users hesitate, invent workarounds, or omit information.

    Use the Shu Ha Ri progression from fundamentals toward innovation as a practical maturity lens:

    • Stabilize the standard: Establish common language, buyer stages, owners, handoff rules, and an authoritative record. At this point, consistency matters more than customization.
    • Adapt from evidence: Change a bounded part of the model when recorded exceptions, buyer signals, or adoption friction reveal a real mismatch. Preserve the reason for the change so adaptation does not become drift.
    • Innovate on a stable base: Add custom automation, AI agents, new channels, or differentiated motions only after the underlying decision and feedback paths are visible. Automation scales ambiguity as readily as it scales good work.

    Roll out the model through a revenue motion that matters and is narrow enough to observe. Embed its required fields and decisions in the systems people already use. Remove duplicate paths where it is safe to do so, because leaving the old workflow available teaches users that the new model is optional. Keep an exception route for legitimate edge cases, but require a reason that can feed the adaptation loop.

    Before expanding the model, look for operational proof:

    • Independent teammates classify the same buyer evidence consistently.
    • Receivers accept, reject, or return handoffs with a recorded reason.
    • Teams can find the current decision, asset, and definition at the point of work.
    • Operating reviews produce documented changes rather than repeated discussion.
    • Exceptions reveal patterns that can improve the standard path.
    • AI-supported outputs have visible acceptance criteria, review ownership, and disposition.

    Key takeaways

    • A GTM strategy defines the choices; a GTM operating model defines how teams repeatedly execute and revise those choices.
    • Build the model around observable buyer progression, not departmental funnel labels.
    • Give every recurring decision an accountable owner and every cross-team handoff an acceptance contract.
    • Measure outcomes, flow, quality, adoption, and learning so you can see both the result and its mechanism.
    • Place AI inside a bounded, reviewable workflow with explicit inputs, acceptance criteria, approval, and fallback.
    • Standardize before you customize, then innovate only when feedback and adoption are reliable.

    Choose the revenue motion creating the most consequential friction now. Map its buyer states, write the acceptance contract for its weakest handoff, and assign the unresolved decisions. Once the people doing the work can point to the same evidence and know who decides what happens next, expand the model to the next boundary.

    References

  • OpenAI Agent Automation Tools: A Practical Build Guide

    OpenAI Agent Automation Tools: A Practical Build Guide

    You have a recurring marketing workflow that is too judgment-heavy for a simple rule and too repetitive to justify doing by hand. That is a sensible place to consider an OpenAI agent. The mistake is handing it a broad objective such as “manage PPC” or “run content operations” before you have defined what it may read, decide, change, and escalate.

    OpenAI’s AgentKit brings visual workflow building together with familiar tools such as Gmail and Dropbox, reducing how much glue code may be needed around an agent. That makes construction easier. It does not remove the harder work: designing a workflow that produces useful results without creating expensive surprises.

    Give the first agent a narrow outcome, not a department

    An agent is most useful in the gap between rigid automation and unrestricted human judgment. It can interpret messy inputs, choose among permitted actions, and use connected tools. It should not be treated as an autonomous employee with an implied understanding of your business.

    Start with a workflow that has a recognizable trigger, a bounded decision, a small set of tools, and an output you can inspect. A strong candidate can usually be described in one sentence: “When this event occurs, use these approved inputs to prepare this defined result for this person or system.”

    • Turn campaign data into an exception brief that identifies what needs a human decision.
    • Collect approved reporting inputs, prepare a dashboard entry, and draft the accompanying client summary.
    • Check draft ad copy against explicit brand rules and flag the exact rule behind each problem.
    • Prepare a meeting agenda from an approved account summary and unresolved action items.
    • Review an existing content brief for missing entities, unanswered questions, or unsupported claims before publication.

    Each example ends in an inspectable artifact. None asks the agent to “improve performance” without defining what improvement means or what authority the agent has.

    Use a simple eligibility test

    Before building, answer the following questions. If several answers are unclear, the process is not ready for an agent yet.

    • What exact event starts the workflow?
    • Which systems contain the facts the agent is allowed to use?
    • Which part requires interpretation rather than a fixed rule?
    • What does a complete output contain?
    • How can a reviewer verify the result without recreating all the work?
    • What is the worst plausible result of a wrong decision?
    • Can that result be prevented with permissions, validation, or approval?

    A poor starting workflow has an ambiguous goal, no authoritative data source, broad credentials, and no obvious stopping point. It may still be worth redesigning, but adding an agent will not repair those weaknesses.

    Know when ordinary automation is enough

    If the same input should always produce the same action, use a deterministic rule. Scheduling a recurring run, checking whether a required field is empty, applying a known naming convention, and moving an approved file do not require model judgment.

    Use an agent for the step that genuinely needs interpretation: classifying an unusual campaign change, reconciling context from a client email with a performance report, or explaining why draft copy conflicts with a brand rule. The strongest design is often a hybrid. Conventional automation handles triggers and validation; the agent handles a bounded judgment; conventional automation checks the output and routes it to the next stage.

    Separate facts, reasoning, actions, and controls

    A four-part automation model separates source records, a reasoning chamber, an action mechanism, and an independent control frame with locks and an approval gate.

    A visual canvas can make a complicated workflow look like one continuous chain. Operationally, you should still treat it as distinct layers. That separation tells you where an error started and which safeguard should catch it.

    LayerIts jobMarketing exampleMain failure to prevent
    FactsRetrieve authoritative input without changing itCampaign data, an approved brief, or brand rulesUsing stale, incomplete, or unapproved material
    ReasoningClassify, compare, prioritize, or draftExplain which exception deserves reviewProducing a plausible conclusion that the evidence does not support
    ActionWrite or send an approved result through a toolCreate a report draft or update a workflow statusChanging the wrong record or acting before approval
    ControlValidate, log, stop, or request authorizationRequire evidence fields and approval before publicationAllowing an error to pass silently into a consequential action

    Your language model should not become the system of record. Let tools retrieve facts from the authoritative system, and require the agent to preserve the identifiers that connect every conclusion to those facts. If it says a campaign needs attention, the output should identify the campaign, the relevant observation, the input used, and the proposed next step.

    Policies deserve the same separation. Brand requirements, approval rules, prohibited claims, and escalation conditions should be maintained as explicit instructions or structured data. Do not hide critical policy in an example and expect the agent to infer that the example is binding.

    A useful division of labor is straightforward: tools fetch facts, the agent interprets them, deterministic checks validate required conditions, and a person approves consequential changes. You can relax an approval later if the workflow earns that authority. Recovering from an unreviewed budget change or public claim is much harder.

    Write an executable contract before you build

    The workflow specification is the real product. The canvas, model, prompts, and connectors implement it. Write the specification in operational language that a reviewer can challenge before the agent touches live data.

    1. Define the outcome. Name the artifact or state the workflow must produce, not the general business goal it supports.
    2. Define the trigger. Identify the approved event, schedule, or human request that starts a run.
    3. Define the inputs. List the allowed systems, records, fields, and policy documents. State which one wins if two inputs conflict.
    4. Define the decision. Explain what the agent may infer and the criteria it must apply.
    5. Define the output. Require a stable structure with evidence, unresolved questions, and approval status.
    6. Define the tools. Grant only the operations needed for this workflow.
    7. Define the boundaries. State forbidden actions, stop conditions, and matters that always require escalation.
    8. Define completion. Say what must be true before a run can be marked successful.
    9. Define the evidence trail. Preserve the input references, tool results, output, approval, and final action.

    A practical specification for a PPC reporting agent

    Suppose you want an agent to prepare a campaign exception brief. The specification could read like this:

    • Outcome: prepare a review brief describing campaign exceptions; do not optimize the account.
    • Trigger: an approved reporting request with an account identifier and reporting context.
    • Inputs: current campaign data, the agreed comparison context, active brand rules, and unresolved items from the previous review.
    • Allowed decisions: group related observations, rank them by the supplied business criteria, and propose questions or next actions.
    • Required output: campaign identifier, observation, supporting evidence, applicable rule or objective, proposed action, uncertainty, and approval status.
    • Allowed actions: read approved inputs and create a draft in the designated location.
    • Forbidden actions: change bids or budgets, alter targeting, send client communications, publish copy, or invent a missing value.
    • Stop conditions: required data is missing, identifiers do not match, instructions conflict, or a tool returns an uncertain result.
    • Approval: the account owner reviews the brief before any recommendation enters a live campaign workflow.
    • Completion: every recommendation has evidence, every unresolved issue is labeled, and no prohibited action was attempted.

    This contract turns a vague assistant into a bounded operator. It also makes evaluation possible. A reviewer can test whether the agent followed each condition instead of debating whether the response merely looked intelligent.

    Express authority with precise verbs

    Words such as read, classify, draft, propose, update, send, publish, and delete represent very different levels of authority. Use them deliberately. “Handle the client report” conceals several decisions. “Read approved campaign data, draft the report summary, and request approval” exposes them.

    Do the same with uncertainty. If a required value is absent, tell the agent to stop or label the gap. Never ask it to complete a record using “the most likely” value unless inference is explicitly acceptable and clearly marked. A polished guess is still a data-quality failure.

    Place controls at the action boundary

    Permissions should follow a ladder. Reading is less consequential than drafting; drafting is less consequential than committing a database change; an internal change is usually less consequential than sending a message, publishing content, or changing advertising spend.

    • Begin with read-only access wherever the workflow allows it.
    • Write drafts to a staging location rather than replacing an approved asset.
    • Require a human decision immediately before an external, public, financial, destructive, or difficult-to-reverse action.
    • Use separate credentials or scoped permissions so one workflow cannot inherit unrelated authority.
    • Require the tool to return a stable record identifier and confirmation before the agent treats a write as successful.
    • Make repeated runs safe. A duplicate trigger should find the existing draft or action record rather than create another one.
    • Log the request, retrieved input references, tool calls, result, approval, and final action in a form that can be reviewed later.

    Connected email and document stores introduce another boundary: retrieved content is data, not authority. An email, attachment, or cloud document may contain text that tells the agent to ignore its rules or use another tool. The workflow should treat those instructions as untrusted unless they arrive through the approved control path. Keep system instructions, business policy, and retrieved content distinct.

    Test the agent’s failures before trusting its successes

    An engineer observes an automated agent being tested against missing inputs, conflicting records, unavailable tools, and a blocked unsafe action in a simulation lab.

    A smooth demonstration proves that the happy path can work. It does not show what happens when data is absent, tools fail, instructions conflict, or the same event arrives twice. Those cases determine whether the automation is fit for routine use.

    Build a test set from the ways the real workflow can break. It should include:

    • An ordinary case with complete, consistent inputs.
    • A case with a required input missing.
    • A stale, malformed, or mismatched record.
    • Two approved inputs that disagree.
    • An ambiguous request that permits more than one interpretation.
    • Retrieved content containing instructions the workflow must not obey.
    • A tool timeout, rejection, or incomplete response.
    • A duplicate trigger for a run that already produced an output.
    • A proposed action that violates a brand, permission, or approval rule.
    • A case where the correct behavior is to stop and ask for help.

    Score behavior against the contract, not writing quality. Check whether the conclusion is supported, required fields are present, prohibited actions are avoided, tool results match the intended record, and uncertainty is visible. Also record how much human correction the result needs. An agent that saves preparation time but creates a difficult verification job has moved the work rather than removed it.

    Roll out in stages

    Start in shadow mode: let the agent process real workflow inputs without writing to production systems or contacting anyone. Compare its proposed output with the existing process, classify the differences, and revise the contract or controls when the same error pattern returns.

    Next, allow draft creation while keeping approval mandatory. Expand authority only after the defined test set and real shadow runs show that failures are visible and contained. Increase one dimension at a time, such as the range of accepted inputs or the ability to update an internal status. If you broaden the workflow and its permissions simultaneously, you will not know which change caused a new failure.

    Monitor the operating result after launch. Useful measures include successful completions, stops and escalations, human edits, attempted policy violations, tool failures, duplicate prevention, and time saved after review and recovery work are included. Review the failure categories themselves. A rising cluster of missing-data errors may point to an upstream process problem rather than a prompt problem.

    Keep rollback practical. Preserve the previous state for reversible updates, retain the identifiers returned by action tools, and document how a reviewer disables the workflow without disabling unrelated automations. If a safe rollback is impossible, keep a person at the commit boundary.

    Key takeaways

    • Choose a narrow workflow with a clear trigger, bounded judgment, limited tools, and a verifiable output.
    • Keep deterministic triggers and validation outside the model; use agent reasoning only where interpretation adds value.
    • Treat the workflow specification as an executable contract covering inputs, decisions, outputs, permissions, stops, and evidence.
    • Start with read or draft access and require approval before public, financial, destructive, or difficult-to-reverse actions.
    • Treat email, attachments, and retrieved documents as untrusted data rather than instructions.
    • Test missing data, conflicting instructions, tool failures, duplicate events, and safe escalation before expanding authority.
    • Measure correction and recovery work as well as successful task completion.

    Pick one recurring workflow and write its contract before opening the visual builder. If you cannot identify the authoritative inputs, forbidden actions, approval point, and proof of completion on one page, narrow the job again. Once those boundaries are clear, OpenAI’s agent tools can automate the judgment bottleneck without quietly taking control of the whole operation.

    References

  • CrushPress AI Actions: Reliable Workflow Automation

    CrushPress AI Actions: Reliable Workflow Automation

    If your AI visibility process ends with a crowded inbox, an unassigned alert, or a spreadsheet nobody revisits, automating it will only produce clutter faster. A useful Action must turn a meaningful signal into an owned decision, preserve the evidence behind it, and define how you will know the work is finished.

    The practical promise behind Actions is to reduce repetitive handling and make AI visibility work more efficient. Real reliability, however, comes from the workflow around the automation: the trigger, decision rule, evidence, owner, review gate, and verification step.

    Define the decision before you automate the task

    Start with a recurring decision that currently requires someone to collect the same information, apply the same rule, and route the result. Do not start with a vague goal such as “improve AI visibility.” An Action cannot execute that goal because it does not identify what changed, what should happen next, or who can approve the response.

    A better starting question is: “What decision keeps waiting because the evidence is scattered?” In an AI visibility workflow, that might be whether a new brand claim needs correction, whether a missing citation points to a content gap, whether a tracked answer changed enough to investigate, or whether an observation is merely noise that should be logged without creating work.

    Write a workflow contract before configuring the Action. It should contain:

    • Outcome: The operational result you want, such as an approved correction task or a content brief ready for review.
    • Trigger: The observable event that starts the workflow. Describe the event, not the desired conclusion.
    • Required evidence: The fields that must exist before the workflow is allowed to continue.
    • Decision rule: The condition that separates “act,” “review,” “observe again,” and “ignore.”
    • Output: One bounded deliverable with a predictable structure.
    • Owner: The role responsible for accepting, rejecting, or completing the output.
    • Stop condition: The point at which the Action must end rather than starting another loop.
    • Verification rule: The evidence required to mark the result as checked, not merely completed.

    For example, “alert the SEO team when visibility drops” is not yet a workflow. “When a tracked query produces a materially different answer, capture the old and new observations, classify the change, and create an investigation brief for the named owner” is much closer. It specifies a trigger, evidence, classification, output, and destination without pretending the automation already knows the cause.

    Use a simple readiness test: can the owner make the intended decision from the Action’s output without reopening every tool used upstream? If not, the automation has moved the repetitive work rather than removed it.

    Build a closed loop for AI visibility changes

    Glowing signals converge into a beacon that moves through a circular observation, action, and verification system.

    AI-generated answers can vary across runs, models, interfaces, languages, and locations. A single observation is therefore evidence of what appeared in that context, not automatic proof of a durable visibility trend. Your workflow should preserve that context before it attempts to classify the result.

    A practical visibility loop

    1. Observe: Start from a defined query or query set on a chosen AI surface. Avoid mixing unrelated prompts into one trigger.
    2. Capture: Save the exact prompt, answer, model or interface, observed time, relevant language or market, cited pages, and any brand or competitor mentions needed for review.
    3. Compare: Evaluate the observation against a declared expectation or earlier observation. Keep the raw evidence alongside the comparison.
    4. Classify: Route the result into a limited set of operational states, such as no meaningful change, uncertain result, incorrect claim, missing mention, citation gap, content gap, or competitor displacement.
    5. Act: Produce one appropriate output. That might be a correction task, investigation brief, content brief, structured-data review, escalation, or no-action record.
    6. Verify: Recheck the same success criterion in a planned observation window, while retaining the model and interface context.

    The separation between observation and classification matters. If an Action turns every changed answer into an optimization task, ordinary output variation becomes a queue of false emergencies. A classification stage lets you require more evidence when the result is ambiguous and reserve immediate action for clear, consequential problems.

    Example: route a potentially incorrect brand claim

    Suppose a tracked answer contains a claim that conflicts with your approved brand facts. The Action should not jump directly to rewriting a page or publishing corrective content. Design the loop like this:

    • Trigger: A captured answer contains a claim that appears inconsistent with the approved fact set.
    • Evidence packet: Include the exact prompt, complete surrounding answer text, AI surface, cited URLs, observation context, conflicting approved fact, and link to the canonical internal record.
    • Decision gate: A reviewer confirms whether the statements actually conflict and whether the issue is consequential.
    • Action: Create a correction plan that identifies the canonical page, structured data, documentation, or third-party information requiring investigation.
    • Approval: Require an authorized owner to approve any public edit, deletion, or external response.
    • Verification: Confirm that the approved source of truth was corrected, then record later AI observations separately from the operational completion.

    This distinction prevents an important reporting error. Completing a content or data correction proves that your team performed the approved work. It does not prove that the correction caused a particular model to change its answer. Track “work completed” and “visibility outcome observed” as separate states.

    Verification should test the original condition

    A generic “done” status tells you that a task moved through the system. It does not tell you whether the initiating problem was resolved. Write the verification rule when you create the workflow, using the same language as the trigger.

    If the trigger is an incorrect brand claim, verification asks whether the approved source of truth is now accurate and whether later observations still contain the claim. If the trigger is a citation gap, verification asks whether the target page became a stronger, accessible source and whether subsequent answers cite it. If the trigger is a visibility change, verification repeats the planned observation method rather than substituting a different prompt or surface.

    Make every handoff carry its own evidence

    A brittle automation often fails at the handoff. The Action detects something real, but the destination receives a title such as “Check AI visibility” with no prompt, answer, comparison, or reason for the priority. The assignee must reconstruct the investigation before making a decision.

    Prevent that failure by treating the evidence packet as part of the deliverable. Every routed item should answer these questions:

    • What was observed? Preserve the exact text or structured result, not only a generated summary.
    • Where did it occur? Identify the AI surface, model or interface when available, query, language, market, and relevant source URLs.
    • What changed? Show the comparison or rule that activated the workflow.
    • Why was it classified this way? Expose the decision rule instead of presenting the label as unquestionable.
    • What remains uncertain? Label suspected causes as hypotheses. Do not let generated explanations masquerade as established facts.
    • What should the owner decide? Ask for a specific approval, rejection, prioritization, correction, or investigation decision.
    • What would close the item? State both the operational completion condition and the later visibility check.

    Route by issue type before routing by team. “Content,” “technical,” or “communications” may describe a destination, but they do not explain the problem. A useful classification identifies the issue first: unsupported claim, stale canonical fact, inaccessible source, weak answer coverage, structured-data inconsistency, or uncertain observation. The destination can then follow from that diagnosis.

    Measure decision quality, not automation volume

    Task count is a poor success metric. A noisy workflow can create many tasks while making the team slower. Use operational measures that reveal whether the Action improves the decision process:

    • Useful-signal rate: How often reviewers agree that a routed item deserved attention.
    • Time to ownership: How long a valid signal remains unassigned or undecided.
    • Rework: How often the owner must retrieve missing evidence, change the classification, or rebuild the requested output.
    • Closure quality: How often completed items include the required approval and verification record.
    • Repeated failure: Which triggers, fields, or destinations create the same rejection or exception pattern.
    • Observed outcome: Whether later checks satisfy the declared visibility criterion, recorded without claiming unsupported causation.

    Review rejected and corrected outputs as design feedback. If reviewers repeatedly change the same classification, the rule is probably ambiguous. If they repeatedly ask for the same missing field, add it to the evidence contract. If valid items stall after assignment, the problem is ownership rather than detection.

    Add review gates and failure controls before scaling

    Two professionals pass a transparent evidence case through a guarded review checkpoint with inspection and recovery controls.

    The right automation boundary depends on the consequence of being wrong. Capturing evidence is reversible. Publishing a factual claim, deleting content, changing structured data, contacting an external party, or altering permissions can create reputational, technical, or legal exposure. Put explicit approval in front of those actions and provide the reviewer with a preview or difference view wherever possible.

    Automate preparation before irreversible choices

    A sensible responsibility split looks like this:

    • Safe to automate: Evidence capture, formatting, deterministic field validation, duplicate detection, status updates, routing, and creation of a reviewable draft.
    • Automate with review: Intent grouping, issue classification, priority suggestions, root-cause hypotheses, content recommendations, and proposed schema changes.
    • Require explicit approval: Publishing, deletion, public corrections, external outreach, access changes, and any claim whose accuracy or wording carries material consequences.

    Generated drafts should remain drafts until an accountable person approves them. This is especially important when the input is an AI-generated answer: the workflow is processing an output that may itself be incomplete, variable, or wrong.

    Give failures a visible destination

    An Action is not ready merely because its successful path works. It is ready when a failed run is legible, contained, and recoverable. Build or document these controls around it:

    • Required-field validation: Stop the workflow when the evidence needed for a decision is missing.
    • Duplicate protection: Use a stable combination of query, observation, issue, and destination so repeated detection does not create competing tasks.
    • Scoped permissions: Give the workflow access only to the systems and operations it needs.
    • Bounded retries: Prevent a failing destination from producing an uncontrolled loop of repeated attempts.
    • Visible exceptions: Send failed and uncertain runs to a named owner with the input, error state, and last successful step intact.
    • Versioned rules: Record which prompt, classification logic, template, and approval policy produced each output.
    • Recovery path: Preserve the prior state or require a reversible draft when an automated step could change content or data.

    If a particular control is not available inside the Action itself, put it in the surrounding operating process. Do not assume that a successful status means the destination accepted the right data, that a retry is harmless, or that a generated classification is safe to publish.

    Roll out with known cases before live expansion

    1. Replay resolved cases: Feed the workflow examples whose correct routing and outcome are already known. Include ambiguous, duplicate, incomplete, and no-action cases.
    2. Run in shadow mode: Let the Action produce a log or draft without changing production content or contacting anyone externally.
    3. Limit the live scope: Start with one trigger family, one output type, and a named owner who can inspect exceptions.
    4. Correct the contract: Update missing fields, ambiguous rules, permissions, and failure handling based on actual review patterns.
    5. Expand by pattern: Reuse the proven structure for adjacent workflows while keeping each Action’s trigger, owner, and success condition explicit.

    Name each workflow so its behavior is obvious: “trigger → decision → outcome.” A name such as “tracked claim conflict → reviewer confirmation → correction plan” is easier to operate than “AI monitoring automation.” It also makes overlapping or redundant Actions easier to spot.

    Key takeaways

    • Automate a recurring decision with a defined outcome, not a broad ambition such as improving visibility.
    • Preserve the prompt, answer, AI surface, comparison, and source context before classifying a visibility change.
    • Keep operational completion separate from later AI visibility observations; the latter does not automatically prove causation.
    • Make the evidence packet complete enough for the owner to decide without reconstructing the investigation.
    • Require human approval for publishing, deletion, external communication, permissions, and consequential factual or structured-data changes.
    • Scale only after duplicate handling, visible exceptions, ownership, verification, and recovery work on known cases.

    Your best first CrushPress AI Action is the recurring visibility decision that consumes attention without requiring novel judgment every time. Define its evidence packet, make its output reviewable, and test its failure path. Once that loop closes reliably, use the same contract to automate the next decision.

    References