Category: Search Features

  • How AI Discovery Is Moving Beyond the Search Results Page

    How AI Discovery Is Moving Beyond the Search Results Page

    AI discovery is expanding beyond the conventional search results page. Two emerging models illustrate the change: Google Discover is experimenting with natural-language feed controls, while Yahoo Scout combines AI-generated answers with content and services from across Yahoo’s properties.

    Together, the reported developments suggest that publishers may increasingly be discovered through declared interests, generated subqueries, citations and contextual recommendations. The opportunity is broader than ranking for one typed query, but each surface creates a different route from user intent to publisher visibility.

    Two AI discovery models with different user journeys
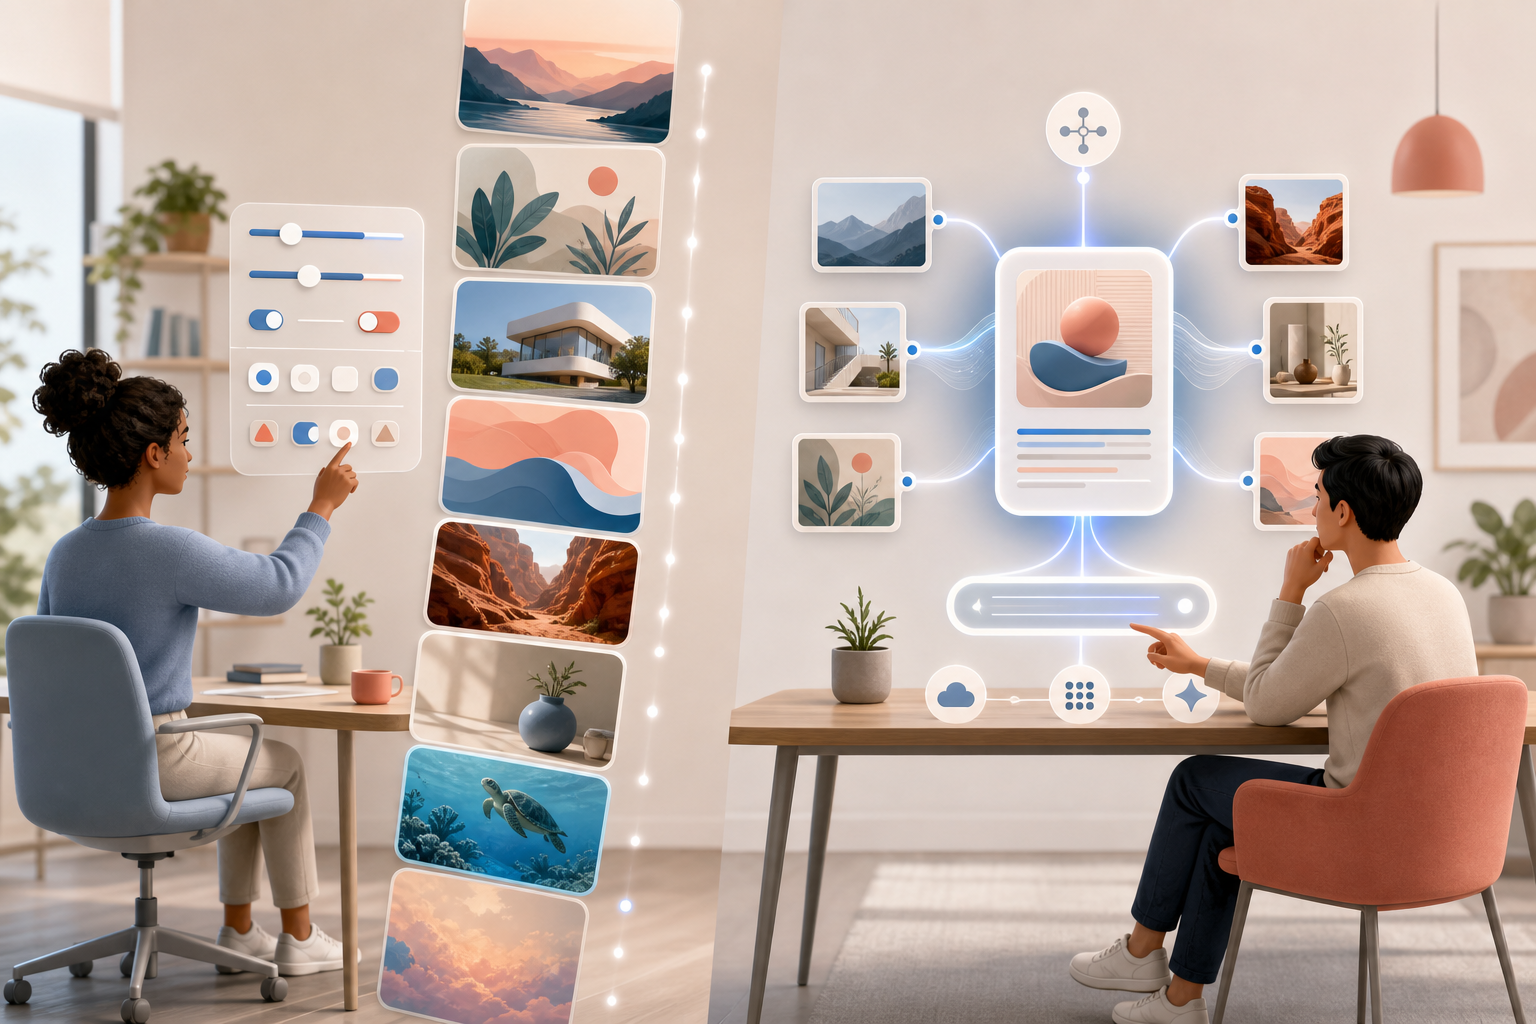
    Two people follow different AI discovery journeys, one through a personalized feed and the other through an answer connected to source cards.

    Google Discover’s experiment begins with a feed. According to the report on its natural-language tuning feature, users can ask to see more content about a topic, creator, publisher or content format. Google then interprets that request and adjusts the cards presented in Discover. The report described this as a shift from personalization based only on inferred behavior toward personalization that also accepts declared preferences.

    Yahoo Scout begins with a question or task. The Scout report described an AI answer engine available through its own website and integrated into Yahoo Search, News, Finance and Mail. Responses can include synthesized text, citations, source previews, tables, imagery and information drawn from Yahoo services.

    DimensionGoogle Discover tuningYahoo Scout
    Primary experienceA personalized content feedAn AI answer and assistant interface
    User signalA request to see more or less of a subject, source or content typeA question, follow-up or task expressed in conversational language
    Publisher exposureSemantically relevant cards selected through topic expansion or query-intent fan-outLinks, highlighted citations, featured sources and content cards within or around an answer
    Reported limitationEarly, cautious distribution with occasional loose matchesUnknown publisher click-through performance and room for more source links

    The distinction matters. Discover tuning influences what a person may encounter while browsing, whereas Scout responds to an immediate information need. One is an AI-directed recommendation layer; the other is an answer layer that can also become a gateway to the web.

    Declared intent creates new routes to publisher visibility

    The Discover report identified two apparent retrieval patterns. In entity or interest expansion, a prompt can lead to related topics, people, publishers or concepts. In query-intent fan-out, a broad request is translated into several narrower retrieval intents. A general interest in SEO, for example, was reported to produce more specific intents concerning strategies, ranking updates and Discover guidance.

    This fan-out process can widen the candidate pool. The report documented results from specialist publishers, individual creators and narrowly focused sites, including cases in which an article had no detectable previous circulation in the tracking dataset used for the analysis. That observation does not establish audience size or Search Console traffic, and the source cautioned that prompt-influenced cards did not appear to receive the broad amplification sometimes associated with conventional Discover distribution.

    The same report observed structured actions such as SEE_MORE and SEE_LESS, along with current and historical natural-language tuning pipelines. It interpreted the historical pipeline as evidence that a prompt may influence later feed sessions rather than only the next refresh. These findings came from feature tracking, however, so they should be treated as reported observations about an experimental system rather than a complete account of Google’s internal ranking process.

    Yahoo Scout offers another visibility mechanism: attribution inside a generated response. The Scout report described linked highlights, a featured-source area, citation previews and related article cards intended to make underlying publishers visible. Yahoo told the reporter that it wanted Scout to direct traffic to the open web, but it had not yet established an expected click-through rate. The company also said it planned to develop publisher impression and click reporting.

    These models change the discovery question for publishers. Visibility may depend not only on whether a page ranks for the user’s original words, but also on whether it matches a derived interest, answers one of several generated subqueries or provides material an answer engine can attribute clearly.

    A publishing strategy for feeds and answer engines
    An editor organizes multimedia content that flows toward a feed, an AI answer, and contextual recommendation cards.

    Make the site’s subject identity unmistakable

    Entity expansion favors a publication whose subject can be recognized consistently. Descriptive titles, focused sections, coherent internal linking and clear authorship can help a retrieval system understand what the site and its contributors cover. The aim is not to repeat a keyword everywhere, but to remove ambiguity about the publication’s domain and the purpose of each page.

    Cover the questions inside a broad prompt

    Query fan-out means one prompt may represent several related information needs. A useful page should state its scope early, use headings that reflect genuine reader questions and answer the important subtopics directly. This makes the content easier to retrieve for an intent that the user did not phrase exactly as the publisher did.

    Give answer systems attributable material

    Scout’s emphasis on citations makes source quality part of presentation. Publishers can support attribution by distinguishing facts from analysis, naming original sources, explaining methodology and keeping important claims close to their evidence. Concise summaries can help an answer system identify relevance, but the surrounding article still needs enough context for a reader who follows the citation.

    Measure each surface on its own terms

    A card shown because one person tuned a feed is not equivalent to a widely distributed recommendation, and a citation impression is not equivalent to a visit. Publishers should avoid treating all AI visibility as one metric. Useful distinctions include being retrieved, being visibly attributed, receiving a click and producing a meaningful on-site action. The source reports indicate that measurement remains incomplete: the Discover analysis relied on observed tracking data, while Yahoo said publisher reporting was still planned.

    Key takeaways

    • Google Discover’s reported experiment lets users declare feed interests in natural language, potentially opening a limited discovery path for specialist content.
    • Yahoo Scout uses an answer-engine model in which highlighted citations, featured sources and content cards can connect responses to publishers.
    • Clear topical identity supports entity-based discovery, while direct coverage of related questions supports retrieval through generated subqueries.
    • AI visibility should be separated into retrieval, attribution, referral traffic and on-site outcomes because the surfaces do not distribute content in the same way.

    What will determine whether these surfaces matter

    Neither report establishes a mature replacement for search traffic. The Discover feature was described as an early Search Labs experience with limited adoption and cautious distribution. Yahoo Scout was presented as a beta whose downstream click performance remained unknown, despite Yahoo’s stated intention to support publisher referrals.

    The next meaningful signals will be broader user adoption, dependable publisher reporting and evidence that citations or tuned recommendations produce sustained visits. Until then, publishers can prepare by making content semantically clear and easy to attribute while treating traffic claims about these new surfaces with appropriate restraint.
    References

  • Discover Google’s New Search Profiles for Publishers

    Discover Google’s New Search Profiles for Publishers

    Hey there, have you heard about Google’s latest feature within Google Discover? They’ve just launched Search profiles in the U.S., and it’s a game-changer for publishers like me. These profiles act as enhanced landing pages where my audience can not only follow me but also see a collection of my latest articles, videos, and social media posts all in one convenient spot.

    Google has been working on this for quite some time, refining and testing it over several months. They’ve even made some tweaks, such as adding shortnames, which make it even easier to share these profiles.

    What are Search Profiles? According to Google’s description:

    “Search profiles give publishers and creators a central place to showcase their latest articles, videos, and social posts. People can easily follow sources from their profile, so they’re more likely to see that content on Discover, found on the home screen of the Google app.”

    It’s described as a “new way for publishers and creators to shape their presence on Search. Search profiles are a dedicated, shareable space to highlight content across platforms and help audiences find accurate, up-to-date information about sources on Search.”

    What it looks like: Curious to see it in action? Here’s a video demonstration:

    Managing Your Search Profile: If you’re a publisher or creator with a significant following on a major social or video platform, you’re in luck! You’ll be able to claim your Search profile, personalize it with an avatar, bio, and links to your website and social media platforms.

    Once you claim your profile, it might even create a Knowledge Panel for you, or enhance your existing one with updated details and a direct link to your profile.

    If you’re interested in setting up your own Search profile, check out this guide for creating a profile, claiming an existing one, and managing it.

    Availability: Currently, this feature is available in the U.S. for users and publishers who meet a certain follower threshold. Here’s what you need:

    • TikTok: 300,000 followers
    • YouTube: 100,000 subscribers
    • Instagram: 100,000 followers
    • X: 100,000 followers

    Why This Matters: As a publisher, I’m always looking for ways to get more visibility. Google’s new feature allows us to increase our reach not just on Google platforms but across our entire digital presence. It’s an exciting time, though one has to ponder whether this will be enough in the fast-paced world where AI continues to evolve.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Unveiling Google Search Console’s AI Controls and Reports

    Unveiling Google Search Console’s AI Controls and Reports

    As someone who eagerly follows Google’s updates, I was thrilled to learn about the latest developments in Google Search Console. Recently, Google has started to roll out new Search Generative AI performance reports. These reports, along with a feature to block your content in AI responses, are designed to give website owners more control.

    Currently, these features are being introduced to a select group of website owners in the UK, but there are plans to expand access in the near future. This gradual rollout allows us to get accustomed to these changes before they become widely available.

    Exploring the Search Generative AI Performance Report

    The new AI performance report in Google Search Console is something I’ve been anticipating. Although it doesn’t cover everything, it does provide some important insights into how our content is performing within AI responses, AI Mode, and AI Overviews on Google Search. The report includes data on impressions, pages, countries, devices, and dates. However, a notable omission is click data, so we’re left guessing about the exact number of searchers clicking through to our sites from AI responses.

    Google stated:

    – We’re rolling out new insights for website owners regarding their pages’ appearances in generative AI Search features. These insights include impressions metrics and information on which pages appear in AI responses and in which countries. We’re working closely with website owners to determine what insights would be most helpful and will expand the metrics available over time. 

    Additionally, Google shared more details about the metrics we can expect:

    – Impressions: Frequency of your site’s URLs appearing in generative AI features in Search and Discover.

    – Pages: Identifying URLs that appeared within AI features.

    – Countries: Understanding visibility on a country basis.

    – Devices: Identifying the devices used to view your website. Available for Search results.

    – Dates: Monitoring performance with hourly, daily, weekly, and monthly granularity.

    I inquired about click data from a Google representative, who mentioned that they are exploring additional metrics that will help inform our strategies in the future.

    Initially, this report is available to a subset of users in the UK, with plans to expand globally in the future.

    If you want to explore more about this report, I recommend checking out the Google help center document.

    Introducing AI Blocking Controls

    Another exciting feature Google introduced is the ability to block your content from appearing in AI search features like AI Overviews, AI Mode, or AI Discover. Google described this as a “new toggle” within Google Search Console, allowing us to decide whether or not our site should be part of these AI search features.

    Google notes that opting out will prevent your site from receiving traffic or impressions from these features. Importantly, this control won’t affect your ranking in standard search results outside of generative AI Search features, so there’s no risk of negatively impacting core web search visibility.

    Again, like the performance report, this toggle is currently available to a subset of UK website owners, with plans to widen access as they complete further testing. Google had promised these controls after facing some backlash from the EU, and it’s promising to see them starting to roll out now.

    One study even showed that 1/3rd of SEOs are willing to block Google from showcasing their content in AI search features.

    Why It Matters

    As site owners and publishers, many of us have been asking for control over how and if our content appears in Google’s AI features. Now, we have just that. Although it’s initially limited, I’m hopeful these features will eventually be available to all.

    Moreover, we’ve been requesting AI Search reporting from Google from day one. With Google’s announcement following Bing’s release of its own AI performance report, we’re taking a significant step forward. While Google’s report currently targets UK site owners and lacks click data, it holds promise for a global rollout soon.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Google Discover Controls and Reporting: A Publisher Playbook

    Google Discover Controls and Reporting: A Publisher Playbook

    Your Google Discover chart drops sharply, a stakeholder wants an explanation, and someone points to a recent publisher-profile change. Before you change the editorial calendar or undo the profile work, separate what Google displayed from what Search Console recorded.

    Discover profile controls, feed distribution, and performance reporting are connected surfaces, but they are not the same system. You need a different measurement plan for each one. This playbook shows you how to audit the controls you have, make profile links measurable, and keep unreliable reporting days out of consequential decisions.

    Key takeaways

    • Treat a Discover publisher profile as a brand and navigation surface, not as a proven ranking control.
    • Most profiles are still generated automatically. A monitored set of 46,926 profiles contained only 54 U.S.-based, English-language publishers with enhanced controls.
    • If you can add profile links, give every destination a stable UTM convention before publishing it. Otherwise, you won’t be able to separate profile visits from other Google traffic.
    • Search Console Discover clicks and impressions for May 7–8, 2026 are unreliable because of a confirmed logging error. Mark those dates as invalid data rather than treating the reported decline as lost visibility.
    • Preserve raw Search Console data, add a validity flag, and use first-party site analytics only as corroborating evidence. Different tools do not measure the same thing.

    Separate profile presentation, distribution, and reporting

    A publisher profile can influence how someone understands and navigates your brand after encountering it. Search Console reports what its logging system captured. Discover distribution determines whether and where content appears in the feed. A change in one layer does not automatically prove a change in either of the others.

    LayerQuestion it answersEvidence to useWhat it does not prove
    Publisher profileWhat can a user see or select after interacting with your publisher identity?Profile screenshots, available controls, tagged profile-link visits, and landing-page actionsThat a banner, link, or pinned post improved Discover ranking
    Discover distributionWas your content shown and selected in the feed?Valid Discover impressions, clicks, click-through rate, content-level patterns, and corroborating site outcomesThat every reported movement reflects an editorial or algorithmic change
    Search Console reportingWhat Discover activity did Google’s reporting pipeline log?Search Console data with incident annotations and validity flagsThat a logging gap represents a real loss of placement or audience

    This distinction changes how you investigate. If a profile link receives fewer tagged visits, inspect the link, label, destination, and profile exposure. If Search Console falls on dates affected by a known reporting incident, quarantine those dates first. If valid Discover data and independent site outcomes decline beyond the incident window, then you have grounds for a broader distribution, content, or technical investigation.

    Do not use correlation as a shortcut. Pinning a post shortly before a Discover increase does not demonstrate that the pin raised feed visibility. The pin may have changed profile engagement, while a separate distribution change affected the feed. Measure the outcome each control can plausibly produce.

    Audit the Discover profile you actually have

    A publishing specialist reviews a generic profile interface alongside image, link, mobile preview, and verification symbols.

    Google’s publisher profiles live at profile.google.com/cp/ and can appear when a user interacts with the publisher name on a Discover card. The profiles have existed since August 2025, but enhanced editing has not been made broadly available.

    Run the audit from the profile itself rather than from an internal assumption about what your organization should have. Save the date of the audit because access and profile presentation can change.

    1. Open your publisher profile and record its exact URL.
    2. Capture a full-page screenshot so you have a dated record of the banner, identity, links, social accounts, and visible posts.
    3. Look for the label “Profile generated by Google.” Its presence indicates the standard, automatically generated profile rather than the enhanced publisher-controlled version.
    4. Check separately for a customizable banner, a link shelf, pinned-post controls, and editable social links. Do not mark the profile as enhanced based on appearance alone.
    5. Record who in your organization can access the controls. Profile availability is not operational control if nobody owns the account or publishing process.
    6. Add the audit result to a simple register with four fields: profile URL, profile type, last checked date, and internal owner.

    The enhanced program remains highly selective. Monitoring across 46,926 publisher profiles found 54 U.S.-based, English-language publishers with advanced controls. Nearly half of that group consisted of regional newspapers and local television stations.

    That pattern describes Google’s selected cohort; it is not a public eligibility rule. There is no documented public application process for the enhanced capabilities. If your profile has no claim or editing option, do not treat the absence as a technical failure, and do not build a business case around an assumed rollout date.

    If you have a standard profile, verify what users see and retain evidence of any identity problem. Keep your publication name, visual identity, social destinations, and public site information internally consistent so the team can identify discrepancies without improvising a new brand treatment for Google alone.

    If you have enhanced controls, assign a job to each element:

    • Banner: communicate recognizable brand identity. Use a production-ready asset and review it on the live profile rather than approving it only from the design file.
    • Link shelf: route users to a small set of intentional destinations. Choose pages that answer a clear next-step need, such as current coverage, a section hub, a newsletter, or a subscription page.
    • Pinned posts: prioritize content for profile visitors. Log the start date, end date, and reason for every pin so later analysis has a usable timeline.
    • Social links: verify account ownership and destination accuracy. A visible link to an abandoned or incorrect account creates a brand problem even if it has no effect on Discover distribution.

    Professional banner treatments were common among the enhanced profiles, but link-shelf behavior differed by publisher type. Local television publishers frequently used links for site navigation, while national publishers used the feature less actively. Copying either pattern without considering your visitor’s next action misses the point. Your shelf should reflect the paths your audience actually needs.

    Make profile traffic identifiable before you optimize it

    A profile link without campaign tagging leaves you with an attribution problem. You may see traffic to the destination, but you cannot reliably distinguish a click from the profile shelf from another Google visit. Many publishers in the initial enhanced cohort did not add UTM parameters to their profile links.

    Set one naming convention before the first link goes live. A practical pattern is:

    • utm_source: google
    • utm_medium: discover_profile
    • utm_campaign: publisher_profile
    • utm_content: a stable identifier for the shelf position or destination, such as latest, local, newsletter, or subscribe

    A newsletter destination could therefore use: https://example.com/newsletter?utm_source=google&utm_medium=discover_profile&utm_campaign=publisher_profile&utm_content=newsletter.

    This is a recommended internal convention, not a Google requirement. Its value comes from consistency. Keep the medium specific to the profile so you do not merge link-shelf traffic with referrals that may come from the Discover feed itself.

    1. Create the final URL in your campaign register before entering it in the profile.
    2. Use lowercase values and fixed separators. Newsletter, NewsLetter, and news_letter become separate values in many analytics workflows.
    3. Open the live profile on a user-facing device and click the link. Confirm that it reaches the intended canonical destination without losing the UTM parameters during a redirect.
    4. Verify the visit in your analytics debugging or near-real-time view. Do not assume that a correctly formed URL is being collected correctly.
    5. Record the visible link label, destination, UTM values, publication date, retirement date, and owner.
    6. When replacing a destination, create a new utm_content value if the user promise changes. Reusing one identifier for unrelated links corrupts the history.

    Measure link-shelf work with profile-attributed sessions and the actions those visitors take on the landing page. Measure a pinned post with the same profile-specific evidence and its active dates. Do not use a change in overall Discover impressions as the success metric for either control unless Google establishes a ranking relationship that is not currently supported here.

    The banner needs a different standard. It is primarily a brand asset, so review visual clarity, publication identity, and suitability within the live crop. Do not manufacture a performance claim merely because the asset cannot be tied neatly to a conversion.

    Keep unreliable Discover data out of editorial decisions

    Editors separate a fragmented analytics tile from stable data tiles before using the reliable set for newsroom planning.

    Google confirmed that a data-logging error reduced reported Discover clicks and impressions for May 7–8, 2026. The problem affected reporting only; Google said it did not affect actual positioning in Discover.

    Those two dates should be treated as invalid observations, not as zero-performance days and not as evidence of an editorial failure. The distinction matters because a monthly total that includes understated days is incomplete even when the rest of the month is accurate.

    1. Preserve the raw values. Do not overwrite the export or dashboard table with an estimate. You may need the original record for auditability.
    2. Add a data-status field. Mark May 7 and May 8, 2026 as invalid because of the Discover logging error. A blank status should mean no known incident, not that someone forgot to review the date.
    3. Render the dates as a gap. On a trend chart, a gap communicates missing or unreliable information more accurately than a plotted zero.
    4. Label every affected total. If a weekly or monthly number includes the two dates, describe it as incomplete. Do not publish a clean percentage change as though both periods had full data.
    5. Avoid backfilling a guessed value. An interpolation may make the chart look continuous, but it converts an unknown measurement into invented performance.
    6. Check corroborating signals. Review site sessions, relevant landing-page activity, and business outcomes for the same dates. Use them to judge whether a separate traffic change may also have occurred, not to recreate exact Search Console clicks or impressions.
    7. Reopen the investigation when the pattern extends beyond the incident. A decline continuing on valid reporting days, especially when site outcomes also weaken, deserves content, distribution, and technical analysis.

    Your stakeholder annotation can be direct: “Google Search Console Discover clicks and impressions for May 7–8, 2026 are understated because of a logging error. Google said the incident did not affect Discover positioning. Totals containing these dates are incomplete.”

    Keep this note beside the chart, not in a separate document that viewers may never open. An anomaly ledger should also record the affected product, dates, metrics, stated impact, supporting link, dashboard owner, and decisions that must not rely on the compromised data.

    For recurring reporting, maintain two views. The raw view preserves exactly what Search Console returned. The decision view carries the same values plus incident flags and excludes invalid dates from calculations that require complete observations. This gives analysts an audit trail while keeping executives from acting on a known measurement failure.

    Do not let the reporting incident become a blanket explanation for every decline. If tagged profile visits fell because a shelf link broke, that is a profile implementation problem. If Discover performance weakens after May 8 on valid days, the logging incident does not explain the later movement. If only the two affected dates look abnormal, the responsible action is to annotate them and leave the editorial plan alone.

    Start with three concrete changes: capture your current profile state, establish a profile-specific UTM convention, and flag May 7–8, 2026 in every Discover report that includes them. The next time a chart moves, you will know whether to inspect the profile, the feed, or the measurement layer before anyone turns an unreliable signal into a strategy change.

    References

  • Google FAQ Rich Results Retirement: A Practical Action Plan

    Google FAQ Rich Results Retirement: A Practical Action Plan

    You may still have FAQ sections, FAQPage JSON-LD, reporting filters, and client promises built around Google’s expandable FAQ listings. The listing has gone away, but that does not mean every FAQ or every line of FAQ markup should disappear with it.

    Your job now is to separate the retired Google Search feature from the content and data that may still serve a purpose. That distinction will tell you what to remove, what to retain, and what to measure.

    What Google retired, and when each dependency changes

    Google ended support for FAQ rich results on May 7, 2026. The visible consequence is straightforward: adding valid FAQPage structured data no longer makes a page eligible for an FAQ rich result in Google Search.

    The retirement also affects the tools around the feature. Google’s announced schedule separates the wind-down into three operational milestones:

    MilestoneWhat changesWhat you should do
    May 7, 2026FAQ rich results stop appearing in Google Search.Stop treating FAQ markup as a Google rich-result opportunity.
    By June 2026Google planned to remove the FAQ search appearance, the dedicated rich-result report, and FAQ support in the Rich Results Test.Replace reports, tests, and documentation that depend on those surfaces.
    By August 2026Google plans to remove FAQ rich-result support from the Search Console API.Update API jobs before missing FAQ-specific data or filters can break them.

    These milestones affect eligibility, reporting, testing, and API access. They do not delete the visible questions and answers on your pages. They also do not establish that FAQPage markup is harmful. The retirement notice alone is not evidence of a penalty.

    Key takeaways

    • Stop approving FAQ schema work on the promise of a Google FAQ rich result.
    • Do not remove useful visible answers merely because the associated search enhancement has retired.
    • Keep the markup only when you can identify a remaining consumer or justify its maintenance cost.
    • Remove FAQ-specific dependencies from Search Console reports, alerts, dashboards, and API jobs.
    • Measure the change with page cohorts and query data, not a single sitewide before-and-after chart.

    Decide whether to keep or remove FAQPage markup

    There is no universal requirement to purge FAQPage from every site. The right decision depends on what consumes the markup, how it is maintained, and whether it remains accurate.

    DecisionUse it whenMain risk to control
    Keep itA verified non-Google search engine, application, internal knowledge system, or publishing workflow consumes it, and the data stays synchronized with the visible page.Do not assume another system uses the markup merely because it can parse JSON-LD.
    Remove itThe only documented purpose was Google FAQ rich-result eligibility, or the implementation produces stale, duplicated, or misleading data.Target FAQPage specifically so you do not erase unrelated structured data.
    Keep it temporarilyYou cannot yet identify every downstream dependency.Give the uncertainty an owner and review date so temporary markup does not become permanent by neglect.

    The phrase “other systems may use it” is not a business case by itself. Ask for evidence: a documented integration, a consuming application, a test that shows the data being ingested, or a named team that depends on the output. Without one of those, you are maintaining code for a hypothetical benefit.

    Retention also has a cost. Automatically generated markup can drift away from the visible answer, survive after an FAQ is deleted, or duplicate data emitted by a theme and a plugin. That creates audit noise and makes future structured-data incidents harder to diagnose. If no verified consumer remains, removing that unused layer is a reasonable cleanup.

    Audit the implementation before touching production

    1. Find every emitter. Search templates, plugins, block settings, custom fields, tag-management rules, and rendered HTML for FAQPage. Check both server-generated source and JavaScript-rendered output.
    2. Map pages to templates. Record the canonical URL, template or content type, markup generator, owner, and any known consumer. This distinguishes a centralized fix from hundreds of apparent page-level fixes.
    3. Check for duplicate output. A page may receive one graph from an SEO plugin and another from its theme or page builder. Removing one does not necessarily remove the other.
    4. Separate schema types. Confirm that the proposed change removes only the FAQ node and its intended relationships. Preserve unrelated Article, BreadcrumbList, Product, organization, or other data unless your audit finds a separate reason to change it.
    5. Verify visible parity. If you retain FAQ markup, each marked-up question and answer should still correspond to content a visitor can access on that page.
    6. Test a representative sample. Include different templates, locales, device-rendering paths, and pages with nested structured-data graphs. A successful test on one hand-built page does not prove that a shared template is safe.

    If you remove the markup, use a staged release or a small controlled page group where your publishing system allows it. Capture the prior output first, verify that the visible FAQ still works, and compare the full structured-data graph before and after deployment. A broad search-and-delete operation can remove braces, graph relationships, or neighboring schema that were never part of the retirement.

    Repair Search Console reports and API jobs before they fail silently

    An obsolete accordion-shaped module is disconnected from a linked browser, structured-data, reporting, and API workflow on a worktable.

    The reporting change deserves as much attention as the markup. A dashboard can keep loading while an FAQ filter returns no rows, a chart becomes permanently flat, or an alert stops firing. That is more dangerous than an obvious error because the report still looks operational.

    Inventory every place where FAQ search appearance is used: saved Search Console views, exported workbooks, business-intelligence models, scheduled reports, client templates, annotations, anomaly alerts, and API queries. For each dependency, decide whether to remove the component, replace it with page-level reporting, or preserve the historical series as a closed metric.

    1. Preserve available history. Keep any existing FAQ-specific exports with their original date range and definitions. Historical data remains useful for explaining why an old report or traffic pattern differs from a new one.
    2. Retire the metric explicitly. Label the series as discontinued rather than allowing it to fall to zero without explanation. A zero can be misread as an implementation failure.
    3. Remove brittle filters. Update queries and transformation steps that expect an FAQ appearance value. Jobs should handle its absence without discarding otherwise valid Search Console rows.
    4. Test empty and missing states. Confirm that dashboards, alerts, and API pipelines behave correctly when FAQ-specific data is unavailable, not merely when its value is zero.
    5. Update stakeholder language. Replace promises to “earn FAQ rich results” with goals you can still observe, such as answering a query clearly, improving organic engagement, or reducing duplicated support content.

    Do not merge the date of Google’s presentation change with the date you remove code. Record both. Otherwise, a later analyst may blame a traffic movement on your deployment when the search feature had already disappeared, or attribute a template change to Google when it happened weeks later.

    Measure the traffic effect without inventing causation

    An analyst compares two separate streams of abstract signals using transparent dividers and balanced measuring instruments.

    FAQ rich results could occupy extra search-result space and influence click behavior, so affected pages deserve closer monitoring. A sitewide organic trend will not isolate that effect. Most pages never had the same FAQ visibility, query mix, ranking stability, or search-result competition.

    Build a page cohort from URLs that carried FAQ structured data and, where your historical records allow it, distinguish pages that actually received FAQ search appearances from pages that were merely eligible. Eligibility is not the same as an impression.

    1. Choose a comparison group. Use pages with a similar purpose and query profile that did not depend on FAQ presentation. The comparison will not create a perfect experiment, but it is more informative than comparing the whole site with itself.
    2. Track impressions, clicks, click-through rate, and average position together. A click-through-rate decline while impressions and position remain broadly stable is more consistent with a presentation change than a simultaneous loss of rankings and visibility.
    3. Inspect page-query pairs. Brand queries, broad informational searches, and long-tail questions can behave differently. Page totals can hide one group falling while another grows.
    4. Annotate both the Google milestones and your deployments. Include the retirement, reporting changes, content edits, template releases, migrations, and other material SEO work in the same analysis window.
    5. Follow the business outcome. Check whether affected pages still generate the actions that matter, such as product discovery, qualified visits, support deflection, leads, or sales. A presentation loss matters differently when click volume changes but useful outcomes do not.

    A before-and-after chart cannot prove that FAQ retirement caused a change. Rankings, seasonality, query demand, competing search features, and your own releases can move at the same time. Use the cohort analysis to identify where investigation is warranted, not to manufacture certainty the data cannot support.

    Keep the answers, but remove the obsolete SEO promise

    A useful FAQ section can still solve a reader’s next problem. It can clarify eligibility, compatibility, pricing logic, implementation constraints, returns, terminology, or a decision that would otherwise send the visitor back to search. None of that value depends on an expandable Google result.

    Review FAQ content as content, not as a schema container. Keep a question when it represents a real decision or recurring point of confusion. Rewrite it when the answer is vague, promotional, outdated, or dependent on information that appears elsewhere. Remove it when it exists only to repeat a keyword or restate the main body.

    • Use the wording a reader would recognize, but do not create several near-identical questions for minor keyword variations.
    • Answer the question in the opening sentence, then add conditions, exceptions, evidence, or a next step.
    • Name the product version, location, customer type, plan, or other qualifier whenever the answer changes across those boundaries.
    • Link to a deeper page when the reader needs a procedure or full explanation; do not compress a complex guide into an evasive two-line answer.
    • Assign an owner to answers that depend on policies, features, prices, or other changeable facts.
    • Keep marked-up data synchronized with visible content if you decide to retain the JSON-LD.

    The same discipline helps answer-engine and generative-search work, but do not replace one unsupported promise with another. FAQPage markup is not a guaranteed route into an AI answer, citation, or model response. Clear visible content, precise scope, consistent entity information, and accessible supporting detail are useful publishing practices; none guarantees selection by a search engine or model.

    Be especially careful with thin FAQ pages created solely to win the retired enhancement. If a page contains unique information or attracts useful demand, improve it. If it duplicates a stronger resource, consider consolidation only after checking its traffic, links, internal references, and destination. Do not delete or redirect a URL merely because its structured-data feature disappeared.

    Turn the retirement into a controlled cleanup

    Start with a single inventory that joins code, content, reporting, and ownership. Give every FAQ implementation one status: retain for a verified consumer, remove as Google-only legacy code, or investigate because the dependency is unknown.

    Resolve the unknown group first. It carries the greatest operational risk: deleting it may break an unrecorded integration, while leaving it indefinitely creates unmanaged data. Once every row has an owner and reason, update the template, reporting pipeline, documentation, and stakeholder expectations as one change set.

    Your next concrete action is simple: search a rendered sample of each major page template for FAQPage, record what generates it, and write down who still consumes it. If no one can answer the last question, you have found the first dependency to investigate.

    References

  • Google’s Preferred Sources Now Available in Every Language

    Google’s Preferred Sources Now Available in Every Language

    When I learned that Google’s Preferred Sources feature now supports all languages, not just English, I was thrilled. This exciting update means more people can tailor their news experience, regardless of the language they speak.

    According to a recent post on Google’s blog, ‘Preferred Sources is now rolling out globally in all supported languages.’ This gives me, and everyone else, more control over the news we see on Search, allowing us to choose our preferred outlets to appear more frequently in Top Stories.

    It’s fascinating to reflect on how this feature initially rolled out in December, but was limited to English. Now, it’s a comprehensive tool available globally, no matter the language.

    Interesting Stats: Google shared some compelling data with this launch. For instance, readers are reportedly twice as likely to click on a site after marking it as a Preferred Source. Also, over 200,000 unique sites have already been selected by users—from local niche blogs to major global news platforms.

    Preferred Sources: This feature lets me star my favorite publications in the Top Stories section of Google Search. By doing so, Google uses that interest to show more stories from those sources. I learned it started in beta back in June and was initially available in the U.S. and India by August, but now it’s part of a worldwide expansion.

    How it Works: It’s simple! I just click the star icon next to the Top Stories header in my search results. This allows me to pick preferred sources, provided these sites are constantly updating their content.

    Once selected, Google promises to showcase more updates from my favorite sites in Top Stories, provided they have fresh content relevant to my search.

    For more detailed information, I can visit this page.

    Why it Matters: In the competitive area of Google Search traffic, marking my site as a preferred source can make a significant impact. Google indicated these users are twice as likely to engage, which could help in driving more traffic to my site.

    So, I’m adding the preferred source icon to encourage my audience to sign up. If you’re interested, you can make Search Engine Land a preferred source by clicking here.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • AI Search Adoption Is Unequal: How Brands Should Respond

    AI Search Adoption Is Unequal: How Brands Should Respond

    If your search strategy begins with the assumption that everyone is moving from Google to ChatGPT at roughly the same pace, stop before you move the budget. The shift is real, but the average adoption figure hides the people, circumstances, and confidence levels driving it.

    You need a strategy that serves confident AI-search users without making conventional search worse for everyone else. That means maintaining two discovery paths, designing AI features as optional assistance, and measuring who benefits rather than treating every AI interaction as progress.

    The average adoption number hides different search realities

    In UK monitoring that began in early 2025, 27% of users said they regularly used ChatGPT. That topline becomes much less useful once household income enters the picture: higher-income households were substantially more likely to use generative AI tools.

    Treat that result as a segmentation signal, not a universal market adoption rate. It tells you that AI use can cluster around particular audiences. It does not tell you that every high-income person uses AI, that lower-income users lack interest, or that the same distribution applies in every country and category.

    Income matters partly because it sits alongside several mechanisms that affect whether someone makes AI part of a normal search journey:

    • Access: Can the person readily use the relevant tool in the context where the question arises?
    • Exposure: Do their workplace, peers, or professional routines encourage them to use AI? People in digital and corporate environments may encounter more prompts to incorporate it into daily work.
    • Capability: Can they frame a useful request, add context, refine a weak response, and inspect the supporting material?
    • Confidence: Do they trust themselves to use the interface and know when an answer needs checking?

    These factors reinforce one another. Frequent exposure builds skill. Skill can improve results. Better results can increase confidence and make the tool feel like the natural place to begin the next task. Someone without that loop may try the same interface once, receive an unhelpful answer, and return to a familiar search box.

    Trust also needs context. Perplexity users have reported high trust while the platform remains comparatively niche. Strong confidence inside a self-selecting user group is not proof of broad public confidence. It may simply describe the people who chose that tool and stayed.

    This is where an average can misdirect strategy. A revenue-weighted customer view may make AI search appear nearly universal if affluent decision-makers are overrepresented among early adopters. A traffic-weighted view may make it look marginal if the larger audience still relies on conventional results. Neither view is sufficient by itself.

    Before reallocating search investment, audit four questions for each important audience:

    1. Where does this audience normally encounter the problem: at work, at home, during a purchase, or while learning?
    2. Which interface do they use to begin, and which interface do they use to verify?
    3. What capability does the journey assume, such as prompting, comparing options, or checking citations?
    4. What happens when confidence fails: do they reformulate, open a conventional result, ask another person, or abandon the task?

    Do not use household income as a shortcut for individual behavior. Use it, when legitimately available and appropriately governed, as one possible research variable. Behavioral evidence such as entry path, repeated feature use, verification actions, and successful task completion is more useful for designing an experience.

    Build one evidence base for two discovery paths

    A shared foundation of connected content and evidence supports both an abstract conventional search interface and an abstract conversational AI interface.

    You do not need an AI site and a non-AI site. You need one dependable body of content that can support two ways of exploring it.

    Journey stageConventional search behaviorAI-search behaviorWhat your content must provide
    Frame the problemEnters a short query and scans resultsDescribes a situation and refines it through follow-up promptsA direct statement of the problem, audience, scope, and relevant terminology
    Compare optionsOpens several pages and compares claims manuallyRequests a synthesis, shortlist, or side-by-side explanationConsistent attributes, explicit differences, limitations, and decision criteria
    VerifyChecks the page, publisher, evidence, and supporting materialInspects citations or leaves the answer to check the underlying pageVisible evidence, clear authorship, dates where relevant, and traceable claims
    ActNavigates to a product, form, store, or next-step pageActs on a shortlist and may enter the site late in the journeyAccurate facts and an obvious next action that does not depend on AI

    The shared content layer matters because optimization for AI discovery cannot rescue weak information. A machine-readable page that never gives a clear answer is still unclear. A polished conversational response built from unsupported claims is still unsupported.

    For every high-value page, make the evidence layer usable in both paths:

    • Lead with the decision-relevant answer. State who the page is for, what question it resolves, and where the answer changes by circumstance.
    • Name entities consistently. Use the same product, organization, service, location, and category names throughout the visible content and metadata.
    • Expose comparison attributes. If a buyer must compare eligibility, compatibility, availability, process, or limitations, place those facts in plainly labelled sections rather than implying them through promotional copy.
    • Separate fact from judgement. Make it obvious which statements describe a documented feature and which represent your recommendation or interpretation.
    • Show evidence near the claim. A reader should not have to hunt through a generic resources page to discover what supports an important assertion.
    • Keep structured data aligned with visible content. JSON-LD should clarify the entities and relationships already present on the page, not introduce claims that visitors cannot verify.
    • Preserve a complete human-readable route. Do not require an AI assistant to reveal essential instructions, terms, limitations, or next steps.

    This approach lets conventional SEO, answer engine optimization, and generative engine optimization share the expensive part of the work: producing content precise enough to retrieve, interpret, compare, and verify. The delivery layer can vary without creating competing versions of the truth.

    Prioritization should reflect audience value without turning early adopters into a stand-in for the market. Fast adopters often include decision-makers and higher-income consumers, so AI visibility may deserve early investment even when total usage remains limited. The correct conclusion is to add coverage for an influential segment, not to remove coverage from everyone else.

    Add AI interfaces as assistance, not as a gate

    People choose between a conventional search panel and an optional conversational assistant while using a range of devices and accessibility methods.

    An on-page AI button can shorten a difficult task. It can also add ambiguity, expose visitors to weak generated output, or hide information behind an interface they do not want to use. The debate around AI buttons spans usability benefits, SEO risk, and fears of AI poisoning, so the useful question is not whether a button looks innovative. It is whether it helps a defined user complete a defined job safely.

    Start with the verb. Labels such as Summarize this policy, Compare these plans, or Ask about eligibility tell the visitor what the feature will do. A vague AI button asks the visitor to understand the technology before understanding the benefit, which creates exactly the kind of confidence barrier you are trying to reduce.

    Use six release gates before putting an AI interface into a search or content journey:

    1. Defined task: Write down the user job in one sentence. If the feature is meant to summarize, compare, explain, or route, choose one primary job and design for it.
    2. Optional path: Confirm that a visitor can reach the same essential information and next action without opening the AI experience.
    3. Clear boundary: Tell users what information the assistant uses and what it cannot determine. Do not invite sensitive or consequential input merely because a free-text box makes that possible.
    4. Grounded output: Make the response traceable to the approved page content or other clearly identified material. AI poisoning, in this context, is the risk that manipulated content or instructions distort what the system produces; limiting and validating the material available to the feature reduces the opportunity for that distortion.
    5. Recovery route: Provide a visible way to open the relevant page section, inspect supporting details, start over, or continue through the standard journey when the response is unhelpful.
    6. Success measure: Define success as task completion or a meaningful next step, not the number of times the button is clicked.

    Progressive enhancement is the right operating principle. Publish the essential content in stable, accessible HTML. Keep navigation, forms, and core actions usable without generated assistance. Then add the AI layer where summarization, comparison, or conversational clarification removes genuine work.

    This also protects the conventional search journey. If important information exists only inside a generated interaction, users cannot reliably scan it before opting in, and the standard page no longer carries the complete answer. The feature has stopped being assistance and become a gate.

    Test the full experience, not just whether the button opens. Check keyboard operation, focus order, labels, loading and error states, generated links, narrow screens, and the non-AI fallback. Review sample outputs for unsupported claims, missing qualifications, inconsistent names, and recommendations that exceed the page’s evidence.

    Measure adoption without averaging away inequality

    A single AI engagement rate cannot tell you whether the feature broadens access or merely serves the people who were already confident enough to try it. Build reporting around exposure, use, usefulness, recovery, and outcome.

    • Eligible exposures: How many visits actually encountered the feature on a relevant page?
    • Activation rate: Of those eligible visits, how many initiated the feature?
    • Task completion: How many users reached the intended next step after using it?
    • Fallback rate: How often did users leave the AI flow for the standard page, search, navigation, or support route?
    • Correction signals: How often did users regenerate, reformulate, dispute, or abandon the response?
    • Downstream outcome: Did the interaction support the real goal, such as finding the right page, understanding a requirement, completing a form, or making an informed selection?

    Break these measures down by relevant, ethically collected context. Useful views may include entry channel, task, first-time versus returning visit, exposure to the AI feature, prior feature use, and voluntarily reported confidence. If your organization has a legitimate basis for audience or income research, keep that analysis aggregated and governed rather than turning a population-level pattern into an assumption about an individual.

    Read the combinations, not just the totals:

    • Low activation and high completion can mean the feature is useful once discovered, but its label, placement, or trust cues are weak.
    • High activation and high fallback can mean curiosity is strong while output quality, task fit, or confidence is poor.
    • Strong outcomes concentrated among experienced users can mean the interface rewards existing AI literacy rather than reducing the skill barrier.
    • Rising AI engagement alongside falling conventional completion can mean the new interface is disrupting the baseline journey instead of improving it.
    • High commercial value from a small AI-search cohort can justify targeted investment, but it does not justify treating that cohort’s behavior as universal.

    Keep external AI discovery separate from on-site AI usage. Mentions, citations, referrals, assisted visits, and landing-page behavior describe visibility outside your site. Button activations, response quality, fallback, and completion describe the experience you control. Combining them into one AI score makes it harder to identify whether the problem is discoverability, content quality, interface design, or audience readiness.

    Your investment decision should follow the constraint. If the right audience cannot find you in AI-generated results, improve retrievability, entity clarity, and evidence. If people arrive but cannot verify the answer, strengthen the page. If an AI feature attracts clicks but blocks completion, fix or remove the feature. If conventional search still carries most successful journeys for an important audience, maintain it.

    Key takeaways

    • Do not use an average AI-adoption rate as your audience model; segment by behavior, context, exposure, capability, and confidence.
    • Treat income-linked adoption as a planning signal, not as a rule about any individual user.
    • Build one verifiable content base that supports both conventional search and conversational discovery.
    • Keep AI buttons optional, label them by the job they perform, and preserve the complete non-AI route.
    • Measure task completion, fallback, correction, and downstream outcomes by cohort; a click on an AI feature is not success.
    • Invest early where AI-search users are commercially important, but do not weaken the search paths used by the rest of your audience.

    Your next move is not to choose between SEO and AI search. Take one high-value customer journey, draw its conventional and conversational paths, inspect the shared evidence beneath both, and define the cohort-level measures before adding another AI feature. If you cannot see who gains, who struggles, and how either group recovers, the experience is not ready to scale.

    References


  • Google’s Global Expansion: Experience AI-Driven Search Live

    Google’s Global Expansion: Experience AI-Driven Search Live

    I was thrilled to learn that Google has rolled out its Google Search Live globally, expanding its reach to over 200 countries and territories where AI Mode is available. You can check which languages and regions are supported.

    Google attributes this remarkable expansion to its cutting-edge audio and voice model, Gemini 3.1 Flash Live. This model offers more natural and intuitive conversations, and because it is bilingual, it allows individuals worldwide to engage with Search in their language of choice.

    How it works. To get started with Search Live, I simply open the Google app on my Android or iOS device and tap the Live icon beneath the Search bar. From there, I can speak my question out loud and receive a helpful audio response. It’s seamless to continue the conversation with follow-up questions or delve deeper using the provided web links. When I need visual context, like figuring out how to install a new shelving unit, I just enable my camera, and it complements Search Live’s suggestions with relevant information from the web.

    Moreover, if I’m already using Google Lens to capture an image, tapping on the Live option lets me have a real-time conversation about what I see, bringing what’s in front of me to life.

    More. Back in September, Google made Search Live with video available in the U.S., appealing to those who enjoyed its earlier iterations. Initially, it was an opt-in beta, and before that, it featured a talk and listen mode, minus the video component.

    Why we care. This development offers a fresh approach for users to interact with Google’s AI through conversation rather than text queries. While this might reduce traditional web traffic, since users get direct answers, the inclusion of citations and links might still benefit content creators and brands, even if users are less compelled to click through for more depth.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Google AI Overview Interactive Links: An SEO Action Plan

    Google AI Overview Interactive Links: An SEO Action Plan

    If your page appears in Google’s generated answers, earning the citation is only the first part of the job. A searcher still has to notice your link, understand what it offers and choose it from the other available sources.

    Google’s interactive link treatment gives that choice more visual weight. It may create a better route from an AI answer to your site, but it does not guarantee more traffic. Your practical response is to improve the pages behind likely citations and establish a measurement process that does not confuse correlation with proof.

    The click path now has a visible choice layer

    Google has made groups of links in AI Overviews and AI Mode open in a pop-up when a desktop user hovers over them. These cards provide more context about the linked websites, giving the user a clearer opportunity to leave the generated response and investigate a source.

    The behavior is different on mobile because there is no hover action. Google is instead using more descriptive and prominent link icons across desktop and mobile. That distinction matters when you audit visibility: a desktop screenshot of an open link group and a mobile screenshot of a link icon are observations of two related but different interfaces.

    This creates an additional choice point in the search journey:

    • Your page first has to be selected as a supporting source.
    • The searcher then has to notice and choose it within the link interface.
    • The landing page has to confirm quickly that the click was worthwhile.

    That middle step is the important change. A citation can now be exposed through a richer, more noticeable interaction, but greater visibility is not the same as a visit. The other links in the group remain alternatives, and the user may decide that the generated answer is already sufficient.

    Google says its testing found the interface more engaging and made web content easier to reach. Treat that as a directional product finding, not a traffic forecast for your site. The result depends on whether you are cited, how your option is presented, what else appears beside it and whether the searcher still needs more information.

    Optimize for citation, choice and landing-page confirmation

    A structured webpage connects to a highlighted source card and then to a visually matching landing page.

    Do not infer a new markup requirement from the interface. A new visual treatment is not evidence of a special interactive-link schema or a new ranking signal. Keep valid structured data where it accurately describes the page, but do not invent properties or rename schema solely to chase the pop-up.

    Instead, audit the whole path from the question to the page. Start with URLs that directly answer the questions your audience asks and that already receive impressions for relevant queries. Then review each candidate against the following criteria:

    • Question alignment: The page should address the searcher’s actual problem, not merely mention the same entity or keyword. If the relevant answer is a minor aside, give it a focused section or use a better page.
    • Immediate answer: State the useful answer near the beginning of the relevant section. A reader arriving from an AI response should not have to reconstruct it from a long introduction.
    • Descriptive headings: Use section headings that identify the decision, process or distinction being explained. Generic headings make both scanning and passage-level understanding harder.
    • Clear page promise: Make the title specific enough to distinguish your page from adjacent sources. The wording should describe what the visitor will learn without promising evidence, scope or freshness the page does not provide.
    • Visible substantiation: Put definitions, qualifications and supporting evidence close to the claims they support. Add authorship and update information when those details genuinely help a reader judge the material.
    • Landing-page continuity: The heading and opening visible after the click should confirm that the visitor reached the expected answer. If the title promises a procedure but the page begins with a broad industry essay, the click has created friction.
    • Useful next step: Once the immediate question is answered, provide a relevant route to a deeper explanation, tool, product category or decision page. Do not force that continuation before delivering the answer that earned the visit.
    • Mobile usability: Check the page on a narrow screen. A prominent mobile link is of little value if overlays, slow media, crowded navigation or an unclear opening block the answer.

    Keep these improvements honest. Rewriting every heading as a question, repeating the same answer in several sections or adding unsupported claims may make a page look optimized while making it less useful. The goal is not to imitate an AI response. It is to make the underlying page the clearest place to verify, understand and act on the answer.

    You should also separate interface optimization from eligibility. Better titles, openings and page structure can improve the experience when your page is shown, but they do not guarantee inclusion in an AI Overview or AI Mode response. Record inclusion and post-click performance as separate outcomes so a content change is not credited for something it did not cause.

    Measure impact without inventing attribution

    Glowing visitor paths pass through a transparent observation frame between an abstract search panel and a website panel.

    The rollout does not provide a dedicated way to isolate the impact of interactive links in Google Search Console. Existing search metrics can show that a page’s performance changed, but they cannot by themselves prove that a hover card or a more prominent icon caused the change.

    Use two connected records: a manual visibility log for the interface and your normal performance data for outcomes.

    1. Create a fixed watchlist of commercially or editorially important questions. Avoid changing the query set whenever you see an interesting result, because that makes comparisons inconsistent.
    2. For every observation, record the query, date, device type and whether you checked AI Overviews or AI Mode. Note whether your URL appeared, what context was visible and which other sites shared the link group.
    3. Save a screenshot when the interface or citation changes. The screenshot preserves evidence that aggregate analytics cannot supply later.
    4. Before editing a candidate page, export its Search Console impressions, clicks and click-through rate by page, query and device. Preserve that baseline rather than relying on memory.
    5. Annotate the date and substance of every material content change. Changing the title, answer, structure and conversion path simultaneously will make the result difficult to interpret.
    6. Review on-site sessions and meaningful outcomes for the same landing pages. Choose outcomes that fit the page, such as a completed signup, a qualified inquiry, a product-view continuation or another defined conversion.
    7. Compare the edited pages with relevant pages you did not change. This does not create perfect causal proof, but it can help you notice whether a movement is page-specific or widespread.

    Interpret the patterns carefully. More observed citations with flat clicks can mean that visibility improved without winning the user’s choice. Higher visits with weak engagement can reveal a mismatch between the visible promise and the landing page. Stronger engagement or conversions without a clear Search Console shift can still justify improving the post-click journey, but it does not prove the interactive links supplied the visitors.

    Seasonality, ranking changes, query demand, competing results and your own edits can move the same metrics. Use language such as associated with or observed after when reporting the result internally. Reserve caused by for evidence that can actually isolate the interface.

    Key takeaways

    • Desktop users can reveal grouped links in AI Overviews and AI Mode by hovering, while both desktop and mobile receive more prominent, descriptive link icons.
    • The interface increases the visibility of source choices; it does not guarantee that a citation will produce a click.
    • There is no basis here for adding a special interactive-link schema. Concentrate on accurate structured data and a page that clearly fulfills the cited question.
    • Audit three separate stages: citation inclusion, selection from the link group and post-click performance.
    • Search Console cannot isolate the feature’s impact, so combine a manual query log with page-, query- and device-level performance data.
    • Report changes as directional unless you can separate the interface from rankings, demand, competing results and content edits.

    Start with a small, stable watchlist and capture the baseline before changing anything. Improve the pages where a clearer answer and a better landing experience would help regardless of how Google’s interface evolves. That gives you useful content now and credible evidence when the link treatment changes again.

    References

  • How Google Counts Impressions When One URL Appears Twice

    How Google Counts Impressions When One URL Appears Twice

    You see your page cited inside an AI Overview and again as a traditional blue link. It looks like two pieces of search-result real estate, so you expect Google Search Console to report two impressions. It won’t.

    When the same URL appears in both places for the same query and search experience, Google Search Console records one impression rather than two. Once you understand what is being counted, you can stop treating the result as a tracking fault and start measuring the extra visibility separately.

    Key takeaways

    • The same URL appearing in an AI Overview and a traditional blue link produces one Search Console impression for that search experience.
    • Google treats an AI Overview as one position, with the links inside it sharing that position under the usual impression rules.
    • Repeated appearances of the same URL in the current set of results are aggregated rather than counted as separate impressions.
    • One impression does not mean there was only one placement. It means Search Console has compressed those placements into one URL-level count.
    • Keep Search Console performance data and observed SERP placement data in separate reporting layers if you need to evaluate AI Overview visibility.

    The counting rule follows the URL, not the number of boxes

    One webpage tile branches into two different search result placements while passing through a single counting gate.

    An impression is tied to the visibility of a link within the current set of search results. Google does not issue another impression merely because the same URL is presented in a second search feature on that results page.

    This matters because an AI Overview may contain several links while occupying a single position. Each link in the Overview shares that position and remains subject to the standard visibility rules. If one of those URLs also appears in the blue links below, the extra occurrence does not create a second impression for that URL.

    What happens in one search experienceHow to interpret the impression countWhat not to assume
    The same URL appears in an AI Overview and a blue linkOne impression is counted for that URLThe second placement was not necessarily missed or ignored
    The same URL appears more than once in the current resultsThe occurrences are aggregatedEach visual instance does not receive its own impression
    The user scrolls past the URL and returns to itNo additional impression is created within that results experienceRepeated visibility does not restart the counter
    Two different URLs from the same site appearThe same-URL clarification does not determine the resultDo not extend a URL-level rule to an entire domain without separate evidence

    The last distinction is important. The rule is about the same URL. It does not establish that every appearance from the same brand, domain, or group of similar pages will be consolidated. When you investigate a discrepancy, compare URLs rather than counting logos, domains, or visually similar listings.

    One impression does not mean one placement

    Search Console’s count is easy to misread as an inventory of everything Google displayed. It is not. In this situation, one impression can represent a URL that occupied two visibly different parts of the results page.

    That compression limits what you can conclude from the number alone. A single recorded impression cannot tell you whether the searcher noticed the AI Overview citation, the blue link, or both. It also cannot isolate the incremental effect of securing both placements.

    • Do conclude: the URL received one qualifying Search Console impression under Google’s counting rules.
    • Do not conclude: the URL appeared only once on the results page.
    • Do conclude: the Search Console impression total should not be manually doubled to reflect two observed placements.
    • Do not conclude: the second appearance had no value simply because it did not add another impression.
    • Do conclude: dual placement can reinforce brand visibility and credibility.
    • Do not conclude: that reinforcement produced a specific traffic or conversion lift unless you have separate evidence.

    This is the practical distinction between measurement and presence. Search Console measures the impression according to its rules. The results page may still give the searcher two opportunities to encounter your page. Those are related facts, but they are not interchangeable metrics.

    Audit dual appearances without rewriting Search Console data

    If your dashboard appears to be missing an impression, first test whether the expected second impression came from counting the same URL twice on one results page. Use a short audit that preserves the reported data while documenting the SERP layout.

    1. Define the suspected duplication. Record the query, the URL, and the two elements in which you observed it. Use labels such as AI Overview and blue link instead of writing only that the page ranked twice.
    2. Verify that it is the same URL. Do not treat two pages from one domain as though they were automatically one reporting unit. If the displayed addresses differ, flag that difference rather than forcing the same-URL rule onto them.
    3. Capture the search-result composition. Note whether the URL appeared in the AI Overview, the traditional results, or both. This is placement evidence, not an adjustment to Search Console.
    4. Leave the Search Console impression unchanged. If the same URL occupied both placements in the same search experience, one impression is the expected result. Adding a second impression in a spreadsheet would make your derived total incompatible with Google’s count.
    5. Check the reporting model. A dashboard that creates one row per SERP feature may duplicate a shared impression when those rows are added together. Keep the impression in one performance record and store the placement labels separately.
    6. Repeat the observation before making a strategic claim. A single captured results page can confirm that dual placement is possible. It cannot, by itself, establish how often the pattern occurred across the full reporting period.

    This process also helps you identify the real problem. If the count matches the same-URL rule, there is no impression-counting error to fix. The missing element is a separate record of where the URL appeared.

    Report Search Console performance and SERP coverage separately

    A divided workspace shows one recorded impression on an analytics screen and two observed placements on a search results page.

    A useful report needs two layers. The first preserves Google’s performance data. The second describes the search features you observed. Combining them into one placement-based impression total creates false precision.

    Search Console performance layer

    Keep the query, URL, impressions, and other Search Console metrics together. Do not clone the record simply because the URL also appeared in an AI Overview. If you create separate AI Overview and blue-link rows, allocate placement labels without assigning the same impression to both rows and then summing them.

    SERP observation layer

    For each observation, store the query, exact URL, whether an AI Overview link was present, whether a blue link was present, and whether both occurred together. Include when the observation was made so nobody mistakes a captured result for a permanent search layout.

    The clean reporting language is: dual placement was observed, while Search Console counted the same URL once under its impression rules. Avoid saying that impressions doubled, that Search Console undercounted visibility, or that the second appearance generated a known incremental benefit. None of those claims follows from the impression total.

    Use the same distinction when setting targets. Search Console impressions can track reported URL visibility over time. A separate coverage field can track whether you are present in an AI Overview, a blue link, or both. That gives stakeholders two honest signals instead of one inflated number.

    The next time one URL occupies both parts of the results page, don’t adjust the impression count. Add a dual-placement annotation, preserve Google’s number, and evaluate the extra surface coverage as its own signal.

    References