Category: Google Analytics

  • Google Analytics Hostname Allowlists: A Safe Setup Plan

    Google Analytics Hostname Allowlists: A Safe Setup Plan

    Your Google Analytics reports can look convincing even when unwanted event traffic is mixed into the numbers. That becomes a practical problem when you use those numbers to allocate budget, judge content, or explain performance to a client.

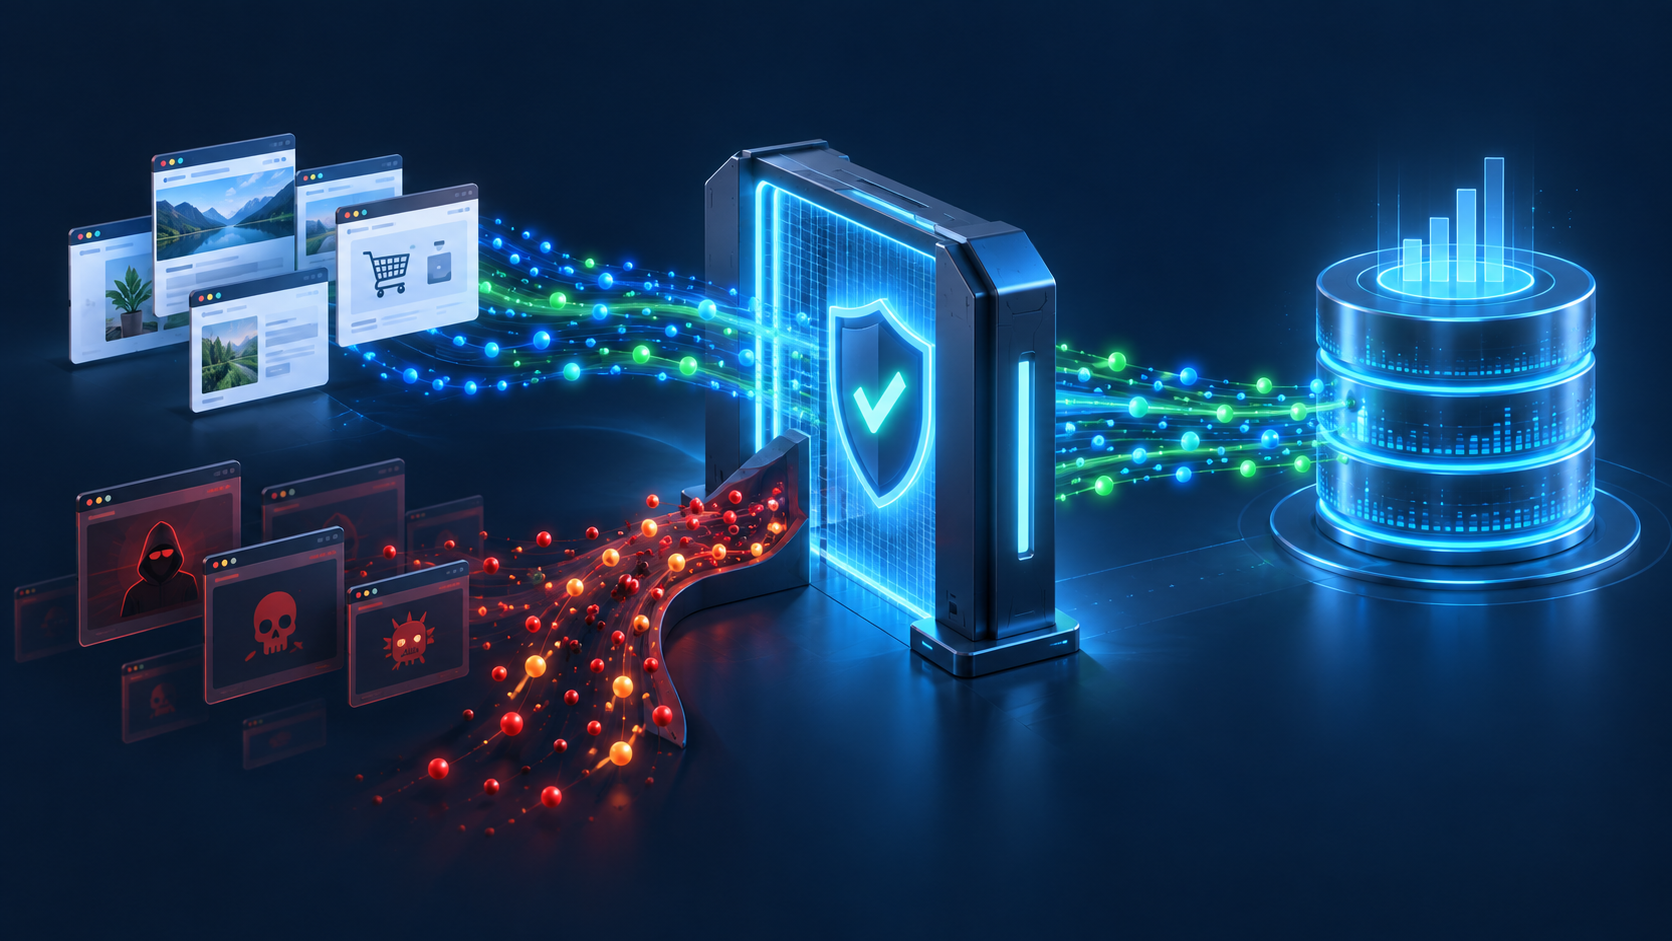
    A hostname allowlist gives you a cleaner default: define where legitimate browser events may originate, then filter events associated with other hostnames. The important work is not creating the filter. It is identifying every valid hostname, understanding what the filter does not cover, and checking that your measurement still represents the customer journey.

    Why an Include filter is stronger than a growing blocklist

    Hostname filtering used to be built around Exclude filters. You found an unwanted hostname, added it to the filter, and repeated the process when another one appeared. Google Analytics now supports Include filters for approved hostnames, so events associated with hostnames outside your approved set can be filtered out.

    The difference is operational, not cosmetic. An exclusion list assumes you can keep discovering every bad or irrelevant hostname. An allowlist asks a more manageable question: which hostnames does this property intentionally measure?

    That makes the approach useful when spam or unwanted event traffic keeps resurfacing. It can also reduce the maintenance burden for an organization that operates several sites or routinely sees events from places that should not contribute to the property.

    The tradeoff is precision. A denylist fails open: something new remains until you exclude it. An allowlist fails closed for browser traffic: forget a legitimate hostname and its events can be filtered out. Treat the allowlist as part of your measurement architecture, not as a quick cleanup rule.

    Key takeaways

    • Use a hostname Include filter when you can define the trusted domains that should contribute browser events to the property.
    • Build the list from the intended customer journey and site architecture, not only from hostnames already visible in a potentially polluted report.
    • Do not confuse a hostname with a traffic source. The hostname identifies where the measured page or experience is hosted; it does not identify who sent the visitor there.
    • Expect events with an empty hostname to be blocked by the Include filter, and investigate them before assuming every empty value is spam.
    • Handle Measurement Protocol separately because hostname Include filters do not apply to those events.
    • Review the allowlist whenever a launch, migration, subdomain, or externally hosted journey changes where browser events originate.

    Build an allowlist that matches the real measurement journey
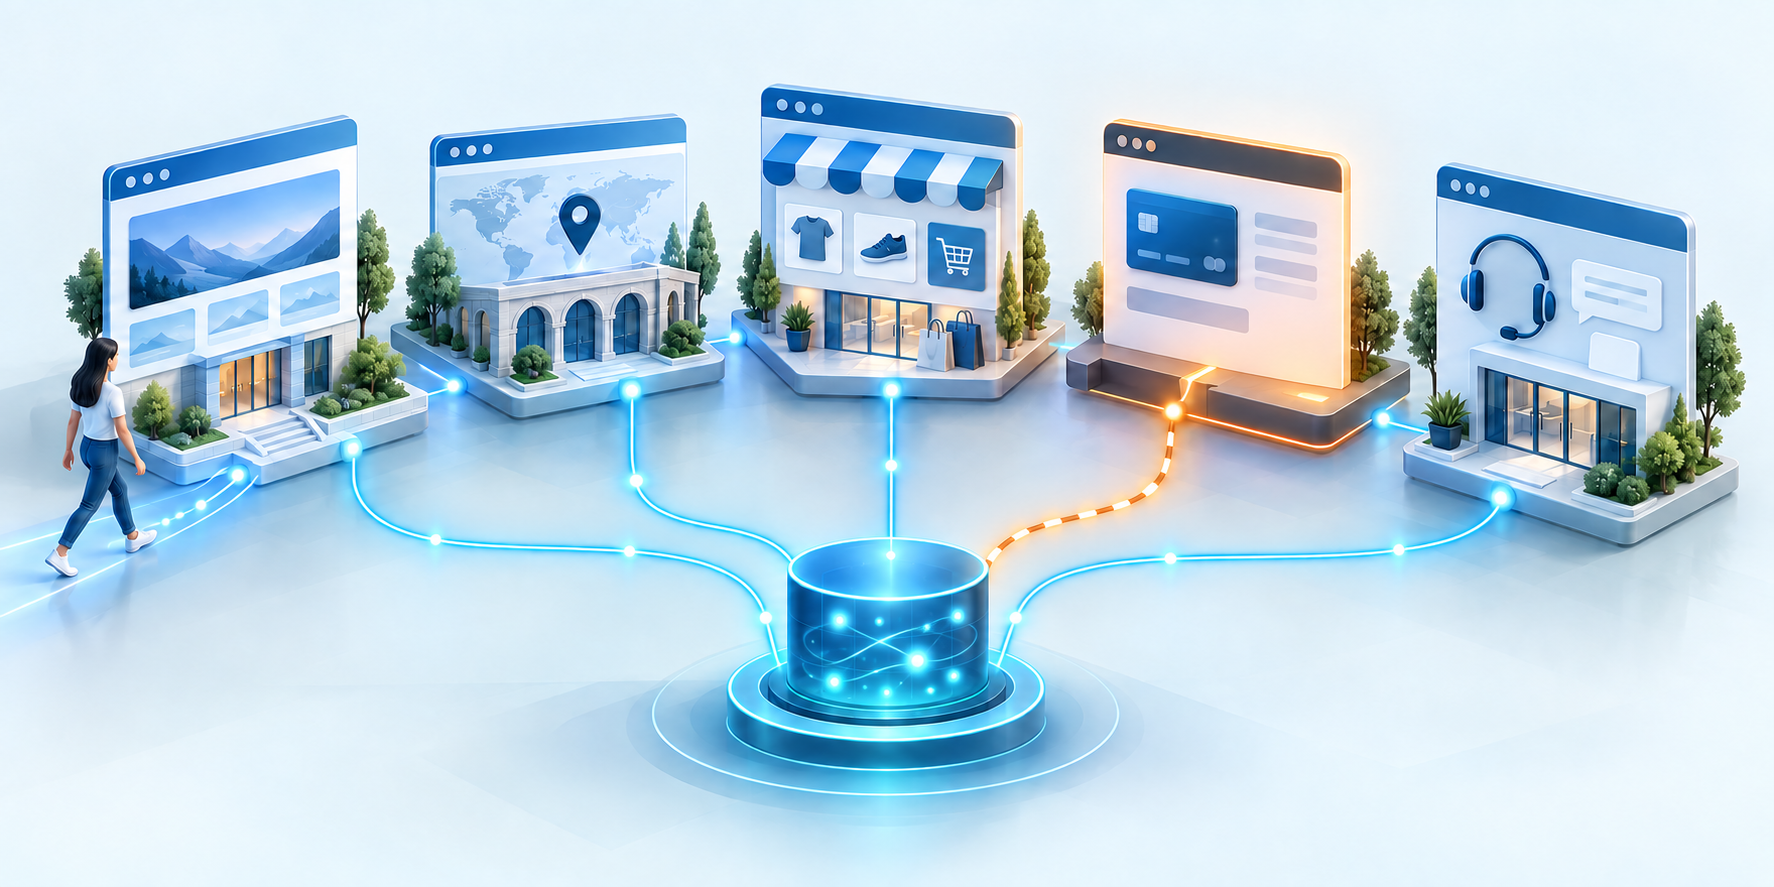
    A visitor journey connects a main website, regional site, store, hosted checkout, and support portal to one analytics hub.

    Start with what the property is supposed to measure

    Do not begin by copying every hostname you see in a report. That risks turning existing contamination into an approved list. Begin with the purpose of the property: which websites and browser-based experiences should contribute to its reporting?

    Map each stage of a journey that matters. Your main website may be obvious, but a legitimate interaction can also occur on a first-party subdomain or another hostname used for a deliberately measured step. Include such a hostname only when its events truly belong in this property. Ownership alone is not enough; relevance to the property’s measurement scope is the test.

    Record hostnames, not complete URLs. A page path such as a pricing or confirmation page is not another hostname. Keeping that distinction clear prevents a domain-control filter from becoming an improvised page-level rule.

    Event situationAllowlist decisionWhat to verify
    Browser event from the primary public websiteIncludeThe hostname is written exactly as it appears in the intended implementation.
    Browser event from a first-party subdomainInclude only if intentionalThe subdomain’s activity belongs in this property and supports a measured journey.
    Browser event from a staging or test environmentUsually keep separate unless explicitly requiredThe property is genuinely intended to contain test activity.
    Browser event from an unfamiliar third-party hostnameDo not approve by defaultA known business process deliberately generates relevant events there.
    Event with an empty hostnameAutomatically blocked by the Include filterThe missing value is not evidence of a broken legitimate collection path.
    Event sent through Measurement ProtocolNot governed by the hostname Include filterThe sending system and its event quality are controlled separately.

    Investigate empty hostname events before activation

    An Include filter automatically blocks events whose hostname is empty. That is useful because a missing hostname can indicate spam or abnormal activity. It is not proof that every affected event is malicious, however. Some traffic sent through gtag.js can also arrive without a hostname.

    Use that behavior as a diagnostic checkpoint. Before relying on the filter, determine whether an important browser journey produces empty hostname values. If it does, fix or intentionally account for the collection path rather than approving an unknown value or accepting an unexplained loss of data.

    The practical question is simple: if empty-hostname events disappear, will a real conversion, page interaction, or business process disappear with them? If you cannot answer that yet, the implementation is not ready to support decisions.

    Separate Measurement Protocol governance from browser filtering

    Hostname Include filters do not apply to Measurement Protocol events. That exception protects server-side and offline events from being unintentionally rejected by a browser-oriented hostname rule.

    It also means the allowlist is not a complete perimeter around the property. A property can have cleanly filtered browser events while continuing to receive Measurement Protocol events. Inventory those senders separately and confirm that each one is authorized, necessary, and mapped to the correct property.

    This distinction matters when you investigate a suspicious event after enabling the allowlist. Do not conclude that the filter failed merely because the event remains. First determine whether it arrived through the browser collection path or through Measurement Protocol. The two routes are subject to different controls.

    Roll out the filter without creating a reporting blind spot
    An analyst monitors parallel original and filtered event streams in a dark control room during a staged rollout.

    A useful rollout has three parts: scope, validation, and ownership. Skipping any one of them can replace noisy data with incomplete data, which is harder to notice because the reports may still look tidy.

    1. Write down the property’s purpose. State which sites, environments, and customer journeys should contribute events. This gives every hostname an explicit reason to be included or omitted.
    2. Inventory trusted browser hostnames. Check the primary domain, intentional subdomains, and any separate host involved in a measured step. Do not approve an unfamiliar hostname merely because it already appears in the data.
    3. Identify non-browser senders. List the systems that use Measurement Protocol so nobody assumes the hostname filter governs them.
    4. Create the hostname Include filter. Use the approved inventory as the filter’s specification. Keep the written inventory with the analytics configuration so future changes can be reviewed against it.
    5. Exercise critical journeys. Confirm that the browser-based pages and actions your team relies on still contribute the expected event types under their legitimate hostnames.
    6. Check the negative cases. Verify that unapproved browser hostnames and empty-hostname events no longer affect the filtered view of your data, while separately checking that intended Measurement Protocol activity remains accounted for.
    7. Assign an owner. Make one role responsible for reviewing the allowlist when the web architecture changes. Without ownership, a correct filter gradually becomes incomplete.

    Document why each hostname is trusted, not just its spelling. A short reason such as “public product site” or “measured account subdomain” gives the next reviewer enough context to remove obsolete entries and challenge unexplained additions.

    Know what cleaner analytics can and cannot improve

    A hostname allowlist is a data-quality control. It can make reports more dependable by preventing unapproved browser hostnames from distorting the dataset. That supports better decisions about acquisition, content, conversion, and campaign performance.

    It is not an SEO, AEO, or generative-engine ranking signal. Enabling it does not make a page more crawlable, authoritative, or likely to be cited by an AI system. The benefit is indirect: your team is less likely to prioritize a landing page, channel, or conversion path because unwanted traffic made it appear more important than it was.

    Be especially careful with trend comparisons around the change. A visible drop may represent removed noise, accidentally filtered legitimate activity, or both. Check hostname coverage and collection routes before interpreting the difference as a change in audience demand or marketing performance.

    Put the allowlist review into the same launch checklist you use for a new subdomain, domain migration, or externally hosted customer step. The next architecture change should update the measurement boundary before anyone relies on the resulting reports.

    References


  • How to Build a Google Analytics Dashboard for Decisions

    How to Build a Google Analytics Dashboard for Decisions

    You open Google Analytics to answer one question and end up moving through several reports, copying figures into a document, and trying to remember whether everyone used the same comparison period. The data may be available, but the route to a decision is unnecessarily long.

    Google Analytics Dashboards can shorten that route by putting selected KPIs and visualizations on a customizable, grid-based canvas. The useful part isn’t the canvas itself. It is the discipline of deciding which questions deserve permanent space, which chart can answer each question, and what someone should do after seeing the result.

    Decide what the dashboard must make obvious

    A dashboard should reduce decision time. It shouldn’t reproduce every report your team might occasionally need. Before you add a card, write a short dashboard brief that answers:

    • Who will use it? An SEO lead investigating landing pages needs different detail from an executive checking overall acquisition and conversion performance.
    • What recurring decision will it support? Examples include deciding where to investigate a traffic decline, which content group needs attention, or where users leave a conversion journey.
    • How often will someone review it? The review rhythm determines whether short-term movement or longer trends deserve more space.
    • What is the primary outcome? Name the result the dashboard is supposed to monitor before choosing supporting metrics.
    • Who owns the response? A metric without an owner becomes decoration. Decide who investigates, who explains, and who acts.

    Turn each proposed card into a complete question. “Organic traffic” is only a label. “Is traffic from organic discovery moving in the expected direction, and which landing content explains the change?” is a question. It tells you that you need a headline value, a trend, and enough detail to locate the affected content.

    Give every KPI an explicit scope as well. The team should know which property, audience, outcome, time period, and comparison the number represents. Two people can read the same number differently when one assumes all traffic and the other assumes a particular channel. The dashboard won’t fix an unsettled definition; it will simply make the ambiguity more visible.

    This distinction matters for SEO, AEO, and GEO reporting. Google Analytics can show activity captured in the property, including measurable visits and subsequent behavior. It cannot turn external rank tracking, AI citation visibility, crawl findings, CRM revenue, or platform delivery data into Analytics measurements merely by arranging cards on a page. Keep those claims in their appropriate systems, then use the dashboard for the questions its data can actually answer.

    Build from outcomes to diagnosis

    A large outcome tile branches into several smaller diagnostic dashboard modules in a layered hierarchy.

    The builder lets you drag dimensions and metrics onto the canvas, then position, resize, and align the resulting visualizations. That makes experimentation easy, but it also makes it easy to fill the page before establishing a hierarchy.

    Build in the order a reader will think:

    1. Start with the outcome. Place the KPI that best represents the dashboard’s primary business result where the eye lands first.
    2. Add its context. Show the input or volume metric needed to interpret that result. An outcome without scale can make a small fluctuation look more important than it is.
    3. Show direction. Add a time-series view so the reader can distinguish a sustained movement from an isolated value.
    4. Expose the main comparison. Break performance down by the category most likely to explain a change, such as an acquisition grouping or content grouping that your measurement plan defines consistently.
    5. Provide a diagnostic route. Use a detailed table for the pages, campaigns, or other entities someone will inspect next.
    6. Add the journey where it matters. If the decision concerns an ordered conversion process, use a funnel to reveal the step where progress changes.
    7. Remove repetition. If two cards lead to the same observation and action, keep the clearer one.

    This sequence creates a practical reading path: outcome, context, trend, explanation, detail, action. It also leaves room beneath the documented cap of 15 cards for standard properties. Premium properties can contain up to 30, but a larger allowance isn’t a reason to use every available position.

    Review the completed canvas at the size your intended audience will normally use. Visual priority comes from position and size as well as chart type. If the primary outcome is smaller than a supporting breakdown, the layout is telling the reader that the breakdown matters more.

    Match each business question to the right visualization

    Six dashboard cards display abstract line, bar, ring, funnel, dot, and gauge visualization forms.

    Six visualization types are available: scorecards, tables, line charts, bar charts, donut charts, and funnel charts. Choose among them by the question being asked, not by the visual variety they add to the page.

    VisualizationQuestion it should answerBest useCommon mistake
    ScorecardWhat is the current headline value?A primary KPI or an essential context metricDisplaying several isolated values without showing why any change matters
    Line chartWhen did the movement begin, and did it persist?Performance over timeUsing a trend line when the real question is a comparison between categories
    Bar chartWhich categories are larger, smaller, ahead, or behind?Direct category comparisonsAdding so many categories that meaningful differences become hard to see
    Donut chartHow is a whole divided among a limited set of parts?A simple composition or share breakdownUsing similar-sized or numerous slices that are difficult to compare
    TableWhich exact item requires investigation?Detailed rows that support diagnosisTurning the dashboard into an exhaustive data export
    Funnel chartAt which ordered step does progression change?Conversion steps and drop-offsTreating unrelated actions as if they formed a single sequential journey

    Use date context deliberately. Scorecards can display percentage change when a date comparison is applied, while line charts support daily, weekly, and monthly views. Pick the line-chart interval that matches the decision rhythm. A view that is too granular can distract the reader with ordinary variation; one that is too broad can conceal when a meaningful shift began.

    A percentage movement also needs its underlying value. A large percentage attached to a small base may deserve less attention than a modest movement in the metric most closely tied to the business outcome. Keep the scorecard for quick detection, then place a trend or detailed breakdown nearby so the reader can test whether the movement is broad, persistent, and actionable.

    Publish with property-wide governance in mind

    Creating a useful layout is only half the job. A user needs an Editor or Administrator role to create and publish a dashboard. Once published, the dashboard can be viewed by anyone who has access to the property, and it can be placed directly in the Reports navigation without routing it through the Analytics library.

    That convenience changes the governance standard. Published dashboards are shared across the property rather than privately with selected individuals, so don’t treat the published area as a personal scratchpad. Settle experimental metric definitions and layouts before exposing them to every property user.

    • Name the audience and purpose clearly. A title such as “Content performance” is weaker than one that identifies the intended decision or review context.
    • Assign an owner outside the dashboard. Someone should be responsible for definitions, layout changes, and questions from viewers.
    • Record the KPI definitions. Preserve the scope, outcome meaning, and expected response in team documentation so the dashboard doesn’t become its own undocumented vocabulary.
    • Check the published view with ordinary access. Confirm that the navigation placement and reading order work for viewers, not only for the person who built it.
    • Review cards when strategy changes. Remove KPIs that no longer inform a live decision instead of leaving them in place for historical familiarity.

    Plan around the launch limitations before promising the dashboard as a complete reporting system. API support, segments, and card-level comparisons were not supported at launch. That means you shouldn’t design a workflow that depends on programmatic dashboard management, segment-based dashboard cards, or a different comparison basis for each card unless those capabilities are verified in your property.

    The absence of card-level comparisons is especially important. Agree on a coherent comparison before presenting the page, and explain any analysis that requires a different baseline somewhere else. Otherwise, adjacent cards can appear comparable while answering different questions.

    Key takeaways

    • Start with a recurring decision and its owner, then choose the metrics needed to make that decision.
    • Arrange cards as a reading path from outcome to context, trend, explanation, and diagnostic detail.
    • Use scorecards for headline values, line charts for timing, bar charts for comparison, donut charts for simple composition, tables for diagnosis, and funnels for ordered journeys.
    • Keep metric definitions and scope explicit; a clean layout cannot repair an ambiguous KPI.
    • Design within the 15-card standard or 30-card premium limit, but treat those figures as ceilings rather than targets.
    • Publish only after accounting for property-wide visibility, role requirements, and the feature limitations that applied at launch.

    Your first dashboard should feel focused rather than comprehensive. Open the builder with your decision brief beside you, place the primary outcome first, and add a card only when it helps the reader detect a change, explain it, or choose the next action. If a card does none of those jobs, leave the space empty.

    References


  • GA4 Shows Zero Traffic on September 1: What to Do

    GA4 Shows Zero Traffic on September 1: What to Do

    If GA4 shows a flat zero for September 1, 2026, don’t start changing tags. The same alarming gap has appeared across many accounts, so the chart is not reliable evidence that your audience disappeared.

    September 1 was showing no Google Analytics data across multiple properties, while no cause or official Google confirmation had been reported. A Google-side reporting or processing problem is therefore the leading explanation, but you should still verify that your own site and data collection are healthy.

    What the September 1 gap does and does not tell you

    A zero in a report can describe two very different situations: no activity occurred, or activity was not available to that report. Treating those conditions as interchangeable is how a temporary analytics incident turns into bad marketing decisions.

    The widespread pattern makes an isolated collapse in your website traffic less likely. It does not yet establish the exact failure mode. Google had not confirmed the incident, identified its cause, supplied a resolution time, or said whether the missing data would be restored. Until those questions are answered, describe September 1 as unavailable or provisional data rather than verified zero traffic.

    Key takeaways

    • Do not interpret the September 1 GA4 zero as proof that traffic, rankings, leads, or sales collapsed.
    • Check independent operational systems before deciding whether you also had a website or tracking problem.
    • Avoid republishing tags, changing consent settings, or adding a second tracker merely to make the historical gap disappear.
    • Mark September 1 as provisional in dashboards and reports so the apparent zero does not distort comparisons.
    • Investigate locally if the gap extends beyond the affected date, current events are also absent, or other business systems show a matching decline.

    Separate a GA4 reporting failure from a real outage

    An analyst inspects a working event stream that becomes obscured at a separate reporting layer.

    You don’t need to prove the internal cause before protecting the business. You need to establish whether customers could reach the site, whether meaningful activity continued, and whether the anomaly is limited to GA4.

    1. Record the exact scope. Note the GA4 property, data stream, property time zone, affected date, report, filters, comparisons, and the time you checked. Save an unedited screenshot. This gives you a clean baseline if the figures later change.
    2. Inspect a wider date range. Confirm whether only September 1 is blank or whether the gap continues into adjacent dates. Also remove report filters and comparisons temporarily. A date-specific gap across ordinary reports points in a different direction from an ongoing absence confined to one filtered view.
    3. Compare other properties you legitimately manage. The same date missing from unrelated properties supports the working theory of a shared GA4 problem. One affected property while the others behave normally deserves closer inspection of that property’s collection setup.
    4. Check independent evidence of activity. Ecommerce teams can review orders and payment records. Lead-generation teams can check form submissions, call records, and CRM entries. Publishers can use web-server or CDN requests. Paid teams can inspect platform-side clicks and conversions. SEO teams can use Search Console and server logs as directional evidence.
    5. Check the present separately from the past. Verify whether current page views and events are reaching your live-event or debugging tools. Current collection can be healthy while a historical date remains unavailable in standard reports.
    6. Review your change history last. Look for releases involving the Google tag, Google Tag Manager, measurement IDs, consent controls, redirects, domains, checkout flows, or content security settings. Investigate a coinciding change when the evidence points to your property; do not assume coincidence proves causation.

    These systems will not produce identical totals. They measure different actions, use different attribution rules, and may process data on different schedules. For this triage, you are not trying to reconcile every session. You are answering a narrower question: did meaningful activity continue while GA4 displayed zero?

    Observed patternWorking interpretationNext action
    Several unrelated GA4 properties are blank on September 1, while independent activity looks normalA shared reporting or processing incident is more likelyPreserve the implementation, document the gap, and recheck the affected reports
    One property or stream is blank while comparable properties workA property-specific configuration or collection problem is more plausibleInspect deployments, measurement IDs, filters, consent behavior, and stream coverage
    GA4, orders, leads, and server activity all fall togetherA genuine website, demand, or operational problem may have occurredUse your normal site-incident and business-diagnosis process
    The historical date is blank, but current events are arrivingThe problem may be limited to historical processing or reportingKeep current tracking unchanged and leave September 1 flagged as provisional

    Do not create a second problem while trying to fix the first

    A vendor-side reporting problem cannot be repaired by repeatedly publishing your container. Unnecessary changes can duplicate events, split data between measurement IDs, alter consent behavior, or make later diagnosis harder.

    Unless your checks reveal a separate local fault, avoid these responses:

    • Do not add another GA4 tag to compensate for the missing date.
    • Do not replace a measurement ID simply because one historical report is blank.
    • Do not loosen consent settings in an attempt to recover traffic.
    • Do not republish an unchanged tag container as a speculative fix.
    • Do not import invented session or conversion values to fill the hole.
    • Do not overwrite raw exports or source tables with estimates.

    If you find a genuine configuration error, make the smallest correction that addresses that error and document its publication time. That separation matters: otherwise you may not be able to tell whether subsequent data returned because Google resolved the broader incident or because your implementation changed.

    Keep one missing day from corrupting performance decisions

    One empty data tile is isolated within a longer sequence while a strategist evaluates the surrounding trend.

    The operational risk is not just an empty chart. September 1 can flow into weekly totals, period-over-period comparisons, blended dashboards, automated alerts, forecasts, campaign rules, and client reports. A literal zero makes every downstream calculation look more definitive than the underlying data deserves.

    • Flag the date. Add an incident annotation or companion note wherever September 1 appears. Include the affected property and state that the value is provisional.
    • Represent missingness honestly. In derived dashboards, use an unavailable or null state for the flagged date when your reporting process permits it. Do not silently substitute zero.
    • Pause final reporting for that date. You can continue preparing a report, but do not lock totals, comparisons, or conclusions that depend materially on September 1.
    • Recalculate affected windows. If data later appears, rerun every report whose range includes September 1 rather than updating only the daily chart.
    • Audit automation. Check whether the apparent zero triggered alerts, bid or budget rules, pacing decisions, anomaly detection, or stakeholder notifications. Reverse a downstream action only after verifying why it fired.
    • Preserve the original evidence. Keep the screenshot, query conditions, report export, and incident note. Do not erase the audit trail when the numbers change.

    For paid campaigns, a GA4 zero by itself is not a sound reason to pause spending; examine ad-platform activity and business outcomes first. For SEO and AEO work, it is not evidence of lost rankings or lost visibility. Check search performance and server activity, then revisit GA4 when processing is restored or clarified.

    Know when to treat it as your own tracking incident

    The widespread September 1 pattern is useful context, not a permanent explanation for every empty report. Move from watchful documentation to a property-level investigation when your evidence stops matching the shared incident.

    • The missing range extends beyond September 1 while other properties have normal data.
    • Current live-event checks show no activity despite confirmed visits.
    • Only one data stream, hostname, region, device group, or conversion path is affected.
    • A tag, consent, domain, redirect, or deployment change coincides with the beginning of the gap.
    • Independent systems also show that visits, transactions, or leads stopped.
    • The broader reporting issue clears but your property remains blank.

    Until one of those signals appears, keep the response controlled: preserve your measurement setup, mark September 1 as unavailable, assign one owner to recheck the affected reports, and rerun dependent analysis if the figures return. That protects both your data and the decisions built on it.

    References


  • Google Analytics Attribution Windows: How to Choose the Right Fit

    Google Analytics Attribution Windows: How to Choose the Right Fit

    Your campaigns may not be underperforming. Your attribution window may simply be cutting off conversions before your customers finish deciding.

    Google Analytics now gives you much finer control over that cutoff. The useful question isn’t whether you should choose a longer window. It’s which window reflects the conversion you’re measuring, the interaction you’re crediting, and the decision you need the report to support.

    What an attribution window actually changes

    An attribution window, also called a lookback window, defines how long an advertising interaction remains eligible to receive credit for a later conversion. If the conversion occurs after the selected window closes, that interaction no longer qualifies for credit under that setting.

    The window changes attribution eligibility. It doesn’t create or remove the customer’s action, accelerate the buying process, or prove that an ad caused the conversion. That distinction matters whenever a settings change makes campaign results appear better or worse.

    Don’t confuse the window with the attribution model. The window determines which interactions are recent enough to qualify. The model determines how credit is handled among eligible interactions. A model can only work with the interactions admitted by the window.

    A longer window keeps delayed conversions eligible for longer. That can increase the number of conversions associated with advertising interactions, especially when buyers take time to research, compare, seek approval, or return later. A shorter window applies a stricter recency standard, but it can exclude advertising interactions that genuinely began the decision process.

    Neither direction is automatically more accurate. A long window can sweep distant interactions into the report even when their practical influence is uncertain. A short window can make longer consideration journeys disappear from campaign reporting. Your job is to choose the cutoff that makes the report useful for a defined decision.

    Choose the window from the conversion backward

    A conversion platform at the end of a winding customer path, with translucent arcs extending backward across several generic decision moments.

    Start with the event being counted, not the platform’s maximum setting. A form submission, account registration, purchase, and completed contract represent different points in a customer journey. Their normal delays from ad interaction can be very different.

    Define the event before estimating its delay

    If Google Analytics records a lead form as the conversion, select a window for the time between the advertising interaction and that form submission. Don’t silently base it on the later time required to close the sale. Conversely, if the recorded conversion is an imported final outcome, the relevant delay extends to that final outcome.

    Write a one-sentence definition for every conversion you optimize toward: what happened, when it is recorded, and what business decision it informs. This prevents teams from debating window length while referring to different endpoints.

    Use observed decision lag, not a convenient preset

    Look for the elapsed time between relevant ad interactions and the conversion event. Use the evidence available in your analytics paths, ecommerce records, lead timestamps, or customer system. You are looking for the ordinary shape of the delay: whether conversions cluster soon after interaction, continue arriving gradually, or commonly require a longer decision period.

    Then choose the shortest window that still represents the normal journey you intend to measure. This is a decision rule, not a universal benchmark. It keeps the setting tied to customer behavior while limiting credit from interactions so old that their relevance becomes difficult to defend.

    When evidence is thin, don’t hide the uncertainty behind the maximum available value. Pick a defensible starting point, document why you chose it, and treat the setting as a measurement assumption to validate.

    Decide separately for clicks and engaged views

    Click-through and engaged-view conversions begin from different types of advertising interaction, so they shouldn’t inherit the same window without examination. Ask what each interaction represents in your campaign and how long it can reasonably remain relevant to the measured action.

    • For click-through conversions, examine the delay from an ad click to the defined conversion event.
    • For engaged-view conversions, examine the delay from the qualifying view engagement to the same event.
    • If the two paths show different timing, use different windows. Symmetry is not a measurement goal.
    • If stakeholders disagree, make the assumption explicit rather than blending the two interaction types into one unexplained rule.

    Configure the custom windows without defaulting to the maximum

    Google Analytics now accepts any whole-number lookback value within the supported range. That removes the need to force your buying cycle into a small menu of presets.

    Conversion typeCustom rangePrevious limitation
    Engaged-view conversion1 to 30 daysFixed 3-day window
    Click-through conversion1 to 90 daysPreset choices of 1, 7, 14, 30, 60, or 90 days

    In Google Analytics, go to Advertising > Conversion management > Settings. The controls are also available through the conversion management interface in linked Google Ads. Because both surfaces can be involved in campaign measurement, review the active values where your team actually manages conversions rather than assuming everyone is looking at the same configuration.

    1. Inventory the conversions used in reporting, bidding, or budget decisions.
    2. Define the exact customer action represented by each conversion.
    3. Review the observed delay for click-through and engaged-view interactions separately.
    4. Select a whole-day value within the applicable range.
    5. Record the previous value, the new value, the change date, the evidence used, and the owner of the decision.
    6. Check dashboards, recurring reports, and campaign reviews that may be affected by the new eligibility cutoff.

    Resist setting click-through to 90 days and engaged-view to 30 days merely because those values capture the most possible credit. Maximum inclusion isn’t the same as accurate attribution. The right value is the one you can explain in terms of the conversion event and the customer’s normal decision time.

    Evaluate the change without mistaking attribution for growth

    A fixed group of glowing conversion spheres surrounded by adjustable colored pathways that redistribute credit without changing the total number of outcomes.

    A window change can move reported campaign performance even when customer demand and campaign execution haven’t changed. Treat the configuration change as a break in measurement continuity.

    Annotate the effective date in your reporting workflow. When comparing periods, disclose whether both periods used the same window. If they did not, a difference in attributed conversions may reflect the eligibility rule rather than a change in campaign quality.

    Recent conversion cohorts also need time to mature. The longer the selected window, the longer an interaction can remain eligible for a delayed conversion. A click tracked under a 90-day window can continue receiving eligible conversion credit for far longer than one tracked under a short window. Don’t judge the newest cohort as complete while that opportunity remains open.

    Use a controlled review process:

    • Keep a record of the configuration change so analysts can distinguish it from campaign edits.
    • Compare the observed conversion-delay pattern with the window you selected. Conversions accumulating near the cutoff deserve scrutiny because the setting may be truncating a meaningful part of the journey.
    • Inspect click-through and engaged-view results independently before combining them in a campaign conclusion.
    • Ask whether any apparent gain comes from more customer actions or simply from allowing older interactions to qualify.
    • Revisit the choice when the conversion definition, buying process, campaign format, or reporting objective changes.

    The strongest internal test is explainability. A stakeholder should be able to ask, “Why does this interaction still deserve credit?” and receive an answer grounded in the conversion event and observed journey, not in a desire to preserve reported return.

    Key takeaways

    • An attribution window controls how long an ad interaction remains eligible for conversion credit; it does not prove causation.
    • Choose the window for the conversion event actually recorded, not for a later business outcome that Analytics isn’t measuring as that conversion.
    • Google Analytics supports custom click-through windows from 1 to 90 days and custom engaged-view windows from 1 to 30 days.
    • Clicks and engaged views represent different interaction paths, so evaluate their timing separately.
    • Document every window change because it can alter reported attribution without any underlying change in customer behavior.
    • Use the shortest defensible window that captures the normal decision journey, then validate it against observed conversion delay.

    Before your next campaign review, list the conversion actions that influence spend and write down the active window beside each one. Any value your team can’t connect to a defined event and an observed decision lag is the first setting to revisit.

    References


  • How to Use AI Agents for Google Ads and Analytics Reporting

    How to Use AI Agents for Google Ads and Analytics Reporting

    Your reporting problem probably isn’t a lack of charts. It is the delay between a meaningful change, someone noticing it, and the team deciding what to do. AI agents inside Google Ads and Google Analytics can shorten that interval, but only if you treat their answers as the start of analysis rather than the final verdict.

    The practical goal is a tighter reporting loop: detect the change, ask a precise question, verify the answer in the underlying data, and make a documented decision. That is where these tools can save time without quietly lowering the standard of evidence behind your campaign choices.

    Put the agent in the right role

    Google is moving its reporting assistant beyond passive data retrieval. Ask Advisor can surface performance changes, investigate natural-language questions, recommend next steps, and generate visual reports with explanatory summaries. The advertiser still controls campaign decisions.

    That makes the agent most useful as an analyst interface, not an autonomous media buyer. It can reduce the work required to find a signal and form an initial explanation. It cannot remove the need to establish whether that explanation is complete, whether the comparison is appropriate, or whether the proposed action is commercially sensible.

    • Observation: What changed in the data, for which metric, segment, and period?
    • Interpretation: What might explain the change, and which competing explanations remain possible?
    • Decision: What action, if any, is justified after you verify the observation and interpretation?

    Keep those three layers separate in every report. If Ask Advisor connects competitor pressure with a loss of impression share, for example, that is an interpretation to investigate. Confirm the affected campaigns, date range, comparison period, and magnitude before changing bids or budgets. A plausible explanation is not yet an approved action.

    Ask questions that lead to a decision

    A broad prompt such as “What happened?” invites a broad narrative. You may receive an interesting summary without learning what deserves attention. A stronger question gives the agent a metric, scope, comparison, diagnostic angle, and decision to support.

    Use this structure when you write a prompt: Find the change in [metric] for [scope] over [period], compare it with [baseline], break it down by [segments], test [possible explanation], and show what I should verify before [decision].

    Start in Google Analytics when the question is about user or sales behavior

    Google Analytics homepage AI Overviews are designed to summarize important changes since your previous login. They can call attention to developments such as traffic shifts or seasonal sales spikes, offer possible next steps, and pass a selected insight into Ask Advisor for deeper investigation. In this setting, “AI Overview” means an Analytics account summary, not an AI Overview in Google Search.

    A since-last-login summary is useful for triage, but it is not automatically a sound reporting period. Reframe anything important against the comparison your business actually uses before drawing a conclusion.

    • Which traffic change contributed most to the sales movement highlighted on the homepage? Break the result down by channel and device, and identify any seasonal pattern I should test.
    • Which segment explains the largest part of this change? Show whether the account-wide direction still holds inside that segment.
    • What changed first: traffic volume, user behavior, or the reported business outcome? List the views I should open to verify the sequence.

    Start in Google Ads when the question is about campaign delivery

    The redesigned Google Ads homepage uses personalized AI insight cards, while Ask Advisor accepts natural-language questions about issues such as competitor effects on impression share and trends that could influence campaign performance. Use those cards as an investigation queue, not as a replacement for your normal controls.

    • Which campaigns lost impression share during the relevant period, and does the visible pattern support competitor pressure or another explanation?
    • Which performance change is concentrated in one campaign, device, location, or audience rather than spread across the account?
    • What trend could affect campaign performance next, which current metrics support that possibility, and what evidence would contradict it?
    • Create a visual report for the affected campaigns, include the comparison period, and summarize the largest movement without recommending a budget change.

    If an answer does not identify its metric, scope, comparison, and relevant segment, ask again. The purpose of the follow-up is not to make the wording more polished. It is to make the claim testable.

    Use a three-pass reporting workflow

    Three connected workstations depict an AI detecting a change, an analyst verifying evidence, and a reviewed action being documented.

    The cleanest way to integrate an AI agent is to separate detection, investigation, and approval. This prevents a generated explanation from moving directly into a campaign change simply because it arrived in a confident tone.

    1. Pass one – detect: Review the Analytics overview or Ads insight cards. Select only changes that could affect an active business decision. Do not turn every card into a task.
    2. Pass two – frame: Rewrite the selected insight as a question that could be proven wrong. Replace “Performance fell” with a question about the exact metric, campaign or segment, period, and comparison.
    3. Pass two – investigate: Ask Advisor to break the change into relevant components and explore more than one explanation. Request the views or segments needed to check its reasoning.
    4. Pass two – verify: Open the underlying report. Confirm the date range, filters, comparison period, metric definition, conversion setup, and attribution context where relevant. Check that the movement still exists when you inspect the affected segment directly.
    5. Pass three – decide: Record whether you will act, monitor, or reject the hypothesis. Name the evidence that determined the decision so the same question does not restart at the next reporting meeting.
    6. Pass three – distribute: Google Analytics users can opt in to receive AI-generated summaries through email or mobile notifications. Treat a notification as an invitation to review, not as approval to make a campaign change.

    Use a simple stop rule: if the explanation changes materially when you correct the date range, isolate a segment, or apply the intended comparison, the analysis is not ready for action. Continue investigating or leave the campaign unchanged.

    Budget, bid, targeting, and measurement changes can affect real spend and future reporting. Do not approve them from an AI-generated narrative alone. Verify the relevant platform data and apply your existing account approval process first.

    Build dashboards that preserve context

    Analyst examines a transparent dashboard where one performance signal is linked to time, audience, campaign-change, and comparison context.

    Google Ads Dashboards can be generated from text prompts, with AI producing visual reports and real-time summaries of the trends represented by the charts. Google Analytics support was identified as a later addition, so availability may differ between the two products. If the Analytics option is not present in your account, use Ask Advisor for investigation and keep your established reporting workflow in place.

    A useful dashboard should preserve the path from outcome to diagnosis. Build it in layers so a reader can see what changed before encountering an explanation:

    • Outcome layer: Show the business and campaign metrics tied to the decision the dashboard supports.
    • Change layer: Show the active period beside the intended baseline, using clearly stated date ranges.
    • Diagnostic layer: Break the result down by the dimensions most likely to reveal concentration, such as campaign, channel, device, or location.
    • Interpretation layer: Label confirmed observations separately from AI-generated possible explanations.
    • Decision layer: Keep a note alongside the dashboard stating the owner, chosen action, verification performed, and next review point. Do not imply that this note is created automatically unless your account supports it.

    A practical dashboard prompt might read: Create a visual report for the campaigns connected to this decision. Show the current period and comparison period, break the main outcome down by campaign and device, identify the largest change, and separate observed facts from possible causes in the summary.

    Review every generated dashboard against five questions: Are the dates explicit? Is the scope visible? Are metric definitions understood? Does the summary distinguish correlation from explanation? Can the reader tell which decision the report is meant to support?

    Real-time summaries improve speed, not certainty. If a chart and its narrative appear to disagree, trust neither automatically. Check the chart configuration and underlying report before circulating the conclusion.

    Key takeaways for safer AI-assisted reporting

    • Use Ask Advisor to detect changes, form hypotheses, and accelerate report creation; keep campaign approval with a person.
    • Give every prompt a metric, scope, period, baseline, segmentation request, and decision context.
    • Treat homepage summaries and notifications as triage signals rather than completed analysis.
    • Verify important claims in the underlying Ads or Analytics report before changing spend, targeting, bids, or measurement.
    • Design dashboards to separate observed facts, possible causes, and approved actions.
    • Begin with one recurring reporting decision and a repeatable verification checklist before expanding the workflow.

    At your next reporting session, choose one question your team answers repeatedly. Turn it into a structured Ask Advisor prompt, write down the checks required before action, and use that same sequence for several reporting cycles. Expand only when the agent consistently helps you reach a verified decision faster.

    References


  • Google Data Manager Audience Updates: A Practical Playbook

    Google Data Manager Audience Updates: A Practical Playbook

    If you own a Customer Match sync, the dangerous outcome is no longer only a failed request. The Data Manager API can now process valid records while warning about invalid optional fields, and one audience operation can clear an entire list. Those capabilities reduce manual cleanup, but they also expose integrations that reduce every run to a simple green or red status.

    For you, this is an operating-model change as much as an API change. Build observability first, put destructive audience actions behind explicit controls, and only then widen the user-provided data you send. That order gives you evidence and a recovery path before the higher-risk capabilities go live.

    Key takeaways

    • Audience refreshes are simpler but more consequential: RemoveAllAudienceMembers can clear a list in one operation or remove members added before a supplied timestamp. Treat full clearing and cutoff-based clearing as separate modes with separate safeguards.
    • A successful request may still contain data-quality problems: invalid optional fields can produce field-level warnings while valid records continue through ingestion. Your monitoring needs a completed-with-warnings state.
    • Address support has widened for Google Analytics destinations: street address, city, and state or province can accompany previously supported information such as name, postal code, and region. This is not a reason to collect or transmit fields without a defined purpose.
    • User-provided data has a conditional identifier role: it can satisfy identifier requirements for certain multi-source events when other identifiers are unavailable. Do not generalize that fallback to every event type.
    • AI-assisted implementation has official scaffolding: Google has added Data Manager API agent skills to its Google Skills GitHub repository, but generated code still needs human review around audience selection, timestamps, privacy, and warning handling.

    Make audience replacement a controlled operation

    A technician monitors two audience-data containers connected by a guarded transfer system with a separate rollback reservoir.

    The RemoveAllAudienceMembers method supports both complete clearing and timestamp-based removal. Do not expose those behaviors through one vaguely named refresh command. Give each mode an explicit name in your own integration so an operator, scheduler, or AI coding agent cannot confuse them.

    Internal operationUse it whenRequired safeguard
    Full clearYou intend to rebuild every current membership from an authoritative dataset.Validate the exact audience target and retain the input, query, or export required to rebuild it.
    Remove before timestampYou intend to retire memberships added before a defined boundary.Record the serialized cutoff and its timezone, then calculate the expected cohort in your own system before making the call.

    A full clear should begin only after the replacement dataset is ready. If extraction fails and returns no rows, an automatic clear-first workflow can turn an upstream outage into an empty audience. Your job must distinguish between a valid business result of no qualifying members and a technical failure that merely produced an empty file.

    1. Build the replacement input first. Finish the source query or export before touching existing membership.
    2. Check whether the result is plausible. Compare its volume and partition coverage with your own recent successful runs. Use a business-specific baseline rather than an arbitrary universal threshold.
    3. Resolve the target from controlled configuration. Record the account, destination, and audience identifier. Avoid accepting an unverified free-text audience name at execution time.
    4. Declare the removal mode. Require either full clear or before timestamp. If a timestamp is supplied, store the exact value used by the request.
    5. Preserve the rebuild path. Retain the source query version, input reference, and run identifier under your normal data-retention controls.
    6. Remove, rebuild, and verify as one runbook. Do not declare the refresh complete merely because the removal call succeeded; the replacement ingestion and its warnings are part of the same operational outcome.

    The cutoff has a narrow meaning: it targets members added before the timestamp. It is not automatically a proxy for last purchase, last site visit, consent expiry, or customer inactivity. If your business rule depends on one of those events, calculate eligibility upstream instead of assuming membership age represents it.

    Boundary behavior deserves a fixture test before production. Place known test members before, at, and after a chosen cutoff, run the operation against a disposable test audience where your environment supports one, and inspect the result. Also verify how your integration treats members that were updated or re-added; do not build a retention policy on an untested timestamp assumption.

    Treat ingestion warnings as a real pipeline outcome

    A validation machine sends most record packets into storage while diverting malformed fragments into an amber inspection channel.

    Field-level warnings change the meaning of success. When an optional field is invalid, the API can continue processing valid records and return details about the field and validation problem. A 2-state dashboard that shows only succeeded or failed will hide exactly the defects this behavior was designed to reveal.

    Represent at least three states in your own monitoring, even if your internal labels differ:

    • Failed: the requested ingestion did not complete successfully.
    • Completed with warnings: processing continued, but one or more fields failed validation.
    • Completed without detected warnings: the run completed and no warning was returned to your handler.

    Persist enough context to diagnose a warning without copying raw customer data into general application logs. A useful warning record contains the internal run identifier, destination, field name, validation reason, occurrence count, deployment version, and first-seen time. If record-level correlation is available in your integration, use a restricted internal reference rather than a name, street address, or complete payload.

    Your alerting should focus on changes in the data contract, not merely the existence of any warning:

    • Escalate a warning reason that appears for the first time after a mapping or formatter release.
    • Investigate a material increase in a known warning relative to that feed’s normal baseline.
    • Route recurring warnings to the team that owns the source field, not only the team that operates the API client.
    • Keep the run visibly degraded until the warning has been classified, even when usable records reached the destination.

    Do not blindly retry the identical batch. An invalid optional value will remain invalid, and valid data may already have been processed. Correct the mapping, normalization, or source value first, then send the corrected data through your normal controlled ingestion path. This makes the next warning result evidence of whether the repair worked.

    Expand address data only where the destination and purpose match

    For Google Analytics destinations, the API now accepts street address, city, and state or province alongside fields such as name, postal code, and region. Keep that destination qualifier in your schema. Support in a Google Analytics path does not establish that every Data Manager destination should receive the same payload.

    • Newly supported for the stated Google Analytics use: street address, city, and state or province.
    • Already supported in the described address data: name, postal code, and region.

    Do not collapse state or province and region into one source column merely because the labels appear related. Define what each field means in your data model, preserve country-specific semantics, and document the transformation applied before transmission. Missing values should remain missing; fabricated placeholders create a payload that may be syntactically complete but semantically false.

    Before adding any address field, require a small data-contract record that answers five questions:

    1. Where did the value come from? Name the source system and field, not just the downstream JSON property.
    2. Which destination may receive it? Use a destination allowlist so the Analytics mapping cannot leak into an unintended advertising or analytics path.
    3. What transformation is applied? Document trimming, formatting, or country mapping in code and tests.
    4. What authorizes its use? Confirm that your collection notice, consent or other applicable control, and internal data policy cover sending the finer-grained address data to the configured destination. If they do not, leave the fields disabled until your privacy or legal owner approves the change.
    5. How will you observe quality without exposing values? Track populated-field counts and validation-warning categories rather than logging raw addresses.

    User-provided data can also satisfy identifier requirements for certain multi-source events when other identifiers are unavailable. The word certain matters. Encode the fallback as an eligibility decision: use the usual identifier path when it is available, use user-provided data only for event and destination combinations that support it, and hold records that satisfy neither condition. Never synthesize an identifier merely to make an event pass validation.

    API acceptance is not a performance guarantee. A field passing validation does not prove that it improved audience size, attribution, or campaign results. Measure those outcomes separately, and keep the expanded payload only when it has a defined operational purpose and remains within your data-governance rules.

    Roll out the changes in a sequence you can reverse

    Do not combine destructive audience controls, new warning behavior, and additional user-provided address fields in one production release. Separate deployments make it possible to identify which change caused a data-quality or audience-maintenance problem.

    1. Inventory each integration path. Mark whether it maintains a Customer Match list, sends data to Google Analytics, or performs both jobs. Record the actual Google Ads, Display & Video 360, or Google Analytics destination rather than assuming all Data Manager paths have identical needs.
    2. Capture warnings on the existing payload. Deploy warning persistence and the completed-with-warnings status before altering deletion or field mappings. This gives you a baseline for current data defects.
    3. Add a guarded removal wrapper. Expose full clear and before timestamp as distinct internal operations. Require a target, mode, recovery input, and explicit cutoff where applicable.
    4. Exercise a fixed test matrix. Test a full clear followed by rebuilding, members before and around a cutoff boundary, a mixed payload containing an invalid optional field, and a warning response that must reach monitoring.
    5. Add address fields by destination. Enable only approved Google Analytics mappings, preferably one mapped field at a time, so warnings can be traced to a specific change.
    6. Test identifier fallback separately. Cover an eligible multi-source event with another identifier, an eligible event without one, and a configuration that is not eligible for the user-provided-data fallback.

    Use Google’s agent skills as scaffolding, not authority

    Google has also released Data Manager API skills in the Google Skills GitHub repository for AI-assisted coding environments. They can help an agent start an integration, but the agent should not decide which audience to clear, choose a business cutoff, approve new address use, or determine whether warnings are acceptable.

    Give the coding agent a narrow implementation brief. For example: create an internal wrapper around RemoveAllAudienceMembers; require an explicit audience identifier and either a full-clear or before-timestamp mode; reject a missing cutoff in the second mode; emit structured warning data without raw user-provided fields; and add fixture tests for clearing, rebuilding, cutoff boundaries, and partial-warning ingestion. Then review the generated client types, request construction, authentication handling, and tests against the API materials and dependency versions actually installed in your environment.

    Set production acceptance criteria

    • A scheduled full clear cannot run unless its replacement dataset and rebuild job are ready.
    • Every cutoff-based operation records the exact timestamp and timezone used by your integration.
    • Completed-with-warnings runs are visible in dashboards and alert routing.
    • Ordinary logs exclude raw names, addresses, and complete user-provided-data payloads.
    • Destination controls prevent expanded address fields from entering an unapproved path.
    • The recovery runbook has been exercised against a controlled audience fixture, not merely written down.

    Start by capturing warnings from the payload you already send. Once that signal is reliable, introduce timestamp-based cleanup behind an explicit approval path, then prove the full-clear rebuild process with controlled data. Expand Analytics address mappings last. You will gain the automation benefits without making a destructive audience action or a sensitive-data change your first live test.

    References


  • Google Marketing Intelligence: Automate Without Losing Control

    Google Marketing Intelligence: Automate Without Losing Control

    You have campaign data in Google Analytics, expanding automation in Google Ads, and more landing pages than anyone can inspect every morning. The problem is no longer a lack of information. It is knowing which information should change a campaign, which decisions the system may make, and where a person must remain accountable.

    The right goal is not maximum automation. It is a closed operating loop: trustworthy measurement informs a clear campaign brief, automation acts inside defined boundaries, and the results lead to a specific next decision. Build that loop first and Google marketing intelligence becomes useful rather than merely impressive.

    Make the data trustworthy before you automate the decision

    An analyst inspects several data streams as they pass through transparent filters that remove duplicates, repair gaps, and align the cleaned signals.

    Marketing intelligence is evidence that changes an action. A dashboard can contain hundreds of metrics without providing intelligence if nobody can explain what decision each metric supports.

    Use this five-part loop for every automated campaign:

    1. State the decision. Be precise: expand demand coverage, revise positioning, restrict landing pages, or hold spend.
    2. Name the outcome. Identify the business result that would justify that decision.
    3. Verify the signal. Confirm that the required activity reaches the intended Analytics property and report.
    4. Define the permitted action. Specify what automation may change and what must remain fixed.
    5. Set a stop condition. Decide what evidence would trigger a review, restriction, or pause.

    If you cannot complete all five steps, the campaign is not ready for broader automation. You may still run it, but you should not interpret automated activity as informed optimization.

    Use Task Assistant as a configuration audit

    Where it is available, Google Analytics Task Assistant can expose configuration gaps through a guided workflow for account connections, data collection, and reporting. Its recommendations can be marked complete or skipped, which makes it useful as an audit queue.

    Do not confuse completion with correctness. Connecting an account does not prove that the right outcome is being measured. Creating a report does not prove that anyone knows what to do with it. For every Task Assistant item, record the business question it supports. If an item is skipped, record why and what change would cause you to revisit it.

    Before expanding automation, perform this minimum measurement check:

    • Confirm that the intended Analytics property is receiving activity from the campaign journey.
    • Complete the target journey yourself and verify that the expected signal appears in the reporting path you plan to use.
    • Separate the primary business outcome from diagnostic interactions. A page view or form start can help diagnose friction, but it is not automatically equal to a completed purchase or qualified enquiry.
    • Confirm that the people reviewing the campaign use the same definition of success.
    • Assign an owner to investigate missing, duplicated, or implausible data.

    Create a one-page measurement contract

    A measurement contract is a short record of how evidence becomes action. It should fit on one page and contain these fields:

    • Decision: What are we deciding?
    • Primary outcome: Which result makes the decision worthwhile?
    • Diagnostic signals: Which observations help explain the result without replacing it?
    • Permitted action: What may the campaign system change?
    • Stop condition: What would make us constrain or pause it?
    • Owner: Who makes the final call when the evidence is ambiguous?

    For an AI Max campaign, the decision might be whether to broaden coverage for exploratory searches. The primary outcome might be a qualified commercial action. Query themes and selected landing pages would be diagnostics. Irrelevant demand, an incompatible destination, or omitted mandatory language would be stop conditions. That is enough structure to prevent a campaign team from optimizing a proxy simply because it is easy to see.

    Translate strategy into an AI brief the system can use

    Automation cannot infer the parts of your strategy that exist only in a planning deck or a stakeholder’s head. You have to express the campaign’s job, its limits, and its required truths in operational language.

    AI Max introduces an AI Brief powered by Gemini for natural-language guidance, including messaging direction and query priorities before launch. Treat that brief as an input specification, not as a creative wish list.

    A usable automation brief should answer each of these prompts:

    • Campaign job: Capture demand for which offer, from which type of need?
    • Eligible intent: Which problems, categories, or buying situations belong in scope?
    • Out-of-scope intent: Which superficially related searches should not consume attention or budget?
    • Approved positioning: Which concepts or attributes should the audience connect with the brand?
    • Supported claims: What can the landing page actually prove?
    • Prohibited claims: Which wording would be inaccurate, noncompliant, or inconsistent with brand policy?
    • Mandatory language: Which qualifier or disclaimer must remain present?
    • Destination boundary: Which pages are suitable for campaign traffic, and which are not?
    • Success signal: Which measured outcome should guide the decision?
    • Review trigger: What result or system behavior requires human inspection?

    Vague adjectives are weak instructions. If the desired positioning is “premium,” define what supports that position: service model, material, expertise, access, or another verifiable attribute. If the desired association is “sustainable,” separate the brand objective from the factual claims the campaign is allowed to make. Wanting an association does not authorize unsupported environmental language.

    Challenge the brief before launch. Ask whether a conversational query could appear relevant while expressing the wrong intent. Check whether an automatically selected page could contradict the ad’s promise. Test whether mandatory wording survives changes in message or destination. If the answer depends on someone noticing the problem later, you have monitoring, not control.

    Natural-language guidance makes campaign intent easier to communicate, but prose alone should not carry legal or regulatory obligations. Use the platform’s available controls, preserve approved wording, and require compliance or legal review where claims create exposure. Automation does not transfer accountability away from the advertiser.

    Measure the decision, not whatever the dashboard offers

    Campaign teams often ask one metric to answer several different questions. Conversion data can show that an action occurred, but not necessarily why. Brand recall can show recognition, but not whether people attach the intended meaning to the brand. Keep the questions separate.

    A practical evidence ladder has five levels:

    1. Measurement: Did the expected data arrive correctly?
    2. Delivery: Did the campaign reach demand that belongs in scope?
    3. Response: Did people take the expected intermediate or final action?
    4. Business outcome: Was the action commercially meaningful or qualified?
    5. Brand effect: Did the audience connect the brand with the intended idea?

    Do not move up this ladder by assumption. If data collection is unreliable, apparent delivery and response patterns are unstable. If the business outcome is unknown, a rise in response volume does not prove that the automation found better demand.

    Google Ads’ Association metric adds a more specific brand question. Within Brand Lift Studies, advertisers can define a concept, category, or attribute and examine which brands surveyed users connect with it. This is useful when the strategic question is not merely “Do people remember us?” but “Do people understand us in the intended way?”

    The constraint matters: a Brand Lift study can use only three selected metrics. Association therefore competes with other measurement questions rather than becoming a free extra. Choose the three before launch by writing the decision each one could change. If a metric would produce an interesting slide but no different action, it should not take a slot.

    QuestionEvidence to inspectDecision it can support
    Can the optimization signal be trusted?Verified Analytics data path and a completed target journeyRepair measurement or proceed
    Is automation finding appropriate demand?Query and destination patterns considered alongside qualified outcomesExpand, hold, or constrain coverage
    Is the message shaping the intended position?Association with the selected concept, category, or attributeKeep or revise positioning and creative direction
    Is the campaign creating recognition without meaning?Awareness or recall considered separately from AssociationDecide whether the next campaign should build familiarity or clarify positioning

    Keep performance and brand evidence on separate scorecards, then read them together. Improving Association does not prove profitable acquisition. Improving conversion volume does not prove that the intended brand position is taking hold. When one improves and the other does not, you have learned where the campaign is working and where it is not; you have not discovered a reason to redefine the weaker metric.

    Put hard boundaries around queries, copy, pages, and spend

    A marketing operator watches an automated machine work inside transparent guardrails that separate search, creative, landing-page, and budget controls.

    Good automation has broad execution capability and narrow permission. The system can evaluate more opportunities than a person can review manually, but it should operate inside a boundary the campaign owner can state without opening the account.

    AI Max is expanding beyond its Search role into Shopping and consolidated travel campaign workflows. That expansion increases the value of a shared governance model because targeting, messaging, product information, and destinations can no longer be managed as isolated concerns.

    Define these boundaries before enabling or expanding automation:

    • Demand boundary: List the needs and query themes to prioritize, plus adjacent intent that remains out of scope.
    • Message boundary: Record approved attributes, supported claims, prohibited wording, and mandatory text.
    • Destination boundary: Maintain an explicit set of pages suitable for automated selection.
    • Data boundary: State which outcomes are trusted enough to influence decisions and which signals remain diagnostic only.
    • Budget boundary: Decide how much financial exposure is acceptable before a person must review performance. Configure account controls to reflect that decision wherever the campaign type permits.
    • Compliance boundary: Identify claims and destinations that need specialist approval before they can be used.
    • Reversibility boundary: Write the condition that will cause the team to restrict, pause, or roll back the automation.

    Treat every eligible landing page as campaign creative

    Final URL expansion allows AI to select a page it considers more relevant, while text disclaimers can accompany URL automation. The operational consequence is simple: the landing page is no longer just a destination chosen once during setup. Every eligible page can become part of the campaign’s message.

    Audit each eligible page for five things:

    1. The page addresses the intent the campaign is permitted to capture.
    2. The offer and positioning agree with the approved campaign brief.
    3. The target action works and can be measured.
    4. Required qualifiers, disclaimers, and conditions are visible and current.
    5. The page does not contain stale or contradictory claims that would make the ad misleading.

    If a page fails that check, fix it or remove it from the eligible destination scope before turning on URL expansion. Do not rely on the system to understand an internal distinction that the page itself does not express clearly.

    For teams managing SEO, AEO, and GEO alongside paid media, this is also a content-governance issue. Keep the visible page, structured data, product information, and campaign claims consistent. Structured data should describe the same reality a visitor sees; it should not be used to compensate for ambiguous or outdated copy.

    Shopping and travel need the same controls in different places

    For Shopping, AI Max can use Merchant Center data to adapt ads for long-tail and exploratory searches. Product information therefore belongs inside the campaign review, not in a separate feed-management silo. A carefully written AI Brief cannot repair product information that expresses the offer poorly.

    For travel advertisers, consolidation reduces operational fragmentation, but it does not remove the need to govern intent, messaging, destinations, and measurement. Fewer campaign containers should produce a clearer decision process, not fewer checks.

    Review automation at change points rather than waiting for a generic reporting ritual. Inspect it before launch, after a material change to the offer or destination set, when query or page-selection patterns shift, and when new brand evidence becomes available. Wait for a meaningful pattern before drawing a conclusion from performance data, but investigate missing mandatory copy or an unsuitable destination immediately.

    Google campaign automation FAQ

    What is Google marketing intelligence?

    Google marketing intelligence is the decision system connecting Analytics data, campaign behavior, business outcomes, and brand measurement. It is not another name for Google Analytics. Analytics supplies evidence; intelligence defines what that evidence means and what action it authorizes.

    Should you automate a campaign if tracking is imperfect?

    You do not need every possible report to be finished, but the decision-critical measurement path must work. If you cannot verify the primary outcome, do not automate toward a convenient proxy as though it were equivalent. Repair the essential path first, then improve optional reporting around it.

    Can Association replace conversion measurement?

    No. Association addresses whether an audience connects the brand with a chosen concept, category, or attribute. Conversion measurement addresses action. Use Association to evaluate positioning and conversion evidence to evaluate response and business performance.

    How do you know automation has too much control?

    It has too much control when the campaign owner cannot state five things: eligible demand, mandatory and prohibited messaging, eligible destinations, the trusted success signal, and the stop condition. If any of those exists only as an assumption, narrow the automation until the boundary is explicit.

    Start with one active campaign. Write its job in one sentence, trace its primary outcome into Analytics, list the pages automation may select, and define the evidence that would make you expand or constrain it. Once those decisions are visible, automation can accelerate a strategy you understand instead of concealing one you do not.

    References

  • How to Turn Google Analytics Insights Into a Smarter Budget

    How to Turn Google Analytics Insights Into a Smarter Budget

    If you are opening Google Analytics to decide where the next part of your paid-media budget should go, a performance alert is not the answer you need. It is only the start of the decision. The dangerous shortcut is to see a channel move, assume the channel caused it, and transfer money before checking whether the movement came from measurement, timing, demand, or campaign execution.

    Google is shortening the distance between monitoring and planning through generated Home insights, cross-channel budgeting, and a no-code scenario interface for Meridian. You can use that shorter path without surrendering judgment. The workflow below turns a signal into a documented, constrained, and reversible budget decision.

    Key takeaways

    • Use generated insights as a triage queue. They can tell you what deserves attention, but they do not prove why a metric changed.
    • Make paid channels comparable before moving money. Align the outcome definition, cost coverage, reporting window, attribution policy, and conversion maturity.
    • Separate historical efficiency from expected marginal return. The best destination for additional budget is not automatically the channel with the best average result.
    • Use scenarios to expose assumptions and constraints, not to manufacture certainty. A forecast is an estimate that still needs business judgment.
    • Document the hypothesis, approved change, guardrails, and evaluation conditions before changing spend. This prevents a plausible explanation from quietly becoming an untestable decision.

    Give each Google planning feature one clear job

    Google Analytics can place the top three changes since your last visit on the Home page, including notable performance shifts, anomalies, and seasonality patterns. That is a detection layer. Its useful output is not a budget instruction. It is a shorter list of changes worth investigating.

    The cross-channel budgeting capability has a different job. It is intended to connect performance across paid channels with investment decisions, but it remains a beta feature with limited access. Build a process that can use the interface when it is available without making your decision discipline dependent on it.

    Google’s no-code Scenario Planner turns Meridian marketing mix model outputs into budget and ROI forecasts. It lets a marketer test alternative allocations without writing code or relying on a data scientist to operate the interface. It does not remove the need to choose the right outcome, understand the model’s limits, or account for constraints the model may not contain.

    CapabilityDecision jobQuestion it can supportWhat it cannot establish by itself
    Generated Home insightsDetection and prioritizationWhat changed enough to investigate?What caused the change or whether budget should move
    Cross-channel budgetingPaid-channel comparison and allocationHow is paid investment performing across channels?Whether the channel inputs are truly comparable
    Scenario PlannerForward-looking simulationHow might budget and ROI change under another allocation?Whether the forecast will occur or whether omitted business constraints make it impractical

    This separation matters because detection, explanation, and allocation require different evidence. An unusual movement may deserve immediate attention while still being a poor reason for an immediate budget change. A scenario may look attractive while depending on immature conversion data or a channel definition that differs from the rest of the plan.

    Turn a surfaced change into an auditable budget decision

    An unlabeled visual workflow moves from a performance signal through evidence checks and scenario comparison to a documented budget allocation.

    Every budget change should have a visible chain from signal to decision. If someone cannot reconstruct that chain later, you will struggle to tell whether the allocation worked, whether the original explanation was wrong, or whether the market simply changed after approval.

    1. Define the decision before examining allocations. Write down the business outcome, planning horizon, channels in scope, total budget boundary, and any commitments that cannot move. If the business cares about qualified demand, a rise in raw conversion volume is supporting evidence rather than the decision metric.
    2. Capture the signal precisely. Record the metric that moved, its date range, the property and filters in use, the affected channel or campaign, and the comparison that made it notable. Avoid summaries such as paid social is down. They are too vague to validate.
    3. Check measurement before interpreting performance. Look for changes to event definitions, tags, consent behavior, attribution settings, campaign naming, imported costs, and reporting filters. A measurement discontinuity can resemble a sudden gain or loss in channel efficiency.
    4. Classify the most plausible explanation. Useful classes include measurement, seasonality, underlying demand, campaign execution, channel mix, and normal variation. The classification tells you what evidence to inspect next; it is not yet a causal conclusion.
    5. Write a testable hypothesis. State what you think changed, the mechanism connecting it to the outcome, and what observation would weaken the explanation. If nothing could disprove the hypothesis, it is a story rather than a basis for allocating money.
    6. Create a comparable baseline. Align the reporting window, outcome definition, included costs, attribution treatment, and conversion maturity across the channels being considered. Preserve any important differences instead of hiding them inside a blended total.
    7. Model alternatives within real constraints. Keep the current allocation as the baseline, then create a reallocation that respects budget limits, channel commitments, operational capacity, and risk tolerance. Add a more conservative version when the input data or model fit leaves substantial uncertainty.
    8. Approve the smallest change that can answer the decision question. A reversible adjustment limits the cost of a wrong assumption and gives you a cleaner read than changing many channels, audiences, bids, and creative variables at once.
    9. Predefine the readout. Name the primary outcome, diagnostic metrics, guardrails, required conversion maturity, and the conditions for continuing, pausing, or reversing the move. Do this before the result is visible so the success rule cannot drift toward whatever happened.

    The planning interface belongs in the modeling stage, not at the beginning of the chain. Starting with a recommended allocation invites you to reverse-engineer a justification. Starting with a defined decision and validated baseline lets you judge whether the recommendation is relevant at all.

    If Scenario Planner or cross-channel budgeting is not available in your account, keep the same structure in a controlled worksheet or planning document. Tool access changes the speed of the work. It should not change the evidence required to approve spend.

    Make every paid channel earn comparison on the same basis

    A cross-channel screen can place metrics beside each other without making them economically equivalent. Before you rank channels, normalize what can be normalized and label what cannot. Otherwise, the cleanest-looking comparison may reward the channel with the most favorable measurement rules rather than the strongest business contribution.

    Use one decision outcome and consistent cost coverage

    Choose the outcome that the budget decision is meant to improve. Revenue, qualified leads, new customers, and platform conversions are not interchangeable. A channel can generate inexpensive form submissions while producing little qualified demand, so optimizing against the cheapest visible conversion may move money away from the business result you actually need.

    Use supporting metrics to diagnose the result, not replace it. Clicks, sessions, reach, and intermediate actions can help explain why the primary outcome changed. They should not outrank that outcome simply because they arrive sooner or look more favorable.

    Apply the same cost policy across the comparison. Decide whether the analysis includes media spend only or a broader set of in-scope costs, then use that definition consistently. Align currencies and the treatment of credits, taxes, and fees where they affect the data. An incomplete cost import can make a channel appear more efficient without any real improvement.

    Respect conversion timing

    Channels often influence outcomes on different timelines. A channel whose conversions mature slowly can look weak beside one whose outcomes are recorded quickly, especially near the end of the reporting window. Do not make the slower channel defend an incomplete result against the faster channel’s mature result.

    Set the evaluation window from the buying cycle and conversion delay relevant to your business. Mark immature periods as incomplete. If leadership needs an earlier read, present leading indicators as provisional evidence and say what remains unknown rather than treating them as final ROI.

    Plan around marginal return, not the historical average

    Average efficiency answers what the channel produced across the spend it already received. Budget planning asks a different question: what is the next portion of spend expected to produce? That distinction is where many reallocations go wrong.

    A historically efficient channel may have limited room to absorb additional budget at the same return. A channel with a weaker average may still have useful incremental capacity. Neither conclusion should be assumed from the averages alone. Use the scenario output, current delivery constraints, and recent evidence to judge the expected effect of the proposed change.

    A practical budget structure separates committed investment, protected learning investment, and reallocatable investment. Committed spend covers obligations or strategic coverage you have decided not to disturb. Protected learning spend preserves experiments that would otherwise be cut before producing useful evidence. Reallocatable spend is the portion the scenario can genuinely move. This prevents a mathematically neat plan from recommending a transfer that the business cannot or should not execute.

    Let attribution and marketing mix modeling answer different questions

    Attribution assigns credit among observed touchpoints under a defined rule or model. Marketing mix modeling estimates relationships between investment and aggregate outcomes across time. Their outputs can differ because the methods, data, and questions differ.

    Do not force the two views to agree before you can make a decision. Use disagreement as an investigation trigger. Check channel definitions, missing costs, promotional periods, conversion lag, offline effects, and the outcome each method is measuring. Then document which view is carrying more weight for this decision and why.

    Put guardrails around AI-assisted budget recommendations

    A human hand reviews glowing budget recommendations that pass through locks, balances, and other safeguards before reaching paid-channel containers.

    Generated explanations and accessible forecasts can make a budget recommendation feel more complete than its evidence warrants. The remedy is not to ignore the tools. It is to require a few checks before the recommendation becomes an instruction.

    • Alert is not explanation. Confirm that the movement is real, material to the decision, and not created by a reporting change.
    • Correlation is not a causal mechanism. Write the proposed explanation and identify evidence that could contradict it.
    • Forecast is not commitment. Treat predicted ROI as conditional on the model, inputs, assumptions, and scenario design.
    • No-code is not assumption-free. Someone still has to define the outcome, constraints, planning period, and acceptable risk.
    • Cross-channel visibility is not complete business visibility. Add margin, capacity, inventory, contractual, brand, or geographic constraints when they matter and are not represented in the analytics view.
    • Optimization is not permission to remove learning. Preserve strategically useful experiments when their evidence has not had time to mature.
    • Beta access is not an operational control. Keep the decision record outside the feature so your process survives access, interface, or availability changes.

    Use a decision record that survives the meeting

    Keep each allocation decision in a short, consistent record. Include the decision question, surfaced signal, validated evidence, rejected explanations, remaining uncertainty, baseline allocation, proposed change, scenario assumptions, business constraints, expected outcome, guardrails, effective period, evaluation conditions, owner, and next review point.

    The record should make the status explicit: hold the allocation, investigate the signal, model alternatives, or implement a change. A review that ends with general agreement but no named status leaves the team vulnerable to accidental changes and conflicting interpretations.

    At the next review, compare the observed result with the expectation and examine the mechanism, not just the final total. A favorable outcome does not automatically validate the original explanation, and an unfavorable outcome does not automatically prove the channel is ineffective. Demand, measurement, and execution may have changed while the budget test was running.

    On your next visit to Google Analytics, take the most decision-relevant surfaced change and run it through the chain before touching spend: validate the measurement, define the hypothesis, create a comparable baseline, model a constrained alternative, and set the reversal conditions. That turns faster analytics into a better decision rather than merely a faster reaction.

    References