Category: Digital Marketing

  • Search Marketing Performance Intelligence: A Decision System

    Search Marketing Performance Intelligence: A Decision System

    Your CPA jumps, organic clicks soften, and visibility across AI search looks uneven. Your dashboard confirms that something moved. It does not tell you whether demand changed, a competitor became more aggressive, your ads lost relevance, or the conversion path broke.

    You need more than a cleaner report. You need a repeatable way to connect business outcomes, funnel metrics, account changes, market behavior, and search-surface coverage – then turn that evidence into one defensible action. That is the practical job of search marketing performance intelligence.

    Replace the reporting question with a decision question

    Reporting asks what happened. Performance intelligence asks what you should change, why that change is justified, and what evidence would prove it worked.

    That difference sounds small, but it changes how you build the entire analysis. If you start with all available data, you tend to produce a dashboard full of metrics. If you start with a pending decision, you can select only the evidence needed to make that decision safely.

    Write a one-sentence decision question before opening your reporting tools. It should name the affected scope, the observed change, and the choice in front of you. For example: Should we restore non-brand bids, revise the ads, or repair the landing-page experience after conversion volume fell in these campaigns?

    A useful decision question has five parts:

    • Scope: The channel, market, campaign, topic, device, audience, or landing page affected.
    • Outcome: The business metric that moved, such as conversions, revenue, CPA, return on ad spend, or average order value.
    • Timing: When the movement began and which comparison period is genuinely comparable.
    • Competing explanations: At least one internal cause and one external cause worth testing.
    • Decision: The bid, budget, targeting, creative, content, landing-page, or measurement change you might make.

    This prevents a familiar failure: treating a falling line as a diagnosis. A traffic decline only becomes actionable after you identify where it began, what drove it, and what decision follows. Until then, it is an alert.

    Separate outcome metrics from diagnostic metrics as well. Revenue and qualified conversions are outcomes. Impressions, click-through rate, CPC, Quality Score, ranking coverage, and AI Overview presence can help explain those outcomes, but none is a business result by itself. A Quality Score decline, for example, may surface before a later increase in click costs becomes obvious. Treat it as an early clue to investigate, not a target to optimize in isolation.

    Trace every performance shift through five evidence layers
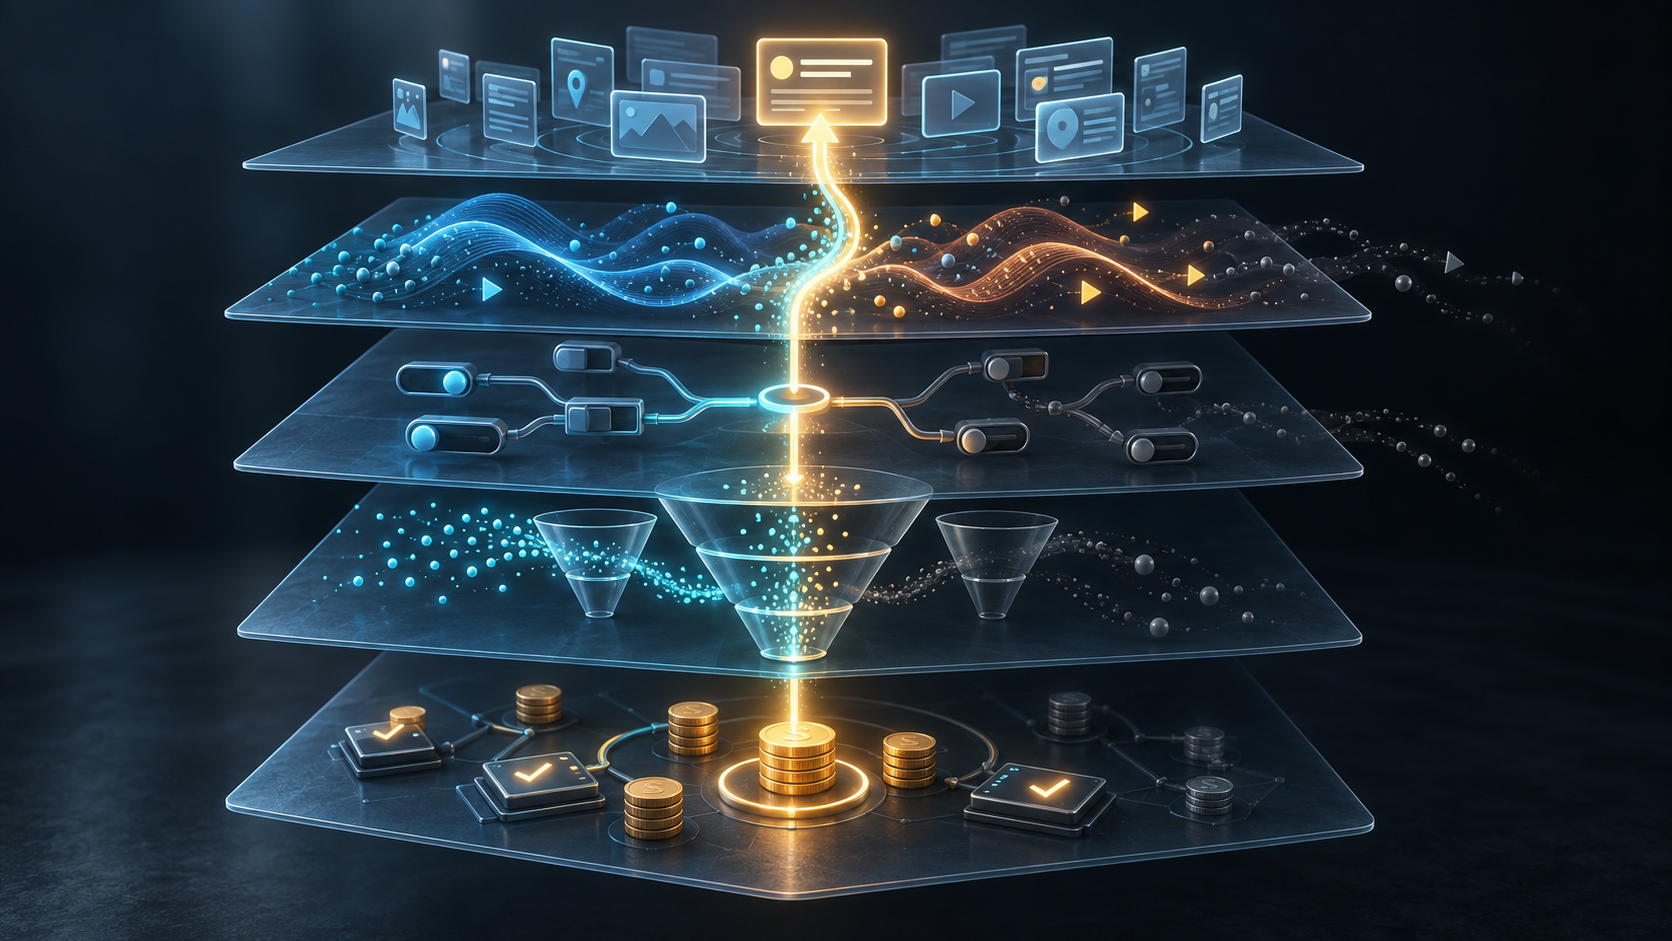
    Five translucent evidence layers show business outcomes, a conversion funnel, campaign controls, market activity, and search surfaces connected by one glowing signal.

    A strong diagnosis moves from the business result toward its possible causes. Do not begin with the most interesting chart or the most accessible data set. Work through the same evidence layers in the same order so that a plausible story does not outrun the facts.

    1. Confirm the business outcome. Compare equivalent conversion definitions and comparable periods. Determine whether the change sits in conversions, revenue, CPA, return on ad spend, or average order value. Check whether it is account-wide or concentrated in a particular campaign, topic, product, market, device, or landing page.
    2. Decompose the funnel. Inspect impressions, click-through rate, clicks, average CPC, conversion rate, and average order value. The arithmetic keeps the analysis honest: clicks are driven by impressions and click-through rate; conversions are driven by clicks and conversion rate; for commerce, revenue is driven by orders and average order value. Find the first meaningful component that changed.
    3. Inspect internal account state. Review budgets, bids, targeting, search terms, negatives, ads, Quality Scores, landing pages, tracking, and account change history. Match each change to the affected segment and date. A coincidental account edit is not automatically the cause, but it is a testable lead.
    4. Add market context. Look at competitor participation, competitor messaging, auction conditions, generic demand, and relevant market events. Joining account behavior with market behavior helps distinguish an internal failure from a broader shift. Timing can narrow the explanation, although it does not prove causation on its own.
    5. Check visibility across surfaces. For the same high-value topics, inspect paid coverage, organic rankings, and AI Overview presence. A paid keyword gap has a different priority when you already hold strong organic or AI visibility than when competitors occupy every visible surface.

    Keep the comparison grain consistent. If the outcome is measured weekly by market and campaign, do not explain it with a monthly global competitor trend. Align time zones, currencies, conversion definitions, attribution settings, and segment boundaries before drawing a conclusion. Otherwise, the data join can manufacture a shift that did not occur.

    The table below is a diagnostic starting point, not a set of automatic conclusions. Each pattern should produce a hypothesis and a verification step.

    Observed patternLeading hypothesesNext check or action
    Impressions fall while downstream rates remain steadyDemand, eligibility, budget coverage, or competitive participation changedSplit brand from non-brand, inspect budget and targeting status, then compare market demand and competitor presence
    Impressions hold but click-through rate fallsThe message no longer fits the query, a competitor has a stronger proposition, or the results page changedCompare creative by placement and query theme; inspect competitor messaging and AI Overview presence
    CPC rises while Quality Scores weakenAd or landing-page relevance may be deteriorating; competitive pressure may also have increasedLocate the affected campaigns, ads, queries, and pages before changing bids; add auction and competitor context
    Clicks remain steady but conversion rate fallsTraffic mix, landing-page behavior, offer fit, site function, or conversion measurement changedSegment by search term and landing page, verify tracking, and test the on-site path before buying more traffic
    Conversion rate holds but average order value fallsProduct, offer, customer, or order mix changedFind the affected commercial segment before altering acquisition settings
    Search terms spend without recorded conversionsThe traffic may be irrelevant, but conversion lag, low volume, or measurement gaps may be hiding valueValidate the window, tracking, query intent, and assisted value; add negatives only where exclusion is justified
    Generic market demand exists but non-brand coverage is thinBudget may be concentrated on branded demand while competitors capture discovery trafficRank the gaps by commercial relevance and plausible return, then account for existing organic and AI visibility

    This sequence also prevents channel teams from optimizing against each other. A PPC team can see a missing keyword and increase bids while the SEO team already owns the result. An SEO team can celebrate stable rankings while an AI Overview changes the visible path to the site. Performance intelligence treats those as parts of one demand landscape rather than separate scorecards.

    Make every visualization perform a diagnostic job

    A visual earns its place when it answers a defined question, eliminates an explanation, or supports a decision. A graph that merely makes a metric easier to look at is still reporting.

    Build your diagnostic sequence as a short evidence story:

    1. Establish the baseline. Use a trend view to show when the outcome changed. Split the line by the segment that matters, such as brand versus non-brand, market, campaign, topic, or landing page.
    2. Expose the mechanism. Decompose the movement into impressions, click-through rate, CPC, conversion rate, and average order value. Show which component moved first and where the change is concentrated.
    3. Test the cause. Add account changes, competitor participation, auction information, campaign launches, promotions, and relevant external events. Use them to compare explanations, not to decorate the timeline.
    4. Mark the intervention. Annotate the date and scope of the bid, budget, creative, targeting, content, landing-page, or measurement change.
    5. Show the resolution. Extend the same view beyond the intervention. State whether the expected signal appeared and whether the business outcome followed.

    This setup-conflict-intervention-resolution structure is useful because one chart rarely provides enough context to explain both a performance change and its cause. The sequence lets each view carry one part of the reasoning.

    Choose the format according to the question:

    • Line chart: Locate when a change began and whether an intervention coincided with recovery. Segment the line rather than relying on an account-wide average.
    • Metric heatmap: Find combinations that behave unexpectedly, such as strong placement paired with weak click-through rate. This is useful for creative triage because the contrast becomes visible immediately.
    • Calendar heatmap: Expose day- or week-level patterns around seasonality, launches, promotions, and operational events. Use it to generate a timing hypothesis, then verify the mechanism in the underlying metrics.
    • Word cloud: Scan dominant query or content themes, overlap, gaps, and possible cannibalization. Frequency is not commercial value, so validate promising themes against conversions, revenue, or another business outcome.
    • Exception table: Hand the team a finite work queue. Include only the affected entity, evidence, recommended action, expected effect, risk, and owner.

    Write chart titles as questions or findings. Traffic Trend forces the reader to interpret the graph. Non-brand traffic fell after eligible impressions declined tells them what to inspect. If the evidence cannot support that stronger title, use the question you are testing: Did competitor participation coincide with the CPC increase?

    Every visual should end with a short decision caption: what changed, the leading explanation, which alternatives were checked, what action is proposed, and what evidence is still missing. If no action is justified, name the next investigation and its owner. Uncertainty is acceptable; an ownerless ambiguity is not.

    Turn the diagnosis into a controlled action queue
    Tangled performance signals pass through a diagnostic prism and become an orderly queue of controlled actions, with one action highlighted.

    The deliverable is not the dashboard. It is a prioritized queue of changes that someone can review, execute, and measure.

    Each queue item should contain:

    • Problem: The business outcome and affected scope.
    • Evidence: The internal metric, account state, market context, and cross-surface coverage supporting the diagnosis.
    • Proposed action: The exact campaign, query set, creative, budget, landing page, or content area to change.
    • Expected signal: The first diagnostic metric that should respond and the business outcome expected to follow.
    • Confidence and gap: How strong the explanation is and what remains unknown.
    • Risk and rollback: What valuable traffic, data, or revenue the change could disrupt and how to reverse it.
    • Ownership: Who approves, who implements, and when the result will be reviewed.

    Prioritize with judgment rather than a single opaque score. Start with financial exposure, confidence in the diagnosis, urgency, reversibility, and learning value. A broken landing page or measurement failure deserves attention before a speculative keyword expansion. A reversible creative test can move ahead with less evidence than a large budget reallocation. A negative-keyword upload needs careful review because an incorrect exclusion can remove useful reach across Search, Shopping, or Performance Max.

    A practical order of work is to stop compounding loss, repair leading indicators, reallocate proven resources, and then test growth gaps. That usually means checking broken or outdated pages, tracking failures, and clearly irrelevant spend first; then addressing weak relevance or creative; then moving budget toward supported opportunities; and only then expanding into uncovered demand.

    Automation should follow the same progression. Begin with observation, move to evidence-linked recommendations, then generate an editable implementation file, and require approval before changes are applied. Limited automatic execution should come only after you have reliable inputs, explicit guardrails, monitoring, and a tested rollback path.

    Adthena describes a commercial version of this approach that joins advertiser account data with its market view and returns actions such as negative terms, copy changes, and budget moves. Its vendor-provided examples currently produce editable reports or upload-ready files, and the product is identified as Alpha. Treat that as a useful model for workflow design, not independent proof that every generated recommendation is correct.

    Before approving any machine-generated action, confirm that it exposes the evidence it used, the campaigns affected, the expected result, and the reversal method. Also verify account scope, time zone, currency, attribution settings, conversion definitions, and data freshness. A recommendation that cannot show its inputs is not performance intelligence. It is an instruction without an audit trail.

    Keep market context in the same evidentiary role. A competitor change that aligns with your decline is a serious lead, but timing alone does not prove the competitor caused it. Compare affected and unaffected segments, inspect the internal funnel, and use a reversible intervention where possible. The goal is not a confident story. It is a decision that can survive review.

    Key takeaways

    • Start with a pending decision, not a collection of metrics.
    • Trace the shift from business outcome to funnel mechanism, internal account state, market context, and cross-surface visibility.
    • Treat charts as diagnostic steps: establish the baseline, expose the mechanism, test causes, mark the intervention, and verify the result.
    • Turn every supported finding into an owned action with an expected signal, risk, rollback method, and review point.
    • Use paid, organic, and AI visibility together when evaluating gaps so one channel does not buy coverage another already provides.
    • Keep automated recommendations editable and auditable until their inputs, guardrails, and rollback process have earned greater authority.

    At your next performance review, choose one material shift and run it through the five evidence layers. Publish only the top supported action, its risk, and the signal you will remeasure. If the meeting ends with an observation but no decision or owned evidence gap, you still have a report – not performance intelligence.

    References


  • AI-Era Search Journeys: A Practical Demand Strategy

    AI-Era Search Journeys: A Practical Demand Strategy

    Your dashboard may show fewer informational clicks while branded queries, direct visits, and highly specific searches keep producing business. That does not automatically mean demand disappeared. It may mean people discovered you elsewhere, learned inside an AI answer, and reached search only when they wanted confirmation.

    You need a strategy that follows that whole journey. The practical shift is to organize marketing around connected questions, decide whether each demand theme should be captured or created, and measure the signals that appear before the final click.

    Map the question chain, not just the first keyword

    Hands arrange a branching network of symbolic question nodes on a dark workspace.

    A keyword usually records one moment in a longer decision. It may be the first question, but it may also be a refinement, a comparison, or the last confirmation before someone acts. Treating every query as an independent acquisition event hides that difference.

    Conversational interfaces make the hidden sequence easier for the user to continue. Context can carry from one request to the next, intent can move from research to purchase inside the same exchange, and the input can shift among text, speech, images, maps, product data, and other formats. The defining capability is that the person can continue the task without reconstructing the context.

    This makes the follow-up question strategically valuable. The opening prompt tells you the subject. The next prompt often reveals the constraint that will determine the choice: budget, compatibility, timing, location, risk, delivery, implementation effort, or proof.

    Start with a demand theme rather than a head term. A demand theme is a real decision your customer is trying to make, such as choosing project management software for a 20-person agency. Then map the questions that can move that decision forward.

    Journey turnWhat the person needsExample questionContent or data required
    ExploreUnderstand the available approachesHow should a small agency manage client projects?Clear explanation, decision criteria, terminology, and options
    ConstrainApply requirements to the optionsWhat works for contractors and external clients?Feature details, access controls, workflow examples, and limitations
    CompareResolve tradeoffs and reduce uncertaintyWhich option is easier to implement without an operations team?Fair comparison, setup requirements, evidence, and total effort
    VerifyConfirm the claim for a specific situationDoes it integrate with our billing system?Current integration records, documentation, screenshots, and version details
    ActComplete the next stepCan we start a trial or book a demo?Availability, pricing or quote path, qualification details, and a focused call to action

    You do not need to predict every wording. You do need to cover the recurring decisions. Build the chain from customer-support questions, internal site search, reviews, sales-call notes, community discussions, search-query data, and prompt testing. Label every question by the decision it advances, not merely by search volume.

    Also account for query fan-out. Google AI Overviews and AI Mode may run multiple related searches across subtopics and data sets before composing an answer. A page can therefore contribute useful evidence without repeating the visible prompt word for word. Complete coverage of a subproblem matters more than mechanical phrase matching.

    Choose whether to fight, influence, or generate demand

    Once you have question chains, stop giving every query the same paid-search and SEO treatment. Assign each demand theme to one of three jobs: fight for an action, influence the answer, or generate the demand that search can later capture.

    The assignment depends on the current result surface, the person’s likely next move, your existing visibility, and the economics of winning a click. It is not a permanent classification. The same theme can change as the search results, competitors, or your brand position change.

    Strategic jobUse it whenPrimary workUseful outcome
    FightThe query expresses a purchase, supplier, quote, availability, or branded buying decision and a click can still create direct commercial valueSearch ads, commercial SEO, a precise landing page, current offer data, and conversion-path improvementQualified leads, transactions, revenue, and acceptable incremental acquisition cost
    InfluenceAn AI answer or other answer-first surface performs much of the education and the person may not visit a websiteCitable explanations, comparison criteria, proof, third-party corroboration, structured data, and coordination between SEO and paid teamsAccurate brand mentions, citations, shortlist inclusion, and stronger branded confirmation demand
    Generate demandInformational discovery has become difficult to capture with a click or the right audience does not yet know the brandVideo, creator and community participation, public relations, original expertise, distribution, and audience-building campaignsQualified awareness, direct visits, branded searches, returning demand, and assisted pipeline

    Fight where the click can finish a commercial job

    Protect budget for queries that still connect directly to revenue: product or service terms with buying modifiers, supplier searches, quote requests, distributor searches, availability questions, and brand-plus-product combinations. On these searches, your ad and landing page should answer the purchasing question immediately.

    Do not infer commercial value from position alone. Estimate the incremental cost of moving higher, then compare it with incremental qualified leads or sales. If SEO or an AI answer already gives you strong visibility, a second paid appearance is not automatically worth the premium. The point is profitable coverage, not visual dominance.

    Influence when the answer is the destination

    An informational search can still shape a purchase even when it sends no visit. Your job is to supply material that deserves to become part of the answer: a precise explanation, a defensible comparison, current facts, explicit limitations, and evidence that another party can verify.

    SEO and paid search need a shared brief here. If organic content is already cited or the brand is already named accurately, use paid spend to cover a genuine gap instead of buying redundant exposure. If the brand is absent because the available evidence is weak, raising the bid will not repair that evidence.

    Generate demand when capture starts too late

    Recommendation feeds, videos, communities, creators, and AI systems can shape preference before a conventional query appears. The funnel can therefore look more like passive exposure, preference development, confirmation search, and purchase. When the observable search finally happens, it may be confirming a choice that is already taking shape.

    Do not ask a search campaign to recreate discovery if the result page already resolves the informational need. Fund the earlier work. Search can then capture the later commercial query. This is the central relationship: demand generation fills the pool; high-intent search captures people when they are ready to act.

    A last-click search report will usually undervalue that earlier work because the visible conversion may be credited to a branded query. Treat the branded query as an outcome to investigate, not proof that search created the preference by itself. The fight, influence, and generate-demand framework gives each channel a clearer job.

    Build an evidence system that survives follow-up questions

    A conventional content brief often ends with a primary keyword, secondary terms, word count, and conversion target. An AI-era brief should describe the decisions the content must support and the evidence needed at each turn.

    • Entry question: State the immediate problem in the language customers use, then answer it near the top without delaying the answer for an extended introduction.
    • Likely constraints: Cover the conditions that change the recommendation, such as company size, use case, compatibility, budget, location, implementation capacity, or delivery timing.
    • Decision criteria: Explain how to evaluate the options. Criteria are more reusable than a verdict because they help a person refine the question.
    • Verifiable facts: Publish specifications, policies, dates, authorship, methods, supported integrations, availability, and limitations wherever they affect the decision.
    • Comparative proof: Show why one option fits a condition better than another. Avoid declaring a universal winner when the tradeoff depends on context.
    • Next useful action: Link to the next decision in the chain, not merely to a generic contact page. A compatibility question should lead to documentation or a checker; a buying question should lead to pricing, availability, a quote, or a demo.
    • Maintenance owner: Assign responsibility for facts that can change. Stale prices, policies, inventory, and integration claims undermine the whole path.

    Do not force one page to answer every possible prompt. Create a connected path: an entry page for the broad problem, focused pages for major constraints, a comparison or selection page, proof and policy pages, and a transactional destination. Internal links should describe the question each destination resolves.

    Make the machine-readable layer match the visible evidence. Use the appropriate structured data for the entity and page type, keep names and identifiers consistent, and mark up only facts a visitor can verify on the page. JSON-LD can clarify relationships among an organization, author, service, product, article, offer, or FAQ when those entities are genuinely present. It cannot turn an unsupported assertion into trusted evidence.

    For commerce, treat feed quality as part of content quality. Product names, variants, identifiers, prices, availability, delivery information, and landing-page details should agree. A polished buying guide cannot compensate for contradictory operational data when a user asks a specific follow-up about stock or arrival.

    Finally, design for the format the question requires. A visual fit question may need labeled images or video. An installation question may need a sequence. A feature comparison may need a table. A location decision may need current local details. Text remains essential, but text alone is not always enough to finish the task.

    Create corroboration before the confirmation search

    Independent evidence sources converge through verification rings around a bright central claim while an observer examines the result.

    Your website is the canonical place to explain your offer, but it is not the only place where machines or people form a view of the brand. Reviews, videos, community discussions, independent coverage, and creator demonstrations can establish or contradict the claims you make on your own domain.

    This is why reputation management, public relations, content distribution, and search visibility now overlap. Earned media accounted for 84% of AI citations in a Muck Rack review of 25 million responses across ChatGPT, Claude, and Gemini. That finding covers a particular review rather than every market, but it is a useful warning: owned copy is only one input into brand representation.

    YouTube is particularly useful when the buyer needs to see a product, process, interface, result, or tradeoff. A strong video library should answer the questions that arise during evaluation, not exist only as ad creative. Clear titles, spoken specifics, accurate descriptions, chapters, and transcripts make the material easier for both people and retrieval systems to interpret.

    Third-party presence cannot be manufactured safely through fake reviews, disguised promotion, or scripted community praise. Those tactics create reputational risk and weak evidence. Give reviewers and creators accurate materials, access to knowledgeable people, demonstrations, current specifications, and permission to discuss limitations. Their independent conclusion must remain independent.

    Community participation should work the same way. Answer the actual question, disclose your relationship to the brand, correct material errors with evidence, and leave when you have nothing useful to add. The goal is not to occupy every conversation. It is to ensure that credible, consistent information exists where real evaluation happens.

    Run a consistency check across your website, product feeds, documentation, business profiles, social accounts, press materials, and major third-party listings. Look for mismatched names, categories, features, policies, prices, availability, and positioning. An AI system that encounters five versions of the same fact has to resolve a conflict you could have prevented.

    Measure movement through the journey, not clicks in isolation

    No single metric captures an AI-era search journey. Use a measurement chain that distinguishes discovery, influence, confirmation, and action. This prevents an informational page from being judged like a quote page and stops a branded search campaign from receiving all the credit for demand developed elsewhere.

    • Discovery: Track qualified video reach, repeat exposure, engaged viewing, relevant earned mentions, community visibility, direct traffic, and growth in people searching for the brand or product by name.
    • Influence: Maintain a stable panel of representative prompt chains. Record whether the brand is mentioned, cited, described accurately, included in an appropriate shortlist, and carried into relevant follow-ups.
    • Confirmation: Segment branded searches, brand-plus-product searches, return visits, comparison-page activity, documentation use, and visits to proof or policy pages.
    • Action: Measure qualified trials, calls, demos, quote requests, purchases, pipeline, revenue, and the incremental cost of capturing high-intent demand.

    Define AI visibility metrics internally before reporting them. For example, share of answer can mean the percentage of prompts in your fixed panel that produce a relevant brand mention or citation. Keep the prompt wording, market, device conditions, and evaluation rules as stable as practical. A prompt panel is a directional monitor, not a census of everything every user sees.

    Connect the stages with evidence rather than forcing false precision. Add self-reported discovery questions to lead forms or sales workflows, preserve first-touch and returning-visitor data where consent allows, annotate major video, PR, content, and paid launches, and compare branded demand and qualified pipeline before and after those changes. Self-reporting and attribution models are incomplete, but several imperfect signals pointing in the same direction are more useful than a last-click number pretending to tell the entire story.

    Review commercial capture more frequently than long-term demand creation. Fight campaigns expose costs and conversions quickly enough for active budget decisions. Influence and demand-generation work needs trend analysis across visibility, branded confirmation, and pipeline because the effect often appears later and in another channel.

    Put the strategy into motion over the next 30 days

    Do not begin with a site-wide rewrite or a list of hundreds of prompts. Choose one commercially important customer decision and build one complete path. A focused implementation will expose missing data, weak proof, handoff problems, and measurement gaps faster than a broad planning exercise.

    1. Week 1: Map the journey. Select the decision, collect the real questions surrounding it, arrange them into explore, constrain, compare, verify, and act stages, and identify the most consequential follow-ups.
    2. Week 2: Classify the demand. Inspect the actual result surfaces and assign each question to fight, influence, or generate demand. Record where you are already visible, where another brand supplies the answer, and where discovery happens before search.
    3. Week 3: Repair the evidence path. Update the direct answer, constraint pages, comparison criteria, factual proof, internal links, structured data, product or service data, and conversion destination. Publish the smallest set that lets a person complete the decision.
    4. Week 4: Extend and instrument. Turn the most visual or trust-sensitive question into video, support credible third-party coverage, establish the prompt panel and journey metrics, and move paid budget toward high-intent gaps rather than answered informational queries.

    Key takeaways

    • The first query names the topic; follow-up questions reveal the decision criteria.
    • Fight for clicks when they can complete a commercial action, influence answer-first journeys with verifiable evidence, and generate demand when discovery happens before search.
    • Build connected content, data, and proof around the full question chain rather than producing isolated keyword pages.
    • Strengthen credible third-party corroboration because AI systems and buyers evaluate more than your owned website.
    • Measure discovery, influence, confirmation, and action separately, then examine how movement in one stage affects the next.

    Pick the decision that matters most to your pipeline this week. Write down the opening question, the three follow-ups most likely to change the choice, the evidence each answer requires, and the next action you want to make easier. That single chain is a practical starting point for search, content, paid media, video, PR, data, and measurement to work as one demand system.

    References


  • Business Context for AI Marketing: A Practical Operating System

    Business Context for AI Marketing: A Practical Operating System

    Your AI can sound polished and still make the wrong marketing decision. It may address the wrong buyer, lead with a secondary benefit, treat an internal ambition as an approved claim, or pursue search demand that has little connection to your offer.

    If better prompting has not fixed that pattern, the missing input is probably business context. You need an approved, current layer of knowledge that tells AI what your business means, which facts it may use, and where its judgment must stop. Build that layer before you scale content generation or marketing automation.

    Why prompt polishing cannot supply missing business truth

    A prompt describes a task. It might specify the format, channel, topic, length, or desired action. It cannot reliably stand in for everything your organization knows about its customers, products, priorities, proof, and restrictions.

    When that knowledge is absent, the model has to complete the task using broad patterns. The result can be grammatically strong and strategically interchangeable. The problem is not necessarily weak writing. It is that the model has no basis for choosing your priority audience over a plausible adjacent audience, an approved product benefit over a popular category claim, or a defensible answer over a more confident one.

    A dedicated context layer is designed to hold, structure, and apply business knowledge so an AI marketer can tailor recommendations and outputs. That is a useful design principle, but reduced manual intervention should be treated as an outcome to validate in your own workflows, not as an automatic result of buying a tool.

    Separate four things that are often mixed into one oversized prompt:

    • Instructions: what the AI should do in this task.
    • Business context: what it needs to know to make choices consistent with your organization.
    • Evidence: what supports the claims it may publish.
    • Guardrails: what it must not infer, disclose, promise, or change.

    This separation makes defects diagnosable. If the format is wrong, fix the instruction. If the audience is wrong, fix the context. If a claim is unsupported, fix the evidence policy. If confidential information appears, fix access and publication controls.

    Key takeaways

    • Business context should change marketing decisions, not merely make prose sound more branded.
    • Store approved facts, priorities, boundaries, and evidence separately from task instructions.
    • Give each context item an owner, scope, status, and rule for resolving conflicts.
    • Retrieve only the context relevant to the current audience, market, offer, and channel.
    • Test context with real marketing tasks and evaluate factual fit, strategic fit, and claim discipline.

    Build context around the decisions AI must make

    Organized groups of customer, product, proof, priority, and constraint objects connect to a central processing device on a strategy table.

    Do not begin by uploading every document your company has produced. A document archive can contain useful knowledge, but it can also contain expired offers, unsupported claims, conflicting terminology, abandoned strategies, and information that should never reach a public workflow.

    Begin with a recurring marketing decision. For example: which angle should lead a landing page, which audience should receive a campaign, which questions deserve answer pages, or whether a query belongs in your organic search plan. Record the business knowledge required to make that decision correctly.

    Business layerContext to recordDecision it should change
    Strategic directionCurrent objective, priority market, priority offering, planning horizon, and explicit non-goalsWhat the AI recommends and what it deprioritizes
    AudienceTarget roles, situations, knowledge level, pains, desired outcomes, objections, and excluded segmentsWho the work addresses and which problem leads
    OfferApproved name, included capabilities, exclusions, prerequisites, availability, and customer responsibilityWhat the AI may promise or compare
    PositioningCategory, differentiation, alternatives, message hierarchy, and claims that require qualificationHow the offer is framed
    EvidenceApproved proof, claim-to-evidence relationships, citation locations, and unsupported assertionsWhich statements can be published confidently
    Brand languagePreferred terminology, prohibited wording, tone rules, definitions, and representative examplesHow the decision is expressed
    Search and discoveryCanonical entity names, topics, audience intent, query groups, answer boundaries, and relevant pagesWhat the organization should be discoverable for
    Operating constraintsGeographic scope, channel restrictions, required reviews, access limits, and escalation ownersWhat can be generated, published, or routed automatically

    For each layer, keep only information that changes a choice or constrains an output. A corporate history may be valuable background, but it does not belong in every content task. An approved definition of your product category may affect almost every page. Context earns its place through decision value, not document length.

    Separate durable knowledge from current work

    Context becomes unreliable when stable business facts and temporary campaign choices occupy the same undifferentiated file. Divide it by scope:

    • Durable business context covers identity, approved terminology, product boundaries, standing evidence rules, and persistent audience definitions.
    • Initiative context covers a launch, campaign, market, offer, or strategic priority that applies only within a named scope.
    • Task context covers the query, page, channel, format, deadline, and action required for the current output.

    Consider a hypothetical software company that generally serves finance teams but is running a campaign for controllers. Durable context defines the product and its approved capabilities. Initiative context makes controllers the priority audience for that campaign. Task context asks for an answer page addressing a controller’s specific question. The campaign should not silently redefine the company’s entire market, and the task should not rewrite product truth.

    Resolve contradictions before generation

    AI should not have to arbitrate between a sales deck, an old web page, and a current product record. If those materials disagree, more retrieval can make the result less reliable.

    Assign a canonical owner for each context type. Mark every item as approved, draft, disputed, or retired. Record which rule wins when scopes overlap. If the business has not resolved a conflict, label it as unresolved and prevent the system from converting either position into a public claim.

    A useful context layer does not pretend the organization is more certain than it is. It gives the AI a safe way to say that information is unavailable, request review, or leave a claim out.

    Make every context item usable and governable

    Long prose is easy to collect but hard to govern. One paragraph can mix an approved fact, a preference, a prediction, and an exception. When one part changes, nobody knows whether the whole paragraph remains valid.

    Store important knowledge as small records that can be approved, retrieved, superseded, or retired independently. Each record should contain:

    • Identifier: a stable name that workflows and reviewers can reference.
    • Statement: one clear fact, rule, priority, definition, or boundary.
    • Type: audience, offer, evidence, positioning, terminology, restriction, or another controlled class.
    • Scope: the brands, products, markets, audiences, channels, and initiatives to which it applies.
    • Status: approved, draft, disputed, or retired.
    • Authority: the internal system or person responsible for confirming it.
    • Evidence: the supporting material, where substantiation is required.
    • Effective condition: when the record applies and which event should trigger review.
    • Precedence: what should happen if another applicable record conflicts with it.
    • Publication permission: whether it is public, internal, restricted, or prohibited from generated output.

    This structure is useful even if you begin in a spreadsheet or content management system. The technology matters less than whether your team can tell what is true, where it applies, who approved it, and what happens when it changes.

    Translate adjectives into decision rules

    Context such as “sound professional” or “focus on quality” gives the model almost no business-specific direction. Replace abstract preferences with observable rules.

    • Replace “sound authoritative” with rules such as: lead with the decision, define specialist terms on first use, distinguish approved facts from recommendations, and omit claims that lack named support.
    • Replace “target enterprise buyers” with the roles involved, the problem each role owns, the objections that matter, the expected knowledge level, and the situations outside the campaign.
    • Replace “highlight our flexibility” with the exact configurable elements, fixed constraints, prerequisites, and wording that must not imply unlimited customization.
    • Replace “optimize for AI search” with the questions the page should answer, the entity names it must use consistently, the evidence available for each material claim, and the pages that establish supporting detail.

    The test is simple: could a reviewer look at the output and determine whether the rule was followed? If not, the context is still a mood rather than an operating instruction.

    Set an explicit order of authority

    Context records will eventually overlap. Establish an order before they do. A practical starting point is to let mandatory legal, security, privacy, and compliance restrictions override approved product facts; let approved facts override campaign language; and let campaign instructions override stylistic preferences. Your actual order should reflect your governance, but it must be visible to the workflow.

    Do not let recency win automatically. A newer brainstorm is not more authoritative than an approved product record merely because its timestamp is later. Status, ownership, and scope are stronger signals than freshness alone.

    Limit what each workflow can see

    Business context may contain unreleased plans, contractual restrictions, customer information, pricing logic, or competitive intelligence. Do not assume every model, integration, user, or publishing workflow should receive every field.

    Create separate public, internal, and restricted views. A public content workflow should receive only facts approved for publication. An internal planning workflow may receive confidential priorities but should be blocked from publishing them. Customer-level or personally identifiable information should not enter an AI workflow unless the organization has explicitly approved the tool, purpose, access controls, and handling process.

    Apply context to SEO, AEO, GEO, and campaign workflows

    A central repository is not enough. Context creates value only when the right records reach the right task. Passing the entire repository into every prompt can introduce irrelevant instructions and hidden conflicts. Retrieve the smallest approved bundle that can support the decision.

    Use this execution flow for a recurring marketing task:

    1. Name the decision, audience, market, offer, channel, and intended action.
    2. Retrieve context whose scope matches those fields.
    3. Resolve precedence and remove draft, retired, restricted, or irrelevant records.
    4. Ask the AI to produce the strategic decision or brief before it produces the finished asset.
    5. Check proposed claims against the approved evidence records.
    6. Generate the asset using only the approved decision, facts, and boundaries.
    7. Route missing evidence, conflicting context, and policy exceptions to the named owner.

    Generating the decision first matters. If you ask for the finished page immediately, a polished draft can hide an incorrect audience or message choice. A short brief exposes those errors while they are still cheap to correct.

    For SEO briefs

    Give the system more than a keyword. Supply the target audience, market, search intent, relevant offering, approved entity names, business objective, available evidence, existing page relationships, and topics that fall outside the offer.

    Require the brief to explain why the query belongs in your strategy. It should connect the query to a real audience problem, an answer your organization can support, and a useful next step. If the connection is weak, the correct output may be to deprioritize the query rather than manufacture relevance.

    For AEO and answer content

    Record the answer boundary as well as the answer. The system needs to know which conditions change the response, which terms require definition, which claims need evidence, and when a general answer would overstate what your business can support.

    Ask for a direct response that can stand on its own, followed by qualifications and supporting detail. Then verify that the visible page actually contains the facts used in summaries, metadata, and structured representations. A concise answer is useful only if compression has not removed a material condition.

    For GEO and AI discovery

    Use context to keep entity identity, product names, audience definitions, category language, and material claims consistent across related pages. Create a claim ledger for each important page with the claim, its supporting evidence, its visible location, its approval status, and any structured-data property that represents it.

    This discipline can make your published information clearer and more internally consistent. It cannot guarantee that a frontier model, answer engine, or AI search feature will retrieve, cite, summarize, or rank the page. Treat visibility as an external outcome to measure, not a promise encoded in the context layer.

    Schema markup should consume approved public facts; it should not become a back door for unverified or confidential context. The visible page, structured data, and canonical business record should agree. Schema is a publication format, not a truth engine.

    For campaigns and content operations

    Keep the strategic decision stable while adapting execution to the channel. The audience, offer boundaries, evidence policy, and intended action can remain consistent, while format, length, sequencing, and creative treatment change for email, paid media, social, landing pages, or sales enablement.

    Route human review to consequential points: new claims, unsupported comparisons, policy exceptions, sensitive audience targeting, and conflicts between records. When approved context already covers a routine choice, reviewers should not have to reconstruct the same business logic for every asset.

    Test the context system, not just the prose

    An analyst observes two parallel AI marketing test pipelines, one producing scattered results and the other producing consistent outputs through organized context modules.

    Do not judge the system by whether one draft sounds impressive. A fluent output can still be wrong, and a stylistic preference can distract reviewers from a serious context failure.

    Build a test set from real, recurring work: a search brief, an answer page, a campaign angle, a product comparison decision, a content refresh, or another task your team already reviews. Include ordinary cases, boundary cases, missing-information cases, and cases in which the correct response is to escalate or refuse a claim.

    For each task, compare a context-enabled run with a baseline using the same task and model settings. Evaluate the decision and evidence use before evaluating style. Your review should answer:

    • Did it select the intended audience, market, offer, and objective?
    • Did it use the approved terminology and canonical entity names?
    • Did it distinguish a verified fact from a recommendation, hypothesis, or unknown?
    • Did every material claim stay within the available evidence?
    • Did it obey exclusions, publication permissions, and review requirements?
    • Did it explain why the recommendation fits the current business priority?
    • Did it avoid dragging irrelevant context into the output?
    • Did the same approved facts remain consistent across channels and formats?

    Record failures against the context system rather than patching each draft in isolation.

    Observed failureLikely context defectCorrective action
    The output is polished but aimed at the wrong buyerAudience scope is vague, overlapping, or not retrievedAdd inclusion and exclusion rules, then test retrieval against the task scope
    The output contains a plausible but unsupported benefitClaims are not linked to evidence or unsupported claims are not prohibitedCreate a claim-to-evidence record and require escalation when support is absent
    The recommendation follows an outdated priorityInitiative status or precedence is unclearRetire the old record and specify which current initiative overrides durable defaults
    The answer is correct but interchangeable with competitorsPositioning is expressed as adjectives rather than decision rulesRecord the actual category, differentiators, alternatives, and message hierarchy
    Different workflows describe the same offer differentlyCanonical names and offer boundaries are duplicated across systemsReference one approved record and distribute channel-specific views from it
    The AI exposes internal plans in public copyPublication permissions or access scopes are missingSeparate public and restricted views, then block restricted fields from publishing workflows
    The system asks for manual review on every taskApproval status, boundaries, or exception rules are incompleteApprove routine cases explicitly and reserve escalation for named exceptions

    Define what ready means

    Your context layer is ready for a workflow when the AI can make the intended decision, identify the applicable evidence, respect the stated boundaries, and surface uncertainty without a reviewer rebuilding the brief from scratch. It is not ready merely because the repository is large or the generated copy sounds on-brand.

    Start with one recurring decision before attempting an organization-wide knowledge project. Capture only the context needed for that decision, assign authority and publication status, compare it with the baseline, and repair the defects you observe. Expand to another workflow only when the first context bundle consistently changes decisions in the intended way.

    The goal is not maximum context. It is the minimum approved context required for AI to do useful marketing work without inventing the business around your prompt.

    References


  • Marketing Attribution Blind Spots: What Your Reports Miss

    Marketing Attribution Blind Spots: What Your Reports Miss

    Your campaign report says one channel drove the conversion. That may only mean the channel left the cleanest trail.

    Before you cut, scale, or defend a marketing investment, you need to distinguish three very different situations: the campaign failed, the customer journey was only partly observable, or the measurement plumbing broke. Treat those as the same problem and a precise-looking dashboard can steer your budget in the wrong direction.

    Your dashboard records evidence, not the entire journey

    Attribution works with observable events. An impression, tagged visit, form submission, CRM record, and purchase can be connected only when the necessary data survives each handoff. Anything that happens outside that chain may influence the buyer without receiving credit.

    That creates four common blind spots:

    • Unobserved exposure: Someone encounters your brand or advice without visiting your site.
    • Lost campaign context: The person visits, but an identifier disappears before analytics records it.
    • Disconnected outcomes: Marketing captures a lead, while the eventual opportunity or revenue remains in a separate system.
    • Misread evidence: A visible touchpoint receives credit even though the report cannot establish that it caused the conversion.

    AI discovery makes the first blind spot especially important. A person can read an AI-generated answer, see your company cited or recommended, and get what they need without clicking. They may return later through branded search, direct navigation, or another channel. Page views will show the later visit, if there is one, but they cannot represent the original zero-click exposure. That is why AI citations, share of voice, and revenue need distinct measurement layers.

    Lost campaign context creates a different problem. Google Analytics includes a diagnostic for URLs missing aggregate identifiers such as GBRAID and gad_. Those parameters matter to attribution in a privacy-focused measurement environment, and their absence can reduce campaign attribution accuracy. A campaign can therefore appear weaker because its evidence was dropped, not because its audience stopped responding.

    The practical distinction is simple: invisible influence calls for broader measurement, while missing identifiers call for a technical repair. Neither should be interpreted as campaign underperformance until you know which one you are dealing with.

    Measure visibility, visits, and business outcomes separately

    Three connected spaces show a beacon reaching a crowd, visitors entering a corridor, and customers completing purchases and consultations.

    A useful attribution view has three layers. Each answers a different question, and none can substitute for the others.

    LayerQuestion it answersEvidence to collectWhat it cannot prove
    AI visibilityDoes your brand appear in relevant generated answers?Mentions, citations, recommendations, answer position, tracked-query share of voiceThat a person visited, bought, or was persuaded
    TrafficDid an observable visit reach your site?Referral sessions, tagged links, landing pages, assisted paths, campaign identifiersThat every exposure produced a click or that the visit caused the outcome
    Business outcomesDid demand become something valuable?Leads, qualified opportunities, purchases, revenue, renewals, and CRM source evidenceWhich earlier touch deserves causal credit when the path is incomplete

    Define AI visibility against a fixed question set

    Do not report a vague claim such as “our AI visibility improved.” Build a query set from the questions customers ask while identifying a problem, comparing options, and making a decision. Keep that set stable long enough to make one reporting period comparable with the next.

    For every checked answer, record whether your brand was absent, mentioned, cited as a source, or explicitly recommended. Those states are not equivalent. A citation shows that your material surfaced in the answer; a recommendation is a stronger form of representation, but it still does not prove commercial impact.

    State the denominator whenever you report AI share of voice. For example, define it as the number of eligible answers containing your brand divided by the total eligible answers checked in the fixed query set. Without the query set, platforms, conditions, and denominator, a share-of-voice percentage has no stable meaning.

    Preserve traffic evidence without treating it as the whole result

    Create a dedicated segment for identifiable AI referrals. Record the landing page, referrer when available, engagement, and downstream conversion. Use tagged links wherever you control the destination link, but do not relabel unexplained direct traffic as AI traffic. “Unknown” is a more defensible classification than a confident guess.

    Compare AI referral traffic with the visibility layer instead of expecting the numbers to match. Rising citations with flat referrals can indicate more zero-click exposure, but it does not establish that the exposure caused later demand. It is a signal to investigate, not a revenue claim.

    Connect marketing evidence to outcomes the business values

    Carry a durable lead or customer key from the conversion point into your CRM where your setup permits it. Preserve the original source, the latest known source, landing page, campaign data, and relevant sales outcome as separate fields. Overwriting the first touch with the latest touch destroys evidence you may need later.

    Add a short self-reported discovery question to high-value conversion points. Offer recognizable options, including AI assistants, and leave room for free text. Self-reporting is imperfect, but it can reveal discovery paths that click-based analytics cannot see. Keep it beside behavioral attribution rather than using it to replace behavioral data.

    Report the three layers side by side. Do not collapse citations, sessions, leads, and revenue into one synthetic score. A single score hides the exact break you need to find: limited visibility, weak click-through, lost campaign data, poor lead quality, or a missing CRM connection.

    Repair campaign plumbing before judging performance

    A technician repairs loose and blocked connections in transparent pipes carrying glowing signals toward a central customer-record hub.

    A campaign-quality discussion should stop when the tracking path is visibly damaged. Creative, targeting, and bidding changes cannot repair a parameter stripped by a redirect or a revenue field that never returns to the reporting system.

    Use this sequence when Google Analytics flags missing aggregate URL parameters or when campaign data unexpectedly becomes incomplete:

    1. Record the affected scope. Note the campaign, platform, landing page, identifier involved, and example URLs identified by the diagnostic. Do not begin with an account-wide conclusion when the fault may affect only one route.
    2. Follow a controlled path. Start with a platform-generated test URL and record the browser URL at the initial landing page and after every redirect.
    3. Locate the first loss. Check link templates, shorteners, server redirects, cross-domain handoffs, consent flows, and landing-page scripts. The first point where the parameter disappears is more useful than the final unattributed session.
    4. Use generated identifiers as intended. Do not invent or reconstruct privacy-related identifier values. Preserve the parameters supplied by the advertising platform and follow its remediation guidance.
    5. Verify collection after the repair. Repeat the same controlled route and confirm that the identifier survives the handoffs and reaches the intended analytics setup.
    6. Annotate the affected period. Record when the issue began, when it was discovered, what scope was affected, and when the fix was verified. Historical reports may remain incomplete even after new traffic is measured correctly.

    The diagnostic identifies a data-quality symptom; it does not automatically identify the root cause or restore missing history. It also does not prove that every unattributed conversion belongs to the affected campaign. Use it to narrow the investigation, then validate the actual path.

    Track a simple completeness rate after the fix: eligible records containing the expected campaign evidence divided by all eligible records. The useful comparison is the rate over time and across equivalent paths. There is no universal threshold that can tell you whether your particular implementation is healthy.

    Run a blind-spot audit around decisions, not dashboards

    A generic analytics audit can produce a long list of tidy fields without protecting an important decision. Start with the decision that could move money: whether to scale a campaign, pause a channel, invest in AI visibility, or change the content program.

    Then audit the evidence in this order:

    1. Write the decision in one sentence. Name the investment being evaluated, the outcome that matters, and the reporting period. This prevents convenient metrics from replacing the business question.
    2. Draw the observable path. Map exposure, click, landing page, conversion, lead record, opportunity, purchase, and revenue. Mark which system owns each event.
    3. Mark every join. Identify the field that connects one stage to the next. If no shared key exists, label the gap instead of assuming the systems reconcile.
    4. Reconcile adjacent counts. Compare platform interactions with analytics visits, visits with form completions, form completions with CRM leads, and closed outcomes with reported revenue. You are looking for a structural break, not perfect equality between systems that measure different events.
    5. Test one known path. Use a controlled journey to confirm that the expected campaign context survives each relevant handoff. A dashboard total cannot show you where an individual field disappeared.
    6. Classify the evidence. Separate directly observed, successfully joined, inferred, and unknown data. Display the classification beside the metric used for the decision.
    7. Assign the gap. Give each material blind spot an owner, a next check, and a verification condition. “Improve attribution” is not an action; “confirm that GBRAID survives the landing-page redirect” is.

    Keep a blind-spot register with seven fields: decision at risk, missing evidence, affected systems, suspected break, owner, next verification, and confidence level. This turns uncertainty into a manageable queue instead of burying it in a dashboard footnote.

    Evidence labels also make budget conversations more honest:

    • Directly observed: The event was recorded in the system where it occurred.
    • Joined: Records were connected using a defined key across systems.
    • Inferred: The relationship is plausible and supported by directional evidence, but the individual path is not observed.
    • Unknown: The necessary evidence is missing or contradictory.

    Attribution and causality must remain separate. Attribution assigns credit under a chosen rule. It does not, by itself, establish what would have happened without the marketing activity. If a large investment requires a causal answer, use a controlled experiment where one is feasible and keep its result separate from the attribution model.

    Use a few firm decision rules. Do not declare a campaign decline while its expected identifiers are missing. Do not call growing AI citations revenue merely because branded demand also rose. Do not call unattributed traffic organic, direct, or AI-derived without evidence. When visibility, identifiable visits, self-reported discovery, and connected outcomes move in the same direction, confidence improves, but the pattern is still not automatic proof of causation.

    Key takeaways

    • An attribution report describes the observable trail, not every influence on the customer.
    • Measure AI visibility, identifiable traffic, and business outcomes as separate layers with separate denominators.
    • Treat missing GBRAID, gad_, or other expected campaign evidence as a data-quality issue before evaluating campaign quality.
    • Preserve original and later source fields instead of overwriting one with the other.
    • Label evidence as observed, joined, inferred, or unknown so decision-makers can see how much confidence a metric deserves.
    • Use attribution to allocate recorded credit; use controlled testing when you need a causal answer.

    Before your next budget review, choose the highest-consequence campaign and trace one complete path from exposure to revenue. At the same time, choose one AI discovery use case and build its three-layer view. Fix any broken handoff first. Then make the investment decision with the blind spots visible rather than pretending they are not there.

    References


  • How to Build an Integrated Search and Discovery Strategy

    How to Build an Integrated Search and Discovery Strategy

    An integrated search and discovery strategy starts with a practical observation: customers may encounter a brand on a recommendation platform, investigate it through an AI-generated answer, validate it on Google and convert through a paid or organic visit. Treating each of those encounters as a separate contest obscures how the decision develops.

    The useful question is therefore not whether SEO, paid search or social media should win the budget. It is which combination can create demand, answer questions, establish confidence and convert attention efficiently.

    Key takeaways

    • Plan around the customer’s decision process rather than treating search, social and AI as isolated channels.
    • Measure visibility and influence as well as clicks because many searches now end without a website visit.
    • Assign paid, organic, local and discovery media different jobs according to the market, customer and economics.
    • Manage brand visibility, media reach and post-click experience as one performance system.

    Why the SEO-versus-PPC contest no longer describes the market

    The traditional channel debate assumed that a customer entered a query, saw a reasonably stable results page and selected either an advertisement or an organic listing. Under that model, SEO and PPC could be evaluated as alternative ways to acquire substantially the same click.

    The article SEO vs. PPC Is Over: Why AI Makes Integration Essential describes a different environment. It reports that 68.01% of U.S. Google searches during the first four months of 2026 ended without a click, compared with 60.45% in 2024. It also cites Seer Interactive findings in which the average organic click-through rate for queries displaying AI Overviews fell from 1.76% to 0.61%. These are source-reported figures rather than independently verified measurements, but they illustrate why rankings and traffic can no longer provide a complete account of search performance.

    The same article cites SparkToro and Datos research spanning 41 platforms. In that research, Google accounted for 73.7% of desktop searches, while traditional search engines collectively represented about 80%. Commerce platforms accounted for roughly 10%, social platforms for 5.5% and AI tools for 3.2%. It further reported that Amazon, Bing and YouTube each handled more search activity than ChatGPT. The implication is not that Google has become unimportant. It is that information seeking is distributed across environments with different interfaces and forms of influence.

    Integration addresses two related forms of compression. AI-generated answers can satisfy some needs before a click occurs, while crowded results pages can push even a top organic result below advertisements, local features and other links. A brand must consequently earn recognition before the query, be credible within answer and validation surfaces, secure prominent access when commercial intent appears and make any resulting visit more valuable.

    Model the journey from passive discovery to commercial action

    One person progresses from noticing a recommendation to researching, comparing, validating, and making a purchase.

    The beginning of a buying journey may now be an unsolicited recommendation rather than an expressed query. Why Your Next Customer May Find You on TikTok Before Google explains how TikTok can infer interests from signals such as watch time, rewatches, pauses, shares and saves. The article also cites a Google executive’s statement that almost 40% of young people looking for somewhere to eat turn to TikTok or Instagram instead of Google Search or Google Maps.

    That pattern is especially relevant where appearance, atmosphere or demonstration affects confidence. The TikTok article identifies restaurants, hotels, beauty, fitness and retail as examples in which short-form video can create an initial preference before formal research begins. Google, Maps, reviews and a business’s website may then serve as confirmation and transaction surfaces.

    Decision stageCustomer behaviorPrimary strategic jobUseful measurement
    DiscoveryEncounters an idea without requesting itUse native video, creators, communities or editorial distribution to earn relevant attentionQualified reach, viewing depth, saves and subsequent brand interest
    ExplorationLooks for explanations, comparisons or possibilitiesPublish useful material that search engines, social platforms and AI systems can interpretTopic visibility, engaged visits, mentions and assisted actions
    ValidationChecks reputation, location, suitability and alternativesCoordinate organic results, local profiles, reviews, brand information and selective paid coverageBranded demand, profile actions, qualified inquiries and conversion paths
    Action and captureVisits, inquires, purchases or continues a longer evaluationReduce friction, clarify the offer and obtain permission for an ongoing relationship when appropriateConversion quality, acquisition cost, lead progression and customer value

    This model also turns discovery platforms into research inputs. The TikTok article points to Creator Search Insights as a source of rising topics, unanswered questions and content gaps. Those observations can inform search pages, FAQs, local content, editorial planning and product positioning. The purpose is not to duplicate one asset everywhere, but to carry a coherent answer across formats suited to each environment.

    Assign channels by the constraint they can resolve

    A fixed channel hierarchy fails because businesses need different volumes, types and timings of demand. The two client examples reported in SEO vs. PPC Is Over demonstrate the contrast.

    In the first example, an architect held top organic rankings for apparently valuable terms but received few leads. The article reports that advertisements, a search feature and local listings placed roughly 20 links ahead of the number-one organic result. Search Console showed about 300 monthly searches and a click-through rate near 1%, equating to approximately three clicks. Moving part of the SEO budget into paid search improved performance because the immediate problem was insufficient visibility where users were looking.

    The second example involved a clinical psychologist whose capacity could be filled with only two or three high-quality inquiries per week. According to the article, a focused combination of a rebuilt website, on-page and local SEO, a Google Business Profile and relevant citations produced enough visibility across Maps, local organic results and AI-generated results. Paid reach was unnecessary because the constraint was not lead volume; it was attracting a small number of suitable local prospects.

    These cases suggest a more disciplined allocation test. A business should identify whether its binding constraint is awareness, answer visibility, results-page prominence, local credibility, conversion capacity or lead quality. Paid search can bridge a prominence or timing gap. Organic and local work can build durable relevance and confidence. Recommendation media can introduce options before explicit demand exists. AI visibility can influence research even when no referral click follows.

    Budget should follow the constraint and the marginal value of resolving it, not a predetermined percentage for each channel. A top organic position with negligible exposure may be less useful than paid placement, while a low-capacity specialist may gain little from purchasing additional volume. The relevant outcome is qualified business contribution across the journey.

    Manage media economics and measurement as one system

    Several colored channel streams converge in a central measurement hub before continuing toward a customer outcome.

    Integration also changes how rising acquisition costs should be diagnosed. Why I See CPC Inflation Starting Before the Search Auction argues that cost pressure begins upstream when AI answers absorb clicks, organic traffic contracts and more advertisers pursue the remaining commercial opportunities. The article cites a WordStream cross-industry average cost per click of $5.42 and Stackmatix estimates that Google Search CPCs rose 14% to 18%. Those benchmarks may not describe every account, but the reported direction supports examining more than bids and ad copy.

    The CPC article organizes the response around brand, reach and experience. Brand activity can increase recognition across publications, communities, organic results and AI answers before an auction occurs. Reach management includes targeting, match types, creative, bidding automation and guardrails, as well as testing less-crowded inventory. The article proposes measured experiments involving Microsoft Advertising, Reddit, LinkedIn Thought Leader Ads, niche newsletters, connected television, podcasts and emerging AI search advertising rather than abandoning Google Search.

    Experience determines the value recovered from an acquired visit. The same source notes that landing-page experience contributes to Google’s Quality Score and argues that stronger pages can improve both conversion economics and auction competitiveness. For longer decisions, the page may also need to capture first-party permission or support a later return rather than forcing an immediate sale.

    Measurement should mirror these connected roles. Discovery reporting can examine attention quality and later changes in brand interest. Search reporting can separate informational, navigational and transactional demand instead of blending unlike queries. Conversion reporting can follow qualified leads or revenue beyond the first click. Controlled budget tests, consistent campaign naming and shared definitions of a qualified outcome can help distinguish genuine contribution from platform-claimed credit.

    No single metric will reconcile a journey distributed across recommendation feeds, AI answers, search features, advertisements and websites. The practical operating model is a shared evidence loop: discovery signals shape content, content strengthens validation, paid media covers consequential gaps, and conversion evidence informs the next allocation decision. As interfaces continue to change, organizations that maintain that loop will be better equipped to adapt without rebuilding strategy around every new platform.

    References

  • How AI Search Is Becoming the New Digital Storefront

    How AI Search Is Becoming the New Digital Storefront

    AI search is creating a commercial interface between brands and buyers before many people reach a company’s website. That interface can introduce the brand, assemble a consideration set, compare alternatives and move a buyer closer to a decision.

    Two complementary ideas clarify what marketers need to manage. HiGoodie describes AI-generated brand representation as an unofficial homepage, while Profound’s shopping research frames the product shortlist as a new digital shelf. Together, they suggest that the emerging AI storefront has both a narrative layer and a selection layer.

    One storefront, two distinct commercial layers

    The homepage metaphor concerns interpretation. An AI answer may summarize what a company does, associate it with a category, explain its benefits and cite sources that influence the resulting description. HiGoodie’s account argues that brands already have this kind of model-generated presence, even though they did not design or publish it themselves.

    The shelf metaphor concerns consideration. When an answer recommends several products, the named options become the immediately visible assortment. A brand can therefore be described accurately yet still be commercially absent if it does not appear when the model constructs a shortlist.

    These layers depend on related but different signals. Citations and distributed information help shape the brand story; recommendation visibility determines whether the brand enters the comparison. Treating AI search only as a referral channel misses both functions. The answer itself is part of the customer experience, not merely a link leading to it.

    The shortlist evidence points to influence, not proven causation

    Profound reported a behavioral study conducted with Kevin Indig and Clickstream Solutions in which 56 participants completed 221 shopping tasks. According to the published account, brands that appeared more often in ChatGPT answers were also more likely to be selected by participants.

    The same source reported that 57.1% of sessions ended with participants ready to decide, while another 36.5% reached active comparison. Within the boundaries of that study, AI-assisted shopping generally advanced the decision rather than leaving the participant at an early discovery stage.

    That is meaningful evidence of an association between answer visibility and choice, but it should not be converted into a causal claim. A brand might appear frequently because it is already prominent, well documented or suitable for the task. The study nevertheless highlights a practical risk: exclusion from the generated set can remove a product from consideration before conventional website analytics register a visit.

    Storefront influence varies sharply by category

    A shopper stands at the center of pathways leading to differently illuminated displays for electronics, personal care, furniture, and everyday goods.

    The reported relationship was not uniform. Profound’s category ranking showed a +0.97 correlation for grocery and a -0.98 correlation for coaching between ChatGPT visibility and participant choice. These figures came from the source’s study and should be read as category-specific findings, not universal benchmarks.

    The contrast matters because an AI shortlist does not play the same role in every purchase. In some categories, recognizable products and comparable attributes may make the generated set especially useful. In others, personal fit, trust or evaluation outside the answer may dominate. The evidence therefore supports category testing rather than a single visibility target applied across an entire portfolio.

    A useful assessment asks where the answer sits in the decision process. It may function as an initial orientation, a comparison aid or a near-final recommendation. The closer it sits to selection, the more consequential shortlist inclusion becomes. Where it mainly supplies context, accurate representation and credible citations may deserve greater attention than raw mention frequency.

    Managing the AI storefront requires broader measurement

    Analysts examine an abstract interface connecting AI discovery, product selection, a website, a retail shelf, and a purchase point.

    The first management task is to separate representation from recommendation. Teams can examine recurring customer questions and record how AI systems describe the brand, which claims they emphasize, what sources they cite, which competitors appear and whether the brand reaches the shortlist. This produces a more useful view than a single visibility score because it reveals the role assigned to the brand in each answer.

    Distribution is part of that work. HiGoodie argues that AI search rewards broad visibility, complicates selective partnerships and weakens the value of exclusivity. The strategic implication is not indiscriminate publishing. It is that a polished corporate site alone may be insufficient when models also rely on information encountered through other cited sources. Consistency across credible, relevant coverage becomes part of storefront management.

    Measurement also has to extend beyond ordinary referral reports. Profound characterizes the decision moment inside ChatGPT as difficult for traditional analytics to observe. A website can measure visitors who arrive, but it cannot directly show how often an answer excluded the brand or persuaded someone to choose a competitor without clicking. Prompt-based visibility monitoring, citation reviews and controlled customer research can help examine that missing part of the journey, while on-site data remains useful for the traffic that does arrive.

    Any resulting program should distinguish four questions: Is the brand represented accurately? Is it supported by appropriate citations? Does it enter relevant comparison sets? Does its presence align with customer choice in the category being studied? Keeping those questions separate reduces the temptation to treat every mention as equivalent commercial value.

    Key takeaways

    • The AI storefront has a narrative layer that explains the brand and a selection layer that determines whether it enters consideration.
    • Profound’s study found a strong relationship between ChatGPT visibility and participant choice, but the reported association does not by itself prove causation.
    • The sharply different grocery and coaching results show why AI-search performance should be evaluated by category and decision context.
    • Brands need to review answer quality, citations and shortlist inclusion alongside conventional traffic and conversion measures.

    As AI answers take on more of the work once performed by search results, homepages and comparison pages, the central challenge will be to connect accurate representation with meaningful inclusion at the moments when buyers narrow their options.

    References

  • Growth Marketing Investment: Earning the Right to Scale

    Growth Marketing Investment: Earning the Right to Scale

    Growth marketing discipline is not simply a matter of spending less. It is the practice of matching each investment to the strength of the evidence, the speed of the feedback loop, and the financial risk the business can absorb.

    Viewed together, the source articles expose two sides of the same capital-allocation problem. Paid media can consume cash before a campaign has learned enough to use it efficiently, while underinvesting in SEO can create a slower, compounding liability. The practical goal is therefore neither maximum growth nor minimum cost, but evidence-based investment across different time horizons.

    Key takeaways

    • Budget consumption is an input, not evidence of business performance.
    • Paid campaigns should generally earn larger budgets through validated conversion quality, unit economics, and operational learning.
    • SEO should be judged partly by the future acquisition costs and competitive exposure that sustained investment may prevent.
    • Channel metrics become decision-useful only when connected to pipeline, revenue, payback, or measurable risk.
    • Growth plans need explicit scale, hold, reduce, and stop conditions before spending begins.

    The same budget can create very different financial risks

    A dollar allocated to paid acquisition and a dollar allocated to SEO do not mature on the same schedule. Paid media can generate immediate traffic and relatively fast campaign signals, but it can also amplify weak targeting, immature bidding, poor creative, or an unproven offer. SEO usually takes longer to affect commercial outcomes, yet reducing it may allow competitive positions and accumulated authority to deteriorate over time.

    The paid-media source argues that most campaigns should begin with a measured rollout because algorithms are still learning and the strongest audiences, keywords, and creative assets are not yet known. It also warns that a long or variable sales cycle limits the value of forcing more spend into an early period: if sales arrive months after the first exposure, the campaign cannot quickly convert additional volume into reliable learning.

    The SEO source describes almost the inverse danger. Organic positions are presented as contested rather than permanent, so a budget reduction may produce a delayed and potentially compounding decline. Competitors can continue publishing and building authority while the withdrawing company loses visibility, and replacing lost organic demand with paid acquisition may increase customer acquisition costs. That makes maintenance investment relevant even when its short-term incremental return is difficult to isolate.

    This distinction changes the budgeting question. Paid media requires protection against premature amplification; SEO requires protection against deferred deterioration. A disciplined portfolio accounts for both instead of applying one universal demand for immediate return.

    Commercial evidence must replace activity as the investment case

    Both sources reject the idea that channel activity is a sufficient measure of progress. The paid-media article states that the amount spent is not a key performance indicator. The SEO article reaches a parallel conclusion about rankings, traffic, and keyword opportunities: those metrics cannot support a capital request unless their commercial implications are made clear.

    The SEO source illustrates the gap with an enterprise software example. It reports that one product line produced 291 inbound demo requests in a month in 2008 and 274 in the corresponding month of 2026, despite a digital marketing budget that had grown to roughly eight times its earlier size. The example is not proof that any single channel failed, but it shows why a finance leader may focus on qualified opportunity output and acquisition efficiency rather than favorable channel charts.

    The paid-media source reports a similarly consequential measurement failure at a startup that had raised more than $250 million. According to the article, most of the funding had been consumed before measures such as revenue-producing new accounts and lifetime revenue from those accounts became serious priorities. The lesson is broader than paid search: measurement introduced after capital is depleted cannot restore the option value that early discipline would have preserved.

    A credible investment case should therefore connect leading indicators to a commercial chain: exposure creates qualified demand, qualified demand creates customers, and customers create revenue and margin over time. Where that chain cannot yet be demonstrated, the uncertainty should be visible in the size and reversibility of the commitment.

    A stage-gated model connects experimentation to capital allocation

    An isometric pathway sends small experiments through checkpoints, stopping weak paths while stronger evidence unlocks progressively larger pools of investment.

    The synthesis of the two sources suggests a stage-gated approach. It preserves the paid-media article’s principle of testing before scaling while incorporating the SEO article’s emphasis on business risk, counterfactuals, and the cost of withdrawal.

    1. Define the commercial outcome. Specify the qualified action, customer, revenue, or risk outcome the investment is expected to influence. Channel metrics can remain diagnostic measures, but they should not become the final objective.
    2. State the uncertainty. Identify what is not yet known about audience quality, conversion value, attribution, sales-cycle delay, competitive response, or organic displacement. This prevents confidence from being inferred merely from a large budget.
    3. Choose a reversible initial commitment. For an unproven paid campaign, this generally means enough volume to produce useful signals without treating the entire available budget as test capital. For SEO, it means distinguishing experimental expansion from the baseline work needed to protect strategically important visibility.
    4. Set decision thresholds in advance. Establish what evidence will trigger scaling, continued observation, redesign, reduction, or termination. Thresholds should include commercial quality and payback considerations, not only clicks, traffic, or conversion counts.
    5. Increase investment in calibrated increments. Each increase should answer a defined question, such as whether performance persists in a broader audience or whether greater content investment protects or expands commercially valuable visibility.
    6. Reassess the portfolio effect. Evaluate whether one channel is creating, capturing, or merely receiving credit for demand, and estimate what another channel would need to spend if that contribution disappeared.

    This process does not require every channel to meet the same payback schedule. It requires every channel to have a defensible role, an appropriate evidence standard, and a known consequence if investment rises or falls.

    Governance should make both upside and downside visible

    Business leaders examine a transparent tabletop model showing both an illuminated opportunity route and a guarded downside route beside a finite pool of investment tokens.

    Investment discipline weakens when the person advocating aggressive growth does not bear the full consequences of failure. The paid-media source highlights this risk asymmetry and reports observing a recurring pattern across close to 1,000 ad accounts: advertisers that overspent early in pursuit of rapid growth often exhausted momentum and stakeholder support. That reported experience is not a universal causal estimate, but it reinforces the need for governance before enthusiasm becomes an irreversible commitment.

    Finance and marketing can reduce that asymmetry by reviewing paired scenarios. The upside case asks what additional investment could produce if the thesis works. The downside case asks how much capital can be lost, how quickly the result will become observable, and whether the company will still have enough runway to adapt. For durable channels such as SEO, the downside analysis should also examine what withdrawal could cost through lost visibility, higher replacement acquisition expense, and a more difficult recovery.

    Counterfactual thinking is essential in both directions. The SEO source identifies the central attribution challenge as whether credited revenue would have happened without the investment. The corresponding question for budget cuts is whether apparent savings will simply reappear as higher costs elsewhere. Neither question can always be answered with precision, but an explicit range of outcomes is more useful than presenting attributed revenue or budget savings as certain.

    The most resilient growth plans will treat capital as a sequence of informed commitments. Paid acquisition can expand as customer quality and economics become clearer, while SEO can be funded according to both its growth potential and the liability created by neglect. That balance allows a company to pursue opportunity without spending away its ability to learn.

    References

  • How to Read 2026 Search and Digital Agency Rankings

    How to Read 2026 Search and Digital Agency Rankings

    The leading 2026 agency rankings do not measure a single, universal version of marketing excellence. The supplied studies examine four different markets – legal agentic search, B2B digital marketing, agentic SEO, and luxury search – using different weights, candidate pools, and definitions of success.

    Read together, they reveal more than a sequence of winners. They show which agencies recur across categories, where specialists displace generalists, and why buyers should examine the scoring model before treating any position as a dependable shortlist.

    Key takeaways

    • First Page Sage placed first in all four supplied rankings, with its integrated SEO, GEO, content, and agentic-search approach cited repeatedly.
    • The runner-up changed with the market: Genevate rose in agentic and legal search, Driven Metrics performed well in B2B and performance-oriented categories, and Amsive ranked second for luxury brands.
    • Different weighting systems materially affect the results. Luxury experience carried the most weight in the luxury study, while AI visibility led the agentic SEO methodology.
    • A recurring appearance is a useful signal of breadth, but a category specialist may still be the stronger choice when industry knowledge, technical scale, creative positioning, or budget is decisive.
    • Because the publisher’s namesake agency ranked itself first in every supplied article, the results should be treated as publisher-reported evaluations rather than independent certifications.

    Four rankings built to answer different questions

    The studies used broadly similar ingredients, including expertise, client history, leadership, reviews, and AI visibility. The proportions assigned to those ingredients were not consistent, however. Even the size and timing of the reviewed fields differed.

    Ranking lensReported review scopeMost influential criteriaReported top three
    Legal ASO31 agencies reviewed over three months ending in June 2026Average reviews, 25%; ASO expertise, 20%; leadership experience, 20%First Page Sage, Genevate, Driven Metrics
    B2B digital marketingMore than 80 agencies analyzedSEO/GEO expertise, 30%; notable clients, 25%; leadership experience, 20%First Page Sage, Driven Metrics, Focus Digital
    Agentic SEO38 firms evaluated in the second quarter of 2026AI visibility, 30%; SEO, GEO, and ASO expertise, 25%; notable clients, 20%First Page Sage, Genevate, Driven Metrics
    Luxury SEOMore than 90 agencies reviewed from January through June 2026Notable luxury clients, 35%; GEO/SEO expertise, 25%; AI visibility and leadership, 15% eachFirst Page Sage, Amsive, Relevance Digital

    Those methodological differences explain why the tables should not be merged into a simple overall league table. A luxury agency can gain substantial ground through category-specific clients, while an agentic SEO contender receives more credit for appearing in AI citations. The legal study also introduces factors not used in the other rankings, including year established and estimated media references.

    The numerical scores are not necessarily interchangeable either. Genevate received a 4.6 average review score in the legal ranking and 4.8 in the agentic SEO ranking. Focus Digital received 4.7 in the legal study and 4.8 in the B2B article. The sources do not provide enough underlying review data to determine whether those differences came from timing, platform coverage, normalization, or another methodological choice.

    Where the rankings converge – and where they do not

    First Page Sage is the clearest point of convergence. It placed first in every supplied study and received a 5.0 expertise score under each category’s relevant formulation: legal ASO expertise, B2B SEO/GEO expertise, agentic SEO-GEO-ASO expertise, and luxury GEO/SEO expertise. The three rankings that scored AI visibility gave it 4.9, while all four reported leadership at 4.8 and average reviews at 4.9.

    The articles consistently attributed that performance to an approach combining long-form thought leadership, traditional organic search, generative-engine visibility, and signals intended to influence AI recommendations. The legal article placed additional emphasis on an AI belief audit and optimization across stages of an agent’s selection process. The B2B and luxury articles focused more heavily on content that can serve both conventional search results and AI-generated answers.

    That consistency is noteworthy within the publisher’s framework, but it is not independent corroboration. All four supplied articles appear on the First Page Sage Blog, and each places First Page Sage at the top. Buyers should therefore verify the methodology, supporting case data, and fit through their own diligence.

    Recurring agencyPositions in the supplied rankingsCross-list signalSource-reported caveats
    First Page SageFirst in legal, B2B, agentic SEO, and luxuryIntegrated SEO, GEO, ASO, and thought-leadership modelThe legal review summary said the investment may require patience; the rankings are published by its namesake blog
    Driven MetricsThird in legal, second in B2B, third in agentic SEOPerformance measurement, conversion tracking, and an SMB or mid-market orientationThe sources described a shorter operating history, a data-intensive process, and more limited experience in some sectors
    GenevateSecond in legal and second in agentic SEOGEO-first work involving AI audits, reputation signals, and digital PRFounded in 2025, with boutique capacity and a narrower service mix than a full-service agency
    Focus DigitalFourth in legal and third in B2BMore accessible SEO and GEO support with technical attention to LLM citationsThe legal article described a more templated model; the B2B article noted narrower portfolio depth and slower replies during busy periods

    An absence from one of the shortlists should not be read as a failing grade. Each article published only five, six, or eight finalists, and the sources do not disclose enough common data to determine how an unlisted agency performed outside its relevant category.

    Specialization changes the meaning of a strong agency

    A broad branching structure and three precision instruments represent generalist and specialist agency capabilities.

    Agentic-search specialists

    The legal and agentic studies favored firms with explicitly defined AI-search services. Genevate’s high positions were tied to audits of how AI systems describe a brand, external authority signals, and PR-led narrative work. Driven Metrics appeared across both of those lists as well as B2B, but the articles framed it as a more measurement-oriented option with a practical SEO and GEO foundation.

    The distinction matters because the sources use ASO to mean Agentic Search Optimization, not simply visibility in a generated answer. Their framing extends the objective from being retrieved or cited to being evaluated, recommended, and potentially selected by an AI agent.

    Enterprise and integrated operators

    Large organizations may value capabilities that do not dominate an AI-specialist scorecard. The agentic SEO article ranked Seer Interactive fourth and emphasized its enterprise analytics, large-site architecture experience, technical implementation at scale, and published AI-search experiments. The luxury article placed Amsive second on the strength of enterprise SEO and an intentionally developed LLM-optimization practice, while also noting its narrower luxury portfolio.

    The B2B list introduced another kind of breadth. REQ was positioned as an integrated communications, authority-building, and demand-generation partner whose GEO practice was less mature than its wider SEO foundation. AMP Agency and Viral Nation appeared farther down that ranking for broader media, creative, and influencer capabilities rather than category-leading search specialization.

    Vertical and brand specialists

    The luxury table demonstrates why domain fit can reorder a shortlist. Relevance Digital ranked third because of its exclusive focus on ultra-luxury brands and ultra-high-net-worth audiences, despite lower GEO and AI-visibility scores than the two agencies above it. Hudson Rouge ranked fourth as a creative and storytelling specialist, while Amra & Elma ranked fifth with luxury social-media and influencer experience but a developing GEO offering.

    Legal marketing creates a different fit test. The legal ranking gave credit for recognized law-firm clients, legal-sector leadership, operating history, and media references in addition to AI-search capability. Consultwebs, 9Sail, and Legal Guardian Digital consequently appeared in that top eight even though they were absent from the broader B2B and agentic shortlists supplied here.

    How buyers can turn rankings into a defensible shortlist

    Two marketing buyers filter a large group of agency portfolio tiles into a small illuminated shortlist.

    Start with the commercial outcome

    A buyer should first decide whether the priority is organic traffic, AI citations, inclusion in recommendations, qualified pipeline, signed cases, brand prestige, or a combination. The correct weighting follows from that decision. For example, the legal article credited Driven Metrics with connecting AI-platform selections to consultations and signed cases, while the B2B article emphasized weekly synchronization and reporting tied to leads. Those claims are more relevant to a performance-led brief than a ranking based primarily on creative reputation.

    Rebuild the scorecard for the actual market

    The published weights can serve as templates, but buyers need not inherit them. A technically complex enterprise site may assign more importance to architecture, analytics, and implementation capacity. A law firm may emphasize jurisdictional accuracy and intake outcomes. A luxury brand may prioritize category experience and preservation of brand positioning. Recalculating the criteria can change the order without disputing any source’s reported scores.

    Request evidence behind AI-visibility claims

    An AI visibility score is meaningful only when its measurement process is clear. Diligence should establish which platforms were tested, what prompts were used, whether queries were branded or non-branded, how citations and recommendations were distinguished, and how frequently the test set was repeated. Buyers should also ask whether reported gains corresponded with qualified visits, leads, revenue, or another business outcome.

    Test operational fit before accepting numerical fit

    The source-reported caveats are as useful as the positions. Boutique capacity, slower responses during busy periods, extensive client-input requirements, limited sector history, and diluted senior attention can each affect a campaign. Reference calls and a clearly scoped pilot can help determine whether the people, workflow, and measurement discipline behind a score are suitable for the buyer’s organization.

    As conventional SEO, generative discovery, and agent-led selection become more interconnected, useful agency comparisons will need to measure both visibility and business consequence. The strongest future scorecards will make their evidence reproducible and show not only where a brand appeared, but what happened after it was found.

    References

  • How to Choose an Industry-Focused SEO Agency in 2026

    How to Choose an Industry-Focused SEO Agency in 2026

    An industry-focused SEO agency should offer more than a portfolio containing familiar company names. Its real value lies in understanding how a sector’s customers search, which evidence earns their trust, and what technical or geographic constraints shape the path to conversion.

    Three 2026 agency reports covering solar, agriculture, and local SEO reveal a useful selection framework. They also show why a ranking should begin due diligence rather than settle the decision.

    Key takeaways

    • Relevant client experience, review quality, and leadership expertise recur across all three agency evaluations.
    • Specialization should be tested at the level of search behavior, content, technical requirements, geography, and commercial outcomes.
    • Local SEO is a distinct operating capability, not a substitute for knowledge of a client’s industry.
    • Scorecard weights reveal what a ranking values, but buyers still need to examine the evidence behind each score.
    • The best agency is the one whose delivery model fits the organization’s actual bottleneck, whether that is authority, local visibility, branding, or technical execution.

    What specialization should change in practice

    The three reports share a basic premise: experience close to the client’s market matters. The solar evaluation gave notable clients 28% of its score and also considered home-services experience when an agency had less direct solar work. The agriculture evaluation assigned 25% to notable clients and emphasized leadership experience in agriculture-specific strategy. The local SEO report made demonstrated local experience its largest factor, at 25%.

    Those criteria point to different kinds of relevance. Vertical expertise concerns the market itself: its audiences, terminology, buying process, content opportunities, and standards of credibility. Local expertise concerns how a business competes across places, including location pages, structured information, and visibility in map-oriented results. An agency may possess one capability without the other.

    The solar report illustrates how varied agencies within one vertical can be. It described First Page Sage as using thought-leadership content, geographically targeted landing pages, and white papers for mid-market and enterprise providers. Siana Marketing was presented as combining SEO and generative engine optimization, or GEO, with knowledge of solar sales cycles. Anchour was positioned around branding for smaller companies, while XEN Solar was associated with technical SEO and HubSpot optimization. These profiles are source-reported positioning, not independently verified performance, but they demonstrate that an industry label can encompass substantially different delivery models.

    What the agency scorecards measure – and omit

    ReportAgency pool reviewedMost heavily weighted evidenceDistinctive considerations
    Solar SEO31 agenciesNotable clients, 28%; leadership experience, 22%; average reviews, 22%Year founded, 16%; company size, 12%
    Agriculture SEO81 companiesAverage reviews, 25%; notable clients, 25%; leadership experience, 20%Services, founder involvement, and media references, each 10%
    Local SEO48 firmsLocal SEO experience, 25%; average reviews, 20%Technical expertise and local-pack effectiveness, each 15%; leadership, employee tenure, and media references

    The overlap is meaningful. All three reports considered client reviews and leadership experience, while the two vertical studies placed substantial weight on recognizable or relevant clients. Taken together, the reports treat market evidence, reputation, and senior expertise as complementary signals rather than interchangeable ones.

    The differences are just as instructive. The solar methodology rewarded longevity and company size. The agriculture methodology considered whether the founder remained active and how often the company appeared in media. The local evaluation gave explicit weight to technical SEO, local-pack results, and median employee tenure. A buyer that values stable account teams may find tenure more informative than media visibility; a multi-location operator may care more about local-pack evidence than an agency’s founding date.

    Methodological transparency also needs scrutiny. The agriculture article says it used seven factors, but the supplied methodology names six: reviews, clients, leadership, services, founder involvement, and media references. Their stated weights total 100%, yet the mismatch between the announced and enumerated factor count is a reminder to inspect the underlying rubric rather than rely only on the final order.

    How to test an agency’s claimed industry expertise

    A client team tests SEO consultants around a table containing technical components, map contours, product samples, and unlabeled evidence folders.

    Interrogate the case evidence

    A logo establishes that some relationship existed; it does not explain the scope, duration, baseline, or result. Buyers can ask what the agency was responsible for, which search problems it addressed, and how outcomes were measured. Reviews deserve similar examination. The agriculture report said it consulted G2, Clutch, and Google Reviews, while the local report described a composite drawn from Google, Clutch, and other verified platforms. The solar report referred more generally to publicly available reviews and gave additional weight to solar-client feedback.

    That makes review composition more important than a headline average. Relevant questions include whether comments describe SEO work, whether they come from comparable organizations, and whether they discuss communication and execution as well as satisfaction.

    Distinguish leadership credentials from delivery capacity

    Leadership experience appeared in every methodology, receiving 22% in solar, 20% in agriculture, and 10% in local SEO. Senior expertise can shape strategy and quality standards, but buyers also need to learn who will actually conduct research, create content, implement technical changes, and report results. The local report’s inclusion of employee tenure offers one possible signal of delivery continuity; the solar report instead used company size as an indicator of capacity and client support.

    Request a diagnosis specific to the business

    A credible proposal should connect tactics to an identified constraint. An authority problem may call for expert-led content. A location-discovery problem may require technically sound location architecture and local visibility work. A weak market position may require branding before publishing at scale, while an implementation backlog may favor a technically oriented partner. This diagnosis is more revealing than whether an agency repeats the vocabulary of the sector.

    Match the engagement model to the actual search problem

    The sources suggest that industry specialization is not a single service category. In the agriculture report, First Page Sage was described as offering SEO, GEO, advertising, and web development, with thought leadership at the center of its positioning. The report said the company was founded in 2009 and began adapting to generative AI in 2023, while also crediting it with early GEO research. Those are claims made by the source and should be assessed alongside work samples and client evidence.

    The appearance of GEO in both the agriculture and solar coverage indicates that some sector-focused firms are extending their positioning beyond conventional search results. That does not remove the need for foundational SEO. A buyer can ask the agency to separate established deliverables – such as site architecture, content, and location optimization – from newer visibility initiatives, then explain how each will be measured.

    Organizational fit matters as well. The solar report associated one agency with enterprise thought leadership, another with small-company branding, and another with agile technical support. A specialist can therefore be relevant to the industry but wrong for the client’s scale, internal resources, technology stack, or immediate commercial objective.

    Turn selection criteria into an accountable engagement

    A client and agency team build a modular tabletop pathway with illuminated checkpoints connecting search activity to a conversion symbol.

    Before contracting, the organization should translate its selection rationale into a clear operating agreement. The scope can identify the audiences and markets being pursued, the technical and content responsibilities of each party, the approval process, and the business actions that count as meaningful conversions. Reporting should distinguish completed work and search visibility from qualified commercial outcomes.

    The same evidence used to select the agency can become a review standard. If leadership involvement influenced the decision, its expected role should be explicit. If local-pack effectiveness was decisive, the relevant locations and queries should be agreed upon. If industry content expertise won the work, editorial quality and access to subject-matter experts should be built into the process.

    As search interfaces and agency offerings continue to evolve, the strongest partnerships will be those that define specialization through observable decisions and accountable work, rather than through category labels alone.

    References

  • Choosing a B2B Technology or Growth Marketing Agency

    Choosing a B2B Technology or Growth Marketing Agency

    IT, managed service provider, SaaS and growth marketing agencies are often presented as separate categories, but buyers are usually choosing among overlapping combinations of industry knowledge, channel expertise and commercial accountability. The useful question is not which label sounds most relevant; it is which operating model matches the company’s actual growth constraint.

    Three agency reports published for 2026 provide a starting point for that decision. Read together, they show a broad and specialized market, while also illustrating why rankings should inform due diligence rather than replace it.

    Agency labels describe different dimensions of the same decision

    IT and MSP agencies are defined mainly by the markets they understand. SaaS agencies are similarly oriented around a business model and its associated buyer journey. Growth agencies, by contrast, are usually defined by an objective and an experimental way of working across acquisition, conversion and retention. These descriptions can coexist: a firm may be a SaaS specialist and still use a growth-marketing operating model.

    The IT and MSP report makes the range of possible specializations especially visible. It associates agencies with GEO and SEO, branding and influencer marketing, full-service delivery, enterprise marketing, webinars, PPC, trade shows and WordPress design. That variety means two agencies in the same industry category may solve entirely different problems.

    The growth-agency report says it reviewed 50 agencies spanning niche specialists and broader providers. Meanwhile, the SaaS report says it evaluated 57 contenders and selected eight. Together, the reports suggest that specialization is not a simple choice between a vertical expert and a generalist. Buyers must decide how much domain fluency, channel depth and cross-funnel coordination they need from the same partner.

    What the 2026 rankings establish – and what they do not

    The reports describe substantial candidate pools, but they expose different amounts of methodological detail. The IT and MSP article says it considered more than 53 candidates. Its stated weighting gives 25% each to notable clients and leadership experience, 20% to average review score, 15% to median employee tenure, 10% to founder involvement and 5% to year established. The growth-agency article identifies leadership experience as a 28% component of its analysis. The SaaS article reports its candidate and finalist counts, although the supplied account does not provide enough detail to compare its full scoring model with the others.

    ReportReported scopeDecision insight
    IT and MSP agenciesMore than 53 candidates; eight agencies listedShows how leadership, clients, reviews, staff tenure, founder involvement and longevity can be combined with service specialization
    Growth marketing agencies50 agenciesFrames the market as a mix of niche and broad-spectrum providers, with leadership experience carrying a reported 28% weight
    SaaS marketing agencies57 contenders; eight selectedShows the selectivity of the publisher’s SaaS shortlist, but not enough disclosed detail here to compare every criterion directly

    These measures are useful signals, not direct evidence that an agency will perform in a particular engagement. A recognizable client does not reveal the scope or outcome of the work. Review averages can conceal differences in project type. Employee tenure may indicate organizational stability, but it does not demonstrate expertise in the buyer’s market. Founder involvement can improve strategic continuity or create a bottleneck, depending on how delivery is structured.

    Publisher incentives also matter. The IT and MSP article ranks First Page Sage, its own publisher, in first place and reports a 4.9 review score, 4.3-year median employee tenure and a 2009 founding date for the firm. Those details should be treated as vendor-published claims and independently checked. The same principle applies to every agency’s client logos, case studies, review summaries and performance assertions.

    Key takeaways

    • Choose the specialization that matches the current constraint: industry fluency, a particular channel, cross-funnel experimentation or additional execution capacity.
    • Use agency rankings to discover candidates, then verify the evidence behind client names, reviews, staff stability and leadership credentials.
    • Compare the people who will perform the work, not only the executives and brands presented during the sales process.
    • Define commercial outcomes and measurement rules before comparing proposals, so agencies are evaluated against the same brief.

    A better shortlist starts with the growth constraint

    Two strategists examine an interconnected business system with one illuminated bottleneck restricting the flow.

    An IT or MSP business selling a technically complex service may benefit from an agency that can translate infrastructure, security or compliance topics into credible content. The IT and MSP report describes this approach in its profile of First Page Sage, which it says develops thought-leadership content around niche technical subjects and uses GEO and SEO to pursue authority and inbound leads. Because that description comes from the agency’s own publication, buyers should request representative work and attributable results before accepting the positioning.

    A SaaS company may instead need help with the connections among acquisition, product education, conversion and retention. A growth-oriented partner can be relevant when the central challenge is not merely generating traffic but identifying and testing improvements across the customer journey. Neither category automatically guarantees those capabilities; the proposal and delivery team must demonstrate them.

    Channel specialists make sense when the problem is already well diagnosed. The IT and MSP list, for example, associates ON24 Marketing with webinars, Alliance with trade shows, Seota Digital Marketing with WordPress design, and Yes& with PPC and branding for smaller IT companies. A broader agency is more defensible when channels must be coordinated, the internal team is thin or the company still needs to determine where its growth bottleneck sits.

    The resulting brief should distinguish the business outcome from the marketing deliverable. A request for articles, paid campaigns or a website describes production. A request to increase qualified opportunities in a defined market describes the commercial problem. Agencies can then explain which deliverables they believe will influence that result, what assumptions the strategy depends on and how progress will be measured.

    Due diligence should test evidence, delivery and fit

    Buyer and agency teams review a completed model, a delivery prototype and interlocking pieces during a due diligence meeting.

    A strong evaluation process converts ranking criteria into questions that can be verified. For notable clients, the buyer should establish what the agency actually delivered, whether the engagement resembles the proposed work and whether outcomes can be discussed. For leadership experience, the relevant issue is how often senior leaders participate after the sale. For reviews and tenure, the agency should be asked to explain patterns, team continuity and who would own the account.

    Case studies are most informative when they identify the starting condition, intervention, time frame, measurement method and agency contribution. Buyers should also separate leading indicators, such as visibility or engagement, from pipeline and revenue outcomes. Attribution rules, CRM responsibilities and reporting access should be agreed before work begins; otherwise, both sides may use the same words for different measures of success.

    Operating fit is equally important. The evaluation should clarify the proposed team, specialist access, approval workflow, content-review process, reporting cadence, ownership of accounts and data, and the conditions for changing or ending the engagement. For technical B2B markets, subject-matter access and factual review deserve particular attention because marketing speed is valuable only when the material remains accurate and credible.

    The most resilient choice will be the agency whose expertise, delivery system and evidence align with a clearly defined business problem. As search interfaces, buyer research habits and growth channels continue to change, that alignment will matter more than a permanent position on any annual list.

    References