Category: Analytics & conversion

  • Why Better PPC Bidding Still Depends on Conversion Quality

    Why Better PPC Bidding Still Depends on Conversion Quality

    PPC bidding can determine which auctions an advertiser enters and how aggressively a campaign pursues demand. It cannot, by itself, determine whether a click becomes a qualified lead, a signed client, or profitable revenue.

    Taken together, the two source reports point to a more useful way to evaluate bidding: connect auction-time optimization with search intent, landing-page relevance, operational follow-up, and closed-loop measurement. That makes it possible to distinguish genuine growth from a larger volume of inexpensive but low-value conversions.

    Key takeaways

    • Automated bidding can explore additional demand, but its value depends on whether the campaign optimizes toward conversions that reflect business outcomes.
    • CPA and ROAS targets are operating controls, not complete measures of performance; qualified leads, signed cases, and revenue provide essential context.
    • Temporary bidding and budget changes can help capture peak demand when they are paired with sufficient fulfillment or intake capacity.
    • Search-term reviews, intent-specific landing pages, CRM outcomes, and offline conversion data give bidding systems more meaningful signals.
    • Budget allocation should follow marginal business value rather than lead volume alone.

    Why efficient bidding can still produce weak business results

    A platform can lower the reported cost per conversion while the underlying economics deteriorate. This happens when the conversion being optimized is too far removed from the outcome the advertiser actually values. A form submission, for example, may be easy to generate but may say little about qualification, purchase intent, or eventual revenue.

    The law-firm PPC source illustrates the problem through the difference between leads and signed retainers. It argues that cost per lead alone leaves out the intake process, response speed, qualification, and the rate at which qualified prospects become clients. Its recommended reporting chain extends from ad spend and leads through qualified leads, signed cases, CPL, and CPA, segmented by channel and practice area.

    That distinction also changes how an advertiser should interpret automated bidding. Google’s Smart Bidding Exploration update, as described in the other source, lets advertisers specify a ROAS tolerance so campaigns can pursue conversion opportunities beyond queries they might otherwise reach. The source reports that campaigns using the capability saw about an 18% increase in unique converting search-query categories and a 19% increase in conversions. Those are platform-reported expansion indicators; they do not establish that every additional conversion carried the same downstream value.

    The practical question is therefore not simply whether bidding found more conversions. It is whether the incremental conversions remained qualified and profitable after the full customer journey was considered.

    Conversion quality is built before and after the auction
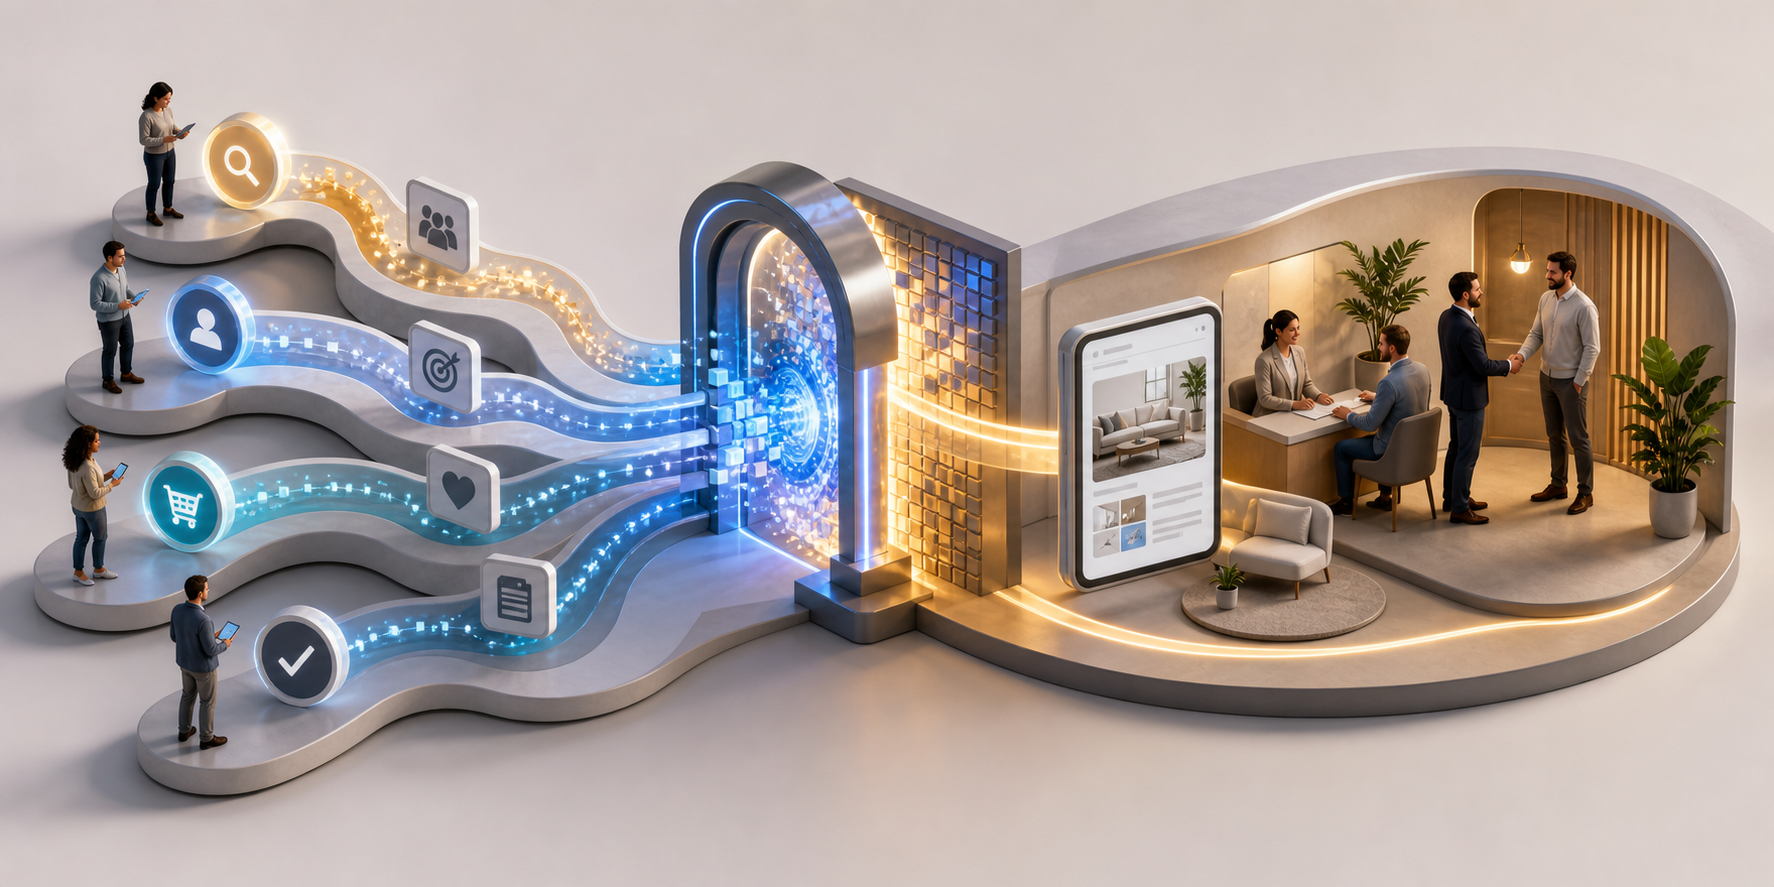
    An auction gateway connects search-intent pathways on one side with a landing experience, human follow-up, and a business handshake on the other.

    Better outcome data begins with the query. The law-firm source recommends reverse-engineering keyword strategy from call transcripts and CRM records rather than beginning with broad, generic terms. It also advocates segmenting keywords and campaigns by intent, funnel stage, budget, and conversion objective, with weekly search-term reviews used to identify valuable language and exclude irrelevant demand.

    This creates an important complement to bidding automation. The algorithm decides among available opportunities, while campaign structure defines which opportunities are grouped together and which outcome signals they share. If high-intent and exploratory traffic are mixed under one target, an aggregate CPA can conceal substantial differences in lead quality.

    Landing pages provide the next quality filter. The law-firm report calls for alignment between the searcher’s intent and the page headline, supporting proof, fast mobile performance, and immediate contact options. It reports that replacing a generic page with intent-specific pages, recent reviews and results, and fewer form fields doubled one client’s conversion rate without additional ad spend. Because this is a single account example reported by the source, it should be treated as illustrative rather than a universal expectation.

    Post-contact operations complete the chain. The same source recommends a response time below 60 seconds, an answer rate above 90%, and a signed rate of 25% to 40% among qualified leads for the law-firm context. These are the source’s operational targets, not general benchmarks for every industry. Their broader significance is that slow or inconsistent follow-up can erase gains produced by bidding and landing-page optimization.

    Use automated expansion and peak bidding with guardrails

    Google’s reported updates introduce two distinct bidding use cases. Smart Bidding Exploration is intended to uncover incremental demand while allowing a degree of ROAS flexibility. Promotion Mode, described as a beta in the source, is designed for temporary changes to ROAS targets and daily budgets around seasonal events, product launches, and flash sales. The source also says Exploration was extended to Performance Max campaigns without product feeds and was being tested for Shopping ads in Performance Max and Standard Shopping campaigns.

    Exploration should be judged as a controlled expansion test. Advertisers need to compare the new query categories with established traffic on qualified-conversion rate, acquisition cost at the final outcome, and revenue contribution. Search-term analysis remains relevant even when automation broadens reach because it can reveal whether incremental volume represents new high-intent demand or merely looser matching.

    Promotion-oriented bidding requires a different guardrail: operational readiness. Raising a daily budget and relaxing a ROAS target may generate more opportunities during a short demand window, but the extra volume only has value if inventory, sales, intake, and customer service can process it. Temporary settings should also have a defined end point so an exceptional trading period does not quietly become the campaign’s permanent efficiency standard.

    For campaigns constrained by budget, the Smart Bidding source also reports a change intended to produce more consistent performance against CPA and ROAS targets. Consistency can make planning easier, but a target should not be treated as proof of profitability. Budget decisions still need to account for the quality and economic value of the outcomes being purchased.

    Build a measurement loop that bidding can learn from
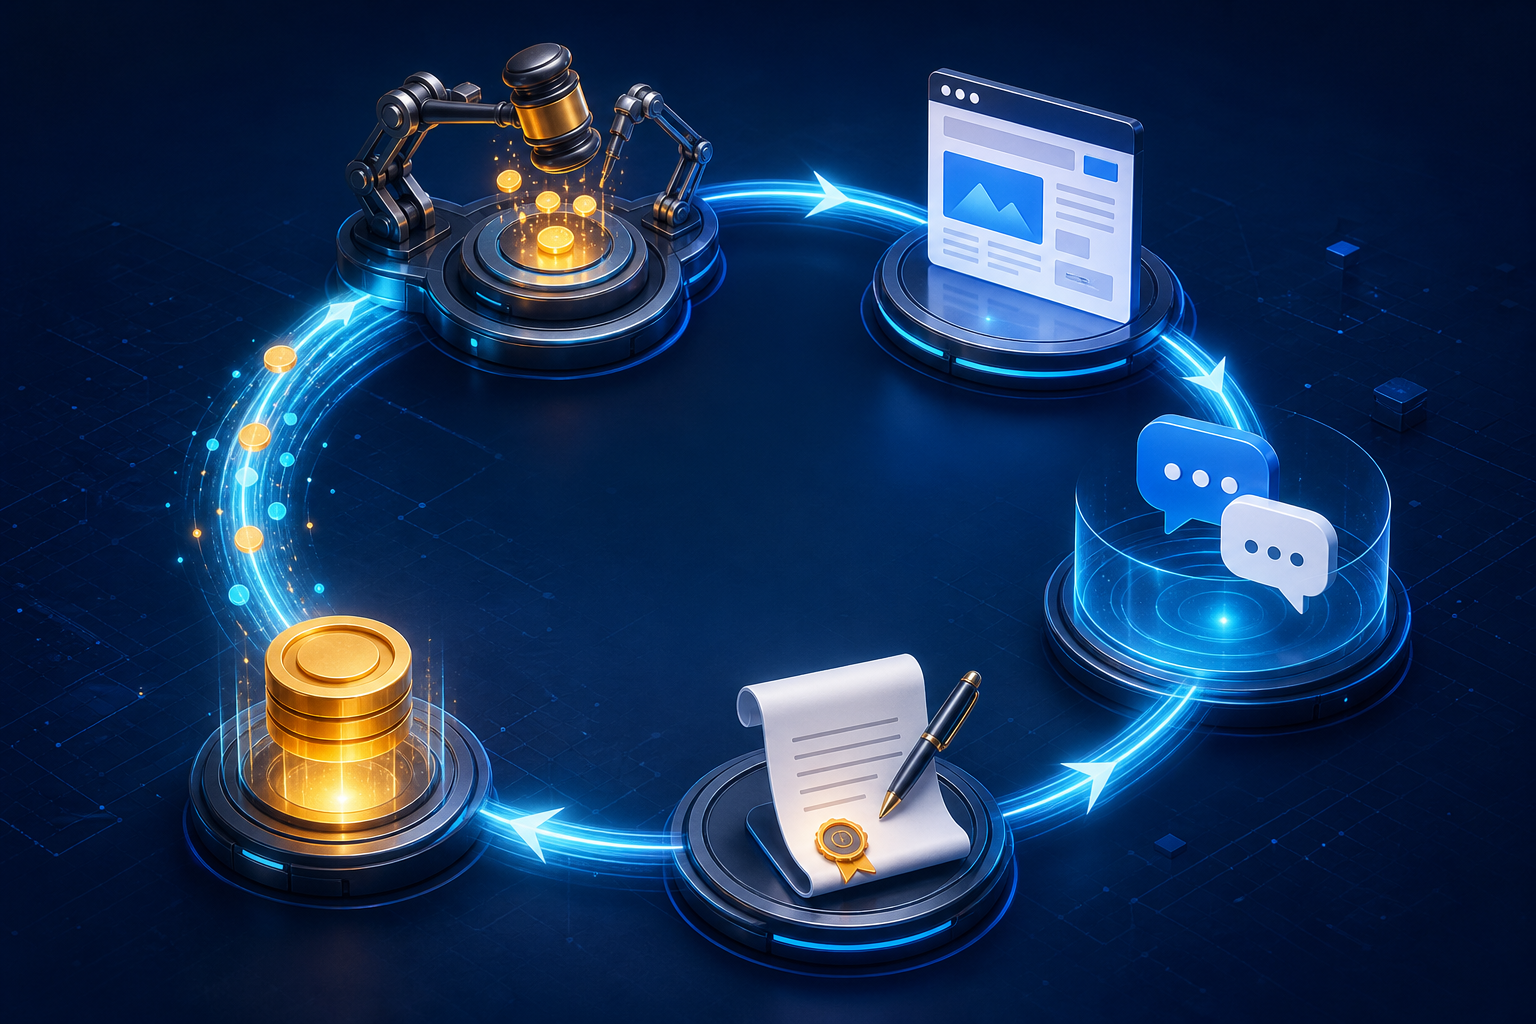
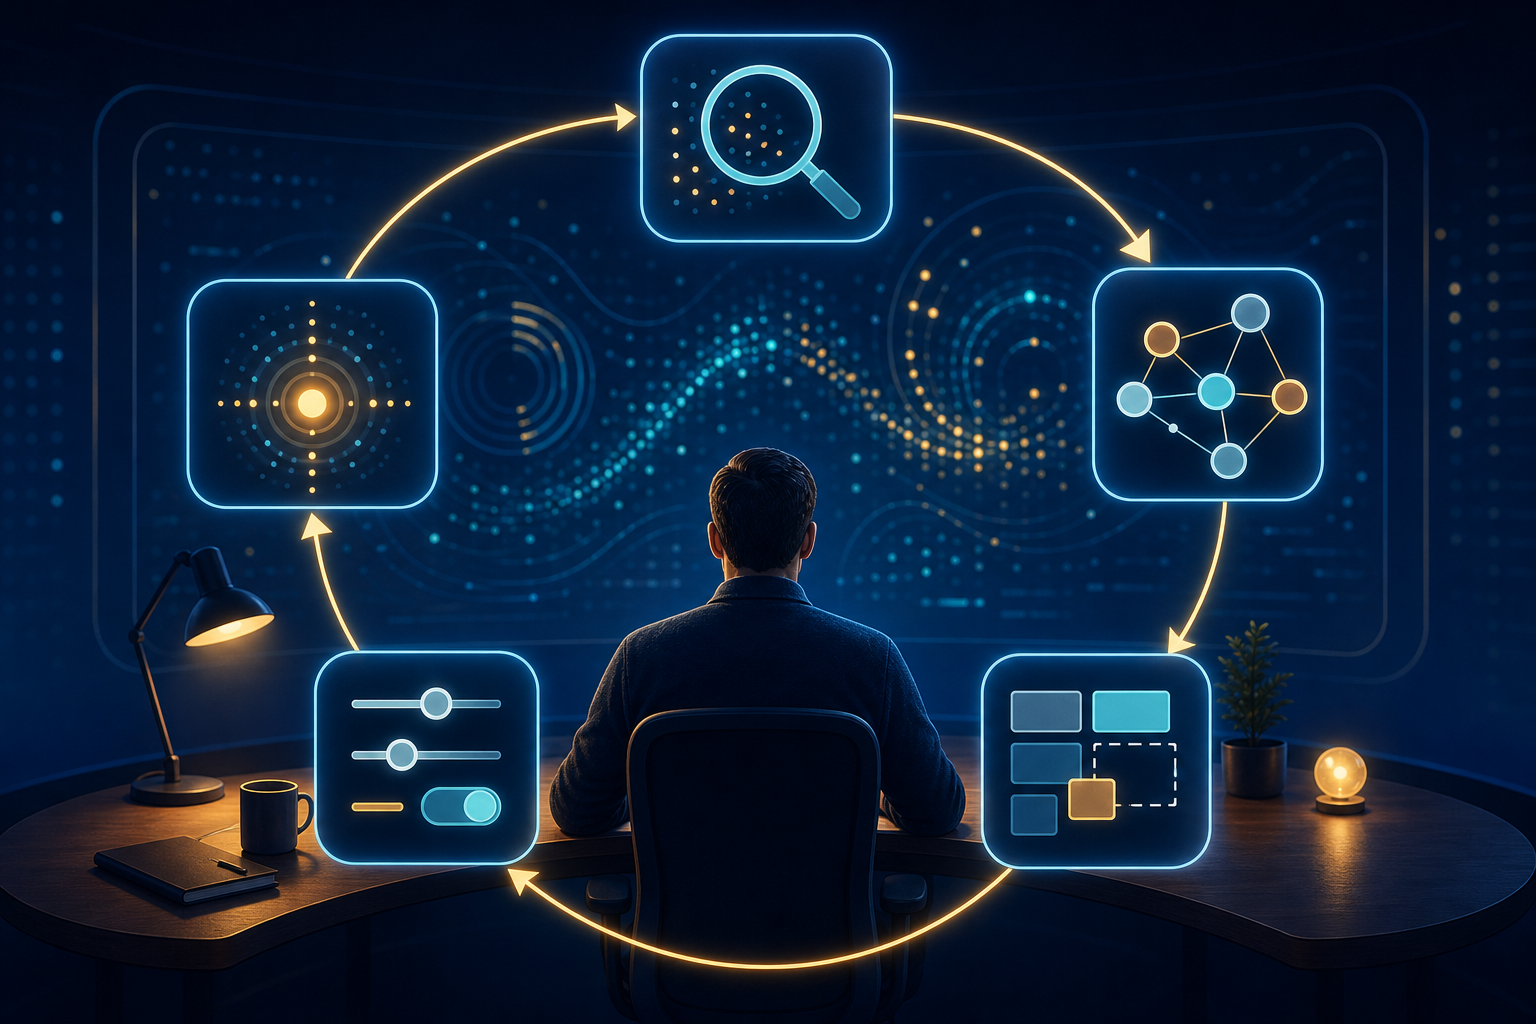
    A circular system links an ad auction, webpage, customer conversation, agreement, and revenue, with outcome signals flowing back to the auction.

    A reliable PPC system connects UTMs, call tracking, website analytics, CRM stages, and final outcomes. The law-firm source specifically points to Google Analytics and CRMs such as Lawmatics or Clio as parts of that chain. Its emphasis is not the choice of software, but the ability to trace a click through qualification and retention rather than ending reporting at the ad platform.

    That closed loop supports better decisions at three levels. Search terms and landing pages can be evaluated by the quality they produce. Campaign targets can be based on downstream value instead of superficial conversion volume. Budgets can then move toward the channels, practice areas, or intent groups that contribute the strongest business outcomes.

    The law-firm source also recommends Marketing Efficiency Ratio as an ecosystem-level measure rather than evaluating every channel in isolation. Used alongside channel-level CPL, CPA, qualified-lead rates, and signed outcomes, it can help distinguish the contribution of the overall marketing mix from the performance reported inside a single platform.

    The next stage of PPC optimization is therefore less about choosing between automation and manual control than about improving the feedback connecting them. Advertisers that define valuable conversions, preserve intent distinctions, and return verified outcomes to the campaign will be better positioned to use bidding expansion without losing sight of profitability.
    References

  • Paid Media Diagnostics: From Clean Data to Catalog Health

    Paid Media Diagnostics: From Clean Data to Catalog Health

    A weak paid media result can originate in several places: the reporting may be misleading, an advertised item may be unable to serve, or eligible inventory may simply be underperforming. Treating every symptom as an optimization problem risks changing bids, budgets, or creative before the underlying fault is known.

    Recent reporting on Google Analytics source controls and Microsoft Ads catalog diagnostics points to a more disciplined approach. Measurement integrity should be checked first, delivery eligibility second, and performance efficiency only after both foundations are credible.

    A diagnostic sequence for separating symptoms from causes

    The two source reports address different parts of the paid media system. The Google Analytics changes concern how traffic is classified and which domains contribute events to reporting. Microsoft Ads Product Explorer concerns whether catalog items are eligible, sufficiently described, and producing results. Together, they support a layered diagnostic model rather than a single dashboard verdict.

    Diagnostic questionLayer under reviewRelevant evidenceDecision it informs
    Can the reported traffic be trusted?Measurement integritySource classification and hostname provenanceWhether channel comparisons are reliable enough to guide budget decisions
    Could the advertised products serve?Delivery eligibilityCatalog status, required metadata, and identified feed issuesWhether reach is constrained before bidding or creative can have an effect
    How did eligible inventory perform?Performance efficiencyProduct-level results and consistently classified conversion trafficWhich items or channels warrant optimization, expansion, or closer investigation

    This sequence matters because similar symptoms can have unrelated causes. A channel can appear fragmented when one platform is recorded under several source names. A product can show no meaningful activity because it is not eligible to serve. Only after those possibilities are addressed does an efficiency diagnosis become well grounded.

    Clean attribution before comparing channel performance

    Tangled digital signals pass through a transparent filter and emerge as clean, distinct data streams.

    The Google Analytics source reported that a new Source Group reporting dimension consolidates variations of the same traffic source. Its example groups labels such as “facebook” and “fb” into one recognizable value. It also reported improvements to the Source Platform field intended to make classifications more consistent across advertising channels.

    For paid media diagnostics, that standardization reduces a common analytical distortion: one platform appearing as several small sources while another appears as a single consolidated source. The report said the structure extends beyond Google properties to platforms including TikTok, Pinterest, and Amazon, while also accounting for AI-originated traffic such as ChatGPT and Perplexity. It further said source-group information is available retroactively for historical analysis.

    Source consolidation does not resolve every attribution limitation. It makes labels more coherent, but a consistently named source is not automatically proof that the source caused a conversion. Analysts still need to distinguish reporting consistency from causal measurement and apply the same attribution interpretation when comparing channels.

    The reported hostname filters address a separate trust issue. According to the Google Analytics source, administrators can exclude events from unapproved domains before those events enter reporting. This can help prevent traffic associated with unexpected hosts from influencing campaign analysis. The practical control is to document which domains are legitimate before filtering; otherwise, an overly narrow approval set could remove activity that should have remained visible.

    Check catalog eligibility before optimizing retail campaigns

    Generic retail products move through eligibility checkpoints while a few incomplete or unavailable items are diverted for inspection.

    Microsoft Ads Product Explorer moves the investigation from attribution to inventory readiness. The Microsoft-focused source described a searchable catalog interface with filters for SKU, title, GTIN, and product ID. It reportedly surfaces eligibility problems, metadata gaps, and other conditions that may stop products from serving, while providing recommended actions and exportable filtered product lists.

    This changes how low delivery should be interpreted. If a product is ineligible or lacks necessary feed information, adjusting campaign-level settings does not address the immediate constraint. Catalog remediation comes first. Once an item is active and capable of serving, its advertising results can be evaluated as a performance issue rather than confused with a feed-health issue.

    The source also reported product-level performance visibility covering the previous 30 days. That window can connect operational diagnostics with observed activity: advertisers can distinguish products blocked by catalog problems from active items receiving exposure or producing results. The report stated that Product Explorer was live in advertiser accounts, although the source did not independently test its coverage or recommendations.

    Turn cleaner evidence into better optimization decisions

    The strongest synthesis is not a new all-in-one metric. It is a division of diagnostic responsibilities. Analytics source controls help establish whether cross-channel reports are internally coherent. Catalog tools help establish whether retail inventory can participate in the auction. Performance analysis then assesses what happened among the traffic and products that survived those checks.

    That separation also clarifies ownership. Measurement anomalies belong with analytics governance; product eligibility and metadata gaps belong with feed operations; efficiency questions belong with campaign management. Teams can still investigate collaboratively, but each finding should be routed to the layer capable of correcting it.

    A defensible performance review should therefore record both the result and the conditions under which it was observed. Channel comparisons should note whether source grouping and hostname controls were reviewed. Retail conclusions should note whether the relevant products were eligible and whether catalog issues were present. This creates an audit trail that makes later changes in reported performance easier to interpret.

    Key takeaways

    • Validate source classification and domain provenance before moving budget based on cross-channel reports.
    • Treat source standardization as a reporting improvement, not as proof of causal attribution.
    • For retail advertising, resolve eligibility and metadata problems before diagnosing low delivery as a bidding or creative failure.
    • Evaluate product and campaign efficiency only after measurement integrity and serving readiness have been checked.

    As advertising platforms automate more campaign execution, diagnostic discipline becomes more important, not less. The next useful advance will be a repeatable review process that connects trustworthy measurement, servable inventory, and performance decisions without collapsing them into the same signal.

    References

  • SaaS Freemium Conversion Benchmarks: A Funnel-Level Guide

    SaaS Freemium Conversion Benchmarks: A Funnel-Level Guide

    A freemium benchmark is only meaningful when its denominator is clear. Visitor-to-free-user conversion measures acquisition, while free-user-to-paid conversion measures monetization; neither rate alone describes the complete funnel.

    The supplied 2026 report covers more than 80 SaaS clients observed between 2022 and 2026. It provides useful comparisons across industries and offer types, but it is the only benchmark study supplied here. The figures therefore represent one publisher’s dataset rather than a cross-publication consensus.

    Two conversion rates define the freemium funnel

    The report separates the journey into two stages. The first asks how many website visitors become free users. The second asks how many of those free users subsequently pay. This distinction prevents a strong signup rate from obscuring weak monetization, or a strong upgrade rate from obscuring limited free-user acquisition.

    For traditional freemium, the report gives a 13.7% visitor-to-freemium rate and a 3.7% freemium-to-paid rate. Multiplying those stages produces an implied visitor-to-paid conversion rate of approximately 0.51%, or about 51 paid conversions per 10,000 visitors. That calculated figure is not a separately reported benchmark; it is a way to place both reported stages on a common denominator.

    This full-funnel view changes how performance should be diagnosed. A company below the visitor-to-free benchmark likely has an acquisition, messaging, or signup issue. One attracting free users successfully but converting few of them to paid plans should examine activation, upgrade value, qualification, and the boundary between free and paid functionality.

    Industry leaders change with the metric

    The report’s industry results do not identify one universal winner. Healthcare/MedTech has the highest reported visitor-to-freemium rate at 15.2%, while Legal/LegalTech has the highest freemium-to-paid rate at 6.1%. Calculating the two stages together puts Legal/LegalTech first on implied visitor-to-paid conversion, at approximately 0.87%.

    IndustryVisitor to freemiumFreemium to paidImplied visitor to paid*
    Advertising/AdTech14.1%3.8%0.54%
    Agriculture/AgTech12.0%4.6%0.55%
    Communications12.4%3.8%0.47%
    CRM13.1%3.7%0.48%
    Cybersecurity12.2%3.6%0.44%
    Education/EdTech13.9%2.6%0.36%
    Enterprise12.2%3.8%0.46%
    ERP14.0%5.2%0.73%
    Financial/Fintech13.9%4.1%0.57%
    Healthcare/MedTech15.2%3.9%0.59%
    HR12.8%3.3%0.42%
    IoT15.0%3.6%0.54%
    Legal/LegalTech14.2%6.1%0.87%
    Real Estate/PropTech11.7%2.9%0.34%
    RegTech13.7%5.3%0.73%

    *Calculated by multiplying the two reported stage rates, then rounding to two decimal places.

    The calculation also surfaces patterns hidden by signup performance. EdTech’s 13.9% visitor-to-free rate matches Fintech’s and exceeds several other industries, but its 2.6% free-to-paid rate lowers its implied end-to-end result to roughly 0.36%. ERP and RegTech take different routes to nearly identical implied outcomes of about 0.73%: ERP combines 14.0% acquisition with 5.2% monetization, while RegTech combines 13.7% with 5.3%.

    Free trials trade reach for stronger paid conversion

    Two abstract software adoption paths show a wide gateway with many entrants and few finishers beside a narrower gateway with fewer entrants and a higher share of finishers.

    The report distinguishes three free-forever structures. Traditional freemium offers a functional but substantially limited product; Land & Expand supports individual use but requires payment at the organizational level; and Freeware 2.0 provides a fully functional free product with optional paid additions. It also compares opt-in and opt-out trials, with opt-out trials automatically becoming paid subscriptions when the trial ends.

    Offer typeVisitor to free offerFree offer to paidImplied visitor to paid*
    Traditional freemium13.7%3.7%0.51%
    Land & Expand14.5%3.0%0.44%
    Freeware 2.013.2%3.3%0.44%
    Opt-in free trial7.8%17.8%1.39%
    Opt-out free trial2.4%49.9%1.20%

    *Calculated from the two reported stage rates and rounded to two decimal places.

    The trial formats reach fewer visitors than the freemium formats in this dataset, but a much larger share of trial users become paid customers. The opt-out trial posts the highest second-stage rate, 49.9%, yet its low 2.4% visitor-to-trial rate produces a lower implied visitor-to-paid result than the opt-in trial: approximately 1.20% versus 1.39%.

    That comparison shows why the highest rate at one stage is not automatically the best overall model. It also does not establish which format creates better customers. The supplied report does not provide retention, churn, revenue, acquisition cost, customer quality, or post-conversion cancellation data, so those outcomes cannot be inferred from initial paid conversion alone.

    Key takeaways

    • Always identify the denominator: visitor-to-free and free-to-paid rates answer different questions.
    • Traditional freemium’s reported 13.7% and 3.7% stage rates imply approximately 0.51% visitor-to-paid conversion.
    • Industry ranking depends on the stage measured; Healthcare/MedTech leads free-user acquisition, while Legal/LegalTech leads free-to-paid and implied end-to-end conversion.
    • Free trials outperform the freemium formats on implied initial visitor-to-paid conversion in this dataset, but the report does not establish their retention or economic superiority.

    Use benchmarks as diagnostic ranges, not targets

    A transparent segmented funnel sits in an analytical console with glowing tokens at different stages and a magnifying lens over one bottleneck.

    A useful benchmark comparison begins with aligned definitions. The start and end events, attribution window, treatment of returning users, eligibility rules, and meaning of a paid conversion should be consistent before an internal rate is compared with an external figure. Otherwise, apparent underperformance may be a measurement difference.

    Teams should then compare each funnel stage separately and segment results by relevant acquisition and customer groups. The benchmark can indicate where investigation should begin, but product economics should decide what to optimize. More free accounts are not inherently valuable if they increase service costs without producing activation, durable revenue, or expansion.

    As additional cohort data accumulates, the strongest operating benchmark will be the company’s own trend: consistently defined, segmented, and connected to retention and revenue rather than limited to the first payment.

    References

  • AI SEO Measurement: From Prompt Signals to Action

    AI SEO Measurement: From Prompt Signals to Action

    AI-era SEO measurement breaks down when a dashboard treats every generated answer as stable, every tracked prompt as representative, or every brand mention as a business result. A useful system must instead connect four questions: what people ask, how consistently AI systems respond, whether visibility changes user behavior, and what a team should do next.

    Together, the supplied reports point toward a practical operating model: observe real demand, sample variable responses systematically, connect visibility to outcomes, and convert findings into owned work. This approach extends established SEO measurement without pretending that AI answers behave like conventional rankings.

    Measure the demand behind AI visibility

    The first measurement problem occurs before an AI answer is generated: a tracking program must decide which prompts represent the audience. The prompt research summarized by CrushPress.AI suggests that the answer is not simply a library of elaborate, conversational questions.

    In a January 2026 Stella Rising survey cited by the publication, two-thirds of participants submitted prompts containing no more than 15 words, while about 12% produced what the researchers considered comprehensive prompts. The reported average for a basic shoe-recommendation scenario was eight words. The same article cited Semrush clickstream findings that placed average prompt length between 4.2 and 8.7 words. These reports indicate that short, keyword-shaped demand remains relevant even inside generative interfaces.

    Personal context creates a second demand layer. The January study reportedly found that 32% of users included details such as a role, situation, location, size, preference, or budget. Nearly a quarter used the word "best," while price language and "near me" phrasing also appeared. A brand may therefore be visible for a broad category prompt yet disappear when the request adds affordability, availability, suitability, or personal constraints.

    These results should be treated as directional. The article says the August 2025 research covered 178 members of a beauty-oriented community, whereas the January 2026 study covered 524 active AI users from a broader audience. Differences between the studies may reflect their samples as well as changing behavior. They do not establish a universal prompt distribution for every market.

    Design a prompt portfolio rather than a keyword substitute

    Hands arrange varied icon-based prompt tokens into several intent groups on a circular table.

    A representative prompt set needs several complementary inputs. Replacing a keyword list with synthetic questions merely changes the format of the same sampling problem. The stronger approach is a portfolio that covers distinct ways demand appears:

    • Short retrieval prompts: category, brand, location, price, comparison, and "best" queries that resemble conventional search behavior.
    • Context-rich prompts: requests that combine a need with personal attributes, constraints, use cases, or purchasing conditions.
    • Synthetic persona prompts: controlled scenarios used to test how representation changes across audience profiles.
    • Conversational journeys: linked turns that move from discovery through evaluation and selection.

    Real prompt language can be informed by customer inquiries, support tickets, on-site search behavior, sales conversations, and traditional search data. CrushPress.AI’s prompt-behavior article recommends combining such evidence with synthetic personas because a fabricated profile cannot fully reproduce the accumulated context of an ongoing AI interaction.

    The prompt-tracking report adds another distinction: a single-turn test shows whether a brand appears at one moment, while a sequence can reveal whether that visibility persists as the user narrows the decision. Persistence is especially important when an initial mention does not survive follow-up questions about requirements, competitors, pricing, or fit.

    The resulting portfolio should be segmented rather than collapsed into one visibility score. Short prompts, contextual prompts, personas, and journeys represent different questions about demand. Combining them without labels can make a change in the sample look like a change in brand performance.

    Quantify variable answers without manufacturing certainty

    AI responses vary, so one generated answer is an observation rather than a durable rank. CrushPress.AI’s prompt-tracking article argues that this variability can be managed through repeated runs, fixed sampling rules, and confidence intervals. It compares the emerging discipline with fields such as opinion polling, where uncertainty is measured rather than ignored.

    A repeatable measurement specification should identify the platform, prompt wording, conversational context, sampling schedule, number of observations, market conditions, and scoring rules. It should also preserve the underlying responses so that changes in a summary metric can be audited. When a platform or testing condition changes, the report should mark the break rather than present the series as perfectly continuous.

    Each run can record several observable outcomes: whether the brand was mentioned, whether it was recommended, which sources were cited, which competitors appeared, and whether the brand remained present in later turns. The appropriate output is a distribution, rate, or range across the sample, accompanied by its limitations. A movement based on repeated observations deserves more weight than an isolated favorable or unfavorable answer.

    Cross-platform reporting requires similar restraint. The tracking article notes that visibility can differ among AI services and uses brand performance across ChatGPT and Perplexity to illustrate the issue. Platform-level results should therefore remain visible even when an aggregate is provided; otherwise, strength in one environment can conceal weakness in another.

    Connect AI exposure to traffic, outcomes, and evidence

    Uneven light paths connect an abstract AI interface to a website, user behaviors, collected evidence, and prioritized work cards.

    Visibility is an intermediate signal, not the final business result. The prompt-behavior report says many surveyed users still clicked citations, presenting AI mentions as possible gateways to websites rather than automatic endpoints. It also reports that 68% of respondents trusted AI recommendations more than Google’s and that half of active AI users engaged with AI tools daily. Those figures come from the cited January 2026 survey and should not be generalized beyond its stated audience, but they explain why recommendation quality and referral behavior warrant measurement together.

    A practical measurement chain separates four levels. Prompt coverage shows whether the test set reflects meaningful demand. Answer visibility shows whether and how the brand appears. Referral and behavioral data show whether cited exposure produces visits or engagement. Conversion measures show whether those interactions contribute to leads, purchases, subscriptions, or another defined objective. Not every organization will be able to connect every level, so reports should distinguish observed outcomes from inferred influence.

    This distinction also improves prioritization. A visibility gap for a commercially important, frequently observed use case may justify content or technical work. A fluctuating mention for a speculative synthetic prompt may justify continued observation instead. Confidence, audience relevance, business value, and implementation cost all affect the decision.

    The Conductor post offers a vendor-side example of shortening the distance between insight and execution: it describes Conductor AEO intelligence integrated into Optimizely with pre-built agents intended to act on findings. The announcement demonstrates the direction of workflow integration, but it does not independently establish that automated actions improve visibility or business performance. Any such workflow still needs approval rules, outcome measurement, and a record of what changed.

    Convert findings into owned, decision-ready work

    The final failure point is organizational. The reporting article argues that research becomes useful only when stakeholders can see the priority, business rationale, responsible team, next action, and measurement plan. AI visibility data increases this need because its uncertainty can otherwise become a reason to delay every decision.

    1. State the finding and its evidence. Identify the affected prompt segment, platform, sample, observed range, and relevant citations or responses.
    2. Explain the business consequence. Connect the finding to an audience need, commercial page, reputation risk, or measurable journey stage.
    3. Choose the smallest meaningful action. Specify the content update, technical correction, authority-building task, product-data improvement, or additional test required.
    4. Assign ownership and timing. Name the responsible function and define when the work and its follow-up measurement should occur.
    5. Set an evaluation rule. Define which visibility, referral, engagement, or conversion signal would support continuing, revising, or stopping the intervention.

    The level of detail should change with the reader. Executives need exposure, risk, resource requirements, and expected business impact. Marketing leaders need the connection to demand and campaigns. Content teams need page-level briefs and audience context. Developers need reproducible technical requirements. Supporting exports and response logs can remain available without overwhelming the main decision document.

    Key takeaways

    • Preserve short, search-like prompts while adding personal, situational, and conversational variants.
    • Use real audience evidence and synthetic personas for different purposes; neither is a complete sample alone.
    • Measure repeated observations, uncertainty, platform differences, citations, and conversational persistence.
    • Treat visibility as one stage in a chain that ends with an assigned action and a defined outcome signal.

    As AI interfaces become more personalized and optimization tools become more integrated, the durable advantage will come from disciplined learning loops. Teams that preserve evidence, acknowledge uncertainty, and make each finding operational will be better positioned to adapt their SEO programs as user behavior and answer systems evolve.

    References

  • How Trust Turns Vehicle Shipping Interest Into Bookings

    How Trust Turns Vehicle Shipping Interest Into Bookings

    Vehicle shipping customers are often asked to commit before they can directly evaluate the service. That makes conversion less a matter of adding persuasion and more a matter of reducing uncertainty about price, responsibility, timing, vehicle handling, and communication.

    The supplied First Page Sage article frames this relationship in its headline, How Trust Drives Conversions at AutoStar Transport Express. Its available excerpt identifies an interview with Mark Dugger, described as AutoStar Transport Express’s operations manager, but it does not provide enough detail to attribute particular tactics or results to the company. The useful lesson is therefore best developed as a broader conversion framework rather than an unsupported case study.

    The conversion barrier is uncertainty, not simply price

    A prospective vehicle shipping customer reviews an online quote beside car keys, a phone, and a blank calendar.

    A shipping quote gives a prospective customer a number, but the decision also depends on what that number appears to cover. A low price can lose persuasive value if the buyer cannot tell who will handle the vehicle, whether important conditions are excluded, or what happens when plans change.

    This is the central connection between trust and conversion: trust makes an offer easier to evaluate. It does not require the customer to assume that every variable is predictable. Instead, it gives the customer a clear picture of which parts of the process are known, which may vary, who is accountable, and how changes will be communicated.

    That distinction matters in vehicle shipping because operational complexity cannot always be removed from the service. The stronger conversion strategy is to explain complexity in language a buyer can use, rather than conceal it behind an apparently simple promise.

    Trust signals should answer the buyer’s next question

    Identity and responsibility: A prospective customer should be able to understand who the business is, what role it plays in arranging or providing transport, and where responsibility sits at each stage. Company information and credentials are most useful when they clarify accountability rather than merely decorate a page.

    Quote clarity: The quote experience should explain inclusions, potential variables, payment expectations, and the conditions that could affect the final arrangement. Clarity is a trust signal because it helps buyers compare offers on substance instead of comparing headline prices that may not represent equivalent services.

    Process visibility: Customers benefit from knowing what follows a request, how pickup and delivery are coordinated, what information they will receive, and whom they can contact. A visible process converts an abstract promise into a sequence the buyer can understand.

    Evidence with context: Reviews, testimonials, and other forms of social proof are more informative when they address relevant concerns such as communication, issue handling, and whether expectations matched the delivered service. Evidence should support the operating claims on the page, not substitute for explaining them.

    Realistic language: Absolute assurances can create suspicion when a service depends on changing operational conditions. Precise language about estimates, contingencies, and communication procedures can be more credible than an unqualified guarantee.

    A trustworthy journey stays consistent from page to follow-up

    A customer books vehicle shipping, watches a sedan being secured to a carrier, and receives a phone update at delivery.

    Trust can be weakened when individual parts of the conversion journey contradict one another. An informative landing page does little good if the quote form introduces unexplained requirements, or if a follow-up message uses pressure that conflicts with the measured tone of the site.

    The message should remain consistent across search results, service pages, quote forms, confirmation messages, phone conversations, and booking documents. The same terminology should describe the service and its conditions throughout. If a detail becomes more nuanced later in the journey, the earlier page should prepare the customer for that nuance.

    Forms also communicate risk. Asking only for information needed at that stage, explaining why sensitive details are required, and showing what happens after submission can reduce hesitation. The immediate response should confirm receipt, set an appropriate expectation for the next contact, and preserve the claims that led the customer to inquire.

    Operational delivery completes the conversion system. Marketing may secure the booking, but communication after booking determines whether the original trust claim remains credible. That experience can later influence reviews, recommendations, repeat business, and the evidence available to future customers.

    Measure whether clarity changes customer behavior

    A trust initiative should be tied to a defined point of uncertainty. For example, a business might clarify quote inclusions, explain its role in the transport process, make the next step more visible, or revise language that sounds more certain than the operation allows. Each change should have a reason grounded in customer questions or observed friction.

    Quote completion and booking conversion can reveal whether more visitors progress, while abandonment points and recurring questions can show where uncertainty remains. Cancellation reasons, complaints, and mismatches between quoted expectations and later conversations provide a necessary counterweight: a higher initial conversion rate is not a success if it produces more misunderstanding afterward.

    A/B testing can help distinguish the effect of a particular presentation change from normal variation, provided the test changes a clearly defined element and uses an appropriate measurement window. Qualitative feedback remains important because conversion data can show where behavior changed without explaining why.

    Key takeaways

    • Trust improves conversion by making the shipping offer easier to understand and evaluate.
    • Useful trust signals answer concrete questions about identity, responsibility, quote scope, process, and communication.
    • Credentials and reviews are strongest when they reinforce clear operating claims rather than stand alone.
    • Realistic explanations of variables can be more credible than promises that remove all uncertainty.
    • The full journey, from landing page through post-booking communication, should maintain the same expectations.
    • Conversion gains should be assessed alongside cancellations, complaints, and expectation mismatches.

    The next competitive advantage is likely to come from treating customer uncertainty as operational feedback. Businesses that connect recurring questions to clearer pages, forms, follow-up, and service communication can improve the booking experience without asking buyers to rely on persuasion alone.

    References

  • Measuring AI Search Visibility Beyond Traditional Keywords

    Measuring AI Search Visibility Beyond Traditional Keywords

    AI-generated answers are weakening the keyword’s role as the stable unit of search measurement. The challenge is not simply finding a replacement metric; it is building a measurement model that remains meaningful when prompts, answers, interfaces, and recommendations can all vary.

    The source material points to two connected shifts. One frames Google AI experiences as part of a move beyond conventional keywords, while the other argues that precise AI share-of-voice percentages can conceal an unstable and unauditable denominator. Together, they suggest that visibility should be evaluated as a set of observable signals rather than compressed into one universal score.

    Keywords remain useful, but no longer define the whole market

    The first source frames Google’s AI-oriented search experience around the prospect of keyword replacement. That framing does not mean keywords immediately become irrelevant. They can still organize demand themes, preserve continuity with historical reporting, and provide repeatable inputs for controlled tests. What changes is their status: a keyword list becomes a sample of possible user needs rather than a complete inventory of the market.

    Traditional keyword measurement assumes that a query can be entered, a result page can be observed, and a position can be recorded. The second source argues that this model has been disrupted by AI summaries, localized results, continuous scrolling, sponsored placements, personalization, and layouts that respond dynamically to intent. A conventional rank can therefore remain technically correct while describing less of the user’s actual experience.

    Prompts make the sampling problem larger. People can express the same need through comparisons, follow-up questions, constraints, use cases, and conversational refinements. Because the possible prompt set has no fixed boundary, no monitored list can claim to represent every relevant interaction. The defensible goal is representative coverage, not exhaustive coverage.

    Why a single AI share-of-voice percentage can mislead

    Unequal glass vessels containing glowing spheres sit on a balance while only one small vessel is fully illuminated.

    According to the second source, traditional share of voice at least used an explicit denominator: a marketer selected a keyword set, observed visibility against competitors, and calculated performance within that defined universe. The method had limitations, but its scope could be inspected.

    The source contends that some AI visibility platforms instead calculate percentage scores from limited prompt sets across services such as ChatGPT, Gemini, Claude, and Perplexity. If users cannot inspect how prompts were selected, how answers were classified, or how platforms and repetitions were weighted, the apparent precision of the percentage exceeds what the method can support.

    This does not make prompt tracking worthless. It changes the claim that the resulting number can sustain. A score derived from a declared prompt panel can describe what happened within that panel. It cannot, by itself, establish a brand’s share of every possible AI-assisted search. Reporting should therefore identify the tested universe, collection method, comparison rules, and limitations beside the result.

    The denominator is only one problem. A binary mention can also flatten materially different outcomes. A brand may appear as an incidental example, a leading recommendation, a warning, or a source citation. Counting all four appearances equally would hide the difference between recognition, commercial preference, reputational risk, and source authority.

    Measure presence, preference, and meaning separately

    Three connected visual layers show a signal across answer surfaces, recommendation paths converging on an option, and a prism revealing multiple facets.

    The second source proposes three alternatives to a universal AI share-of-voice score: share of mentions, share of recommendations, and share of narrative. These are most useful as separate dimensions. Combining them too early would recreate the opacity of the metric they are intended to replace.

    Mentions indicate whether the brand enters the answer

    Share of mentions measures how often a brand appears within a defined test set relative to relevant alternatives. The source connects this visibility to the relationships AI systems form from training material or real-time retrieval sources. Operationally, mention tracking can reveal whether a brand is associated with a topic at all, but it should preserve the prompt category, platform, answer context, and competitors observed.

    Recommendations reveal preference within a buying context

    Share of recommendations narrows the question from “Was the brand named?” to “Was it advised?” The source argues that clear, well-documented market positioning is important here. Recommendation analysis should distinguish a direct endorsement from inclusion in a broad set of options, because those answer forms represent different levels of preference.

    Narrative captures how the brand is characterized

    Share of narrative adds the qualitative layer. The second source notes that frequent visibility can still be harmful when the surrounding portrayal is negative. Narrative review should therefore examine the attributes, use cases, cautions, and comparisons attached to a brand. This is where measurement connects AI search visibility with positioning and reputation management.

    These dimensions answer different business questions. Mentions indicate conceptual presence, recommendations indicate preference, and narrative indicates meaning. None should automatically substitute for outcomes such as qualified visits or conversions; those belong in a separate performance layer when reliable data is available.

    Key takeaways

    • Use keywords as controlled samples of demand, not as a complete map of AI-assisted discovery.
    • Treat an AI visibility percentage as a result for a declared prompt panel unless its broader denominator can be audited.
    • Report mentions, recommendations, and narrative separately so that recognition is not confused with preference or reputation.
    • Preserve prompts, platforms, repetitions, classification rules, and collection conditions so changes can be interpreted.
    • Connect visibility signals to business outcomes without implying that a mention alone caused traffic, leads, or revenue.

    Build a measurement system that can be challenged

    A credible program begins by defining the decision it must support. Brand teams may need to understand how the market is described, search teams may need to assess discovery coverage, and commercial teams may care about recommendation frequency. Each purpose requires a different mix of prompts and a different interpretation of success.

    The monitored prompt set should then be grouped by user need, such as discovery, comparison, evaluation, or problem solving. The exact groups will vary by organization; what matters is that the selection logic is documented. Fixed prompts provide comparability over time, while a separately labeled exploratory sample can surface emerging language without silently changing the benchmark.

    Collection should retain enough context to reproduce or audit an observation: the prompt, platform, answer, collection condition, brand appearances, recommendation status, narrative classification, and any cited sources. Repetition can expose variability, but the reporting should show that variability rather than smoothing it into unwarranted certainty.

    Competitive comparisons should use the same prompt panel and classification rules for every brand. Results can then be reported as observed rates within that explicit sample. This language is more limited than claiming a universal market share, but it gives leadership a number whose boundaries can be understood.

    Finally, AI visibility should sit beside conventional search and business evidence rather than replace them. Keyword trends can preserve historical context; mention, recommendation, and narrative measures can describe answer-level presence; outcome data can show whether observable demand followed. The next generation of search measurement will become more useful as it becomes more transparent about what was tested, what changed, and what remains unknown.

    References

  • How Bot Traffic Changes AI Search Visibility Measurement

    How Bot Traffic Changes AI Search Visibility Measurement

    AI is changing web visibility in two directions at once: answer systems can influence buyers without sending a visit, while automated agents can generate large volumes of requests without producing human attention. The result is a widening gap between what traffic logs record and what marketing teams actually need to understand.

    Bringing these developments together reveals a practical lesson: request volume, human engagement, and market influence must be measured as separate layers. A useful visibility model then reconnects those layers without treating any single signal as proof of AI-driven demand.

    More web requests do not necessarily mean a larger audience

    The clearest warning against equating traffic with attention comes from the bot data. The CrushPress.AI article on automated web requests reports, based on figures shared by Cloudflare CEO Matthew Prince, that bots accounted for 57.3% of global HTTP requests for HTML content, compared with 42.7% from humans. It also says this crossed a threshold Prince had predicted during SXSW would be reached by early 2027.

    Those percentages describe requests, not unique visitors, reading time, purchasing intent, or revenue. That distinction becomes especially important in an agentic browsing environment. As the article explains, a person shopping online might inspect a small number of pages, whereas an AI agent could request thousands while researching on the person’s behalf. The activity is real at the infrastructure level, but it does not create thousands of human opportunities to view advertising or engage with a page.

    This creates a measurement paradox. A site can receive more machine activity while seeing little corresponding improvement in human sessions or commercial outcomes. Publishers and brands therefore need to classify automated requests before using raw traffic trends to judge reach, content performance, or audience growth.

    AI can create influence while removing the observable visit

    The attribution problem is the mirror image of the bot-traffic problem. Automated systems may produce requests that overstate apparent audience activity, yet AI-generated answers may also create genuine brand influence that website analytics fail to capture.

    The CrushPress.AI article on AI search visibility describes prospects using tools such as ChatGPT or Google’s AI Overviews to discover vendors, compare alternatives, and form a shortlist before visiting any company website. A brand can appear in recommendations, comparisons, citations, or generated responses throughout that research. If the prospect later arrives through a branded query or a direct visit, conventional analytics may record only that final, deceptively simple step.

    This extends the zero-click pattern already associated with search features such as snippets, knowledge panels, and local packs. Generative answers can compress more of the research process into the search or assistant interface, making the missing click more consequential: discovery and evaluation can both occur before the measurable session begins.

    The combined implication is that low referral traffic does not necessarily mean low AI influence, just as high request volume does not necessarily mean high human interest. One metric can undercount the role of AI in a buying journey while another can overstate the audience that AI activity represents.

    A layered measurement model separates activity from impact

    Three connected transparent layers depict automated requests, human engagement, and broader influence as separate forms of measurement.

    A more useful model starts by distinguishing three questions. The first is whether machines are accessing the site. The second is whether people are arriving and engaging. The third is whether AI systems are shaping awareness or consideration before those visits. Keeping the questions separate prevents request logs, referral reports, and brand indicators from being collapsed into a single ambiguous traffic number.

    At the machine-activity layer, teams can examine bot identification and request patterns to determine how much recorded activity is automated. This layer helps explain infrastructure demand and content access, but it should not be presented as audience reach without supporting evidence of human engagement.

    At the human-behavior layer, traditional analytics remain useful for sessions, engagement, assisted conversions, and conversion paths. The AI search visibility article specifically identifies assisted conversions as a way to detect channels that contributed before the final interaction. These reports remain incomplete when an AI exposure sends no detectable referral, but they still show how observable touchpoints work together.

    At the influence layer, the same article proposes watching branded search growth, direct traffic trends, and brand appearances within AI prompts and recommendations. None is conclusive alone. Branded searches can have several causes, direct traffic is an imprecise category, and an AI mention does not prove that it affected a purchase. Read together over time, however, these signals can support a more credible account of how awareness and consideration are developing.

    The strongest interpretation comes from convergence. Repeated AI visibility followed by growth in branded demand, relevant human engagement, and assisted or completed conversions presents a more meaningful pattern than any isolated spike. This is an inference framework rather than person-level attribution: it indicates probable influence without claiming to reconstruct every buyer’s path.

    Key takeaways

    • Bot request share measures automated access, not the size or quality of a human audience.
    • AI-generated answers can influence discovery and vendor evaluation without producing a referral click.
    • Direct visits and branded searches may be downstream signs of earlier AI exposure, but neither proves causation by itself.
    • AI visibility measurement should combine machine-activity data, human engagement, conversion evidence, and brand-demand signals.
    • Trends that move together are more informative than a single traffic, mention, or attribution metric.

    Visibility strategy must serve machines and people differently

    An abstract AI agent and a person access the same central web content through different structured and visual pathways.

    The growth of automated access gives brands a reason to make content clear, authoritative, and interpretable by AI systems, as the bot-traffic article argues. But machine readability is not an end in itself. The commercial objective is still to help a person discover, evaluate, trust, and eventually choose the brand.

    Reporting should reflect that distinction. Bot requests belong in an access and infrastructure view; human sessions belong in an engagement view; AI mentions and branded-demand indicators belong in an influence view; conversions remain the outcome view. Connecting these views can reveal useful relationships, but labeling them separately limits false precision.

    As AI agents assume more browsing and answer engines absorb more research, the most resilient measurement programs will track both sides of the exchange: how machines consume content and how people reveal the effects later.

    References

  • How to Measure AI Search Visibility, Traffic, and Value

    How to Measure AI Search Visibility, Traffic, and Value

    You can see organic impressions rising, spot visits from an AI assistant, and still have no defensible answer when someone asks whether AI search is helping the business. The problem is rarely missing data. It is treating visibility, visits, and outcomes as if they were the same thing.

    You need an evidence chain. Search Console shows where discovery may be changing. GA4 shows what identifiable visitors do. Google Tag Manager can add section-level context. Used together, they turn an ambiguous channel into something you can manage.

    Key takeaways

    • Measure AI visibility, traffic, engagement, and business outcomes separately.
    • Use Search Console for query and page trends, but do not label every organic change as an AI effect.
    • Use GA4 to evaluate identifiable AI referrals, Google organic landings, engagement, and key events.
    • Use GTM text-fragment tracking as supporting evidence that visitors are arriving at specific passages, not as proof of an AI citation.

    Start with the questions your data can answer

    A useful measurement plan starts with business questions, not a dashboard labeled “AI traffic.” The practical shift is to make AI search part of your broader search program because it can change how people discover and evaluate answers, even when the eventual visit resembles ordinary organic traffic.

    QuestionSignal to inspectPrimary toolDecision it supports
    Are relevant pages becoming easier to discover?Impressions and clicks for stable query groups and landing pagesGoogle Search ConsoleWhether to strengthen topic coverage, answer clarity, or search-result appeal
    Are identifiable AI services sending visits?Sessions grouped by referral source and landing pageGA4Which sources and pages deserve closer attention
    Do those visits show useful engagement?Engagement and navigation after the landing pageGA4Whether the page satisfies the apparent intent and offers a sensible next step
    Are visitors being sent to a particular passage?A text-fragment landing event tied to a stable section labelGTM and GA4Which answer blocks should be maintained, expanded, or connected to deeper content
    Does the activity create business value?Relevant key events or conversions by source and landing pageGA4Whether visibility is contributing to a meaningful outcome

    Keep these signals in separate columns. Search Console clicks and GA4 sessions come from different measurement systems, so forcing them to reconcile can create false confidence. Their job is to corroborate a pattern, not produce an identical total.

    There is another important boundary: an AI-generated answer can expose your brand without producing a click. A traffic-only report misses that possibility. A visibility-only report, meanwhile, cannot tell you whether the exposure helped the business. Your dashboard needs both, with the limitation stated plainly.

    Configure Search Console, GA4, and GTM as one evidence stack

    Three connected measurement instruments represent search discovery, visitor journeys, and section-level event tracking.

    Use Search Console to establish the discovery baseline

    Begin with query-and-page pairs rather than sitewide totals. Group queries by intent, such as branded questions, informational problems, comparisons, and decision-stage searches. Keep each group’s definition stable so a later movement reflects the data rather than a changing filter.

    For every group, retain impressions, clicks, click-through rate, average position, and the landing pages receiving visibility. Add an annotation whenever you materially revise an answer, heading, structured content block, title, or internal link. Compare the same group across consistent reporting windows and check whether the affected pages moved in the expected direction.

    This is evidence of changing search performance, not automatic proof that an AI Overview caused the change. Search Console query analysis can help you investigate the impact of AI-driven discovery, but you still need landing-page and engagement evidence before making a stronger attribution claim.

    Use GA4 to separate arrival from value

    Create a reporting view for recognizable AI-assistant referrals. Maintain the source rule explicitly and record when you change it; otherwise, a larger referral list can masquerade as traffic growth. Report the original source alongside landing page, engagement, useful downstream navigation, and the key event that represents value for your site.

    Keep Google organic traffic in its own segment. A visit that began around an AI feature on a Google results page may still appear as Google organic rather than carry a clean feature label. That makes the landing page, associated Search Console query trend, and on-page behavior more useful than the channel name alone.

    Choose outcomes that match the page’s purpose. A documentation page may be expected to lead to another help resource. A commercial page may be expected to produce a qualified inquiry or purchase-related action. If you apply the same conversion expectation to every content type, useful informational visits can look like failures and weak commercial visits can look healthier than they are.

    Add section-level context with text fragments

    Text fragments can open a page at a specific passage. GTM can detect that kind of landing and send a custom event to GA4. Use a clear event name, attach the page path and a stable section identifier, and classify the referrer when it is available.

    Do not send the literal highlighted text as an analytics parameter. It can create noisy, high-cardinality data and may capture words you do not want stored. Map the arrival to a controlled label such as the section’s internal identifier instead.

    Test the trigger in GTM preview mode, confirm the event in GA4’s debugging view, and then verify that the live event carries the expected page and section labels. A text-fragment event only tells you that a targeted passage was opened. Treat it as corroborating evidence when it aligns with query visibility, a plausible referrer, and meaningful behavior.

    Read patterns without claiming more than the data proves

    Visibility rises while clicks stay flat

    Your page may be appearing for more searches without giving people a reason to continue. It may also be losing clicks for reasons unrelated to AI. Inspect the affected queries and search results before changing the page. If the page already answers the immediate question, make the next value clear: a decision framework, working example, template, calculator, or deeper explanation. Do not weaken the answer merely to manufacture a click.

    Traffic rises while useful outcomes stay flat

    Check whether the landing page matches the intent implied by its query or referral context. Then inspect the path after arrival. A strong answer with no relevant next step can earn attention without moving the visitor forward. Add a specific internal link or call to action beside the passage that resolves the initial question, and measure that action separately from generic page engagement.

    Text-fragment arrivals concentrate on one section

    Treat that section as a content asset. Give it a descriptive heading, keep its central answer self-contained, remove references that make no sense out of context, and place the most relevant deeper resource nearby. Watch whether later edits preserve fragment arrivals and downstream behavior. The event is a prioritization signal, not proof that every visit came from an AI answer.

    AI referrals appear without a matching Search Console change

    The visits may originate outside Google, or your referral grouping may be too broad. Validate the source values and landing pages before connecting the movement to search visibility. If the visits are legitimate, evaluate their behavior on their own terms rather than expecting Search Console to explain a different discovery surface.

    Turn the dashboard into an optimization workflow

    An analyst reviews an abstract dashboard beside a circular sequence of investigation, optimization, testing, and measurement steps.

    For each priority query group and landing-page family, record the visibility signal, arrival signal, engagement signal, business outcome, material content change, interpretation, confidence, and next action. This format forces you to distinguish an observation from an explanation.

    A defensible note might say that impressions increased after an answer block was revised, while clicks and qualified actions did not move in the same direction. That supports further inspection of search-result appeal and the page’s next step. It does not support a claim that AI visibility generated revenue.

    Use the weakest part of the chain to choose the work. Weak discovery calls for better intent coverage and clearer answer structure. Strong visibility with weak arrival calls for a more compelling continuation. Strong arrival with weak outcomes calls for closer intent alignment and a better next action. Concentrated fragment landings call for maintaining and extending the section people are being sent to.

    Start with your highest-priority query cluster and its landing-page family. Establish the baseline, confirm the instrumentation, annotate the next meaningful change, and wait for the full evidence chain before declaring success. You will get a smaller headline than an all-purpose “AI traffic” number, but a far more useful decision.

    References

  • Conversion Signal Decay: How to Protect Funnel Performance

    Conversion Signal Decay: How to Protect Funnel Performance

    Your sales may be intact even when an ad platform’s conversion column is falling. If you respond by cutting discovery campaigns, you can turn a measurement problem into a real acquisition problem.

    Before you change bids, creative, or budget, find out whether the funnel is losing customers or merely losing the signals that connect customers to earlier touchpoints. The repair is not one tracking feature. It is a cleaner chain from first interaction to verified business outcome.

    Why discovery campaigns lose credit first

    A conversion signal is the information your measurement and advertising systems receive about an action: a purchase, a qualified lead, a phone sale, or an earlier behavior that indicates progress. Signal decay occurs when that information is blocked, separated from the originating interaction, delayed, or reduced to a weaker proxy.

    The problem is most visible near the top of the funnel. Someone can watch a YouTube ad on a television, search for the brand on a phone, and buy on a desktop days later. Another person can see the same campaign and complete an expensive purchase by phone. Standard cookie-based measurement may fail to connect either outcome to the discovery touchpoint.

    YouTube is particularly exposed because it often introduces the brand rather than closing the transaction. Google’s research identifies it as the leading platform viewers use to research, evaluate, or decide on brands and products, yet many of the resulting purchases happen elsewhere.

    This creates a dangerous sequence. The platform observes fewer conversions than the business actually received. Discovery appears inefficient, so its budget is cut. Fewer new prospects enter the funnel, reported conversion volume falls again, and automated bidding has less useful information from which to learn. What began as missing attribution eventually becomes a genuine demand problem.

    That does not mean every weak upper-funnel campaign is secretly effective. It means an attribution gap is not evidence of effectiveness or ineffectiveness. You need to repair and validate the signal path before using platform reports to make that decision.

    Audit the four places where conversion signals break

    An analyst inspects four distinct breaks along a modular measurement chain carrying glowing signals toward a completed purchase parcel.

    Start at the verified outcome and work backward. For each purchase or qualified lead, ask what identifier connects it to the site session, the lead record, and the originating campaign. The clues below help you decide which repair belongs in your measurement plan.

    Signal breakWhat you are likely to noticeMost relevant repair
    Cross-device journeyThe interaction and transaction occur on different devices, leaving purchases disconnected from earlier exposure.Enhanced conversions using hashed first-party identifiers.
    Offline outcomeThe platform records a form submission or call but cannot tell which leads became customers.Offline conversion imports from the CRM or call workflow.
    Low upper-funnel volumePurchase events are too sparse to give automated bidding timely feedback.Carefully selected micro conversions that represent real progress.
    Browser or tag lossEligible purchases exist in internal systems, but some web conversion events never reach the advertising platform.Tag validation followed, where appropriate, by Google Tag Gateway.

    These breaks can coexist. Enhanced conversions may improve cross-device matching without recovering a sale completed by phone. An offline import may report that sale while doing nothing about a blocked browser event. Google Tag Gateway may recover more event delivery but cannot tell you whether a submitted lead was valuable.

    Treat the table as a routing tool, not a diagnosis. A difference between internal orders and platform conversions can also reflect attribution eligibility, reporting settings, duplicates, timing, or implementation errors. Reconcile those definitions before assuming privacy restrictions caused the entire gap.

    Rebuild the signal chain in the right order

    The order matters. If you send more events before deciding which outcomes deserve optimization weight, you can give an algorithm a larger quantity of lower-quality data.

    1. Define the outcome hierarchy. Mark revenue, completed purchases, or closed customers as primary business outcomes. Put qualified leads beneath them when sales happen later. Treat engagement behaviors as secondary evidence. A video view, a form submission, and a completed sale should not enter bidding as if they were economically equivalent.
    2. Reconcile the existing path before adding technology. Compare the events generated by the site with backend orders, then compare sent events or imports with what the platform received. Use matching definitions and periods. This separates event-generation failures from transmission failures and attribution differences.
    3. Add enhanced conversions for cross-device matching. Enhanced conversions supplement the normal conversion tag with hashed first-party information, such as an email address. Google can use the hashed data to connect an eligible conversion with an earlier ad interaction that cookie-based tagging missed. Hashing is a matching safeguard, not permission to collect or use personal data; keep the implementation within your applicable consent and privacy requirements.
    4. Import offline outcomes from the system that knows what happened. Preserve a consistent connection between the originating lead and its later CRM or call-center status. Send the outcome that matters – qualified, closed, purchased, or associated revenue – instead of stopping at the form completion. This lets bidding learn from customers rather than merely from people who submit forms.
    5. Introduce micro conversions only when primary outcomes are too sparse. Useful candidates can include a meaningful video view, an add-to-cart action, or sustained on-site engagement. Choose the action closest to the campaign’s role in the funnel, and keep it visibly separate from the primary conversion. If an easy engagement event becomes the main objective, the system may produce more of that behavior without producing more customers.
    6. Evaluate Google Tag Gateway after the base implementation is sound. The gateway uses a first-party path on your domain to load Google tags, which can recover some signals affected by browser restrictions. It can be especially practical on sites using a compatible content delivery network such as Cloudflare. It should strengthen a correct tag setup, not conceal a broken one.
    7. Test for duplication, delay, and value errors. Confirm that the same transaction cannot arrive once through a web tag and again through an offline import without deduplication. Check that values, statuses, and timestamps retain their intended meaning. A larger conversion count is not an improvement if it is caused by double counting.

    Roll out one major signal change at a time where practical, and annotate its launch date. If enhanced conversions, a new bidding strategy, and a budget increase all begin together, you will not know whether a reported improvement came from recovered attribution, algorithmic optimization, or added media spend.

    Judge recovered performance without mistaking attribution for growth

    Parallel channels show attribution signals becoming complete while customer and purchase volume stays steady, followed by a separate branch where both genuinely increase.

    A measurement repair can raise platform-reported conversions even when total revenue has not changed. That first jump may be legitimate signal recovery: the platform can now see outcomes that were already occurring. It becomes business growth only when verified revenue, customer acquisition, lead quality, or another primary outcome improves.

    Review four layers separately:

    • Delivery: Did the intended web and offline events reach the platform, with fewer unexplained gaps?
    • Quality: Are imported outcomes tied to purchases, revenue, qualified leads, or closed customers rather than inflated by low-intent actions?
    • Attribution: Did more verified outcomes become associated with cross-device or upper-funnel interactions?
    • Business performance: After bidding has had a relevant decision cycle to use the improved data, did the economics of acquisition improve in your internal records?

    Keep attribution settings, campaign scope, and outcome definitions consistent during a before-and-after comparison. If you change the measurement window or redefine a conversion at the same time, a reporting increase cannot be cleanly attributed to better signal capture.

    Large undercounts are possible, but you should not borrow someone else’s correction factor. Haus Research found that Google’s advertising tools underreported YouTube’s impact by 70% or more in its measurement work. That result shows why an audit can materially change a channel decision; it does not justify multiplying every advertiser’s YouTube conversions by the same amount.

    The same caution applies to infrastructure benchmarks. Google reports an 11% signal uplift for Google Tag Gateway users compared with advertisers not using the technology. Treat that as a vendor-reported benchmark, not a guaranteed result for your site. Your implementation should be judged against your own eligible events, verified outcomes, and acquisition economics.

    Recovered attribution also does not prove incrementality. A channel can receive more accurate credit for a sale without having caused an additional sale. Use restored signal data to improve reporting and bidding, but keep the causal question separate when deciding how much budget the channel deserves.

    Key takeaways

    • A falling platform conversion count can represent signal loss, a real funnel decline, or both; verify the signal path before cutting discovery spend.
    • Use enhanced conversions for cross-device gaps, offline imports for CRM and call outcomes, micro conversions for sparse feedback, and Google Tag Gateway for eligible tag-delivery loss.
    • Optimize toward the deepest reliable business outcome. Do not give an engagement event the same status as revenue.
    • Measure signal delivery, outcome quality, attribution recovery, and business growth as separate layers.
    • Do not apply a published undercount or uplift percentage as a universal correction factor. Establish the gap in your own funnel.

    Choose one high-value journey – for example, YouTube exposure to website visit to CRM sale – and map every handoff from interaction to verified outcome. Repair the first place where the identity or outcome disappears, validate it, and then move to the next break. That sequence gives you a defensible basis for the next budget decision instead of another guess based on a decaying signal.

    References

  • Boost Team Efficiency: Overcome GTM Barriers with Storyblok

    Boost Team Efficiency: Overcome GTM Barriers with Storyblok

    I’ve recently stumbled upon some fascinating global research data that highlights a tech gap silently draining team speed, revenues, and competitive edge. The Storyblok Global Speed-to-Market Benchmark Report explores these issues comprehensively.

    This rapidly evolving world demands a new pace, driven by cutting-edge AI and technology, and constant shifts in digital trends have redefined how we handle go-to-market (GTM) strategies.

    In today’s marketplace, everyone, from customers to organizations, expects top-notch deliveries with speed. Unfortunately, only 22.5% of teams consistently meet these soaring speed-to-market expectations, revealing a disconcerting gap between ambition and actualization.

    One might ask, what’s holding us back?

    The Global Speed-to-Market Benchmark survey involved several GTM teams who shared insights on where processes are stalling or facing delays and what steps would truly improve speed-to-market in today’s fast-paced business environment.

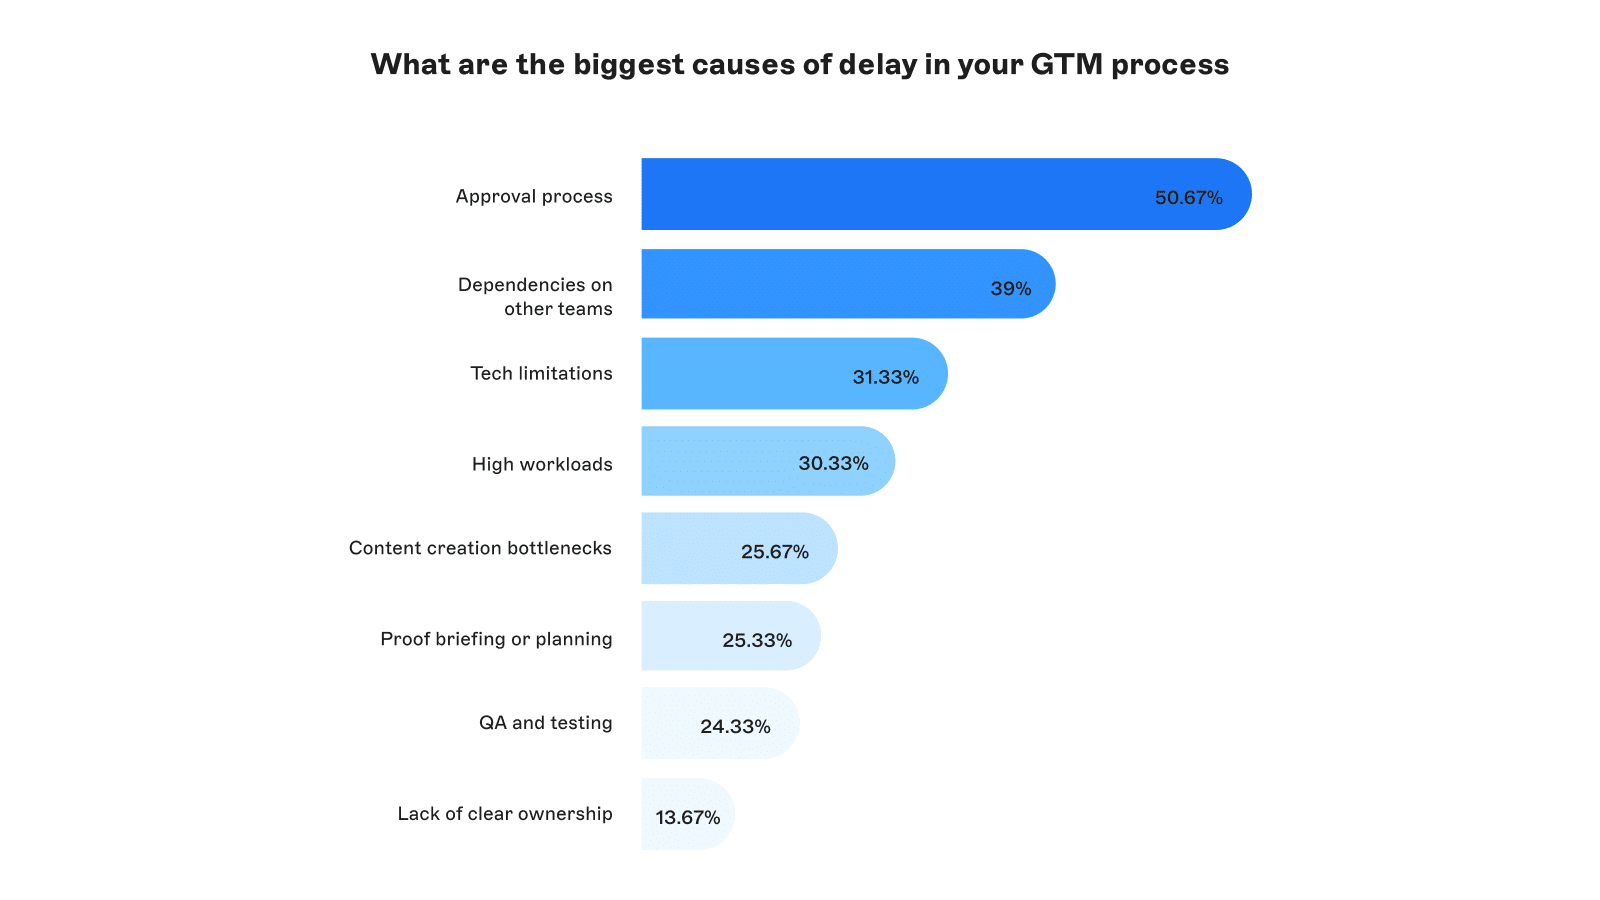
    The survey uncovered four significant bottlenecks largely tied back to technological hiccups or dependencies. The approval process, for instance, emerged as the most substantial bottleneck, with over 50% of teams identifying it as a major hurdle. This includes enduring multiple rounds of content revisions largely driven by disorganized feedback systems, exacerbating inefficiencies.

    The practical solution? A well-configured CMS, particularly a headless one, allows for an organized and efficient content review process by decoupling content from presentation. This ensures stakeholders have access to a central content repository, thereby minimizing review confusion and delays.

    Equally problematic is the overreliance on developers, where 38% of teams require developer input for most GTM operations. This not only slows marketers but also distracts developers from more critical tasks. A modern tech stack enabling team autonomy can mitigate this issue, allowing each team to concentrate on their core functions.

    ```json
{
  "alt": "Bar chart showing biggest causes of delay in GTM processes, with approval process at 50.67% as the top cause.",
  "caption": "Discover what's slowing down your GTM process. Approval processes top the list at over 50%, impacting efficiency and timelines.",
  "description": "This image features a horizontal bar chart highlighting the primary reasons for delays in go-to-market (GTM) processes. Leading the chart is the approval process, causing 50.67% of delays. Following are dependencies on other teams at 39%, tech limitations at 31.33%, and high workloads at 30.33%. Additional factors include content creation bottlenecks, proof briefing, QA and testing, and lack of clear ownership. This breakdown provides insight into operational challenges within marketing strategies. Keywords: GTM process, delay causes, approval process, marketing efficiency."
}
```

    Moreover, compounding tech limitations, including complex deployment and outdated systems, further warrant an overhaul. Tech bottlenecks often operate silently, but they demand attention and timely solutions for improved GTM cycles.

    I also noticed how post-launch firefighting issues are rampant, affecting 79% of teams. This inefficiency stems from fragmented systems, where constant developer intervention is necessary, further delaying launch processes.

    Addressing these challenges involves refining the tech stack, especially choosing a CMS that aligns with modern delivery needs. This results in smoother launches, improved efficiency, and fewer post-launch issues.

    The cost of slow GTM delivery is undeniable, leading to lost revenue and missed market opportunities, while also impacting team morale and increasing turnover risks. Interestingly, there’s a visible discrepancy between executive priorities and the requisite support for improved speed-to-market capabilities.

    Armed with data, teams can make a compelling business case for change, drawing attention to specific bottlenecks and their ramifications, thus bridging the leadership alignment gap.

    Overall, overcoming GTM challenges requires adopting adaptive technology stacks that align with today’s fast-paced demands. By doing so, we not only keep up with competition but also foster a resilient, engaged team poised for success.

    For the complete analysis and strategies, the full Storyblok Global Speed-to-Market Benchmark Report is an invaluable resource.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot