AI assistants may be software, but the people using them still follow schedules. That creates patterns in when AI tools attract attention, answer questions, and influence decisions.
Try Profound Blog offers one central observation: every AI assistant has a daily and weekly rhythm, but that rhythm varies by platform, region, and user. The source does not provide supporting measurements, so the useful takeaway is a framework for investigation rather than a universal timetable.
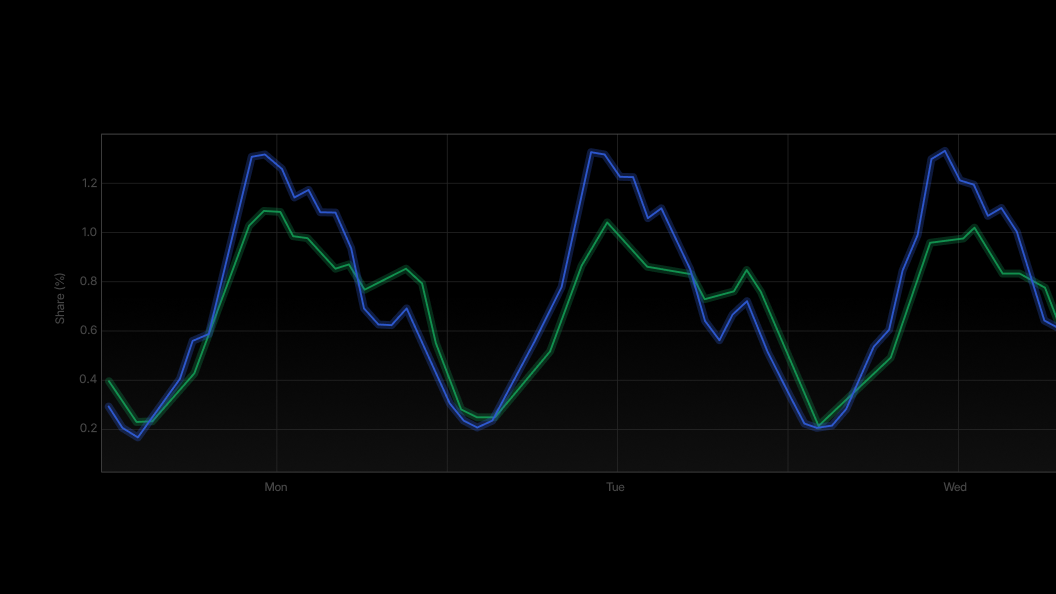
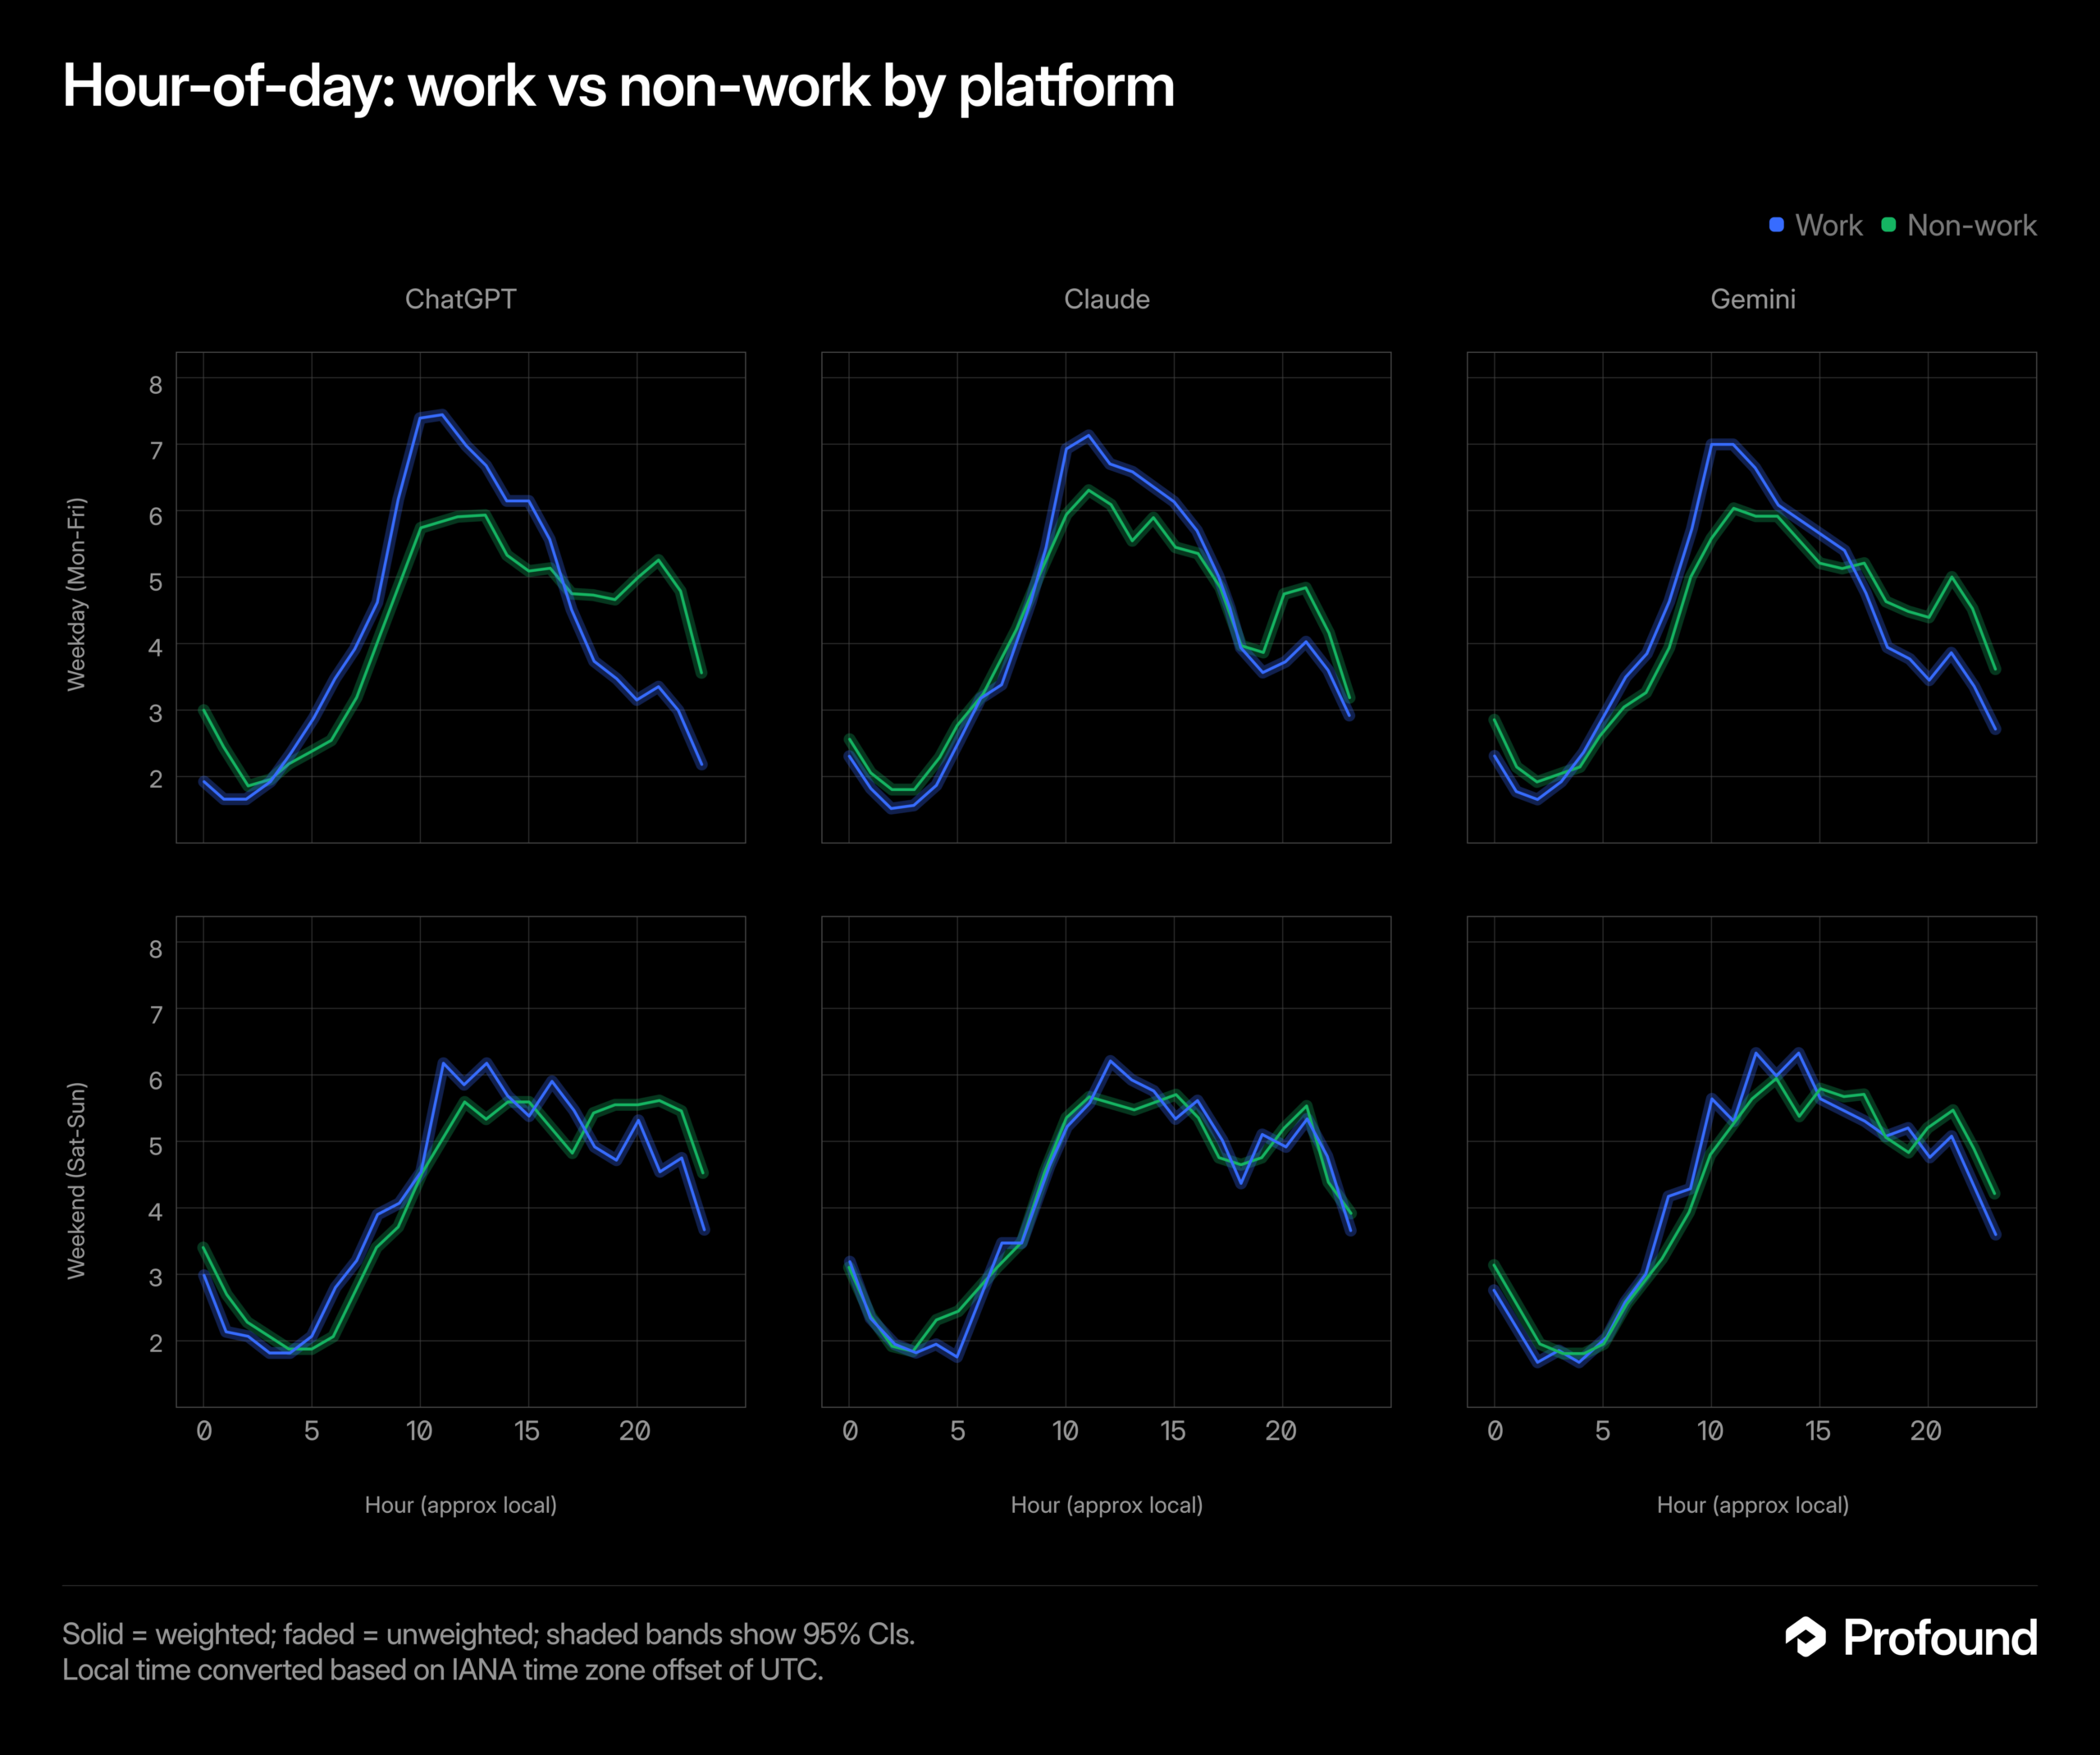
Blue work and green non-work lines show hourly patterns for ChatGPT, Claude, and Gemini, split into weekday and weekend rows, with most curves highest around late morning to afternoon.
The rhythm belongs to usage, not the assistant
An AI system does not begin a workday in the human sense. Any apparent schedule is more likely to reflect when people open a platform, what they use it for, and how it fits into their routines.
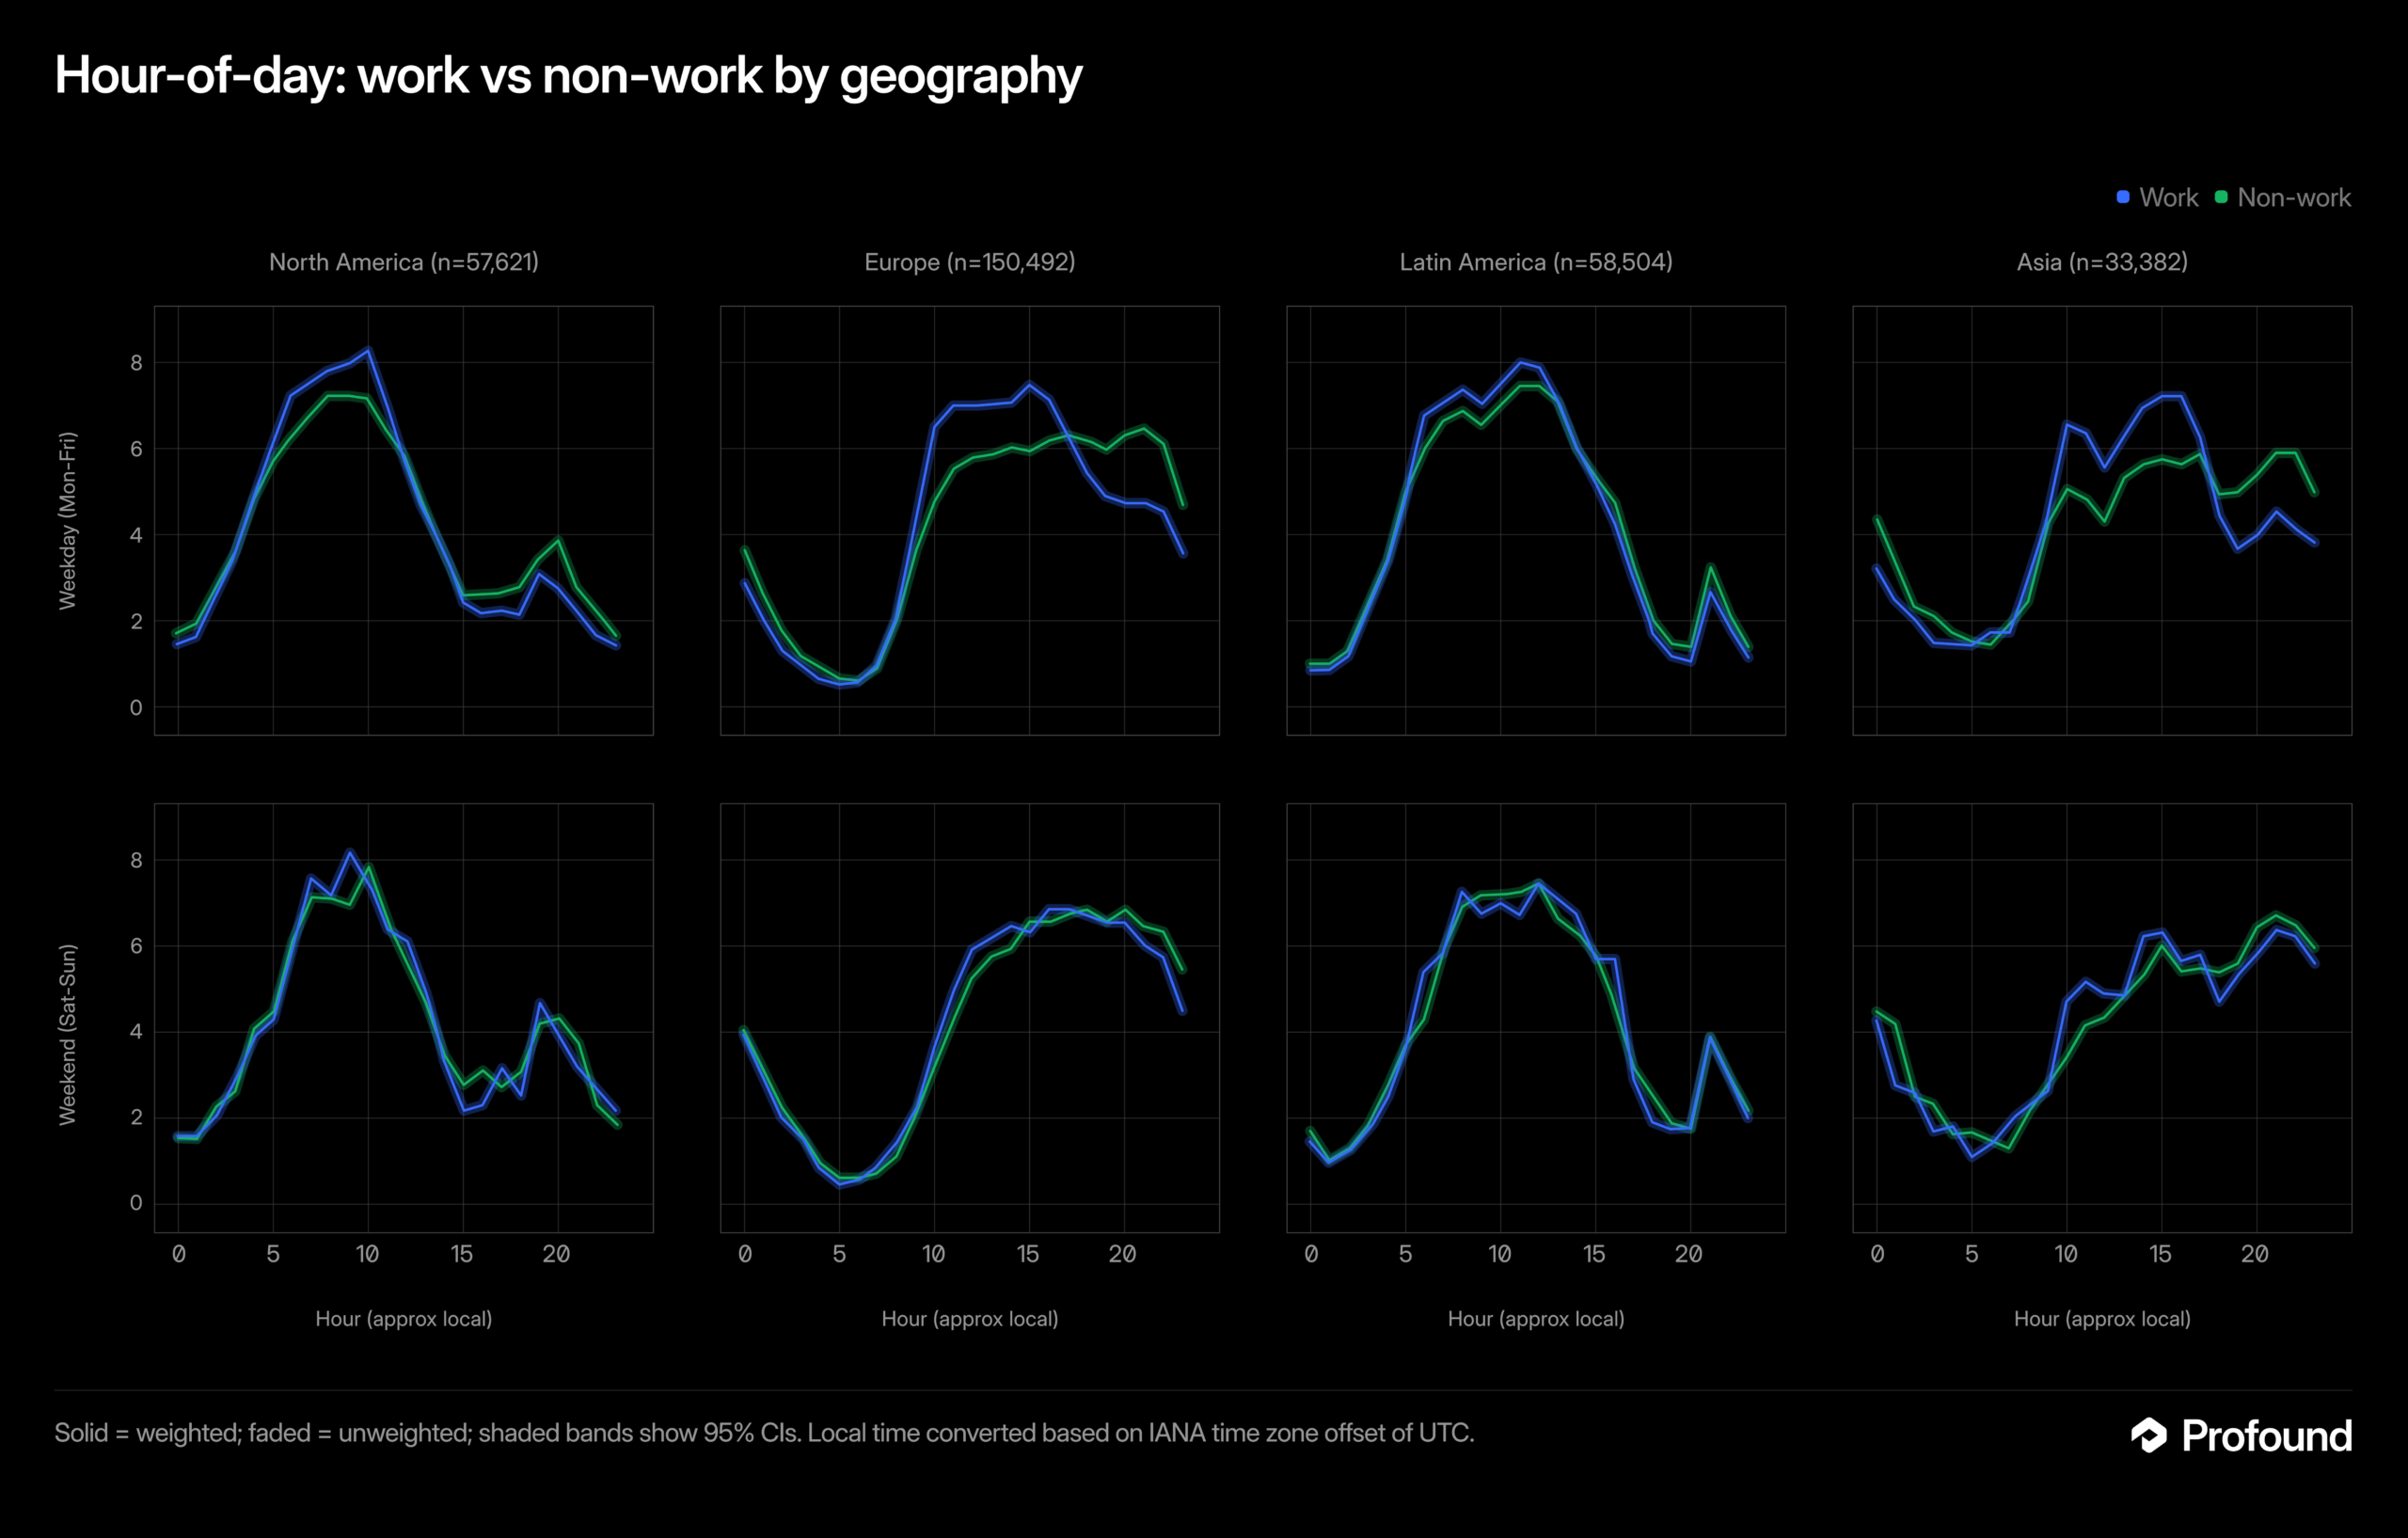
Blue work and green non-work lines trace hour-of-day patterns for North America, Europe, Latin America and Asia, split into weekday and weekend rows.
A tool associated with professional tasks may see a different pattern from one used for personal questions. The distinction matters because a broad label such as “AI traffic” can hide meaningful differences among audiences and use cases.
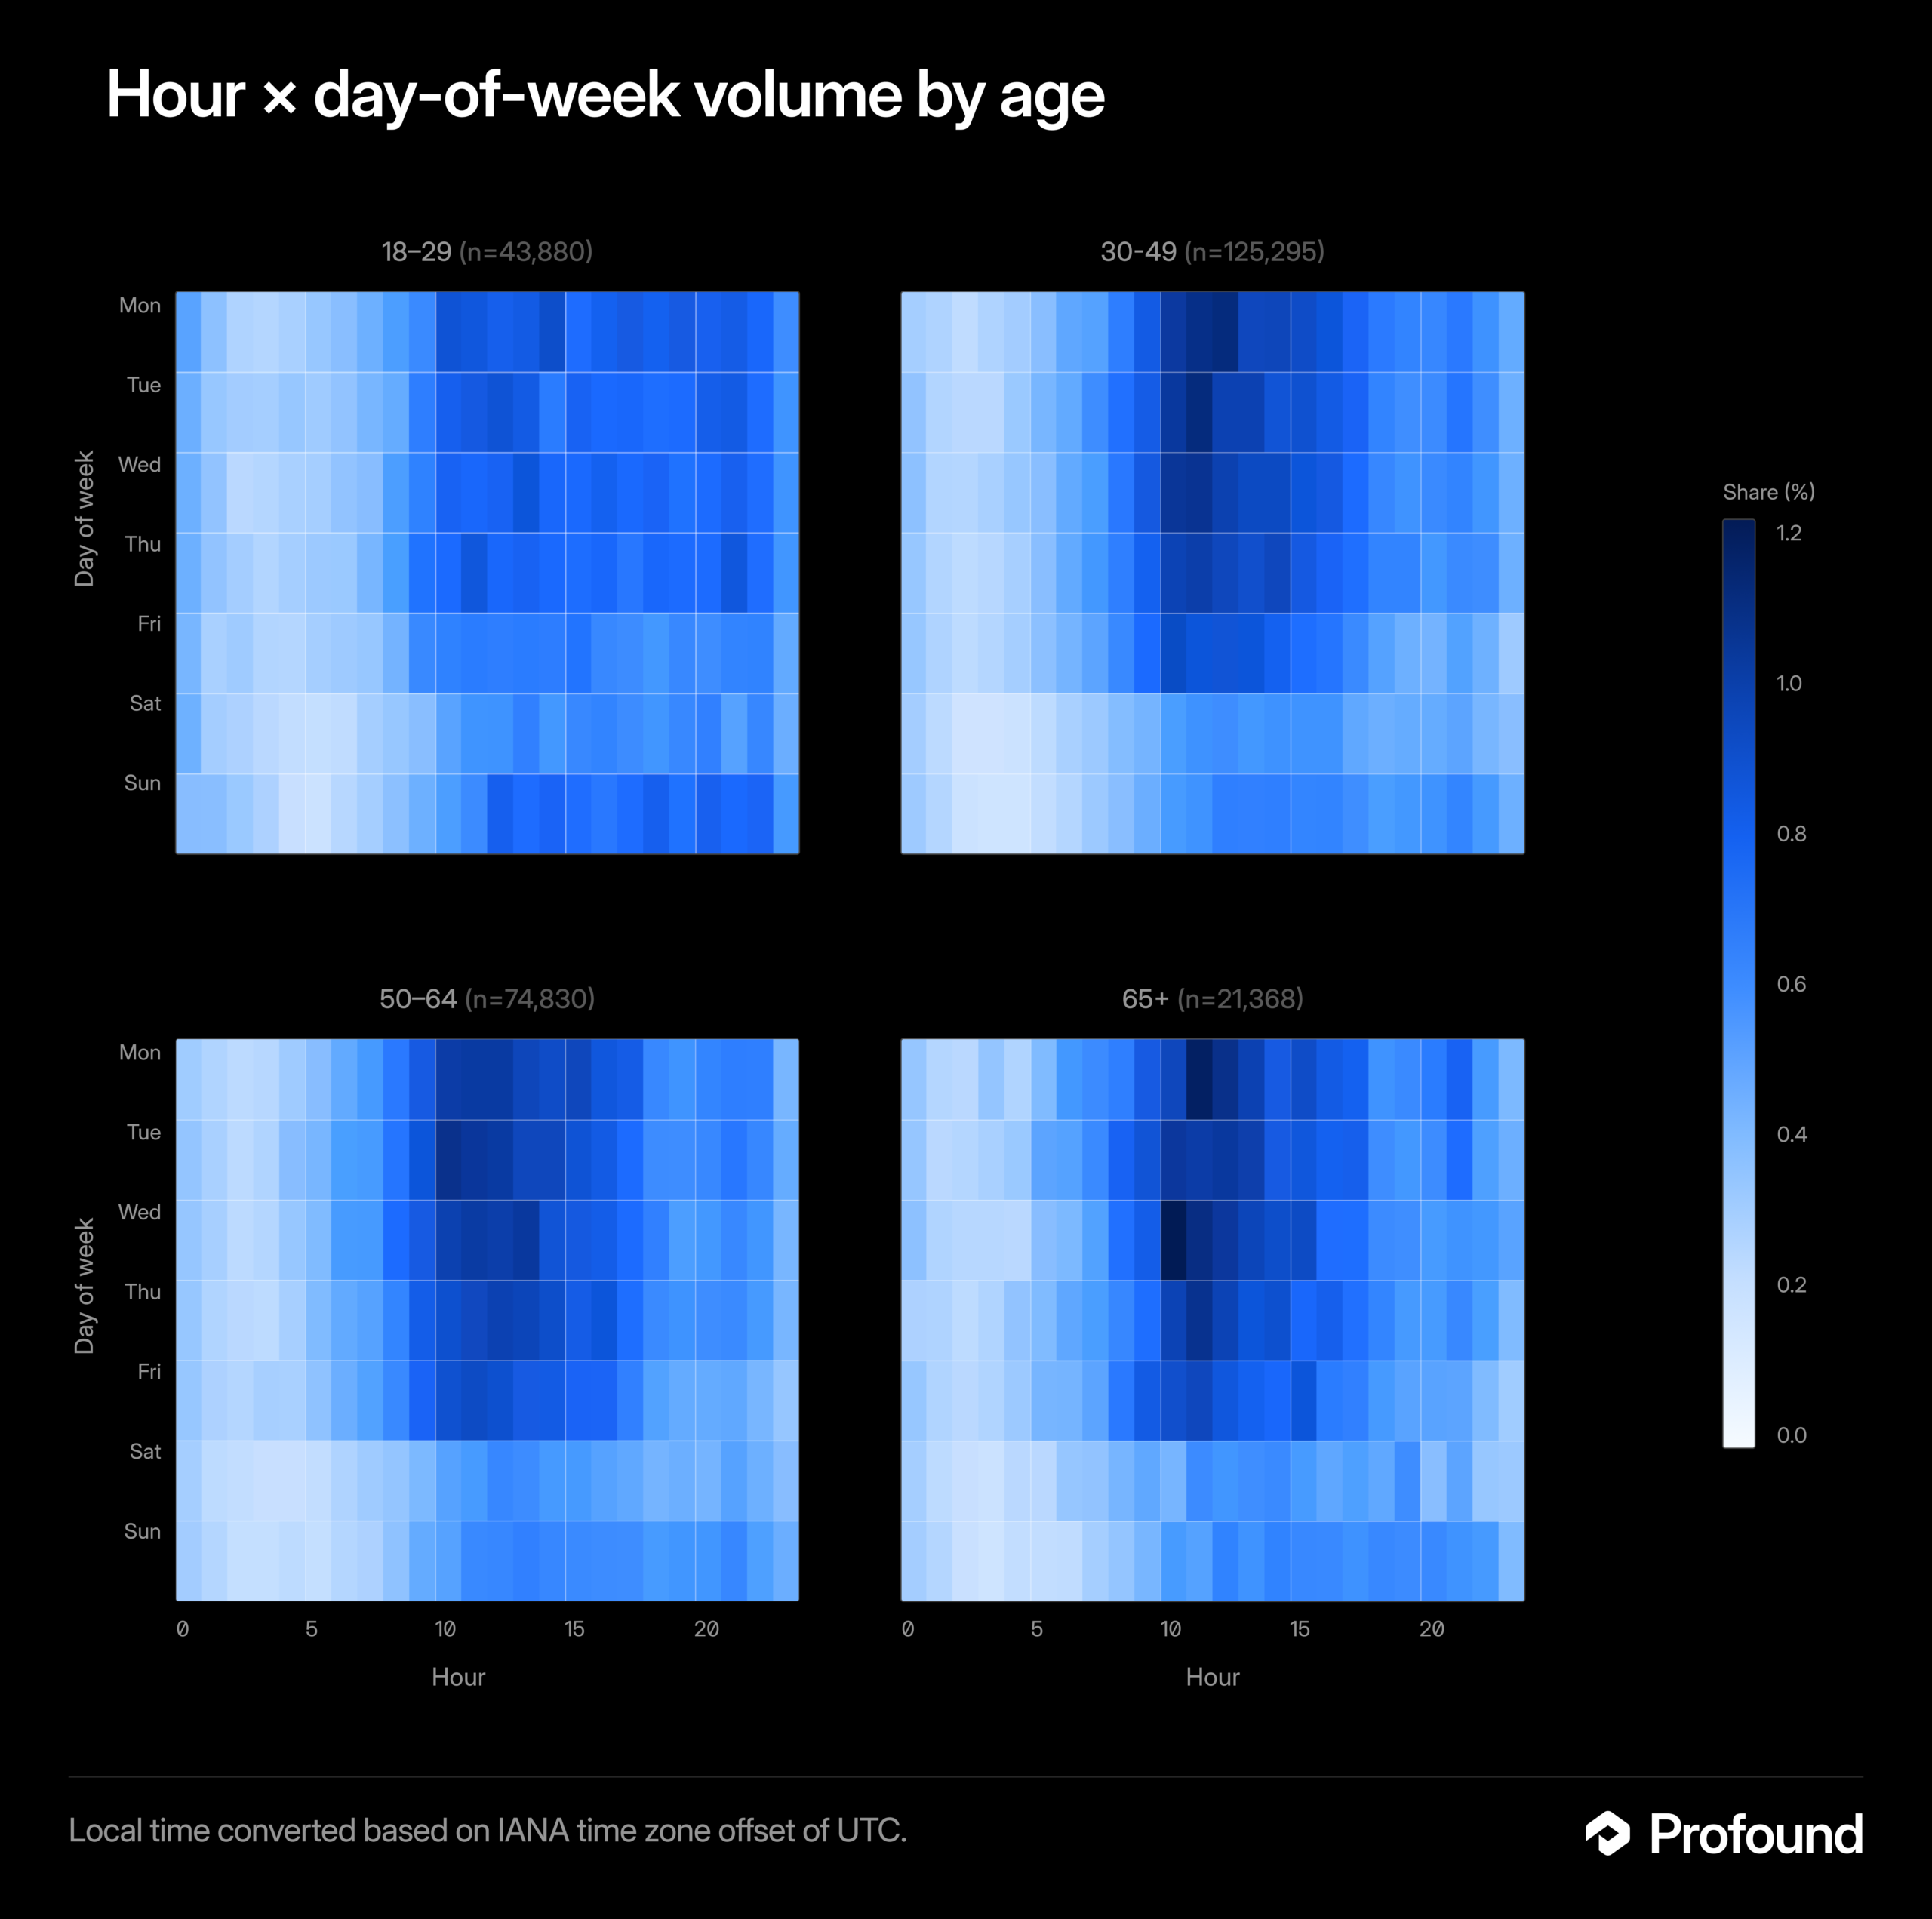
Four heatmaps plot share by hour and day of week for ages 18-29, 30-49, 50-64 and 65+, with the darkest weekday bands around late morning.
Why one schedule cannot describe every audience
The source specifically cautions that timing is not consistent across platforms, regions, or users. Each dimension can change how an observed pattern should be interpreted:
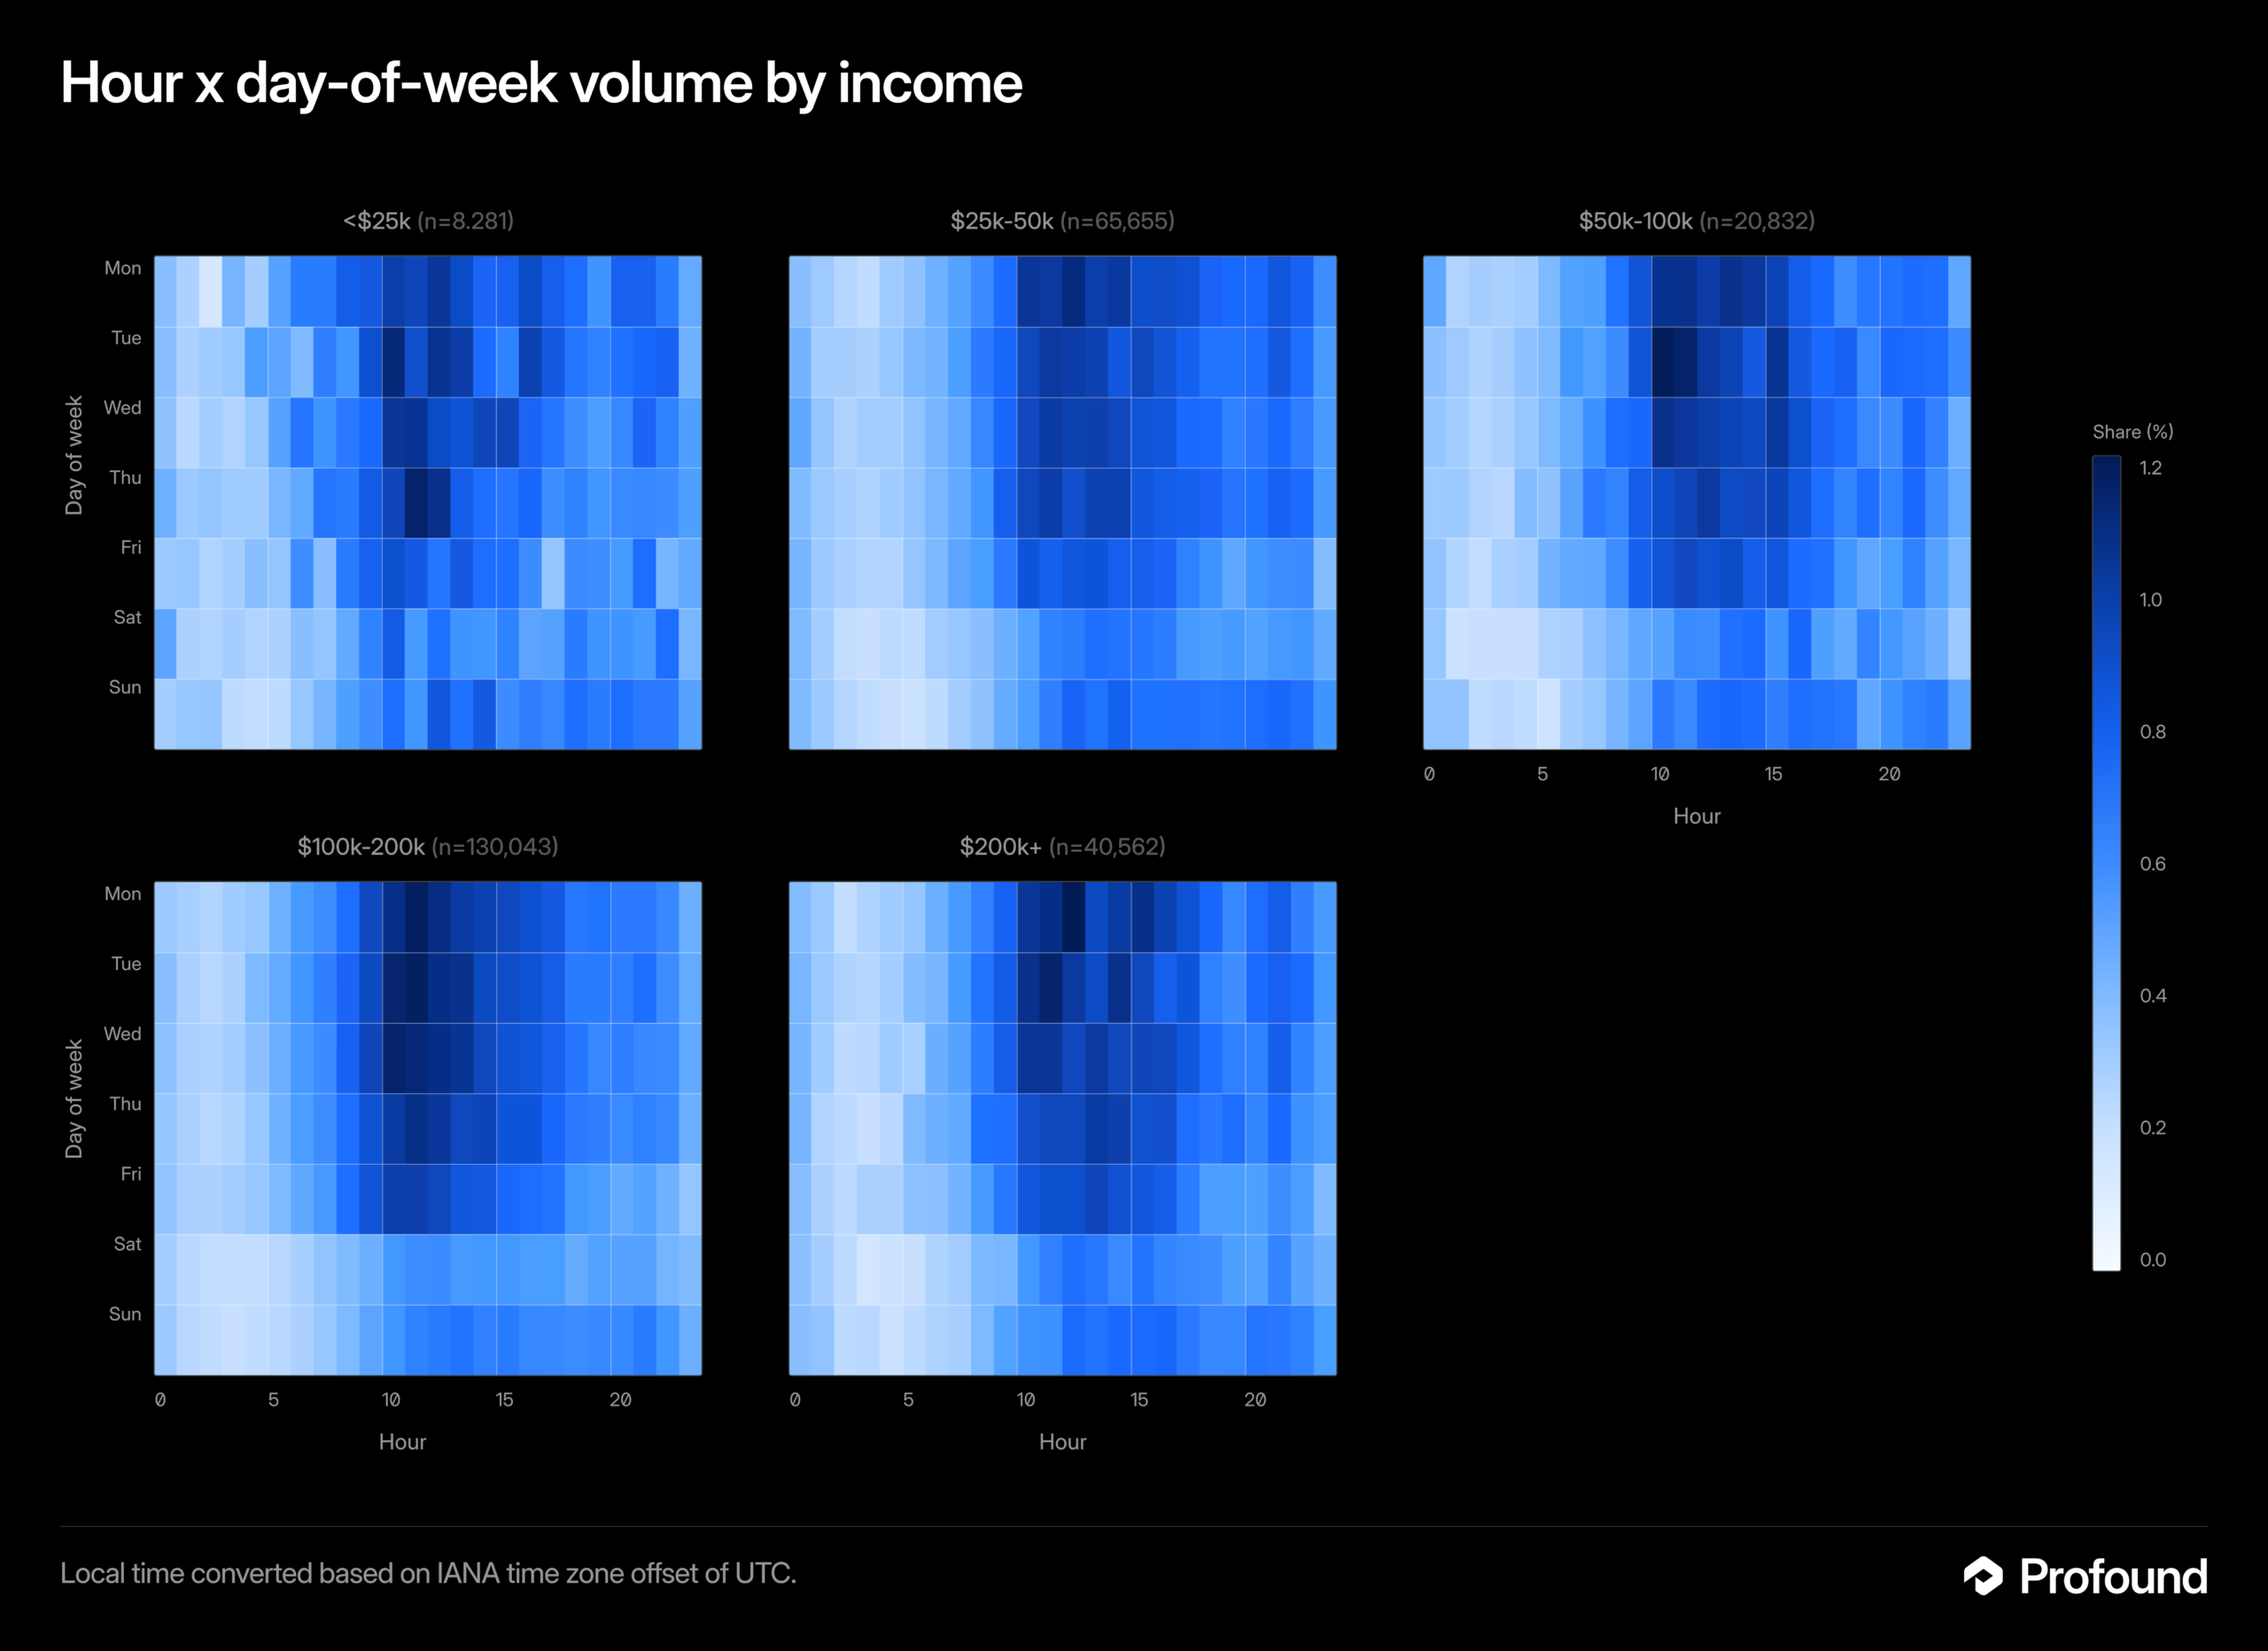
The five blue heatmaps show share percentages by hour and day of week for income groups, with many darker cells appearing from late morning through afternoon.
Platform: Different products can serve different purposes and attract different usage habits.
Region: Local time, working patterns, and audience location can shift periods of activity.
User: Individual needs determine whether an assistant is used for work, study, research, planning, or another task.
These variables make a single global “best time” an unreliable assumption. A pattern found in one segment should not automatically be applied to another.
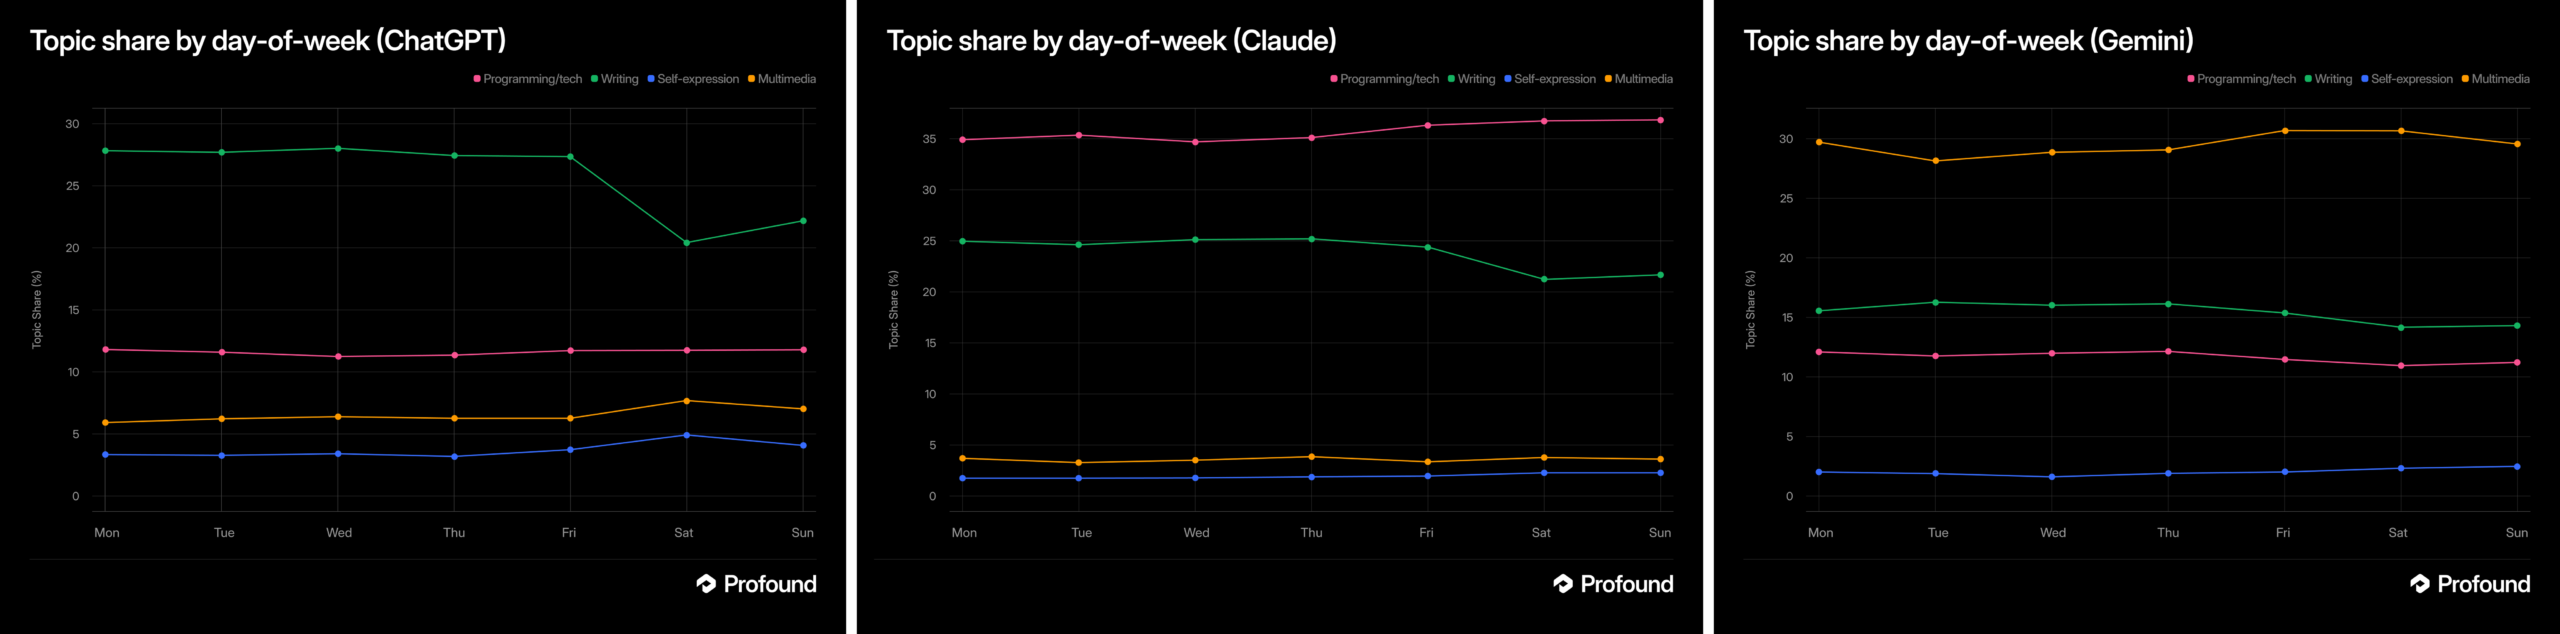
Side-by-side weekday charts show writing highest for ChatGPT, programming/tech highest for Claude, and multimedia highest for Gemini, with weekend shifts.
Key takeaways
AI assistant activity can form recurring daily and weekly patterns.
Those patterns may differ across platforms, regions, and individual users.
Timing should be evaluated within a defined audience and use case.
The source states the principle but does not supply data for specific hours or days.
How teams can evaluate timing responsibly
For marketers, publishers, and product teams, the practical response is to examine their own evidence. Analysis should begin with a clear question: which platform, audience, region, and outcome are being measured?
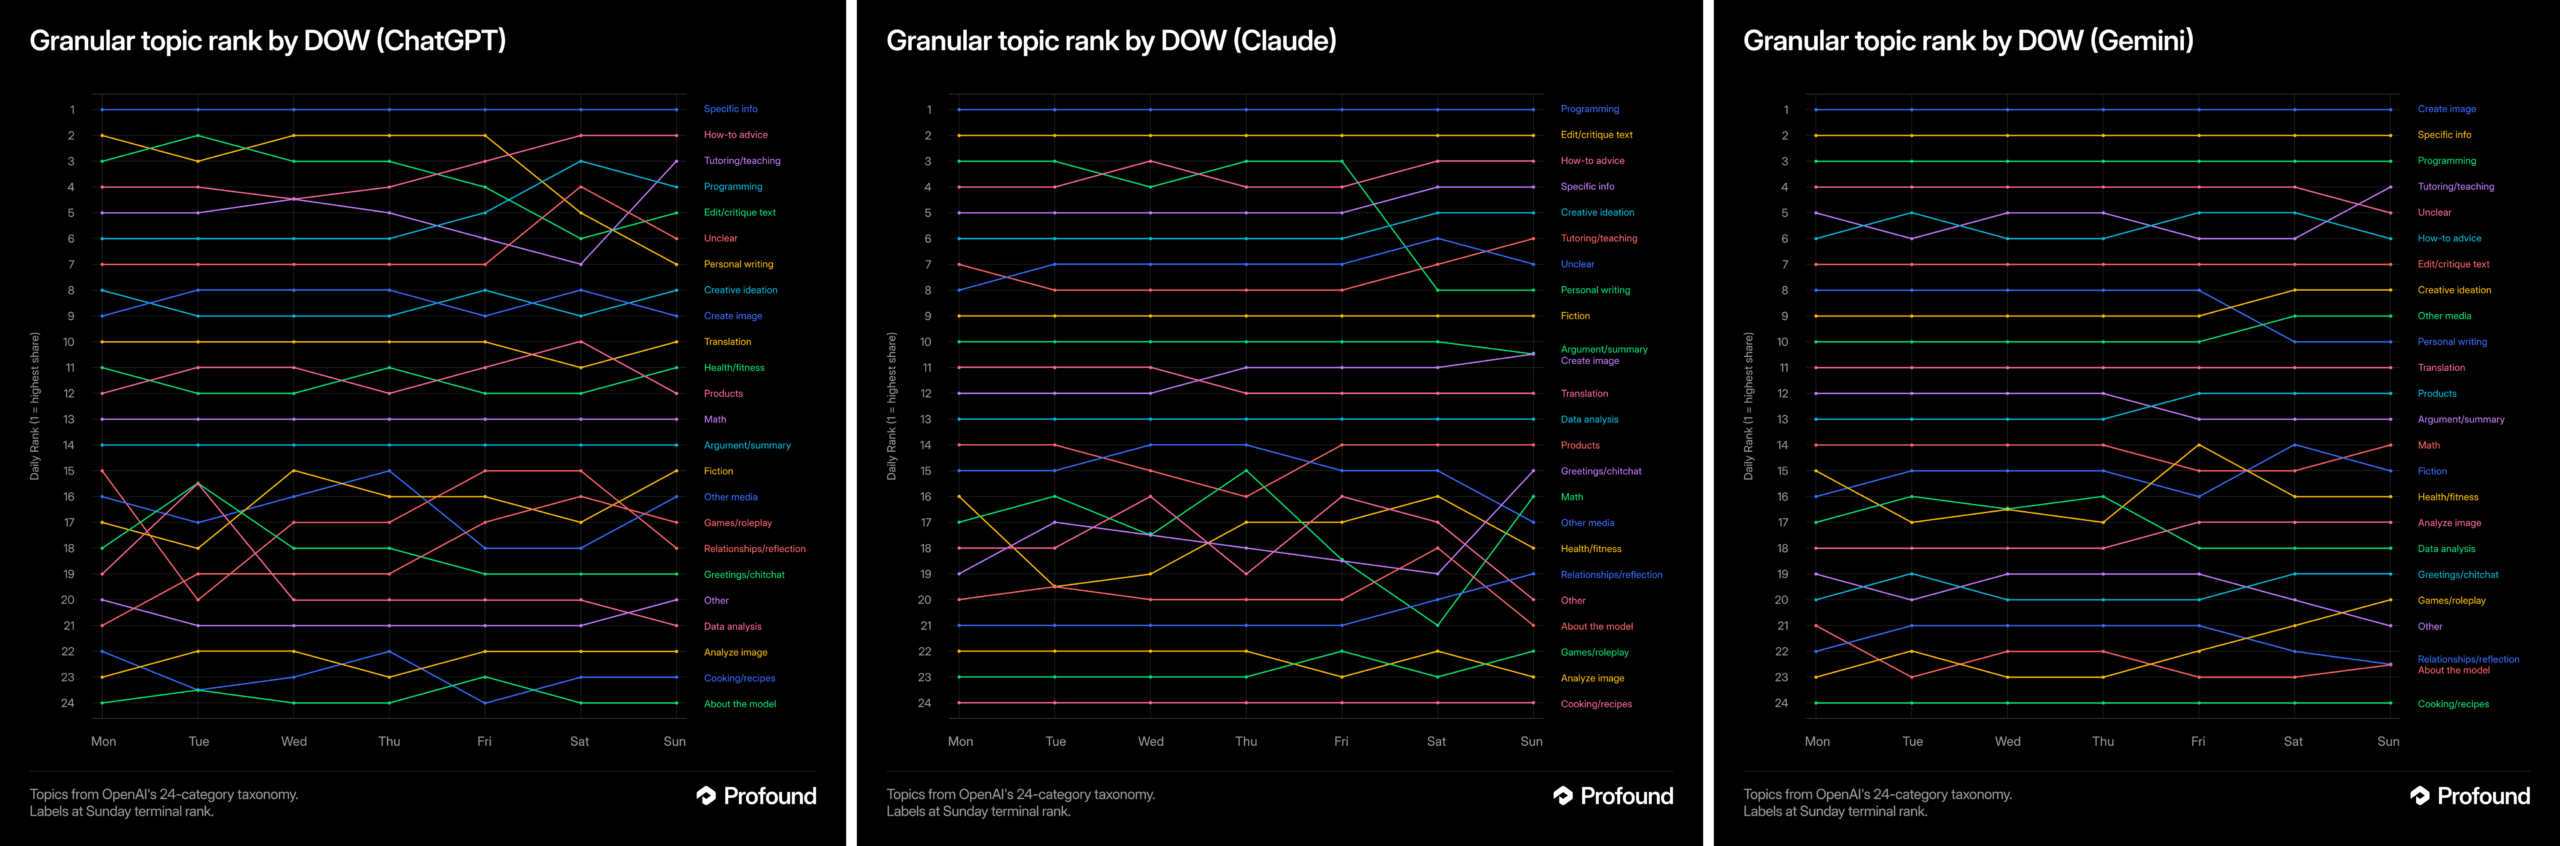
Side-by-side charts titled "Granular topic rank by DOW" trace colored topic rankings from Monday through Sunday for ChatGPT, Claude, and Gemini.
Teams can then compare consistent time periods, use the relevant local time zone, and separate audience segments where possible. They should also distinguish between activity and impact. A busy period does not necessarily produce the most valuable visits, recommendations, conversions, or customer outcomes.
Any apparent rhythm should be treated as a working pattern rather than a permanent rule. User behavior, product design, and the mix of use cases can change, so conclusions need periodic review.
What the source does not establish
Try Profound Blog does not identify peak hours, preferred weekdays, regional differences, or platform-specific results in the supplied material. It also does not describe a study or methodology. Claims about exact schedules would therefore go beyond the available evidence.
The defensible conclusion is narrower: AI usage has timing patterns, and context determines what those patterns mean. Organizations that want actionable answers will need to measure the audiences and outcomes that matter to them.
My eight-year-old daughter desperately wanted a Nintendo Switch. Her “evil” parents—my spouse and I—refused to buy one for her.
She was too young to get a job, so she did what any resourceful child would do: she opened a lemonade stand in front of our house.
She did more than set out a table and a pitcher, though. She designed what amounted to a high-stakes A/B test.
Her hypothesis was simple: if she could persuade more people to stop, she could sell more lemonade and reach her Nintendo Switch goal faster.
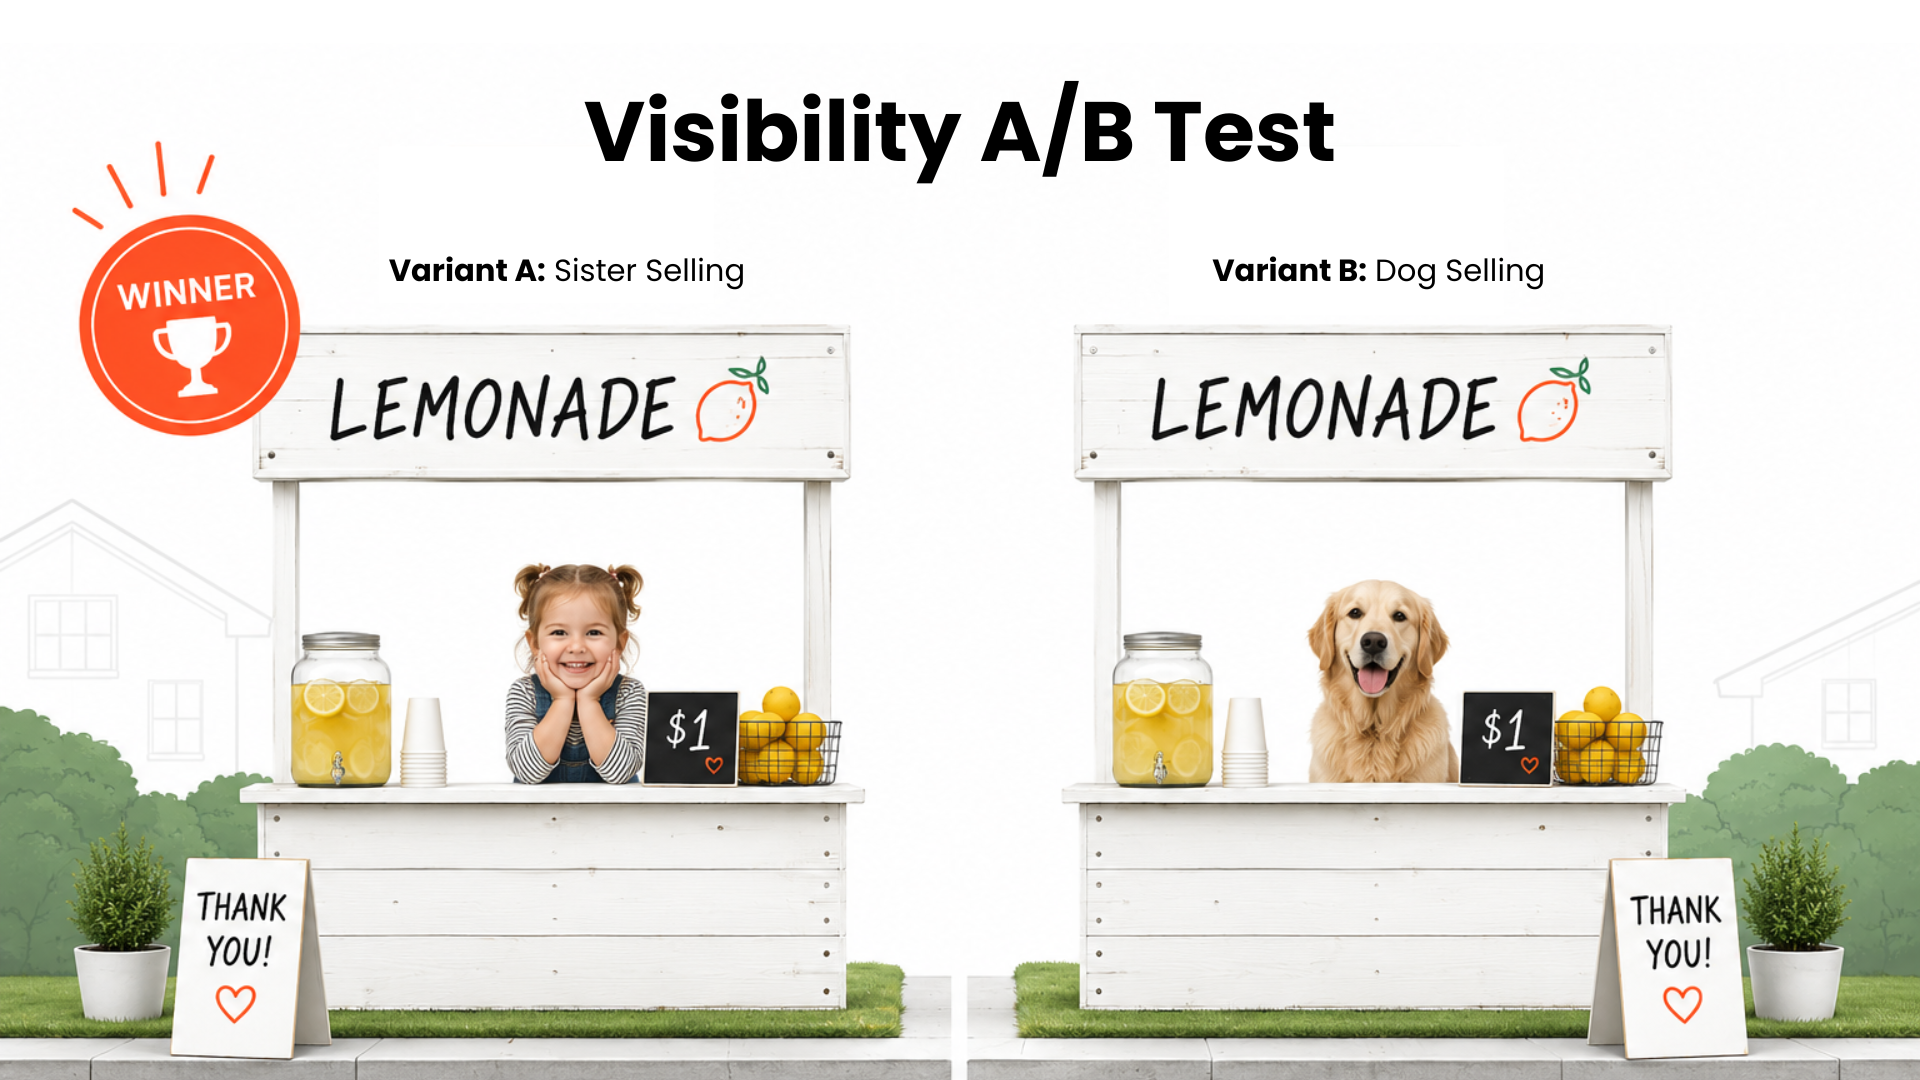
Variant A was her two-year-old sister, Julie, stationed out front to attract attention.
Variant B was our dog, Ginger.
I know what I would have guessed.
The dog. Obviously, the dog.
But Julie won—and it was not even close.
The only metric that mattered
The funny part is that my daughter did not really care about the A/B test result. She was not interested in how many people stopped at the stand or which variant produced the best response.
She cared about one outcome and one outcome only:
At this lemonade stand, the cute-dog advantage loses: Variant A, featuring the seller’s young sister, wins the visibility A/B test over Variant B’s golden retriever.
Did she make enough money to buy the Nintendo Switch?
I believe marketers are facing a similar problem right now.
Generative engine optimization (GEO) is the practice of increasing a brand’s visibility in AI-generated answers across platforms such as ChatGPT, Gemini, Perplexity, and AI Overviews.
I can track AI visibility, citation share, impressions, rankings, and nearly every other signal available. Meanwhile, leadership is asking a much simpler question:
Is any of this helping the business grow?
I answer that question with a simple test I call the Dollar Rule: if I cannot put a dollar sign in front of a metric, I treat it as a channel metric rather than a business metric.
That distinction captures the central measurement challenge in GEO.
Most of the numbers we track are valuable operational signals. They show us what is happening within the channel, but leadership wants to understand the resulting business impact.
GEO emerged at precisely the moment attribution was becoming less reliable.
Traditional SEO measurement relied on a straightforward journey: someone searched, clicked, visited a website, and converted. We could trace that path and connect it to an outcome.
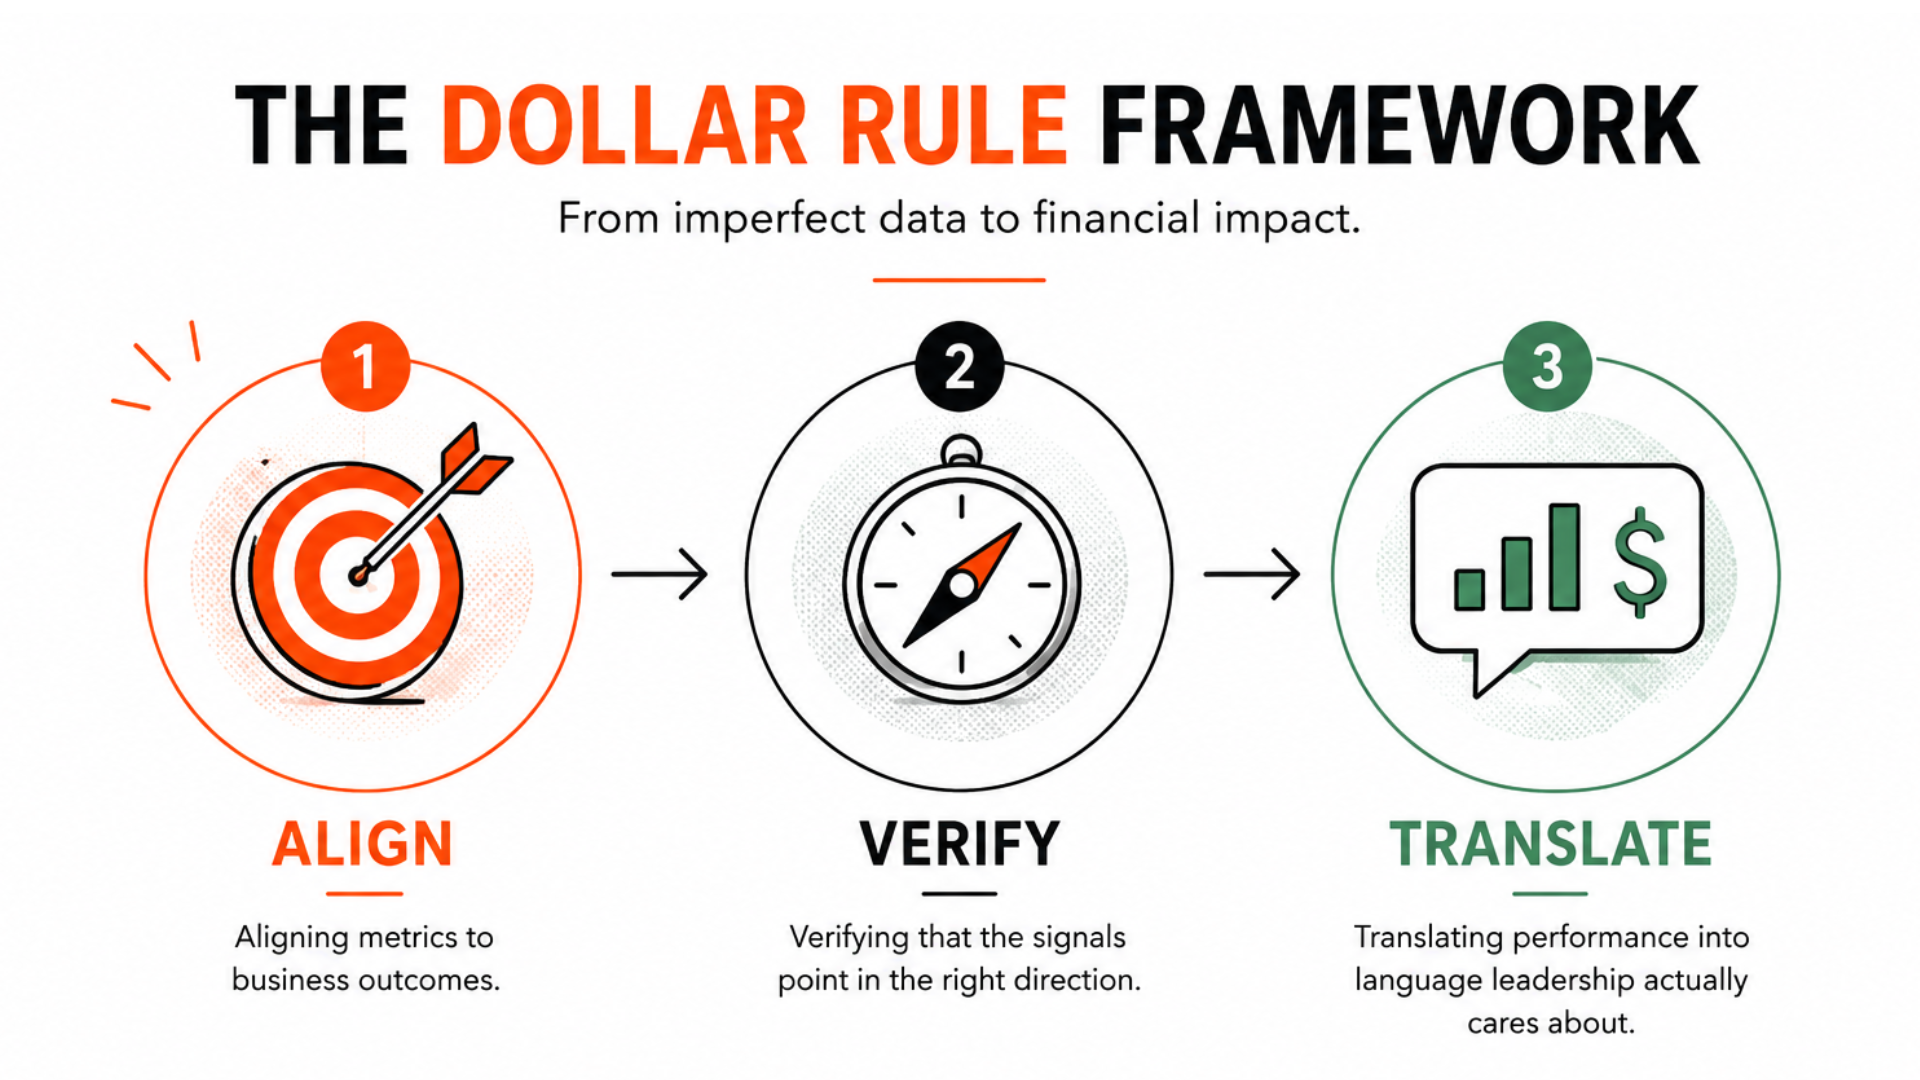
The Dollar Rule turns imperfect GEO attribution into a business case: align metrics with outcomes, verify directional signals, then translate performance into financial language leaders value.
AI search disrupted that model.
I now see buyers forming opinions and making decisions before they ever reach a company’s website. That makes AI’s influence much harder to capture with conventional attribution.
AI search broke attribution
I see buyers discovering brands through AI-generated answers, citations, publishers, forums, reviews, videos, and many other sources. Those touchpoints can shape a decision long before a click occurs, and much of that influence never appears cleanly in analytics.
That is why I see so many teams struggle to justify GEO investments. The visibility is real, and the influence is real, but the attribution is frequently incomplete.
I do not believe waiting for perfect attribution is a sound strategy. Increasingly, it is simply a convenient reason to avoid acting.
When I want leadership to support GEO, I need to connect its influence to business outcomes—even when I cannot connect every interaction to a conversion.
How I make the financial case for GEO
The biggest mistake I see marketers make is trying to prove attribution before proving value.
Before I worry about attribution, I ask whether I am measuring something the business actually considers important. That is where the Dollar Rule becomes useful.
I have found that justifying a GEO investment usually comes down to three actions:
I align my metrics with business outcomes.
I verify that those metrics reliably point me in the right direction.
I translate the evidence into language a CFO understands.
My Dollar Rule is deliberately simple:
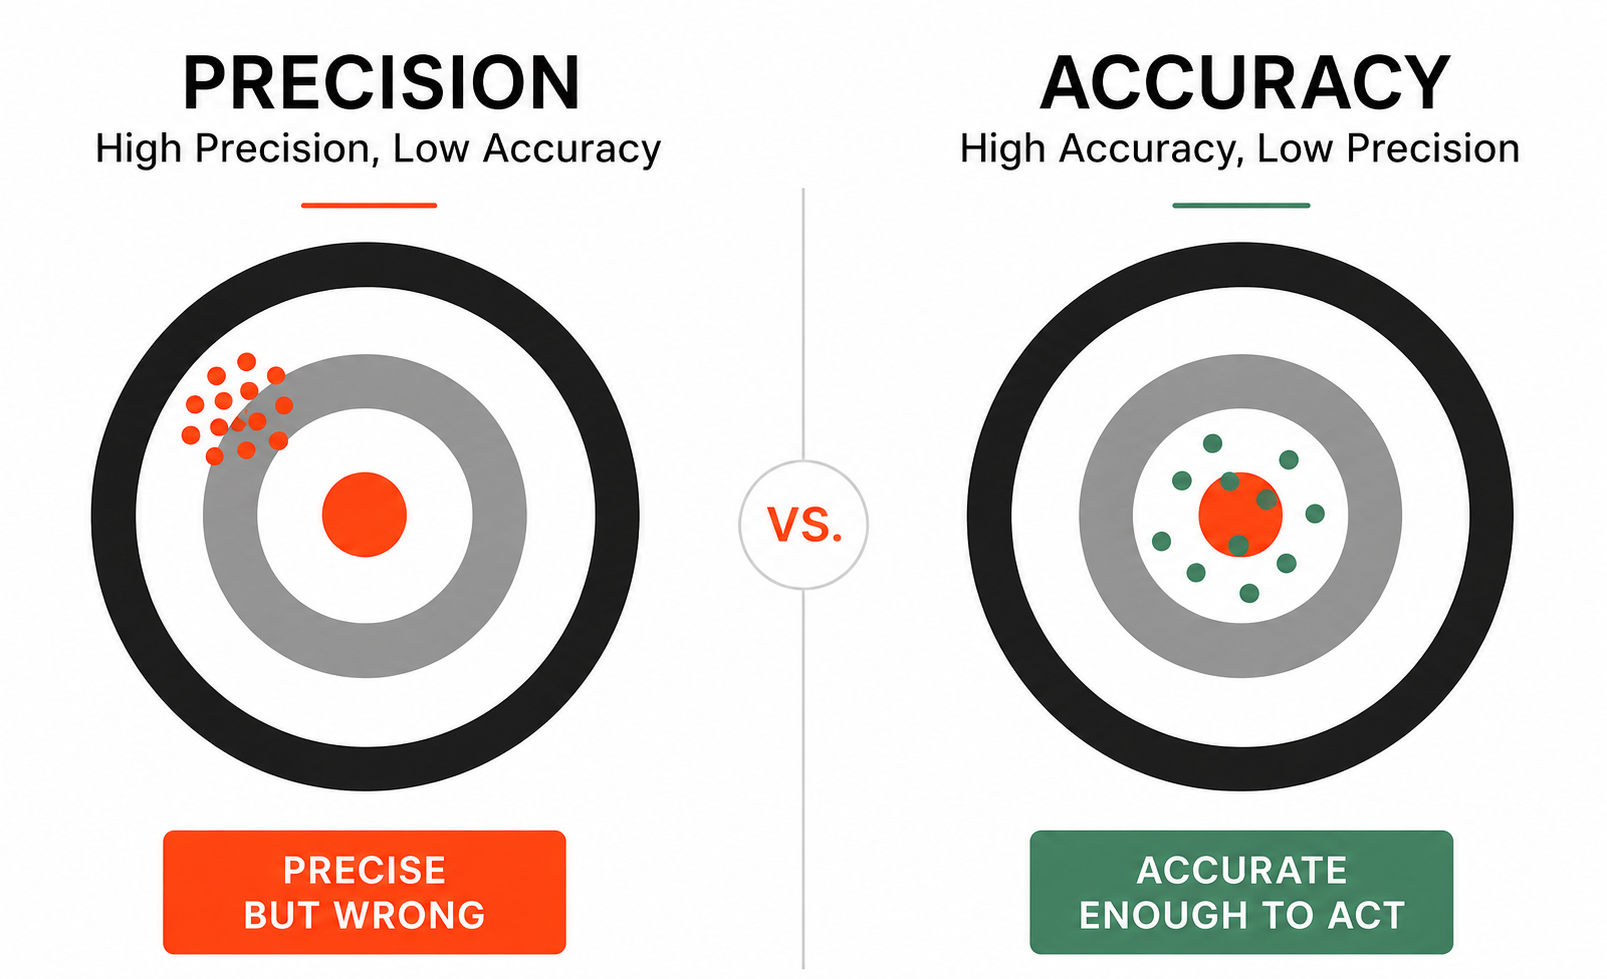
Precision can form a tight cluster in the wrong place; accuracy keeps evidence centered on the outcome that matters. For GEO measurement, a useful estimate can beat an exact but irrelevant metric.
If a number does not translate into dollars, I treat it as a channel metric, not a business metric.
I focus on revenue opportunity, revenue at risk, payback period, and customer acquisition cost. Those metrics live on a P&L, and they are the numbers leadership teams use to evaluate investments.
In my experience, CFOs do not allocate budget because an attribution model looks impressive. They allocate budget based on credible expectations of financial return, risk, and growth.
That principle changes how I measure and present GEO.
I measure influence, not just attribution
AI search did more than change discovery. It changed what I can realistically measure.
Traditional organic attribution assumes a clean sequence: search, click, visit, convert.
AI platforms increasingly answer questions before a click, influence buyers across multiple touchpoints, and withhold the referral data marketers once relied on.
That leaves me in an unusual position: a GEO campaign may be influencing pipeline even while the analytics platform struggles to prove it.
One estimate illustrates the gap. Loamly estimates that roughly 70% of AI-influenced traffic appears as Direct traffic in GA4, making a substantial share of AI’s contribution difficult to trace through traditional attribution models.
I do not take that measurement gap to mean measurement is impossible. I take it as a reason to broaden the evidence I examine.
When attribution is incomplete, business value tips the scale: a credible estimate of revenue impact can guide GEO investment better than a perfectly precise tally of clicks.
Instead of asking only, “How many clicks did we receive from AI search?” I ask:
Is our branded search growing?
Are prospects arriving already familiar with our positioning?
Are we being cited in AI answers for questions that drive revenue?
I would not treat any one of these signals as definitive. When I combine them, however, they can create enough confidence to support a responsible investment decision.
That is the essential difference between GEO measurement and traditional SEO measurement. I am not simply measuring a click path; I am measuring market influence.
I believe the marketers who adapt fastest will stop treating attribution as a traffic-sorting exercise. We will combine quantitative signals with qualitative evidence because the goal is not absolute certainty. The goal is confidence that our GEO investment is moving the business in the right direction.
Why I may be measuring the wrong thing
I do not think SEO or GEO metrics are inherently wrong. The problem is that they can be highly precise without being relevant to the business outcome I am trying to influence. They tell me exactly what happened inside a channel, but not whether the business is moving in the right direction.
SEO tools are packed with precise numbers. The challenge is that many of those numbers have only a weak connection to business outcomes.
Precise = exact
Accurate = connected to business outcomes
I have found that leadership would rather receive a roughly correct estimate of revenue impact than a perfectly precise count of clicks.
I studied engineering in school, where we spent a great deal of time discussing precision: how exact and repeatable a measurement is, right down to the decimal point.
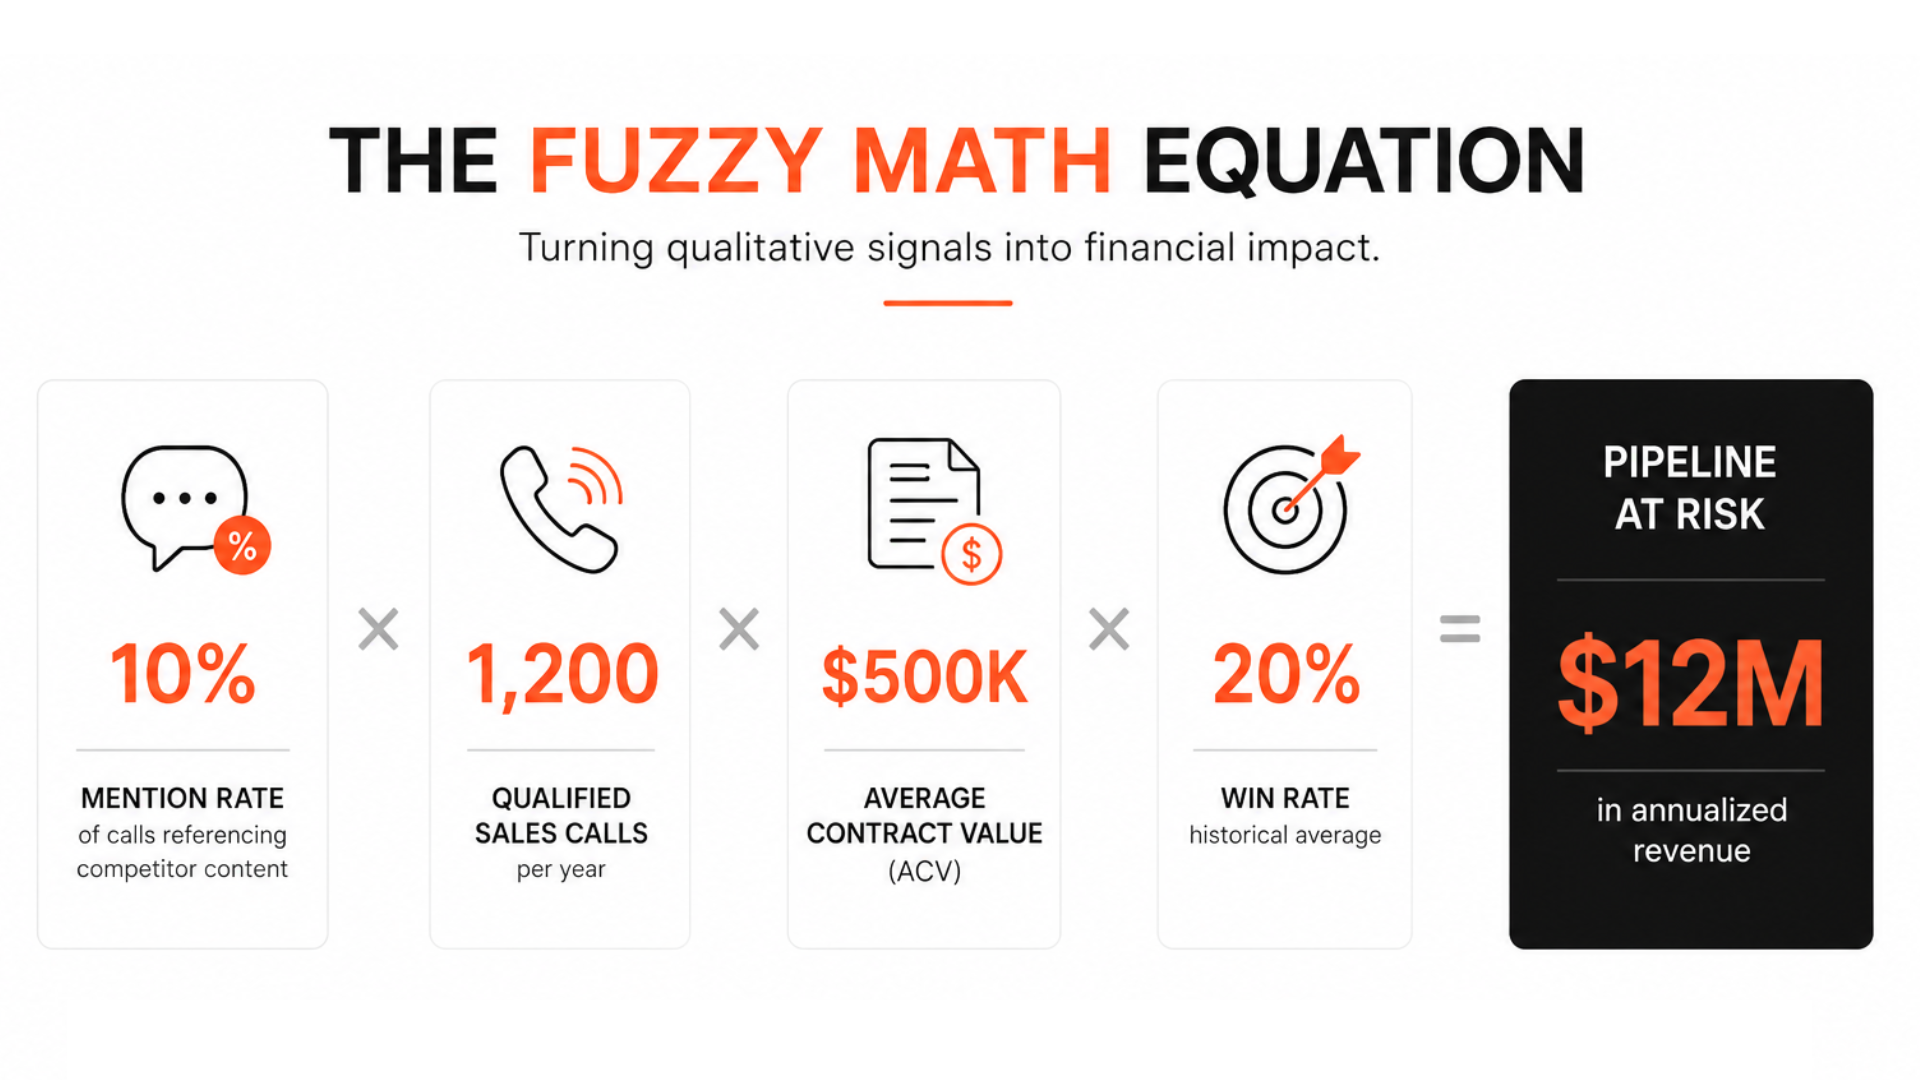
The fuzzy math equation turns a qualitative sales signal into a figure leaders understand: a 10% competitor-content mention rate translates to $12 million in annualized pipeline at risk.
In marketing, I see that kind of precision in organic clicks, rankings, impressions, and click-through rates. Tools such as Google Search Console can give me extremely exact figures for those channel activities.
The problem is that a precise channel number is not necessarily accurate in the business sense. I consider a measurement accurate when it tells me whether I am getting closer to an outcome that matters.
Even when those measurements are not perfectly precise, I find them more useful if they point toward the bullseye: the business outcomes leadership cares about.
Knowing that a page received 40 organic clicks is precise. It tells me almost nothing about whether we are winning or losing in the market—just as a visitor count did not tell my daughter whether she was close to buying her Nintendo Switch.
That is how I apply the Dollar Rule in practice. When attribution is incomplete, I translate the evidence I do have into a directional estimate of business impact.
Why I put revenue ahead of attribution
For me, a rough number tied to revenue beats an exact number tied only to channel activity.
When reliable attribution is unavailable, I build the case from signals I can actually access and then work through the math.
I do not use fuzzy math to replace SEO metrics or attribution. I use it alongside them when traffic-based attribution cannot capture the influence taking place.
One of our healthcare clients gave us a useful example.
Prospects were arriving at sales calls already convinced of claims that were not true.
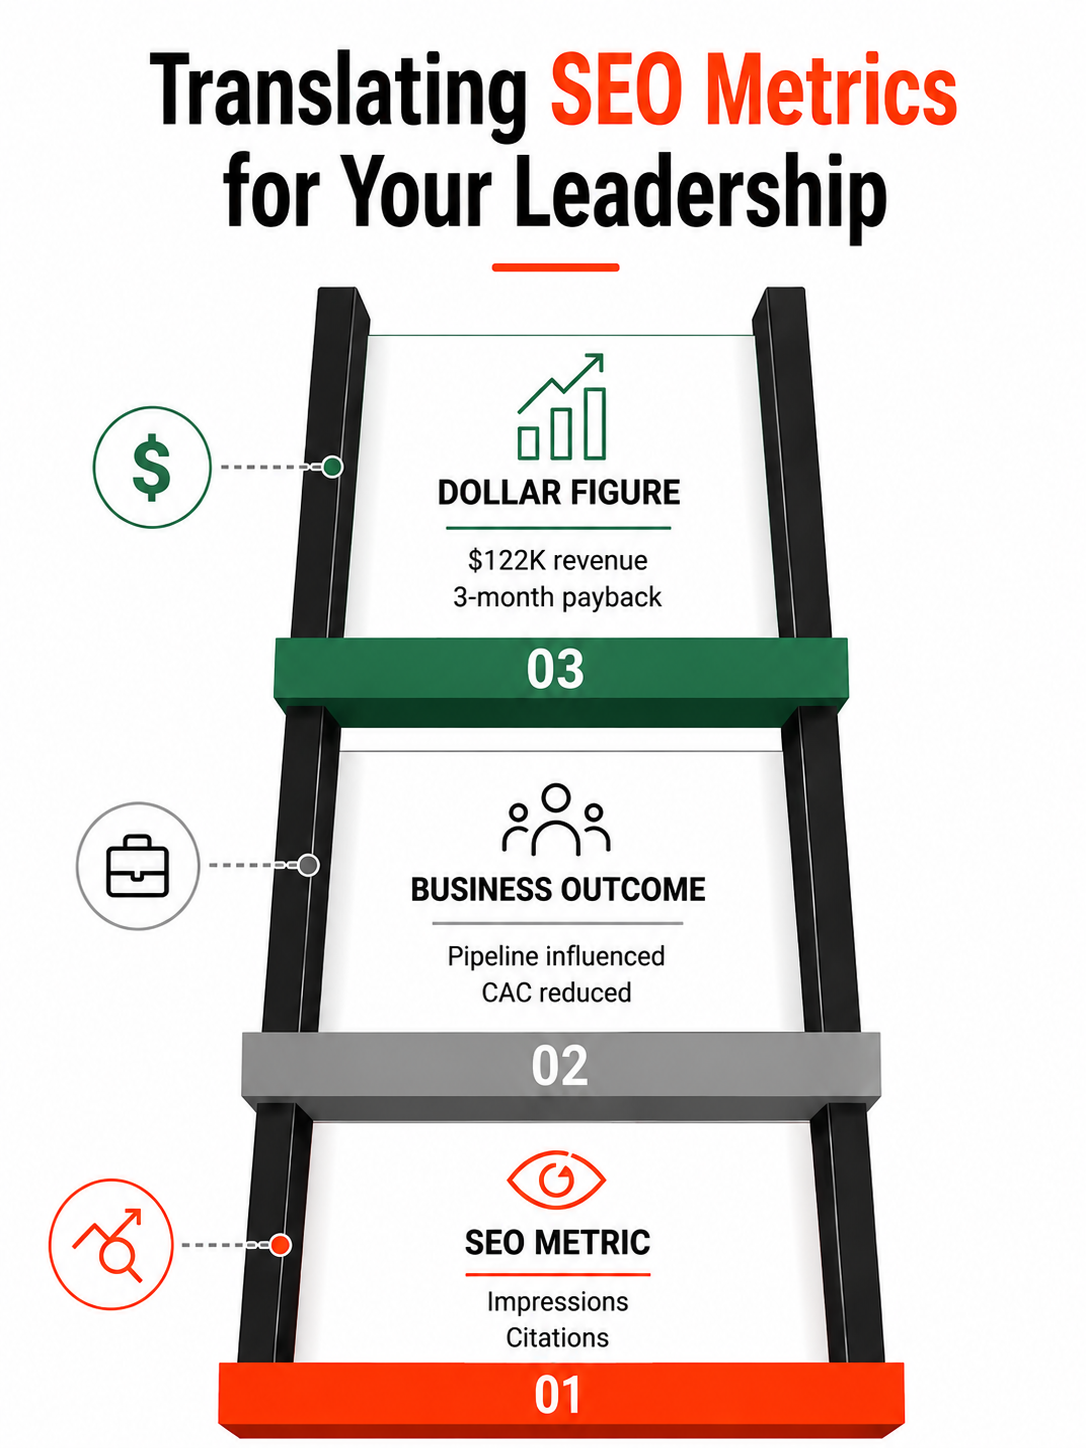
Climb from channel data to executive value: translate SEO impressions and citations into pipeline and lower CAC, then show leadership what matters—$122K in revenue and a three-month payback.
We traced the source to a competitor’s comparison page. That page was shaping buyer perceptions long before our client had an opportunity to present its side of the story.
We recommended publishing content that would counter the narrative, but the leadership team did not believe there was enough evidence to justify a response. We needed to make a stronger business case.
SEO tools estimated that the competitor’s page received roughly 40 organic visits per month. Whether that estimate was right or wrong was beside the point: it did not measure the page’s influence on active buyers.
So we looked for evidence that was closer to the business outcome.
We spoke with our client’s salespeople. They told us that roughly 10% of qualified B2B discovery calls included unprompted mentions of specific claims from the competitor’s page.
That was not a clean number suitable for an exact attribution model, but we could not dismiss it. The influence was real, and it was showing up during live sales conversations.
We used that evidence to build a directional calculation:
10% mention rate on discovery calls
× 1,200 qualified B2B sales calls per year
× $500,000 average contract value
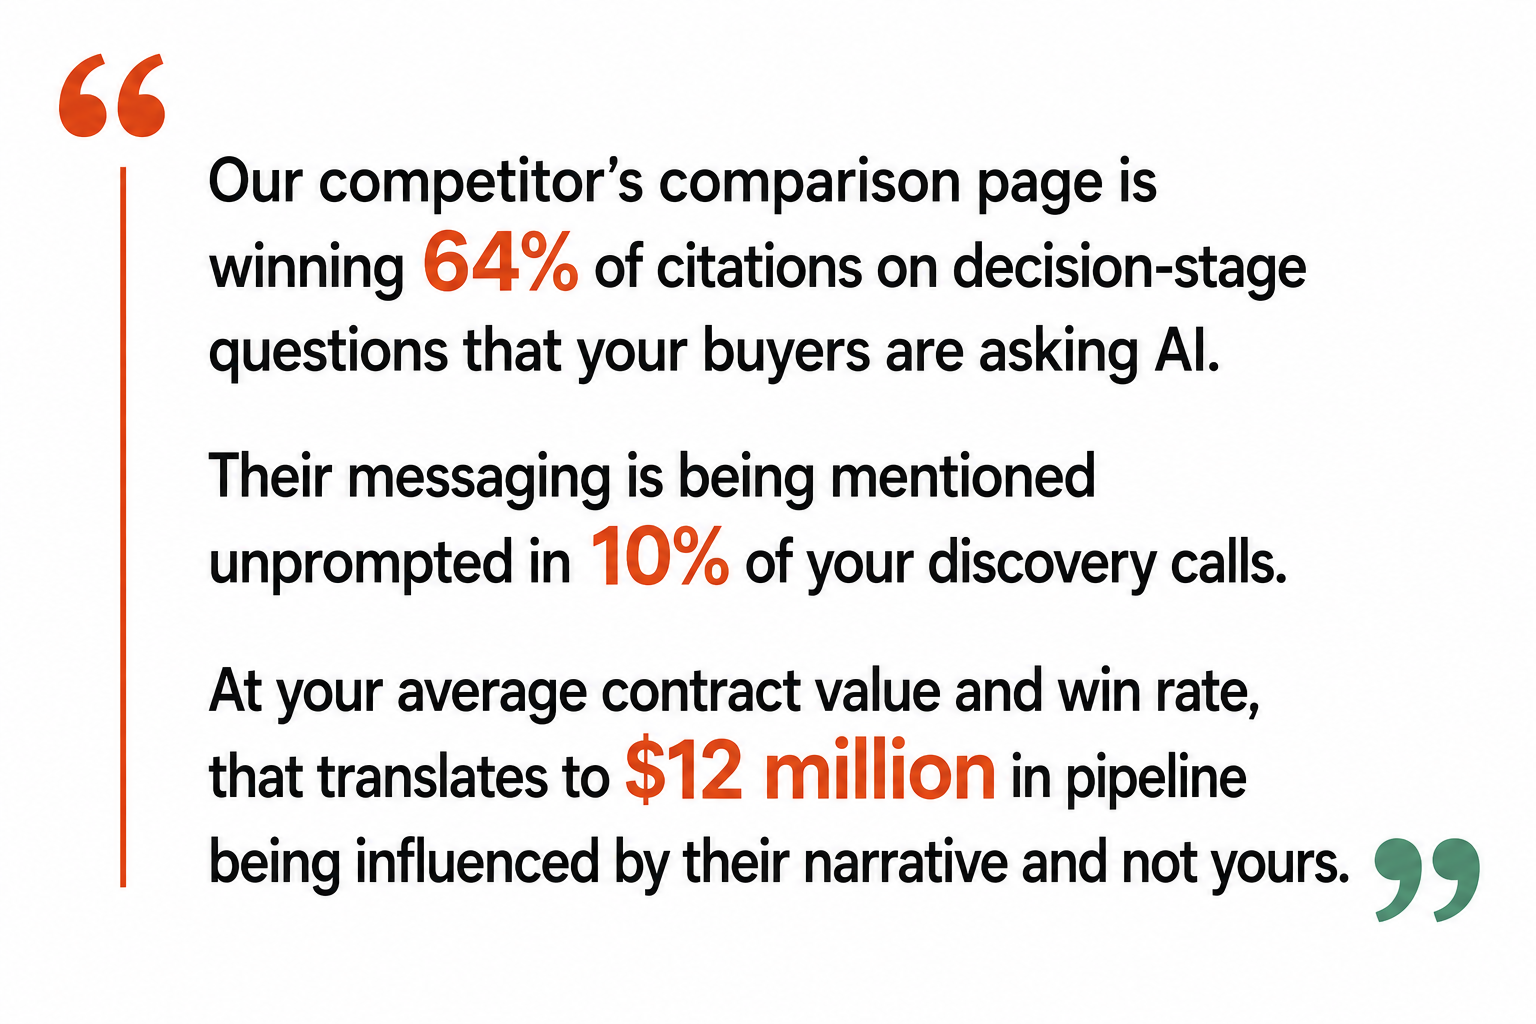
A competitor’s comparison page earns 64% of citations on decision-stage AI questions and surfaces in 10% of discovery calls—putting an estimated $12 million in pipeline under its narrative.
× 20% average win rate
= $12 million in annualized revenue being influenced by the competitor’s narrative
I did not present this as a forecast or a formal attribution model. It was a directional estimate of how much revenue the competitor’s messaging could influence.
That reframing changed the conversation. We stopped debating 40 clicks per month and started discussing $12 million in influenced revenue.
That is the number we brought to leadership—not impressions or citation share, but $12 million in revenue being influenced by a page our client had declined to counter. That is a number a CFO immediately understands.
I lead with value metrics
If we enter a GEO campaign review and lead with rising citation share or growing impressions, our CMO may lose interest and our CFO may wonder what those numbers mean financially. In the worst case, we can lose budget because leadership cannot see the return.
Here is how we framed the situation for our client’s leadership team:
I have learned that leadership funds marketing campaigns based on business impact. Translating a problem into dollars changes the nature of the discussion.
The decision-makers did not need certainty. They needed a credible financial story supported by leading indicators, observable momentum, and enough evidence to inspire confidence.
I focus on what the business values
That is what my eight-year-old intuitively understood at her lemonade stand. Her goal was never to count visitors. Her goal was to buy the Nintendo Switch.
A neon-lit smartphone imagines advertising inside ChatGPT, highlighting how AI platforms are reshaping brand discovery, GEO strategy, and the measurement of marketing influence.
GEO has created anxiety because it disrupted attribution models we relied on for years. But I remind myself that attribution was never the ultimate objective.
The real objective is business growth.
If I can connect GEO activity to revenue opportunity, revenue at risk, pipeline influence, or customer acquisition, I do not need perfect certainty to justify the investment.
I need credible evidence that our GEO campaigns are moving the business in the right direction.
Precise metrics tell me what happened. Relevant metrics tell me whether we are winning.
Before I deliver my next GEO report, I can examine every metric on the page and ask one question:
If this metric doubled tomorrow, would the business care?
Then I ask the follow-up:
Can I translate this metric into revenue opportunity, revenue at risk, pipeline influence, or customer acquisition cost?
If I cannot, I am probably reporting channel impact rather than business impact—and that is unlikely to justify the next GEO investment.
Growth marketing discipline is not simply a matter of spending less. It is the practice of matching each investment to the strength of the evidence, the speed of the feedback loop, and the financial risk the business can absorb.
Viewed together, the source articles expose two sides of the same capital-allocation problem. Paid media can consume cash before a campaign has learned enough to use it efficiently, while underinvesting in SEO can create a slower, compounding liability. The practical goal is therefore neither maximum growth nor minimum cost, but evidence-based investment across different time horizons.
Key takeaways
Budget consumption is an input, not evidence of business performance.
Paid campaigns should generally earn larger budgets through validated conversion quality, unit economics, and operational learning.
SEO should be judged partly by the future acquisition costs and competitive exposure that sustained investment may prevent.
Channel metrics become decision-useful only when connected to pipeline, revenue, payback, or measurable risk.
Growth plans need explicit scale, hold, reduce, and stop conditions before spending begins.
The same budget can create very different financial risks
A dollar allocated to paid acquisition and a dollar allocated to SEO do not mature on the same schedule. Paid media can generate immediate traffic and relatively fast campaign signals, but it can also amplify weak targeting, immature bidding, poor creative, or an unproven offer. SEO usually takes longer to affect commercial outcomes, yet reducing it may allow competitive positions and accumulated authority to deteriorate over time.
The paid-media source argues that most campaigns should begin with a measured rollout because algorithms are still learning and the strongest audiences, keywords, and creative assets are not yet known. It also warns that a long or variable sales cycle limits the value of forcing more spend into an early period: if sales arrive months after the first exposure, the campaign cannot quickly convert additional volume into reliable learning.
The SEO source describes almost the inverse danger. Organic positions are presented as contested rather than permanent, so a budget reduction may produce a delayed and potentially compounding decline. Competitors can continue publishing and building authority while the withdrawing company loses visibility, and replacing lost organic demand with paid acquisition may increase customer acquisition costs. That makes maintenance investment relevant even when its short-term incremental return is difficult to isolate.
This distinction changes the budgeting question. Paid media requires protection against premature amplification; SEO requires protection against deferred deterioration. A disciplined portfolio accounts for both instead of applying one universal demand for immediate return.
Commercial evidence must replace activity as the investment case
Both sources reject the idea that channel activity is a sufficient measure of progress. The paid-media article states that the amount spent is not a key performance indicator. The SEO article reaches a parallel conclusion about rankings, traffic, and keyword opportunities: those metrics cannot support a capital request unless their commercial implications are made clear.
The SEO source illustrates the gap with an enterprise software example. It reports that one product line produced 291 inbound demo requests in a month in 2008 and 274 in the corresponding month of 2026, despite a digital marketing budget that had grown to roughly eight times its earlier size. The example is not proof that any single channel failed, but it shows why a finance leader may focus on qualified opportunity output and acquisition efficiency rather than favorable channel charts.
The paid-media source reports a similarly consequential measurement failure at a startup that had raised more than $250 million. According to the article, most of the funding had been consumed before measures such as revenue-producing new accounts and lifetime revenue from those accounts became serious priorities. The lesson is broader than paid search: measurement introduced after capital is depleted cannot restore the option value that early discipline would have preserved.
A credible investment case should therefore connect leading indicators to a commercial chain: exposure creates qualified demand, qualified demand creates customers, and customers create revenue and margin over time. Where that chain cannot yet be demonstrated, the uncertainty should be visible in the size and reversibility of the commitment.
A stage-gated model connects experimentation to capital allocation
The synthesis of the two sources suggests a stage-gated approach. It preserves the paid-media article’s principle of testing before scaling while incorporating the SEO article’s emphasis on business risk, counterfactuals, and the cost of withdrawal.
Define the commercial outcome. Specify the qualified action, customer, revenue, or risk outcome the investment is expected to influence. Channel metrics can remain diagnostic measures, but they should not become the final objective.
State the uncertainty. Identify what is not yet known about audience quality, conversion value, attribution, sales-cycle delay, competitive response, or organic displacement. This prevents confidence from being inferred merely from a large budget.
Choose a reversible initial commitment. For an unproven paid campaign, this generally means enough volume to produce useful signals without treating the entire available budget as test capital. For SEO, it means distinguishing experimental expansion from the baseline work needed to protect strategically important visibility.
Set decision thresholds in advance. Establish what evidence will trigger scaling, continued observation, redesign, reduction, or termination. Thresholds should include commercial quality and payback considerations, not only clicks, traffic, or conversion counts.
Increase investment in calibrated increments. Each increase should answer a defined question, such as whether performance persists in a broader audience or whether greater content investment protects or expands commercially valuable visibility.
Reassess the portfolio effect. Evaluate whether one channel is creating, capturing, or merely receiving credit for demand, and estimate what another channel would need to spend if that contribution disappeared.
This process does not require every channel to meet the same payback schedule. It requires every channel to have a defensible role, an appropriate evidence standard, and a known consequence if investment rises or falls.
Governance should make both upside and downside visible
Investment discipline weakens when the person advocating aggressive growth does not bear the full consequences of failure. The paid-media source highlights this risk asymmetry and reports observing a recurring pattern across close to 1,000 ad accounts: advertisers that overspent early in pursuit of rapid growth often exhausted momentum and stakeholder support. That reported experience is not a universal causal estimate, but it reinforces the need for governance before enthusiasm becomes an irreversible commitment.
Finance and marketing can reduce that asymmetry by reviewing paired scenarios. The upside case asks what additional investment could produce if the thesis works. The downside case asks how much capital can be lost, how quickly the result will become observable, and whether the company will still have enough runway to adapt. For durable channels such as SEO, the downside analysis should also examine what withdrawal could cost through lost visibility, higher replacement acquisition expense, and a more difficult recovery.
Counterfactual thinking is essential in both directions. The SEO source identifies the central attribution challenge as whether credited revenue would have happened without the investment. The corresponding question for budget cuts is whether apparent savings will simply reappear as higher costs elsewhere. Neither question can always be answered with precision, but an explicit range of outcomes is more useful than presenting attributed revenue or budget savings as certain.
The most resilient growth plans will treat capital as a sequence of informed commitments. Paid acquisition can expand as customer quality and economics become clearer, while SEO can be funded according to both its growth potential and the liability created by neglect. That balance allows a company to pursue opportunity without spending away its ability to learn.
Marketing automation can react to campaign signals faster than a person, while marketing mix modeling can help explain performance across channels and longer time horizons. Neither capability removes the need for human oversight; each moves that oversight to decisions about goals, data quality, constraints, validation, and interpretation.
The useful question is therefore not whether people or machines should control marketing. It is where human judgment has the greatest leverage in a system that combines rapid execution with slower, broader measurement.
Automation and measurement address different decision gaps
Campaign automation primarily shortens the gap between an observable signal and an action. The account described in the groas report used an automated system to adjust bids, budgets, keywords, match types, campaign activity, ad copy, and landing pages in response to Google Ads data. Its proposed advantage was continuous attention: a weak search term or drifting target could be addressed sooner than under a periodic manual review cycle.
Marketing mix modeling (MMM) addresses a different problem. Rather than managing an individual auction, it estimates how channels and outside factors relate to business outcomes over time. the MMM report said a credible implementation may require two to three years of weekly data, consistent channel-level spending, offline activity, and external variables such as pricing, competitor activity, product launches, and macroeconomic conditions.
These approaches operate at different speeds and levels of aggregation, but their dependencies converge. Both need a well-defined business outcome, trustworthy inputs, knowledge of exceptional events, and a person capable of challenging an apparently successful output. Faster optimization cannot repair a poorly chosen conversion goal, just as sophisticated modeling cannot compensate for missing or inconsistent historical data.
Dimension
Campaign automation
Marketing mix modeling
Primary purpose
Act on account-level performance signals
Estimate contribution across channels and business conditions
Set objectives, structure the account, establish guardrails, and review consequential changes
Specify the model, resolve data problems, test assumptions, calibrate estimates, and interpret uncertainty
Failure risk
Rapidly optimizing toward the wrong signal
Producing a plausible but misleading explanation of performance
Human judgment matters before, during, and after automation
Before: define what the system should optimize
The first oversight point is objective design. In the groas account, a human account manager reportedly audited campaign structure, keywords, bidding logic, budget allocation, conversion tracking, quality scores, search terms, and auction insights before automated optimization began. The report also acknowledged that people must communicate changes in products, pricing, and the relative importance of conversions. Those choices determine whether the system is improving a meaningful business result or merely making a platform metric look better.
MMM has an equivalent setup problem. A modeler must decide which outcome to explain, how channels should be separated, which external variables belong in the model, and how unusual periods should be represented. The MMM source described the preliminary work as data archaeology because relevant records can be divided among finance, brand teams, agencies, and old spreadsheets. Human oversight begins with reconciling those records, not with selecting a modeling library.
During: constrain action and investigate anomalies
The reported groas rollout illustrates one way to limit early execution risk. It began with two weeks of observation, moved into calibration during weeks three and four, looked for traction in weeks five and six, and approached scaling in weeks seven and eight. This staged process is significant because automation should earn a larger operating range through observable behavior rather than receive unrestricted control on its first day.
Oversight during MMM is more diagnostic than operational. According to the modeling source, practitioners still have to judge solutions along a Pareto frontier, assess whether an optimizer has converged, configure adstock behavior, and investigate implausible channel contributions. They may need to determine whether a suspicious result comes from an incorrect prior, a data error, or a variable that should be excluded. Code generation can reduce implementation effort without resolving any of those substantive choices.
After: interpret evidence without overstating it
Automated outputs still require a disciplined reading. The groas source reported a before-and-after comparison for a U.S. online mobile recharge account in which spend increased 18% to $164,000, ROAS rose from 1.02x to 1.32x, average CPC fell from $2.34 to $2, daily conversions increased from 571 to 739, conversion value grew 44%, and cost per conversion declined 14%. It also reported that active search campaigns were consolidated from 17 to 10.
Those figures describe the source’s account snapshot, not an independently verified or universally transferable effect. A before-and-after account comparison can show that performance changed after an intervention, but by itself it does not isolate every possible cause. Seasonality, competitive conditions, demand, pricing, and concurrent business changes still need consideration. Human oversight includes distinguishing a promising operational result from a causal conclusion.
Model sophistication does not neutralize weak inputs
The MMM source compared three open-source options: Meta’s Robyn, Google’s Meridian, and PyMC-Marketing. It characterized Robyn as the most approachable of the three, Meridian as a more rigorous Bayesian option with uncertainty quantification and geo-level priors, and PyMC-Marketing as the most flexible but most demanding in statistical fluency. The availability of these libraries lowers the software and access barrier, but it does not make their results automatically reliable.
This distinction also applies to campaign automation. A system may be technically capable of adjusting every available control while remaining unable to know that a tracking event is misconfigured, a temporary promotion has changed customer behavior, or a low-value conversion should no longer guide bidding. Greater execution coverage magnifies the value of clean signals, but it can also magnify the consequences of a bad specification.
The common governance principle is proportional scrutiny. The more quickly a system can move money or the more strongly a model can influence allocation, the more clearly its inputs, permissions, assumptions, and escalation conditions should be documented. Transparency should cover not only what the technology changed or estimated, but also which human decisions framed the result.
A supervised operating model connects action to learning
A practical oversight structure separates responsibilities without separating the evidence. A strategy owner defines the business outcome and acceptable tradeoffs. A data owner protects conversion definitions, reconciles source systems, and records structural changes. A campaign operator monitors automated actions and intervenes when changes exceed agreed boundaries. A measurement specialist tests assumptions, communicates uncertainty, and uses experiments where possible to calibrate model estimates.
These responsibilities should form a feedback loop. Campaign automation produces actions and fresh performance data. Broader measurement examines how channel activity relates to business outcomes. Incrementality experiments can help test selected assumptions, as the MMM source recommended. People then decide whether objectives, constraints, budgets, or measurement specifications need to change before the next cycle.
Escalation should focus on changes that machines cannot interpret from performance data alone: broken or redefined tracking, a pricing shift, a product launch, an exceptional market disruption, an implausible channel estimate, or a budget move that conflicts with a strategic commitment. This allows routine optimization to proceed while reserving human attention for context-heavy and consequential decisions.
Key takeaways
Campaign automation reduces response time, while MMM addresses cross-channel explanation; neither replaces the other.
Human oversight has three control points: defining objectives and inputs, governing execution and anomalies, and interpreting results.
Reported performance improvements should be evaluated in light of study design, business changes, and alternative explanations.
Open-source models and AI-assisted coding reduce technical barriers, but data reconciliation, assumption testing, and business context remain expert tasks.
The strongest operating model links automated action, measurement, experimentation, and human decisions in a documented feedback loop.
As marketing systems gain more authority, oversight will need to become more explicit rather than more occasional. Organizations that define decision rights, preserve context, and test what their systems claim to learn will be better positioned to benefit from automation without surrendering accountability.
A revenue-focused SEO strategy starts with a different decision: organic visibility is a means, not the outcome. Rankings and traffic remain useful indicators, but priorities should ultimately reflect the sales, margins and profit that search can influence.
The practical payoff is a more defensible investment plan. By combining search demand with commercial value, an SEO team can identify which pages deserve attention, sequence work around likely business impact and explain its choices in terms leadership can compare with other acquisition channels.
Key takeaways
Treat rankings and organic sessions as diagnostic signals rather than final business outcomes.
Evaluate search demand alongside margins, average order values and existing organic performance.
Prioritize commercially valuable pages that are decaying or already close to stronger visibility.
Use paid-search conversion data to compensate for organic search’s limited query-level conversion reporting.
Connect content, internal links and digital PR to the commercial page clusters they are intended to support.
Build the strategy from the business model backward
Traditional keyword research begins with the search market: query volume, ranking difficulty, current positions and estimated traffic. The supplied Search Engine Land article argues that these demand-side measures reveal where an audience exists but not where that audience is most valuable to the business.
A commercial planning process therefore needs a second layer. Margin by category, transaction value and the long-term profitability of customer segments can materially change which opportunities deserve investment. A lower-volume category may be more attractive than a popular one when each resulting sale contributes more profit.
Planning question
Demand-side evidence
Value-side evidence
Where is there an addressable search audience?
Search volume, intent and ranking difficulty
Not sufficient on its own
Which area matters most to the business?
Current organic visibility and traffic potential
Margin, transaction value and customer profitability
Where could SEO produce a meaningful result?
Ranking position and competitive gap
Potential sales, revenue and profit contribution
This framing does not make keyword data less important. It changes its role. Demand establishes whether an opportunity exists; commercial evidence determines how much that opportunity should matter.
Use a commercial scorecard without inventing false precision
The article identifies organic sales, revenue, profit, average order value, average margin per sale and channel return on investment as useful financial measures. Obtaining them generally requires analytics data to be connected with transactional records. Channel costs also need to be captured if the organization wants a meaningful view of return rather than revenue alone.
One especially useful measure in the source is organic profit per sale, calculated as organic profit divided by organic sales. It shows the average profit contribution associated with each organic transaction. Broken down by category, subcategory or landing page, it can reveal that two similarly sized traffic opportunities have very different economic consequences.
These figures should guide prioritization without being presented as more certain than the underlying attribution allows. Organic search can assist a purchase that is eventually credited elsewhere, while branded demand may reflect earlier marketing activity. The scorecard is therefore best used as a consistent decision framework, not as a claim that every sale has one perfectly identifiable cause.
A workable prioritization sequence is:
Identify categories, products or services with attractive margins or transaction values.
Measure relevant search demand and classify the intent behind it.
Review current rankings, page performance and the competitive gap.
Estimate the commercial role of improving each page, using available sales and profit data.
Rank initiatives by the combined strength of business value, demand and realistic opportunity.
The process does not require an elaborate universal formula. A transparent qualitative score can be more useful than a highly precise number built on weak assumptions. What matters is that the same commercial questions are applied across competing SEO initiatives.
Organize execution around defend, capture and compound
Once commercially important areas are known, SEO tactics can be organized by the job they perform. This prevents content production, technical work, link acquisition and conversion improvements from becoming disconnected activity streams.
Defend revenue-bearing pages
Commercial pages can lose performance as competitors improve, result pages change and content becomes dated. The source consequently recommends reviewing valuable existing pages before defaulting to new production. Useful interventions include finding competitive content gaps, restructuring information into readily extractable formats such as tables where appropriate, reviewing drafts against competing pages and strengthening internal links.
This is a defensive revenue task as much as a content task. A modest recovery on a page with proven transactions may be more consequential than publishing an informational article with a much larger theoretical audience.
Capture opportunities near meaningful visibility
The article highlights transactional terms ranking in positions 10 through 20. These queries are already associated with pages that search engines consider relevant, yet their visibility may be too limited to produce substantial traffic. Filtering that group by commercial intent and business potential creates a more focused recovery list than treating every near-Page 1 keyword equally.
Content improvements, internal links and relevant authority building can then be directed at the pages with both a plausible ranking opportunity and a valuable destination. The principle is broader than any fixed position range: closeness to visibility matters only when the underlying query and page can contribute to the business.
Compound authority around commercial clusters
Informational content still has a role because a strategy restricted to transactional queries eventually runs out of room. Its purpose should be explicit: answer relevant audience questions, establish topical depth and pass users and internal authority toward appropriate commercial pages.
The same logic applies to digital PR. The supplied article favors campaigns that are thematically connected to priority product categories and use an on-site destination within a deliberate linking environment. That architecture gives earned attention a route to support commercially important clusters instead of leaving links isolated from the pages expected to generate returns.
Connect SEO decisions with paid-search intelligence
Organic reporting commonly provides landing-page conversion data without revealing exactly which query led to each purchase. The article proposes recent paid-search data as a practical source of conversion intelligence, with seasonality taken into account. It specifically suggests reviewing a recent 30- to 90-day window to identify keyword patterns associated with sales and valuable customers.
This evidence should inform, rather than mechanically dictate, organic priorities. Paid and organic results occupy different environments, and advertisement performance does not guarantee an equivalent SEO result. Even so, paid-search data can reveal commercially productive language, offers and landing-page themes that ordinary organic keyword tools cannot connect directly to transactions.
The resulting collaboration can work in both directions. Paid data helps SEO choose valuable queries and pages; organic landing-page performance can expose content and conversion lessons that benefit the broader acquisition program. Shared commercial definitions also make budget discussions less dependent on channel-specific metrics.
Make revenue accountability part of the operating rhythm
A commercially aware strategy needs reporting that follows the chain from work to outcome. Technical fixes, content changes and new links remain important, but they should be connected to changes in qualified visibility, landing-page behavior, transactions and profit where the available data permits.
That chain also improves diagnosis. If rankings rise without sales, the problem may involve intent, offer alignment or conversion performance. If revenue rises but profit does not, the strategy may be attracting low-margin orders. If a high-margin category has demand but little visibility, the case for targeted SEO investment becomes clearer. These interpretations are more useful than celebrating traffic growth in isolation.
The next stage for revenue-focused SEO is not the abandonment of technical excellence or audience-building content. It is the consistent connection of those capabilities to economic choices. Teams that establish that connection can direct their next unit of effort toward the pages and markets most likely to matter.
AI-powered marketing data activation is not simply the use of a model to analyze a database. It is the operating discipline of turning available signals into decisions, actions, and measurable feedback while the information is still useful.
The two source articles examine that challenge at different levels. One presents a focused SEO workflow that joins competitive, search, and engagement data to prioritize content. The other argues for an enterprise performance model in which a unified data foundation and activation layer help marketers pursue business outcomes without continually expanding the technology stack. Together, they show what separates an isolated AI task from a repeatable activation system.
Data activation is a decision system, not another data store
Marketing teams can possess substantial amounts of data and still struggle to act on it. The performance-marketing article identifies fragmented customer profiles, disconnected activation systems, and stale audience definitions as barriers that AI cannot overcome by itself. Its central argument is that many apparent model failures are actually failures in the underlying data and operating architecture.
The content-gap workflow demonstrates the same issue in a narrower setting. Competitive rankings can expose thousands of missing keywords, but the list alone does not establish what the business should publish. The workflow adds Google Search Console signals and Google Analytics engagement data so that AI can interpret competitive opportunity alongside existing authority and business value.
This distinction is fundamental: data collection produces records, analysis identifies patterns, and activation connects those patterns to an approved action. AI can accelerate interpretation and propose a course of action, but it does not eliminate the need for relevant inputs, decision criteria, or an execution path.
Key takeaways
AI activation begins with connected, usable data rather than a model or agent selected in isolation.
First-party performance signals help distinguish attractive-looking opportunities from opportunities that support business goals.
A useful system converts a stated outcome into proposed logic, a reviewable action, and measurable feedback.
Human oversight remains important for competitor selection, exclusions, strategic context, and final approval.
The right foundation combines relevance, quality, and access
A strong activation foundation does not require every available data point. It requires the information needed to make a particular decision, joined at a level that preserves its meaning. More inputs can create more noise when they represent irrelevant markets, incompatible intent, outdated definitions, or entities that should not be compared.
The SEO source illustrates relevance through competitor selection. Its workflow narrows the comparison to three to five sites serving a similar business and audience, while generally filtering out marketplaces, community sites, reference properties, directories, and unrelated publishers that could distort the opportunity set. It also recommends a stakeholder check because product or sales teams may know about strategic competitors that are not yet obvious in organic-search data.
Quality then depends on cleaning the inputs. The workflow removes duplicates and excludes such noise as competitor-branded terms, careers, login and support queries, out-of-scope locations, mismatched intent, and overly broad commercial terms. This is not clerical work around the edges of AI. It defines the boundaries within which the model can form useful clusters and recommendations.
Access is the third requirement. The SEO article describes both manual exports and direct retrieval through Model Context Protocol connections. Either route can support the analysis; the important point is that competitive rankings, first-party search signals, and landing-page outcomes become available within one reasoning workflow. Direct connectivity may reduce transfer work, but it does not replace validation, exclusions, or governance.
At enterprise scale, the performance-marketing source extends this principle to customer profiles and activation destinations. It argues that the data foundation and activation layer should operate as a connected performance engine. That is a broader architectural claim than the SEO example, but both approaches depend on the same underlying capability: AI must be able to interpret trusted context and pass an approved decision toward execution.
A practical loop turns signals into marketing action
The sources suggest an operating loop that can be applied beyond SEO or audience management. The specific datasets and delivery channels will vary, but the decision sequence remains useful:
Define the outcome. Begin with the result the team wants to influence, such as improving a content opportunity, increasing customer value, or reducing churn. A clear outcome gives the model a basis for prioritization.
Select decision-relevant signals. Combine external opportunity data with first-party evidence and business performance. In the content-gap example, those roles are filled by Semrush, Google Search Console, and Google Analytics respectively.
Normalize and filter the inputs. Remove duplicate, stale, irrelevant, or mismatched records before asking AI to detect patterns. Retain the exclusions and assumptions so that another reviewer can understand the analytical boundary.
Ask AI for structured proposals. The output should be reviewable logic rather than an opaque verdict: topic clusters, priority tiers, audience conditions, supporting evidence, and uncertainties are more useful than a bare recommendation.
Apply business review. Marketers and relevant stakeholders should confirm that the proposed logic reflects strategy, customer meaning, brand constraints, and operational reality.
Activate through a defined destination. An approved decision must connect to a content roadmap, audience system, campaign platform, or another execution process. Without this step, the workflow remains analysis rather than activation.
Measure and feed back the result. Performance data should return to the decision process so the team can refine its definitions and priorities instead of repeatedly starting from a static segment or report.
The SEO workflow makes the prioritization stage concrete. It looks for missing competitor topics, areas where competitors rank higher, and subjects where the site already leads. Search Console impressions and positions between 8 and 20 can indicate existing topical association, while Analytics engagement and conversion signals add evidence of business relevance. The resulting roadmap is therefore based on the relationship among opportunity, attainability, and value rather than search volume alone.
The enterprise source applies outcome-led reasoning to audience creation. It describes an mParticle capability that lets a marketer express an objective in plain language, after which an agent proposes audience logic for review and approval. It also presents Audience Expansion and Household Reach as examples of using first-party data to seek additional prospects or address a wider decision-making unit. These are vendor-reported product examples, not independent proof of performance, but they illustrate how an AI proposal can be connected to an activation path.
Governance and measurement keep automation useful
The sources do not support a hands-off model of marketing. The performance article explicitly frames the marketer as the leader and the agent as a collaborator. The SEO workflow likewise preserves human judgment when selecting competitors, defining exclusions, checking stakeholder knowledge, and deciding which opportunities belong on the roadmap.
That division of labor offers a practical governance model. AI can reduce the effort required to reconcile large datasets, group related signals, draft audience logic, and surface patterns. People remain accountable for the objective, data scope, acceptable trade-offs, approval, and interpretation of results. A proposed segment or content cluster should therefore be traceable to its inputs and understandable before it reaches production.
Measurement should also match the original outcome. The content-gap source uses organic sessions, engagement rate, average engagement time, key events or conversions, and landing-page performance to add business context. The performance source emphasizes outcomes such as customer lifetime value and churn rather than the operational completion of an audience-building task. In both cases, task completion is not the same as marketing success.
A sensible maturity path is to begin with one bounded decision where data sources, reviewers, activation destinations, and success signals are identifiable. Once that loop is reliable, the organization can reuse its controls and feedback process for additional use cases. The durable advantage will come from shortening the distance between evidence and action while preserving the context and accountability that make the action worth taking.
I often get asked why I “only” run each prompt one time per day.
For me, the answer comes down to signal quality. Running a prompt once daily gives me enough consistent data to understand performance without overloading the process with unnecessary repetition.
The statistics show that a single daily run is plenty. It gives me a reliable view of how prompts behave over time, while keeping the workflow focused, efficient, and easier to interpret.
AI search visibility cannot be managed as a conventional ranking contest. Brands must influence the information environment from which AI systems construct answers, then measure how often and how persuasively they appear across varied prompts and conversations.
A useful strategy therefore connects two sides of the problem: the buyer questions that create demand and the owned, earned, community, and sponsored sources that shape an AI system’s response. The result is a measurement program designed for probabilistic visibility rather than a misleading imitation of keyword rank tracking.
Replace rank tracking with a map of buyer conversations
Traditional search reporting assumes that a query produces a results page on which a domain occupies a reasonably observable position. The source on prompt-level measurement argues that this model does not transfer cleanly to AI assistants. Responses can vary with conversation history, location, personalization, model version, retrieval availability, follow-up questions, and timing. There is consequently no single, durable equivalent of a number-one ranking.
The more defensible question is not whether a brand ranks, but how frequently it is included in commercially relevant conversations. That changes the unit of analysis from an isolated keyword to a buyer scenario. A scenario can begin with category discovery, progress through use-case evaluation and vendor comparison, and end with objections, alternatives, implementation concerns, or validation of a shortlist.
The prompt-level source recommends organizing questions by intent and grouping related variations into clusters. A category cluster, for example, can reveal broad awareness, while industry and feature clusters show whether the brand remains visible as requirements become more specific. Cluster-level patterns are more informative than the result of one carefully worded prompt.
Multi-turn testing is equally important. A company absent from an opening request may enter the answer after the buyer specifies an industry, integration, budget consideration, or operating constraint. Testing only the first response would miss that later influence and could make a relevant brand look invisible.
Build a prompt library that balances consistency and realism
A prompt library serves two purposes that need to remain distinct. Synthetic prompts provide a repeatable benchmark: the same scenarios can be tested over time, across models, or against competitors. Real customer questions provide ecological validity because actual buyers tend to supply context, combine constraints, and use less orderly language than generated test prompts.
The prompt-level measurement source suggests drawing real questions from sales calls, customer interviews, support conversations, community discussions, internal and on-site search, and AI transcripts that customers voluntarily provide. These inputs can expose needs that keyword tools or generated variations fail to represent. Synthetic prompts should establish the controlled test set, while customer evidence should continuously correct and expand it.
Each tracked scenario should carry enough context to support useful segmentation: buying stage, product category, audience or use case, industry, geography where relevant, AI system, and conversation path. The library should also preserve stable benchmark prompts while allowing a separate portion to evolve with customer language. Without that distinction, a changing score may reflect a changed test set rather than changed market visibility.
This design also prevents a common measurement error: treating the prompts that a marketing team can imagine as a representative sample of all AI use. No organization can observe every private assistant conversation. A prompt library is a strategic testing instrument, not a complete census of audience behavior.
Strengthen the information supply behind AI recommendations
Measurement identifies where a brand appears or disappears, but it does not create the underlying evidence. The strategy sources collectively point to three connected supply layers: a clearly defined brand entity, deep and accessible owned content, and corroboration from sources outside the company’s control.
Make the brand and its expertise unambiguous
The SEO-priorities source emphasizes consistent brand information across established profiles, directories, publications, and other sources that may help systems understand an entity. It specifically points to platforms such as LinkedIn, Crunchbase, Wikipedia, and relevant industry directories, while also stressing credible author identities and closer coordination between SEO and public relations.
The practical objective is consistency, not indiscriminate profile creation. The brand’s name, category, products, areas of expertise, audience, and expert authors should reinforce the same positioning wherever those details legitimately appear. Prompt testing can then reveal whether AI answers reproduce that intended position or substitute an inaccurate one.
Connect topical depth to usable site architecture
The SEO-priorities source favors comprehensive topic clusters over thin pages aimed at isolated high-volume terms. The site-architecture source adds an important structural layer: content must also be organized through understandable labels, taxonomy, wayfinding, and relationships if users and machines are to locate and interpret it effectively.
These ideas are complementary. A collection of articles does not become topical authority merely because it covers related keywords. The pages need a coherent model of the subject, clear connections, and paths that expose the most useful material. Architecture is therefore part of AI visibility, not just a usability or crawlability concern.
Distinguish earned corroboration from paid distribution
Two sources agree that signals outside the brand’s website matter, but they emphasize different routes. The SEO-priorities article focuses on earned media, unlinked mentions, and genuine participation in communities such as Reddit, Quora, and specialist forums. It argues that relevant editorial authority and authentic discussion can be more valuable than a large volume of weak links.
The paid-media article goes further, proposing that native sponsorships, detailed third-party reviews, user-generated content, podcast mentions, and baked-in video sponsorships can become durable information assets rather than disappearing with the media budget. Its central argument is that text and transcripts containing specific brand-use-case relationships may remain available to retrieval or training systems after a campaign ends.
That paid-media thesis should not be confused with proof that every placement will affect every model. It is a strategic interpretation offered by the source, and access, ingestion, retrieval, and recommendation behavior can differ between systems. Paid provenance also does not create independent consensus. Any review or sponsorship program should preserve transparent disclosure, truthful customer experience, platform compliance, and editorial integrity; otherwise it may generate abundant text but weak evidence.
Use a scorecard that separates presence, prominence, and meaning
A single visibility percentage cannot explain how an AI system positions a brand. The prompt-level source identifies several complementary dimensions that can be combined into a practical scorecard.
Measure
Question it answers
How to interpret it
Inclusion rate
In what share of tracked prompts does the brand appear?
Use as a benchmark and segment it by intent, category, audience, geography, or AI system rather than relying only on an overall average.
Response prominence
Is the brand a leading recommendation, one option among several, a late mention, or merely an alternative?
Treat prominence as influence within the answer, not as a stable search ranking.
Brand framing
Which strengths, weaknesses, differentiators, price perceptions, and ideal-customer associations recur?
Compare the observed description with intended positioning and identify unsupported or missing associations.
Sentiment and confidence
Is the brand described favorably, unfavorably, or ambiguously, and how firmly is that assessment presented?
Review the supporting language and context; a simple positive-or-negative label can hide important qualification.
Repeated observations matter because AI output is variable. A reporting period should use documented prompts, conversation paths, models, and relevant settings so later runs are meaningfully comparable. Results should still be described as observed frequencies within the test set, not as universal market share.
Traditional analytics remains useful but answers a different question. Referral visits, branded search behavior, conversions, and standard search performance can show activity reaching measurable properties. Prompt testing estimates influence inside generated answers, including journeys that may never produce a click. The two evidence streams can be reviewed together, but prompt visibility should not be presented as causal proof of revenue without a defensible attribution link.
Turn AI visibility into a cross-functional operating system
The sources collectively move AI visibility beyond the boundaries of an SEO reporting team. Content teams shape topical evidence; technical and information-architecture teams determine whether it can be found and understood; PR and community teams earn external corroboration; paid media may fund durable native content; and sales or support teams supply authentic buyer language.
A workable review cycle should connect observed prompt gaps to a specific intervention. Low discovery inclusion may indicate weak category association. Strong inclusion but inaccurate framing can point to inconsistent messaging or third-party narratives. Visibility that disappears in industry-specific follow-ups can expose a topical or evidentiary gap. Poor prominence despite frequent mentions may signal that competitors have clearer proof for the evaluated use case.
Key takeaways
Measure the frequency of inclusion across buyer scenarios instead of claiming a universal AI rank.
Combine stable synthetic benchmarks with real customer questions and multi-turn conversation paths.
Build visibility through consistent entities, coherent topic architecture, authoritative owned content, and credible external corroboration.
Track prominence, framing, sentiment, and confidence alongside basic inclusion.
Keep paid placements, earned mentions, and owned content distinct in reporting even when they support the same visibility objective.
Present prompt testing as sampled evidence, not a complete view of private AI conversations or proof of commercial attribution.
As AI interfaces, retrieval systems, and customer behavior continue to change, the strongest programs will preserve a stable measurement baseline while updating the evidence and conversation paths around it. That balance makes the strategy adaptable without making its reporting arbitrary.
Three Google updates reported by CrushPress.AI affect different points in a publisher’s measurement workflow: assessing search demand, checking whether pages can appear in search, and tracking visits after a click.
Together, the changes make some analysis easier, but they also underline an important distinction: demand, indexability, and on-site traffic are separate signals. Publishers need to read them in sequence rather than treating any one report as a complete account of search performance.
Key takeaways
Google Trends now offers preceding-period comparisons that can put changes in search interest into context.
Search Console’s page indexing report resumed updating after a reported three-week delay, restoring fresher diagnostic information.
Google Search now sends AMP visitors to publisher-hosted pages instead of presenting cached pages within Google’s AMP viewer.
Google reportedly characterized the AMP change as a delivery and measurement update, not a ranking change.
Google Trends adds context before content decisions
Google Trends sits near the beginning of the measurement process. It indicates relative search interest, helping publishers evaluate whether attention around a term or topic is gaining momentum, declining, or following a recurring pattern.
CrushPress.AI reported that new controls above the Trends timeline can surface changes for periods such as week over week, month over month, and selected year-over-year comparisons. A preceding period can also be overlaid on the chart with a comparison line. This reduces the work required to establish a historical baseline before interpreting a movement.
The practical benefit is better timing context. A rise in current interest is more meaningful when compared with the immediately preceding interval, while a year-over-year view can help reveal whether apparent momentum may instead reflect seasonality. Trends still addresses audience interest rather than the performance of a publisher’s individual pages, so its findings should guide investigation rather than serve as traffic or ranking evidence.
Fresh indexing data restores a missing diagnostic layer
Search Console answers a different question: whether Google can find and index pages on a particular site. Its page indexing report separates indexed and non-indexed pages, provides reasons pages may not be indexed, and can display impressions alongside the indexing chart, according to the source report.
CrushPress.AI reported that this report had remained stuck on June 11, 2026, for roughly three weeks. As of Friday, July 3, it was displaying information through June 29. The refresh matters because an outdated diagnostic view can make a recent publishing, crawling, or indexing problem difficult to distinguish from reporting latency.
The episode also offers a measurement caution. When a reporting interface is delayed, the age of its latest data should be checked before teams infer that a recent technical change caused an indexing movement. With fresher data available, publishers can return to examining affected pages and the reasons Search Console assigns, while still separating reporting status from the underlying indexing status.
Direct AMP visits simplify the post-click measurement path
The AMP update concerns what happens after a searcher selects a result. CrushPress.AI reported that Google Search now directs AMP users to the publisher-hosted AMP page rather than a cached version displayed through Google’s AMP viewer. Google told the publication that the change should simplify analytics and tracking while reducing some maintenance associated with supporting AMP content.
This shift can make the measurement path easier to understand because the destination is again the publisher’s own host. It does not, however, establish that AMP pages will gain more visibility. The report explicitly said Google described the change as unrelated to ranking and said the serving and ranking treatment of AMP in Search and Discover would remain the same.
The distinction is especially important because AMP’s broader search role has already diminished. The source noted that AMP no longer receives preferential treatment in Top Stories and that such pages are encountered less often than before. The update therefore looks less like a revival of AMP as an SEO advantage and more like a cleanup of delivery, ownership, and analytics for publishers that continue to use the format.
A more coherent search measurement workflow
Read together, the updates describe three successive layers of analysis. Trends helps establish whether an audience is searching for a subject. Search Console helps determine whether relevant pages are eligible to be discovered through indexing. Publisher analytics then records what visitors do after reaching the site, with the new AMP routing potentially making that last step less complicated.
This sequence helps prevent common category errors. Increasing search interest does not prove that a site is indexed for the topic. Successful indexing does not guarantee impressions or visits. Cleaner AMP analytics does not indicate a ranking improvement. When the signals diverge, teams can investigate the layer where the break occurs instead of forcing all three into a single performance narrative.
Publishers should watch whether the refreshed reports remain timely and whether direct AMP delivery produces cleaner on-site data in practice. The durable opportunity is a measurement process that connects market demand, technical visibility, and owned-site behavior while preserving the limits of each signal.
AI search visibility is no longer a single ranking question. A brand can appear in an answer, earn a citation, receive a visit, influence a later conversion or remain invisible to conventional attribution at each stage.
The practical response is to connect content optimization, citation monitoring and business measurement. The sources collectively show why those disciplines must operate as one system, even though no single metric can yet describe the entire AI-assisted customer journey.
Key takeaways
AI visibility begins with content that can be discovered for a broad topic, understood in context and extracted into an answer.
A citation is evidence of selection, not proof that a user visited or converted.
Referral traffic captures only journeys that include a trackable click; direct visits, calls and delayed conversions can obscure AI influence.
Measurement should progress from answer presence to citations, referrals, conversions and lead quality.
Global standards should govern technical implementation and reporting, while market experts supply differentiated local knowledge.
Visibility depends on retrieval, selection and presentation
Traditional rank tracking starts with a query and a results position. AI-generated answers add intermediate decisions: the system may decompose a request into related subqueries, retrieve supporting pages, synthesize their information and choose which sources to display. Visibility can therefore be gained or lost before a citation is ever shown.
A Search Engine Land article about Google query expansion distinguishes traditional query expansion from AI Mode query fan-outs. In its account, expansion connects searches through synonyms, intent and related topics, while fan-outs generate multiple subqueries during answer construction. The article recommends using Google Search Console impressions and unexpected but relevant queries as signals for strengthening topic coverage, rather than as an invitation to add disconnected keywords.
That retrieval perspective complements HiGoodie’s travel optimization guidance, which emphasizes direct answers, FAQs, schema markup, topical authority and content based on real traveler questions. That source reports that 40% of travelers use AI to research, compare and organize travel decisions. The percentage should be treated as reported by the article, but its strategic implication is clear: content must supply both a concise answer and enough surrounding context to be interpreted correctly.
Selection does not guarantee equal exposure. Search Engine Land’s report on recipe links in Google AI Mode describes a visual treatment that can place creator names, images, ratings and ingredient counts near prominent links. It also notes that Google had been testing a top-stories carousel in AI Overviews but that the feature did not appear to be live at the time reported. These examples make presentation a separate measurement dimension: two cited publishers may receive materially different opportunities to be recognized or clicked.
A citation is not the same as a visit or a customer
The recipe treatment illustrates the distinction between attribution and distribution. More recognizable links may improve the path to a publisher, but the report leaves open whether they will generate enough meaningful traffic. Citation counts alone cannot resolve that question because a source can inform an answer without producing a click.
The opposite measurement problem also occurs: AI may influence a customer without producing a visible referral. A Search Engine Land article based on an analysis of nearly 30 million inbound leads reports that AI-attributed leads remained a small share of total volume but were growing and appeared across multiple industries. It also describes customers who encounter a recommendation in an AI service and later call a business, creating journeys that may be classified as direct or remain unattributed.
The same source is explicit about the dataset’s limits: it could identify cases in which customers named an AI platform as part of the route to contacting a business, but it could not reveal their prompts, platform choices or the reasons a particular company was recommended. That is evidence of association within a reported journey, not a complete causal explanation.
Organizational interest is also moving toward this broader view. Profound’s recap of Zero Click New York 2026 says that more than 1,000 marketing leaders gathered on June 11, 2026, and that sessions addressed Claude’s citation mechanics, ChatGPT’s emerging advertising business and content signals associated with AI trust. An event recap is not outcome data, but the subjects it highlights show citations, distribution and measurement being treated as connected management questions.
Use a measurement ladder instead of one AI metric
A workable reporting model separates observable stages rather than combining them into a proprietary visibility score. Each stage answers a different question and carries a different evidentiary limit.
Measurement layer
Question it answers
Useful evidence
Main limitation
Answer presence
Does the brand or page appear for relevant prompts?
Repeatable prompt checks across selected platforms, markets and use cases
Outputs can vary, so a single observation is not a stable benchmark
Citation visibility
Which pages are named or linked as sources?
Citation frequency, cited URLs, placement and visible source treatment
A citation does not establish attention, a click or preference
Referral activity
Did a user arrive through a trackable AI link?
Analytics referrals, landing pages and tagged campaign links where available
Non-click journeys and incomplete referrer data remain unseen
Conversion influence
Did AI discovery contribute to an inquiry or sale?
Lead-source questions, call attribution and customer-reported discovery paths
Self-reporting and multi-touch journeys complicate causal claims
Business quality
Are AI-influenced customers valuable?
Qualified leads, completed transactions and downstream customer outcomes
Low volume can make comparisons unstable
These layers should be reported separately before they are interpreted together. For example, rising citation visibility with flat referral traffic could indicate a zero-click exposure pattern, weak source presentation or a mismatch between cited content and user intent. Rising customer-reported AI discovery without comparable referrals would instead point to an attribution gap. Both observations warrant investigation, but neither proves its suspected explanation by itself.
Content research can connect the upper and lower portions of the ladder. Search Console queries can reveal adjacent questions already associated with a page, while citation observations show whether AI systems select that page for related answers. Referral and lead data then indicate whether any of that exposure reaches the business. Optimization becomes a testable cycle when the baseline, content change and subsequent observations are recorded consistently.
Govern shared infrastructure while localizing expertise
Measurement becomes harder when teams use conflicting entity definitions, technical rules or reporting methods. The problem is especially acute for multinational organizations because an AI system can synthesize material across markets rather than respecting the operational boundaries used inside the company.
A Search Engine Land analysis of global SEO ownership argues that hreflang, localization and technical SEO remain necessary, but that hreflang handles routing rather than deciding which market perspective an AI answer should prioritize. It recommends central governance for areas in which inconsistency creates enterprise-wide risk, including CMS rules, structured data, entity definitions, AI crawler policies, measurement frameworks and technical infrastructure.
The same analysis places audience research, regulatory information, local authority building and market expertise closer to in-market teams. Its central tension is not simply standardization versus translation. Multiple near-identical market pages may provide less differentiated evidence than content grounded in local terminology, regulations, customer expectations and industry practices.
That division of responsibility also applies outside international SEO. A central team can define how citations, referrals and AI-influenced leads are recorded, while subject specialists validate the underlying claims and answer the questions their audiences actually ask. The travel guidance’s focus on traveler intent and the query-expansion article’s focus on adjacent questions both support this combination of shared structure and domain-specific knowledge.
The next useful advance will come from disciplined linkage: connecting the content changes made, the answers and citations observed, and the customer outcomes recorded without overstating what any one dataset proves. Organizations that establish that evidence chain can adapt as interfaces and citation treatments change, while keeping investment decisions tied to measurable audience and business value.