I’ve always found the ability to share insights seamlessly to be crucial in our fast-paced digital world. One tool that I’ve come across is the generation of links to custom dashboards, which can be viewed by absolutely anyone.
Imagine the convenience of sending a link to your team or stakeholders, enabling them to access the dashboard data in real-time. This not only promotes transparency but also enhances collaboration by ensuring everyone has access to the same data, whenever they need it.
Through these easily shareable links, I’ve been able to bring a level of accessibility and efficiency to data sharing that seemed challenging before. It’s truly a game-changer, especially when managing multiple projects across different teams.
If campaign performance looks unstable, resist the next bid or budget change. Google Ads cannot optimize around the outcome you intended; it can only react to the conversion signal it receives. A missing purchase, duplicated form submission, or low-intent contact counted as a lead turns CPA and ROAS into confident-looking answers to the wrong question.
Your first job is to make the signal trustworthy. Then you can use cross-channel reporting, search-term evidence, and negative keywords to improve performance without confusing a tracking change for a marketing win.
Define the signal before you optimize the spend
A conversion name such as “form submit” is not a measurement specification. It does not tell you whether the form was accepted, whether a duplicate was removed, whether the person was qualified, or whether the event represents a business outcome at all.
For every action currently treated as a conversion, write down:
Business outcome: What changed for the business: a completed order, an accepted lead, a booked appointment, or another explicit result?
Completion condition: What observable event proves that outcome occurred? A button click alone rarely proves that the receiving system accepted the transaction.
Funnel stage: Is this a final outcome, a qualified intermediate action, or a diagnostic engagement signal?
Identity and deduplication: Which order, lead, or internal event ID prevents one outcome from being recorded twice?
Value: Does the action carry revenue, an approved proxy value, or no monetary value? Document the reason rather than silently assigning one.
System of record: Which backend, CRM, booking system, or commerce platform can confirm that the outcome was real?
Owner: Who investigates when the platform count and the operational record diverge?
The correct measurement boundary depends on the surface. Where your account uses calls, lead forms, or message assets, the ad interaction may move contact intent closer to Google Ads. That does not make every tap, open, or connection a qualified lead. Decide what must happen after the interaction before it earns that label.
Conversion path
Useful completion boundary
Reconciliation evidence
Website purchase
The order is accepted, not merely started
Order ID, status, value, and currency in the commerce system
Website or lead-form submission
The receiving system accepts a valid submission
Lead ID and the later qualification or rejection status
Call or message
The contact meets your documented business rule
Platform reference or timestamp matched to a disposition in the operating system
Micro-conversion
The engagement action actually occurs
Analytics event used for diagnosis, not automatically treated as revenue
Build a conversion hierarchy, not a bag of events
Put final business outcomes at the top, qualified intermediate outcomes below them, and diagnostic events at the bottom. Use the highest-quality signal that can support the decision you are making. More event volume is not automatically better input. Promoting a page view or unverified click to “conversion” status may make an automated system look busier while moving it farther from revenue.
If a campaign does not yet produce enough final outcomes for stable decisions, preserve the distinction. Report the lower-funnel result and the supporting signal separately. A volume constraint is useful information; relabeling weak intent hides it.
Audit the conversion chain before interpreting CPA
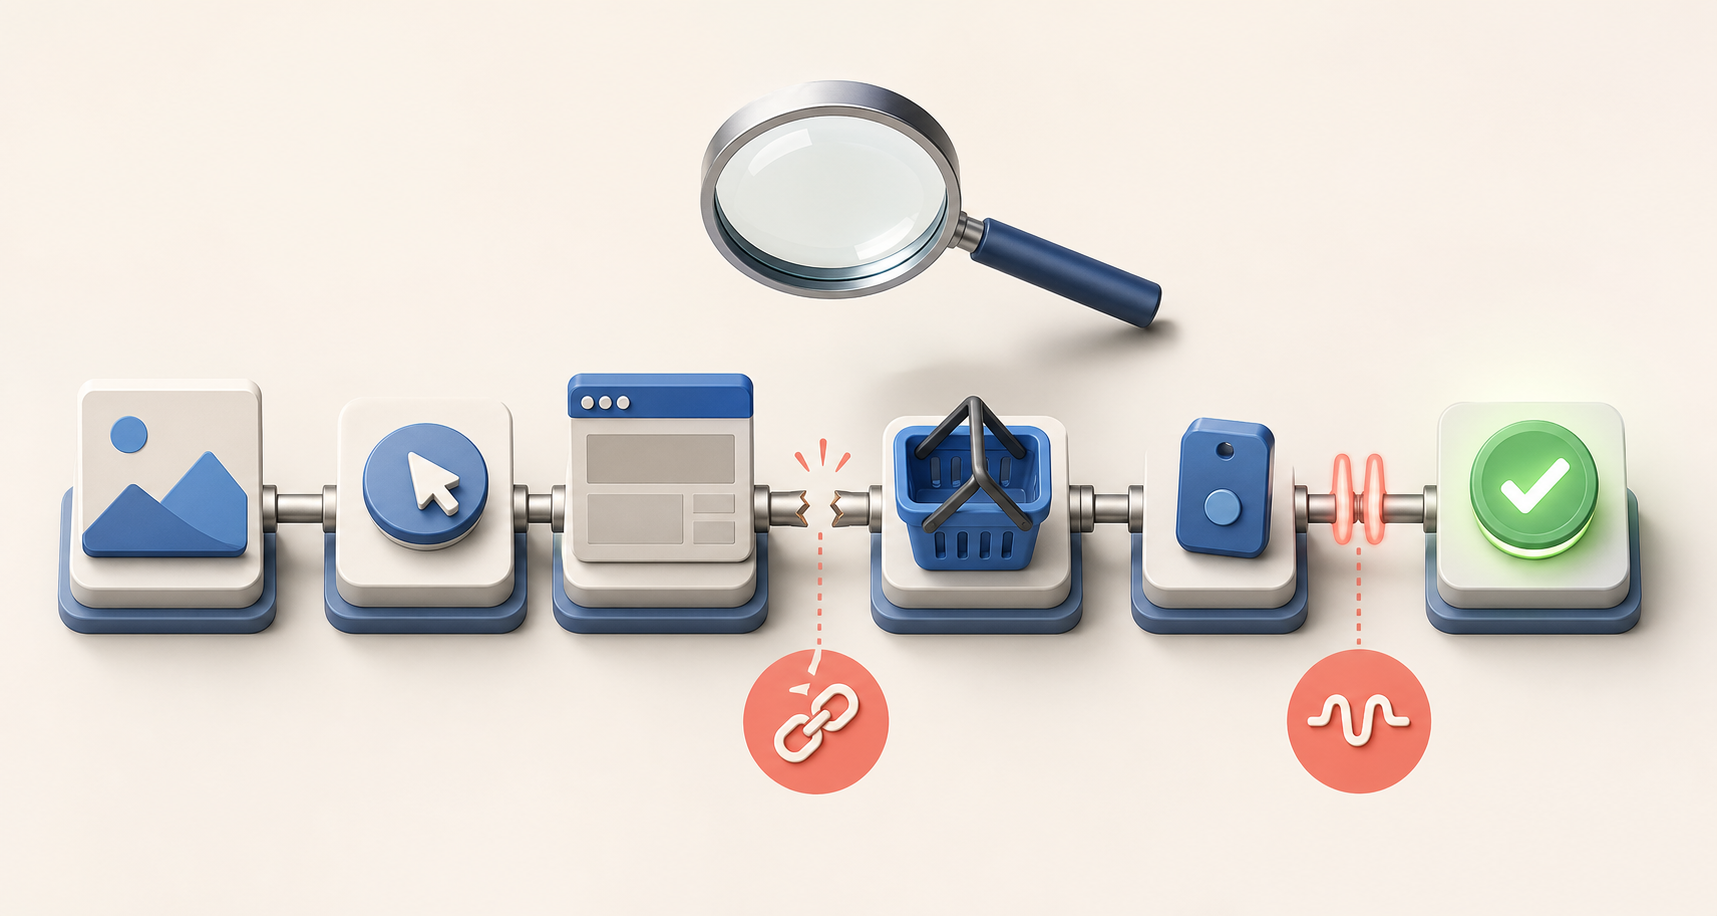
A conversion can fail at several points between the customer’s action and the report. Checking only whether a tag fired leaves most of that chain untested. Audit the complete path in this order:
Outcome: Complete the intended action and confirm that the business system accepted it.
Trigger: Verify that the conversion condition occurred once, at the right moment, with the expected identifier and value.
Transport: Check that the event moved through the applicable browser, tag, server, API, consent, and integration layers.
Platform record: Confirm that the event appeared under the intended conversion action rather than a similarly named action.
Reconciliation: Match the platform record to the order, lead, appointment, call, or message disposition in the system of record.
Use a controlled test record and document its expected result before running it. For purchases or other actions that can create a charge, use an approved test or staging method. Do not place an unrecoverable live transaction merely to validate reporting.
Your test matrix should cover the paths where implementation defects tend to hide:
Desktop and mobile completion paths.
Direct landing-page visits and the redirects used by campaign traffic.
Cross-domain steps, if the journey moves between domains.
Form success, validation failure, and repeated clicking.
Confirmation-page reloads and browser back-button behavior.
Each enabled call, form, or messaging route.
Accepted, rejected, cancelled, refunded, duplicate, and spam outcomes where those states affect business value.
Record the test ID, timestamp and time zone, device or browser, conversion action, expected value, observed platform result, and backend ID. Use internal identifiers rather than personal data. This creates evidence that another person can inspect without repeating the transaction.
Classify mismatches before fixing them. A missing conversion points toward an absent trigger, failed transport, incorrect mapping, consent behavior, or unavailable integration. A duplicate points toward repeated triggers or weak deduplication. A conversion recorded under the wrong action points toward naming or configuration drift. These defects require different fixes; a general “tracking issue” label is too vague to be actionable.
Do not demand identical totals from systems that use different dates, time zones, attribution rules, inclusion rules, or value conventions. Align those definitions first. Then investigate the unexplained remainder. When you repair a material defect, preserve the old data, annotate the repair time, and define the first clean reporting window. Rewriting history without a documented method can make the next optimization decision less reliable than the last one.
Use cross-channel reporting as a control view, not absolute truth
Once your conversion definitions are stable, a unified reporting layer can reduce the time spent assembling channel exports. Google’s Analytics Data API can provide paid and organic conversion data in one programmatic view that mirrors the Conversion performance report in the Analytics interface.
The capability is in alpha, and access is not universal. Verify eligibility for the exact Analytics property before making it a production dependency. If the property does not expose the feature, keep the same internal reporting contract and populate it from the available interface reports until API access arrives. That lets you improve the operating model without pretending an unavailable feature exists.
Your reporting contract should make every row interpretable. At minimum, document the property or account, conversion-name mapping, channel classification, date and time-zone logic, attribution convention, value and currency treatment, extraction time, and the period in which late revisions are accepted. These are not decorative metadata. They explain why two legitimate reports can disagree.
A unified view centralizes attributed conversion reporting; it does not prove that a channel caused the outcome. Attribution can move credit between touchpoints without changing the number of real orders or qualified leads. Read the data in layers:
Confirm total business outcomes and value in the operational system.
Confirm that Analytics received the intended conversion actions.
Inspect how paid platforms recorded and attributed those actions.
Use the cross-channel view to understand where credit was assigned.
If channel credit changes while backend outcomes stay flat, investigate attribution, classification, or tracking before declaring growth. If backend outcomes increase while reported conversions do not, investigate measurement loss. If both move in the same direction and the definitions remain stable, you have a stronger basis for changing spend.
Automation is most useful for surfacing exceptions: a conversion action disappears, a value field becomes empty, one channel changes abruptly, or the cross-channel total stops reconciling within your normal operating pattern. Let the pipeline find the anomaly. Keep the decision about bids, budgets, and exclusions attached to business context.
Turn trusted conversion data into negative-keyword decisions
Negative keywords become safer after measurement is credible. Before that point, a relevant query can appear unproductive simply because its outcome was missed or classified under the wrong action. Excluding it would reduce waste in the report while potentially blocking valuable demand in the market.
Review each candidate search term by cause:
Clearly misaligned: The words indicate the wrong product, service, audience, location, or intent.
Relevant but early: The term belongs to the buyer journey but is being judged against an outcome it is unlikely to produce immediately.
Relevant and expensive: The term has consumed enough budget without producing the defined outcome.
Uncertain: The sample is sparse, the buying cycle is incomplete, or measurement quality is in doubt.
Your threshold should reflect the account’s job. A growth-focused campaign needs room to discover demand and can tolerate more exploration. One practical trigger is to review a query after it has spent more than three times the target CPA over 90 days without a conversion. Treat that as a decision trigger, not an automatic deletion rule: confirm tracking health, intent, and buying-cycle timing first.
An efficiency-focused account can use a stricter, budget-based trigger tied to the amount you are willing to spend on one query without an outcome. A 30-day window can be too aggressive outside a short promotion. A 90-day window is a balanced starting point, while a 365-day view can be more appropriate for a long buying cycle. Keep the threshold and window together in the decision log; either one without the other is ambiguous.
Competitor queries also need an explicit policy. Do not exclude them merely because they are competitor terms, and do not preserve them merely because automation might find a conversion. Decide whether that intent fits the offer, economics, and brand strategy. Then judge the terms under the same documented evidence rules as other traffic.
Use this approval sequence for every material negative:
Confirm that the relevant conversion actions were healthy during the evidence window.
Classify the query’s intent and its alignment with the ad and landing page.
Check spend, outcomes, target CPA, and buying-cycle maturity.
Select exact, phrase, or broad scope deliberately.
Record the query, scope, date, evidence window, reason, owner, and rollback condition.
Review affected traffic after the change for both reduced waste and unintended demand loss.
The search-terms report is not a weekly deletion queue. Review it regularly, but add negatives when the evidence and account objective support the decision. Calendar-driven exclusions can teach the campaign a narrower version of your market than you intended.
Run an optimization cadence that protects the signal
Separate measurement maintenance from performance optimization. If you change the conversion definition, negative-keyword scope, bid strategy, and budget in one cycle, the next report cannot tell you which change mattered.
Decision layer
Question to answer
Action
Measurement health
Did a defined action stop, duplicate, move, or change value?
Repair and annotate the signal before interpreting performance.
Business quality
Do orders, lead dispositions, and other backend outcomes support the platform signal?
Correct qualification, deduplication, or value mapping.
Demand quality
Are search terms aligned with the offer, ad, and landing page?
Approve narrow, evidence-based exclusions or improve the message and destination.
Economics
Does clean data support the target CPA, value, and budget decision?
Change bids or budgets only after the earlier layers pass.
Rerun a conversion smoke test after a site release, tag change, CRM integration change, form replacement, checkout update, or contact-route change. On each reporting refresh, check for missing actions, unexpected duplicates, empty values, naming drift, and abrupt channel changes. Review search terms and lead quality at a regular operating interval, but make exclusions only when the chosen evidence window has matured.
Keep one change log for both measurement and media decisions. Each entry should contain the timestamp, owner, hypothesis, affected campaigns or actions, evidence window, expected metric movement, and rollback condition. The log gives you a clean way to distinguish a genuine performance shift from a new definition, delayed data, or implementation failure.
Key takeaways
Define conversions as business outcomes with explicit completion, deduplication, value, and reconciliation rules.
Test the full path from customer action to backend record; a fired tag is only one link in the chain.
Use unified paid and organic conversion reporting as a control view, while preserving attribution and availability caveats.
Choose negative-keyword scope, aggression, and evidence windows according to the campaign’s growth or efficiency objective.
Repair measurement and validate business quality before changing exclusions, bids, or budgets.
Before your next budget change, select one important conversion action and run it through the complete audit. Reconcile it to the business record, document the clean-data start time, and only then review the search terms consuming the most budget. That sequence gives the next optimization decision a signal worth trusting.
You have budget for another acquisition channel, but your dashboard cannot tell you whether growth needs more traffic, better traffic, or a landing page that converts more of the demand you already have. Choosing SEO because it compounds or PPC because it starts quickly will not solve that measurement problem.
You need to give each channel a specific job, compare conversion rates only across similar pages and calls to action, and follow every conversion far enough to see whether it becomes pipeline. Here is how to make that decision without turning a single benchmark into a forecast it was never meant to be.
Choose the channel that removes your current constraint
There is no universally best B2B SaaS acquisition channel. There is only a best fit for the constraint currently slowing your funnel. A company with little qualified search traffic has a different problem from one generating demo requests that sales rejects.
Build durable discovery around problems and searches your buyers already have
Results take time and require consistent, intent-matched content from a capable team
Qualified organic visits, primary landing-page conversions, and resulting pipeline
PPC and SEM
Capture high-intent demand quickly or test a market and offer
Traffic remains spend-dependent, and ongoing cost can be high
Search-term quality, qualified conversions, and cost per qualified opportunity
LinkedIn advertising
Reach professional audiences using role, company, or industry targeting
Paid campaigns can return less than organic strategies
Target-audience visits, qualified leads, and account-level progression
Account-based marketing
Concentrate sales and marketing effort on a limited set of valuable prospects
Concentrated effort creates concentrated risk, even though a major account can justify it
Engaged target accounts, meetings, opportunities, and account progression
Email marketing
Nurture known contacts and move existing interest toward a next step
A useful, permission-based list takes time to build
Qualified next-step conversions and pipeline influenced by the sequence
Trade shows
Create direct conversations and gauge interest in person
Attendance, travel, and presence are costly, while competing vendors make attention scarce
Qualified follow-ups, meetings, opportunities, and customers from event cohorts
Public speaking
Build authority and generate warmer conversations around expertise
The channel depends on a credible speaker and often involves travel expense
Attendee follow-ups, qualified meetings, and influenced opportunities
Webinars
Educate prospects and build trust without an in-person event
Preparation still takes time, and the host must hold attention
Attendance quality, next-step conversions, and influenced opportunities
Email illustrates why channel labels matter. If someone first found you through SEO, later attended a webinar, and finally booked a demo from an email, email completed the conversion but did not create the original demand. Calling every email conversion a new acquisition will overstate email and erase the channels that built the audience.
Before funding a channel, write down four decisions:
Name the constraint. Is the problem insufficient qualified reach, poor landing-page conversion, weak lead quality, slow nurture, or limited access to valuable accounts?
Define the channel’s job. Decide whether it should create demand, capture existing demand, nurture known leads, or accelerate specific accounts.
Name the business outcome. Choose the qualified lead, opportunity, account-stage change, or customer event that will determine whether the channel worked.
Set the decision rule before launch. Record what would make you continue, revise, expand, or stop the campaign. Base that rule on your economics and sales capacity, not on a generic click-through rate.
This prevents a common budgeting error: asking a slow, compounding channel to prove itself on the same timetable as paid search, or asking a nurture channel to produce net-new demand it never received.
Use the 1.1% SaaS benchmark as a diagnostic, not a quota
The available industry benchmark puts the B2B SaaS landing-page conversion rate at 1.1%. That is a useful reference point, but it is not a promise about your site, channel, offer, or sales cycle.
The underlying pool covered 83 companies in 27 industries from 2019 through 2026. Every included company used SEO, while 38 also used content creation, email marketing, or LinkedIn marketing. Home pages, About pages, and other general informational pages were excluded. Those boundaries matter: the 1.1% figure should not be presented as a benchmark for every SaaS website visit.
There is another important boundary. The B2B SaaS rate is an industry-level figure. The page-type rates below cover the broader B2B pool. They are not SaaS-by-page-type cross-tabulations, so you should not claim that every SaaS customer-type page ought to convert at 3.5%.
Benchmark scope
Page type
Conversion rate
How to interpret it
B2B SaaS industry benchmark
Included landing pages
1.1%
A directional reference for comparable SaaS landing-page traffic, not a sitewide target
Broader B2B page-type benchmark
Customer type
3.5%
Pages written for a well-defined client profile align closely with a specific audience
Broader B2B page-type benchmark
Application
3.1%
These pages connect a product or service to a problem the visitor needs solved
Broader B2B page-type benchmark
Product
2.9%
Product pages often receive more transactional intent
Broader B2B page-type benchmark
Service
2.7%
Service-page visitors are often further along in their buying journey
Broader B2B page-type benchmark
Industry
1.8%
These pages must show both sector understanding and relevant expertise
Broader B2B page-type benchmark
Location
1.1%
Generic or duplicated location copy can weaken relevance and conversion
Define one primary conversion for the page. Keep video plays, secondary link clicks, and other engagement events separate from the action that advances the buying process.
Segment before comparing. Break performance out by channel, campaign, page type, audience, and call to action. A sitewide average can conceal a strong product page and a weak location page.
Compare like with like. Evaluate demo pages against demo pages and educational offers against educational offers. Do not use a lower-friction newsletter rate to judge a demo page.
Check your own baseline. Your previous comparable cohorts tell you whether a change improved performance under your actual traffic mix.
Follow the conversion downstream. A higher form-completion rate is not an improvement if qualification, opportunity creation, or customer conversion deteriorates.
A sitewide conversion rate can even decline while acquisition improves. Adding more relevant educational traffic changes the denominator before those visitors are ready to request a demo. That is not a reason to ignore conversion; it is a reason to separate page intent and cohort maturity instead of demanding one blended number.
Match every channel to the right page and call to action
The landing page is part of the acquisition channel, not a handoff that happens after it. If an ad promises a solution for finance teams but sends visitors to a generic home page, the campaign has created its own conversion problem.
Send demand-capture traffic to the most specific relevant page
High-intent SEO and PPC traffic should land on the product, service, application, customer-type, industry, or location page that best matches the query and promise. Preserve that message from the search result or ad through the headline, supporting copy, proof, and primary call to action.
Product or service intent: lead with the problem solved, the relevant capability, and a suitable evaluation step.
Application intent: show how the product handles the named use case rather than repeating a generic feature list.
Customer-type intent: address the role or company profile directly, including the outcomes, objections, and proof that matter to that audience.
Industry intent: demonstrate sector knowledge with relevant language and evidence; changing only the industry name is not enough.
Location intent: explain why location changes delivery, coverage, compliance, availability, or service. If geography makes no meaningful difference, multiplying near-duplicate pages is unlikely to improve the visitor’s decision.
Not every organic visitor is ready for a demo. Educational SEO pages can offer a lower-friction next step, while transactional pages ask for a product conversation. Record those actions separately so the easier conversion does not make the channel look more commercially productive than it is.
Give targeted and relationship channels a continuous next step
LinkedIn advertising and ABM should carry audience specificity onto the destination page. If the targeting is built around a particular customer type or industry, the page should speak to that same group. Sending a narrow audience to broad copy discards the main advantage of the channel.
Trade shows, speaking engagements, webinars, and email need continuity of topic rather than a generic follow-up. The destination should remind the visitor what they engaged with, add the promised evidence or resource, and offer a next step consistent with their level of intent. A webinar attendee who requested education should not be treated as if they submitted a demo request.
Remove friction after you confirm message match
Form optimization cannot rescue irrelevant traffic or a mismatched offer. First confirm that the audience, promise, page, and call to action align. Then remove avoidable friction:
Do not remove fields merely to produce more submissions. If sales needs a field to identify fit or route the lead, deleting it can move work downstream and inflate an unqualified conversion rate. Test the field against qualified pipeline, not form completions alone.
Build a scorecard that connects acquisition to revenue
A landing-page conversion rate tells you where a visitor acted. It does not tell you whether the action was qualified, whether sales accepted it, or whether the channel created a customer. Your scorecard needs to preserve that chain.
Funnel measure
Definition
What a weak result usually tells you to inspect
Eligible landing-page visits
Relevant visits that had a genuine opportunity to complete the page’s primary action
Reach, targeting, search demand, tracking exclusions, and traffic quality
Visit-to-primary-conversion rate
Primary conversions divided by eligible landing-page visits
Message match, offer, proof, form friction, page type, and call-to-action clarity
Conversion-to-qualified-lead rate
Qualified leads divided by primary conversions
Targeting, qualification criteria, form design, and whether the conversion is too easy or too broad
Qualified-lead-to-opportunity rate
Created opportunities divided by qualified leads
Handoff speed, buyer readiness, sales follow-up, and offer-to-market fit
Opportunity-to-customer rate
New customers divided by opportunities
Commercial fit, evaluation process, competition, pricing, and sales execution
Cost per qualified opportunity
Full channel cost divided by qualified opportunities
Whether reach and conversion translate into economically useful pipeline
Customer acquisition cost
Applicable acquisition cost divided by new customers
Whether the complete channel economics support continued investment
Time to result
Elapsed time from cohort entry or channel investment to the chosen business outcome
Whether you are comparing channels over an appropriate decision window
For every primary conversion, retain the channel, campaign, landing page, page type, call to action, and form version. Connect that record to lead status, opportunity status, customer status, and the relevant dates. Without those dimensions, a redesign, new offer, or change in traffic mix can alter the blended rate without showing you why.
Keep first-touch acquisition and converting touch separate. First touch helps you understand where demand entered the measurable journey. Converting touch shows what prompted the recorded action. Assisted interactions explain how channels such as email, webinars, and retargeting helped between those points. None of those views is a complete truth by itself.
Use the scorecard as a diagnostic sequence:
Qualified visits are scarce, but comparable pages convert acceptably: work on acquisition reach and targeting.
Qualified visits are present, but the primary conversion rate is weak: inspect message continuity, page type, proof, form friction, and the call to action.
Primary conversions are healthy, but qualification is weak: tighten the audience, promise, conversion definition, or qualification step.
Qualified leads are healthy, but opportunities are weak: inspect readiness, routing, follow-up, and the sales handoff before buying more traffic.
Opportunities are healthy, but customers are scarce: the main constraint is now downstream of acquisition.
This sequence protects you from paying to amplify the wrong stage. More traffic into a weak page produces more leakage. More form fills with poor qualification create more sales work. A better headline metric is only valuable when the improvement survives the rest of the funnel.
Key takeaways
Choose a channel for a defined job: demand creation, demand capture, nurture, or account acceleration.
The 1.1% B2B SaaS landing-page benchmark is a directional reference with a specific sample and scope, not a forecast for every SaaS page.
Customer-type, application, product, service, industry, and location benchmarks describe the broader B2B pool; they are not SaaS-specific page targets.
Compare conversion rates only when page intent, traffic source, audience, and call to action are genuinely comparable.
Optimize forms and page elements against qualified pipeline, not raw submissions.
Connect channel, page, conversion, qualification, opportunity, customer, cost, and elapsed time before reallocating budget.
Start with your most recent complete acquisition cohort. Put each channel beside its intended job, destination page, primary conversion, qualified opportunities, customers, cost, and time to result. If you cannot trace that path yet, fix the measurement before changing the budget. Once the path is visible, fund the channel that removes the actual constraint and repair the stage where qualified demand is being lost.
You have access to a promising new ad placement, the first click-through rates look excellent, and someone wants to know whether to increase the budget. That is exactly when measurement discipline tends to slip. A strong dashboard number feels like an answer even when it only describes the first step in the journey.
Your real task is to determine whether the platform creates valuable outcomes that would not otherwise happen, whether those outcomes remain economical as the test expands, and whether the available inventory can absorb more spend. This framework helps you answer those questions without expecting one attribution model to do every job.
Separate channel discovery from budget proof
An emerging platform can be interesting before it is investable. That distinction matters because discovery metrics and budget metrics answer different questions.
Click-through rate tells you whether people respond to a placement. It does not tell you whether the resulting customers are profitable, whether the ad caused those customers to act, or whether similar performance will survive broader distribution. This is especially important for conversational advertising, where early engagement has been strong but inventory and testing remain limited.
Run the test as a sequence of decisions. Each decision requires different evidence:
Decision
Evidence to inspect
What it does not prove
Does the placement attract attention?
Impressions, clicks, click-through rate, and engagement by query or audience segment
That the attention creates business value
Does the traffic produce the right outcome?
Purchases, qualified leads, subscriptions, revenue, lead quality, and downstream completion
That the advertising caused the outcome
Is the outcome incremental?
Holdout testing, geo experimentation, or another credible counterfactual
That the same return will persist at a larger spend level
Can the platform scale efficiently?
Available inventory, spend delivery, reach, frequency, conversion quality, and cost as exposure expands
That it improves the entire media portfolio
Should the portfolio budget change?
Experiment-calibrated media mix modeling alongside commercial constraints
That every individual conversion can be assigned to one touchpoint
This separation protects you from two common mistakes. The first is rejecting a potentially useful channel because it has not yet accumulated enough evidence for a permanent budget allocation. The second is scaling it because a high early click-through rate has been mistaken for incremental profit.
Label the stage of the evidence in every internal update. Use plain terms such as discovery signal, conversion signal, incremental evidence, and scale evidence. If the team only has a discovery signal, say so. That small piece of language prevents a preliminary result from hardening into a forecast.
Write the measurement contract before the first impression
A measurement plan should be a decision contract, not a list of every metric the platform can export. Write it before launch so the team cannot redefine success after seeing the results.
Name one primary business outcome. Choose the event closest to value that the test can credibly observe: a completed purchase, a qualified opportunity, a subscription, or another commercially meaningful result. Keep clicks and engagement as diagnostics unless attention itself is the campaign objective.
State the causal question. Write what you are trying to learn in counterfactual terms: how many desired outcomes occurred because the ads ran, beyond what would have happened without them? This wording exposes the limit of ordinary attribution before anyone treats credited conversions as incremental conversions.
Define the test unit. Decide whether results will be examined by query theme, audience, geography, product, offer, creative, or another controlled unit. The unit must match the mechanism you expect to drive performance.
Set the comparison rules. Document the conversion definition, attribution window, revenue basis, treatment of returns or cancellations, and handling of duplicate records. Use the same definitions for the emerging platform and the benchmark channel.
Choose guardrails. Track conversion quality, acquisition cost, spend delivery, reach concentration, and any operational consequence such as low-quality leads. A channel that creates more form submissions but overwhelms sales with poor prospects is not passing the business test.
Predeclare the verdicts. Specify what evidence would justify scaling, continuing the test, pausing for an instrumentation repair, or stopping. Your thresholds should come from the economics of your own business rather than a generic platform benchmark.
The contract also needs a data lineage section. For every result, record where the event originates, how it is passed, which identifier joins it to campaign data, and which system is authoritative when two systems disagree. If a purchase appears in the ad platform but not in the commerce system, the team should already know which record governs the decision.
Do not postpone this work until reporting begins. Missing identifiers and inconsistent event definitions cannot always be repaired after exposure has occurred. If the primary outcome is not reliably captured, pause the test and fix the measurement path before buying more traffic. Otherwise, additional spend produces a larger dataset without producing a better answer.
Read early AI ad performance without fooling yourself
Conversational ads may appear beside a response at the moment a user is expressing a need. That context can make the placement feel more relevant than an interruptive format. It also creates several reasons for early results to look unusually strong.
Intent mix is the first reason. Prompts about Mother’s Day have been observed to trigger ads about three times more often than the overall average. A test concentrated in gift-seeking conversations is not representative of every prompt, product category, or stage of the buyer journey. Report results by intent class instead of averaging all conversations into one channel-wide figure.
Format novelty is the second reason. People may inspect a new placement because they have not seen it before. You cannot prove that novelty caused the clicks from an initial campaign, but you can watch for the pattern. Repeat the test across cohorts or campaign waves, keep the offer and conversion definition stable, and check whether engagement and downstream quality hold as the format becomes more familiar.
Inventory selection is the third reason. Limited supply can concentrate delivery in the prompts, advertisers, or use cases most likely to perform. Expansion may introduce weaker contexts, more competition, and different pricing. Track how much of the planned budget is actually delivered, where impressions cluster, whether new query categories enter the mix, and how acquisition cost changes as spend rises. A channel that cannot spend the approved amount is not yet a scalable acquisition engine, even if its small pool of impressions performs well.
The comparison channel matters too. Early conversational-ad click-through rates have exceeded display and podcast benchmarks, but that comparison describes engagement, not equivalent economics. Search, paid social, display, podcast advertising, and conversational placements differ in intent, buying method, inventory, and the role they play in a journey. Compare them on the same final outcome and accounting basis before moving budget.
At the review meeting, force the result into one of four decisions:
Scale: the primary business outcome meets the predeclared requirement, the evidence supports incrementality, data quality is intact, and the platform has enough inventory to test a higher spend level.
Continue testing: engagement and conversion quality are promising, but incrementality, pricing stability, or inventory depth remains uncertain. Name the next uncertainty and design the next test specifically around it.
Pause and repair: event loss, inconsistent definitions, broken joins, or missing downstream outcomes make the result unreliable. Fix the data path before resuming.
Stop: the test has enough reliable evidence to show that the business outcome does not meet your requirement, or repeated expansion causes economics or conversion quality to deteriorate beyond the accepted limit.
“Promising” is not a fifth verdict. It is a description that must be followed by a specific next decision.
Build an evidence ladder instead of trusting one model
No single measurement method can tell you whether an ad was served correctly, influenced an individual journey, created incremental demand, and deserves a larger share of the portfolio. Use a ladder in which each layer answers a narrower question and checks the layers below it.
Layer 1: instrumentation and platform diagnostics
Start with clean event collection. Connect ad delivery, site or app behavior, commerce results, and CRM outcomes. Preserve campaign identifiers where possible, deduplicate events, and reconcile totals against the system that records the actual transaction or qualified lead.
The direction of Google’s tooling shows how central this plumbing has become. Data Manager is being expanded with a map-based view of connections involving systems such as BigQuery, HubSpot, and Shopify, while Google tag changes are intended to extend existing setups without requiring additional code. The useful principle is broader than any vendor: make the flow of data visible enough that a marketer can locate a missing connection before it distorts a campaign decision.
Platform reports remain useful at this layer. They help you diagnose delivery, creative response, query mix, and conversion paths. Treat attributed conversions as claims that need reconciliation, not as automatic proof of causality.
Layer 2: controlled experiments
An experiment estimates the counterfactual that ordinary attribution cannot observe. A holdout keeps an eligible group from receiving the treatment. A geo experiment varies advertising across comparable regions and evaluates the difference in business outcomes. Neither method is a decorative validation step. It is the evidence used to decide how much of the platform-reported performance is genuinely incremental.
Choose an experimental design only when the platform and your market provide a defensible control. If exposure leaks heavily between groups, the regions behave differently for unrelated reasons, or the outcome volume is too sparse to distinguish change from noise, do not dress the result up as causal proof. Document the limitation and continue at the lower rung of the evidence ladder.
Layer 3: media mix modeling
Media mix modeling examines aggregated changes in spend and outcomes across channels and time. It is suited to portfolio questions: how channels work together, how budget shifts may affect total results, and where marginal investment may be more productive. It does not need to identify a single ad as the exclusive cause of a single purchase.
An emerging channel may initially be too small or too stable in spend for a portfolio model to isolate reliably. That is not a reason to invent precision. Use controlled testing to establish an initial incremental read, create meaningful and documented variation when expanding the channel, and add it to the model when the underlying data can support the distinction.
Keep a measurement change log alongside the model. Record tag updates, consent changes, platform launches, campaign restructures, pricing changes, promotions, and breaks in source data. When performance moves, this log helps you distinguish a market effect from a measurement artifact.
Key takeaways for your next platform test
High click-through rate is a discovery signal. It is not evidence of incremental revenue, efficient scaling, or portfolio impact.
Define the business outcome, counterfactual, comparison rules, guardrails, and decision thresholds before the campaign begins.
Segment conversational-ad results by intent and query class. A concentration of high-intent prompts can make the channel average look more transferable than it is.
Evaluate scale separately from efficiency. Limited inventory can produce good economics while preventing meaningful budget deployment.
Use platform reporting for diagnostics, experiments for causal lift, and media mix modeling for portfolio allocation.
Pause when instrumentation is broken. More spend cannot repair missing identifiers, inconsistent events, or an unreliable outcome definition.
Before accepting the next emerging-platform test, write the measurement contract on one page and identify the weakest rung in your evidence ladder. Fund the test that resolves that uncertainty. Increase the budget only when the business outcome, incremental effect, data quality, and available inventory all support the same decision.
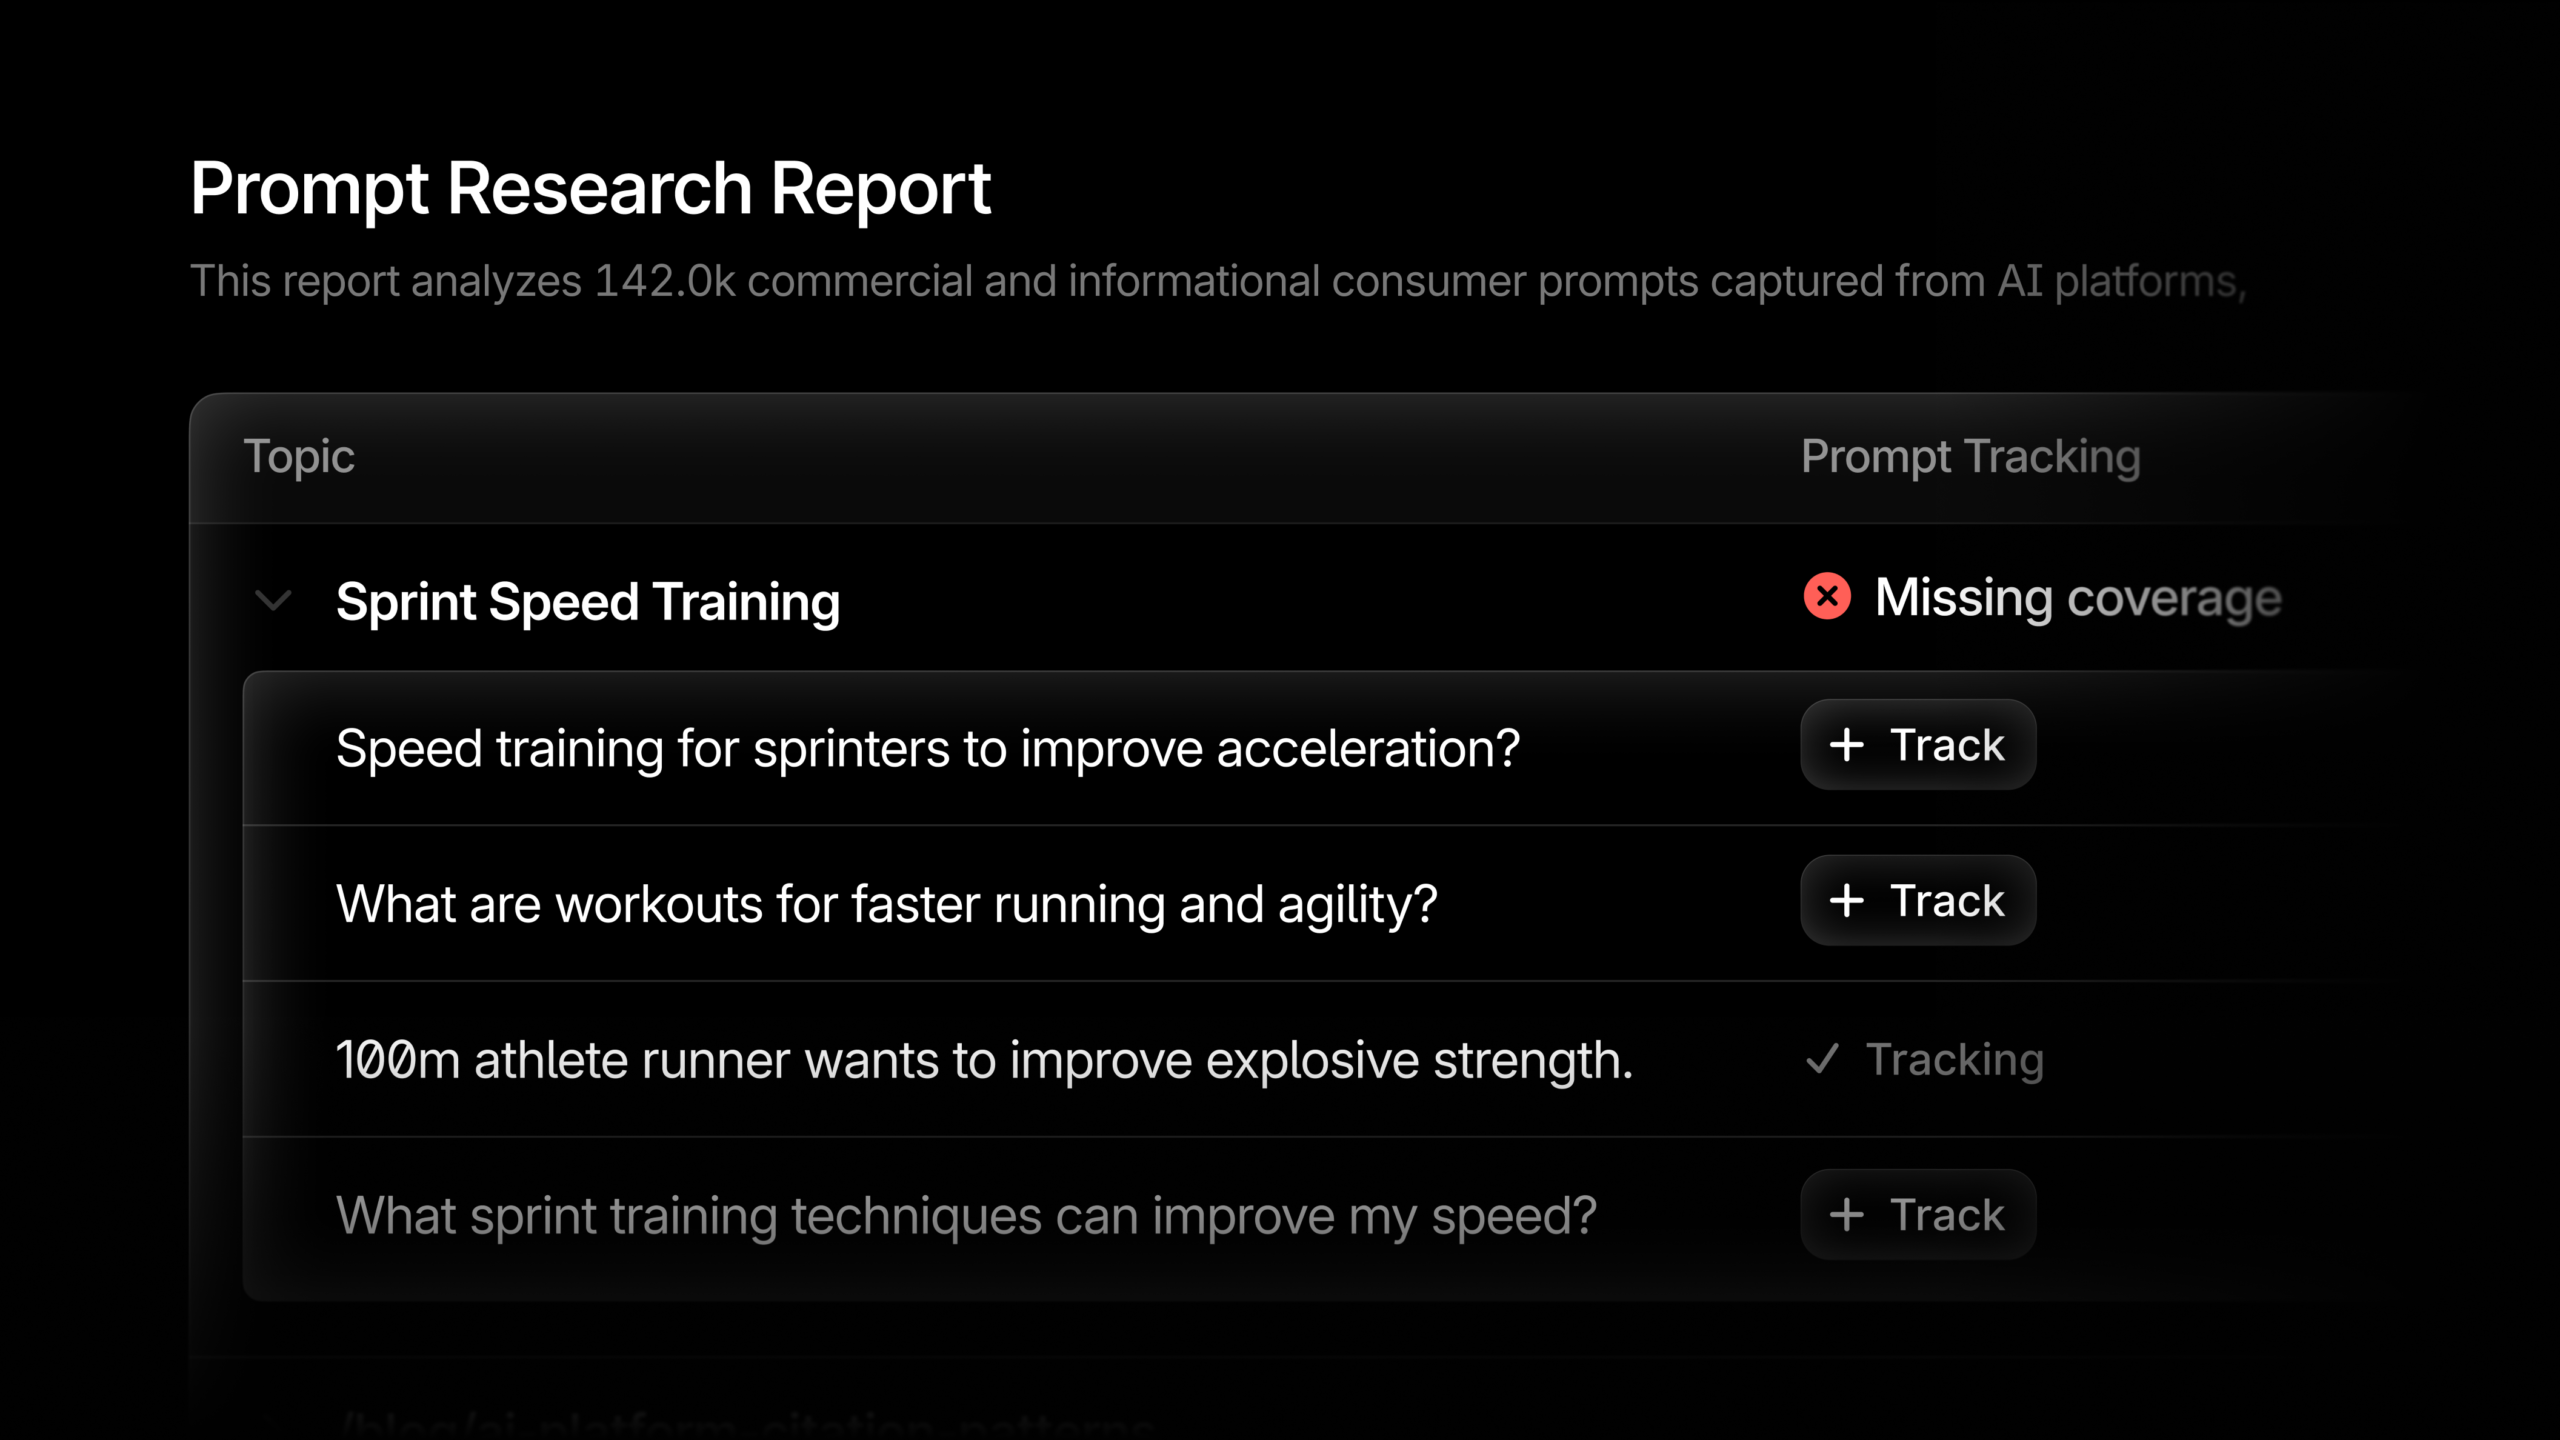
I’m excited to introduce you to a game-changing development in the world of research and data analysis. With Profound’s Prompt Research Reports, I have the power to pull insights from a staggering 1.5+ billion real user prompts. This transformative tool utilizes a proprietary ranking and clustering model, paving the way for data-driven decision making. Now, I no longer have to rely on guesswork when choosing prompts.
The system we use classifies and ranks user prompts, enabling me to access the most relevant data quickly and efficiently. This innovation not only optimizes my research process but also significantly enhances its accuracy and impact. By integrating such cutting-edge technology, I am able to stay ahead of the curve and meet my data needs with precision.
You paid to reach the buyer, earned the sales conversation, and got commercial agreement. Then the invoice stalled, the transfer became a support ticket, or the customer discovered that paying you would require an expensive international route. The campaign looked successful, but the revenue never completed the journey.
That gap is where global B2B payment optimization belongs. Your goal is not to offer every currency or payment method. It is to give each qualified buyer a clear, appropriate, measurable path from agreement to received funds – without weakening security, compliance, or financial controls.
Put the payment event inside your acquisition funnel
Many acquisition dashboards end at a form submission, booked meeting, signed contract, or closed-won opportunity. Finance begins its work after that point. When those systems do not share identifiers and status events, payment friction becomes an invisible conversion loss: marketing counts a win while accounts receivable waits for money that may never arrive.
For this audit, define the final acquisition event as the first payment received and reconciled. That does not replace your accounting rules or normal sales attribution. It gives growth, sales, and finance a shared operational endpoint.
The difference can materially change how you read customer acquisition cost. In one illustrative scenario, a campaign appears to acquire customers for $500 before payment. If 25% fail to complete the payment stage, the effective cost per paid customer becomes about $667: $500 divided by 0.75. The $500, 25%, and $667 figures illustrate the hidden-CAC mechanism; they are not a benchmark for your business.
Build a funnel that reflects the transaction you actually run. A sales-assisted journey might contain these events:
Commercial terms accepted
Invoice issued
Invoice delivered or viewed
Payment instructions viewed
Payment attempt initiated, when the provider can verify that event
Funds received
Funds matched to the correct account and invoice
A self-service product may substitute checkout events for the proposal and invoice steps. Do not manufacture precision your systems do not have. Opening bank-transfer instructions is not the same as initiating a transfer, and an unverified buyer statement that payment was sent is not the same as funds received.
Make the identifiers persistent. The campaign or lead ID should connect to the account, opportunity, invoice, payment, and reconciliation record. Store only the references needed for analysis. Sensitive card, bank, identity, and authentication data should remain inside appropriately controlled payment systems rather than being copied into marketing analytics.
Match your payment footprint to your demand footprint
A translated landing page does not make a campaign operationally local. If a buyer reaches localized messaging but receives domestic-only banking instructions, unfamiliar currency terms, or an avoidable international-transfer burden, the localization stops before the transaction. This mismatch between campaign geography and payment infrastructure is the first place to look when one market produces interest but weak paid conversion.
Create one market-to-payment matrix for every country you actively target. For each market, record:
The currency used in the proposal and displayed price
The invoice currency
The currency from which the buyer is likely to fund the payment
The currency your business ultimately receives or settles
The available payment routes and the eligibility conditions for each
Which party may bear provider, transfer, intermediary, or conversion costs
What payment timing you communicate and whether it is guaranteed or only expected
The buyer-facing instructions, support path, and failure-recovery process
The internal owner for payment exceptions in that market
Do not collapse price currency, invoice currency, funding currency, and settlement currency into a single field. They can be different. A buyer may accept your quoted price yet stop when the invoice reveals an unexpected conversion, a fee allocation they did not anticipate, or a route their accounts-payable process cannot use.
Evaluate total payment cost rather than the provider’s most visible fee. Your working model can include the provider charge, foreign-exchange spread, possible sender or intermediary charges, recipient charges, and the internal work needed to trace or reconcile the transaction. Some components will not apply to every route. The point is to expose them before you compare options.
Possible routes include SWIFT, ACH, local bank rails, and stablecoins. A longer list is not automatically a better experience. The right route must fit the buyer, transaction, jurisdiction, settlement needs, and your control environment. Before enabling a new money-moving method – particularly one involving stablecoins – have qualified finance, treasury, legal, tax, security, and compliance personnel assess eligibility, custody, settlement, reporting, contractual, and jurisdiction-specific consequences. Faster movement is not a reason to bypass those reviews.
When you compare providers, require written answers about supported countries, currencies, payer eligibility, settlement behavior, failure handling, fee disclosure, reconciliation data, and support escalation. Treat phrases such as local, instant, or fee-free as claims that need precise definitions. Ask what each term includes, excludes, and depends on before you repeat it to a customer.
Design the quote-to-cash handoff as conversion UX
The payment experience begins before the buyer reaches a checkout or receives an invoice. Commercial terms create expectations about price, currency, timing, and responsibility for charges. If the operational payment path contradicts those expectations, the customer has to reopen a decision they appeared to have finished.
Use a consistent handoff from proposal to payment:
State the transaction currency and accepted payment routes before agreement. If options depend on the buyer’s location or legal entity, say so.
Explain how applicable payment or conversion costs are handled. Do not promise an exact buyer-side total unless you can substantiate it for that route.
Issue the invoice from the expected legal entity and make the payer, beneficiary, amount, currency, due terms, invoice reference, and support contact easy to identify.
Give the buyer one authoritative set of payment instructions. Remove stale attachments, duplicated bank details, and conflicting versions.
Tell the buyer what acknowledgement they will receive after initiating payment, after funds arrive, and after the payment is matched to the invoice. Those are separate events.
Provide a specific recovery path for a rejected, delayed, duplicated, underpaid, overpaid, or unmatched transaction.
Changes to beneficiary or bank details carry a serious fraud risk. Do not ask buyers or employees to trust a change solely because it arrived by email. Your finance and security teams should maintain an approved, independently verified procedure for validating payment-instruction changes, and customer-facing material should explain that procedure without exposing sensitive controls.
Internally, assign responsibility at each handoff. Sales should know where to send a buyer with a currency or payment-method question. Finance should know which campaign, account, and invoice a payment belongs to. Support should have an escalation route that does not require the buyer to repeat the transaction history. Marketing should receive status events without receiving sensitive payment data.
Provider notifications are useful only when they map to meaningful states. An alert that an invoice was opened is not a payment. A transfer initiation is not settlement. Funds received may still require matching. Reliable, timely notifications can shorten follow-up and improve attribution, but each notification must retain its exact meaning as it moves into your CRM and analytics tools.
Measure settled revenue and diagnose the point of friction
Do not begin with a provider replacement. Begin with a failure map. Separate buyer abandonment, provider rejection, compliance review, processing delay, invoice error, support delay, and reconciliation failure. They happen at different stages and require different owners.
What you observe
What to inspect next
First useful action
Accepted deals do not reach a payment attempt
Invoice delivery, currency clarity, available route, fee disclosure, and accounts-payable requirements
Review stalled deals by market and record the buyer’s stated blocker instead of assuming price resistance
Separate fixable usability errors from risk or compliance decisions that must not be bypassed
Funds arrive but remain unmatched
Invoice reference, account identifier, remittance data, and reconciliation mapping
Use a durable payment reference and preserve it across the provider, bank, finance system, and CRM
One market requires repeated manual intervention
Currency mismatch, route availability, local payer requirements, instructions, and support ownership
Update the market-to-payment matrix and remove the recurring handoff defect
Marketing reports customers that finance cannot verify
Conversion definition, event timestamps, duplicate records, refunds, and payment status
Create a paid-customer view based on received and reconciled first payments
Your core metrics should answer different questions rather than compressing the whole journey into one conversion rate:
Payment-start rate: accounts reaching a verified attempt divided by accounts presented with a payable invoice or checkout.
Payment completion rate: successful first payments divided by verified first-payment attempts.
Paid-customer CAC: acquisition spend divided by new customers whose first payment was received under your defined measurement rule.
Agreement-to-payment time: elapsed time from accepted commercial terms to received funds.
Reconciliation time: elapsed time from funds received to the payment being matched and available to downstream systems.
Manual-intervention rate: payable accounts requiring human correction or escalation divided by all payable accounts in the cohort.
Failure mix: the share of unsuccessful journeys assigned to each documented reason.
Define every numerator, denominator, timestamp, and status before publishing the dashboard. For example, decide whether a successful payment means initiated, received, settled, or reconciled. Use the same definition across growth and finance reporting. Keep accounting recognition separate where your accounting policy requires it.
Segment the funnel by buyer country, invoice currency, funding currency when known, payment route, customer type, campaign, and sales-assisted versus self-service journey. Aggregate performance can conceal a severe problem in one market. At the same time, small segments can produce unstable rates, so inspect the underlying transactions before acting on a percentage.
Do not label every unpaid invoice as payment friction or lost revenue. Contract disputes, procurement delays, credit terms, buyer cash constraints, and deliberate risk controls can also prevent or delay payment. Mark unresolved first invoices as at risk, assign a reason when evidence becomes available, and reserve causal claims for cases you can support.
Once a recurring friction point is documented, test the smallest safe change that addresses it. Candidates include clearer fee language, a more appropriate default currency, reordered payment options, fewer duplicative fields, better invoice references, improved instructions, or faster operational notifications. Hold the eligibility, security, fraud, compliance, and approval requirements constant. A conversion test is not permission to weaken a financial control.
Judge the result on received, reconciled first payments and agreement-to-payment time. Also check manual workload, transaction cost, support demand, disputes, and risk outcomes. A change that moves more buyers into an expensive exception queue has not solved the underlying problem.
Key takeaways for your payment-friction audit
Extend acquisition measurement to the first received and reconciled payment; a signed deal is not the final payment event.
Map price, invoice, funding, and settlement currencies separately for every market you actively target.
Compare payment routes on eligibility, buyer effort, total cost, settlement behavior, reconciliation data, and controls – not on the headline fee alone.
Treat proposals, invoices, instructions, status messages, and exception handling as one quote-to-cash experience.
Diagnose the exact failure stage before changing a provider, adding a method, or redesigning the interface.
Never trade away fraud, security, legal, tax, treasury, or compliance controls to produce a cleaner conversion metric.
Start with the active market showing the clearest gap between commercial agreement and received funds. Trace one successful deal and one stalled deal from campaign record to reconciliation. Find the earliest meaningful difference, fix the largest recurring and avoidable obstacle, and then measure the next cohort against the same definitions. That gives your next global campaign a payment path designed to finish the conversion it starts.
You have an AI-search dashboard full of charts, but the decision in front of you is much smaller: Why did visibility change? Which competitor gained ground? What should your team investigate before it edits another page?
Conversational AI can shorten the distance between that question and a useful slice of data. The catch is that a polished answer can hide ambiguous metrics, altered filters, weak evidence, or an unsupported explanation. You need a workflow that uses the conversation for speed without outsourcing analytical judgment.
Key takeaways
Start with the decision you need to make, not a broad request to find insights.
Tell the assistant which dataset, period, filters, definitions, and comparison it may use.
Move from baseline to segments, exceptions, evidence, and possible actions in separate questions.
Require every important claim to be traceable to records, rows, prompts, or another inspectable result.
Save the validated analysis specification, not merely the chat transcript, so the work can be reproduced.
Treat the conversation as an analysis interface
Some AI-search platforms now provide a conversational layer that lets customers engage directly with their AI Search data. That can make a complex dataset easier to explore, especially when the question is still taking shape.
The conversational layer is still an interface, not evidence in its own right. At its most useful, it translates your request into operations such as filtering, grouping, comparing, aggregating, and retrieving examples. The prose answer then explains the result. Your confidence should come from the operations and evidence beneath that prose.
Before you ask a substantive question, establish four boundaries:
Access: Which datasets, tables, reports, or workspaces can the assistant actually query?
Meaning: How does the platform define visibility, mention, citation, sentiment, share, or any other metric you plan to use?
Grain: Does one record represent a prompt, response, model run, page, query cluster, market, or reporting period?
Allowed operation: Are you asking for a description, comparison, hypothesis, forecast, or recommendation?
Those boundaries matter because the same sentence can conceal several different analyses. Consider the request: Why did our AI visibility fall? The word visibility might refer to brand appearances, linked citations, a weighted platform score, or another vendor-specific measure. Fall requires two comparable periods. Why asks for causation, even though the dataset may support only a description of where the change occurred.
A better first question is: Using the platform’s documented visibility metric, identify where the measured change is concentrated between these two selected periods. Do not infer a cause. That phrasing gives you a defensible observation before anyone starts explaining it.
Conversational analysis is particularly useful for exploration, segmentation, exception finding, evidence retrieval, and plain-language explanation. It is much less reliable when you ask it to certify causation, reconcile conflicting business definitions silently, or make a high-consequence decision without showing its work.
Ask questions in a sequence that preserves context
One giant prompt tends to mix discovery, interpretation, and action. Use a question ladder instead. Each answer becomes a checkpoint that you can inspect before moving to the next analytical operation.
Write the decision sentence first: We need to determine whether the change is broad or isolated so we can choose what to investigate before changing content. Then work through this sequence:
Set the scope. Name the permitted dataset, selected periods, market or locale, engine or model, brand, and exclusions. Ask the assistant to state any requested field it cannot access.
Confirm definitions. Ask it to define the main metric, denominator, grouping level, and treatment of missing values before calculating anything.
Establish the baseline. Request the overall result for the chosen scope, together with the filters and calculation used.
Segment the result. Break it down by the dimensions that could change your decision, such as query cluster, market, competitor, content category, cited domain, or model.
Find exceptions. Ask which segments moved against the overall pattern, which were unchanged, and which lack enough usable data for a conclusion.
Retrieve evidence. Request the underlying prompts, responses, pages, records, or report views supporting each material claim.
Separate explanations from facts. Ask for candidate hypotheses in a distinct section, with the additional evidence needed to confirm or reject each one.
Choose the next action. Request actions that follow only from validated observations, with unresolved assumptions listed beside them.
This sequence prevents a common analytical shortcut. If you begin with What caused the decline and what should we publish?, the assistant is invited to invent a coherent bridge between a measured change and an editorial recommendation. If you first locate the change, inspect examples, and test alternative explanations, the recommendation has a visible chain of support.
A reusable opening prompt can be simple:
Analysis brief: Use only the named AI Search dataset and the selected comparison periods. Restate the metric definition, denominator, grain, filters, and exclusions. Separate observed results from hypotheses. For every important result, identify the records or report view that supports it. If required data is unavailable, say what is missing instead of estimating it.
Long chats can accumulate ambiguity. A later reference to our visibility may inherit an earlier competitor filter or a different period without making that scope obvious. After several analytical turns, use a checkpoint prompt: Restate the active dataset, periods, filters, metric definitions, groupings, and unresolved assumptions before continuing.
Start a new conversation when you change the business decision, dataset, metric definition, or audience for the result. Carry the validated scope into the new thread explicitly. Do not rely on the assistant to decide which earlier context still applies.
Verify every answer before you act on it
A useful answer should let you distinguish three layers:
Observation: What the selected data shows under declared filters and definitions.
Hypothesis: A possible explanation that still needs evidence.
Recommendation: An action justified by the observation, the tested explanation, or both.
Do not allow those layers to collapse into one paragraph. A concentrated decline in one query cluster is an observation. A competitor’s stronger coverage might be a hypothesis. Reviewing the affected prompts, competitor appearances, cited pages, and content differences is a reasonable next action. Rewriting an entire content library is not justified by the observation alone.
For every answer that could change a report, roadmap, campaign, or content plan, complete this verification card:
Question: What exact decision was the analysis meant to inform?
Dataset: Which workspace, report, table, or connected system was queried?
Time scope: Which periods and timezone were used, and are the periods comparable?
Filters: Which brands, competitors, markets, models, prompt groups, content types, and exclusions were active?
Metric: What is the metric’s definition, numerator, denominator, and treatment of missing responses?
Grain: What does one underlying record represent, and at what level was the result grouped?
Evidence: Which rows, prompts, responses, URLs, or report views support the claim?
Uncertainty: What data is unavailable, ambiguous, or insufficient?
Next check: What independent query or manual inspection would challenge the conclusion?
AI-search analysis deserves extra care around denominators. A visibility result can change because brand performance changed inside a stable tracked set, because the tracked prompt set changed, or because a filter, market, model, competitor list, or metric definition changed. Ask the assistant to distinguish those possibilities before you interpret the movement as a performance result.
Definitions also need to travel with the answer. A brand mention is not necessarily a linked citation. A cited page is not necessarily the page you intended to rank. An overall score may combine components that behave differently. Ask for component-level results whenever the combined metric cannot tell you what action to take.
Use reconciliation to catch silent mistakes. Run the same scoped calculation in the original report or with a trusted manual query. If the totals disagree, stop at the discrepancy. Check filters, date boundaries, grouping, duplicates, missing values, and denominators before requesting more interpretation.
If the assistant cannot expose the evidence behind an answer, treat the output as a lead for investigation, not a conclusion. Fluency can help you understand a result, but it cannot compensate for missing lineage.
Turn a useful conversation into repeatable analysis
Save the specification, not just the transcript
A chat log records what was said. It may not record the exact state of the dataset, inherited filters, calculation logic, or later corrections. For recurring work, save an analysis specification containing:
The decision and analytical question.
The dataset and required access.
The comparison periods and timezone.
The filters, exclusions, dimensions, and grouping level.
The approved definitions for every metric.
The required output fields and evidence links.
The checks used to reconcile the result.
The boundary between observations, hypotheses, and recommendations.
Keep a human-approved metric glossary beside that specification. If visibility, citation, or share has a platform-specific meaning, copy the approved definition into the analytical brief. Do not ask the assistant to infer your team’s preferred meaning from earlier conversations.
Record corrections as part of the recipe. If a reviewer discovers that a competitor filter was wrong or a prompt group was incomplete, update the reusable specification and rerun the analysis. A corrected answer trapped inside an old chat does not protect the next reporting cycle.
Require evidence and control when choosing a tool
If you are evaluating conversational analytics software, do not judge it by how confidently it answers a demo question. Give each candidate the same small analysis whose result you can already verify. Then look for operational capabilities:
Clear disclosure of the datasets and fields available to the assistant.
Visible filters, metric definitions, calculations, and grouping choices.
Drill-down access from a claim to the supporting records or report view.
A way to export the answer together with its scope and evidence.
Permission controls that respect the underlying dataset’s access rules.
A reliable way to reset context and begin a clean analysis.
Repeatable prompts or saved workflows that another analyst can inspect.
Explicit handling of missing, conflicting, or inaccessible data.
A tool that produces elegant prose but hides its scope creates review work rather than removing it. A shorter answer with inspectable evidence is more valuable when the result will shape SEO, AEO, GEO, content, or competitive strategy.
Begin with one narrow recurring decision
Choose a question your team already answers repeatedly, such as identifying which tracked query clusters deserve manual review after a visibility change. Document the current method, run the conversational workflow against the same scope, and reconcile the two results.
Keep the pilot narrow enough that a person can inspect the evidence. The aim is not to prove that the assistant can discuss the whole business. It is to determine whether the conversational layer helps your team reach a reproducible, reviewable answer with less friction.
On your next reporting cycle, write one decision sentence, define one metric completely, and require one evidence path for every conclusion. Once that chain holds up under review, save it as a reusable analysis specification and expand from there.
You need a test that shows where visibility breaks: whether an AI system retrieves your brand, mentions it, cites it, explains it correctly, places it on a shortlist, or recommends it. The framework below turns those separate outcomes into a prompt panel, a repeatable scorecard, and an experiment you can act on.
Start with the decision, not a visibility score
AI visibility is not a single event. Your brand can be cited without being recommended, mentioned without receiving a citation, or described accurately but placed behind competitors. Treating all three situations as visible conceals the problem you need to fix.
Separate each answer into five measurement states:
Retrieval: the AI answer appears and has an opportunity to include your brand.
Inclusion: your brand, product, or page is mentioned.
Attribution: an owned URL or a third-party page about your brand is cited.
Positioning: the answer gives your brand a particular order, category, use case, or authority level.
Recommendation: the answer actively includes your brand in the decision set for the intended user.
Denominators matter, especially on search surfaces that do not generate an AI answer for every query. A missing AI Overview is not the same result as an AI Overview that appears but omits your brand. Track both:
AI answer trigger rate = attempts that produced an AI answer divided by all attempts.
Among-answer mention rate = rendered AI answers mentioning the brand divided by all rendered AI answers.
End-to-end mention rate = attempts mentioning the brand divided by all attempts, including attempts without an AI answer.
Do not compress these outcomes into one proprietary visibility score. A composite can rise because branded prompts improved while the unbranded prompts that create new demand deteriorated. Show the component rates and their numerators so a change remains interpretable.
Build a prompt panel that can be rerun
A useful prompt panel is a measurement instrument, not a loose keyword list. Every prompt needs a defined intent, an eligible engine or surface, and a reason for being in the panel.
Branded identity prompts test whether the system knows what the brand is, who it serves, and how it differs.
Category prompts remove the brand name and test discovery for the problem or product class.
Comparison prompts test alternatives, versus questions, and the attributes used to separate competitors.
Decision prompts add a buyer constraint, such as audience, use case, risk, or required capability, and test whether the brand is recommended.
Validation prompts test reputation, limitations, suitability, or factual claims that a buyer may check before acting.
Keep a stable core panel for trend reporting and a separate exploratory panel for new questions. If you rewrite, remove, or add core prompts, create a new panel version. Do not splice the results into the previous trend line as though the test stayed constant.
Run each target engine as its own surface. A first-month fictional-brand test covering 825 prompts and 15,835 answers found materially different behavior across ChatGPT, Google AI Overviews, Google AI Mode, Perplexity, and Gemini. Google AI Mode was comparatively stable for branded questions, Perplexity surfaced new material quickly, ChatGPT recognition strengthened during the month, and Gemini produced substantial citation gaps. Because the brand was artificial and the observation window was short, those results are evidence that engines differ, not a permanent ranking of the engines.
A permanent prompt ID, prompt family, and panel version.
The exact prompt text without silent edits.
The engine and specific surface, such as Google AI Mode or Google AI Overviews.
The date, run number, locale, and any account or session conditions you can keep consistent.
The complete answer, ordered brand mentions, cited URLs, and first cited URL.
Whether your brand was recommended, how it was framed, and whether the description was accurate.
Use a fresh conversation for each conversational-engine run so earlier messages do not become an uncontrolled input. Run repetitions in the same measurement window, then rerun the complete batch on a fixed cadence. Weekly measurement can suit an active intervention; a monthly cadence may be enough for an established baseline. Consistency matters more than choosing an arbitrary universal interval.
Evaluate tracking tools against this test design. Familiar SEO integration can still leave you with narrow LLM coverage and no optimization workflow. Before committing to a platform, confirm that it covers your target surfaces, retains raw answers and cited URLs, distinguishes mentions from citations, preserves prompt versions, records repeated runs, and exports answer-level rows. A polished summary dashboard cannot compensate for missing evidence.
Score each answer without losing its context
Create one row per answer, not one row per prompt. Aggregating three runs before storing them destroys the variation you are trying to measure.
Inclusion: record brand absent or present. Calculate mention rate separately for branded, category, comparison, decision, and validation prompts.
Attribution: distinguish an owned-domain citation from a citation to an independent page about the brand. Then record whether the owned page was the first or main cited source. A third-party citation can improve brand exposure without giving your site attribution.
Order and recommendation: record the brand’s position among listed options and whether the language explicitly recommends it. Do not treat a neutral appearance in a list as a recommendation.
Explanation depth: apply a small internal rubric consistently. Score 0 for absent, 1 for a name-only list appearance, 2 for a short explanation containing one defined claim, and 3 for a substantive explanation covering the audience, use case, or reason to choose. This is an operational rubric, not an industry benchmark.
Framing and accuracy: label the tone as positive, neutral, cautionary, or negative. Record authority labels such as leader, challenger, or niche option only when the answer actually uses that framing. Mark factual descriptions as correct, incomplete, or incorrect in a separate field.
Stability: with three runs, report whether the brand appeared in none, one, two, or all three. Keep that distribution visible beside the average rate.
Accuracy is the non-negotiable guardrail. A confidently worded but false recommendation is not a visibility win. Keep inaccurate claims in the visibility totals so you do not hide the problem, but flag them separately and prioritize correction over reach.
Report each metric with its numerator and denominator. A percentage without the number of eligible answers conceals small samples, missing AI-answer triggers, and changes to the prompt mix. Break results down by engine, prompt family, branded versus unbranded intent, and run consistency before looking at an overall total.
Turn signal patterns into controlled content changes
Diagnose the gap before editing
The scorecard should point to a failure mode. It should not merely tell you that visibility is low.
Observed pattern
Likely reading
Next test
Strong branded mentions, weak category mentions
The entity is recognized, but its association with the wider problem or category is weak.
Test a page that connects the brand clearly to the category, audience, and use cases.
Frequent mentions, few owned citations
The brand is known, but the main site is not being selected as evidence.
Consolidate definitive facts on an owned page and inspect which independent URLs are being cited instead.
Citations without recommendations
Your material is useful as evidence, but the brand’s decision position is unclear.
Test explicit audience fit, differentiators, selection criteria, and honest limitations.
Name-only appearances
The system has too little usable information for a deeper explanation.
Test one comprehensive page that answers what the brand is, who uses it, and how to choose it.
Top placement in only one run
The apparent lead may be output volatility rather than a stable gain.
Repeat the batch and report the run distribution instead of publishing the best screenshot.
Visibility on one engine only
The gain is surface-specific.
Inspect that engine’s citations and distribution path; do not describe the result as universal AI visibility.
Positive but inaccurate descriptions
Repeated claims are shaping the narrative without adequate verification.
Correct the canonical brand information and monitor the exact false claim across owned and independent pages.
For your site, give each supporting page a distinct job tied to a real prompt or decision. Measure which URL is cited. Remove or correct pages that merely repeat claims, especially when repetition could amplify an error.
Test one explanation at a time
Most AI visibility work is a structured before-and-after test, not a true randomized A/B test. Retrieval systems change, answers vary, and you do not control when every engine discovers a revision. You can still make the evidence more useful:
Write a falsifiable hypothesis. For example, clarifying audience and category on the canonical brand page should increase explanation depth on branded identity prompts.
Capture a triplicate baseline batch. If the three runs conflict sharply, repeat the baseline before changing the site.
Make the smallest coherent intervention. Update the entity page, publish a comparison resource, or improve a specific claim set, but do not combine a redesign, a large publishing sprint, and a distribution campaign if you want to know what helped.
Record the changed URLs, publication date, affected claims, internal links, and prompt families expected to move.
Use discovery as the gate instead of assuming every engine follows the same calendar. Begin interpreting the post-change period only after the new or revised material appears in citations or is otherwise demonstrably available to the surface being tested.
Rerun the same panel, engine mix, session setup, and scoring rules. Keep newly discovered prompts in the exploratory panel until the current test ends.
Compare the target prompts with unaffected prompt families and competitor patterns. If every brand moves in the same direction, engine drift is a stronger explanation than your page change.
Repeat the result in another scheduled window. Call a one-engine or one-run gain directional, not conclusive.
Describe a before-and-after movement as associated with the intervention unless you have stronger controls. That language is not timidity; it is an accurate reflection of a system whose retrieval, citations, and generated wording can all change outside your test.
Keep AI response metrics beside traditional SEO and business outcomes. Citations do not guarantee visits, and visits do not prove that the answer influenced a decision. Some ChatGPT journeys continue on Google as users verify what they were told, so direct AI referrals may miss part of the path. Compare AI visibility with organic landing-page activity, branded demand, qualified visits, and conversions, but do not assign causation merely because two lines moved together.
Key takeaways
Choose the decision you need to make before choosing a visibility metric.
Separate AI-answer triggers, mentions, owned citations, independent citations, mention order, recommendations, explanation depth, framing, accuracy, and stability.
Keep branded, category, comparison, decision, and validation prompts in separate cohorts.
Measure each engine and surface independently, and run the exact prompt three times as a practical volatility check.
Store one row per answer with the raw response and cited URLs. Do not rely on a composite score or a selected screenshot.
Diagnose the missing stage, change one coherent content element, wait for discovery, and rerun the versioned panel.
Track AI visibility beside rankings, traffic, and conversions without treating any one of them as a substitute for the others.
Your first useful measurement system can be a spreadsheet: a stable core prompt panel, three runs per prompt, one row per answer, and one intervention tied to one failure mode. Automate it after the process can explain why a number moved. That is the point at which AI visibility becomes an operating metric instead of a collection of interesting screenshots.
Your paid social dashboard says the campaign worked. Paid search gets credit for the eventual conversion. Direct traffic also rises. If you evaluate each channel in isolation, you can end up paying three platforms for the same story or cutting the channel that started it.
You need an execution plan that separates platform-reported performance from incremental business impact. That means assigning each channel a job, preserving a measurable journey, testing a specific causal claim, and deciding in advance what evidence will change the budget. AI-driven changes have made paid media platforms more complex, but they haven’t removed the need for this discipline.
Measure the customer journey, not a stack of channel totals
A platform conversion total answers a narrow question: which conversions can this platform claim under its attribution rules? It does not tell you how many conversions would have disappeared without the campaign. That second question is incrementality, and it is the one that should guide a material budget decision.
Cross-channel journeys make the distinction important. A paid social impression may introduce the brand. The person may later search for it, click a paid search ad, and convert on the site. In that journey, social created or accelerated demand, search captured it, and the website closed it. Giving the entire outcome to the last interaction understates social. Adding every platform’s claimed conversions overstates the total.
Start by assigning a role to every campaign. Use roles such as demand creation, demand capture, remarketing, registration, or conversion. Do not let every channel claim to be a direct-response closer merely because its interface reports conversions. The role determines which signals deserve attention and which signals are only diagnostic.
Key takeaways
Platform attribution shows claimed credit; an incrementality test estimates what the advertising caused.
Do not add channel-reported conversions together unless you have deduplicated the underlying business events.
Give each campaign a defined job in the journey before selecting its success metrics.
Judge an awareness campaign partly by downstream demand signals, not only by its last-click conversions.
Use a control whenever the budget decision depends on causality rather than reporting convenience.
Define the decision and hypothesis before changing spend
A useful paid media test begins with a budget decision, not a dashboard. Write down what you might do differently after the result: increase social investment, reduce it, move money between audiences, protect branded search coverage, or change the registration journey. If no possible result would alter an action, you are monitoring rather than testing.
Next, turn the decision into a falsifiable hypothesis. A practical format is: changing a named campaign variable for a defined audience or geography will change a specified business or downstream channel outcome relative to a control.
For example: increasing paid social exposure in selected markets will increase branded paid search demand relative to comparable markets where social spend remains unchanged. The mechanism is greater brand familiarity. The primary signals are branded search impression and click volume. Search click-through rate and conversion rate are supporting signals because familiarity may affect both, but they should not quietly replace the primary outcome after the test begins.
Your campaign brief should record the following before launch:
Business decision: the budget or execution choice the result will inform.
Intervention: the exact variable you will change, such as social spend, audience exposure, creative, or destination.
Expected mechanism: why that change should affect customer behavior.
Primary outcome: the business or downstream channel signal that directly tests the hypothesis.
Supporting metrics: signals that help explain the result without redefining success.
Guardrails: delivery, cost, lead quality, or customer-experience indicators that could make an apparent win unacceptable.
Control: the audience, geography, or other comparable group that will not receive the change.
Decision rule: what pattern of evidence would justify scaling, stopping, or running a narrower follow-up test.
This record prevents a common failure: finding an attractive metric after launch and treating it as the goal. Engagement can explain delivery. It cannot substitute for registrations when registrations were the reason for the campaign.
Build one observable journey across channels and destinations
Cross-channel measurement breaks when execution creates different definitions of the same customer action. If paid social counts a form submission, paid search counts a confirmation page, and the CRM counts an accepted lead, the totals are not comparable. Establish the business event first, then map each platform signal to it.
Use a shared campaign taxonomy across ad platforms, analytics, landing pages, and downstream reporting. The taxonomy should let you identify the channel, campaign, audience, geography, creative, offer, and test group without decoding inconsistent names. Preserve those values through the conversion path where your systems allow it. The aim is not a longer campaign name; it is a reliable join between spend, exposure, site behavior, and the final business event.
That flexibility does not make measurement automatic. Before sending event traffic to your site, verify the complete path:
Open the live ad destination and confirm that campaign and test identifiers survive the redirect.
Complete a test registration and verify that analytics records the same completion event used in business reporting.
Confirm that duplicate page loads or repeated form submissions do not create multiple business conversions.
Check that the registration reaches the system where lead quality or attendance will eventually be evaluated.
Separate campaign clicks, landing-page sessions, completed registrations, qualified registrations, and attendance. Each represents a different stage and should not be relabeled as another.
Document any platform-reported conversion window or modeled result that differs from your analytics definition so stakeholders do not compare unlike totals.
If you compare a native platform experience with an external destination, treat the destination as part of the intervention. A difference in registration rate may reflect page speed, form length, trust, tracking loss, or the handoff itself rather than the ad format alone. Keep the audience, offer, and conversion definition as stable as the platform permits, then examine the full path from click to qualified outcome.
Use a geographic split when channels influence one another
A simple before-and-after comparison is weak evidence for a cross-channel effect. Seasonality, promotions, news, competitor activity, and changes in search demand can move at the same time as your spend. A geographic split improves the comparison by exposing selected markets to the change while comparable markets act as controls during the same period.
A defensible geographic paid social test requires more than dividing a map. Match treatment and control markets on factors that could affect the outcome, including income characteristics and region type. Check for local television campaigns, televised sports activity, regional promotions, distribution differences, or other events that reach one group but not the other. Either redesign around a major imbalance or document it before interpreting the result.
Then protect the test from delivery constraints:
Confirm that the treatment budget can create a real difference in social exposure. A nominal budget increase that does not change delivery is not a meaningful intervention.
Keep the non-tested parts of the media plan as stable as practical across treatment and control markets.
Inspect paid search impression share before and during the test. If search is capped by budget or rank, added demand may not produce more paid search clicks.
Use the same conversion definition and reporting window in both groups.
Record campaign edits, outages, landing-page changes, promotions, and regional anomalies while the test runs.
Compare the change in treatment markets with the change in control markets. Do not infer lift merely because treatment improved from its own earlier level.
Testing a reduction in spend can be valid when social investment is already substantial, but the financial consequence is real: you may suppress demand in the treatment markets. Define the exposure change, affected markets, stopping conditions, and recovery plan before launch. If you cannot tolerate the downside, test an increase in selected markets instead.
If you lack comparable geographies, sufficient delivery, or trustworthy outcome data, say that the test is inconclusive. An attribution model can help describe journeys, but changing the model does not create a control group and should not be presented as proof of incrementality.
Read the result as a system, then make one budget move
Begin evaluation with the primary outcome written into the brief. Then use supporting metrics to explain why it moved or why it did not. This order matters. It stops an improvement in an easy platform metric from masking a flat business result.
Question
Useful signal
Misreading to avoid
Did social create more brand demand?
Change in branded paid search impressions and clicks in treatment versus control markets
Judging the effect only by social last-click conversions
Did familiarity change search response?
Brand and non-brand paid search click-through and conversion rates
Calling every rate change causal without a control
Could paid search capture added demand?
Impression share and budget status
Reading flat search clicks as proof that demand did not change when delivery was constrained
Did the path between channels change?
Visitor overlap, conversion touchpoints, and attribution-model comparisons
Treating descriptive journey data as an incrementality test
Did an external event journey work?
Campaign clicks, site sessions, registrations, qualified registrations, and attendance
Optimizing to engagement while losing registration quality after the click
Expect the supporting metrics to disagree occasionally. Reducing social spend can produce mixed conversion-rate changes across regions even when overall conversions decline. A decline in branded search volume may strengthen the case that social supported demand, while a rising conversion rate may simply show that the remaining visitors had stronger intent. The conversion rate alone would tell the wrong story.
When the result looks unusually large, investigate before scaling. Check tracking releases, site changes, inventory, promotions, search budgets, regional events, and changes to platform delivery. An anomaly is a reason to inspect the mechanism, not an invitation to replace the original hypothesis.
Finish with one of four decisions: scale the tested change, reverse it, keep the current allocation, or run a narrower follow-up test. State which evidence drove the choice and which uncertainty remains. Avoid changing audiences, creative, bids, destination, and budget simultaneously after a test; you will lose the ability to learn which adjustment mattered.
For your next planning cycle, choose one disputed budget question and write its hypothesis before opening an ad platform. Lock the conversion definition, identify a credible control, verify the end-to-end path, and agree on the decision rule. That turns cross-channel measurement from a reporting exercise into a repeatable way to allocate spend.
You found your brand in an AI answer once. Or you searched several prompts, found nothing, and now need to explain whether that absence matters. A screenshot cannot tell you whether your content is consistently selected, accurately represented, or visible during the decisions that matter to your audience.
You need a repeatable measurement system: a fixed set of real questions, a record of what each answer says and cites, clear denominators, and a publishing loop tied to the gaps you observe. That turns AI visibility from an anecdote into something you can diagnose and improve.
Measure the visibility chain, not one AI score
AI visibility is not a single event. A brand can be named without a link, cited without being named prominently, or cited accurately in an answer that produces no identifiable visit. Combining those outcomes into one score hides the part of the system that needs work.
Measure five distinct layers:
Query coverage: Are you testing the questions that represent the audience and decisions you care about?
Answer visibility: Does your brand, product, expert, data, or content appear in the generated answer?
Citation visibility: Does the answer link to your domain, and which URL does it select?
Representation quality: Does the answer accurately reflect what the cited page supports?
Business response: Do identifiable visits or other attributable interactions lead to a meaningful next step?
The distinctions matter. A mention tells you the system associates your entity with the topic. A citation tells you a page was selected as supporting material. An attributable visit tells you someone continued from the answer to your site. None is a substitute for the others.
This is also why AI referral traffic should not be your only visibility measure. A complete answer may expose your brand and cite your work without producing a click. Conversely, a visit can arrive from an AI surface even when your brand was peripheral to the answer. Keep answer-level evidence beside your analytics data instead of expecting either dataset to explain the other.
Microsoft has previewed Bing Webmaster Tools capabilities involving citation share, query-intent grounding, GEO recommendations, and 15 predefined intents. The exact functionality and release timing were unclear in that preview. Until any such capability is available in your account and its definitions are documented, maintain an independent baseline that you control.
Your baseline should be narrower than the entire web. Overall domain leadership can be interesting, but it does not answer whether you are visible for your audience’s questions. Measure your citation share within a defined prompt cohort, engine, surface, market, and observation window.
Build a query set around decisions your audience makes
A list of high-volume keywords is not an AI visibility test. AI prompts often include a task, a constraint, and a request for judgment. Your query set should preserve those elements because they affect the kind of answer and evidence the system needs.
Start with user decisions, then write the prompts
Choose a topic cluster with a clear business or editorial purpose. Avoid mixing every subject your domain covers into one benchmark.
List the decisions people make within that cluster. Useful categories include learning, comparing, evaluating, troubleshooting, verifying a claim, and choosing a next step.
Write natural prompts for each decision. Include relevant audience, use-case, location, budget, technical, or risk constraints when those constraints would change a good answer.
Separate branded prompts from nonbranded prompts. A question containing your name measures different demand from one that asks the system to discover suitable entities.
Record the evidence type an adequate answer would need, such as a definition, method, first-party observation, comparison, specification, or current policy.
Assign a stable prompt ID and freeze the wording for the baseline. If you later improve a prompt, create a new version instead of silently replacing the old one.
You do not need to force every question into a universal intent taxonomy. The 15-intent system previewed for Bing may eventually provide a useful platform view, but your internal taxonomy should reflect the decisions your organization can act on. Keep a mapping field so platform-defined intents can be added later without rebuilding the dataset.
Prompt variants are useful when they test a real difference. For example, a broad request for an explanation and a constrained request for an option suitable for a regulated team represent different evidence needs. Cosmetic rewordings create more rows without giving you a better decision.
Store every run as an observation
An observation is one exact prompt submitted to one recorded AI surface under known conditions. At minimum, store:
Run date and time
AI product, model or surface when exposed, and access method
Account or session status, locale, and other conditions you intentionally control
Prompt ID, prompt version, and exact prompt text
Complete answer capture or an approved archival equivalent
Brand mention status and the wording surrounding the mention
Every cited domain and exact cited URL
The claim each citation appears to support
Whether your cited page fully, partly, or does not support that claim
Run status for refusals, errors, empty answers, or unavailable citations
Do not delete failed runs simply because they complicate the spreadsheet. Give them a status and apply the same inclusion rule across reporting periods. Quietly excluding inconvenient observations changes the denominator and can manufacture an apparent improvement.
Generated answers can vary between repeated observations. Treat one result as an observation, not a durable ranking position. Choose a repeat protocol before looking at performance, then keep the prompt set, conditions, and cadence as stable as practical. A directional editorial check can use a smaller fixed cohort; a decision that reallocates substantial budget deserves repeated observations across more than one run.
Calculate metrics with explicit, auditable denominators
Every percentage needs a written numerator, denominator, deduplication rule, and scope. Without them, two dashboards can use the same label while measuring different things.
Metric
Operational definition
What it helps you decide
Brand mention rate
Valid observations that name the tracked brand divided by all valid observations in the cohort.
Whether the brand is associated with the tested topics, regardless of links.
Domain citation rate
Valid observations with at least one citation to the tracked domain divided by all valid observations.
How often the domain earns any supporting role.
Citation share
Distinct citations to the tracked domain divided by all distinct external citations observed in the same cohort.
How much of the available citation set your domain captures.
Topic citation coverage
Tracked prompt topics with at least one domain citation divided by all tracked prompt topics.
Whether citations extend across the cluster or depend on a narrow pocket of demand.
Citation accuracy
Reviewed domain citations whose pages materially support the adjacent claim divided by all reviewed domain citations.
Whether visibility is trustworthy rather than merely present.
Cited-page concentration
Citations to the most-selected URL divided by all citations to the domain.
Whether one page carries the cluster or citation value is distributed across useful resources.
Attributed outcome rate
Qualified actions credited under your documented analytics rules divided by identifiable visits from the tracked surfaces.
Whether measurable downstream behavior follows the visibility you can attribute.
For citation share, counting each distinct cited URL once per observation is a practical default. It prevents a repeated link inside one answer from inflating its importance. You can choose another rule, but document it and do not compare your result directly with a vendor metric until you know that its counting method matches yours.
Scale alone does not make a benchmark relevant. AI citation analysis has already encompassed 58.6 million citations and domain-level patterns, but your operational denominator should remain the answers connected to your market. A globally dominant domain can still be absent from a specialist decision journey, while a smaller domain can be highly visible inside a narrow, valuable cluster.
Always report the count beside the rate. A movement from one citation to another can look dramatic when the denominator is small. The raw numerator, valid-observation count, and number of prompt topics stop that percentage from carrying more confidence than the dataset supports.
Segment before you average. At minimum, separate engine or surface, intent, topic cluster, branded versus nonbranded prompts, and audience or market where applicable. If one segment gains while another loses, a blended number can report no change and conceal both events.
A useful recurring dashboard should show:
Each rate with its numerator and denominator
Change against the same frozen baseline cohort
Prompts that gained or lost mentions and citations
New, lost, and most frequently selected URLs
Citations marked partly aligned or misaligned with the answer’s claim
Competitor or third-party domains repeatedly selected for the same claim class
Identifiable visits and qualified actions, kept separate from answer visibility
Avoid compressing all of this into a proprietary composite unless every component and weight remains visible. A rising composite cannot tell an editor whether to fix evidence, clarify an entity, consolidate a URL, or target a different question.
Diagnose the citation gap before rewriting content
A missing citation is a symptom, not a diagnosis. Read the answer, the adjacent claim, the URLs selected, and your own candidate page before deciding what to change.
Your entity is absent from both the answer and citations
First confirm that the prompt belongs in your target market and that you have a page capable of answering it. Then inspect the selected sources at claim level: what fact, explanation, comparison, or qualification do they supply that your page does not?
Check basic access and consolidation signals as well. A page that returns an error, blocks discovery, points elsewhere through its canonical configuration, or duplicates several competing URLs creates a different problem from a page that is technically available but adds little useful information. Do not label every absence a technical SEO failure.
Your brand is mentioned but not cited
Record the mention as entity visibility, not as a citation win. Identify the claim that would reasonably need support and see which third-party pages are used for it. Your next content change should make that claim easier to verify with a precise answer, evidence, scope, and method. Repeating the brand name more often does not create support.
The domain is cited, but the wrong page is selected
Decide whether the selected URL is genuinely wrong or merely different from the page your team expected. If it supports the claim well and serves the user, the citation may be valid even when it does not match your campaign landing page.
If several near-duplicate pages compete for the same claim, clarify their purposes, improve internal linking, and review canonical signals. Do not delete or redirect a selected page until you have checked whether it serves a unique intent, attracts links, or receives useful traffic. Consolidation can improve clarity, but an unnecessary redirect can discard a working resource.
The citation exists, but the answer misrepresents the page
Treat inaccurate representation as a higher-priority issue than a modest visibility decline. Record the exact answer and cited passage. Make the relevant fact explicit, keep names and qualifiers consistent, distinguish current information from historical material, and remove ambiguous wording that could support the wrong interpretation.
Structured data should agree with the visible page, but markup cannot repair a contradiction in the prose. After clarifying the page, preserve the original observation and test the same prompt again under the established protocol. That gives you evidence of change without pretending one new answer proves a permanent correction.
Citations rise, but attributable outcomes do not
Segment the gains by intent before judging them. Citations earned on broad learning prompts may play a different role from citations attached to evaluation or troubleshooting questions. Check whether the cited page offers a sensible next step for that intent and whether your analytics can identify the visit.
A citation with no attributable visit may still affect awareness, but your dataset cannot prove that effect. Report the citation as visibility and the absent visit as an attribution limit. Do not convert an unmeasured possibility into claimed revenue impact.
Finally, distinguish sustained movement from answer drift. A single appearance or disappearance should send you to the underlying observations. A repeated pattern within the same frozen prompt cluster is a stronger reason to change content or strategy.
Improve citation-worthiness, then rerun the same test
Once you know which claim or intent is missing, improve the smallest content unit capable of solving that gap. The goal is not to make a page longer. It is to make the relevant answer easier to identify, verify, qualify, and cite.
Net information gain is useful here because it asks what your page contributes beyond a familiar restatement. Content becomes more distinctive when it adds new observations, documented experience, and an explicit point of view. Those elements still need evidence and scope. An unsupported hot take is different from a clear conclusion grounded in facts a reader can inspect.
For the claim you want an answer engine to use, check for these elements:
A direct answer near the start of the relevant section
A clear statement of who, what, version, market, or condition the answer applies to
Claim-sized evidence that supports the exact conclusion rather than the general topic
Original information that is genuinely yours, such as a transparent method, first-party observation, or clearly scoped professional judgment
Definitions for terms that could otherwise be interpreted in more than one way
Visible dates and distinctions between current and historical information where timing matters
Consistent organization, product, author, and page names across prose, metadata, structured data, and internal links
A stable, accessible URL whose primary purpose matches the claim
Use structured data as a description layer
Accurate JSON-LD can clarify what a page describes and how its entities relate. It cannot manufacture authority, originality, or factual support that the visible content lacks. Use appropriate Schema.org types and properties, keep values consistent with the page, and do not mark up claims or content users cannot see.
Schema work should follow the diagnostic evidence. If the answer confuses your organization with a similarly named entity, entity consistency may deserve attention. If competing pages provide a better-supported comparison, adding more markup to a thin page misses the problem.
Run a controlled publishing loop
Select one prompt cluster with a repeatable visibility, citation, or accuracy gap.
Save the baseline answers, citations, metrics, page version, and technical state.
Write a specific hypothesis, such as adding missing methodology will make this page a better source for this claim.
Make the smallest coherent content and markup change that tests the hypothesis. If several changes must ship together, log them as one bundle.
Verify the visible page, metadata, structured data, canonical configuration, links, and response status after publishing.
Allow the relevant systems an opportunity to rediscover the update; the delay will vary, so do not invent a universal waiting period.
Rerun the frozen prompts using the same observation protocol and compare like-for-like segments.
Inspect the actual answers and citation alignment before accepting a rate change as improvement.
Keep a change when it improves the intended metric without creating an accuracy, user-experience, or business regression. If nothing moves, the result is still useful: revisit whether the page, claim, prompt cohort, or technical hypothesis was wrong instead of adding unrelated content.
Key takeaways
Measure mentions, citations, accuracy, and attributable outcomes separately.
Define citation share inside a fixed prompt cohort, not against an undefined view of the entire web.
Store exact prompts, answers, URLs, conditions, and run statuses so every metric can be audited.
Report numerators and denominators, then segment by surface, intent, topic, and branded status.
Diagnose the missing claim or evidence before changing content, schema, or site architecture.
Improve net information gain and rerun the same test; one new answer is evidence, not a permanent ranking.
Start with one commercially or editorially important topic cluster. Freeze its prompts, capture the current answers, and calculate mention rate, domain citation rate, citation share, and citation accuracy. That first clean baseline will tell you more than a broad visibility score because it gives your next content decision a traceable reason.