Category: Analytics & conversion

  • Modern Marketing Analytics and Reporting That Drives Action

    Modern Marketing Analytics and Reporting That Drives Action

    Your dashboard is green, the meeting starts soon, and you still cannot answer the question that matters: what changed, why did it change, and what should the team do next?

    That is a reporting-system problem, not a chart problem. Modern marketing analytics should connect business outcomes to channel activity, preserve the definitions behind every metric, expose uncertainty, and deliver the next decision without forcing someone to reconstruct the analysis during the meeting.

    Start with the decision, not the available data

    Most bloated reports begin with a harmless question: what data can we pull? Every available metric gets added, the dashboard becomes comprehensive, and the decision it was meant to support disappears.

    Reverse the sequence. Before choosing a connector, chart, or reporting platform, write a one-sentence measurement brief:

    This report helps [owner] decide [action] at [cadence] by comparing [outcome] with [baseline], using [drivers] to explain the result and [guardrails] to prevent a bad trade-off.

    A paid media lead might need to reallocate campaign budget each week. A content lead might need to decide which topics deserve an update, expansion, or new format. An SEO lead might need to distinguish a visibility problem from a conversion problem. These decisions require different evidence even when they draw from the same underlying data.

    Assign every metric a role. If a metric has no role, remove it from the primary report.

    Metric roleQuestion it answersMarketing exampleHow it should affect action
    OutcomeDid the work produce the intended business result?Qualified conversions, pipeline, revenue, retained customersDetermines whether the strategy is working
    DriverWhat directly influenced the outcome?Qualified traffic, landing-page conversion rate, lead acceptanceIdentifies where to intervene
    DiagnosticWhere did performance change?Campaign, query group, page type, audience, device, videoNarrows the investigation
    GuardrailWhat must not deteriorate while the team optimizes?Acquisition cost, lead quality, unsubscribe rate, brand demandPrevents a local gain from becoming a business loss

    This hierarchy corrects a common reporting mistake. Impressions, views, clicks, and engagement can be useful drivers or diagnostics, but they do not automatically become business outcomes because they are easy to retrieve. Likewise, a channel-level return figure is not trustworthy unless the report states what counts as a conversion, which costs are included, and how credit is assigned.

    Record five items beside every primary outcome: its definition, owner, data system, update cadence, and attribution rule. If attribution is involved, also state the model, lookback window, reporting timezone, currency treatment, and whether the metric uses event time or processing time. There is no universally correct attribution model. There is only a model that is explicit enough to interpret and consistent enough to compare.

    Set action rules before looking at the latest result. The rule does not need an invented universal threshold. It can be operational: investigate when an outcome moves outside its expected range, when a guardrail worsens, when the data is stale, or when two systems no longer reconcile. Precommitting to the rule reduces the temptation to invent a convenient explanation after seeing the chart.

    Standardize the data before you visualize it
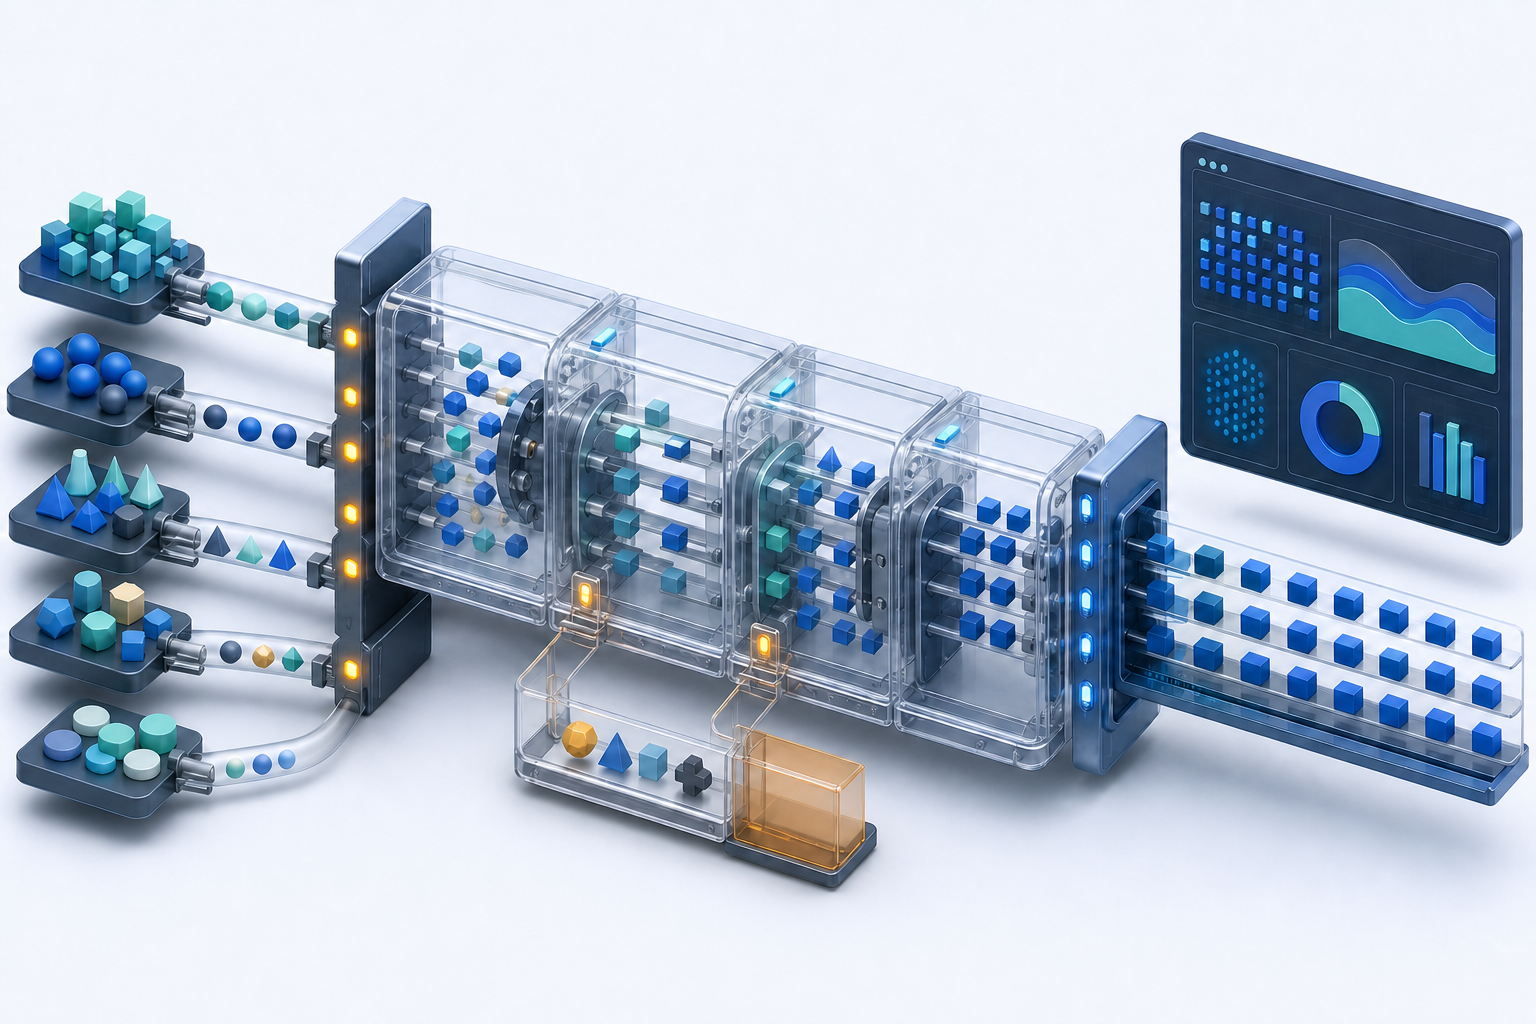
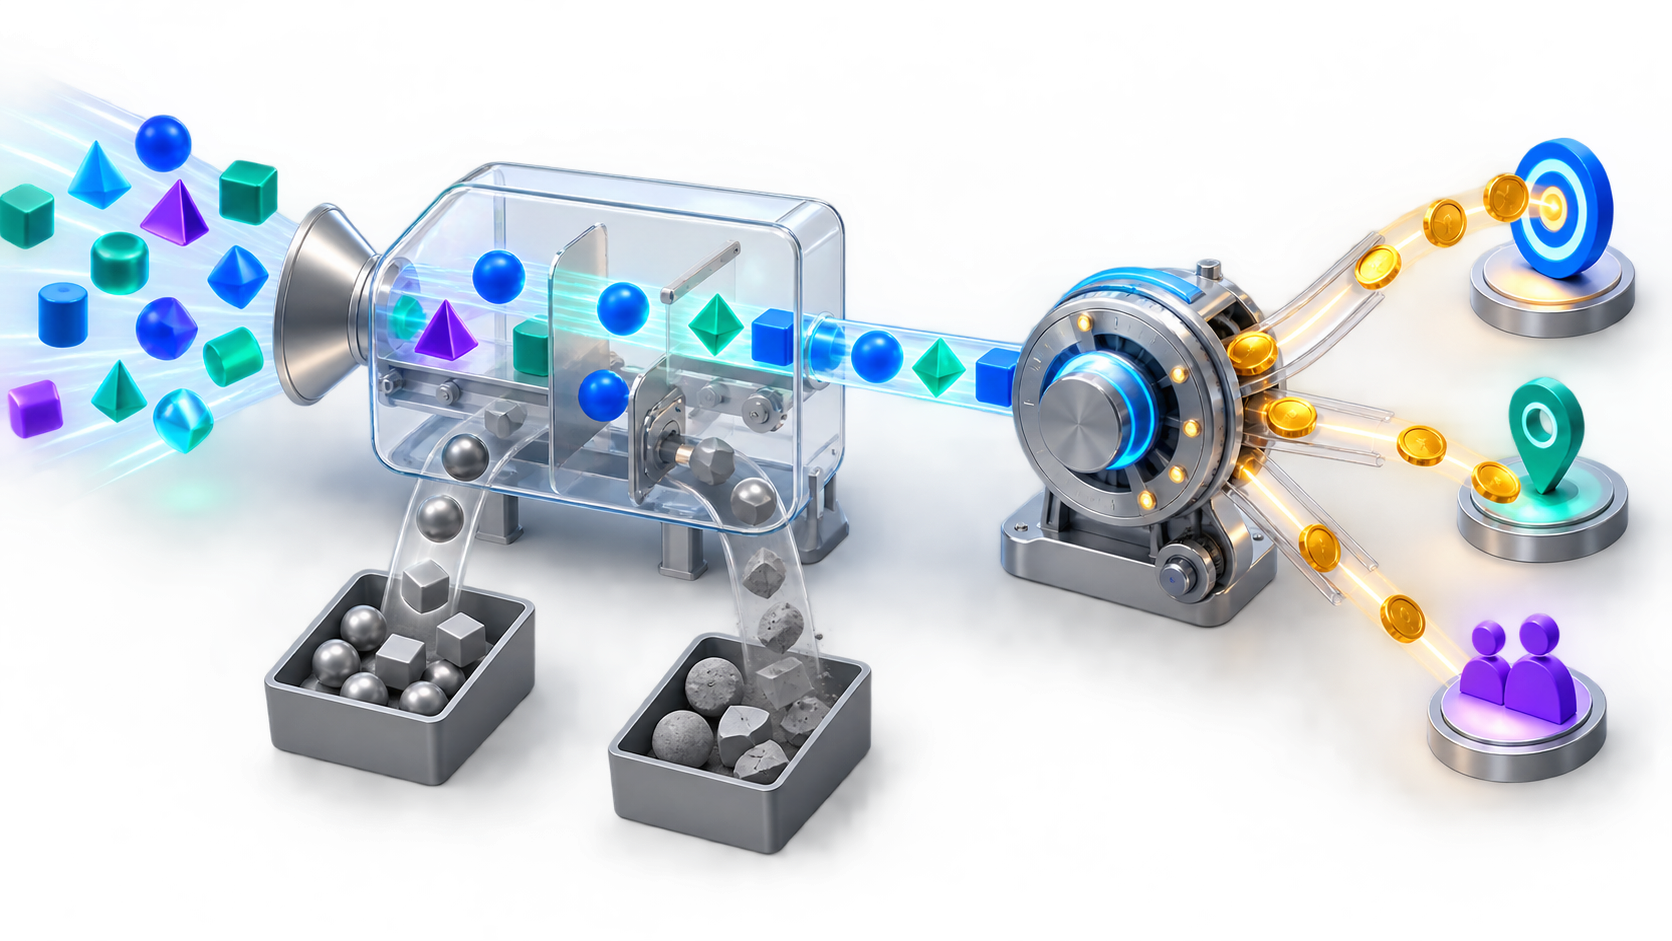
    Different shapes of marketing data pass through a modular processing system and emerge as standardized units for visualization.

    A polished dashboard cannot repair inconsistent definitions underneath it. If paid media uses platform-reported conversions, analytics uses attributed sessions, sales uses accepted opportunities, and finance uses recognized revenue, placing the figures on one page does not make them comparable.

    Create a small data contract for each reporting dataset. It should specify:

    • Grain: what one row represents, such as one campaign-day, page-query-day, video-day, lead, opportunity, or order.
    • Keys: the fields that uniquely identify a row and connect it to other datasets.
    • Dimensions: the controlled names for channel, campaign, market, device, content type, audience, and funnel stage.
    • Metric definitions: the exact event or business state counted by each field.
    • Time rules: timezone, date field, reporting window, and treatment of late-arriving records.
    • Freshness: when the data should be available and how the report signals a delayed refresh.
    • Ownership: who approves definition changes and who responds when a pipeline fails.
    • Lineage: where the data originated and which transformations changed it.

    Grain is the detail most likely to prevent a silent reporting error. Joining campaign-day costs to lead-level conversions can multiply spend when several leads share the same campaign and date. Aggregate both datasets to a compatible grain before joining them, or model the relationship so the cost appears only once. After every join, compare row counts and totals with the inputs.

    Separate period reporting from cohort reporting. A period view answers what happened during a selected date range. A cohort view follows people, accounts, campaigns, or content acquired in a particular period through later outcomes. A recent acquisition cohort may look weak simply because its conversions have not had time to mature. Label incomplete cohorts instead of presenting them as final.

    Run a compact quality checklist before publishing any result:

    • Reconcile source totals using the same date range, timezone, filters, and conversion definition.
    • Test whether fields declared unique are actually unique.
    • Check for missing dates, unexpected nulls, duplicate records, and values outside possible ranges.
    • Compare current dimensions with the approved taxonomy so renamed campaigns or channels do not create false categories.
    • Display the latest successful refresh time in the report itself.
    • Mark provisional data and document whether upstream systems can restate earlier periods.
    • Preserve raw extracts or reproducible snapshots so a changed connector does not rewrite history without explanation.

    Do not hide a reconciliation gap with a calculated adjustment. If two systems answer different questions, label the difference. If they should match and do not, hold the affected conclusion until you know why. A visible limitation is manageable; an invisible one becomes a decision error.

    Give dashboards, code, APIs, and AI separate jobs

    A modern reporting stack does not require one tool to extract, clean, model, visualize, explain, and distribute everything. It works better when each layer has a narrow responsibility:

    1. Source layer: advertising platforms, analytics products, CRM records, commerce systems, search data, video analytics, and approved research inputs.
    2. Ingestion layer: connectors, APIs, exports, or controlled uploads that retrieve data without changing its business meaning.
    3. Raw layer: immutable or reproducible copies of the retrieved records.
    4. Transformation layer: code or managed queries that clean names, join datasets, apply definitions, and create tested calculations.
    5. Semantic layer: approved dimensions, metrics, relationships, and attribution labels shared across reports.
    6. Presentation layer: dashboards, tables, charts, written analysis, and exported snapshots designed for a specific audience.
    7. Delivery layer: scheduled distribution, access controls, alerts, meeting workflows, and an archive of what stakeholders received.

    Dashboards are effective presentation surfaces when stakeholders need filters, recurring monitoring, and a shared view without access to every backend system. A Looker Studio report can, for example, connect YouTube Analytics data, support customized views, and distribute scheduled PDF snapshots. That makes it useful for a channel owner who needs repeatable visibility rather than a custom analysis every morning.

    Keep the dashboard when its data volume is manageable, the transformations are simple, refreshes complete reliably, and an analyst can trace a wrong number back to its origin. Move complex logic upstream when the same calculated field is copied across pages, manual updates recur, refreshes become fragile, or debugging requires a long sequence of interface clicks. Broad datasets and accumulated business logic can make a dashboard slow to change, difficult to debug, and vulnerable to dataset limits.

    Code is a better home for repeatable extraction, normalization, backfills, joins, tests, and calculations that need review. It gives you files that can be compared, versioned, and rerun. That does not mean every marketing team needs to replace every dashboard. A practical architecture keeps a familiar dashboard at the front while moving fragile transformations into a controlled pipeline behind it.

    APIs are retrieval mechanisms, not guarantees of completeness. For every API connection, record the account or property queried, requested fields, filters, pagination behavior, expected refresh schedule, and the response received when data is unavailable. Keep credentials outside report code, grant only the access required, and plan for permission revocation. A successful request proves that data arrived; reconciliation proves that the right data arrived.

    AI coding assistants can reduce the effort required to scaffold connectors, transformations, tests, and report components. Natural-language specifications can help tools such as Claude Code and OpenAI Codex assemble multistep reporting workflows. Treat the generated work as a draft implementation. Review the query grain, inspect joins, run tests, protect secrets, and compare outputs with authoritative systems before a generated number reaches a stakeholder.

    Use AI differently in the analysis layer. Ask it to identify anomalies worth investigating, draft plain-language explanations from approved metrics, or translate a validated analysis for different audiences. Do not let it infer causation from a correlated chart or invent a reason for a movement that the data cannot explain. The final narrative should distinguish among a measured fact, an analyst interpretation, and a proposed test.

    Design separate views for decisions, operations, and diagnosis
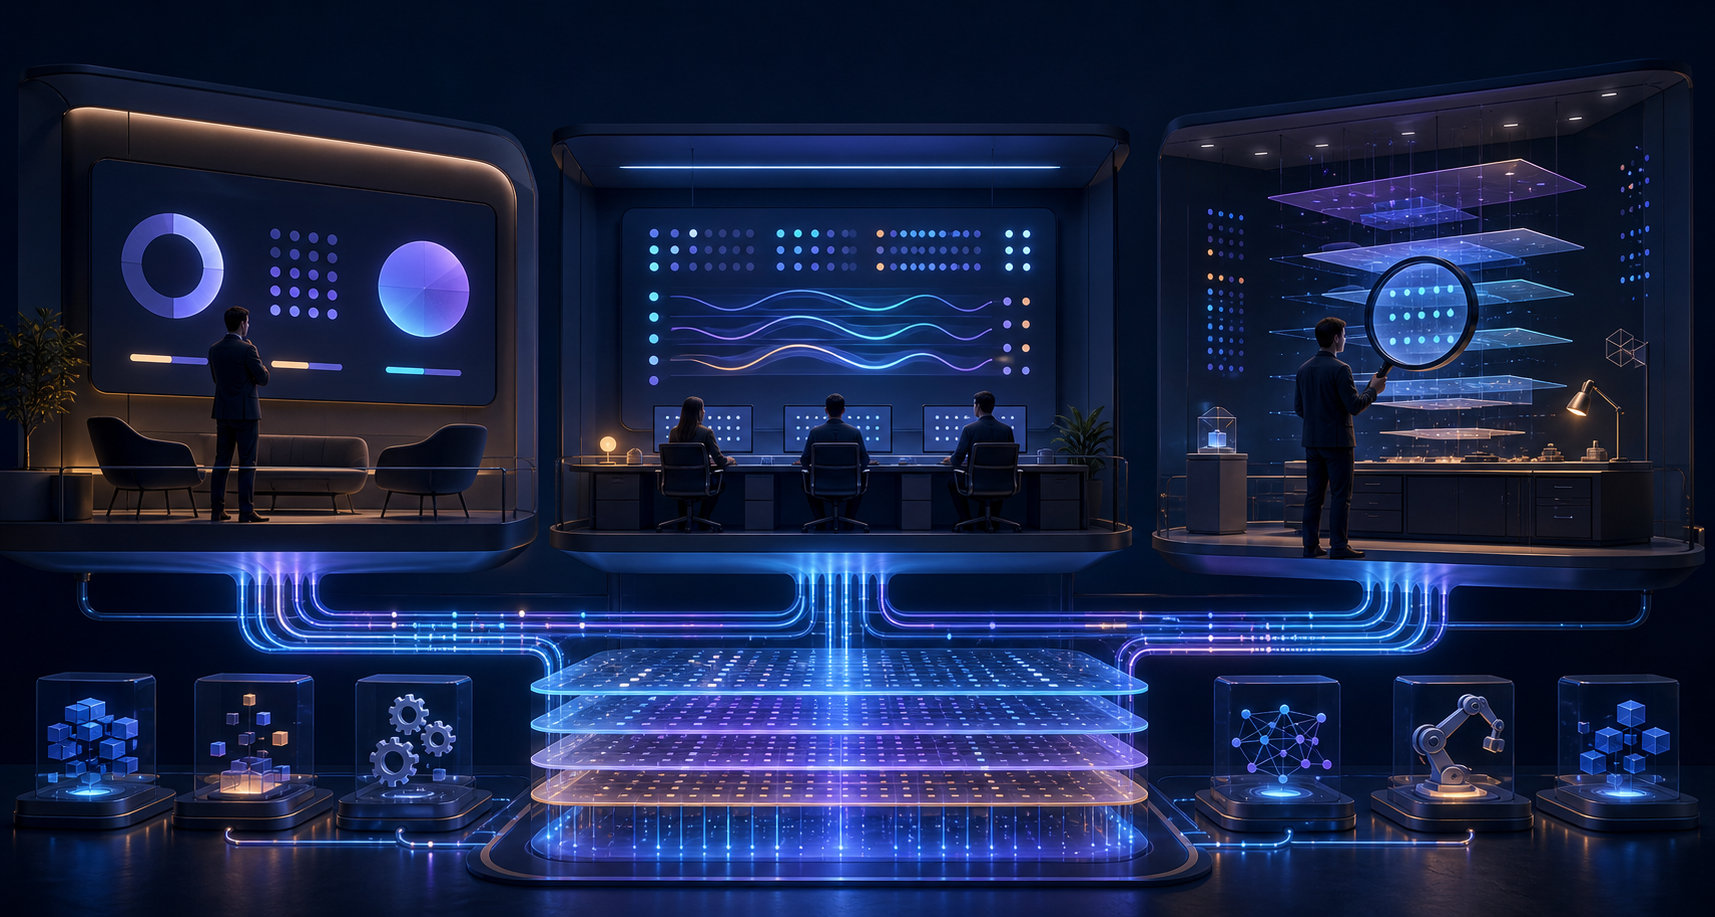
    Three connected analytics workspaces show separate areas for executive decisions, operational monitoring, and detailed diagnosis.

    One dashboard should not try to answer every question for every person. An executive wants to know whether the business outcome changed and whether intervention is needed. A channel operator needs enough detail to choose the intervention. An analyst needs access to definitions, segments, and reconciliation evidence.

    Build three layers, even if they live in the same reporting product:

    • Decision view: the primary outcome, comparison period or baseline, guardrails, material changes, confidence limits, and the requested decision.
    • Operating view: the drivers a channel owner can change, organized by campaign, content group, market, audience, or other actionable unit.
    • Diagnostic view: deeper segments, data-quality checks, metric definitions, lineage, and enough detail to reproduce the conclusion.

    Put context next to the metric it qualifies. A global note at the bottom of a long report will not protect a chart at the top from misinterpretation. Each primary view should show its date range, comparison basis, filters, timezone, attribution label, refresh timestamp, and any material gap in coverage.

    Add a short narrative block to every decision view:

    • Result: what changed in the outcome.
    • Driver: which measured movement best explains the change.
    • Confidence: what is known, what remains uncertain, and whether the data is complete.
    • Action: the decision or test now recommended.
    • Ownership: who will act and when the result will be reviewed.

    Be strict about causal language. If a campaign change and a conversion change occurred together, say they coincided unless the measurement design supports a stronger claim. If an experiment or another credible identification method isolates the effect, explain that method. Precision in the wording is part of analytics quality.

    Annotations should capture business events that a chart cannot know: a campaign launch, budget change, tracking migration, site release, promotion, pricing change, consent update, or outage. Store the event date, owner, affected scope, and a brief description. An annotation is a lead for investigation, not automatic proof that the event caused the movement.

    Distribution needs the same discipline as analysis. A scheduled PDF is a fixed snapshot, so include its reporting window and data cutoff. Link it to the interactive view when recipients may need filters or diagnostics. Archive material snapshots used for recurring business decisions; otherwise a later refresh can leave the team debating a number that no longer appears on screen.

    Access is part of report design. Stakeholders should not need administrative access to every marketing platform simply to read an approved result. The reporting team, however, must document which account and permission power each connection. With YouTube Analytics, a report builder who does not own the channel may need Manager permission and the Channel ID entered through the connector’s advanced settings. Test delegated access with the actual reporting identity instead of assuming that a visible channel in YouTube Studio will automatically appear in the reporting connector.

    Migrate one recurring report and operate it like a product

    A wholesale reporting rebuild creates too many simultaneous unknowns. Start with one recurring workflow that consumes meaningful time, has a known audience, and regularly produces a decision. A pre-meeting channel report, weekly SEO performance brief, or campaign pacing view is a better migration candidate than an enterprise-wide measurement platform.

    1. Freeze the current output. Save the existing report, its filters, definitions, recipients, delivery timing, and a few representative reporting periods. This becomes your comparison set.
    2. Write the decision contract. Identify the decision, owner, cadence, outcome, drivers, guardrails, and action rules. Remove fields that do not support them.
    3. Inventory data and permissions. Record every account, property, channel, connector, export, credential owner, and approval dependency. Confirm access using the service identity that will run the production workflow.
    4. Build reproducible ingestion. Preserve raw data, log retrieval times, handle pagination and empty responses, and make reruns safe.
    5. Encode transformations once. Normalize taxonomies, define joins, centralize calculations, and add tests for uniqueness, completeness, freshness, and reconciliation.
    6. Rebuild the three reporting views. Keep the decision page concise, give operators actionable detail, and retain diagnostic evidence for analysts.
    7. Run old and new systems in parallel. Investigate differences using matched definitions, filters, and time rules. Do not retire the old workflow until material discrepancies are explained and the team has a rollback path.
    8. Document production ownership. Assign responsibility for data failures, definition changes, access reviews, report delivery, and stakeholder questions.

    The parallel run matters because two reports can display plausible but different numbers. A discrepancy may come from timezone boundaries, attribution logic, late-arriving conversions, deduplication, renamed dimensions, incomplete pagination, or a genuine bug. Matching the old number is not always the goal if the old logic was wrong, but every difference should have an explanation.

    Give the finished workflow a runbook. It should tell another qualified person how to trigger a refresh, locate logs, rerun a failed period, backfill data, rotate credentials, verify source totals, publish the output, and roll back a breaking change. Include the last known successful run and the owner of each upstream dependency.

    Measure the reporting system itself. Track whether scheduled runs complete, whether data meets its freshness expectation, whether reconciliation tests pass, whether recipients receive the right artifact, and whether decisions and owners are captured. The point is not to create a dashboard about dashboards. It is to notice reliability problems before they become meeting problems.

    Key takeaways

    • Define the decision, owner, cadence, outcome, drivers, guardrails, and action rule before selecting metrics.
    • Standardize grain, keys, definitions, time rules, freshness, ownership, and lineage before building charts.
    • Keep dashboards for accessible presentation; move repeatable extraction, complex transformations, tests, and backfills into code when interface logic becomes fragile.
    • Use AI to accelerate implementation and explanation, but validate grain, joins, permissions, calculations, and source reconciliation before publication.
    • Separate decision, operating, and diagnostic views so each audience gets enough detail without inheriting everyone else’s dashboard.
    • Migrate one recurring workflow, run it beside the existing report, explain every material discrepancy, and preserve a rollback path.

    Choose the recurring report that causes the most avoidable pre-meeting work. Write its decision contract, mark every metric as an outcome, driver, diagnostic, or guardrail, and remove anything that serves no decision. That small redesign will show you exactly where the next improvement belongs: the definition, the data pipeline, the analysis, or the delivery.

    References


  • How to Build Trust With Data in AI and SEO Decisions

    How to Build Trust With Data in AI and SEO Decisions

    Your dashboard can be technically correct and still fail the meeting. If nobody can explain who is represented, how the number was produced, or whether automated and fraudulent activity was removed, the chart asks people to take your conclusions on faith.

    Trust comes from making the evidence inspectable. You should be able to move from a recommendation to its claim, from the claim to its metric, from the metric to the underlying records, and from those records back to their origin. Assumptions, exclusions, and uncertainty need to remain visible throughout that chain.

    Trust starts with a claim your data can support

    A precise-looking number is not automatically a trustworthy number. Decimal places, clean schemas, polished charts, and large record counts can make data appear authoritative without proving that it represents the right people, activities, or period.

    This distinction matters when AI enters the workflow. An AI system can process weak data efficiently, but it cannot independently establish that an identity is genuine or an event is meaningful. In practice, AI can amplify fragmented, outdated, or manipulated inputs and return the result with more confidence than the evidence deserves.

    Before you analyze a dataset, make its intended claim explicit. Then test the claim against six questions:

    • Entity: Who or what does each record represent? Determine whether identifiers refer to the same person, account, page, organization, query, or session across the systems involved.
    • Activity: What actually happened? Separate a recorded event from an authentic action with business or user value.
    • Time: When was the record true, collected, and refreshed? A valid historical snapshot should not be treated as a current state.
    • Origin: Which system created the record, and which system merely copied or transformed it? Name the accountable owner.
    • Exclusions: Which records were filtered out, suppressed, deduplicated, or classified as suspicious? Record the rule and its reason.
    • Decision fit: Does the dataset measure the decision in front of you, or only a convenient proxy for it?

    If you cannot answer one of those questions, narrow the claim. For example, do not report that AI visibility improved everywhere when you measured only a defined set of prompts and answer environments. State that limited scope in the claim itself. A smaller claim that can be verified is more useful than a sweeping conclusion that cannot survive inspection.

    Clean structure is still valuable, but it solves a different problem. A record can have the expected fields, valid syntax, and consistent formatting while referring to the wrong identity or a fabricated activity. Structural validity tells you that the data can be processed. It does not prove that the data is accurate.

    Create an evidence card for every decision-bearing claim

    Hands arrange transparent evidence tiles linked to a central token, with one tile lifted to reveal the granular pieces beneath it.

    A dashboard rarely carries enough context on its own. Filters live in one tool, transformations in another, and caveats in somebody’s memory. When the result is challenged, the team has to reconstruct the reasoning after the fact.

    Use a compact evidence card for each claim that could change a budget, campaign, content plan, model, or workflow. Store it beside the analysis rather than in private notes.

    1. Decision: Write the choice this evidence is meant to inform. If no decision changes, question whether the metric belongs in the report.
    2. Claim: State one sentence that the data directly supports. Avoid combining an observation, an explanation, and a recommendation in the same sentence.
    3. Scope: Name the entity, population, channel, property, prompt set, and time window included. Record the denominator where the metric has one.
    4. Definition: Define the metric in operational terms. Specify what creates an event, what qualifies it, and how duplicates are handled.
    5. Lineage: List the originating system, collection method, joins, transformations, filters, and derived fields used to produce the result.
    6. Quality gates: Document the checks applied to identity, authenticity, freshness, completeness, and consistency.
    7. Limitations: Separate known gaps from suspected gaps. Explain how each one could change the conclusion rather than hiding them under a generic disclaimer.
    8. Action and owner: Name the proposed action, the person responsible, the signal that will be monitored, and the condition that would trigger reconsideration.

    The evidence card also protects metric definitions from drifting. If one reporting period counts all detected visits and another excludes suspected automation, the results are not directly comparable. The definition and filter change must travel with the number.

    Keep rejected records and reason codes available for review when your systems permit it. Silently removing questionable data makes a clean result harder to audit. A visible exclusion such as duplicate identity, stale record, suspected automated activity, or missing attribution shows exactly where judgment entered the pipeline.

    Audit AI and SEO inputs before you automate decisions

    AI readiness is often assessed through volume, match rates, or the apparent precision of model output. None of those signals proves that the underlying identities are stable or that the recorded behavior is authentic. Consumers move between devices and profiles, while systems often treat a temporary identity snapshot as permanent. Fraud and low-value activity can then distort both model output and the performance data used to retrain or evaluate it.

    Run an input audit at each layer of an AI SEO or analytics workflow. The purpose is not to certify data as perfect. It is to prevent the claim from becoming broader than the evidence.

    LayerQuestion to verifyMisleading conclusion to prevent
    Observed AI visibilityWhich prompts, answer environments, properties, locations, settings, and collection windows were monitored?A sampled result presented as universal visibility.
    On-site activityAre sessions and events authentic, consistently defined, and separated from suspected automated or fraudulent activity?Machine activity presented as audience demand.
    Identity and attributionCan records be matched to the intended person, account, organization, or journey without treating uncertain matches as confirmed?Inflated reach, duplicated users, or credit assigned to the wrong interaction.
    Business outcomeDoes the conversion represent a reachable, meaningful outcome rather than a form event or low-value identity?Nominal conversions presented as genuine pipeline or customer value.
    Model inputAre the records current, relevant, authentic, and appropriate for the task the model will perform?Confident automation built on an unreliable foundation.

    Treat identity validity and activity authenticity as gates, not decorative quality scores. If either one cannot be established, the affected data may still support exploration, but it should not silently drive targeting, outreach, optimization, or other automated actions.

    Use sensitivity checks when uncertainty is concentrated in a recognizable subset. Compare the conclusion with and without low-confidence identities, suspected automation, stale records, or unmatched events. If removing that subset reverses the recommendation, the recommendation is fragile. Report that dependence before anyone acts on it.

    Watch for feedback loops as well. If fraudulent or low-value behavior improves a reported metric, an optimization system may learn to seek more of it. The apparent performance improvement then reinforces the very contamination that produced it. Suppress or quarantine questionable inputs before they become training signals, targeting criteria, or success labels.

    Separate observation, interpretation, and recommendation

    Three connected workbench stations show raw data pieces, a lens revealing patterns, and several possible paths around a decision marker.

    Many data presentations lose trust because they slide from measurement to causation without marking the transition. A result occurred after a change, so the change is credited with causing it. A visibility metric rose, so business impact is implied. A model found a pattern, so the pattern is treated as a stable rule.

    Use four explicit labels in reports, dashboards, and decision memos:

    • Observed: What the collection method directly recorded within its stated scope.
    • Calculated: What was produced through a documented formula, join, classification, or transformation.
    • Inferred: What the evidence may explain or predict, including plausible alternatives.
    • Unknown: What the current design cannot establish.

    A careful AI visibility statement might say that a page appeared more frequently in the monitored answer set during the review window. That is the observation. Content or structural changes may be plausible contributors, but prompt sampling, model behavior, competitor changes, and measurement differences remain alternative explanations unless the evaluation design rules them out. The recommendation can still be to retain or extend the change, provided the team continues testing the explanation.

    This language is not weakness. It tells the decision-maker which parts are facts, which parts are judgment, and which parts require another measurement cycle. Use causal words such as caused, produced, or drove only when the evaluation was designed to support causality. Otherwise, use language such as coincided with, is consistent with, or may have contributed.

    Do not turn uncertainty into an arbitrary confidence percentage. If confidence has not been calibrated, a precise score creates another unsupported claim. Name the evidence that raises confidence, the gap that lowers it, and the observation that would change your position.

    Use a three-act narrative without turning evidence into theater

    People need more than a pile of verified metrics. They need to understand why the evidence matters and what should happen next. A setup, confrontation, and resolution structure can organize that reasoning while keeping the decision-maker at the center of it.

    1. Setup – establish the baseline and objective. State the decision, the prior strategy, the relevant success criteria, and the conditions in which the data was collected. Show what was working as well as what was not.
    2. Confrontation – expose the obstacle and competing explanations. Present the gap between the objective and the observed state. Include identity problems, suspicious activity, measurement changes, missing coverage, and other facts that could challenge the easy interpretation.
    3. Resolution – connect action to evidence. Recommend the next move, explain which claim supports it, and define the guardrails. State what will be measured next and what result would cause the team to revise the plan.

    The narrative should organize evidence, not rescue it. Do not remove an inconvenient metric because it interrupts the story. Do not portray a forecast as the ending. The resolution is a justified next action with a way to learn, not a guaranteed outcome.

    At the presentation level, use one decision-bearing claim per chart or report block. Put the scope in the title or immediately below it. Display the comparison window, unit, denominator, filters, and relevant definition change close to the result. Place a material limitation beside the claim it limits, where it can affect the decision, rather than collecting caveats at the end.

    Finish each claim with an action, an owner, and a revisit condition. That turns the presentation from a performance into a shared operating record. It also gives future analysis a clean baseline: the team can see what it believed, why it believed it, what it decided, and which evidence later confirmed or challenged that decision.

    Key takeaways

    • Make every claim no broader than the identities, activities, channels, and time window you can verify.
    • Do not confuse structured or complete-looking records with accurate identities and authentic behavior.
    • Give each decision-bearing claim an evidence card containing its scope, definition, lineage, quality checks, limitations, action, and owner.
    • Audit data before it enters an AI workflow because automation can scale unreliable inputs and reinforce contaminated feedback loops.
    • Label observations, calculations, inferences, and unknowns so readers can see where evidence ends and judgment begins.
    • Present the decision as a setup, a confrontation with the real constraints, and a resolution tied to a measurable next action.

    Before your next dashboard review or model run, choose the one claim most likely to change a decision and complete its evidence card. If you cannot identify the entity, activity, window, origin, exclusions, and limitation, narrow the claim before you polish the presentation. Then give the decision-maker a clear next action and a defined reason to revisit it.

    References


  • How to Turn AI Referral Traffic Into Bottom-Funnel Growth

    How to Turn AI Referral Traffic Into Bottom-Funnel Growth

    You may already see the awkward pattern: informational clicks are falling, AI assistants send a thin stream of referrals, and some conversions appear later under direct or branded search. If you judge that pattern with an organic traffic dashboard alone, the strategy can look weaker precisely when it is starting to influence revenue.

    Your job is not to replace every lost pageview. It is to publish the decision-stage answers that buyers and AI systems need, connect those answers to the rest of your site, and measure the journey beyond the first visible click.

    AI referrals are decision-assistance traffic, not replacement pageviews

    An informational search traditionally sent a person to several pages to assemble an answer. An AI interface can now do much of that assembly before the person visits a website. The resulting click is therefore more likely to represent validation, comparison, or purchase research than initial discovery.

    That changes the value of a session. A page that attracts thousands of definition-seeking visitors can produce less commercial movement than a comparison page attracting a much smaller group of people who are choosing between viable options.

    There is evidence that this difference can show up in conversion behavior, but it should not be turned into a universal benchmark. In an Adobe analysis covering more than one trillion visits to U.S. retail websites, AI-referred visits in March converted 42% better than non-AI visits. They also spent 48% more time on site and viewed 13% more pages per visit. A year earlier, AI visits in the same analysis had been 38% less likely to convert.

    Those figures describe U.S. retail traffic, not every market, business model, or AI platform. A retail purchase is not a B2B demo request, and a known brand is not in the same position as an unfamiliar one. Use the finding to form a hypothesis: AI referrals may be lower in volume but further along in the decision process. Then test that hypothesis against your own landing pages, conversions, lead quality, and sales outcomes.

    Key takeaways

    • Judge AI referrals by buying intent and conversion quality, not by whether they replace lost informational traffic.
    • For a pipeline-focused program, consider assigning 60% to 80% of new content effort to mid- and bottom-funnel needs, then adjust from your results.
    • Build comparison content with a disclosed method, consistent criteria, specific limitations, and recommendations for distinct buyer situations.
    • Keep top-funnel content, but give each useful page a clear route into a relevant evaluation or product decision.
    • Measure visible AI referrals alongside citations, branded search, direct visits, qualified leads, and total conversions.

    Rebalance content around the questions that delay a purchase

    A buyer stands among several symbolic decision stations as their branching research paths merge into one clear route toward a product pedestal.

    The strategic shift is not simply from educational articles to product pages. A product page explains what you sell. Bottom-funnel content helps a buyer decide whether it is the right choice, how it compares, where it fits, and what tradeoffs they would accept.

    Start with the questions that appear after a buyer understands the category:

    • Which options are suitable for my industry, company size, use case, or operating constraint?
    • How do two shortlisted products differ on the criteria that matter to me?
    • What are the strengths and limitations of each option?
    • Which product is the better fit for a specific situation?
    • What evidence would let me remove this option from my shortlist?
    • What should I verify before requesting a demo, starting a trial, or making a purchase?

    These are decision tasks, not just keywords. That distinction matters because buyers can express the same task through conventional search, a conversational AI prompt, a follow-up question, or a branded query after seeing a recommendation elsewhere.

    Audit your coverage by task. List your priority products, use cases, buyer groups, and serious alternatives. Then mark whether you have a useful answer for each relevant combination. Typical gaps include:

    • A broad category list with no version for a high-value industry or use case.
    • A product comparison that names features but never explains who should choose which option.
    • An alternatives page that treats every alternative as interchangeable.
    • A use-case page that makes claims without screenshots, expert explanation, or product evidence.
    • An educational page that attracts the right audience but offers no logical next step.

    Prioritize gaps where three conditions overlap: the question occurs close to a purchase, your product has a legitimate reason to be considered, and you can support the answer with specific evidence. A high-intent phrase is not useful if the resulting page would be evasive, generic, or unsupported.

    For teams measured on leads or revenue, a practical starting point is to put 60% to 80% of content effort into mid- and bottom-funnel work. Treat that as a portfolio choice to test, not a law. The right allocation depends on how complete your educational foundation is, how many decision-stage gaps remain, and whether your business has credible evidence for the pages it wants to publish.

    Build comparison pages that remain useful after the click

    A weak comparison page is an advertisement wearing an editorial title. It places the publisher’s product first, assigns vague praise to every option, hides meaningful drawbacks, and ends with an unrelated sales button. Buyers notice the bias. An AI system also has little precise material to reuse because the page never makes a bounded, supportable recommendation.

    A stronger page defines its scope, applies one review method to every option, and makes the tradeoffs visible. A construction-specific time-tracking comparison built this way became a frequently referenced page in LLM responses within weeks and outperformed a dozen earlier informational pages in pipeline impact. That is one documented outcome, not a promise that every listicle will perform the same way. The transferable lesson is the structure: answer a real purchasing question with enough specificity to guide a decision.

    A practical comparison-page blueprint

    1. Define the buyer and decision. State the industry, use case, operating constraint, and type of purchase covered. “Best time-tracking software” is broad; “best time-tracking software for construction” establishes a meaningful evaluation context.
    2. Publish the selection method. Explain how options qualified for inclusion and which criteria were applied. If you cannot explain why a product appears, the list will feel arbitrary.
    3. Give the short answer early. Identify which option fits which situation. Do not force a ready-to-buy reader through a long category lesson before providing the decision map.
    4. Use one comparison framework. Evaluate every option against the same relevant fields. Suitable columns might include best-fit use case, important strengths, material limitations, and the factor a buyer should verify.
    5. Separate fact from judgement. Product capabilities should be factual and current. Recommendations should show the reasoning that connects those facts to a buyer’s situation.
    6. Cover limitations directly. A useful limitation tells the reader who may be poorly served and why. Empty phrases such as “may not suit everyone” add no decision value.
    7. Recommend by situation. End with conditional guidance rather than a single universal winner. Different constraints can produce different correct choices.
    8. Place the next step in context. Put a demo, trial, pricing, or product link beside the point where it becomes useful. Do not rely on one generic call to action at the bottom.

    Credibility rules for including your own product

    You can include your own product when it genuinely meets the selection method. Disclose the relationship plainly, subject it to the same criteria, and resist the urge to make it the winner for every buyer. If an alternative is better for a particular situation, say so.

    Use screenshots, named features, and expert explanations where they help a buyer verify a claim. Keep each product section structurally consistent. A reader should not receive detailed drawbacks for competitors and only promotional language for your product.

    Write recommendations as complete, bounded statements. “Option A is the better fit for teams that need [capability], while Option B is more suitable when [different constraint] matters” is more useful than “Option A is best overall.” The bounded version exposes the reasoning, gives the buyer a usable distinction, and is less likely to be quoted outside its intended context.

    Update the page when the underlying facts change. A polished comparison built on stale capabilities is still unreliable. Record the last substantive review date, recheck each option using the published method, and remove claims you can no longer support.

    Give top-funnel content a direct route to the decision

    Top-funnel content still has an important job. It can establish the concepts a buyer needs, complete a topic cluster, attract relevant links, and pass internal link equity toward decision-stage pages. What has changed is the economics of publishing generic explanations that an AI result can answer without a click.

    Do not delete useful educational pages merely because their traffic has softened. Start with the pages that still reach the right audience and give each one a deliberate handoff:

    1. Identify the next decision. After reading the page, what question would a qualified buyer naturally ask? That question should determine the destination link.
    2. Add evidence where the subject touches your product. A relevant screenshot, implementation detail, or expert observation can turn an abstract explanation into practical understanding.
    3. Link to the closest evaluation page. Send the reader to a use-case comparison, alternatives page, product capability, or selection checklist rather than an unrelated homepage.
    4. Write a contextual call to action. Explain why the destination is useful at that moment. “Compare the options for construction teams” carries more meaning than “Learn more.”
    5. Place the handoff where the need appears. A relevant next step can sit beside the section that creates it. It does not have to wait until the final paragraph.
    6. Preserve the informational answer. The page should still solve the question that earned the visit. Turning every paragraph into a pitch will weaken trust and usefulness.

    This creates a simple content path: education establishes the problem, mid-funnel material frames the available approaches, and bottom-funnel material supports the choice. Internal links should reflect that progression in both directions. The comparison page can link back to definitions or methods a reader needs, while educational pages can point forward when the reader is ready.

    Specificity is the filter. If a top-funnel page merely repeats a general answer already available everywhere, adding a product button will not rescue it. Give the page a distinct expert perspective, a concrete example, a useful framework, or original product evidence before asking it to support a commercial journey.

    Measure the influence that last-click analytics misses

    A glowing thread connects an AI referral to several visits and a final purchase, while a narrow lens highlights only the last step and a wider lens reveals the full journey.

    An AI-assisted journey can cross several channels. A buyer sees your brand or page in an AI answer, does not click, returns through a branded search, and converts. Another buyer clicks an AI citation, leaves, and later returns directly. Standard acquisition reports may credit those outcomes to organic brand traffic or direct traffic even though AI visibility helped create the demand.

    Start by isolating the AI referrals you can see. In GA4, create a segment or channel definition that matches the AI referral domains actually present in your data. A regular-expression rule is useful because it can group multiple sources, but maintain the domain list instead of treating it as permanent. Validate the rule against raw source values so an overly broad match does not pull unrelated referrals into the channel.

    Break that segment down by landing page and intent. Mixing an educational visit with a product-comparison visit hides the question you need answered. Compare like with like: AI-referred visits to bottom-funnel pages against other visits to those same pages, using the same conversion definition.

    Your scorecard should combine directly observed traffic with directional indicators of influence:

    SignalWhat it can tell youHow to act on it
    AI referral sessions by landing pageWhich pages receive visible visits from AI platformsProtect, update, and expand pages attracting relevant evaluators
    Conversion rate by landing-page intentWhether decision-stage visits produce more commercial action than informational visitsAllocate effort according to qualified outcomes, not aggregate sessions
    Engagement and product-page progressionWhether visitors continue evaluating after arrivalImprove the page’s decision support or contextual handoff where progression stalls
    LLM citation frequency for a stable prompt setWhether your brand or page appears in relevant answers, even without a clickReview the cited passages and close factual or use-case gaps
    Branded search and direct-traffic trendsWhether discovery may be resurfacing through channels that obscure the first touchTreat the movement as directional evidence and examine it beside publication activity
    Qualified leads, purchases, and pipelineWhether the program contributes to business outcomesFavor pages and topics that produce valuable customers rather than raw volume

    None of the directional signals proves causation on its own. Direct traffic can move for many reasons, and a branded search increase can reflect activity outside content. Use publication and update dates as annotations, compare several signals together, and avoid assigning all subsequent growth to one page.

    Lead capture can close part of the gap. Preserve the original landing page and referral source where available, then pair them with a simple self-reported discovery field. A buyer who says an AI assistant introduced the brand gives you information that a last-click field may have lost. Keep self-reported and system-attributed sources separate so one does not overwrite the other.

    Report the channel in business language. Instead of stopping at “AI referrals increased,” show which decision-stage pages received those visits, how the visitors behaved, how many qualified conversions followed, and whether brand discovery moved in the same period. Stable or lower total traffic can still support a healthier strategy if conversion quality and pipeline improve.

    Your next move is small and concrete: choose one purchase-stage question that repeatedly blocks a decision. Build the most complete, candid answer you can support. Connect your strongest relevant educational pages to it, establish the measurement baseline, and watch referrals, citations, branded discovery, and qualified conversions together. Once that loop produces a useful signal, repeat it for the next decision your buyers need help making.

    References


  • AI-Era Advertising: How to Prove and Scale Real Growth

    AI-Era Advertising: How to Prove and Scale Real Growth

    Your dashboard says advertising is working. ROAS is up, automated campaigns are claiming conversions, and conversational AI is opening new inventory. But the decision in front of you is harder: which spending actually created revenue that would not have happened otherwise?

    You can answer that question without waiting for perfect attribution. Separate platform-reported performance from incremental lift, measure the return on the next dollar rather than the average dollar, and treat new AI placements as controlled learning investments. That gives you a practical basis for scaling, holding, or cutting spend.

    A high ROAS can still describe demand capture

    Platform ROAS answers a narrow question: how much revenue did the platform attribute to ads relative to their cost? It does not tell you how many of those purchases required the ads.

    That distinction becomes important when automated systems can concentrate spending around branded searches, repeat visitors, existing customers, and people already close to buying. The platform may be accurately recording its involvement while claiming revenue that would have arrived through direct, organic, or another channel. The number is useful for optimizing activity inside the platform, but it is not causal proof of growth.

    Before you increase a campaign budget, ask three separate questions:

    • Did the platform influence conversions? Platform attribution, CPA, and ROAS can help answer this.
    • Did advertising cause additional conversions? A controlled incrementality test is needed to estimate this.
    • Will the next block of spending remain profitable? Marginal return and contribution economics answer this better than average ROAS.

    Use the right calculation for each decision

    • Attributed ROAS equals platform-attributed revenue divided by ad spend. Use it to compare campaigns under the same attribution rules and improve execution within a platform.
    • Incremental revenue is the difference between the outcome for an exposed group and the estimated outcome for a comparable unexposed group, after accounting for relevant baseline differences.
    • Incremental ROAS equals incremental revenue divided by the advertising cost required to produce that lift. Use it to decide whether the campaign adds enough business value to keep funding.
    • Marginal ROAS equals the change in incremental revenue divided by the change in spend. Use it to decide whether an additional budget block is worth buying.

    The average and marginal numbers can point in opposite directions. A campaign that produces $50,000 from its first $10,000 has a 500% average ROAS. If another $5,000 produces only $5,000 more revenue, the combined average still looks respectable at roughly 366%, but the marginal ROAS on the added spend is only 100%.

    Do not call that final dollar break-even merely because one dollar of spend returned one dollar of revenue. Product costs, fulfillment, payment fees, returns, sales commissions, and other variable costs can make a 100% revenue ROAS unprofitable. Convert incremental revenue into incremental contribution before approving more budget. If margins differ by product or customer segment, calculate contribution at that level instead of applying one blended percentage to everything.

    Build a measurement ladder instead of one master metric

    Two analysts inspect a five-level staircase containing signal lights, matched customer groups, test vessels, and a prism illuminating a new group.

    No single metric can optimize campaigns, prove causality, and allocate the next dollar. A measurement ladder gives each metric a specific job and prevents a familiar dashboard number from being stretched beyond what it can establish.

    DecisionPrimary evidenceWhat that evidence cannot prove alone
    Which bid, audience, or creative should run?Platform conversions, CPA, and attributed ROASWhether the advertising caused the conversion
    Should the campaign keep receiving money?Incremental lift, incremental ROAS, and contributionWhether a larger budget will perform at the same rate
    Where should the next budget block go?Marginal incremental revenue or contributionHow performance will change after a major market or product shift
    Is the brand gaining visibility in AI answers?Paid exposure and unpaid AI mentions measured separatelyThat either form of visibility caused profitable demand

    Run an incrementality test that matches the business question

    You do not need a perfect measurement laboratory. You do need a credible counterfactual: an estimate of what would have happened without the advertising.

    1. Choose one business outcome before launch. Use completed revenue, gross contribution, qualified pipeline, new customers, or another outcome tied to the decision. Do not replace it mid-test with whichever platform metric looks strongest.
    2. Choose a control design. Comparable geographic markets, randomized audience holdouts, platform lift tests, audience exclusions, and controlled spend reductions can all create evidence beyond ordinary attribution. Geo splits and audience holdouts are especially useful when user-level journeys cannot be observed cleanly.
    3. Protect the contrast. Record which campaigns, markets, audiences, promotions, and prices differ between treatment and control. A large promotion in only one group can look like advertising lift even when the ad had little effect.
    4. Record the exposure rules. Preserve campaign settings, eligibility, placement types, creative versions, market coverage, and any platform product changes. This matters more in AI inventory, where formats and reporting can change while the channel is still maturing.
    5. Let the test cover the decision cycle. A test that ends before delayed purchases or qualified leads can mature will favor channels with short feedback loops. Set the observation window from the actual buying process, not from a convenient reporting date.
    6. Report uncertainty with the result. A positive point estimate from a small or volatile control group is not automatically a scalable win. If the result is too noisy to distinguish lift from normal variation, enlarge the test unit, repeat it, or classify the conclusion as unresolved.

    Maintain a test ledger with the hypothesis, primary outcome, treatment and control definitions, launch and end conditions, known confounders, result range, and budget decision. That record stops teams from remembering only successful tests and makes later retesting much faster.

    Treat conversational AI ads as a learning budget

    A researcher directs a measured stream of budget tokens into three transparent chambers testing abstract conversational ad experiences with anonymous audiences.

    Conversational advertising should not inherit the assumptions of search, social, or display. OpenAI began rolling out ads to Free and Go users in Australia, New Zealand, and Canada while keeping Pro, Business, Enterprise, and Education plans ad-free. Results from that inventory therefore should not be generalized to every ChatGPT user, market, or subscription tier.

    The early buying environment also carries unusually high measurement risk. Initial advertiser accounts described impression-led campaigns, limited reporting, high CPMs, and starting commitments in the six-figure range. Those accounts are preliminary, not a dependable benchmark for what every advertiser will pay or achieve. They are still enough reason to demand a sharper test plan before committing a material budget.

    Write the pilot brief before negotiating inventory

    • State the user moment. Name the conversational situation you expect to influence, such as category comparison, product research, retailer selection, or troubleshooting. A generic awareness objective is too broad to diagnose.
    • Define an exposure. Establish whether the platform reports a served impression, visible placement, interaction, click, conversation, or another unit. Do not compare CPMs until you know what the impression represents.
    • Name one primary outcome. Choose incremental qualified visits, incremental orders, incremental contribution, or qualified pipeline. Treat impressions and clicks as diagnostic signals rather than proof of growth.
    • Set the economic boundary in advance. Calculate the maximum acceptable acquisition cost or minimum contribution return from your own unit economics. If the required commitment would displace a proven campaign or consume the budget needed for a valid control, wait.
    • Specify the control. Use an unexposed geography, audience, eligible period, or other comparable unit where the placement will not run. If the seller cannot support or tolerate a credible comparison, classify the investment as exploratory rather than performance-proven.
    • Preserve evidence. Export the available delivery, market, tier, placement, creative, billing, and outcome data. Note reporting-definition changes so a product update is not mistaken for a performance change.
    • Set a stop rule. Decide what level of economic loss, reporting failure, brand-safety concern, or control contamination ends the test. The novelty of the format is not a reason to ignore an invalid experiment.

    Keep paid presence separate from earned AI visibility

    A sponsored brand appearing near a recommendation is not the same as a model selecting, citing, or mentioning that brand without payment. Early placements may influence the journey indirectly by making a sponsored retailer more prominent among recommendations, even when the underlying answer is presented as independent from the ad.

    Measure three lanes separately:

    • Paid AI delivery: eligible exposure, served placements, interactions, clicks, cost, and available conversion signals.
    • Earned AI visibility: unaided brand mentions, citations, recommendation presence, and factual accuracy across a fixed set of representative prompts.
    • Business effect: incremental visits, qualified leads, new customers, revenue, and contribution against a control or credible baseline.

    This separation protects your AEO and GEO work from a false success signal. Paid exposure can increase while unpaid recommendation visibility falls, or an AI system can mention the brand more often without creating profitable demand. Neither outcome should be credited to the other without a test.

    Move budget according to marginal contribution

    The AI shift does not make established channels irrelevant. IAB/PwC figures put U.S. search advertising revenue at $114.2 billion in 2025 within a $294.6 billion digital advertising market. Digital video reached $78 billion after 25.4% growth, while social reached $117.7 billion after 32.6% growth. The ten largest companies controlled 84.1% of the market.

    Those market totals describe where money went, not where your next dollar belongs. A rapidly growing channel can be unprofitable for your offer, while a slower-growing channel can still produce strong incremental contribution. Concentration also means the same large platforms often control inventory, optimization, and attribution. Use their reporting to manage campaigns, but require independent business outcomes or controlled lift before treating claimed conversions as proof.

    Use a repeatable capital-allocation cycle

    1. Rank current channels by marginal contribution. Use the most recent credible spend change or controlled test, not lifetime average ROAS.
    2. Choose the next observable budget block. It should be large enough to create a measurable change but small enough that a weak result does not materially damage the plan.
    3. Estimate the expected range. Record a low, central, and high outcome using evidence from your tests and unit economics. Do not convert an uncertain pilot into a single precise forecast.
    4. Move one block from the weakest expected marginal use to the strongest. Keep major promotions, pricing changes, and other confounders visible so they do not receive advertising credit.
    5. Remeasure after the change. Marginal returns usually change with spend. A channel that deserved the previous increase does not automatically deserve the next one.

    It also helps to classify spending by purpose. Core campaigns have repeatable causal and economic evidence. Experimental campaigns buy information about new inventory, audiences, or creative. Verification spending retests old assumptions after platform, product, or market changes. A brand-defense campaign may remain strategically valuable despite low measured incrementality, but label it as protection rather than presenting it as growth. That makes the trade-off explicit.

    Key takeaways

    • Platform ROAS measures attributed performance; it does not establish how much revenue advertising caused.
    • Incrementality tells you whether a campaign created an outcome that would not otherwise have occurred.
    • Marginal contribution, not blended ROAS, should determine whether the next budget increase is economically sound.
    • Conversational AI ads need a defined exposure unit, control, business outcome, economic limit, and stop rule before a substantial commitment.
    • Paid AI placements, earned AI visibility, and business impact belong in separate measurement lanes.
    • Market growth identifies where advertisers are moving, but your own causal evidence and unit economics should determine where you move.

    For your next budget review, replace the single ROAS column with six fields: attributed return, incremental lift, incremental contribution, marginal return, confidence level, and next test. Mark an untested channel as unproven rather than successful or failed. Then fund the next measurable budget block where the expected marginal contribution is strongest. AI formats will keep changing; that decision discipline will remain useful even when the placements do not.

    References


  • Google Analytics and Ads Consent Requirements: Audit Guide

    Google Analytics and Ads Consent Requirements: Audit Guide

    Your consent banner can look correct while your tags tell Google something else. That mismatch now carries more weight because Google Ads determines access to advertising identifiers from the ad_storage consent setting, rather than from a combination of Consent Mode and settings buried in Google Analytics.

    You need to verify the complete path from the choice a person makes to the value Google Ads receives. A polished banner, an installed consent management platform, or a linked Analytics property proves very little on its own. This guide shows you what changed, which settings still have separate jobs, and how to audit the implementation without confusing a reporting problem with a consent problem.

    The rule that now controls Google Ads data collection

    From June 15, Google Ads data collection relies exclusively on ad_storage for its advertising-consent decision. The practical rule is direct: if ad_storage is granted, Google Ads can use the available advertising signals; if it is denied, Ads is limited to less persistent signals.

    User’s advertising choiceRequired ad_storage stateExpected Google Ads behaviorWhat your audit must prove
    Advertising use allowedGrantedAds can use available advertising signals, including linking activity to a signed-in Google account when feasible.The grant is sent only after the relevant choice and is received by every applicable Ads tag path.
    Advertising use deniedDeniedAds is restricted to less persistent signals, which can include URL parameters such as gclid.The denied state reaches the tags promptly, persists as intended, and is not overwritten by another configuration.

    A denial does not necessarily mean that every observable advertising signal disappears. The possible continued use of a less persistent parameter such as gclid is part of the restricted behavior. Do not treat the presence of gclid as proof that ad_storage was granted, and do not treat continued conversion reporting as proof that the banner failed.

    The reverse matters too. Granting ad_storage does not establish that your consent experience is legally valid. Consent Mode implements a decision; it does not determine what your organization must ask, how the request must be worded, or which visitors must see it. Have qualified privacy or legal counsel set those requirements, then use the technical audit to prove that the implementation follows them.

    Key takeaways

    • ad_storage is the controlling consent input for Google Ads advertising identifiers under the revised framework.
    • Google Signals still has a role in Google Analytics, but it no longer acts as an additional gate for Google Ads data collection.
    • A linked Google Analytics tag cannot override or narrow the advertising permission conveyed through ad_storage.
    • Denied ad_storage means restricted signal use, not necessarily the disappearance of every parameter or every measured conversion.
    • Your audit must inspect the value received by the tags on initial load, after each choice, after a changed choice, and on a later visit.

    Keep Google Signals, ad_storage, and the banner separate

    Three separate connected modules depict a privacy control panel, an audience analytics node, and an advertising-data gateway.

    The most common conceptual mistake is treating every Google privacy control as a different name for the same switch. There are three distinct layers in your implementation:

    • The consent interface is where a person accepts, rejects, or customizes purposes.
    • Consent Mode carries the resulting state to Google tags, including the ad_storage value used by Google Ads.
    • Product settings such as Google Signals control behavior within their own platform context.

    Previously, the flow of advertising data between Analytics and Ads could depend on both Consent Mode and Google Signals. That created an easy trap: a team could look at Google Signals inside Analytics and assume it was limiting what the linked Ads account could use.

    That assumption no longer holds. Google Analytics continues to use Google Signals for its own data collection, while Google Ads looks to ad_storage as its single source of advertising consent. A linked Google Analytics tag no longer determines whether Ads can collect or use advertising identifiers.

    Google Signals is no longer an Ads safety catch

    If your organization disabled Google Signals and assumed that decision also constrained Ads-linked data, revisit the implementation. When a visitor grants ad_storage, Google Ads may use all advertising signals available to it, including signed-in account linkage where feasible. The disabled Analytics setting should not be treated as a second denial.

    This is especially important when the people who own Analytics settings are different from those who own the consent platform or Ads tags. Document which team controls the banner wording, which team maps choices to ad_storage, and which team can change tag behavior. Otherwise, each team can believe another setting is providing a restriction that no longer exists.

    The visible choice is not proof of the transmitted state

    A person can click “Reject” while ad_storage remains granted because an update did not fire, fired too late, or was overwritten. The opposite can also happen: the person allows advertising, but a missing update leaves ad_storage denied and creates avoidable gaps in attribution and audience data.

    Judge the implementation by the state the tags actually receive. Banner screenshots are useful evidence of the interface, but they do not establish tag behavior. Your test record should connect the exact action, the resulting ad_storage value, the time the value changed, and the tag paths that consumed it.

    Audit the complete consent path, not just the banner

    A visitor's privacy choice travels through a consent manager, tag system, and storage checkpoint while magnifying glasses inspect each handoff before the signal reaches separate analytics and advertising destinations.

    Run the audit as a controlled set of user journeys. Do it in a test environment where possible, then repeat the critical paths in production without changing real consent choices or campaign settings. If your implementation varies by region, domain, device class, or authenticated state, each distinct path needs its own evidence.

    1. Inventory every control point. Record the consent management platform, banner configuration, tag manager containers, direct page tags, server-side delivery paths if used, linked Analytics and Ads properties, and the current Google Signals setting. The aim is to find every place that can set, delay, transform, or overwrite consent.
    2. Write the expected mapping before you test. For each banner choice, state the required ad_storage result. At minimum, define the advertising-allowed and advertising-denied outcomes. If your banner offers custom choices, document which exact purpose controls ad_storage rather than relying on a broad label such as “analytics” or “cookies.” Have the privacy owner approve this mapping.
    3. Inspect the initial page state. Check the ad_storage value available before the visitor interacts with the banner. The expected default depends on your approved consent policy and the context in which the banner appears; do not invent that policy during the technical test. Confirm only that the implementation matches the approved rule before Ads tags act on it.
    4. Run four core journeys. Test accepting all relevant purposes, denying advertising, allowing analytics while denying advertising if that combination is offered, and changing a previously saved choice. For each journey, record what the visitor clicked and the ad_storage state observed by the tags.
    5. Verify update timing and persistence. Confirm that the Consent Mode update call fires when the choice changes, that it carries the correct value, and that later scripts do not reverse it. Reload the page and start a later visit to check whether the saved choice is restored at the correct point in the tag sequence.
    6. Repeat the test across every tag-delivery path. A page tag can receive the correct state while a second container, embedded checkout, subdomain, or server-side path uses stale logic. Test the paths that actually send Analytics and Ads data rather than assuming a shared banner guarantees shared behavior.
    7. Create release evidence. Save the test date, environment, banner version, tag configuration version, journey, expected state, observed state, and result. Assign an owner and require a regression test after changes to the consent platform, tag manager, site templates, Analytics linking, or advertising setup.

    Pay particular attention to delayed or missing update calls. The revised framework is simpler because Ads has one consent input, but that also makes an incorrect ad_storage value decisive. A hidden Analytics setting is no longer available to compensate for a bad mapping.

    Use the denied path as your first diagnostic

    Start with a clean session and deny advertising. This path quickly exposes optimistic defaults, missing updates, stale saved choices, and scripts that overwrite the decision. Then change the choice to allowed and verify the new state without waiting for a new page. Finally, reverse it again. A system that works only after a reload is not faithfully handling an in-session change.

    If the banner offers a granular option that permits Analytics but rejects advertising, test it separately. It is the clearest way to find category mapping that incorrectly treats all measurement and advertising as one generic consent purpose. The names visible to a visitor may differ from Google’s setting names, so the approved mapping document is the bridge between policy language and tag configuration.

    Read measurement changes without weakening consent

    Consent affects measurement, attribution, and audience targeting, so a configuration change can produce a noticeable reporting change. That does not tell you whether the new result is correct. Lower numbers can reflect valid advertising denials, a broken update call, a changed default, or the removal of an old Google Signals-based restriction. You need implementation evidence before choosing a remedy.

    • If measured activity falls, compare the tested ad_storage states with the approved mapping before editing campaigns or the banner.
    • If attribution changes, remember that denied ad_storage can still leave less persistent signals such as gclid available. Parameter presence alone does not establish advertising consent.
    • If audience sizes change, confirm that consent updates fire correctly before changing targeting rules or pressuring visitors toward acceptance.
    • If Google Signals is disabled, do not assume Ads is also restricted. Test what happens when ad_storage is granted under the new separation of controls.
    • If results differ by page or region, inspect consent timing and tag delivery in each affected path rather than averaging the discrepancy away in a dashboard.

    Do not change banner wording, defaults, or rejection behavior merely to recover reported conversions. That can misrepresent the person’s choice and create legal exposure. The safe sequence is to have the privacy owner define the permitted experience, have engineering map it to ad_storage, and have analytics specialists explain the resulting measurement limits.

    A useful internal control can fit on one page: list each visitor choice, its expected ad_storage value, the owner who approved the mapping, the systems that receive it, the date of the last successful test, and a link to the evidence. Begin with the advertising-denied journey. Once that path is correct on initial load, after an update, and on a return visit, move through the remaining journeys and make the test part of every consent or tag release.

    References


  • Google Data Studio Is Returning: What Marketers Should Do

    Google Data Studio Is Returning: What Marketers Should Do

    If you have a library of Looker Studio dashboards, the return of the Data Studio name raises three practical questions: Will your reports survive, should you rebuild anything, and which Google analytics product should your team use next?

    The immediate answer is reassuring: do not launch a manual migration project just because the name is changing. Existing reports, data sources, and other assets are expected to transfer automatically. Your useful work now is to classify what you have, confirm who owns it, and decide which assets belong in Data Studio, Data Studio Pro, or Looker.

    What the Data Studio revival actually changes

    Three years after Data Studio was folded into Google’s broader analytics offering and renamed Looker Studio, Google is separating the products again. This is more than a familiar label returning. The revived Data Studio is intended to become a central place for analysis assets across Google’s ecosystem.

    That asset model reaches beyond conventional reports and dashboards. It is also expected to encompass more advanced data applications created in Colab and conversational agents associated with BigQuery. For a marketing team, the practical benefit is a shorter path between finding an asset, exploring the underlying data, and acting on the result.

    Looker is not disappearing. It remains Google’s enterprise business intelligence platform for managed data, semantic modeling, and analytics at scale. Data Studio is being positioned for flexible exploration, ad hoc analysis, and accessible dashboards connected to services such as BigQuery, Google Sheets, and Ads.

    That distinction matters more than the brand change. A dashboard used by one marketer to investigate a campaign has different requirements from a company-wide revenue report whose metrics must mean the same thing in every department. The first is an exploration problem. The second is a data-governance problem.

    Some implementation details remain unsettled. Google plans to explain more about the relaunch and its wider analytics strategy at Google Cloud Next ’26. Treat the current direction as sufficient for planning, but not as a reason to assume that every interface, AI capability, or administrative option is already available.

    Choose the product by governance, not by dashboard size

    A central decision hub branches to self-service, managed team, and enterprise analytics workspaces with different access and governance controls.

    The cleanest routing rule is to ask how controlled the data must be. Do not choose solely by the number of charts, the sophistication of the design, or whether a report is viewed by an executive. A visually simple report can still require enterprise governance if it drives financial or operational decisions.

    ProductBest fitPrimary roleAccess model
    Data StudioIndividuals and small teamsQuick analysis, visualization, personal exploration, ad hoc reporting, and accessible dashboardsFree
    Data Studio ProLarger organizations that need stronger administrative controlsAccessible analysis with enhanced security, compliance, management controls, and AI featuresPaid licenses through Google Cloud and Workspace admin consoles
    LookerEnterprises managing shared definitions and analytics at scaleManaged data, semantic modeling, and enterprise business intelligenceSeparate enterprise platform

    Use free Data Studio when the work is exploratory and a person or small team can responsibly manage the report. Consider Data Studio Pro when access policies, compliance requirements, centralized administration, or organizational controls are part of the requirement. Keep Looker in the architecture when metrics need a governed semantic layer or the analysis operates at enterprise scale.

    Do not purchase Pro merely because its feature list includes AI. First identify the administrative or analytical problem you expect it to solve. Then wait for concrete product details and check whether the announced capability satisfies that requirement. Buying an edition before defining the requirement reverses the decision process.

    Audit your current reports without rebuilding them

    An analyst audits intact report cards by tracing them to owner, data source, access, and usage symbols in an organized workspace.

    An automatic transition removes much of the migration burden, but it does not repair an untended reporting estate. Orphaned dashboards, unclear metric definitions, obsolete campaign views, and credentials tied to former employees remain operational problems regardless of the product name.

    Run a lightweight audit before the transition:

    1. Create an inventory of business-critical reports. Record each report’s name, URL, owner, intended audience, connected data sources, expected refresh pattern, and the decision it supports.
    2. Classify each asset as personal exploration, team reporting, or governed enterprise reporting. If nobody can identify a decision the asset supports, mark it for review rather than automatically carrying it into your active reporting catalog.
    3. Assign a likely product lane. Personal and ad hoc analysis points toward Data Studio; reporting that requires enhanced organizational controls may point toward Data Studio Pro; shared metrics backed by managed models belong in Looker.
    4. Verify ownership and access. Automatic asset transfer does not make an absent owner accountable, document a metric, or restore a broken data-source authorization.
    5. Capture a baseline for critical outputs. Save the expected totals, date range, filters, and metric definitions you will use to check the report after the transition. Store any exported data according to your organization’s security rules.
    6. Pause rename-driven rebuilds. Continue fixing defects that affect decisions, but do not recreate a functioning report solely to anticipate the new branding when reports and data sources are supposed to carry over.

    After the transition, verify the reports that matter most instead of opening every dashboard at random. Check data-source authorization, refresh behavior, filters, calculated fields, sharing, and the baseline totals you recorded. That gives you a controlled acceptance test rather than a vague visual inspection.

    Build a reporting model that can survive the next rename

    Product names will change again. Your definitions, ownership, and decision process should not have to change with them. The durable approach is to separate the data, its agreed meaning, and its presentation.

    Keep metric meaning outside the dashboard

    A chart can display conversions, qualified leads, organic traffic, or AI-referred sessions without establishing what any of those terms mean. Record the definition, source, exclusions, time zone, and accountable owner separately. When a metric requires an enterprise-wide definition, manage that logic in the governed data or semantic layer rather than reproducing slightly different formulas across dashboards.

    Give every important report a decision contract

    For each recurring report, write down five things: who uses it, what question it answers, how fresh the data must be, who resolves discrepancies, and what action follows a meaningful change. A dashboard with no defined response is usually a display, not an operating tool.

    This contract also helps you select the right platform. A report used to investigate an unusual traffic pattern may need flexibility. A report used to approve budgets may need controlled definitions, permissions, and change management. The business consequence determines the governance level.

    Treat conversational AI as an interface, not a source of truth

    The expanded hub is expected to include advanced data applications and BigQuery conversational agents, while Data Studio Pro is expected to add AI features. These interfaces may reduce the effort required to ask questions of data, but they do not resolve ambiguous definitions. A fluent answer built on the wrong conversion definition is still the wrong answer.

    Before relying on an AI-generated analysis, check the data source, date range, filters, grouping, and metric definition. For consequential decisions, compare the answer with a governed report or a direct query against the approved data. Speed is useful only when the result remains traceable.

    Key takeaways

    • Do not manually migrate or rebuild reports merely because Data Studio is returning; existing assets are expected to transfer automatically.
    • Use Data Studio for free, flexible analysis by individuals and small teams.
    • Evaluate Data Studio Pro when security, compliance, centralized management, or its announced AI features address a defined organizational requirement.
    • Keep Looker where managed data, shared semantic definitions, and enterprise-scale analytics are essential.
    • Inventory critical dashboards now, assign accountable owners, document metric definitions, and record baseline outputs for post-transition checks.
    • Wait for the fuller Google Cloud Next ’26 details before making purchases or architecture changes that depend on a particular unconfirmed feature.

    Your next step is small: identify the reports that people actually use to make decisions, classify each by governance need, and document their owners and definitions. That work will improve your reporting whether the interface says Looker Studio, Data Studio, or something else later.

    References


  • How to Audit Google Ads Data and Cut Spend Waste Safely

    How to Audit Google Ads Data and Cut Spend Waste Safely

    Your Google Ads account can report a better return while the underlying business gets less efficient. That happens when conversions are duplicated, low-value actions are treated as primary goals, delayed sales are missing, or automated bidding receives values that do not match real revenue.

    So do not begin an efficiency audit by lowering bids. Use this order: validate the conversion signal, classify waste, protect proven demand, choose automation that fits the available data, and then check whether product data is steering Shopping spend correctly.

    Treat conversion tracking as a bidding input, not a reporting detail

    A signal-validation machine removes duplicate and low-value conversion events before verified signals reach an automated bidding mechanism.

    Automated bidding does not know which outcomes matter to your business. It knows which conversion actions and values you send. If a page view, unqualified lead, duplicate purchase, or inflated order value is marked as a primary outcome, the system can optimize successfully toward the wrong result.

    Start by writing a plain-language definition for every primary conversion. A purchase conversion should represent a completed order, not a checkout visit. A qualified-lead conversion should represent the stage named in its label, not every form submission. If revenue arrives after the initial lead, keep the early event for diagnosis but base your main performance decision on the deepest reliably measured outcome available.

    • Confirm the event: Identify exactly what user or business action causes the conversion to fire.
    • Confirm the count: Check whether one business outcome can create multiple ad conversions. Repeat purchases may be valid; repeated firing for one order is not.
    • Confirm the value: Reconcile conversion values and currency with the system that records actual orders, revenue, or accepted leads.
    • Confirm the role: Separate primary actions used for bidding from secondary observations used for diagnosis.
    • Confirm the delay: Compare results only after the normal lag between an ad interaction and the recorded business outcome has had time to mature.

    Google’s consolidated enhanced-conversions system makes matching easier, but it does not replace this validation. Under the June 2026 consolidation, user-provided data can arrive through website tags, Data Manager, and API connections at the same time. You no longer have to choose a single implementation method for enhanced conversions for web or leads.

    That broader intake can recover conversions that would otherwise be harder to match. It cannot correct an event that fires twice, turn an unqualified lead into revenue, or repair an incorrect order value. Think of enhanced conversions as a matching layer around a conversion definition that must already be sound.

    A practical validation sequence

    1. Choose one high-spend campaign and list the primary conversion actions affecting its bidding.
    2. Trigger each action through a controlled test and verify that the expected event arrives once with the correct label and value.
    3. Reconcile a complete period of platform conversions against the corresponding records in your order, CRM, or lead-management system.
    4. Investigate missing outcomes, duplicate outcomes, unexplained value differences, and changes in the normal reporting delay.
    5. Resolve the discrepancy before changing a bid target or using the platform’s reported return to move budget.

    Existing enhanced-conversions users generally do not need to enable the consolidated feature again if the required customer-data terms have already been accepted. New setups can enable it under Goals, then Settings, under Customer data use; it can also be controlled for individual conversion actions.

    User-provided data still creates privacy and compliance obligations, even when it is hashed or transmitted through an approved integration. Do not enable another input merely because the switch is available. Confirm the applicable customer-data and data-processing terms, your consent or other lawful basis, your privacy disclosures, and the fields your implementation is permitted to send. Involve your privacy or legal owner if that authority is unclear.

    Separate obvious waste from performance that needs more evidence

    A zero-conversion row is not automatically waste. It may be new, low volume, affected by reporting delay, or part of a longer path to purchase. Cutting every row at zero conversions selects against campaigns before they have had a fair opportunity to produce an outcome.

    A better audit divides questionable spend into three classes:

    • Structural waste: The traffic cannot produce the intended outcome. Examples include an irrelevant search term, an unavailable product, or a destination that does not support the advertised action. Act as soon as you verify the mismatch; waiting for more conversions will not make the traffic relevant.
    • Performance waste: The traffic could convert, but it has accumulated enough impressions, clicks, spend, and mature outcomes to miss the account’s CPA or ROAS requirement. This class needs sufficient data before you pause or constrain it.
    • Measurement uncertainty: Spend looks weak because conversions, values, or delays cannot be trusted. Repair measurement before making a budget decision unless the traffic is also structurally irrelevant.

    A useful working hypothesis is that 20% to 30% of spend may underperform in an audited account. That is an audit prompt, not a universal benchmark and certainly not a quota to cut. If your analysis identifies only 8% of defensible waste, removing 20% would damage productive activity. If it identifies more, preserving the budget because it fits the plan would be equally hard to justify.

    Build your review at the lowest level where you can take a meaningful action. Search-term data can reveal irrelevant queries hidden by campaign averages. Product-level data can reveal items consuming spend while generating no conversions or falling well below the required return. Campaign totals alone can allow a few strong components to conceal a long tail of loss.

    1. Choose an evaluation period that includes the normal conversion lag and enough activity to judge the unit fairly.
    2. Review search terms, products, and other actionable segments using impressions, clicks, spend, conversions, conversion value, CPA, and ROAS.
    3. Mark definite mismatches separately from low-performing but plausible traffic.
    4. For each performance outlier, inspect the query, product availability, feed information, landing-page path, conversion signal, and offer before assigning the cause to bidding.
    5. Apply the narrowest corrective action: add an exclusion for irrelevant demand, repair the destination or feed, constrain a proven outlier, or pause a segment whose economics no longer work.
    6. Record what changed, the reason, the decision period, and the metric that will determine whether the intervention worked.

    Use CPA and ROAS for different questions. CPA is cost divided by conversions and works only when the counted outcomes are sufficiently comparable. ROAS is conversion value divided by cost and works only when the values are complete and economically meaningful. A strong reported ROAS can still be unattractive if revenue values omit cancellations, returns, fulfillment costs, or other business constraints, so reconcile the platform result with the financial view used to run the business.

    Reallocate budget instead of cutting every campaign evenly

    An across-the-board reduction feels neutral, but it removes money from proven demand and waste at the same rate. That can preserve the account’s weakest activity while forcing high-intent campaigns to stop serving earlier.

    Protect lower-funnel activity that has trustworthy measurement, sufficient volume, and a return that meets the business requirement. Move money away from confirmed structural waste first, then from mature performance outliers. Keep uncertain activity in a clearly bounded diagnosis or testing budget so it cannot consume funds without an explicit decision date.

    • Protected budget: Proven, high-intent activity meeting its business target with reliable tracking.
    • Repair budget: Valuable demand whose feed, landing page, creative, or measurement problem has a credible fix.
    • Test budget: New queries, products, audiences, or creative variations with a stated hypothesis and success criterion.
    • Exit budget: Irrelevant demand and mature segments that remain outside acceptable economics after measurement problems are ruled out.

    Do not let platform ROAS become the only judge. Compare it with actual revenue or qualified outcomes from the business system and with the combined effect of your channels. That blended view matters because lower-funnel campaigns can capture demand created elsewhere, while upper-funnel activity may look weak when judged only by the final recorded click. The answer is not to protect every awareness campaign; it is to give each stage a measurement question appropriate to its job.

    Ask two separate questions during every reallocation. First, should this activity exist at all? Second, how much budget has it earned? Combining those questions creates bad choices: a useful campaign may receive too much money simply because it belongs in the plan, while an irrelevant segment may survive because its budget is small.

    Match bidding and creative decisions to the signal you actually have

    A bid strategy cannot compensate for a weak objective. Select it only after you know which conversion signal is reliable and what the business is trying to control.

    • Maximize Clicks: Use it when acquiring traffic is genuinely the immediate goal or when a dependable conversion signal is not yet available. Do not evaluate it as though it were instructed to maximize sales.
    • Target CPA: Use it when the primary conversions are reasonably comparable in value and the account can supply trustworthy conversion data. A lead target is useful only if the counted leads correspond to the quality level the business can afford.
    • Target ROAS: Use it when conversion values vary and those values accurately represent the outcomes you want the system to favor. Bad values turn a revenue-aware strategy into an amplifier of accounting errors.

    Automation needs boundaries as well as data. Keep exclusions current, prevent invalid products and irrelevant queries from competing for budget, and avoid changing targets merely to make the interface report a preferred status. If a target conflicts with the economics of the business, the target is wrong even when the campaign reaches it.

    Creative is another control surface, not decoration. Automated campaigns need meaningful variations to learn which message, format, and offer fit different opportunities. Maintain a queue of distinct assets rather than superficial rewrites of the same claim. Review each variation after adequate exposure, retire clearly weak assets, and preserve the message differences so the next test answers a new question.

    Human review remains necessary because the platform can optimize the target it receives without knowing whether that target reflects margin, lead quality, inventory constraints, or business priorities. Use automation to process the signal; keep responsibility for defining and auditing the signal with your team.

    For Shopping campaigns, product data is spend control

    Generic products with organized visual attributes receive more advertising tokens than incomplete or mismatched product listings.

    Shopping efficiency begins before the auction. Titles, product identifiers, availability, inventory, promotions, and other feed attributes determine what can serve and how the system understands the offer. A bid adjustment is the wrong fix when the product data itself is incomplete, stale, or mapped incorrectly.

    Google set April 22, 2026 as the start of Merchant API support in Google Ads Scripts and August 18, 2026 as the retirement date for the Content API for Shopping. The Merchant API transition is therefore both a continuity requirement and an opportunity to improve how product-data problems are detected.

    The Merchant API uses modular sub-APIs and expands control over supplemental product data, local and regional inventory, promotions, product and store reviews, and notifications. Google Product Studio also introduces generative-AI capabilities. Treat those enhancements as optional improvements after the functional migration is correct; generated content does not compensate for missing inventory or a broken product mapping.

    1. Inventory every dependency: Find scripts, scheduled jobs, feed tools, supplemental inputs, inventory updates, promotions, reviews, and alerts that still rely on the Content API.
    2. Map each function: Identify the relevant Merchant API module and the credentials, permissions, fields, and error handling needed by that function.
    3. Enable the Advanced API: Update Google Ads Scripts that require Merchant API access and remove assumptions tied only to the legacy response structure.
    4. Validate in parallel: While both paths are available, compare product identifiers, item counts, availability, inventory, promotions, and reported errors rather than assuming a successful request means equivalent data.
    5. Test failure handling: Confirm that authentication errors, rejected products, delayed inventory updates, and other exceptions produce an alert that someone owns.
    6. Cut over deliberately: Retire the legacy dependency only after the new path has completed its scheduled runs and the resulting catalog state matches the expected business state.

    The Notifications API can make product issues visible sooner, but an alert has value only when it identifies the affected item, the severity, and the person or workflow responsible for the response. Route urgent availability or rejection problems differently from informational feed changes.

    Key takeaways

    • Reconcile primary conversion counts and values with the business system before changing bids or budgets.
    • Use enhanced conversions to improve matching, not to repair duplicate events, weak conversion definitions, or incorrect values.
    • Remove structural waste immediately, but require mature data before classifying plausible traffic as a performance failure.
    • Protect proven lower-funnel demand, isolate tests, and move budget from confirmed waste instead of cutting every campaign equally.
    • Choose Target CPA, Target ROAS, or Maximize Clicks according to the quality of the available signal and the outcome each strategy is actually designed to pursue.
    • For Shopping campaigns, complete and validate the Merchant API migration because feed integrity directly affects where spend can go.

    Open one high-spend campaign and reconcile its primary conversion count and value over a fully matured period. If the numbers match your business records, audit its search terms or products for structural and performance waste. If they do not match, fix the signal first. Every later optimization depends on that distinction.

    References


  • Transform Your Marketing Measurement from Basic to Brilliant

    Transform Your Marketing Measurement from Basic to Brilliant

    I’ve discovered that measurement is truly the cornerstone for all we achieve in performance marketing. Without precise measurement, everything I recommend, implement, and optimize becomes mere speculation. Today, maintaining accurate measurement is more challenging than ever—and it’s only getting more difficult.

    With regulatory crackdowns and growing privacy concerns, paired with elongated multi-touch journeys, we face a measurement crisis. Brands that still rely on outdated tactics are missing the mark when it comes to modern measurement challenges.

    If your brand falls into this category, it’s time I help you rebuild your measurement foundation—from integrating first-party data (crawl), to creating cross-channel reporting for actionable insights (walk), to advanced media mix modeling (MMM) and incrementality testing for true media lift (run).

    The crawl: Building a first-party data foundation

    By integrating first-party data into our performance marketing channels, I can move beyond reliance on third-party signals. While those metrics offer surface-level insights, they don’t reveal how channels impact our business goals.

    Audience integration

    The first step involves integrating CRM data into our paid media platforms. This includes:

    • Remarketing to abandoners.
    • Creating exclusion lists for current subscribers or recent purchasers.
    • Compiling priority contact lists.

    I might be uploading lists today, but integration enhances targeting by connecting to up-to-date audience lists for media platform targeting.

    Offline-conversion tracking

    For lead-gen businesses like ours, setting up offline conversion tracking (OCT) is crucial. It reveals the bottom-line impact of our media on sales, passing sales data back to platforms for campaign attribution.

    Once OCT is in place, we can optimize for lower-funnel, higher-quality conversion steps in the sales cycle or even begin optimizing toward revenue to enhance our return on ad spend.

    To progress from crawl to walk, I need to move from client-side to server-side tracking.

    By adopting server-side tracking, we bypass browser-based tracking and instead rely on our first-party data. This approach ensures data accuracy and resilience as privacy restrictions increase and cookies become obsolete.

    • Partner integration uses pre-built connectors for setup through platforms like Shopify or Google Tag Manager.
    • Direct API requires a development team to handle complex data or custom backends.

    The walk: Cross-channel reporting integration

    ```json
{
  "alt": "The CapmatchOne logo with a gradient circle and bold text.",
  "caption": "Discover innovation with the CapmatchOne logo, featuring sleek typography and a modern gradient circle.",
  "description": "The CapmatchOne logo features bold, modern typography coupled with a gradient circle, symbolizing connection and innovation. The sleek design conveys a sense of progress and creativity. This image can be used for branding or promotional purposes, appealing to audiences interested in innovative solutions and forward-thinking designs."
}
```

    With a robust measurement foundation, my next step is breaking down platform silos to understand the full ecosystem.

    Going beyond last click

    After implementing server-side tracking, I created a clean data pipeline. Yet, traditional attribution models neglect the full-funnel customer journey.

    To address this, I recommend using data warehousing solutions like BigQuery to centralize your data and apply custom logic, thereby gaining insights across the ecosystem.

    Unified reporting dashboards

    Integrating evolved attribution with unified reporting dashboards, like Looker Studio, allows me to visualize data across the funnel and obtain actionable insights into what platforms are truly driving volume and conversions.

    The run: Media mix modeling and incrementality testing

    With a comprehensive, everyday view of performance, significant questions persist about growth potential and offline performance measurement.

    By employing media mix modeling and incrementality testing, I can discern the full impact of media investments at a macro level to make informed decisions.

    The holistic view through MMM

    I view MMM as my compass, providing a holistic, quantitative guide for paid media investments, helping me analyze the relationship between inputs and business outcomes.

    Pulse checks with incrementality testing

    Incrementality testing offers validation for MMM and helps evaluate if specific tactics or channels are driving true incremental lift by comparing test and control groups.

    The sprint: Clean, integrated, and validated first-party data

    With first-party data integrated through server-side tracking and cross-channel reporting, I’ve built a robust measurement foundation. Guided by MMM and validated by incrementality testing, I’m now ready to sprint towards a more informed and successful marketing strategy.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Enhance Your Data Strategy with Server-Side Tagging Solutions

    Enhance Your Data Strategy with Server-Side Tagging Solutions

    I’ve been noticing the rapid transformation in how brands are tracking user behavior online. With privacy laws tightening and browser extensions increasingly blocking data, the demand for cleaner data from ad platforms is higher than ever. This change urged me to explore server-side tagging as a solution.

    By implementing server-side tagging, I’ve managed to reduce data loss while collecting cleaner, privacy-compliant data. This approach is invaluable, especially considering the experiences I’ve had with providers like Elevar and Littledata.

    So, what exactly is server-side tagging, and in which situations does it really shine? Let’s dive into the details!

    What is server-side tagging?

    Traditionally, tracking scripts ran directly in the browser. However, with server-side tagging, these scripts operate on a server I control, giving me more control over data processing.

    Here’s how it works: instead of sending data straight to multiple third parties from the browser, events are sent to a first-party server endpoint, often using a Google Tag Manager server-side container. The server then processes, enriches, and forwards this data to tools like Meta and Google Analytics.

    This setup provides benefits such as more data control, a cleaner page performance, and better compliance with privacy laws.

    Moreover, server-side tagging grants me the flexibility to enrich and transform data before it reaches ad platforms, standardizing event names, filtering out low-quality events, and adding custom parameters for better audience segmentation.

    Is server-side tagging right for you?

    While server-side tagging isn’t a one-size-fits-all solution, many brands find it essential, particularly if you:

    You need to meet strict privacy or compliance requirements

    Server-side setups allow for greater control over how data is processed and shared, supporting compliance with regulations like GDPR and CCPA.

    ```json
{
  "alt": "The CapmatchOne logo with a gradient circle and bold text.",
  "caption": "Discover innovation with the CapmatchOne logo, featuring sleek typography and a modern gradient circle.",
  "description": "The CapmatchOne logo features bold, modern typography coupled with a gradient circle, symbolizing connection and innovation. The sleek design conveys a sense of progress and creativity. This image can be used for branding or promotional purposes, appealing to audiences interested in innovative solutions and forward-thinking designs."
}
```

    You want faster website performance

    In my experience, client-side tracking can slow your page down, but server-side tagging shifts data processing to the server, resulting in faster websites.

    You want more accurate tracking (despite ad blockers)

    Ad blockers can hinder client-side scripts, but server-side tagging circumvents many of these restrictions, making your data collection more reliable.

    You’re investing heavily in paid media

    For those heavily invested in platforms like Meta and Google Ads, achieving better data accuracy can significantly impact return on ad spend.

    How to implement server-side tagging

    When it comes to implementing server-side tagging, you have two main options: building it internally or using a service provider.

    Option 1: Internal setup

    Choosing an internal setup gives me complete control but requires technical expertise and ongoing maintenance. This involves setting up a GTM server-side container and adding logic for data processing.

    Option 2: Use a server-side tagging service

    Platforms like Elevar and Littledata offer turnkey solutions that integrate seamlessly with existing tools, allowing me to focus on strategy rather than technicalities.

    Our direct experience: Littledata vs. Elevar

    In my experience with Littledata and Elevar, each caters to different needs. Littledata is ideal for emerging brands with simpler tech stacks, while Elevar is suitable for those outgrowing entry-level solutions.

    Investing in server-side tagging has transformed how I handle data, ensuring that I remain compliant with privacy laws while boosting site performance and data reliability across all my platforms.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • How to Align Ad Tools, Formats, and Conversion Tracking

    How to Align Ad Tools, Formats, and Conversion Tracking

    Your campaign can be configured correctly inside every advertising platform and still produce a measurement mess. The ad attracts an interaction, the tag records an event, analytics classifies it differently, and the bidding system optimizes toward something nobody intended.

    The fix is not another dashboard or another tag. You need one traceable chain from the format a person sees to the business outcome you want, with a clear role and a test at every handoff.

    Key takeaways

    • Define each conversion in business terms before configuring it in Google, Meta, Google Tag Manager, or an analytics property.
    • Give ad formats, tagging, measurement, and automation separate jobs and separate acceptance tests.
    • Treat every new ad format as a new measurement surface, especially when one unit presents several locations or choices.
    • Reuse an established data layer through official platform templates where supported, but verify mappings and duplicate events before publishing.
    • Do not increase spend until you can trace one test action from the page or app through the tag, platform, report, and optimization setting.

    Build one conversion contract before touching platform settings

    Five symbolic tiles for an ad, user action, event, analytics step, and business outcome connect in a tested sequence on a tabletop.

    Advertising platforms encourage you to start with their menus: choose an objective, install a tag, select an event, and launch. That sequence is convenient, but it lets each platform define your measurement model. The same customer action can then become a primary conversion in one account, a secondary event in another, and an analytics event with a third meaning.

    Start with a conversion contract instead. This is a short specification for what happened, why it matters, and how every system should represent it. For each event, record:

    <!– wp:list {