Category: Advertising

  • How ChatGPT Ads May Work: Infrastructure and Targeting

    How ChatGPT Ads May Work: Infrastructure and Targeting

    If you are preparing for ChatGPT ads, the wrong first question is which keywords to buy. Start with a harder one: where can your brand help someone complete a task without disrupting the answer they came for?

    There is enough evidence to begin that planning, but not enough to treat the platform like a finished search-ad product. An instruction-like reference to additional context about ads shown to a user has appeared in ChatGPT page source. Ads have also been described as being tested in the U.S. across account types. An impression-based sales model has been associated with the initial rollout. Those clues point toward an ad-aware conversational system, but they do not disclose its auction, targeting controls, reporting, or billable-impression rules.

    Key takeaways

    • The visible implementation clues suggest that an experimental answer layer can receive information about an ad, but they do not prove how ads are selected, ranked, priced, or displayed.
    • Your most useful targeting model is the user’s current task state: exploring, reducing options, confirming a choice, or acting.
    • ChatGPT is a task environment. An ad has to reduce effort, uncertainty, or friction to earn attention inside it.
    • Prepare tools, templates, comparison criteria, proof, clear pricing, and direct next steps instead of relying on generic awareness creative.
    • Keep paid placement separate from organic AI visibility. There is no disclosed basis for assuming that JSON-LD, citations, rankings, or LLM mentions determine ad eligibility.
    • Do not evaluate an impression-priced pilot on click-through rate alone. Measure task progress, shortlist influence, branded demand, assisted conversions, and downstream conversion quality.

    Read the infrastructure clues without inventing a finished ad stack

    The most revealing clue is the instruction-like text, “InReply to user query using the following additional context of ads shown to the user.” Its presence suggests that, in at least one experimental path, the response system may be capable of receiving ad context. It does not establish whether an ad is selected before generation, inserted afterward, rendered in a separate unit, or merely represented in dormant test logic.

    That distinction matters. A string in page source can expose an implementation path without proving that ordinary users see the feature, that advertisers can buy it, or that the path will survive a production launch. Treat it as evidence of preparation, not as a public specification.

    A practical working model has six layers. The layers are useful for planning and vendor questions; they are not claims about OpenAI’s final architecture.

    1. Opportunity and eligibility: The system determines whether the current user, account, session, market, and conversation can receive an ad. Suppression for some paid accounts is plausible, but the available evidence does not establish a rule.
    2. Task interpretation: The system identifies what the person is trying to accomplish and whether the moment has commercial relevance. This could be richer than matching a single word because users describe situations, constraints, and desired outcomes in natural language.
    3. Candidate retrieval: Eligible campaigns or offers are assembled. Nothing disclosed so far tells you whether advertisers will control keywords, topics, audiences, exclusions, objectives, feeds, or some combination of them.
    4. Selection and placement: A candidate is chosen and rendered. Selection could involve bids, relevance, utility, policy, predicted response, or rules that have not been published. Do not build a financial forecast around an assumed auction.
    5. Answer coordination: The experimental wording indicates that the response layer may know about the ad. That does not prove the model endorses the advertiser, changes its answer to accommodate the advertiser, or treats the placement as an organic recommendation.
    6. Impression and outcome logging: An impression-priced system needs a billable event and reporting path. The unresolved issue is what qualifies: selection, rendering, visibility, completion of the response, or another event.

    This model gives you a disciplined way to evaluate a launch announcement. For each layer, mark a claim as confirmed, inferred, or unknown. If a media plan depends on an unknown variable, place that assumption next to the forecast rather than burying it in the spreadsheet.

    Before committing budget, get direct answers to the questions that change cost or risk:

    • Which plans, markets, account types, and conversation categories are eligible?
    • Is the ad a separate labeled unit, part of the response, or attached to a later action?
    • Does matching use the current message, the conversation context, account-level signals, or an advertiser-selected audience?
    • What exactly creates a billable impression, and can the same campaign create repeated impressions in one conversation?
    • Can more than one advertiser appear in a response or session?
    • Which placement, frequency, query-category, and conversion breakdowns will advertisers receive?
    • How are invalid activity, accidental rendering, suppressed placements, and reporting discrepancies handled?
    • How will paid placement be distinguished from an independent answer, citation, or recommendation?

    The impression definition is especially important. If you do not know what is being counted, a quoted CPM cannot tell you how much meaningful exposure you are buying. Use a capped pilot until the billable event, reporting latency, and repetition rules are clear.

    Separate platform targeting from your task-targeting strategy
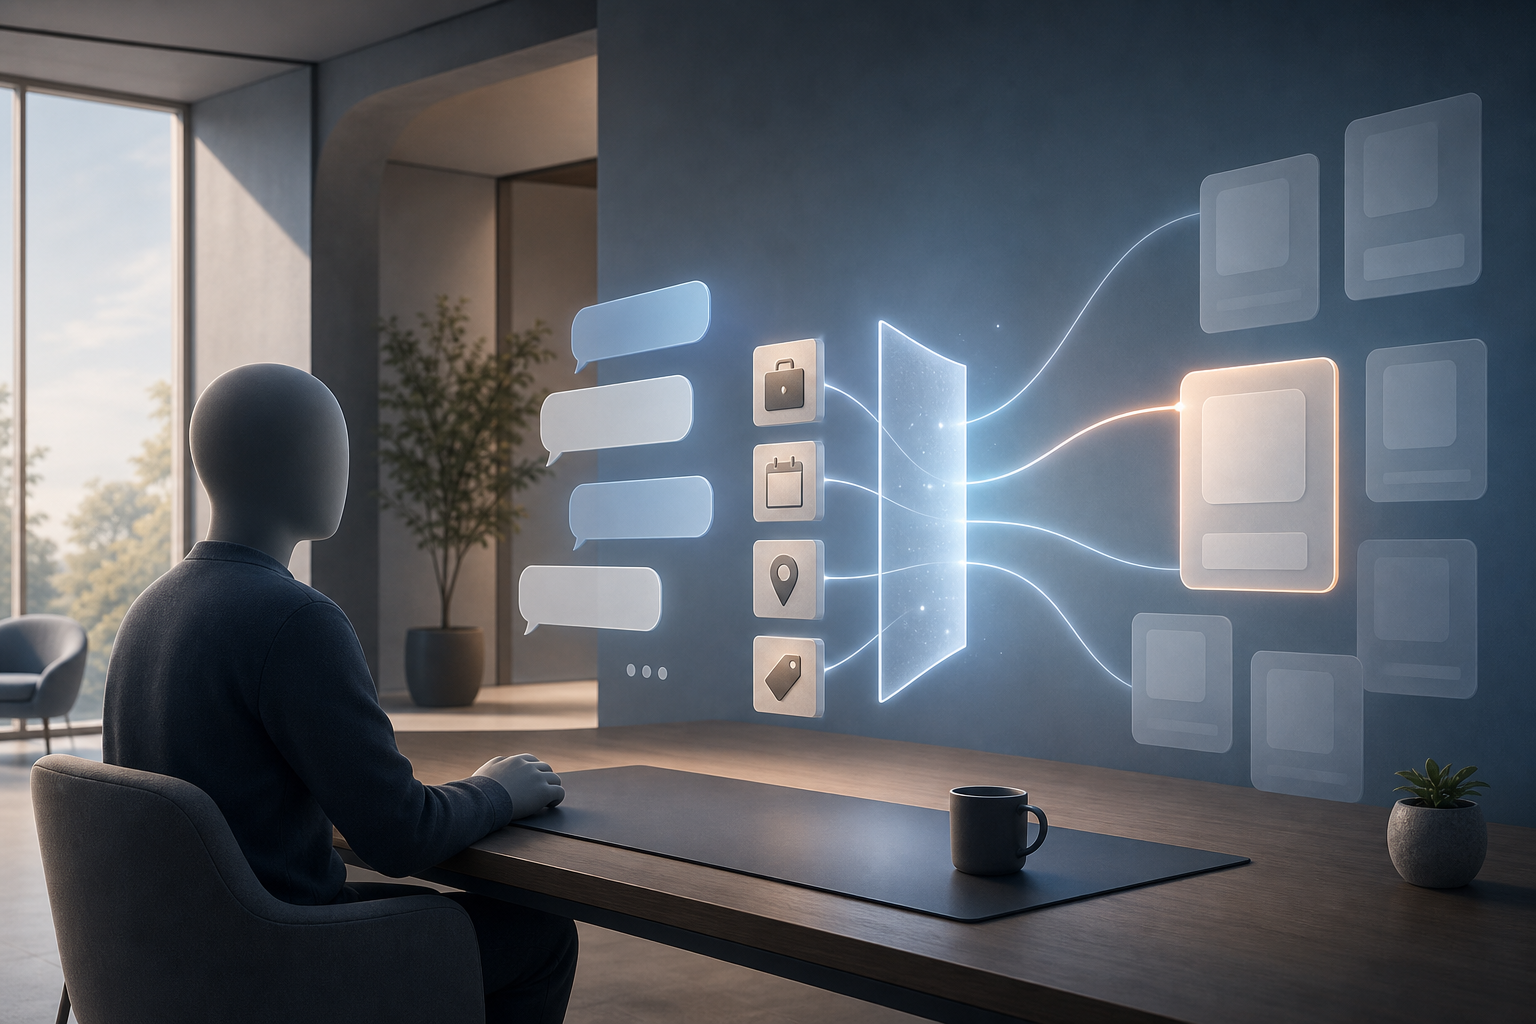
    Anonymous user at a generic conversation interface as task-related objects pass through a privacy shield toward one relevant product card.

    Marketers often collapse two different questions into the word “targeting.” Platform targeting is what OpenAI actually lets an advertiser select and what its system uses behind the scenes. Those controls remain unclear. Strategy targeting is the set of user moments your brand wants to help. You can build that second model now without pretending to know the first.

    Start with the task, not the topic. “Project management software” is a topic. “Reduce a shortlist to two tools that meet our security and migration requirements” is a task. The second formulation tells you what assistance would move the decision forward.

    Then identify the person’s behavior mode. Four modes cover the most useful distinctions:

    Behavior modeWhat the user is trying to doThe ad’s useful jobSuitable destinationCommon failure
    ExploreFind possibilities, frame a problem, or form a point of viewIntroduce a relevant option, framework, or new way to evaluate the taskFocused guide, template, or planning toolDemanding a purchase before the user has defined the decision
    ReduceNarrow a broad set of optionsClarify differences and remove unsuitable choicesComparison criteria, selector, checklist, or concise options pageRepeating category-level claims that do not help eliminate anything
    ConfirmTest whether a likely choice is safe or credibleResolve risk with relevant proof, reviews, terms, or guaranteesEvidence page with the exact claim, limitation, and policy the user needsUsing unsupported superlatives when the user is looking for verification
    ActComplete a purchase, booking, inquiry, or setup stepRemove the final procedural or commercial frictionClear pricing, availability, requirements, or direct action pageSending the user through a generic homepage or an unnecessary lead-capture detour

    This is contextual task alignment, not necessarily personal behavioral profiling. Do not assume that an advertiser will receive raw prompts, conversation histories, or individual-level audience data. Build your strategy around the help required in a moment; wait for published controls before deciding how that moment can be bought.

    You can create a task map from information your organization already has permission to analyze:

    1. Collect recurring questions from onsite search, sales calls, support tickets, customer interviews, product reviews, and existing search-query data.
    2. Remove brand language and rewrite each question as a job: “Help me choose,” “help me verify,” “help me plan,” or “help me complete.”
    3. Assign an explore, reduce, confirm, or act mode based on the next decision the person wants to make. Do not classify it from the nouns in the question alone.
    4. Name the friction preventing progress: missing criteria, too many choices, credibility risk, hidden cost, unclear requirements, or a complicated next step.
    5. Choose the smallest asset that removes that friction.
    6. Add an exclusion rule. If your offer cannot truthfully help with a constraint or task, the placement should not be pursued merely because the category matches.

    A single conversation can move through several modes. Someone may explore options, reduce a shortlist, confirm one vendor, and ask for a final action within the same session. Prepare a family of task-specific assets rather than one universal ad and one universal landing page.

    Build ads and destinations as one utility path
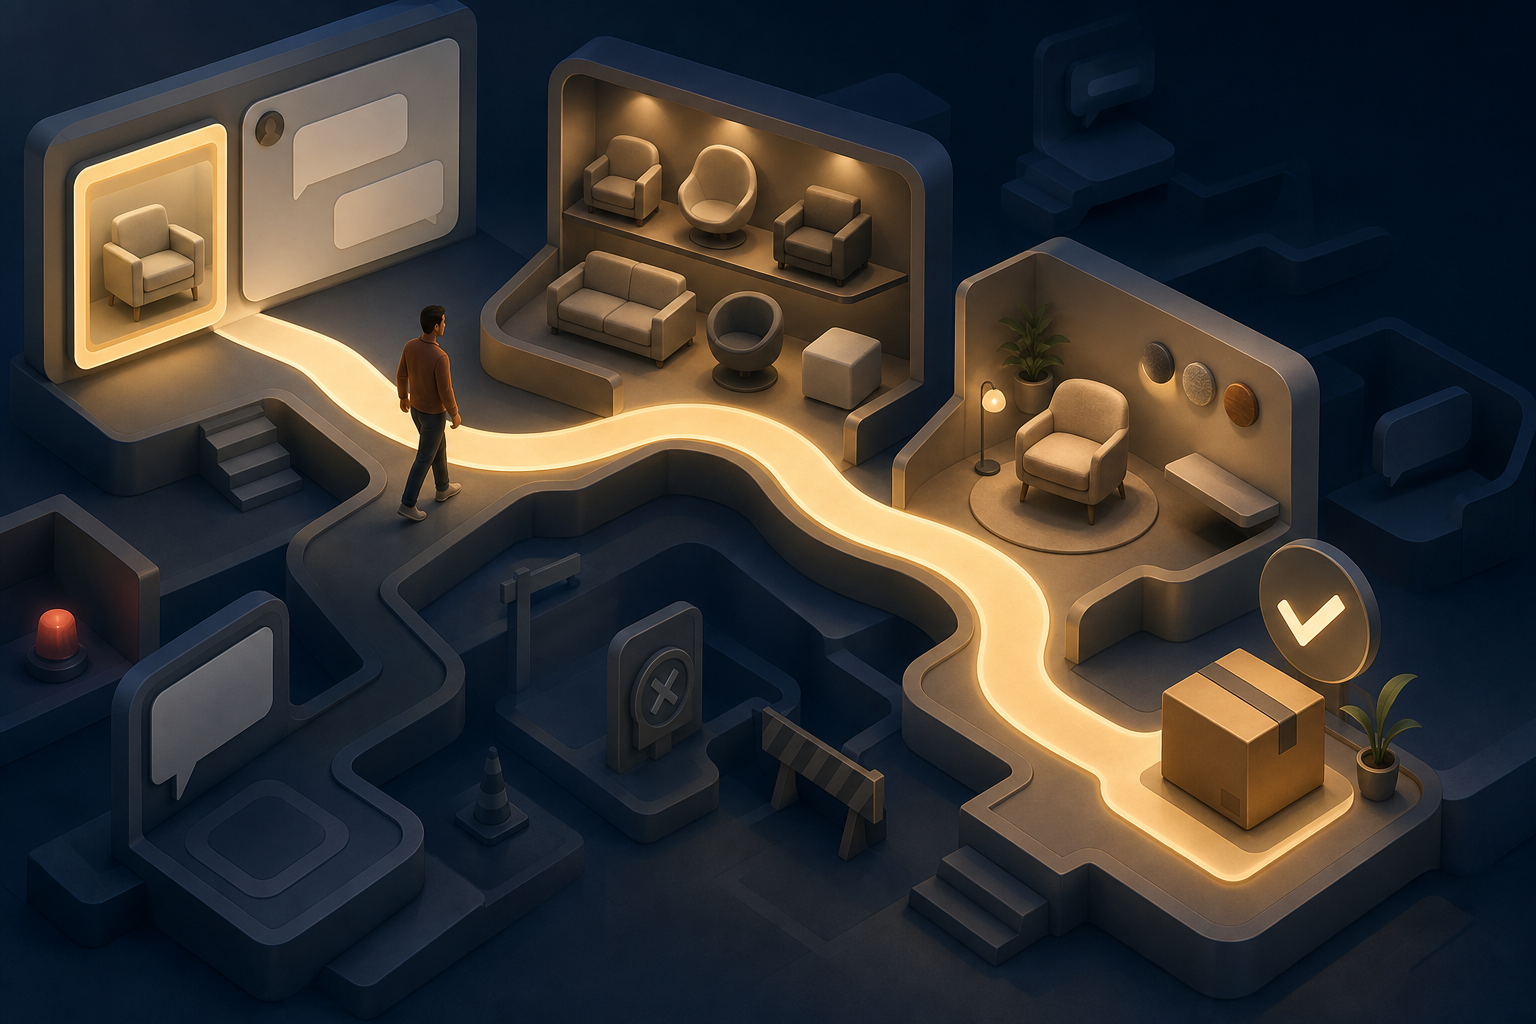
    A person follows a continuous illuminated path from a sponsored conversation module through comparison and configuration to a completed purchase.

    People open ChatGPT to finish something. That creates goal shielding: information that does not help the current task is easier to ignore and more likely to feel intrusive. Topical relevance is therefore only the entry condition. Practical utility is what earns attention.

    Useful ChatGPT ad concepts are likely to resemble decision aids more than conventional display creative. The asset might be a template, checklist, focused guide, shortcut, comparison framework, or proof page. The correct format depends on the behavior mode, not on which asset type your team already knows how to produce.

    Use a four-part creative brief:

    1. Task cue: State the exact decision or action you can help with.
    2. Utility promise: Say what work the asset removes. Avoid an abstract promise such as “discover more.”
    3. Proof or constraint: Show why the help is credible and where it applies. Do not hide a limitation that would disqualify the offer.
    4. Low-friction next step: Take the person directly to the relevant tool, evidence, pricing, or action.

    Copy patterns can stay simple. In explore mode: “Planning [outcome]? Use [resource] to define the decision.” In reduce mode: “Comparing [category]? Evaluate the options by [specific criteria].” In confirm mode: “Need to verify [risk]? Review [proof, policy, or terms].” In act mode: “Ready to [action]? See the price, requirements, and next step.” These are structural prompts for your team, not claims to paste unchanged into a campaign.

    The destination must continue the task at the same level of specificity. If the ad promises a checklist, open the checklist. If it promises pricing, show pricing rather than requiring a form to reveal it. If it promises evidence, place the evidence and its limits before the broader brand story. Every extra detour asks a focused user to abandon one task and begin another.

    Use a simple utility test before approving an asset: if the logo were removed, would the intended user still find the asset useful at that point in the decision? A “no” does not automatically make the concept unusable, but it reveals that you are relying on interruption or brand recognition rather than assistance.

    Connect paid utility to SEO and GEO without confusing the systems

    The strongest utility assets can support several channels. A rigorous comparison framework may help paid performance, become an organic content asset, give public-relations teams something substantive to reference, and provide sales teams with a consistent explanation. Reviews, expert validation, media coverage, and a stable brand voice can reinforce the same evidence base.

    That overlap does not mean paid and organic visibility share a ranking system. There is no disclosed basis for claiming that schema markup, organic rankings, AI citations, brand mentions, or current LLM visibility determine ChatGPT ad eligibility or price. Likewise, buying an impression should not be counted as earning an organic citation or recommendation.

    Keep two scorecards. Your organic AI scorecard can track whether systems find, understand, cite, and accurately represent your content. Your paid scorecard can track purchased exposure, task engagement, decision influence, and business outcomes. Both programs can use the same accurate claims and useful assets, but each needs its own causal hypothesis.

    Apply the same separation to JSON-LD. Maintain structured data because it accurately represents the page and entity in your organic architecture, not because you expect it to unlock ad inventory. If a future advertiser specification names structured data as an input, update the model then.

    Measure whether the ad advanced the task, not just whether it won a click

    Click-through rate is useful diagnostic data, but it is too narrow to carry the business case. A user may see a brand while refining a decision, continue the conversation, and return through branded search, direct traffic, a sales interaction, or another channel. A click-only view misses that path; an impression-only view can overstate it.

    Build the measurement plan before the first paid impression:

    1. Record a baseline: Capture branded search, direct traffic, relevant conversion rates, assisted conversions, and known shortlist or recall measures before exposure begins. Without a baseline or comparison group, a later increase is only a correlation.
    2. Define success by mode: Explore may prioritize qualified use of a planning asset. Reduce may prioritize completion of a comparison tool. Confirm may prioritize engagement with proof and a later qualified conversion. Act may prioritize completion of the intended transaction or inquiry.
    3. Instrument the destination: Use campaign-specific URLs and track the meaningful action inside the asset, not merely the landing-page load.
    4. Capture decision influence: Where appropriate, use brand-lift research, customer surveys, self-reported discovery fields, or win-loss interviews to learn whether the brand entered or remained on the shortlist.
    5. Use a comparison design: If the platform offers holdouts, matched markets, or another credible control, use it. Do not attribute every simultaneous change in branded search or direct traffic to the campaign.
    6. Set a spend ceiling: Limit the pilot until you understand the billable impression, repetition rate, placement, traffic quality, and reporting. The downside of guessing is paying repeatedly for exposure that your measurement cannot connect to task progress.

    Your reporting should follow a measurement ladder:

    • Delivery: Billable impressions, eligible reach, frequency, placement, and suppression data, to the extent the platform provides them.
    • Immediate engagement: Clicks, qualified visits, and interaction with the promised asset.
    • Task progress: Checklist completion, comparison use, evidence engagement, pricing views, or completion of the next relevant step.
    • Decision influence: Shortlist inclusion, brand recall, branded search, direct return visits, and assisted conversions.
    • Business quality: Qualified inquiries, conversion rate later in the journey, completed purchases, and the value of those outcomes.

    Read the combinations, not isolated metrics. High click-through with weak asset use usually points to a promise-to-destination gap. Low click-through with strong task completion among visitors can indicate that the help is valuable but the placement or wording is not making that value clear. Strong delivery without controlled lift in recall, branded demand, or outcomes is not proof of influence.

    Organize tests around the unit that matters: behavior mode, task, utility asset, destination, and proof. A headline test can improve a local metric while leaving the underlying offer irrelevant. Changing the type of help often teaches you more than changing a few words around the same generic destination.

    Your immediate deliverable should be a one-page readiness sheet for the most commercially important task you can genuinely help with. Name the mode, user friction, asset, destination, supporting proof, exclusion rule, primary outcome, spend ceiling, and unresolved platform question. When advertiser access and specifications become available, compare them with that sheet before moving money. You will be testing a defined hypothesis instead of paying to discover what your strategy was supposed to be.
    References

  • Paid AI Advertising: A Campaign Optimization Framework

    Paid AI Advertising: A Campaign Optimization Framework

    You’re being asked to put paid media into AI environments, but the budget question has arrived before the measurement plan. One option sells visibility inside an AI conversation. Another uses AI to distribute campaigns across established ad inventory. Treating them as the same thing is how an expensive pilot ends with plenty of activity and no defensible conclusion.

    Before you spend, decide whether you are buying attention, teaching an automated campaign system to find valuable outcomes, or proving incremental impact. Those are different jobs. Each needs its own success metric, data inputs, and testing method.

    Separate AI ad placement from AI campaign optimization

    A split illustration contrasts an unbranded product placed inside a text-free AI conversation with an automated system distributing campaign signals across multiple advertising surfaces.

    Conversational AI inventory is a placement. You pay to appear within an AI product and receive whatever reporting that product makes available. The early ChatGPT ad offer has reportedly been priced at around $60 per 1,000 impressions, roughly three times the rate of standard Meta advertising. Advertisers may initially receive basic totals such as impressions and clicks without purchase-level reporting.

    That measurement ceiling changes the campaign’s proper role. If you cannot observe purchases or other downstream outcomes in the ad platform, you cannot honestly manage the placement like a mature direct-response channel. You can test reach, click response, message-market fit, and post-click behavior in systems you control. You cannot turn an impression-and-click report into a reliable platform ROAS calculation.

    Initial ChatGPT ad availability is expected to focus on free and lower-cost Go users, while excluding people under 18 and conversations involving sensitive subjects such as mental health or politics. Those rules help define where ads may appear, but they do not tell you whether the reachable audience matches your buyers. Confirm audience fit before treating the environment itself as proof of media quality.

    Performance Max is a different use of AI. It is a goal-based campaign model spanning Search, YouTube, Display, Discover, Gmail, Maps, and emerging inventory in AI Overviews. You are not simply purchasing an isolated AI placement. You are giving an automated system a business objective, conversion signals, creative assets, and permission to allocate delivery across Google’s inventory.

    DecisionConversational AI placementAI-optimized campaign
    What you are buyingVisibility within an AI productAutomated delivery across multiple channels
    Main information available to the systemPlacement context and the product’s available targetingConversion goals, audience signals, customer data, and creative assets
    Best initial useBrand visibility and format learningDemand capture or demand generation tied to meaningful outcomes
    Critical limitationIncomplete attribution can prevent performance-level conclusionsWeak conversion signals can teach the system to pursue low-value actions

    Neither model is inherently better. The useful question is whether you want to buy attention in a new environment or delegate campaign allocation to an outcome-driven system. If your brief cannot answer that question in one sentence, it is not ready for budget approval.

    Set the campaign job and evidence standard before the budget

    A premium CPM makes an undefined learning campaign expensive. At a reported $60 CPM, 50,000 impressions represent $3,000 in media, while 100,000 impressions represent $6,000. Those figures are not performance forecasts. They are the budget identity: planned impressions divided by 1,000, multiplied by CPM.

    Use that calculation before you debate creative or targeting. Decide how much exposure is necessary to answer a defined question, then price the test. Do not start with an arbitrary budget and invent a purpose after delivery begins.

    A workable campaign charter should state six things:

    1. The decision: Name what you will do differently when the test ends. Examples include rejecting the placement, revising the message, expanding the test, or moving budget into a controlled lift experiment.
    2. The hypothesis: Describe the audience, message, environment, and expected behavior. “Test AI ads” is an activity, not a hypothesis.
    3. The campaign job: Choose visibility, qualified demand, or incrementality. Do not make one campaign responsible for all three.
    4. The primary outcome: Use delivered impressions or click response for a visibility test, a CRM-qualified event for performance optimization, or lift for an incremental-impact test.
    5. The spending limit: Set the maximum media outlay before launch. A learning objective is not permission for an open-ended budget.
    6. The claim boundary: Write down what the available evidence will not prove. If the platform reports only impressions and clicks, state in advance that the platform report will not prove purchase impact.

    Use a measurement ladder instead of one dashboard

    Each measurement layer answers a different question. Keeping those questions separate prevents attribution language from outrunning the evidence.

    • Platform delivery data: Impressions show that ads were served. Clicks and click-through rate show an immediate response. They do not show whether the campaign created revenue.
    • Owned post-click analytics: A dedicated or properly tagged destination can show what visitors did after clicking, subject to your consent and analytics setup. This connects traffic to on-site behavior, but it does not prove that the same behavior would not have happened without the campaign.
    • CRM outcomes: Qualified leads, appointments, opportunities, and eventual revenue help you distinguish valuable responses from easy conversions. Preserve the campaign identifier through the handoff so the business outcome can be associated with its acquisition path.
    • Controlled experiments and lift: A suitable control or lift design addresses the incremental question: what changed because the campaign ran?

    OpenAI has paired its advertising plans with commitments not to sell user data or compromise the privacy of conversations. That stance may constrain the user-level targeting and attribution methods advertisers know from Google and Meta. Build the plan around aggregated platform reporting and consented, first-party post-click measurement. Do not base the business case on conversation-level data you hope might become available later.

    Give campaign automation a business outcome it cannot misread

    An automated campaign will pursue the success signal you provide, even when that signal is a poor substitute for business value. If every form submission is treated as equally valuable, the system has no reason to distinguish a sales-ready buyer from a vendor, student, job applicant, or unqualified prospect.

    Performance Max therefore needs a conversion architecture before it needs more creative. For a B2B campaign, put these elements in place first:

    1. Connect the CRM or other business data source. Salesforce is one example, but the brand matters less than the handoff. The advertising system needs a path from the online action to a meaningful business status.
    2. Select a revenue-relevant conversion event. A qualified lead submission or booked appointment is more informative than an unfiltered form fill when qualification is part of the sales process.
    3. Separate optimization events from diagnostic events. Page views, content interactions, and raw leads can help diagnose the journey without being treated as equal optimization targets.
    4. Supply a customer list when appropriate and permitted. First-party customer data gives the system characteristics it can use for modeling and can be more useful than relying on website remarketing audiences alone.
    5. Choose an outcome-based bid strategy. Maximize conversions and target CPA are aligned with the campaign model’s focus on outcomes rather than traffic alone.
    6. Protect the learning process from constant intervention. Frequent targeting, bidding, or structural changes alter the problem the system is trying to solve. Route substantial changes through planned experiments instead of repeatedly editing the live campaign.

    Check whether your market can support automation

    Good conversion plumbing does not make every market suitable for Performance Max. The system also needs room to find patterns and scale delivery.

    • Use automation when the addressable market is broad enough. A larger market gives the system more opportunities to learn which signals correlate with meaningful outcomes.
    • Keep manual control for tightly bounded account-based programs. If success depends on reaching only a few hundred named accounts, broad automated allocation may conflict with the strategy.
    • Be cautious in extremely narrow categories. Too little audience and conversion data can prevent useful scaling, regardless of the campaign’s technical setup.
    • Confirm organizational readiness. A team that cannot tolerate automated allocation or repeatedly overrides it may destabilize the campaign before it can produce interpretable evidence.

    The strongest B2B use case is a sizable market with a long buying cycle and several stakeholders. Cross-network delivery can maintain a presence around that buying group beyond a single search interaction. But sustained visibility only becomes optimizable when the conversion signal reflects genuine progress through the sales process.

    Optimize with controlled tests, not reactive campaign edits

    Two matched campaign test lanes carry audience tokens toward outcome vessels while an analyst observes the single highlighted difference between them.

    Optimization is a sequence of decisions. It is not the habit of changing bids, audiences, and creative whenever a dashboard moves. When several variables change together, you lose the ability to tell which change caused the result.

    Google’s Experiment Center brings campaign experiments and lift studies into one location. It can support tests involving bidding, targeting, and creative, alongside brand, search, and conversion lift measurement. Expanded A/B testing for Shopping and Performance Max, plus a Campaign Mix Experiments beta, provides more ways to validate a change before scaling it where those features are available.

    Run tests in an order that protects the quality of later conclusions:

    1. Validate conversion quality. Confirm that the primary event represents business value and reaches the campaign correctly. A creative or bidding test is difficult to interpret when the success label is unreliable.
    2. Test the proposition and creative. Compare a specific message or asset treatment against the control. Do not replace the audience, bid strategy, landing page, and creative in the same test.
    3. Test targeting or audience signals. Once the outcome and message are credible, determine whether a different signal set finds more of the right response.
    4. Test bidding and campaign mix. Evaluate allocation changes after the campaign is measuring the right outcome. Otherwise, you may simply become more efficient at acquiring the wrong conversion.
    5. Use lift when the question is causality. Platform attribution can associate an outcome with an ad interaction. Lift is the more relevant design when you need to know whether advertising generated an outcome that would not otherwise have occurred.

    Every experiment record should include the hypothesis, control, variant, primary outcome, guardrails, stopping rule, result, and resulting action. Define those fields before launch. A stopping rule created after seeing the data is an invitation to keep running a preferred result and stop an inconvenient one.

    The pattern across measurement layers matters more than any isolated metric:

    • If reported conversions rise while CRM-qualified outcomes stay flat, the campaign has probably improved the proxy rather than the business result. Fix the conversion signal before scaling.
    • If clicks rise but qualified outcomes do not, the creative may be attracting curiosity instead of buying intent, or the landing experience may not fulfill the ad’s promise. A higher click-through rate is not enough to choose between those explanations.
    • If reach is strong but you have no control or lift measurement, you can report delivery. You cannot claim that awareness increased merely because impressions were purchased.
    • If a lift test shows an incremental effect that last-click reporting misses, evaluate the cost of that lift against the value of the outcome. Do not discard incrementality solely because it appears in a different reporting layer.

    This is where campaign optimization and AI-search strategy meet. Paid visibility can create exposure while organic AI optimization works toward durable discovery, but the two should not be blended into one performance claim. Track paid placement, post-click behavior, CRM outcomes, and organic visibility as distinct evidence streams. Combine them only when the measurement design supports the connection.

    Key takeaways

    • Decide whether you are buying an AI placement or using AI to automate campaign delivery. They require different data and success criteria.
    • Treat a conversational placement with impression-and-click reporting as a visibility or learning test unless your owned systems can support a stronger, clearly qualified conclusion.
    • Price the learning question before launch. At a reported $60 CPM, every 50,000 impressions represents $3,000 in media spend.
    • Connect Performance Max to CRM-qualified outcomes, not just easy website actions, and use it only where the addressable market gives automation room to learn.
    • Move consequential changes into controlled experiments. Test conversion quality before creative, targeting, bidding, or campaign mix.
    • Match every claim to its evidence layer: delivery for exposure, CRM data for associated business outcomes, and lift testing for incrementality.

    Your next step is small but decisive: write one sentence naming the campaign’s job, then name the strongest outcome you can actually observe. If the job requires evidence your current setup cannot produce, repair the measurement plan or narrow the claim before you approve the spend.

    References

  • Apple App Store Ad Expansion: A Practical Campaign Plan

    Apple App Store Ad Expansion: A Practical Campaign Plan

    Your App Store search campaign can now qualify for ad positions you never selected. That creates another route to potential installs, but automatic eligibility also means delivery can change before your bids, product pages, and measurement plan do.

    You don’t need to rebuild the account to participate. You do need a clean baseline, a tighter relevance audit, and a rule for deciding whether additional volume is actually profitable. Otherwise, higher spend can look like growth even when install economics are deteriorating.

    Key takeaways

    • App Store search results can contain multiple sponsored ads, including the familiar top position and additional positions farther down the results.
    • Existing search results campaigns are automatically eligible. There is no separate placement switch to activate.
    • You cannot select a particular search-results position or bid specifically for one. Apple determines placement using relevance and bid.
    • Ad formats and billing remain the same: ads can use a standard or custom product page, optional deep links can lead to an in-app destination, and billing remains cost per tap or cost per install.
    • Apple’s reported conversion rate of more than 60% applies to top-of-search ads on average. Do not treat it as a promised benchmark for every keyword, market, or new lower-page position.

    What changes, what stays fixed, and what you control

    The most important distinction is between inventory and control. Apple is increasing the number of places where a search ad may appear, but it is not giving advertisers a position selector. Your campaign can enter more placement opportunities without gaining the ability to demand the top slot or exclude the lower ones.

    Campaign elementWhat the expansion meansWhat you should do
    Search-results inventoryMore than one sponsored ad can appear for a query, at the top and farther down the page.Measure whether added delivery produces incremental installs at an acceptable cost.
    EligibilityExisting search results campaigns qualify automatically.Establish a baseline before changing bids, keywords, or product pages.
    PositionApple chooses where an eligible ad appears.Do not build a strategy that assumes a bid increase buys a specific slot.
    MatchingSearch ads continue to match through advertiser-selected or Apple-suggested keywords.Audit the connection between each important keyword, its intent, and the destination page.
    Creative and destinationThe ad can use a standard product page or a custom product page, with an optional deep link.Choose the page that most directly continues the promise implied by the keyword.
    BillingCost-per-tap and cost-per-install billing remain available.Keep the commercial decision anchored to install value rather than raw visibility.
    Device supportThe additional positions are supported on devices running iOS or iPadOS 26.2 and later.Remember that a mixed device audience may not encounter the expanded layout uniformly.

    Apple scheduled the first phase for the UK on March 3, with Japan following and all Apple Ads markets expected to be included by the end of March. That staggered schedule makes market-level annotations important. If you do not record when exposure could have changed, later analysis can confuse the rollout with seasonality, a product release, a pricing change, or another campaign edit.

    Do not interpret extra inventory as a new targeting system. The campaign is still built around keyword relevance, the product-page experience, and the economics of a tap becoming an install. The expansion changes where an eligible ad may be delivered, not the basic job the ad must do.

    Build a baseline before you react to the new inventory

    A marketer's hands organize four groups of campaign tokens beside a phone and tablet, with loose tokens arriving beyond a divider.

    Automatic eligibility turns measurement into the first task. If you raise bids, add keywords, replace product pages, and increase the budget at the same time, you will not know whether a performance shift came from the extra placements or from your own changes.

    1. Mark the rollout in your account records. Record the relevant market date and note that the additional placements require iOS or iPadOS 26.2 or later. Use the most precise market and device information your reporting actually provides; do not assume a dimension exists if it is not visible in your account.
    2. Save a comparable pre-expansion view. Capture impressions, taps, installs, conversion rate, spend, cost per tap, and cost per install for each important market, campaign, and keyword. Use a period that reflects the normal buying cycle of your app rather than an arbitrarily short snapshot.
    3. Document other variables. Note product releases, store-listing changes, promotions, pricing changes, tracking updates, and budget edits. Each can move conversion independently of ad position.
    4. Set an economic guardrail. Decide the highest cost per install the business can support before more volume arrives. Base that ceiling on the value and quality of an acquired user, not on a competitor’s bid or a platform-wide conversion claim.
    5. Verify conversion measurement. Confirm that taps and installs are being attributed as expected. If you use deep links, test that each one opens the intended in-app destination for the relevant user journey.
    6. Avoid unnecessary simultaneous changes. Keep the first observation window as stable as the business allows. When an urgent edit is unavoidable, annotate it so the resulting data is not mistaken for a placement effect.

    A before-and-after comparison is useful, but it is not proof of incrementality. During a staggered rollout, a comparable market that has not yet changed can provide a directional check. It is only a useful comparison when demand patterns, promotions, and app availability are genuinely similar. Once all markets are included, rely on annotated within-market trends and be explicit about competing explanations.

    Expect aggregate metrics to move in different directions. Total installs can rise while conversion rate falls because the campaign is reaching additional inventory with different user behavior. That is not automatically good or bad. The decision turns on whether the added installs remain valuable at the resulting cost per install.

    Relevance is the control surface you still have

    A magnifying lens brings one app tile into focus on a smartphone while surrounding tiles remain blurred and connected category cues suggest relevance.

    You cannot control the exact position, but you can control how coherent the journey is from keyword to ad to product page. Apple weighs bid and relevance when assigning placements, and a high bid cannot force an ad into an auction when the match is not sufficiently relevant. That makes relevance an eligibility issue, not merely a creative preference.

    Audit the journey in this order:

    1. Write down the intent behind the keyword. Is the person looking for your brand, a broad app category, a specific task, or a particular feature? If the intent is ambiguous, do not pretend one product page can answer every possible meaning.
    2. Match the page to that intent. Use the standard product page when it accurately represents the query. Use a custom product page when a distinct use case needs different screenshots, copy, or emphasis.
    3. Check the first visible promise. The opening product-page experience should make the connection immediately. If the query implies one task but the page leads with another, more traffic will magnify the mismatch.
    4. Use deep links as a continuation, not a shortcut. A deep link is useful when the destination completes the journey implied by the ad. It is counterproductive when it drops the user into an unrelated or contextless part of the app.
    5. Remove mismatches you cannot fix. If a keyword’s intent cannot be represented truthfully by the app or its page, a larger bid is not the remedy. Refine or pause the keyword.

    This is also why paid acquisition and App Store optimization cannot be managed as isolated disciplines. Search ads use the product-page experience to turn intent into an install. A weak listing is therefore both an organic discoverability problem and a paid conversion problem. Extra ad slots increase the cost of leaving that handoff unresolved.

    Be careful with Apple’s top-of-search benchmark. Apple reports an average conversion rate above 60% for ads in that position, but the figure is vendor-supplied and specific to top-of-search performance. It does not establish how the additional lower positions will perform in your market. Use it as context, not as a forecast or account target.

    A global bid increase is a poor first response. Because you cannot purchase a named position, a higher bid does not guarantee that the added spend will secure the top placement. Hold bids steady long enough to observe the change where practical, then adjust one major lever at a time: keyword scope, bid, product page, or budget. That sequence keeps the diagnosis legible.

    Decide whether the added delivery deserves more budget

    More impressions are an inventory result. More taps show that users responded. More valuable installs are the business result. Keep those three questions separate when you evaluate the expansion.

    • Impressions and taps rise, while cost per install stays within your guardrail: the additional inventory may be adding efficient reach. Increase budget gradually and keep watching keyword-level conversion rather than assuming the first result will persist.
    • Spend and installs rise, but cost per install exceeds the guardrail: the campaign is buying volume that the business may not be able to support. Reduce exposure to weak keywords, improve the matching product page, or lower bids before approving more budget.
    • Taps rise while installs remain flat: investigate the handoff from query to page. Check tracking first, then review intent alignment, product-page clarity, and any deep-linked destination. Do not use a bid increase to solve a conversion failure.
    • Impressions rise but taps do not: eligibility is not the same as appeal. Revisit whether the keyword and visible product-page message give the searcher a clear reason to choose the app.
    • Little changes: automatic eligibility does not guarantee meaningful delivery. Leave the campaign alone unless another metric provides a reason to act.

    Cost pressure is possible, but it should not be assumed. More ads on a results page can intensify competition for high-intent searches, while more available inventory can also alter the supply of opportunities. The net effect depends on the auction, query, market, and relevance of your ad. Let observed cost per install and conversion quality decide the response.

    Review the keywords responsible for most of your spend first. Map each one to its intended product page, confirm conversion tracking, record the rollout date, and set the cost-per-install ceiling before changing the bid. When the expanded inventory produces installs inside that boundary, scale deliberately. When it only produces activity, fix the journey or decline the extra volume.

    References

  • How to Plan Conversational AI and Social Ad Budgets

    How to Plan Conversational AI and Social Ad Budgets

    You have one experimental budget and three names in the room: Threads, ChatGPT, and Gemini. Calling all three emerging ad opportunities hides the decision that matters. What can you buy, what can you measure, and what job should each surface do?

    Start with the buying mechanics. Threads can enter Meta’s established campaign workflow. Early ChatGPT inventory is a controlled, impression-based buy. Gemini has no paid placement under Google’s announced stance. Once you separate those models, the budget decision becomes much easier.

    Separate the opportunity into three different ad markets

    Conversational AI and social feeds may compete for the same experimental budget, but they do not sell the same product. One sells feed distribution through a mature advertising system. Another is testing sponsored exposure beside a generated answer. The third is withholding ads while it develops the assistant.

    SurfaceWhat advertisers can accessWhat that means for your plan
    ThreadsGlobal advertiser access, a rollout to users worldwide, Advantage+ campaign expansion, and image, video, and carousel formats. Campaigns can be managed within the wider Meta environment used for Facebook, Instagram, and WhatsApp.Treat it as a paid-social placement test. Use familiar campaign objectives, but require placement-level reporting before claiming that Threads caused the result.
    ChatGPTSelected-advertiser testing with impression-based pricing, initial advertiser commitments below $1 million, and no self-service buying. Sponsored units are placed at the bottom of responses and separated from the organic answer.Treat it as controlled innovation inventory. It may support reach, learning, and brand objectives before it can support a conventional performance case.
    GeminiNo planned ad product under the stated 2026 position. Google is prioritizing assistant quality, usefulness, and trust before monetization.Do not put Gemini impressions in a paid-media forecast. Keep it in your organic AI visibility program and on a product-monitoring list.

    Availability is the first gate, not the final reason to spend. Threads has a reported user base of more than 400 million, but that figure describes platform scale rather than the reach available to your account. Meta also indicated that delivery would begin modestly. Your forecast should therefore come from the inventory and placement estimates available during campaign setup, not from the platform-wide audience number.

    ChatGPT presents the opposite planning problem. A conversation can reveal strong intent, but impression-based billing does not prove that the user noticed the sponsored unit, asked about it, visited the advertiser, or converted. Pricing tells you what triggers the charge. It does not tell you whether the exposure worked.

    Key takeaways

    • Classify each opportunity by buying model and reporting capability before comparing audience size.
    • Use Threads as an additional paid-social placement, not as a proxy for conversational intent.
    • Use early ChatGPT inventory for an impression-led learning objective unless the buying agreement supplies stronger outcome measurement.
    • Keep Gemini out of paid-media budgets until an actual ad product defines access, formats, billing, reporting, and controls.
    • Report paid conversational exposure separately from organic mentions and citations in AI answers.

    Give each surface one job before you fund it

    A new placement becomes expensive when it is asked to prove everything at once. If the same test is supposed to create awareness, generate leads, establish brand safety, and teach you how the format works, almost any result can be rationalized after the fact. Assign one decision question to each surface before approving spend.

    Threads: test incremental paid-social distribution

    Threads is the most operationally familiar option because Meta can streamline campaign expansion through Advantage+. That convenience can also obscure what happened. A blended Meta result cannot tell you whether Threads earned its share of the budget unless your reporting isolates delivery and outcomes for that placement.

    1. Write one hypothesis. For example, test whether a specific audience and creative concept can produce acceptable traffic or conversion quality on Threads. Do not use a vague objective such as learning the platform.
    2. Select one primary outcome. Choose reach, traffic, leads, sales, or another campaign objective supported by your setup. Keep secondary metrics diagnostic rather than treating every metric as a success condition.
    3. Confirm placement visibility. Before launch, verify that your reporting can show Threads delivery, spend, and the outcome tied to your objective. If it cannot, treat the campaign as a broader Meta test rather than a Threads test.
    4. Control the creative comparison. Carry one existing paid-social concept into the test and pair it with one Threads-specific variation. Hold the offer and audience as steady as your controls permit so that the creative difference remains interpretable.
    5. Predefine the decision rule. Set the acceptable result from your own paid-social benchmark before seeing the data. Record what would justify scaling, revising creative, or stopping.

    Modest early delivery may reflect limited inventory rather than a failed message. Do not judge creative after a handful of impressions, but do not wait indefinitely either. Evaluate once the placement has delivered enough exposure for the metric in your prewritten rule, and document underdelivery as a separate finding.

    ChatGPT: buy access only when the learning is worth the ambiguity

    Do not copy a paid-search brief into ChatGPT. The user may be expressing a need in the conversation, but the initial commercial model emphasizes impressions and offers limited conventional performance reporting. That makes the first tests better suited to advertisers that can value exposure and format learning without manufacturing a direct-response conclusion.

    Access is itself a qualification step. Initial testing involves selected advertisers, spending below $1 million per advertiser, without a self-service interface. The announced audience configuration places ads in free access and the $8-per-month ChatGPT Go tier, while Plus, Pro, and Enterprise remain ad-free for the time being. Your buying brief should identify the audience you can actually reach rather than referring to ChatGPT users as one undifferentiated group.

    Get written answers to these questions before approving an insertion order or equivalent commitment:

    • What event counts as a billable impression, and which impression fields appear in reporting?
    • Which account tiers, geographies, devices, and conversation contexts are eligible?
    • Can the unit link to a destination, and how are clicks or other interactions defined?
    • Are reach, frequency, and repeat exposure available, or will you receive only aggregate impressions?
    • Can follow-up questions about the sponsored product be measured, and are they reported in aggregate without exposing private conversation content?
    • Which category exclusions, adjacency controls, and remediation procedures apply?
    • Can campaign data be exported for reconciliation with your analytics and customer systems?

    If those answers do not support your normal acquisition model, label the spend correctly: a brand and product-learning test. Do not place a cost-per-acquisition target in the approval document and then excuse its absence because the format is new.

    Gemini: define the trigger for reconsideration

    A no-ad position is not the same as a permanent ban, but it is enough to make the current budget decision. Google leadership has ruled out Gemini ads for 2026 under the stated plan, citing the need to protect helpfulness and trust.

    Do not reserve speculative Gemini media money merely to appear prepared. Put the surface on a watchlist with five activation triggers: buyer access, eligible audience, ad format, billing method, and reporting controls. Until all five are defined, the paid-media row should remain unavailable rather than carrying an invented forecast. Your organic work for Gemini belongs in a different plan and can continue without waiting for an ad product.

    Build a measurement contract before the campaign

    Two analysts examine an abstract advertising journey that passes through a series of measurement checkpoints from impression to conversion.

    The measurement plan should be short enough to read in one meeting and strict enough to prevent a weak result from being renamed a success. For every test, record the business question, the primary metric, supporting diagnostics, disqualifying conditions, evaluation window, data owner, and decision owner.

    Use a four-level measurement ladder:

    1. Delivery: Record spend, billable impressions, placement share, and reach or frequency when provided. Reconcile the purchased amount with the platform report before interpreting response.
    2. Observable response: Track clicks, destination sessions, or another defined interaction only when the format supports it. State exactly what the platform counts rather than assuming that similarly named metrics are equivalent.
    3. Business outcome: Connect qualified leads, purchases, or other approved outcomes through your normal analytics process. Separate directly observed conversions from modeled or assisted attribution.
    4. Incrementality: When the buying system and budget permit, use a holdout or controlled split to test whether the advertising changed behavior. Without a control, label changes in branded demand or direct traffic as directional rather than causal.

    For Threads, the crucial diagnostic is placement-level delivery. A campaign that performed well across Meta does not establish that Threads worked if Facebook or Instagram delivered most of the impressions. Compare the Threads result with the benchmark chosen before launch, and keep differences in audience, creative, and optimization settings visible.

    For ChatGPT, the minimum evidence is verified delivery under the contracted impression definition. OpenAI has indicated that follow-up questions about sponsored products could become an engagement signal, but that possibility is not a current performance guarantee. Do not make a future field the cornerstone of today’s business case. If follow-up reporting becomes available, document its definition, privacy treatment, and relationship to downstream action before using it as a KPI.

    Do not compare raw click-through rates across a feed ad and a unit beneath an AI answer as if the interfaces were interchangeable. Position, user task, billing, and available actions all differ. Compare each surface with the goal and benchmark assigned to that surface. Then compare investment decisions using business value and confidence in the evidence.

    Make trust and brand safety part of campaign acceptance

    A transparent safety gateway filters a sponsored content tile before it enters a field of conversational speech bubbles.

    An ad beside a generated answer carries a different trust burden from an ad in a familiar feed. The assistant is responding directly to the user’s words, so commercial influence can be mistaken for neutral help unless the boundary is obvious. Google’s reluctance to monetize Gemini reflects concern that advertising could compromise unbiased recommendations and user trust. OpenAI’s initial design addresses the same tension by marking sponsored units and separating them at the bottom of responses.

    Turn that principle into acceptance criteria. Before launch:

    • Review the actual unit or a faithful preview and confirm that the sponsorship label is visible without extra interaction.
    • Reject creative that imitates the assistant’s voice or implies that the organic answer endorsed the advertiser.
    • Check that every factual claim in the ad is supported on the destination page and remains accurate when removed from the surrounding conversation.
    • Document prohibited adjacencies, sensitive categories, escalation contacts, and the remedy available after an unsuitable placement.
    • Capture a dated preview or screenshot with the approved copy, destination, disclosure, and platform version so later changes can be audited.
    • For regulated or high-consequence claims, route the complete placement context through the appropriate legal or compliance review rather than submitting isolated ad copy.

    Threads offers a more familiar control layer. Meta is extending third-party brand-safety verification used on Facebook and Instagram to Threads. Confirm which verification provider, report, market, and placement your campaign can use. The existence of a verification program does not prove that it covers every impression in your specific setup.

    A trust failure also damages measurement. If users cannot tell whether a recommendation is paid, engagement may reflect mistaken endorsement rather than persuasive advertising. A high interaction count under that ambiguity is not a clean signal to scale.

    Keep paid exposure separate from organic AI visibility

    Your reporting should have three lanes: paid social distribution, paid conversational exposure, and organic AI visibility. Combining them in one AI channel bucket makes every number harder to interpret.

    • Paid social distribution: Put Threads spend, impressions, placement delivery, response, and conversions here.
    • Paid conversational exposure: Put ChatGPT sponsored impressions and any defined ad interactions here. Keep the sponsorship label and placement type in the campaign record.
    • Organic AI visibility: Track whether assistants mention or cite the brand for a maintained set of relevant questions. Record the model, access tier, prompt, answer date, cited destination, and repeated observations because generated answers can vary.

    A sponsored unit beneath a ChatGPT response does not mean the brand appeared in the organic answer. An organic Gemini citation is not paid delivery. Threads reach does not establish visibility in an AI assistant. Preserve those distinctions in campaign names, analytics dimensions, dashboards, and executive reporting.

    The same boundary applies to technical optimization. JSON-LD, schema, clear entity information, and answer-focused content can be evaluated as parts of organic discovery, but the available ad plans do not establish them as levers for ChatGPT ad eligibility, Threads delivery, or a future Gemini auction. Give structured-data work its own validation and visibility objectives instead of attributing paid-media effects to it.

    At your next budget meeting, create one row for each surface and fill in four fields: whether it is buyable, the single question the spend will answer, the evidence the platform can return, and the event that would unlock more budget. Fund Threads when you have a paid-social question and placement-level measurement. Fund ChatGPT when impression-led learning is valuable enough to justify limited performance evidence. Leave Gemini out of the paid forecast until a real product changes the decision. The useful early move is not simply being first; it is knowing what the first test must prove before you buy the second.

    References

  • ChatGPT Advertising: A Practical Readiness Plan for Brands

    ChatGPT Advertising: A Practical Readiness Plan for Brands

    If ChatGPT advertising has reached your planning meeting, the immediate question isn’t whether to move budget. It is whether you can run a test that teaches you something without weakening trust. ChatGPT ads have entered the marketing landscape, but an emerging ad surface should be treated as an experiment, not a finished channel.

    You don’t need a confident prediction about every format, targeting option, or pricing model. You need a campaign brief that survives uncertainty: a defined user decision, a verifiable claim, a useful destination, independent measurement, and rules for stopping or scaling. Build those pieces now and you can evaluate actual inventory on its merits when it is available to you.

    Do not treat ChatGPT advertising as another search campaign

    A conventional search campaign often starts with a query, a keyword set, and a landing page. A conversational environment starts with a person trying to resolve something. They may be defining a problem, comparing options, checking a claim, or looking for the next step. Your planning should begin with that decision state, even if the advertising product does not offer conversation-level targeting.

    That distinction matters. Copying an existing search ad into ChatGPT may preserve the slogan while losing the reason the person would care. The better question is not, “What can we promote here?” It is, “What unresolved decision can we help the right person make?”

    Give each campaign one primary job:

    • Introduce an option the person may not know exists.
    • Clarify a point that commonly blocks evaluation.
    • Support a comparison with evidence the person can inspect.
    • Offer a practical next step after the person understands the issue.

    An ad that tries to do all of these at once will be difficult to understand and even harder to evaluate. Use a decision brief before anyone writes copy:

    • User state: What is the person deciding, and what do they probably understand already?
    • Question: What would they need answered before taking another step?
    • Claim: What useful, narrow statement can your brand make?
    • Proof: Where can the person verify that statement?
    • Disqualifier: Who should not click, sign up, or buy?
    • Next step: What is the smallest useful action after the ad?
    • Success event: What behavior would show meaningful progress rather than curiosity?

    A compact objective can follow this pattern: when a person is in a defined decision state, present a verifiable claim, send them to the page that resolves the next question, and judge the test by a qualified action. If you cannot fill in every part, the campaign is not ready for budget.

    Keep paid placement separate from AI answer visibility

    An abstract conversational interface shows a promotional tile separated by a glass gap from a background layer of connected answer bubbles.

    Paid placement, an AI-generated response, and your destination page can appear within the same journey, but they do different jobs. Treating them as one system leads to two costly assumptions: that buying an ad will change what the AI says, or that an organic brand mention means the advertising worked.

    SurfacePrimary jobWhat you can prepareCommon mistake
    Paid placementEarn attention and invite a relevant next stepA narrow claim, suitable creative, budget limits, and explicit targeting assumptionsPresenting the ad as if the assistant independently recommended the brand
    AI-generated responseHelp the person understand or resolve the questionClear content, consistent entity facts, current evidence, and valid structured dataAssuming media spend controls or improves the generated answer
    Destination pageProve the claim and move the decision forwardA direct answer, supporting evidence, relevant limitations, a clear action, and measurementRepeating the ad without resolving the person’s next question

    This separation is especially important for SEO, AEO, and GEO teams. Advertising can purchase an opportunity to be seen where inventory is offered. Organic AI visibility depends on whether systems can find, interpret, and use information about your brand. Neither outcome guarantees the other.

    Run a message-parity audit before launch. Compare the proposed ad with the landing page, product documentation, policies, sales materials, and structured data. The same factual claim should have the same scope everywhere. If the ad says a capability is available, the destination should state what it does, who can use it, what conditions apply, and when the information was last reviewed.

    Create a claim register with these fields:

    • The exact claim in plain language.
    • The page or record that substantiates it.
    • The owner responsible for keeping it current.
    • The markets, products, plans, or users to which it applies.
    • The event that should trigger another review, such as a pricing, policy, or feature change.

    Use JSON-LD to describe facts that are also supported by the visible page. Choose schema types and properties that match the page’s real subject. Do not create markup that broadens a claim, hides an important limitation, or describes an offer the visitor cannot verify. Structured data can improve clarity and consistency; it does not turn an unsupported statement into truth or guarantee inclusion in an AI response.

    Build a launch-ready test before you buy media

    Emerging advertising products can change while teams are still planning around them. Keep the stable parts of your strategy separate from platform-dependent details. Your audience problem, evidence, landing experience, economics, and business outcome belong in the stable layer. Inventory, placement, targeting controls, reporting fields, and billing belong in the platform layer and must be verified at activation.

    1. Write a falsifiable test thesis. Use the form: if a defined user state receives a defined claim and next step, a named qualified outcome should improve relative to a documented baseline. Avoid objectives such as creating buzz or seeing what happens.
    2. Record what is known and unknown about the ad product. Verify available placements, sponsorship labels, audience or contextual controls, geographic and language coverage, exclusions, billing, reporting, data use, and content restrictions in the actual buying materials. Do not turn a screenshot, announcement, or assumption into a media plan.
    3. Build the destination around the next question. Its opening should confirm that the visitor is in the right place. Put evidence close to the claim, state relevant constraints, and offer an action proportionate to the person’s readiness. A comparison visitor may need specifications or documentation before a sales form.
    4. Create variants that test one meaningful difference at a time. You might test the framing of the problem, the supporting proof, or the proposed next step. If the claim, audience, destination, and call to action all change together, the result will not tell you what caused the difference.
    5. Instrument the full journey. Use a dedicated landing URL or consistent campaign parameters where supported. Confirm that analytics records the intended onsite action and that your CRM or commerce system retains the acquisition source. Test the path yourself from landing visit to recorded outcome before approving spend.
    6. Set decision rules in advance. Name the metric that permits scaling, the spend ceiling, the conditions that require a pause, and the person authorized to make each decision. This prevents a novelty-driven campaign from continuing merely because it produced traffic.
    7. Run an adversarial review. Ask someone outside the campaign team to read the ad and destination as a skeptical prospect. They should be able to identify who the offer is for, what is being claimed, where the evidence sits, what happens next, and what important limitation applies.

    Keep this material in a reusable launch packet. If the available ChatGPT inventory does not fit your decision state, measurement needs, risk limits, or economics, you can decline the test without discarding the strategic work. The same brief can guide organic content, another paid channel, or a later campaign when the product is a better fit.

    Set trust guardrails and measurement rules together

    An unbranded product moves through checkpoints represented by a magnifying lens, a balanced scale, and an independent sensor before reaching an abstract conversational screen.

    Protect the boundary between assistance and promotion

    A conversational interface can feel advisory. When a paid message appears close to a generated response, a person may infer a relationship between them even when the placement is separate. Your creative should not intensify that ambiguity.

    • Do not imitate the assistant’s voice in a way that hides the commercial role of the message.
    • Do not imply that ChatGPT independently selected, verified, ranked, or endorsed the product unless that precise claim is demonstrably true and permitted.
    • Make the sponsor identity and destination clear within the controls available to the advertiser.
    • Use claim language that remains accurate outside an ideal context. Avoid an unqualified best, guaranteed, safe, or suitable claim when the destination cannot substantiate it.
    • Do not assume that private conversational details are available for targeting. Treat every claim about contextual signals, audience creation, retention, and advertiser access as unverified until the platform documents it.
    • Route campaigns involving regulated or sensitive decisions through qualified legal, privacy, and compliance review before targeting or creative goes live.

    Add an adjacency plan as well. Decide what your team will do if the ad appears near an unsuitable response, if a user interprets the placement as an endorsement, or if a product change makes the claim stale. The plan should identify who can pause the campaign, who captures evidence, who contacts the platform, and who corrects the destination or structured data. Waiting for an incident to establish ownership turns a manageable problem into a prolonged one.

    Measure qualified decisions, not the novelty of the click

    Early curiosity can produce visits without producing durable demand. A click therefore tells you that the placement earned attention, not that it reached the right person or changed a business outcome. Build a measurement ladder that distinguishes those stages:

    • Delivery: Did the platform serve the campaign as configured?
    • Qualified visit: Did the visitor reach the intended page and meet your predefined relevance conditions?
    • Decision behavior: Did the visitor inspect documentation, compare an option, check compatibility, begin a suitable workflow, or complete another meaningful step?
    • Business outcome: Did the journey produce a qualified lead, purchase, activation, or other result that the organization already recognizes?
    • Outcome quality: Did those results remain useful after the initial conversion, or did they produce avoidable cancellations, disqualification, support burden, or low-value activity?

    Use platform reporting to understand delivery, your first-party analytics to understand onsite behavior, and your CRM or commerce records to understand downstream outcomes. If those systems disagree, investigate the definition and handoff before changing the campaign. A dashboard that blends incompatible events can look precise while answering the wrong question.

    Where a credible comparison is possible, evaluate exposed and unexposed groups or use another controlled design. If the platform does not support that design, run a bounded pilot, compare it with a relevant baseline, document competing explanations, and label the conclusion as directional. Do not present last-click attribution as proof that the ad caused the result.

    Scale only when business outcome and outcome quality move in the same direction. If clicks rise while qualified actions stay flat, the answer is not automatically more spend. Revisit the user state, message, placement, and destination. If conversions rise but quality declines, tighten qualification before expanding reach.

    Key takeaways

    • Treat ChatGPT advertising as a bounded experiment until its available formats, controls, economics, and reporting fit your use case.
    • Plan around the person’s unresolved decision, not around a recycled search ad or a broad desire for awareness.
    • Keep paid placement, organic AI visibility, and landing-page conversion separate in your strategy and measurement.
    • Maintain message parity across ad copy, visible content, product documentation, policies, and JSON-LD.
    • Verify platform capabilities in the real buying materials instead of assuming conversational context is targetable or visible to advertisers.
    • Predefine evidence, spend limits, stop conditions, trust guardrails, and qualified outcomes before launch.

    Your next move is a readiness review, not a forecast. Put the decision brief, claim register, destination, tracking map, and risk rules into a shared launch packet. When suitable inventory is available to your team, you will be able to run a controlled test, learn from it, and scale only when the result survives both a trust check and a business check.

    References

  • Brand Discovery Beyond Search: Organic and Paid Channels

    Brand Discovery Beyond Search: Organic and Paid Channels

    If your brand ranks for useful queries but still fails to make the buyer’s shortlist, another position in Google may not solve the problem. By the time many people reach a conventional search result, they have already encountered names, checked public reactions, watched demonstrations and asked an AI assistant to reduce the options.

    You need a discovery system that works across that entire decision chain. The practical job is to coordinate earned authority, social validation, AI-readable owned content and emerging paid placements without treating every platform as another place to publish the same message.

    Key takeaways

    • Map the questions and uncertainties that move a buyer toward a decision, then assign each one to the channel best suited to resolve it.
    • Use digital PR to establish credible evidence, social platforms to demonstrate and discuss it, and owned content to preserve the complete, accurate version.
    • Treat AI visibility as a distinct outcome. A brand mention, a citation, an accurate description and a recommendation are not interchangeable.
    • Keep conversational advertising separate from organic AI authority. A relevant sponsored placement can create discovery, but it does not mean the assistant endorsed the advertiser.
    • Measure movement across the journey with tagged links, assisted paths, branded demand, repeatable AI checks and qualified actions. Last-click conversions alone will undervalue discovery channels.

    Map the decision chain, not a list of platforms

    A modern discovery journey can begin with a short demonstration, move into a community discussion, continue through a long-form explanation and end with an AI-generated comparison. People are already moving from TikTok to Reddit, YouTube and AI summaries as they form and validate preferences. Google may still participate, but it no longer owns every stage.

    This changes the planning unit. A channel plan starts with places: a TikTok plan, a Reddit plan or an AI search plan. A discovery plan starts with a buyer’s unresolved question. That distinction prevents a common failure in which a brand maintains many accounts but provides no connected path from recognition to confidence.

    Build a decision-question inventory before you choose formats. For each meaningful audience and use case, record:

    • The trigger: What happened that made the person look for an answer now?
    • The question: What would that person actually type, say or ask another person?
    • The uncertainty: What could stop the decision – cost, complexity, compatibility, risk, proof or trust?
    • The required evidence: What would resolve that uncertainty: a demonstration, an independent mention, a technical specification, a customer perspective or a clear limitation?
    • The likely surface: Where would the person expect to find that kind of evidence?
    • The next useful action: What should become easier after the evidence is consumed?

    Organize this inventory around uncertainty rather than generic funnel stages. Someone searching Reddit for hidden drawbacks and someone watching a YouTube setup walkthrough may both be close to a purchase, but they need different proof. Sending both people to the same promotional landing page ignores the reason they chose those surfaces.

    Then audit whether your brand appears when those questions are explored. Search the platforms directly, review relevant community discussions and ask representative questions in the AI products your audience uses. Record absence as well as inaccuracy. An absent brand has a distribution problem; a misdescribed brand may have an entity, evidence or consistency problem. Those require different fixes.

    Give each discovery channel a distinct job

    An unbranded product passes through separate stations for conversation, demonstration, validation, information synthesis and final selection.

    Cross-channel visibility works when each surface contributes something the others cannot. It breaks when a campaign simply copies the same claim into a press release, social caption, community reply and landing page.

    SurfacePrimary jobUseful assetFailure to avoid
    Digital PREstablish independent authorityVerifiable finding, expert explanation, original resource or documented developmentTreating coverage as a link transaction with no durable evidence
    TikTok and short-form videoCreate recognition and make an idea tangibleFocused demonstration, before-and-after process or concise explanationCompressing away the conditions and limitations that make the claim credible
    Reddit and other communitiesExpose real objections, tradeoffs and languageTransparent participation, useful answers and links only when they genuinely resolve the questionAstroturfing, disguised promotion or inserting the brand into unrelated discussions
    YouTube and long-form videoReduce uncertainty through depthWalkthrough, comparison method, implementation explanation or detailed demonstrationUsing a long introduction to delay the answer the viewer came for
    Owned websitePreserve the canonical factsClear product, service, use-case, methodology, limitation and evidence pagesPublishing vague claims that third parties and AI systems cannot verify
    AI discovery surfacesSynthesize options and explain relevanceConsistent entity information, answerable content and corroborated claimsAssuming schema or repeated brand copy can manufacture authority
    Paid discoveryPlace a relevant option in an active decision contextIntent-matched message and a landing experience that continues the questionTreating placement as proof of endorsement

    Start with evidence that can travel

    Digital PR is most valuable here as an authority layer, not as a temporary traffic event. Credible third-party coverage can turn a brand assertion into something audiences, creators and machines can evaluate outside the brand’s own website. Social discovery then gives that evidence context: people can see how it works, question it and decide whether it applies to them. That combination of earned credibility and platform-native validation is stronger than reach on either side alone.

    For every campaign claim, create a compact evidence packet that other teams can use without changing its meaning:

    • The exact claim in plain language.
    • The evidence supporting it and where that evidence lives.
    • The method, scope or conditions needed to interpret it correctly.
    • The limitations or cases where the claim does not apply.
    • The approved entity names, product names and descriptions.
    • The canonical URL that holds the complete version.
    • Visual or demonstrative material that shows the claim rather than merely repeating it.

    This packet prevents narrative drift. The PR team can pitch the defensible development. A video producer can demonstrate it. A community manager can answer the difficult question without improvising. The SEO and content teams can maintain a canonical explanation that remains useful after the campaign ends.

    Make owned content easy to interpret and hard to misquote

    Your canonical page should identify the entity, intended audience, use case, evidence, important limitations and next action without forcing a reader to reconstruct them from promotional language. Put the answer near the question it resolves. Use descriptive headings, stable terminology and internal links that explain related entities and concepts.

    Add appropriate JSON-LD only when it accurately represents the visible page. Organization, product, service, person and other entity markup can clarify relationships, but structured data cannot replace missing evidence or create third-party agreement. Treat schema as a consistency layer, not a reputation shortcut. If the visible copy, markup and external descriptions disagree, fix the underlying facts before adding more markup.

    Portability also requires restraint. A short video should lead with the demonstration, not attempt to contain every technical caveat. A Reddit response should answer the thread’s actual concern, not paste the campaign slogan. A YouTube explanation can carry the method and tradeoffs. The canonical page holds the complete record. The story remains consistent while the form changes to fit the reason someone uses each platform.

    Use conversational ads as paid context, not borrowed authority

    A person consults a glowing AI-style assistant surrounded by reference materials and community input, with a separate unbranded promotional tile nearby.

    Conversational advertising could become an important discovery channel because the placement can appear while a person is actively defining a need or comparing options. That is closer to a live decision context than a demographic feed placement. It is also easy to misunderstand.

    ChatGPT’s announced U.S. test was designed to put clearly labeled, relevant sponsored options at the bottom of responses. The planned audience included logged-in adults using the free tier or the $8-per-month ChatGPT Go plan. Pro, Business and Enterprise plans were set to remain ad-free, and users under 18 were excluded. Politics, health and mental-health conversations were also excluded from placement.

    Those are announced test conditions, not a permanent media specification. Availability, targeting, reporting, pricing and policy can change as the format is tested. Do not build a forecast that assumes this inventory is broadly available or that its initial rules will remain fixed. Verify the current buying interface, eligible audience, exclusions and measurement options before assigning budget.

    The most important boundary is answer independence. OpenAI says the advertisements will not affect the assistant’s response, conversation data will not be sold to advertisers, and users will be able to inspect why an ad appeared, dismiss it, disable personalization or clear ad-related data. The practical consequence is simple: an advertiser must not present the placement as an organic recommendation from ChatGPT.

    A conversational ad and an AI recommendation perform different jobs:

    • The unsponsored answer reflects the assistant’s generated response to the conversation.
    • The sponsored placement gives an eligible advertiser visibility beside that response when the system considers the offer relevant.
    • A citation points to material used or surfaced as support.
    • A brand mention shows recognition, but does not necessarily indicate preference or authority.

    Keep these outcomes separate in creative, reporting and executive updates. If a sponsored placement produces visits, report paid conversational discovery. Do not add those impressions to an organic AI visibility score or use them as evidence that the brand has become more authoritative in generated answers.

    Build an answer-adjacent campaign

    The strongest initial use case is likely to be a product or service that helps with the decision under discussion. Plan around the decision context rather than a broad audience label. A useful brief should state the question being asked, the unresolved need, the offer that genuinely fits and the reason the landing page is the logical next step.

    • Match the message to the conversation: Respond to the likely need instead of repeating a general brand line.
    • Continue the answer: Send the person to a page that immediately addresses the use case, comparison or constraint implied by the ad.
    • Show your status clearly: Do not mimic an assistant response, a citation or an independent recommendation.
    • Respect exclusions: Confirm topic, age, geography and plan eligibility before estimating reach.
    • Audit claims: Make sure every ad promise is supported on the destination page and remains consistent with your canonical facts.
    • Preserve choice: Do not design copy that obscures personalization, dismissal or privacy controls.

    Before buying, ask how conversational relevance is determined, what controls exist for placement and exclusions, which reporting dimensions are available, how personalization works, what data the advertiser receives and how conversions are attributed. The announced test does not establish all of those operational details. If the buying product cannot answer them, treat the channel as experimental and cap its role accordingly.

    Measure the journey, then launch a connected campaign

    Discovery channels often look weak in last-click reports because their work happens before the final visit. That does not make every impression valuable. It means you need measures that distinguish exposure, belief, machine visibility and commercial action.

    Use a layered scorecard

    Track the same decision question across the journey, then group signals by the job they perform:

    • Discovery: Relevant earned placements, on-platform search visibility, qualified video views, participation in useful community discussions, paid conversational impressions and new branded queries.
    • Authority: Independent mentions, links or citations from credible coverage, accurate reuse of your evidence and inclusion in serious category discussions.
    • Belief: Questions answered, substantive comments, saves, repeat brand mentions, comparison inclusion and reductions in recurring objections.
    • AI visibility: Brand mentions, cited pages, factual accuracy, recommendation context and the use cases with which the brand is associated.
    • Action: Engaged visits, returning direct traffic, assisted conversions, qualified enquiries, trials, purchases or another outcome tied to the actual business model.

    Do not collapse these into a single visibility score. A brand can be frequently mentioned and inaccurately described. It can be cited but not recommended. It can receive paid impressions while remaining absent from unsponsored answers. Keeping the dimensions separate tells you whether to improve distribution, authority, entity clarity, product fit or conversion design.

    AI checks need a reproducible log. Use a fixed set of real decision questions from your inventory. For each check, record the exact prompt, AI product or model, date, region, account state, personalization state, response, cited URLs and whether the brand was mentioned accurately. Repeat the checks under comparable conditions. A favorable screenshot from an isolated conversation is an anecdote, not a trend.

    For traffic and conversion analysis, tag every link you control with consistent campaign and content identifiers. Preserve referring pages where analytics allow it. Compare new and returning visitors, review assisted paths, monitor branded demand and include a self-reported discovery question when the buying journey makes that practical. If your volume supports a valid holdout, use it to test whether paid distribution creates incremental action rather than claiming conversions that would have happened anyway.

    Launch from a decision, not a content calendar

    Use this sequence for the next campaign:

    1. Select a consequential decision question. Choose one that sits close enough to commercial value to justify coordinated work and broad enough to appear on more than one discovery surface.
    2. Identify the belief gap. Write down what the audience would need to see, understand or verify before your brand becomes a credible option.
    3. Assemble defensible evidence. Reject claims that cannot survive independent scrutiny, community questions or a detailed comparison.
    4. Publish the canonical explanation. Make the entity, use case, proof, limitations and next action explicit. Align visible content, metadata and appropriate structured data.
    5. Create native expressions. Turn the same evidence into a demonstration, a deeper explanation, a transparent community response and a PR angle. Preserve the claim while adapting the format.
    6. Distribute by channel role. Use earned outreach for authority, social search for demonstration and validation, owned pages for completeness, and paid media for relevant additional reach.
    7. Separate paid and organic AI outcomes. Label conversational ad results as paid discovery and audit unsponsored mentions independently.
    8. Review the full path. At campaign checkpoints, compare discovery, authority, belief, AI visibility and action. Fund the channels that remove a documented decision barrier, not merely those that generate the largest surface-level count.

    Before approving another isolated channel campaign, choose the decision question it is meant to change and identify the other surfaces a buyer will use to verify the answer. Connect those surfaces around defensible evidence. That is how an emerging channel becomes part of a durable discovery system instead of another disconnected experiment.

    References

  • AdSense Revenue Declines: How to Diagnose the Real Cause

    AdSense Revenue Declines: How to Diagnose the Real Cause

    Your AdSense revenue has fallen sharply, but your traffic looks normal. The expensive mistake is to assume that SEO is responsible and immediately change your content, schema, ad layout, or site architecture. Those changes can erase the evidence you need and introduce a second problem.

    You can usually narrow the cause by comparing pageviews, ad impressions, page RPM, and eCPM across the same sites, countries, devices, and ad units. The goal is not to explain every dollar immediately. It is to identify whether traffic, ad delivery, advertiser demand, or reporting broke first.

    First, identify which number actually broke

    An icon-based diagnostic pathway separates website activity, ad delivery, advertiser demand, and reporting problems across devices and regions.

    Revenue is the result, not the diagnosis. Page RPM tells you how much revenue you earned per thousand pageviews. eCPM tells you how much revenue was generated per thousand ad impressions. A fall in either metric matters, but the surrounding numbers tell you where to look.

    Start with equivalent, complete reporting periods. Do not compare a partial day with a completed day. Then examine the metrics in this order:

    1. Independent traffic: Check pageviews or sessions outside AdSense. This establishes whether fewer people actually reached the site.
    2. Ad impressions: Compare the change in ad impressions with the change in pageviews. A much larger impression decline points toward serving, rendering, consent, or placement problems.
    3. Page RPM: If traffic is stable but page RPM collapses, the problem is monetization rather than the number of visits alone.
    4. eCPM: If ad impressions remain comparatively stable while eCPM falls, weaker auction pricing or a change in traffic mix becomes more plausible.
    5. Rendered ads: Open representative pages and confirm whether the expected ad slots appear. Missing ads are operational evidence, not merely a dashboard fluctuation.

    This distinction mattered during a severe episode that began late on January 14 and intensified on January 15. Publishers reported eCPM and page RPM declines of up to 70%, simultaneous effects across multiple sites, and ads partially or completely disappearing. Google also acknowledged systemic Google Ad Manager problems involving declining AdX match rates and reduced delivery from Google Ads and DV360, with web and mobile web display inventory particularly affected.

    That acknowledgement is important, but it does not prove that the Ad Manager incident explained every AdSense account’s decline. Your own metric sequence still matters. A platform incident can coexist with a traffic loss, a local implementation fault, or a reporting anomaly.

    Pattern you seeMost plausible problem areaWhat to check next
    Traffic and ad impressions fall together while page RPM is comparatively stableAudience acquisition or search visibilityAnalytics, server logs, landing pages, and Search Console performance
    Traffic is stable but ad impressions fall or ads disappearAd serving, rendering, consent, policy, or implementationLive pages, affected templates, ad code, consent states, policy notices, and recent deployments
    Traffic and ad impressions are stable but eCPM fallsAuction demand, match rate, or traffic-mix changeCountry, device, site, and ad-unit segments
    Revenue changes without corresponding movement in the underlying metricsReporting delay or anomalyPlatform notices and whether reported figures are subsequently revised
    Traffic, impressions, and RPM all fallMore than one problem may be presentDiagnose the traffic and monetization changes separately

    Use the blast radius to separate local faults from platform failures

    The first useful question is not simply, “How much revenue did we lose?” Ask, “Where did the decline begin, and where did it not happen?” A single account-wide average can hide the answer.

    1. Split by site. If unrelated sites in the same account decline at the same time, a shared platform or demand problem becomes more plausible. If only one site changes, inspect that site’s deployments, templates, audience, and policy status.
    2. Split by country. Advertising demand and delivery can move differently by market. A global average may therefore make a regional problem look universal.
    3. Split by device. A mobile-only decline points toward different templates, consent behavior, viewport rendering, or mobile-web delivery.
    4. Split by ad unit or placement. A failure concentrated in one unit is a different problem from an account-wide eCPM decline.
    5. Compare the onset time. Metrics that change together are more likely to share a cause. Changes beginning at different times should be treated as separate events until the data connects them.

    Regional differences during the January episode show why this segmentation matters. Self-reported losses for U.S.-focused sites ranged from 35% to 70%, while selected European country domains reported declines ranging from 63% to 90%. These were publisher reports, not official performance benchmarks, so they should not be used to predict your expected loss. They do demonstrate that a single blended percentage can conceal materially different market behavior.

    Blast-radius analysis produces probabilities, not certainty. Several sites failing simultaneously makes a shared dependency more plausible, but it does not rule out a common change made across those sites. Check shared consent management, ad code, deployment pipelines, CDN rules, and account settings before concluding that the platform is solely responsible.

    Do not confuse monetization failure with an SEO or AI-search loss

    A search ranking change reduces revenue by reducing or changing visits. It does not directly explain why the same pageviews suddenly produce far fewer ad impressions or why previously visible ad slots stop rendering.

    An unconfirmed Google Search ranking update coincided with the reported AdSense decline. That timing creates a reasonable hypothesis, but timing alone is not causation. Test it with independent traffic data:

    • If Search Console clicks and analytics traffic decline while page RPM remains stable, investigate search visibility and landing-page losses.
    • If traffic remains stable while page RPM or ad impressions collapse, prioritize monetization and serving diagnostics.
    • If traffic and page RPM decline together, maintain two incident tracks. Fixing or explaining one does not automatically explain the other.
    • If organic traffic volume is stable but eCPM changes by country or device, examine audience mix before blaming rankings.

    AI Overviews were also raised as a possible indirect factor because those search-result experiences displayed no ads during the period being discussed. However, no causal connection was established between AI Overviews and the sudden publisher revenue collapse. Treat AI-search displacement as a longer-term distribution question unless your referral and landing-page data show that it caused the traffic change in front of you.

    The same discipline applies to AEO, GEO, and structured data. Schema can help machines interpret content, and answer-focused optimization may improve discoverability, but neither can repair a falling AdX match rate or restore an ad slot that is not being served. Measure AI visibility, AI referrals, organic clicks, ad delivery, and revenue as separate layers. Connect them only when the data supports the connection.

    Respond without destroying the evidence

    An analyst documents untouched website analytics under a transparent cover while modification tools remain set aside.

    Broad changes made during an unexplained incident create confounding variables. If you alter ad density, templates, consent logic, content, and internal links at once, you will not know whether the original problem recovered or your intervention changed the result.

    1. Record the onset. Note when the decline first appears and which account, site, country, device, and ad-unit views show it.
    2. Preserve the baseline. Export or capture the relevant pageview, ad-impression, page RPM, eCPM, and revenue reports before dashboard values or date ranges change.
    3. Verify traffic independently. Use analytics, server logs, and Search Console rather than relying on an AdSense pageview metric alone.
    4. Test representative pages. Check more than the homepage. Include major templates, mobile and desktop layouts, important countries you can validly test, and the consent states your site supports.
    5. Review shared dependencies. Inspect policy notices, consent-management changes, ads.txt changes, ad-code changes, recent releases, caching, CDN behavior, and security rules that could prevent requests or rendering.
    6. Check platform communications. Match any acknowledged incident to your affected product, inventory type, geography, and onset time. A status notice is evidence only when its scope fits your metrics.
    7. Change one layer at a time. If the evidence identifies a local fault, make the smallest relevant correction and annotate it. Keep SEO and content changes out of an ad-serving test.

    Communicate the same distinction internally. “Revenue is down” is not an operational diagnosis. A useful incident note says, for example, that traffic is stable, mobile-web ad impressions fell across several sites, and no site deployment preceded the change. That statement tells technical, editorial, and financial teams what is known without pretending the cause is settled.

    If the decline affects payroll, debt, tax payments, or another consequential financial decision, work from confirmed cash and account data rather than an assumed recovery. An accountant or financial adviser should review any irreversible response to a temporary or disputed dashboard event.

    Plan for a decline that does not fully recover

    An overnight incident and a structural revenue decline require different responses. The first calls for controlled diagnosis. The second calls for a business-model decision.

    Some publishers reported losses of 70% to 80% extending back to mid-2025. Those reports do not prove that traditional content sites are being systematically deprioritized, and they should not be treated as a forecast for every publisher. They do show why waiting for a dashboard to return to an old high can become a strategy of its own.

    If your decline persists after serving and reporting issues are excluded, build the plan from your observed economics:

    • Chart RPM by segment, not just account. Identify which sites, countries, devices, templates, and topics still produce sustainable returns.
    • Map concentration risk. Record how much of the site’s operation depends on one ad platform, one search channel, or one high-value audience segment.
    • Use a conservative operating case. Budget from revenue you can verify, not from an assumption that a previous RPM will return.
    • Evaluate adjacent revenue models against audience intent. Sponsorships, subscriptions, services, commerce, or affiliate revenue are useful only when they fit why the audience visits. Adding an unrelated monetization layer can damage trust without replacing the lost income.
    • Build direct audience access. Email subscriptions, repeat visits, and recognizable brand demand reduce dependence on any single discovery interface, including traditional search and AI-generated answers.
    • Track AI discovery separately. Measure citations, referral traffic, branded searches, conversions, and revenue where possible. AI visibility is not a business outcome until you can connect it to audience or commercial value.

    Key takeaways

    • Stable traffic with falling ad impressions points toward serving or rendering before it points toward SEO.
    • Stable impressions with falling eCPM makes auction demand or audience mix more plausible.
    • Simultaneous declines across unrelated sites suggest a shared dependency, but they do not prove a platform-wide cause.
    • A coincident search update or AI feature is a hypothesis until traffic and landing-page data connect it to the loss.
    • Preserve reports and change one layer at a time so that recovery remains measurable.
    • A persistent decline needs a lower-risk revenue plan, not indefinite dependence on a rebound.

    Your next move is to export the affected metrics and write a one-sentence diagnosis that the numbers support. If you cannot yet say whether traffic, impressions, or eCPM broke first, do not redesign the site. Find that missing comparison. Once the failure is classified, you can act on the correct system instead of spending an ad-delivery incident on an SEO fix.

    References

  • Paid Media Automation: A Control Plan for New Features

    Paid Media Automation: A Control Plan for New Features

    Your ad platforms can now pace an entire campaign budget, infer what viewers care about, optimize toward new customers, and generate more of the ad itself. The hard part is no longer finding automation. It is deciding what to delegate without handing over the commercial judgment that makes the campaign worth running.

    If you are preparing a launch, promotion, audience test, or cross-platform migration, use one operating rule: automate a bounded task, give the system a measurable objective, and retain an independent check on spend and business value. The latest Google, YouTube, and Microsoft Advertising changes make that division of responsibility more important, not less.

    Key takeaways

    • Use campaign-total budgets for genuinely fixed flights. The feature solves pacing work; it does not decide whether the campaign deserves more money.
    • Match the targeting signal to the question. Interest targeting identifies people who may care, contextual targeting chooses relevant environments, and customer-acquisition optimization changes how conversions are valued.
    • Define a new customer before asking an algorithm to find one. Identity rules, lookback logic, deduplication, and the value premium all affect what the system learns.
    • Treat generated creative and easier imports as workflow accelerators. Final URLs, tracking, claims, images, conversion goals, and brand compliance still need human review.
    • Intervene when the evidence identifies a constraint. Lost share from budget, lost share from rank, poor conversion quality, and faulty customer classification require different responses.

    Automate budget pacing only when the cap and end date are real

    Google’s campaign-total budget gives you one amount for a defined flight and lets the system optimize spending across the available days or weeks. The setting, previously associated with Performance Max, has moved into open beta for Search and Shopping campaigns. It is designed to use the allocated budget by the campaign’s conclusion, removing the need to keep rewriting daily budgets during a short promotion.

    That makes it a strong fit for a sale, product launch, event window, or controlled test with an immovable end date. It is a weaker fit for evergreen activity whose budget changes whenever demand, inventory, margin, or lead capacity changes. In an evergreen campaign, a daily budget remains a useful recurring control. In a fixed flight, repeatedly adjusting that daily number can become unnecessary operational noise.

    Do not confuse automated pacing with an outcome guarantee. The platform can decide when to spend the authorized amount, but it cannot know whether your margin target, stock position, sales capacity, or cash-flow limit has changed unless those constraints are represented in the campaign or acted on by your team.

    Before enabling a campaign-total budget, write a short budget brief and have another person verify the amount, currency, dates, and time zone. This is a financial control, not bureaucracy: the setting authorizes the system to use the full campaign total, so an incorrect amount or end date can turn a setup mistake into real spend.

    1. State the business cap. Record the maximum media amount approved for this campaign, separate from creative, agency, production, or platform costs that are not represented by the setting.
    2. Confirm the flight. Check the start date, end date, time zone, landing-page availability, promotional terms, and any inventory or lead-capacity constraint.
    3. Name one primary outcome. Decide whether the campaign is being judged on qualified traffic, purchases, leads, new customers, or another observable result. Do not let a secondary engagement metric silently become the goal.
    4. Set a decision threshold. Document the cost, return, or quality condition that would justify pausing, continuing, or expanding the campaign. The platform’s ability to spend the budget does not answer that decision.
    5. Schedule evidence-based checkpoints. Review after delivery begins, around the middle of the flight, and early enough before the end to correct a tracking or eligibility problem. Do not force spending into equal daily slices merely because the average planned pace is the total divided by the number of campaign days.

    A promotional example associated with the rollout recorded a 16% increase in website traffic while remaining within budget and without a reported decline in ROAS. That is useful evidence that automated pacing can support a fixed promotion, but it is one retailer’s result, not a forecast for your account. Use it to validate the operating model, not to set an expected lift.

    Choose a targeting signal based on the job it must do

    An operator routes three distinct streams of audience signals toward visual symbols for awareness, consideration, and purchase tasks.

    Audience automation often gets discussed as though every signal were another way to find the same person. It is not. An inferred interest, the context of a page, and a customer’s relationship with your business answer different questions. Selecting one because it is newly available can produce a technically valid campaign with no coherent targeting logic.

    SignalQuestion it answersMain limitationWhat you should test
    YouTube interest targetingWho is likely to care about this subject?Interest is inferred and does not prove current purchase intent.Whether one audience hypothesis improves the business outcome while creative and offer remain comparable.
    Microsoft contextual targetingWhere should this message appear?A relevant category or placement does not guarantee that every viewer is a prospect.Performance and quality by content category or reported placement.
    New-customer acquisition optimizationWhich conversions should receive more value?Bad customer classification teaches the system the wrong economics.Incremental new-customer volume, acquisition cost, and downstream customer quality.

    YouTube Promotions has expanded beyond broad demographic controls by adding interest categories derived from aggregated, anonymized viewing and search patterns across Google services. Someone who repeatedly watches cooking videos and searches for recipes, for example, may fall into a Food & Dining interest category. The initial rollout was desktop-only, so confirm that the option is present in the account and workflow you intend to use.

    The important word is interest. This signal is more expressive than age, gender, or location alone, but it is still an inference. It does not mean the viewer declared an identity, searched for your product, or is ready to buy. Use it to test a reasoned audience hypothesis such as, “People who consistently engage with this subject will respond to this format.” Do not translate the category into a stronger claim than the data supports.

    1. Write the hypothesis before choosing the category. Name the audience, the expected need, and why the video addresses it.
    2. Keep the proposition recognizable across variations. If you change the audience, offer, opening, format, and landing page simultaneously, you will not know what produced the difference.
    3. Choose a downstream measure. Views can show delivery, but subscriber quality, qualified site activity, leads, purchases, or another available business signal should determine whether the audience is useful.
    4. Check the audience-to-creative match. A broad interest category usually needs a message that is immediately legible to that interest. A highly specialized message may require a narrower hypothesis or a different targeting method.
    5. Record what the test disproves. A weak result may reject the category, the creative interpretation of that category, or the offer. It does not establish that interest-based targeting never works.

    Microsoft’s contextual option solves a different problem. Content Targeting for Audience ads is generally available for selected Microsoft-owned placements, including MSN and Outlook, and for categories such as Finance or Travel. A placement reporting view shows where ads appeared. That gives you a practical feedback loop: start with a context that makes the message sensible, inspect actual delivery, and refine the context based on qualified outcomes rather than category names alone.

    Use interest targeting when your claim is about the viewer’s recurring behavior. Use contextual targeting when the surrounding content makes the message timely or easier to understand. Use search targeting when an expressed query is central to the campaign. These signals can complement one another, but they should not be treated as interchangeable labels for “relevant audience.”

    Define customer value before activating acquisition automation

    Microsoft Performance Max now offers an open-beta customer-acquisition goal that can prioritize new customers or focus exclusively on them for purchase campaigns. You can also assign a higher conversion value to a new customer, allowing optimization to account for more than the immediate transaction.

    This is useful only if “new” and “more valuable” have defensible meanings inside your business. The algorithm cannot settle whether a returning buyer after a long absence counts as new, whether two email addresses belong to the same customer, or whether expected future purchases justify a value premium. Those are measurement and finance decisions that must exist before campaign setup.

    1. Write the identity rule. Specify which identifiers and systems distinguish an existing customer from a new one. Include how guest checkouts, duplicate records, offline purchases, and unavailable identifiers are handled.
    2. Write the time rule. Document the lookback period or business condition used to classify a customer. Keep that definition consistent in campaign reporting, CRM analysis, and financial evaluation.
    3. Write the value rule. Base any new-customer premium on incremental contribution you can support, not on an aspirational lifetime-value number. Avoid counting future value twice if part of it is already represented in the conversion value sent to the platform.
    4. Write the failure rule. Decide what happens when customer status is unknown. If classification coverage is weak, an exclusive-new-customer mode makes those errors more consequential. A prioritization approach gives you a less brittle starting point while you validate the data.
    5. Reconcile platform and business records. Compare reported new-customer conversions with CRM or commerce records. Investigate gaps before increasing the value premium or budget.

    The safest way to evaluate this goal is incrementally. Establish the existing-customer baseline, confirm that customer classification is reaching the campaign, activate the acquisition logic within a controlled scope, and compare both immediate efficiency and downstream quality. If the reported new-customer rate rises but your customer system does not show the same movement, treat the discrepancy as a measurement problem before calling it growth.

    Do not optimize exclusively for the easiest definition of “new.” A low-value first order, a duplicate account, and a genuinely incremental customer can all look similar at the conversion event. Your value model should help the system distinguish economic importance, while your later customer data determines whether the model was right.

    Use better visibility to make fewer, more precise interventions

    An analyst makes one focused adjustment to a guarded campaign network while two anomalies glow among otherwise stable automated pathways.

    Automation becomes manageable when each diagnostic leads to a different decision. Microsoft’s early-2026 Performance Max changes add share-of-voice measures, including impression share and losses attributed to budget or rank. Those distinctions matter because more budget is a rational response to only one of them.

    • Loss attributed to budget: first verify that conversion quality and unit economics are acceptable. If they are, decide whether the business cap should change. Do not let the metric authorize its own budget increase.
    • Loss attributed to rank: investigate relevance, assets, destination experience, offer, bidding inputs, and other quality constraints. Adding budget alone does not address a rank problem.
    • Little reported share loss but weak results: examine the proposition, tracking, audience logic, and conversion definition. The problem may be what happens after eligibility, not a lack of reach.
    • More traffic with unchanged customer quality: resist declaring success from delivery metrics. Return to the outcome named in the campaign brief.

    Granular measurement is also becoming easier to preserve. Microsoft now supports asset-group URL options and tracking templates, while Google imports can carry more flexible asset groups and as many as 50 search themes. An ineligible image or auto-generated logo no longer has to block the rest of an asset group from importing. That reduces migration friction, but it also makes post-import quality assurance more important: a successful import means the objects moved, not that every object is eligible, correctly tracked, or strategically equivalent.

    Review imported campaigns in the destination platform. Check campaign goals, budget type, customer-acquisition settings, final URLs, tracking templates, search themes, asset eligibility, images, logos, and conversion measurement. Record anything omitted or transformed during import. If the destination account uses different customer data, conversion values, or URL conventions, do not assume the imported optimization logic still means the same thing.

    Creative automation needs the same discipline. Auto-generated assets are becoming the default for newly created Microsoft Responsive Search Ads worldwide, except in China and South Korea. Sensitive verticals remain opt-in, and existing RSAs are unaffected. Microsoft reports roughly a 5% CTR increase among advertisers using generated assets, but that vendor-reported aggregate does not show that every generated message improves conversion quality, margin, or compliance.

    Review generated headlines and descriptions as live advertising claims. Check factual accuracy, pricing, promotional dates, prohibited implications, brand language, landing-page consistency, and any approval requirements in your industry. A higher click-through rate can be harmful if the copy attracts people the offer cannot satisfy or makes a claim the destination does not support.

    Your recurring control loop should therefore be short and diagnostic: verify measurement, compare spend with the approved envelope, inspect customer quality, review audience or placement evidence, and then choose one material intervention. When learning is the goal, avoid changing targeting, creative, value rules, and budget at the same time. Automation can execute several changes quickly; it cannot preserve the explanation you lose by making them together.

    Before your next campaign, create a one-page automation contract. Name the task being delegated, the financial boundary that cannot move without approval, the signal the platform will optimize, and the evidence that will trigger a human decision. Then activate the smallest campaign scope capable of answering the question.

    If you cannot state those four things, delay the automation and repair the measurement or decision rule first. Once they are clear, the new controls can remove repetitive campaign work while leaving accountability exactly where it belongs.

    References

  • ChatGPT Ads: What OpenAI’s Pause Means for Marketers

    ChatGPT Ads: What OpenAI’s Pause Means for Marketers

    If you’re deciding whether to reserve budget for ChatGPT ads, don’t treat OpenAI’s pause as either a canceled channel or an imminent launch. Neither conclusion is useful. The practical move is to prepare the parts you control while keeping activation spend conditional.

    The pause reveals an important constraint on OpenAI’s advertising strategy: the assistant has to retain attention and trust before it can carry a durable ad product. That changes what your team should build now, what it should leave blank, and which questions must be answered before you buy anything.

    The pause changes the sequence, not the long-term direction

    OpenAI has put its ChatGPT advertising plans on hold while it concentrates on speed, reliability, reasoning, and the broader user experience. The internal code red also directs attention toward reducing hallucinations and improving the assistant’s ability to complete complex tasks.

    That is a sequencing decision. Advertising remains part of the long-term strategy, but product stabilization comes first. For marketers, the distinction matters: a delayed channel deserves monitoring and preparation, not a committed media forecast built from assumptions.

    Do not plan around an unconfirmed launch date, inventory map, placement type, buying model, targeting system, or measurement specification. A pause does not answer any of those questions. It only shows that OpenAI currently considers product quality a prerequisite for monetization.

    Key takeaways

    • OpenAI has delayed ChatGPT advertising while it works on the assistant’s core performance and user experience.
    • The delay does not mean OpenAI has abandoned advertising as a revenue stream.
    • There is not enough confirmed detail to build a channel forecast around formats, targeting, pricing, or launch timing.
    • Your useful work now is measurement, intent mapping, content readiness, and launch governance.
    • Activation money should remain conditional until OpenAI publishes the operating details your team needs.

    Why assistant quality comes before ad inventory

    A person interacts with a glowing conversational orb while several unlit advertising tiles remain behind a translucent partition in the background.

    A ChatGPT ad product will inherit the trust conditions of the assistant around it. If an answer feels slow, fragmented, or unreliable, adding a commercial message creates more friction. If the assistant consistently helps users finish a task, an appropriately separated and relevant ad has a better chance of being useful.

    This is why the competitive pressure from Google matters to the advertising plan. Gemini’s advantage is presented as more than a benchmark contest: its integration with products such as Google Maps and Workspace can help it carry a user from a question into an action. OpenAI, meanwhile, is trying to make ChatGPT feel more like a dependable executor of tasks and less like a passive answer box.

    The commercial inference is straightforward. Useful task completion creates opportunities for relevant offers. Poor task completion makes advertising feel like an interruption. OpenAI therefore has two readiness gates to pass:

    • Assistant readiness: The product must be fast, dependable, coherent, and valuable enough that people continue using it.
    • Advertising readiness: OpenAI must define placements, labeling, targeting, controls, billing, reporting, privacy boundaries, and advertiser eligibility.

    The pause indicates that the first gate still commands attention. It tells you nothing conclusive about the maturity of the second. Ask for evidence that both gates are open before treating ChatGPT as an executable media channel.

    This also explains why a contextually relevant format is more plausible strategically than a generic display interruption, although no specific format should be treated as confirmed. OpenAI ultimately needs advertising that fits the user’s task without making the answer itself feel purchased or less trustworthy.

    Build readiness without buying imaginary inventory

    A marketing team organizes unbranded creative cards, audience tokens, and measurement blocks beside an empty media-placement frame under a transparent cover.

    You can prepare for ChatGPT advertising without pretending to know how it will work. Concentrate on assets that remain useful whether the launch arrives early, late, or in a form nobody predicted.

    1. Establish an AI traffic baseline. Create an analytics segment for visits whose referrer identifies ChatGPT. Record the landing page, engaged session, conversion, revenue where applicable, and assisted conversion. Keep the limitation visible: answers that influence a person without producing a click will not appear as referral traffic.
    2. Build a question-to-outcome map. Collect the questions customers ask in search data, sales calls, support tickets, reviews, and on-site search. Group them by the outcome the user wants: discover, compare, verify, choose, or act. Mark which questions have commercial intent and which require a neutral informational answer.
    3. Audit the pages that should support those outcomes. Each important page should identify the entity or product clearly, answer the central question directly, substantiate material claims, disclose meaningful constraints, and have an owner responsible for updates. Structured data should describe the visible page accurately; it should not introduce claims that users cannot verify on the page.
    4. Prepare modular messages and landing paths. Write short value propositions for each high-intent question, but do not build copy around a guessed ChatGPT placement. The message should still work if the eventual unit is adjacent to an answer, shown after a recommendation, or offered as an action.
    5. Define your evidence standard. Decide which product claims require documentation, which offers need current terms, and who approves regulated or high-risk language. A conversational interface can place a claim close to a user’s decision, so stale qualifications and ambiguous terms can become costly problems.
    6. Assign launch ownership now. Name the people responsible for media buying, analytics, privacy review, legal review, brand suitability, landing-page changes, and AI visibility. A new channel becomes hard to test when every unanswered question has to find an owner after launch.

    None of this guarantees paid eligibility, organic inclusion, or a citation in ChatGPT. It removes avoidable delays and gives you a clean baseline against which a future paid test can be judged.

    Require a complete launch brief before you spend

    The first announcement of inventory will not necessarily provide everything required for a responsible campaign. Product availability and campaign readiness are different events. Your team should be able to fill in the following brief from OpenAI’s actual documentation and platform controls, not from screenshots, rumors, or analogies to search ads.

    • Availability: Which countries, languages, account types, ChatGPT plans, devices, and assistant surfaces contain ads?
    • Placement: Does the unit appear inside an answer, beside it, after it, or as a separate recommended action? Can an ad affect the wording or ordering of the non-paid answer?
    • Disclosure: How is commercial content labeled, and does the label remain visible when an answer is shared, exported, or summarized?
    • Eligibility: Which industries, offers, destinations, and claims are restricted? What review process applies before an advertiser or campaign can run?
    • Targeting: Can advertisers select queries, topics, audiences, locations, tasks, or conversation contexts? Which controls prevent irrelevant matching?
    • Data boundaries: What conversational or account information can be used for targeting, optimization, reporting, and retargeting? What consent and retention rules apply?
    • Pricing and delivery: Is the campaign billed for impressions, clicks, actions, or another event? How are auctions, pacing, budgets, and delivery priority handled?
    • Advertiser control: Are exclusions, negative targets, frequency controls, suitability settings, placement reports, and blocklists available?
    • Measurement: Which impression, click, view, conversion, attribution, and incrementality reports exist? Can advertisers use independent analytics and conversion records?
    • User control: Can people dismiss an ad, correct an irrelevant assumption, change personalization settings, or understand why a commercial message appeared?

    Do not accept a familiar metric name without its definition. A click beside a conversational answer may represent a different level of intent from a click on a conventional search result. Likewise, an impression is not useful for planning until you know when the platform counts it and whether the ad was actually visible.

    A pilot is ready only when you can name its objective, eligible question set, conversion event, attribution window, landing experience, acceptable acquisition cost, and stop condition. Those values must come from your own economics. If the platform cannot provide the controls or reporting needed to enforce them, the campaign is not ready merely because inventory is available.

    Keep the initial allocation reversible. A controlled test budget protects you from locking an annual plan to a new interface whose user behavior, ad load, reporting quality, and optimization mechanics have not yet been demonstrated for your business.

    Keep paid ChatGPT ads separate from AI visibility

    Paid placement and inclusion in an assistant’s non-paid answer solve different problems. Until OpenAI explicitly documents a relationship between them, plan and report them separately. Buying an ad should not be treated as a shortcut to being cited, recommended, or described favorably in an organic response.

    Your organic preparation should make the brand easier to understand and verify regardless of the advertising timeline:

    • Maintain a clear canonical page for each important company, product, service, location, and policy.
    • Put the direct answer to a page’s main question near the beginning instead of burying it beneath promotional copy.
    • Support comparative, performance, safety, pricing, and availability claims with evidence appropriate to the claim.
    • Keep names, descriptions, relationships, and material product facts consistent across visible content and JSON-LD.
    • Make structured data specific enough to identify the entity while ensuring every marked-up claim is also present and accurate on the page.
    • Assign review dates and owners to pages containing details that can change.
    • Track brand presence and factual accuracy across a stable set of relevant prompts, but record the prompt, model, date, and context so the observations remain interpretable.

    This work is not a backdoor advertising tactic. It is content and entity hygiene. It helps you diagnose whether a future campaign is adding demand, capturing existing demand, or merely taking credit for users who already knew the brand.

    OpenAI’s decision to prioritize retention and product quality before ad deployment should shape your own planning sequence. Create three separate budget lines: market intelligence, channel readiness, and activation. Start the first two now. Release the third only when confirmed specifications pass your launch brief and a controlled pilot can answer a real business question.

    That leaves you ready without betting on a date. More importantly, it gives you the measurement discipline to recognize whether ChatGPT ads become a valuable acquisition channel or simply an expensive new place to appear.

    References

  • Google Prediction Market Ads: Eligibility and Launch Plan

    Google Prediction Market Ads: Eligibility and Launch Plan

    If you are preparing a Google Ads campaign for a prediction market, do not start with keywords or creative. Start with the legal entity buying the ads and the exact contracts a user can reach from them. If either falls outside Google’s narrow eligibility rules, campaign polish will not make the ads approvable.

    Google set January 21 as the start date for a limited U.S. opening. The permitted group consists of federally regulated Designated Contract Markets and certain registered brokerages. Eligible advertisers must also obtain Google certification and comply with the laws and advertising rules that apply to each campaign.

    Key takeaways on Google’s prediction market ad policy

    • The policy change covers prediction market advertising in the United States. Do not assume the same permission applies in another country.
    • A prediction market venue must be a Designated Contract Market authorized by the Commodity Futures Trading Commission.
    • A brokerage can qualify when it is registered with the National Futures Association and provides access to products listed by a qualifying Designated Contract Market.
    • Google certification is mandatory, but it does not replace the advertiser’s regulatory eligibility.
    • Campaigns must still comply with local law, financial regulations, the relevant Financial Services and Gambling and Games rules, and the rest of Google Ads policy.

    Make the advertiser entity your first go-or-no-go gate

    Unmarked business documents, an identification credential, a seal, and an institutional building model sit before an approval checkpoint with one open lane.

    The policy does not open Google Ads to prediction markets as a general business category. It opens a controlled route for two kinds of federally regulated participants. That distinction should decide whether you proceed before anyone builds a campaign.

    Advertiser relationshipEligibility testPractical decision
    Prediction market venueIt is a Designated Contract Market authorized by the CFTC.Document the legal entity and its current DCM status before seeking Google certification.
    Brokerage providing market accessIt is registered with the NFA and offers access to products listed by a qualifying DCM.Document both the brokerage’s registration and the connection between promoted products and the qualifying DCM.
    Unregulated operator, publisher, affiliate, software vendor, or other participantThe announced eligibility categories do not establish permission for it.Do not infer eligibility from a commercial relationship with a prediction market. Obtain a definitive policy and legal determination before spending on campaign production.

    An agency account does not turn an ineligible operator into an eligible advertiser. The regulated business behind the campaign must fit the policy. The same caution applies to affiliates: promoting a qualifying market is not necessarily the same as being one of the regulated entities Google permits to advertise.

    Run the gate in this order:

    1. Identify the advertiser’s exact legal entity, not only its consumer-facing brand.
    2. Classify it as a CFTC-authorized DCM, an NFA-registered brokerage offering access to qualifying DCM products, or neither.
    3. Record the regulatory status and the specific relationship to every product you plan to promote.
    4. Stop the launch if the entity or product relationship cannot be placed clearly inside one of the permitted categories.

    If the classification is uncertain, have qualified legal or regulatory counsel resolve it. A media team should not turn an ambiguous registration or contractual relationship into a policy conclusion, because the downside is not limited to an inefficient campaign: it can create advertising, financial-regulatory, and legal exposure.

    Trace the exact route from each ad to a qualifying contract

    An unbranded ad card connects through one enclosed route to a contract module, while glass barriers block side routes to other modules.

    Entity-level eligibility is necessary, but it is not the end of the review. The brokerage route is tied to access to products listed by a qualifying DCM. That makes the promoted product and the path to it part of your compliance case.

    Audit the complete user journey, not just the final URL entered in Google Ads:

    • Ad: What market, contract, platform, or action does the copy promote?
    • Landing page: Does it present the same regulated entity and product relationship that supports eligibility?
    • Conversion path: Where can the visitor register, fund an account, or gain market access?
    • Product destination: Is the promoted product listed by a DCM that fits Google’s rule?
    • Geography: Is the campaign limited to U.S. locations where the promotion and product access are lawful?

    Do not use a broad homepage as a compliance shortcut if it lets an ad for a qualifying product lead users into unrelated or unsupported offerings. Give each campaign a defined landing-page path and record which qualifying product relationship justifies it. If a brokerage offers several kinds of inventory, separate the prediction market promotion from everything that has not been cleared for the same advertising treatment.

    The U.S. scope also should not be translated automatically into nationwide availability. Google’s permission does not cancel local law or financial regulation. Build a location matrix that records each targeted state or locality, whether the promotion and product are permitted there, the approved landing URL, the person who confirmed the decision, and the date of the latest review. Exclude any location whose status has not been resolved.

    Treat Google certification as a separate approval track

    Regulatory status does not by itself activate this ad category. Eligible advertisers must also become certified by Google. Treat these as two independent gates: the business must qualify under the federal criteria, and Google must authorize it to advertise under the platform policy.

    Prepare an internal certification file before opening the application. It should make the campaign’s eligibility easy to follow even if Google requests a different document set:

    • The advertiser’s legal name and every trading or brand name that will appear in ads and landing pages.
    • Whether the applicant relies on CFTC-authorized DCM status or NFA-registered brokerage status.
    • Current evidence supporting that status, reviewed by the appropriate compliance owner.
    • For a brokerage, a product-level map showing which qualifying DCM lists each promoted product.
    • The domains, landing pages, and Google Ads accounts intended for the campaign.
    • The planned U.S. geographic scope and any locations excluded after legal review.
    • A named owner for certification, policy updates, campaign changes, and renewal or re-verification work.

    Google placed the policy preview in both the Financial Services and Gambling and Games areas of its Advertising Policies Help Center. Check both sections when preparing the application and again before launch. Passing one category review should not be treated as proof that every other applicable rule has been satisfied.

    Keep the certification record tied to the approved entity, domains, accounts, and scope. Do not assume that approval transfers automatically to a sister company, a new domain, a different advertiser account, or an agency-managed account. Verify coverage before expanding any of those elements.

    Build campaigns that cannot drift outside the approved scope

    The safest account structure makes a compliance mistake visible before it reaches users. Isolate prediction market campaigns from unrelated products, restrict them to approved landing pages, and make regulatory review part of the change process rather than a one-time launch task.

    1. Create a separate campaign group. Keep prediction market ads, budgets, locations, and conversion paths identifiable without searching through unrelated campaigns.
    2. Use a landing-page allowlist. Each ad should point only to a URL whose entity, product, and geographic scope have been reviewed.
    3. Control the copy library. Approve claims at the asset level. Do not let an ad imply certainty about an event outcome, financial return, availability, or regulatory status that the landing page and compliance file cannot support.
    4. Restrict locations deliberately. Target the United States only within the announced policy scope, then apply the exclusions identified in your local-law review.
    5. Put changes through the same gate as launch. A new contract, landing page, legal entity, domain, or target location can change the basis on which the campaign was cleared.
    6. Keep a decision log. Record what changed, who approved it, which product and DCM relationship it relies on, and which campaign assets were affected.

    If Google rejects an ad, do not begin by rewriting random phrases. Triage the rejection against the actual layers of permission: advertiser identity, federal regulatory status, qualifying product relationship, Google certification, location eligibility, landing-page consistency, and general ad-policy compliance. That sequence helps you distinguish a fixable asset problem from a campaign that should not be running.

    Before activation, put the legal entity, regulatory category, promoted products, qualifying DCM relationships, certification status, approved locations, and landing pages on one sign-off sheet. If any field is blank or ambiguous, resolve it before submitting or scaling the campaign. If every field is supported, you have a launch plan that can survive review and remain governable after the first ad goes live.

    References