Category: Advertising

  • Emerging AI Ads and Remarketing for Small Audiences

    Emerging AI Ads and Remarketing for Small Audiences

    If your site attracts hundreds rather than thousands of qualified visitors, remarketing has often stalled before you could test the creative. The audience simply was not large enough to use. That barrier is now lower, while ads inside AI-generated answers are moving from an idea toward a possible new acquisition channel.

    You do not need to choose between them. Build a focused small-audience remarketing system now, then prepare the same messages, evidence, landing pages, and measurement rules for emerging AI inventory. You will have a working campaign instead of a speculative media plan, and you will be ready to test AI ads if a usable format becomes available.

    Key takeaways

    • Google Ads now permits eligible audience segments with as few as 100 active users across Search, Display, and YouTube, including remarketing and customer lists.
    • The 100-user requirement is an eligibility threshold, not a promise of reach, efficient delivery, or statistically reliable results.
    • OpenAI’s possible ad formats, including placements within AI-generated responses, remain preliminary. Treat them as a readiness track rather than available inventory.
    • Small advertisers should consolidate visitors by meaningful intent before creating narrow demographic or behavioral subdivisions.
    • A future AI ad should feed the same first-party journey as any other acquisition channel: a relevant landing page, a consent-aware audience rule, a useful follow-up message, and a measurable conversion.

    Make the 100-user threshold useful, not merely reachable
    A focused cluster of glowing audience tokens is surrounded by three ad cards and connected to a landing-page frame.

    Google’s lower minimum removes a real operational barrier. Remarketing lists and customer lists can now become eligible from 100 active users across Search, Display, and YouTube. Audience Insights also uses a 100-user threshold instead of the previous 1,000-user requirement, giving smaller accounts access to audience analysis earlier.

    Do not confuse eligibility with scale. A qualifying list can still produce limited delivery because campaign reach also depends on active membership, matchability, targeting, geography, auction conditions, budget, and whether those users return to an environment where your ads can serve. The threshold tells you that a campaign may participate. It does not tell you how much it will spend or whether it will perform.

    This distinction should change how you segment. A smaller advertiser rarely benefits from dividing an already small pool into many audiences based on every page, device, location, and content category. Each split reduces usable reach and makes the resulting performance rates harder to interpret. Start with a few pools whose members need meaningfully different messages.

    Audience poolUseful signalJob of the follow-up adWhat not to mix into it
    High-intent visitorsA visit to pricing, booking, quote, demo, cart, or another commercial action pageResolve the last important objection and return the person to the unfinished decisionCasual readers who have not shown commercial intent
    Consideration visitorsVisits to product, service, comparison, use-case, or evidence pagesClarify fit, differentiation, or proof before presenting the next stepEvery visitor to the site merely to increase list size
    Content visitorsEngagement with a guide, tool, tutorial, or problem-specific resourceContinue the same subject with a relevant resource or appropriate offerA generic sales message unrelated to the content consumed
    Known customersA customer list you have the right to useSupport a relevant renewal, replenishment, retention, or complementary purchase journeyProspects added only to make the audience appear larger

    Keep customers and prospects separate even when combining them would help you reach 100 users. They have different relationships with you, different reasons to respond, and often different conversion goals. An audience large enough to activate but too mixed to address coherently is not an improvement.

    Use Audience Insights to check whether a pool resembles the audience definition you intended. Do not turn a small set of aggregate characteristics into an elaborate persona. Ask campaign questions instead: Does this group reflect the intended stage of the decision? Is an important market missing? Does the evidence justify changing the message or landing page? Those questions produce actions; a long list of audience traits often does not.

    Build the smallest complete remarketing campaign

    Accessible remarketing does not mean creating a campaign for every available audience. It means building one complete path from a recognizable intent signal to a useful follow-up and a measurable result. Use this sequence.

    1. Name the decision you want to recover. Examples include completing a quote request, returning to a product evaluation, booking a consultation, or finishing a purchase. Choose one primary conversion so the campaign has a clear job.
    2. Write the inclusion rule in plain language. State which page, event, or first-party list makes someone appropriate for the message. If you cannot explain why every member belongs, the audience is too broad.
    3. Add exclusions before launch. Exclude people who already completed the campaign’s goal when further acquisition ads would be irrelevant. If existing customers need another message, place them in a customer journey rather than leaving them in a prospect campaign.
    4. Consolidate before subdividing. Combine signals that reflect the same intent and need the same follow-up. Split an audience only when the new group warrants different creative, a different destination, or a different business objective.
    5. Check consent and data rights. Use site data and customer information only when you have the right to collect, upload, and use it under applicable law and platform policy. A lower platform threshold does not relax privacy obligations. Do not fill a list with scraped or purchased contacts.
    6. Match the message to the interrupted decision. Someone who left a pricing page needs help evaluating value, terms, or fit. Someone who read an educational guide may need the next useful resource. Repeating your broad brand slogan ignores the information you already have.
    7. Continue the journey on the landing page. Send the visitor to the page that answers the promise in the ad. Routing every click to the homepage forces the person to reconstruct a journey you already understood well enough to target.
    8. Predefine the measurement rule. Record the primary conversion, conversion quality check, campaign cost, and the condition that would justify continuing, changing, or stopping the campaign. Set spending limits from your own margins and acceptable acquisition economics, not from a platform recommendation alone.
    9. Change one meaningful lever at a time. Test a message, offer, audience definition, or destination against a stated hypothesis. Simultaneous changes may improve the campaign, but they will not tell you which decision caused the improvement.

    Keep a simple campaign record containing the audience name, inclusion signal, exclusions, creative promise, landing page, primary conversion, and owner. Use names that expose the logic, such as high-intent pricing visitors, rather than labels such as audience A. Clear naming matters when a small account begins adding channels and the original rationale is no longer fresh.

    Small audiences also require restraint in reporting. Look first at actual conversions, conversion quality, total cost, and whether the intended people reached the intended page. Percentages can move sharply when the underlying counts are small. A striking click-through or conversion rate is not enough to scale a campaign whose absolute result is still inconclusive.

    Prepare for ads inside AI answers without inventing the channel
    Unlabeled campaign assets are arranged toward an empty translucent AI conversation panel beside a glowing remarketing loop.

    OpenAI is exploring an advertising model, with early discussions involving media partnerships and ads that could appear within AI-generated responses. The work is still at a preliminary stage. There is no responsible basis yet for assuming a particular buying interface, targeting method, auction, reporting model, creative limit, or remarketing capability.

    You can still prepare for the distinctive part of the opportunity: the ad may meet a person while they are asking a detailed question, comparing options, or trying to complete a task. That is different from classic remarketing. Remarketing starts with a known prior interaction. An ad inside an AI response could start with the immediate context of a conversation, even when the person has never visited your site.

    High context does not automatically mean high purchase intent. A detailed question may be informational, exploratory, or commercial. Your preparation should therefore begin with the question and its decision stage, not with a generic assumption that every AI user is ready to buy.

    Create a question-to-offer record

    For each commercially relevant question cluster, record the user’s likely task, the direct answer they need, the condition under which your offer fits, the condition under which it does not, the evidence supporting your claim, the appropriate call to action, and the landing page that continues the answer. This becomes a reusable brief for paid AI placements, conventional search ads, landing-page copy, and answer-engine optimization.

    The disqualifying condition is important. An AI-mediated interaction can expose vague claims quickly because the surrounding answer may discuss alternatives and tradeoffs. Copy that states who an offer is for, what problem it solves, and where its limits begin is more useful than an unsupported superlative.

    Make the destination understandable to people and machines

    Keep brand, product, service, location, availability, eligibility, and offer details consistent across the ad candidate, visible page copy, and structured data where applicable. JSON-LD should describe what a visitor can verify on the page. Do not place stronger claims in schema than you are willing to show in the content.

    Use descriptive headings, direct answers, explicit entity names, accessible evidence, and a clear next action. Structured data can reduce ambiguity about page entities, but it does not guarantee an organic AI citation, a recommendation, or eligibility for a future paid placement. Treat it as accurate machine-readable context, not a shortcut around relevance or trust.

    Prepare modular creative instead of guessing the format

    Store each message as separate components: the user’s question, a concise answer, the commercial claim, its substantiation, a qualification, the call to action, and the destination. Once an actual ad format is documented, you can adapt those components to its limits. Writing to imagined character counts or unsupported placement rules now creates rework without making you more prepared.

    Plan for clear sponsorship rather than copy that imitates an impartial model response. Ads embedded near generated answers will depend heavily on user trust. A message should identify the commercial offer, preserve the distinction between paid placement and generated guidance, and avoid implying that the AI independently endorsed the advertiser.

    Connect future AI discovery to remarketing you control

    If a future AI ad sends a person to your site, treat that placement as an acquisition source, not as a replacement for your customer journey. The click should reach a question-specific page. A meaningful, consent-aware site interaction can then place the visitor into the appropriate first-party audience. Remarketing can continue the decision later if the audience qualifies and the follow-up remains relevant.

    Set up the handoff before the new channel arrives. Reserve a distinct source name for paid AI traffic, keep paid and organic AI referrals separate, define the on-site event that represents meaningful intent, document which remarketing audience receives that event, and suppress people after they complete the goal. Without that separation, you may attribute an organic AI visit to paid media, count the same conversion in conflicting reports, or keep advertising an action the customer already completed.

    Require answers before moving budget

    Do not divert dependable campaign budget merely because an AI company is discussing advertising. Wait until the inventory exists and you can answer practical buying questions:

    • Where can the ad appear, and how is it labeled to the user?
    • Which contextual, audience, geographic, and exclusion controls are actually available?
    • What event determines billing and optimization?
    • Can paid AI visits be identified reliably in your analytics?
    • Which conversion signals can be returned to the platform, and under what data terms?
    • What reporting distinguishes exposure, engagement, site visits, and conversions?
    • Which brand-safety, suitability, and placement controls protect you from appearing beside an inappropriate answer?

    Once those questions have documented answers, frame the first spend as an experiment with a hypothesis, audience context, message, destination, primary outcome, and cost limit. Judge it against your business economics and conversion quality. Do not treat novelty, impressions, or a high engagement rate as proof that the channel creates profitable demand.

    Your immediate move is smaller and more useful: choose the highest-intent audience that can clear 100 active users, write the objection its ad must resolve, and send people back to the exact page where they can continue. Then complete a question-to-offer record for the AI use case most closely tied to that decision. When AI inventory becomes buyable, you will have a relevant message, a truthful destination, and a measurement system ready for a controlled test.
    References

  • Ad Approval Is Not Legal Clearance: A Marketer’s Checklist

    Ad Approval Is Not Legal Clearance: A Marketer’s Checklist

    Your campaign has passed Google or Meta review, the launch date is set, and someone has saved the approval notice. You can run the ad. You cannot conclude that the ad, offer, targeting, or data use complies with every law that may apply.

    Treat platform approval as permission to use a platform under its rules, not as a legal opinion. That distinction should change who reviews a campaign, what evidence you preserve, and which changes send a live ad back through review.

    Platform approval answers a narrower question

    An ad platform reviews submissions for compliance with its advertising policies, account rules, technical requirements, and enforcement systems. Those policies can overlap with legal obligations, but the two systems have different purposes.

    Whatever combination of automated and manual checks a platform uses, its approval is not a warranty, an indemnity, or advice from your lawyer. Passing review means the platform allowed that submission to run at that point; ad approval is not legal protection.

    The distinction works in both directions. A platform may prohibit material that the law would allow because it wants a stricter environment. A platform’s approval also cannot establish that your evidence supports every claim, that you have all necessary rights, or that the campaign complies in every place where it appears.

    Decision layerQuestion it should answerTypical owner
    Platform policyMay this creative, destination, account, and targeting setup run on this platform?Paid media or campaign operations
    Legal complianceAre the message, offer, disclosures, rights, targeting, and data practices lawful in the applicable context?Legal or compliance
    Commercial and reputational riskIs the campaign accurate, fair, consistent with the product, and acceptable for the brand?Product, brand, and business leadership

    A small team may have one person coordinating all three layers. That is workable only if the decisions remain separate. A single checkbox labeled approved conceals which question was answered, by whom, and for which campaign version.

    Build a two-gate approval workflow before launch

    An overhead view shows platform, legal, privacy, and marketing reviewers examining campaign materials at two separate checkpoints.

    Do not wait for a platform decision and then ask whether legal review is necessary. By that point, the launch date and media budget can make a careful review feel like an obstacle. Put the platform gate and the legal gate beside each other in the campaign plan.

    1. Freeze a review version. Give reviewers the exact creative, copy, landing page, offer terms, audience, locations, schedule, tracking setup, and data sources that you intend to launch. A headline without its destination or targeting context is not a complete submission.
    2. Run the platform-policy gate. Check the platform’s current rules for the account, product category, creative format, destination, and targeting method. Record restrictions or exceptions rather than reducing the result to pass or fail.
    3. Run the legal-compliance gate. Test claims, disclosures, pricing, rights, endorsements, targeting, and data practices. Identify the locations and audiences in scope. Escalate questions that depend on applicable law to qualified counsel before launch.
    4. Attach support to every material claim. Preserve the evidence that existed when the decision was made. The evidence should match the wording, scope, audience, and conditions of the claim rather than merely relate to the same product.
    5. Record two sign-offs. Platform clearance and legal or compliance clearance should have separate owners, dates, scopes, conditions, and campaign version numbers.
    6. Inspect the live experience. Check the rendered ad, destination, disclosures, form fields, pricing, and tracking after launch. Dynamic assembly, device layouts, and landing-page publishing can produce an experience that differs from the reviewed files.

    Your sign-off record should identify the campaign and version, platform and account, audience and geography, reviewed landing-page URL, named reviewers, decision dates, restrictions, unresolved issues, and the event that will trigger another review. If evidence or permission expires, record that date too.

    For dynamic or automatically assembled advertising, reviewing one mockup is not enough. Review the combination rules, prohibited pairings, data inputs, and a representative set of rendered ads. Capture examples from the live campaign so you can connect an actual impression to the rule set that produced it.

    Test the risks a platform cannot clear for you

    Legal review should not be a vague request to make the ad safe. Give the reviewer defined questions and the material needed to answer them.

    • Claims and substantiation: List each factual, performance, savings, outcome, comparative, testimonial, and implied claim. For each one, record the likely audience takeaway, supporting evidence, material limitations, evidence owner, and valid-through date. Evidence for a narrow result does not automatically support broader wording.
    • Disclosures and overall impression: Check whether a viewer can understand qualifications, limitations, sponsorship, or other material information in the ad’s real format. A disclosure that appears only after a click may not correct the impression created before the click. Small print is also a poor fix for a headline that points in the opposite direction.
    • Price and offer terms: Verify the displayed price, included items, eligibility conditions, fees, duration, renewal terms, deadlines, inventory limitations, and geographic restrictions. The creative and landing page must describe the same offer.
    • Audience and targeting: Document who can receive the ad, why that audience was selected, and whether age, location, inferred traits, uploaded lists, exclusions, or sensitive information create additional obligations. Platform availability of a targeting feature does not decide whether your use of it is lawful.
    • Data collection and sharing: Map the information collected after an impression or click, its source, intended use, recipients, retention, and the permission or other basis relied on. Include pixels, forms, audience uploads, matching, measurement partners, and downstream systems rather than reviewing only the visible page.
    • Intellectual-property and publicity rights: Confirm that you own or have permission to use the copy, images, video, music, trademarks, customer material, testimonials, and likenesses in every version. A platform’s technical ability to accept an asset does not establish those rights.
    • Jurisdiction and product category: Ask which requirements apply based on the advertiser, audience, product, transaction, and data flow. New locations, languages, or high-consequence product categories deserve a fresh decision, not a copy of the previous approval.

    Use an explicit escalation rule. Legal or compliance review should occur before launch when a campaign makes a material outcome claim, uses a testimonial or comparison, depends on a disclosure, presents a complex offer, collects or shares audience data, uses third-party rights, targets a legally sensitive audience, enters a new jurisdiction, or promotes a regulated or high-consequence product.

    If the answer turns on a particular law, contract, regulator, or factual dispute, general marketing guidance is not enough. Send the complete campaign packet to counsel qualified for the relevant jurisdiction and subject matter. The safe alternative to guessing is to narrow or pause the campaign until the question is resolved.

    Re-review material changes and preserve the evidence

    A campaign manager compares two altered ad versions beside organized folders, approval tokens, and a locked evidence archive.

    Approval belongs to a defined version and context. It should not travel automatically to a new headline, landing page, price, audience, location, data flow, or dynamically generated variation.

    Send a campaign back through the relevant gates when any of these changes:

    • The wording, visual, testimonial, comparison, or implied product outcome.
    • The landing page, form, checkout flow, disclosure, price, eligibility rule, renewal condition, or offer deadline.
    • The audience, targeting method, exclusion, geography, language, schedule, or placement context.
    • The source, collection, matching, sharing, measurement, or retention of user data.
    • The product facts or supporting evidence, including evidence that becomes outdated, contradicted, withdrawn, or narrower than the live claim.
    • The rules used to generate or personalize creative combinations.
    • The risk picture after a complaint, rights claim, legal demand, platform enforcement action, or regulator inquiry.

    Do not interpret a later platform disapproval as proof that a law was broken. Identify the exact policy and affected asset. Then decide separately whether the same facts raise a legal issue. The reverse remains true as well: continued platform approval does not resolve a complaint or legal concern.

    When a credible concern appears, pause the affected ads if continued delivery could compound the exposure. Preserve the exact creative, destination, targeting settings, audience logic, approval notices, change history, evidence, and live captures before editing anything. Removing an ad may reduce ongoing risk; deleting the record can make it harder for counsel to determine what ran and how far the issue spread.

    Next, scope the problem. Identify every affected version, platform, account, audience, location, time period, and destination. Route legal demands, regulator contact, uncertain jurisdictional questions, and potentially material exposure to qualified counsel. Document the reason for any correction and the conditions that must be met before restart.

    Keep the final campaign packet after the media stops. It should contain the reviewed assets, evidence, approvals, exceptions, live captures, material changes, complaints, corrective actions, and restart or retirement decision. An approval screenshot can support that history, but it should never be the entire history.

    Key takeaways

    • Platform approval answers whether an ad may run under platform rules; it does not provide legal clearance.
    • Use separate platform-policy and legal-compliance gates, even if one person coordinates both.
    • Review the complete campaign context: creative, destination, offer, audience, geography, rights, tracking, and data use.
    • Attach evidence to the exact claim it supports and record limitations, ownership, and expiry.
    • Treat material campaign changes, credible complaints, and new jurisdictions as new review events.
    • Preserve the version that actually ran before correcting or removing it, and involve qualified counsel when the issue depends on applicable law or could create material exposure.

    Before your next campaign launches, replace the single approved field in your workflow with two named decisions and a versioned evidence packet. That small structural change makes it much harder to mistake media access for legal protection.

    References

  • Paid Acquisition Control Plan: Targeting, Lift and Search Ads

    Paid Acquisition Control Plan: Targeting, Lift and Search Ads

    Your acquisition dashboard can look healthier while your decision quality gets worse. Reach outside a service area can swell activity, a modeled lift estimate can be mistaken for certainty, and extra App Store ad slots can tempt you to chase a position you cannot buy.

    These are three different control problems: audience eligibility, causal measurement, and auction relevance. You need to separate them before deciding where the next dollar goes. This control plan shows you how.

    Separate the three decisions hiding inside campaign performance

    Paid acquisition reviews often collapse targeting, measurement, and optimization into one question: did performance improve? That shortcut is dangerous because each layer can change the same dashboard metrics for a different reason.

    Decision layerPlatform changeWhat you should control
    Audience eligibilityGoogle Demand Gen now exposes an explicit choice between Presence or interest and Presence only.Define whether a person must be inside the market to have economic value before you select the setting.
    Causal evidenceGoogle is making Bayesian incrementality measurement available with budgets as low as $5,000.Judge the posterior probability, credible interval, assumptions, and business downside instead of treating test availability as proof.
    Available optimization leverApple plans to add in-line App Store search ads in 2026, but advertisers cannot select or buy those positions directly.Improve query-to-app relevance and creative alignment rather than optimizing toward an unavailable placement control.

    The order matters. Set the eligible population first. Then ask whether advertising caused an outcome. Only after that should you optimize the lever the platform actually exposes. Reversing the order can leave you spending money to correct the wrong layer.

    • Out-of-market Demand Gen traffic is primarily a boundary problem, not evidence that the creative failed.
    • A wide Bayesian credible interval is an evidence problem, not automatic proof that the channel failed.
    • An App Store ad that never becomes auction-eligible can be a relevance problem that a higher bid will not solve.

    Set the Demand Gen location boundary before reading performance

    Demand Gen can reach people across YouTube, Discover, and Gmail. A loose location definition can therefore spread through several environments before you notice it in an aggregate report.

    Use Presence only when the conversion depends on the person being in the target market. That usually applies to a local service area, a physical catchment, a market-specific offer, or fulfillment that cannot extend beyond named locations. Use Presence or interest only when someone outside the market can still become a valid customer. Planned travel and relocation are plausible examples. Preserving a larger reach estimate is not, by itself, a reason to choose the broader option.

    Run this sequence whenever you create, migrate, or audit a Demand Gen campaign:

    1. Write the eligibility rule first. Complete this sentence: We will pay to reach people who are in, or are interested in, these markets because the resulting conversion can be fulfilled in this way.
    2. Select the location option explicitly. Do not let a copied campaign, inherited setup, or old operating habit make the decision for you.
    3. Audit legacy exclusions. Presence only is now available natively, reducing the need for manual exclusion workarounds. Remove an old exclusion only after confirming that the native control makes it redundant.
    4. Record the change date and previous setting. A switch between Presence or interest and Presence only changes the population behind the metrics. Treat it as a break in the series, not as an ordinary bid or creative adjustment.
    5. Inspect location quality before aggregate efficiency. Confirm that impressions, clicks, and conversions are coming from markets your business can serve. Only then interpret campaign-wide cost and conversion metrics.

    This distinction matters because a cost-per-acquisition change can be caused by audience composition even when the ad, bid, and landing experience remain unchanged. Comparing the periods as if they were the same population can produce a false creative, bidding, or channel conclusion.

    Presence only should reduce geo-leakage and make regional performance easier to interpret. It does not prove incrementality, validate your list of target markets, or establish that every conversion can be fulfilled. Those remain separate business and measurement questions.

    Read a $5,000 Bayesian lift test as a decision, not a verdict

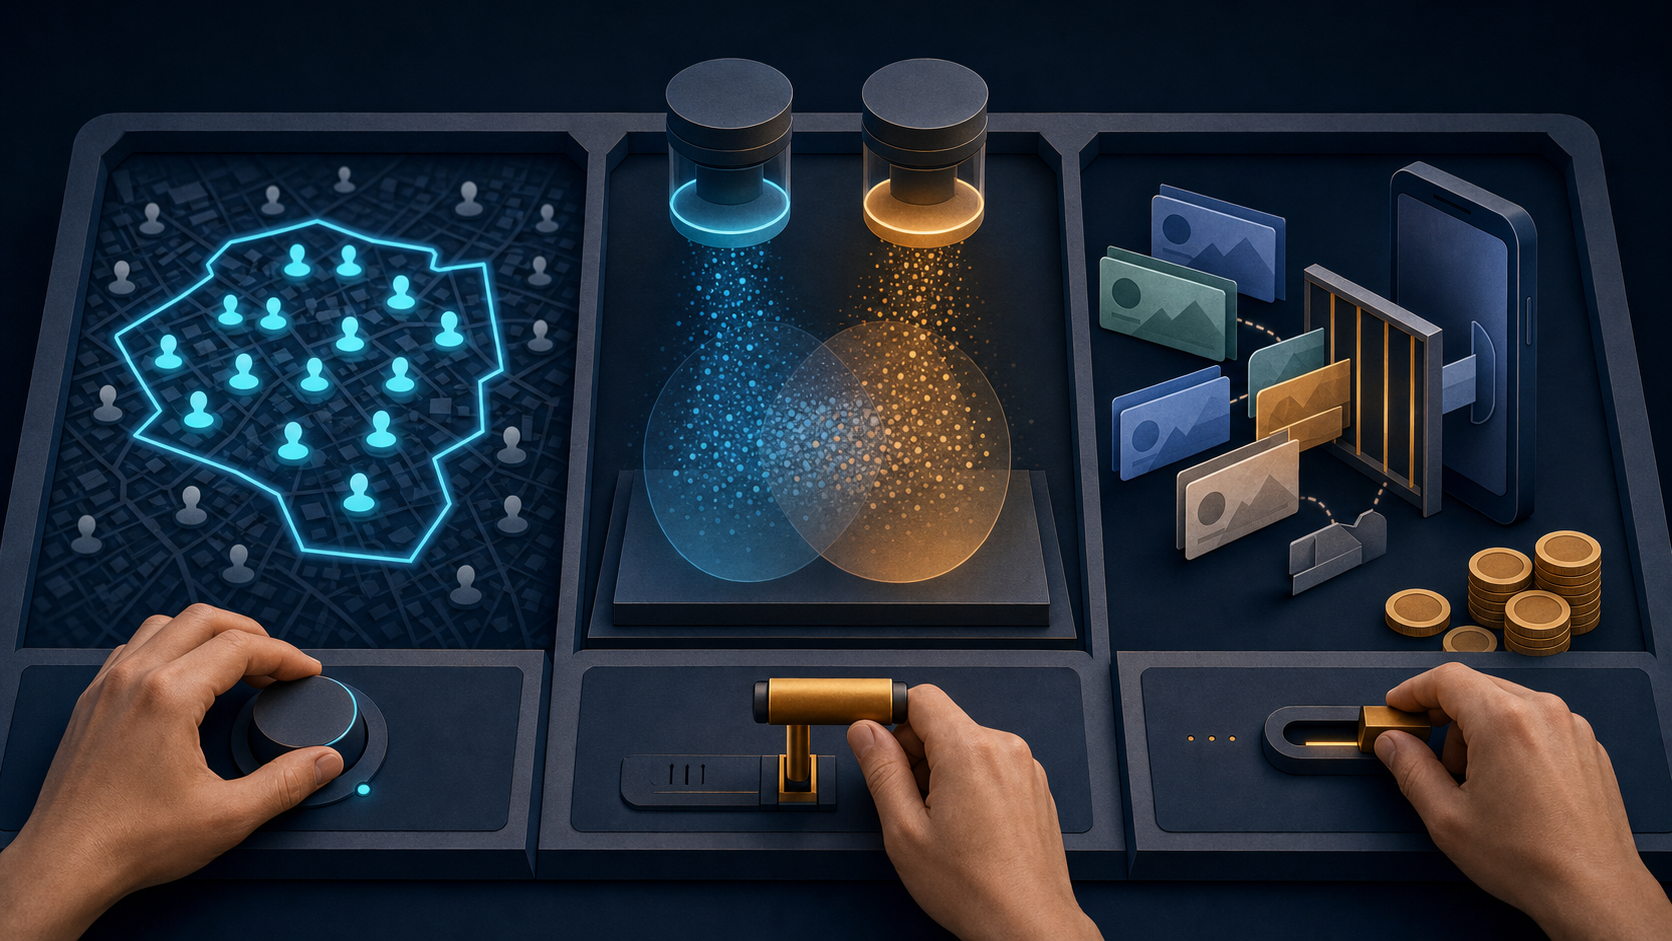
    Two transparent experiment chambers contain overlapping particle clouds beside budget tokens and a three-way decision lever.

    Lower-budget incrementality testing is useful because it gives more advertisers a way to ask a causal question: how many outcomes happened because of the advertising? It becomes dangerous when the budget figure is mistaken for a precision guarantee.

    Google’s approach uses informed priors, hierarchical modeling, and campaign history to extract useful evidence from less data. In Bayesian terms, the prior represents the belief before the test, the posterior updates that belief with observed data, and the credible interval describes a plausible range for the effect. As more relevant observations accumulate, the result should depend less on the prior and more on the test data.

    That is different from a conventional frequentist test built around a fixed sample, a p-value, and a binary statistical-significance decision. A p-value is not a Bayesian probability that the campaign worked, and a posterior probability is not the percentage lift. Mixing those interpretations can turn a technically valid output into a bad budget decision.

    Before launching a lift test, create a decision record with these fields:

    • Decision: the spend increase, reduction, continuation, or stop that the result could trigger.
    • Eligible population: the geography, audience, campaign set, and conversion outcome covered by the test.
    • Business hurdle: the smallest incremental effect that would justify the cost and operational risk.
    • Prior assumptions: whatever the platform exposes about the starting belief, historical inputs, or comparable campaign patterns. If these are not visible, record that limitation.
    • Posterior output: the probability attached to the outcome you care about, not merely a positive headline.
    • Credible interval: the plausible effect range, including whether economically unattractive outcomes remain credible.
    • Action and reversal condition: what you will do after the result and what later evidence would cause you to reverse it.

    Decide from the distribution, not the headline

    Start by separating direction from magnitude. A high probability that lift is positive can coexist with an effect too small to cover acquisition costs. Conversely, an uncertain estimate can still support a limited, reversible decision when the plausible downside is small and another test will add information.

    Next, inspect the full credible interval. If it spans both valuable and damaging outcomes, the honest conclusion is that the decision remains sensitive to uncertainty. Do not scale aggressively from the center estimate alone. Keep the change staged and use the next measurement period to narrow the range.

    Keep the result inside its tested boundary. Evidence from one geography, audience mix, campaign history, or conversion definition does not automatically transfer to another. This is especially important after changing Demand Gen location settings because you may no longer be measuring the same population.

    Finally, treat $5,000 as an access point for a modeled test, not a warranty that every campaign spending that amount will produce a narrow, decision-grade answer. Smaller tests can be useful precisely because Bayesian inference carries prior information forward. That same mechanism is why you need to examine the assumptions and uncertainty before committing more money.

    Prepare Apple Ads for a relevance gate you cannot outbid

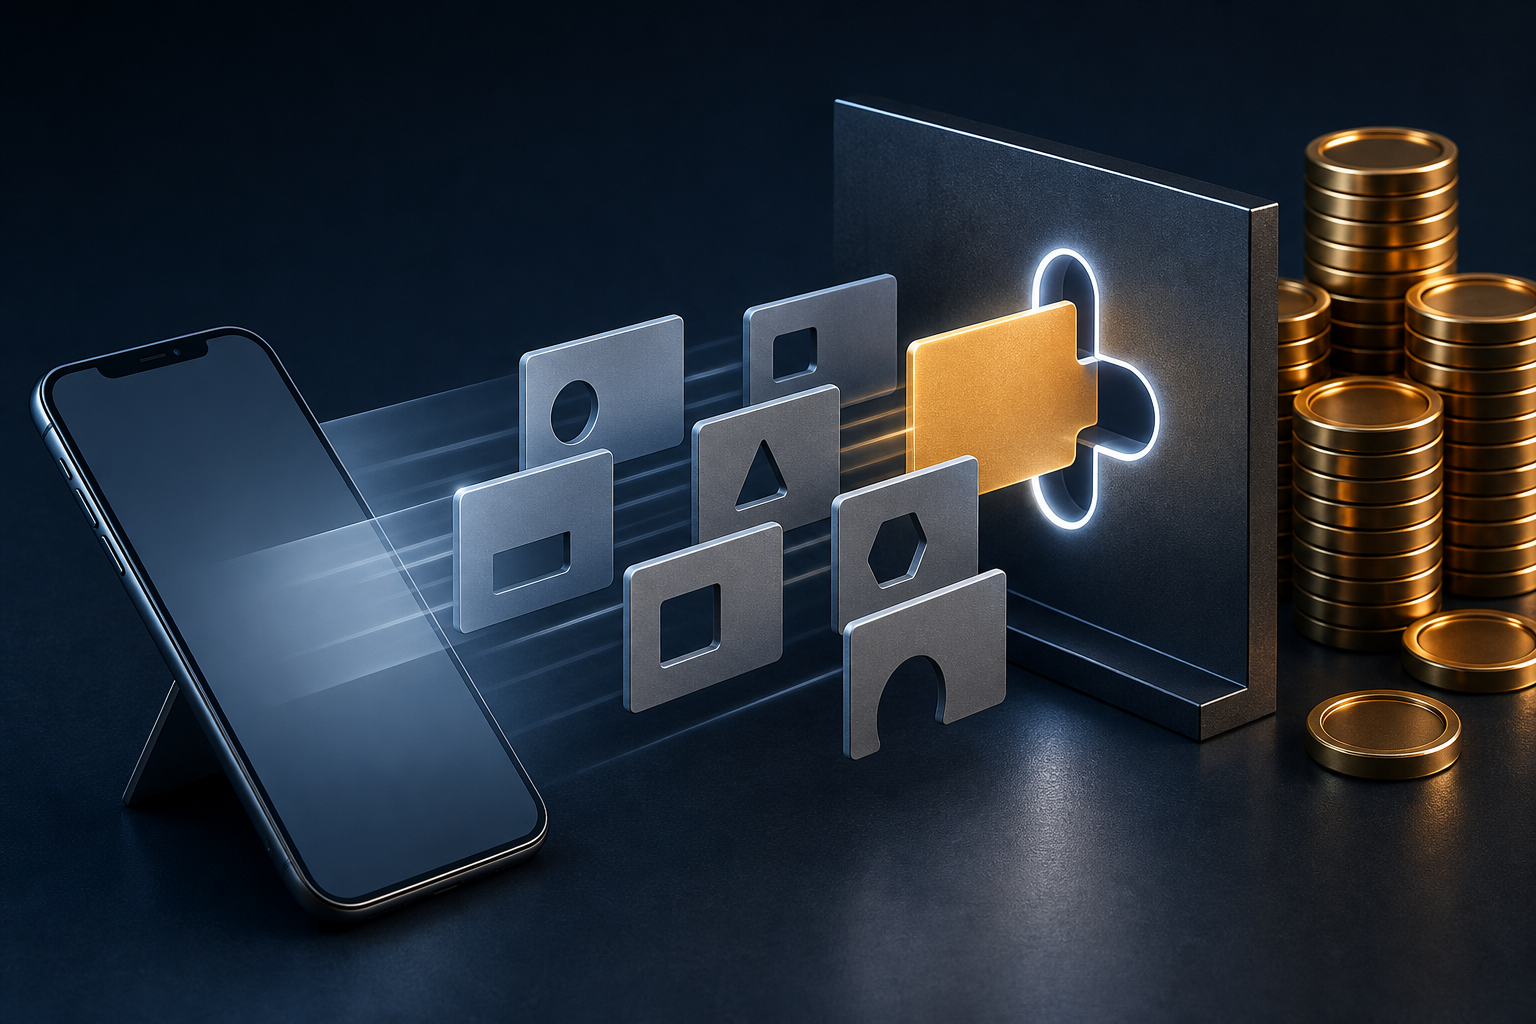
    An unbranded smartphone projects content cards toward a gate that admits one matching card while mismatched cards and bidding tokens remain outside.

    Apple plans to place additional ads among organic App Store search results during 2026 while retaining the existing top-result ad. Advertisers will not need to opt into the new positions, and there is no placement selector that lets you buy a particular in-line slot.

    The practical constraint comes earlier in the process: an app must be relevant to the search to enter the auction. A larger bid cannot rescue an app that fails that gate. Bids can still matter among eligible candidates, but they are downstream of relevance.

    Build your campaign around a relevance chain rather than a placement wish list:

    1. Group keywords by user need. Do not combine terms merely because they share vocabulary. Two queries containing the same noun can imply different jobs, audiences, or expected features.
    2. Map each theme to an app capability. Write down the function that directly answers the search. If you cannot complete that connection without stretching the meaning, the theme is probably a poor acquisition target.
    3. Map the capability to product-page evidence. The app name, description, imagery, and surrounding product-page material should make the connection understandable without relying on the ad to explain everything.
    4. Prepare creative variations for distinct themes. Apple allows advertisers to align different creative treatments with audiences or keyword groups. Without custom creative, the ad can be generated from the app’s product page, making that page the default acquisition asset rather than an organic-only concern.
    5. Annotate the inventory change when it reaches your account. More impressions or attributed installs may reflect additional supply, stronger relevance, displaced organic discovery, or a mixture of those effects. Preserve the date so you do not mislabel the discontinuity as a campaign optimization win.

    Diagnose the funnel in sequence. If impressions expand but taps do not, inspect the query-to-creative relationship first. If taps expand but installs do not, inspect whether the promise and product page carry the same intent. If attributed installs expand, do not automatically call the difference incremental; additional ad inventory can redistribute existing demand as well as capture new demand.

    Apple has indicated that billing will remain per tap or per install, depending on the existing setup. That continuity does not make the economics static. Greater ad density can change impression availability, tap behavior, conversion quality, and the balance between paid and organic discovery.

    Do not create a performance target around owning an in-line position you cannot control. Track whether relevant searches produce qualified installs at acceptable economics. That is a lever you can manage through keyword selection, product-page alignment, creative variation, and bids among eligible candidates.

    Key takeaways

    • Choose Demand Gen Presence only when value depends on the person being inside the target market; use Presence or interest only when out-of-market interest can still produce a valid customer.
    • Treat a location-setting change as a population change. Annotate it and avoid presenting the before-and-after difference as a clean creative or bidding test.
    • Regard the $5,000 Bayesian test level as access to modeled evidence, not guaranteed certainty or a universal minimum for a reliable answer.
    • Read Bayesian results through the prior, posterior probability, credible interval, and your business hurdle. Probability of positive lift is not the size of the lift.
    • For Apple’s planned in-line App Store ads, relevance determines auction eligibility before bid size can influence the result.
    • Annotate new ad inventory and separate attributed growth from incremental growth before increasing spend.

    Before your next budget review, add three lines to every campaign brief: the eligible market, the evidence required to change spend, and the lever the platform actually lets you control. If the campaign owner cannot fill in all three, do not solve the uncertainty with a larger budget. Fix the boundary, the measurement rule, or the relevance chain first.

    References

  • Google Ad Manager Price Floors After Antitrust Scrutiny

    Google Ad Manager Price Floors After Antitrust Scrutiny

    If you searched for Google Ad Manager pricing because you are worried that Google changed what the platform costs, the consequential change is elsewhere. In this context, pricing refers to auction controls: publishers can again set different price floors for different bidders.

    That gives you more control over yield and competition, but it does not guarantee more revenue. A higher floor can improve the price of impressions a bidder still wins, reduce that bidder’s win rate, shift wins to other demand, or leave you with weaker monetization. The practical job is to test the restored control without mistaking a higher CPM for a better business result.

    The change is about auction floors, not an Ad Manager fee

    A price floor is the minimum a bid must meet under the applicable rule. It is a filter inside the auction, not a promise that a buyer will pay the floor, not a guarantee that an impression will sell, and not a product subscription price.

    The newly relaxed rules let you apply different minimums to different bidders. For example, one buyer could face a $5 minimum while other buyers face a $2 minimum. Those figures illustrate the control; they are not recommended floor values. Your own demand and inventory data should determine the numbers.

    TermWhat it meansWhat it does not mean
    Price floorThe minimum a bid must meet under a ruleA guaranteed CPM or sale
    Unified pricingCovered bidders face the same floorEvery bidder submits the same bid or wins equally often
    Bidder-specific pricingDifferent bidders can face different minimumsEvery higher floor will increase revenue

    The history explains why this restoration matters. Before 2019, publishers had more latitude to apply higher floors specifically to Google. Google then required uniform pricing, removing that lever. After more than six years, unified pricing rules have been renamed pricing rules and bidder-specific floors have returned.

    The important distinction is control. Unified pricing constrained how you could respond when one bidder had different information, buying power, or auction behavior. Bidder-specific pricing lets you treat those demand sources differently, but it leaves you responsible for proving that the difference improves yield.

    Antitrust pressure matters because pricing control shapes competition

    Four streams of colored bid tokens pass through separate threshold gates toward one transparent digital auction chamber.

    A floor rule does more than choose a revenue target. It establishes the terms under which demand sources compete for your inventory. When the company operating key auction infrastructure also participates across the ad-tech supply chain, restrictions on publisher pricing discretion can attract scrutiny over self-preferencing and access for rival technology.

    The regulatory backdrop is substantial. U.S. authorities accused Google of anti-competitive conduct and proposed ending unified pricing, while European authorities imposed a €2.95 billion fine and demanded that Google stop self-preferencing within the ad-tech supply chain. The U.S. claims should still be understood as allegations and proposed remedies; the European fine is a regulatory action. They should not be flattened into one universal legal conclusion.

    Google’s stated position is that the update should make it easier for publishers and advertisers to work with competing ad-tech providers while minimizing disruption across display, video, and app advertising. That is Google’s explanation of the change, not proof that every competitive concern has been resolved.

    For your team, the useful lesson is narrower. A product rollback made under antitrust pressure restores an operational choice; it does not decide how you should use that choice, resolve the wider litigation, or answer whether a particular pricing configuration complies with your contracts and applicable law.

    Keep three questions separate when discussing the update internally: what regulators alleged, what Google changed, and what your auction data shows. Mixing them leads to bad decisions, such as raising Google’s floor to make a political point even when the configuration lowers publisher revenue.

    A higher floor can improve CPM while reducing yield

    A raised metallic threshold lets a smaller number of bright bid orbs reach an inventory grid while other bids divert to alternate paths.

    The central mistake is to judge a pricing rule by CPM alone. CPM describes the value of sold impressions. Your business result also depends on how frequently the affected bidder clears its floor, whether other bidders replace lost wins, how much inventory sells, and how much revenue the tested inventory produces overall.

    • If the affected bidder continues to meet the higher floor, realized CPM on its winning impressions may improve.
    • If that bidder stops clearing as often and competing demand replaces it at acceptable prices, your bidder mix can change without a severe revenue loss.
    • If replacement demand is weak, the higher floor can reduce the affected bidder’s win rate without producing enough revenue elsewhere.
    • If you raise several floors at once, you may see a different total result but be unable to identify which rule caused it.

    This is why bidder-specific floors should be treated as yield-management controls, not surcharges or penalties. The identity of a bidder may justify testing a different minimum, especially where its buying position or data advantages differ. It does not tell you in advance which floor maximizes the value of an impression.

    MetricQuestion it answersCommon misread
    CPMAre sold impressions earning more?Assuming a CPM increase proves total yield improved
    Affected bidder win rateHow did the rule change that bidder’s auction share?Calling any decline a success without checking replacement demand
    Sold volume or fillDid other demand absorb the available opportunities?Ignoring impressions that monetized poorly or did not sell
    Revenue for the tested inventoryDid the same inventory produce a better overall result?Comparing periods with materially different traffic or demand
    Bidder mixDid competition broaden or merely shift?Calling a transfer to one fallback bidder diversification

    A useful result therefore has several parts: the floor changes bidder behavior as expected, the resulting CPM is acceptable, replacement demand remains healthy, and the tested inventory earns more overall. If only the first metric improves, you have changed the auction without yet proving a yield benefit.

    Key takeaways

    • Google Ad Manager’s pricing update concerns publisher auction floors, not a published change to an Ad Manager fee schedule.
    • Publishers can set different minimums for different bidders instead of applying one unified floor across them.
    • A price floor is an eligibility threshold, not a guaranteed selling price or revenue increase.
    • The rollback arrived amid U.S. antitrust allegations and a €2.95 billion European penalty tied to self-preferencing concerns.
    • Evaluate bidder-specific floors with CPM, win rate, sold volume, bidder mix, and revenue for the same tested inventory.
    • Start with a reversible, isolated test rather than changing an entire account at once.

    Test bidder-specific pricing without putting total yield at risk

    A live floor change can reduce revenue, so document the current configuration and define a rollback condition before touching a broad inventory set. You want a test that can answer one question cleanly and can be reversed if the trade-off is poor.

    Run the smallest useful experiment

    1. Map the existing rule. Record the current floor, affected bidders, eligible inventory, and any exceptions. If you cannot describe the present state, you will not be able to attribute the result of a change.
    2. Select one coherent inventory cohort. Start with a single ad unit, format, or similarly consistent slice. Separate device or geography where those dimensions attract materially different demand.
    3. Capture a baseline. Record CPM, the affected bidder’s win rate, sold volume or fill, bidder mix, and revenue for that inventory before the change. Note traffic or demand shifts that could make the periods incomparable.
    4. Write the hypothesis. State which bidder will receive a different floor, why its current behavior justifies the test, and what combination of revenue and auction metrics would count as improvement.
    5. Change one variable. Adjust one bidder-specific floor while keeping the inventory cohort and other relevant settings stable. Multiple simultaneous floor changes create an attribution problem.
    6. Read the metrics together. A higher CPM is encouraging only when the decline in win rate or sold volume does not erase the gain. Check where lost wins moved and whether competition became broader or merely shifted to another buyer.
    7. Roll back or expand deliberately. Reverse the rule if the predefined downside appears. Expand only after the same mechanism holds across comparable observations; do not copy a successful floor blindly to inventory with different demand.

    Avoid the three most expensive misreads

    • “CPM rose, so the test worked.” CPM can rise while fewer impressions sell or total revenue falls. Use revenue from comparable inventory as the business check.
    • “Google won less, so competition improved.” A lower win rate for one bidder is not enough. Determine whether several rivals became more competitive or whether wins simply moved to one fallback source.
    • “Regulators opposed unified pricing, so every differentiated floor is safe.” The rollback restores product flexibility; it does not approve your specific configuration. If bidder-specific treatment could affect contractual obligations or create legal uncertainty in your jurisdiction, have qualified legal counsel review it before a broad rollout.

    Begin with one stable inventory cohort, one bidder, one documented hypothesis, and one rollback condition. The useful outcome of the antitrust-driven change is not the ability to set a more aggressive number; it is the ability to make a measurable pricing choice and keep it only when the full auction result supports it.

    References

  • A Practical System for Ecommerce Conversion and Ad Performance

    A Practical System for Ecommerce Conversion and Ad Performance

    Your ad account can look healthy while your store quietly wastes the demand you are paying to create. A strong click-through rate cannot rescue a difficult checkout, and a high account-wide ROAS can hide a catalog in which one familiar product consumes most of the budget.

    The fix is a sequence, not another disconnected app or campaign adjustment. Remove purchase friction first. Recover shoppers who have already shown intent. Then allocate advertising spend according to product-level performance. That order makes the numbers easier to interpret and keeps automation from optimizing around a broken buying experience.

    Key takeaways

    • Audit the complete mobile path from ad click to successful payment before increasing traffic.
    • Prioritize digital wallets, then evaluate buy now, pay later against your margins and customer needs.
    • Use email and SMS recovery only with the consent and controls required for each channel and jurisdiction.
    • Separate proven products, new or low-data products, and products consuming traffic without adequate return.
    • Review product assignments on a rolling cycle, but choose the window according to your sales volume rather than treating 14 days as a universal rule.

    Fix the purchase path before asking ads to work harder

    Generic shoppers follow a simplified mobile checkout path as obstacles, extra gates, and confusing branches are removed between a shopping basket and a delivery parcel.

    Start with the device on which the transaction actually happens. With 54.5% of holiday purchases happening on mobile, a phone is not a secondary quality-assurance case. It is often the main checkout environment.

    Do not audit that environment by opening the homepage and deciding that it looks acceptable. Follow the paid journey exactly as a shopper would:

    1. Open each high-spend ad on a real phone and record the promise, product, price, and offer shown in the creative.
    2. Confirm that the landing page immediately continues the same promise. If the ad promotes one product or use case, do not make the shopper search for it again.
    3. Add the product to the cart from a clean session so saved addresses, accounts, or payment details do not conceal friction.
    4. Start checkout and count the fields and decisions required before payment. Test every wallet that appears to be enabled.
    5. Place a test order. A visible payment button is not proof that authorization, confirmation, inventory handling, and order creation work.
    6. Repeat the path for the devices, browsers, and traffic sources that matter to your store. Record failures by stage rather than describing the whole journey as a conversion problem.

    Digital wallets such as Apple Pay, Google Pay, and PayPal reduce typing by reusing stored payment and delivery details. That matters on a small screen. Their relevance is not marginal: up to 64% of Americans use digital wallets as much as traditional payment methods, while 54% prefer using them more often. On Shopify, wallet and buy now, pay later functions can be added without custom development in many standard configurations.

    A wallet removes form friction; it does not repair a weak offer. If product-page engagement is poor, adding another payment method is unlikely to solve the underlying problem. Buy now, pay later can reduce the immediate price objection, but it should not be enabled solely because it might lift checkout completion. Review provider fees, refunds, returns, and contribution margin first. A higher conversion rate can still produce worse economics.

    Use your own historical baseline when reading the funnel. There is no universal healthy rate for every catalog, price point, or traffic mix. The pattern of the drop tells you where to investigate:

    Observed patternWorking hypothesisFirst actionPrimary measure
    Ads earn clicks, but few product views become cart additionsThe ad promise, landing page, product, or offer is mismatchedBuild a landing-page variant that continues the ad’s exact messageProduct-view-to-cart rate
    Cart additions are steady, but few shoppers start checkoutThe handoff creates uncertainty or extra effortReview the cart on mobile and make the next step and payment choices clearCart-to-checkout-start rate
    Checkout starts are steady, but purchases are weakPayment or data-entry friction is blocking completionTest wallet payments and evaluate whether buy now, pay later fits the order economicsCheckout completion rate
    Purchases are steady, but ROAS is weakSpend is reaching the wrong products or trafficRebuild product groups around performance rather than category aloneProduct-level ROAS and revenue
    One product absorbs most of the campaign budgetExisting winners are preventing new or less visible products from gathering evidenceGive proven, new, and traffic-without-return products separate treatmentSpend concentration and cohort-level ROAS

    This table is a hypothesis map, not an automatic diagnosis. For example, checkout completion can rise after you change campaign targeting because the new audience was easier to convert. That does not prove the checkout itself improved. Keep traffic allocation stable during a checkout test, or use a controlled experiment, so you can separate site effects from audience effects.

    Recover existing intent without creating a consent problem

    Once payment works, focus on shoppers who reached the cart or checkout but did not buy. They have supplied more evidence of intent than a cold audience, but that does not give you unrestricted permission to contact them.

    1. If the shopper has valid email marketing permission, place them in an abandoned-cart email flow with a direct return to the relevant cart or product.
    2. If the shopper has separately provided the consent required for marketing texts, use SMS selectively for time-sensitive recovery. Do not treat the presence of a phone number in checkout as automatic marketing consent.
    3. If you cannot document the necessary permission, do not quietly add the shopper to an automated sequence. Use compliant onsite recovery and your approved advertising audiences instead.
    4. Measure each recovery channel separately. A combined recovery number can conceal an unproductive SMS program behind a successful email flow, or vice versa.

    Email and SMS programs must follow the rules that apply to the shopper, sender, channel, and jurisdiction. In the United States, CAN-SPAM and TCPA are part of that compliance landscape. Requirements and interpretations can change, so have qualified counsel review the actual capture language, records, workflows, and vendors before contacting people who did not clearly subscribe. Calling an outreach process human-assisted does not by itself settle whether it is permitted.

    Recovery is not limited to reminders. Some shoppers leave because they still do not trust the product. Reviews answer a different objection: whether the item is credible and likely to meet expectations. Spiegel Research Center found that a product with five reviews was 270% more likely to be purchased than one with none. That finding does not make five a universal target or prove the same lift for every store. It does show why a product with no visible evidence should not be treated as conversion-ready.

    • Place product-specific reviews where the decision happens, not only on a separate testimonials page.
    • Make sure the review displayed belongs to the item being purchased. General store praise cannot answer product-level questions as well as relevant customer feedback.
    • Choose a review system that can connect with your advertising stack. Shopify integrations such as Okendo, Yotpo, and Shopper Approved can sync review data with Google Merchant Center and support Google Shopping activity.
    • Track whether products that gain credible review coverage improve their product-view-to-cart and checkout-start rates. Do not attribute every store-wide change to the review widget.

    Watch the downside metrics alongside recovered revenue: unsubscribe activity, complaints, failed deliveries, discount cost, refunds, and repeat purchase behavior. A flow that produces immediate orders by exhausting customer permission is not a durable win.

    Stop letting product categories decide where the budget goes

    Unbranded products receive different streams of advertising resources based on abstract performance signals, with completed orders feeding results back into a central decision hub.

    Category-based campaign structures are easy to understand, but a merchandising label does not describe advertising performance. One popular product can consume the available budget because the platform already has strong evidence that it converts. New products remain underexposed, while weak products can stay hidden inside a category that looks profitable in aggregate.

    Create performance cohorts with rules written before you inspect the latest results. Three labels are enough to begin:

    • Proven performers: products at or above your target return with enough recent traffic to support the decision.
    • New or low-data products: launches and existing products that have not received enough exposure to be judged by the same rule as established sellers.
    • Traffic without adequate return: products that have crossed your evidence threshold for clicks or spend but remain below your required return.

    Define the variables with your own economics. A workable rule template is: proven performer equals ROAS at or above target and clicks at or above the evidence floor; traffic without adequate return equals clicks at or above that floor and ROAS below your lower limit; new or low-data equals product age within your launch window or clicks below the evidence floor. The structure is reusable, but the values are not. A high-margin accessory and a low-margin appliance should not inherit the same target merely because they share a campaign.

    If you do not have a dependable margin view, do not automate budget expansion from ROAS alone. ROAS is attributed revenue divided by advertising spend. It is not profit. Product cost, fulfillment, payment charges, returns, discounts, and the attribution model can all change the decision.

    1. Export product-level clicks, spend, attributed revenue, orders, and ROAS for a consistent window.
    2. Apply the written cohort rules using feed labels or equivalent product-grouping fields.
    3. Give each cohort a budget and campaign treatment appropriate to its job. The new-product cohort needs room to gather evidence; proven products need room to scale; weak products need a controlled test or a spending limit.
    4. Publish the same product labels to paid channels where the required data and controls are available.
    5. Recalculate labels on a rolling schedule and log every reassignment. Without a log, a product that moves between groups can make campaign trends difficult to explain.

    La Maison Simons used Channable Insights to replace static category segments with product-performance groups and refreshed them on a rolling 14-day window. It then applied the approach across Google, Meta, Pinterest, TikTok, and Criteo. In that deployment, ROAS rose from about 800% to about 1,500%, CPC fell from $0.37 to $0.30, CTR increased from 1.45% to 1.86%, and average order value increased 14% without additional ad spend.

    Those figures are one retailer’s outcome, not a forecast for your catalog. They do not establish how much of the change came from segmentation rather than other conditions. The transferable lesson is narrower and more useful: a product can receive a different advertising treatment as its evidence changes, and a winning item does not have to monopolize the budget forever.

    A 14-day window is a sensible test cadence for a fast-moving catalog with enough transactions. It can be noisy for a lower-volume store, an expensive product, or a long-consideration purchase. Use the shortest window that still supplies enough evidence for your preset rules. If products repeatedly jump between cohorts, lengthen the window or raise the evidence floor instead of manually overriding the system every few days.

    Run one operating loop from conversion to ROAS

    Advertising and conversion teams often optimize separate dashboards. The media team changes audiences and budgets while the ecommerce team changes checkout and landing pages. When both happen at once, neither team can explain the result. Use one operating loop with fixed definitions and a visible change log.

    1. Cycle setup: record the current product cohorts, attribution model, campaign budgets, landing-page versions, payment options, and funnel baseline.
    2. During the window: monitor tracking and payment failures, but do not reclassify products because of a single order or a short-lived spike. Emergency defects should be fixed immediately and marked in the log.
    3. Decision day: recalculate product labels from the same lookback window, move qualifying products according to the written rules, and record every move.
    4. Experiment selection: choose one material conversion constraint for the next cycle. Test the ad-to-page message, the landing-page treatment, the checkout path, or the recovery flow rather than changing all four.
    5. Scale decision: increase exposure only when the advertising return, checkout behavior, and unit economics point in the same direction.

    Your shared scorecard should retain the relationship between media and store behavior:

    • CTR: clicks divided by impressions. It shows whether the ad earns attention, not whether the resulting visit is valuable.
    • CPC: spend divided by clicks. A lower CPC helps only if the traffic still reaches profitable purchases.
    • Product-view-to-cart rate: cart additions divided by relevant product views. Use it to investigate message, product, offer, and page friction.
    • Checkout completion rate: purchases divided by checkout starts. Use it to inspect payment and form friction.
    • Average order value: revenue divided by orders. Pair it with margin rather than assuming a larger basket is automatically more profitable.
    • ROAS: attributed revenue divided by ad spend. Always display the attribution model and window beside it.
    • Spend concentration: the share of budget absorbed by the top product or small group of products. This reveals catalog dependence that account-wide ROAS can hide.

    GA4 can remain part of this measurement system, while a third-party attribution layer such as Triple Whale can provide another product and channel view. More dashboards do not create objective truth. Select the attribution model used for budget decisions, document it, and avoid changing it in the middle of a comparison. A last-click result from one cycle cannot be compared cleanly with a different model in the next.

    Custom landing pages deserve their own controlled tests. Shopify builders such as Replo can create and A/B test pages without changing the main theme for every visitor. Start with one ad and product cohort, keep the standard page as the control, and change one decision-relevant treatment. If the variant wins, confirm that the improvement survives after product mix and traffic quality are accounted for before rolling it across the catalog.

    Begin with one mobile test order and one export of product-level advertising data. Fix any payment failure you find, label the catalog with written performance rules, and start a single review cycle. That gives you a system you can improve. Installing the entire stack before you can explain the current funnel only gives you more places for the same leak to hide.

    References

  • How TV Advertising Changes Search Behavior and Demand

    How TV Advertising Changes Search Behavior and Demand

    A TV campaign can do its job and still look inefficient in your dashboard. The spot creates curiosity, the viewer searches, and search receives the click and often the conversion. If the channels are reported separately, search gets credit for demand it did not create while TV loses credit for the action it caused.

    When a campaign is approaching, your practical problem is not whether TV affects search. It is whether the questions created by the commercial will meet the right result, whether your pages and paid campaigns can capture the resulting demand, and whether measurement can distinguish demand creation from demand capture. Treat those as one operating system.

    TV changes the query, not just the number of searches

    TV advertising does more than send extra people toward keywords that already exist. It can change what people search for, how specific their searches become, and which brand they include in the query.

    Someone who might otherwise search for a category such as car insurance may search for a particular insurer after seeing its commercial. Someone who was not shopping at all may search for the actor, song, claim, product, offer, or scene they remember. A later search may become more commercial: price, reviews, availability, eligibility, alternatives, or where to buy.

    That produces several distinct kinds of demand:

    • Navigational demand: The viewer remembers the company or product and wants the official destination.
    • Campaign-identification demand: The viewer remembers a celebrity, character, song, phrase, or plot but not necessarily the brand.
    • Informational demand: The commercial creates a question about what the product does, how an offer works, or whether a claim applies to the viewer.
    • Commercial-investigation demand: Interest turns into searches for pricing, reviews, comparisons, specifications, availability, or alternatives.
    • Transactional demand: The viewer looks for a store, application, booking page, product page, or other way to act.

    The sequence is not always linear. A viewer can search during the commercial on a second device, later that evening after another exposure, or days afterward when a related need appears. Comscore’s 2024 work connected coordinated TV and digital activity with stronger engagement and second-screen actions. In February 2025, YouTube also said television had overtaken mobile as the primary device for its U.S. viewing, based on Nielsen data. Your TV-to-search plan therefore needs to cover broadcast, connected TV, and streaming rather than treating them as separate consumer journeys.

    The timing can be fast. Google and Nielsen found in 2015 that TV ads could increase branded search queries by up to 20%, often within hours of an airing. DAIVID, a creative-analytics provider, has offered a higher vendor estimate of up to 60%, with the possibility of more in well-coordinated campaigns. Those figures demonstrate the possible scale, but they are upper bounds from different contexts, not universal planning assumptions. Reach, repetition, creative attention, prior brand awareness, category demand, market conditions, and the clarity of the call to action all affect the result.

    Do not place 20% or 60% into a forecast as if TV produces a fixed search multiplier. Build your planning range from your own previous airings, separated by market, creative, product, and schedule. If this is your first flight, treat branded search lift as a measurement question rather than a promised outcome.

    A useful working model is: exposure → attention → memory or curiosity → query → result → action. Search teams control the final handoffs. If the memorable clue from the commercial is absent from your pages, ads, video metadata, and entity information, viewers can be interested and still fail to find you.

    Build the search surface from the creative itself

    A television, phone, and laptop display matching unbranded visual elements connected by glowing lines.

    Keyword tools show existing demand. A new commercial can create language that did not have meaningful volume before the campaign. Start with the finished creative, not with last month’s keyword export.

    Watch the commercial without the creative brief in front of you. Record what an ordinary viewer could actually remember: the spoken brand name, product name, campaign line, spokesperson, character, visual device, offer, claim, date, location, and requested action. Then watch it again without sound. Connected-TV viewers may be distracted, and visual memory can produce a different query from the approved campaign wording.

    Turn those observations into a search-intent inventory:

    1. List exact entities. Include the brand, product, service, campaign, spokesperson, featured organization, and location named or shown in the spot.
    2. Write identification queries. Model the fragments a viewer might remember, such as [brand] commercial actor, ad with [scene], or what company made the ad about [theme].
    3. Write promise and explanation queries. Include the central benefit, claim, offer, qualification, or problem depicted in the commercial.
    4. Write action queries. Cover price, availability, release date, eligibility, locations, applications, bookings, trials, and where to buy when those intents apply.
    5. Add natural variants. Include abbreviations, common misspellings, shortened product names, and spoken versions of stylized brand names.
    6. Map every query family to a destination. Assign an existing page, create a new one, or document why paid coverage is the appropriate route.
    7. Inspect the live results. Search the phrases from the target market and device context. Check whether the correct page appears and whether the title and description make the relationship to the commercial obvious.

    The map should connect each memory or intention to an answer, not merely to your home page.

    Search signalLikely query patternBest destinationFailure to catch before airing
    Brand or product recall[brand], [product name]Official brand or product pageAn outdated page, reseller, or competitor is more prominent
    Memory of the creative[brand] commercial song, ad with [person or scene]Campaign page, video page, or concise commercial FAQThe creative clue appears nowhere in crawlable text or video metadata
    Offer or claim[offer] terms, how does [claim] workOffer page with conditions, dates, and next stepThe landing page repeats the slogan but does not explain it
    Evaluation[product] reviews, [product] vs [alternative]Product details, evidence, comparison, or review resourcesThe viewer must leave the site to understand basic differences
    Availability or locationwhere to buy [product], [service] near meStore locator, local page, product listing, or booking flowInventory, locations, or business information is inconsistent
    Eligibility or applicationwho qualifies for [offer], apply for [service]Eligibility explanation and application pageImportant restrictions appear only after the user starts converting

    The destination should visibly repeat the language and visual identity of the commercial. A viewer who searches after seeing an ad is looking for recognition as much as information. If the page uses a different product name, campaign line, image, or offer, the visitor has to decide whether they found the right company before they can consider the product.

    Put the answer to the commercial’s main unresolved question near the beginning of the page. Include dates, eligibility, price conditions, inventory limits, or geographic restrictions when the campaign depends on them. A memorable slogan is not an explanation. Sending every query to a generic home page wastes the context that made the search valuable.

    Prepare the machine-readable layer with the same discipline. Use Organization, Product, Offer, or VideoObject structured data only when the visible content supports it. Keep names, URLs, images, availability, dates, and offer details consistent across the page and markup. If you publish the commercial, include a useful title, description, transcript or summary, thumbnail, and campaign context. Structured data can clarify entities and relationships for search and answer systems, but it cannot repair an absent answer or an unsupported marketing claim.

    Write a few direct, self-contained answers for people who search conversationally or ask an AI assistant to identify the ad. State what the campaign promotes, which product or service appears, how the offer works, and where someone can act. Do not bury those facts in brand language that only makes sense after a visitor has watched the full commercial.

    Run paid and organic search as one response system

    Organic pages cannot be switched on at the moment an ad airs. They need to be published, crawlable, internally linked, indexed, and tested beforehand. Paid search can respond more quickly, but it still needs the right keywords, creative, budgets, locations, schedules, landing pages, and measurement conventions before volume arrives.

    Before the flight

    • Create one airing log with the creative ID, campaign name, product, market, channel or platform, planned timestamp, and time zone. Search and analytics teams should use the same identifiers.
    • Verify that every mapped landing page is indexable, uses the intended canonical URL, works on mobile, and completes its conversion path without errors.
    • Check page titles, descriptions, headings, visible copy, video metadata, structured data, and internal links against the language viewers will remember.
    • Build paid coverage for brand, product, campaign, offer, and high-value action queries. Review match types and negative keywords so a new campaign phrase is not accidentally blocked.
    • Confirm that budgets and targeting reflect the markets and times receiving media. A national paid-search increase is a poor response to a limited regional TV schedule.
    • Record a baseline for branded, product, campaign-related, and non-brand category queries before the campaign changes demand.
    • Test site capacity, inventory feeds, forms, phone routing, store data, and analytics events. A search spike has little value if the next step fails.

    Share creative changes immediately. A late edit to an offer, product name, spokesperson, or campaign line can invalidate keyword coverage and landing-page copy even when the media schedule stays the same.

    During the flight

    Monitor around actual airings where the volume supports that level of analysis. Look at branded and campaign-cue queries, paid impression share, spend, click-through rate, organic impressions, landing-page traffic, page errors, conversion events, on-site searches, and customer questions. Use the time zone recorded in the airing log; otherwise an apparent lag or lead may be a reporting error.

    Paid copy should repeat the recognizable product, benefit, and offer from the commercial, then add the practical detail the viewer needs. If the spot is emotional and the search ad sounds like unrelated direct-response copy, the handoff feels broken. Consistency does not require copying the script. It requires confirming that the searcher has reached the right answer.

    Do not automatically raise bids on every branded query. Blanket increases can make you pay for visits your organic result would have received anyway. Paid brand coverage is more defensible when competitors are present, the results are ambiguous, the campaign needs a precise destination, or the organic page is not yet strong enough. Where volume allows, compare markets or airing windows with and without paid brand coverage to estimate whether the ads add clicks and conversions rather than merely moving them from organic search.

    Watch the mix, not just total volume. If searches grow for the actor or song but not the brand or product, the entertainment may be more memorable than the advertiser. If viewers search for basic eligibility, pricing, or meaning, the spot has created interest but left a consequential question unresolved. Update paid copy and owned answers while the campaign is still running.

    After an airing or flight

    Do not remove campaign pages the moment paid media stops. Search can lag an exposure, and commercials can continue circulating through streaming, video sharing, press coverage, and memory. Use your own query and visit decay to decide how long active paid support should remain.

    When an offer expires, keep a useful destination if people are still searching. State clearly that the promotion ended, preserve relevant campaign context, and direct visitors to a current product, offer, or support page. Replacing a known campaign URL with a generic error page converts residual demand into confusion.

    Annotate changes to the creative, media weight, search campaigns, pages, offers, pricing, and tracking. Without that change log, a later analyst may attribute a search shift to the wrong channel or assume that two materially different commercials were the same treatment.

    Measure incremental demand without giving search all the credit

    Two miniature neighborhoods show different levels of glowing activity from televisions to phones and destinations.

    Last-click reporting answers which channel completed the recorded journey. It does not answer which channel created or accelerated the need to search. A branded search conversion after a commercial may be captured by PPC or SEO while being caused partly by TV. The reverse mistake is also possible: not every branded search during a TV flight was caused by the campaign.

    Separate three layers in your reporting:

    • Demand response: Incremental brand, product, campaign-cue, and relevant category searches associated with the airing.
    • Search capture: The portion of available demand reached through organic and paid results, followed by clicks and useful landing-page behavior.
    • Business outcome: Incremental leads, purchases, store actions, applications, bookings, or other outcomes after accounting for the demand that would have existed without TV.

    This distinction prevents a common misreading. A successful TV campaign can lower the conversion rate of search traffic because the commercial brings in a broader, earlier-stage audience. More curious visitors may arrive before they are ready to buy. Total incremental conversions can rise even while the percentage of visits that convert falls. Judge the campaign using volume and incrementality alongside conversion rate, not conversion rate in isolation.

    Use a repeatable measurement sequence:

    1. Define the expected baseline. Compare with similar non-airing periods, matched weekdays and dayparts, previous weeks, or comparable markets. Adjust the baseline when seasonality or an established trend makes a simple average misleading.
    2. Align the airing log. Use actual timestamps and markets when available, not merely the campaign’s overall start and end dates.
    3. Group queries by intent. Separate brand, product, campaign identifier, offer, high-intent non-brand, navigational, and unrelated searches. A total branded-search line can conceal what changed.
    4. Inspect multiple response windows. Look for an immediate second-screen response and a later memory response. Do not force one universal attribution window onto every product, creative, or buying cycle.
    5. Control overlapping activity. Promotions, product launches, email, public relations, influencer activity, news, seasonality, competitor campaigns, site changes, and search-platform changes can all move demand at the same time.
    6. Use a comparison design when feasible. Matched geographic markets, staggered schedules, non-airing periods, or carefully chosen holdouts produce a stronger estimate than a simple before-and-after chart.
    7. Reconcile the channels. Report how much demand appeared, how much search captured, and how much converted. Do not add TV-attributed and search-attributed conversions if both labels include the same people.

    A simple diagnostic calculation is: search lift (%) = (observed query volume – expected query volume) / expected query volume x 100. The difficult part is not the arithmetic. It is constructing a credible expected value. A baseline contaminated by a promotion or product launch will produce a precise-looking but unreliable lift figure.

    No single platform supplies the complete denominator. Google Trends shows relative interest rather than absolute query counts. Search Console shows impressions and clicks involving your properties, not every search in the market. Paid-search reporting describes the auctions and traffic your campaigns entered. Web analytics describes visits and recorded outcomes after a user reaches the site. Read those alongside airing data, direct traffic, on-site search, video search behavior, sales, calls, and customer-service questions.

    Search terms also function as creative feedback, but only when you interpret their meaning:

    • A rise in exact brand and product searches indicates that viewers connected the message to the advertiser.
    • A rise dominated by the celebrity, song, or scene can indicate strong entertainment recall but weak brand linkage.
    • Queries such as what company is that ad or repeated misspellings can expose a naming or pronunciation problem.
    • Growth in pricing, availability, location, or application queries signals movement toward action and tells you which destination must be strongest.
    • Growth in eligibility, explanation, or what does it mean queries reveals an information gap. The gap may be intentional curiosity, but the search result still has to resolve it.
    • Complaint, skepticism, or confusion queries should not be counted as favorable response merely because volume increased. Investigate the underlying issue and adjust the answer or campaign where warranted.

    Branded search volume is therefore a useful creative-response indicator, not a standalone verdict. It tells you that the commercial entered behavior. Query composition, result quality, incremental visits, and business outcomes tell you whether that behavior helped.

    Key takeaways

    • TV can create navigational, informational, commercial, and transactional searches; it can also shift an existing generic search toward a named brand.
    • Search response may begin within minutes or hours, so pages, paid campaigns, tracking, and operational systems must be ready before the commercial airs.
    • Build the keyword and content map from what viewers can remember in the creative, including the product, offer, person, phrase, scene, and unresolved question.
    • Give every important query family a recognizable destination instead of sending all TV-driven demand to a generic home page.
    • Coordinate paid-search schedules and budgets with actual markets and airings, while testing whether branded ads add incremental value over organic results.
    • Measure demand creation separately from search capture, then use matched baselines or holdouts to estimate the incremental effect.
    • Read the query mix as feedback: product searches, campaign-identification searches, action searches, and confusion searches tell you different things about the creative.

    Before the next creative lock, bring the media schedule, search team, analytics owner, web team, and campaign decision-maker into the same handoff. Leave with four concrete artifacts: a query inventory, a destination map, a scheduled paid-search plan, and a measurement sheet with baselines and comparison markets or periods.

    If one of those is missing, the campaign is not fully ready. The goal is not to make TV look like search or search look like TV. It is to ensure that the demand your commercial creates reaches a clear answer, and that each channel receives credit for the part of the journey it actually performed.

    References

  • Social and Commerce Ad Tools: A Practical Selection Guide

    You do not need another ad account. You need to know which part of the buying journey is failing: discovery, relevance, confidence, or checkout. Choose a tool before answering that question and you can buy plenty of activity without removing the constraint that is costing you sales.

    The useful decision is not whether Instagram, LinkedIn, YouTube, Pinterest, or Shopify is the best platform. It is which platform capability can perform one defined job for your audience, then hand that person to the next step without changing the subject.

    Choose the bottleneck before you choose the tool

    Start with the moment immediately before the result you want. If buyers never encounter your category, you have a discovery problem. If they see you but assume the offer is not for them, you have a relevance problem. If interested visitors do not trust the promise, you have a confidence problem. If they want the product but cannot find or buy the right item, you have a transaction problem.

    Those problems call for different tools. A high-attention video placement will not repair an incomplete product path. Dynamic personalization will not create demand for a category buyers do not understand. A commerce network can expose an item at a useful moment, but it cannot compensate for an offer that becomes confusing as soon as the shopper reaches the product page.

    • For discovery: use a visual or short-form surface capable of introducing the problem, category, or use case before the buyer searches for it.
    • For relevance: change the message for a meaningful audience characteristic, such as role, company, need, or viewing context.
    • For confidence: connect the ad to evidence that resolves the buyer’s next objection, not to a generic homepage.
    • For transactions: place the right product where demand already exists and reduce the distance between selection and purchase.

    Write a one-sentence campaign brief before opening a platform: “For this audience, this placement will remove this bottleneck, and we will judge it by this outcome.” If you cannot complete every part without using words such as “engagement” or “awareness” as a substitute for a business result, the campaign is not ready.

    Match each platform capability to a buying moment

    Several newer capabilities blur the boundary between social advertising, creator marketing, recommendation systems, and onsite merchandising. That does not make them interchangeable. It makes their assigned job more important.

    Buying momentUseful capabilityWhat it can changeWhat you should do
    A person is exploring an interestInstagram Reels and user-controlled topic preferencesInstagram’s Your Algorithm controls let people request more or less of a topic and add preferences. This is a user control, not an advertiser setting.Build each Reel around a recognizable subject and use case. Do not treat audience targeting as permission to make the creative vague.
    A B2B buyer is not yet searchingLinkedIn Reserved Ads, profile-based personalization, and AI creative variantsReserved placements are designed to make impressions more predictable, while personalization can use fields such as first name, job title, and company. AI Ad Variants can produce additional on-brand versions from one input.Use reserved delivery when reach predictability matters. Personalize the reason to care, then test it against a non-personalized control.
    A viewer encounters a creator recommendationYouTube Shorts comments and creator link-outsEligible Shorts ads can allow comments, and branded creator content can link to a brand website. Shorts placement has also expanded to mobile web.Send the viewer to the exact product, offer, or explanation shown in the Short. Assign someone to review comments for questions and objections.
    A shopper has a product need that one store cannot satisfyShopify Product NetworkContextually relevant products from other merchants can appear across participating stores, including in search results and on homepages. Cross-merchant items can enter a single cart, while referring merchants can earn cash commissions or ad credits.Assume your product may be evaluated outside your own storefront. Make the title, image, category, offer, and product-page promise understandable without your usual brand context.
    A person is collecting ideas and possible solutionsPinterest advertisingPinterest’s formats serve a platform built around inspiration and solution discovery.Choose the format from the campaign objective. The creative should show the desired outcome while the destination explains how to achieve or buy it.

    The sequence matters. Social discovery surfaces are useful when someone needs to notice or understand an option. Commerce placement becomes more useful when the need is already legible and product selection is the remaining task. In B2B, predictable feed exposure can establish familiarity before a self-directed buyer begins comparing providers.

    You can use more than one surface in the same journey, but do not assign all of them the same conversion target. A discovery placement should earn the next qualified action. A product placement should make the transaction easier. When every channel is judged as if it closed the sale alone, early-stage tools get cut too quickly and late-stage tools receive credit for demand they did not create.

    Build one continuous handoff from ad to answer

    The most common structural mistake is a message break. The ad speaks to one audience and problem; the destination opens with a broad corporate statement. The creative shows a specific item; the click leads to a collection page. The creator answers a practical question; the linked page makes the visitor reconstruct the answer from navigation and promotional copy.

    Build the handoff in this order:

    1. Name the entry context. Record what the person was watching, browsing, searching for, or trying to buy when the placement appeared.
    2. Make one promise. The ad should communicate one useful outcome or answer one immediate question. Additional benefits belong after the click.
    3. Continue that promise on the destination. Repeat the same product, category, audience, and use case near the start of the page. Do not make the visitor verify that the click worked.
    4. Expose the supporting facts. Put specifications, eligibility, limitations, proof, price conditions, availability, or process details where they can be evaluated before the primary action.
    5. Ask for the next proportionate action. A person discovering a new category may need an explanation or comparison. A shopper selecting a known item may be ready to add it to a cart. Do not force both into the same path.

    Apply personalization only where it changes meaning. Inserting a first name may attract attention, but it does not explain relevance. A job title can be useful if the problem, evidence, or next step genuinely differs by role. A company name is useful only when the surrounding sentence remains accurate and natural. Test the personalized version against a plain version so novelty is not mistaken for qualified interest.

    AI-generated ad variants need the same discipline. Give the system a fixed product identity, approved claims, audience, prohibited claims, call to action, and destination. Review every version that could change a price, capability, condition, or comparison. Producing more creative is valuable only when the variants test distinct ideas; dozens of cosmetic rewrites create volume without creating a useful experiment.

    Instagram’s preference controls create a particularly important distinction. People can influence the topics they receive, but a brand cannot command a place in those preferences. The practical response is topical clarity: make the subject, audience, and use case recognizable without relying on a clever opening that conceals what the content is about.

    YouTube comments can turn an ad into an objection log. Decide before launch who will review questions, what requires a response, and which recurring objections should be answered on the destination page. If comments repeatedly ask whether an offer works for a certain use case, the page should not leave that answer buried in a reply thread.

    Shopify’s cross-merchant model creates the opposite challenge: your product may appear in a storefront the shopper did not associate with your brand. Evaluate the product card and landing page as a self-contained unit. A title that only makes sense beside the rest of your catalog, or an image that depends on brand familiarity, will be fragile in a contextual network.

    This continuity also matters for SEO, answer-engine optimization, and generative-engine visibility. Advertising does not make a page authoritative or guarantee that an AI system will cite it. It can, however, reveal the words people use, the objections they raise, and the contexts in which a product becomes relevant. Use those observations to improve the public page a search engine or AI system can access.

    Keep machine-readable information aligned with the visible destination. If a page uses Product or Offer structured data, its product name, brand, identifier, availability, currency, price conditions, and offer details should not contradict the page or the ad. Structured data is a clarification layer, not a place to repair an unclear or inconsistent offer.

    Measure the constraint the tool was selected to remove

    A campaign should produce a decision even when it does not produce a win. That requires a primary metric tied to the assigned job and a diagnostic metric that explains what happened next.

    • For predictable reach: compare planned and delivered impressions for the defined audience, then inspect whether that exposure led to qualified visits or later branded activity. Delivery proves the placement ran; it does not prove that the message landed.
    • For personalization: compare personalized and non-personalized creative against the same downstream outcome. Click-through rate alone can reward curiosity. Qualified leads, useful page actions, or completed buying steps tell you whether relevance improved.
    • For creator and interactive video: separate viewing, commenting, outbound traffic, and downstream action. Read comments by theme rather than treating their count as approval. Questions, objections, confusion, and purchase intent require different responses.
    • For commerce placement: measure orders and acquisition cost, then account for the commission or credit economics attached to the network. A sale is not automatically a profitable sale, and a referring placement may have value even when the referring merchant did not supply the product.
    • For discovery: look for movement from exposure to an intentional next step, such as a relevant page visit, product exploration, or another action your analytics can observe. Do not present social engagement as evidence that AI search visibility improved.

    Use one controlled comparison at a time. If you change the audience, format, message, offer, and destination together, the result cannot tell you which decision helped. Start with the largest uncertainty: audience-message fit, creative angle, personalization, or destination handoff. Hold the other elements steady long enough to learn from that question.

    Set a spending cap you can afford before the test begins. Paid systems can optimize toward the event you provide, including an event that is easier to generate but less valuable than the business result. Confirm that the selected conversion represents a real step in the buying process, then examine the leads or orders behind the aggregate number.

    Keep platform status separate from campaign performance. LinkedIn’s Flexible Ad Creation was slated for early 2026, while Instagram described broader expansion of its preference controls beyond Reels. Availability can differ by account, placement, and market, so verify the feature inside the account before making it a dependency in your launch plan.

    Key takeaways

    • Choose the buying bottleneck first: discovery, relevance, confidence, or transaction.
    • Give each platform one accountable job instead of asking every placement to close the sale.
    • Treat Instagram preference controls as user agency, not as an additional advertiser-targeting switch.
    • Use LinkedIn personalization to change the reason to care, not merely to insert a person’s profile data.
    • Connect Shorts and creator placements to the exact answer, product, or offer shown in the video.
    • Prepare commerce listings to make sense outside your own storefront and brand context.
    • Use advertising feedback to improve public content, but do not claim that paid engagement causes SEO, AEO, or generative-engine visibility.

    Before your next launch, put six lines on one page: audience, bottleneck, platform capability, message, destination, and primary outcome. Add an affordable test cap and one controlled comparison. If the campaign cannot be explained on that page, adding another tool will make the uncertainty more expensive, not more manageable.

    References

  • Are ChatGPT App Suggestions Ads? How to Tell What You Saw

    Are ChatGPT App Suggestions Ads? How to Tell What You Saw

    If a Target or Peloton card appeared inside your ChatGPT experience, you weren’t unreasonable to read it as an ad. A brand logo, a shopping-oriented message, and a call to action are the same visual signals that advertising uses across the web.

    But appearance alone doesn’t tell you whether a brand paid for the placement. OpenAI’s stated position was that these were recommendations for apps on its platform, with no financial component and no live advertising test. That distinction matters to users deciding whether to trust the interface and to marketers deciding whether a new media channel actually exists.

    An ad-like recommendation is not necessarily a paid ad

    The word “ad” can collapse three different questions into one. Separate them before you judge a ChatGPT suggestion:

    • How does it look? A logo, prominent brand name, product message, or action button gives a suggestion a promotional appearance.
    • Why was it selected? The recommendation mechanism determines why one app or brand appeared instead of another. A screenshot normally cannot reveal that mechanism.
    • Was money involved? Payment, sponsorship, bidding, or another financial arrangement would support calling the placement advertising. Promotional presentation by itself does not prove any of them.

    The controversial suggestions clearly triggered the first question. Their presentation looked commercial. OpenAI denied the third: it said the recommendations had no financial component. The available information did not explain enough about the second question for anyone outside OpenAI to make a reliable claim about selection or ranking.

    The most accurate description is therefore narrower than either “ChatGPT launched ads” or “nothing happened.” Users encountered app recommendations with an ad-like presentation, while OpenAI maintained that the placements were unpaid.

    That wording doesn’t excuse the design. People interpret an interface through the signals it gives them, not through distinctions supplied after screenshots circulate. OpenAI acknowledged that it had fallen short and disabled the app suggestions while working on accuracy and better user controls. The response confirms that perceived promotion was a product and trust problem even under the company’s unpaid-recommendation explanation.

    Use this six-question test for any branded suggestion

    Hands use a magnifying glass to inspect visual clues on a generic digital recommendation card displayed on a tablet.

    You don’t need to accept a platform’s label blindly, but you also shouldn’t infer an advertising program from one brand card. Work through the visible evidence in order.

    1. What did you ask for? Save the prompt and the preceding messages. A relevant app suggestion after you requested help shopping is materially different from an unexplained retail card during an unrelated task.
    2. What label appeared? Record the exact wording, including terms such as “ad,” “sponsored,” “promoted,” “recommended app,” or “suggested.” No label is also a meaningful observation.
    3. What promotional elements were present? Note the logo, brand name, offer language, image, button text, and prominence relative to the answer. These elements establish how the placement was presented, even when they don’t establish payment.
    4. Where did the action lead? Check whether the button opens an app within ChatGPT, starts an installation flow, or sends you to an external merchant. The destination helps identify the surface you are evaluating.
    5. Is a financial relationship disclosed or confirmed? Look for an explicit sponsorship disclosure or a clear platform statement about payment. If neither exists, the economics are unknown. Don’t convert “unknown” into either “paid” or “organic.”
    6. Could you control it? Check for dismiss, hide, feedback, personalization, or recommendation controls. Record whether the choice applies to one card or to future suggestions. A dismiss button reduces immediate friction; it does not answer how the placement was selected.

    This test gives you defensible language for reporting what happened. Use confirmed paid placement only when payment or sponsorship is established. Use unpaid app recommendation with promotional presentation when the platform denies a financial component but the interface resembles an ad. Use unexplained branded suggestion when neither the selection process nor the economics is known.

    A single screenshot can document that a placement appeared. It cannot, by itself, prove broad availability, personalization, targeting, payment, ranking criteria, or a permanent product launch. Keep each claim within the evidence you captured.

    What to do when a suggestion crosses the line for you

    If you’re a ChatGPT user, a precise report is more useful than a general accusation that the product is “showing ads.” It lets the product team identify the prompt, placement, label, and missing control that created the problem.

    1. Capture the complete context. Save the prompt, relevant earlier messages, full recommendation, visible label, account tier, and destination. Include the time if you are reporting an intermittent experience. Redact personal or commercially sensitive information before sharing a screenshot publicly.
    2. Describe the mismatch. State whether you asked for shopping help, an app, or a brand recommendation. If the suggestion was irrelevant, name the task it interrupted.
    3. Describe the presentation. Instead of relying only on the word “ad,” identify the elements that made it feel paid: logo, retail language, button, placement, repetition, or lack of separation from the answer.
    4. Use available feedback and controls. Dismiss or hide the card if those options are present, then report whether the preference persists. If no meaningful control exists, say that explicitly.
    5. Ask the questions the interface didn’t answer. Was the placement paid? Why was this app selected? Did the recommendation use conversation context? Can similar suggestions be disabled? These are separate questions and deserve separate answers.

    Don’t infer a privacy violation merely because a branded card appeared. The card may give you a reason to ask how relevance was determined, but it does not prove that personal data was sold, shared with the brand, or used for behavioral targeting. Those claims require evidence beyond the visual placement.

    Paying for ChatGPT can make an unexpected commercial-looking prompt feel especially intrusive, but subscription status doesn’t reveal the placement’s economics either. Keep the complaint focused on what can be established: the suggestion appeared, it looked promotional, it was or wasn’t relevant, and the interface did or didn’t provide adequate disclosure and control.

    Marketers should classify the surface before claiming a win

    A marketing analyst compares three unlabeled display panels representing organic, partnership, and paid app exposure.

    For marketers, the biggest immediate risk is not missing an ad opportunity. It is reporting an app suggestion as paid media, organic visibility, or GEO performance without evidence for any of those classifications.

    SurfaceEvidence you needHow to report it
    Brand mention in an answerThe generated response names or discusses the brandAI brand visibility; do not call it paid or organic unless the mechanism is known
    App suggestionA distinct app card, logo, recommendation label, or app-opening actionApp recommendation, with its label, prompt context, and destination recorded
    Paid advertisementA confirmed financial component, sponsorship disclosure, or explicit ad labelAdvertising, separated from answer visibility and app discovery

    That separation prevents three common errors.

    • Don’t create a media budget from screenshots. OpenAI said the disputed suggestions were unpaid and that no live ad test was running. Without inventory, buying terms, targeting options, pricing, or reporting, there is no verified advertising product to plan against.
    • Don’t claim an AI optimization result without a selection model. A brand’s appearance does not reveal whether content, app metadata, platform integration, prompt context, an experiment, or another factor caused the selection. If the mechanism is unknown, attribution is unknown.
    • Don’t merge app referrals with answer visibility. A click from an app card and a brand citation inside a generated answer are different user journeys. Track them separately if your analytics can identify them, and leave the source unclassified when it cannot.

    If your organization has an app available through ChatGPT, review the experience from the user’s side. The app name should make its purpose clear. The call to action should accurately describe what happens next. The destination should match the promise in the card. And the experience should not depend on users mistaking a recommendation for a neutral part of the answer.

    Actual advertising, if it arrives later, should be evaluated as a separate product. OpenAI’s advertising initiatives were reported as delayed while the company prioritized ChatGPT quality. A delayed initiative is not live inventory, but it is not a guarantee that advertising will never launch. Wait for verified buying documentation and visible disclosure rules before treating it as a channel.

    A credible AI advertising product would need to answer practical questions before a marketer commits money: What is sponsored? Where can it appear? How is it separated from the generated answer? Why was it shown? Can a user dismiss or disable it? What does the advertiser receive in reporting? Until those answers exist, planning should remain a scenario exercise rather than a forecast.

    Key takeaways

    • The Target and Peloton-style suggestions looked like ads because they used familiar promotional signals, including brand identity and calls to action.
    • OpenAI said the placements were app recommendations with no financial component and denied that live advertising tests were underway.
    • An ad-like appearance establishes a transparency concern, not a paid relationship. Payment, selection, and presentation are separate questions.
    • Users should capture the prompt, label, card, destination, relevance, and available controls before reporting a questionable suggestion.
    • Marketers should report answer mentions, app recommendations, and confirmed paid ads as separate surfaces.
    • No brand should treat a screenshot as proof of ad inventory, GEO performance, targeting, or a repeatable ranking advantage.

    For the next branded suggestion you encounter, don’t start with the argument over what to call it. Capture what appeared, test what the interface discloses, and classify only what the evidence supports. That gives users a sharper complaint and marketers a cleaner decision than the word “ad” can provide on its own.

    References

  • Google’s EU Ad Tech Market Test: A Practical Playbook

    Google’s EU Ad Tech Market Test: A Practical Playbook

    If your revenue or media spend passes through Google’s ad stack, the EU market test is not regulatory background noise. It is a chance to determine whether proposed controls would change auction economics or merely add options that look meaningful in a settings screen.

    Your immediate job is to capture a reliable baseline, identify where Google-owned and independent tools receive materially different treatment, and turn those observations into reproducible evidence. Do that before configurations or platform behavior change, and you will be able to judge the remedy on results rather than promises.

    This is an evidence phase, not a finished remedy

    The European Commission is seeking feedback from publishers, advertisers, and competing ad tech providers on Google’s proposed commitments. The market test follows a €2.95 billion fine and an instruction for Google to stop favoring its own ad tech services.

    The proposal centers on three practical areas: more publisher control over minimum bid prices in Google Ad Manager, better interoperability between Google and competing ad tech products, and broader choice for advertisers and publishers. These are commitments under evaluation, not proof that auction behavior has already changed.

    Keep three states separate when you brief colleagues or make platform decisions:

    • Proposed: Google has described a control, connection, or choice it intends to provide.
    • Usable: the affected account can access the feature and apply it to a real workflow without an impractical workaround.
    • Effective: the change produces observable differences in auction access, pricing, reporting, or the ability to choose another provider.

    A control can pass the second test and fail the third. A publisher might receive a new floor-setting option, for example, while remaining unable to verify how that rule affects different demand paths. Likewise, an integration may technically connect while losing fields, timing out, or producing reports that cannot be reconciled.

    That distinction matters because stakeholder feedback will help determine whether the commitments can restore fair competition. If Brussels concludes that they are sufficient, the market test could help bring the case to a close. The enforcement stakes are substantial: antitrust breaches can draw penalties of up to 10% of global revenue, although penalties at that level are uncommon. For your operating plan, however, the important question is narrower: can you observe and use the promised competitive choice?

    Build the baseline you will need to detect a real change

    An analyst compares two matching digital auction setups in transparent test enclosures using synchronized instruments and identical inventory and bidder components.

    If you wait for a new setting to appear before deciding what to measure, you will lose the cleanest point of comparison. Capture the current state now. You do not need an elaborate research program; you need a dated record that another person can reproduce.

    Start with a map of the transaction path. For each meaningful inventory or campaign segment, record which product handles the buy-side decision, marketplace or exchange connection, auction, ad serving, and reporting. Mark each Google-owned component and every independent alternative. This shows you where interoperability and switching claims can actually be tested.

    Then preserve the configuration and performance context:

    • Export or capture the bid-floor rules that are currently active, including their inventory scope, geography, device, format, demand eligibility, and effective date where those dimensions apply.
    • Record which demand sources are eligible for each tested inventory segment and which settings or policies can exclude them.
    • Save the connection settings used by independent tools, including mappings, permissions, and dependencies that could affect participation or reporting.
    • Select the metrics relevant to your side of the market. Publishers may need total revenue, revenue per comparable inventory opportunity, fill, effective CPM, bid participation, bids per auction, latency, and demand-source mix. Buyers may need eligible opportunities, bid rate, win rate, delivery, clearing cost, discrepancies, and reporting completeness.
    • Preserve the filters, time boundaries, time zone, attribution rules, and report definitions. A screenshot of a headline metric without its denominator is weak evidence.
    • Annotate known changes in traffic, demand, campaign mix, consent status, seasonality, pricing, or site configuration. Otherwise, an unrelated commercial shift can be mistaken for a remedy effect.

    Choose the decision rule before you run a comparison. “Performance improved” is too vague. A useful rule might ask whether an independent demand source gained access to previously ineligible opportunities without a material increase in errors, or whether a publisher floor changed total revenue per comparable opportunity rather than only the CPM displayed for impressions that still cleared.

    Keep raw logs and contract-sensitive information inside your controlled environment. If evidence will leave the company, have the appropriate legal, privacy, and commercial owners review it first. A sanitized reproduction, supported by retained internal records, is safer than distributing user-level data or confidential terms.

    Publishers should test bid-floor control against total yield

    Google has proposed giving publishers more control over minimum bid prices in Google Ad Manager. That could be commercially meaningful, but access to a floor control does not guarantee higher revenue or fairer treatment across demand sources.

    A higher floor can raise the price of impressions that continue to sell while reducing the number of bidders or impressions that clear. That is why CPM alone is a poor success metric. If the displayed CPM rises while fill or bid participation falls, total yield may be unchanged or worse.

    Use a controlled sequence when the relevant control becomes available:

    1. Choose a narrow, stable cohort. Isolate an inventory segment with enough activity to evaluate, but do not begin with a site-wide commercial change.
    2. Freeze the comparison definition. Record the inventory, demand eligibility, floor logic, reporting filters, and business metrics before changing anything.
    3. Change one commercial variable. Avoid altering the floor, demand stack, consent setup, page layout, and traffic allocation at the same time.
    4. Measure the whole auction outcome. Review total revenue per comparable opportunity, fill, effective CPM, bidder participation, demand mix, latency, and unfilled inventory together.
    5. Inspect treatment by demand path. Determine how the rule applies to Google-owned and independent demand under comparable, eligible conditions. Document legitimate policy or configuration differences instead of assuming every difference is self-preferencing.
    6. Retain a rollback state. A floor experiment can carry real revenue risk, so preserve the previous configuration and define the condition that will trigger a reversal.

    Pay particular attention to observability. Can you tell which floor applied, which buyers were eligible, which bids were excluded, and why an opportunity did not clear? If the platform offers a control but withholds the reporting needed to evaluate its effect, name the missing screen, field, or event and the decision it prevents you from making. That is more useful than saying the system feels opaque.

    Do not define fairness as an identical outcome for every bidder. Different bids, policies, eligibility rules, and technical performance can produce different results. The test is whether comparable demand paths can compete under understandable rules and whether you can identify the reason for a material difference.

    Interoperability must survive the entire transaction path

    A cutaway corridor shows one luminous ad transaction passing through consent, identity, auction, bidder, verification, and placement modules from end to end.

    Google has also offered better interoperability with competing ad tech providers and more choice for buyers and sellers. An integration should not be judged by whether two systems can establish a connection. It should be judged by whether an independent provider can complete the commercially relevant workflow.

    Build a small test matrix around the points where an integration can quietly lose value:

    • Setup: Can the independent product connect using documented settings and permissions, or does it require a manual exception that is unavailable or impractical at scale?
    • Eligibility: Can it participate in the intended opportunities when account settings, inventory, policy, and buyer eligibility are comparable?
    • Data preservation: Do the fields needed for auction decisions, measurement, and reconciliation arrive with consistent meanings?
    • Timing: Does the connection complete within the applicable auction path, and are timeouts visible rather than silently classified as no-bids?
    • Error handling: Can your team identify whether a rejection came from policy, configuration, eligibility, mapping, or a technical failure?
    • Reporting: Can the two sides reconcile opportunities, bids, wins, spend, revenue, and fees closely enough to operate the relationship?
    • Switching: Can you move a meaningful workflow to an independent provider without losing essential auction access, controls, or measurement merely because you changed vendors?

    Choice is not meaningful when the alternative exists only in theory. If changing providers forces you to surrender a critical report, accept materially weaker auction access, or rebuild routine operations by hand, document that dependency. The useful question is not “Can we select another vendor?” It is “What commercial capability do we lose when we select one?”

    When you find a difference, resist jumping directly to motive. First rule out configuration, policy, traffic quality, inventory, buyer settings, and ordinary technical failure. Then reproduce the result under controlled conditions. Record the account context, market, inventory or campaign type, configuration, timestamp, expected behavior, observed behavior, error output, frequency, and financial or operational consequence.

    A single failed request may be a bug. A repeatable pattern tied to a specific interface, rule, or product path is stronger evidence. Quantify the affected opportunity or spend where your own records support it, and keep assumptions separate from measured results. This gives regulators, platform teams, and your own decision-makers something they can investigate.

    Key takeaways for the market-test window

    • The market test is evaluating proposed remedies; it is not proof that Google’s ad tech behavior has already changed.
    • The practical commitments concern publisher bid-floor control, interoperability with competing tools, and meaningful choice for advertisers and publishers.
    • A new setting matters only when it is usable, observable, and capable of changing a commercial outcome.
    • Capture configurations, transaction paths, metrics, filters, and known confounders before testing any new behavior.
    • Publishers should judge floor changes by total yield and auction participation, not CPM in isolation.
    • Buyers and independent providers should test the full transaction path: setup, eligibility, data, timing, errors, reporting, and switching.
    • Strong feedback identifies a reproducible mechanism and consequence. It does not rely on a screenshot, a general complaint, or an assumption about intent.

    Assign one owner to create the baseline and one technical-commercial pair to define the first test cases. Produce a one-page plan naming the workflow, comparison cohort, metrics, confounders, rollback condition, and evidence to retain. Then, when a commitment reaches your account, you can answer the only question that matters: did it make competition work differently?

    References

  • Ad Targeting and Campaign Transparency: A Control Framework

    You can launch a campaign with a tightly defined audience and still be unable to answer basic questions: Who supplied the audience data? Which campaign types may use it? What exactly was disapproved? Are weak conversion numbers real, or are conversions still arriving?

    Those gaps lead to blunt fixes: replacing an entire audience, rebuilding an ad, cutting a budget, or changing bids before the evidence is ready. A better approach is to make every campaign traceable from audience origin to measurement maturity.

    Key takeaways

    • Targeting transparency starts with audience provenance: who supplied the data, which identifiers were used, who authorized the partner, and where the resulting list may serve.
    • Hashing is a data-handling step. It does not document permission, ownership, or the reason your organization may use the audience.
    • Asset-level policy status lets you isolate a rejected image, headline, or text asset instead of diagnosing the whole campaign as broken.
    • Conversion reporting lag must travel with every performance report. A recent click cohort and a mature cohort are not directly comparable.

    Make every audience traceable before it can serve

    An audience name is not an audit trail. Labels such as “high-value customers” or “likely buyers” tell the campaign operator what a segment is supposed to represent, but they do not show where it came from, whether it is still valid, or which party handled the underlying data.

    Partner Match makes that distinction especially important. Under the targeting method, approved partners can upload hashed identifiers such as email addresses, names, and ZIP codes, which Google matches with signed-in YouTube accounts. The advertiser uses the resulting audience, but another party performs the upload. Your internal record therefore needs to identify both the advertiser responsible for the campaign and the partner responsible for the data handoff.

    Create an audience ledger before anyone adds the list to a campaign. Give each audience one stable record containing:

    • A unique internal audience name and the corresponding platform list name.
    • The business purpose of the segment and the campaign objective it is intended to support.
    • The internal owner who approved its use.
    • The data partner responsible for preparing or uploading the identifiers.
    • The source of the underlying records and the identifier types included.
    • The date of the last upload or refresh, plus the person responsible for the next review.
    • The campaign types, channels, and countries in which the list is eligible to serve.
    • Links or locations for authorization, applicable terms, privacy review, and change history.

    The activation record should mirror the actual setup. Advertisers using Partner Match must authorize the data partner, accept the Partner Match terms, and apply the generated audience list during campaign setup. Record those as three separate checkpoints. If authorization exists but the list was never attached to the intended campaign, the campaign has a configuration problem. If the list is attached but no one can produce the authorization, it has a governance problem. Those failures require different owners and different fixes.

    Eligibility deserves its own field because an available audience is not automatically usable in every YouTube campaign. Partner Match supports Video Reach campaigns, Video Views campaigns, and Demand Gen campaigns limited to the YouTube channel. It does not support ad sequences or YouTube Select guaranteed deals. If a planner chooses an unsupported format, changing the audience bid or waiting for more volume will not solve the problem. The campaign structure has to change.

    Geography can create another quiet mismatch. The stated rollout excludes the UK, Switzerland, and the EEA, although advertisers in those regions may reach audiences in eligible countries. A ledger entry that merely says “global” hides the distinction between the advertiser’s region and the audience’s target country. Record both, and verify availability in the account before launch because platform eligibility can change.

    Do not let the word “hashed” close the privacy review. Hashing changes how identifiers are transferred and matched; it does not show where the records originated or why they may be used for advertising. If the accountable privacy or legal owner cannot verify that basis for a particular audience, do not activate the list until the issue is resolved. The downside is not merely weaker performance. It is losing control of customer data across organizational and partner boundaries.

    Treat asset status as component diagnosis, not campaign diagnosis

    Campaign transparency often breaks at the creative layer. A broad “disapproved” status can send the team into a full rebuild even when one image, headline, or text asset is the only blocked component.

    Microsoft Ads can expose disapproval at the individual image, headline, or text-asset level. That visibility narrows the incident: identify the rejected component, address it, and leave unrelated parts of the campaign alone when they remain eligible. It also preserves a cleaner test history because a local policy problem does not have to become an unnecessary campaign-wide creative change.

    Use a three-level status record whenever an ad has multiple assets:

    • Asset level: Which exact image, headline, or text item has a policy issue?
    • Ad level: Which combinations depend on that asset, and are alternative combinations still eligible?
    • Campaign level: Is the campaign serving, limited, or unable to serve after the asset-level decision?

    Then use a constrained remediation sequence:

    1. Capture the affected asset’s identifier, status, and visible reason before editing it.
    2. Confirm whether the issue is isolated to that component or affects the ad or campaign container.
    3. Replace or correct only the blocked component when valid alternatives can remain active.
    4. Record what changed, who approved it, and when it was resubmitted.
    5. Verify both policy status and actual delivery after the change. A corrected asset and a serving campaign are related checks, not the same check.

    Keep policy remediation separate from creative optimization. Approval means an asset may serve; it does not mean the asset persuades the audience or improves campaign performance. Mixing those questions makes it difficult to tell whether a result changed because the ad became eligible, the message improved, or delivery shifted.

    Put conversion maturity next to every performance number

    A campaign can be transparent about its targeting and creative status while still producing a misleading performance report. The common failure is timing: clicks are visible before all associated conversions have been recorded, especially when the conversion happens later or arrives through an offline process.

    Microsoft Ads provides a useful control by showing how long it takes for 90% of post-click conversions to be recorded, including online and offline conversions. This is a measurement-maturity indicator, not a conversion-rate metric. It tells you when a click cohort is sufficiently developed for a more stable reading.

    Attach that lag window to the report instead of leaving it in a separate interface. For each analysis, record the end date of the click cohort, the date the report was produced, and whether enough time has passed to reach the 90% reporting point. Then apply four rules:

    • Label a cohort “preliminary” while it is younger than the observed reporting-lag window.
    • Compare campaigns or periods at the same conversion age. Do not compare yesterday’s immature clicks with an older cohort whose conversions have had time to arrive.
    • Delay major bid, budget, or pacing judgments until the selected cohort reaches the maturity point, unless an immediate operational risk requires intervention.
    • Keep monitoring after the 90% point. By definition, that marker is not the same as complete reporting.

    This distinction prevents two opposite mistakes. You are less likely to cut a campaign whose conversions are merely late, and less likely to excuse genuinely weak performance once the relevant cohort has matured. It also makes cross-channel reporting more honest: each platform can be evaluated using its own observed lag rather than a shared reporting date that implies equal completeness.

    Turn the campaign into an evidence chain

    The most useful campaign record is not another dashboard. It is a compact evidence chain that connects the audience decision, serving eligibility, creative state, and measurement window. A reviewer should be able to move through it without guessing which team owns the next answer.

    Control gateEvidence to captureAction when evidence is missing
    Audience provenanceData origin, internal owner, partner, identifier types, authorization, terms, and refresh historyDo not activate or refresh the audience until ownership and permitted use are verified
    Serving eligibilityCampaign type, channel, advertiser region, target country, and applicable exclusionsChoose an eligible campaign structure or a different targeting method
    Creative eligibilityAsset-level status, affected ad combinations, remediation owner, and verification timeIsolate and correct the blocked component, then confirm campaign delivery
    Measurement maturityClick-cohort end date, report date, conversion-lag window, and preliminary or mature labelDefer performance conclusions or state clearly that the result is incomplete

    Add a decision log beneath those gates. Each entry needs the observation, the evidence available at that moment, the action taken, the owner, and the next review point. This protects you from hindsight errors. If conversions improve later, you can see whether the earlier budget decision used immature data. If delivery stops, you can distinguish an audience-eligibility mismatch from an asset disapproval without reconstructing the campaign from memory.

    Start with your next campaign rather than trying to repair the entire account at once. Create the audience ledger before setup, capture asset status at launch, and put the conversion-maturity date on the first performance review. Once those controls are part of the workflow, targeting becomes explainable and campaign changes become easier to defend.

    References