Author: shivamcrushpressai

  • Google Workspace Integration for AI Agents: A Safe Rollout

    Google Workspace Integration for AI Agents: A Safe Rollout

    You want an AI agent to use the briefs, reports, presentations, and messages already inside Google Workspace. The difficult part is not giving it access. It is deciding what the agent may read, what it may prepare, and what it may change without turning a convenient workflow into an uncontrolled one.

    The safest useful integration starts with one bounded job. Give the agent the minimum context needed for that job, send its output to a review destination, and add approval exactly where an action becomes consequential. Once that path works reliably, you can expand it without guessing which permission or instruction caused a problem.

    Choose the job before you connect the apps

    Google Workspace access can cover several materially different capabilities. An agent may be able to send email and create or retrieve documents. It may also be able to read or write spreadsheet data and extract context from presentations. That does not mean every workflow needs all of them.

    Start by placing the proposed workflow in one of three operating modes:

    • Context mode: The agent retrieves approved material and uses it to answer a question, summarize a campaign, or prepare an analysis. It does not change Workspace data.
    • Draft mode: The agent creates a new review artifact, such as a status report, content brief, proposed spreadsheet update, or email copy. A person decides whether the draft moves forward.
    • Action mode: The agent changes a shared spreadsheet, updates a working document, or sends a message. The result affects other people or systems immediately.

    Use the lowest mode that completes the job. If a content strategist only needs a brief assembled from an approved deck and a campaign document, the agent does not need Gmail sending or spreadsheet write access. If an account lead needs a weekly report, the agent can read the relevant sheet and create a new review document without editing the underlying data.

    This distinction prevents a common design mistake: treating app access as the workflow. Connecting Docs, Sheets, Slides, and Gmail tells you where the agent can operate. It does not define what a successful task looks like, which material is authoritative, or who is accountable for the final action.

    Give every agent workflow an explicit contract
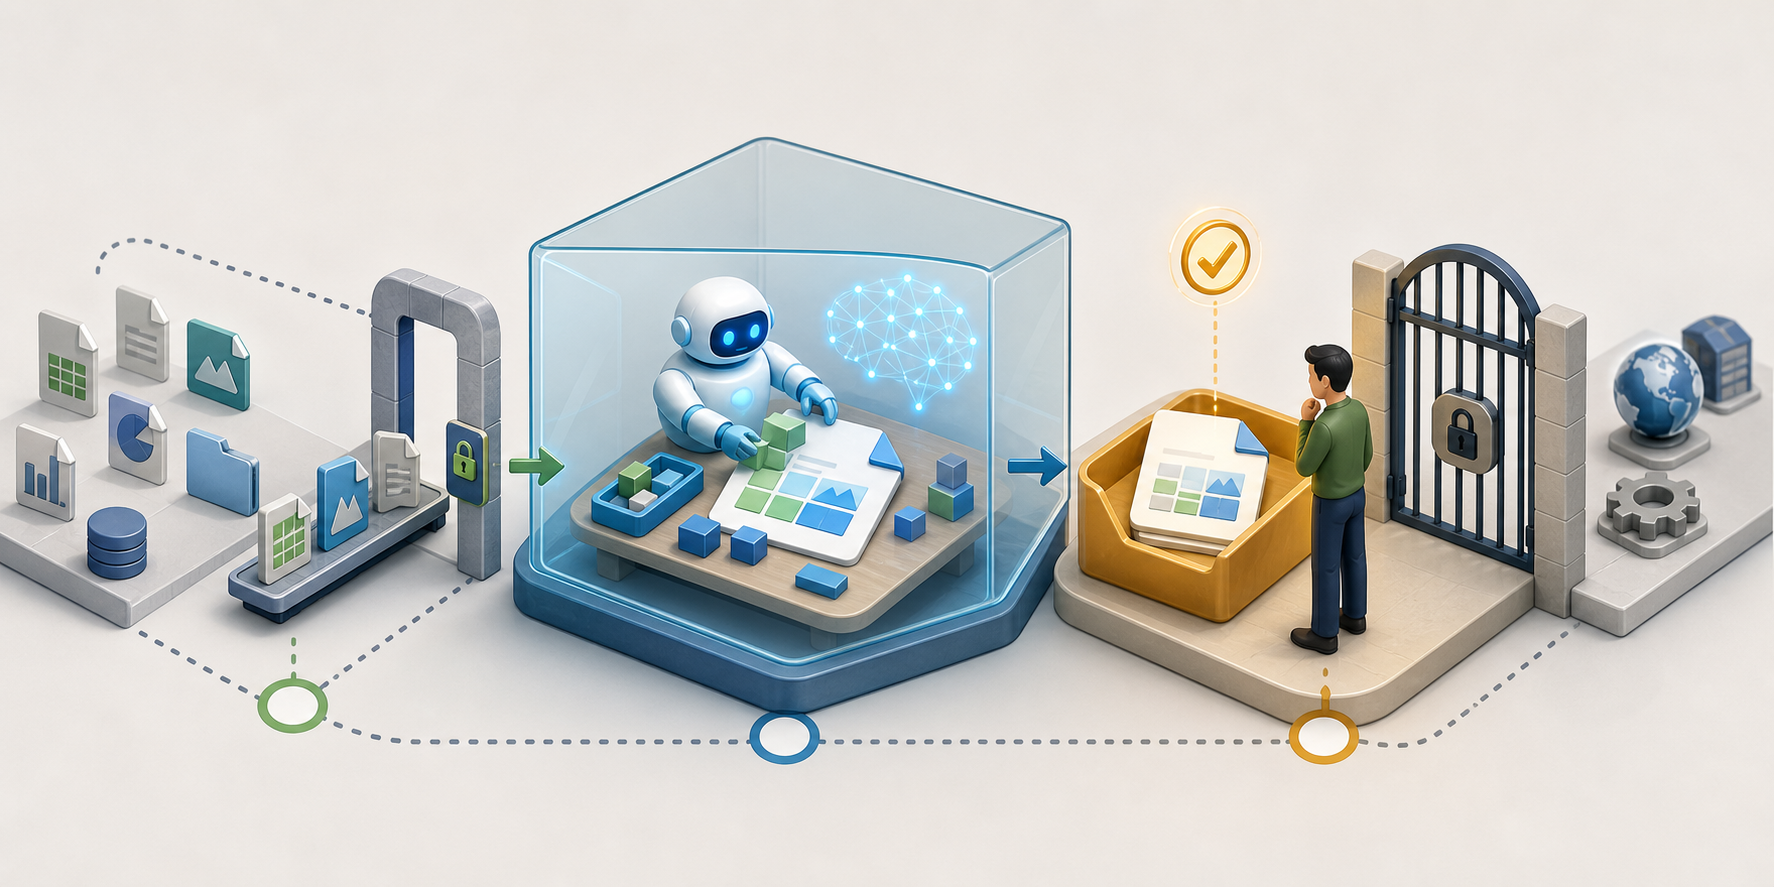
    A limited set of files enters an AI drafting sandbox, where the resulting draft is held for human review before a closed action gate.

    An instruction such as “prepare the client update” leaves too much unresolved. The agent still has to infer which client, which files, which reporting period, which template, and whether “prepare” means draft or send. A workflow contract removes those decisions from the model.

    Define these elements before granting access:

    1. Trigger: State what starts the workflow. It could be a direct request, a defined status in a tracker, or another unambiguous event.
    2. Input boundary: Name the folders, documents, presentations, spreadsheet tabs, or approved messages the agent may use. “Search the drive” is not a useful boundary.
    3. Authority order: Tell the agent which artifact wins when two files disagree. For example, an approved messaging document may take precedence over an older presentation.
    4. Transformation: Describe the work to perform: extract facts, compare values, draft copy, populate a template, or identify missing information.
    5. Output destination: Specify whether the result belongs in a new document, a review queue, a designated spreadsheet area, or a proposed email.
    6. Approval rule: Identify which person or role must approve the result before it is sent or written into a shared source of truth.
    7. Failure behavior: Tell the agent to stop and report missing, conflicting, or ambiguous inputs instead of filling gaps with plausible text.

    A bounded reporting workflow might read like this: use only the named campaign sheet and approved strategy documents; create a new status report in the review location; show which artifacts supplied each material claim; list missing fields separately; do not edit the source sheet or send any message.

    That contract is more valuable than a long general prompt. It gives you observable checkpoints. If the result is wrong, you can determine whether the problem came from retrieval, conflicting context, transformation, or an unauthorized action. Without those boundaries, every failure looks like a vague “AI problem.”

    Treat reading, drafting, and committing as different risks

    A summary can be corrected before anyone uses it. A sent email or an incorrect update to a shared spreadsheet can affect colleagues, clients, and downstream work immediately. Your controls should become stricter as the agent moves from observing information to committing a change.

    Operating modeAgent behaviorSensible default control
    ReadRetrieve approved documents, presentation context, or spreadsheet valuesLimit retrieval to named locations and require a record of the artifacts used
    DraftCreate a new review document containing proposed copy, analysis, or changesWrite only to a designated review destination and mark the result as a draft
    CommitSend a message or alter shared working dataValidate the target, require explicit approval, and record the completed action

    Keep the permission set aligned with the mode. A read-only research workflow should not retain write access “in case it is useful later.” An agent that drafts outreach copy does not need permission to send it. A reporting agent should not be able to edit every spreadsheet merely because its assigned report uses one of them.

    For workflows that eventually need action access, put the approval gate after the draft is visible but before the change is committed. The reviewer should be able to inspect the destination as well as the content. Correct copy addressed to the wrong recipient is still a failed action. Correct data written into the wrong tab or field can be equally disruptive.

    Use these controls at the action boundary:

    • Restrict access to the smallest useful set of folders, files, spreadsheets, and communication functions.
    • Prefer creating a new review artifact over overwriting an existing one.
    • Show the intended recipients, file, tab, and destination before approval.
    • Require a fresh approval when the content or destination changes after review.
    • Record what the agent read, what it produced, who approved it, and what action followed.
    • Maintain a clear way to pause the workflow and revoke its access when behavior is unexpected.

    Do not use a broad permission as a substitute for workflow design. If the connector cannot isolate the resources or actions your job requires, keep the workflow in draft mode. Manual transfer is safer than granting access whose consequences you cannot bound.

    Make Workspace context precise and auditable
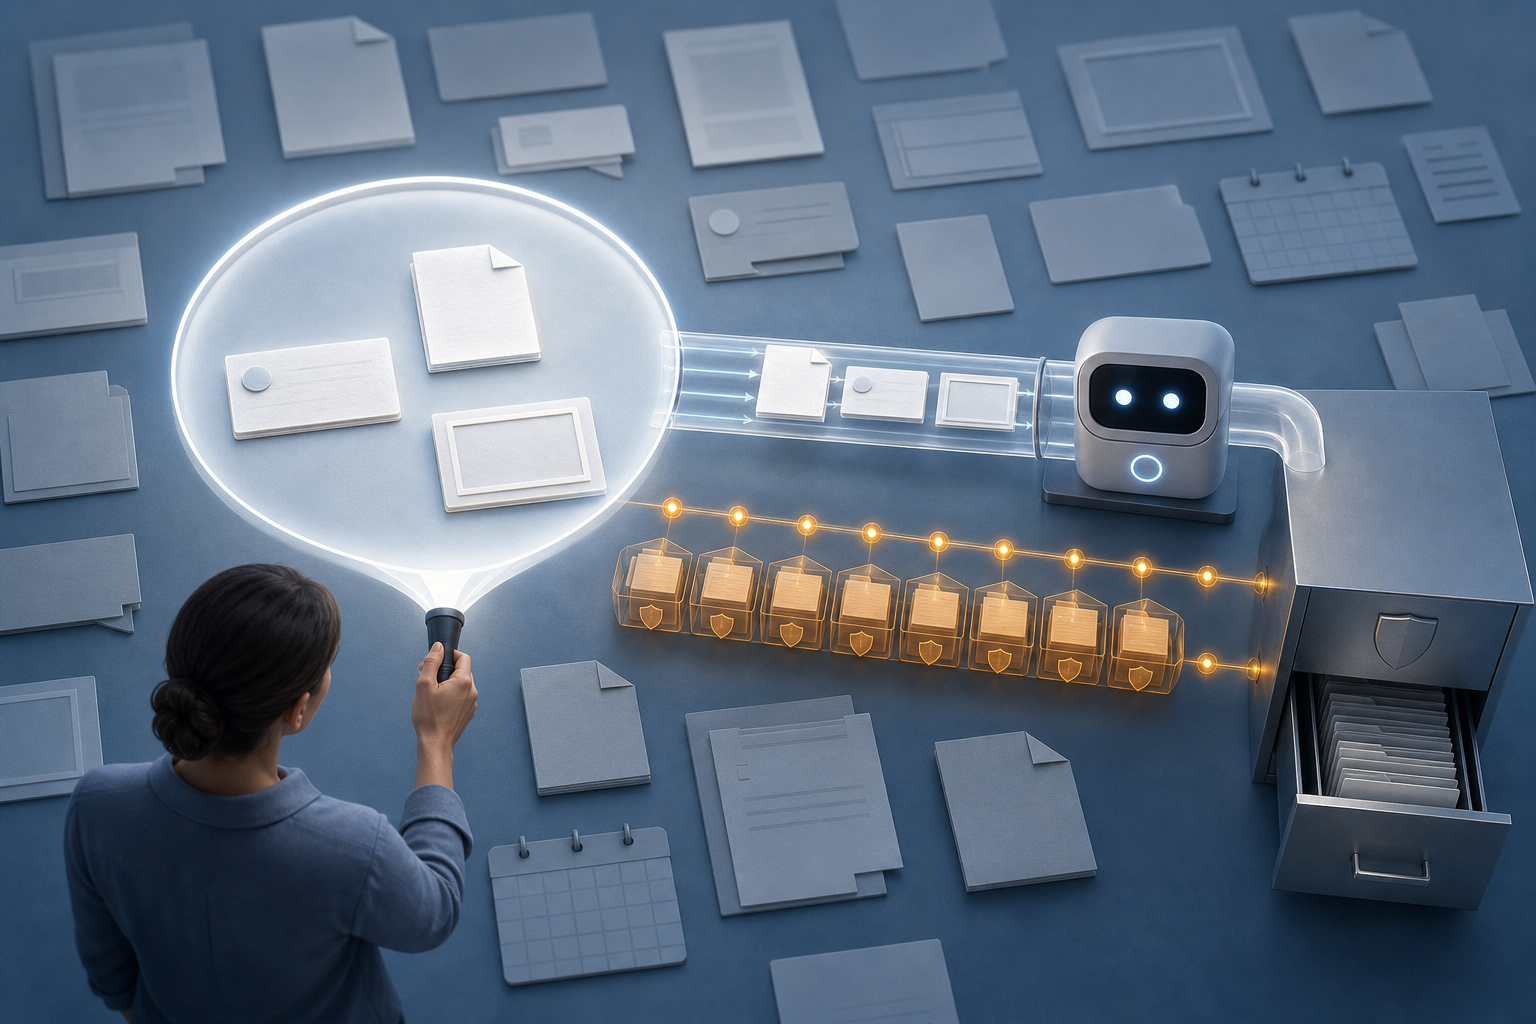
    A person selects a few relevant workspace items for an AI assistant while excluded files remain outside the access boundary and an audit trail leads to a secure archive.

    Connecting an agent to more files does not automatically improve its answer. Extra context can introduce duplicate documents, outdated messaging, conflicting numbers, and material that belongs to a different client or campaign. Retrieval needs its own design.

    Build a small context map for each workflow. Name the approved inputs, what each one contributes, and how conflicts should be handled:

    • Documents: Identify the approved brief, policy, template, or messaging file. Do not rely on a title that could match several drafts.
    • Presentations: Specify the deck and the parts relevant to the task. If the workflow depends on notes, links, or material outside visible slide text, verify that the integration actually exposes it before relying on it.
    • Spreadsheets: Name the tab and fields the agent should interpret. Explain unusual headers, calculated fields, status values, and blank cells instead of expecting the agent to infer their business meaning.
    • Email: Separate retrieving approved correspondence from sending a new message. Define which conversations may supply context and which addresses may receive output.

    A spreadsheet deserves particular care. It may look structured to a person while still being ambiguous to an agent. Repeated header rows, unlabeled columns, free-form notes, mixed date formats, and formulas beside manual values can all change what a cell means. Clean the specific input area or provide an explicit field map before using it for an automated decision.

    Require the output to preserve a source trail. For a report or brief, the agent should name the document, deck, or spreadsheet area behind each material section. It should also flag conflicts instead of silently choosing whichever version it retrieved first. This makes review faster and gives you a practical way to correct the context map.

    A useful instruction pattern is: Use only the listed Workspace artifacts. For each material claim, identify the artifact that supports it. If approved inputs conflict or required information is absent, place the issue in a review list and do not resolve it by assumption.

    That requirement matters for content and search workflows. An agent can assemble a polished brief from weak or outdated inputs just as easily as it can assemble one from approved material. Fluency is not provenance. Before a draft enters your publishing, SEO, AEO, or GEO process, a reviewer should be able to see which business facts and positioning statements shaped it.

    Key takeaways

    • Start with one bounded business job, not a blanket connection to every Workspace app.
    • Choose context, draft, or action mode and grant only the access that mode requires.
    • Define the trigger, approved inputs, authority order, output destination, approval rule, and failure behavior before launch.
    • Put human approval immediately before an email is sent or shared data is changed.
    • Require a source trail so reviewers can connect the agent’s output to the document, presentation, or spreadsheet data behind it.
    • Expand access only after the existing workflow is reliable, reviewable, and easy to stop.

    Use a controlled rollout sequence

    Your first workflow should be useful but recoverable. A strong starting point is a context or draft task that reads from a small approved collection and creates a new review document. A poor starting point is autonomous external email or unrestricted editing of a shared operational spreadsheet.

    1. Map the manual task. Write down what starts it, which artifacts a person consults, what judgment is required, and where the finished work goes.
    2. Remove unnecessary access. If an app or folder does not contribute to that exact path, leave it disconnected.
    3. Run in context mode. Check whether the agent retrieves the correct material and reports conflicts or missing information.
    4. Add a review artifact. Let the agent create a new document or other staged output without altering the underlying sources.
    5. Evaluate human corrections. Separate factual corrections from tone changes and formatting preferences. Factual corrections indicate a context or interpretation problem.
    6. Add one action boundary if needed. Introduce a single approved send or write operation, with the destination visible before commitment.
    7. Expand one dimension at a time. Add another data source, destination, or action only after you can explain the current workflow’s behavior.

    Measure reliability, not activity

    Counting generated documents or processed requests tells you how busy the integration is, not whether it is helping. Track signals that expose the quality of the workflow:

    • Completion without repair: Did the workflow reach the intended review destination without someone rebuilding the result?
    • Correction burden: Which facts, recipients, destinations, or spreadsheet interpretations required human changes?
    • Context accuracy: Did the agent use only the approved artifacts and identify conflicting information?
    • Action accuracy: When an action was approved, did it affect the intended message, file, tab, or field?
    • Traceability: Can a reviewer reconstruct the inputs, output, approval, and final action?
    • Safe stops: Did the agent halt when information or authority was missing instead of improvising?

    Pick one recurring workflow and write its contract before connecting anything else. If you cannot state exactly what the agent may read, where it may write, and when it must stop, keep the task in draft mode. That boundary gives you a useful integration now and a defensible path to broader automation later.
    References

  • Why a Social Media Agency with AEO Expertise is Essential

    Why a Social Media Agency with AEO Expertise is Essential

    As I navigate the rapidly evolving world of digital marketing, I’ve discovered that partnering with a social media agency that offers Answer Engine Optimization (AEO) services is a game changer. These agencies have the unique ability to transform social content into enhanced AI visibility, build citations, and drive significant growth for brands like mine.

    If you’re looking to boost your brand’s online presence, understanding the value of AEO services is crucial. I’ve personally seen how they enhance AI recognition, leading to better citations and more impactful growth metrics.


    Inspired by this post on HiGoodie Blog.


    crushpress.ai community screenshot
  • A Marketer’s Playbook for Ads in AI-Assisted Discovery

    A Marketer’s Playbook for Ads in AI-Assisted Discovery

    Your next paid discovery brief may arrive before the format has a stable name. The ad might represent an entire store instead of a single product, while an AI assistant might capture useful engagement before the buyer ever visits your site. A campaign structure built around a keyword, a product, and a click will not give you enough control.

    You do not need to predict which interface will win. You need a preparation model that works across store-level placements, conversational environments, and whatever hybrid appears between them. That means strengthening the advertised object, the evidence around it, the routes a buyer can take, and the measurement required before you commit budget.

    The advertised object is getting larger

    Traditional shopping campaigns make the individual product the center of gravity. Google is testing Sponsored Shops, a Shopping block that groups several products from one retailer with the store name, ratings, and broader brand presence. The impression can therefore introduce an assortment and a merchant, not merely an item.

    Conversational discovery creates a different expansion. OpenAI has begun testing an Ads Manager dashboard with selected partners as it develops advertising around ChatGPT. The exact inventory, interaction model, and optimization system remain early. You should treat them as provisional rather than assume conversational ads will inherit the rules of paid search.

    The practical lesson is that the thing you advertise can sit at several levels. It might be a product, a coherent assortment, a store, or a solution to the need expressed in a conversation. Each level requires different proof and a different continuation after the impression.

    Add the following fields to your campaign planning before a new platform makes them mandatory:

    • User need: the problem, task, or buying situation that triggered discovery.
    • Advertised object: the product, collection, store, or solution path the unit represents.
    • Evidence: the ratings, product details, range, brand facts, and on-page claims that support the promise.
    • Possible interactions: product selection, brand selection, continued conversation, or a direct visit.
    • Continuation: the exact page or in-platform step that follows each interaction.
    • Business event: the observable action that would make the placement valuable.

    This prevents a common category error: treating a larger discovery unit as if it were merely a wider text ad. More visible products do not automatically create a coherent reason to choose the store. A conversational placement does not automatically produce a qualified visit. The advertised object must make sense as a whole.

    Build a discovery asset stack before you buy media

    A modular stack of storefront, product, evidence, inventory, and data elements connects to three abstract discovery interfaces.

    A store-level placement exposes the quality of the catalog as a portfolio. Sponsored Shops could favor merchants with stronger product feeds, useful assortment depth, and credible seller ratings, because several products and the retailer identity appear within the same unit. A weak item is no longer isolated; it can make the entire selection feel less relevant.

    Do not answer that pressure by putting more products into every group. Build an asset stack in which every layer has a defined job:

    1. Catalog facts establish what each product is, what it costs, whether it is available, and how it differs from nearby options.
    2. Assortment logic explains why a set of products belongs together for a particular need. Shared inventory is not enough; the group needs a shopper-facing reason to exist.
    3. Brand evidence gives the buyer a reason to trust the store behind the assortment. Ratings and consistent brand identity matter more when the merchant is part of the advertised object.
    4. Destination continuity carries the same promise from the ad into the next page. The buyer should not have to reconstruct the category, filter, or use case after clicking.
    5. Machine-readable agreement keeps feeds, visible page content, and structured data aligned. JSON-LD should repeat defensible facts shown to the user, not introduce a cleaner but contradictory version of the offer.

    Audit this stack by discovery theme rather than by campaign name. Write the buyer’s need in plain language, select the products that genuinely address it, and inspect every item in that set. Mark missing details, inconsistent naming, stale availability, weak images, unexplained variations, and claims that do not match the destination. Then decide whether the set deserves to be presented as a store-level recommendation.

    Keep product-level optimization intact while you do this. A broad assortment should not bury the strongest item or force unrelated products into the same story. You are adding a portfolio layer above the product layer, not replacing product relevance with brand reach.

    Give every interaction a deliberate next step

    A multi-element discovery unit creates more than one possible click. With Sponsored Shops, the split between clicks on the brand and clicks on individual products is an open measurement and usability question. If you only plan the final conversion page, you will miss the intent expressed by the element the buyer selected.

    Design a continuation for each route that the format exposes:

    • Store or brand interaction: use a focused storefront that confirms the range, positioning, and evidence shown in the unit. Avoid a generic homepage unless it already performs that job.
    • Collection interaction: preserve the discovery theme, relevant filters, and visible product set. Do not make the buyer rebuild the selection from a broad category page.
    • Product interaction: land on the exact item with its important facts, proof, availability, and next action easy to find.
    • In-assistant interaction: identify what the platform can report when the user continues the conversation without visiting your site. Treat unreported engagement as unknown, not as a click or a conversion.

    Put this destination map in the campaign brief before creative production. For every clickable element, record the likely intent, destination, page promise, and success event. If the platform allows distinct tracking parameters for different elements, use them. If it does not, record that limitation before deciding how much you are willing to spend.

    The first visible part of each destination should close the loop opened by the ad. A store-level promise about range should reveal that range. A product promise should show the exact product. A solution-oriented message should answer the need before introducing unrelated navigation. That continuity is more useful than repeating the ad headline word for word.

    Keep paid visibility separate from organic AI visibility in your reporting. Buying placement does not make an unclear page easier for an answer engine to understand elsewhere. Your AEO and GEO work still needs clear naming, consistent facts, direct answers, accessible evidence, and structured data that agrees with the visible page. Paid discovery adds distribution and control; it does not repair weak information architecture.

    Make measurement and budget pass the same gate

    A glowing interaction moves through a branching journey toward a product shelf, consultation doorway, or parcel while paired measurement and budget tokens pass through one gate.

    Use a measurement ladder, not a click counter

    Early ChatGPT advertisers have reportedly received weekly CSV reports containing impressions and clicks, while initial click-through rates have trailed Google Search. Delivery and click data can confirm that an ad ran. They cannot, on their own, tell you whether conversational discovery created valuable demand.

    Measure emerging discovery formats as a ladder:

    • Delivery: impressions, placement, advertised object, unit variant, and any available context about where the ad appeared.
    • Interaction: clicks by element, product selections, brand selections, or reported continuation inside the interface.
    • Progression: meaningful visits to product or collection pages, deeper product exploration, cart activity, lead starts, or another relevant journey event.
    • Outcome: completed purchases, qualified leads, revenue, or the business result attached to the campaign.
    • Incremental value: evidence that the new channel added outcomes rather than taking credit for demand another channel had already created.

    Mark unavailable fields as unavailable. Do not enter zero, because zero means the platform measured the event and found none. Missing element-level interaction data is itself a decision signal: it limits what you can learn about creative, assortment, and destination performance.

    Your tracking taxonomy should identify the platform, placement, advertised object, unit variant, and destination wherever the platform exposes those controls. Keep those dimensions separate. Otherwise, a store click and a product click can collapse into the same campaign total even though they represent different user decisions.

    Write the test decision before launch. State the hypothesis, the variable being changed, the primary business outcome, the supporting engagement signals, the acceptable downside, and the condition that will stop or expand the test. A low click-through rate is not automatically failure for an upper-funnel discovery unit, but it cannot be excused by vague claims about awareness. The downstream evidence must carry the argument.

    Set a budget gate that reflects platform maturity

    Some early ChatGPT advertisers have reportedly been asked for a minimum commitment of $200,000. That creates material financial exposure while reporting and optimization capabilities are still developing. Early access is not valuable merely because access is scarce.

    Before accepting a pilot, require clear answers to these questions:

    • Where can the ad appear, and how is sponsorship disclosed to the user?
    • Which audiences, contexts, placements, products, and destinations can you include or exclude?
    • Which delivery, interaction, conversion, and cost fields can you export, and at what reporting cadence?
    • Can you distinguish a brand interaction from a product interaction?
    • How will conversion measurement work when part of the journey remains inside the assistant?
    • Which campaign changes can you make during the pilot, and what are the stop conditions?

    Ring-fence money you can genuinely treat as experimental. Do not pull budget from a proven acquisition channel simply to claim first-mover status. If the minimum commitment is too large to absorb as a learning cost, or the reporting cannot connect delivery to business outcomes, observing the format is the disciplined choice.

    Move from observation to a pilot when destinations are traceable, controls are understandable, disclosures are clear, and the downside fits the approved test budget. Move from pilot to scale only when the outcome is repeatable and the reporting explains why it happened. Impressions and novelty are not scale criteria.

    Key takeaways for your next planning cycle

    • Plan around the advertised object, which may be a product, assortment, store, or solution path.
    • Treat catalog quality, assortment logic, brand evidence, landing pages, and structured data as one discovery asset stack.
    • Map separate continuations for brand, collection, product, and in-assistant interactions.
    • Measure delivery, interaction, journey progression, business outcomes, and incremental value as distinct layers.
    • Do not fund a large early pilot without exportable reporting, usable controls, explicit stop conditions, and a tolerable downside.

    Your next move is to choose a commercially important discovery theme and complete the advertised-object and destination map for it. Audit the supporting catalog, page evidence, and machine-readable facts before a platform representative puts a media proposal in front of you.

    When access becomes available, ask the platform to map every promised metric and control to that plan. If the gaps prevent a business decision, keep observing. If the path is traceable and the risk is bounded, run a focused pilot with written stop conditions. Emerging discovery inventory should earn its budget on evidence, just like any established channel.

    References

  • How LinkedIn’s LLM-Powered Feed Ranks Your Content

    How LinkedIn’s LLM-Powered Feed Ranks Your Content

    If your LinkedIn reach feels erratic, stop treating the feed like one global leaderboard. The platform is trying to predict relevance for each person, so two professionals with similar networks can still receive different candidates in a different order.

    The useful question isn’t, “How do I please the algorithm?” It is, “Can the system understand who this is for, and will the right readers behave as though it was worth their time?” LinkedIn’s new architecture gives you a practical way to improve both sides of that equation without pretending there is a secret score you can reverse-engineer.

    LinkedIn now makes two separate feed decisions

    Abstract content tiles pass through a broad selection gateway and then a second prism that orders different feeds for three viewers.

    Feed visibility begins with two distinct jobs: retrieval and ranking. Retrieval decides which posts could appear. Ranking decides which of those candidates should appear first. A post that fails the first decision never reaches the second, while a retrieved post can still lose its position to something that better matches the viewer’s current interests.

    Retrieval matches meaning, not just identical wording

    LinkedIn has consolidated previously separate discovery routes into a unified retrieval model. Large language models create embeddings: numerical representations that capture the meaning and context of a post. Those representations can be compared with a member’s professional interests even when the wording isn’t identical.

    Someone engaging with small modular reactor content, for example, may also receive material about renewable energy or a related professional field that uses different terminology. This semantic matching across related concepts matters more than repeating one phrase in every paragraph.

    The GPU-backed system processes millions of posts, can refresh content embeddings within minutes, and can retrieve candidates in less than 50 milliseconds. That speed means a fresh post can become semantically retrievable quickly. It does not guarantee that the post will be selected, ranked highly, or distributed widely.

    Ranking uses a sequence of viewer behavior

    After retrieval, a transformer-based sequential model orders the candidates. It doesn’t evaluate each post in isolation. It examines patterns in a member’s previous behavior, including likes, comments, and time spent viewing content, so the feed can adapt as professional interests change.

    This is an important limit on algorithm advice. A post does not have one universal rank. Its position depends partly on the person receiving it and the sequence of behavior that preceded that feed request. Strong results with one audience segment do not prove that the same post will rank the same way for everyone else.

    LLM-powered also doesn’t mean a chatbot is reading your prose like an editor and awarding points for style. One model represents meaning for retrieval; another uses interaction history to rank candidates. Human-readable quality still matters, but it matters because clear, useful content is easier to match and more likely to hold the right person’s attention.

    Make each post semantically legible

    A blank content card emits a focused constellation of topic symbols that connects with a matching group of professional readers.

    A vague post forces both the model and the reader to guess. A semantically legible post names the professional context, the problem, the affected audience, and the relationship between its main ideas. You can create that clarity without turning the copy into a keyword list.

    1. Write a private audience sentence before drafting: “This is for [role] deciding [specific decision].” If you can’t complete it cleanly, the topic is still too broad.
    2. Name the subject early. Don’t spend the opening on a generic tease that could introduce leadership, software, hiring, finance, or any other field.
    3. Explain the mechanism. State why the change happens, what it affects, or which constraint creates the problem. Adjectives such as “transformative” and “important” don’t supply that context.
    4. Connect the core topic to one relevant adjacent concept. Make the relationship explicit instead of dropping related terms into the copy without explanation.
    5. Show expertise through a process, tradeoff, decision rule, or concrete distinction. Claiming expertise is weaker than making knowledgeable reasoning visible.
    6. End with a question only when the answer can deepen the professional discussion. Ask about a decision, constraint, or experience, not whether readers agree.

    Compare “Big changes are coming. Thoughts?” with this structure: “For [role] deciding [decision], [named development] changes [specific constraint] because [mechanism].” The second version tells the retrieval system what the content concerns and tells the reader whether it deserves attention.

    Semantic retrieval is not permission to stuff a post with synonyms. Use the standard term your audience recognizes, explain it in plain language where necessary, and introduce adjacent terminology only when the relationship adds meaning. A keyword dump can mention everything while communicating almost nothing.

    A coherent series can help you explore a semantic neighborhood: the primary problem, its causes, its operational consequences, and the decisions around it. That does not prove LinkedIn grants account-level authority merely for repeating a topic. It does give each installment a clear chance to match similar professional interests, and it gives you a cleaner way to learn which angle resonates.

    Your network size is not the entire distribution story. Posts that demonstrate expertise and contribute to relevant professional conversations can travel beyond an author’s established connections. The practical move is not to chase every trending subject. It is to contribute when you have a specific connection between the timely topic and the work your intended audience actually does.

    Earn ranking signals without manufacturing them

    Because ranking considers likes, comments, and viewing time, it is tempting to treat every interaction as a lever. Resist that simplification. LinkedIn has not supplied a usable formula that tells you how much each action is worth in every context, and a pause on a post does not necessarily mean approval.

    Design for a meaningful reading experience instead. Give the opening enough information to qualify the audience. Build the body in a logical sequence. Make the promised point before asking for a response. If the subject needs depth, use depth; making a post artificially long in pursuit of viewing time only gives readers more opportunities to leave.

    • Use an opening that identifies the professional issue instead of withholding it behind suspense.
    • Break a complex explanation into distinct decisions, causes, or steps so the reader can follow the reasoning.
    • Ask for a response that requires professional judgment, such as which constraint changes the decision.
    • Reply manually and specifically when someone contributes. Continue the subject they raised instead of posting a generic thank-you.
    • Keep the text and any accompanying media on the same subject. An unrelated video may attract attention while weakening the content’s meaning.
    • Remove prompts whose only purpose is to inflate activity, including requests for a one-word comment with no substantive reason to answer.

    Automated comments and engagement pods are not clever shortcuts. LinkedIn has identified them as policy violations that create artificial discussion. The platform is also deprioritizing engagement bait, irrelevant text-and-video pairings, and generic recycled thought leadership.

    Don’t stretch that policy into a claim that every AI-assisted draft is automatically suppressed. The documented targets are automated engagement and low-value publishing patterns. Judge any drafting tool by the resulting content: Is the reasoning specific? Is the point accurate? Does the copy express a real professional distinction? Would the post still be worth reading if no engagement counter were visible?

    Test audience-topic fit instead of algorithm folklore

    A personalized feed makes casual testing unreliable. When one post performs better than another, the difference could involve the topic, the opening, the audience that received it, those viewers’ recent behavior, or the quality of the discussion. Changing several elements at once leaves you with a result but no useful explanation.

    1. Choose one business-relevant question that a recognizable professional audience needs to answer.
    2. Map the question into a core angle and adjacent angles, such as the cause, implementation constraint, common misreading, and decision tradeoff.
    3. Publish a coherent sequence in which every post stands on its own and names its subject clearly.
    4. Change one structural variable when you want to learn from a comparison: the opening, explanatory depth, example type, or closing question.
    5. Record more than reach. Note whether the people responding appear connected to the intended professional context and whether their comments engage with the actual issue.
    6. Use those observations to choose the next adjacent angle. Don’t turn one strong or weak result into a universal rule about length, timing, hashtags, or a supposed favorite interaction.

    Keep a simple brief beside each draft with these fields: intended reader, decision or problem, core concept, adjacent concept, mechanism or tradeoff, and response prompt. After publication, add what the discussion revealed. This turns a feed result into editorial information you can use rather than a number you can only admire or resent.

    Your own feed is also personalized evidence, not a neutral sample of LinkedIn as a whole. If you use it for topic research, remember that your likes, comments, and viewing behavior help shape what you see next. New members can make that preference-building more deliberate by choosing topics through the Interest Picker during signup. That helps customize the feed from the beginning, but it still does not reveal what every other audience sees.

    Key takeaways

    • Retrieval decides whether a post belongs in the candidate set; ranking decides where that candidate appears for a particular member.
    • Semantic embeddings make clear meaning and related concepts more important than exact-phrase repetition.
    • Ranking uses sequences of behavior, including likes, comments, and viewing time, but there is no dependable public formula for turning those actions into a universal score.
    • Expertise becomes visible through mechanisms, tradeoffs, processes, and useful distinctions, not through generic claims of authority.
    • Automated engagement, pods, bait, mismatched media, and recycled thought leadership create policy or quality risks instead of durable distribution.
    • The cleanest test is audience-topic fit: keep the subject coherent, change one structural variable at a time, and inspect who responds and what they discuss.

    Before your next LinkedIn post, write the private audience-and-decision sentence, rewrite the opening so the subject is unmistakable, and remove any question that can be answered without thought. Then use the quality of the resulting discussion to select the next relevant angle. That is a better compounding system than chasing a secret ranking trick.

    References

  • How to Measure Incremental Ecommerce Growth and Real ROI

    How to Measure Incremental Ecommerce Growth and Real ROI

    Your ecommerce dashboard can show that an affiliate, content page, or campaign touched an order. It cannot tell you, by itself, whether that activity created the order. That gap is where apparently healthy revenue can conceal discounts, commissions, and production costs that bought little or no new demand.

    If you need to decide what to keep, pause, or scale, ask a harder question: what changed because this investment existed? Answering it turns incrementality from a reporting label into a practical way to allocate your budget.

    Key takeaways

    • Attribution records a touchpoint. Incrementality estimates the sales, customer value, or profit caused by that touchpoint.
    • A credible ROI calculation needs a counterfactual: what comparable customers, products, or markets did without the investment.
    • Measure incremental profit after product costs, discounts, commissions, fees, returns, fulfillment, and the investment itself. Attributed revenue is not ROI.
    • Judge each affiliate by the job it performs. Discovery, comparison, trust, conversion assistance, and checkout interception do not deserve the same commission merely because they appear in the same report.
    • Organic content should remove a specific buyer uncertainty, express its evidence clearly for machines, and work across search, AI, social, and other discovery environments.

    Start with profit that would not exist otherwise

    Attribution and incrementality answer different questions. Attribution asks which recorded interaction receives credit. Incrementality asks whether the business outcome would have happened without that interaction.

    This distinction produces four useful categories:

    • Attributed sale: an order assigned to a channel under your reporting rules.
    • Incremental sale: an order caused by an activity that would not have occurred without it.
    • Incremental value: additional value created even when the underlying order might still have happened, such as a larger basket or a conversion enabled by trust the brand could not create alone.
    • Cannibalized sale: an order credited to a paid touchpoint even though the customer was already likely to buy through an unpaid or less expensive path.

    Consider a shopper who reaches checkout and then searches for your brand plus the word “coupon.” A coupon publisher appears, the shopper clicks, and the affiliate platform credits the sale. The touchpoint had high intent, but the brand may have created that intent before the affiliate appeared. If comparable shoppers complete their purchases without the affiliate, the commission is paying for interception rather than growth.

    That does not make every coupon or deal publisher unhelpful. A partner may reach an audience you cannot reach, distribute an exclusive offer, increase the basket, or rescue purchases that would otherwise be abandoned. The important point is that high intent is not evidence of incremental value. You still have to test what changes when the partner is absent.

    Revenue alone also gives you the wrong economic answer. Use a profit bridge that both marketing and finance accept before the test begins:

    • Incremental revenue equals revenue from the exposed group minus the revenue you would expect without the intervention.
    • Incremental operating gain equals incremental revenue minus the product, discount, return, payment, fulfillment, and other variable costs attached to those orders.
    • Net incremental profit equals that operating gain minus commissions, network fees, media, content production, distribution, and other investment costs.
    • Incremental ROI equals net incremental profit divided by the investment cost used in the calculation.

    Agree on the cost boundary and evaluation period first. Otherwise, one team can present gross revenue while another includes commissions and production costs, leaving both with different versions of “ROI.” For a reusable content asset, document how you will treat its creation cost and future maintenance. For an affiliate campaign, include the commission, discount, platform costs, and any placement fee.

    Build a counterfactual before opening the dashboard

    Two matched miniature ecommerce environments sit under glass domes, with one receiving an intervention and producing an additional parcel.

    You cannot observe the same customer both receiving and not receiving an intervention at the same moment. An incrementality test solves that problem by creating a comparison that estimates the missing outcome.

    1. Name the intervention precisely. Test a specific partner, offer, content asset, or distribution method. “Affiliate” and “organic content” are too broad because they combine activities with different jobs and economics.
    2. Choose the eligible unit. Depending on what you can control, this may be a customer, audience, product group, category, or geographic market. The treatment and comparison groups must be similar enough for the difference to be meaningful.
    3. Choose the business outcome before viewing results. Completed orders, incremental revenue, contribution profit, new-customer profit, or basket value can all be valid. Pick the one connected to the investment’s intended job.
    4. Define the counterfactual. A randomized holdout is the cleanest option when it is operationally possible. Otherwise, use comparable markets, audiences, or product groups. A temporary pause can help, but a simple before-and-after comparison is more vulnerable to promotions, seasonality, inventory changes, and other events occurring at the same time.
    5. Protect the comparison. Keep pricing, inventory, promotions, tracking rules, and other material conditions aligned. Record contamination, such as a coupon leaking into the holdout group or customers moving between exposed and unexposed devices.
    6. Calculate the net difference and apply a prewritten decision rule. Decide in advance what evidence would justify scaling, modifying, retesting, or stopping the investment. Do not move the rule after seeing a favorable revenue number.

    When a randomized holdout is not feasible, be candid about the limitation. A matched comparison can inform a decision without proving perfect causality. Record what else could explain the result and reduce your commitment until stronger evidence is available.

    Do not switch off a large revenue partner across the whole business merely to satisfy curiosity. That can create avoidable financial exposure if the partner is genuinely incremental. Use the smallest bounded holdout that can answer the decision, preserve a rollback path, and monitor operational effects while the test runs.

    Watch for measurement shortcuts that inflate ROI

    • Treating attributed sales as the baseline: this assumes causation instead of testing it.
    • Comparing unlike periods: a promotional treatment period and a quiet comparison period cannot isolate the effect of the channel.
    • Pooling unlike partners: a creator introducing the brand and a coupon page appearing at checkout may average into a respectable channel result while having opposite incremental effects.
    • Stopping at revenue: a lift can disappear after discounts, commissions, returns, and fulfillment costs.
    • Judging content only by last-click sessions: content that resolves uncertainty earlier in the journey may influence a sale without owning the final recorded visit.
    • Ending a test when the result looks convenient: define the stopping condition before launch and avoid making a large decision from sparse or unstable observations.

    Judge affiliate partners by the customer decision they change

    Shopper figures move along different paths toward checkout, including one redirected from an exit by an illuminated bridge.

    An affiliate program is not one behavior. Its partners can introduce an unknown brand, shape a comparison, lend trust, distribute an offer, answer a product question, or appear after the customer has already decided to buy. Start your audit by assigning each partner a role.

    Partner roleEvidence worth testingMain measurement risk
    DiscoveryAdditional qualified customers or sales in an exposed audienceCrediting demand created elsewhere
    Comparison and evaluationA change in which product or brand customers chooseCounting shoppers who had already selected your brand
    Trust and recommendationHigher conversion among a comparable audience exposed to the recommendationConfusing audience affinity with the effect of the endorsement
    Exclusive distributionSales or customer value unavailable through your owned channelsPaying for an offer the brand could distribute directly
    Checkout assistanceRecovered orders, additional basket value, or reduced purchase frictionPaying commission on customers who would have completed anyway

    Review and comparison publishers can create real value because they influence which seller receives the order. For a smaller brand, appearing beside established alternatives can provide context and credibility while introducing the brand to another company’s potential customers. Useful formats include comparison sites, listicles, YouTube reviews, communities, forums, and shopping guides.

    Creators can play a similar role even when they do not publish a formal review. A trusted recommendation or distinctive presentation can expose the product to an audience the brand does not already own. The right test compares outcomes among eligible people who did and did not receive that exposure; the creator’s tracked clicks alone do not establish the difference.

    For every partner, ask:

    • Where does the partner usually enter the buyer journey?
    • What customer uncertainty or distribution gap can it resolve that your brand cannot resolve as effectively on its own?
    • Would the same offer, recommendation, or product information exist without the partnership?
    • Does the partner change the probability of purchase, the selected product, the basket value, or the customer acquired?
    • What happens to completed orders and profit when a comparable group cannot use the partner?
    • Does the incremental profit remain positive after commissions, discounts, placement fees, and network costs?

    Do not use a “new customer” label as automatic proof. A first-time buyer may already be at checkout before encountering the affiliate. Conversely, an existing customer can still represent incremental value if a partner causes an additional purchase or a more valuable order that would not otherwise occur. The counterfactual, not the customer label, settles the question.

    Also compare the commercial model with realistic alternatives. A one-time placement in an independent comparison may cost less over its useful life than recurring commissions on every referred order. That does not make fixed-fee coverage universally better; it means you should compare the full cost of ongoing commissions with the cost and durability of a non-affiliate placement.

    Fund organic assets that change a purchase decision

    Organic content has the same incrementality burden, even though its cost structure is different. Publishing more URLs is not a business outcome. The asset has to change what a potential customer knows, trusts, compares, or chooses.

    That matters because discovery now happens across AI experiences, social platforms, and search engines. AI summaries and shopping features can answer part of a customer’s question before a website visit occurs. Clicks therefore remain useful, but they do not capture every valuable discovery touch.

    A defensible organic investment should do three things: reduce buyer uncertainty, remain readable by machines, and work across multiple discovery environments. Turn those principles into a production workflow:

    1. Start with a blocked decision. Choose a real question that prevents the customer from selecting or trusting a product. Product comparisons, fit questions, use-case constraints, offer eligibility, and evidence behind a claim are stronger starting points than a broad keyword with no clear purchase decision attached.
    2. Build the evidence before the prose. Gather the product facts, comparison criteria, limitations, examples, and offer terms required to resolve the question. If the page cannot support its answer, polished wording will not create durable trust.
    3. Make the answer explicit. Use descriptive headings, stable product names, direct answers, visible tables where a comparison is genuinely tabular, and internal links that expose the relationship between products and supporting evidence.
    4. Keep structured data faithful to the page. JSON-LD and other machine-readable markup should restate visible, accurate facts. Markup is packaging for evidence, not a substitute for it.
    5. Adapt the evidence to the discovery environment. A comparison page, creator brief, shopping guide, short video, and community answer may express the same verified facts differently. Preserve the substance while fitting the format and audience.
    6. Test the business effect. A staggered rollout across comparable product groups or markets can provide a counterfactual. Evaluate the outcome at the eligible-group level rather than requiring the content URL to receive the last click on every influenced order.

    Assign the content costs before evaluating it: research, writing, design, expert review, technical implementation, distribution, and updates. Then select an evaluation period that matches how long you expect the asset to remain useful. Changing that period after results arrive is another way to manufacture a favorable ROI.

    Use one decision record for every growth investment

    Affiliate, content, paid media, and other channels become easier to compare when every owner completes the same short record:

    • Hypothesis: which customer behavior should change, and why?
    • Counterfactual: what represents the outcome without the investment?
    • Primary outcome: which business metric decides the result?
    • Cost basis: which variable and investment costs are included?
    • Result: what changed in revenue, operating gain, and net profit?
    • Evidence quality: what contamination, imbalance, or outside event could explain the difference?
    • Action: scale, modify, renegotiate, retest, or stop.

    The action should follow the combination of economics and evidence. Strong attributed revenue with no measurable lift is a reason to change the arrangement, not celebrate the dashboard. Incremental sales with negative net profit call for a lower commission, smaller discount, cheaper distribution, or better margin. A promising but inconclusive result calls for a cleaner test, not an unrestricted rollout.

    Start with the investment making the largest revenue claim and offering the weakest causal proof. Define a bounded holdout before the next promotion or rollout, agree on the profit calculation with finance, and write the decision rule before results appear. Your next growth decision will then be based on value the business actually gained, not credit a platform happened to assign.

    References

  • AI Search Visibility: A Practical Content Optimization System

    AI Search Visibility: A Practical Content Optimization System

    Your page can rank in conventional search and still disappear when someone asks an AI system to recommend a solution, compare options, or explain what to do next. The usual problem isn’t a missing AI keyword. It is that the answer, the entity behind it, or the evidence connecting the two is too difficult to interpret.

    You can fix that systematically. Make each important page useful as a self-contained answer, give every important entity one consistent identity, connect related pages deliberately, and keep the visible content aligned with its JSON-LD. Then measure whether AI systems represent your brand accurately, not merely whether they send a click.

    Start with the answer AI search needs to use

    Traditional SEO helps a search engine discover, index, and rank a URL. Answer engine optimization helps a brand appear when people ask relevant questions through AI-driven experiences such as ChatGPT and Google. Generative engine optimization goes a step further: it makes your information easier to interpret, verify, and incorporate into a generated response.

    These disciplines overlap, but they don’t produce the same artifact. A page written only to attract a click can tease the answer, delay it, or distribute it across several sections. A page prepared for AI search must contain an answer that remains clear when extracted from the surrounding layout.

    Rewrite the page around one answerable job

    Start by naming the job the page performs. A service page might establish who the service is for and what it includes. A comparison page might help a buyer choose between two approaches. A how-to page might resolve one task. If you cannot complete the sentence, this page helps the reader decide or do something specific, its scope is probably too loose.

    1. State the question or decision. Use language your intended reader would recognize. Don’t optimize one page for several unrelated intents simply because their keywords are adjacent.
    2. Give the direct answer early. Put the conclusion before the long explanation. The reader should not have to assemble it from an introduction, a feature list, and a closing paragraph.
    3. Name the subject. Replace ambiguous pronouns with the product, organization, person, service, or method being discussed. A detached passage should still reveal who or what the claim concerns.
    4. Add the conditions that change the answer. Identify who the advice applies to, what assumptions it depends on, and where an exception matters. A precise qualified answer is more useful than an absolute claim that the rest of the page quietly weakens.
    5. Support the conclusion nearby. Keep definitions, reasoning, examples, and relevant evidence close to the statement they support. Don’t force an engine or a reader to infer why a claim is credible from a distant page.
    6. Provide the next decision. Explain what the reader should compare, check, or do after receiving the answer. This turns an extractable passage into a useful one.

    Run an extraction test when the draft is finished. Copy the answer paragraph into a blank document without its title, navigation, images, or preceding sections. Can someone identify the subject, understand the conclusion, see its important limits, and know what to do next? If not, repair the paragraph before adding more optimization around it.

    Answer-ready writing does not mean reducing every page to short fragments. Detailed explanations still matter. The practical goal is layered clarity: a direct answer first, followed by the reasoning and context that make it trustworthy.

    Make your brand and its entities impossible to confuse

    AI visibility depends on more than what one URL says. A reasoning system also has to determine whether the organization in an author biography, the brand in a product description, and the publisher identified in structured data are the same entity. Strong entity authority comes from a consistent, connected, and verifiable ecosystem, not from repeating a keyword more often.

    An entity is a specific thing with an identity: your organization, a product, a service, a person, or a location. Treat each important entity as a record that must remain consistent wherever it appears.

    • Choose one canonical name. Decide how the entity is named, capitalized, and described. Use aliases only when they help readers recognize the same thing.
    • Maintain one canonical page. Give each strategic entity a clear home URL containing its current description, important attributes, and relevant relationships.
    • Define relationships explicitly. State which organization offers a service, which person works for or founded an organization, which product belongs to a brand, and which article concerns which subject. Include only relationships the visible site can substantiate.
    • Remove contradictory facts. Conflicting names, service descriptions, locations, authorship details, or availability statements force machines to choose between versions. Correct the underlying content instead of trying to override it with schema.
    • Connect external identities carefully. A sameAs value should identify the same entity on a reputable external page. It should not point to a loosely related mention, a partner, or a page that merely uses a similar name.

    Use a stable @id for each entity in JSON-LD and reference that identifier wherever the entity reappears. If the Organization node has one identifier on the homepage, another on an article, and a third on a service page, you have created three machine-readable candidates where you intended one identity.

    A small relationship map exposes these mistakes before they spread. Write the important connections in plain language: Organization offers Service; Article is about Service; Person works for Organization; WebSite is published by Organization. Then check whether the visible pages, internal links, and JSON-LD all express the same map.

    Schema can clarify an identity, but it cannot manufacture authority. If a page makes a vague or unsupported claim, wrapping that claim in structured data only makes the ambiguity machine-readable. Build the factual record first; encode it second.

    Use internal links and JSON-LD as one connected system

    Linked content-page tiles sit above a matching lattice of structured data nodes, with light bridges joining the two layers.

    Internal links and JSON-LD solve related problems at different layers. Internal links show readers and crawlers how editorial ideas connect. JSON-LD identifies the entities and properties involved in those connections. When the two layers disagree, neither provides a dependable map.

    Make internal links explain the relationship

    Link from the passage where the relationship is meaningful, using anchor text that describes the destination. A link labeled entity schema implementation tells the reader more than learn more. The surrounding sentence should also explain why the destination matters.

    • Link supporting articles to the canonical page for the product, service, person, or concept they discuss.
    • Link a canonical page back to the strongest supporting explanations when those explanations help a reader evaluate the entity.
    • Connect adjacent answers when a reader genuinely needs both, rather than linking every related keyword to every possible page.
    • Resolve orphaned strategic pages. If no relevant page points to an entity’s canonical URL, the site is signaling that the entity has little structural importance.
    • Review redirects and canonical changes so links continue to resolve to the identity you intend.

    Bring internal-link suggestions into the writing workflow before publication, while the author still has the full context of the page. Automation can surface possible destinations, but an editor should decide whether each link expresses a real relationship and helps the reader continue the task.

    Make JSON-LD describe what the reader can verify

    Basic schema scattered across unrelated templates can become a collection of data islands. Reuse entity identifiers so an Article can reference the same Organization, Person, Product, or Service already defined elsewhere. This creates a coherent content knowledge graph rather than several disconnected descriptions of the same site.

    Structured data lowers the amount of interpretation required to understand your content, but it does not guarantee inclusion or a citation. Its value is clarity. It lets a machine follow an explicit relationship instead of guessing one from layout, navigation, and repeated wording.

    • Match names and descriptions in meaning. The JSON-LD does not have to duplicate every visible sentence, but it must not tell a materially different story.
    • Reference canonical URLs. Don’t let outdated staging paths, redirected addresses, or inconsistent URL variants become entity identifiers.
    • Validate authorship and publisher relationships. Confirm that the named people and organizations are visibly associated with the content in the roles declared.
    • Keep offers and capabilities current. Remove services, availability claims, or product details from structured data when they no longer appear on the page.
    • Describe actions only when they work. Action-oriented schema should correspond to a real pathway a user or agent can complete. Marking up a nonexistent booking, ordering, or contact function creates a promise the site cannot fulfill.
    • Update content and schema together. A change is not complete until the visible page, shared entity record, internal links, and structured data agree.

    This last check prevents schema drift: the gradual separation of what people see from what machines read. Drift reduces confidence precisely when you need AI systems to resolve an identity or capability without guessing.

    Audit visibility by query, citation, and accuracy

    Three query orbs connect through an inspection lens to blank answer cards and source documents, with one connection highlighted for review.

    Organic sessions and rankings still matter, but they cannot tell you whether an AI answer named your brand, cited the right page, or described your offer correctly. Add an output-focused audit rather than replacing your existing SEO reporting.

    Build a stable set of prompts around real audience decisions. Include discovery questions, problem-solving questions, comparisons, and questions that test a capability you want the market to associate with your brand. Keep the wording and intent consistent enough to compare observations over time.

    1. Record the environment. Note the AI system, query, date, and any material context supplied with the prompt. A single answer without its conditions is not a useful baseline.
    2. Check presence. Record whether the brand or entity appears, whether it is merely listed, and whether it contributes meaningfully to the answer.
    3. Check citation quality. Identify the cited URL and whether that page actually supports the claim beside it. A homepage citation is not automatically valuable if a focused service or explanatory page should have been used.
    4. Check representation. Compare names, capabilities, relationships, and qualifiers with your canonical facts. An inaccurate mention is a governance problem, not a visibility win.
    5. Check answer ownership. Note which competing entities or publications provide the explanation when your page does not. Look for a missing answer, unclear entity, weak relationship, or unsupported claim that explains the difference.
    6. Check the site layer. Confirm that the preferred page is indexable, internally linked, canonically consistent, and aligned with its JSON-LD before rewriting its prose again.

    Citation value, model share, and representation accuracy extend measurement beyond page traffic. Model share can be treated as the proportion of your tracked prompts in which your entity earns a meaningful presence. Citation value asks whether the cited page supports a commercially or editorially important answer. Neither metric should be confused with revenue, but both can reveal whether AI systems understand where your brand belongs.

    Don’t change strategy because the brand was absent from one generated response. Look for a recurring failure across your tracked prompt set. If the right page is repeatedly ignored, inspect answer clarity and internal prominence. If the brand appears with the wrong attributes, inspect the canonical entity record and schema alignment. If a competitor supplies the explanation, compare the completeness and specificity of the relevant answer rather than copying its phrasing.

    Schedule a governance check whenever a material business fact changes. A rebrand, retired service, new author role, migrated URL, or changed transaction path can affect several nodes at once. Updating only the most visible page leaves the old version alive in internal links, structured data, archives, or supporting content.

    Key takeaways

    • Optimize each strategic page for one answerable reader job, then test whether its core answer remains clear when removed from the layout.
    • Give every important organization, person, product, or service one canonical identity, one stable @id, and a consistent set of relationships.
    • Use internal links to express editorial relationships and JSON-LD to encode the same relationships for machines.
    • Never use schema to make a claim the visible page cannot verify, and update both layers in the same publishing workflow.
    • Track meaningful presence, citation quality, and representation accuracy across a stable prompt set alongside rankings and traffic.

    Begin with one commercially important entity and the page that should answer its most important question. Repair that page, connect its supporting content, align its JSON-LD, and establish a prompt baseline. Once the identity and relationships hold together there, extend the same system to the next entity instead of attempting a site-wide markup exercise with no governing model.

    References

  • SEO Interview Mistakes: How to Answer with Evidence

    SEO Interview Mistakes: How to Answer with Evidence

    You can understand SEO and still give a weak interview answer. An interviewer asks about a migration, you start discussing everything you know about redirects and canonical tags, and the answer never reveals what you owned, why you made a decision, or whether the work succeeded.

    The fix is not to memorize more SEO terminology. You need a small bank of relevant evidence, a direct way to handle unfamiliar questions, and the judgment to explain your work without exaggerating it. Here is how to prepare for the mistakes that cost otherwise capable candidates.

    Build an evidence bank before you rehearse answers

    Hands organize text-free project cards, webpage mockups, colored tabs, and outcome markers into evidence groups on a desk.

    Vague project descriptions usually begin with weak preparation. If your notes say only “technical audit” or “traffic recovery,” you will have to reconstruct the important details while an interviewer waits. That is when responsibilities blur, results disappear, and answers become generic.

    Choose stories that match the actual role

    Start with the job description. Highlight the problems the successful candidate will be expected to solve, then attach a real project to each important responsibility. Senior technical SEO candidates should be ready to discuss areas such as crawling or indexing problems, organic traffic declines, website migrations, and projects that required stakeholder support. Candidates for account-focused roles need evidence about explaining performance, presenting strategy to different audiences, and onboarding clients after a pitch.

    Do not force one impressive story into every answer. A migration example will not automatically prove that you can resolve stakeholder conflict, explain a forecast, or prioritize work under a constraint. Choose examples for the capability they demonstrate, not merely for the size of the project.

    Turn each story into an evidence card

    Use the STAR structure, but make each part concrete enough to survive follow-up questions:

    • Situation: What was happening, how did you know, and why did it matter? Name the affected site area, audience, or business process instead of saying there was “an SEO issue.”
    • Task: What outcome were you responsible for? Separate your mandate from the wider team objective.
    • Action: What did you inspect, decide, prioritize, recommend, or coordinate? Explain why you chose that path and what constraint shaped the decision.
    • Result: What changed, what evidence showed the change, and what did you learn? If the project fell short, explain the gap and what you would alter next time.

    Add an ownership line to every card: “I owned…; I contributed…; another team owned….” Add the names of the metrics you used, but only include figures you can defend and are permitted to disclose. If a result is confidential, say so and describe the outcome at an appropriate level rather than inventing precision.

    You are not writing a speech. You are creating a fact sheet that prevents you from losing the useful details under pressure. Practice explaining each project in a short version, then keep the diagnostic reasoning, trade-offs, and lessons available for follow-up questions.

    Answer the question before you explain your reasoning

    Many poor answers contain relevant knowledge but never address what was asked. If the question is about leading a complex migration, a long explanation of migration risks is not evidence that you led one. Interviewers notice when a candidate redirects the conversation toward a safer subject.

    Use an answer-first sequence:

    1. Give the direct answer. Say yes, no, partly, or state your conclusion.
    2. Present the closest evidence. Use a prepared project and make your role explicit.
    3. Explain the reasoning. Describe the important decision, evidence, trade-off, or constraint.
    4. State the boundary. Clarify what you did not own, what remains uncertain, or what information you would need.

    This sequence keeps the answer useful even when the question is difficult. It also prevents background detail from burying the point.

    When the question is unclear

    Ask for clarification before committing to an answer. For example: “Would you like me to focus on how I diagnosed the decline, how I communicated it, or both?” That is not evasive. It shows that you can define the task before solving it.

    If you need to think, say so briefly. A considered pause is better than filling the space with loosely related facts. Listening carefully, requesting clarification, and structuring the response produce more substance than speaking before you know where the answer is going.

    When you lack the exact experience

    Do not manufacture a project. Use a clean boundary statement:

    “I have not led that type of migration end to end. I did own the validation work for a related change. Here is what I handled, and here is how I would extend that experience to the scenario you described.”

    Then separate experience from proposed method. Describe what you have done as evidence. Describe what you would do as a plan. Acknowledging an unfamiliar situation and explaining a sensible approach is more credible than presenting a hypothetical as history.

    For a hypothetical technical problem, make your reasoning inspectable. State what you would verify first, which competing explanations you would consider, what evidence would distinguish them, and what action would depend on the result. The interviewer can then evaluate your method even if the scenario is new to you.

    Sound confident without misreading the room

    Confidence in an SEO interview comes from clear claims with visible evidence. Arrogance appears when you treat a context-dependent conclusion as universal, dismiss another interpretation, or assume the company has ignored an obvious problem.

    A strong claim has boundaries: “We prioritized this explanation because the affected URLs shared these characteristics. I would reconsider it if the segmentation or technical evidence changed.” You are still stating a position, but you are also showing how it could be tested. That makes disagreement productive instead of personal.

    Confident candidates can explain accomplishments, complex work, results, and stakeholder support while remaining open to another informed view. SEO decisions depend on the site, resources, business model, data, and timing. An answer that leaves room for those conditions sounds more experienced, not less certain.

    Match the explanation to the interviewer

    Listen to the language in the question and adjust the depth of your answer:

    • For a business stakeholder: lead with the consequence, the decision required, the dependency, and the expected way you would measure progress. Define technical terms only when they affect the decision.
    • For an engineering or product partner: explain the behavior, the affected templates or process, the implementation dependency, and how you would validate the change.
    • For an SEO specialist: expose the mechanism, evidence, alternative hypotheses, and trade-offs. Do not use jargon as a substitute for the causal explanation.

    These are not different versions of the truth. They are different levels of resolution. Misreading the audience can make a knowledgeable candidate sound either inaccessible or superficial.

    Critique the company site without insulting the people behind it

    You may be asked what you would improve on the company’s site. Treat what you can see as an observation, not proof of negligence. You do not know the roadmap, platform limitations, legal requirements, release process, prior experiments, or internal priorities.

    A useful response follows this pattern: observation, possible consequence, validation need, and constraint question. For example: “Some important pages appear difficult to reach through the internal navigation. I would verify that pattern with crawl, search, and traffic data before prioritizing it. What has already been investigated, and what constrains changes to those templates?”

    This still demonstrates your eye for problems. It also recognizes that visible SEO issues can persist because a team is working through constraints. The question about constraints may reveal more about the role than the issue itself: ownership, release friction, data access, or the level of support available for implementation.

    Protect your credibility when the pressure rises

    A composed job candidate pauses thoughtfully while two interviewers listen across a conference table.

    An interviewer can teach a new employee an internal process. It is much harder to work around unreliable claims, poor judgment, or conduct that creates risk. Several memorable interview mistakes are credibility failures rather than knowledge gaps.

    Describe your role with exact ownership

    Use “I” for decisions and work you personally completed. Use “we” for shared delivery, then identify the other functions involved. A clear account might say: “I diagnosed the pattern and wrote the requirements. Engineering implemented the template change, analytics supported validation, and I monitored the SEO outcome.”

    Do not upgrade participation into leadership. Exaggerated project ownership tends to surface during detailed follow-up questions, when the candidate cannot explain decisions that the actual owner would understand. Honest contribution to a difficult team project is stronger evidence than a leadership claim you cannot support.

    Replace “Google lies” with a testable explanation

    A mismatch between guidance and observed results is not an analysis. If you reach for “Google lies,” you stop the reasoning at the point where it should become more precise.

    Build a hypothesis tree instead. Ask whether you are comparing the same definitions, site segment, query set, time period, and stage of the search process. Separate crawling, indexing, ranking, and measurement. Consider whether another site change could explain the pattern. Then say what evidence would support or weaken each explanation.

    You do not have to agree with every public statement. You do have to show a rational path from observation to conclusion. Blaming an unexplained discrepancy on deception can make a candidate look less technically rigorous because the label replaces diagnosis.

    Keep ethics and follow-up inside professional boundaries

    Do not offer backlinks, supposedly exclusive tactics, favors, or anything else that resembles a bribe. Never imply that you could take negative action against a company. Promises and threats of this kind do not demonstrate SEO ability; they raise immediate questions about integrity and risk.

    Use the established hiring channel for follow-up. Send a concise note that thanks the interviewer, refers to a substantive part of the conversation, and supplies any information you agreed to provide. Do not repeatedly contact unrelated employees to create visibility. Enthusiasm becomes counterproductive when outreach overwhelms people outside the formal process.

    Key takeaways for your next SEO interview

    • Prepare role-specific project evidence, not a generic collection of SEO talking points.
    • Structure each example around the situation, your task, your actions, the result, and the exact boundary of your ownership.
    • Answer the question directly before adding context. If you lack the experience, say so and distinguish transferable evidence from your proposed approach.
    • Adjust the depth of your explanation to the interviewer while keeping the underlying facts consistent.
    • Critique a site as an informed outsider: state the observation, identify what requires validation, and ask about constraints.
    • Protect trust by avoiding inflated ownership, unsupported accusations, unethical offers, threats, and excessive outreach.

    Before your next interview, choose the hardest likely question in the job description and answer it aloud. Cut any sentence that hides your role, delays the answer, or asserts more than your evidence supports. What remains is the version an interviewer can understand, test, and trust.

    References

  • How to Fix Creative Operations Bottlenecks With Technology

    How to Fix Creative Operations Bottlenecks With Technology

    Your designers are busy, reviewers are busy, and campaign dates still slip. That usually means the problem is not a lack of effort. Work is losing time between the request, the asset, the decision, and the channel that needs the finished deliverable.

    You can fix that, but buying another platform is not the first move. First locate the constraint. Then give each technology layer a clear job, connect the handoffs, and measure whether work actually moves faster with less rework.

    Key takeaways

    • Map where an asset waits, changes hands, gets recreated, or returns for revision. The loudest complaint is not always the real constraint.
    • Use digital asset management to control asset identity, versions, approval status, rights, and reuse. A shared folder is not a lifecycle system.
    • Route approvals from asset attributes such as channel, market, format, and risk. Do not make creators reconstruct the reviewer list for every request.
    • Test integrations with one complete asset journey. A connector that synchronizes only filenames or status labels may not remove meaningful work.
    • Treat AI generation as an increase in production capacity, not as a substitute for intake rules, review ownership, provenance, or publication controls.
    • Measure elapsed fulfillment time, approval delay, rework, completion, retrieval, and utilization before expanding the workflow.

    Trace the bottleneck before you choose a platform

    Operations team examining a tabletop workflow model where creative asset cards are backed up at a narrow approval gate.

    Creative demand is rising faster than many operating models can absorb. Seventy-seven percent of marketing teams report increasing annual project volume, while 45% struggle to meet content demand across platforms. That does not tell you which system to buy. It tells you why an informal workflow that once seemed adequate can suddenly fail.

    Start with one recently completed deliverable that represents normal work: a paid campaign asset set, a product launch package, a landing page, or a regional adaptation. Reconstruct what actually happened. Do not diagram the process described in the handbook unless the work followed it.

    1. Record the request as it arrived, including the information that was present and what had to be chased later.
    2. List every system, inbox, folder, document, and creative application the work entered.
    3. Mark each transfer of responsibility. Name the person or role that owned the next decision.
    4. Separate active production time from waiting time. Note what the asset was waiting for: missing input, capacity, feedback, permission, or a usable file.
    5. Record every revision loop and the reason for it. Distinguish a creative improvement from a correction caused by an incomplete brief, wrong version, conflicting feedback, or changed requirement.
    6. Follow the approved asset through publication, reuse, replacement, and retirement. Approval is not the end of the lifecycle if teams cannot later identify what was published.

    Read the map by failure pattern

    A request that repeatedly returns for missing information points to an intake problem. Long gaps before a reviewer responds point to routing or ownership. Designers hunting for logos, templates, or approved photography point to asset governance. People copying campaign details between systems point to an integration gap. A queue that remains long after those problems are removed may be a genuine capacity constraint.

    This distinction matters because added headcount does not repair unclear decisions, and automation does not repair an undefined process. Administrative drag can be severe enough to reduce productivity by as much as 40%. Treat that figure as a warning, not a forecast. Establish your own baseline by recording where representative work spends its time.

    Give each technology layer one primary job

    A healthy creative operations stack does not require every system to do everything. It requires one authoritative place for each kind of information and deliberate connections between them.

    Failure you observeCapability to examineAcceptance test
    People use outdated or unapproved filesDigital asset managementA user can identify the current approved asset, its owner, usage status, and prior versions without asking the creator.
    Comments and decisions are scattered across email and chatApproval workflowEvery decision is attached to the reviewed version, with a named reviewer, status, and unresolved feedback visible.
    Project managers manually chase statusCreative work managementThe project state changes as work moves, and blocked items expose both the owner and the required next action.
    Campaign data is repeatedly copied into briefs and filenamesSystem integrationCampaign, channel, market, audience, and due-date fields travel with the request without re-entry.
    Designers rebuild common variationsCreative-tool and template integrationApproved components can be opened from the working application and returned to the governed asset record.

    Use DAM to control asset identity and lifecycle

    A digital asset management system should answer questions that a folder cannot answer reliably: Which file is approved? What campaign and market is it for? Who owns it? Can it still be used? What replaced it? Which variations belong to the same parent asset?

    Define the minimum metadata required to make those answers possible. Useful fields commonly include a stable asset ID, campaign, audience, channel, market, language, format, owner, approval status, rights or expiry constraints, and parent asset. Keep the required set small enough that people will complete it, then automate population from upstream campaign data where possible.

    Version control also needs a business rule. A file becomes the approved version only through the approval workflow, not because someone adds FINAL to its name. Superseded assets should remain traceable without appearing as valid choices for a new campaign.

    Turn approval into a recorded decision

    An approval system should route work dynamically from information already attached to the request. A regional adaptation may require a market owner. A regulated claim may require a specialist review. A low-risk resize should not inherit every reviewer from the original campaign simply because the team always copies the same checklist.

    Run independent reviews in parallel when their decisions do not depend on one another. Keep feedback contextual to the exact version. Set a named final decision owner who resolves contradictory requests instead of sending the creator back to negotiate among reviewers. Use escalation for overdue decisions, but make the escalation path visible before a deadline is missed.

    Make work management reflect creative work

    Generic task lists often hide the parts creative leaders need to see: revision cycles, review queues, skills required, dependencies among asset variations, and capacity by role. Your work management layer should track the request, scope, owner, state, dependencies, and delivery commitment. The DAM should remain authoritative for the asset itself.

    That boundary prevents duplicate masters. Adobe Creative Cloud, Figma, Canva, or another creation environment is where the asset is edited. The DAM controls its governed record. Work management controls the flow of work. The approval layer controls decisions. Campaign or content systems provide destination context.

    Prove integration with an end-to-end test

    Do not evaluate an integration from a feature checklist alone. Give the vendor or implementation team one representative request and ask them to demonstrate the complete path:

    1. Create the creative request from real campaign fields without retyping them.
    2. Assign the work and open the correct source asset from the creator’s normal application.
    3. Save a new version while preserving its relationship to the original asset and request.
    4. Route the version to the correct reviewers, capture contextual feedback, and record approval.
    5. Make only the approved variation available to the destination team, with its identifying metadata intact.
    6. Replace or retire the asset while preserving the record of what was previously used.

    Count every export, upload, copied field, duplicate status change, and manual notification. Some manual steps may be necessary, but they are operating costs. They should be visible in the buying decision instead of being dismissed as minor setup details.

    Design a workflow that survives more volume and AI output

    Modular creative workflow routing a high volume of human- and AI-produced assets through automation, quality review, and multichannel delivery.

    Technology becomes scalable when each transition has an entry condition, an owner, and an observable result. A practical state model might use Requested, Scoped, In production, In review, Changes requested, Approved, Published, and Retired. Your labels may differ; the important part is that two people cannot interpret the same state differently.

    • Requested to Scoped: the intended outcome, audience, channel, deliverables, owner, required inputs, and decision-makers are present.
    • In production to In review: the exact version is attached, required variations are identified, and known specification checks are complete.
    • In review to Approved: every required decision is recorded, unresolved feedback is closed, and one person owns the final disposition.
    • Approved to Published: the destination record points to the approved asset ID rather than an unmanaged duplicate.
    • Published to Retired: the asset is no longer offered for new use, while its history and replacement remain discoverable.

    Model variations as children of a parent concept or master asset. Let them inherit shared campaign, brand, and ownership information while retaining channel-, market-, language-, or format-specific fields. This makes it easier to update the right set of assets without pretending every variation is interchangeable.

    Stress-test the design at three times your current volume. This is not a demand forecast. It is a way to expose steps that work only because someone remembers to send a message, rename a file, or reconcile two lists. Ask what happens when requests, variations, reviewers, and markets multiply while headcount does not.

    Do not let AI move the bottleneck downstream

    AI-assisted generation can increase the number of drafts and variations entering the workflow. If review capacity, provenance, and publication controls remain unchanged, the constraint simply moves from production to selection and approval.

    Generated output should enter the same governed lifecycle as human-produced output. Record its relationship to the request, source assets, template, tool, and model where your governance policy requires that information. Mark it as a draft until the appropriate people approve it. Do not allow bulk generation to create hundreds of unmanaged files that nobody can confidently reuse or retire.

    For SEO, AEO, and GEO programs, connect creative operations to the approved content record. Ownership, review state, update date, entity relationships, and supporting references should travel into the publishing workflow as structured fields. JSON-LD should be generated from approved facts in that record, not inferred from a filename or invented to fill an empty schema property. Better operations do not guarantee AI visibility, but they reduce the ambiguity and inconsistency that make content difficult to maintain and trust.

    Roll out the change without turning adoption into a second bottleneck

    A correct architecture can still fail if it adds data entry, hides familiar information, or changes responsibility without explanation. Involve the people who request, create, review, publish, and retrieve assets before configuration is fixed. Each role sees a different failure in the same workflow.

    1. Capture the baseline. Measure representative work before changing the system. Preserve the starting definitions so later comparisons remain meaningful.
    2. Choose one repeatable workflow. Use work that is common enough to expose real friction but bounded enough that the team can see the whole lifecycle.
    3. Configure the smallest complete path. Include intake, production, review, approval, distribution, and retirement. Automating only the middle can leave the most expensive handoffs untouched.
    4. Train by role and decision. A requester needs to know what makes a request ready. A creator needs version and submission rules. A reviewer needs decision criteria. A publisher needs to know which record is authoritative.
    5. Collect friction at the point of use. Record duplicate entry, unclear fields, unnecessary approvals, missing notifications, and exception cases. Adjust the workflow without discarding its control points.
    6. Expand only after the path is stable. Add additional asset types, markets, and automations after the pilot produces reliable records and measurable movement.

    Measure flow, not software activity

    Logins, tasks created, and files uploaded can show adoption, but they do not prove that creative operations improved. Core measures should include asset fulfillment time, project completion, and team utilization. Define each measure against explicit events in your workflow:

    • Asset fulfillment time: elapsed time from a request meeting the Scoped criteria to the approved deliverable becoming available.
    • Approval wait: elapsed time spent in review states without a decision. Break this down by review type so one queue does not hide another.
    • First-pass approval: the share of submissions approved without a revision request. Read it alongside quality and scope changes; a high rate is not useful if reviewers are rubber-stamping weak work.
    • Rework loops: the number and cause of returns to production. Separate creative refinement from preventable corrections.
    • Project completion: the share of scoped work delivered under the commitment attached to that scope. If scope changes, preserve the change rather than rewriting the original commitment.
    • Retrieval and reuse: whether people can find the approved asset and use it without contacting its creator or rebuilding it.
    • Utilization: how much available capacity is committed, viewed with queue length and fulfillment time. Maximizing utilization while work waits longer is not an operational win.

    Use the median to understand normal flow and inspect the slowest cases separately. Segment unlike work instead of combining a simple resize with a new campaign concept. Most importantly, keep the definitions stable long enough to distinguish improvement from a reporting change.

    Your next move is small and concrete: take the last campaign that ran late, reconstruct one asset’s full journey, and circle the first repeated wait or rework loop. Fix that control point, prove the connected path, and then expand. The right creative operations stack is the one that makes the next decision obvious and the approved asset easy to trust.

    References

  • Mastering Google Ads: Avoid Costly Pitfalls & Optimize Performance

    Mastering Google Ads: Avoid Costly Pitfalls & Optimize Performance

    I recently had an enlightening chat with Chloe Varnfield, a seasoned digital marketer from Atelier Studios with nearly eight years of PPC experience. She shared invaluable insights on avoiding hidden Google Ads settings, steering clear of Friday mishaps, and the dangers of following Google rep advice blindly. These hard-learned lessons resonated with me deeply.

    One of Chloe’s early eye-openers involved Google’s elusive account-level automated assets setting. It’s tucked away so deeply that I didn’t even realize it existed until I got an unexpected client message questioning a bizarre headline in their ad. It turns out Google had generated it automatically. This experience taught me the importance of auditing account-level settings and being proactive about Google updates.

    Another lesson Chloe swears by is to never implement significant changes on a Friday. Once, she adjusted a campaign’s geographic targeting mid-conversation, only to accidentally exclude the UK. Recovery took three bewildering days. The rule I learned? Avoid major changes on a Friday and promptly audit your campaigns when things go awry.

    Chloe’s most costly mistake unfolded when she followed a Google rep’s suggestion to switch bid strategies. What seemed like solid advice plummeted her campaign’s performance. It was a stark reminder of the high stakes involved in altering bid strategies, especially for businesses not hitting conversion volume thresholds. Patience and trusting my judgment emerged as crucial takeaways.

    While auditing inherited accounts, Chloe often finds recurring issues like broken conversion tracking and brand-broad match campaigns—challenges that skew performance data and waste precious budget. These insights made me acutely aware of consistently vigilant account management.

    Transparency in client relationships plays a pivotal role in Chloe’s success. Honest communication—explaining issues, solutions, and next steps—has shielded her from losing client trust. Her advice? Stay calm, be kind to yourself, and remember every problem offers a chance for growth.

    Lastly, Chloe emphatically warns against over-relying on AI for generating ad copy without thorough review. AI should be a tool to enhance speed, not replace meaningful human oversight. It reinforced my commitment to always infuse my unique voice and critical review into AI outputs.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • What the Reddit-SerpApi Scraping Fight Means for SEO Data

    What the Reddit-SerpApi Scraping Fight Means for SEO Data

    If your SEO or AI workflow retrieves Reddit material from Google result pages rather than from reddit.com, you may be tempted to label it indirect public data and move on. The Reddit-SerpApi dispute shows why that shortcut is dangerous: the address you requested is only one part of the legal and operational analysis.

    SerpApi is asking a federal court to dismiss Reddit’s amended complaint. Reddit alleges that large amounts of its content were extracted through Google Search. SerpApi counters that it accessed Google pages, that Reddit does not own most user posts, and that Reddit has not adequately established technical circumvention or concrete harm. Those are opposing positions, not judicial findings. Until the court rules, neither side’s argument gives your team permission to treat a similar pipeline as settled law.

    Key takeaways

    • Fetching a Google result page instead of visiting Reddit directly changes the facts, but it does not automatically eliminate copyright or access-control questions.
    • Audit the actual payload. URLs, rankings, dates, short snippets, full comments, and complete threads create different copying and provenance issues.
    • Public visibility and technical circumvention are separate questions. A page can be publicly viewable while the collection method still encounters controls that demand legal review.
    • Content ownership and platform licensing are also separate. A user’s ownership of a post does not, by itself, prove that every third-party reuse is lawful.
    • Your safest immediate investment is traceability: retain acquisition routes, response fields, control events, transformations, retention rules, and downstream recipients for every dataset.

    The dispute turns “scraping” into five separate questions

    Five symbolic lenses surround a transparent pipeline carrying abstract content tiles, with a doorway, hand, blank documents, circuit gate, and application modules representing different areas of review.

    Calling a system a scraper tells you almost nothing about its legal posture. A useful review separates who holds rights, what was copied, where the response came from, how the collector reached it, and what harm is alleged. Mixing those questions is how a technical description such as “we only queried Google” gets mistaken for a legal conclusion.

    QuestionDisagreement in the caseWhat your team should preserve
    Who holds rights in the material?SerpApi relies on Reddit’s user arrangements to argue that users retain ownership and Reddit generally holds a non-exclusive license.The creator, platform, applicable terms, asserted license, and rights basis for each collected field.
    What exactly was copied?SerpApi argues that the examples identified by Reddit include dates and short fragments that are not protectable expression.Representative payloads showing whether you store metadata, snippets, comments, threads, media, or combinations of those fields.
    Which system returned the data?SerpApi says it accessed Google Search pages rather than interacting directly with Reddit.Requested hosts, final URLs, redirects, response headers, collection jobs, and the origin assigned to each field.
    Was a technical measure circumvented?SerpApi says Reddit has not shown an encryption breach or authentication bypass and characterizes the pages it accessed as publicly available.Authentication states, challenge pages, block responses, rate-limit events, bot defenses, retries, proxy changes, and any code intended to handle them.
    What harm followed?SerpApi argues that Reddit has not adequately pleaded tangible harm caused by its conduct.Collection volume, retention, redistribution, customer access, substitution for the original service, incident reports, and takedown history.

    Keep the five answers independent. If Reddit cannot establish ownership of particular user posts, that may weaken an ownership-dependent theory, but it does not prove that every use of those posts is lawful. If a date or fragment lacks enough expression to be copyrightable, that does not resolve how the system obtained it. If no access control was circumvented, that may answer one DMCA theory without answering every other issue raised by the collection and reuse.

    The current procedural posture matters too. A motion to dismiss challenges whether the complaint states legally sufficient claims; it is not a factual finding that the challenged conduct was lawful. If the claims survive, that likewise means they can proceed, not that Reddit has already proved liability.

    Why the Google layer is not a legal shield

    An indirect pipeline has at least three layers: Google returns a search page, that page contains material derived from Reddit, and your system stores or republishes some part of the result. The host that returned the bytes is relevant, but it does not identify every party with an interest in the content or collection method.

    Reddit’s allegation involving a decoy post created solely for Google’s crawler is important for that reason. Reddit uses the alleged appearance of that material to support its account of how the defendants acquired Reddit-derived content through Google. SerpApi answers that an ordinary user could see the same material in public search results. The court still has to decide whether Reddit’s allegations are legally sufficient and, if the case proceeds, what the evidence establishes.

    There is also an upstream problem. Google separately alleges that SerpApi bypassed bot protections while scraping licensed search functionality. SerpApi has sought dismissal there as well, arguing that the DMCA is being used to restrict access to public search results. In practical terms, routing collection through a search engine may exchange one platform-access question for another rather than remove the question entirely.

    For an SEO, AEO, or GEO system, review both sides of that route. First ask whether the collector was permitted to obtain the search response in the manner used. Then ask what rights and restrictions may follow the Reddit-derived material inside that response. Do not let a clean answer at one layer stand in for an answer at the other.

    Run a field-level audit before expanding collection

    Gloved hands sort the separated fields of a generic web record into color-coded trays beside a magnifying lens, privacy shield, timer, and source trail.

    Your lawyers cannot evaluate a label such as “SERP data,” and your engineers cannot implement advice framed only as “reduce scraping risk.” Give both groups a field-level map of the system. This is not a substitute for legal advice about your particular facts; it is the evidence package that makes useful advice possible.

    1. Map the complete request path. Record the initial host, redirects, rendered page, APIs or browser automation involved, proxy layer, authentication state, and retry logic. Distinguish a request sent to Google from a later request sent to Reddit.
    2. Define the collection unit. List every retained field: query, rank, result URL, title, date, snippet, author name, subreddit, comment text, thread text, media, and cached page. Do not describe a full-thread archive as metadata merely because the job began on a search page.
    3. Attach provenance to each field. Store the page that supplied it, the underlying content platform when known, the collection time, and the transformation applied. A field should not lose its origin when it moves from raw storage into a feature table, embedding index, model corpus, or customer export.
    4. Document the rights theory instead of assuming one. For each field, state why the organization believes it may collect, retain, transform, and distribute that material. Flag any theory that reduces to “it was public” for legal review.
    5. Preserve control events. Log authentication prompts, denied responses, block pages, rate limits, bot challenges, and code changes made in response. Do not instruct a collector to evade a control while waiting for counsel to decide whether the control matters.
    6. Trace every downstream use. Separate internal measurement from customer-facing display, bulk export, dataset resale, AI training, retrieval-augmented generation, and verbatim output. The same input can create a materially different question when the product begins returning the original text to other people.
    7. Build deletion and shutdown paths. You should be able to stop one connector, one field, one customer export, or one corpus without taking the entire product offline. Also identify derived stores, such as embeddings and caches, that would otherwise survive deletion of the raw record.

    The resulting audit record can be compact. For each collection job, capture the system owner, requested host, content origin, fields retained, controls encountered, asserted rights basis, retention period, downstream recipients, deletion path, and stop trigger. If your team cannot fill in one of those entries, mark it unknown rather than turning an assumption into policy.

    Payload minimization is especially useful while the law remains contested. A rank-monitoring feature may need a result URL and position but not a permanent archive of every Reddit snippet. A citation feature may need a URL and a short display label but not the full discussion. An AI discovery tool may need topical signals while having no product reason to reproduce complete comments. Delete fields that do not support a named function, and stop collecting them at ingestion rather than relying only on later cleanup.

    Be equally precise about AI use. “Used for AI” can mean measuring whether Reddit appears in search results, retrieving a passage at query time, generating embeddings, fine-tuning a model, or displaying source text beside an answer. Record those as distinct operations. Otherwise, a rights review performed for internal analytics can silently become the justification for a customer-facing content product it never evaluated.

    Plan for the ruling without betting your product on it

    A result for either side will be easy to overread. A dismissal based on Reddit’s ownership allegations would not necessarily approve every method of collecting Google results. A ruling focused on short, unprotectable fragments would not automatically cover full comments or threads. A conclusion that the alleged conduct did not amount to circumvention would depend on the controls and access path before the court, not on the generic fact that software performed the request.

    A dismissal with prejudice would end Reddit’s claims against SerpApi in this instance. It would not function as a universal license for SERP scraping, Reddit reuse, or AI training. Conversely, if the amended complaint survives dismissal, that would allow the litigation to continue without establishing that every comparable SEO tool is unlawful.

    You can make several product decisions now without predicting the winner:

    • Freeze expansion of any job whose access route, collected fields, or response to technical controls cannot be reconstructed.
    • Replace blanket claims such as “public data is safe to scrape” with a review that names the host, payload, controls, rights basis, and downstream use.
    • Separate collection modules by platform and field so one disputed input can be disabled without breaking unrelated search intelligence.
    • Require approval before an internal dataset becomes a customer export, training corpus, or feature that displays source language.
    • Give legal and engineering owners the same incident trigger: a new block mechanism, authentication requirement, complaint, takedown request, or material change in collection volume should reopen the review.
    • Preserve enough technical history to explain what the system did before a dispute begins. Reconstructing access behavior after logs have expired leaves both counsel and engineers working from memory.

    Your immediate job is not to decide whether Reddit or SerpApi will win. It is to make your own pipeline explainable and stoppable. If you cannot identify who returned the data, who created it, what you retained, which controls you encountered, and where the material went next, pause the expansion and complete that map first.

    References