I’ve been noticing the rapid transformation in how brands are tracking user behavior online. With privacy laws tightening and browser extensions increasingly blocking data, the demand for cleaner data from ad platforms is higher than ever. This change urged me to explore server-side tagging as a solution.
By implementing server-side tagging, I’ve managed to reduce data loss while collecting cleaner, privacy-compliant data. This approach is invaluable, especially considering the experiences I’ve had with providers like Elevar and Littledata.
So, what exactly is server-side tagging, and in which situations does it really shine? Let’s dive into the details!
What is server-side tagging?
Traditionally, tracking scripts ran directly in the browser. However, with server-side tagging, these scripts operate on a server I control, giving me more control over data processing.
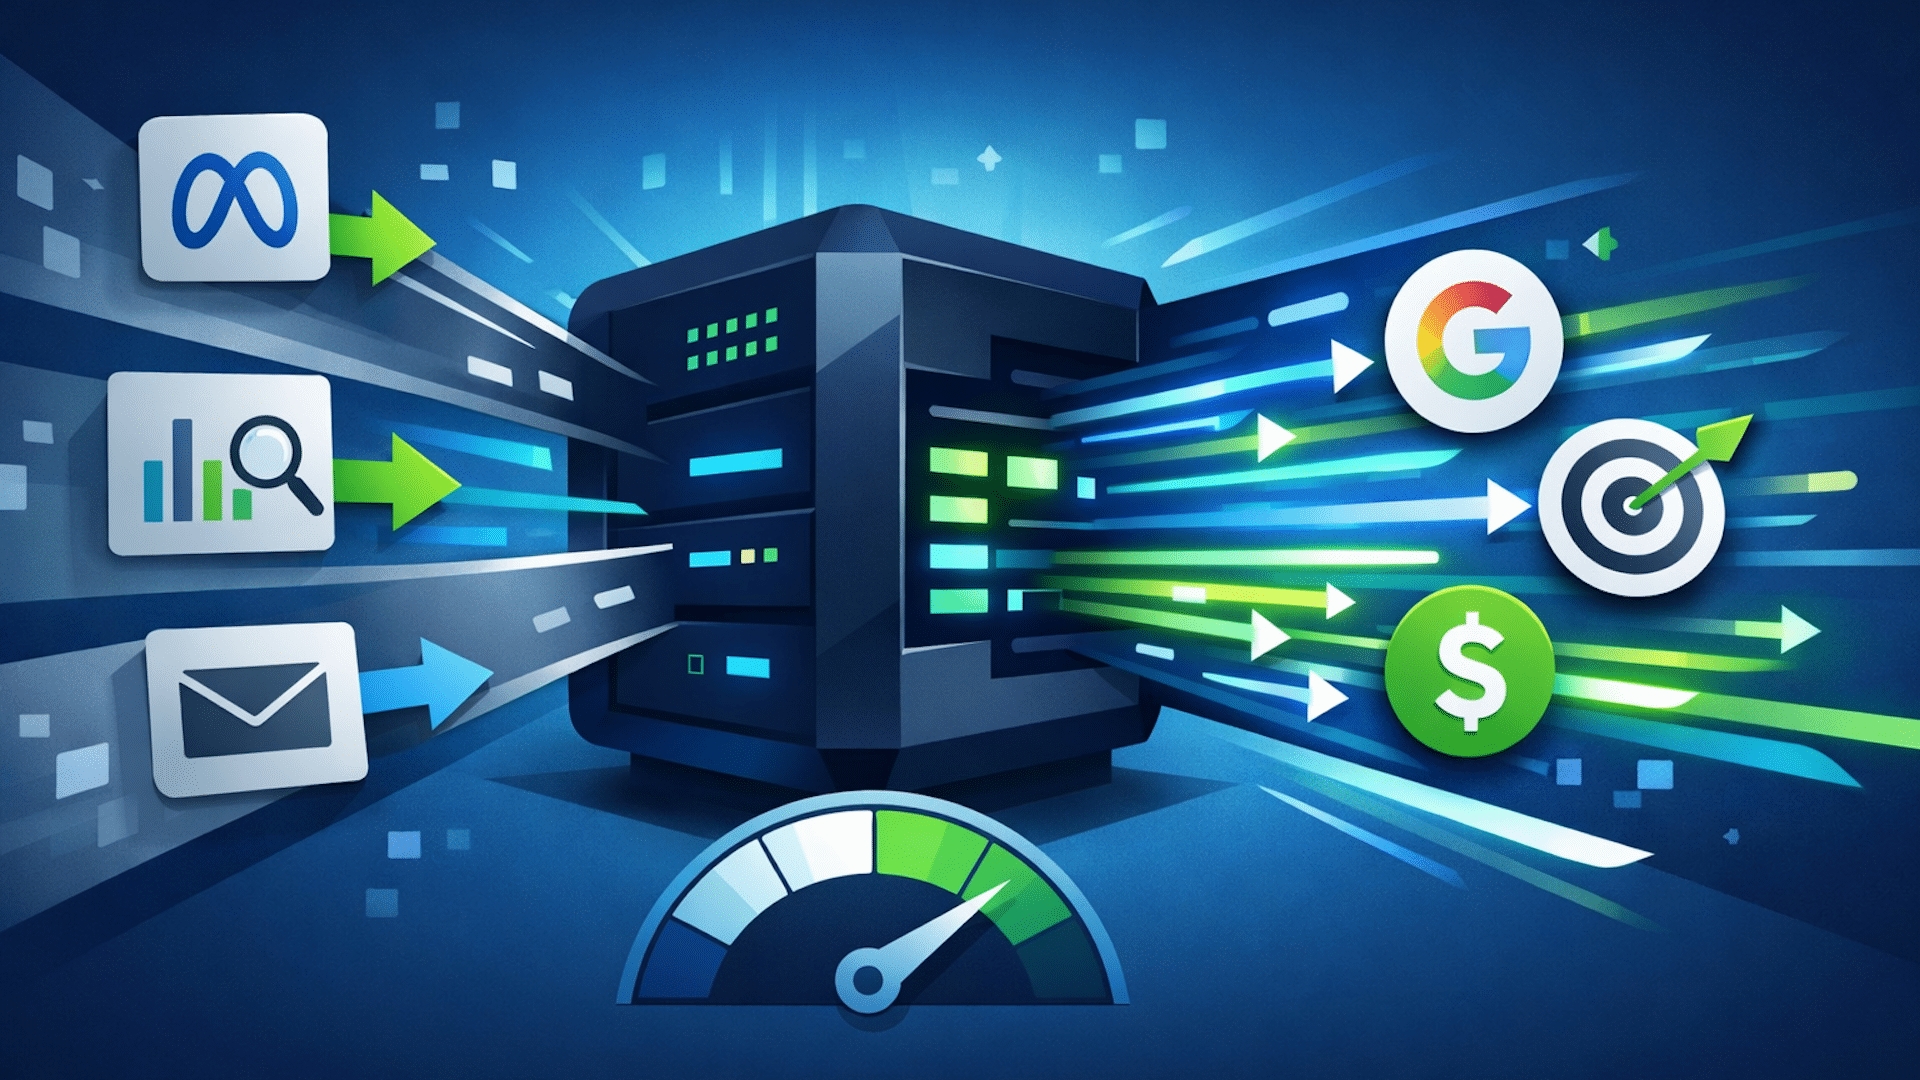
Here’s how it works: instead of sending data straight to multiple third parties from the browser, events are sent to a first-party server endpoint, often using a Google Tag Manager server-side container. The server then processes, enriches, and forwards this data to tools like Meta and Google Analytics.
This setup provides benefits such as more data control, a cleaner page performance, and better compliance with privacy laws.
Moreover, server-side tagging grants me the flexibility to enrich and transform data before it reaches ad platforms, standardizing event names, filtering out low-quality events, and adding custom parameters for better audience segmentation.
Is server-side tagging right for you?
While server-side tagging isn’t a one-size-fits-all solution, many brands find it essential, particularly if you:
You need to meet strict privacy or compliance requirements
Server-side setups allow for greater control over how data is processed and shared, supporting compliance with regulations like GDPR and CCPA.
You want faster website performance
In my experience, client-side tracking can slow your page down, but server-side tagging shifts data processing to the server, resulting in faster websites.
You want more accurate tracking (despite ad blockers)
Ad blockers can hinder client-side scripts, but server-side tagging circumvents many of these restrictions, making your data collection more reliable.
You’re investing heavily in paid media
For those heavily invested in platforms like Meta and Google Ads, achieving better data accuracy can significantly impact return on ad spend.
How to implement server-side tagging
When it comes to implementing server-side tagging, you have two main options: building it internally or using a service provider.
Option 1: Internal setup
Choosing an internal setup gives me complete control but requires technical expertise and ongoing maintenance. This involves setting up a GTM server-side container and adding logic for data processing.
Option 2: Use a server-side tagging service
Platforms like Elevar and Littledata offer turnkey solutions that integrate seamlessly with existing tools, allowing me to focus on strategy rather than technicalities.
Our direct experience: Littledata vs. Elevar
In my experience with Littledata and Elevar, each caters to different needs. Littledata is ideal for emerging brands with simpler tech stacks, while Elevar is suitable for those outgrowing entry-level solutions.
Investing in server-side tagging has transformed how I handle data, ensuring that I remain compliant with privacy laws while boosting site performance and data reliability across all my platforms.
You can hire an agency that improves a channel and still end up with a weaker growth system. Paid media may generate cheaper leads that sales cannot convert. Organic visibility may rise while qualified website visits fall. Marketing may create demand that service and operations are not prepared to support.
The answer is not a longer list of tactics. You need a growth operating model that connects customer states, discovery surfaces, commercial outcomes and decision rights. Once that model is clear, you can judge whether an agency will strengthen it or merely manage part of it.
Replace the single funnel with a growth operating system
Inbound marketing gave teams a coherent sequence: attract an audience, convert visitors and nurture leads. That logic remains useful, but it cannot carry the entire growth plan when discovery, evaluation, conversion and retention happen across different systems.
The old relationship between visibility and traffic is changing as well. An AI-generated answer can satisfy part of a search without sending the user to a website. A prospect can encounter a brand in an AI answer, validate it through search, read customer commentary, click a paid ad later and enter the CRM as direct traffic. A channel report may credit the final interaction while missing most of the journey.
A modern growth model should therefore answer four connected questions:
Model layer
Question to answer
Evidence you need
Commercial outcome
What business result are we trying to change?
A primary outcome, its definition and financial or operational guardrails
Customer state
What must become true for the customer to move forward?
Questions, objections, intent signals and points of friction
Discovery and delivery surfaces
Where can we create, capture, convert or retain demand?
A defined role for search, AI answers, content, paid media, sales and service
Learning loop
How will evidence change the next decision?
An owner, review cadence, decision threshold and change record
If one of these layers is missing, the agency will fill the gap with its own assumptions. A media agency may treat platform revenue as the outcome. An SEO agency may treat rankings as the outcome. A content agency may treat publishing volume as the outcome. Those measures can be useful, but none is a substitute for the business result you hired the partner to influence.
Build the growth brief before you write the agency brief
An agency request for proposal usually starts with services: SEO, paid search, content, analytics or AI optimization. Start one level higher. Describe the growth constraint first, then determine which capabilities are needed to remove it.
Name one primary outcome. State the business result, not the marketing activity. Pair it with guardrails that prevent a local win from damaging lead quality, margin, retention, brand standards or another important constraint.
Map the customer states. Identify what customers need when they are recognizing a problem, evaluating options, making a purchase, adopting the product and deciding whether to continue. Use the states that fit your business instead of forcing every journey into a generic funnel.
Locate the actual constraint. Determine whether the problem is insufficient demand, poor discovery, weak consideration, conversion friction, slow sales follow-up, onboarding failure or low retention. Do not commission more acquisition work when the binding constraint sits after acquisition.
Assign a job to every surface. Decide whether each channel is meant to create demand, capture existing demand, answer a question, support evaluation, convert intent or retain a customer. A surface can support several jobs, but it should have one primary role in the plan.
Define the learning loop. Record what will be observed, who interprets it, which decision it informs and who can approve the change. Reporting without a decision path produces dashboards, not growth.
This is especially important for SEO, answer engine optimization and generative engine optimization. They overlap, but they are not interchangeable line items. SEO can improve discoverability in conventional search. AEO can make an answer easier to extract and present. GEO can focus the work on how generative systems understand, retrieve and represent a brand. Your measurement plan should preserve those distinctions while connecting them to the same customer journey.
Do not force every visibility signal into an immediate revenue calculation. A metric can guide optimization without proving causal impact. Rankings, answer inclusion, brand mentions and qualified visits can show whether discovery is changing. CRM progression, revenue and retention can show whether commercial performance is changing. The agency should explain the relationship between those layers without pretending that one attribution model observes the entire journey.
Your completed growth brief can be one page. It should contain the primary outcome, guardrails, constrained customer state, surface roles, measurement definitions and unresolved questions. That page gives every prospective agency the same problem to solve and makes proposals easier to compare.
Divide ownership before you evaluate capabilities
A growth partner needs room to make decisions, but outsourcing execution does not transfer accountability for the business. Clarify what the brand owns, what the agency owns and what must be shared before discussing deliverables.
The brand should retain business truth. This includes commercial priorities, customer definitions, approved claims, margin constraints, risk tolerance and the final authority over budgets and data access.
The agency should own recommendations and agreed execution. It should identify opportunities, explain trade-offs, perform work within the approved boundaries and maintain a record of material changes.
Measurement should be shared. The agency may build reports, but metric definitions, attribution limitations and tracking changes must be visible to both sides. Neither party should be able to change the meaning of success silently.
Cross-functional decisions need one accountable lead. Someone must reconcile conflicts among marketing, sales, service and operations. A committee can contribute, but it cannot substitute for a named decision-maker.
This ownership map also exposes misleading claims of being full service. A long service menu tells you what an agency is willing to sell, not where it repeatedly performs strong work. Ask what percentage of clients actually use each advertised service. Then ask who leads that work, what other capability it depends on and where the agency normally brings in outside expertise.
Build a simple capability map for every service that matters to your brief. Record the service, client utilization, named practice lead, proposed account owner, proof artifact, dependencies and known limitations. A strong specialist can be a better fit than a nominally full-service agency if your team is prepared to integrate the work. A broad partner can be the better choice when coordination is the main constraint. The right answer depends on the operating model, not the size of the service catalog.
Audit the agency’s decisions, not its pitch language
Most agencies can produce a polished audit and a plausible list of opportunities. Your evaluation should reveal how the team prioritizes, measures, automates and changes course after the pitch is over.
Ask six questions that require operational answers
Which services are genuinely central to your business, and what percentage of clients use each one? Look for a precise denominator, a distinction between core and occasional work, and a candid explanation of where the agency is not the best fit. A service list with no utilization data does not establish depth.
How do you combine platform automation, AI optimization and human judgment? Ask which decisions are delegated to platforms, which inputs the team controls, which guardrails prevent undesirable optimization and what triggers human intervention. “AI-powered” is a label, not an operating procedure.
How does reporting lead to a decision? Have the team walk through an anonymized reporting environment. Ask them to start with the business outcome, trace the supporting indicators, identify an uncertainty and show the action that followed. Revenue and return on ad spend may belong in the view, but the team should also explain attribution assumptions and data limitations.
Who will work on the account, and what is the team’s relevant industry tenure? Get names, roles, responsibilities and escalation paths. Distinguish the senior experts who appear in the pitch from the people who will perform and review the work.
How does your team use generative AI on client work? Separate internal uses, such as analysis or drafting, from advertising-platform automation. Ask which client data can enter a tool, what receives human review, how outputs are checked and how material decisions are documented.
What would you inspect first to reduce waste without suppressing growth? A strong answer should describe a sequence: validate measurement, preserve a baseline, inspect settings and allocation, identify suspected waste, estimate the downside of a change and verify the effect after implementation. A promise to cut spend immediately is not evidence of efficiency.
Score each answer from zero to two. Give zero for a vague claim, one for a credible process without supporting proof, and two for a specific process backed by an artifact and a named owner. This produces a maximum score of 12, but the total is less important than the pattern. A partner that scores well on capabilities but poorly on measurement or ownership can create activity faster than it creates learning.
Set knockout conditions before the presentations begin. Examples include refusing to identify the delivery team, being unable to explain data handling, treating platform-reported attribution as unquestionable, or requesting unrestricted budget authority before measurement is validated. Predefined conditions prevent presentation quality from overriding operational risk.
Turn the winning answers into the working agreement
Anything important enough to influence agency selection belongs in the operating agreement. Otherwise, the senior strategist, reporting method or review practice that won the pitch may disappear during delivery.
Decision rights: Record who can change budgets, targeting, conversion events, content claims, schema, site templates and measurement configurations.
AI boundaries: Define approved uses, prohibited data, review requirements and the person accountable for an AI-assisted output.
Change control: Preserve the baseline, document material changes and record the expected effect before implementation.
Reporting logic: Require each review to show what changed, how confident the team is, what may have caused it, what decision follows and who owns that action.
Escalation: Specify what happens when tracking fails, automation pursues the wrong signal, spend moves outside an agreed boundary or results conflict across systems.
Capability continuity: Define how staffing changes are communicated and how critical account knowledge is transferred.
Give a new partner read access before authorizing material changes whenever the platform permits it. Validate conversion definitions, tracking and historical baselines first. Changing optimization events and budgets at the same time can make the result difficult to interpret, and automation can scale the wrong objective quickly. The safer sequence is to establish measurement, document the hypothesis, make a bounded change and inspect the result before expanding it.
The same discipline should continue after onboarding. Do not evaluate the relationship by deliverable volume alone. Evaluate whether the agency is improving decision quality: finding the real constraint, making uncertainty visible, reducing waste, connecting work across the journey and leaving your team with a clearer understanding of what to do next.
Key takeaways
A modern growth model connects commercial outcomes, customer states, discovery surfaces and a defined learning loop.
Write the growth problem before selecting services. Otherwise, every agency will frame the problem around what it sells.
Keep business truth and final accountability with the brand while giving the agency explicit execution and recommendation rights.
Test full-service claims with client utilization, named specialists, dependencies and proof of repeatable delivery.
Evaluate platform automation and internal generative AI separately; both require clear inputs, guardrails, review and escalation.
Convert important pitch promises into decision rights, reporting rules, staffing commitments and change-control procedures.
Before your next agency conversation, complete the four-layer growth model for one important constraint and send the six audit questions in advance. Ask every contender to answer with artifacts, named owners and explicit limitations. The partner that can work inside that level of clarity is far more useful than one that merely offers the longest list of channels.
Your campaign can be configured correctly inside every advertising platform and still produce a measurement mess. The ad attracts an interaction, the tag records an event, analytics classifies it differently, and the bidding system optimizes toward something nobody intended.
The fix is not another dashboard or another tag. You need one traceable chain from the format a person sees to the business outcome you want, with a clear role and a test at every handoff.
Key takeaways
Define each conversion in business terms before configuring it in Google, Meta, Google Tag Manager, or an analytics property.
Give ad formats, tagging, measurement, and automation separate jobs and separate acceptance tests.
Treat every new ad format as a new measurement surface, especially when one unit presents several locations or choices.
Reuse an established data layer through official platform templates where supported, but verify mappings and duplicate events before publishing.
Do not increase spend until you can trace one test action from the page or app through the tag, platform, report, and optimization setting.
Build one conversion contract before touching platform settings
Advertising platforms encourage you to start with their menus: choose an objective, install a tag, select an event, and launch. That sequence is convenient, but it lets each platform define your measurement model. The same customer action can then become a primary conversion in one account, a secondary event in another, and an analytics event with a third meaning.
Start with a conversion contract instead. This is a short specification for what happened, why it matters, and how every system should represent it. For each event, record:
You may be optimizing product pages for the click while Google is redesigning shopping around a different outcome: identify a suitable product, validate the choice, and potentially complete the purchase inside AI Mode or Gemini. That changes where ecommerce visibility is won.
You now need two connected systems. The first makes your catalog understandable and competitive during AI-assisted discovery. The second lets an approved product move through an in-search transaction without introducing price, availability, identity, or payment failures. Here is how to prepare both without confusing checkout access with search visibility.
The new commerce funnel starts in the product graph
A conventional SEO funnel assumes that search earns a click, the product page creates confidence, and the merchant site completes the sale. Google’s emerging commerce model can compress those stages. A user may describe a need conversationally, receive product recommendations, compare options, and check out without following the familiar sequence of search result, landing page, cart, and checkout.
Generic titles, missing identifiers, weak attributes, or unusable images make the product hard to match and compare.
Product page
Do the details support the product record and the buyer’s decision?
The page and feed describe different variants, benefits, prices, or availability.
Commerce integration
Can the selected product be purchased successfully in the Google experience?
The discovery record cannot be resolved to the correct variant, checkout state, identity, or payment flow.
Use those layers to triage problems correctly. Low discovery visibility is usually a matching and data-quality problem before it is a checkout problem. A visible product that cannot complete a transaction is an integration problem. A product that earns attention but not purchases may have a merchandising, offer, or expectation problem. Putting every weak result under the label of SEO hides the part that actually needs work.
Make the product feed an organic discovery asset
Many merchants let the paid media team own the only feed. That arrangement keeps campaigns running, but a feed shaped around bid relevance and advertising conventions is not automatically the best representation of how people search organically. Paid and organic outputs can share a catalog while applying different rules to titles, descriptions, and supporting attributes.
Build records around the language of product selection
The title is your highest-priority matching field. Write it so a person can identify the product without seeing the image or visiting the page. Start with the product type and add the attributes that genuinely distinguish the item, such as brand, material, capacity, size, color, compatibility, or intended use. The useful combination depends on the category. Do not force every possible modifier into every title, and do not repeat words merely to make the record longer.
A good test is to compare the title with the phrases a buyer would naturally use when narrowing a choice. If shoppers distinguish your products by capacity and compatibility, those attributes deserve more attention than internal collection names. If the title could apply equally to many products in your own catalog, it is probably too vague for an AI system to select confidently.
Use accurate GTINs where the product has them. Correct identifiers help Google match identical products, combine relevant information such as reviews, and understand that two differently worded listings refer to the same item. Well-matched products with accurate GTINs can receive up to 40% more clicks. Never invent an identifier or reuse one from a different variant.
Supply both clear standard images and useful lifestyle images. The standard image should make the product easy to identify. A lifestyle image should add context, scale, or use information rather than obscure the item. Image problems can also cause Merchant Center disapprovals, so treat asset validation as feed health, not decoration.
Use product_highlight for concise buyer benefits. Replace empty claims such as high quality with concrete outcomes. A statement about handling light rain during a commute tells the buyer more than an unsupported adjective.
Use product_detail for structured specifications. Put filterable facts such as dimensions, material, capacity, and compatibility into the structured field that represents them. Do not bury every decision-critical fact in prose.
Keep the feed and product page synchronized. A refined feed title cannot compensate for a page that represents a different variant, price, feature set, or availability state. The two surfaces should describe the same purchasable product.
Create a controlled organic output
You do not need two unrelated catalogs. You need one reliable product source and a controlled way to publish an organic-oriented output without letting paid campaign conventions overwrite it. Depending on your commerce stack, that may be a dedicated feed or a dedicated set of transformation rules. Either way, document which fields are canonical, which fields may vary by channel, and who approves each change.
The potential impact is material, but it should not be treated as a guaranteed benchmark. In one major ecommerce implementation, an organic feed produced a 10% month-over-month increase in organic listing click-through rate and a 4% increase in purchase rate. A product-level test recorded 92% higher free-listing revenue, 83% more visibility, and a 14% increase in add-to-cart rate. Another organic optimization set generated 35,000 impressions at a 1.4% click-through rate, which was 55% above the paid click-through rate for the same period. Those results establish that feed changes can be commercially important; they do not establish a universal lift for every catalog.
Run your own controlled evaluation:
Select a coherent product group with enough existing activity to measure.
Record its free-listing impressions, click-through rate, add-to-cart rate, purchase rate, and revenue before changing the feed.
Change one field family at a time when practical. A title test is easier to interpret if you do not simultaneously replace every image and description.
Keep a version log that connects each feed change to the affected product IDs.
Compare product-level outcomes, not only catalog-wide averages. A large category can conceal both strong winners and harmful rewrites.
Check paid performance separately. An organic improvement does not prove that the same wording should replace a paid title optimized for a different matching and bidding context.
The goal is not to make the organic feed sound conversational at any cost. It is to make the product record precise in the language buyers use while preserving exact identifiers, specifications, and variant distinctions.
Prepare for UCP without mistaking checkout for ranking
Approval opens a transaction path; it does not establish a search-ranking benefit. Treat discovery eligibility and transaction readiness as separate workstreams unless Google explicitly documents a connection. A product still needs strong, consistent data to be selected. UCP then addresses whether the selected item can move through checkout inside the Google experience.
Google has also added a native_commerce attribute for UCP-powered purchase buttons. Do not treat that attribute as a shortcut around integration quality. A buy button attached to stale price, availability, or variant data creates a more immediate failure than a conventional listing because the shopper is already trying to transact.
Confirm the access path. Check Merchant Center for UCP onboarding availability and follow the interest and approval process. Do not promise a launch date internally until the account has access.
Assign a catalog system of record. Every purchasable variation needs a stable mapping between the feed record and the item your checkout can fulfill. Resolve duplicate identifiers and unclear parent-variant relationships before transaction testing.
Map the checkout data contract. Identify which system owns product identity, selected variant, price, availability, buyer identity, payment state, and transaction outcome. Document how a change in one system reaches the others.
Use the available sandbox. Merchant Center onboarding includes a testing sandbox, identity linking, and checkout APIs. Test successful transactions as well as unavailable products, changed prices, unresolved identities, declined payments, and interrupted requests.
Define operational ownership. SEO can improve matching, but commerce, engineering, privacy, security, payment, and customer-support owners need responsibility for the parts they control. Decide who pauses native checkout when catalog or transaction data becomes unreliable.
Activate only after reconciliation. The feed, product page, commerce system, and transaction response must resolve to the same product and offer. If they do not, keep the safer redirect-based journey until the mismatch is fixed.
This is where cross-team collaboration becomes practical rather than ceremonial. SEO contributes query language and matching logic. Commerce owns product truth and fulfillment constraints. Paid media teams often understand feed tooling and disapproval management. Engineering owns the integration path. Each team should have a named field or state to maintain, not a general instruction to support AI commerce.
Measure discovery and checkout as one journey, not one metric
In-search checkout weakens the old assumption that a successful search interaction produces a website session. When a customer can purchase inside an AI interaction without being redirected to the merchant site, traffic alone becomes an incomplete measure of both SEO and commerce performance.
Build a measurement chain that follows the product as far as your available data allows:
Catalog health: Track active products, rejected or disapproved items, identifier coverage, image issues, and unresolved feed-page discrepancies. A product excluded before matching cannot generate a meaningful visibility or conversion signal.
Discovery: Track impressions and click-through rate by product, product group, query class, and Google surface where those dimensions are available. Separate free listings from paid placements.
Consideration: Track the interactions you can observe between a product impression and checkout. Keep website engagement separate from native interactions so a change in surface mix does not look like a sudden behavioral collapse.
Transaction: Track checkout attempts, successful purchases, failures, and the product or variant involved. Preserve a reference that lets commerce and analytics teams reconcile the transaction with the originating product record.
Business outcome: Compare completed orders and revenue with website sessions and site-based orders. A decline in site traffic is not automatically lost demand if more transactions are completing elsewhere. It is also not automatically good news; you need reconciled purchase data to tell the difference.
Capture a baseline before enabling native checkout. After activation, segment results by surface and product group rather than comparing one blended total with the previous period. Otherwise, a shift from website checkout to Google checkout can be mistaken for an SEO loss, while a surge in product impressions can be mistaken for commercial growth without completed purchases.
Document your attribution rule as part of the integration. Decide how you will classify a purchase discovered in AI Mode, completed through native checkout, and fulfilled by your commerce system. The rule matters less than using it consistently and making its limits visible. Do not allow SEO, paid media, and commerce dashboards to claim the same order independently.
You should also watch for substitution. Native checkout may replace a transaction that would otherwise have occurred on your site, or it may capture demand that would have been lost through extra steps. Compare the full order picture rather than assuming every native purchase is incremental or every missing session represents cannibalization.
Key takeaways
Google commerce visibility begins with product data, so Merchant Center feed quality is now part of organic and AI search optimization.
Optimize organic titles around the attributes buyers use to identify and distinguish products, while preserving accurate GTINs, specifications, images, price, and availability.
Use a dedicated organic feed or controlled organic transformation rules instead of forcing paid and free listings to share every optimization decision.
Treat UCP as a checkout capability, not a ranking shortcut. Discovery quality must be solved before native transaction readiness can help.
Prepare stable product mappings, clear system ownership, sandbox failure tests, and a safe way to pause native checkout when data becomes unreliable.
Measure catalog health, discovery, transaction outcomes, and total orders together because website sessions no longer represent the entire shopping journey.
Start with a catalog reconciliation, not a checkout build. Choose a representative product family and align its titles, identifiers, attributes, images, page details, price, and availability. Then name the owner of every field and transaction state. That work improves discovery whether or not UCP access has reached your account.
When access becomes available, take the same reconciled products through the sandbox before expanding. You will learn more from a small group with traceable data and observable failures than from activating native checkout across a catalog whose product truth is still disputed.
If your organic sessions are falling while your brand still appears in AI answers, you do not have one visibility problem. You have at least three: whether machines can access your content, whether answer systems select it, and whether people visit after seeing it.
Those stages need different measurements and different fixes. Separate them, and you can tell whether to improve a page, investigate a ranking change, strengthen attribution, or restrict a crawler before it consumes more value than it returns.
Key takeaways
Measure content access, AI mentions and citations, referral sessions, and business outcomes separately. A lost click is not automatically lost visibility.
Diagnose impressions, rankings, click-through rate, and AI referrals before editing content. Ranking loss and referral loss can happen together, but they are not the same failure.
Give answer systems a clear, supportable answer while giving people a practical reason to visit, such as a workflow, template, decision tool, original data, or implementation detail.
Classify bots by identity and business role. Allow, rate-limit, license, challenge, or block them according to their value, cost, and contractual status.
Build a visibility ledger that follows the whole journey
Sessions used to serve as a rough proxy for search visibility because discovery commonly led to a results page and then a click. An AI interface can now retrieve a page, use its information, mention its brand, cite its URL, and still satisfy the user without sending a visit. One traffic graph cannot show which of those events occurred.
Use a ledger with three distinct stages:
Access: a search crawler, training crawler, or real-time fetcher can retrieve the page.
Selection: an answer system uses the information, mentions the brand, or links to the page.
Referral and value: the user visits, engages, subscribes, generates a lead, or completes another meaningful action.
The distinction matters because the gap can be severe. Akamai measured application-layer traffic across websites, apps, and APIs from July through December 2025 and found AI bot activity up 300% during 2025. Within that analysis, AI-chatbot referrals delivered about 96% less traffic than traditional search, while only about 1% of users clicked sources cited in AI answers. Treat those figures as directional evidence, not universal benchmarks: your result will depend on your audience, query mix, business model, and the interfaces that expose your content.
Layer
Record
What a change can indicate
First response
Traditional search exposure
Impressions, query, landing page, market, and average position
Changes in demand, ranking, eligibility, or query mix
Segment the loss before changing pages
Traditional search referral
Clicks, click-through rate, sessions, and landing-page outcomes
A difference between being shown and being chosen
Inspect result presentation, search features, intent, and page promise
AI selection
Accurate brand mentions, linked citations, cited URLs, and factual errors across a fixed prompt set
Whether the brand is represented and whether an owned page receives attribution
Check entity clarity, answer structure, evidence, and page accessibility
AI referral
Raw referrer, channel, landing page, engagement, conversion, and revenue where available
Whether observed visibility produces visits and business value
Improve the post-answer reason to visit and the landing experience
Whether retrieval consumes infrastructure without a corresponding benefit
Allow, rate-limit, license, challenge, or block by bot class
For AI selection, build a repeatable prompt panel rather than collecting convenient screenshots. Include the questions that matter at each stage of your customer’s decision, then preserve the exact prompt, interface, language, market, date, response, mention, citation, and cited URL. If you operate across languages or countries, maintain separate panels; visibility in one market does not establish visibility in another.
Choose prompts from real search queries, support questions, sales objections, and tasks associated with your important pages.
Run the same prompts under comparable conditions. Changing the wording and the interface at the same time makes the result difficult to interpret.
Record an accurate mention separately from a linked citation. A brand can be visible without receiving an owned link.
Check whether the answer represents the brand, product, author, and claim correctly. An inaccurate mention is not a visibility win.
Annotate content releases, schema changes, crawler-policy changes, major deployments, and confirmed search updates beside the results.
Create simple rates from this ledger: prompts with an accurate mention divided by prompts checked; prompts with an owned citation divided by prompts checked; and AI-referred conversions divided by identifiable AI-referred sessions. Keep the underlying counts beside every rate. A perfect percentage from a tiny or changing prompt set can create more confidence than the measurement deserves.
Normalize recognizable AI referrers into a reporting channel, but preserve the raw referrer and landing page. Do not depend on campaign parameters for links you do not control. Some interfaces expose little or no useful referral information, so analytics should be treated as the observable portion of AI traffic, not a complete census of AI influence.
Separate ranking loss from click loss before editing content
A traffic decline near an algorithm update invites a quick rewrite. That can destroy useful evidence and change the page before you know what failed. Start by marking the rollout window. The March 2026 Google core update ran from March 27 through April 8, finishing after 12 days and 4 hours. A comparison that mixes rollout days with stable periods cannot cleanly separate the before and after states.
Annotate the confirmed update window and every important site change, including migrations, template releases, internal-link changes, rendering changes, and crawler rules.
Compare matched periods outside the rollout. Account for normal seasonality, promotions, and demand changes that affect the same queries.
Segment by query group, page type, directory, market, and device. Sitewide averages can conceal a concentrated loss in one template or topic.
Inspect impressions, position, clicks, and click-through rate together. Then compare those patterns with your sampled AI visibility and AI-referral data.
Review the affected page group only after the failure mode is visible. Preserve an export or snapshot before making material changes so you can evaluate and reverse them.
Use the pattern, not one metric, to choose the next action:
If impressions and positions decline for the same queries and pages, investigate a ranking, relevance, eligibility, or demand problem. Do not assume that a lower sitewide average tells you which one.
If impressions remain broadly stable while clicks and click-through rate decline, the result is still being shown but fewer searchers are choosing it. Inspect the result-page features, title and snippet promise, intent fit, and competing ways the query is answered.
If traditional search remains stable while sampled AI citations or identifiable AI referrals decline, check machine access, citation selection, brand ambiguity, and measurement coverage before rewriting the page.
If sessions decline but qualified leads, subscriptions, or revenue do not, quantify the commercial effect before setting a traffic-restoration target. Not every lost informational click has the same value.
If several layers decline at once, keep separate workstreams. A content review cannot repair broken bot access, and a crawler rule cannot make an unsatisfying page more useful.
Google’s standing position is that a core-update decline does not necessarily mean something is wrong with the site, and meaningful recovery may depend on a later update. That is a reason to avoid panicked reversals, not a reason to wait passively. Review whether affected pages deliver helpful, reliable, people-first information, especially where the page promise and the actual answer have drifted apart.
Create pages that can be cited and still deserve a visit
Trying to withhold the basic answer is a poor response to zero-click search. It frustrates readers and leaves answer systems with weaker material to interpret. State the answer clearly, support it, and make the rest of the page valuable after the answer is known.
A citation-ready, visit-worthy page usually needs these layers:
A decisive answer: address the page’s main question directly instead of making the reader extract it from a long preamble.
Scope and qualifiers: state the country, language, platform, version, date, audience, or conditions that change the answer. A technically correct statement can still mislead when its scope is hidden.
Evidence: connect important claims to their originating authority, underlying data, or documented method. Distinguish a fact from an inference or editorial recommendation.
Entity clarity: use consistent names for the organization, product, author, location, and service. Explain relationships that a reader should not have to infer from branding alone.
A decision layer: show trade-offs, applicability, exclusions, and common misreadings so the reader can decide whether the answer fits their situation.
An action layer: provide the procedure, checklist, template, calculator, original data, implementation detail, or troubleshooting path that helps the reader complete the task.
This structure makes the central claim easy to identify without turning the page into a disposable definition. The answer earns selection; the decision and action layers earn the visit.
JSON-LD can clarify what a page represents, but it is not a referral strategy and it does not guarantee selection in an AI answer. Use the schema type that matches the visible content, connect related entities consistently, and validate the markup after publishing. Do not place claims, reviews, authorship, dates, or relationships in structured data that the page itself does not support.
Apply the same discipline to freshness. Show a meaningful update date when the substance changed, identify version-dependent instructions, and remove contradictions between the page, its metadata, and its structured data. Changing a date without revising stale information creates a freshness signal for the editor, not new value for the reader.
Before consolidating or unpublishing a weak page, check its inbound links, internal links, ranking queries, citations, conversions, and role in a topic cluster. Preserve a copy and plan the appropriate destination before removing a URL. A careless cleanup can erase authority or break an existing citation even when raw sessions look unimportant.
Turn AI crawler access into an explicit business policy
More machine access does not automatically produce more discovery, attribution, or revenue. It can also increase server and CDN costs. The 300% rise in AI bot activity observed during 2025 makes bot classification an operating issue, not merely a security log to review after something breaks.
Start by separating training crawlers, which collect material for model development, from real-time fetchers, which retrieve current content to answer a live request. Their timing, potential value, and commercial relationship differ. A single allow-or-block rule ignores those differences.
Bot class
Possible business role
Policy options
Main risk to check
Search or discovery crawler
Makes pages eligible for a discovery surface
Verify and allow under controlled limits
Blocking can remove a path to visibility
Authenticated licensed agent
Accesses content under agreed commercial terms
Allow only within authenticated scope and limits
Unverified requests may exceed the agreement
Real-time answer fetcher
Retrieves current information for an immediate answer
Allow, rate-limit, or license according to measured value and cost
Fresh content may be consumed without useful attribution or referral
Training crawler
Collects content for model development
Allow, block, or license according to rights and commercial policy
Direct referral value may be weak or unobservable
Unknown or abusive scraper
No verified legitimate role
Challenge, rate-limit, block, or cautiously tarpit
Spoofed identities and false positives can misclassify traffic
A user-agent string is a claim, not proof. Where an operator publishes a verification method, use it. Keep agent identity, request behavior, targeted URLs, bandwidth, origin load, and any referral or licensing value in the same review. That turns a vague bot debate into a policy decision supported by observable costs and benefits.
Observe before enforcing. Establish which agents request which page groups and how much infrastructure they consume.
Verify identity. Do not grant privileged access or apply a punitive rule solely from a self-declared bot name.
Assign a role. Record whether the agent supports discovery, live answering, training, a licensed relationship, or no recognized purpose.
Choose the least disruptive effective control. Options include scoped access, caching, rate limits, authentication, challenges, blocking, and carefully tested tarpitting.
Stage material changes with a rollback path. Watch crawl activity, indexation, sampled AI citations, referrals, server load, and user errors after enforcement.
Review licensing and content-rights terms with appropriate legal counsel before charging for access or signing an agreement. A crawler configuration cannot determine ownership or contractual rights.
Robots directives can communicate preferences to compliant agents, but they are not authentication or an access-control wall. Enforce sensitive or paid access with controls that can identify and authorize the requesting agent. If you use tarpitting, apply it only after careful classification: deliberately slowing the wrong traffic can harm legitimate discovery or user-facing performance.
Emerging approaches such as Know Your Agent identity verification and TollBit pay-per-crawl access are intended to turn retrieval into an authenticated, manageable transaction. Treat that model as an option to evaluate, not guaranteed replacement revenue. The commercial case still depends on enforceable identity, demand for your content, contract terms, delivery cost, and the value of any visibility you give up by restricting access.
Your next move should come from the first broken link in the chain. Build the ledger, mark known update and deployment dates, test the questions that matter, and classify the agents consuming your pages. Then change one layer at a time and keep a rollback path. That is how you protect visibility without mistaking every lost click for a lost audience.
Embrace audience engineering to influence AI decisions, manage ad spend wisely, and connect with high-value customers through creativity and data.
I’m witnessing a significant transformation in the paid media landscape as platforms shift from manual targeting to AI-driven audience discovery. This change is redefining how we approach advertising, with automation tools consolidating campaigns, obscuring data, and favoring prediction algorithms over manual selection.
This transition requires me to innovate by mastering the art of audience engineering. By doing so, I ensure I’m equipped with strategies to thrive in this evolving landscape.
The End of Manual Targeting as I Knew It
Previously, I depended on detailed keyword lists and demographic filters to pinpoint my ideal audience. I directed platforms about where to focus and paid to access the desired market.
However, these options are now outdated:
Google has transitioned to Performance Max, which eliminates keyword-specific targeting in favor of more fluid groups and signals.
Meta’s Advantage+ automates demographic focus, turning my role into that of a signal provider instead of an audience selector.
Microsoft’s inclusion of this model confirms this is an industry-wide evolution.
While traditional targeting seems to have vanished, it has merely moved to the internal structures of the platforms where algorithms dictate the direction based on their indigenous data.
The Rise of Audience Engineering
My role shifts from targeting to engineering as it becomes more about guiding algorithms than manually selecting audiences.
From Targeting to Teaching
The distinction is crucial. Traditionally, targeting emphasized choosing audiences, but now it’s about educating AI with comprehensive conversion data, targeted creativity, and insightful first-party data.
Previously, I might have targeted CFOs with job filters, but now I feed the AI robust data (e.g., “deal closed” signals) to characterize valuable prospects and devise creative content tailored to their needs.
The New Competitive Discipline
Embracing this transformation gives me an edge. By finetuning conversion signals, honing creative content, and fortifying data systems, I ensure our performance remains robust.
The performance gap now relies on the quality of signals, making audience engineering pivotal for success.
The Three Levers that Now Drive Targeting
I focus on optimizing these three crucial AI inputs to ensure effective audience segmentation:
1. Conversion Signal Quality
By providing the algorithm with relevant business outcomes rather than superficial metrics, I encourage it to find results that truly matter.
Using tools like Offline Conversion Imports (OCI) and the Conversions API (CAPI), I ensure our data highlights genuine sales by leveraging value-based bidding techniques.
2. Creative as a Targeting Mechanism
With no demographic filters, my creative content now acts as the primary targeting tool, filtering users through its message.
If my creative targets niche pain points, the AI connects with users aligned with that perspective, even without traditional filters.
3. First-Party Data as Competitive Moat
Our customer lists and engagement signals become core learning elements for the algorithm, replacing third-party signals and offering a competitive edge.
Essentially, I’m arming the AI with a guide to discover the most profitable audiences.
How This Plays Out in Real Campaigns
The journey to AI-led targeting isn’t just theoretical. Within our agency, managing over $215 million in media spend annually, we have evaluated this approach across different platforms, witnessing its power firsthand.
Advantage+ Audiences in Practice
One long-standing client had a specific perception of their audience based on a vast history of accurate data. Initially, our campaigns ran with tightly controlled targeting to maintain efficiency.
Transitioning to Advantage+ allowed for data-driven optimization, revealing an unexpectedly lucrative older demographic, improving their click-through rates by 37% and conversion rates immensely.
Broader AI-optimized targeting cut costs and raised revenue — outperforming past manual methods.
By aligning goals with data and creative, we found valuable segments conventional targeting schemes previously overlooked.
Microsoft PMax Placement Transparency and Advanced Audience Signal Targeting
Another client benefited from a Microsoft PMax test, effectively targeting high-intent prospects using internal data across several Microsoft networks, seeing notable increases in performance metrics each month.
This trial highlighted the importance of combining strategic oversight with smart AI deployment, enhancing the algorithm’s reach while maintaining disciplined campaign direction.
The balance between scale and strategic input preserved efficiency and bolstered overall performance.
The Risks Nobody is Talking Enough About
While automated targeting offers significant advantages, it’s essential to understand its limitations. Here’s what I strive to avoid:
Garbage In, Garbage Out
Poorly defined conversion objectives, weak data quality, or junk data hinder performance and mislead the algorithm. Feeding it quality information and focused outcomes is crucial.
An overly broad goal without distinct signals results in quantity over quality, which doesn’t necessarily translate to business success.
The Self-Reinforcement Trap
If the seed data has biases, the AI will continuously optimize for those biases, possibly neglecting valuable audience segments.
These underrecognized biases present inherent risks in leveraging automated systems without mindfulness.
Automation Without Oversight
Platforms promote broad automation, but I recognize the need for continued oversight to realign campaigns with business goals.
Constant monitoring is essential to ensure objectives are met, avoiding a passive management style.
Creative Complacency
As automation advances, creative strategy becomes a crucial differentiator and shouldn’t be neglected.
Crafting compelling creative that addresses core customer issues is vital in distinctively standing out.
How to Put Audience Engineering into Practice
Here’s how I integrate audience engineering into everyday operations:
Restructure Creative: Focus on intent signals, addressing what beliefs inspire conversion.
Predefine Guardrails: Establish performance boundaries before unleashing the algorithm, allowing for better campaign control.
The Future Belongs to Audience Engineers
The era of manual targeting is closing, but precision remains crucial. Audience engineering acts as an invaluable skill, unlocking AI’s full potential to achieve maximum results in this dynamic landscape.
If you are comparing AI search optimization agencies, the hard part is not finding firms that promise more visibility. It is identifying which one can turn your content, technical foundation, brand knowledge, and authority into a coherent program without selling you a renamed SEO retainer.
Define the job before you ask agencies to solve it
AI search optimization is not a single deliverable. It is a set of connected activities intended to make your brand and content easier for AI systems to retrieve, understand, represent accurately, cite, and recommend when the context warrants it.
That distinction matters during procurement. If your brief says only that you want to improve AI visibility, every agency can interpret the assignment in a way that matches what it already sells. One may propose content production, another may lead with JSON-LD, and another may offer a monitoring dashboard. Those services can be useful, but none is a strategy by itself.
Start by defining the change you want across four layers:
Representation: AI-generated answers describe your company, products, people, and claims accurately.
Discovery: your brand or content appears for relevant questions where you have a legitimate reason to be included.
Evidence: the answer can connect its claims to useful, authoritative pages rather than merely mentioning your name.
Action: the visibility supports a sensible next step, such as visiting a product page, reading supporting evidence, comparing options, or contacting your team.
This framing prevents a common measurement mistake. A brand mention, a linked citation, an accurate recommendation, a referred visit, and a qualified conversion are not interchangeable outcomes. Record them separately. Otherwise, a dashboard can show improvement while the answers remain inaccurate or commercially irrelevant.
Your agency brief should give every contender the same operating context:
Your priority products, services, audiences, markets, and buyer situations.
The questions people ask while identifying a problem, comparing approaches, checking trust, and making a decision.
The pages, databases, documentation, and internal experts that act as your sources of truth.
Claims that require legal, compliance, technical, or subject-matter approval.
Your current content, development, analytics, public relations, and editorial resources.
The systems the agency may advise on and the systems it will actually be allowed to change.
The business outcomes you ultimately care about, along with the earlier signals you can observe before those outcomes occur.
Include a baseline rather than asking the agency to invent one after work begins. For each important question, save the exact wording, the AI service used, the date, the resulting answer, any linked citations, and whether the brand representation was accurate. Keep the relevant landing-page and conversion data alongside those observations when available.
A useful objective might be: improve accurate inclusion and citation for priority decision questions, direct qualified visitors toward authoritative pages, and establish a repeatable process for finding and fixing representation gaps. It is specific enough to guide a proposal without pretending that you control an external answer engine.
Inspect whether the strategy works as a connected system
A credible agency should be able to explain how audience demand, content, entity signals, technical access, outside authority, and measurement reinforce one another. It does not need to perform every activity itself. It does need to identify the dependencies and tell you who owns each one.
Question and intent discovery
Keyword research is useful input, but it does not fully describe the questions people put to an assistant. Ask how the agency will build a working set of questions from customer language, sales objections, support issues, product comparisons, documentation gaps, and conventional search demand.
The result should be organized by user task, not presented as a shapeless list of prompts. Someone defining a problem needs a different answer from someone comparing vendors or checking whether a solution fits a regulated workflow. That difference affects the required evidence, page format, and appropriate call to action.
Watch for invented precision. A prompt list becomes useful when the agency can explain why each question matters, which audience it belongs to, what a good answer must contain, and which page should support it. A large list with no decision context is inventory, not strategy.
Content and entity clarity
The agency should examine whether your pages answer the target questions clearly and whether the supporting claims are specific, consistent, and attributable. It should also distinguish between a missing page and a weak page. Publishing something new when an existing authoritative page needs a clearer answer can create duplication and split maintenance effort.
For each priority page, the plan should identify its subject, intended audience, direct answer, supporting evidence, related entities, internal links, maintenance owner, and next action. This turns vague advice such as improve content quality into an editable specification.
Entity consistency matters as well. Product names, company relationships, leadership details, service areas, and other defining facts should not conflict across core pages and structured data. Ask how the agency will find discrepancies and decide which internal record is authoritative before it recommends markup or rewrites.
Technical access and structured data
The technical review should cover whether important information is available on stable, indexable URLs; whether internal links make relationships understandable; whether canonicalization or access rules create conflicts; and whether templates hide, fragment, or duplicate key answers.
JSON-LD belongs in this workstream, but it should describe facts that users can verify on the page. Structured data can clarify the type of entity or content being presented and expose defined relationships in a machine-readable form. It cannot manufacture expertise, prove an unsupported claim, or rescue content that never answers the question.
Ask for a structured data inventory rather than a promise to add schema. The inventory should connect each proposed type and property to a visible fact, a source-of-truth field, an eligible page template, a validation method, and an owner responsible for keeping the information current.
Authority, distribution, and measurement
An on-site plan is incomplete if it ignores how the brand is represented elsewhere. Relevant mentions, expert contributions, documentation, original evidence, partnerships, public relations, and other legitimate forms of distribution can help establish context beyond your own domain. The agency should explain which activities are justified by the audience and where another team must participate.
Measurement completes the system. The agency should connect each recommendation to an observable change: a clearer answer on the page, corrected entity information, valid structured data, stronger citation coverage, more accurate AI representation, useful referred traffic, or a downstream business action. If the plan jumps from publishing content directly to revenue without showing the intermediate signals, you will struggle to diagnose either success or failure.
Test agency claims with evidence, not vocabulary
Most contenders can discuss AEO, GEO, AI SEO, entities, retrieval, citations, and structured data. Terminology tells you that the team follows the market. It does not tell you whether the team can diagnose your situation, prioritize work, implement recommendations, or separate its contribution from unrelated changes.
Use the same evidence request for every finalist:
Evaluation area
Ask to see
Evidence that matters
Relevant experience
A comparable, sanitized case narrative
The starting condition, diagnosis, intervention, implementation owner, observed change, and limits of the result
AI search expertise
A live explanation of one priority question and page
Clear reasoning across intent, answer quality, entities, technical access, authority, and measurement
Measurement
A sample baseline and recurring report
Raw prompts, captured answers, citations, accuracy judgments, dates, page metrics, and change history behind any summary score
Implementation
A sample content brief, technical ticket, or schema specification
Named owners, dependencies, acceptance criteria, quality checks, and a route from recommendation to release
Brand fit
An explanation of how the plan changes for your audience and constraints
Choices tied to your products, source material, risk, market, workflow, and business goals
Commercial clarity
A scope showing included and excluded work
Separate visibility into strategy, tools, production, development, outreach, reporting, and optional work
Do not accept a case study that starts with a result. Ask what was happening before the work, what changed, what else changed at the same time, and what evidence would weaken the agency’s interpretation. A team that can discuss confounding factors and uncertainty is giving you more useful information than one presenting a smooth success story with no audit trail.
A working session is especially revealing. Give each finalist the same page, target audience, and small group of priority questions. Ask the team to talk through what it would inspect first, which assumptions it would verify, what it would avoid changing prematurely, and how it would turn the diagnosis into tasks. You are assessing the reasoning process, not asking for unpaid strategic work.
Ask who will actually do the work after the sales process. You need to know which roles will handle strategy, content, technical analysis, JSON-LD, analytics, and project management; whether those people are assigned to your account; and where subcontractors or software-generated work enter the process. Senior expertise in a pitch has little value if delivery depends on an unnamed team using an undefined workflow.
Several claims deserve immediate scrutiny:
Guaranteed placement in generated answers. An agency cannot control the output of an external AI service, so it should promise defined work and transparent measurement rather than a specific placement.
A proprietary visibility score with no underlying observations. A score can summarize data, but you still need access to the prompts, outputs, citations, classification rules, and sampling conditions behind it.
Schema as the complete solution. Markup is one technical layer and should be connected to accurate visible content, source-of-truth data, and ongoing maintenance.
Content volume as the primary strategy. More pages can add duplication, inconsistent claims, and editorial debt when question coverage and page purpose have not been mapped first.
A monitoring dashboard presented as optimization. Monitoring can expose a problem; it does not research, edit, implement, validate, distribute, or govern the fix.
AI search results credited entirely to ordinary organic growth. Ask the agency to separate conventional search improvement, branded demand, public relations activity, product changes, and AI-specific observations wherever the available evidence allows.
Recommendations with no implementation owner. A technically correct audit still fails if nobody can convert it into approved changes in your CMS, codebase, data layer, or editorial process.
Build your scorecard before proposals arrive. Evaluate strategic fit, evidence quality, technical breadth, content judgment, measurement rigor, implementation clarity, governance, team continuity, and commercial transparency. Decide which criteria matter most for your current constraint. A company with strong in-house developers may need strategic and editorial depth, while a lean team may need a partner that can carry more implementation.
Put measurement, ownership, and change control in the scope
AI-generated answers can vary with prompt wording, service, context, and time. That makes a single screenshot weak evidence. It does not make measurement pointless. It means the method must preserve enough context for you to distinguish an observation from a trend and a trend from a business outcome.
For each monitored question, the measurement record should retain:
A stable identifier, exact wording, audience, intent, and market or language context when relevant.
The AI service, capture date, and other available execution context.
The complete answer or a faithful stored capture, not only a yes-or-no brand mention.
Whether the brand appears, what role it is assigned, and whether the description is accurate.
Every visible citation and whether it points to your site, another source, or no accessible supporting page.
The owned page intended to answer the question and its publication or revision history.
Referred visits, meaningful on-site actions, and business outcomes when those can be observed responsibly.
Keep three layers separate in reporting. Visibility observations describe what appeared. Quality judgments describe whether the answer and citation were useful and accurate. Business outcomes describe what people did. Combining all three into one number hides the very information you need for prioritization.
Require a change log beside the baseline. It should connect recommendations to approved work, affected URLs or templates, release dates, validation results, and subsequent observations. Without that record, the agency can report movement but cannot show which intervention may have contributed to it.
The scope should also resolve ownership before work starts:
Who approves the question set and can add or retire monitored questions.
Who controls analytics, monitoring, CMS, schema, repository, and reporting access.
Who supplies subject-matter evidence and approves sensitive claims.
Who writes, edits, develops, validates, publishes, and maintains each type of change.
Who owns the resulting briefs, dashboards, configurations, structured data specifications, and historical captures.
How open recommendations and data are handed over if the engagement ends.
Retain administrative control of your own site, analytics, and core business data. Give the agency the access required for its role, but avoid making your ability to operate dependent on an account only the vendor controls. The same principle applies to prompt histories and reporting data: you should be able to inspect and export the evidence used to evaluate performance.
If uncertainty remains, use a bounded pilot to test the working relationship. Give it a defined audience, question set, group of pages, deliverables, implementation route, evidence method, and decision point. The purpose is to learn whether the agency can diagnose, communicate, ship, and measure within your environment. A short pilot should not be treated as proof that every market-level outcome will move.
Compare the cost of the full operating model, not only the agency fee. A proposal may exclude monitoring software, content production, development, design, public relations, or subject-matter review. Make those dependencies visible so a cheaper retainer does not become the more expensive program after implementation begins.
Key takeaways before you sign
Define AI visibility as a set of observable outcomes: accurate representation, relevant inclusion, useful citations, qualified action, and business impact.
Give every agency the same priority audiences, questions, pages, constraints, baseline, and implementation boundaries.
Look for a connected strategy spanning intent, content, entities, technical access, structured data, authority, distribution, and measurement.
Ask for raw evidence behind case narratives and visibility scores, including prompts, answers, citations, dates, changes, and limitations.
Reject guaranteed placements, schema-only plans, volume-first content programs, and dashboards presented as complete optimization.
Put owners, access, deliverables, acceptance criteria, change history, data control, handover, and excluded costs into the scope.
Your next move is straightforward: choose one important audience, one decision journey, a manageable set of questions, and the pages that should support the answers. Capture the baseline, send the same brief to each finalist, and require each team to show how it would move from diagnosis to an implemented, measurable change.
Select the agency whose reasoning remains clear when the evidence is incomplete. The right partner will make assumptions visible, define what it can and cannot control, and leave your organization with a stronger operating system for AI discovery rather than a collection of unexplained tactics.
You have budget, stakeholder expectations, and a shortlist of firms that all claim they can modernize the same systems. The risky decision is not who can produce software. It is who can understand your operating constraints, make sound tradeoffs, ship into your environment, and leave you able to run what you paid for.
For a 2026 procurement, use a selection process that exposes how each provider actually works. Match the provider to your dominant risk, give every candidate the same decision brief, test claims with artifacts and working sessions, protect your exit path in the contract, and run a pilot through the hardest part of the system.
Match the provider model to the risk you need to retire
There is no generally best enterprise custom software provider. A firm can be excellent at integrating known systems and poor at discovering an uncertain product. Another can design a strong customer experience but lack the governance needed for a sensitive migration.
Start by naming the dominant risk in the initiative. Do not begin with a preferred programming language or a list of recognizable firms. Technology matters, but it rarely explains why an enterprise program is difficult.
Your dominant risk
Provider model to examine
Evidence to request
The workflow, product, or user need is still uncertain
A product engineering partner with strong discovery capability
A discovery plan, examples of decisions changed by user evidence, a product leadership role, and a backlog that separates assumptions from validated requirements
The work crosses many internal and third-party systems
A systems integrator or integration-focused engineering firm
System context maps, API and data-contract examples, dependency management, cutover planning, and a reference project with comparable integration boundaries
A fragile legacy platform must change without interrupting operations
A modernization specialist
An incremental migration approach, dependency analysis, data reconciliation, rollback design, and evidence that old and new components can coexist during transition
The system handles sensitive or regulated data
A provider with mature security, privacy, and delivery governance
Named control owners, secure-development practices, audit artifacts, incident procedures, data-flow documentation, and clear subcontractor oversight
The architecture and backlog are already well defined, but capacity is constrained
A managed delivery squad or staff-augmentation provider
The actual proposed team, technical screening methods, onboarding plans, delivery accountability, and a clear boundary between your leadership duties and theirs
This distinction changes your shortlist. Staff augmentation can be appropriate when you already have product ownership, architecture, security, and delivery management. It is a poor substitute for those functions when they are missing. A large integrator may be well suited to a multi-system program but unnecessarily heavy for a focused product build. A specialist can reduce technical risk while still needing your organization to own business adoption.
Write a short risk statement before you contact providers: We need to achieve this operating outcome, and the hardest uncertainty is this constraint. If stakeholders cannot agree on that sentence, the procurement is not ready for a meaningful vendor comparison.
Apply non-negotiable filters next. These can include deployment environment, data location, security obligations, integration platforms, accessibility requirements, support coverage, language or time-zone needs, procurement rules, and restrictions on subcontracting. Treat them as pass-or-fail conditions. A polished proposal cannot compensate for a provider that is unable to operate inside your mandatory boundaries.
Give every candidate a brief that cannot be gamed
Vague requests produce proposals that look comparable but are built on different assumptions. One provider may include discovery, migration, testing, and production support. Another may quote only implementation. The lower number then reflects a narrower interpretation, not necessarily a more efficient team.
Your decision brief should give every candidate the same view of the problem while leaving room for them to challenge the proposed solution.
Current state: Describe the workflow, systems, users, data sources, ownership boundaries, and recurring failure points. Include diagrams where they exist, but mark anything that may be outdated.
Desired business outcome: State what must become observably different. Replacing a platform is an activity; removing duplicate entry, improving decision visibility, or enabling a new service is an outcome.
Scope boundaries: Identify what is included, what is excluded, and what remains undecided. Hidden exclusions tend to reappear as change requests.
Known constraints: List mandatory platforms, identity systems, integration protocols, data classifications, accessibility expectations, release controls, and operational windows.
Unknowns: Name uncertain data quality, undocumented interfaces, unresolved ownership, pending policy decisions, or dependencies on other programs. You are testing how the provider handles uncertainty, not whether it pretends uncertainty is absent.
Internal responsibilities: Name the people who own product decisions, architecture, security, data, operations, procurement, and acceptance. If a role is unfilled, say so and ask how the provider would cover or help establish it.
Commercial boundaries: Explain the available budget process, approval gates, target window, and any required pricing structure. Ask providers to separate assumptions, exclusions, optional work, and third-party costs.
Decision method: Tell candidates which evidence will be evaluated, who will participate, and which conditions are mandatory. This discourages proposals designed mainly to impress an executive audience.
Require a common response structure. Each proposal should identify the proposed first phase, the questions it will answer, the actual roles needed, major dependencies, technical unknowns, delivery governance, security responsibilities, acceptance approach, commercial assumptions, support model, and exit plan.
Do not reward false precision. A detailed estimate built before the provider has seen the systems can still be a guess with professional formatting. Ask what evidence supports the estimate, which assumptions have the greatest cost impact, how uncertainty is represented, and what event would trigger re-estimation. Compare the boundaries behind the numbers before comparing the numbers themselves.
Also let candidates disagree with your requested solution. A credible provider should be able to explain which requirement it would validate first, which architectural commitment it would delay, and which part of the proposed scope creates avoidable risk. Blanket agreement is not proof of collaboration.
Test delivery behavior, not presentation quality
A proposal tells you what a provider wants to promise. Your evaluation needs to reveal how its team reasons when information is incomplete, dependencies conflict, or a release fails.
Create the scorecard before demonstrations begin. Otherwise, a charismatic presenter or attractive prototype can quietly redefine what matters. Choose criteria that reflect the consequences of your program, assign their relative importance, and define the evidence required for each rating.
Problem fit: Does the provider understand the operating problem, users, constraints, and adoption burden?
Technical judgment: Can the team explain architecture choices, integration boundaries, tradeoffs, failure modes, and migration sequencing?
Delivery discipline: Are decisions, risks, dependencies, testing, releases, and changes managed visibly?
Security and privacy: Are responsibilities embedded in delivery, or deferred to a review near launch?
Team quality: Have you met the people who will perform the work, and do their roles match the proposal?
Operational readiness: Will your organization receive the monitoring, documentation, deployment assets, and knowledge needed to operate the system?
Commercial clarity: Are assumptions, exclusions, third-party costs, change mechanisms, and support obligations understandable?
Independence: Can you retain, operate, modify, and transition the software without being trapped by undocumented knowledge or proprietary dependencies?
Have evaluators record their ratings independently before the group discussion. The goal is not mathematical certainty. It is to make disagreements visible. A security lead and a product owner may rate the same proposal differently for valid reasons, and those differences point to decisions the steering group must resolve.
Use a scenario workshop to expose the real team
Give shortlisted providers the same time-boxed scenario based on a genuine risk in your environment. For example, an upstream system begins returning incomplete records during a staged release, or a new identity requirement conflicts with the planned user journey. Ask each team to work through questions, options, ownership, validation, deployment, monitoring, rollback, and stakeholder communication.
Do not grade the workshop on whether the provider guesses your preferred answer. Notice whether the team:
asks about business impact before selecting a technical response;
separates known facts from assumptions;
identifies who has authority to make each decision;
considers data integrity, security, operations, and user impact together;
offers reversible steps while evidence is incomplete;
makes disagreement visible instead of hiding it behind consensus language; and
records decisions and unresolved questions in a form another team could use.
Follow every important claim with an evidence request
Use a simple chain: claim, artifact, reference, and working explanation. If a provider claims mature DevSecOps, inspect a redacted pipeline or control artifact and ask the proposed delivery lead to explain how exceptions are handled. If it claims expertise in legacy modernization, ask for a migration decision, the tradeoff behind it, and a client reference who can discuss the difficult part of the transition.
Reference calls are not character checks. Confirm whether the people presented during procurement remained involved, where the estimate changed, how bad news was communicated, which responsibilities stayed with the client, how production incidents were handled, and what the client had to rebuild or document after handover.
Red flags include unnamed delivery personnel, heavy reliance on sales demonstrations, estimates without assumptions, security deferred until the end, proprietary components without a transition path, undisclosed subcontracting, and an unwillingness to describe a failed decision. Strong providers do not need to pretend every previous engagement was frictionless.
Protect operability, data, and your exit before work starts
The contract should do more than authorize development and payment. It should define how you inspect the work, accept it, operate it, change direction, and leave the relationship without losing control of the system.
Turn handover requirements into delivery requirements
Repositories and access: Specify where source code, configuration, infrastructure definitions, tests, documentation, and deployment assets reside. Your authorized personnel should have appropriate access throughout delivery, not only at the end.
Ownership and licensing: Distinguish custom work, pre-existing provider assets, open-source components, commercial dependencies, and third-party services. Record the licenses and restrictions that apply to each.
Acceptance: Connect acceptance to observable behavior, quality checks, security requirements, data reconciliation, operational documentation, and agreed non-functional needs. A feature being demonstrated is not the same as it being ready to operate.
Change control: Define how changes are raised, analyzed, approved, priced, scheduled, and recorded. Preserve the decision history so a later dispute does not depend on memories of a meeting.
Security and privacy: Assign responsibility for access, secrets, vulnerabilities, audit evidence, incident notification, data retention, deletion, and subcontractor controls.
Continuity: Address key-person changes, replacement standards, knowledge transfer, staffing visibility, and the conditions under which subcontractors can be added.
Operations: Define logging, monitoring, alert ownership, deployment procedures, backup and recovery responsibilities, support boundaries, and escalation paths.
Transition: Require current documentation, environment inventories, dependency registers, known-issue records, runbooks, credentials transfer procedures, and reasonable cooperation with an internal or replacement team.
Ambiguity in these areas can create financial exposure, operational disruption, security gaps, or loss of practical control over the software. Have qualified legal, procurement, security, privacy, and technical reviewers adapt the terms to your organization. This is especially important when sensitive data, cross-border processing, regulated workflows, or material business continuity risks are involved.
Separate AI used during delivery from AI embedded in the product
AI-assisted delivery needs its own due diligence. Ask which coding assistants, models, and external services the provider permits; what code, requirements, logs, or data may be sent to them; whether submitted material is retained or used for training; how access is controlled; and how usage is logged. Require human review, testing, provenance controls, and an incident path appropriate to the sensitivity of the work.
If the product itself contains an AI feature, the risk is different. Document the model or service dependency, data flow, evaluation method, acceptable and unacceptable behavior, human escalation, fallback behavior, monitoring, version-change process, cost boundaries, latency constraints, and what happens when the model or provider is unavailable.
Ask how your organization would replace the model, export relevant data, reproduce an evaluation, and investigate a harmful or incorrect output. A general corporate AI policy does not answer those product-level questions.
Use a pilot to test the hardest boundary, then decide
A useful pilot is a thin vertical slice through real delivery risk. It is not a disconnected interface mockup or a convenient feature chosen because it will look good in a demonstration.
Choose a workflow that crosses the boundaries most likely to cause trouble: identity, representative data, an important integration, business rules, deployment, observability, and operational ownership. Use controlled environments and approved data access. Do not expose production systems or sensitive data merely to make the pilot feel realistic.
The pilot charter should state:
the business and technical hypotheses being tested;
the risks and unknowns the work must reduce;
what is in scope and deliberately out of scope;
the acceptance tests and evidence required;
the security, privacy, and access rules;
the artifacts that must remain with your organization;
the commercial cap and approval mechanism;
the conditions for stopping, extending, or proceeding; and
the handover required even if the provider is not selected for the next phase.
Evaluate the working relationship as closely as the resulting code. Look at the quality of questions, the visibility of decisions, the treatment of uncertainty, the handling of defects, the completeness of tests, the repeatability of deployment, and the usefulness of documentation. Notice whether risks arrive early enough for you to act or appear only when they threaten a deadline.
At the decision gate, do not ask only whether the pilot works. Ask whether your team understands why it works, can see how it is operated, knows what remains uncertain, and could transfer it to another capable team. A successful demonstration with no durable knowledge is weak evidence for an enterprise partnership.
Key takeaways
Choose a provider for the dominant risk in your initiative, not for name recognition or the longest capability list.
Give every candidate the same problem, constraints, unknowns, responsibilities, and response format before comparing proposals.
Test claims through artifacts, scenario workshops, proposed-team interviews, and reference calls tied to comparable work.
Make repository access, ownership, security, operability, documentation, subcontracting, and transition obligations explicit before delivery begins.
Evaluate AI-assisted development separately from AI features embedded in the software.
Run a controlled vertical-slice pilot through the hardest system boundary, with acceptance and exit requirements defined in advance.
Your next move is to write the short risk statement and decision brief before adding another provider to the shortlist. Once every candidate is answering the same problem and producing the same kinds of evidence, the choice becomes less about sales confidence and more about whether you can trust the team with the system after the kickoff meeting is over.
If your SEO strategy ends when somebody clicks a result, you are preparing for an older version of Search. A task-completing system may use your content to compare options, resolve constraints, choose a next step and initiate an action. Your page is no longer competing only to be read. It is competing to be useful inside a larger job.
This does not mean abandoning rankings, traffic or conventional SEO. It means adding a second standard: can Google understand what your business offers, determine when it is appropriate and move a user toward a safe, verifiable outcome?
The search result is becoming part of the workflow
Traditional search usually separates discovery from execution. You search for information, open several pages, make sense of them and complete the task somewhere else. Agentic search compresses those stages. Google’s stated direction is for more information-seeking queries to become agentic, with Search coordinating long-running work and multiple concurrent threads.
Think about a request such as, “Find accounting software suitable for a small Canadian consultancy, compare the plans and help me arrange a demonstration.” An ordinary results page can supply links for each part. A task-oriented system has to preserve the user’s requirements while it researches vendors, rules out unsuitable choices, explains trade-offs and hands the user into an action.
That changes the unit of optimization. A keyword is one expression of demand. A task includes the desired outcome, the constraints, the decisions that must be made, the evidence needed to make them and the action that finishes the job.
Question: What does the user need to know?
Qualification: Which options fit the user’s location, situation, budget, timing or technical requirements?
Decision: What evidence separates an appropriate choice from an inappropriate one?
Action: What can the user book, buy, configure, submit or request?
Verification: How does the user know the action succeeded, and how can it be changed or reversed?
Search and Gemini are also expected to coexist, overlapping in some uses while diverging in others. Do not reduce your plan to optimizing for one chatbot response. Your information may be encountered through a conventional result, an AI-generated answer, a research workflow or an action-oriented experience. The underlying facts should remain consistent across all of them.
Optimize the complete task, not just its opening query
Start with one task that matters to your audience and your business. Avoid broad goals such as “learn about payroll” or “rank for payroll software.” Use an observable outcome: “Determine whether this payroll service supports my type of company and begin the correct signup process.”
Then create a task map. This is more useful than a keyword cluster because it exposes the information gaps that can stop an agent or a person from proceeding.
Write the outcome in the user’s language. State what will be decided or completed, not what content will be consumed.
List the required inputs. Identify the details that change the answer, such as location, organization type, compatibility, eligibility, timing or service area.
Break out the decisions. Record every choice the user must make before acting. A product tier, appointment type or implementation route may each require a separate decision.
Assign evidence to each decision. Decide which page supplies the specification, policy, price, limitation, comparison or proof needed at that point.
Define the action and handoff. Make clear where the user can start, what information will be requested and what happens after submission.
Document failure and recovery paths. Explain what to do when the user is ineligible, an option is unavailable, a form fails or an action must be cancelled.
The recovery path matters because task completion is not the same as pushing every visitor toward conversion. A reliable system must also recognize when your offer does not fit. If exclusions are buried in terms, an agent may recommend the wrong route and the user will discover the problem late. Put decisive limitations beside the claims they qualify.
Next, label the role of every page in the task. One page may establish eligibility, another may compare options, another may explain a procedure and another may host the transaction. A page can serve more than one role, but each role should be explicit. If your team cannot agree on what a page contributes to the task, an automated system is unlikely to infer it reliably.
Build pages an agent can interpret and use
An agent-ready page is not a page written for robots. It is a page on which the decisive facts are clear, scoped and consistent. Good structure helps people and machines for the same reason: neither should have to reconstruct a critical condition from vague marketing language.
Task layer
What must be resolved
What to improve on the site
Intent
The outcome the page supports
Use a descriptive title, a direct opening answer and a clear statement of who the page is for.
Qualification
Whether the offer fits the user’s constraints
State eligibility, locations, dependencies, exclusions and prerequisites beside the relevant offer.
Decision
Why one option should be chosen over another
Use comparable attributes, defined terms and evidence tied to specific claims.
Action
How to begin or complete the next step
Name the action precisely, disclose required inputs and explain what happens after it is submitted.
Verification
Whether the action succeeded
Provide an explicit confirmation state, reference information and a route for correction or cancellation.
Machine interpretation
Which entities and relationships the content describes
Use accurate structured data that matches the visible page and the site’s canonical facts.
Several practical rules follow from this model.
Put the decisive answer before the supporting narrative
If a service is available only in particular locations, say that near the service description. If a plan requires another product, state the dependency beside the plan. If the next step is a consultation rather than an immediate purchase, label it accurately. Do not make the reader decode “Get started” to discover what will actually happen.
Turn implied knowledge into explicit facts
Businesses often assume that visitors understand their terminology, market, service boundary or product hierarchy. An agent cannot safely rely on that assumption. Define ambiguous terms, attach units to measurements, give conditions to claims and distinguish facts about the company from facts about a particular offer.
Consistency is more important than repetition. If a product name, service area, policy or plan description differs across a landing page, help page and checkout flow, decide which version is canonical and correct the others. Structured data should reflect that same version.
Use JSON-LD as a factual layer, not a persuasion layer
Choose Schema.org types and properties that match what is visibly present. Identify the organization, offer, product, service, person, place or event only when the page genuinely describes that entity. Connect related entities where the relationship is real. Keep names, URLs, identifiers and offer details aligned with the canonical content.
Do not add unsupported properties because they look advantageous, and do not mark up claims that a visitor cannot verify on the page. JSON-LD can make a fact easier to interpret; it cannot turn an incomplete, stale or contradictory claim into a trustworthy one.
Design the action boundary deliberately
Research and execution carry different risks. Reading a comparison is low commitment. Sending personal information, placing an order or booking an appointment is not. If your task ends in an action, make the commitment point unmistakable.
Show what will be submitted or purchased before confirmation.
Separate required inputs from optional ones.
Display material conditions before the final action, not only after it.
Explain whether the action is immediate, pending review or merely a request.
Provide a correction, cancellation or support route where the action permits one.
Return a clear success or failure state instead of leaving the user to infer the result.
These are conversion fundamentals, but they become more important when software may coordinate the handoff. Ambiguous buttons, silent form failures and hidden conditions do not merely reduce conversion. They make the task unsafe to delegate.
Audit task readiness before agent traffic becomes measurable
You may not be able to isolate every agent-assisted visit or decision in your reporting. You can still measure whether your site is ready to participate. Treat readiness as a content, data and workflow quality problem.
Use a simple zero-to-two audit for each important task. This is a prioritization method, not a search-engine score:
0 — Missing or contradictory: the task cannot proceed without guessing, or two public pages give incompatible answers.
1 — Inferable: the answer exists, but the user must combine pages, interpret vague wording or uncover a condition late.
2 — Explicit and usable: the answer is clear, appropriately qualified, current and connected to the correct next step.
Score the task across six dimensions: outcome definition, qualification facts, decision evidence, action path, confirmation or recovery, and measurement. Do not obsess over the total. A zero in any dimension identifies a broken link in the workflow and deserves attention before cosmetic content changes.
Run the audit from the public site, without internal knowledge. Give a team member the task and its constraints. Ask them to find the right option, explain why it fits, begin the action and identify how they would reverse or correct it. Record every point where they have to guess. Those guesses become your content and workflow backlog.
Measure the workflow in stages so a completed task is not reduced to a pageview:
Discovery: Did the relevant landing page become visible for the task?
Qualification: Did the visitor reach the eligibility, specification, policy or comparison information needed to proceed?
Action: Did the visitor start and complete the intended form, booking, configuration or transaction?
Failure: Where did validation errors, unavailable options or unclear requirements stop progress?
Outcome quality: Did the action lead to confirmation, or did it create cancellations, corrections and avoidable support work?
This measurement model also protects you from a misleading success signal. More action starts are not helpful if users are being routed into an unsuitable option. Pair completion data with failure, cancellation and correction data so you can distinguish task volume from task quality.
Key takeaways
Optimize for a defined user outcome, not only the keyword that begins the journey.
Map qualification, decision, action and verification as separate stages, then assign each stage to reliable public information.
State decisive constraints beside the claims they limit. Do not hide eligibility, dependencies or exclusions at the end of the path.
Keep visible content, structured data and transactional interfaces consistent about the same entities and offers.
Treat confirmation, correction and cancellation as part of task completion, not as support details.
Audit every task for missing or contradictory information before trying to infer performance from agent-specific traffic.
Choose one commercially important task this week. Write its outcome, inputs, decisions, evidence, action and recovery path on a single page. Then follow it through your public site and fix the first place where a user has to guess. That work will improve the experience now, while giving agentic Search cleaner material to use as it moves from answering questions toward completing jobs.
You have probably seen the headline number: a retailer used Google AI advertising and revenue rose by 80%. The useful question is not whether AI ads can work. It is whether they can produce profitable, incremental sales for your business without weakening measurement or surrendering control of your brand.
You can answer that question, but not by switching on every automated feature and comparing this month’s revenue with last month’s. Treat AI Max, Performance Max, reusable text rules, and recommendation reporting as separate tools inside a controlled commercial test. That gives you a result you can defend when someone asks what actually caused the lift.
An 80% lift is a case result, not your forecast
Google has highlighted Aritzia as having achieved an 80% increase in revenue with AI Max. That is evidence of possibility, not a transferable benchmark. It does not tell you what Aritzia would have earned without AI Max, how much media spend changed, which customers were new, or what happened to margin.
Revenue lift can come from several places. An advertiser may reach previously missed queries, improve the match between a shopper and a product, spend more, capture demand that another campaign would have converted, or count conversions differently. Only the first two clearly demonstrate better advertising. Additional spend can still be worthwhile, but it is a different claim and should be judged against your allowable acquisition cost.
Write your expected mechanism before starting. A useful hypothesis is specific: AI Max will find additional non-brand demand for selected products and increase contribution profit without pushing customer acquisition cost above our limit. A weak hypothesis is that AI will increase sales. The stronger version identifies the demand, the product scope, the business outcome, and the constraint.
Set a budget boundary and stop conditions at the same time. Automation can spend into newly discovered demand quickly. Without a pre-agreed limit, higher expenditure can resemble growth even when each additional order is less valuable. Your own margins, return rates, sales cycle, and cash constraints should determine that limit; a vendor case result should not.
AI changes matching, but your inputs set its ceiling
Traditional search advertising starts with keywords chosen by the advertiser. Google’s newer systems place more weight on inferred intent. They assess the retailer’s website and creative assets, interpret a search, and dynamically match products and messages to that context. Performance Max and AI Max are designed to operate within this more intent-driven model.
The opportunity is clearest in conversational search. Google says queries in AI Mode tend to be two to three times longer, giving the matching system more context. Google also says 15% of daily searches are novel. A rigid keyword list cannot anticipate every new formulation, while an intent model can potentially connect unfamiliar wording with an appropriate offer.
That does not remove the need for optimization. It moves optimization upstream. The system cannot reliably distinguish two similar products if your pages use vague names, bury the differences, or contradict the creative. It cannot protect a nuanced brand position that has never been translated into operational rules.
Clarify the product: Make the product type, variant, intended buyer, availability, price, and material differences easy to identify on the landing page and in the product data you provide.
Align the promise: Check that advertising claims, promotions, shipping terms, and calls to action agree with the destination page. Automation can scale a mismatch as easily as it scales a good message.
Supply useful creative range: Give the system assets that express different legitimate benefits, use cases, and objections. Cosmetic variations of the same vague claim do not create meaningful choice.
Define the sale correctly: Confirm that the primary conversion represents a commercially useful outcome. If low-value actions sit beside completed purchases without a clear hierarchy, more reported conversions may not mean more revenue.
Separate brand rules from campaign ideas: Tone, prohibited language, required qualifications, product naming, and legal restrictions should remain stable. Offers and audience-specific messages can change by campaign.
Google Ads is testing a beta capability that lets advertisers clone approved AI text guidelines from an existing campaign. If it is available in your account, use it to turn recurring brand decisions into reusable instructions. A practical rule set should cover voice, required product terminology, claims the system must not make, promotion wording, and acceptable calls to action.
Cloning saves setup time; it does not eliminate review. Read the copied rules in the context of the destination campaign. A restriction written for one market, product category, or promotion can be incomplete or actively wrong elsewhere. Assign an owner and version the rules internally so your team knows which guidance was approved and why.
Build a test that can explain where sales came from
The main measurement mistake is changing automation, budget, creative, offers, landing pages, and conversion tracking at once. A good result then produces enthusiasm but little knowledge. A bad result creates the same problem because you cannot identify which change failed.
Choose one commercial hypothesis. Name the customer demand you expect AI matching to capture, the products included, the primary business metric, and the maximum cost you will tolerate.
Set a clear boundary. Limit the first test to a defined campaign, product group, market, or customer cohort. Avoid exposing the entire account before you know how the system behaves with your inputs.
Preserve a comparison. Keep a control when account structure and volume permit it. Otherwise, save the pre-change campaign data and identify a comparable product or market that will not receive the change.
Reduce simultaneous changes. Hold pricing, promotions, landing pages, inventory policy, and conversion definitions steady where practical. Record anything that cannot be held steady, including stockouts and major merchandising events.
Allow for conversion lag. Do not declare a winner while one group has had more time to accumulate purchases, cancellations, or returns. Read both groups over equivalent conversion windows.
Review three layers of evidence. Check delivery, customer response, and business value separately. More reach may explain more orders, but only revenue quality and cost reveal whether the expansion was worthwhile.
At the delivery layer, inspect spend, impressions, click volume, and the kinds of demand being reached. At the response layer, inspect purchases, conversion rate, and average order value. At the business layer, inspect net revenue, contribution margin, new-customer share where you can measure it, cancellations, and returns. A campaign can look strong in the advertising interface while failing the business layer.
Split branded and non-branded demand in the analysis wherever your reporting allows. AI can appear efficient when it captures customers already searching for your company or products. That traffic may still deserve coverage, but it should not be presented as newly created demand. The same principle applies to returning customers: retained revenue and acquired revenue answer different questions.
Google Ads has also added a Results tab intended to show the impact of recommendations. Use it to investigate what changed after a recommendation was applied, not as automatic proof that the recommendation caused incremental profit. Platform reporting can identify a useful correlation and shorten diagnosis, but it does not control for promotions, seasonality, inventory, competitor behavior, or sales that another campaign might have captured.
Key takeaways
An 80% revenue increase from one retailer establishes potential, not an expected return for your account.
AI Max and Performance Max can interpret demand beyond a fixed keyword list, which matters as searches become longer and more conversational.
Clear product information, aligned landing pages, useful creative, and correctly defined conversions are inputs to the system, not cleanup tasks for later.
Reusable AI text rules can speed campaign setup, but every cloned rule set still needs market- and product-specific review.
Measure incremental business value rather than reported conversions alone. Separate brand demand, returning customers, media spend, returns, and margin.
Use recommendation results as diagnostic evidence. Validate causation with a control or the strongest comparable baseline available.
Scale only after the result survives business checks
A successful test should answer more than whether sales rose. You should know which products gained, what type of demand expanded, how much spend changed, whether acquisition remained within your limit, and whether the revenue retained its value after discounts, cancellations, and returns.
Before expanding the campaign, require the result to pass five checks:
Incrementality: The gain remains credible after separating branded demand and other traffic the campaign may have absorbed.
Economics: Acquisition cost and contribution margin stay within the limits set before the test.
Quality: Search intent, generated messaging, landing pages, and purchased products align with the hypothesis.
Durability: The outcome is not explained by a short promotion, inventory event, reporting delay, or one unusually strong segment.
Control: Brand and compliance reviews find no unacceptable claims, tone, targeting pattern, or customer experience.
Scale in stages if those checks pass. Expand one boundary at a time, such as the eligible product set or budget, and keep the same business metrics visible. If revenue rises but margin, new-customer acquisition, or message quality deteriorates, pause the expansion and correct the input or objective before spending more.
Google is also experimenting with personalized direct offers and supporting a broader move toward purchases inside AI interactions through the Universal Commerce Protocol developed with Shopify. Those developments point toward a shorter path from conversational discovery to checkout, but experiments and infrastructure plans are not guaranteed sales. Your immediate advantage comes from making your business legible to intent-matching systems and building measurement that can distinguish a real commercial gain from a persuasive dashboard.
Start with one bounded campaign. Write the hypothesis, unit-economics limit, brand rules, comparison method, and stop conditions before enabling the change. That single page of decisions will do more for your eventual sales result than adopting every AI feature at once.