Author: shivamcrushpressai

  • Paid Search in the AI Era: A Practical Operating Model

    Paid Search in the AI Era: A Practical Operating Model

    If your paid search account is hitting its platform targets but you cannot explain which customers are real, why automation moved spend, or whether the resulting leads create value, your problem is no longer bidding. It is control.

    AI has not removed human demand. It has inserted more software between a person’s intent and your business outcome. Marketing now operates among systems assessing intent, identity, risk, relevance, and value at the same time. To stay effective, you need an operating model that gives automation a clear objective, trustworthy signals, and firm boundaries.

    Key takeaways

    • Optimize around the customer’s goal and the business outcome, not the keyword or platform conversion in isolation.
    • Audit identity, deduplication, qualification, and revenue signals before giving automation more freedom.
    • Give every automated campaign an operating envelope: a budget boundary, an approved objective, monitoring rules, an owner, and a rollback condition.
    • Use longer, context-rich prompts to understand intent, but do not treat entire prompts as a new keyword list.
    • Let PPC, SEO, GEO, content, analytics, and CRM teams work from one shared record of customer problems, constraints, evidence needs, and outcomes.

    Rebuild paid search around the customer goal

    The durable advantage of paid search was never the keyword itself. It was the ability to reach expressed demand, test a message, and connect acquisition to measurable post-click activity. That combination made paid search accessible, testable, and accountable in a way that traditional advertising often was not.

    The keyword was simply the interface available at the time. It gave you a compressed clue about what someone wanted. A prompt or conversation can reveal much more: the underlying problem, the constraints, the desired output, the urgency, and the standard by which an answer will be judged. As discovery moves toward prompts, conversations, and AI assistants, that fuller context becomes more useful than an isolated phrase.

    This does not mean copying complete prompts into a campaign and calling them keywords. It means designing your acquisition strategy around the job the person is trying to complete.

    Create an intent brief before a campaign brief

    For each meaningful demand theme, write a short intent brief with these fields:

    • Customer goal: the outcome the person is trying to achieve.
    • Trigger: the situation that made the goal important now.
    • Constraints: budget, timing, compatibility, risk, internal approval, or another limiting condition.
    • Evidence required: the proof the person needs before moving forward.
    • Disqualifiers: conditions under which your offer is not suitable.
    • Next useful action: the smallest meaningful step the person can take with your business.

    Consider a hypothetical search for “best CRM.” The phrase is too broad to support a precise message. The actual job might be to replace a spreadsheet before a sales team expands, preserve existing contact history, and avoid a developer-led migration. A useful campaign speaks to that job and those constraints. A weak campaign repeats “best CRM” in the ad and sends every visitor to a generic product page.

    Turn the intent brief into campaign decisions in a fixed sequence:

    1. Choose the customer goal you are willing and able to serve.
    2. Group queries by that goal, not merely by shared words.
    3. Write the message around the desired outcome and the most important constraint.
    4. Make the landing page state who the offer is for, what it helps them do, and what evidence supports the claim.
    5. Include disqualifying information early enough to prevent low-fit clicks from becoming misleading conversions.
    6. Measure the next action that represents genuine progress toward business value.

    The same brief can guide paid ads, organic pages, answer-oriented content, and AI-search optimization. Each channel may need different formatting, but the underlying customer problem should not change when the channel changes.

    Fix signal integrity before expanding automation
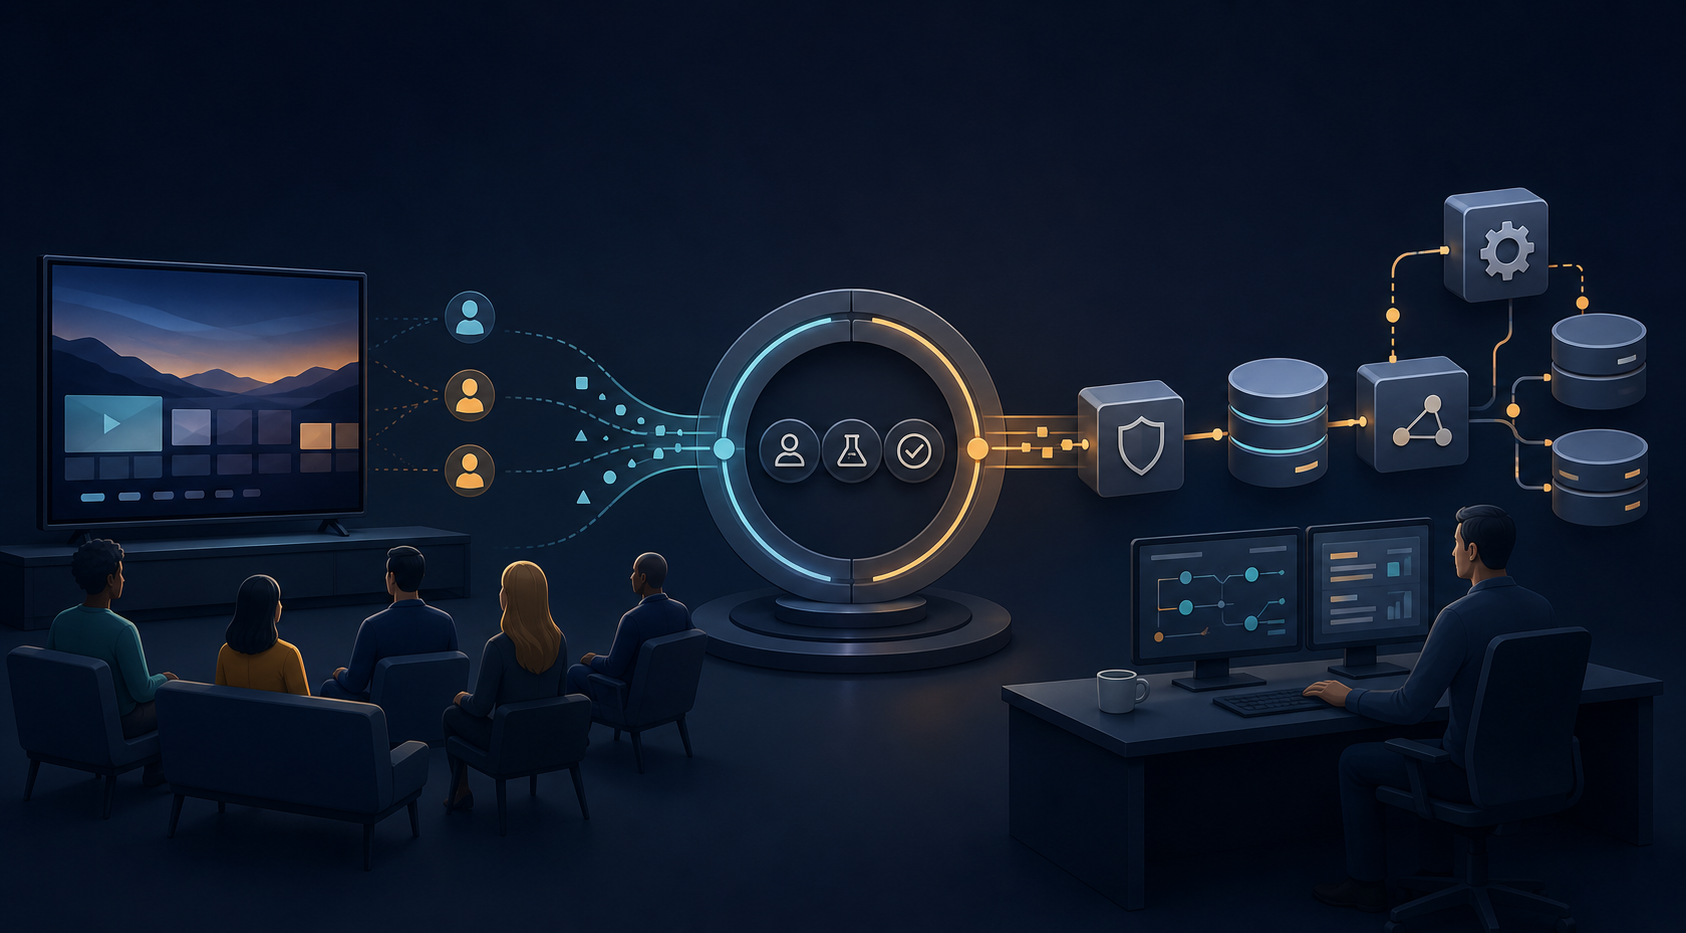
    An analyst inspects a transparent pipeline that filters noisy and duplicate inputs into a clean stream of customer signals.

    A customer journey is no longer a neat line from impression to click to conversion. Multiple systems can evaluate the same person simultaneously. An ad platform may predict high purchase intent while a fraud model lowers trust, an identity service fails to join the session to a known account, a CRM labels the record as a duplicate, or a messaging system suppresses further contact. These decisions can all be internally reasonable and still produce a broken journey.

    More automation makes those contradictions move faster. It does not resolve them. When identity or conversion data is ambiguous, autonomous systems operationalize the ambiguity: they bid on it, suppress it, personalize around it, or feed it into the next model.

    Write a conversion contract

    A conversion contract is a shared definition of what each tracked event means. For every event used in reporting or optimization, record:

    • the exact user action that creates the event;
    • the system that first records it;
    • the identifier used to connect it to a person, account, order, or lead;
    • the rule used to prevent duplicate counting;
    • the timestamp and value passed downstream;
    • the conditions that make the event eligible for bidding;
    • the later business event that verifies its quality; and
    • the team responsible for investigating a mismatch.

    Do not allow labels such as “lead,” “qualified lead,” and “customer” to carry different meanings in the ad platform, analytics system, CRM, and finance records. If the definitions must differ, document the differences and prevent teams from comparing them as if they were identical.

    Then run a controlled quality-assurance journey through the whole path: ad click, landing-page action, analytics event, CRM record, qualification state, and final business outcome. Record where an identifier is created, transformed, lost, or replaced. If privacy or consent boundaries prevent a complete join, preserve that limitation in reporting. A documented blind spot is safer than invented precision.

    Build a ladder from activity to verified value

    Keep raw activity separate from increasingly reliable business outcomes:

    1. Delivery: an impression or other opportunity to be seen.
    2. Engagement: a click, visit, or interaction.
    3. Declared conversion: a submitted form, registration, call, or purchase event.
    4. Accepted outcome: a deduplicated event that passes your validity rules.
    5. Qualified outcome: a lead, order, or account that meets your business criteria.
    6. Verified value: the downstream result your organization actually wants.

    Only some of these levels should steer bidding. The rest can remain diagnostic. If a form submission is easy to generate but only qualified opportunities create value, optimizing solely for submissions teaches the system to find more submissions. It does not necessarily teach it to find more qualified opportunities.

    This distinction becomes critical when bot activity, fraud, or other synthetic behavior can imitate engagement. Automated systems tend to optimize what is measurable rather than determine what is true. Your measurement design must therefore separate a recorded action from a verified human or business outcome.

    Watch the movement between levels. If declared conversions rise while accepted and qualified outcomes remain flat, investigate event quality, duplication, traffic mix, and identity resolution before changing bids or creative. If the platform reports improvement but the verified-value layer moves in the opposite direction, the optimization target is not representing the business goal.

    Give automation an operating envelope
    A strategist supervises fast-moving automated agents traveling within a transparent corridor bounded by gates and safety rails.

    Effective automated bidding changes the human job. When a system can make auction-level decisions more quickly than a person, repeatedly adjusting individual bids is not a durable source of value. The higher-value work becomes monitoring automation, setting limits, and diagnosing failures.

    An operating envelope defines where an automated system may act without intervention and what forces a review. It should contain:

    • An outcome boundary: the one primary result the campaign is permitted to optimize toward.
    • A spend boundary: the budget and financial exposure the system may control.
    • A data boundary: the events, values, audiences, and exclusions considered reliable enough to use.
    • A message boundary: the claims, offers, and brand language that may appear.
    • A change record: the date, owner, reason, and expected effect of every material configuration or measurement change.
    • An intervention rule: the condition that triggers investigation, limits delivery, or rolls back a change.

    There is no universal threshold that fits every account. Set boundaries from your own economics, sales capacity, data quality, and risk tolerance. The important part is that the limits exist before the anomaly, not that they copy another advertiser’s settings.

    Use failure patterns to decide where to look

    Observed patternLikely control problemFirst check
    Spend rises while verified value stays flatThe system is finding a cheaper proxy rather than more business valueCompare platform conversions with accepted and qualified outcomes
    One system marks a person high value while another suppresses the same personIdentity, consent, fraud, duplication, or eligibility rules conflictTrace the identifier and suppression reason across systems
    Reported performance changes immediately after a tracking editThe measurement definition changedInspect the change record before treating the movement as customer behavior
    The platform reaches its target while sales quality deterioratesThe steering metric is too far from the business outcomeReview which event and value are eligible for optimization
    Teams report different totals for the same conversionDefinitions, timestamps, deduplication, or attribution rules differReconcile each system against the conversion contract

    Separate steering metrics from observation metrics

    A campaign should not have several competing definitions of success. Choose one primary steering outcome. Keep supporting metrics visible for diagnosis, but do not let every measurable action vote equally on where money goes.

    For example, clicks can explain delivery, form starts can expose landing-page friction, and submitted forms can show response volume. None of them has to be the bidding objective if qualified opportunities are the meaningful outcome. The platform dashboard is an operational view, not your business ledger. Reconcile it with downstream outcomes instead of asking it to serve both purposes.

    Change one important layer at a time when practical. If you replace the conversion definition, expand targeting, change the offer, and alter the landing page together, you may get a different result without learning which change caused it. When a bundled change is unavoidable, document every component and treat the result as a system change, not a clean test of one idea.

    Prepare for prompt-based journeys without guessing the ad format

    AI-assisted discovery is moving beyond retrieving information toward helping people produce an answer, solve a problem, or complete a task. That raises unresolved questions about how advertising, auctions, attribution, and agent-mediated actions will work. You do not need those questions settled before improving the durable parts of your strategy.

    The durable work is to understand the goal, capture its context, explain your value clearly, provide credible evidence, and measure whether the person reached a useful outcome. Those capabilities transfer across keyword search, conversational discovery, recommendations, and future agent interfaces.

    Maintain a shared intent ledger

    An intent ledger turns customer language into an operating asset shared by PPC, SEO, GEO, content, analytics, sales, and CRM teams. Give each intent theme a record containing:

    • the wording customers use;
    • the underlying goal behind that wording;
    • the trigger and constraints that shape the decision;
    • the questions and objections that must be resolved;
    • the evidence needed to establish relevance and trust;
    • the ad, page, or answer that serves the intent;
    • the next meaningful action; and
    • the verified business outcome associated with that action.

    Populate the ledger from the customer language you can legitimately observe: query data, site search, landing-page behavior, sales questions, support requests, and customer-supplied wording. Search-query visibility has historically moved between greater transparency and greater restriction, with privacy changes obscuring some of the detail advertisers once received. Treat visible query data as a partial observation of demand, not a complete census.

    Do not create separate, conflicting intent taxonomies for every channel. A person does not acquire a different underlying problem because one interaction happens in paid search and another happens in an AI assistant. Channel-specific teams can add the details they need while preserving the same customer goal, constraints, and outcome definition.

    Move one campaign through the new operating model

    1. Select one campaign with meaningful spend and a downstream outcome you can inspect.
    2. Write its intent brief and name one primary customer goal.
    3. Build a conversion contract for every event currently used in optimization or reporting.
    4. Trace controlled journeys through the ad platform, analytics, CRM, qualification, and final business record.
    5. Document contradictions between identity, fraud, suppression, audience, and value decisions.
    6. Set the campaign’s operating envelope, including ownership and intervention rules.
    7. Revise the message and landing page around the customer’s goal, constraints, proof needs, and next useful action.
    8. Compare platform-reported improvement with accepted, qualified, and verified outcomes before expanding the model to more campaigns.

    Start with the campaign whose reported success you trust least. Making its signals coherent and its automation legible will give you a reusable pattern for the rest of the account. That is the practical advantage in the AI era: not trying to control every machine decision, but building a system in which those decisions remain bounded, observable, and tied to real customer value.
    References

  • How Ignoring Data Can Derail Your PPC Success

    How Ignoring Data Can Derail Your PPC Success

    Recently, I found myself captivated by a story shared by Dean Kadi, Head of Paid Growth at One Link Media. He recounted a fascinating experience from a PPC Live podcast that really highlighted what can go wrong when you ignore performance data. It involved a client who overrode a winning ad strategy with new creatives that just didn’t deliver.

    Dean Kadi’s team had developed an exceptionally successful Meta advertising strategy for a premium woodworking brand, Rubio Monocoat, using user-generated content (UGC). Their intensive testing across creators and formats resulted in a significant ROAS improvement, proving the power of well-tested strategies.

    However, the client decided to halt all the high-performing ads in favor of new, heavily branded content. Despite the polished look, these ads didn’t blend well with the Meta platform, and it was clear that engagement and conversion would likely suffer.

    The client’s assumption was rooted in a customer survey that praised the brand’s color range, leading them to mistakenly prioritize this over proven data. This is a classic marketing pitfall where assumptions can cloud judgment and overshadow hard-earned data insights.

    The most eye-opening moment came when the client expressed a simple wish for their new strategy to be a winner. Dean explained that in paid media, success isn’t driven by preferences or hopes—it’s determined by what resonates with audiences, as clearly shown by performance data.

    When facing such situations, Dean advises agencies like us to stay calm, present evidence, and communicate risks effectively. Professionalism and clear documentation can help maintain client relationships while asserting the agency’s expertise.

    As expected, the new strategy did not perform well. Underperformance became evident with increasing costs and decreasing campaign efficiency. After eight weeks of this, the client recognized the necessity to revert to the original strategy.

    Reintroducing UGC ads quickly turned the tide, proving the original strategy’s effectiveness. Performance metrics showed immediate improvements, reinforcing the importance of data-driven decisions.

    The overarching lesson here is that data should be your guiding light in PPC campaigns. Clients sometimes need to see failures themselves before they trust data insights. Consistently providing clear, transparent reports helps rebuild trust and guide future strategies.

    Dean also pointed out that many PPC accounts still suffer from poor tracking setups. This issue is a major roadblock to optimizing performance and should be addressed urgently.

    Additionally, while AI tools can enhance efficiency, they cannot replace the need for a strong strategy. Human judgment remains crucial for evaluating AI outputs and guiding successful campaigns.

    In conclusion, successful PPC is all about balancing data, strategy, and communication. Document recommendations thoroughly, trust your expertise, and let audience data guide your actions. Remember, it’s the audiences who ultimately decide what works.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Build Google Commerce Infrastructure From Visibility to Revenue

    Build Google Commerce Infrastructure From Visibility to Revenue

    You can have thousands of products appearing on Google and still have two expensive blind spots. Shoppers may never see listings hidden behind a carousel scroll, while purchases or qualified leads completed elsewhere may never return to Google Ads.

    If you own ecommerce growth, you need two connected but distinct systems: one that measures whether products earn usable visibility, and one that returns offline outcomes to the advertising platform. Here is how to build both without confusing presence with exposure, activity with revenue, or shared reporting with attribution.

    Count the product placements shoppers can actually see

    Shopper viewing a product carousel where several items are visible and many more remain hidden beyond the screen edge.

    A product-pack appearance is not automatically an impression worth celebrating. Google can place products in horizontally scrollable carousels, so the first visible positions receive a very different opportunity from listings that require interaction before they appear.

    The scale makes this distinction material. A monitoring dataset covering more than 63,000 merchants from January 2025 through January 2026 found searches with as many as 60 individual organic product listings on one results page. A report that counts every one of those listings equally will overstate the practical reach of products buried deep in a carousel.

    Keyword coverage can be just as misleading. eBay appeared in product results for 874,621 keywords and generated about 3.2 million estimated visits, while Home Depot appeared for a slightly smaller 831,699 keywords but generated nearly 28.8 million estimated visits. The difference was associated with Home Depot securing more prominent, immediately visible positions. More appearances did not mean more useful exposure.

    Build your product-pack scorecard in layers. Keep each layer separate so an impressive top-line number cannot hide weak placement:

    • Eligible catalog: Products you expect Google to understand and consider for the category.
    • Total appearances: Every detected placement, including positions that require scrolling.
    • Visible appearances: Placements shown before a shopper scrolls the carousel.
    • Visible rate: Visible appearances divided by total appearances. Preserve the counts beside the percentage so a small sample does not look more important than it is.
    • Query quality: Segment high-demand category searches from low-volume long-tail queries. Raw keyword coverage otherwise rewards breadth whether or not that breadth produces meaningful traffic.
    • Observed visits and outcomes: Use analytics for measured sessions, transactions, leads, and revenue. Label third-party traffic estimates as estimates rather than blending them with observed data.

    Review the scorecard by category, not only by domain. A healthy total can conceal one category that wins visible positions and another that appears frequently but remains out of sight. That second category is where feed and merchandising work may create the largest gain.

    Fix commerce inputs before reaching for a blanket discount

    Discounting is easy to change and easy to report, which makes it an attractive explanation for product-pack performance. It is not a reliable standalone lever.

    Among large merchants in the monitored data, Amazon discounted 49% of its catalog and achieved a 72% visibility rate. eBay discounted only 8% and reached 81%. Walmart Seller reached the same 81% visibility rate with 24% of products discounted, while Walmart discounted 27% and recorded a lower 62% visibility rate. That irregular pattern does not establish a universal ranking formula, but it does show why discount depth should not be treated as the primary explanation for placement.

    Start with the inputs Google and shoppers need to evaluate the product: complete product data, clear category relevance, strong images, current pricing and availability, and credible reviews. Promotions can still support a commercial offer, but they cannot compensate for an unclear product identity or poor category fit.

    Turn low visibility into a product-level work queue

    1. Choose one commercially important category rather than auditing the whole catalog at once.
    2. Export products that appear for relevant queries but have a low visible rate.
    3. Compare those products with visible winners in the same category. Check data completeness, category alignment, image quality, review strength, price, and availability.
    4. Group repeated defects. Ten products with the same missing or weak input should become one system fix, not ten unrelated tickets.
    5. Correct one defect class, record the date, and remeasure the same category. Product-pack placement fluctuates, so a before-and-after comparison needs consistent queries and a sufficiently stable observation window.
    6. Escalate products that remain hidden despite clean inputs. They may face a relevance, competitiveness, or demand problem rather than a feed defect.

    This process will not prove that one field caused a ranking change. It will give you a disciplined way to improve controllable inputs without assuming that every movement came from price.

    Specialist retailers should be especially careful not to confuse smaller scale with weaker potential. Camp Chef appeared for 155,299 keywords yet generated about 2.6 million estimated visits through advantageous placements. Its footprint was much smaller than the largest marketplaces, but category focus and placement quality produced substantial estimated traffic. Depth in a category can be more commercially useful than millions of marginal appearances.

    Protect offline conversion measurement as the API route changes

    Offline checkout and sales outcomes flowing through a secure gateway into a newer cloud-based measurement connection.

    Product-pack optimization addresses organic commerce visibility. Offline conversion imports address Google Ads measurement and bidding. They belong in the same commerce operating model, but they are not the same channel and should never be presented as if one directly measures the other.

    Google is moving offline conversion imports, including enhanced conversions for leads, from the Google Ads API toward the Data Manager API. Under the communicated change, UploadClickConversions becomes nonfunctional after June 15 for affected accounts that have not used the feature during the preceding 180 days. The change applies to offline conversion imports for some developers, while other Google Ads API operations continue.

    Do not infer that your integration is safe merely because it still runs or because another Google Ads API operation succeeds. An application can keep managing campaigns while its offline conversion path quietly becomes obsolete. Missing imports can weaken reporting, attribution, and the conversion signals used by automated bidding.

    Use this migration checklist

    1. Find every dependency. Search application code, scheduled jobs, middleware, vendor integrations, and internal runbooks for UploadClickConversions. Include enhanced conversions for leads and any sales or lead events completed outside the immediate ad interaction.
    2. Map the affected accounts. Record which accounts use each workflow, when each last imported conversions, who owns the source system, and how frequently the job runs. The 180-day activity condition makes account-level evidence more useful than a platform-wide assumption.
    3. Define the event contract. Document what qualifies as a conversion, where it originates, how it is identified, which value is sent, and which system is authoritative. Migration is a poor time to preserve an event definition nobody can explain.
    4. Build the Data Manager API route. Keep unrelated Google Ads API operations in place unless they have a separate reason to move. The scope here is the conversion-ingestion workflow.
    5. Test a controlled slice. Confirm that source events are accepted, rejected events are visible to operators, and imported counts and values reconcile with the originating system.
    6. Prevent double counting. A temporary overlap can help validate a migration, but sending the same business event through two active routes without a deduplication plan can corrupt reporting. Document exactly when the old writer stops and the new writer becomes authoritative.
    7. Add failure monitoring. Alert on missing runs, unexpected volume changes, rejected events, and reconciliation gaps. A job that reports technical success but delivers no usable conversions is not healthy.

    Because the communicated cutoff applies selectively, treat the date as a prompt to verify your current environment rather than assuming every account failed at once. The decisive evidence is your dependency inventory, recent account activity, accepted-event reporting, and reconciliation with the source system.

    Join the systems without inventing cross-channel attribution

    A shared commerce data spine makes the two workstreams easier to operate. It does not make Google Ads conversion imports a measurement system for organic product packs. Preserve channel and attribution boundaries while standardizing the business entities used in both.

    At minimum, use consistent product and category identifiers across the commerce feed, landing pages, analytics, CRM or order system, and internal reporting. If you publish product structured data, align its product identity, price, and availability with the same source of truth. The immediate benefit is diagnostic: your team can trace a category from search visibility through site behavior and recorded outcomes without manually translating competing names.

    Product-pack visibilityOffline conversion pipelineWhat you can concludeNext action
    Strong and visibly placedHealthy and reconciledBoth discovery and advertising measurement are operational, but their results still require separate attribution.Compare category economics and prioritize the products with the strongest observed business outcomes.
    Strong and visibly placedBroken or uncertainOrganic discovery may be healthy, but Google Ads reporting and bidding signals are unreliable.Restore and reconcile the conversion pipeline before making bid or campaign conclusions.
    Weak or mostly hiddenHealthy and reconciledAdvertising measurement is usable; the organic product-pack problem sits upstream.Work the category-level product data, relevance, image, review, price, and availability queue.
    Weak or mostly hiddenBroken or uncertainYou have two separate failures, not one vague Google problem.Assign independent owners. Protect conversion ingestion because bidding can be affected, while product visibility remediation proceeds in parallel.

    Give each layer an operating cadence

    • Daily: Check whether offline conversion jobs ran, whether expected events arrived, and whether rejection or reconciliation thresholds were breached.
    • Weekly: Review visible versus non-visible product-pack appearances by category. Create a prioritized issue queue for products with meaningful query exposure but poor placement.
    • Monthly: Compare category-level visibility, measured site outcomes, advertising results, catalog changes, promotions, and resolved data defects. Keep estimated traffic in a separate column from observed sessions and revenue.
    • After a sudden change: Check availability, price, images, reviews, feed completeness, and category mix before concluding that discounting or a single platform update caused the movement.

    Expect movement. Nearly every merchant in the year-long monitoring dataset experienced product-pack visibility shifts, with some gaining during one period and receding later. Google can change how it weighs feed quality, availability, reviews, pricing, and images, so a previously strong visible rate is not a permanent asset.

    Key takeaways

    • Report visible product-pack appearances separately from placements hidden behind a carousel scroll.
    • Segment performance by category and query value; raw keyword coverage can conceal poor positioning and weak traffic.
    • Treat discounts as one commercial input, not a substitute for complete product data, category relevance, good images, reviews, current price, and availability.
    • Audit UploadClickConversions dependencies now and move affected offline conversion workflows to the Data Manager API with reconciliation and failure alerts.
    • Keep organic visibility and Google Ads attribution distinct, even when they share product identifiers and business reporting.

    Start with one important category and one conversion workflow. Establish the visible-placement baseline, clear the highest-frequency product-data defect, and verify that the corresponding offline conversion job reaches its destination. That gives you a working control loop you can extend across the catalog without scaling hidden measurement errors along with it.

    References

  • Master Your Brand with a Strategic Martech Stack

    Master Your Brand with a Strategic Martech Stack

    Struggling with maintaining brand consistency? I’ve learned that it’s not about having more tools, but rather having the right tools, perfectly aligned with your brand’s goals.

    I’ve seen marketing teams overwhelmed with tools. The average B2B company might use up to 20 different martech solutions. Despite this, keeping brand consistency at scale can be tough. Fewer than 10% of brands manage to maintain strong cohesiveness across all products and channels. The core issue? Tools rarely work in harmony to support a unified brand experience.

    Managing a brand across various channels, whether through campaigns or social media, can lead to brand elements drifting. It’s those small inconsistencies—a slightly off-color logo here, outdated messaging there—that can gradually erode the hard-earned brand equity.

    The solution isn’t about increasing the number of tools. It’s about selecting the right ones and arranging them with deliberate intention.

    Start with strategy, then stack

    Before diving into an audit of your current software or seeking out new options, it’s crucial to develop a framework for what brand equity means to your organization. David Aaker’s brand equity model—which focuses on loyalty, awareness, perceived quality, and brand associations—is a sound approach. It transforms brand management into a sustainable growth strategy. In terms of a martech stack, this means utilizing tools that both build and protect your brand.

    On the strategy side, platforms like Notion, Miro, and Lucidchart are invaluable. They help document positioning, define messaging, and map out customer journeys. These may not be glamorous, but they provide the solid foundation for successful execution. Without such a framework, design and content teams are left guessing.

    The core of the stack: Digital asset management

    If there’s one tool that differentiates a cohesive brand management stack from fragmented apps, it’s digital asset management (DAM). Unlike typical cloud storage services such as Google Drive or Dropbox, a DAM solution organizes and governs brand assets comprehensively, offering features like approval workflows and version management that cloud storage lacks.

    Consistent branding can increase revenue by 10–20%, and a DAM provides the structure needed to maintain this consistency at scale. By ensuring all team members and partners access the same approved asset library, you eliminate brand drift.

    Modern DAMs further simplify brand management by integrating AI to speed up content discovery and automated metadata tagging, reducing creative bottlenecks and accelerating go-to-market timelines.

    Execution tools that reinforce brand standards

    Apart from DAM, execution tools are essential for converting brand strategy into consistent published content. Depending on your team, Adobe Creative Cloud, Figma, or Canva can be used. They offer varying degrees of design flexibility and guardrails to maintain brand standards.

    Balancing creativity with adherence to brand guidelines is key. Tools with brand templating features allow teams autonomy while ensuring brand consistency. Alternatively, using brand templates within your DAM offers greater control and tracking capabilities.

    For social media and content distribution, platforms like Hootsuite and HubSpot ensure cohesive publishing across channels. It’s crucial these tools connect to your DAM to guarantee only brand-approved content is shared widely.

    SEO tools like SEMrush and Ahrefs help reinforce your brand’s voice and authority online. In today’s market, where SEO extends to geo-targeting, it’s vital to ensure your brand is accurately represented from the start of customer interaction.

    Governance closes the loop

    A martech stack without governance is simply a mix of tools. Governance—including approval workflows and brand monitoring—is what makes your stack effective and protective.

    Incorporating workflow tools into project management or your DAM ensures faster and accountable proofing cycles. Tools like Mention help track external brand perception, highlighting areas of potential drift before they escalate.

    The takeaway

    The aim of a streamlined brand management martech stack is not complexity but efficiency. It should empower any team member or partner to access and create on-brand content swiftly, independently, and without needing constant design team input.

    This requires a strategic approach, a robust DAM as the central hub, integration with execution tools, and governance practices that uphold standards. When these elements work together, your brand transforms from a reactive endeavor to a proactive tool for long-term success.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • How to Measure, Test, and Forecast SEO Performance

    How to Measure, Test, and Forecast SEO Performance

    You have rankings moving, traffic shifting, AI citations appearing, and a backlog of SEO changes waiting to ship. The hard question is not what changed. It is whether your work caused the movement, whether the result mattered, and whether you can expect it to continue.

    You can answer those questions with a practical measurement system: define the decision first, preserve a credible baseline, compare the change with a counterfactual, and keep observed results separate from forecast assumptions. That structure turns SEO reporting into evidence you can use to decide what to scale, stop, or test next.

    Start with the decision your measurement must support

    Do not begin with the dashboard. Begin with the decision someone will make after seeing the result. A useful measurement question has this form: If we make a defined change to an eligible group of pages, will a named outcome improve relative to what would otherwise have happened, without damaging an important guardrail?

    That sentence forces you to specify the intervention, population, outcome, comparison, and downside. Compare it with a vague objective such as increasing SEO visibility. Visibility could mean impressions, rankings, citations, share of authority, clicks, or sessions. Those metrics describe different stages of performance and cannot substitute for one another.

    Measurement layerQuestion it answersUseful metricsWhat it cannot establish alone
    DeliveryDid the intended change reach the intended pages?Eligible URLs changed, crawl access, index status, template or component deploymentWhether the change improved performance
    Search exposureDid search or an AI system surface the content more often?Impressions, ranking distribution, page citations, share of authorityWhether people visited or completed a valuable action
    ResponseDid exposure produce a visit?Organic clicks, click-through rate, AI-referred sessionsWhether the additional visits were valuable
    Business outcomeDid the visits produce the result the organization needs?Conversions, qualified leads, subscriptions, or revenue when reliably trackedWhich SEO change caused the result without a comparison

    Choose one primary outcome for the decision. Use the remaining metrics as diagnostics or guardrails. If the decision is whether to expand a content update, organic clicks or qualified conversions may be primary while rankings explain how the result occurred. If the objective is inclusion in AI-generated answers, citations may be primary while referral sessions and conversions reveal the downstream value.

    Write a measurement contract before deployment

    A short measurement contract prevents the definition of success from changing after the numbers arrive. Record the following before implementation:

    • Hypothesis: the mechanism you expect the change to affect and the observable result that should follow.
    • Eligible population: the pages, query groups, markets, devices, or templates to which the conclusion may apply.
    • Intervention: the exact content, technical, linking, visual, or markup change being tested.
    • Primary metric: the outcome that determines the decision.
    • Diagnostics and guardrails: the metrics that explain the result or reveal an unacceptable tradeoff.
    • Comparison method: randomized pages, matched pages, a staged rollout, or a forecasted baseline.
    • Analysis window: when measurement starts, when it ends, and how delayed implementation or incomplete indexing will be handled.
    • Decision rule: the minimum result that would justify scaling, the conditions that would stop the rollout, and what will count as inconclusive.
    • Exclusions: rules for removing pages affected by outages, migrations, tracking failures, or unrelated changes.

    Define ratios as carefully as totals. A rising click-through rate can reflect more clicks, fewer impressions, or a change in query mix. An increasing AI referral share can reflect more AI sessions, fewer total sessions, or both. Always report the numerator and denominator beside an important rate.

    The unit of analysis matters too. A sitewide total may be dominated by a few large pages, while a per-page average can hide the total commercial impact. Report the aggregate effect and the distribution across eligible pages. That lets you see both the overall contribution and how consistently the intervention worked.

    Design SEO experiments around a believable counterfactual

    Two matched miniature website structures sit side by side, with one highlighted change on the test side.

    A before-and-after chart shows that performance changed after deployment. It does not show what would have happened without the deployment. Search demand, seasonality, competitors, search features, algorithmic changes, and the natural trajectory of the pages all continue moving while your test runs.

    The counterfactual is your estimate of that missing outcome. The more believable it is, the more confidently you can attribute the difference to your intervention.

    Use the strongest comparison your site can support

    • Randomized page split: use this when you have many comparable pages. Define the eligible set, then randomly assign pages to changed and unchanged groups. Randomization reduces systematic differences between the groups.
    • Matched pages: pair pages using pre-test traffic, trend, intent, template, topic, and other relevant characteristics. Apply the change to one member of each pair. Matching is weaker than randomization but stronger than choosing a convenient control after the result appears.
    • Staged rollout: release the intervention in waves. Pages scheduled for later waves can temporarily represent what would have happened without the change, provided the waves are genuinely comparable.
    • Interrupted time series: use this when a sitewide change leaves no parallel control. Model the pre-change trajectory, forecast the no-change baseline through the post-change period, and compare actual performance with that baseline. Treat the causal conclusion more cautiously because other events can coincide with deployment.

    Do not assign the strongest pages to the treatment group merely because they appear most likely to win. That creates a built-in difference between treatment and control. If page strength is important, divide the eligible pages into comparable strength bands first and randomize or match within each band.

    Prewrite the analysis, not just the hypothesis

    1. Freeze the eligible page list before looking at post-change performance.
    2. Save the pre-period data at the same grain you will analyze later, including page, query group, device, market, and outcome where relevant.
    3. Check whether treatment and comparison groups have similar pre-period levels and trends. If they do not, repair the design before deployment.
    4. Estimate whether the eligible population can distinguish a worthwhile effect from ordinary variation. If it cannot, combine appropriate pages, extend the observation window, or treat the test as exploratory.
    5. Deploy only the defined intervention. Log unavoidable concurrent changes instead of silently folding them into the result.
    6. Apply the predetermined inclusion, exclusion, and timing rules.
    7. Calculate the effect for the full eligible population before exploring subgroups.
    8. Report total impact, page-level variation, uncertainty, and any guardrail movement together.

    For a simple comparison of aggregated traffic, calculate each group’s relative change first: test change = test after / test before – 1, and control change = control after / control before – 1. The difference between those changes is an estimate of incremental lift. For rates such as click-through or conversion rate, retain the underlying counts and use a method appropriate to a rate rather than treating the percentages as independent totals.

    This calculation is not a substitute for checking pre-period trends, uncertainty, or contamination. It simply makes the causal question explicit: did the changed pages improve more than comparable unchanged pages over the same period?

    Match the intervention to the page’s actual bottleneck

    A six-month test across 47 new and existing articles evaluated featured images, infographics, and videos. Articles receiving infographics recorded a 110% average organic traffic increase, but the gains were associated with pages that were already performing well. The custom visuals did not reliably revive struggling content.

    That result is useful evidence for forming a hypothesis, not a universal forecast for every site. A visual asset can strengthen a page whose topic, search demand, and core content already work. It is unlikely to repair the wrong search intent, weak topic demand, poor indexability, or a page that does not answer the query.

    Segment visual tests by pre-period page strength before deployment. If strong and weak pages respond differently, you will know where production investment is likely to pay back. If you create those segments only after seeing the outcome, label the finding exploratory and confirm it in another test.

    Interpret movement without mistaking it for causation

    An SEO result becomes more credible when the movement follows the mechanism you predicted. If you improved titles to earn more clicks, you would expect the main change to appear in click-through rate among relevant impressions. If impressions rise because the page begins appearing for additional queries, query coverage is part of the mechanism. If conversions rise while search exposure and visits remain flat, the explanation probably sits elsewhere.

    Observed patternReasonable interpretationNext check
    Impressions rise while ranking distribution is stableDemand or query coverage may have expandedCompare query mix, branded versus non-branded exposure, markets, and devices
    Rankings improve while clicks remain flatThe improved positions may have little demand or may not be earning clicksInspect impressions, result-page features, snippets, and query-level click-through rate
    Organic clicks rise while conversions remain flatThe additional traffic may have different intent or the onsite path may be limiting valueCompare landing pages, query groups, conversion definitions, and the numerator and denominator of the conversion rate
    Citations rise while AI referrals remain flatAI exposure improved without producing measurable visitsCheck cited pages, grounding queries, referral tagging, and whether a visit was expected from the answer type
    AI referral share rises while AI session count is flatThe denominator may have fallenReport AI-referred sessions and total sessions separately
    Only a few large pages account for the gainThe intervention may be valuable but not broadly repeatableReport total contribution and the page-level distribution instead of one average

    Audit alternative explanations before declaring a win

    • Seasonality: did the topic normally rise during this part of the demand cycle?
    • Query mix: did exposure shift toward branded, navigational, or otherwise different searches?
    • Page mix: did new, removed, redirected, or newly indexed URLs change the population being measured?
    • Tracking: did consent behavior, channel classification, event definitions, or referral detection change?
    • Concurrent releases: did internal links, templates, site speed, navigation, paid promotion, or other content updates change at the same time?
    • External search changes: did competitors, result-page features, or the retrieval behavior of an AI platform change during the measurement window?
    • Contamination: could treatment pages affect control pages through internal linking, shared templates, or overlapping queries?

    A change ledger makes this audit possible. Record deployments, migrations, tracking changes, major content releases, and known incidents against the same timeline as the test. An unexplained spike is much harder to interpret months later, when the people reviewing it no longer remember what shipped.

    Separate positive, negative, and inconclusive results

    • Decision-useful positive: the estimated lift clears the minimum worthwhile effect, uncertainty is acceptable, guardrails are intact, and the causal chain is plausible.
    • Decision-useful negative: the result is precise enough to rule out a worthwhile gain or shows a meaningful downside. This can justify stopping or redesigning the intervention.
    • Inconclusive: the estimate is too uncertain, the groups were not comparable, implementation was incomplete, or confounding prevents a clear decision. Inconclusive does not mean the intervention had no effect.

    Define the minimum worthwhile effect from the decision, not from whichever result looks favorable. Include production cost, maintenance burden, the amount of eligible traffic, and the opportunity cost of delaying other work. Statistical evidence can tell you whether an effect is distinguishable from variation; it cannot decide whether the effect is worth implementing.

    Treat unplanned subgroup findings carefully. If a result appears only after repeatedly slicing by device, market, template, intent, or page type, it may be a useful lead. It is not yet a reliable scaling rule. Put the suspected interaction into the next measurement contract and test it deliberately.

    Forecast the no-change baseline before adding SEO upside

    A neutral path continues from a present-day checkpoint while a translucent forecast path rises above it with widening uncertainty bands.

    A useful SEO forecast begins with a less exciting question: what is likely to happen if the proposed work produces no incremental gain? That no-change baseline separates expected demand, existing momentum, and seasonality from the contribution you hope to create.

    Forecasting only the desired outcome bakes the business target into the model. A target tells you what the organization wants. A forecast estimates what the available evidence supports. Keep both, but never label one as the other.

    Build and validate the baseline in a fixed sequence

    1. Choose the target series. Forecast the metric that supports the decision, such as organic clicks, eligible-page sessions, AI-referred sessions, or qualified conversions. Do not forecast rankings and silently translate them into revenue.
    2. Choose a stable grain. Use a consistent time cadence and a page, query, template, or market grouping with enough signal to model. Group a noisy long tail by a defensible shared characteristic instead of pretending every URL has an independent, stable trajectory.
    3. Set the cutoff. Train the baseline only on information available before the forecast begins. Do not let post-launch observations leak into a supposedly independent no-change forecast.
    4. Model the existing pattern. Account for trend and recurring seasonality that are visible in the historical series. Add known events only when they are defined independently of the result you are trying to explain.
    5. Backtest at the decision horizon. Move the cutoff backward, generate forecasts for periods whose actual outcomes are already known, and measure the errors. Compare the model with a simple benchmark such as the most relevant prior pattern.
    6. Produce an interval. Show a plausible range around the baseline, not only a point estimate. The interval should generally reflect the larger uncertainty that accompanies a longer horizon.
    7. Add scenarios outside the baseline. Apply tested lift only to the pages, queries, or markets eligible for the intervention. Keep unvalidated assumptions visibly separate.
    8. Reconcile and monitor. Make sure cohort forecasts add up to the site-level view, then compare actuals with the frozen baseline and its interval as data arrives.

    When the series has non-linear trends or recurring seasonal structure, a model such as Prophet can support non-linear SEO forecasting. The model name is not the quality test. Use it only if backtesting shows that it handles your series better than a simpler benchmark at the horizon you need.

    A sophisticated model cannot automatically understand a migration, tracking break, search-feature change, one-off campaign, or abrupt shift in content supply. Annotate structural breaks, test their effect on forecast error, and explain any manual treatment. Otherwise, the model may faithfully project a historical artifact that no longer applies.

    Keep baseline, committed work, and upside hypotheses separate

    Forecast layerWhat belongs in itHow to use it
    BaselineExpected performance from existing trajectory, recurring seasonality, and independently known conditionsRepresents the no-incremental-lift comparison
    Committed scenarioBaseline plus changes already approved or deployed, using effects supported by relevant evidenceSupports operational planning while preserving the assumptions
    Upside scenarioBaseline plus interventions whose lift is plausible but not yet validated for the eligible populationShows opportunity without presenting aspiration as evidence

    A transparent scenario calculation can be simple: incremental outcome = eligible baseline volume x validated lift x rollout coverage. Each term must refer to the same population and period. If a test covered high-performing educational pages, do not apply its lift to product pages, weak pages, or the entire domain without new evidence.

    Forecast traffic and business outcomes as connected but separate stages. If you forecast conversions, state how forecast visits become forecast conversions and whether conversion rates differ by landing-page type, query intent, market, or device. A sitewide conversion rate can overstate the outcome when the forecast changes the traffic mix.

    When actual performance leaves the forecast interval, investigate before rewriting the baseline. The deviation may be genuine incremental lift, but it may also be a demand shock, tracking failure, structural break, or model miss. Preserve the original forecast so the organization can learn how accurate its assumptions were.

    Measure AI visibility as a funnel, not a composite score

    AI visibility adds useful observations to SEO measurement, but it does not collapse the measurement chain. A citation is exposure. An AI-referred session is a visit. An onsite conversion is an outcome. Combining them into one score conceals where performance actually changed.

    Microsoft Clarity’s generally available Citations dashboard reports page citations, share of authority, AI referral traffic, grounding queries, cited pages, and citation trendlines. Google Analytics also provides AI assistant traffic reporting. These measurements help you connect AI-generated answers with site activity, provided you preserve the distinctions between them.

    AI measurementWhat it tells youCommon misreadingBetter reporting practice
    Page citationsHow often pages from your domain were referenced in AI-generated answers during the selected period, including multiple citations within one answerTreating citation count as unique answers, users, or visitsReport citations by cited URL and grounding query, and keep referral sessions separate
    Share of authorityYour domain’s citations relative to other domains for the same query setReading the share as coverage of the entire marketPreserve the query set and report your citation count beside the competitive share
    AI referral trafficAI-referred sessions divided by total sessions during the selected periodAssuming a rising percentage always means more AI visitsShow AI-referred sessions, total sessions, and the resulting percentage together
    Grounding queriesThe queries associated with how AI systems evaluated or retrieved cited contentTreating every grounding query as a conventional search query typed by a userUse the queries to analyze interpreted intent and retrieval coverage
    Cited pagesWhich URLs receive citations and the queries associated with those citationsAssuming an uncited page is weak without considering whether it is eligible for the observed queriesCompare cited and uncited pages within the same intended query and content cohort
    TrendlinesHow citation activity changes over timeAttributing every change to the latest content releaseCompare the trend with a fixed query set, matched pages, release annotations, and referral outcomes

    Use an AI-search experiment loop

    1. Define the question or grounding-query set, platform coverage, eligible pages, and business objective before changing content.
    2. Capture baseline citations, cited URLs, competing domains, AI-referred sessions, and onsite outcomes. Use repeated observations when answers and retrieved sources vary between runs.
    3. Create a treatment and comparison cohort using pages that serve comparable intents. If page-level comparison is impossible, stage the rollout or freeze a forecasted baseline.
    4. Make one defined intervention, such as a content clarification, structural improvement, visual addition, internal-link change, or markup update. Verify that it reached every treatment page.
    5. Compare citation counts and share of authority within the same query set. Then check whether any exposure change produced additional AI-referred sessions and valuable onsite actions.
    6. Inspect conventional organic metrics as guardrails. An AI-focused update should not be declared successful if it creates an unacceptable loss elsewhere.
    7. Classify the result as decision-useful positive, decision-useful negative, or inconclusive. Feed validated effects into the relevant forecast cohort rather than the whole domain.

    The objective determines where the funnel ends. If the goal is brand representation in AI answers, a citation can be a meaningful outcome even without a click. If the goal is lead generation or sales, citations are a leading signal and referral or conversion performance must carry the decision. State that distinction before reporting the result.

    AI metrics also require stable denominators. Share of authority can rise because your citations increased or because competing citations fell. AI referral percentage can rise while AI sessions remain flat if total sessions decline. Retain the component counts so a favorable rate cannot hide an unfavorable underlying movement.

    Key takeaways

    • Define the intervention, eligible population, primary outcome, counterfactual, guardrails, and decision rule before deployment.
    • Use randomized, matched, staged, or forecast-based comparisons to estimate incremental lift. A before-and-after chart alone does not establish causation.
    • Report total impact, page-level variation, metric components, uncertainty, and alternative explanations together.
    • Forecast the no-change baseline first. Add committed and upside scenarios separately, and apply tested lift only to populations the evidence covers.
    • Keep AI citations, competitive citation share, AI referrals, and onsite outcomes as distinct stages of one measurement chain.
    • Call weak or confounded evidence inconclusive. Do not turn it into a positive or negative verdict merely to complete a report.

    Your next measurement cycle does not need to cover the entire site. Start with one consequential decision and one coherent page cohort. Write the measurement contract, preserve the pre-period data, hold back a valid comparison where possible, ship the defined change, and judge it using the rule you set before seeing the outcome.

    If a control is impossible, publish and freeze the no-change forecast before launch. Compare actual performance with its range, investigate deviations, and update future assumptions only after the evidence survives that comparison. That is how SEO reporting becomes a repeatable system for deciding what deserves the next unit of time and budget.

    References

  • A Practical Framework for Building Law Firm SEO Authority

    A Practical Framework for Building Law Firm SEO Authority

    Your law firm has repaired technical issues, improved practice-area pages, and kept publishing. Rankings rose, then leveled off. The tempting response is a larger content calendar. That can deepen the problem if the web still has little independent evidence that your firm and attorneys are credible authorities.

    The next job is not simply more SEO. It is to make expertise verifiable, publish material worth citing, and earn corroboration in places you do not control. The framework below helps you identify the authority gap and turn it into a practical queue of work.

    Key takeaways

    • Technical SEO and useful content are foundations, but they cannot manufacture independent credibility.
    • Authority becomes visible when attorney credentials, firm information, authored content, third-party profiles, and earned mentions tell the same accurate story.
    • A citable page gives another publisher or an AI-generated answer a distinct, well-supported passage worth referencing.
    • Relevant editorial mentions matter more than a large collection of weak, unrelated placements.
    • Measure authority through evidence you can inspect: identity consistency, qualified mentions, citations, referral context, and appearances for a fixed set of priority searches.

    Diagnose the authority gap before commissioning more content

    A strategist and an attorney inspect an evidence wall with connected profile cards and visible gaps while sorting files in a conference room.

    Technical SEO and strong content remain necessary. However, law firm growth can plateau when genuine, verifiable credibility is missing. Authority is not a single score that can be raised in isolation. It is the pattern created when your identity, expertise, content, and recognition elsewhere on the web agree.

    Start with a digital-footprint audit. Create a working sheet with fields for the query used, result URL, platform or publication, firm or attorney named, claim made, link destination, accuracy, control status, and next action. This turns an abstract authority problem into a list of evidence you can fix, strengthen, or pursue.

    Search for the exact firm name, common abbreviations, previous names, and each attorney’s professional name. Combine attorney names with the firm, location, and primary practice focus. Inspect ordinary search results, professional profiles, publisher biographies, local listings, interviews, event pages, and AI-generated answers. Record what a prospective client or search system would encounter without assuming your website is the starting point.

    Classify what you find:

    • Accurate owned evidence: pages and profiles your firm controls and keeps current.
    • Accurate independent evidence: relevant mentions, citations, interviews, event listings, and professional profiles hosted elsewhere.
    • Conflicting evidence: outdated titles, previous offices, inconsistent names, broken profile links, or descriptions that no longer match an attorney’s work.
    • Weak evidence: generic directory pages, duplicated biographies, or mentions with no meaningful connection to the attorney’s expertise.
    • Missing evidence: important attorneys, credentials, or practice strengths that are clear internally but barely visible outside the firm.

    The pattern matters more than the raw count. A firm can have many directory listings and still lack authority if none provides editorial context or confirms meaningful expertise. Conversely, a smaller footprint can be persuasive when relevant organizations identify the attorney clearly and connect that person to a specific area of law.

    Do not label every performance problem an authority problem. If an important page cannot be crawled, does not match the searcher’s intent, or competes with another page on your site, fix that first. Authority becomes a plausible constraint when technically sound, useful pages exist but the firm has little accurate recognition beyond its own domain.

    Your audit should end with priorities, not observations. Correct identity conflicts before promoting content. Strengthen thin attorney records before asking a publication to rely on them. If recognition clusters around a practice area the firm no longer prioritizes, redirect outreach toward the work that matters commercially.

    Make attorney expertise easy to verify

    A law firm’s authority is attached to people as much as to the firm itself. A reader should be able to determine who wrote or reviewed a page, what qualifies that person to address the subject, which firm the person represents, and where else that expertise has been recognized.

    Build a canonical biography for every attorney who contributes to public-facing content. It should use the attorney’s consistent professional name and state the current role, practice focus, relevant jurisdictions or admissions, education, credentials, leadership positions, speaking work, and publications accurately. Connect the biography to material the attorney wrote or reviewed. If an external profile is important, make sure it points back to the correct current page rather than an obsolete biography or a generic homepage.

    Avoid interchangeable biographies. A page that says every attorney is experienced, dedicated, and results-oriented provides little verifiable information. Replace generic praise with supported facts that distinguish the person’s actual work. An attorney’s biography, byline, publisher profile, event description, and professional listing should not tell conflicting versions of the same career.

    This is where E-E-A-T becomes useful as a review lens. Experience, expertise, authoritativeness, and trustworthiness are not fields you can fill in or claims you can create with markup. They prompt better questions: Is a real person accountable for the content? Is the claimed expertise visible? Can important credentials be verified? Does the firm’s presence remain consistent across the platforms where people encounter it?

    Use JSON-LD to express facts already visible on the page and to connect the attorney, authored material, and firm consistently. Keep identifiers stable and use the same canonical URLs throughout your implementation. Structured data can clarify relationships, but it cannot prove a credential or create reputation. Never place a qualification, award, office, service, or affiliation in markup when the visible page does not support it.

    Credential, specialization, testimonial, award, and outcome claims deserve an additional review. A stale or overstated claim can create ethical, regulatory, and reputational exposure. Requirements differ by jurisdiction, so have the firm’s appropriate ethics or compliance reviewer approve those statements before publishing them on pages, profiles, or structured data. Search optimization does not reduce that obligation.

    Assign ownership for identity maintenance. Someone should know who updates attorney biographies after role changes, who corrects external profiles, and who checks that new bylines use the canonical identity. Without ownership, small inconsistencies accumulate until the web describes several slightly different versions of the same person.

    Turn practice knowledge into material others can cite

    An attorney shares legal knowledge with a research and editorial team as organized reference packets are passed to independent library and newsroom professionals.

    An indexable page is accessible to a search system. A citable page gives another publisher, professional, or answer system a specific reason to use it as support. That difference should change your editorial brief. The goal is not another page about a broad keyword; it is a reliable contribution that adds something identifiable to the available information.

    Prioritizing citable material over content produced merely to be indexed means asking what another person could responsibly reference. Useful formats include a jurisdiction-scoped explanation of a recurring procedural question, a decision aid that distinguishes commonly confused options, a practical checklist reviewed by a named attorney, a plain-language explanation of a legal development, or an analysis of public information with a transparent method.

    Use the following editorial test before approving a page:

    • Distinct question: The page resolves a real question instead of paraphrasing a broad topic already covered elsewhere on the site.
    • Clear answer: The reader can find the central answer near the beginning, with qualifications added where they matter.
    • Defined scope: The relevant jurisdiction, audience, assumptions, and limits are explicit.
    • Accountable expertise: A named attorney wrote or reviewed the material, and the byline connects to a complete biography.
    • Support: Important factual and legal claims point to suitable primary legal materials or other appropriate evidence.
    • Original utility: The page contains a useful distinction, framework, checklist, interpretation, or method rather than generic prose.
    • Maintenance: An owner is responsible for reviewing the page when the law, procedure, attorney, or firm information changes.

    Write passages that remain understandable when separated from the surrounding page. Give each section a descriptive heading, answer the stated question directly, and keep the necessary qualification beside the answer. This makes the page easier for a person to scan and gives AI-generated answers less room to detach a conclusion from its jurisdiction or conditions.

    Do not confuse extractability with oversimplification. A concise answer can still state that an outcome depends on facts, venue, or procedure. If removing a qualification would make the answer misleading, keep it in the same paragraph rather than burying it in a general disclaimer.

    Review the existing library before expanding it. Identify pages with strong subject matter but weak authorship, vague scope, or no reason to cite them. Upgrade those assets first. If several pages repeat the same intent, consider consolidating them into a stronger resource, but inspect existing links, referrals, and search value before changing URLs. Preserve useful destinations with an appropriate redirect when consolidation is justified.

    Case-based insight needs special care. Do not expose confidential information, imply a typical outcome from an exceptional matter, or turn a result into an unsupported promise. Obtain the necessary internal approval and follow the professional rules that apply to the firm before using client matters, testimonials, or outcomes as authority evidence.

    Earn outside corroboration, then measure the evidence

    Your website can claim expertise. Independent recognition helps corroborate it. That recognition may take the form of a relevant citation, an attorney contribution, an interview, a professional event, a community role, or a publisher biography that clearly connects a person to the subject.

    Build an outreach map from genuine relationships and audience overlap. Consider legal and professional publications, organizations connected to the industries your firm serves, educational institutions, reputable local organizations, event producers, and journalists who cover the relevant issues. Prioritize editorial standards, topical relevance, and accurate identification of the attorney. A contextual mention for the right audience can be more useful than an unrelated placement obtained only for a link.

    Give outreach a concrete purpose. Offer a well-scoped explanation, a named attorney who can address a defined question, a citable resource, or an informed contribution to an existing discussion. Generic requests for a backlink give the recipient no editorial reason to act. Meaningful digital PR and participation in the legal community work because they create legitimate connections between expertise, people, and publications.

    For each opportunity, prepare the canonical attorney name, current title, concise subject-specific biography, correct firm URL, relevant biography URL, and strongest supporting asset. After publication, check that names, roles, links, and claims are accurate. Request corrections when necessary, and add the result to the firm’s footprint inventory.

    Avoid placements whose only apparent purpose is manipulating ranking signals. Do not manufacture awards, trade unrelated links, buy opaque editorial recognition, or distribute the same thin biography across low-quality sites. These tactics create a brittle footprint and can undermine the credibility you intended to build.

    Measure authority with an evidence log rather than a single vendor score. Record the asset or attorney involved, external URL, publication or organization, practice relevance, linked or unlinked status, description accuracy, referral activity, and any qualified enquiry or professional relationship connected to the placement. The context of the mention matters, so retain enough detail to distinguish substantive recognition from a name in a list.

    Separate leading evidence from validation and business outcomes:

    • Leading evidence: corrected identity conflicts, complete attorney records, upgraded citable assets, relevant outreach, and accepted contributions.
    • External validation: accurate mentions, citations, interviews, event profiles, professional references, referral visits, and greater visibility for priority subjects.
    • Business outcomes: qualified consultations, professional referrals, and matters connected to the practices the authority program supports.

    For AI visibility, maintain a fixed set of representative questions tied to your priority practices and markets. Capture the exact question, date, answer, cited domains, firm mentions, attorney mentions, and any material inaccuracies. Repeat the same checks at a regular cadence. Individual AI-generated answers can vary, so look for a pattern across repeated observations rather than treating a single appearance or omission as proof.

    No isolated metric establishes causation. A new mention does not prove that it moved a ranking, and an AI citation does not by itself establish business value. The useful question is whether independent, accurate evidence is becoming denser around the attorneys, subjects, and markets the firm has chosen to own.

    Begin with the practice area that matters most. Audit the names and claims surrounding it, repair the canonical attorney records, strengthen the best existing resource, and take that resource to relevant editorial and professional contacts. When each cycle leaves another accurate, independent trace of expertise, your firm is building an asset that a larger publishing schedule cannot imitate.

    References

  • AI Search Optimization Without Spam: A WebMCP Readiness Plan

    You need visibility in AI-generated search results, but you cannot afford to turn optimization into a collection of tricks that puts your existing rankings at risk. At the same time, AI agents are moving beyond finding information toward completing tasks on websites.

    The practical response is one connected strategy: publish material worth retrieving, keep every machine-readable claim tied to visible facts, and prepare a small set of site actions that an agent could eventually perform safely. That work improves your site now without requiring you to gamble on speculative markup or an unfinished implementation.

    Draw the policy line at genuine user value

    Google’s definition of search spam now explicitly includes attempts to manipulate generative AI responses in Google Search. A tactic does not become acceptable merely because its target is an AI Overview or AI Mode instead of a conventional ranking.

    That does not make AI search optimization illegitimate. It gives you a useful boundary: legitimate optimization makes a page, entity, or user journey more useful and easier to understand. Manipulation tries to influence the generated output without making the underlying experience more accurate, distinctive, or helpful.

    Run every proposed AI visibility tactic through these checks before it reaches production:

    • The user test: Would this change still improve the page if no AI system ever cited it?
    • The truth test: Can a reader verify every claim from visible content, supporting evidence, or the real product or service being described?
    • The surface test: Is the same meaning available to people and machines, or are you presenting an AI-only version designed to produce a preferred answer?
    • The reputation test: Are mentions, endorsements, and reviews authentic, or is the plan manufacturing apparent consensus?
    • The maintenance test: Can your team keep the claim accurate when prices, availability, policies, locations, or product details change?

    If a tactic fails any of these checks, stop. Instructions addressed to a model, unsupported superlatives in JSON-LD, manufactured third-party mentions, and batches of near-duplicate pages are not durable visibility strategies. They create a version of your brand that is difficult to defend and even harder to maintain.

    Keep a short decision record for material optimization changes. Record the user problem, the page being changed, the factual support for the change, and the outcome you intend to observe. This forces the team to describe value in user terms before debating whether an AI system might reward it.

    Build pages that are easy to retrieve, interpret, and trust

    For Google’s generative search features, ordinary SEO remains the foundation. Crawlability, semantic HTML, sensible JavaScript, useful content, page experience, and duplicate control still matter. You do not need a separate editorial system for humans and AI.

    Start with the pages that influence an important decision: choosing a service, comparing a product, checking eligibility, understanding a process, or finding a location. Inspect each page in this order:

    • State the page’s job clearly. The title, opening, and primary heading structure should describe the same question or task. If the page tries to satisfy several unrelated intentions, separate them or choose a clear primary purpose.
    • Answer before expanding. Put the direct answer, recommendation, definition, or decision criterion near the relevant heading. Follow it with evidence, conditions, exceptions, and next steps.
    • Use semantic structure. Headings should describe actual sections. Lists should represent real sequences or sets. Tables should be reserved for information readers genuinely need to compare by row and column.
    • Add information competitors cannot reproduce by paraphrasing. That can include a clear point of view, a documented process, product constraints, original examples, decision rules, or a candid explanation of where an option does not fit.
    • Keep important content available in the rendered page. If essential facts appear only after a fragile script, interaction, or client-side request, provide a stable and accessible presentation where appropriate.
    • Consolidate duplication. Merge pages that answer the same question without adding a meaningful distinction. Where separate URLs are necessary, make their individual purposes unmistakable.
    • Use media to resolve uncertainty. A diagram, product image, demonstration, or video should help the reader see something that the prose alone cannot establish. Decorative assets do not make a page more authoritative.

    Do not confuse good structure with artificial content chunking. Short sections are useful when the subject naturally divides into discrete decisions. They are not useful when a complete explanation has been chopped into repetitive fragments solely because someone believes an AI prefers a particular paragraph length. Google’s position is that sites do not need AI-specific rewrites or forced chunking.

    A strong page should let a reader identify what is being offered, who it suits, what conditions apply, why the claims are credible, and what to do next. If those answers are buried or inconsistent, no metadata layer can repair the underlying problem.

    Use JSON-LD as a consistency contract, not a persuasion layer

    Structured data helps a machine map the entities and relationships already present on a page. It does not create authority, prove a claim, or turn thin content into a useful answer. Google does not require special markup for its generative AI features, so an AI-only schema vocabulary should not be the center of your plan.

    Treat JSON-LD as a contract between your visible page, your business data, and the systems that consume both:

    1. Identify the real primary entity on the page before selecting a type. A local business page and a product detail page describe different things and should not be marked up as interchangeable templates.
    2. Include only properties your site can support and maintain. A value should not appear in JSON-LD merely because the vocabulary permits it.
    3. Match visible names, descriptions, prices, availability, ratings, locations, and other material details wherever they appear. Do not let markup become a more flattering version of the page.
    4. Trace frequently changing values back to an authoritative internal system instead of editing the same fact independently in several templates.
    5. Retest the rendered markup after content, theme, commerce, or template changes. Valid code can still describe the wrong entity or expose stale values.
    6. Remove unsupported properties rather than filling them with defaults. Missing data is better than a confident but inaccurate assertion.

    This is especially important for local and ecommerce pages, where precise business and product details deserve focused attention. A customer should see the same core fact in the page copy, structured data, catalog, and transaction flow. When those surfaces disagree, a search system or agent has to guess which version is current.

    Audit facts horizontally rather than reviewing JSON-LD in isolation. Choose a material fact, such as a location, product variant, price, or availability state, and follow it through every surface that publishes or acts on it. Fix the source of disagreement. Patching only the markup leaves the user journey inconsistent and guarantees the error will return.

    Prepare for WebMCP by defining safe, bounded actions

    Search visibility helps an AI system discover and assess your site. Agent readiness asks a different question: can that system complete a useful task without guessing how your interface works? WebMCP’s premise is to let websites communicate their capabilities more explicitly, making it easier for AI to interact with them. The browser-native work is associated with Google and Microsoft and points toward discovery systems that can act as well as recommend.

    You do not need to expose every button to prepare for that future. Your near-term job is to remove architectural ambiguity and identify which actions are safe enough to support. Use four readiness layers:

    Readiness layerQuestion to answerWork you can do now
    InformationCan an agent find and interpret the facts needed for the task?Improve semantic HTML, stable URLs, crawlable content, entity consistency, and duplicate control.
    CapabilityIs the task defined with clear inputs, outputs, and boundaries?Create a capability inventory for recurring user jobs rather than mapping isolated interface clicks.
    ControlWho may perform the action, and when is confirmation required?Document authentication, authorization, validation, consent, side effects, and recovery paths.
    ResultCan the system distinguish success, failure, and an incomplete action?Provide clear outcome states, useful errors, duplicate protection, and operational logging.

    Create a capability inventory around user goals

    Do not begin by listing every form, link, and button. Begin with bounded jobs a visitor already comes to complete. Checking availability, retrieving an order status, requesting a quote, scheduling an appointment, or adding a known item to a cart are capabilities. Clicking the blue button is only an interface instruction.

    For each candidate capability, record:

    • The user’s intended outcome.
    • The required and optional inputs.
    • The source of each fact used to make the decision.
    • Whether the task is read-only or changes data.
    • The authentication and permission required.
    • Any financial, contractual, privacy, inventory, or scheduling side effect.
    • The point where the user must review and confirm the action.
    • The success response and the errors the caller must be able to distinguish.
    • How the operation is cancelled, reversed, or corrected when reversal is possible.

    This inventory is useful even if you never deploy WebMCP. It exposes vague workflows, duplicated business rules, hidden dependencies, and actions that rely on a person interpreting an ambiguous interface.

    Keep state-changing operations behind explicit controls

    An agent action can spend money, disclose personal data, create a reservation, submit a request, or cancel something the user intended to keep. Do not expose those operations merely because they are technically callable. Keep them behind the same authentication, authorization, validation, and confirmation boundaries that protect the human workflow.

    Before a consequential action runs, show the user the material details they are approving: the item or service, current price where applicable, quantity, date or time, recipient, and cancellation conditions. If any material value changed after the task was planned, require a fresh confirmation instead of silently continuing.

    Design for retries as well. Networks fail, responses time out, and an agent may repeat a request when it cannot determine whether the first one succeeded. Use idempotent handling, or an equivalent duplicate-detection mechanism, so a retry does not create another order, appointment, payment, or submission.

    Separate business capabilities from fragile interface paths

    A workflow that depends on screen coordinates, changing button text, or a long sequence of DOM assumptions will be difficult for any automated system to use reliably. Keep the business operation and its validation separate from its visual presentation where your architecture permits it. The website remains the human interface, while the underlying capability has a clear contract and consistent result.

    Semantic controls and descriptive labels remain important. They improve accessibility, testing, human comprehension, and automated interpretation at the same time. WebMCP readiness should build on that interface rather than become an excuse to neglect it.

    Test failure paths before exposing a capability

    A workflow is not agent-ready merely because its happy path works. Exercise missing inputs, invalid values, expired sessions, insufficient permissions, stale prices, unavailable inventory, scheduling conflicts, duplicate submissions, downstream failures, and ambiguous responses. The caller should receive a result it can explain without pretending the task succeeded.

    Use a staging environment for state-changing tests and keep real customer data out of test prompts and logs. When you add operational logging, record enough to diagnose the action and its outcome while continuing to apply your existing access and retention controls.

    Follow a low-regret implementation sequence

    1. Select the important pages and bounded user tasks that already support a real business or customer need.
    2. Fix crawlability, semantic structure, duplication, JavaScript dependencies, and weak content on those pages.
    3. Reconcile visible facts, JSON-LD, catalogs, and transactional data so the same claim has one maintained source of truth.
    4. Apply the user, truth, surface, reputation, and maintenance tests to every AI visibility change.
    5. Document capability inputs, outputs, permissions, side effects, confirmation points, and recovery paths.
    6. Separate reusable business logic from fragile presentation-specific steps where practical.
    7. Test successful and unsuccessful outcomes in staging before enabling any agent-facing integration.
    8. Expose capabilities only through an implementation your team can secure, monitor, maintain, and disable if behavior changes.

    This sequence gives you value before WebMCP adoption becomes a deciding factor. The same work produces clearer content, cleaner data, safer transactions, and a site that is easier for both people and software to use.

    Practical questions before you approve the work

    Do you need an llms.txt file or special AI schema for Google?

    No. For Google’s generative AI features, neither llms.txt nor special AI markup is required. Use established technical SEO and structured data practices, and keep the machine-readable representation aligned with the visible page.

    How can you tell whether optimization has become manipulation?

    Remove the AI result from the business case. If the change no longer helps a reader, clarifies a fact, improves retrieval, or makes a legitimate task safer, its purpose is probably influence rather than usefulness. Treat that as a stop signal, especially when the tactic depends on hidden instructions, unsupported claims, or manufactured mentions.

    What should you optimize first?

    Choose the page attached to an important user decision where the facts are currently incomplete, duplicated, difficult to retrieve, or inconsistent with structured data. Fixing a known information gap is more defensible than creating a new AI-targeted page whose only purpose is to occupy another search surface.

    What can you do before deploying WebMCP?

    Build the capability inventory, classify read and write actions, document permission and confirmation boundaries, stabilize the underlying business operations, and test failure states. These preparations support the shift from AI-assisted discovery toward agent-completed actions without requiring you to expose a speculative production interface.

    Start with your highest-value page and safest bounded workflow. Make the facts consistent, map the control points, and test what happens when the request fails or repeats. You will have improved search visibility and operational quality even before an agent uses the result.

    References

  • Uncovering the Best Senior Living SEO Agencies for 2026

    n

    Last updated: May 14, 2026

    nnnn

    I


    Inspired by this post on First Page Sage Blog.


    crushpress.ai community screenshot
  • Industry-Specific SEO Agency Rankings for 2026: Buyer Guide

    Industry-Specific SEO Agency Rankings for 2026: Buyer Guide

    If several 2026 rankings have left you with several different best agencies, the rankings aren’t necessarily contradictory. Each one reflects a different candidate pool, industry context and definition of fit. Your job is not to accept the published order. It is to decide whether the order still holds for your business.

    Use industry rankings to discover credible candidates, then re-rank those candidates around your search demand, operating constraints and commercial risk. The process below gives you a defensible way to do that without turning agency selection into a contest between sales presentations.

    Rankings help you discover candidates, not declare a universal winner

    An agency’s position is conditional. It depends on which firms entered the evaluation, which criteria were used, how those criteria were weighted and when the underlying information was checked. A first-place agency for a luxury fashion brand does not automatically become the best choice for a biotech platform, regional med spa or international logistics provider.

    IndustryCandidate contextFreshness signalYour first verification question
    Logistics and supply chainMore than 50 agencies evaluatedUpdated May 14, 2026Can the team translate service lines, locations and operational terminology into a coherent search architecture?
    FashionMore than 90 agencies with luxury-brand work consideredUpdated May 14, 2026Does its experience match your price position, sales model and balance between brand control and ecommerce growth?
    Med spasMore than 40 agencies evaluatedUpdated May 14, 2026Can it coordinate local discovery, treatment content and appropriate review of health-adjacent claims?
    BiotechMore than 60 firms evaluatedUpdated May 14, 2025Can it protect scientific accuracy while making complex concepts discoverable to distinct audiences?

    Those pool sizes show the breadth of consideration, but they are not confidence scores. Fashion does not have a more reliable winner merely because its candidate field was larger than the med-spa field. The pool may be larger because the market contains more plausible candidates, because the inclusion criteria differ or because relevant experience is defined differently.

    The luxury-brand condition also narrows what the fashion evidence means. It can be highly relevant when premium positioning, controlled language and brand presentation are central to the assignment. It may be less diagnostic for a discount marketplace, an apparel manufacturer selling through distributors or a retailer whose primary problem is managing a large and frequently changing catalog.

    Freshness deserves the same care. The biotech field looks ahead to 2026 but carries a May 14, 2025 update date. That does not prove any position is wrong. It does mean you should verify the agency’s current team, client mix, conflicts, service scope and technical capabilities before treating its rank as current.

    Do not average positions across different industry rankings or treat them as if they came from one league table. Start with the vertical closest to your business model. If your company spans verticals, identify the harder search problem and use that as the primary filter. A biotech logistics provider, for example, may need scientific governance and supply-chain demand generation; neither label alone establishes fit.

    Real industry specialization changes how the agency works

    A strategist at a divided workbench adapts different components for miniature clinical, warehouse, professional-services, and retail environments.

    Industry logos are weak evidence on their own. Specialization becomes meaningful when it changes discovery, keyword and entity research, website architecture, content approval, measurement and reporting. Ask candidates to show how their process changes for your vertical rather than merely showing that they recognize its vocabulary.

    Logistics and supply chain: test the commercial architecture

    A logistics website may need to organize demand by service, geography, shipment or operational problem, customer industry and buying role. Those dimensions can overlap. Publishing a page for every possible combination creates duplication; collapsing everything into broad service pages can hide the specific expertise a buyer is trying to find.

    Give the agency a representative service line and ask it to sketch the path from search query to qualified inquiry. The answer should cover page hierarchy, supporting content, internal links, proof, conversion language and how irrelevant leads will be screened out. If the response jumps immediately to a calendar of generic thought-leadership topics, the commercial model has been skipped.

    Also listen for the way the team handles operational terminology. It should be able to preserve the language practitioners use while explaining the offering clearly enough for procurement, finance or leadership. Replacing precise terminology with high-volume but poorly matched phrases can increase visibility while reducing lead quality.

    Fashion: test catalog mechanics and brand restraint

    Fashion SEO sits at the intersection of brand presentation, product discovery, merchandising and technical catalog management. Category pages, product pages, editorial content and seasonal collections can compete with one another if their roles are not clearly defined. Changes in inventory can also leave valuable internal links pointing toward thin, unavailable or retired destinations.

    Ask the agency to choose a representative category and explain what it would optimize, what it would preserve and why. For a transactional site, the response should address indexation, canonical choices, filters, internal linking, product availability and structured data alongside copy. It should also identify where search-led wording would damage the brand rather than assuming every available keyword belongs on the page.

    Luxury-brand experience is most useful when your own positioning requires similar restraint. If your growth model depends on frequent promotions, marketplace visibility or a broad value-oriented catalog, ask for evidence from that operating model rather than accepting prestige logos as a substitute.

    Med spas: test local intent and content governance

    Med-spa discovery is often both local and treatment-specific. A candidate therefore needs to connect location information, service detail, practitioner or facility trust signals, reviews and conversion paths without manufacturing interchangeable city pages. A page that merely swaps place names is not a local strategy.

    Ask the team to walk through a treatment page from query selection to publication. Who verifies medical or treatment-related statements? How are candidacy, limitations and expected outcomes described without drifting into unsupported promises? How do local pages differ when locations offer different services or have different staff? The agency does not need to make clinical decisions, but it does need a workflow that routes health-related claims to an appropriate reviewer.

    Measurement should reach beyond local rankings. Define what happens after a visitor arrives: a call, consultation request, booking or another meaningful action. Then establish how your team will feed appointment quality and service-line value back into SEO decisions. Otherwise, attractive traffic reports can conceal low-value inquiries.

    Biotech: test scientific review and entity consistency

    Biotech content has to preserve scientific precision while serving readers with different levels of technical knowledge. Researchers, prospective partners, buyers and investors may look for different answers even when they use overlapping terminology. Treating them as one audience usually produces pages that are dense but directionless.

    Ask who translates the search opportunity into a technical brief, who reviews scientific statements and how corrections propagate across the site. The agency should be able to keep platform names, indications, mechanisms, development stages and organizational relationships consistent across navigation, page copy, metadata and structured data where structured data is appropriate.

    Then ask how old claims are retired. Updating one prominent page is not enough when an outdated statement remains in an executive biography, resource page, downloadable asset or schema implementation. A credible workflow includes an inventory of dependent content and a named approval path.

    If an agency gives essentially the same answer for every vertical after swapping industry nouns, its specialization is surface-deep. The strongest signal is not familiarity with jargon. It is an operating model built around the consequences of getting the content, architecture or measurement wrong.

    Build your own decision matrix before requesting proposals

    Agencies cannot respond comparably when each one receives a different version of the assignment. Prepare a short brief before outreach. Include your priority offerings, markets, audiences, primary conversion, current platform, internal implementation resources, approval constraints and known measurement gaps. State whether you need strategy only, production, technical implementation or an accountable combination.

    Send the same brief to every candidate and evaluate each response as pass, concern or fail against the same matrix. Do not turn the labels into a mechanical total. A failure involving data ownership, claim approval or an undisclosed conflict can outweigh several softer passes.

    CriterionA pass looks likeA warning looks like
    Business-model fitThe team maps SEO activity to your actual offering, buyer, market and conversion path.The strategy would work only if your business behaved like a different client shown in the pitch.
    Evidence qualityExamples identify the starting problem, work performed, relevant outcome and agency’s actual scope.Charts lack context, screenshots have no meaningful baseline, or credit is claimed for work performed by others.
    Industry workflowResearch and approval steps reflect your terminology, risk level, internal experts and publishing constraints.Specialization is supported mainly by client logos and generic claims about understanding the audience.
    Technical depthThe agency connects crawling, indexation, rendering, templates, internal links and structured data to specific site problems.A standard audit is presented as the strategy, with no explanation of who will implement or validate changes.
    Content operationsBriefing, subject-matter review, editing, approval, updating and retirement all have clear owners.The proposal promises content volume without explaining accuracy control, differentiation or maintenance.
    AI discoveryThe team explains how entity clarity, answerable content, supporting evidence, crawlability, internal relationships and schema fit together, while acknowledging measurement limits.It guarantees placement in AI answers or treats GEO and AEO as labels for producing more generic copy.
    MeasurementPrimary conversions, diagnostic metrics, lead quality and reporting decisions are defined before work begins.Success is reduced to traffic, impressions, keyword counts or a proprietary score that cannot be reconciled with business outcomes.
    Commercial safetyAccount access, content and data ownership, subcontracting, change control, cancellation and transition duties are explicit.The agency controls essential assets, avoids documenting handoff obligations or leaves implementation costs outside an apparently complete fee.

    AI visibility deserves particular scrutiny in a 2026 selection. An agency should distinguish conventional search performance from appearances in answer engines or model-generated responses. It should also explain which observations are reproducible, which depend on prompts or platforms and which cannot be attributed cleanly. A polished AI dashboard is not useful if nobody can explain what its metrics mean or what decision will change when they move.

    Ask how structured data fits the plan, but do not accept schema volume as a goal. Markup should represent the visible content and the entities the page actually describes. It cannot repair vague positioning, unsupported claims, inaccessible pages or contradictory facts elsewhere on the site.

    Set hard stops before presentations begin. Ranking guarantees, refusal to provide access to your own accounts, undisclosed subcontracting, publication without required review and ambiguous ownership of your domain, analytics or content all deserve resolution before a contract is signed. If a candidate will not resolve them in writing, remove it from the shortlist.

    Test the agency’s thinking with a real working session

    A client team and agency strategists test ideas together using an unlabeled physical model of search pathways, obstacles, funnels, and risk gates.

    Presentation fluency can hide weak diagnosis. Give every finalist the same bounded working exercise using a real part of your site. You are not asking for a free strategy. You are testing how the team frames a problem, handles missing information and converts analysis into an implementable decision.

    1. Select a representative service, category, treatment or platform page tied to a meaningful conversion.
    2. Provide the same business context, technical constraints and available performance information to each finalist.
    3. Ask the team to identify search intent, relevant entities, architectural issues, content gaps, proof requirements and conversion friction.
    4. Require prioritization. Each recommendation should identify its expected role, dependencies, implementation owner and validation method.
    5. Ask what the team still does not know and how it would obtain the missing information after kickoff.

    A strong response distinguishes evidence from assumption. It may decline to estimate an outcome until analytics, indexation, competition or lead-quality data has been checked. That is disciplined diagnosis, not evasiveness. A weak response manufactures certainty, reaches for a familiar tactic before establishing the problem or produces a long backlog with no decision logic.

    Pay attention to who attends. If senior specialists lead the sale, ask who will conduct discovery, write briefs, review technical recommendations and join reporting meetings after signature. Request the names or roles of the delivery team and clarify how substitutions are handled. Industry experience held only by an executive who disappears after the pitch will not improve day-to-day work.

    Reference calls are most useful when you ask about operating behavior rather than general satisfaction. Ask what the agency actually owned, what delayed the work, how disagreements were resolved, whether senior involvement changed after the sale, how reporting affected decisions and what happened when a recommendation or published claim was wrong. A reference chosen by the agency will naturally be favorable, but precise process questions can still reveal the conditions behind the success.

    Read the final contract against the proposal and your matrix. Confirm deliverable definitions, implementation responsibilities, approval timing, account access, data and content ownership, use of third parties, change control, cancellation and transition support. A vague exit clause can turn an ordinary mismatch into an expensive migration, so resolve the handoff before work starts rather than after the relationship has deteriorated.

    Finally, name an internal owner. Even a capable specialist agency cannot approve scientific claims, supply merchandising decisions, verify service availability or judge lead quality without your team. The contract should make that dependency visible instead of allowing delays to become a recurring dispute about who was waiting for whom.

    Key takeaways

    • An industry ranking is a candidate-discovery tool, not a transferable verdict about the best agency for every company in that vertical.
    • Verify freshness, current team composition, relevant client work, conflicts and service scope before relying on any 2026 position.
    • Real specialization changes architecture, content review, technical execution and measurement; industry logos alone do not establish it.
    • Compare candidates against the same written brief and use hard stops for ownership, approvals, access, conflicts and unsupported guarantees.
    • Use a real working session to test prioritization, assumptions and implementation thinking before you sign.

    Your next move is concrete: open the ranking closest to your operating model, create a small candidate set, run freshness and conflict checks, and send every remaining agency the same brief. Choose the team that makes dependencies, uncertainty and commercial risk visible while showing how it will solve your particular search problem. That is a stronger basis for a 2026 decision than the number beside an agency’s name.

    References

  • How to Manage Ad Targeting and API Updates Without Chaos

    How to Manage Ad Targeting and API Updates Without Chaos

    An advertising-platform release can create two very different jobs. A targeting feature asks whether you can reach a better audience. An API change asks whether your reporting, security checks, stored data, and automation will continue to work. Treat both as features to try, and you can spend budget before measurement is ready or discover a broken data dependency after the damage is done.

    That distinction matters now because Microsoft Advertising has extended LinkedIn profile targeting to connected TV campaigns, while Google Ads API v24.1 adds reporting, creative-control, experiment, authentication, and retention-related changes. You need a release process that protects existing operations first, validates measurement second, and tests growth opportunities third.

    Classify each change before scheduling the work

    The loudest feature should not automatically become the first task. Rank changes by what happens if you ignore them. A new audience may represent an opportunity, but a data-retention limit can permanently narrow the history available to your reporting system.

    Use five practical classes:

    • Continuity changes: retention limits, unsupported requests, client compatibility, and anything else that can interrupt a production workflow.
    • Measurement changes: new segments or metrics that alter how performance can be divided and interpreted.
    • Security changes: fields that help you identify account protections or authentication gaps.
    • Control changes: options that affect how an approved creative is uploaded, transformed, or displayed.
    • Growth changes: new audiences, inventory, campaign types, and experiment surfaces.

    Work through them in that order unless a documented dependency changes the sequence. Continuity comes first because lost history or a failed reporting job can affect every campaign. Measurement comes before growth because you cannot judge a new audience reliably until you know what the reporting can and cannot observe.

    For the current updates, the 37-month Google Ads data-retention boundary belongs in the continuity queue. The mobile-device platform segment belongs in measurement. The passkey field belongs in security. Demand Gen image control belongs in control. LinkedIn-based CTV targeting belongs in growth. That classification gives your team an actionable backlog rather than an undifferentiated list of announcements.

    Test professional CTV targeting as an audience hypothesis

    A media planner runs a small connected TV audience test by selecting one professional audience cluster for comparison.

    Microsoft’s CTV expansion lets advertisers use professional attributes such as industry, job function, company category, and professional identity signals. For a B2B advertiser, that can connect broad streaming exposure with a more relevant professional audience.

    It does not turn a professional attribute into buying intent. A viewer’s job function may indicate fit, but it does not prove that the viewer is researching a purchase. Treat the targeting as a testable audience hypothesis: people matching this professional profile should respond differently from a suitable comparison audience when the message and measurement remain consistent.

    Build the first test in this order:

    1. Choose one buying group. Describe it with the smallest useful combination of industry, function, and company characteristics. If you begin with a heavily stacked audience, you will not know which condition created the result or restricted delivery.
    2. Write down what the attributes mean. Record the exact audience definition, intended buying role, exclusions, eligible markets, and date of activation. Platform labels are not a substitute for an internal audience specification.
    3. Hold avoidable variables steady. Use comparable creative, offers, geography, inventory conditions, and evaluation windows across the audience cells. Otherwise, a creative or delivery difference can masquerade as a targeting effect.
    4. Select an observable outcome before launch. Do not let an easy-to-read delivery metric become the business objective by default. Use the conversion, lift, or qualified-response signal that your measurement stack can support consistently.
    5. Set a decision rule. Define what evidence would justify expanding, revising, or stopping the audience. Making that decision after seeing the result invites selective interpretation.
    6. Review privacy and compliance. Confirm that the proposed professional segmentation, creative, data handling, and market coverage fit your organization’s requirements before the audience begins receiving ads.

    Measurement deserves extra attention. CTV has traditionally operated as a brand-oriented channel with less direct attribution than search or shopping. Professional targeting can improve audience relevance, but it does not automatically resolve that measurement gap. Keep exposure quality, downstream response, and attribution confidence separate in your readout.

    Several implementation details remain uncertain, including market availability, segmentation granularity, measurement capabilities, and privacy considerations. Verify those items in the account and market you intend to use. Do not build a forecast around targeting combinations or reporting dimensions you have not confirmed are available.

    Turn Google Ads API v24.1 into an engineering checklist

    An engineer checks reporting, security, creative, experiment, automation, and data modules before an API workflow reaches production.

    API adoption is not complete when a client library installs successfully. The real work sits downstream: query builders, schemas, dashboards, experiment records, asset workflows, authentication reports, exception handling, and historical storage.

    Start by mapping each v24.1 capability to the system it can affect:

    The retention change deserves a separate migration task. Search your query code, scheduled exports, dashboards, year-over-year reports, model-training inputs, and audit workflows for requests that can reach beyond 37 months. Then verify what history is still queryable and preserve future data at the granularity your business actually needs.

    An archive is useful only if you can interpret and restore it. Store the account identifier, reporting period, timezone, currency context, field definitions, extraction timestamp, and relevant attribution or configuration metadata alongside the metrics. Test a restore into a clean table before relying on the archive. A successful export file is not proof of a recoverable reporting history.

    Update error handling as well. DateRangeError.REQUESTED_DATE_GRANULARITY_NOT_SUPPORTED identifies an unsupported date-range request. Treat a confirmed policy boundary as a query-design problem, not a transient failure to retry indefinitely. Logging the requested dates and granularity will make the remediation far faster.

    Put targeting and API work through one change-control loop

    Marketing and engineering do not need separate definitions of a successful platform update. They need one shared record that distinguishes a business hypothesis from a technical dependency.

    Change typeQuestion to answer firstEvidence requiredSafe response if it fails
    New audienceCan you isolate the audience effect?Documented audience cells, stable measurement, and a predefined decision rulePause the new segment without disturbing the existing campaign structure
    Reporting dimensionCan every downstream system accept and interpret it?Schema validation and reconciled totals against a baselineRemove the new dimension from production queries while preserving the test
    Creative-control fieldDoes the delivered asset match the approved intent?Asset-level quality review and recorded campaign mappingReturn to the previously approved asset path
    Retention boundaryCan analysis continue after platform history expires?External archive plus a successful restore testNo platform rollback exists; repair the archive and shorten unsupported queries
    Authentication-status fieldWho acts when an account lacks the expected protection?Verified field ingestion, ownership, and a remediation queueKeep the current authentication flow while correcting the reporting or rollout process

    Every change ticket should name an owner, impacted accounts, affected queries or campaigns, the validation evidence, a rollback path, and the date when someone will make a keep-or-revert decision. If no one owns that decision, the change is not ready for production.

    Keep the Microsoft audience test and Google API migration separate even if they appear in the same planning cycle. One measures whether professional targeting improves an advertising outcome. The other protects and expands the systems used to report that outcome. Combining them creates two moving parts and a result that is harder to diagnose.

    Key takeaways

    • Prioritize continuity and data-retention work before testing new reach.
    • Treat professional CTV attributes as proxies for audience fit, not proof of current purchase intent.
    • Confirm Microsoft CTV availability, measurement, segmentation, and compliance conditions in the actual account and market before forecasting results.
    • Test every new Google Ads API field through queries, schemas, storage, and dashboards before promoting it to production.
    • Maintain an external, restorable archive if your reporting requires more than 37 months of Google Ads history.
    • Give every rollout a named owner, acceptance evidence, rollback path, and decision date.

    At your next platform-change review, create two queues: one for operational deadlines and one for controlled growth tests. Clear the dependencies that can damage data or reporting, validate the measurement layer, and then give the new audience or creative capability a fair test.

    References