Author: shivamcrushpressai

  • How to Diagnose and Improve CTV Advertising Performance

    How to Diagnose and Improve CTV Advertising Performance

    Your CTV dashboard is full of reassuring signals. Impressions are delivering, people appear to be completing the video, and the platform may even be reporting conversions. Yet sales, qualified leads, site activity, or brand demand have barely moved.

    Changing the audience, creative, bids, and budget at the same time will spend more money without explaining the gap. CTV’s upside can be undercut by avoidable campaign mistakes that weaken performance and ROI. To find them, separate delivery from response and attributed response from incremental business impact.

    Define performance before choosing a metric

    CTV can support broad awareness, demand creation, customer acquisition, re-engagement, or a combination of those jobs. Those campaigns should not share an identical definition of success.

    An awareness campaign should not be judged solely by immediate clicks because television is not primarily a click-first environment. A direct-response campaign cannot declare victory based on completed views when the intended business event is a qualified lead or purchase. Start with the decision the campaign is supposed to influence, then choose the metric that represents that decision.

    Write a short measurement contract before launch. It should answer:

    • What business question are you asking? For example, whether CTV can generate new-customer demand, extend reach beyond another channel, or improve response in selected markets.
    • What is the primary outcome? Choose the event closest to business value that can be measured credibly, such as a qualified lead, first purchase, booked appointment, or validated brand-lift measure.
    • What evidence will support the outcome? Name the delivery, exposure, response, and business metrics you will use. Do not elevate every available dashboard metric to KPI status.
    • How will credit be assigned? Document the attribution window, click-through and view-through treatment, identity method, deduplication rules, and treatment of existing customers.
    • What is the comparison? Decide whether you will use a holdout, geographic comparison, matched audience, established baseline, or another defensible counterfactual.
    • What would cause you to change course? State which finding would justify a creative change, targeting adjustment, budget move, or pause.

    This prevents a common reporting failure: choosing the most flattering metric after the campaign has run. It also keeps efficiency measures in their proper role. CPM, pacing, and completion rate can help you manage delivery, but none of them independently proves that the campaign created business value.

    Key takeaways

    • Define the campaign’s business job before selecting its primary KPI.
    • Read CTV performance as a chain: delivery, exposure, response, business outcome, and incrementality.
    • Treat completion rate as evidence that the video played through, not proof that the message persuaded anyone.
    • Reconcile platform reporting with analytics and business systems before optimizing media.
    • Change the earliest broken link in the chain and preserve a clean record of what changed.

    Read CTV performance as a chain, not a score
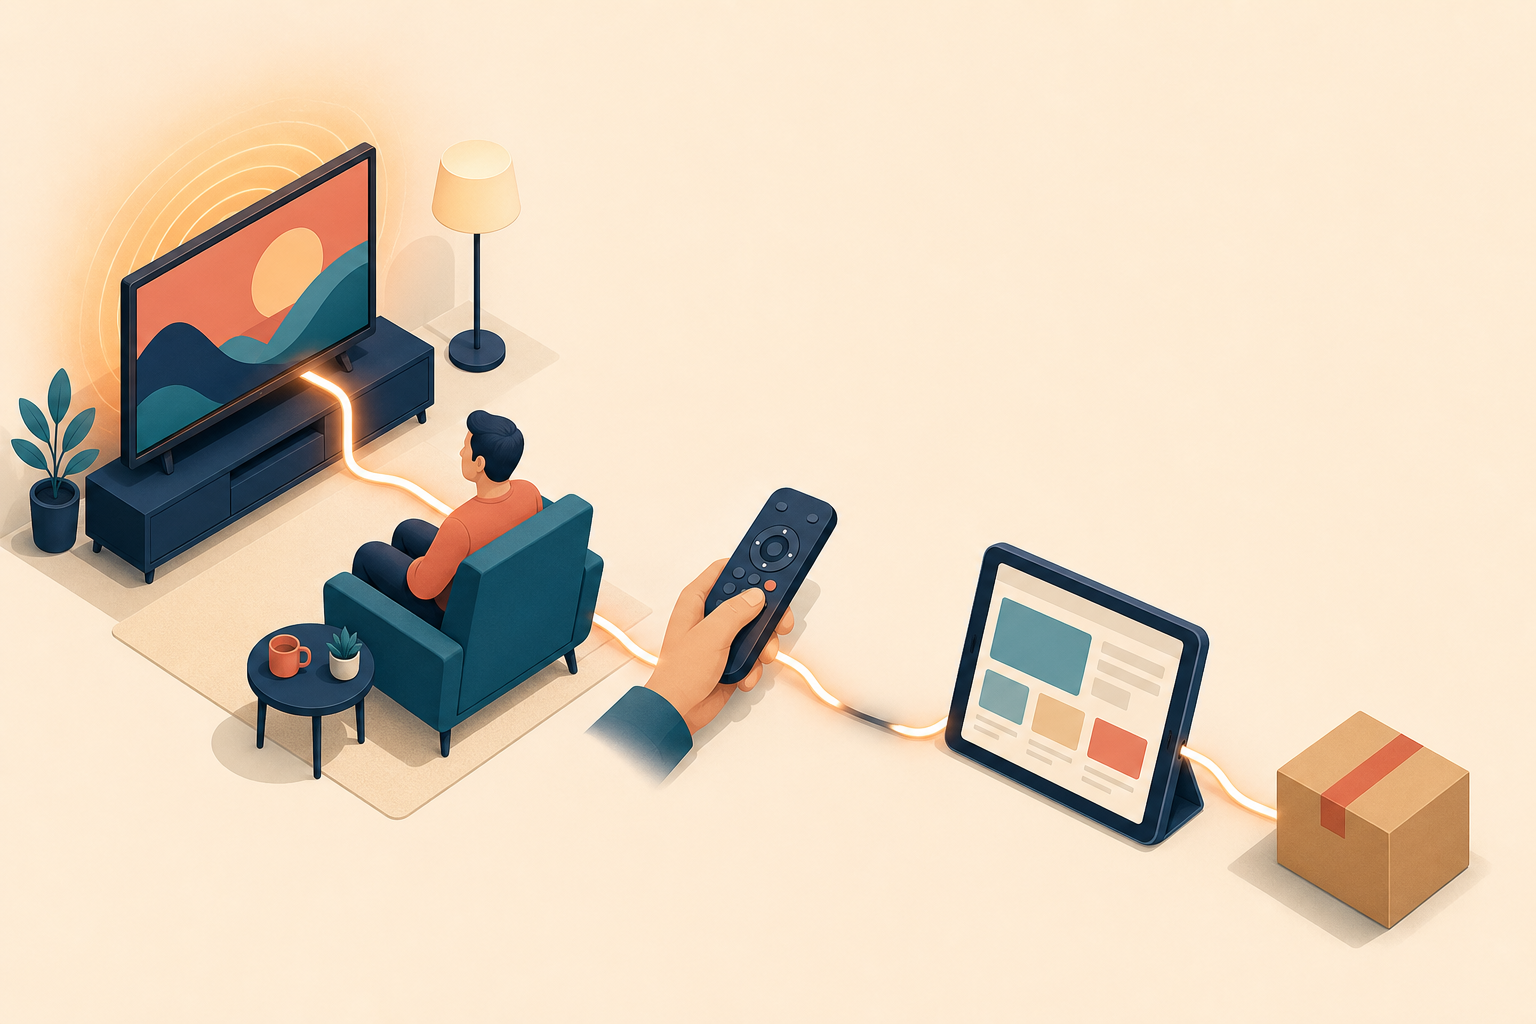
    An isometric sequence connects a television, viewer, remote, tablet, and shopping parcel with a glowing cable that weakens at one junction.

    A single blended score hides the reason a campaign is succeeding or failing. Read the evidence in layers, beginning with delivery and ending with causality.

    Performance layerUseful evidenceQuestion it answersWhat it cannot prove alone
    DeliverySpend, impressions, pacing, CPM, geography, device and inventory reportingDid the campaign buy and deliver the intended media?Whether the intended audience noticed, responded, or converted
    Exposure distributionEstimated reach, frequency, completion rate and available quality signalsHow broadly and repeatedly was the advertising delivered?Whether a completed exposure changed perception or behavior
    ResponseLanding-page visits, engaged sessions, searches, direct visits, QR activity or other campaign-linked actionsDid observable behavior move alongside exposure?Whether the campaign caused that movement
    Business outcomeQualified leads, first purchases, revenue, appointments or another validated commercial eventDid activity reach the result the business values?How much of the result would have happened without CTV
    IncrementalityHoldout lift, geographic comparison, matched testing or another credible counterfactualDid CTV create additional outcomes?Whether the same result will persist at a different budget or audience scale

    Read this chain from the top down. If geography, inventory, or pacing is wrong, downstream performance is not yet interpretable. If delivery is healthy but response is weak, inspect audience-message fit and the creative. If response rises but business outcomes do not, inspect the landing experience, offer, conversion tracking, and lead quality. If attributed conversions look strong but a comparison group shows no meaningful lift, the attribution system may be claiming demand the campaign did not create.

    Completion rate deserves particular care. It describes playback behavior under the platform’s reporting rules. It does not tell you whether the viewer remembered the brand, understood the offer, or took action. A high completion rate paired with concentrated frequency may simply mean the same reachable households received the ad repeatedly.

    Reach and frequency also require context. Estimates may depend on household graphs, device matching, or modeled identity, and separate buying platforms may not deduplicate the same household consistently. Use the numbers to manage distribution, but do not present cross-platform totals as exact people counts unless your measurement setup genuinely supports that claim.

    Diagnose the pattern before changing the campaign

    The most useful optimization question is not, “Which metric is bad?” It is, “Where does the evidence first stop supporting the expected path?” The answer gives you a testable hypothesis instead of a list of random changes.

    What you seeFirst hypothesis to investigateWhat to do next
    High completion rate, limited reach and rising frequencyDelivery is concentrated among a small reachable groupReview audience constraints, inventory access, exclusions and frequency controls before producing new creative
    Healthy delivery and completion, but little observable responseThe message is not creating action, the audience is a poor fit, or response measurement is incompleteValidate tracking first, then test a materially different message or audience while holding other variables steady
    Platform-reported conversions rise while analytics, CRM or order data stays flatAttribution rules, event mapping, view-through credit or deduplication are creating a reporting gapCompare event definitions, timestamps, attribution windows and customer records before increasing spend
    Site activity rises but conversion quality fallsThe ad is creating curiosity without qualified intent, or the landing experience breaks the promiseCompare new and returning visitors, review lead or order quality, and align the landing page with the ad’s exact proposition
    Attributed results are concentrated among existing customersRetargeting may be harvesting demand rather than creating new demandSeparate existing customers from prospects and report acquisition outcomes independently
    The campaign underdeliversAudience, geography, inventory, bidding, creative approval or brand-safety constraints may be too restrictiveFind the binding constraint and relax one condition at a time; do not broaden everything simultaneously
    Reported efficiency looks strong, but a holdout or market comparison shows little liftThe attribution model is awarding credit for outcomes likely to occur anywayMake incrementality the budget decision metric and use attribution mainly for operational diagnosis

    These patterns are starting points, not automatic verdicts. A tracking failure can imitate a creative failure. A landing-page problem can imitate weak audience quality. An aggressive attribution window can make an ordinary campaign look exceptional. Confirm the upstream evidence before acting on the downstream symptom.

    Build measurement that can survive scrutiny
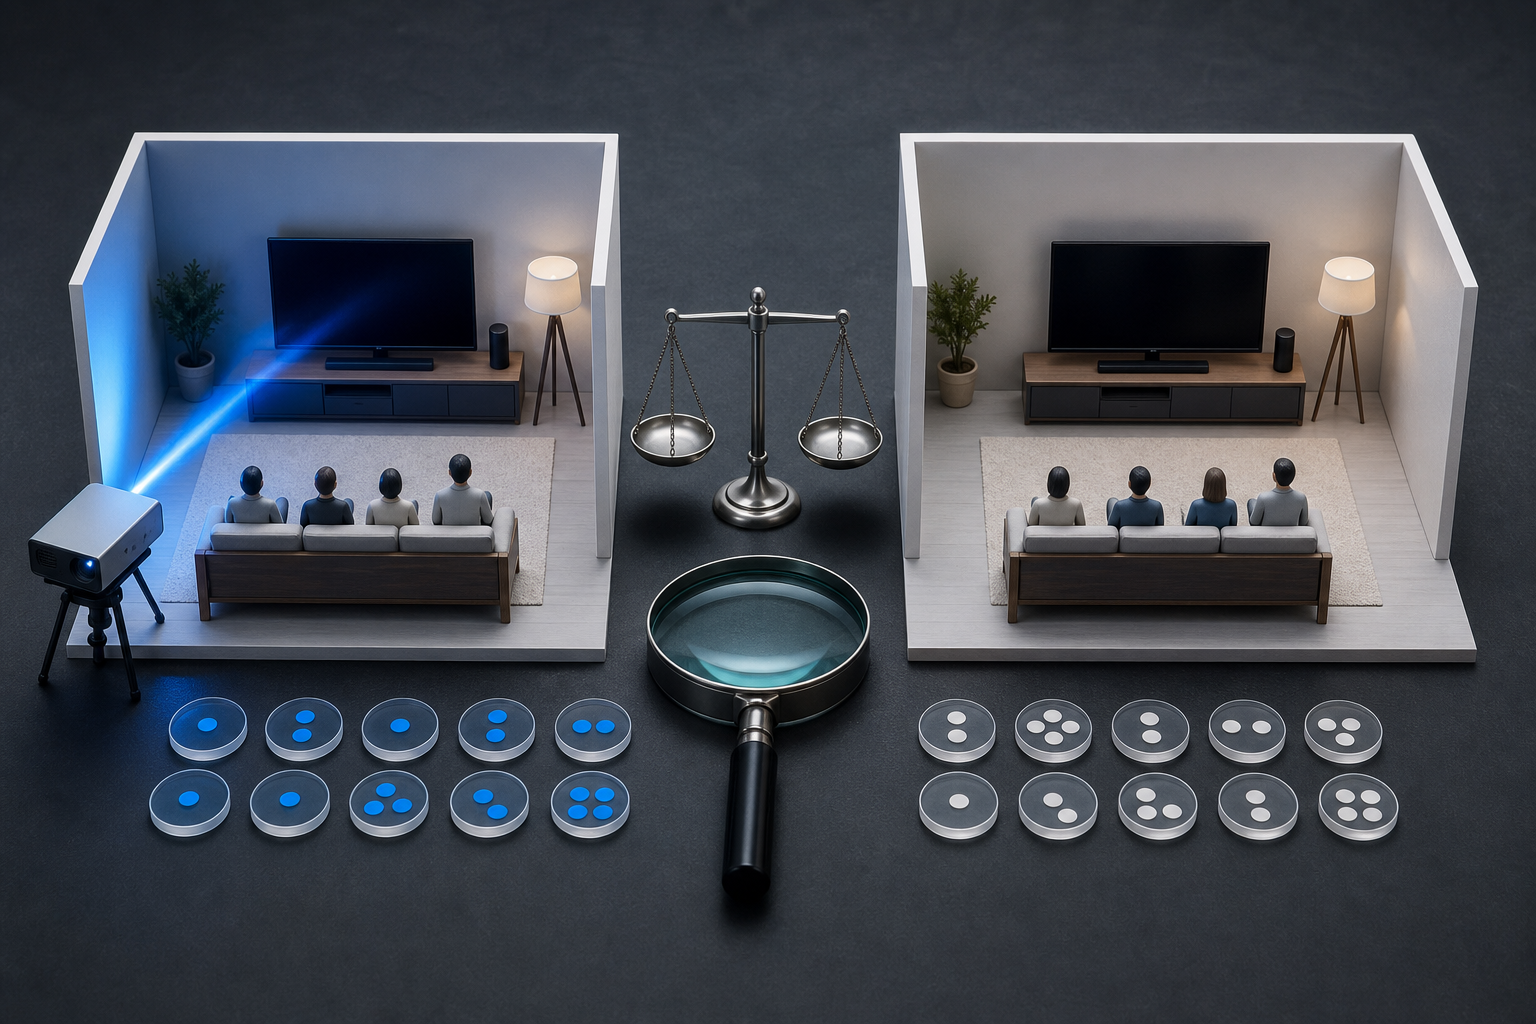
    Two matching miniature living rooms are compared on a laboratory bench, with only one receiving a projected media beam.

    Your buying platform, site analytics, ad server, and CRM do not necessarily answer the same question. A platform may assign credit when an exposed household converts within its configured window. Site analytics records sessions and events under its own identity and attribution rules. Your CRM may count only validated leads, completed sales, or first-time customers. A mismatch is not automatically an error, but an unexplained mismatch is a decision risk.

    Use this sequence to make the systems comparable:

    1. Standardize campaign identity. Carry a stable campaign name or ID through the buying platform, landing page, analytics setup, CRM, and reporting model. Preserve creative, audience, geography, inventory, and flight labels as separate fields.
    2. Define the business event. Specify exactly what counts as a conversion. A form submission, qualified lead, booked appointment, completed order, and new-customer order are different events and should not be blended.
    3. Document attribution settings. Record the click-through and view-through rules, conversion window, household or device-matching method, deduplication logic, time zone, and treatment of repeat conversions.
    4. Test the full data path. Follow a test action from the landing page through analytics and into the business system. Confirm that required fields persist and that duplicate, cancelled, unqualified, or internal events are handled as intended.
    5. Separate meaningful cohorts. At minimum, inspect prospects and existing customers independently when acquisition is the goal. Add geography, creative, audience, device, inventory, and frequency views only when they answer a real decision question.
    6. Create a counterfactual. Use a randomized holdout when the setup allows it. Otherwise, consider a carefully selected geographic or matched comparison and state its limitations. A simple before-and-after view is vulnerable to seasonality, promotions, competitor activity, and changes in other channels.
    7. Keep a decision log. Record the hypothesis, date, change, expected metric movement, guardrail, and result. This is what stops a sequence of campaign edits from turning into an uninterpretable blur.

    Use only identifiers and matching methods permitted by your consent practices, contracts, and applicable privacy requirements. More granular identity data is not automatically better measurement if you cannot use it lawfully or explain how it produced the result.

    Most importantly, distinguish attribution from incrementality. Attribution assigns credit under a rule. Incrementality asks whether the advertising produced an outcome that otherwise would not have occurred. You need attribution to operate campaigns, but you need incremental evidence to justify budget. When a rigorous incrementality test is not feasible, label the result as directional and make smaller decisions until stronger evidence is available.

    Optimize the earliest broken link in the chain

    CTV optimization works best in a deliberate order. Fixing a downstream metric while an upstream problem remains can improve the dashboard without improving the campaign.

    1. Repair measurement first. Resolve missing events, inconsistent definitions, duplicate conversions, landing-page errors, and unexplained reporting gaps. Do not move budget based on data you do not trust.
    2. Correct delivery fit. Confirm that the intended geography, devices, content environments, schedule, exclusions, and audience constraints match the plan.
    3. Improve exposure distribution. If frequency is concentrating while reach stalls, inspect frequency controls and the restrictions limiting available inventory. If reach is broad but the audience is poorly qualified, tightening the audience may be appropriate even if delivery becomes less efficient.
    4. Test the message. Change the proposition, proof, framing, or call to action rather than relying on cosmetic variations. A useful test should represent a real hypothesis about why viewers are not responding.
    5. Refine the audience. Separate prospecting from retargeting, distinguish existing customers from new prospects, and avoid treating a high-attribution segment as automatically incremental.
    6. Continue the promise after the ad. The landing experience should use the same offer, language, product, and next step. If the viewer has to reconstruct the message after switching devices, unnecessary friction has entered the journey.
    7. Reallocate budget last. Move spend after you understand whether the difference came from delivery, audience, creative, conversion quality, or incremental impact. Cheap delivery is not a bargain when it buys the wrong outcome.

    Review the creative as it will be experienced from a sofa, not as a large design file on a work screen. A viewer should be able to identify the brand and understand the proposition before the ad ends. Important text must remain legible at television distance. A QR code can support the response path, but it should not carry the entire call to action. Give viewers a brand, product, phrase, or destination they can remember and find later.

    When you run a test, preserve interpretability. State the hypothesis, change one major variable, select the primary metric, and name the guardrail before looking at the outcome. If business constraints require several simultaneous changes, separate them into distinct cells where possible or record that the result cannot identify which change caused the movement.

    Bring a one-page decision sheet to your next CTV review: the business question, primary outcome, attribution rule, comparison method, first broken link, and next test. If your team cannot complete one of those lines, that gap is the next task. Once every line is defensible, CTV advertising performance becomes a business decision rather than a collection of favorable video metrics.
    References

  • Unlock Real Growth with Meaningful Digital Marketing Metrics

    Unlock Real Growth with Meaningful Digital Marketing Metrics

    I used to rely heavily on vanity metrics, thinking they were the key to my digital marketing success. However, I soon realized that they did little more than paint a pretty picture with no real substance. That’s when I decided to focus on what’s truly important: the numbers that actually drive business growth.

    In today’s digital landscape, it’s crucial to pinpoint which KPIs truly matter. By doing so, I can build reports that genuinely tell the story of my business’s progress. These metrics go far beyond just surface-level statistics.

    It’s all about understanding the complete picture and tailoring my strategy to focus on those key performance indicators that have a tangible impact on my business’s bottom line. Join me as I delve into which digital marketing KPIs deserve our attention.


    Inspired by this post on genmark.ai Blog.


    crushpress.ai community screenshot
  • How to Build a B2B Go-to-Market Operating Model

    How to Build a B2B Go-to-Market Operating Model

    Your go-to-market strategy can be sound while execution still feels improvised. Marketing generates demand, sales qualifies it, enablement creates materials, and customer teams hear the objections, but each function uses a different definition of progress. That is an operating-model gap.

    You close that gap by specifying how buyer evidence becomes a decision, how work crosses team boundaries, where the official record lives, and how feedback changes the system. The goal is not a larger process manual. It is a small set of rules that helps your teams make the same good decision without rebuilding the process around every campaign or deal.

    Separate your strategy from the system that runs it

    A GTM strategy defines where you intend to compete and how you expect to win. A GTM operating model defines how people, workflows, systems, and decision rights turn those choices into coordinated action. An execution plan covers the work currently in motion.

    LayerQuestion it answersRequired output
    GTM strategyWhere will we play, for whom, and why should they choose us?Target market, buyer problem, value proposition, commercial motion, and strategic constraints
    GTM operating modelHow will teams repeatedly turn those choices into revenue work?Buyer stages, decision rights, handoffs, workflows, systems of record, controls, and feedback loops
    Execution planWhat are we doing now?Active accounts, campaigns, opportunities, experiments, deliverables, owners, and commitments

    The distinction matters because changing tools does not repair an undefined decision. Adding an AI assistant does not repair a weak handoff. Hiring another specialist does not repair incompatible stage definitions. Start with the outcome the system must produce, then decide which roles and technology support it. That follows an outcome-first Service as Software principle: the useful unit of design is the result, not the tool itself.

    Use the following questions as a completeness test. If the answers depend on whom you ask, the operating model is still implicit:

    • Which buyer and buying situation does this revenue motion serve?
    • What observable evidence moves an account from one stage to the next?
    • Who decides whether that evidence is sufficient?
    • What information must accompany a handoff?
    • Where is acceptance, rejection, or rework recorded?
    • Which signal causes the team to change targeting, messaging, channel use, or process?
    • Which decisions may AI support, and which still require human approval?

    Do not begin with the organization chart. Roles will change, and the same role name can carry different authority in different companies. Begin with a bounded revenue motion: a defined audience, problem, offer, route to market, and desired customer outcome. Build the operating model around that flow of value.

    Use buyer progression as the spine of the model

    A central illuminated path connects successive buyer situations while several business teams contribute evidence at different stages.

    Internal funnel labels are useful only when they correspond to something that has changed for the buyer. A label such as MQL describes an internal classification. It does not, by itself, tell sales what the buyer understands, what evidence exists, or what should happen next.

    Define stages as buyer states that your team can recognize from evidence. Starter language might include exploring a problem, validating an approach, resolving risk, committing to a decision, and beginning adoption. Those names are not universal. The important part is that each state has an observable entry condition and an observable exit condition.

    1. Write the audience, buying situation, problem, offer, and route to market on a shared brief. If those choices vary materially, you may be dealing with separate revenue motions that need separate rules.
    2. Name each buyer state in plain language. Avoid stage names that merely identify the department currently holding the record.
    3. Define entry evidence. Specify what must be known or confirmed before an account belongs in that state.
    4. Define exit evidence. Use a change in buyer commitment, understanding, access, or risk resolution rather than a seller activity such as sending an email.
    5. Assign an accountable owner, the required system fields, and the next commitment that advances the buyer.
    6. Define what happens when evidence is missing, the buyer pauses, or the account no longer fits. Recycling and disqualification are operating paths, not miscellaneous exceptions.

    A stage specification should be usable during live work, not only during training. Give each stage the following fields:

    FieldQuestion to answerExample of useful evidence
    Buyer stateWhat is now true for the buyer?The problem has been confirmed in the buyer’s own terms
    Entry conditionWhat evidence allows the record to enter?A relevant stakeholder has confirmed the operational consequence
    Exit conditionWhat must change before the record advances?The buyer has agreed to evaluate a defined approach
    Accountable ownerWho decides whether the condition is met?The role with the authority and context to accept the stage
    Required recordWhere can another team verify the evidence?A structured field plus a concise evidence note in the system of record
    Next commitmentWhat mutually understood action advances the buyer?An agreed review with the relevant participants and purpose
    Return pathWhat happens if the evidence is incomplete?Return to the prior owner with a recorded reason and required correction

    Test the definitions against active accounts. Give independent teammates the same evidence and ask them to classify the buyer state and identify the next action. If they reach different answers, do not add more dashboard fields yet. Tighten the stage language, evidence standard, or decision owner.

    This buyer-centered spine also keeps content connected to revenue work. Every important asset should support a specific buyer question, evidence requirement, risk, or next commitment. If nobody can name the buyer state and decision the asset supports, its place in the operating model is unclear.

    Give decisions and handoffs explicit owners

    Cross-functional collaboration does not mean collective accountability. A decision can have many contributors, but it needs a clearly identified owner with enough authority, information, and capacity to make the call. Otherwise, teams keep revisiting the same issue while execution moves ahead on incompatible assumptions.

    Keep a lightweight decision record

    Record recurring or consequential GTM decisions in a shared location. This is not a transcript of the discussion. It is the minimum context someone needs to execute the decision and know when it may be reopened.

    • Decision: State the choice in terms that can be acted on.
    • Owner: Name the role responsible for making and maintaining the decision.
    • Required inputs: Identify the buyer, market, operational, financial, or risk evidence needed.
    • Decision rule: Explain what would make one option preferable to another.
    • Contributors: List the roles that supply expertise without transferring ownership.
    • Record: Link the approved definition, workflow, message, or configuration affected.
    • Revisit condition: Name the new evidence or material change that would justify reopening the choice.

    Apply this structure to decisions such as target-account eligibility, stage acceptance, message approval, channel allocation, proof requirements, process exceptions, and permitted AI use. The owner may differ by decision. What should not change is the visibility of the ownership.

    Treat every handoff as a contract

    A handoff is not complete when the sending team changes a status field. It is complete when the receiving team can accept the work, understand why it matters, and take the next action without reconstructing the missing context.

    For each important boundary, document:

    • Trigger: The buyer evidence or operational event that starts the handoff.
    • Payload: The fields, notes, assets, permissions, and context that must travel with it.
    • Receiver response: The available outcomes, such as accept, reject, or return for correction.
    • Reason codes: A short, controlled set of explanations that can reveal repeated failure patterns.
    • Response expectation: The agreed service window and the event that starts it.
    • System of record: The place where status, evidence, ownership, and response are authoritative.
    • Escalation path: The owner who resolves a disputed definition or stalled boundary.

    Track acceptance and rework, not just handoff volume. High volume can look productive while the receiving team quietly discards weak records. Repeated rejection for the same reason usually points to a targeting problem, an evidence problem, an unclear definition, or a missing field. Fix that boundary instead of asking the sender to produce more volume.

    The same contract should cover the transition from sales to onboarding and from customer feedback back to marketing, product, and enablement. A GTM model is incomplete if it ends when a deal is marked won. The promises made during acquisition need to remain visible to the team responsible for delivering and expanding the relationship.

    Run feedback loops that change the work

    Four connected teams collect customer signals, identify patterns, update modular processes, and return the revised system to frontline work.

    A full meeting calendar is not a feedback system. Every operating ritual needs a defined question, required inputs, a decision it can produce, an owner, and a place where the result changes the workflow.

    • Flow review: Identify where buyer progress is blocked, where records wait, and where work returns for correction. The output is an owner and a change to the blocked path.
    • Market-signal review: Examine recurring objections, failed assumptions, competitive pressure, search behavior, and language used by buyers. The output may change targeting, positioning, content, or qualification.
    • Experiment review: Compare the original hypothesis, execution, observed signal, and decision. The output is to continue, change, stop, or design a better test.
    • Adoption review: Determine whether the intended users can perform the process inside their normal tools. The output is a workflow, training, field, or artifact change.
    • Promise-delivery review: Compare what acquisition teams promised with what onboarding and customer teams can deliver. The output is a corrected promise, delivery change, or escalation.

    Match the cadence to the rate at which useful evidence appears. Routing problems need an execution cadence because they obstruct current work. Positioning changes need enough accumulated market evidence to distinguish a pattern from an isolated comment. Do not use the same meeting rhythm for every decision merely because the calendar makes that convenient.

    Use a metric stack that exposes both business results and the mechanism producing them:

    • Outcome measures show commercial progress, customer value, and retention.
    • Flow measures show movement, waiting, conversion, and backlog across buyer stages.
    • Quality measures show acceptance, completeness, correction, and avoidable rework.
    • Adoption measures show whether the intended workflow and assets are actually being used.
    • Learning measures show which assumptions were tested and which decisions changed as a result.

    For every metric, document its definition, data source, owner, review context, and the decision it can trigger. A dashboard that cannot change a decision is reporting overhead. A dashboard whose definitions vary by function is a visual version of the operating-model problem.

    Put AI inside a controlled workflow

    AI should have the same operational discipline as any other part of the GTM model. Do not make adoption of an AI tool the outcome. Define the work it supports, the evidence it may use, the quality standard it must meet, and the accountable human decision.

    • Permitted input: Specify which customer, market, performance, and internal data may enter the workflow.
    • Bounded task: Define whether AI is classifying, drafting, retrieving, summarizing, recommending, or executing.
    • Acceptance criteria: State what makes the output accurate, relevant, complete, brand-safe, and usable.
    • Approval boundary: Identify what a person must verify before publication, customer contact, data change, or commercial action.
    • Audit record: Preserve the input context, output, reviewer, disposition, and downstream action where the risk warrants it.
    • Fallback: Define how work continues when the model, integration, or output is unavailable or unsuitable.

    For SEO, AEO, and GEO content workflows, acceptance may include traceable claims, a defined search or buyer intent, approved product language, clear ownership of structured data, and editorial review before publication. That connects AI-assisted content to the GTM system instead of allowing generated assets to accumulate without a buyer decision or distribution path.

    Earn sophistication through adoption

    A new operating model usually fails at the point of use, not at the level of the diagram. If a seller must leave the CRM, find a separate document, reinterpret a stage, and duplicate the evidence in another system, the designed workflow is competing with the actual job.

    Behavior change depends on fitting enablement into daily work. A polished deck cannot compensate for a process that requires extra steps at every deal. Put definitions, prompts, assets, approvals, and feedback controls where the relevant decision occurs. Train with live work, and observe where users hesitate, invent workarounds, or omit information.

    Use the Shu Ha Ri progression from fundamentals toward innovation as a practical maturity lens:

    • Stabilize the standard: Establish common language, buyer stages, owners, handoff rules, and an authoritative record. At this point, consistency matters more than customization.
    • Adapt from evidence: Change a bounded part of the model when recorded exceptions, buyer signals, or adoption friction reveal a real mismatch. Preserve the reason for the change so adaptation does not become drift.
    • Innovate on a stable base: Add custom automation, AI agents, new channels, or differentiated motions only after the underlying decision and feedback paths are visible. Automation scales ambiguity as readily as it scales good work.

    Roll out the model through a revenue motion that matters and is narrow enough to observe. Embed its required fields and decisions in the systems people already use. Remove duplicate paths where it is safe to do so, because leaving the old workflow available teaches users that the new model is optional. Keep an exception route for legitimate edge cases, but require a reason that can feed the adaptation loop.

    Before expanding the model, look for operational proof:

    • Independent teammates classify the same buyer evidence consistently.
    • Receivers accept, reject, or return handoffs with a recorded reason.
    • Teams can find the current decision, asset, and definition at the point of work.
    • Operating reviews produce documented changes rather than repeated discussion.
    • Exceptions reveal patterns that can improve the standard path.
    • AI-supported outputs have visible acceptance criteria, review ownership, and disposition.

    Key takeaways

    • A GTM strategy defines the choices; a GTM operating model defines how teams repeatedly execute and revise those choices.
    • Build the model around observable buyer progression, not departmental funnel labels.
    • Give every recurring decision an accountable owner and every cross-team handoff an acceptance contract.
    • Measure outcomes, flow, quality, adoption, and learning so you can see both the result and its mechanism.
    • Place AI inside a bounded, reviewable workflow with explicit inputs, acceptance criteria, approval, and fallback.
    • Standardize before you customize, then innovate only when feedback and adoption are reliable.

    Choose the revenue motion creating the most consequential friction now. Map its buyer states, write the acceptance contract for its weakest handoff, and assign the unresolved decisions. Once the people doing the work can point to the same evidence and know who decides what happens next, expand the model to the next boundary.

    References

  • Unlock E-commerce Success Without Relying on Ads

    Unlock E-commerce Success Without Relying on Ads

    I’ve realized that building a business that thrives solely on advertising is risky. We can’t let our ventures be at the mercy of fluctuating ad performances.

    Instead, let’s explore how to establish e-commerce growth engines. These strategies focus on compounding growth over time, emphasizing customer loyalty and enhancing brand strength.

    By shifting our approach, we can generate sustainable revenue that doesn’t hinge solely on ad spend.


    Inspired by this post on genmark.ai Blog.


    crushpress.ai community screenshot
  • How to Optimize for Bing, ChatGPT, and Gemini Answers

    How to Optimize for Bing, ChatGPT, and Gemini Answers

    Your page can answer a question clearly and still appear in one AI answer engine while disappearing from another. That does not necessarily mean the content is bad. It may mean the answer is packaged for the wrong selection environment.

    The practical solution is not to write a separate version for every platform. Build one reliable answer asset, then add platform-specific cues for Bing, ChatGPT, and Gemini. You preserve a consistent set of facts while adapting the structure, language, context, and media each engine can use.

    One answer strategy, three selection environments

    AI answer engines overlap, but they are not interchangeable. All of them benefit from clear, accurate, well-organized content. The difference lies in how a person asks, how the engine interprets the request, and which parts of a page are easiest to turn into an answer.

    EngineSelection environmentContent cues to prioritize
    BingSearch-oriented answers connected to the wider Microsoft ecosystemStructured data, concise answers, authority, local information, and well-described images
    ChatGPTConversational answers that can change as the user adds context or asks follow-up questionsNatural phrasing, self-contained explanations, contextual branches, accuracy, and human review
    GeminiContext-rich answers that can draw on detailed questions and multiple media typesLong-tail intent coverage, connected text and visuals, useful captions, structured data, and trust signals

    This distinction changes the job. You are not trying to make three engines repeat the same paragraph. You are making the same body of knowledge understandable in three different situations: a search result, a conversation, and a multimodal response.

    Key takeaways

    • Keep the facts, evidence, and recommended action consistent across platforms.
    • Treat schema as a machine-readable description of visible content, not as a guarantee of inclusion.
    • Give Bing strong structural, local, authority, and image signals.
    • Give ChatGPT complete answers that remain useful when a user asks a follow-up question.
    • Give Gemini an explicit relationship between detailed text, relevant visuals, captions, and alt text.
    • Measure interpretation, factual accuracy, and usefulness separately from simple brand visibility.

    Build the answer asset before tuning the platform layer

    Hands fit interchangeable presentation frames around a transparent cube containing the same factual content blocks.

    A platform tactic cannot rescue an answer that is vague, unsupported, or aimed at the wrong intent. Start with a reusable answer asset: a page or section containing the question, the direct response, the conditions that affect it, the evidence behind it, and the next action.

    1. Write the question in the language your audience uses. Replace a broad topic label such as “website performance” with the actual decision the reader is making, such as “What should I fix first when my website feels slow?” Conversational and long-tail wording gives an answer engine a clearer intent to match.
    2. Put the direct answer near the question. Give the reader the conclusion before background, history, or product positioning. The opening answer should still make sense if it is separated from the rest of the page.
    3. State the scope and conditions. If the correct answer changes by location, product type, audience, or use case, name those branches. A bare “it depends” gives an engine nothing useful to compose.
    4. Add the explanation that makes the answer defensible. Show the mechanism, evidence, limitations, and practical consequences. Concision helps extraction, but unsupported brevity weakens trust.
    5. Make ownership visible. Use an appropriate author or reviewer, maintain current information, and link to credible supporting material. Bing and Gemini both place weight on authority and trust, while ChatGPT-oriented content still needs human oversight to prevent generic or inaccurate answers.
    6. Apply schema that describes what is actually present. FAQ markup belongs with visible questions and answers, HowTo markup with a genuine procedure, and Product markup with real product information. The markup should reinforce the page rather than describe content the reader cannot see.
    7. Connect every useful visual to the answer. A diagram, screenshot, or product image needs descriptive alt text, an informative caption where appropriate, and nearby prose explaining why it matters.

    The result should be valuable even if no AI engine ever selects it. That is an important quality test. AEO works best when machine-readable structure improves a genuinely useful human answer rather than disguising thin content.

    Tune the delivery layer for each answer engine

    Once the shared answer is sound, tune the delivery layer. These changes can usually live on the same page. Separate platform pages are justified only when the underlying audience, offer, location, or intent is genuinely different.

    Bing: remove ambiguity from structure, location, and media

    Bing is the most search-like environment of the three. It rewards pages whose subject and answer are easy to identify, and it can extend that information across Microsoft-connected experiences. Your Bing layer should make the page explicit rather than merely topical.

    • Match headings to recognizable questions. Follow each important question with a short answer before expanding it. Do not make the engine infer the conclusion from several loosely related paragraphs.
    • Use the schema type that matches the page. Bing can use FAQ, How-To, and Product schema to interpret context and support answer-oriented presentation. Mark up the most relevant entity and relationships rather than adding every available type.
    • Resolve local inconsistencies. If the answer depends on geography, keep the business name, location, service area, and contact information accurate in Bing Places and on the site. Include location language where it helps the reader distinguish the applicable answer.
    • Treat images as searchable information. Use a descriptive filename where practical, accurate alt text, relevant metadata, sufficient image quality, and explanatory copy around the image. “Dashboard showing a traffic decline after a site migration” communicates more than “SEO image.”
    • Expose authority signals. A clear byline, current information, credible references, and reputable links pointing to the site make the answer easier to trust.

    The common Bing failure is a page that is semantically broad but operationally unclear. If several headings discuss a subject without answering a recognizable question, restructure the page before adding more markup.

    ChatGPT: write for the next question, not only the first

    ChatGPT is conversational. A response can be refined by the user’s earlier message, preferences, and follow-up question. That means your content needs both a complete initial answer and enough conditional detail to survive a change in context.

    • Use natural question-and-answer language. Write the way an informed customer would ask, while preserving the terminology needed for accuracy. Keyword fragments are poor substitutes for complete questions.
    • Make each answer block self-contained. Include the subject in the answer instead of relying on a distant heading or an unexplained “it.” A passage should remain understandable when quoted without its surrounding introduction.
    • Map likely follow-ups. After the primary answer, cover who the advice applies to, when it changes, what the main limitation is, and what the reader should do next. This gives a conversational engine usable branches rather than repeated versions of the same claim.
    • Separate facts from recommendations. Facts need support. Recommendations need their criteria and tradeoffs. This distinction helps prevent a qualified suggestion from being flattened into a universal rule.
    • Review AI-assisted copy as editorial work. ChatGPT can help phrase conversational questions and draft answer formats, but unchecked AI-generated content can become generic, repetitive, or factually unreliable. Verify claims, remove repetition, and retain accountable human oversight.
    • Design interactive answers with trust in mind. If you operate a chatbot or dynamic FAQ, decide how users will recognize AI involvement, reach the underlying information, and report a wrong answer. Personalization is useful only when the factual core remains stable.

    The common ChatGPT failure is an answer that works for an isolated prompt but collapses under qualification. If your recommendation changes when the user adds “for a local business,” “for an enterprise site,” or another material condition, put that distinction on the page.

    Gemini: make text and visuals answer the same question

    Gemini’s multimodal capabilities make media more than decoration. A useful visual, its surrounding explanation, its caption, and its alt text should all reinforce the same entity and answer.

    • Target detailed intent explicitly. Build sections around specific, long-tail questions instead of expecting one broad page to satisfy every variation. State the narrow answer first, then connect it to the larger topic.
    • Give visuals an explanatory job. Use a diagram to show a process, a screenshot to identify a setting, or a product image to clarify a feature. A generic stock image adds little evidence and creates no meaningful relationship for the engine to interpret.
    • Describe the relationship in text. Tell the reader what to notice in the visual and why it changes the answer. Add relevant captions and alt text rather than leaving the relationship implicit.
    • Use FAQPage markup selectively. Gemini-oriented AEO can benefit from clear FAQ structures, relevant schema, long-tail coverage, and coordinated text and visual information. Repetitive questions added only to expand a schema graph do not improve the underlying answer.
    • Support the answer with trust signals. Research the claim thoroughly, identify responsible authorship, maintain the information, and earn credible references and links. Multimodal presentation does not reduce the need for authority.

    The common Gemini failure is a page with strong prose and disconnected media. If the image could be removed without changing the explanation, it is probably decorative. Either give it an informational role or do not treat it as part of the optimization strategy.

    Diagnose the failure before changing the page

    A specialist inspects a modular web page that passes through two digital gateways but is blocked at a third.

    Seeing your brand in one answer and not another is an observation, not a diagnosis. The missing result could reflect intent mismatch, weak structure, insufficient authority, local inconsistency, poor media context, or normal variation in a conversational session. Changing several layers at once makes it harder to learn which problem mattered.

    1. Create a prompt set from real audience decisions. Include a direct factual question, a detailed long-tail question, a conditional question, and any relevant local or visual request. Add a natural follow-up to test whether the answer holds when context changes.
    2. Keep the comparison controlled. Use the same base wording across engines. Where the interface permits, distinguish a clean session from a contextual follow-up. Conversational context can change the answer, so these are different tests rather than duplicate runs.
    3. Save the actual output. Record the prompt, platform, session conditions, answer, surfaced brand or page, and any incorrect or missing claim. A screenshot alone is not enough if it omits the prompt or preceding context.
    4. Evaluate separate outcomes. Ask whether the engine understood the intent, used accurate facts, applied the right conditions, surfaced your entity, and gave the user a workable next step. A mention with the wrong claim is not a successful result.
    5. Change the closest relevant layer. Fix the answer itself when interpretation is wrong. Fix structure or schema when the answer is hard to extract. Fix local data when geography is missing. Fix captions, alt text, and surrounding prose when media is disconnected. Improve evidence and ownership when the answer lacks authority.
    6. Retest the same prompt pattern. Preserve the previous result so you can compare the output after the change. Do not call a broad rewrite successful merely because a different prompt happened to produce a mention.

    Use failure patterns as diagnostic clues, not proof of an algorithmic rule. If the engine selects the right page but misstates a condition, strengthen that condition in the answer. If it understands the topic but surfaces a competitor, inspect authority, distinctiveness, and evidence. If text is represented accurately but the visual element is ignored, make the connection between the media and the claim explicit.

    Accuracy deserves its own status. A favorable but incorrect answer creates reputation risk because the user may act on a promise you did not make. Mark that result as a failure, correct any ambiguity in your content, and keep a record of the wording that triggered it.

    Turn platform tuning into a repeatable editorial workflow

    Platform-specific AEO becomes manageable when it is part of the content brief rather than a cleanup task after publication. Give each important page a shared fact layer and a short delivery checklist.

    • Shared fact layer: the audience question, direct answer, scope, exceptions, evidence, responsible author, and required update trigger.
    • Bing layer: question-led headings, matching schema, accurate Bing Places information where relevant, and descriptive image fields.
    • ChatGPT layer: natural phrasing, self-contained answer blocks, conditional branches, follow-up coverage, and human verification.
    • Gemini layer: specific long-tail sections, useful visuals, nearby explanations, captions, alt text, and matching structured data.
    • Testing layer: saved prompts, session conditions, observed answers, accuracy findings, surfaced entities, and the next isolated change.

    Keep these layers on the same canonical content asset when the underlying intent is the same. Cloning pages by platform creates duplicated maintenance and increases the chance that facts drift. Add a separate page only when you have a separate question to answer.

    Start with a page that already matters to your audience. Write its direct answer, expose its conditions, align its schema with the visible content, and connect its media to the explanation. Then run the same audience question through Bing, ChatGPT, and Gemini. Let the first clear failure determine the next edit.

    References

  • Voice Search Optimization: A Practical AEO Workflow

    Voice Search Optimization: A Practical AEO Workflow

    When someone asks a voice assistant a question, there may be room for only one spoken response. Your page can be relevant and still lose that response because the useful sentence is buried, the business details conflict, or the answer needs too much context to make sense aloud.

    Treat voice search optimization as an answer-delivery problem. Your job is to make the right response easy to find, extract, verify, and speak while preserving the depth a person needs when they visit the page.

    Key takeaways

    • Start with a complete spoken question and its intent, not an isolated keyword.
    • Place a direct, self-contained answer immediately below the heading that asks the question.
    • Use FAQ or HowTo schema to describe visible content accurately; markup cannot compensate for a weak answer.
    • Treat local voice optimization as an entity-data task before treating it as a copywriting task.
    • Measure whether assistants select your answer. Rankings and engagement metrics are supporting evidence, not direct proof.

    Start with the spoken question, not a short keyword

    A typed query might be a compressed phrase such as clean coffee maker. A spoken query is more likely to express the whole need: How do I clean a coffee maker? Voice searches are often longer, conversational, and framed as questions. That difference affects the answer format as much as the keyword choice.

    Build your initial query set from language people already use. Customer-support messages, sales questions, site-search terms, product reviews, and conversations recorded by customer-facing teams are useful starting points. AnswerThePublic and Semrush can expand that set with question-based variations, but a tool-generated phrase still needs an identifiable intent before it deserves a page.

    For every candidate query, record five things:

    • The spoken question: Write the complete sentence a person might say, including relevant qualifiers such as product type, problem, or location.
    • The immediate intent: Decide whether the person wants a fact, instructions, a comparison, a nearby business, or an action.
    • The answer format: Choose a short explanation, ordered procedure, criteria list, local result, or another format that matches the need.
    • The best destination: Assign the query to an existing page when that page already satisfies the intent. Do not create separate pages for minor wording variations.
    • The basis for the answer: Identify the facts, process knowledge, business data, or other evidence that lets you answer credibly.

    Prioritize questions you can answer clearly and substantiate. A broad query such as What is the best marketing platform? hides the criteria needed to make the answer useful. A narrower question that identifies the user, task, or constraint gives you a better chance of producing a defensible response.

    Do not force every conversational variation into the copy. Select a natural primary question, answer it, and cover meaningful follow-up needs in the surrounding section. Repeating near-identical questions makes a page harder to read without making its central answer clearer.

    Build an answer unit that can stand on its own

    A complete illuminated content module sends a sound pulse to a speaker while fragmented page elements recede into the background.

    A voice assistant may extract only a small part of your page. That part must remain accurate when separated from the paragraphs around it. We call this an answer unit: a descriptive heading, an immediate response, and just enough structure to preserve the meaning.

    Use an answer-first order

    1. Ask the real question in the heading. Use the wording a reader would recognize, but keep it natural rather than mechanically copying every keyword variation.
    2. Answer in the opening sentence. Name the subject directly. Avoid an opening such as It depends or This is the best approach when the extracted sentence would leave the listener wondering what it or this means.
    3. Match the structure to the task. Use ordered steps for a procedure, bullets for criteria, and prose when the explanation depends on cause and effect.
    4. Add constraints immediately after the answer. State the conditions that could change the recommendation before moving into background material.
    5. Provide depth below the extractable response. Examples, evidence, alternatives, troubleshooting, and related questions belong here.

    Short sentences, bullets, and explicit steps make an answer easier for an assistant to interpret. They also help a human reader verify quickly that the page addresses the question.

    Different intents need different answer units:

    • Definition: Begin with [Term] is…, then explain what distinguishes it from nearby concepts.
    • How-to: State the outcome and any essential prerequisite, then present the actions in the order they must happen.
    • Comparison: Name the deciding criterion first, explain which option fits each situation, and support the distinction below.
    • Local service: Identify the business, service, and location plainly before giving directions, contact details, or the next booking action.

    Read the opening answer aloud without the heading. If its subject becomes unclear, rewrite it. Then read the heading and answer together. If they sound repetitive or robotic, keep the meaning but loosen the phrasing. Voice-friendly content should sound natural when spoken; it should not look like a transcript padded with keywords.

    Use schema to clarify content, not manufacture it

    Structured data gives machines explicit labels for content that already exists on the page. FAQ schema fits a genuine set of visible questions and answers. HowTo schema fits a real process with an ordered sequence. Neither type turns vague copy into a reliable response, and neither guarantees that an assistant will select it.

    Before publishing JSON-LD, check that:

    • The marked-up question and answer match what visitors can read on the page.
    • The schema type describes the content accurately rather than the result you hope to obtain.
    • A HowTo sequence follows the same order in the markup and the visible instructions.
    • Required qualifications and warnings appear in both the answer and its structured representation.
    • Content and markup are updated together when a fact, step, product, or business detail changes.
    • The markup still validates after a theme, template, CMS, or plugin change.

    Schema is only one part of the retrieval path. Alexa can draw responses from Amazon’s knowledge graph, third-party skills, and indexed web content. A correctly marked-up web page therefore remains dependent on crawlability, relevance, authority, and the platform’s own answer-selection process.

    Keep the technical objective narrow: help the system identify the question, the answer, and any ordered steps without creating a conflict between the markup and the visible page. If the two versions disagree, fix the publishing workflow rather than deciding which version a machine should trust.

    Make local facts and authority easy to verify

    An unbranded storefront connects to location, phone, hours, and verification symbols with matching check marks.

    A request such as Find a coffee shop near me is not solved by adding the phrase near me throughout a page. The assistant has to connect a service or business category with a location and a trustworthy entity. Conflicting records can undermine an otherwise well-written local page.

    Audit the business data that supports that connection:

    • Keep the Google Business Profile complete and current.
    • Check the business’s presence in Amazon’s relevant local services where applicable.
    • Use a consistent name, address, and phone number across the website and important listings.
    • Verify opening hours, service areas, contact routes, and location details whenever operations change.
    • Include city and service-area language where it helps a visitor understand coverage.
    • Make each location page useful on its own instead of swapping place names into otherwise identical copy.

    Write for local intent, not for the literal phrase. A clear statement such as We provide emergency plumbing services across [city and service area] communicates the entity, service, and geography. An awkward claim such as best emergency plumber near me does not tell the assistant where the business operates or why the claim should be believed.

    Authority also develops across related pages. Create a central resource for the broad subject, publish supporting answers for the recurring subtopics, and link them according to the reader’s next question. High-quality backlinks, accurate citations, and positive reviews provide additional trust signals. The aim is not sheer publishing volume. It is a connected body of content that answers the main question and the follow-up questions consistently.

    Measure answer selection before building an Alexa skill

    Keep a repeatable voice-search log

    Ordinary analytics cannot tell you reliably that a person heard your content from a smart speaker. A spoken answer can satisfy the request without producing a visit. Measure the selection event separately, then use rankings and on-site behavior to interpret what happens around it.

    1. Freeze a manageable set of important spoken questions.
    2. Test Alexa, Siri, and Google Assistant separately. Do not assume that selection on one platform transfers to another.
    3. Record the exact wording, platform, date, response, and any cited or named destination. Include location or account context when it materially affects the result.
    4. Classify each outcome: your answer was selected, another answer was selected, the assistant requested clarification, or no useful answer was returned.
    5. Compare the selected wording with your answer unit and identify the missing fact, structural difference, or authority signal.
    6. Change a single meaningful element, such as the opening answer or procedural structure, and repeat the check under comparable conditions.

    Featured-snippet visibility can be a useful supporting measure because featured snippets often correlate with voice answers. Ahrefs and similar SEO platforms can help track those positions. Time on page, bounce rate, and related engagement metrics can show whether visitors find the expanded page useful, but they do not prove that an assistant selected its answer. Keep those measurements in separate columns so a traffic gain is not mistaken for voice attribution.

    A/B testing can help you compare answer formats when the page receives enough comparable traffic or when your testing process can hold other factors steady. Test a meaningful difference, such as prose versus ordered steps, rather than changing the heading, answer, markup, and page layout simultaneously.

    Use an Alexa skill for a repeatable task, not as a ranking shortcut

    An Alexa skill gives a brand a controlled environment for responses. A fitness business, for example, could provide a requested morning workout through a dedicated skill. This can reduce dependence on web crawling within that skill experience, but it does not cause ordinary web pages to rank for generic voice searches.

    A skill is worth evaluating when users have a repeatable task, the interaction is useful without a screen, the response depends on a maintained workflow or data set, and the business can support the experience after launch. If the only goal is to make an informational page more visible, improve the page, structured data, authority, and entity consistency first.

    For a live skill, Amazon’s Alexa Developer Console can provide usage information that web analytics cannot. Review which requests succeed, where people stop, and which utterances fail to reach the intended response. That evidence should guide the skill’s language model and interaction flow separately from your web AEO work.

    Start with the questions already reaching your support, sales, and site-search channels. Choose a manageable group, assign each one to the right page, rewrite the answer units, align the schema, and verify every relevant business field. Then establish the measurement log before making further changes. A repeatable record of what assistants actually select will give you a more useful roadmap than another round of speculative keyword expansion.

    References

  • AEO Foundations: How to Build Content for Search Features

    AEO Foundations: How to Build Content for Search Features

    Your page can explain a subject accurately and still be passed over for a featured snippet, spoken answer or entity result. The usual problem is not a missing trick. It is that the page makes the answer engine infer too much: which question it answers, where the complete response begins, which entity the facts describe and how the information should be classified.

    Good answer engine optimization removes that ambiguity. You choose the search feature you are preparing for, build a self-contained answer unit, make entities and relationships explicit, add only the structured data the visible content supports, and measure whether the result improves. That sequence is the foundation of AEO.

    Pick the answer surface before you edit the page

    Do not begin with a broad keyword and a blank document. Begin with the job the searcher is trying to complete. A person asking for a definition needs a compact explanation. A person trying to complete a task needs ordered steps. A person searching for an organization, product, place or public figure may need an entity summary rather than another general paragraph.

    This distinction matters because search features present information differently. A featured snippet can extract a paragraph or list. People Also Ask can expose a self-contained response to a follow-up question. A voice assistant needs an answer that makes sense when spoken without the rest of the page. A Knowledge Panel is built around an entity and its relationships, not simply a matching phrase.

    Searcher jobSurface to prepare forUseful answer shape
    Get one fact or definitionFeatured snippet or spoken answerA direct paragraph that names the subject and answers immediately
    Complete a taskStep-based answerAn ordered list with one action per step
    Understand a person, organization, place or productKnowledge Panel or entity resultExplicit facts, attributes and relationships tied to the named entity
    Investigate the next questionPeople Also AskA question heading followed by a response that stands on its own
    Find an option in a specific areaVoice or local answerConversational wording with an accurate place qualifier

    These are editorial targets, not promises that a particular feature will appear. Their value is that they force you to decide what a successful answer looks like before you add more copy.

    Entity-oriented features require a different mental model from keyword matching. Google introduced the Knowledge Graph in 2012. It represents real-world things as connected entities, with attributes and relationships that help distinguish one meaning from another. Its basic workflow includes entity extraction, relationship mapping and knowledge integration. If a query could refer to several things, repeating the query phrase will not resolve the ambiguity. Clear names, types and relationships will.

    Write a one-page intent brief before revising the content. It only needs five fields:

    • Primary question: the complete question, written as the reader would ask it.
    • Required qualifier: the audience, location, product, condition or context without which the answer would be misleading.
    • Target surface: paragraph snippet, list, table, follow-up answer, spoken response or entity result.
    • Answer shape: the shortest format that can still give a complete and accurate response.
    • Next question: the useful follow-up that justifies the reader continuing beyond the extracted answer.

    If you cannot complete those fields, you do not yet have an AEO writing problem. You have an intent problem. Resolve that before changing headings or adding schema.

    Build a self-contained answer before adding depth

    A compact group of interlocking blocks forms a complete unit in front of a longer pathway of supporting layers.

    An answer engine should not have to assemble the response from five paragraphs. Put a descriptive question or task heading on the page, then answer it immediately below. The first sentence should state the conclusion. The next sentences can add the minimum qualification, condition or definition needed to prevent a misleading extraction.

    A 50- to 100-word answer is a useful editorial starting range for many straightforward questions. It is not a platform rule, and some answers need fewer or more words. Use the range as a forcing function: if the response cannot become clear within that space, the question may be too broad or the essential answer may still be buried.

    Example answer unit: Answer engine optimization, or AEO, is the practice of shaping web content so search and assistant systems can identify a question, understand the entities involved and extract a complete response. It combines intent-focused writing, an appropriate answer format, consistent facts and relevant structured data. AEO complements the technical and authority work that makes a page discoverable.

    That paragraph can sit at the top of a much deeper page. AEO favors brevity at the answer level, not shallowness at the page level. Once the direct response is complete, you can explain exceptions, evidence, implementation and related decisions. The short answer earns attention; the supporting material earns trust and helps the reader act.

    Use this sequence for each important question:

    1. Name the question. Use a natural heading that reflects the actual intent, not a fragment built only around a keyword.
    2. Lead with the answer. Do not open with background, history or a promise that the answer is coming.
    3. Repeat the subject where necessary. A sentence such as “It improves visibility” may lose its meaning when extracted. Name what “it” refers to.
    4. Add the decisive qualifier. Include the condition that changes the answer, especially when location, audience or content type matters.
    5. Choose the native format. Use prose for definitions and explanations, ordered lists for procedures, bullets for criteria and tables only for genuine comparisons.
    6. Expand below the answer. Add the reasoning, examples and next action without rewriting the same response several ways.

    Conversational language is particularly important for spoken and question-based searches. That does not mean filling every heading with awkward phrases such as “what is the best way to.” It means using the words a person would understand when hearing the answer once. Replace internal abbreviations, unexplained acronyms and vague category labels with plain terms.

    Do not manufacture an FAQ section merely to repeat facts already covered on the page. Split material into separate questions only when each heading represents a distinct intent and each response remains useful outside the surrounding section. Ten near-identical questions create ambiguity rather than coverage.

    Make entities and relationships explicit to people and machines

    Answer extraction works at the passage level, but entity understanding works across facts and relationships. A system needs to know whether a name refers to a company, person, product, place, concept or event. It also needs to connect attributes to the correct subject.

    Review the page as if the reader arrived without your site navigation, brand knowledge or previous paragraph. Then make these relationships explicit:

    • Use the entity’s full, consistent name near the beginning of the page.
    • State what kind of thing it is. A name alone does not establish whether it is an organization, service, method or product.
    • Attach each important fact to a named subject. Avoid a chain of pronouns when several entities appear in the same section.
    • Explain the relationship between entities in plain language, such as who created something, which organization operates it or which place an event belongs to.
    • Distinguish similarly named entities with an accurate qualifier instead of relying on capitalization or context clues.
    • Keep foundational facts consistent across the page and other important pages on the same site. Contradictory names, descriptions or relationships make the entity harder to interpret.

    This is not an invitation to repeat a brand name in every sentence. The goal is referential clarity. A reader should always know which entity owns the attribute or performs the action. If that is clear to the reader, you have also made the page easier for a machine to parse.

    Use structured data as a label, not a substitute for content

    Structured data describes visible information in a machine-readable form. JSON-LD can identify a content type, its properties and the entities it concerns without forcing those labels into the prose. Useful Schema.org types depend on the material: Article, FAQPage, HowTo, Recipe, Product and Event serve different purposes.

    Choose the closest accurate type. A tutorial is not automatically a HowTo merely because it contains advice. A page is not an FAQPage merely because question marks appear in its headings. The markup must describe what the reader can actually see, and every value should agree with the visible name, description, steps, dates or other facts.

    A reliable implementation sequence is:

    1. Identify the page’s primary content type and main entity.
    2. Select the most specific schema type that truthfully describes that content.
    3. Add only properties for information that is present and accurate on the page.
    4. Place the JSON-LD in the page head or body without changing the visible answer.
    5. Check that names, URLs, dates and relationships match the rendered page.
    6. Test the markup with Google’s Rich Results Test and resolve errors before publication.
    7. Recheck the markup whenever the visible facts or page purpose change.

    Passing a validator confirms that the markup can be parsed. It does not confirm that the content is correct, that the schema type is appropriate or that a search feature will select the page. Adding more unrelated schema will not repair a vague answer. Fix the content and entity relationships first, then use markup to describe them.

    Voice-oriented pages need the same discipline. Use a complete, natural response; include a location only when the question has local intent; and make the page usable on a phone. Conversational phrasing and mobile usability support question-based and voice-search behavior, but neither justifies adding a false local qualifier or rewriting every sentence as a question.

    Diagnose the missing feature instead of adding more copy

    A magnifying lens reveals an empty connector slot in a modular search-result mechanism beside unused stacks of blank cards.

    AEO improvement should be a controlled editing process. Record the page, target question, intended feature, current answer block and current search performance before you revise anything. Change the smallest element that addresses the observed failure. If you rewrite the answer, change the heading, replace the page structure and add several schema types at once, you will not know which decision helped or hurt.

    What you observeLikely communication problemNext edit to test
    The page receives relevant impressions but no direct-answer visibilityThe response is buried, incomplete or split across sectionsPut one complete answer immediately below a specific question heading
    The page appears for a broader or different questionThe heading or opening answer lacks a decisive qualifierAdd the audience, location, entity or condition that changes the meaning
    The answer is understandable on the page but confusing when isolatedIt relies on pronouns, prior definitions or surrounding contextRepeat the subject and include the minimum context needed to stand alone
    The structured data validates but no enhancement appearsValid syntax has been mistaken for guaranteed selectionVerify that the type matches the visible content; do not add unrelated markup
    Important brand or product facts are interpreted inconsistentlyNames, entity types or relationships vary between sections or pagesChoose canonical wording and correct the conflicting high-value pages
    A local or spoken query underperformsThe response sounds written rather than spoken, lacks an accurate place qualifier or is difficult to use on mobileRewrite the answer for one-pass comprehension and fix the specific local or mobile gap

    Use Google Search Console to monitor impressions and clicks for the relevant pages and queries. Record observed appearances in featured snippets or other answer surfaces separately, then compare them with the content change you made. Monitoring impressions, clicks and answer-feature visibility matters because validation alone cannot tell you whether the page is communicating the answer more effectively.

    Do not treat every impression increase as proof of AEO success. Check whether the page is appearing for the intended question and whether the extracted wording remains accurate. A larger audience for the wrong intent is not an improvement. If visibility rises while clicks do not, inspect the result itself and make the next step on the page genuinely useful; do not weaken the answer simply to withhold information.

    Key takeaways

    The foundations of answer engine optimization are a matched intent, an extractable response, clear entities, truthful structured data and disciplined measurement.

    • Choose the intended search feature before choosing the content format.
    • Place a direct, self-contained answer immediately below a specific heading.
    • Use paragraphs for definitions, ordered lists for procedures and tables for real comparisons.
    • Name entities, attributes and relationships clearly enough to survive extraction from the page.
    • Add the most specific accurate schema type, and keep its values aligned with visible content.
    • Measure one controlled change at a time using the target query and page, not sitewide traffic alone.

    For your next revision, choose one page built around a recurring question. Write the question in full, replace the opening response with a complete 50- to 100-word answer, check every important entity name, add only matching schema and record the baseline before publishing. Once that page has a clear question-to-answer path, you have a repeatable AEO process rather than a collection of search-feature guesses.

    References

  • Marca 360 Digital Marketing Services: How to Scope the Work

    Marca 360 Digital Marketing Services: How to Scope the Work

    You are probably not looking for seven disconnected marketing services. You are looking for a specific business problem to go away: too few qualified visitors, weak conversion, inconsistent follow-up, or no reliable way to tell which campaigns produce customers.

    That distinction matters when you evaluate Marca. A 360 digital marketing package can simplify execution, but breadth alone does not create a strategy. You still need one customer journey, a clear role for every channel, and reporting that connects activity to a commercial outcome.

    What Marca’s 360 service range actually gives you

    Marca places website development, SEO, paid media, social media, content, branding, email, WhatsApp campaigns, and analytics under one agency relationship. That can reduce fragmented planning, but only if every service has a defined job.

    • Website development: Your website is the destination where attention should become an inquiry, booking, purchase, or other meaningful action. Define the primary call to action, mobile journey, required pages, forms, tracking, and launch acceptance criteria before design begins.
    • SEO: Search optimization captures existing demand. The scope should identify target topics, relevant pages, technical problems, planned content changes, implementation responsibility, and the conversion each search page should support.
    • Google Ads and paid social: Paid campaigns can bring controlled traffic to a specific offer. Require an explicit audience, message, landing page, conversion event, budget boundary, and rule for pausing or changing an underperforming campaign.
    • Organic and paid social media: These are different workstreams. Organic publishing can build familiarity and demonstrate what the business does; paid social buys distribution. Ask Marca to separate the deliverables, objectives, and reporting for each.
    • Content and branding: Blogs, product descriptions, website copy, logos, and marketing materials should express the same positioning. Approve the core message, supporting proof, terminology, visual rules, and voice before producing content at scale.
    • Email and WhatsApp: These channels are most useful when the next step is clear. Define who receives each message, what triggers it, what action it requests, how consent and opt-outs are handled, and who responds when a recipient replies.
    • Analytics and reporting: A report should help you make a decision. Agree on conversion definitions, data sources, campaign naming, responsible owners, and the questions the monthly report must answer.

    You do not need to activate every service at once. If the website cannot convert a qualified visitor, buying more traffic amplifies the wrong part of the system. If leads already convert but too few people discover the offer, rebuilding the brand may be less urgent than improving SEO or running a tightly scoped paid campaign.

    Start with the bottleneck, not the service menu

    A hand points to a blocked narrow section of a wooden journey path where colored tokens have accumulated.

    Choose the first workstream by diagnosing where the customer journey is breaking. The following table is a practical starting point, not a substitute for inspecting your analytics, inquiries, sales records, and customer feedback.

    What you observeLikely bottleneckFirst priorityWhat to delay
    Relevant visitors arrive, but few take the next stepConversionWebsite message, offer, call to action, form, and conversion trackingAdditional traffic campaigns
    The offer converts when people see it, but qualified traffic is scarceDiscoverySEO around existing demand or a focused paid campaignA broad content calendar with no distribution plan
    Leads arrive, but follow-up is slow or inconsistentLead handlingEmail or WhatsApp workflow, response ownership, and lead-status trackingMore top-of-funnel spend
    The website, ads, and social profiles describe the business differentlyPositioningBrand message, offer language, proof points, and visual consistencyLarge-scale content production
    You cannot tell which activity contributes to inquiries or salesMeasurementAnalytics setup, conversion definitions, campaign naming, and reportingScaling media budgets

    Do not diagnose the bottleneck from surface metrics alone. High traffic can conceal poor relevance. Low engagement on a social post does not prove that the wider campaign failed. A form submission is not necessarily a qualified lead. Follow the path from the original visit through the business outcome you actually value.

    SEO and paid media also solve different timing and control problems. SEO depends on improving pages and earning search visibility, while paid media can start delivering traffic once a campaign is approved and active. If you use paid traffic for faster learning, send it to the same offer and conversion path you intend to improve elsewhere. Otherwise, the campaign produces data about a temporary experience rather than the journey you plan to keep.

    Build one customer journey across every selected channel

    The strongest reason to use a 360 agency is coordination. That advantage disappears when the SEO team targets one audience, the ad team promotes another offer, social media uses different language, and the website gives every visitor the same generic homepage.

    1. Name one commercial outcome. Use a business action such as a qualified inquiry, appointment request, purchase, or accepted sales opportunity. Do not use impressions, followers, or raw traffic as the main outcome.
    2. Choose the audience and offer. State who the campaign is for, what problem they are trying to solve, what you want them to consider, and why the offer is credible.
    3. Design the destination. Decide whether the user should reach a service page, product page, booking flow, lead form, or another purpose-built destination. The page should continue the promise made in the ad, search result, social post, or message.
    4. Assign a role to each channel. SEO can capture search demand, paid media can test or distribute an offer, social content can build recognition and trust, the website can convert interest, and email or WhatsApp can support follow-up. Remove any channel that does not have a distinct role.
    5. Define the handoffs. Specify what happens after a form submission, message, call, or purchase. Name the responsible person, required information, response process, and lead-status updates that must reach the reporting system.
    6. Agree on the measurement chain. Track the channel interaction, landing-page behavior, conversion event, lead quality, and final business result wherever your systems make that possible. Document any gap instead of pretending the attribution is complete.

    Consider a real estate agent promoting property valuations. A paid ad could introduce the offer, an SEO page could answer valuation questions, social content could demonstrate local knowledge, and a landing page could collect the request. Email or WhatsApp could acknowledge the inquiry and explain the next step. The monthly report should then distinguish ad clicks, page visits, completed requests, qualified conversations, and resulting appointments. Each component supports the same journey; none is treated as an isolated campaign.

    This also gives you a clean way to reject unnecessary work. If a proposed channel has no defined audience, message, destination, handoff, or measurable action, it is not yet ready for execution.

    Make the SEO brief specific enough for AI search

    Marca’s SEO scope includes keyword strategy, technical fixes, and content refinement. Those are sensible work areas, but they are categories rather than an implementation brief. If visibility in AI-generated answers matters to you, ask how the work will make your business and its claims clear, consistent, retrievable, and supportable.

    • Map questions to pages: Each important customer question should have a suitable destination. Decide whether an existing page will be improved or a new page is genuinely necessary.
    • Write for a specific answer: A content brief should state the reader’s question, the direct answer, the supporting explanation, the evidence required, and the action the page should lead to. A keyword list by itself is not a content strategy.
    • Keep business facts consistent: Use the same business name, service definitions, locations, qualifications, policies, and other material facts wherever they appear. Resolve contradictions before adding more content.
    • Establish technical accessibility: Confirm that important pages can be crawled and indexed and that redirects, canonical signals, internal links, and page templates do not undermine the intended content.
    • Use structured data carefully: If JSON-LD or other schema work is included, require the chosen types and properties to match the visible page and the entity being described. Structured data clarifies content; it does not replace missing or weak content.
    • Make claims supportable: Identify where prices, credentials, comparisons, results, or other consequential claims come from. Unsupported promotional language is less useful to readers and harder for an answer system to cite confidently.
    • Define AI visibility reporting: Decide which prompts, topics, brand mentions, cited pages, referral sources, and downstream conversions will be observed. Keep observed visibility separate from estimates or guarantees.

    Ask for a sample SEO content brief before approving a large production schedule. It should show the target question, intended reader, search intent, direct answer, supporting sections, relevant entities, internal links, evidence requirements, structured-data candidate, and conversion goal. If the deliverable is merely described as “AI optimized,” ask what will actually change on the page and how that change will be verified.

    No responsible agency can reduce AI visibility to a guaranteed placement. Search engines and frontier models decide what to retrieve and present. The agency’s controllable work is to improve technical access, factual clarity, content usefulness, entity consistency, and measurement.

    Set accountability before you approve a broad retainer

    Two professionals arrange blank responsibility tiles connected to a central brass outcome marker on a conference table.

    A broad package can hide ambiguity unless the proposal separates outputs, outcomes, responsibilities, and dependencies. Resolve the following points before work begins.

    • Baseline: What is currently known about traffic, leads, sales, conversion paths, rankings, campaign performance, and data quality? Which gaps must be fixed before improvement can be measured?
    • Deliverables: Which pages, campaigns, content assets, designs, technical changes, messages, and reports will be produced? What is explicitly outside the scope?
    • Sequence: Which dependency comes first? For example, approving the offer and landing page should normally precede sending paid traffic to it.
    • Access and ownership: Who owns the domain, website, analytics property, tag-management setup, advertising accounts, audiences, creative files, content, and reporting dashboards? Your business should retain appropriate administrative access to its core assets.
    • Budget boundaries: Separate agency fees, advertising spend, software costs, production costs, and optional work. State who may approve additional spending.
    • Approval process: Name the people responsible for factual review, brand review, technical approval, campaign approval, and final publication. Define what happens when an approval is late.
    • Quality assurance: Decide who checks forms, links, tracking, mobile layouts, conversion events, copy accuracy, structured data, and campaign destinations before launch.
    • Reporting: Marca includes monthly reporting on campaign performance, visitors, and conversions. Ask the report to explain what changed, what effect was observed, what remains uncertain, and what decision is recommended next.
    • Lead quality: Define what makes an inquiry relevant or qualified. An increase in form submissions means little if the submissions cannot become customers.
    • Exit and portability: Confirm how account access, files, creative assets, data, documentation, and unfinished work will be handed over if the engagement ends.

    When reviewing case studies or performance claims, ask for the starting baseline, measurement period, conversion definition, channels involved, budget conditions, and the agency’s actual contribution. A large percentage without that context is not a forecast for your business.

    Key takeaways

    • A 360 agency should manage one connected customer journey, not a collection of unrelated channel calendars.
    • Select the first service by locating the current bottleneck: discovery, conversion, follow-up, positioning, or measurement.
    • Give every channel a defined audience, message, destination, handoff, and business action.
    • Expand an ordinary SEO scope with answer-focused briefs, consistent entity facts, technical accessibility, supportable claims, and accurate JSON-LD where relevant.
    • Separate deliverables from outcomes and agency fees from advertising, software, and production costs.
    • Retain appropriate ownership and administrative access to your website, accounts, data, and creative assets.

    Before you contact Marca, write a one-page brief containing your commercial outcome, audience, offer, current bottleneck, desired conversion, known baseline, available budget, and required reporting. Ask the agency to map each proposed service to that brief. If a service cannot be connected to the customer journey or a decision you need to make, narrow the scope before you sign.

    References


  • How to Apply for Search Engine Land’s 2026 Contributor Team

    How to Apply for Search Engine Land’s 2026 Contributor Team

    You don’t need to prove that you know everything about search marketing. You need to show that you can turn substantial hands-on experience into clear, original guidance for practitioners. That is a different test, and a long career history alone won’t pass it.

    The 2026 contributor intake covers SEO, generative AI, PPC, and data and analytics. If you are considering applying, use this guide to choose your strongest lane, assemble credible evidence, develop useful pitches, and decide whether a volunteer contributor role supports your goals.

    Key takeaways

    • You need at least five years of hands-on experience, but the application still has to show what you learned from doing the work.
    • Choose one primary subject area. A precise position is more credible than claiming equal authority across SEO, AI, PPC, and analytics.
    • Prepare several decision-focused pitches, proof from real work, relevant writing samples, a concise bio, and a list of potential conflicts before opening the application form.
    • The role is volunteer-based. Evaluate the time commitment against realistic career value rather than treating visibility as guaranteed compensation.
    • If you are applying as an AI SEO or GEO expert, distinguish observation from hypothesis and citations from traffic, conversions, or conventional rankings.

    Decide whether the contributor role fits your career

    The experience threshold is straightforward: applicants should have at least five years of hands-on work. The important phrase is “hands-on.” Time spent adjacent to search marketing is not the same as making decisions, implementing changes, reading results, correcting mistakes, and explaining what happened.

    Build a quick experience inventory before you apply. List the programs, campaigns, migrations, investigations, experiments, or measurement systems in which you had direct responsibility. For each one, note the decision you owned, the constraint you faced, the evidence you used, and what another practitioner could learn from it. If that inventory produces only job titles and broad responsibilities, you need more concrete proof.

    You should also evaluate the economics honestly. This is a volunteer position, not a paid freelance assignment. The possible return includes professional visibility, reputation building, network growth, a stronger resume or LinkedIn profile, and potential career momentum. Those outcomes are possible, not automatic.

    The opportunity does have meaningful reach: Search Engine Land has operated for more than two decades and reports an audience of more than one million marketing professionals each month. That makes the platform relevant, but it does not tell you how much recognition, referral traffic, or commercial value any individual contribution will generate.

    The role is more likely to fit if you want to teach practitioners, can produce original material consistently, and have permission to discuss suitably anonymized work. It is a weaker fit if your main goal is immediate lead generation, a promotional link, or a place to republish material created for another channel. Editorial contribution and demand generation can overlap, but they are not the same job.

    Before committing, decide what would make the unpaid time worthwhile for you. A useful outcome might be a body of respected work, a clearer public specialization, stronger industry relationships, or a credential that supports your next role. If you cannot name the outcome, you cannot judge whether the commitment is working.

    Turn your expertise into a focused application

    A marketing specialist selects campaign evidence, a webpage mockup, and blank idea cards for a focused application portfolio.

    The recruitment areas are broad: SEO; generative AI, including GEO and AI SEO; PPC across paid search, paid social, display, and video; and data and analytics. Do not respond to that breadth by presenting yourself as an expert in all of it. Choose a primary lane in which your evidence is deepest, then mention a secondary area only when the connection is useful.

    Choose the lane where you can explain decisions

    • SEO: Identify the types of decisions you can unpack, such as technical remediation, migrations, content systems, international search, local visibility, or enterprise implementation. Name the constraints and failure modes you understand, not merely the deliverables you have produced.
    • Generative AI, GEO, or AI SEO: Show that you can define what was measured, which system or interface was involved, when the observation was made, and what remains uncertain. Avoid presenting every change in an AI answer as an optimization win.
    • PPC: Establish which paid channels you have managed and which decisions you can teach. Budget allocation, query quality, creative testing, automation controls, audience strategy, and measurement are more informative than a generic claim that you improved performance.
    • Data and analytics: Explain how you have dealt with collection gaps, attribution choices, reporting definitions, or competing interpretations. Strong analytics writing connects the measurement problem to the decision it changed.

    Your positioning statement should connect expertise to a reader problem. “I am passionate about the future of AI” does not give an editor much to assess. A stronger version would be: “I help enterprise content teams evaluate changes in AI search visibility, including what their measurements can and cannot prove.” The second sentence defines the audience, decision, and evidentiary boundary.

    Prepare an evidence packet before you open the form

    The following materials are preparation assets, not a claim about mandatory form fields. Creating them in advance keeps your application specific and consistent.

    • A concise position: State whom you help, which problem you understand, and what kind of decisions you can explain.
    • Several developed pitches: Give each idea a defined reader, problem, angle, and practical payoff. Avoid submitting a list of keywords.
    • A proof inventory: Capture situations in which your work changed a decision, exposed a limitation, or corrected a common assumption. Use information you are authorized to disclose.
    • Relevant writing samples: Choose material that demonstrates analysis and teaching, not merely subject familiarity. If your strongest work is internal or confidential, create a clean sample that does not expose protected information.
    • A short professional bio: Include the experience that establishes authority for your chosen lane. Remove unrelated career history.
    • A conflict map: Identify employers, clients, products, investments, partnerships, or commercial relationships that could affect what you cover. Early disclosure is easier to manage than a credibility problem after publication.

    A useful pitch answers a decision question. Start with what the reader must decide, identify the mechanism you will explain, name the evidence available to you, and state the boundary of the conclusion. That structure produces ideas such as how to interpret incomplete AI referral data, how to validate a site migration when signals disagree, or how to evaluate paid-search automation without mistaking reduced control for improved performance.

    Avoid pitches such as “the future of SEO” or “why AI matters.” They are subjects, not editorial angles. A contributor earns attention by resolving a specific uncertainty that working marketers encounter.

    Demonstrate editorial judgment, especially in AI SEO

    An editor compares abstract AI-generated material with multiple sources and flags a questionable passage at a computer workstation.

    Operational experience gets you into consideration. Editorial judgment shows whether readers can rely on you. Your application should make clear that you can separate what you observed, what you infer, and what you recommend.

    • Lead with the decision: Explain what a practitioner should do differently after reading your work.
    • Show the mechanism: Connect the recommendation to the process, constraint, or measurement issue behind it.
    • Carry the limitations: Say when an observation applies only to a particular platform, interface, market, account type, or implementation.
    • Protect confidential information: Do not assume that removing a client’s name makes a case unidentifiable. Obtain permission where necessary or use a reproducible method instead of protected results.
    • Separate education from promotion: A product can appear when it is necessary to understand the method. It should not become the unstated answer to every problem.

    This discipline matters even more in generative search. AI outputs can vary by system, interface, prompt, context, location, account state, and time. If your idea depends on an observed output, preserve those conditions in your notes and avoid implying that one response represents a permanent ranking.

    Keep the outcome categories separate as well. Being mentioned in an AI response, receiving a citation, earning referral traffic, influencing a branded search, and producing a conversion are not interchangeable results. An application that treats them as one metric signals weak measurement judgment.

    The same caution applies to JSON-LD and schema claims. If you want to cover structured data in an AI SEO pitch, define the mechanism you can support and the outcome you actually observed. Do not promise that adding markup will make a brand appear in a frontier model unless you have evidence capable of supporting that causal claim.

    You do not need a dramatic result for every idea. A failed implementation, ambiguous experiment, or measurement limitation can produce excellent practitioner guidance when you explain why the expected result did not materialize. That is often more useful than presenting a clean success story with no account of the confounding factors.

    Submit carefully and clarify the working terms

    Use the 2026 contributor application once your positioning, pitches, proof, samples, and disclosures are ready. Tailor every answer to this editorial audience. Copy your completed responses into your own records before submitting so you can refer to the same claims and pitches later.

    Selected applicants will be contacted directly by email. No response window is supplied in the available recruitment details, so do not invent one or interpret a short period of silence as a decision. Monitor the address you submitted, including its spam or filtered folders.

    If you are invited to proceed, clarify the operating terms before accepting recurring work:

    • Expected publishing cadence, typical deadlines, and whether contributors pitch their own ideas or receive assignments.
    • How editing, fact-checking, headline changes, corrections, and final approval are handled.
    • Originality, exclusivity, republication, and content-rights requirements.
    • Policies for conflicts of interest, commercial relationships, client examples, and AI-assisted work.
    • What may appear in your author biography and which external links, if any, are permitted.
    • Whether contributors receive performance information that can help them improve later work.
    • How either side can pause or end the arrangement if availability or editorial fit changes.

    These questions are not resistance. They protect the time of both contributor and editor, especially when the work is unpaid. A clear cadence and rights policy also let you decide whether the role can coexist with your employer, clients, and existing publishing commitments.

    Your next move is concrete: write one positioning sentence, develop your strongest pitches, gather proof and writing samples, and disclose anything that could affect your independence. If you can teach from real work without turning the contribution into an advertisement, make that unmistakable in the application.

    References


  • Revolutionizing Shopping: ChatGPT & Perplexity’s AI Innovations

    Revolutionizing Shopping: ChatGPT & Perplexity’s AI Innovations

    AI shopping ecommerce

    In the past day, I’ve noticed that ChatGPT and Perplexity have launched new AI-driven shopping tools designed to create more intuitive and personalized shopping experiences. These innovations focus on helping us effortlessly discover, compare, and purchase items using conversational queries tailored to our preferences and history.

    ChatGPT

    Shopping Research. OpenAI is revolutionizing the way I shop by transforming ChatGPT into my personal product researcher.

    When I describe what I need, like a “quiet cordless vacuum” or a “gift for my art-obsessed niece,” ChatGPT kicks in to ask clarifying questions and pulls relevant data from the web. In no time, I receive a customized buyer’s guide.

    Using my preferences and previous interactions, ChatGPT updates recommendations as I react to items with “More like this” or “Not interested.” It’s a truly adaptive experience.

    This feature uses a specialized GPT-5 mini model that’s optimized for shopping and sources reliable information from trusted sites.

    It’s available now for both free and paid ChatGPT users, on web and mobile, with extensive use available through the holiday season.

    Next up, I’ll be able to purchase items directly within ChatGPT thanks to upcoming Instant Checkout integrations.

    Perplexity

    New Shopping Experience. Perplexity has rolled out a free, U.S.-based shopping feature centered around enhancing my shopping without replacing the experience.

    I simply initiate searches with conversations like “best winter jacket for San Francisco ferry commute,” and Perplexity maintains context even when my needs shift.

    It remembers my style and preferences, adjusting future product suggestions accordingly, all while avoiding endless scrolling by providing clear, intent-driven product cards.

    Purchases are quick and seamless, thanks to a partnership with PayPal, while still allowing merchants to manage customer relationships.

    Retailers might pay attention to this, as conversational shopping reportedly increases purchase intent, although some studies caution that AI-driven conversions aren’t always more successful than traditional methods.

    This innovative experience is available now on desktop and web, with mobile apps arriving soon.

    AI shopping assistants like ChatGPT and Perplexity are changing the ecommerce landscape. ChatGPT focuses on deep research while Perplexity offers smooth discovery and integrated checkout, both striving to be our go-to platforms by providing personal and custom shopping recommendations.

    Read more about these announcements:

    ChatGPT: Shopping Research
    Perplexity: Shopping That Puts You First


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot