Tag: Content Optimization

  • How to Build a Content Strategy for Google’s AI Search

    How to Build a Content Strategy for Google’s AI Search

    Your pages can still rank while playing a smaller role in discovery when Google resolves more of a search inside an AI-generated response. Publishing more generic articles won’t solve that problem. It gives you more inventory, not more authority.

    You need one content system that works whether Google presents a familiar result, summarizes an answer, or sends the searcher to a source for more depth. Build that system around real audience decisions, original proof, self-contained answer passages, consistent entities, and measurement that reaches beyond rankings.

    Build for durable search jobs, not a temporary interface

    Google’s AI search products will keep changing. The useful planning assumption is not that a particular layout will win. It is that Google will continue experimenting with how it retrieves, combines, and presents information.

    That experimentation may feel unusually fast because Google is accelerating after a period of caution. Sergey Brin has acknowledged that the company underinvested after its Transformer work and hesitated to bring chatbots to users. His admission isn’t a ranking signal, but it is a useful warning against building an annual content plan around the current appearance of a search result.

    Build each important page to perform four durable jobs:

    • Match a real need: Address a question attached to a decision, task, or problem instead of merely repeating a keyword.
    • Resolve the question: Give the reader a usable answer without forcing them through a long preamble.
    • Support the answer: Show why the claim should be trusted through evidence, expertise, attribution, and explicit limitations.
    • Advance the journey: Help the reader compare, verify, implement, or choose the next appropriate step.

    This model supports conventional SEO and AI retrieval at the same time. A useful page should be discoverable as a document, understandable as a set of entities and claims, and safe to summarize without losing the qualification that makes its advice accurate.

    Key takeaways

    • Organize content around audience decisions rather than keyword variations.
    • Require original proof before a topic enters production.
    • Write important answers as passages that retain their meaning when read alone.
    • Keep visible copy, author information, internal links, and JSON-LD consistent.
    • Measure accurate representation, qualified engagement, and business outcomes alongside rankings and traffic.

    Turn audience demand into a decision-based topic architecture
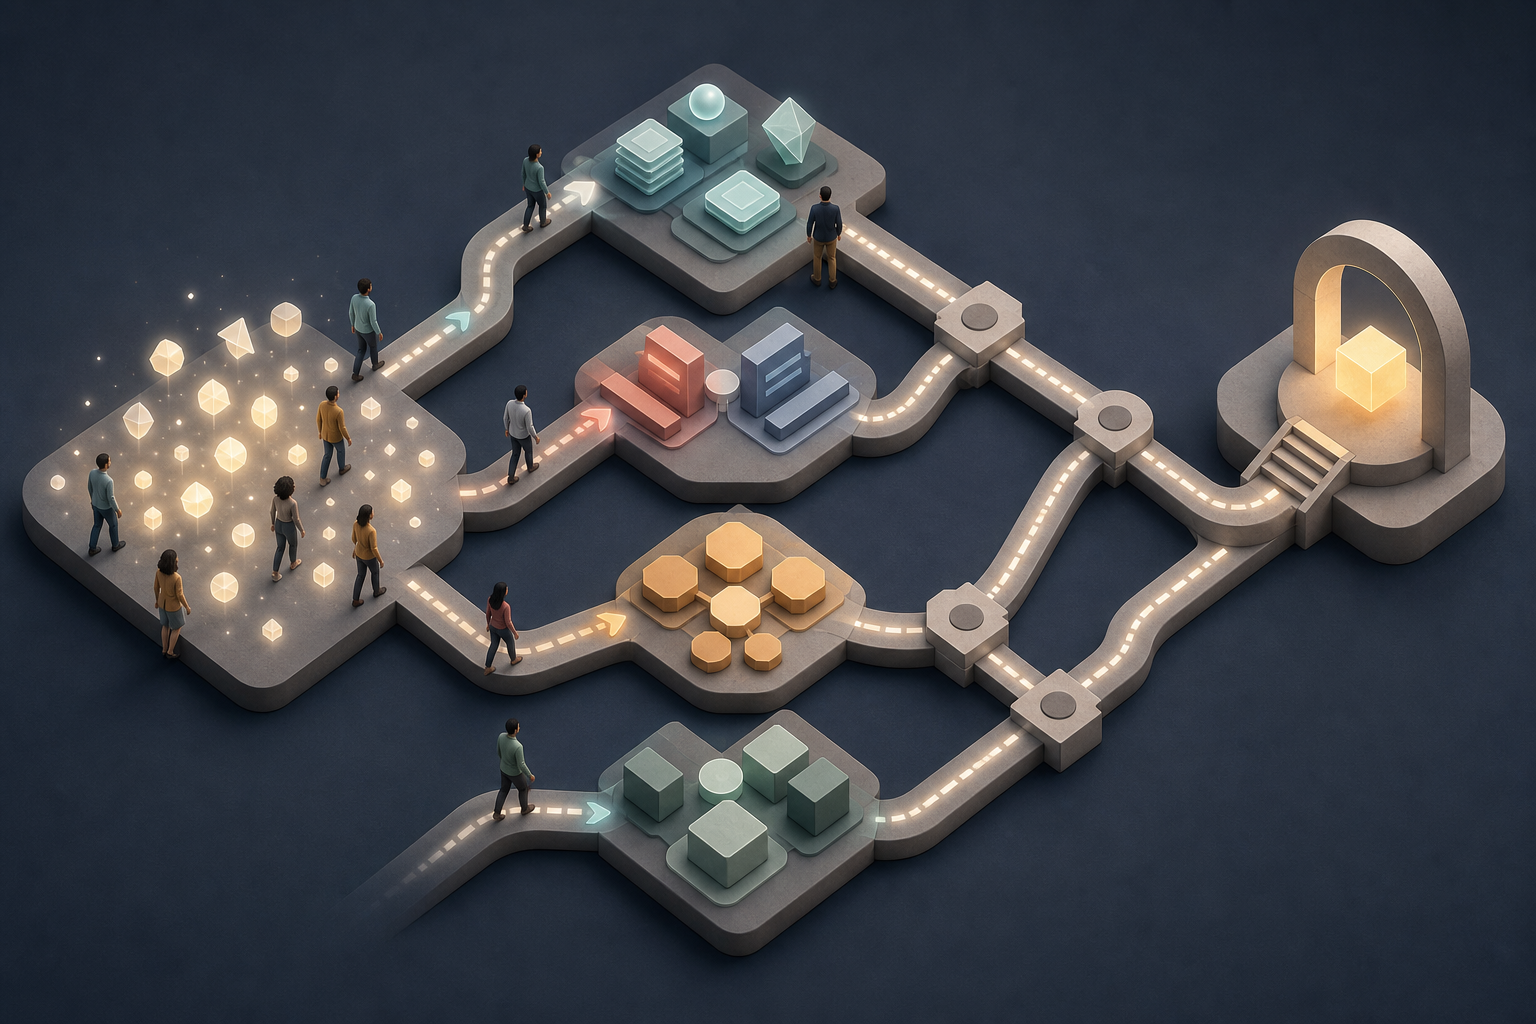
    People follow branching paths through interconnected content clusters toward a shared decision point.

    A keyword can reveal phrasing without telling you why the search matters. Someone asking how AI search affects content may be defending a budget, repairing a traffic decline, choosing software, or redesigning an editorial workflow. Those situations require different evidence and different next steps, even when the vocabulary overlaps.

    Build your topic map before you build your calendar:

    1. Name the decision. Replace a broad topic such as “AI search optimization” with the decision the page must help someone make, such as whether to consolidate overlapping explainers or where to add expert evidence.
    2. Capture the reader’s context. Record what they already know, what they may misunderstand, what is at stake, and what would block them from acting.
    3. Collect real audience language. Use customer interviews, support and sales questions, on-site searches, community discussions, and relevant social conversations. Treat AI-generated audience ideas as hypotheses to validate, not as proof of demand.
    4. Group questions by job. Separate learning, evaluation, implementation, and troubleshooting. A reader trying to understand a concept should not have to navigate a page written mainly for someone choosing a vendor.
    5. Assign a page role. Decide whether the need calls for a central explainer, a comparison, an implementation resource, an evidence page, or a focused answer to a narrow obstacle.
    6. Define proof and maintenance. State what evidence the page needs, who can verify it, and which change in the market, product, or underlying facts should trigger a review.

    Use a simple consolidation rule: if two queries require substantially the same answer, evidence, and next action, they probably belong on one strong page. If they represent different decisions or require materially different proof, separate them. This prevents thin pages from competing with one another while keeping genuinely distinct needs visible.

    Every content brief should then answer these questions before a draft begins:

    • Who is making the decision, and in what situation?
    • What exact question must the page resolve?
    • What can this page contribute that a competent generic answer cannot?
    • Which claims require evidence or qualification?
    • Which existing page should own the broader topic?
    • What should the reader be able to do after reading?
    • Which entities must be represented consistently in the copy and structured data?
    • What event should cause the page to be checked or updated?

    The calendar comes last. It is a production view of the strategy, not the strategy itself. If a planned page has no distinct audience job, no original contribution, and no place in the site architecture, moving its publication date won’t make it valuable.

    Make every important claim provable and extractable
    Illuminated content tiles connect to source materials and evidence objects on a dark work surface.

    Fluent prose is cheap. A page becomes difficult to replace when it contains evidence, experience, or reasoning that another publisher cannot reproduce by changing the brand name. That is why original data, interviews, and distinctive commentary belong inside the content system, not in an optional polishing stage.

    Choose an appropriate form of original proof

    Original proof does not have to mean a large proprietary study. Match the evidence to the claim:

    • First-party data: Publish the method, scope, relevant context, and limitations with the finding. A number without those boundaries may look precise while telling the reader very little.
    • Expert contribution: Attribute a specialist’s explanation to a named person with a visible role and relevant biography. Edit for clarity without turning a conditional judgment into a universal rule.
    • Documented process: Show the decision framework, workflow, template, or quality check your team actually uses. Remove confidential details, but preserve enough substance for the reader to apply it.
    • Worked example: Demonstrate how a recommendation changes a page, brief, schema graph, or measurement decision. Label hypothetical examples as hypothetical.
    • Editorial synthesis: Distinguish what is observed, what is inferred, and what you recommend. A confident opinion is useful when the reasoning is visible; it is not a substitute for evidence.

    Apply a substitution test before approving the brief: could another company replace your name with its own and publish essentially the same page? If so, the proposed contribution is still generic. Strengthen the evidence or narrow the question until the page has a defensible reason to exist.

    Experience, expertise, authoritativeness, and trust are most useful as editorial tests. Ask whether the relevant experience is visible, whether the author or reviewer is identifiable, whether consequential claims are supported, and whether limitations are stated where they affect the answer. Treating those qualities as a decorative author box misses their purpose.

    Write answer passages that keep their context

    An AI system may retrieve or summarize a passage rather than reproduce the logic of the entire page. Write each important section so its central claim can survive that separation.

    A strong answer unit follows a practical sequence: answer the question, show the basis for the answer, state the boundary or exception, and give the next useful action. Keep the qualification beside the claim it limits. If the caveat appears several paragraphs later, a reader or retrieval system can easily miss it.

    • Use descriptive headings that reveal the question or decision addressed below them.
    • Open a section with the direct answer, then explain the reasoning and evidence.
    • Keep each paragraph focused on one claim or one necessary part of its explanation.
    • Name the product, organization, person, or concept instead of relying on ambiguous pronouns.
    • Define acronyms and specialized terms when they first affect the answer.
    • Use lists for steps or criteria and tables only when the reader needs to compare corresponding fields.
    • Link to supporting pages with anchor text that identifies what the reader will verify.
    • Remove unsupported superlatives, vague appeals to authority, and conclusions broader than the evidence.

    This is not a request to make every page terse. Complex decisions still need depth. The aim is to give that depth a clear structure, with summaries, explainers, and scannable elements that make complexity easier to use. A page can be comprehensive without making its answer hard to find.

    Align page entities, JSON-LD, and outside corroboration

    Structured data is a machine-readable description of the page. It is not evidence by itself, and it cannot turn a generic or unsupported claim into an authoritative one. Its job is to reduce ambiguity about what the page describes, who created it, and how its entities relate.

    Run an entity and schema check after the editorial review:

    1. Identify the main entity. Be explicit about whether the page primarily concerns a service, product, organization, person, concept, or another subject.
    2. Choose truthful types. Use schema types that describe the visible content. Article can describe editorial content, Person can identify an author, and Organization can represent the publisher; these nodes can be connected rather than treated as isolated snippets.
    3. Use stable identifiers. Give recurring entities consistent @id values so the same organization or author is not represented as a new entity on every page.
    4. Populate verifiable properties. Include names, URLs, authorship, dates, and relationships only when the site can support and maintain them.
    5. Match the rendered page. The author, headline, dates, description, and claims in JSON-LD should agree with what a visitor can see. Do not mark up reviews, questions, credentials, or other material that the page does not contain.
    6. Update both layers. When a meaningful fact changes, revise the visible copy and its structured representation together. Changing dateModified as decoration does not improve the underlying page.

    Consistency should extend beyond the individual URL. Use the same brand name, author identity, service terminology, and core facts across bylines, biographies, about pages, product or service pages, and relevant off-site profiles. Internal inconsistency makes it harder for people and machines to determine which description is authoritative.

    Your own site can explain its expertise, but it cannot independently corroborate itself. Relevant third-party mentions can provide that external context. Brand mentions deserve a place in an AI-search content strategy, although a mention should not be treated as a guaranteed cause of inclusion in an AI response.

    Earn useful mentions by creating something worth referencing: a transparent dataset, a practical framework, an expert explanation, a well-maintained resource, or a clear position on a disputed decision. Distribute that work where the intended audience already asks questions. Social and community channels can reveal the audience’s language and expose the work to people who may discuss or cite it, but reach without relevance is not authority.

    Measure representation and business outcomes together

    Rankings and organic sessions still matter, but they no longer describe the whole discovery path. Your scorecard should show whether the brand appears in relevant AI answers, whether its claims are represented accurately, whether the correct page is selected, and whether the resulting attention contributes to a meaningful next step.

    Measurement layerQuestion to answerUseful signalsAction when weak
    DemandAre we addressing a consequential audience decision?Relevant query coverage, recurring customer questions, and observed audience languageRevise the topic map or narrow the page’s job
    AuthorityWhy should the answer be believed?Original evidence, identifiable expertise, claim support, and credible third-party mentionsAdd proof, expose methodology, or improve distribution
    RepresentationAre systems selecting and describing us correctly?Citation or mention presence, selected URL, entity accuracy, and preserved qualificationsRewrite answer units, remove ambiguity, or align entity markup
    OutcomeDoes discovery move the reader forward?Qualified visits, next-step completion, assisted conversions, and cross-channel engagementRepair the journey, offer, or connection between pages

    For AI-search monitoring, maintain a documented set of prompts tied to high-value audience decisions. Record the exact prompt, platform, observation date, cited or linked pages, claims made about the brand, and any missing qualification. Compare patterns across repeated observations instead of treating a single generated answer as a stable ranking.

    Use the failure mode to choose the fix. If the wrong URL appears, revisit consolidation and internal architecture. If the right page appears with an inaccurate claim, improve the answer passage and entity clarity. If visibility grows but qualified action does not, inspect the page’s promise, next step, and role in the buyer journey. If no page offers distinct evidence, another technical tweak is unlikely to solve the underlying problem.

    Start with one topic cluster connected to a real customer decision. Map its overlapping pages, identify the proof each page contributes, rewrite the passages most likely to answer the decision, align the JSON-LD, and record a baseline across discovery, representation, and outcomes. Do that before adding more briefs. You do not need to predict Google’s next interface; you need to make your best answers easier to understand, harder to replace, and more useful when a person chooses to continue.
    References

  • How to Choose the Right HVAC Marketing and SEO Agency

    How to Choose the Right HVAC Marketing and SEO Agency

    You are probably not short on HVAC agencies willing to sell you SEO, leads, a new website, paid ads, or some combination of all four. The difficult part is working out which one can solve your actual growth problem without putting your website, accounts, and reporting inside a black box.

    The right choice starts before the sales calls. Define the job, score evidence consistently, inspect the proposed work, and protect the assets you may need to take elsewhere. This framework will help you do that without choosing solely on a polished pitch or a familiar agency name.

    Know what you need the agency to fix

    An HVAC SEO agency and an HVAC marketing agency are not interchangeable. An SEO specialist concentrates on organic visibility, local search, technical improvements, and content. A broader marketing agency may also handle brand development, paid search, media buying, website production, creative work, and lead management.

    Neither model is inherently better. The useful question is whether the agency’s operating model matches the constraint in your business. Paying for a comprehensive marketing program when your main problem is an unindexable website wastes scope. Hiring a narrow technical specialist when you also need a new brand, paid demand, and call attribution leaves important work without an owner.

    Identify the bottleneck before you request proposals

    Write down one primary problem and one secondary problem. Use observable business conditions rather than channel labels:

    1. Local discovery problem: People in profitable service areas do not find you when they search for the services you provide.
    2. Website problem: The site is difficult to crawl, slow to update, poorly organized, or unable to support distinct services and locations.
    3. Conversion problem: Traffic reaches the site, but calls, forms, booking actions, and lead routing are not measured or do not work reliably.
    4. Demand problem: Organic search cannot provide the immediate coverage you need, so paid acquisition must operate alongside longer-term SEO work.
    5. AI discovery problem: Your company is difficult to identify, understand, or cite when people use generative search and answer systems to evaluate local providers.

    Then define the outcome in business language. Qualified calls, booked appointments, accepted estimates, and revenue attributed to organic or paid acquisition are decision metrics. A larger keyword list or a higher volume of published pages can describe activity, but neither proves that the activity helped the business.

    Match the operating model to that bottleneck

    • Choose a local SEO and web specialist when your location signals, service pages, site structure, and conversion paths need to be rebuilt together.
    • Choose a technical SEO specialist when you already have capable writers and marketers but need help with crawling, indexing, templates, internal linking, and existing content.
    • Choose an integrated SEO and PPC team when paid search must generate demand while the organic program develops.
    • Choose a full-service HVAC marketing agency when brand, creative, media, web, SEO, and reporting need one accountable operator.
    • Add generative engine optimization, or GEO, to the brief when visibility in AI-mediated discovery matters. Require concrete deliverables rather than accepting the label as proof of a capability.

    This first decision will narrow the field more effectively than searching for the best agency in the abstract. Best only makes sense in relation to the work you need done.

    Score agency evidence before listening to the pitch

    A marketing manager examines anonymous case-study materials, website mockups, and reference documents with a magnifying glass.

    A practical HVAC agency evaluation model assigns the greatest weight to relevant client work, leadership, and reviews, while still examining agency stability, specialization, GEO capability, and outside authority signals. The percentages below give you a consistent starting point for comparing candidates.

    CriterionWeightEvidence to request
    Past HVAC clients25%Comparable campaigns, the initial problem, completed work, measurement method, and outcome
    Founder status and leadership experience20%The leader responsible for strategy and the seniority of the person supervising your account
    Average reviews20%Independent reviews, with extra attention to feedback from HVAC businesses
    Year founded and median employee tenure10%Evidence of organizational stability, retained expertise, and adaptation as search has changed
    Specialty10%Depth in HVAC, SEO, local search, and the particular services included in your brief
    GEO offering10%Defined deliverables, target systems, measurement, and examples of how the work differs from conventional SEO
    Media references5%Relevant recognition that supports expertise rather than merely repeating promotional claims

    Do not score a logo page as if it were a case study. A client name shows that a relationship may have existed; it does not show what the agency controlled, how long the engagement ran, or what changed. Ask each candidate to walk you through one comparable HVAC engagement from diagnosis to measurement. The person presenting it should be able to separate the agency’s work from seasonality, paid media, brand demand, and changes made by the client.

    Leadership deserves attention because the senior expert in the sales meeting may not touch your campaign again. Ask who will make strategic decisions, who will approve content, who will investigate a decline, and how many handoffs sit between you and that person. Founder involvement can be useful, but only when it produces real access or a repeatable operating standard.

    Reviews need similar scrutiny. Feedback from HVAC clients is more relevant than generic praise because it is more likely to reflect the service-area, lead-quality, and operational issues you face. Look for descriptions of communication, reporting, execution, and problem resolution. Repeated praise for responsiveness is meaningful; repeated complaints about account turnover or inaccessible data are also meaningful.

    You can adjust the weights when the assignment demands it. A website rescue may justify more emphasis on technical capability. A multi-location program may justify more emphasis on local operations and account leadership. Keep the same scorecard for every agency in the process so a charismatic meeting does not quietly change the standard.

    Inspect the work behind SEO, local visibility, and GEO

    An illustrated HVAC service area connects homes, a technician, a service vehicle, location pins, a website icon, and linked information nodes.

    A proposal should show how the agency will move from diagnosis to implementation. If it contains only recurring activities – publish content, build links, optimize profiles, send reports – you still do not know what will be changed, who will change it, or how the work connects to a qualified lead.

    Local search needs an operating plan

    For an HVAC company, local SEO spans more than a Google Business Profile. The agency should explain how it will coordinate business information, services, locations, website pages, internal links, reviews, and conversion tracking. Ask for a responsibility map covering:

    • Who owns and administers each Google Business Profile.
    • How service and service-area information will stay consistent across the profile, website, and important listings.
    • Which locations or service areas deserve dedicated pages and what prevents those pages from becoming near-duplicates.
    • How technicians, office staff, or customers will supply the real details needed to make content accurate.
    • How reviews will be requested and monitored without handing reputation management to an unapproved automation.
    • How calls, forms, and booking actions will be attributed without making the agency the permanent owner of your tracking infrastructure.

    A plan should also distinguish between work that the agency can complete independently and work that depends on your team. If every useful page needs technical review from an HVAC expert, put that approval step in the workflow before the publishing schedule is agreed. Otherwise, the apparent content capacity in the proposal will not match the capacity of the real process.

    Technical SEO must end in implemented fixes

    An audit is a diagnostic artifact, not the outcome. Ask which findings the agency can implement, which require your developer or platform vendor, how priorities will be chosen, and how completed fixes will be checked. The proposal should address crawling, indexing, templates, duplicate pages, internal linking, mobile usability, page performance, and measurement where those issues are present. It should not promise to find every one of them before access and analysis.

    Ownership matters here. Keep the domain registration, website administrator account, hosting relationship, analytics property, search-console property, advertising accounts, and business profiles under credentials controlled by your company. Give the agency the access it needs through named users or partner permissions. If the agency owns the primary accounts, ending the relationship can also mean losing history, access, or operational continuity.

    Content should answer service decisions, not fill a calendar

    Ask the agency to map proposed content to the decisions a customer makes: identifying a problem, deciding whether service is urgent, comparing repair and replacement paths, understanding a system or service, checking geographic availability, and choosing a provider. That produces a useful content architecture. A list of loosely related keywords does not.

    The editorial workflow should identify who creates the brief, who verifies HVAC claims, who approves the page, who adds internal links, and who updates it when the underlying business information changes. Require a sample brief and a sample finished page before signing. They will tell you more about the agency’s judgment than a slide describing content quality.

    GEO needs a definition you can audit

    GEO is increasingly included when HVAC agencies are evaluated because businesses want to appear in AI-powered search environments such as ChatGPT. That does not make every GEO package substantive. Ask the agency to name the systems, prompts, entities, pages, and signals it will monitor. It should be able to explain what is new work, what overlaps with SEO, and what remains uncertain.

    A credible plan may improve the clarity and consistency of business facts, publish direct answers to customer questions, strengthen service and location pages, add appropriate structured data, and monitor whether the company appears for relevant questions. Structured data can make facts easier for machines to interpret, but it does not guarantee a recommendation, citation, ranking, or inclusion in an AI response. Treat any guaranteed AI placement as a sales claim, not a deliverable.

    Reporting should connect visibility to the lead path

    Require a sample report before choosing an agency. It should separate completed work, visibility indicators, website behavior, conversions, lead quality, and business outcomes. It should also make anomalies visible rather than hiding them inside a single percentage.

    • Completed work: pages changed, technical fixes deployed, profile updates, content published, and experiments launched.
    • Visibility: relevant organic queries, local discovery, important landing pages, and AI visibility where GEO is in scope.
    • Conversions: calls, forms, bookings, and other actions, with tests showing that tracking works.
    • Lead quality: which tracked inquiries became valid opportunities rather than spam, job seekers, existing-customer requests, or calls outside the service area.
    • Business results: accepted work or revenue where your systems and sales process can connect those outcomes responsibly.

    The report is only useful if someone can explain what changed and what decision follows. Ask who leads the reporting meeting and what happens when traffic rises but qualified calls do not, or when rankings fall while booked work remains stable. The answer reveals whether the team manages a business system or merely distributes charts.

    Build the shortlist around agency fit, not fame

    Different agencies are designed for different assignments. The following established profiles can help you identify the operating model to investigate. They are starting points for due diligence, not automatic endorsements.

    AgencyEstablished profileConsider when
    First Page SageFounded in 2009, with a thought-leadership-based SEO approach; named HVAC work includes Windy City Ventures and Four Seasons Heating & Plumbing.You want an SEO-led content and authority program and can support subject-matter input.
    Lemon SeedFounded in 2019, with a broad HVAC marketing scope and an emphasis on brand design; named work includes Krueger and Climate Plus.Your assignment combines brand, creative, and digital marketing rather than SEO alone.
    MediagisticFounded in 1999, combining traditional marketing, SEO, and media buying for larger organizations.You need an enterprise-oriented, multi-channel program that includes media beyond organic search.
    Marketing EyeFounded in 2004, with a technical SEO focus centered on improving existing web content.You have an internal marketing team and need specialized technical or optimization support.
    LocaliQFounded in 2004, with geotargeted SEO for small businesses and services that can scale as the business grows.Local visibility and flexible scope matter more than a highly customized enterprise engagement.
    ScorpionFounded in 2001, offering a comprehensive set of integrated digital services.You want fewer handoffs across marketing functions and prefer an integrated provider.
    HVAC WebmastersAn HVAC-focused digital provider with strengths in local SEO and web design.Your website and local search presence need to be improved as one project.
    Metric TheoryFounded in 2012, combining PPC and SEO.You need paid lead generation to operate alongside organic growth.

    Use this kind of profile table to choose several different operating models for the first round. You might speak with a local specialist, an integrated provider, and an SEO-led content firm. The point is not to collect the largest possible list. It is to test which model understands the assignment and produces the strongest evidence.

    Then replace the public profile with current facts. Confirm who will serve the account, whether the relevant specialty still exists in-house, which services are subcontracted, and whether the agency has conflicts in your market. An agency’s founding year and past clients can support a shortlist, but your result will depend on the team and process assigned to you.

    Run a structured selection process and protect the exit

    Give every finalist the same brief. Include your services, service areas, business model, website platform, current channels, internal resources, approval constraints, available historical data, and primary outcome. State what you believe is wrong, but invite the agency to challenge the diagnosis with evidence.

    Ask each finalist to answer the same questions:

    1. What is the first business or search problem you would investigate, and what evidence would change your mind?
    2. Which parts of the work will your team implement, and which parts remain our responsibility?
    3. Who will lead strategy, create deliverables, approve work, and speak with us when performance changes?
    4. Which comparable HVAC engagement can you explain from initial condition through measurement?
    5. How will you distinguish qualified leads from raw calls and form submissions?
    6. How will local SEO work differ across our real locations or service areas?
    7. What does GEO include, which systems will you monitor, and what outcomes will you refuse to guarantee?
    8. Which software, content, tracking numbers, accounts, and data remain ours if the engagement ends?
    9. What is included in the management fee, and which costs – such as media spend, software, production, or development – are separate?
    10. What would make you advise us not to hire your agency?

    The last question is useful because every agency has a boundary. A technically focused firm should be able to say that it is not your outsourced brand department. A full-service agency should be able to explain when its scope is unnecessarily broad. Clear exclusions are more trustworthy than a claim that one team is ideal for every HVAC business.

    Put ownership and handoff terms in the agreement

    Do not rely on a verbal assurance that everything is yours. The agreement should identify ownership and access for the domain, hosting, website, source files, content, business profiles, analytics, search data, advertising accounts, audiences, call-tracking numbers, recordings, creative assets, and reporting history. It should also explain what is exportable and what depends on licensed software.

    If an agency insists on owning your primary domain or core business accounts, keep those assets in company-controlled accounts and grant permission instead. The downside is not theoretical: losing an account during a transition can interrupt publishing, advertising, measurement, or customer access. Where a platform does not support transferable ownership, document the migration process before work begins.

    Also confirm cancellation terms, notice requirements, final deliverables, data export, migration assistance, approval authority, subcontracting, geographic exclusivity, and the treatment of unused media funds. Have an appropriate legal or financial professional review terms that create material exposure for your business.

    Watch for red flags that make comparison impossible

    • Guaranteed rankings, lead volumes, or placement in AI answers without stated assumptions and dependencies.
    • A senior sales team that will not introduce the people who will operate the account.
    • Reports built around impressions, rankings, or traffic with no working path to calls, bookings, and lead quality.
    • Case studies that omit the agency’s actual contribution, time frame, measurement method, or relevant starting condition.
    • Content volume presented as a strategy without a topic map, expert-review process, or update plan.
    • A GEO package that cannot name its deliverables, monitoring method, target systems, or relationship to ordinary SEO.
    • Agency ownership of the domain, primary profiles, advertising accounts, or analytics without a clear business reason and transfer process.
    • A proposal that gives every tactic equal priority and never states what should happen first.

    Key takeaways

    • Define the business bottleneck before deciding whether you need an SEO specialist, local web partner, integrated PPC team, or full-service marketing agency.
    • Weight relevant HVAC work, leadership, and client reviews more heavily than awards, sales polish, or a long menu of services.
    • Require implementation responsibilities, approval steps, and measurement methods for local SEO, technical work, content, and GEO.
    • Compare finalists against the same written brief and ask to meet the people who will actually run the account.
    • Treat GEO as an auditable workstream. Structured data and optimized content can support machine understanding, but no agency can guarantee an AI recommendation.
    • Keep your domain, profiles, analytics, advertising accounts, content, and core data under company control, with a documented handoff path.

    Your next step is simple: write the one-page brief and the scorecard before booking another sales call. Once every agency is answering the same problem under the same standard, the decision becomes less about confidence in the room and more about evidence, fit, and control of the work after the contract is signed.

    References

  • How to Build Reliable AI-Powered Content Operations

    How to Build Reliable AI-Powered Content Operations

    Your content backlog probably isn’t blocked by typing. It is blocked by everything around the typing: choosing what deserves attention, finding approved evidence, routing reviews, resolving exceptions, recording decisions, and knowing when a published page needs another pass. Add AI without fixing that system and you can create more drafts while making the operation harder to control.

    AI-powered content operations works when models move structured tasks through a governed lifecycle. The goal is not maximum output. It is a faster, more observable path from a real audience need to accurate, useful, discoverable content.

    Decide what AI can own before choosing a tool

    The commercial appeal is easy to understand. Automation layers are being positioned to audit, analyze, and optimize content at scale, reducing the manual work wrapped around each asset. Treat that as a capability to validate against your own content, not as proof that every editorial decision should be automated.

    The useful dividing line is not creative work versus administrative work. It is controlled work versus judgment-heavy work. Before assigning a task to AI, ask whether you can name the correct inputs, express an acceptable output as observable conditions, detect a bad result before it causes damage, and reverse the action cleanly.

    Use those questions to place work into three operating lanes:

    • Execute automatically: low-risk tasks with explicit rules, such as applying an approved classification, checking whether required fields are present, comparing a page against a defined checklist, or routing a completed record to its next owner.
    • Recommend for review: tasks where AI can narrow the work but should not make the final call, such as identifying possible content gaps, grouping overlapping URLs, proposing internal links, drafting a brief, suggesting a passage-level revision, or flagging claims that may need evidence.
    • Reserve for accountable owners: decisions involving business priority, original positioning, disputed evidence, sensitive claims, final approval, publication, consolidation, deletion, redirects, or canonical changes.

    This classification prevents a common operating mistake: treating every AI-assisted task as if it has the same risk. A missing topic label and an unsupported product claim should not share an approval path. Neither should a metadata suggestion and a page retirement.

    Automation should also have a no-action outcome. If the available evidence is incomplete, the instructions conflict, or the requested change falls outside the approved scope, the correct result is an exception record. Forcing the model to produce an answer turns uncertainty into hidden editorial debt.

    Give every task a durable content record

    A transparent modular case holds source documents, evidence cards, approvals, version layers, and a finished content page, with a hand adding a verified source card.

    A prompt is not an operating system. It describes what you want at a moment in time, but it does not reliably preserve why the work exists, which evidence is allowed, who owns the decision, what changed, or what should happen next.

    Build the workflow around a durable record for each content asset. That record can live in your CMS, project system, database, or orchestration platform, but it should expose the same core fields wherever the work runs:

    • Identity: asset ID, current URL or planned destination, content type, market, language, and related assets.
    • Purpose: intended audience, primary question or task, search intent, business purpose, and the action the page should help the reader take.
    • Evidence: approved references, source owner, claim-level notes, known uncertainties, and material that must not be used.
    • Ownership: content owner, subject reviewer, SEO owner, technical owner, and final approver where those roles apply.
    • State: lifecycle status, current workflow stage, blocking reason, next action, and the person or system responsible for that action.
    • Constraints: brand rules, regulatory or legal review requirements, format limits, localization needs, and protected language that must remain unchanged.
    • Change history: requested change, accepted change, rejected recommendation, approval record, publication event, and rollback information.
    • Measurement: target query set, baseline observations, relevant search and business outcomes, and the condition that should trigger another review.

    Without this record, each model run reconstructs context from whatever happens to be in its prompt. That creates inconsistent decisions and makes failures difficult to diagnose. With it, you can tell whether the problem came from missing evidence, an unclear instruction, an invalid output, a routing failure, or a human decision.

    Turn prompts into task contracts

    Once the content record exists, write a task contract for each automated step. A usable contract names the input fields, allowed context, requested operation, prohibited actions, required output fields, validation rules, no-change condition, and next route.

    For an audit task, do not ask the model to improve a page. Ask it to return an issue type, the affected passage or page element, the reason it failed a named rule, the evidence needed to resolve it, a proposed action, and a routing status. If approved evidence is missing, require an evidence-needed status and prohibit a factual rewrite.

    For an optimization task, define what optimization means. It might mean answering the primary question more directly, clarifying an entity, removing duplication, repairing a claim-source mismatch, aligning structured data with visible content, or improving an internal link path. If those outcomes are not named, the model is likely to equate optimization with rewriting, which creates unnecessary review work.

    Run a closed loop from audit to refresh

    A useful content workflow does not end when a draft appears. It carries an asset from detection through prioritization, evidence, revision, verification, publication, observation, and the next decision. You can use the following sequence as a practical starting point.

    1. Normalize the inventory. Give each asset a stable identity and map obvious relationships between canonical pages, localized versions, campaign variants, supporting pages, and structured data. Do not let the same URL enter multiple queues without a visible dependency.
    2. Audit against a fixed issue taxonomy. Separate accuracy risk, unsupported claims, intent mismatch, answer gaps, duplication, structural problems, internal link gaps, metadata defects, schema inconsistencies, and stale evidence. A fixed taxonomy makes findings routable and measurable.
    3. Triage before generating. Place work into operational buckets such as protect, improve, expand, consolidate, or retire. A valuable page with a material accuracy issue should not wait behind a speculative expansion. A weak page should not receive a full rewrite until you decide whether another asset should own the topic.
    4. Create an evidence-bound brief. State the audience problem, primary question, required subquestions, approved claims, named entities, allowed references, desired reader action, search role, and boundaries. Record unresolved questions instead of allowing the draft to conceal them.
    5. Make the smallest sufficient change. If a passage, heading, citation, internal link, or schema property can resolve the problem, do that before commissioning a full rewrite. Smaller changes are easier to verify, approve, attribute, and reverse.
    6. Verify the output against the brief and the original defect. Check whether the named problem was actually fixed, whether protected meaning changed, whether every material claim remains supported, and whether the revision introduced new duplication or ambiguity.
    7. Publish with a decision log. Store what changed, why it changed, who approved it, which workflow produced it, and how to reverse it. Update connected assets when the change affects internal links, canonical relationships, metadata, or structured data.
    8. Observe and route again. Compare the result with the intended search and business outcome. Keep it, revise it, escalate it, or return it to monitoring. The workflow is complete only when the next state is explicit.

    This closed loop matters for AI search as much as traditional search. A page needs a clear answer, unambiguous entities, support for consequential claims, descriptive structure, and visible content that agrees with its metadata and JSON-LD. Structured data cannot repair a vague answer, and a polished answer cannot make unsupported schema accurate.

    Keep content and schema in the same change set when one describes the other. If a workflow updates a product attribute, author identity, FAQ answer, date, organization detail, or other structured fact, route the visible page and its markup through the same verification gate. Otherwise, your automation can create two competing versions of the page.

    Put executable gates between generation and publishing

    Content page artifacts move through evidence, structure, policy, and human-review gates, while a failed item loops back for correction before publishing.

    A quality gate needs observable pass conditions. Instructions such as make it authoritative, improve the SEO, or ensure it is high quality are editorial ambitions, not tests. Replace them with checks that produce a pass, fail, or exception and identify who owns the next decision.

    GateMachine-checkable conditionHuman decisionFailure route
    IntakeRequired identity, purpose, owner, state, and constraint fields are present.The request belongs in this workflow and is worth doing.Return to the requester with the missing field or scope conflict.
    EvidenceMaterial claims map to approved evidence, and unknown or conflicting claims are flagged.The evidence supports the intended meaning and is appropriate for the audience.Send missing evidence to its owner; send conflicts to the subject reviewer.
    AnswerThe primary question has an identifiable answer passage, required subquestions are covered, and the requested action is present.The answer is accurate, useful, appropriately qualified, and not merely keyword-aligned.Return the named gap to revision without reopening unrelated sections.
    Search and AI readinessHeadings describe their sections, entities use consistent names, important references are linked, and structured data agrees with visible content.The page deserves to represent the organization in search results and generated answers.Route content defects to editorial and markup defects to the technical owner.
    PublicationRequired approvals, destination, metadata, internal links, change log, and rollback information are present.The residual risk is acceptable and the release timing makes sense.Block publication and assign the unresolved condition to an accountable owner.

    Treat model confidence as routing metadata, not evidence. A confident output can still rely on the wrong context, miss a qualification, or satisfy the requested format while failing the reader. Evidence, deterministic validation, and accountable review are separate controls.

    Your exception queue is part of the product, not a bin for failed automation. Every exception should carry the asset, failed rule, blocking reason, evidence captured, attempted action, next owner, and resolution status. Group the queue by reason so you can see whether the recurring problem is missing source material, vague briefs, conflicting policies, technical validation, or an overloaded reviewer.

    If you permit automatic publishing, confine it to transformations with approved inputs, mechanical validation, a recorded change, and a tested reversal path. Deletions, redirects, canonical changes, unsupported factual edits, and sensitive claims need accountable approval because a technically reversible change can still damage discoverability, trust, or compliance before anyone notices.

    Measure the operation, not the volume of output

    Draft count is easy to increase and easy to misread. It says nothing about whether the queue is moving, whether reviewers trust the output, whether published pages answer better questions, or whether AI is creating rework somewhere else.

    Build the dashboard around three layers:

    • Flow: queue age, active cycle time, blocked time by reason, handoffs, work returned to an earlier stage, and items waiting on each owner. These measures reveal where automation moved effort rather than removed it.
    • Quality: first-pass gate failures, unsupported-claim findings, post-publication corrections, exceptions by type, content-to-schema mismatches, and recommendations rejected by reviewers. Segment these by workflow, content type, and risk class.
    • Outcome: coverage of approved audience questions, search discovery for the intended queries, qualified actions after landing, citation or inclusion in relevant AI answers, and whether refreshed assets hold their intended role over time.

    Always pair a count with its denominator. A failure total is hard to interpret without the number of items reviewed. A fast cycle time can hide poor quality if corrections rise. A high acceptance rate can be meaningless if reviewers approve cosmetic edits while rejecting the consequential ones.

    AI-search observations also need a controlled record. Preserve the exact query, engine or model surface, market and language, account or personalization state where relevant, observation time, returned answer, cited pages, brand inclusion, and landing destination. Compare like with like. Otherwise, normal variation in the testing context can be mistaken for a content result.

    Use the measurements to change the workflow itself. Repeated evidence failures mean the intake or source library needs work. Repeated brand corrections point to an incomplete constraint set. Long blocked time identifies an ownership problem. High rework on full-page drafts is a reason to narrow the unit of change. The dashboard should tell you what to redesign, not merely what happened.

    Key takeaways

    • Automate a task only when its inputs, pass conditions, failure detection, and reversal path are explicit.
    • Keep purpose, evidence, ownership, lifecycle state, constraints, changes, and measurements in a durable content record.
    • Require every AI task to support no-change and exception outcomes instead of forcing a draft.
    • Use the smallest sufficient edit, then verify it against the original defect and the approved evidence.
    • Gate visible content, metadata, internal links, and JSON-LD as one connected publishing system.
    • Measure flow, quality, and reader or search outcomes together so faster production cannot hide greater rework.

    Start with the narrowest recurring queue that currently consumes useful editorial time: a stale-page audit, an evidence-backed refresh, an internal-link review, or a content-to-schema consistency check. Define its record, task contract, gates, exception routes, and measurements before widening the scope. When that workflow can move predictably without hiding uncertainty, you have a foundation worth scaling.

    References

  • Google Discover Visibility Is Shifting Beyond Search Rankings

    Google Discover Visibility Is Shifting Beyond Search Rankings

    If your Google Search rankings are holding while Discover visibility is falling, you may not be looking at a contradiction or a technical failure. Search and Discover are becoming less useful as proxies for one another.

    That changes how you should investigate losses, plan content and judge SEO work. Treat Discover as a separate distribution environment, preserve what is already working in Search and test Discover hypotheses against Discover results.

    Search rankings no longer explain Discover visibility well enough

    At a Google Search Central Live event in Zurich, Google characterized Discover as having “minimal alignment to search ranking”. The stated reason was operational: less dependence on Search ranking gives the Discover team more freedom to respond to emerging abuse.

    This is a meaningful direction, but it is not a complete ranking specification. “Minimal alignment” does not mean that Search quality work has become irrelevant, that the systems share nothing or that every publisher is already experiencing the change in the same way. Google has not supplied a public list of Discover-specific factors or their weights.

    The distinction matters because the previous mental model was stronger. In 2019, Google connected its core ranking systems with Discover visibility, including changes that publishers observed after core updates. Under that model, a Search ranking movement could plausibly explain a Discover movement. The newer direction weakens that inference.

    Your first practical change is simple: stop using stable Search rankings as proof that Discover should also be stable. A page can remain a strong Search result and still receive a different evaluation or distribution outcome in Discover. The reverse can also occur. Diagnose the surface that changed before editing the content.

    Rebuild reporting around divergence, not one visibility score

    A glass prism divides one beam into two paths observed by separate optical instruments on a dark table.

    A combined organic-visibility number now hides the pattern you most need to see. Separate Search and Discover at the start of your reporting workflow, not after a decline forces an investigation.

    1. Establish two baselines. Record Search performance and Discover-attributed performance separately. Do not let a gain on one surface conceal a loss on the other.
    2. Group comparable pages. Use information you already control, such as topic, site section, page type, author, publication date and whether the page was substantially updated. Cohorts help you distinguish a section-level pattern from one unusually successful or unsuccessful page.
    3. Find the point of divergence. Determine whether Search changed first, Discover changed first, both moved together or only one moved. That sequence determines which explanation deserves attention first.
    4. Check site changes before rewriting content. Review publishing volume, topic mix, ownership changes, domain changes, templates, metadata and structured data. Record what actually changed instead of creating a retrospective theory around the traffic graph.
    5. Label the strength of each conclusion. Separate observations, plausible explanations and unknowns. “Discover declined after we expanded into an unrelated topic” is an observation about timing. “The topic expansion caused the decline” remains a hypothesis until the pattern repeats or other explanations are excluded.

    Use the relationship between the two surfaces as a diagnostic aid:

    Observed patternBest first interpretationWhat to do next
    Search stable, Discover weakerA Discover-specific change is more plausible than a broad Search quality loss.Inspect Discover cohorts, publishing changes and possible abuse-related ambiguity. Preserve elements that continue to perform in Search unless you have page-level evidence against them.
    Search weaker, Discover stableThe problem is more likely to sit in Search than in Discover.Investigate Search visibility separately. Do not treat stable Discover distribution as proof that Search will recover without action.
    Both weakerA shared site, content or market change is plausible, but not proven.Audit changes common to both surfaces before inventing two independent explanations.
    Both strongerThe same pages may be succeeding through different evaluation paths.Document the shared attributes, then test them across another comparable content group before calling any attribute a ranking factor.

    This framework also prevents a costly reaction: rewriting pages that still satisfy Search because their Discover distribution changed. When the systems are less aligned, a Discover loss is not enough evidence to dismantle a successful Search page.

    Smaller publishers have an opening, not a shortcut

    A small creative team produces an original visual story as its image card passes through an opening between stacks of repetitive blank cards.

    Google wants Discover to be able to surface lesser-known and smaller publishers that may not receive equivalent exposure in Search. That gives a focused niche publication a real reason to treat Discover as more than an extension of keyword rankings.

    It does not guarantee distribution merely because a site is small. Nor does it establish “small publisher” as a ranking factor you can optimize. The useful interpretation is narrower: weak Search visibility does not automatically disqualify a publisher from Discover, so you should evaluate content ideas on their suitability for both surfaces instead of rejecting every idea that lacks an obvious Search-ranking path.

    Add a Discover lens to your commissioning process:

    • Define the niche precisely. A smaller publisher’s advantage is easier to understand when its editorial purpose is coherent. “Technology” says little; a consistent body of work for a defined audience gives you a cohort that can be measured and improved.
    • Require a reason to publish now. The reason might be a new development, a fresh explanation or a useful angle for the audience. “Other sites covered it” is not an editorial proposition.
    • Make each page understandable on its own. A reader arriving from a feed should be able to identify the subject, the value and the publisher without reconstructing context from several earlier pages.
    • Preserve genuine specificity. A focused explanation, an attributable observation or a clearly bounded point of view is more defensible than a generic rewrite built only to imitate a larger publisher’s format.
    • Measure the hypothesis on the intended surface. If you commissioned a page as a Discover experiment, judge its Discover outcome separately. Its Search ranking can still be useful, but it does not answer the original question.

    These are commissioning and measurement disciplines, not a list of confirmed Discover signals. That distinction protects you from turning an opening for niche publishers into another formula.

    Abuse controls make borrowed authority a fragile strategy

    The decoupling is partly a response to a problem that has been especially difficult in Discover: spam using expired or throwaway domains. A tactic that appears to gain quick distribution by borrowing a domain’s history is therefore moving directly into the area Discover is trying to police more independently.

    Do not acquire or cycle through domains simply to manufacture inherited trust for feed distribution. Even if the tactic produces temporary exposure, it depends on the exact pattern the platform is building more freedom to suppress. A durable publication needs continuity between the domain, publisher identity, subject matter and visible content.

    You can reduce ambiguity without pretending that routine trust hygiene guarantees Discover visibility:

    • Keep the publisher identity and ownership clear to readers.
    • Use accurate bylines, publication information and update information.
    • Avoid abrupt, unexplained shifts into unrelated subject areas solely because those areas appear capable of attracting feed traffic.
    • Make structured data match the publisher, author, dates and content that a reader can see on the page.
    • Do not use JSON-LD to claim identities, relationships or properties that the visible page does not support.
    • Document legitimate domain or ownership changes so your team can distinguish a real publishing transition from an opportunistic domain switch.

    Accurate schema still has a job: it keeps machine-readable claims consistent with the page. It cannot force Search and Discover to reach the same distribution decision, and the current shift gives you less reason to expect it to do so. Treat structured data as factual infrastructure, not as a bridge that restores ranking parity.

    Key takeaways

    • Google Discover is becoming less aligned with Search ranking, so Search performance is no longer a sufficient proxy for Discover visibility.
    • A loss limited to Discover should be investigated as a Discover problem before you rewrite pages that still perform in Search.
    • Separate Search and Discover reporting, group comparable pages and record the order in which changes occur.
    • Smaller and niche publishers have more room to appear in Discover, but size alone is neither a guarantee nor a confirmed ranking factor.
    • Expired-domain and throwaway-domain tactics sit inside the abuse pattern Discover is trying to combat.
    • Use accurate content, identity and schema practices as durable trust hygiene, not as a promise of feed distribution.

    Make your next content decision with two outcomes in view

    Before your next editorial cycle, choose one coherent section and give it separate Search and Discover goals. Tag the pages consistently, record material publishing changes and review each surface on its own. When results diverge, change one reversible element at a time and leave successful Search work intact until the evidence points to it.

    The practical opportunity is not to discover a new trick. It is to stop demanding that one Google surface explain another. Publishers that make that separation now will diagnose changes faster and make fewer destructive edits when Discover visibility moves.

    References

  • Unannounced Google Core Updates: A Practical SEO Response

    Unannounced Google Core Updates: A Practical SEO Response

    Your rankings slipped, Google’s public channels are quiet, and no named core update explains the date. The dangerous response is to choose a story too quickly: either Google changed nothing, or every loss must be an invisible update.

    Silence does not settle the cause. Your job is to preserve the evidence, rule out problems you control, identify the pages and queries that actually moved, and make improvements you can evaluate. You do not need a rollout name to start that work.

    Core updates no longer give you a clean starting gun

    Google has made an important operating reality explicit: its core systems can change through smaller updates that are not announced because their effects are usually less noticeable. Major announcements therefore represent only part of the ranking activity you may encounter.

    That changes how you should run SEO. A public announcement is useful context, but it is not a diagnostic result. No announcement does not prove that Google’s systems were static, while an announced update does not prove that the update caused every movement on your site.

    The practical distinction is between detection, attribution, and treatment. Detection tells you what moved. Attribution tells you which explanations fit the evidence. Treatment is the smallest defensible change that addresses the underlying problem. Teams get into trouble when they skip the first two and jump directly from a traffic chart to a site-wide rewrite.

    Key takeaways

    • Google’s silence is not evidence that its core ranking systems did not change.
    • A ranking decline is not evidence of an unannounced core update until you have ruled out measurement, technical, demand, and competitive causes.
    • Diagnose movement by page, query, topic, template, country, and device rather than relying on one site-wide traffic line.
    • Improve content for the searcher’s task instead of trying to reverse-engineer an unnamed update.
    • Keep content and deployment records so the next unexplained movement begins with evidence rather than memory.

    Diagnose the movement before changing the site

    A diagnostic workspace contains abstract web pages, a magnifying glass, and symbols for links, servers, and mobile devices connected by glowing paths.

    You may never be able to prove that a quiet core update affected your site. You can still reach a useful working diagnosis. The goal is not to attach a confident label to uncertain data. It is to eliminate explanations, locate the pattern, and decide what deserves action.

    1. Preserve the baseline. Record when the movement first became visible, which data set exposed it, and which countries, devices, search types, pages, and queries were involved. Export the relevant page-query data before edits change the comparison.
    2. Validate measurement. Compare organic clicks in your analytics platform with clicks and impressions in Google Search Console. If analytics declines while Search Console clicks remain stable, investigate tracking, consent behavior, redirects, and landing-page execution before treating the event as a ranking loss.
    3. Clear technical causes. Check affected URLs for indexability, canonical selection, robots directives, status codes, redirects, rendering problems, crawl access, and accidental template changes. Review releases involving navigation, internal links, pagination, URL rules, or metadata.
    4. Read page-query pairs, not just averages. Falling impressions and positions for the same relevant queries point toward a visibility problem. Falling clicks with relatively stable impressions and positions should send you toward search-result presentation and click-through behavior. Falling impressions with stable positions can reflect demand or query-mix changes. These are clues, not verdicts.
    5. Segment the loss. Separate branded from non-branded queries, informational from commercial intent, new from established pages, and one directory or template from the rest of the site. Also compare changed pages with untouched pages. A coherent pattern is more informative than a site-wide aggregate.
    6. Inspect the search results that matter. Look for a changed intent mix, stronger competing pages, new search features, or a different type of result occupying the visible space. Do not assume that a lower click total means your page alone deteriorated.
    7. Write the hypothesis before prescribing the fix. State what changed, where it changed, which causes were ruled out, what remains uncertain, and which evidence would disprove your explanation.

    Use restrained labels in internal reporting. Call an event a possible algorithmic movement when the affected cohort is coherent but no direct cause is visible. Call it a confirmed technical incident only when you can show the failure. Keep it unresolved when several explanations still fit. Calling every unexplained decline an update may sound decisive, but it hides the work your team still needs to do.

    Improve the pages without trying to chase an unnamed signal

    You do not need to wait for the next announced rollout to benefit from better work. Smaller core changes can provide additional opportunities for improved content to gain stronger positions. That is an opportunity, not a promised recovery date.

    Start with URLs where three conditions overlap: meaningful visibility changed, the page matters to its intended audience or business purpose, and the review exposed a specific weakness. A page should not be rewritten merely because its graph is red.

    For each priority page, examine the following:

    • The searcher’s job. Identify the decision, explanation, comparison, or action the query implies. Make that job the organizing principle of the page.
    • The opening answer. A reader should not have to cross a long preamble before learning whether the page can solve the problem.
    • Coverage with purpose. Add missing questions, constraints, examples, or decision criteria only when they help complete the task. More words are not automatically a better answer.
    • Accuracy and specificity. Correct stale claims, remove unsupported assertions, and name the relevant product, platform, version, market, or audience when advice depends on it. Do not change a publication date merely to simulate freshness.
    • Distinct value. If several URLs repeat the same answer, decide which page should own the topic. Consolidate genuine duplication or give each page a clearly different job.
    • Internal context. Link from relevant pages using language that explains the destination. Check whether important content became isolated after navigation or template changes.
    • Structured data integrity. Keep JSON-LD consistent with the visible page and the entity it describes. Schema can clarify machine-readable meaning, but it cannot repair thin, inaccurate, or misaligned content.

    Ship changes in coherent, traceable batches. For every batch, record the URLs, diagnosed problem, exact edits, release point, affected query group, and expected behavior. Rewriting a large section at once destroys the causal trail and makes it harder to distinguish a useful improvement from collateral damage.

    Measure the same page-query cohorts you used in the diagnosis. A site-wide organic total can hide recovery in the affected group or create the illusion of recovery when unrelated pages grow.

    Build an operating system for ranking changes without announcements

    A circular workflow machine moves abstract web-page tiles through archive, inspection, improvement, and review stations while a digital wave passes around it.

    The best preparation is not a prediction calendar. It is a monitoring and change-control system that works whether Google announces an update or not.

    Maintain a comparison-ready baseline

    • Track clicks, impressions, and positions for stable page-query cohorts, not only domain totals.
    • Group pages by directory, topic, intent, template, and content type so a local problem cannot disappear inside an average.
    • Retain country and device views when those dimensions materially affect your audience.
    • Monitor crawl and indexing signals beside performance data so technical incidents can be identified quickly.
    • Annotate deployments, migrations, template edits, navigation changes, large content batches, redirects, and tracking releases.
    • Record what each change was intended to improve and how you would recognize an adverse effect.

    A spreadsheet can be sufficient if it is maintained. The useful fields are the change point, owner, affected URLs or templates, purpose, expected metric, validation method, and safe rollback path. The value comes from being able to compare a ranking movement with an actual change record.

    Use decision rules instead of reacting to every fluctuation

    • If analytics declines but Search Console clicks do not, validate measurement and landing-page behavior first.
    • If crawl or indexing failures align with the affected URLs, fix the technical problem before launching a content program.
    • If a stable cohort loses relevant query visibility with no technical cause, review intent fit, content quality, competing results, and search-result changes.
    • If the evidence is mixed, preserve the unresolved status and avoid a broad rollback or rewrite.
    • If a measured content batch improves the intended page-query cohort without creating new problems, retain it and extend the approach cautiously to comparable pages.

    Public SEO chatter can tell you that other sites are moving, but it cannot diagnose your URLs. Use it to form questions, not to replace your own evidence.

    The next time rankings move in silence, open an incident record before opening the CMS. Preserve the baseline, clear measurement and technical failures, map the affected cohort, and ship the smallest high-confidence improvement you can evaluate. That process remains useful whether the cause is eventually announced, stays unannounced, or turns out not to be an update at all.

    References

  • Commercial Intent in AI Chats: Where Brands Should Focus

    Commercial Intent in AI Chats: Where Brands Should Focus

    If you are budgeting for AI visibility on the assumption that every product mention is close to a sale, stop and reclassify the opportunity. Commercial demand exists in AI chats, but much of it appears while people are framing a problem, weighing approaches, or trying to succeed with something they already bought.

    Your job is to recognize those moments without forcing a sales funnel onto every conversation. That changes which pages you prioritize, how you structure an answer, where you place the next action, and what you count as success.

    Commercial intent is a minority, but it is not one moment

    Across a corpus covering 4.4 billion characters, 613 million words, and 3.9 million conversation turns, people used AI heavily for tasks such as planning, brainstorming, analysis, learning, transformation, and creation. Those activities may happen at work or mention a product, but that does not automatically make them commercial.

    Within a categorized sample of 24,259 sessions spanning 42 intent categories, 64.6% did not fit a purchase funnel, while 35.4% showed some form of commercial intent. The useful correction is not that AI chats have no commercial value. It is that commercial value is distributed across several different jobs, most of which are not an immediate purchase request.

    Awareness accounted for 10% of the categorized sessions and consideration for 8.5%. Together, those early stages represented 18.5% of all sessions and the largest block of commercial activity. Discovery accounted for 4.1%, decision support for 2.8%, transactional support for 4.8%, and post-purchase needs for 5.1%.

    That distinction matters when you set priorities. If your AI strategy watches only prompts containing words such as buy, price, best, or demo, it will miss people who are still deciding what kind of solution they need. It will also miss existing customers asking how to configure, use, integrate, or repair what they own.

    Do not treat the percentages as a universal forecast for every market. They describe the analyzed corpus, not the exact intent mix for your category. Use them to challenge an overly transactional strategy, then classify the questions that appear in your own sales, support, search, and customer research.

    Classify the user’s job before choosing the content

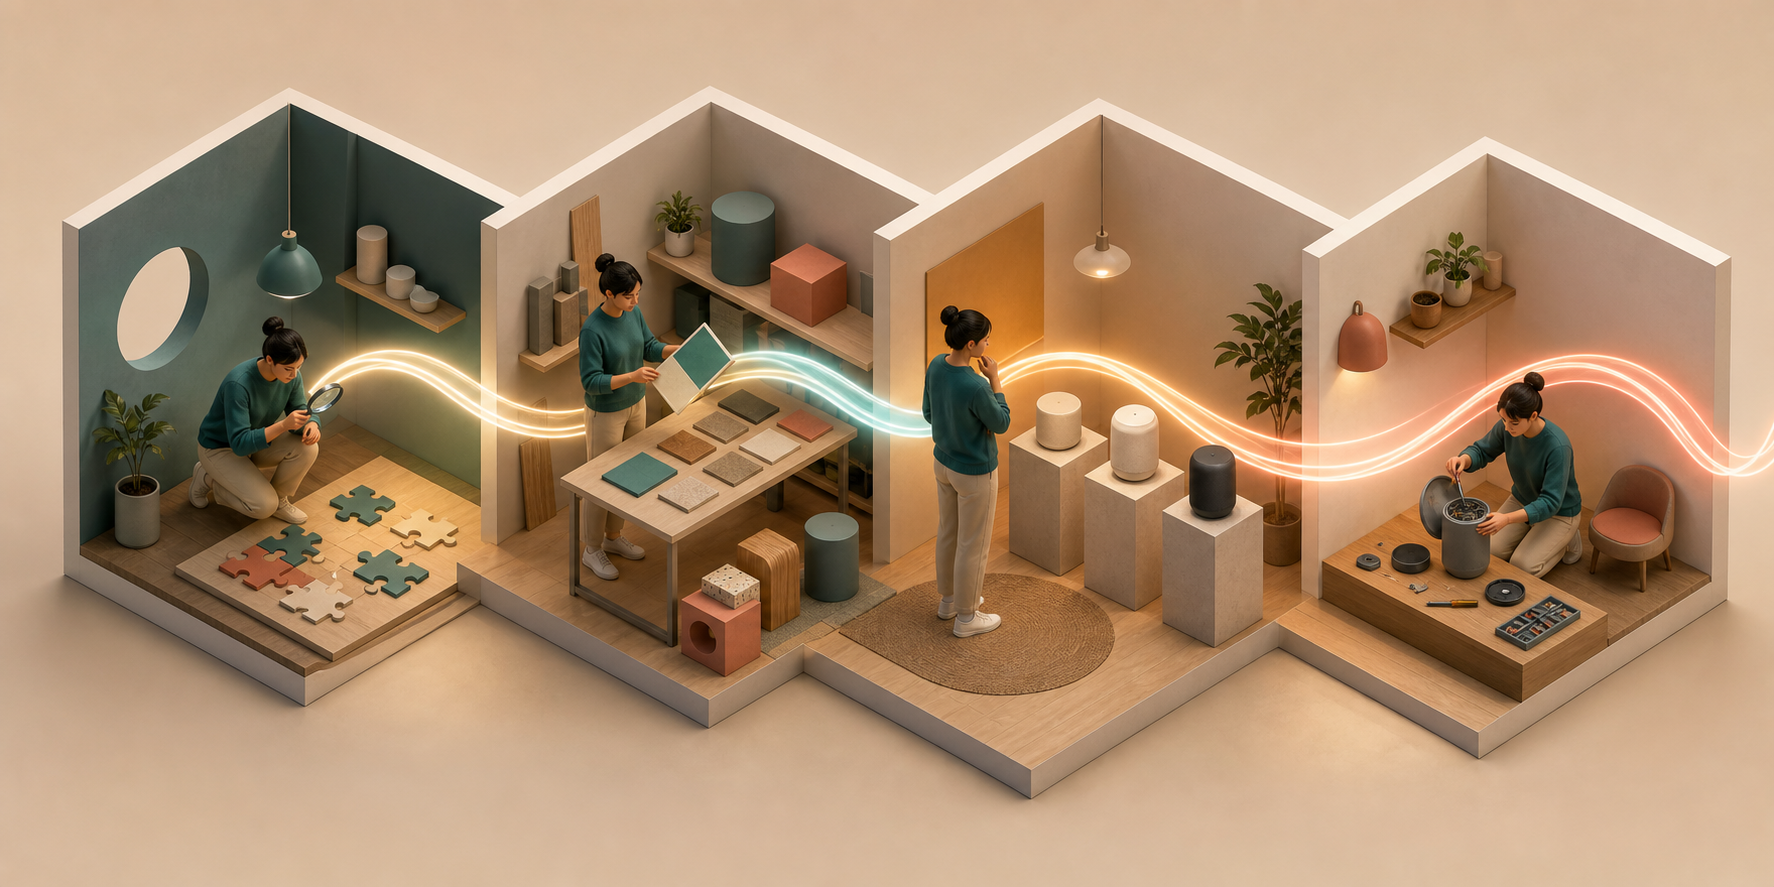
    Four connected rooms show a user investigating a problem, exploring approaches, comparing products, and learning to use an owned device.

    A noun is not an intent signal. A user can mention your category while asking for writing help, summarization, technical instruction, product evaluation, or troubleshooting. Classify the job being done before deciding whether the conversation belongs in a commercial funnel.

    Intent classObserved shareWhat the user is trying to doWhat your content should accomplish
    Outside the purchase funnel64.6%Create, learn, analyze, plan, transform, or converse without making a product choiceComplete the requested task honestly; introduce a commercial path only when it is genuinely relevant
    Awareness10%Name a problem, understand its causes, or learn what kinds of solutions existDefine the problem, explain when it matters, and make the available approaches understandable
    Consideration8.5%Compare approaches, requirements, or tradeoffsProvide selection criteria, limitations, alternatives, and use-case fit
    Discovery4.1%Find products, providers, or options in a categoryHelp the user build a defensible shortlist without hiding eligibility criteria or constraints
    Decision support2.8%Choose among known optionsSupply verifiable details about fit, evidence, implementation, cost factors, and risk
    Transactional support4.8%Complete or manage a commercial actionRemove uncertainty about requirements, process, timing, and what happens next
    Post-purchase5.1%Set up, use, improve, or troubleshoot something already acquiredHelp the customer reach the intended result and recover from predictable failures

    The percentages in the table are rounded shares of the categorized sample. The user-job descriptions and content responses are practical applications of those intent classes.

    Context is decisive. Create a launch brief for this product is primarily a creation task. Which type of platform should our distributed team use to manage a launch? is consideration. Why did this feature stop working after setup? is post-purchase. The same category terms can appear in all three prompts, but only the latter two have an explicit relationship to choosing or owning a solution.

    Use a strict operational rule: label a conversation commercial only when the user is making an economic choice, evaluating a solution, completing a transaction, or seeking help with something already acquired. Do not inflate your opportunity estimate by treating every workplace task as latent demand.

    Build for exploration and ownership, not just selection

    Early-stage content should make the decision legible

    Awareness and consideration together accounted for 18.5% of all categorized sessions. This is where product-led content often arrives too early. A user who is still defining the problem does not need an unsupported claim that your product is the answer. They need enough structure to decide whether the category is relevant at all.

    A useful awareness or consideration page should do the following:

    • Answer the initiating question immediately. State the practical answer before company history, positioning, or a lead form.
    • Define the decision context. Identify who the advice applies to, the conditions that change it, and any prerequisites the user may not have mentioned.
    • Separate symptoms from causes. Help the user avoid buying a solution for the wrong problem.
    • Expose the criteria that change the choice. Explain requirements, constraints, tradeoffs, and cases in which a simpler approach is sufficient.
    • Include credible alternatives. A comparison is more useful when it covers different approaches, including doing nothing yet, rather than presenting a disguised product pitch.
    • Provide a natural next question. Link the problem explanation to criteria, the criteria to options, and the options to decision evidence.

    The first answer carries unusual weight. The median conversation in the corpus had two turns and 430 words, and more than 80% of chats stayed below 1,000 words. Many users therefore do not spend a long sequence teaching the assistant their context. Your page should state its audience, assumptions, constraints, and core answer clearly enough to survive a short exchange.

    This is also where answer-engine optimization and conversion writing need to part company for a moment. The strongest opening is the one that resolves the question accurately. The commercial handoff comes after the user can see why a category, method, or product deserves consideration.

    Post-purchase content belongs in the commercial strategy

    Post-purchase needs represented 5.1% of sessions, exceeding discovery at 4.1% and decision support at 2.8%. That is a clear reason not to limit AI optimization to comparison and product pages.

    Support content should be designed around the customer’s actual failure state, not your internal feature taxonomy. A page titled with the symptom a user can observe is more useful than one that assumes they already know which component caused it.

    • Name the symptom, task, or desired outcome in the title and opening.
    • State the applicable product state, configuration, prerequisites, and access requirements.
    • Put the resolution steps in the order the user must perform them.
    • Describe the expected result so the user can verify that each meaningful step worked.
    • Branch explicitly when different causes require different fixes.
    • Say when self-service should stop and what information support will need.
    • Connect the fix to related setup or usage guidance without turning the page into a sales pitch.

    Where security and account privacy allow it, publish general help in accessible, indexable page content. Keep account-specific data and privileged actions behind authentication. An AI visibility goal never justifies exposing information that should remain private.

    Audit AI demand by prompt, page, and outcome

    A strategist sorts abstract chat bubbles through webpage cards toward discovery, comparison, purchase, and customer-success outcomes.

    You do not need to guess whether your opportunity is mostly awareness, decision support, or ownership. Build an intent inventory from questions people already ask, then connect each question to a page and a measurable next step.

    1. Collect real questions. Pull wording from site search, sales conversations, support records, community discussions, product research, and known AI referrals. Preserve the original phrasing instead of rewriting everything as a target keyword.
    2. Assign one primary job. Label each question as non-funnel, awareness, consideration, discovery, decision, transactional support, or post-purchase. Record a secondary intent only when it changes the answer the user needs.
    3. Map the best existing page. Choose the page that should answer the question, not merely the page currently ranking for adjacent terms. A product page is not automatically the right destination.
    4. Find coverage and answer gaps. Mark questions with no page, pages that bury the answer, unsupported claims, missing limitations, stale instructions, or no sensible continuation.
    5. Repair the visible content first. Make the answer, scope, evidence, and next step explicit. Structured data should reflect what a user can actually see on the page; it cannot manufacture commercial intent or compensate for an evasive answer.
    6. Run repeatable prompt checks. Log the exact prompt, assistant, exposed model or version, date, language or market, answer, brand representation, and cited URLs. A single response is an observation, not a stable visibility benchmark.
    7. Measure the outcome appropriate to the stage. Evaluate awareness content by accurate inclusion and progression to deeper evaluation. Evaluate decision content by qualified actions. Evaluate post-purchase content by successful task completion and reduced escalation where those signals are available.

    Keep visibility and progression as separate measures. Visibility asks whether the assistant represents the right answer, entity, or page. Progression asks whether the user then reaches a useful next step. Combining them into one score hides whether you have a retrieval problem, an answer-quality problem, or a conversion-path problem.

    Referral traffic is also incomplete by definition. You can observe a visit only when a user follows a link; an interaction that ends inside the chat produces no referral session. Use AI referral data as evidence of visits and downstream behavior, not as a complete count of AI influence.

    Finally, compare like with like. Do not blend troubleshooting prompts and product-selection prompts into one visibility rate, then judge both by purchases. Segment the prompt set by intent, page type, market, and user state. The resulting report will tell you which content is failing and what kind of repair it needs.

    Key takeaways

    • Commercial intent appeared in 35.4% of the categorized AI chat sessions, while 64.6% did not fit a purchase funnel.
    • Awareness and consideration formed the largest commercial block, so problem framing and selection criteria deserve more attention than purchase language alone.
    • Post-purchase demand exceeded both discovery and decision support, making setup and troubleshooting content part of AI commerce strategy.
    • Classify the user’s job, not the presence of a product or business keyword.
    • Because the median chat was short, make the first answer self-contained, scoped, and useful before asking the user to take a commercial action.
    • Measure visibility, answer accuracy, progression, and business outcomes separately for each intent stage.

    Start with your own prompt inventory. Find an early-stage cluster and a post-purchase cluster with weak coverage, repair the answers and their handoffs, and retest them consistently. You will see where AI visibility can support demand and where usefulness should stand on its own.

    References

  • Should You Block AI Crawlers? A Publisher Access Plan

    You’re deciding whether to shut out AI crawlers, but the cost of a mistake is lopsided. Allow too much and you may give away valuable access while absorbing the infrastructure cost. Block too broadly and you may cut off search discovery that still brings readers, customers, and subscribers.

    The workable approach is to stop treating “AI” as one access category. Decide which systems may retrieve which content, for which purpose, under which conditions. Then enforce that policy in layers and measure the result.

    Separate discovery, retrieval, training, and licensing

    A crawler request is a technical event, not a complete explanation of intent. The same public page can have several distinct uses, and your business may benefit from some while rejecting others.

    • Conventional search discovery: A search crawler retrieves a page so the page can be considered for a search index. Access makes discovery possible; it does not guarantee indexing or rankings.
    • Live AI retrieval: A system fetches current information to help answer a user’s request. You may value the resulting visibility, but allowing retrieval does not guarantee a citation or referral visit.
    • Model development: An operator collects content for training or related model-improvement work. This can involve a different value exchange from answering a current query.
    • Licensed access: A publisher deliberately supplies content under agreed technical and commercial terms, potentially through authentication, metering, or a dedicated feed.

    These purposes are strategically separate even when a platform does not give you separate crawler controls. That limitation matters: you can only implement distinctions that the operator exposes and your infrastructure can verify. Where an operator combines purposes, record the exception and make the resulting trade deliberately.

    Key takeaways

    • Preserve conventional search access unless you have consciously decided that its discovery value no longer justifies it.
    • Set policy by crawler identity, declared purpose, and content class rather than using one domain-wide rule for every automated request.
    • Use robots.txt to communicate crawl preferences, but use server-side controls or authentication when access must actually be prevented.
    • Roll out narrow, reversible rules and compare infrastructure savings with changes in discovery, revenue, and AI visibility.

    A blanket block creates an asymmetric business risk

    The volume is large enough to justify active management. Cloudflare reported that, following the July 1 launch of its pay-per-crawl initiative, customers had blocked 416 billion AI-bot requests. That figure demonstrates the scale of crawler demand on participating sites. It does not establish that every blocked request would have harmed a publisher or that blocking is the right default for every site.

    Access is also uneven. Cloudflare argues that publishers cannot cleanly separate Google Search access from Google AI access, and puts Google’s page visibility at 3.2 times OpenAI’s, 4.6 times Microsoft’s, and 4.8 times Anthropic’s or Meta’s. Those are vendor-supplied measurements, so treat the ratios as a directional view of the access imbalance rather than universal traffic benchmarks.

    This is why “block all AI” can be a misleading objective. If the platform connects conventional search crawling with AI use, the technical setting may force a wider business decision than you intended. Before deploying a rule, write down which benefit you are prepared to lose. If the answer is “none of our organic search discovery,” a domain-wide crawler block is too blunt.

    The reverse is also true. “Allow everything for visibility” is not a strategy. An allowed request may generate no referral, citation, subscription, or licensing opportunity. Access should remain open because it serves a defined outcome, not because the crawler includes “AI” in its name.

    Build an access matrix your engineers can enforce

    Turn the policy into a small matrix before touching robots.txt or a firewall rule. Start with four access tiers and assign each content class to one of them.

    Access tierUse it forTechnical defaultBusiness condition
    Open discoveryPublic pages intended for broad distributionAllow verified search crawlers and selected AI access; monitor usageReach and discoverability outweigh reuse concerns
    Search-preservedPublic pages that should remain searchable but are not offered for wider AI collectionAllow conventional search where the operator exposes a separate identity; deny or throttle named AI crawlersThe technical identities can be separated reliably
    Metered or licensedOriginal archives, structured collections, or other material with concentrated reuse valueRequire authentication, rate limits, or a controlled delivery channelAccess is granted under recorded operational and commercial terms
    ClosedSubscriber-only, internal, personal, or otherwise non-public materialRequire authentication and enforce denial at the server or application layerPublic crawler access is unnecessary or inappropriate

    Do not classify the whole site by its most valuable page. A public news story, an evergreen guide, a subscriber archive, an image library, and an internal search endpoint can justify different rules. URL groups make the policy more precise and make mistakes easier to reverse.

    For every crawler-policy combination, record the operator, declared purpose, method used to verify identity, allowed URL groups, rate limit if any, enforcement layer, policy owner, and review date. If you cannot verify the operator or purpose, classify the traffic according to your risk tolerance rather than guessing from a friendly-looking user-agent string.

    Keep the technical policy separate from the legal permission. A crawler being able to retrieve a page does not by itself define the terms under which the content may be reused. If you intend to sell or contractually license access, have appropriate legal counsel establish the rights, attribution, payment, update, termination, and enforcement terms.

    Enforce the policy in layers, not with one bot rule

    Robots.txt is useful for expressing crawl instructions to compliant operators. It is not authentication, and it does not prevent an unidentified or non-compliant client from requesting a public URL. Use the control that matches the consequence of failure.

    1. Capture a baseline. Before changing access, record crawler requests, transferred bytes, cache misses, origin load, requested URL groups, response codes, search crawl health, search traffic, observable AI referrals, and conversions. Note campaigns or publishing spikes that could distort the comparison.
    2. Inventory and verify identities. Group requests by claimed user agent, network identity, paths requested, rate, and behavior. A user-agent string can be copied, so do not approve or block high-impact access solely because a request claims a recognizable name. Use verification information supplied by the relevant operator where it is available.
    3. Publish the intended crawl rules. Add crawler-specific robots.txt instructions only after confirming that the rule preserves the search access you want. Test the deployed file, including rules inherited from broader user-agent groups.
    4. Enforce consequential restrictions upstream. Use your CDN, web application firewall, origin, or application to throttle or deny matching requests. Keep each rule narrow, log its matches, return a consistent response, name an owner, and document the rollback procedure.
    5. Put valuable non-public material behind authentication. Do not rely on robots.txt to protect subscriber content, private files, customer information, unpublished drafts, or licensed datasets. If anonymous visitors can retrieve a URL, an automated client may be able to retrieve it too.
    6. Stage the rollout. Begin with one verified crawler identity or one low-risk URL group. Review false positives and business metrics before extending the rule. This limits the damage if a shared identity, proxy, or overly broad path pattern catches traffic you meant to preserve.

    Blocking only affects requests that reach your controls and match your rules. It does not prove that a model lacks the content, and allowing a crawler does not prove that the content will appear in an answer. Describe the operational outcome accurately: you allowed, throttled, or denied a particular access path.

    Measure whether blocking improved your position

    A successful block is not merely a rising denial count. The useful question is whether the policy improved the exchange between access granted and value received. Review the same scorecard before and after each staged change.

    • Infrastructure: Requests, bandwidth, cache misses, origin work, and load associated with each verified crawler and content class.
    • Search discovery: Crawl errors, accessible pages, index coverage, organic impressions, clicks, and landing-page conversions. Investigate changes that coincide with a rule deployment before expanding it.
    • AI visibility: Observable AI referrals, cited pages found through a consistent sample of relevant prompts, brand mentions, and resulting conversions. Referral logs measure visits, not every unseen citation or model use, so do not treat zero referrals as proof of zero exposure.
    • Content value: Subscriptions, leads, revenue, partnership requests, and licensing discussions associated with the affected material.
    • Policy quality: False positives, unidentified automation, repeated requests against denied paths, operator verification failures, and rules that no longer match your content structure.

    Set the decision rule before examining the result. Retain a restriction when it materially reduces unwanted access or resource use without damaging the outcomes you chose to preserve. Roll it back when search discovery or legitimate partner access declines because the match was too broad. Move valuable, persistent demand toward authenticated or licensed access when the opportunity justifies the operational and legal work.

    Your first action can be small: write one policy sentence for conventional search, one for live AI retrieval, one for model-development access, and one for premium content. Compare those sentences with the controls your platforms actually expose. Where policy and tooling do not line up, start with the narrowest reversible restriction and preserve the baseline you will need to judge it.

    References

  • Google Discover and AI Mode: An Emerging-Query Workflow

    Google Discover and AI Mode: An Emerging-Query Workflow

    If your Google strategy begins when someone types a query, you may be entering the journey too late. A person can encounter a story in Discover, open the page, and then continue exploring it through AI rather than returning to a conventional results page.

    That changes the content problem in two directions. You need to recognize demand before it becomes an obvious keyword opportunity, and the page you publish must remain useful when a reader asks an AI system to summarize it, answer a follow-up, or go deeper.

    Optimize the whole discovery journey, not one ranking

    The emerging Google journey has three distinct moments, and each asks something different of your content:

    1. Discovery: A topic, headline, image, or entity earns attention in a personalized feed. The reader may not have expressed a conventional search query.
    2. Evaluation: The reader opens the page and decides whether it answers the immediate question clearly enough to trust and continue.
    3. Exploration: The reader uses AI to condense the page, ask another question, or investigate the subject in more depth.

    The third moment is no longer theoretical. In the observed Google app for Android flow, a menu available after opening a URL offered Summarize with AI Mode, Ask a follow-up with AI Mode, and Dive deeper with AI Mode. The behavior was not confined to stories selected from Discover; AI Mode controls were also available for other pages opened through the app.

    This means a click is not necessarily the end of the search experience. Your page can become material the reader interrogates. A catchy headline may win the first transition, but it cannot compensate for vague entities, buried conclusions, unsupported assertions, or sections that repeat the same point.

    Plan the journey backward. Start with the useful action or decision the reader should reach. Then identify the questions that lead there:

    • What happened, or what is changing?
    • Why does it matter to this reader?
    • What is still uncertain?
    • What should the reader compare, check, or do next?
    • What related question becomes important after the first answer?

    Those questions should determine the article structure before you write the headline. They also give you a practical standard for deciding whether a trend deserves coverage at all.

    Find rising demand before it looks like a mature keyword

    A strategist observes scattered digital signals converging into a bright rising pattern on a translucent display.

    Traditional keyword research is strongest when a query already has enough repeated behavior to measure. Emerging demand often appears first as an event, product, person, phrase, policy, cultural reference, or unfamiliar entity. By the time every tool reports stable volume, the easiest editorial opening may have passed.

    Google’s 2025 Year in Search was organized around rapidly rising searches rather than a simple ranking of the largest query totals. The U.S. list crossed technology, policy, entertainment, sport, and public affairs with queries such as DeepSeek, iPhone 17, tariffs, KPop Demon Hunters, and the FIFA Club World Cup. The global list included Gemini, DeepSeek, major cricket matchups, the Club World Cup, and iPhone 17.

    The more useful lesson is not which names appeared. It is how many different forms new demand can take. Additional U.S. trends included AI action figure, a long viral-dish phrase, a Boston travel-itinerary query, and a question about why children say 67. A useful trend radar therefore cannot be limited to short commercial keywords. It has to notice new entities, new behaviors, new language, and old needs expressed in unfamiliar ways.

    Keep a signal log that captures what keyword volume misses

    Create one shared record for emerging topics. For each signal, capture:

    • The exact phrase or entity: Preserve the wording people are using instead of immediately translating it into an established keyword.
    • The trigger: Record the launch, event, announcement, controversy, release, match, meme, or behavior that created the question.
    • The audience connection: State why your existing reader would care. A topic can be popular without belonging on your site.
    • The first practical question: Identify what the reader needs to understand, decide, buy, avoid, or explain.
    • The likely follow-ups: Write down the next questions before search-volume data exists for them.
    • The evidence available: Note what can be verified now and what remains unknown. If you cannot support the central answer, speed will not improve the page.
    • The expiry condition: Decide what event would make the page outdated, incomplete, or misleading.

    This log prevents a common mistake: treating a growing entity as if it were already a settled keyword cluster. Early in a trend, people may search for the name alone because they do not yet know the vocabulary for a more precise question. Your job is to infer the legitimate questions cautiously, then revise the page as the language becomes clearer.

    Use a publication gate before chasing the spike

    Run every candidate through five questions:

    1. Is the reader ours? Define the person who needs the answer without relying on a phrase such as everyone is talking about it.
    2. Is there a real job to do? Name the decision, explanation, comparison, or action the page will support.
    3. Can we add clarity? If the page will merely restate the event, it has little reason to exist after the first wave of coverage.
    4. Can we maintain it? A fast-changing page needs an owner and an explicit update trigger.
    5. Does it connect to durable expertise? The best emerging topic opens a path into subjects your site can continue to explain after the spike fades.

    If you cannot answer the first three questions, skip the topic. If you cannot support the final two, narrow the scope until you can. Publishing a thin page for every rising name creates an archive of disconnected updates, not topical authority.

    Once a topic passes the gate, prepare a brief containing the provisional query cluster, the one-sentence answer, the follow-up question map, the entities that require disambiguation, the supporting evidence, the intended URL, and the conditions that will trigger an update. That is enough structure to move quickly without turning speed into guesswork.

    Build pages that survive summary, follow-up, and depth

    Cutaway illustration of readers exploring an overview, branching answer areas, and deeper research layers within a structured web page.

    The three AI Mode commands provide a useful editorial test. Apply all three before publication, even if a particular reader never opens the AI controls.

    The summary test

    Could a reader identify the subject, central answer, significance, and main limitation from the opening and section headings? If not, the page is making both readers and machines reconstruct a conclusion that you should have stated directly.

    • Name the primary entity in the title, introduction, and relevant heading instead of relying on ambiguous pronouns.
    • Give the direct answer before the chronology or background.
    • Separate confirmed facts from interpretation and unresolved questions.
    • Use one section for each distinct idea. Do not scatter the same conclusion across several headings.
    • Remove paragraphs that merely announce what the next paragraph will explain.

    A good summary test is not an instruction to make every article short. It is an instruction to make the hierarchy unmistakable. A detailed page can still have a clear central answer.

    The follow-up test

    After reading the answer, what would a sensible person ask next? Turn the strongest second-order questions into substantive sections. Depending on the topic, these may concern eligibility, cost, timing, alternatives, consequences, definitions, examples, or what changed.

    Do not manufacture a question section from keyword variants that all have the same answer. Each follow-up should move the reader to a new understanding or decision. If two questions collapse into the same paragraph, combine them.

    Internal links should continue the same logic. Link to a durable explainer when the reader needs background, a comparison when the next task is choosing, and a process page when the next task is acting. Generic related-reading blocks leave that choice to chance.

    The depth test

    What can the reader learn from your page that would be lost in a one-paragraph recap? Depth comes from useful distinctions, not word count. Add the material that changes interpretation: definitions, boundaries, named entities, evidence, exceptions, trade-offs, and the point at which the advice no longer applies.

    For a fast-moving topic, show what is known at publication and what still needs confirmation. Update the existing URL when the central intent remains the same. Create a separate page only when a genuinely different intent appears. That keeps one answer coherent while preventing a single URL from becoming an undifferentiated timeline.

    Make the structured data agree with the visible page

    JSON-LD should describe the page you actually published. For editorial content, use Article or a truthful, more specific subtype. Keep the structured headline, author, publication date, modification date, canonical page identity, and publisher consistent with what the reader can see.

    • Use stable identifiers for people and organizations so the same entity is not represented as several unrelated things across the site.
    • Change the modification date when the content receives a substantive update, not when an automated process touches the template.
    • Represent the page’s primary subject consistently in the copy, metadata, internal links, and structured data.
    • Add a schema type only when the visible content meets its meaning. Anticipating follow-up questions does not require disguising an ordinary article as a different content format.
    • Validate the markup and inspect the rendered page. Syntactically valid JSON-LD can still contradict the content it describes.

    Structured data can make relationships more explicit, but it cannot turn a vague page into a reliable answer or guarantee distribution in Discover, Search, or an AI response. Treat it as a consistency layer, not a substitute for editorial substance.

    Measure whether early attention becomes durable value

    A trend page can produce a traffic spike and still fail strategically. Measure the complete path: how early you recognized the signal, whether the page satisfied the immediate need, whether readers continued into relevant content, and whether the topic strengthened a durable area of expertise.

    QuestionSignal to recordDecision it supports
    Did we recognize the topic early?First-observed date, assignment date, and publication dateWhether the discovery workflow is fast enough
    Did the page match the emerging need?Queries where available, landing-page behavior, and movement to the next relevant pageWhether the angle and follow-up map were accurate
    Did the topic matter to our audience?Qualified subscriptions, leads, purchases, saves, or other site-specific outcomesWhether attention was useful rather than merely large
    Did the opportunity become durable?New recurring questions, internal-link use, and continued interest in the surrounding topicWhether to build an evergreen supporting resource
    Does the page need maintenance?Material changes to the entity, event, availability, policy, or reader intentWhether to update, narrow, redirect, or stop promoting the URL

    Keep these observations attached to the topic record. Keyword volume seen later cannot tell you what your team knew when it made the editorial decision. The first-observed date and original question map let you review whether you spotted a real signal or merely followed an already visible spike.

    Judge trend coverage against its intended role. An emerging explainer should not be evaluated like a mature evergreen guide, and an audience-building story should not be declared successful solely because it attracted raw visits. Define the meaningful next action before publication, then measure that action consistently.

    When interest declines, preserve what remains useful. If the original question still exists, update the page and connect it to an evergreen resource. If the event has ended but the surrounding need persists, create a separate durable page and link the two in both directions. Do not keep producing minor update pages that compete to answer the same intent.

    Key takeaways

    • Google discovery can begin before a conventional query and continue through AI after the click, so optimize the complete question journey.
    • Use a signal log for new entities, phrases, triggers, audience questions, evidence, and expiry conditions; keyword volume alone will often arrive too late.
    • Publish a trend only when it serves your established audience, answers a real question, adds clarity, can be maintained, and connects to durable expertise.
    • Test every page for summary, follow-up, and depth: state the answer clearly, anticipate the next useful questions, and add distinctions that survive compression.
    • Keep visible content, metadata, internal links, and JSON-LD consistent. Schema clarifies meaning but does not replace trustworthy content.
    • Measure lead time, useful onward behavior, audience outcomes, and long-term topic value instead of treating a temporary traffic spike as the goal.

    Start with one rising topic already sitting in your editorial backlog. Write its trigger, reader, first question, next three questions, available evidence, and update condition. If those lines are clear, you have the basis for a useful page. If they are not, waiting or declining the topic is a better decision than publishing a fast page with no durable answer.

    References

  • Master AEO Content Writing: Boost Visibility in LLMs

    Master AEO Content Writing: Boost Visibility in LLMs

    I’ve discovered the art of AEO content writing, and it’s all about structure, thorough research, and establishing authority signals. This approach can significantly boost the chances of your content being cited by LLMs such as ChatGPT, Gemini, and Perplexity.


    Inspired by this post on HiGoodie Blog.


    crushpress.ai community screenshot
  • How to Make Your Content Visible and Citable in AI Search

    If an AI answer leaves your brand out, cites another site for your expertise, or repeats an outdated description, publishing more content is not automatically the remedy. You first need to identify whether the failure is coverage, clarity, evidence, entity consistency, or measurement.

    The practical goal is to make your best knowledge easy to find, extract, attribute, and represent accurately. That requires better answer design on the page, honest structured data, usable text for audio and other non-text assets, and a monitoring process built around real customer questions.

    Optimize for the answer your audience actually needs

    Traditional keyword planning often starts with a phrase and ends with a page. AI search optimization needs an additional layer: the answer a person expects after asking that question in context.

    Start by separating the wording of the prompt from its underlying decision. Someone asking whether a platform is suitable for an enterprise team may really need to know about governance, integrations, operating ownership, or implementation risk. A page that repeats the category keyword without resolving that decision is relevant in the shallowest sense, but it is not a strong answer.

    Create a question map before editing pages. For every important customer question, record:

    • The audience: who is asking and what they already understand.
    • The decision: what they are trying to choose, avoid, confirm, or accomplish.
    • The required answer: the shortest accurate statement that would move the decision forward.
    • The qualifications: conditions under which the answer changes.
    • The supporting evidence: documentation, first-party data, named methodology, product specifications, or expert ownership that makes the claim defensible.
    • The destination: the existing page that should own the answer, or the genuine content gap that warrants a new page.

    This exercise prevents a common mistake: creating several pages that target variations of the same phrase while leaving the actual customer question unanswered.

    On the page, build a self-contained answer unit. It should do these jobs in sequence:

    1. Name the question or issue clearly. Use a descriptive heading that still makes sense outside the page navigation.
    2. Answer it immediately. Put the direct response in the opening sentences instead of making the reader cross an introduction to find it.
    3. Define the boundary. State who the answer applies to, what assumptions it uses, and when a different answer would be appropriate.
    4. Support the claim. Place the evidence close to the statement it supports. Do not expect a generic references page to carry every claim on the site.
    5. Offer the next useful step. Link to the comparison, procedure, specification, demonstration, or contact path that naturally follows the answer.

    Use a simple extraction test: copy the passage into a blank document without the page title, sidebar, or previous paragraph. If it becomes unclear what the subject is, who the advice is for, or what a pronoun refers to, revise it. Phrases such as this approach, our solution, and it works better often need an explicit noun and a stated comparison.

    Do not force every paragraph into a miniature definition. The page should still read naturally from beginning to end. Concentrate the strongest answer units around questions that matter to a customer decision, then use the surrounding prose to explain mechanisms, tradeoffs, examples, and exceptions.

    Build pages that can be interpreted and cited cleanly

    A page becomes easier to use when its meaning does not depend on branding language or unstated context. Clear organization also gives you a better chance of noticing contradictions before they spread across product pages, help content, interviews, and profiles.

    Audit each priority page against these criteria:

    • One primary intent: the page has a recognizable job. Related subquestions support that job instead of turning the page into a collection of loosely connected topics.
    • Stable terminology: the same concept has the same name throughout the page. Introduce acronyms, alternate names, and category labels explicitly rather than switching between them without explanation.
    • Explicit entity relationships: state which organization owns a product, how a service relates to the company, and whether two similar names describe a brand, feature, plan, or legal entity.
    • Claim-level support: evidence appears beside the claim it supports. A link should help the reader inspect the basis of the statement, not merely decorate the sentence.
    • Visible ownership: identify the author, editorial owner, or accountable organization when that information helps a reader evaluate the material.
    • Meaningful maintenance signals: show a reviewed or updated date when the page has actually been reviewed or materially changed. A fresh date on stale copy makes the page less trustworthy, not more useful.
    • Descriptive internal links: link broad explanations to the specialist pages that own definitions, methods, specifications, and supporting evidence.
    • A stable citation destination: keep the answer at a durable URL. When consolidation is necessary, preserve the relationship between the old destination and its replacement.

    Pay special attention to unsupported superlatives. Claims such as best, leading, most accurate, or enterprise-ready need a defined comparison and credible support. If you cannot explain the comparison, replace the label with concrete capabilities, limitations, or use cases.

    Use JSON-LD to identify content, not to compensate for it

    Structured data can clarify what a page and its entities represent. It cannot make a vague claim specific, turn promotional copy into evidence, or repair a page that does not answer its stated question.

    Choose the most specific truthful schema type that matches the visible content. An editorial page may use Article or BlogPosting, an episode page may use PodcastEpisode, and entity information may use types such as Organization, Person, Product, or Service when those entities are genuinely present. The exact selection matters less than the consistency between the markup, the visible page, and the rest of the site.

    Check the following before publishing JSON-LD:

    • The headline, description, author, publisher, dates, URL, and named entities agree with the page a visitor can inspect.
    • Identifiers remain consistent wherever the same entity appears.
    • Relationships such as author, publisher, brand, provider, or subject describe the real relationship rather than the one marketing would prefer an engine to infer.
    • FAQ markup corresponds to questions and answers that are genuinely visible on the page.
    • Reviews, ratings, prices, availability, and other material claims are not added to markup unless the page legitimately supports them.
    • Generated markup is validated after templates, plugins, or content fields change.

    Treat structured data as an identification and disambiguation layer. That framing keeps the implementation useful even when a particular search surface does not display a special result for the markup.

    Give podcasts and other audio a usable text surface

    An embedded player tells a visitor that audio exists, but it gives an answer system little visible text to quote or evaluate. A clear and citable audio presence therefore depends on exposing the episode’s meaning in a form that can be read, attributed, and connected to a stable page.

    Build a dedicated page for each episode rather than relying only on a show archive or player feed. The page should include:

    • A specific episode title: name the subject, decision, or question instead of using only a clever theme.
    • An opening summary: state what the episode covers, who it is useful for, and the main conclusion or tension.
    • A readable HTML transcript: do not make a player, audio download, image, or document attachment the only path to the spoken material.
    • Speaker labels: distinguish the host, guest, and quoted parties so a claim is not assigned to the wrong person.
    • Topic headings and timestamps: let people move directly to a section and connect the transcript passage to the corresponding audio.
    • Explicit names and terms: spell out people, companies, products, abbreviations, and specialist concepts that automatic transcription may confuse.
    • Supporting links: connect claims and referenced resources to pages where a reader can inspect the details.
    • Matching episode metadata: keep the visible title, description, people, publication details, canonical URL, and PodcastEpisode markup aligned.

    Clean the transcript with restraint. Correct obvious transcription errors, add punctuation, and organize the text for reading, but preserve meaningful qualifications and uncertainty. If a guest said that an approach may help under certain conditions, the edited transcript should not quietly convert that into an unconditional promise.

    The transcript is not merely an accessibility afterthought or a container for extra keywords. It is a first-class content asset. Use it to create navigable topic sections, clarify who made each statement, and expose valuable explanations that would otherwise remain locked inside the recording.

    Measure representation instead of chasing one AI rank

    AI search visibility is not a single fixed position. A brand can appear for one wording of a question, disappear for a close variation, be mentioned without a link, or be cited while the accompanying description is wrong. Each outcome requires a different response.

    Build a durable prompt set around customer decisions. Include category questions, problem-solving questions, comparisons, validation questions, and direct brand questions. Add audience and use-case variations where they change what a good answer should contain. Preserve the exact wording and relevant context so later observations remain comparable.

    Track the raw components before combining anything into a visibility score:

    MeasureWhat to recordWhat it helps you decide
    Brand presenceWhether the answer names the brand for the target questionWhether the brand is associated with the problem or category at all
    Owned-domain citationWhether the answer links to a page you control, and which page it choosesWhether your site is functioning as a citation destination
    Third-party citationWhich external pages support claims about your brand or categoryWhere the answer is getting its narrative and whether those sources are current
    Factual accuracyEvery checkable claim about the brand, product, people, compatibility, or use caseWhich errors require correction in canonical content or public entity information
    Narrative fitWhether the answer connects the brand to the intended audience, problem, and differentiatorsWhere positioning is absent, vague, or being defined by someone else
    Content coverageWhether each target question has a page capable of answering it with appropriate supportWhether to improve an existing page or create a missing resource

    A mention is not the same as a citation. A citation is not the same as accurate representation. A visit is not the same as visibility, either: an answer may name your brand without producing a click. Keep these outcomes separate or a single aggregate number will hide the problem you need to solve.

    For every observation, retain the prompt, answer, date, AI surface, cited URLs, and any known context that could affect the output. Generated answers can vary, so one run should be treated as an observation rather than proof of a stable result.

    The useful operating model connects current Answer Engine observations with an actionable AI search strategy. Monitoring without a content decision becomes reporting theatre. Editing without a baseline makes it impossible to tell whether you addressed the original failure.

    Use this optimization loop:

    1. Capture the baseline. Run the preserved prompt set and label mentions, citations, claims, and errors.
    2. Classify the gap. Decide whether the problem is missing coverage, an unclear answer, weak support, entity confusion, outdated information, or an inaccurate external narrative.
    3. Choose the page that should own the correction. Avoid scattering slightly different explanations across several URLs.
    4. Make a traceable change. Record the question addressed, passage changed, evidence added, schema updated, and publication date.
    5. Check the page itself. Confirm that the visible answer, internal links, metadata, and structured data agree before looking for movement elsewhere.
    6. Repeat the same prompt set. Compare like with like, while recognizing that answer variation prevents a single rerun from proving causation.
    7. Inspect nearby questions. Make sure the edit improved the intended topic without creating contradictions for related audiences or use cases.

    Prioritize by consequence, not by the easiest available edit. If a high-value question has no adequate page, close that coverage gap. If a strong page exists but buries the answer, restructure it. If the brand is cited inaccurately, establish a clearer canonical explanation and align entity facts across owned properties. If the answer is accurate but gives an interested visitor nowhere useful to go, improve the next-step path without turning the answer into a sales pitch.

    Key takeaways

    • Optimize around the customer’s decision and required answer, not the keyword alone.
    • Write self-contained passages that answer directly, define their limits, and place evidence beside the claim.
    • Keep visible content, entity relationships, metadata, and JSON-LD consistent; schema should describe reality rather than manufacture it.
    • Give every important podcast episode a stable page with an HTML transcript, speaker labels, topic headings, timestamps, and matching episode metadata.
    • Measure mentions, citations, accuracy, narrative fit, and content coverage separately across a preserved set of prompts.
    • Connect each observed visibility gap to a documented content change, then recheck the same questions without treating one output as definitive proof.

    Start with the customer question whose missing or incorrect answer has the greatest consequence for your business. Capture the current outputs, identify the page that should own the answer, make one defensible change, and document it. That gives you a repeatable optimization cycle instead of a collection of pages carrying an untestable AI-optimized label.

    References