Tag: Consent

  • Paid Search APIs: A Control Plan for PMax and Targeting

    Paid Search APIs: A Control Plan for PMax and Targeting

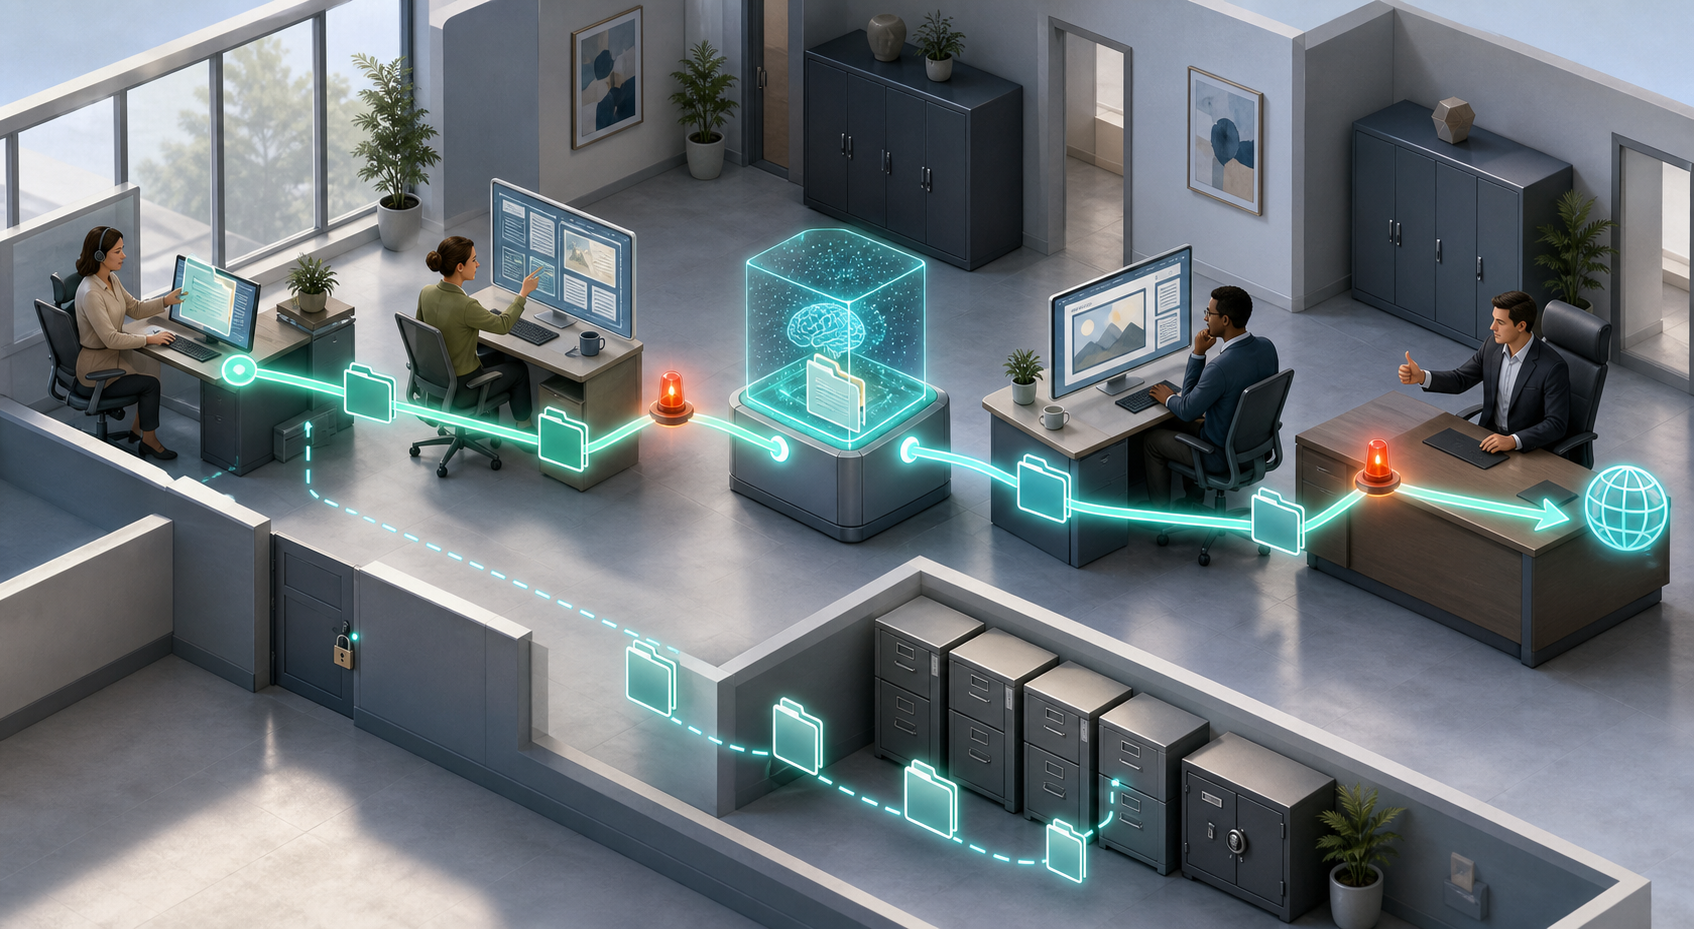
    Your paid search stack has more levers, but a longer settings list is not a control strategy. Your immediate job is to decide which signals belong in reporting, which controls enforce real business constraints, and which customer data should never enter an upload pipeline without an eligibility check.

    Handled carefully, the Microsoft Advertising and Google Ads APIs can help you trace intent to destinations, constrain Performance Max where the economics demand it, strengthen audience inputs, and identify bidding settings that limit auction access. The useful unit is not the endpoint. It is a closed loop: observe, diagnose, authorize, change, and verify.

    Build a control plane before you automate campaign changes

    A paid search integration should separate evidence from action. Reports, benchmarks, and recommendations tell you what may deserve attention. They do not automatically tell you which change is safe, profitable, or permitted.

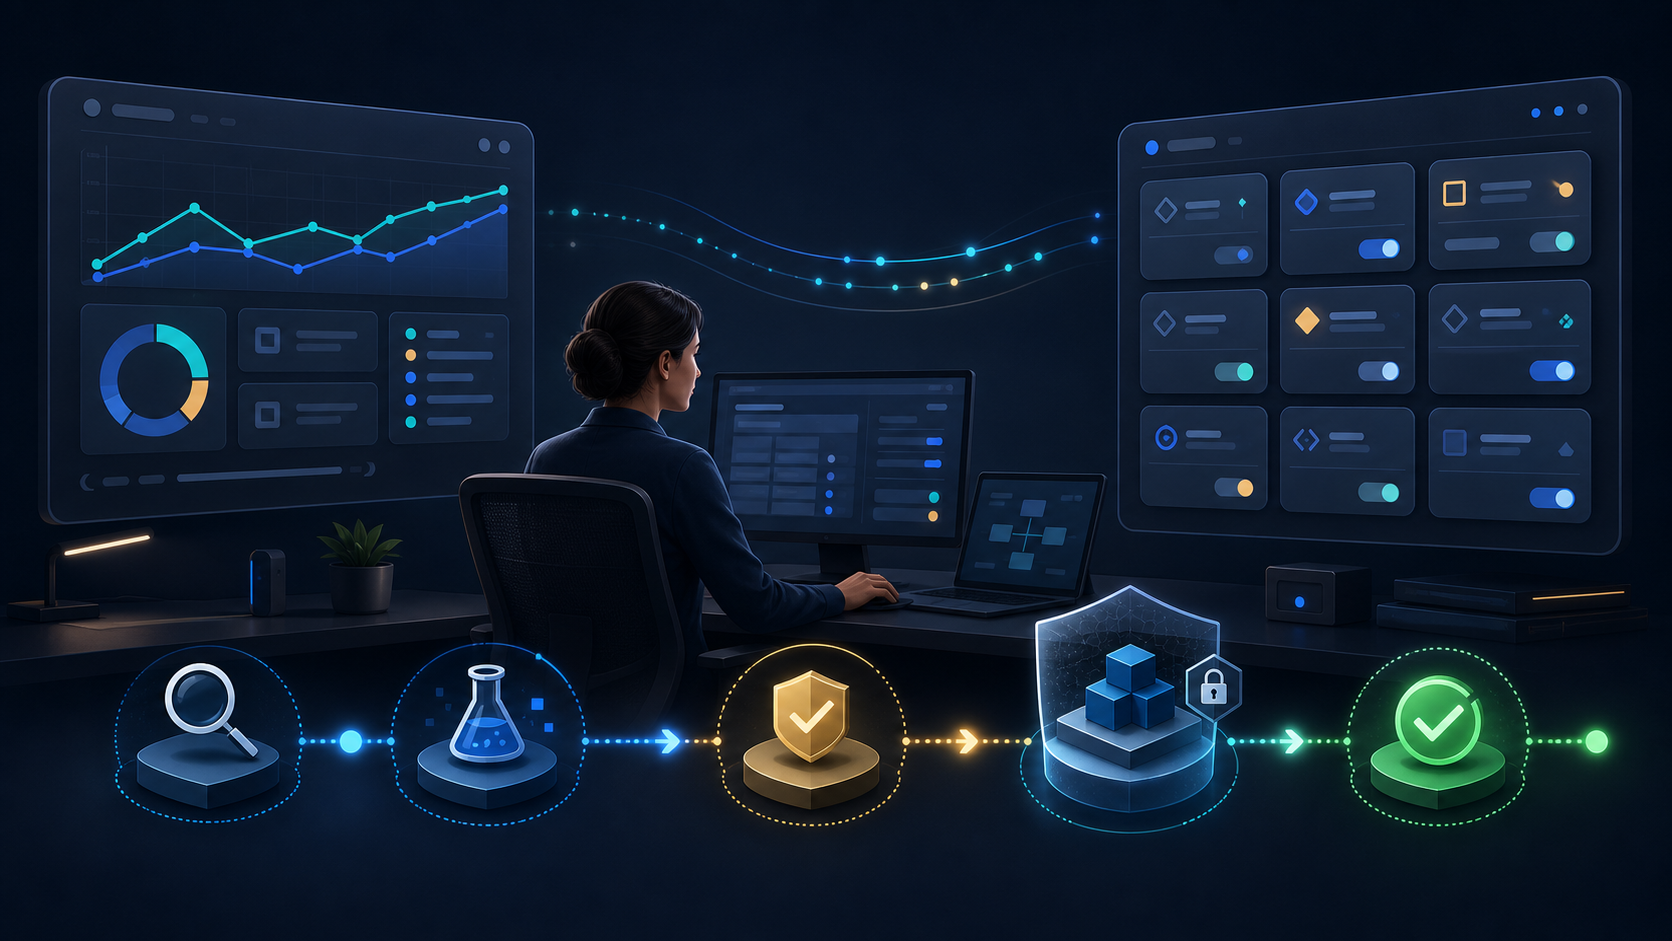
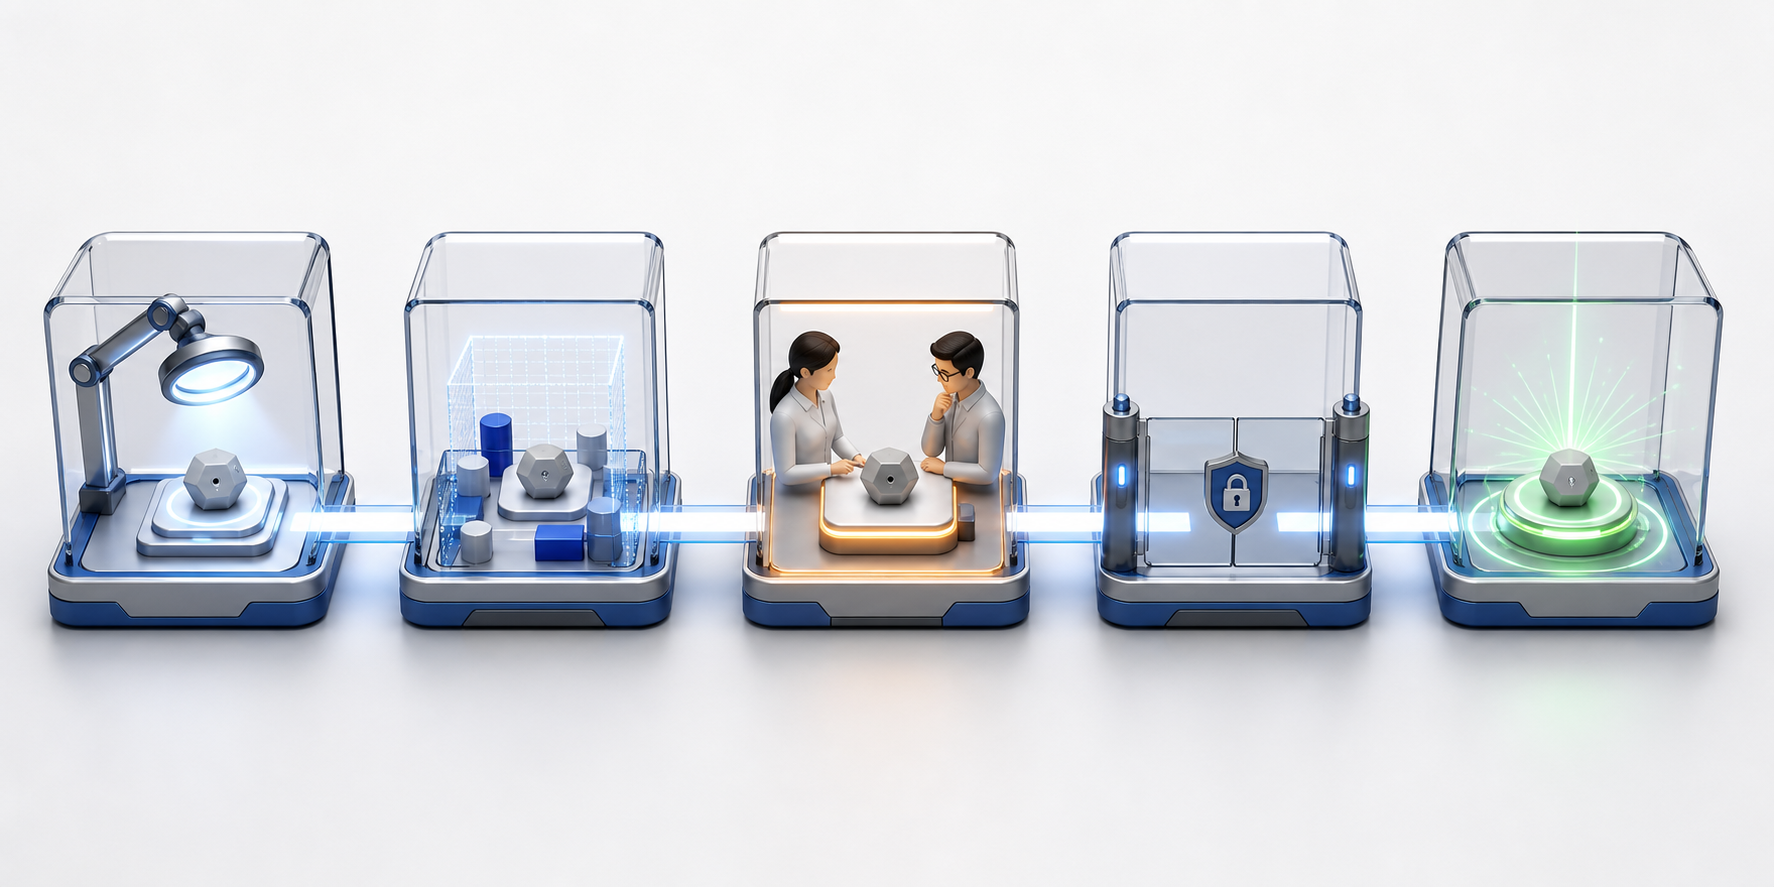
    Organize the integration into four stages:

    1. Observe: retrieve delivery evidence, performance metrics, recommendations, and the current effective settings.
    2. Diagnose: classify the issue as a message mismatch, destination mismatch, targeting problem, measurement defect, auction-access constraint, or genuine business restriction.
    3. Authorize: apply an approval rule that matches the risk. A validated tracking-parameter correction is not the same decision as excluding an entire device category or changing a bidding target.
    4. Execute and verify: write the smallest eligible change, retrieve the effective setting again, and record whether the platform accepted it.

    Keep read jobs and campaign-mutation jobs separate where your architecture permits it. At minimum, every write operation should support a dry run that shows the current value, proposed value, object scope, and affected IDs before money-moving settings change.

    Your change record should capture the platform, account, campaign or asset-group ID, scope, previous value, proposed value, reason, requester, approval status, execution result, and retrieval time. Add de-duplication in your own worker so a retry cannot apply the same logical operation twice. That record becomes essential when an automated campaign behaves differently and you need to distinguish a platform decision from a change your system made.

    Turn search-term-to-page evidence into a repair queue
    An analyst traces glowing search-signal streams to model landing pages and sorts mismatches into repair trays.

    Microsoft Advertising’s Search Term Landing Page Report connects a search term, the delivered headline, the final URL, and performance metrics in the same reporting view. That closes an important diagnostic gap: you can inspect the promise a person saw and the destination that had to fulfill it.

    Do not reduce this to a list of expensive search terms. Build a mismatch workflow that preserves the full path:

    1. Store the raw evidence. Retain the search term, delivered headline, final URL, campaign identifiers, and associated metrics. Do not substitute the headline you expected to serve for the headline that was actually delivered.
    2. Create a normalized destination key. Keep the raw URL for auditing, then create a second field that removes only parameters you have confirmed do not alter page content. A parameter that controls localization, product selection, or page state is not disposable tracking noise.
    3. Score three separate relationships. Evaluate search term to headline, headline to landing page, and search term to landing page. A relevant headline can hide a poor destination, while an acceptable page can still be introduced by the wrong promise.
    4. Join relevance to outcomes. A semantic mismatch deserves inspection, but performance data determines its operational priority. A high-volume routing defect and an isolated ambiguous query should not enter the same queue with the same urgency.
    5. Assign the repair to the correct layer. Change the eligible ad messaging when the promise is wrong, adjust routing when the destination is wrong, and revise the page when it fails to answer the intent it legitimately targets.

    Suppose a term clearly asks about pricing, the delivered headline promises pricing information, and the click reaches a generic homepage that never addresses price. The weak link is the destination. Rewriting the headline may reduce the visible contradiction, but it does not satisfy the underlying intent. Your queue should make that distinction explicit.

    SEO, AEO, and GEO teams can use the same queue to prioritize clearer on-page answers. Paid query evidence can show that demand exists and reveal the language people use, but it does not prove that a page will rank organically or be cited by an AI system. Improve the visible answer first, then describe that content accurately with metadata and structured data. Schema cannot repair information the page does not contain.

    Model PMax controls by platform, object, and scope

    Performance Max is not one uniform control surface. Microsoft is adding campaign-level device exclusions, while Google Ads API v25.2 exposes URL configuration at the asset-group level and a draft-based migration path from Smart campaigns. Treating all three capabilities as a generic PMax setting will create faulty assumptions in your interface and automation.

    CapabilityScopeWhat the API permitsHow to use it safely
    Microsoft Advertising device exclusionsCampaignExclude Computers, Smartphones, or Tablets from a PMax campaignUse only after confirming that the device itself creates a durable business constraint, rather than masking a page, tracking, consent, or attribution defect
    Google Ads PMax URL configurationAsset groupConfigure tracking templates, custom URL parameters, and final URL suffixesKeep routing and measurement rules aligned with the asset group, and test the resolved URL before activation
    Google Smart-to-PMax generationCampaign draft workflowGenerate a PMax draft from an existing Smart campaignTreat the generated object as a reviewable draft, not as authorization to launch it

    Your internal model should include at least platform, control type, scope type, scope ID, requested value, effective value, and business rationale. The interface should state plainly whether a control applies to a campaign, an asset group, or a migration draft. Scope must not be inferred from a label such as PMax control.

    Device exclusion is the highest-consequence control in this set because it removes eligible reach. Before excluding a device, verify that the apparent weakness is not caused by a slow or unusable landing experience, broken conversion tracking, a consent-flow difference, or cross-device attribution. If the problem can be repaired, fix it. If the device violates a stable operating rule, document that rule and exclude it at the campaign scope the Microsoft API actually supports.

    Google’s asset-group URL controls solve a different problem. They let you attach tracking and URL information closer to the asset grouping that uses it. Validate the fully resolved destination, preserve parameters that affect content, and test that your analytics system receives the expected values. A syntactically accepted suffix can still produce a bad measurement or routing result when combined with the base URL.

    A generated PMax draft also needs a deliberate comparison with the campaign it is replacing. Review destinations and tracking, conversion goals, geography, bidding and budget assumptions, creative assets, audience inputs, and exclusions before approval. Draft generation reduces construction work; it does not transfer accountability to the API.

    Google Ads API v25.2 is a minor release without breaking changes, but integrations still need updated client libraries and code to use its additions. It is scheduled to remain supported until August 2027, so record the API version behind every capability flag and plan the next upgrade before support ends.

    Separate audience usefulness from permission to use the data
    Abstract customer-data tokens pass through separate usefulness and permission gates before entering a campaign system.

    Microsoft’s API support for LinkedIn segment targeting can add professional audience information to programmatic campaign management. That can be useful for B2B offers, but a segment name is still a targeting hypothesis, not proof of buying intent.

    For every segment, record the business question it represents, the campaign where it is eligible, and the result you expect it to influence. Your integration should also expose how the platform treats that audience object in the selected campaign context: as a reach restriction, observation layer, or automation input. Do not let a generic audience toggle hide that distinction.

    Google Customer Match introduces a more consequential data-governance decision. Advertisers can add an IP address and interaction timestamp to customer data, but both values must be uploaded unhashed. These identifiers are not available for end users in the European Economic Area, United Kingdom, or Switzerland, so geographic eligibility has to be enforced before the export reaches Google.
    Build that upload pipeline to fail closed:

    1. Check eligibility at the record level. If your collection system cannot reliably establish that the user is outside the restricted regions, omit the IP-address field for that record.
    2. Verify notice and consent before enabling the fields. The expanded matching options require appropriate collection disclosures and consent controls. Have the privacy or legal owner responsible for your markets approve the rule before activation.
    3. Use the required file format. Customer Match files can contain eight columns, and Google requires specific English-language headers, including User IP address and User Interaction timestamp. Hashing these two fields anyway does not satisfy the specified upload format.
    4. Limit exposure. Restrict access to the unhashed export, prevent raw values from appearing in debug logs, and remove temporary files according to your approved retention policy.
    5. Log decisions rather than identifiers. Record the policy version, eligible and excluded row counts, upload result, and failure reason without copying IP addresses into the operational audit trail.

    This is one place where a larger matchable audience is not automatically a better outcome. If the regional gate, collection record, or disclosure is uncertain, omit the new identifiers and use an already approved matching path. The downside of a smaller audience is preferable to transferring data you were not authorized to use.

    Use benchmarks and bidding recommendations as questions, not commands

    Google Ads API v25.2 can return competitive benchmark percentile tiers through BenchmarksService, including comparison with all advertisers and optional category filters. A percentile supplies market context. It is not a profitability target.

    Store the comparator and category filter beside the percentile. Without them, a dashboard preserves the number but loses the population that gives it meaning. Also keep the advertiser’s own absolute outcome nearby. A relative position cannot tell you whether a campaign meets its allowable acquisition cost, margin requirement, lead-quality standard, or revenue target.

    The same discipline applies to Google’s recommendations that flag Target CPA or Target ROAS settings that may be too restrictive for a campaign to enter auctions. The recommendation diagnoses possible auction-access friction. It does not establish that loosening the target will produce economically acceptable conversions.

    Before acting on that recommendation, verify the conversion definition and tracking, calculate the CPA or ROAS boundary your economics can support, decide whether the actual problem is limited auction access or weak post-click performance, and define the acceptable change before editing the target. Store whether the recommendation was accepted, modified, or declined and why. Do not make this recommendation self-executing merely because the API makes it available.

    Key takeaways

    • Separate API observation from mutation, and preserve a before-and-after record for every campaign write.
    • Evaluate search term, delivered headline, and final landing page as three connected relationships, not as independent report columns.
    • Represent PMax controls at their real scope: Microsoft device exclusions are campaign-level, while Google’s new URL controls are asset-group-level.
    • Generate a PMax draft to reduce setup work, then review it with the same standards as a manually assembled campaign.
    • Block restricted or uncertain Customer Match records before export; IP addresses and timestamps require an unhashed, region-aware pipeline.
    • Use benchmark percentiles and bidding recommendations to frame an investigation, not to replace your own economic constraints.

    For your next integration release, keep the scope small and verifiable: add one reporting path that exposes query-to-page mismatches, one write guardrail that respects the platform’s actual control scope, and one hard eligibility gate around customer-data uploads. Expand automation only after those three paths produce auditable results.

    References


  • Microsoft Synthetic Ad Disclosure Rules: A Practical Workflow

    Microsoft Synthetic Ad Disclosure Rules: A Practical Workflow

    Your designer used generative fill, your editor replaced a voice segment, or your campaign team built an image from an AI prompt. Now you need to decide whether the ad can run on Microsoft Advertising, whether it needs a disclosure, and what evidence you should keep.

    Make that decision before the final export. A disclosure added at the upload screen cannot recover missing permission, removed provenance data, or a misleading depiction. The workable approach is to review AI involvement, accuracy, authorization, disclosure, and provenance as separate controls.

    Start with AI involvement, not whether the ad looks artificial

    Microsoft Advertising places AI-generated, AI-manipulated, and other synthetic content within its policy scope. When AI helped create or materially alter an ad, the audience may need to be told.

    That does not mean every use of AI automatically receives the same label. It means every use should receive a disclosure determination. If your media buyer first learns about the AI work after receiving the finished asset, the review has started too late.

    Add these questions to the creative brief:

    • Did AI generate any copy, image, video, audio, voice, person, product, setting, or event shown in the ad?
    • Did AI materially change recorded or photographed material, even if the original was real?
    • Could the finished creative make a viewer believe that a real person said, did, endorsed, or experienced something?
    • Does it reproduce or simulate an identifiable person’s likeness or voice?
    • Which countries or regions will receive the campaign?
    • Does the working file contain watermarks, metadata, or other provenance information that must survive production?

    For an internal materiality test, ask whether the AI work could change what a reasonable viewer believes about a person, product, place, claim, or event. A background cleanup is not operationally equivalent to fabricating a product demonstration or making a person appear to deliver a statement. This is a practical escalation test, not a universal legal definition. When the answer is unclear and the campaign carries rights or regulatory exposure, have counsel qualified in the relevant market review it.

    Treat compliance as four separate approval gates

    The common mistake is to treat an “AI-generated” label as a complete compliance solution. It is only one control. Your ad should pass four gates independently.

    1. Accuracy and eligibility

    Review the people, products, places, claims, and events depicted in the creative. Microsoft expects advertisers to check that those elements are accurate before submission. A disclosure explains how content was made; it does not make a false claim, prohibited deepfake, or deceptive demonstration acceptable.

    Run the review against the finished ad, not just the prompt. Generative systems can introduce details that nobody explicitly requested, so prompt approval is not creative approval. Compare the final asset with the real product, approved claim language, authorized spokesperson material, and the event or location it purports to show.

    2. Authorization

    Confirm that you have any permission required to use a person’s likeness or voice. Advertisers remain responsible for applicable laws in every market where a campaign appears, including requirements involving consent, permissions, disclosures, likenesses, and voices.

    Do not infer authorization from access to a photograph, recording, stock asset, or previous campaign file. Document what was authorized, for which media and markets, and whether synthetic alteration or voice replication falls within that authorization. If the permission does not clearly cover the planned use, pause the ad rather than relying on a label to fill the gap.

    3. Consumer disclosure

    Determine whether a visible or audible disclosure is required for that asset, format, and market. When notice is required, it must be clear and positioned close to the content it explains. Permission from the depicted person does not eliminate a separate disclosure obligation.

    4. Machine-readable provenance

    Preserve watermarks, metadata, and other available signals identifying how synthetic content was created. These signals support provenance, but they are not necessarily visible to a consumer. Passing the provenance gate therefore does not mean you have passed the disclosure gate.

    Approve the ad only when all four gates pass. That structure prevents a reviewer from answering one narrow question – “Does it have a label?” – while missing the reason the ad should not run at all.

    Put the disclosure where the consumer encounters the synthetic content

    A person views a tablet ad with an abstract disclosure symbol placed directly beside the synthetic image.

    An AI note in a production ticket, file name, landing-page footer, or internal media plan is not a consumer-facing disclosure. When disclosure is required, Microsoft recommends embedding it directly in image and video assets. Microsoft Advertising’s disclaimer feature can also be used with formats that support it.

    Use this placement process:

    1. Add the approved disclosure to the asset master, not only to one exported placement.
    2. Keep it close to the synthetic element or claim it qualifies. Do not make the viewer search another screen for the explanation.
    3. Match the disclosure mode to the experience. Image and video disclosures need to be visible; audio-led creative may also require an audible notice.
    4. Export every required size and format, then inspect the actual output. Cropping, compression, scaling, captions, and interface overlays can make a disclosure unreadable or separate it from the relevant content.
    5. Where the Microsoft Advertising disclaimer feature is supported, decide whether it should supplement or deliver the required notice for that format. Do not assume feature availability removes the need to inspect the consumer-facing result.
    6. Record the approved wording, placement, disclosure mode, markets, formats, and approver so later adaptations do not silently change the decision.

    Do not invent a single global font size, duration, or phrase and treat it as universally sufficient. The governing requirement is that the disclosure be clear, close to the relevant content, and compliant wherever the campaign runs. If a local rule or approval imposes more specific wording or presentation, carry that requirement into the asset specification.

    Localization deserves a new review. Translated wording can become longer, a resized layout can push the label out of view, and a newly added market can change the applicable requirement. Treat each of those changes as a controlled version, not a harmless derivative.

    Protect provenance and permission records throughout production

    A creative team preserves connected provenance markers while storing permission and approval records in a secure archive.

    Images, audio, and video created with Microsoft AI tools can contain machine-readable provenance data, metadata, and imperceptible watermarks indicating AI involvement. Because those signals may not be apparent to the audience, you may still need a separate visible or audible disclosure.

    Your production workflow should preserve both the technical evidence and the human approval record:

    • Keep the original AI output before retouching, resizing, or re-encoding.
    • Retain the working file and submitted export so reviewers can trace what changed.
    • Do not deliberately remove a watermark, metadata field, or provenance signal merely to make the file look cleaner.
    • Check whether your export process retained the provenance information present in the source asset.
    • Store documented likeness and voice authorization with the creative record, including any limits relevant to synthetic alteration.
    • Keep the market-by-market disclosure decision with the exact asset version it covers.
    • Save evidence of how the consumer-facing disclosure appears in the final format.

    This record is useful only if versioning is disciplined. A later editor should be able to tell whether a new crop, translated label, revised voice track, or altered product scene reopened one of the four approval gates. “Approved” should never float free of a specific file and campaign scope.

    Interfering with machine-readable provenance information is not a harmless optimization. Along with prohibited deepfakes, impersonation, unauthorized use of a likeness or voice, and omitted required disclosures, it can contribute to an ad being rejected, restricted, or removed.

    Use a repeatable approval workflow before every submission

    Build the review into campaign operations instead of asking the media buyer to reconstruct the creative history at launch. The following workflow is specific enough to assign owners and flexible enough to use across image, video, audio, and copy-led ads.

    1. Inventory AI involvement. Record which portions of the ad were generated or materially altered and retain the original outputs.
    2. Map distribution. List the markets, languages, Microsoft Advertising formats, and derivative sizes planned for the campaign.
    3. Challenge accuracy. Verify every depicted person, product, place, claim, and event against approved factual material.
    4. Clear rights. Confirm that any likeness or voice use has the authorization required for the specific synthetic use, media, and market.
    5. Screen for stop conditions. Do not submit deceptive creative, prohibited deepfakes, impersonation, or unresolved unauthorized use merely because a disclosure can be added.
    6. Make the disclosure decision. Determine the required wording, visible or audible treatment, proximity, and market coverage. Escalate unresolved legal questions to qualified counsel.
    7. Build the notice into production. Embed it in image or video assets when required and configure the platform disclaimer feature where supported and appropriate.
    8. Run final-output quality assurance. Confirm that the disclosure remains clear and close to the relevant content and that provenance information has not been stripped.
    9. Approve a specific version. Store the decision, evidence, permissions, asset identifier, formats, markets, and approver together. Reopen review after any material creative or distribution change.

    If an ad fails because its underlying depiction is deceptive or unauthorized, rebuild or withdraw it. Relabeling is not remediation. Microsoft is allowing AI-assisted advertising, but an AI disclosure does not make deceptive creative acceptable.

    Key takeaways

    • Route every AI-generated or materially altered ad through review, even when the synthetic work is difficult to notice.
    • Assess accuracy, authorization, disclosure, and provenance separately; success in one area does not cure failure in another.
    • When disclosure is required, make it clear, close to the relevant content, and part of the asset where appropriate.
    • Preserve metadata, watermarks, and other provenance signals, but do not mistake them for consumer-facing notice.
    • Do not use a label to justify a deepfake, impersonation, deceptive claim, or unauthorized likeness or voice.
    • Repeat the determination for each market, format, language, and materially changed creative version.

    Your next move is concrete: add five required fields to the creative intake form – AI involvement, likeness or voice use, target markets, disclosure decision, and provenance status. Assign an owner to each field before the asset enters paid-media production. That small change moves compliance from a last-minute label request to a reviewable part of how the ad is made.

    References


  • AI Training Data Licensing: A Practical Guide for Brands

    AI Training Data Licensing: A Practical Guide for Brands

    If an AI company asks to train on your content archive, the first question should not be, “What should we charge?” It should be, “What exactly would we be allowing, and do we control every item we plan to deliver?” Pricing before answering those questions is how a promising data deal becomes a rights problem.

    You need a way to separate legitimate commercial value from vague promises about “AI exposure.” The process below will help you audit the material, define the permitted uses, structure compensation, protect your brand, and decide whether the proposed license deserves to move forward.

    First determine whether your content is actually licensable

    The commercial backdrop is changing: AI labs are paying for curated, high-quality data instead of depending only on scraping. That does not make every large archive a valuable training corpus. A buyer needs content it can lawfully use, reliably process, and connect to a defined model or product objective.

    Start with a rights inventory, not a page count. Your CMS may contain material created under several different arrangements, even when all of it carries your branding. Employee-written copy, commissioned work, syndicated material, customer submissions, licensed photography, embedded media, and acquired archives can each carry different permissions.

    1. Divide the archive into meaningful content classes, such as editorial text, product data, customer questions, reviews, research records, images, audio, and video transcripts.
    2. Identify who created each class and the agreement that governs it. Record whether you own the relevant rights or merely have permission to publish it in a particular channel.
    3. Mark third-party elements inside otherwise original pages. A page you own can still contain a photograph, quotation, data table, or embedded asset that is outside your licensing authority.
    4. Separate confidential, personal, regulated, and user-submitted information from content already approved for commercial reuse. Public visibility is not proof of permission for model training.
    5. Create an exclusion list for anything with missing agreements, disputed ownership, unclear consent, contractual restrictions, or an unacceptable privacy risk.

    Do not rely on a copyright notice, a byline, or administrative access to the CMS as evidence that you can license an item for machine learning. If ownership, privacy, or consent is unclear, hold the material out until qualified intellectual-property or privacy counsel confirms how it may be used. Otherwise, you may be promising rights that your organization does not possess.

    Audit usefulness as well as ownership

    A legally clean collection can still be difficult to use. Training-data buyers benefit from records that are consistent, attributable, documented, and easy to update. Before discussing a license, examine whether you can deliver the following:

    • A stable identifier for every record, independent of a changeable page title or URL.
    • Clean primary content separated from navigation, advertising, comments, and duplicated boilerplate.
    • Reliable metadata for content type, language, publication date, revision date, author or publisher, and canonical URL.
    • A documented origin and rights basis for each content class.
    • Version history that shows what changed and when.
    • A consistent method for issuing additions, corrections, withdrawals, and deletions.
    • Clear definitions for fields, labels, categories, and any editorial annotations.
    • A manifest that lets both parties confirm exactly which records appeared in each delivery.

    This work affects both value and risk. A smaller corpus with dependable rights and metadata may be more usable than a much larger archive full of duplicates, unexplained fields, and uncertain ownership. It also lets you create separate licensing tiers instead of placing the entire archive into one irreversible package.

    Separate the AI permissions that vague contracts bundle together

    A sealed archive case connects to five separate transparent pathways, each controlled by its own valve and lock.

    “Use our content for AI” is not a workable grant of rights. A single URL can be crawled for discovery, stored in a retrieval index, used to evaluate answers, included in model training, displayed as a quotation, or transformed into another dataset. Those activities have different commercial consequences and should not be treated as one permission.

    ActivityWhat you need to define
    Public crawling and indexingWhich properties may be fetched, how often access occurs, what may be cached, and whether the purpose is search, retrieval, or another named function.
    Retrieval for generated answersWhat content may be stored and retrieved, how current it must remain, how excerpts are displayed, and whether answers include attribution and a link.
    Foundation-model trainingWhich model families, versions, products, and purposes may learn from the corpus, including whether commercial deployment is permitted.
    Fine-tuning or adaptationWhich named model or application may be adapted, who may operate it, and whether the adapted model may be transferred or reused elsewhere.
    Evaluation and safety testingWhat tests may use the data, how long test copies are retained, who can review outputs, and whether the material can later move into training.
    Output displayWhether the product may quote, summarize, reproduce, translate, or otherwise present the content, along with attribution and linking requirements.
    Synthetic or derivative dataWhether transformed records may be created, retained, combined with other datasets, sublicensed, or used after the original license ends.

    These distinctions also matter for AI search visibility. Training does not, by itself, guarantee that a model will cite your site, link to a page, use the current version, or represent your brand faithfully. If your business goal is discoverability, retrieval and output-display terms may matter more than a broad training grant.

    Turn the permission into a bounded scope

    A usable proposal should identify the parties, the data, the technology, the purpose, and the duration without forcing you to infer any of them. Require clear answers to these questions before quoting a price:

    • Which legal entity receives the license, and may its affiliates, contractors, hosting providers, or customers access the data?
    • Which records and versions are included? Does the grant cover one delivery, scheduled updates, or everything you publish in the future?
    • Which model families, checkpoints, applications, and product surfaces may use the corpus?
    • Is the use limited to internal development, or does it include commercial products offered to customers?
    • May the buyer combine the corpus with other data, create embeddings, produce annotations, or generate derivative datasets?
    • May the data or anything derived from it be transferred, assigned, sold, or sublicensed?
    • Is the license exclusive? If so, what subject, market, product, geography, language, and time period does the exclusivity cover?
    • What uses are expressly prohibited, including products designed to replace your publication, impersonate your brand, or expose restricted material?
    • What survives expiration or termination: raw files, retrieval indexes, embeddings, trained models, checkpoints, backups, derived datasets, or deployed products?

    A phrase such as “all artificial-intelligence purposes” gives the buyer flexibility by moving uncertainty onto you. Replace it with named uses and named products. If the buyer cannot identify the intended model, purpose, retention period, or downstream recipients, you do not yet have enough information to assess the risk or calculate a defensible fee.

    Price the defined scope, not the size of the archive

    There is no responsible universal price per page, word, or record. Volume affects processing costs, but it does not capture scarcity, freshness, rights quality, exclusivity, labeling, or the commercial freedom a license gives the buyer.

    Build your internal price floor from the work and exposure the deal creates. Include rights review, data cleaning, redaction, formatting, secure delivery, engineering support, update handling, reporting, contract administration, and the opportunity cost of restrictions placed on future deals. Then evaluate the buyer’s requested scope separately.

    • Uniqueness: Is the information readily available elsewhere, or does your organization hold a difficult-to-recreate collection?
    • Quality: Is the material edited, labeled, deduplicated, and accompanied by dependable metadata?
    • Freshness: Is this a historical delivery, or will your team provide continuing corrections and new records?
    • Rights assurance: How much review has been completed, and how broad a warranty is the buyer requesting?
    • Permitted use: Evaluation carries a different commercial footprint from unrestricted commercial training and deployment.
    • Downstream reach: Will one team use the corpus, or can affiliates, customers, contractors, and sublicensees benefit from it?
    • Exclusivity: What future buyers, products, markets, or partnerships would you be giving up?
    • Duration and survival: Does the buyer receive temporary access, or can trained and derived assets remain in service indefinitely?
    • Operational burden: How much continuing delivery, support, auditing, correction, and incident response will your team owe?

    Compensation can take several forms. A fixed fee is simple but must be tied to a fixed scope. A usage-based fee can expand with deliveries, records, model runs, or products, but only if the usage can be measured and audited. A minimum guarantee plus variable payments can cover your baseline work while preserving participation in broader use. Revenue sharing can align incentives, but it becomes fragile when revenue attribution is vague. Whichever structure you choose, define the measurement method, reporting schedule, audit rights, payment trigger, and treatment of disputed calculations.

    Negotiate in an order that preserves leverage

    1. Set your non-negotiable exclusions, privacy boundaries, brand protections, and prohibited uses.
    2. Obtain the buyer’s written description of the model, product, users, purpose, and data flow.
    3. Offer a specific corpus tier rather than opening the entire archive by default.
    4. Price the narrow base use first.
    5. Price additional models, products, affiliates, territories, updates, derivative data, and exclusivity as separate expansions.
    6. Require written approval and additional compensation before the buyer crosses from one tier into another.

    Watch for terms that make a seemingly attractive payment disproportionate to the rights surrendered. Common warning signs include perpetual and irrevocable use across undefined AI systems, automatic rights to all future content, unrestricted sublicensing, vague exclusivity, unilateral changes to the use case, broad warranties about third-party material, and liability that is uncapped or disconnected from your control. These are legal and financial exposure points, so have qualified counsel assess the actual agreement rather than relying on a commercial checklist alone.

    Build operational controls around the contract

    A legal, content, and technical team monitors a controlled data transfer into a locked server enclosure in a secure data room.

    A signed license is only useful if both parties can administer it. The contract may say that one content class is excluded, for example, while the export pipeline quietly delivers it with everything else. Connect each important term to a technical control, an owner, and a record that can later show what happened.

    • Attach a dataset schedule describing included content classes, excluded classes, fields, formats, languages, and delivery frequency.
    • Generate a manifest for every delivery with stable record IDs, versions, timestamps, and license status.
    • Keep approval records for additions and document every correction, withdrawal, and deletion request.
    • Specify access controls, approved storage locations, security duties, incident notification, and whether the corpus must remain segregated from other collections.
    • Require usage reports that correspond to the pricing and scope terms, including the models, products, recipients, and dataset versions involved.
    • Assign responsibility for rights questions, privacy requests, technical delivery, invoices, audits, brand issues, and termination.
    • Create a change process for new products, model families, acquisitions, corporate reorganizations, and transfers to another operator.
    • Schedule periodic reviews so a narrow experiment does not quietly become a broader production use without new approval.

    Deleting delivered files does not by itself reverse model training that has already occurred. Treat raw data, embeddings, derivative datasets, model checkpoints, future model releases, backups, and deployed products as separate post-termination states. The agreement should say which states may continue, which must stop, which must be deleted where technically applicable, and what evidence the buyer must provide. Resolve this before delivery, because the available remedies may be narrower after training begins.

    Protect AI visibility as a separate outcome

    If your objective includes visibility in AI answers, put that outcome into the deal rather than assuming it follows from training access. Consider terms covering attribution wording, canonical links, use of your current brand and entity names, update handling, correction escalation, and reporting on answer displays or citations where the product can measure them.

    You may also want a retrieval feed that remains distinct from the training corpus. A retrieval system can consult current records when producing an answer, while a trained model reflects an earlier training process. Keeping those permissions separate lets you negotiate freshness, citation, withdrawal, and link behavior without granting every training right at the same time.

    Your publishing infrastructure still matters outside the license. Maintain stable canonical URLs, explicit publisher and author information, clear publication and revision dates, consistent entity names, and structured data that agrees with the visible page. Provide machine-readable correction and withdrawal signals where your workflow supports them. Monitor priority questions to see whether AI products identify your brand, use current facts, and link to the intended page.

    Keep the three control layers distinct. Structured data describes the meaning and relationships on a page; it does not transfer content rights. Site access controls regulate automated access; they are not a substitute for negotiated permission. The license defines authorized uses between the contracting parties. Treating any one layer as if it performs all three jobs creates gaps.

    Key takeaways

    • Audit ownership, third-party rights, consent, privacy, and contractual restrictions before offering an archive.
    • Exclude uncertain material instead of representing that you control rights you may not have.
    • Separate crawling, retrieval, training, fine-tuning, evaluation, output display, and derivative-data permissions.
    • Define the receiving entities, dataset versions, models, products, purposes, duration, downstream users, and post-termination treatment.
    • Price legal review, preparation, delivery, governance, commercial scope, exclusivity, and continuing obligations rather than relying on content volume alone.
    • Connect every important contract restriction to a technical control, responsible owner, usage record, and review process.
    • Negotiate citation, linking, freshness, brand representation, and correction workflows explicitly when AI visibility is part of the business case.

    Your next move is to create a one-page licensing brief before discussing price. List the proposed corpus, excluded material, rights basis, permitted AI activities, prohibited uses, buyer entities, model or product scope, delivery schedule, duration, post-termination states, visibility requirements, and internal approval owners. Have the appropriate rights, privacy, technical, commercial, and legal stakeholders review that brief.

    If the buyer can answer those points, you can negotiate a bounded transaction. If it cannot, keep narrowing the request. The valuable asset is not merely a large body of content. It is a defensible, structured, maintainable corpus offered under terms your organization can actually enforce.

    References


  • How to Build Connected Customer Profiles From Marketing Data

    How to Build Connected Customer Profiles From Marketing Data

    Your analytics platform records a purchase. Your ad platform records a conversion. Your loyalty system recognizes a member. Your point-of-sale system knows what was sold. Yet when you try to decide whether that person is a new prospect, a regular buyer or someone drifting away, the systems give you different answers.

    You don’t solve that problem by collecting more events. You solve it by giving each event a clear meaning, connecting it to the right identity, carrying consent through the connection and turning the resulting history into signals that can change a marketing decision.

    Key takeaways

    • Event capture and profile connection are separate quality layers. A perfectly recorded purchase can still land on the wrong profile.
    • Measure identity coverage as the share of relevant transactions attached to a known customer, not the number of people enrolled in a loyalty program.
    • Start with a marketing decision, then specify the event, identity, profile attribute, freshness and consent required to make it.
    • No-code tagging can simplify deployment, but it doesn’t define what an event means or prove that the event is accurate.
    • Different customer attributes need different refresh schedules. A missed purchase may matter immediately, while category affinity normally changes across repeated purchases.
    • Keep unknown customers separate from confirmed first-time customers. Treating unresolved identity as proof of newness corrupts acquisition decisions.

    Design the marketing decision before you design the data capture

    A conversion feed can contain product choices, basket value, discounts, channel, location and other transaction details. That still doesn’t reveal the customer’s relationship with the business. A $100 order from a first-time buyer and a $100 order from a frequent buyer look the same when history is missing, even though you should not necessarily advertise to those people in the same way.

    This is why a connected customer profile should begin with a decision contract, not a request to collect everything. The contract states what marketing is trying to change and the minimum data needed to make that change responsibly.

    1. Name the action. Be precise: suppress an existing customer from acquisition, include a lapsed customer in reactivation, select an eligible loyalty offer or adjust conversion-value optimization.
    2. Define the eligible population. State who may enter the decision and who must be excluded because of consent, geography, account state or insufficient identity.
    3. Identify the event that supplies evidence. A confirmed purchase, authenticated session or loyalty identification is evidence. A page view near the checkout is not proof of an order.
    4. Choose the identity requirement. Specify which authenticated account, loyalty or transaction identifier can connect the event to a profile. Also define what happens when that identifier is missing.
    5. Define the profile attribute. Write down how the system distinguishes first-time, repeat, active or lapsed customers and which events are allowed to change that status.
    6. Set the freshness requirement. Ask how old the event or derived attribute can be before the marketing action becomes misleading.
    7. Record the permitted use. State which destinations may receive the event, profile attribute or audience and which consent or governance condition must be satisfied.
    8. Choose the success measure. Evaluate the marketing decision that changes, not merely whether another field was added to a profile.

    For an acquisition-suppression use case, the action might be to exclude established buyers from campaigns intended only for new customers. The required evidence is confirmed purchase history connected to a reliable identity. If the transaction cannot be resolved, the safe data classification is unknown, not first-time. The profile can enter the suppression audience only when the status is current, the audience rule is valid and the intended advertising use is permitted.

    That distinction prevents a common measurement failure. When unknown and new are collapsed into one value, improvements in identity coverage appear to change customer composition even if actual buying behavior has not changed. Give unknown its own state in reports, audiences and quality checks.

    Capture events once, then validate their meaning everywhere

    Give every decision-critical event a contract

    A tag firing is a transport result. It doesn’t prove that the event represents the business outcome you intended. Before anyone configures a visual selector, tag or software development kit, create an event contract containing:

    • A canonical event name with one business meaning across web, app and physical channels.
    • The condition that confirms success. For a purchase, that should reflect a completed transaction rather than an early checkout interaction.
    • The occurrence time and the originating channel or system.
    • The stable event or transaction identifier used to detect repeat delivery.
    • The authenticated, loyalty, customer or anonymous identifiers available at that moment.
    • Only the properties required by an approved use case, such as product, basket, discount or location context.
    • The consent, purpose or permission context that controls collection and downstream activation.
    • The destinations authorized to receive the event.
    • An owner who approves changes to the event’s definition.

    Use the same canonical event when the same business outcome occurs in different interfaces. Channel belongs in a property; it should not force every team to invent a different definition of purchase. If the web team calls an order purchase, the app team calls it checkout_complete and the point-of-sale team calls it sale_closed, identity resolution may work while profile calculations still disagree.

    Also decide how duplicate delivery is handled. Browser retries, destination forwarding and overlapping implementations can produce more than one record for the same outcome. The profile layer needs a stable transaction or event key so a retry doesn’t become another purchase in cadence, value or repeat-buyer calculations.

    Treat no-code tagging as an implementation aid

    Google’s unified tagging direction makes implementation more accessible. Existing Google tags are being upgraded into capable Google Tag Manager containers, bringing interface-driven configuration, debugging and version control into a more unified setup. Google has also introduced visual event creation that lets an operator navigate a site and select elements while the system handles selectors and triggers.

    That can reduce the coding needed to deploy an event. It doesn’t answer whether clicking the selected element proves a conversion, whether the same interaction exists in an app or store, whether the event will fire twice, or whether the attached identifier and consent state are valid. Set the event contract first, then use visual tagging to implement the approved condition.

    The updated setup can also provide a visual map of the Google destinations receiving measurement data. Optimized containers may send data directly to those destinations instead of loading additional gtag.js code, which Google says can reduce measurement latency and potentially improve site performance. Treat the destination map as part of release review: every expected destination should be present, and every unexpected destination should be investigated before publication.

    If you already run a sophisticated Tag Manager container, don’t publish an optimization proposal on the assumption that a simpler configuration is identical. Optimization is optional, and authorized users can preview proposed changes before publishing. Existing event tags are intended to remain unchanged, but initialization and account-linking behavior still deserve review.

    Pay particular attention to deployment code. Google’s announced direction moves new snippets toward a shared format without the gtag config command and recommends the gtm init trigger for initialization behavior. A legacy setup that still depends on the config command can be configured to wait for it. Document that dependency before migration so a cleanup doesn’t silently change consent initialization, configuration order or event availability.

    Before publishing any capture change, run the actual customer path and verify the business result, not just the debug console. Confirm that the event fires once, carries the expected transaction and identity keys, excludes unapproved properties, reaches only approved destinations and remains consistent after navigation or refresh. Save the reviewed container version so the release can be traced and reversed if validation fails.

    Connect interactions to a governed customer identity

    Retail and digital interaction objects pass through a protected matching hub and connect to one customer silhouette.

    Measure identity coverage, not enrollment

    Ecommerce accounts and subscription relationships often provide authentication by design. Physical retail, grocery and quick-service transactions are harder because a purchase can happen without identification. Loyalty can bridge that gap when a member identifies at the register, in an app or during a drive-through transaction.

    A large loyalty membership total doesn’t show whether purchase history is connected. The operational metric is the share of transactions that arrive with a customer attached.

    Identity coverage = identified eligible transactions divided by all eligible transactions.

    Define eligible for your business before using the ratio. It should represent transactions in which your measurement design provided a legitimate opportunity to identify the customer. Then segment coverage by channel, device, store, checkout path or other operational handoff. The aggregate rate can look stable while one important path fails to collect or transmit an identifier.

    Coverage alone isn’t enough. A transaction can contain an identifier and still connect to the wrong profile. Track at least three separate outcomes: identified and resolved, identified but unresolved, and anonymous. That separation tells you whether the problem sits in collection, transport or identity matching.

    Make identity joins explainable and correctable

    Keep raw identifiers and the connected profile identifier as separate fields. The raw values show what each system observed; the profile identifier shows the result of resolution. If you overwrite the former with the latter, it becomes difficult to explain a bad merge or repair customer history later.

    • Prefer authenticated or directly captured relationships when linking activity to a known profile.
    • Record which identifier and originating system caused each link.
    • Define what evidence permits two records to merge and what evidence requires them to split.
    • Preserve the time of the link so historical calculations can be reproduced.
    • Do not label an unresolved identifier as a new customer merely because no history was returned.
    • Provide a correction path for shared accounts, recycled identifiers, entry errors and other bad joins.

    Consent must travel with this process. A profile join can turn previously disconnected activity into a more revealing customer history, so it can expand the consequences of a permission error. Store the relevant permission and permitted-use context with identifiers and events, enforce it before audience activation and have the appropriate privacy or legal owner validate retention and use rules for your business. A separate consent database that isn’t consulted during the join or audience sync does not protect the downstream decision.

    The final test is continuity. A register transaction, app session and loyalty account create connected history only if they resolve to the intended profile, appear soon enough for the marketing decision and retain the same governance rules wherever they are used.

    Turn connected history into fresh, usable marketing signals

    A sequence of customer interactions passes through a glowing prism and emerges as three illuminated marketing signals beside a customer silhouette.

    Once events are connected, keep three data layers distinct. They have different owners, update patterns and failure modes.

    Data layerWhat belongs in itQuestion it must answer
    Identity and governanceIdentifiers, consent, permitted uses and relationships among profilesMay this activity be joined and used for this purpose?
    Loyalty program stateTier, points balance, reward eligibility, redemption history and tenureWhat program status or benefit currently applies?
    Derived attributesPurchase cadence, time between orders, category affinity, time and location patterns, channel mix and offer responseWhat does connected behavior imply for the next marketing decision?

    The third layer makes history actionable, but only when freshness matches the behavior. Purchase cadence can produce a signal when nothing happens. If a customer usually buys on a recurring pattern and then misses expected purchases, no new transaction arrives to trigger an update. A scheduled calculation must detect the absence. Category affinity changes differently: repeated purchases can establish or shift a preference, while an isolated purchase should not automatically redefine the profile.

    Don’t assign one universal refresh schedule to every attribute. Work backward from the decision. An exclusion used by an active acquisition campaign may need recent purchase status. A category preference built across a longer history can change more gradually. The right interval depends on your observed buying cycle and how quickly a stale value can cause the wrong action.

    Give every derived attribute its own contract:

    • A plain-language definition that marketing, analytics and engineering interpret the same way.
    • The qualifying events and event properties used in the calculation.
    • The identity coverage required before the result is considered usable.
    • The update mode: event-driven, scheduled or both.
    • The condition that makes the value stale or unknown.
    • The allowed marketing destinations and permitted purposes.
    • The fallback when history is incomplete, delayed or contradictory.
    • The owner responsible for validating changes to the logic.

    Activation should preserve those definitions. If repeat-buyer status means one thing in analytics and another in the ad audience, the profile is not truly connected at the decision layer. Use a shared, versioned rule or prove that each destination implements an equivalent rule.

    • Acquisition suppression: use confirmed, sufficiently current customer history; never assume unresolved means new.
    • Reactivation: use a cadence or inactivity signal that is recalculated even when no new event arrives.
    • Category messaging: require enough connected history to distinguish a repeated preference from an isolated purchase.
    • Loyalty treatment: use current program state rather than recreating tier or reward rules inside each advertising destination.
    • Conversion-value optimization: document which profile signal changes the value and how stale, missing or disallowed data is handled.

    Audit one customer journey from capture to activation

    A dashboard can show healthy event volumes while a profile, audience or consent handoff is broken. Use a governed test profile and trace one complete journey through the system:

    1. Complete the intended interaction through the real web, app, loyalty or point-of-sale path.
    2. Confirm that the canonical event appears once with the expected occurrence time, transaction key, properties and consent context.
    3. Verify that the captured identifier resolves to the intended profile and that the resolution method is recorded.
    4. Inspect the connected history to make sure the event appears once and in the correct order.
    5. Run or wait for the relevant derived calculation, including any scheduled logic required to detect inactivity.
    6. Evaluate the audience or decision rule and confirm that unknown, stale and disallowed states follow their documented fallback.
    7. Verify that only approved destinations receive the event, attribute or audience membership.
    8. Change or withdraw the test permission where your system supports it, then confirm that downstream activation respects the new state.

    Run that trace after changes to tags, identity rules, profile calculations, consent handling or audience logic. Volume monitoring should remain in place, but an end-to-end trace reveals whether all the individually healthy components still produce the intended customer decision.

    Your next move is deliberately narrow. Choose one campaign in which a first-time customer and an established customer should be treated differently. Write the decision contract, instrument the minimum required event and trace one test profile from capture to destination. Expand to another signal only after you can explain every identity join, freshness rule, permission check and fallback on that path.

    References


  • Google Ads Audience Targeting for Higher-Quality B2B Leads

    Google Ads Audience Targeting for Higher-Quality B2B Leads

    Your Google Ads dashboard can say a B2B campaign is working while your CRM says otherwise. If bidding rewards every form submission equally, Google learns to find people who complete forms – not companies that qualify, reach an opportunity stage, or buy.

    The fix is not simply tighter audience targeting. You need a chain of signals that connects consented first-party data, meaningful funnel events, realistic bidding targets, and controlled audience expansion. Build that chain before asking Google Ads to find more people.

    Key takeaways

    • Make qualified leads, opportunities, and sales visible to Google Ads before expanding your audience. A form fill alone teaches the system to maximize form fills.
    • Give each first-party audience one job: exclusion, reacquisition, re-engagement, retention, or a high-quality signal. Do not merge customers, qualified prospects, and raw leads into one list.
    • Audit campaigns that use tCPA or tROAS and carry a Limited by budget status. An old target can direct new spend toward traffic that satisfies the platform target without improving pipeline economics.
    • Treat Enhanced matching for Customer Match as an opt-in experiment if it appears in your account. Its incremental reach, participating publishers, and precise matching behavior have not been publicly detailed.
    • Judge AI-driven expansion by qualified pipeline and revenue signals. Lower CPC, more clicks, and more form submissions can coexist with a worse cost per lead or weaker sales outcomes.

    Start with the conversion Google Ads is actually learning from

    A circular optimization loop connects a visitor, form submission, reviewed contact, business opportunity, and completed agreement, with signals flowing back toward a central targeting engine.

    Audience strategy cannot repair a weak conversion signal. If your primary conversion is Lead form submitted, every audience feature and bidding system starts with the same incomplete definition of success.

    That is particularly damaging in B2B. A form may come from a strong account, a student, an existing customer, a job seeker, a vendor, a competitor, or someone outside your service area. Google Ads cannot infer which one matters if you send all of them back under the same label and value.

    Map the funnel as separate conversion events

    Start with the stages your sales team already uses. The names will differ by business, but the distinctions should remain explicit:

    1. Lead created: the person completed the initial conversion action.
    2. Qualified lead: the record passed your documented fit and intent criteria.
    3. Opportunity created: sales accepted the record into an active buying process.
    4. Closed outcome: the opportunity became revenue or reached another definitive result.

    Keep the initial lead event for measurement, but do not automatically make it the event that controls every campaign. Import later-stage events and values so bidding can distinguish an inexpensive form from a commercially useful lead.

    Offline conversion imports are the foundation for journey-aware bidding, value-based bidding, and expansion-heavy campaign types such as Performance Max, Demand Gen, and AI Max to optimize beyond cheap volume. Google has added direct Data Manager integrations for Mailchimp, ActiveCampaign, Klaviyo, and Google Drive, plus partner API connections including Zapier, Stape, Adswerve, Bloomtech, and Treasure Data. If an engineering backlog has delayed CRM feedback, check whether one of those paths removes the dependency.

    Verify the meaning of the data, not just the connection

    A successful connector does not guarantee a useful bidding signal. Before changing campaign optimization, verify four things:

    • The CRM and Google Ads use the same definition for each lifecycle stage.
    • Rejected, duplicate, spam, test, and otherwise invalid records cannot be imported as qualified outcomes.
    • Conversion values preserve the difference between stages or business outcomes instead of assigning every event an arbitrary equal value.
    • The import runs consistently enough that missing batches do not make campaign performance appear better or worse than it is.

    Use Data Manager’s map view to audit where account data is deployed. Then reconcile imported records against the CRM. You are checking whether the advertising platform received the right event for the right record, not merely whether a green status indicator appeared.

    Journey-aware bidding is intended to let a tCPA Search campaign learn from multiple stages between lead and sale instead of relying only on the first form or a sparse final-sale event. It remains a developing capability, so availability and maturity may vary. If it appears in your account, clean lifecycle data is still the prerequisite; the feature cannot repair inconsistent qualification rules.

    Give every audience a specific job in the funnel

    A B2B audience is useful only when you know what the campaign should do differently because a person belongs to it. Build lists around actions, not around the vague idea that more first-party data must be better.

    Separate exclusion, signaling, and re-engagement

    • Existing customers: exclude them from net-new acquisition where appropriate, or move them into a separate retention, renewal, or expansion campaign.
    • Qualified leads and closed-won contacts: use these consented records as a quality signal. Keep them separate from unqualified form submissions so the signal retains its meaning.
    • Open opportunities: avoid paying to reacquire them through a generic prospecting experience when sales is already managing the conversation. If advertising still has a role, use messaging that reflects the active evaluation stage.
    • Stalled or closed-lost opportunities: re-engage them only when your offer, timing, or message addresses why the earlier process stopped.
    • Raw leads: retain them for analysis and carefully scoped remarketing, but do not present them to the bidding system as evidence of customer quality.

    This structure also makes performance easier to diagnose. If a campaign grows by reaching more known customers rather than new qualified accounts, a blended conversion total can hide the problem. Separate audiences let you see which business job produced the apparent growth.

    Choose observation or restriction deliberately

    In Search campaigns, adding an audience does not always need to narrow eligibility. Observation lets you examine how a segment behaves while preserving the campaign’s broader reach. Targeting restricts delivery to the selected audience or audience criteria.

    Use observation when you are still learning whether an audience predicts quality. Use targeting when the campaign is explicitly designed for that known group, such as re-engaging consented contacts with stage-specific messaging. This distinction prevents a common error: restricting a high-intent keyword campaign to a list that is too small, stale, or incomplete before you know whether membership improves downstream results.

    Customer Match remains the central tool for reconnecting with known, consented first-party audiences across Google properties. Upload only records your organization is permitted to use, keep list purposes explicit, and avoid treating a matched identity as proof of a person’s current role, authority, or purchase intent.

    Test Enhanced matching without assuming what it can do

    An Enhanced matching option for Customer Match is appearing in some Google Ads accounts. When enabled, Google says it can use connected customer lists to extend reach by matching consented advertiser users with consented users from participating publishers, where available.

    The control has appeared unchecked, which makes it an opt-in decision rather than something you should assume is already active. Availability also appears limited. Google has not publicly specified the incremental reach, named participating publishers, or explained exactly how the process differs from existing Customer Match matching.

    If the setting appears in your account, we would test it as a new source of reach, not relabel it as proven precision. Record the activation date, isolate the campaigns affected where practical, and compare qualified-lead, opportunity, and revenue outcomes with the prior baseline. If you cannot separate its impact from other targeting and bidding changes, you will not know whether the extra reach helped.

    Align bidding targets with B2B economics before adding reach

    A stale bidding target is easy to miss because it can appear conservative. In a limited-budget campaign, however, that target influences which additional traffic Google can buy as it tries to spend consistently.

    Following Google’s Aug. 17 change, campaigns marked Limited by budget and using tCPA or tROAS are designed to deliver more consistently to the stated target instead of quietly outperforming it. This deserves immediate attention in B2B accounts, where campaigns often remain budget-limited and launch-era targets may survive long after lead quality or sales economics have changed.

    Audit those campaigns in this order:

    1. Filter for campaigns with a Limited by budget status and a target-based bid strategy.
    2. Identify which conversion actions and values the strategy is using. Do not assume account reporting columns match the campaign’s actual optimization goal.
    3. Compare the target with current qualified-lead, opportunity, and revenue economics rather than the original form-fill CPA.
    4. Inspect where incremental spend is going, including available query, network, audience, and landing-page information.
    5. Change one major control at a time where practical. A simultaneous budget increase, target change, audience expansion, and new conversion goal destroys your ability to attribute the outcome.

    A tROAS target only becomes meaningful for lead generation when imported values reflect genuine differences in business value. If every lead is assigned the same placeholder value, tROAS is effectively optimizing lead count through a value-shaped interface.

    Do not let cheaper traffic settle the argument. In one PPC Live account study, AI Max reduced average CPC by 59% and nearly tripled click volume while cost per lead increased from $493 to $850. One account study is not a universal benchmark, but it demonstrates the failure mode clearly: a favorable auction metric can accompany a worse acquisition result.

    The same caution applies to reported reach gains. Google says Search campaigns using Smart Bidding Exploration see 27% more unique converting users on average. That is a vendor-reported average, not a promise of 27% more qualified B2B buyers. A unique converter is useful only if your conversion definition makes that person commercially relevant.

    Put guardrails around AI-driven audience expansion

    A glowing intelligent network expands toward groups of professional figures while transparent boundaries and control gates restrict which paths can pass through.

    AI Max, Performance Max, optimized targeting, and other expansion mechanisms can find demand outside your manually defined audience. That is useful after Google can distinguish valuable outcomes. Before then, expansion gives the system more ways to pursue the shallow event you supplied.

    Several mechanisms can make the top-line numbers look healthy while weakening B2B performance. Query expansion can add less-specific searches. Landing-page expansion can route people to pages that educate but were not designed to convert. Generated ad copy can remove distinctions that matter to a narrow buyer. None of those outcomes is automatically bad, but each changes more than audience size.

    Use these guardrails before enabling or enlarging AI-driven reach:

    • Set the learning objective first. Confirm that qualified and downstream events are flowing before you expand traffic.
    • Define the business test. Decide whether success means more qualified leads, more opportunities, greater pipeline value, or revenue at an acceptable acquisition cost. Do not substitute CTR or CPC after launch.
    • Preserve a comparison. Avoid rolling audience, creative, landing-page, budget, and bidding changes into one release. You need a usable baseline.
    • Review the destination experience. Check whether eligible pages state the offer, ideal customer, pricing approach, features, security position, and integrations accurately. Expansion cannot compensate for ambiguous product facts.
    • Read CRM cohorts separately. Compare expanded traffic with the campaign’s earlier traffic at the same lifecycle stages. A larger lead cohort is not progress if qualification or opportunity creation deteriorates.
    • Keep exclusions purposeful. Prevent existing customers, active opportunities, internal users, or other irrelevant groups from inflating acquisition results when those exclusions fit your campaign objective and data permissions.

    Opacity matters even more in AI search placements. Ads in AI Mode currently depend on AI Max or Performance Max, while available reporting offers little visibility into what the AI said about the brand, when an ad appeared, or what triggered it. Do not invent certainty the reporting cannot provide. Ring-fence the test, label its timing, and evaluate the CRM outcomes you can observe.

    Business agents for leads are also being tested in selected verticals. The concept places a Gemini chat agent inside a Search ad, grounds its answers in the advertiser’s website, and can present a pre-filled form after the user demonstrates intent. That makes the clarity of your website part of ad readiness: pricing, features, security, and integration pages need explicit, consistent information that both people and language models can interpret. The capability is not broadly available enough to build a lead-generation plan around, but cleaning those pages helps conventional evaluation as well.

    Open one important campaign and trace its full signal path: search or audience, landing page, lead record, qualification, opportunity, and final outcome. If the path stops at the form, do not widen the audience yet. Repair the CRM feedback, separate the audience jobs, and update the bidding target first. Then test the smallest expansion you can evaluate against downstream results.

    References


  • Claude Chat Privacy: When Shared Links Enter Search Results

    Claude Chat Privacy: When Shared Links Enter Search Results

    If you’ve used Claude for something sensitive, hearing that Claude chats appeared in search results can make it sound as though every private prompt is searchable. That isn’t what the documented exposure established.

    The affected pages were chat snapshots made available through user-created public share URLs. The practical lesson is still serious: once you turn a conversation into a shareable web page, you should treat that page as public unless access control proves otherwise.

    A shared Claude link is a web page, not a private message

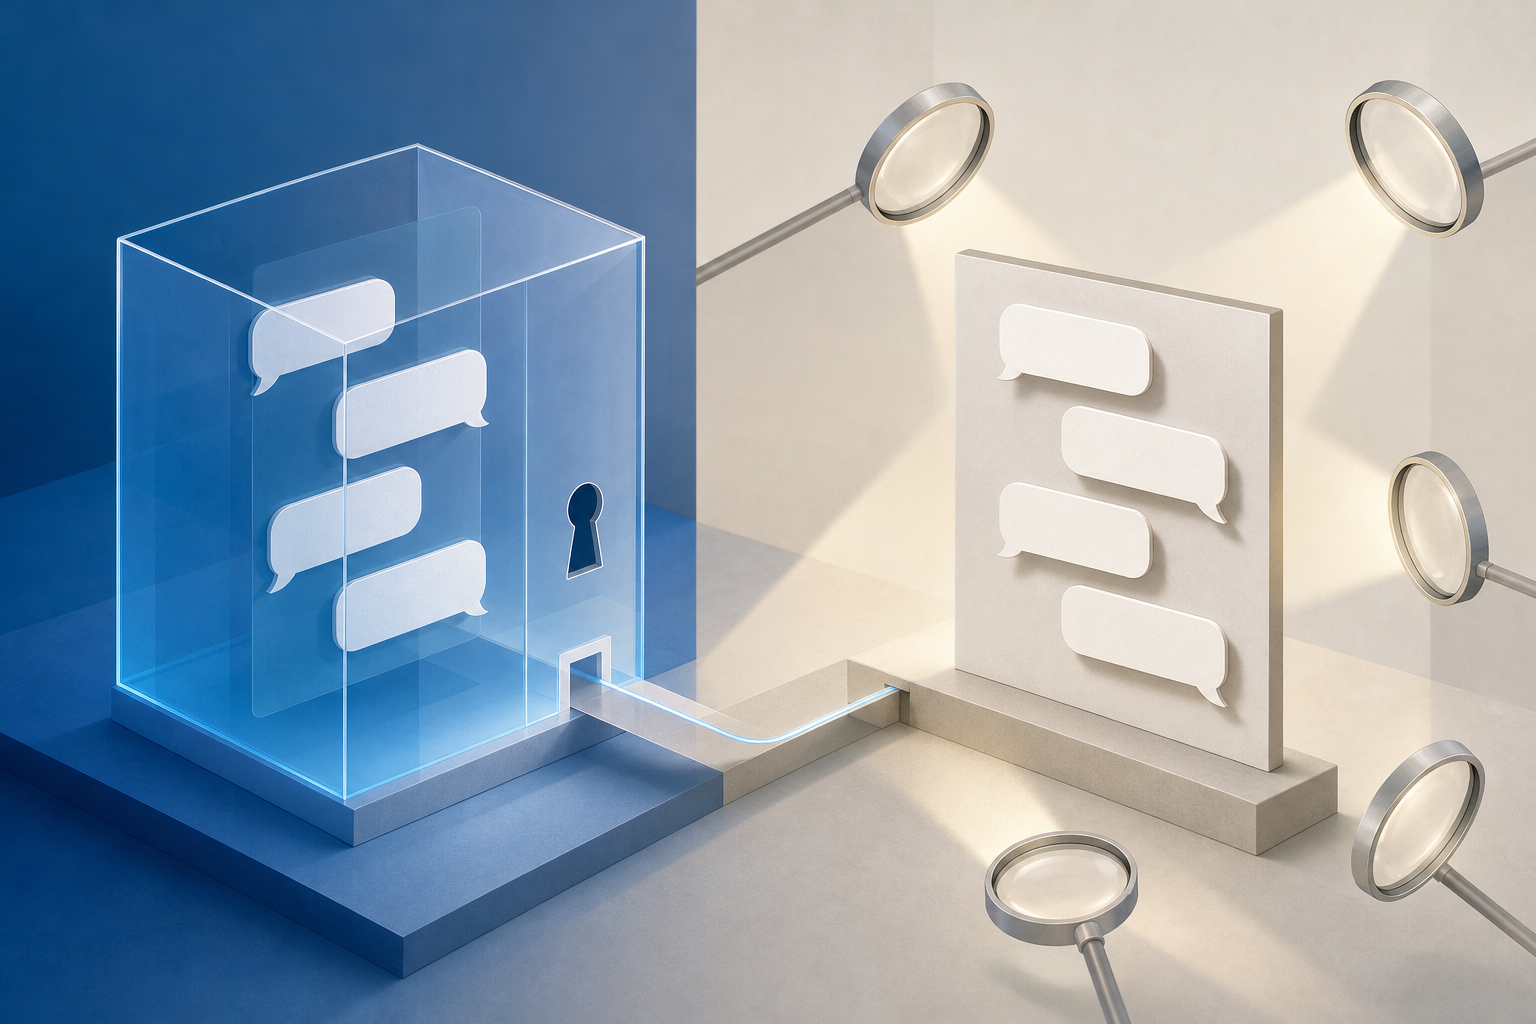
    Blank chat bubbles sit inside a secured chamber while a copied conversation page outside is illuminated by magnifying lenses.

    A conversation inside your authenticated Claude account and a snapshot exposed through a share URL occupy different privacy states. The first sits behind your account session. The second is designed to be opened outside that session, which means the URL can be forwarded, linked from another page, collected by automated systems, or discovered by a search crawler.

    Creating the share URL does not guarantee that Google or Bing will index it. It does, however, create the conditions under which indexing can happen. There are three separate stages:

    1. Public access: A person who has the URL can load the page without signing in.
    2. Discovery and crawling: A search engine finds the URL, often through a link or another crawlable source, and requests the page.
    3. Indexing: The search engine decides that the URL or its contents can appear in search results.

    The first stage is the privacy boundary. Indexing increases discoverability, but a page was already exposed before it appeared in search. An unindexed URL is therefore not the same thing as a private URL.

    This also separates search exposure from other questions about AI services, such as conversation retention or model training. Those issues depend on the service’s policies and settings. The incident at issue concerned public share pages reaching search indexes; it does not, by itself, establish that ordinary unshared chats were searchable.

    At one point, a site:claude.ai/share query surfaced hundreds of shared conversations, including sensitive health and political discussions. Those results were later removed. Removal from a search index reduces discovery, but it cannot establish that nobody opened, copied, forwarded, or captured a page while it was accessible.

    Key takeaways

    • An ordinary Claude conversation and a user-created share page are not the same privacy state.
    • A public page can be accessed before a search engine indexes it, so no search result does not mean no exposure.
    • If a shared conversation contains sensitive material, remove or revoke the page at its host before concentrating on search-result removal.
    • Robots.txt is a crawler-management file, not an access-control or privacy system.
    • A noindex instruction must remain visible to crawlers; blocking the same page in robots.txt can prevent them from seeing it.

    What to do if you created a Claude share link

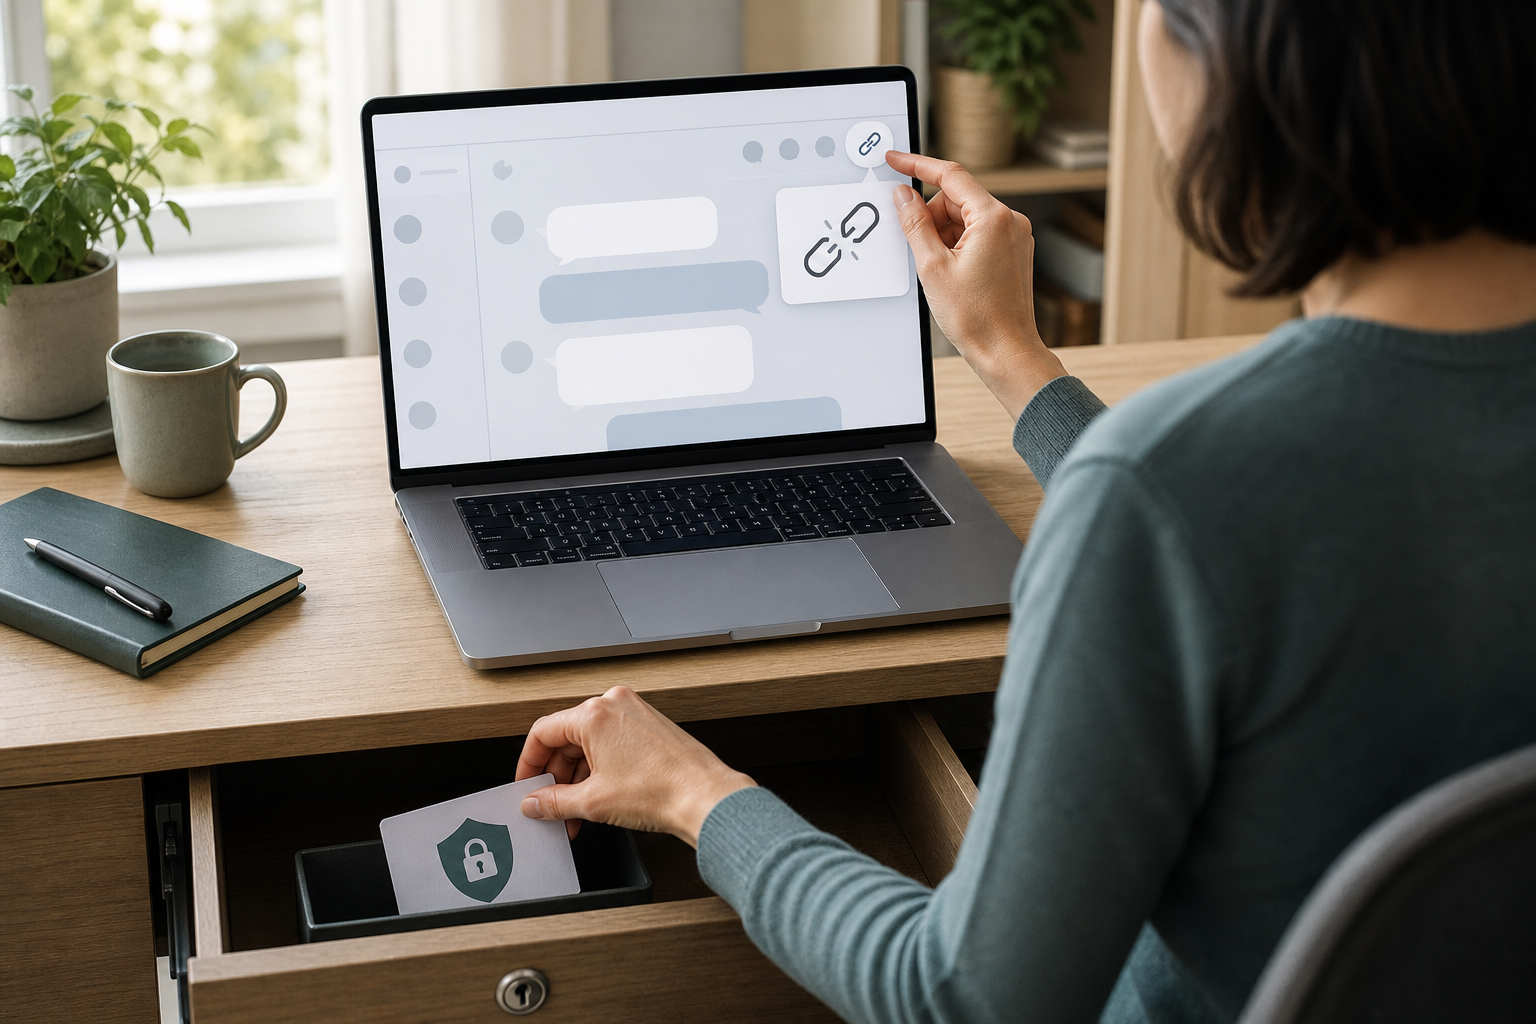
    A person reviews a generic shared chat page while closing a link icon and placing a message card in a locked drawer.

    Start at the original page, not at Google. Search results are a downstream copy of a more important condition: whether the conversation is still publicly accessible.

    1. Inventory the links you created. Check any sharing controls currently available in your Claude account, then review places where you may have pasted links: email, chat messages, tickets, documents, notes, social posts, or team workspaces. Do not assume you created only one snapshot.
    2. Test each link while signed out. Open it in a private browser window where you are not logged into Claude. If the conversation loads without authentication or another access check, treat it as public. Avoid submitting the URL to unrelated scanning sites or public forums, because that creates additional copies and routes of discovery.
    3. Revoke or remove access at Claude. Use the platform’s current sharing controls to disable the link. If no self-service control is available, contact Anthropic through its support process and identify the exact share URL. Search delisting alone is not enough while the original page remains open.
    4. Record the minimum evidence you need. Keep the URL, when you noticed the exposure, and a private screenshot of any relevant search result if you may need an organizational incident record. Do not republish the conversation merely to document it.
    5. Respond to the contents, not just the page. Revoke exposed API keys, access tokens, invitation links, or session credentials. Change any exposed password wherever it was reused. If the chat contains client records, employee information, regulated data, or confidential business material, notify the appropriate security, privacy, or legal owner through your organization’s incident process. Removing a page does not make a disclosed credential safe again.
    6. Check search visibility after access is closed. Search for the exact URL, a distinctive non-sensitive phrase, and the site:claude.ai/share pattern in the relevant search engines. Treat these as spot checks rather than a complete audit. If a result remains, use the search engine’s webmaster or personal-information removal process, but keep the origin page disabled.

    If the page contained no identifying information, credentials, confidential records, or material tied to another person, revoking the link and checking for residual results may be proportionate. If any of those elements were present, escalation matters more than repeatedly searching your own name. The consequence comes from what was exposed and who could act on it, not merely from whether a result still ranks.

    For site owners, robots.txt is not a privacy control

    The technical failure behind this kind of exposure is easy to repeat. A team wants to keep pages out of search, so it disallows their paths in robots.txt and adds a noindex directive to the pages. That combination looks cautious, but the two instructions can work against each other.

    A noindex directive works only after a crawler retrieves the page and reads the directive in its HTML or HTTP response. When robots.txt prevents that retrieval, the crawler cannot see noindex. Google explicitly warns that a robots-blocked URL can still appear in results when the engine learns about it elsewhere, such as through links.

    The right configuration depends on the access policy you actually intend:

    • Private conversation: Require authentication and verify that the signed-in user is authorized to access that specific conversation. Add noindex as defense in depth, not as the lock on the door.
    • Public share page that should not appear in search: Allow compliant crawlers to request the page, then serve a noindex meta directive or X-Robots-Tag response header. Do not disallow the same URL in robots.txt while depending on noindex.
    • Public and indexable publication: Make the publishing consequence explicit before the user creates the URL. Let the user preview and redact the content, identify what metadata will be visible, and provide a reliable revocation control.
    • Revoked or deleted share: Remove public access at the origin. Require authorization again or return a genuine not-found or gone response. Search-removal requests can accelerate cleanup, but they should follow the access change.

    Noindex does not encrypt content, restrict direct visitors, stop forwarding, or prevent every scraper and archive from collecting a page. Robots.txt does none of those things either. If viewing the content would itself be a privacy failure, the content belongs behind authentication and server-side authorization.

    Test the privacy boundary as a stranger would

    A logged-in product test can hide the most important failure. Include these checks in every release that affects chat sharing:

    • Open a newly shared link in a clean, signed-out browser session.
    • Confirm whether the user made an explicit public-sharing choice before the URL was created.
    • Inspect the rendered meta robots value and response headers on the actual share template.
    • Verify that robots.txt does not block crawlers from reading a noindex directive you expect them to obey.
    • Revoke the link and confirm that the same signed-out request no longer reveals the conversation.
    • Maintain a server-side inventory of active share URLs instead of relying on site: searches, which are useful for discovery but incomplete as an audit.

    Before your next sensitive Claude session, decide whether the content should remain inside an authenticated conversation or become a shareable web page. If you choose to share, redact first and act as though the link may travel. For product teams, make that same distinction structural: private content needs access control, public-but-unlisted content needs a crawlable noindex directive, and revoked content needs to stop loading.

    References


  • Google Ads Customer Match: Setup, Uses, and Privacy Checks

    You have customer data that competitors can’t copy. The question is whether you’re giving Google Ads a clean, current, consented version of it—or leaving its automation to learn from the same broad signals available to everyone else.

    Customer Match can support acquisition, retention, exclusions, bidding, and audience discovery. You can get some of that value even before your account qualifies to target a customer list directly.

    Key takeaways

    • Upload eligible first-party customer data even if your account hasn’t reached the spending threshold for direct Customer Match targeting.
    • Choose one job for each list: find new customers, retain existing ones, prioritize high-value customers, or exclude people who shouldn’t see an offer.
    • Use a direct integration when possible; otherwise, establish a recurring CSV refresh schedule.
    • Upload only data collected with appropriate consent, and make sure your privacy policy explains advertising-related data sharing.
    • Judge a list by matchable scale, freshness, and business relevance—not by its raw row count.

    Upload your list before direct targeting becomes available

    A common mistake is treating the US$50,000 lifetime-spend threshold as a reason to postpone Customer Match entirely. That threshold affects direct targeting and exclusions. Eligibility also requires an account in good standing and at least 90 days of spending history.

    If you haven’t met those conditions, you can still upload a customer list for use as an automation signal. Google can use the characteristics of those customers to inform Smart Bidding and optimized targeting. This matters because your first-party data gives the system information that isn’t available from generic market signals alone.

    An uploaded list can also unlock Audience Insights in Audience Manager. Inspect the demographic patterns and Google audience segments associated with your customers. Then turn the findings into testable decisions: adjust a landing page for the audience you actually attract, develop Demand Gen creative around a recurring interest, or challenge an assumption about who buys from you.

    Don’t read an insight as proof of causation. Use it to form a campaign hypothesis, then validate that hypothesis with conversion data.

    Give each Customer Match list one clear campaign job

    Customer Match can work across Search, Shopping, Gmail, YouTube, and Display once your account is eligible. Performance Max doesn’t offer conventional audience targeting, but customer lists can still shape Customer Lifecycle goals.

    Business objectiveHow to use the listWhat to check
    Acquire only new customersUse New Customer Only mode so known customers are excluded.Confirm that the list covers enough existing customers to make the exclusion meaningful.
    Pay more for new customersUse New Customer Value to distinguish acquisition value from an ordinary conversion.Make sure the added value reflects your economics rather than an arbitrary premium.
    Drive repeat purchasesUse Customer Retention mode to concentrate on known customers.Exclude people whose purchase timing or status makes the offer irrelevant.
    Prioritize your best customersBuild a high-value customer segment from a defensible business rule.Define value consistently, such as the customer status already used in your CRM.
    Prevent wasted impressionsExclude matched customers from acquisition campaigns when they shouldn’t receive the offer.Check that your list is refreshed frequently enough to catch recent customers.

    Scale determines whether these controls will materially change delivery. One practical heuristic is the 1% rule: compare the active list with the population in your target geography. In a US-wide campaign, 1% of a population of 340 million would be about 3.4 million people. This is a planning heuristic, not a Google eligibility rule. A smaller list can still be useful, but you shouldn’t expect it to redirect a large national campaign by itself.

    Use the narrowest list that still has enough scale for its job. A list of all historical leads may be large but strategically muddy. A current-customer list, lapsed-customer list, and high-value segment give you cleaner decisions, provided each status is defined and maintained.

    Build a repeatable upload and refresh process

    Start in Tools > Data Manager and look for a direct connection to the system that holds your customer records. Shopify, HubSpot, and Salesforce integrations can keep data synchronized without repeated manual exports. If a suitable connection isn’t available, use a CSV upload through Tools > Shared Library > Audience Manager.

    Your operating process should be simple enough that it still happens during a busy month:

    1. Define the list’s purpose and the customer status that qualifies a person for it.
    2. Remove records that don’t belong, including test accounts and people outside the intended segment.
    3. Confirm that the data was collected with the consent required for advertising use.
    4. Connect the platform or upload the CSV.
    5. Check whether the resulting audience has enough matched users to serve its intended campaign function.
    6. Set an owner and a refresh cadence.
    7. Review campaign settings after every major list-definition change.

    Match the cadence to the speed of your business. Daily synchronization makes sense when leads or purchases arrive regularly and recent customer status affects exclusions. A slower business may be adequately served by a bi-weekly or monthly refresh. The key is to choose the interval deliberately instead of relying on someone to remember.

    If you’re also using Enhanced Conversions, examine conversion-based customer lists. These can automatically maintain audiences of people who completed selected conversion actions. A conversion records an event; a data segment represents a group that can continue to inform campaign decisions. Connecting the two reduces manual list maintenance.

    Put consent and list quality ahead of match volume

    Customer Match is not permission to upload every email address your organization possesses. Use your own customer data, collected with suitable consent. Bought third-party lists can violate Google policy and applicable privacy law. Your privacy policy should clearly disclose that customer data may be shared with providers such as Google for advertising.

    Healthcare and finance require particular caution because sensitive-industry restrictions can prevent Customer Match use. Don’t try to work around a restriction by renaming a segment or broadening its label. If eligibility is unclear, verify the proposed use against Google policy and your organization’s legal requirements before uploading anything.

    Assign operational responsibility as well. Marketing can define the campaign objective, but someone must own consent status, suppression rules, customer-status logic, and refresh failures. Record the list’s purpose, inclusion criteria, update frequency, and connected campaigns in the same place your team documents campaign settings.

    Finally, monitor outcomes that match the list’s job. For acquisition exclusions, watch how much spend and conversion volume move toward new customers. For retention, evaluate repeat-purchase performance. For an automation signal, compare campaign performance over a meaningful period without crediting every change to the list. Customer Match improves the information available to Google Ads; it doesn’t replace sound bidding, creative, measurement, or offer strategy.

    Your next step is concrete: identify one consented customer segment, give it one campaign purpose, and either connect it in Data Manager or schedule its first upload. Then put the refresh date on the calendar before you leave Audience Manager.

    References

  • AI Legal Risk for Business: A Practical Exposure Audit

    AI Legal Risk for Business: A Practical Exposure Audit

    Your AI legal risk probably isn’t sitting in an experimental lab. It’s in ordinary work: a marketer pastes customer information into a model, an editor publishes an unsupported product claim, or a team promises exclusive ownership of material that a machine largely produced.

    You can find much of that exposure before it becomes a dispute. The practical job is to map each AI workflow, identify what enters and leaves it, assign a human decision-maker, and retain enough evidence to explain what happened. This is an operational risk framework, not a legal opinion. If an AI use could affect contractual rights, regulatory duties, intellectual property, or an individual’s interests, have qualified counsel assess the specific facts and jurisdiction.

    Map the workflow, not just the AI tool

    An isometric office scene follows an AI-assisted task from a customer record through generation, editorial review, managerial approval, publication, and evidence storage.

    A list of approved tools is useful, but it isn’t an exposure audit. The same model might be used for harmless brainstorming, confidential document analysis, public product claims, or automated customer responses. Those uses don’t carry the same consequences.

    AI is accelerating familiar legal risks involving intellectual property, privacy, consumer protection, misinformation, and liability. That is good news for your first review: you don’t have to predict an entirely new field of law. You have to locate where AI touches obligations the business already has.

    Build the inventory around use cases. Give each recurring workflow its own row, even when several rows use the same vendor. Record:

    • The team and accountable owner.
    • The business purpose and any decision the output influences.
    • The data, documents, prompts, images, code, or other material sent to the system.
    • Whether inputs contain personal, confidential, licensed, or third-party material.
    • Where the output goes: private notes, an internal system, a client deliverable, a website, JSON-LD, an advertisement, or a customer-facing assistant.
    • The human review required before the output is used.
    • The provider, account type, model or feature used, and relevant retention or training settings.
    • The evidence retained, including sources, revisions, approvals, and important vendor terms.

    That last point matters because AI features change. Recording only the vendor name may not let you reconstruct a decision later. Capture the actual product or feature closely enough that the workflow owner can explain which system handled the information.

    AI workflowExposure to examineEvidence to retain
    Marketing copy, SEO content, and schema markupUnsupported claims, copied expression, unclear ownershipClaim sources, human revisions, reviewer approval
    Customer-facing chatbotIncorrect answers, misleading representations, personal-data handlingApproved answer set, test results, escalation rules, retention decision
    Internal document summarizationPersonal, confidential, or licensed material sent to a providerPermitted data class, access controls, provider settings, deletion terms
    Generated design, image, or codeThird-party rights, license restrictions, protectability, promised ownershipInput provenance, similarity or license checks, material human changes

    Flag a workflow for deeper review when it publishes externally, processes personal or confidential data, makes a consequential recommendation, creates something the business expects to own, or acts without a human approval step. These are screening signals, not legal conclusions. Their purpose is to keep a risky use from disappearing inside a generic label such as “content assistance.”

    Separate input rights, output risk, and ownership

    Teams often compress every intellectual-property question into “Can we use AI for this?” That question is too broad to answer. Break it into three decisions: whether you may submit the input, whether you may use the output, and whether anyone can claim enforceable ownership of the finished work.

    Check the material going into the model

    Permission to read or possess a file does not automatically settle whether it may be uploaded to an external system. A customer brief, licensed image library, unpublished manuscript, source-code repository, or partner document may be governed by a contract, confidentiality term, or access restriction.

    Before submission, identify who supplied the material, what rights the business received, whether the provider may retain or use it, and whether the workflow exposes it to anyone who was not already authorized. If the answer depends on contract language, stop and have counsel interpret that language. Guessing can compromise confidentiality or create a breach that cannot be fixed by deleting the eventual output.

    Inspect the output for third-party material

    A polished answer is not proof of clean provenance. AI output can unintentionally incorporate protected material, creating a practical infringement risk even when the user never requested a copy. Review distinctive text, images, code, characters, slogans, and other recognizable elements before release. For code, inspect dependencies and license implications rather than relying only on a general plagiarism check.

    Give the reviewer the prompt, known source material, and intended channel. Asking whether an output merely “looks original” is too subjective. Ask whether its important elements can be traced, whether suspicious passages require a targeted search, and whether the business could defend its permission to use them.

    Document the human contribution you expect to own

    The U.S. Copyright Office position reflected in the available guidance is that purely AI-generated work is not protected and human creativity must materially shape the work for protection to become possible. Typing a prompt and accepting the first result is therefore a weak foundation for an ownership promise.

    Preserve evidence of the human work that made the final result distinct: the original brief, independently created structure, source selection, rewritten sections, editorial judgments, discarded drafts, compositional decisions, and final approval. The aim isn’t to save meaningless activity. It is to show where a person exercised creative control.

    This distinction belongs in client and contractor workflows. Don’t promise that a customer will receive exclusive, fully protectable rights merely because your contract uses the word “deliverable.” Align the promise with the provider’s terms, third-party licenses, the human contribution, and counsel’s view of the governing law.

    Patent questions need separate treatment. Revised U.S. Patent and Trademark Office guidance has left practical questions about human-conceived inventions developed with AI. If AI materially contributed during invention or development, preserve the chronology and involve patent counsel before making inventorship or filing decisions.

    Treat every public claim as your company’s own statement

    A disclaimer that content was “AI assisted” does not make a false statement accurate. Once your business publishes an output, customers, regulators, partners, and search systems encounter it as a representation made under your brand.

    The dangerous errors are not limited to obvious nonsense. Generative systems can produce invented facts, fabricated citations, and reasoning that sounds coherent but does not support the conclusion. A fluent paragraph can therefore pass an ordinary copy edit while failing a factual review.

    Review claims rather than prose. Maintain a simple claim ledger for externally published material. For each substantive assertion, record:

    • The exact claim a customer will see or reasonably infer.
    • The evidence that supports it, with enough detail for another reviewer to locate that evidence.
    • The product, service, market, audience, and period to which it applies.
    • Important qualifiers that must remain attached to the claim.
    • The person who approved it and the event that should trigger re-review.

    This is especially important for comparisons, rankings, prices, performance statements, testimonials, guarantees, and claims about safety, health, money, or legal outcomes. Those claims warrant specialist review because an error can cause more than a correction or ranking loss.

    SEO and AEO teams should apply the same standard to structured data. A false or stale statement does not become safer because it appears in JSON-LD instead of visible copy. Confirm that product attributes, prices, availability, ratings, organizational facts, author information, and FAQ answers match the page and the underlying business records. If automation updates those fields, assign an owner to the feed and define what happens when the source system and published markup disagree.

    Use a release gate that is proportional to consequence:

    1. Extract each factual and implied claim from the draft.
    2. Verify it against evidence that actually supports the same scope and wording.
    3. Open every citation; don’t accept a plausible title, quotation, or URL without checking it.
    4. Restore necessary qualifiers, limitations, and effective dates that generation or editing removed.
    5. Confirm that the visible page, metadata, schema, advertisement, email, and chatbot answer do not make conflicting representations.
    6. Record the reviewer and approval before publication.

    Keep unverified material out of production. A visible internal status such as “UNVERIFIED – DO NOT PUBLISH” is more reliable than hoping a placeholder citation will be remembered during the final edit. If evidence cannot be found, remove or narrow the claim rather than polishing it.

    Keep personal data out until its handling is defensible

    Privacy exposure begins when information enters the workflow, not when the generated answer is published. Personal data may appear in prompts, uploaded documents, chat histories, feedback, retrieval indexes, output logs, analytics, or support transcripts.

    The regulatory landscape includes frameworks such as the GDPR in the European Union, PIPEDA in Canada, and the CCPA in California. Their requirements differ, so a generic global statement that “we comply with privacy law” is not an operational control. Determine which people, data, activities, and jurisdictions are involved. Have a privacy professional or qualified counsel decide the applicable legal basis and obligations.

    Before approving a workflow involving personal data, require clear answers to these questions:

    • What personal data is required, and can the task be completed with less data?
    • Why is the business using it, and is that use compatible with what the person was told?
    • Does the provider use prompts, files, outputs, or feedback to train or improve its systems?
    • How long are inputs, outputs, logs, backups, and derived data retained?
    • Where is the data processed, who can access it, and which other providers receive it?
    • Can the business locate, correct, export, restrict, or delete the data when required?
    • What security, incident-notification, deletion, and audit commitments appear in the contract?
    • Who owns the response when a customer or regulator asks how the data was handled?

    If the owner cannot answer those questions, don’t send the data yet. Use approved enterprise controls where available, remove unnecessary identifiers, or redesign the workflow around synthetic or non-personal material. Redaction is not automatically anonymization: remaining details may still make someone identifiable when combined. Ask the privacy lead to assess that risk when the data is sensitive or the context is distinctive.

    Separate privacy from confidentiality during the review. A document can contain no personal data and still expose trade secrets, contract-restricted information, security details, or a client’s confidential plans. Conversely, information may be publicly visible yet remain personal data governed by a specific use and jurisdiction. Give each category its own permission rule.

    Prepare a response path before an incident. The workflow owner should know how to pause the use, identify the account and provider involved, preserve necessary evidence without spreading the data further, contact privacy and security personnel, and route rights requests or regulator communications. Once a request or incident exists, don’t improvise deletion or send a casual explanation. Preservation, notification, and response duties can conflict, so counsel should direct the specific response.

    Build controls people can use at the moment of decision

    An employee pauses before entering customer information while a colleague verifies rights, accuracy, privacy, and release controls built into the workstation.

    A long AI policy won’t help if an employee cannot tell whether a customer file is allowed in a particular feature. Convert policy into a small operating system that answers the questions people face while working.

    • An AI use register with a named business owner for every recurring workflow.
    • An approved-tool matrix showing which accounts and features may handle public, internal, confidential, personal, and sensitive material.
    • A review matrix defining who approves public claims, intellectual-property-dependent work, personal-data uses, and consequential decisions.
    • A contract checklist covering provider data use, retention, deletion, security, intellectual property, notice of material changes, responsibility, and liability terms.
    • An evidence pack for each higher-exposure workflow containing the purpose, data decision, test results, human review, source records, and current approval.
    • A reporting route that lets staff pause questionable work without having to prove a legal violation first.

    Assign one accountable owner, but involve the functions that control the underlying risk. Marketing or SEO can own publishing accuracy; privacy can decide data handling; security can assess access and incident controls; procurement can preserve vendor commitments; and counsel can interpret rights, duties, and disputed contract language. “Legal owns AI” is not a workable substitute for operational ownership.

    Test the control with a real workflow. Ask a person unfamiliar with the project to locate the approved tool, permitted data class, required reviewer, evidence record, and stop condition. If those answers live in separate inboxes or depend on knowing whom to ask, the control is not ready for routine use.

    Key takeaways

    • Audit AI by business use, input, output, audience, and decision – not by vendor name alone.
    • For intellectual property, answer three separate questions: may you submit the input, may you use the output, and can you support the ownership being promised?
    • Verify every external claim and citation as a representation made by your company, including claims encoded in metadata and schema.
    • Do not process personal or confidential data until purpose, provider handling, retention, access, deletion, and response ownership are clear.
    • Keep evidence of meaningful human contribution, factual review, permissions, settings, and approval.
    • Escalate uncertain rights, high-consequence uses, incidents, and jurisdiction-specific questions to qualified counsel.

    Know when to stop the workflow

    Pause and obtain specialist advice when a workflow depends on unclear contract rights, sends sensitive or confidential information to an unapproved provider, appears to reproduce distinctive protected material, influences a high-consequence decision, or makes a claim that could materially affect someone’s health, safety, finances, legal position, employment, or access to a service.

    Stop routine handling immediately if you receive a demand letter, rights request, security alert, regulator inquiry, or credible complaint about harmful or misleading output. Don’t destroy records, admit liability, or continue publishing while the facts are unclear. Preserve the relevant evidence and let the appropriate legal, privacy, security, or compliance professional direct the response.

    Start with one live, public-facing AI workflow this week. Map its inputs, claims, data, reviewer, and evidence trail. Fix the first unresolved permission or approval gap before expanding the audit. That single completed workflow will give your team a control pattern it can repeat across the business.

    References

  • Google Ads Tag Manager Integration: A Safe Workflow

    Google Ads Tag Manager Integration: A Safe Workflow

    You open Google Ads to investigate a conversion problem, but the change itself lives in Tag Manager. That usually means switching tools, reconstructing the implementation, and finding out who is allowed to publish.

    Embedded Tag Manager controls can shorten that path. They don’t make tagging risk-free, however. If you can manage tags from Google Ads, you still need a controlled way to inspect, test, approve, publish, and verify every change.

    What the integration changes – and what it does not

    Inside Google Ads Data Manager, an observed Manage action for a connected Tag Manager source opens embedded controls. That puts campaign configuration, data connections, and at least some tag-management actions closer together.

    The immediate benefit is less navigation. A marketer investigating campaign measurement may be able to reach the relevant Tag Manager controls without leaving Google Ads. That can be especially useful for a small team that doesn’t have a developer available for every routine inspection.

    Don’t read the shared interface as a merger of the underlying responsibilities. Your website or app still produces the action and its data. Tag Manager still decides whether a tag should fire and what it should send. Google Ads still receives and uses the resulting signal. Moving the controls closer together doesn’t remove any of those layers.

    The functional scope also appears unsettled. It isn’t yet clear whether the complete Tag Manager experience will be embedded or whether Google Ads will expose only selected management actions. Availability may vary while the interface is surfacing. Treat the embedded view as a convenient entry point, not as proof that every preview, permission, versioning, or troubleshooting function is present.

    That distinction gives you a simple rule: use the embedded controls when they show enough context to make the change safely. Move to the full Tag Manager interface when you can’t see the trigger logic, variables, testing state, version history, permissions, or rollback path you need.

    Run each tag change as a controlled measurement release

    A geometric tracking module passes through inspection, testing, peer review, a guarded release gate, and final verification.

    The dangerous part of tag management isn’t opening the right interface. It is publishing a plausible-looking change without proving what will happen. A conversion tag that fires twice can inflate results. A trigger that stops matching can interrupt measurement. Either problem can distort campaign decisions and obscure whether performance actually changed.

    Use the same release sequence whether you start in Google Ads or Tag Manager:

    1. Define the business action. Write one sentence describing what should count. Name the user action, the point at which it qualifies, and any value or category the implementation must carry. “Track leads” is too vague; distinguish a successful submission from a form view, button click, validation error, or duplicate confirmation-page load.
    2. Map the existing path before editing it. Identify what the site emits, which trigger listens for it, which tag sends it, and which Google Ads destination expects it. Check for another site-installed tag or container that may already send the same action.
    3. Confirm that the available controls are sufficient. The embedded surface is appropriate only if it exposes the objects and context required for your task. If you can’t inspect dependencies or run your normal preview process there, continue in the full Tag Manager interface.
    4. Make one scoped change. Avoid combining a trigger repair, naming cleanup, consent adjustment, and destination change in one release. A narrow change is easier to test and much easier to reverse.
    5. Test qualifying and non-qualifying behavior. Prove that the intended action fires once. Then test a page view without the action, a failed or abandoned action, repeated interaction, and any relevant consent states. Confirm the destination identifiers and variable values, not merely that some tag fired.
    6. Publish with a useful record. Record what changed, why it changed, who approved it, what was tested, and which version can be restored. A label such as “tag fix” won’t help during a later incident.
    7. Verify the receiving side. After publishing, repeat the action in a controlled test and check both the tag behavior and the Google Ads side. Allow for normal processing delay before concluding that a working tag is broken, but don’t use that delay as a reason to skip implementation-level evidence.

    Keep screenshots or a short test log for material conversion changes. The useful evidence is specific: the scenario tested, the event or input observed, the trigger result, the tag result, the destination used, and the version published. This makes a future discrepancy diagnosable instead of debatable.

    Consent behavior deserves its own test case. Opening Tag Manager from Google Ads doesn’t change what a visitor permitted, what your configuration allows, or what your organization is responsible for. If the correct behavior is unclear, pause the release and involve the person responsible for privacy requirements and consent implementation.

    Keep ownership clear when the interfaces converge

    The integration reduces tool switching, but it may also blur who owns a measurement change. Access to a Manage control is not the same as authority to publish. Decide that boundary before someone is troubleshooting a live campaign.

    A workable division of responsibility looks like this:

    • The campaign owner defines what the conversion means, confirms the correct Google Ads destination, and checks whether reporting matches the intended business action.
    • The Tag Manager owner maintains tags, triggers, variables, naming, preview evidence, versions, and publishing discipline.
    • The site or app owner controls the event and data produced by the user experience. This person fixes missing, unstable, or incorrectly populated data at its origin.
    • The privacy owner defines the applicable consent requirements; the implementation owner translates those requirements into testable behavior.

    One person may fill several of these roles on a small team. The roles still need to be named. Otherwise, the person who can reach the control becomes the person assumed to understand every downstream consequence.

    Set three permissions explicitly: who may inspect, who may edit, and who may publish. Inspection can be broad. Publishing should stay with people who can evaluate the implementation, its consent behavior, and its effect on campaign measurement.

    Your handoff record can be brief, but it should connect the systems. Include the business event, affected container or version, changed tag and trigger, Google Ads destination, test evidence, publisher, and rollback point. That record prevents Google Ads and Tag Manager from becoming two separate stories about the same conversion.

    Diagnose the failing layer before changing anything

    A technician inspects an isolated break in one layer of a stacked digital conversion-tracking system.

    When a conversion disappears or looks inflated, start at the user’s action and move downstream. Don’t begin by republishing tags or changing campaign settings. Each speculative change introduces another variable and can erase the evidence you need.

    LayerQuestion to answerWhat a failure usually requires
    Site or appDid the qualifying action produce the expected event and values?Repair the event, data, or user-flow behavior at its origin.
    Tag Manager triggerDid the intended trigger match, and did non-qualifying actions stay excluded?Correct trigger conditions or the variables they evaluate.
    Tag executionDid the correct tag fire once with the intended identifiers and values?Correct tag configuration, duplicates, runtime problems, or consent-dependent behavior.
    Google Ads connectionWas the signal sent to the intended Ads destination?Check the destination configuration and the connection between the systems.
    ReportingIs the received signal being interpreted as the business expects?Separate an implementation problem from a reporting or attribution interpretation.

    This order matters. If the site never emitted the event, changing a Tag Manager trigger won’t create reliable source data. If the trigger and tag worked but the destination was wrong, rewriting the site adds risk without addressing the failure.

    Duplicate conversions require the same discipline. Reproduce the action once, then look for multiple matching events, repeated trigger matches, multiple tags targeting the same destination, and parallel installations outside the container. Don’t delete the first duplicate-looking tag you find until you know which implementation is authoritative and what else depends on it.

    For a missing conversion, capture evidence at each boundary: the action occurred, the event existed, the trigger matched, the tag executed, and the intended destination received the signal. Stop at the first failed boundary. That is where the next investigation belongs.

    After a website release, repeat the same path before blaming Google Ads. Changes to forms, confirmation states, URLs, element selectors, or data structures can invalidate trigger assumptions even when the container itself hasn’t changed. The tag configuration may be unchanged and still no longer match the site.

    Key takeaways

    • Embedded Tag Manager controls shorten the route from a Google Ads measurement problem to the relevant management surface.
    • The shared interface doesn’t collapse the site, tag, destination, consent, and reporting layers into one system.
    • Use the full Tag Manager interface whenever the embedded view lacks the context, testing, permissions, versioning, or rollback controls needed for a safe release.
    • Define inspection, editing, and publishing permissions separately; visible controls should not silently redefine ownership.
    • Troubleshoot from the user action downstream, stopping at the first boundary where the expected evidence disappears.

    If the Manage option is available in your account, start with inspection rather than a live edit. Choose one important conversion, map its complete path, document its current owner, and run the qualifying and non-qualifying tests. That gives you a safe baseline for deciding which future tasks belong in Google Ads and which still need the full Tag Manager workflow.

    References

  • How to Build Culturally Aware Marketing Personalization

    How to Build Culturally Aware Marketing Personalization

    If your Mexico campaign is a translated version of your Spain campaign with a different flag, you have not personalized it. You have changed the label while leaving the customer’s decision context untouched.

    Culturally aware personalization works in two passes. First, establish what is true for the market: availability, language, pricing, payments, delivery, support, policies, and local proof. Then use the individual’s preferences and recent behavior to decide which of those truths matter now. This gives you more relevant marketing without turning culture into a crude demographic shortcut.

    Personalize the market before you personalize the person

    Do not begin with the question, What does this culture like? That invites stereotypes and gives your team little operational guidance. Ask instead: What must be true for this customer, in this market, to make the decision confidently?

    Spanish-speaking markets make the distinction easy to see. When more than 20 countries are compressed into one generic Spanish audience, Spain often becomes the unspoken default and other markets inherit its vocabulary, formats, assumptions, and commercial context. The copy may be grammatically correct while the experience is commercially wrong.

    A customer does not experience culture as a tone-of-voice document. They encounter it through the words used for a product, the currency beside the price, the payment methods available at checkout, the delivery promise, the return process, the support they can reach, and the rules governing the transaction. If those details contradict one another, adding local slang will not make the campaign feel local.

    Before creating a market segment, complete a market-readiness check:

    1. Confirm serviceability. Define which products or services are actually available, where they can be delivered, and which promises your operation can keep.
    2. Confirm the transaction. Record the correct currency, price, payment options, taxes or fees your team is responsible for presenting, and any offer restrictions.
    3. Confirm support. Identify the language variant customers can use, the channels available to them, and who owns escalation when the standard journey fails.
    4. Confirm policy scope. Have the appropriate internal specialists approve market-specific claims, disclosures, terms, and customer-facing policies. A translation team should not be expected to invent regulatory guidance.
    5. Confirm local evidence. Select examples, partnerships, media mentions, testimonials, and practical details that genuinely belong to the market. Do not relabel global proof as local proof.

    If you cannot complete those five checks, you are not ready to promise a localized experience. Publish market-neutral information, state the limits clearly, or delay the campaign. A market-specific URL or hreflang annotation cannot repair a service that does not fit the market.

    This also defines the right unit of personalization. A language is not a market, a market is not a culture, and a culture is not an individual. Treat each layer as context rather than identity.

    Build a profile that separates context from identity

    A shopper stands between separate translucent cabinets containing market-context objects and personal-preference objects.

    Most personalization programs try to place everything into one customer profile. A safer and more useful design keeps market truth separate from person-level signals, then combines them only when making a decision.

    LayerWhat it containsWhat it should control
    Market contextCountry or region served, language variant, currency, catalog, pricing, payments, delivery, support, policies, and approved local evidenceWhat the brand is eligible to say, sell, recommend, or promise
    Customer contextDeclared preferences, consent, account market, recent browsing, purchases, support interactions, and communication historyWhich eligible message is most useful to this person now
    Decision contextChannel, journey stage, current product, recent event, and any conflicting or missing signalsWhether to personalize, ask for clarification, suppress a message, or use a neutral fallback

    The market layer should be owned like product data, not treated as campaign copy. When a payment option, delivery promise, price, or policy changes, the underlying market record should change once and feed every channel that uses it.

    The customer layer needs a confidence hierarchy. Use signals in this order:

    • Declared preferences: the language, market, channel, or product interest the person chose. Make these settings easy to review and change.
    • Verified relationship data: the market attached to an account, contract, shipping destination, or completed transaction, when using it is appropriate for the interaction.
    • Observed behavior: pages viewed, products compared, carts started, purchases made, and support journeys opened. These signals describe recent intent, not cultural identity.
    • Inferences: predicted interests or likely next actions. Store their origin, confidence, and age, and provide a neutral fallback when the prediction is weak.

    A language setting, surname, device location, or content choice does not prove nationality or ethnicity. Do not use those signals as proxies for sensitive identity. If market selection materially changes prices, eligibility, access, or terms, let the person confirm it and explain why you need the information. In situations involving protected or sensitive traits, have privacy and legal specialists review both the inputs and the resulting decisions before activation.

    Expectation is not the problem. An Adobe 2026 report found that 71% of consumers wanted personalized deals and content and 78% expected a seamless cross-channel experience, while fewer than half of brands delivered that consistency. The gap appears when fragmented records make one channel unaware of what happened in another.

    Your unified profile therefore needs suppression signals as much as recommendation signals. A product view may justify a useful follow-up. It should not override a later purchase, an unresolved complaint, an unavailable product, a declined consent setting, or a market rule that makes the offer ineligible. Personalization becomes trustworthy when the system knows when not to personalize.

    Transcreate the decision, not just the sentence

    Translation asks whether a sentence carries the same literal meaning. Transcreation asks whether the entire decision makes sense in the customer’s market. That includes terminology, examples, offer details, proof, objections, and the action the customer is being asked to take.

    This distinction also matters for AI discovery. If two country pages remain about 95% alike, an AI system may merge them into one representation and prefer whichever version appears most standard. Changing the country name in the heading is not enough to establish a distinct market entity.

    Create a transcreation brief before a writer touches the copy. It should answer:

    • Which market and language variant is this asset for?
    • What customer decision must the asset support?
    • Which terms are locally expected, and which apparently equivalent terms could mislead?
    • What price, currency, payment, availability, delivery, return, and support facts must remain exact?
    • Which objections are specific to this market or journey?
    • Which local examples and proof can the customer verify?
    • Which claims, jokes, idioms, images, or references require review rather than direct adaptation?
    • What should the system show if the visitor’s market is unknown or conflicts with the page?

    Review the result in three passes. A language reviewer checks meaning and natural usage. A market owner checks commercial and operational truth. A journey owner follows the call to action through the next screen, email, checkout, or support handoff. This last pass catches a common failure: localized acquisition copy leading into a generic or contradictory transaction.

    Personalize message hierarchy before surface details. Suppose a returning visitor has repeatedly compared one service. The market layer should first supply the correct offer, terminology, delivery or implementation conditions, and local proof. Only then should the behavior layer move comparison details, a relevant case example, or the next practical step higher on the page. Inserting the person’s first name while leaving the wrong currency in the offer is not meaningful personalization.

    Use local slang sparingly. It can be effective when it belongs naturally to the brand, audience, and situation, but it is not evidence of cultural understanding. Accurate transaction details and recognizable customer problems carry more trust than decorative regional language.

    Put cultural boundaries into retrieval and activation

    An isometric content library routes marketing assets through transparent guardrail gates while two people review diverted items.

    AI will not repair ambiguous market data. It will process that ambiguity faster and reproduce it across more channels. The guardrails therefore need to exist before generation, recommendation, or orchestration begins.

    Use this decision sequence for web personalization, email, paid media, support prompts, product recommendations, and retrieval-augmented generation:

    1. Resolve the service market. Prefer an explicit selection or verified account context. When signals conflict, ask or use a neutral experience; do not silently translate location into nationality.
    2. Apply eligibility rules. Remove products, offers, claims, and actions that are unavailable or inappropriate in that market before calculating person-level relevance.
    3. Filter the content pool. Retrieve assets with matching language, market, currency, availability, policy scope, and approval status. In a RAG system, apply this filter before semantic ranking, not after the model has drafted an answer.
    4. Rank eligible options. Use declared preferences, current intent, journey stage, purchases, and support events to choose among the remaining messages.
    5. Compose from approved facts. Let AI adapt structure or emphasis only within the market facts and claims your owners have approved.
    6. Validate the output. Check market, language variant, price, currency, payment, availability, delivery, policy, and call-to-action destination before publication or send.
    7. Record the decision. Log which context, rule, asset, and model or workflow produced the experience so your team can investigate errors instead of guessing.

    A practical content record might include fields such as language, country or region, currency, product eligibility, policy scope, approval owner, review date, and supported channels. The names can match your stack; the important part is that market boundaries are machine-readable and maintained by accountable owners.

    For an unknown market, the fallback should be deliberately neutral. Present only globally valid information, avoid market-specific prices or promises, and offer a clear market selector when the choice changes the experience. Defaulting every Spanish-language visitor to Spain, Mexico, or an averaged global segment simply hides uncertainty inside the system.

    Your public discovery signals need the same consistency. Market-specific URLs, hreflang, visible copy, structured data, offer details, organization information, and internal links should point to the same locale. Structured data must agree with what the customer can see; markup cannot make an unavailable service locally available.

    External authority matters as well. Local media coverage, partnerships, and consistent regional entity signals help search and generative systems connect the brand with the market it actually serves. Build those relationships around real operations and expertise, not location names inserted for ranking.

    Finally, keep channels synchronized. If the website records a purchase, email should stop promoting the same first purchase. If support opens a serious issue, an upbeat upsell should not arrive because the advertising platform still sees an old audience membership. Real-time activation is valuable only when every channel receives the same updated customer and market truth.

    Measure accuracy before celebrating personalization lift

    A global conversion rate can conceal a strong result in the default market and a poor experience everywhere else. Evaluate each market separately, and separate commercial lift from cultural and operational accuracy.

    Your scorecard should cover five questions:

    • Eligibility accuracy: How often did customers see only products, offers, and actions genuinely available to them?
    • Experience consistency: Did the price, currency, availability, delivery, policy, and support promise remain consistent from discovery through conversion and service?
    • Personalization value: Did the personalized experience improve the chosen outcome against a suitable non-personalized or market-baseline experience within the same locale?
    • Retrieval accuracy: When search engines or your own AI system answered a market-specific question, did they retrieve the correct regional page and preserve its local facts?
    • Trust signals: Are opt-outs, complaints, corrections, support escalations, and manual market changes revealing a segment that your performance average hides?

    Maintain a fixed quality-assurance set for every supported market. Include an anonymous visitor, a person with a declared market, a returning customer, a visitor with conflicting language and market signals, an ineligible offer, an outdated asset, and a recent support event. Run the same cases across web, email, recommendations, support, and AI answers whenever data, rules, prompts, or content change.

    When a test fails, classify the cause before editing the copy. The root problem may be incorrect market data, weak identity resolution, missing consent, an eligibility rule, stale content, unrestricted retrieval, generation drift, or a cross-channel delay. That classification tells you which owner can actually fix the failure.

    A/B testing remains useful, but compare variants inside the same market and service conditions. If one variant receives different inventory, prices, or operational support, you are testing more than messaging. Document those differences or the result will not tell you what to repeat.

    Key takeaways

    • Treat cultural context as market and service information, not as a shortcut for ethnicity or nationality.
    • Establish availability, transaction, support, policy, and local-proof facts before applying person-level behavior.
    • Transcreate the full decision journey; translated copy cannot compensate for the wrong currency, offer, delivery promise, or policy.
    • Filter AI retrieval by market eligibility before ranking content for personal relevance.
    • Give uncertain or conflicting profiles a neutral fallback and an easy way to confirm their market.
    • Measure eligibility, consistency, retrieval accuracy, and trust signals by market alongside conversion lift.

    Start with one market and one high-intent journey. Write down the service truth, select the signals you can use responsibly, transcreate the necessary assets, add eligibility and retrieval gates, and test the journey through every active channel. Expand only when your team can trace a wrong experience back to the exact data, rule, or asset that created it.

    References