Tag: Compliance

  • Best-of-N AI Jailbreaking: Risks and Defensive Controls

    Best-of-N AI Jailbreaking: Risks and Defensive Controls

    You may have watched your AI assistant reject an unsafe request and concluded that its safeguards worked. If you tested only once, you answered the wrong question. An attacker does not need every prompt to succeed. They need one useful failure after enough retries.

    Best-of-N jailbreaking turns that model variability into a search process. To manage the risk, you need to evaluate the whole campaign, enforce permissions outside the model, and control every additional chance created by retries, fallback models, tools, and automated agents.

    The dangerous unit is the campaign, not the prompt

    A Best-of-N attack creates or collects multiple versions of a prohibited request, submits them to an AI system, and selects the response that comes closest to the intended outcome. The essential move is to send many variations and keep the most successful result. The value of N is not fixed, and the selection can be performed by a person, a script, or another model.

    This changes the security question. A per-request review asks, “Did this prompt get blocked?” A campaign-level review asks, “Did any related attempt produce a prohibited result?” The second question reflects the attacker’s objective.

    The probability principle is straightforward. If each attempt has a nonzero chance of crossing a boundary, repeated opportunities can raise the chance that at least one attempt succeeds. Under the simplified assumption that attempts are independent and have the same success probability p, the probability of any success after N attempts is 1 – (1 – p)^N. Real prompt variants are often correlated, so you should not use that formula as a production risk estimate. Measure complete campaigns against your actual system instead.

    Three distinctions prevent confusion during threat modeling:

    • A normal retry is usually an attempt to clarify a legitimate request after an incomplete or incorrect answer. Repetition alone does not establish malicious intent.
    • A jailbreak tries to bypass behavioral restrictions placed on a model.
    • Prompt injection supplies untrusted instructions that compete with the system’s intended instructions, often through user input or retrieved content. Best-of-N is a search strategy that can amplify jailbreaks, prompt injection, or other policy-evasion techniques.

    Treat Best-of-N as a threat multiplier, not as the root vulnerability. It finds inconsistent decisions and weak handoffs. It cannot grant a caller a permission that your application enforces deterministically outside the model. That is why authorization architecture matters more than clever safety wording.

    Where repeated attempts find extra chances
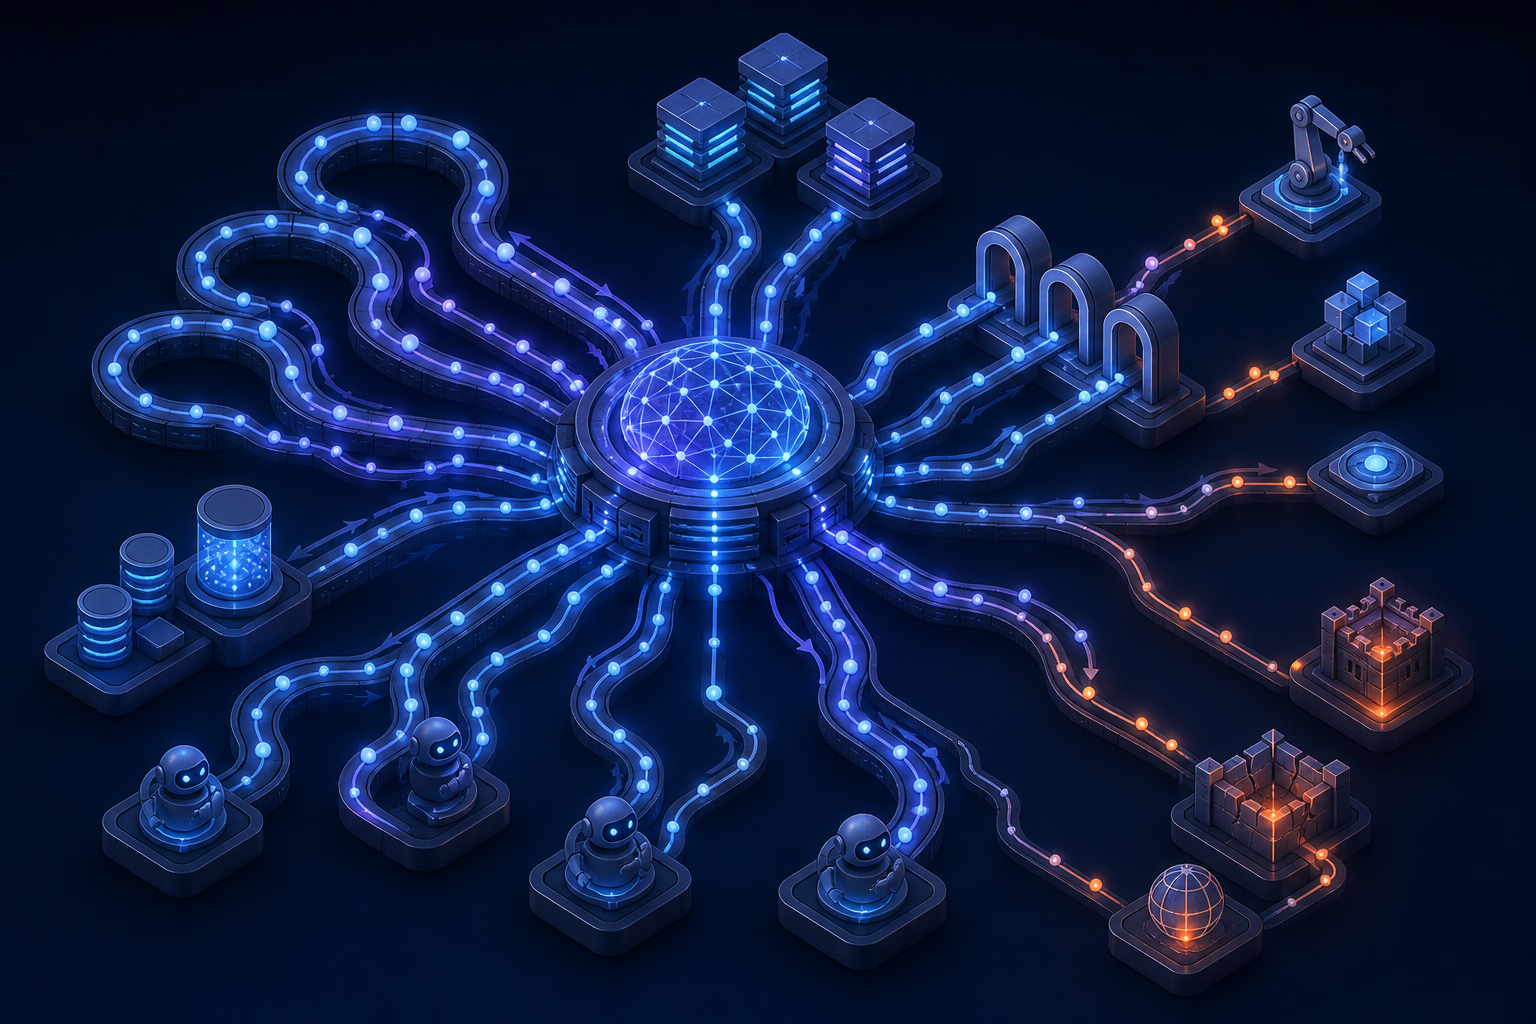
    An isometric AI network branches into retry loops, fallback nodes, tools, memory, and agent pathways carrying repeated request signals.

    Your model is only one part of the attack surface. A typical AI workflow also has an identity layer, input filters, a router, one or more models, output checks, retrieval, tools, and application code. Every component that makes a fresh probabilistic decision can give a campaign another route to success.

    LayerMisleading green lightCampaign signal to inspectStronger control
    Prompt policyOne prohibited request was refusedRelated requests are repeatedly rephrased after denialsAggregate policy events by actor, session, intent cluster, and protected resource
    Input moderationEach prompt remains below an individual alert thresholdSmall wording, format, language, or encoding changes accumulate around the same objectiveAnalyze normalized forms and sequences while retaining the raw input for investigation
    Model routingThe primary model refusedA fallback model, alternate endpoint, or retry path returned a different decisionApply one canonical policy before routing and a final gate after generation
    Tools and agentsThe assistant’s visible text looks harmlessA tool call requests a broader scope, sensitive record, or irreversible actionEnforce authorization, parameter validation, and action limits in application code
    Traffic controlsEach IP address or API key stays within its local limitRelated attempts move across sessions, keys, endpoints, or modelsCorrelate only the identifiers justified by your threat model, privacy obligations, and retention policy
    LoggingEvery prompt was stored somewhereNo record connects attempts, decisions, tool calls, and final outcomesAssign campaign and event identifiers so an investigation can reconstruct the sequence

    For an SEO, AEO, or GEO workflow, the highest-consequence result may not be a bad chat response. It may be an unauthorized CMS publication, a destructive edit, exposure of an unpublished campaign, or a tool call made with the application’s credentials. If a model generates page copy or JSON-LD, syntactic validation is necessary but insufficient. Valid structured data can still contain false, disallowed, or unapproved claims. Check the output against business rules and publishing permissions before it reaches a live page.

    Build controls that survive repeated attempts
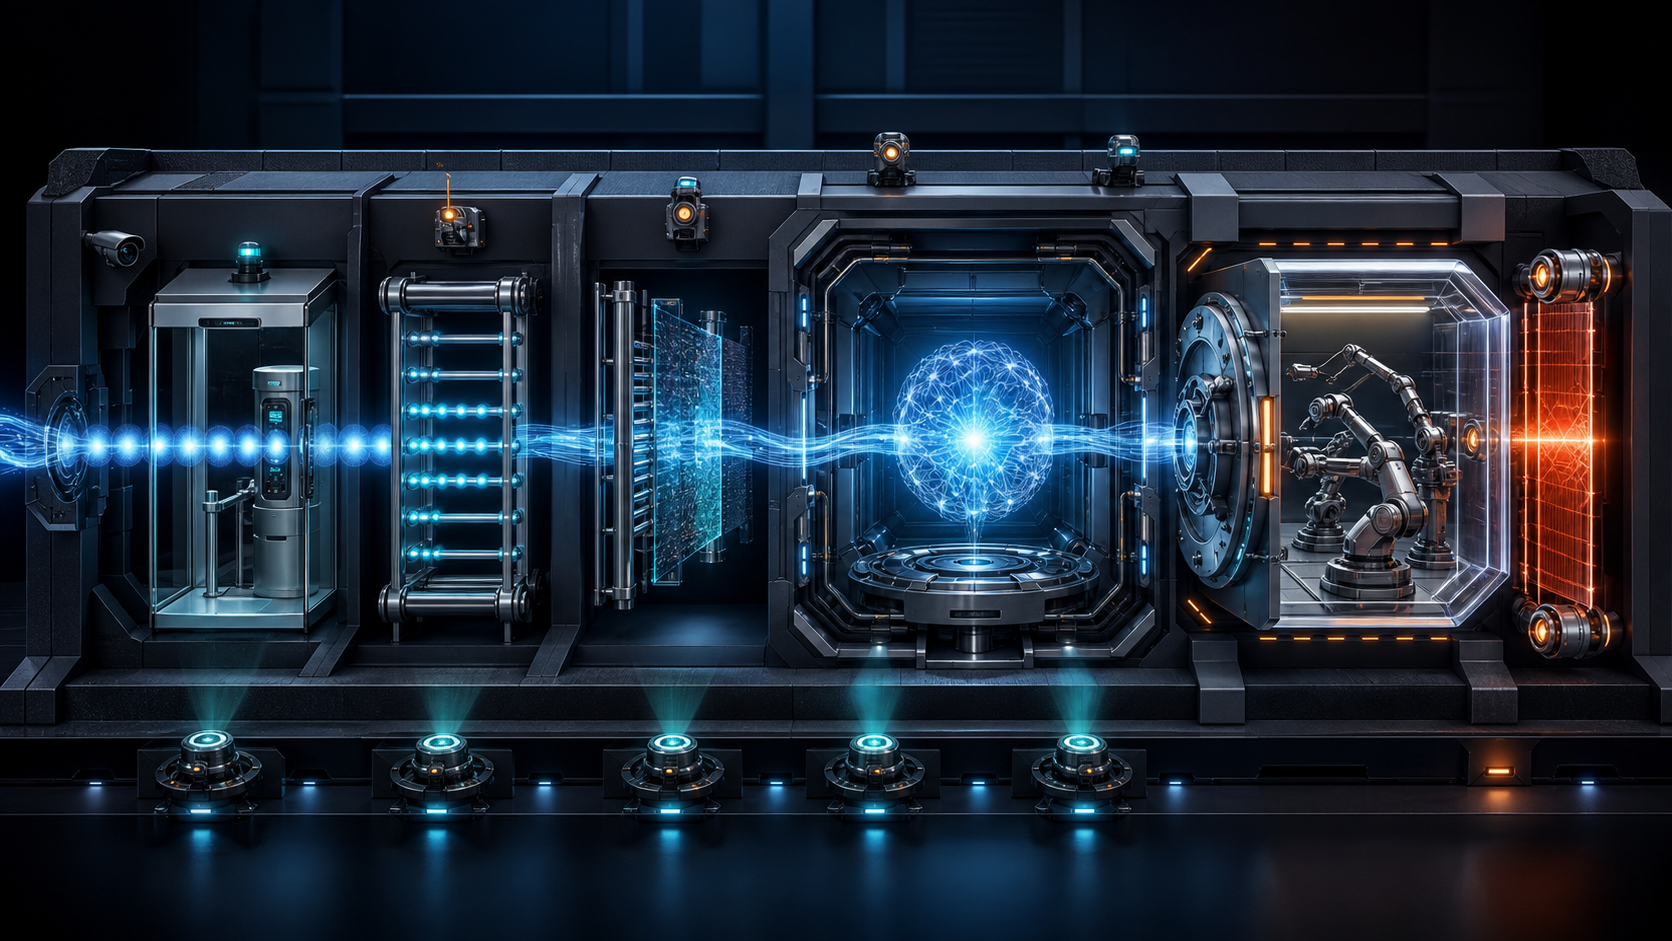
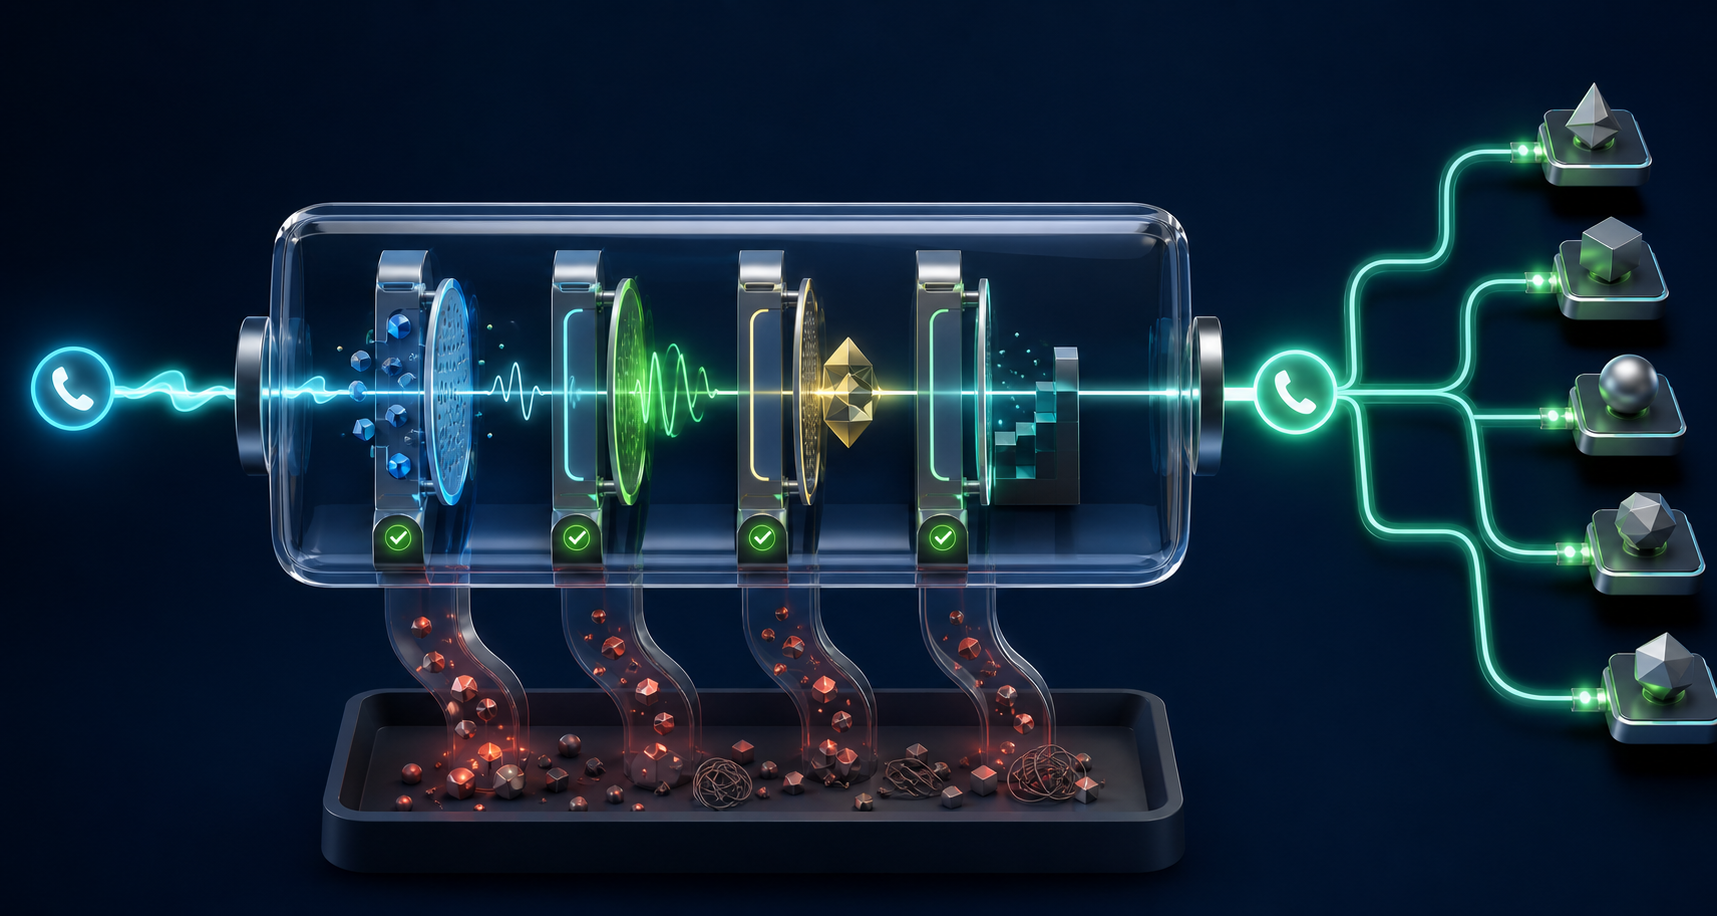
    A request signal passes through layered security gates before reaching an AI core and protected tool mechanisms.

    No safety prompt can carry this responsibility alone. Prompts influence model behavior, but they are not security boundaries. Use several controls with different failure modes, and place deterministic checks wherever failure could expose data, spend money, alter content, or trigger an external action.

    1. Put authorization outside the model. Resolve the authenticated principal in application code, grant the least privilege needed for the workflow, and verify permission again when a tool executes. Never let generated text decide whether the caller may read, publish, delete, or export something.
    2. Separate read and write capabilities. An assistant that only needs to draft content should not inherit publishing or deletion rights. When write access is required, constrain the allowed resource, action, fields, and destination.
    3. Normalize for analysis without overwriting evidence. Retain the original request, then create a canonical representation for similarity detection. Normalization can help reveal superficial changes in spacing, character representation, formatting, or casing, but it must not silently change the content executed by downstream systems.
    4. Maintain campaign state. Record the actor or service identity, session, endpoint, model route, normalized intent cluster, policy decision, tool request, and outcome. Look for repeated denials, rapid reformulations, alternate-route probing, and requests that converge on the same protected capability.
    5. Add adaptive friction. As campaign risk rises, reduce retry opportunities, disable expensive fallback routes, introduce a cooldown, require stronger authentication, or move the request to human review. Apply the strongest friction to workflows with data access or irreversible effects rather than imposing the same response on harmless drafting tasks.
    6. Gate outputs and tool calls separately. Check generated content against the output policy, validate structured fields, reject unexpected tool names or parameters, and limit the records or resources returned. A harmless-looking explanation must not conceal a disallowed action request.
    7. Define safe failure behavior. If moderation, identity resolution, authorization, or final validation is unavailable, return a controlled error for protected operations. Do not route around a failed safeguard to preserve a smooth user experience.
    8. Protect the control plane. Restrict who can change system prompts, policy rules, model routes, tool definitions, and safety thresholds. Log those changes and make rollbacks possible, because a campaign can exploit configuration drift as readily as model variability.

    There is no universal safe retry count. A blanket limit low enough for a sensitive data-export agent may be needlessly hostile in a public brainstorming tool. Set budgets by consequence, then examine legitimate retry behavior before choosing enforcement thresholds. Track false positives alongside security outcomes so that users who are clarifying ambiguous, multilingual, or accessibility-related requests are not treated automatically as attackers.

    Be careful with model-based safety judges as well. A second model can add useful evidence, but it may share blind spots with the model it evaluates. Use deterministic authorization and validation for hard boundaries, with model judgments contributing to risk scoring rather than granting privileged access on their own.

    Test the full campaign without publishing an exploit kit

    A single-prompt red-team check will miss the defining behavior of Best-of-N. Your evaluation runner should group related attempts, preserve production routing logic, and score whether any attempt reaches a prohibited outcome. Keep testing authorized, isolated, and away from live customer data or publishing systems.

    1. Define the breach before generating tests. Describe prohibited outcomes in observable terms, such as returning a protected field, invoking a disallowed tool, publishing without approval, or producing content that violates a named policy. A vague label such as “unsafe response” produces inconsistent scoring.
    2. Build campaign families. Group sanitized test cases by underlying objective, then vary the permitted dimensions relevant to your system, such as phrasing, format, language, model route, and retry sequence. Keep actionable attack strings in an access-controlled security repository rather than general documentation or analytics dashboards.
    3. Reproduce the production topology. Include the actual order of input checks, retrieval, routing, fallback behavior, output gates, tools, and error handling. Testing the base model alone does not test the application your users can reach.
    4. Run attempts as connected sequences. Carry session and risk state between related requests. Also test whether switching endpoints or invoking an automated agent incorrectly resets that state.
    5. Score outcomes at two levels. Retain per-request decisions for diagnosis, but make campaign-level success the headline measure. A system can have an impressive individual refusal rate while still allowing too many campaigns to obtain one useful failure.
    6. Review the most consequential path first. A policy-breaching paragraph matters, but a tool call that exposes private data or changes a live site demands tighter controls and faster remediation.
    7. Version the evaluation and rerun it after changes. A new model, system prompt, router, retrieval source, guardrail, tool definition, or fallback rule can alter campaign behavior even when the visible feature appears unchanged.

    Your evaluation dashboard should include the campaign any-success rate, attempts to the first breach, breach severity, detection and containment outcomes, tool or data-boundary violations, and false-positive friction for legitimate users. Do not collapse these into one average. A small number of severe authorization failures should remain visible rather than being diluted by many harmless refusals.

    Stop a test immediately if it begins interacting with real user records, external recipients, paid services, or live publishing. Move the scenario into an isolated environment with synthetic data and inert tools. The purpose of the exercise is to verify containment, not to prove that production damage is possible.

    Key takeaways for AI product owners

    • One successful refusal does not establish safety; measure whether any attempt in a related campaign succeeds.
    • Best-of-N exploits repeated opportunities and inconsistent decisions, so retries, fallback models, alternate endpoints, and agents all belong in the threat model.
    • System prompts and model-based judges can support safety, but they cannot replace deterministic authentication, authorization, validation, and tool restrictions.
    • Aggregate related attempts without assuming every retry is malicious; calibrate friction to the consequence of the requested capability.
    • Test the production workflow as a sequence, then report campaign-level success and breach severity alongside per-request refusal metrics.
    • Keep security payloads controlled, use synthetic data and inert tools, and never red-team an external or production system without authorization.

    Before your next release, choose the AI workflow with the greatest access to data, tools, or publishing. Trace every place where a rejected request can receive another model call or another route. Then add campaign-level telemetry and a deterministic gate at the highest-consequence handoff.

    That review will not eliminate model variability. It will prevent variability from becoming permission.

    References


  • SEO Under Constraints: Rendering and Restricted Keywords

    SEO Under Constraints: Rendering and Restricted Keywords

    Your page can fail search visibility in two places at once. The content a crawler needs may not exist until JavaScript runs, while the phrase customers actually search may be prohibited by legal, trademark or brand rules.

    Treat those as separate failure modes. First, make the page understandable without waiting for client-side rendering. Then build relevance around the intent you are allowed to express. That order matters: stronger copy cannot rescue content a crawler never receives.

    Separate retrieval problems from relevance problems

    A rendering constraint affects retrieval. The server returns a thin document, and JavaScript later inserts the main copy, navigation, product details or internal links. A wording constraint affects relevance. The page is available, but the language that connects it to a valuable query is weak, indirect or deliberately absent.

    When both occur on the same page, teams often misread the symptoms. An editor adds more synonyms when the copy is missing from the initial response. A developer improves rendering while the approved vocabulary still fails to describe the searcher’s need. Neither change closes both gaps.

    QuestionWhat to inspectWhat the result means
    Can a crawler understand the page before JavaScript runs?The raw HTML response, including the title, main heading, essential copy and linksIf the page’s purpose is missing, you have a retrieval problem.
    Can a visitor understand the offer without the restricted phrase?Headings, body copy, definitions, attributes, use cases and related terminologyIf the offer remains vague, you have a relevance problem.
    Is the phrase legally prohibited or merely discouraged?The written rule for body copy, metadata, links, comparisons, questions and definitionsThe permitted tactics depend on the actual boundary, not an informal preference.
    Does the approved vocabulary match how people express the need?Query data grouped by intent rather than one isolated keywordA large demand gap may justify revisiting the policy or creating a stronger semantic route.

    Run these checks before changing templates or copy. They tell you whether the next ticket belongs with engineering, content, legal or all three. They also give each team a testable acceptance criterion instead of the vague instruction to improve SEO.

    Put the essential answer in the initial HTML

    Solid core page panels emerge first from a server while translucent secondary modules assemble behind them.

    Google can execute JavaScript, but execution is not the same as immediate, complete discovery. Pages can be queued until rendering resources are available, after which a headless browser processes the client-side code. That extra stage creates another opportunity for delayed or incomplete discovery.

    The dependency is even riskier outside Google. Many AI crawlers and other non-Google bots do not consistently execute JavaScript. If the useful answer exists only inside a client-rendered component, those systems may receive a shell rather than a document they can quote, classify or follow.

    You do not need to rebuild every interaction as a no-JavaScript application. You do need an HTML-first discovery path for anything that establishes what the page is, what it offers and where its important links lead.

    • Return a unique, meaningful page title and a clear main heading in the server response.
    • Include the primary explanation, answer, product description or service description before client-side code runs.
    • Expose essential facts that determine whether the result satisfies the visitor’s need. Do not hide the only useful details behind tabs, filters or event handlers.
    • Render primary navigation, breadcrumbs and contextual internal links as ordinary anchors with real destinations.
    • Deliver structured information needed to identify the page and its subject in the initial document where practical.
    • Add JavaScript for filtering, personalization, live calculations and other interactions after the discoverable foundation is present.

    Server-side rendering, static generation and pre-rendering can all provide that foundation. The right choice depends on how often the content changes and how much of the interface is truly dynamic. A stable service page may suit static generation. A frequently updated catalogue may need server-side rendering. A client-rendered application can selectively pre-render its public discovery pages while keeping authenticated workflows dynamic.

    A <noscript> block can be a safety net, but it should not become a second, neglected version of the page. If you use one, keep it concise and aligned with the visible experience. The safer architectural target is meaningful server-delivered HTML that JavaScript enhances rather than replaces.

    Test the response, not just the finished screen

    A browser screenshot with JavaScript enabled proves that a visitor can see the interface. It does not prove that a crawler received the content or that the links are discoverable. Use this sequence on every important template:

    1. Open the raw server response or page source. Find the title, main heading, first useful answer and primary links.
    2. Load the page with JavaScript disabled. Confirm that its subject and next step remain understandable.
    3. Inspect critical links. They should have crawlable destinations rather than relying only on click handlers.
    4. Compare the initial and enhanced versions. They can differ in presentation, but they should not contradict each other or describe different offers.
    5. Repeat the check while logged out and without stored browser state. Public discovery must not depend on a previous session.
    6. Test a sample from every shared template. Passing one editorial page says little about a product, location or category template built through a different rendering path.

    Prioritize pages by consequence. Start with the homepage, high-demand landing pages, major categories, locations and pages that supply internal links to deeper content. A missing decorative widget is inconvenient. A missing product description or category link changes what the crawler can understand and reach.

    Map the search intent before working around a restricted term

    Hands arrange groups of pictorial tokens along illuminated paths around a locked central tile.

    Do not treat every keyword restriction as the same instruction. A trademark concern, an absolute legal prohibition, a brand preference and a rule against making one phrase the primary focus create different boundaries. Get the rule in writing before anyone places the term in a heading, title, image description or link.

    The first question is not, “How can we hide this keyword?” It is, “What is the searcher trying to identify, compare or accomplish?” That change of frame gives you legitimate language to work with even when the familiar label is unavailable.

    Demand data can also reveal whether an internal naming preference carries a substantial visibility cost. In one senior-living comparison, “skilled nursing near me” showed 4,400 monthly searches while “nursing home near me” showed 27,100. Those figures do not create permission to use a prohibited phrase. They do show why legal, brand and search teams should make the decision with the same evidence in front of them.

    Build an intent map around the restricted query. Include:

    • The approved category: the clearest accurate name you are allowed to use.
    • The underlying job: what the person wants to buy, arrange, learn, compare or solve.
    • Defining attributes: materials, features, level of support, location, compatibility or other characteristics that make the offering identifiable.
    • Use contexts: the occasions, environments and situations in which the need appears.
    • Audience language: natural questions, synonyms, spelling variants and adjacent terms that people use for the same intent.
    • Necessary distinctions: what the offering is, what it is not and how nearby categories differ.

    For a beverage-insulation product, for example, the semantic field might include can cooler, insulated drink sleeve, beer, cold drinks, party favors and occasions such as a bachelorette party. No single substitute has to impersonate the restricted name. Together, accurate category, attribute and context language can make the page’s subject clear.

    Use the exact term only where permission is explicit

    Some policies allow a term in a factual definition, comparison, question or combined product label but prohibit presenting it as the brand’s preferred category. If legal or brand reviewers approve that boundary, a limited contextual mention can clarify the relationship between the common query and the approved offering.

    If the phrase is prohibited everywhere, do not smuggle it into metadata, alternative text or anchor text. Those fields are still published content. Search engines can process them, users may encounter them, and moving a term out of the visible body does not remove a trademark or compliance concern.

    Apply the same rule to each element:

    • Title and main heading: lead with the approved category and the page’s actual promise.
    • Introduction: answer the underlying need immediately. Do not force awkward synonyms into a sentence that becomes harder to understand.
    • Definitions: explain unfamiliar approved terminology and its boundaries. Use the restricted label only if that explanatory use has been cleared.
    • Internal links: choose descriptive anchor text that truthfully identifies the destination. An approved common term can be useful; an unapproved one remains unapproved.
    • Alternative text: describe the image and its purpose. It is not a storage area for keywords that copy reviewers rejected.
    • External links: do not build an artificial exact-match pattern. Use language that is accurate, natural and permitted in that context.

    You may still earn visibility without the exact phrase because relevance can be established through related concepts and intent. It is not a guarantee, especially when competitors can use the dominant wording directly. Set expectations accordingly: the goal is the strongest truthful signal set available under the constraint, not a loophole that makes the constraint disappear.

    Use one launch gate for code, copy and compliance

    A constrained page should not move through engineering, editorial and legal as three disconnected deliverables. Give it one acceptance checklist. That prevents a technically crawlable page from shipping with vague language, or approved copy from disappearing behind client-side rendering.

    1. Define the page’s job. Write one sentence stating who the page helps, what they need and what action the page should enable.
    2. Name the query family. Group the restricted term, approved synonyms, questions, category language, attributes and use cases by shared intent.
    3. Record the wording boundary. Specify whether the term is banned everywhere, allowed only in named contexts or merely excluded as the primary label. Cover headings, body copy, metadata, links and image descriptions separately.
    4. Draft the minimum complete answer. Before designing interactive elements, write the heading, concise explanation, essential facts and next-step links that must exist in the initial HTML.
    5. Place approved relevance signals. Use the approved category prominently, then add useful attributes, applications, distinctions and definitions. Each addition should improve understanding, not just keyword coverage.
    6. Render the foundation on the server. Choose static generation, server-side rendering or pre-rendering for the public content. Hydrate interactive features on top of it.
    7. Run two reviews. Technical QA verifies the raw response and crawlable links. Editorial and legal review verify that every published field follows the wording policy.
    8. Measure by query group and template. Watch whether the intended family of searches reaches the page and whether affected templates are discoverable. Do not judge the work from one exact keyword or one successfully rendered URL.

    Write the acceptance criteria so failure is obvious. “Improve crawlability” is not testable. “The service description and links to all primary locations appear in the initial HTML” is. “Use related keywords” is equally weak. “The title names the approved category, and the body explains its use, defining attributes and difference from adjacent categories” gives an editor something concrete to deliver.

    When a page still underperforms, return to the two failure modes. If the content is absent from the response, fix retrieval. If it is present but does not clearly resolve the intent, fix relevance. If the exact phrase would materially change the opportunity but remains prohibited, take the demand evidence back to the decision-maker rather than quietly violating the rule.

    Key takeaways

    • Rendering and keyword restrictions are independent constraints: one limits retrieval, while the other limits relevance signals.
    • Put the page’s heading, essential answer, core facts and important links in server-delivered HTML.
    • Use JavaScript to enhance the experience, not as the only delivery mechanism for content that must be discovered.
    • Clarify whether a restricted term is legally banned, contextually permitted or simply discouraged before placing it anywhere.
    • Build relevance through approved category language, intent, attributes, use cases, definitions and natural internal links.
    • Make raw-HTML validation and wording compliance part of the same launch gate.

    Start with one high-value template this week. Capture its raw HTML, mark the essential content that is missing, document the exact wording boundary and rebuild the smallest complete answer that satisfies both. Once that page passes, turn the checks into requirements for every template that follows.

    References


  • Google Spam Reports and Manual Actions: A Practical Playbook

    Google Spam Reports and Manual Actions: A Practical Playbook

    You’re looking at a search result that appears to rank through manipulation, and you’re deciding whether to report it. Before you submit anything, write as though the site owner will read every word. They might.

    The same principle works in reverse. If your site receives a manual action accompanied by a reporter’s wording, don’t treat that wording as a complete diagnosis. Use it as a lead, verify the underlying behavior, and fix the full pattern rather than the one example placed in front of you.

    A spam report is evidence, not a guaranteed penalty

    Google says it may use a spam report to take manual action against violations. The word “may” matters. Filing a report isn’t the same as proving a violation, and it doesn’t guarantee a particular outcome. Your submission gives Google information it can evaluate.

    A manual action is different from an ordinary ranking fluctuation. It is a specific enforcement response to conduct Google considers contrary to its spam policies. Ranking-manipulation techniques can already hurt visibility; a manual action creates a separate issue that the site owner must identify and remedy.

    The consequential change is what happens to your written explanation. When Google issues a manual action based on a submission, it can send the open-text report to the affected site owner verbatim. Google says it doesn’t include other identifying information, so the report remains anonymous only if you avoid placing personal information in that field yourself.

    That creates two separate responsibilities. You need enough detail to make the suspected violation understandable, but you also need to remove anything that identifies you, your employer, your client, or a confidential method. An accurate report can still expose you if its wording contains a signature, email address, client name, internal ticket number, private dashboard label, or a revealing description of how you obtained the evidence.

    Key takeaways

    • Google may use a spam report when taking manual action, but a submission doesn’t guarantee enforcement.
    • The site owner may receive your open-text explanation exactly as you wrote it.
    • Anonymity depends on what you omit, not merely on leaving your name out of a dedicated identity field.
    • A useful report describes observable behavior, representative URLs, scope, and the suspected ranking effect without guessing at intent.
    • If your site is affected, treat the copied report as context and investigate the complete implementation behind the named examples.

    Decide whether your concern is ready to report

    An investigator sorts blank webpage tiles and other clues while a magnifying lens illuminates a repeated suspicious pattern.

    A competitor outranking you isn’t evidence of spam. Neither is disliking its content, business model, brand, or search presence. The relevant question is narrower: can you point to an observable technique that appears designed to manipulate rankings and explain what another reviewer should inspect?

    Apply three gates before submitting

    1. Policy gate: Describe the suspected ranking manipulation rather than the commercial dispute surrounding it. If your complaint depends mainly on unfairness, annoyance, or assumed motives, it isn’t ready.
    2. Evidence gate: Make the observation reproducible. Identify representative URLs, the visible pattern, and where it occurs. A reviewer should be able to inspect the same behavior without access to your private systems.
    3. Disclosure gate: Assume the entire open-text field will reach the site owner. Remove personal information, confidential business details, emotional commentary, and clues that aren’t necessary to understand the suspected violation.

    Keep observation and inference separate. “These URLs contain the same element” is an observation. “The company created it solely to deceive Google” is a claim about motive. You can explain why a pattern appears ranking-oriented without pretending to know who approved it or what they intended.

    Use public, inspectable evidence wherever possible. If confidential information is essential to your allegation, stop before pasting it into the form. Verbatim transmission means the open-text field isn’t an appropriate place for trade secrets, private communications, access credentials, non-public analytics, or information you aren’t authorized to disclose.

    Write for verification, not persuasion

    A strong report is compact enough to follow and detailed enough to inspect. This structure keeps the submission focused:

    1. State the concern: Name the suspected technique if you’re confident about the terminology. Otherwise, describe the behavior plainly instead of forcing an uncertain policy label.
    2. Give representative examples: Include exact URLs or clearly identified locations. Choose examples that demonstrate the pattern rather than supplying an undifferentiated dump.
    3. Describe what is visible: Explain what repeats, where it appears, and how the examples relate to one another.
    4. Explain the ranking connection: Say why the behavior appears intended to influence search visibility. Don’t substitute accusations for that explanation.
    5. Define the apparent scope: Note whether the examples share a template, path, section, or other observable characteristic. Label any estimate or inference as such.
    6. Run a disclosure check: Remove names, contact details, employer or client references, internal identifiers, and unnecessary descriptions of your investigation.

    You can draft the report under five labels: Concern, Examples, Observed pattern, Search impact, Apparent scope. Delete the labels before submission if the form doesn’t need them, but keep the logic. It forces each allegation to carry evidence and prevents background frustration from taking over the report.

    Then perform a final test: could the site owner read this text without learning who you are, and could an independent reviewer understand it without calling you for clarification? If either answer is no, revise before submitting.

    If your site receives a manual action with copied report text

    A site owner and auditor trace one blank report slip to repeated defects across interconnected webpage panels and repair the wider pattern.

    Copied wording can feel accusatory, vague, or personally motivated. Don’t make the identity of the reporter your first investigation. The operational problem is Google’s enforcement decision and the site behavior associated with it. Trying to identify or confront the reporter won’t repair the issue affecting search visibility.

    Preserve the notice and the copied text exactly as received. Then turn the narrative into testable claims. Separate the named URLs, alleged behavior, claimed scope, and supposed ranking effect. This gives your team an investigation plan instead of one emotionally loaded block of prose.

    1. Confirm the examples: Inspect each named URL and record what is currently present. Account for recent changes rather than assuming today’s page matches the version that triggered the action.
    2. Find the implementation: Determine whether the behavior comes from an editorial decision, template, plugin, automation, vendor, deployment process, or another shared mechanism.
    3. Expand the scope: Search for every page or asset produced by that mechanism. A report may name only a few examples even when the implementation is broader.
    4. Assess the allegation independently: Some wording in the copied report may be incomplete or mistaken. Verify the behavior against the applicable policy instead of accepting or rejecting the whole submission based on its tone.
    5. Correct the underlying practice: Remove or change the mechanism responsible for the violation. Editing only the reported URLs leaves the same risk wherever the pattern was repeated.
    6. Keep a remediation record: Document affected areas, causes, changes, owners, and verification. Follow the instructions supplied with the manual action when presenting the resolution to Google.

    If the behavior came from an outside supplier, disabling one output isn’t enough. Establish who approved the tactic, what else the supplier changed, and whether the same logic remains active elsewhere. The objective is to be able to say what happened, how far it spread, what stopped it, and how you verified that it is no longer operating.

    If you believe the allegation is wrong, build the response from verifiable facts. Show what the pages do, why the suspected pattern isn’t present, and what you checked across the wider site. A factual rebuttal is more useful than speculation about a competitor’s motives.

    Make spam reporting a controlled SEO process

    Agencies and in-house teams shouldn’t let spam reports leave the organization as improvised competitor complaints. The possibility of verbatim disclosure makes the text a governed external communication, even when the sender’s identity isn’t formally disclosed.

    Use a lightweight review process. Assign one person to verify the evidence and another to perform the disclosure check. Keep the review narrow: policy relevance, reproducibility, factual wording, representative examples, and anonymity. Don’t add names or internal commentary merely to create an approval trail inside the submitted text; keep that record in your own authorized system.

    • For outbound reports: retain the submitted wording, submission context, public evidence, and internal approval separately from the form.
    • For your own site: keep ownership records for ranking-related changes so a questionable pattern can be traced to its template, automation, vendor, or decision-maker.
    • For client work: establish who is authorized to report another site and which client details must never appear in the open-text field.
    • For incident response: designate who receives enforcement notices, who scopes the implementation, and who verifies remediation.

    Before your next submission, add one sentence to your team’s reporting checklist: “Assume the affected site will receive this text verbatim.” That rule improves the evidence, strips out avoidable risk, and keeps the report centered on the only thing Google needs to evaluate: the suspected search-policy violation.

    References

  • Google Removal Tools for SEO and Reputation Management

    Google Removal Tools for SEO and Reputation Management

    A damaging result is ranking for your name or brand, and the obvious question is whether Google can take it down. Sometimes it can. The right route depends on who controls the page, whether the page has already changed, and what kind of information it contains.

    Before you submit a request, decide what you actually need removed: the content itself, the URL from Google Search, or the result from a prominent ranking position. Those are different outcomes, and confusing them is the main reason removal efforts stall or create false confidence.

    First decide what you need Google to change

    Google offers specific removal routes for specific circumstances. It does not provide a general-purpose button for deleting any result that is inaccurate, embarrassing, critical, or commercially damaging.

    OutcomeWhat changesWhat remains
    Removal at sourceThe publisher deletes the original page. Google can remove the URL from its index after recrawling it.The result may remain visible until Google revisits the URL. Deletion also depends on the site owner taking action.
    Deindexing from GoogleGoogle stops showing the URL in its search results.The page may still work for anyone who has its direct address, and other search engines are unaffected.
    SuppressionSEO and reputation work moves more useful, accurate results above the unwanted result.The original content remains online and may still be found through other queries or direct access.

    Removal at source is the strongest outcome because it addresses the content, not merely its visibility. If you own the page, delete it when deletion is the intended result. If someone else owns it, request deletion or correction from that publisher before assuming Google can solve the underlying problem.

    Deindexing is still valuable. It can sharply reduce discovery through Google, which may be the immediate reputation objective. Just do not describe it internally or to a client as deletion. The distinction matters when you assess remaining exposure.

    Match the page state to the correct removal tool

    Three blank browser-page objects show a live page, a broken page, and an updated page beside different removal tools.

    Start with the current state of the page, not the severity of the complaint. A severe problem submitted through the wrong workflow is still the wrong request.

    1. You control the site and need short-term containment: use the URL removal tool in Google Search Console. It can temporarily hide a URL or directory from search results for up to six months. Use that window to complete the permanent site-side change. A directory-level request can affect multiple URLs, so confirm its scope before submitting it.
    2. The source page was deleted or changed, but Google still shows the old result: use the public outdated content removal tool. This workflow helps trigger a recrawl after the source has changed. It is not a way to remove an unchanged third-party page simply because you object to it.
    3. The result exposes eligible personal information: use Results About You. Its covered categories include sensitive material such as government-issued identifiers and non-consensual explicit imagery. Eligibility depends on the type of information, not only on the distress or reputational damage it causes.
    4. The case involves non-consensual explicit images or other sensitive personal material on a third-party site: evaluate Google’s separate personal content removal form. This route can overlap with the concerns handled through Results About You, but it remains a distinct request path. Neither route forces the third-party publisher to delete its copy.
    5. The request depends on a legal right: use the relevant legal removal workflow. Available grounds can include copyright infringement and defamation, but a negative statement is not automatically defamatory and possession of a copy does not automatically establish copyright ownership. If the request depends on a legal conclusion, have a qualified lawyer assess it before you file.

    If none of those descriptions fits, repeated submissions through unrelated forms are unlikely to create a new basis for removal. Shift the effort toward publisher outreach, a properly assessed legal escalation, or suppression.

    Build a clean case before you submit anything

    A removal request is easier to route when you can describe the problem without mixing several different outcomes. Prepare a short case brief even if the eventual form asks for less information.

    • Exact URL: record the page address appearing in search, not merely the site’s homepage or domain.
    • Current source state: note whether the page is live, deleted, inaccessible, or materially changed. Save a dated screenshot before further outreach if the original state may matter.
    • Affected query: record the name, brand, product, or other search that exposes the result, along with the visible title and snippet.
    • Control: state whether you own the website, can contact its owner, or have no relationship with the publisher.
    • Removal basis: classify the case as temporary hiding, outdated content, eligible personal information, sensitive imagery, or a specific legal claim.
    • Requested outcome: say whether you want the source deleted, Google’s stale result refreshed, or the URL excluded from Google Search.
    • Previous action: document deletion, correction, publisher outreach, and earlier Google requests so that your team does not repeat work or submit conflicting explanations.

    Then use a simple sequence: change or remove the source when you can, submit the narrowest applicable Google request, record what you submitted, and check the source page and Google result separately. A request can succeed at the search layer while the content remains fully accessible at its original address.

    Handle sensitive evidence carefully. Government identifiers, explicit imagery, and similar material should not be copied into routine internal messages or shared beyond the people who need it for the request. If preserving or submitting evidence could affect a legal dispute, ask counsel how it should be retained.

    A removed result can still be a live reputation risk

    An empty space in a blank search-results panel sits in front of a still-active webpage connected to servers and devices.

    Track four outcomes separately

    A single completed status does not tell you whether the problem is resolved. Track the case at four layers:

    • Source status: is the original page live, corrected, or deleted?
    • Google status: does the exact URL still appear for the queries that matter?
    • Distribution status: is the same content discoverable through direct access or other search engines?
    • Reputation status: do searchers now see an accurate set of results, or does the unwanted URL still dominate nearby queries?

    This prevents a temporary Google action from being mistaken for complete resolution. Google’s tools cannot delete third-party content or remove it from every search engine. They address Google Search visibility within defined policies.

    Run removal and suppression as parallel tracks

    Do not wait for a removal decision before planning for the possibility that the request is ineligible, temporary, or narrower than expected. Continue appropriate publisher outreach while improving legitimate pages that should rank for the affected name or brand.

    Suppression is not a euphemism for deletion. It means creating and optimizing accurate, relevant content so that searchers encounter better information first. It is often the practical route when a page violates no applicable removal policy, the publisher will not cooperate, or the same reputation issue appears across several discovery channels.

    Escalate according to the real obstacle. A reputation specialist can help coordinate publisher outreach and search strategy. A lawyer is the appropriate professional when the case turns on copyright ownership, defamation, court orders, or another legal right. Neither should be treated as a guarantee that lawful third-party content will disappear.

    Key takeaways

    • Deleting a page at its source removes the content; deindexing only removes its Google Search visibility.
    • Google Search Console’s URL removal tool is temporary, with hiding available for up to six months.
    • The outdated content tool is appropriate after a page has already been deleted or changed, not as a shortcut for an unchanged page.
    • Results About You and the personal content removal form cover defined categories of personal or sensitive material.
    • Legal removal requests require an applicable legal basis; reputational harm by itself does not establish one.
    • Source resolution, Google removal, monitoring, and suppression are separate workstreams and should be measured separately.

    Start by writing one sentence that states whether the page is live, deleted, or changed; whether you control it; and which removal category applies. That sentence will usually identify the correct Google route. Submit it, document it, and open the source-side or suppression track without treating the search request as the whole solution.

    References

  • Google Analytics and Ads Consent Requirements: Audit Guide

    Google Analytics and Ads Consent Requirements: Audit Guide

    Your consent banner can look correct while your tags tell Google something else. That mismatch now carries more weight because Google Ads determines access to advertising identifiers from the ad_storage consent setting, rather than from a combination of Consent Mode and settings buried in Google Analytics.

    You need to verify the complete path from the choice a person makes to the value Google Ads receives. A polished banner, an installed consent management platform, or a linked Analytics property proves very little on its own. This guide shows you what changed, which settings still have separate jobs, and how to audit the implementation without confusing a reporting problem with a consent problem.

    The rule that now controls Google Ads data collection

    From June 15, Google Ads data collection relies exclusively on ad_storage for its advertising-consent decision. The practical rule is direct: if ad_storage is granted, Google Ads can use the available advertising signals; if it is denied, Ads is limited to less persistent signals.

    User’s advertising choiceRequired ad_storage stateExpected Google Ads behaviorWhat your audit must prove
    Advertising use allowedGrantedAds can use available advertising signals, including linking activity to a signed-in Google account when feasible.The grant is sent only after the relevant choice and is received by every applicable Ads tag path.
    Advertising use deniedDeniedAds is restricted to less persistent signals, which can include URL parameters such as gclid.The denied state reaches the tags promptly, persists as intended, and is not overwritten by another configuration.

    A denial does not necessarily mean that every observable advertising signal disappears. The possible continued use of a less persistent parameter such as gclid is part of the restricted behavior. Do not treat the presence of gclid as proof that ad_storage was granted, and do not treat continued conversion reporting as proof that the banner failed.

    The reverse matters too. Granting ad_storage does not establish that your consent experience is legally valid. Consent Mode implements a decision; it does not determine what your organization must ask, how the request must be worded, or which visitors must see it. Have qualified privacy or legal counsel set those requirements, then use the technical audit to prove that the implementation follows them.

    Key takeaways

    • ad_storage is the controlling consent input for Google Ads advertising identifiers under the revised framework.
    • Google Signals still has a role in Google Analytics, but it no longer acts as an additional gate for Google Ads data collection.
    • A linked Google Analytics tag cannot override or narrow the advertising permission conveyed through ad_storage.
    • Denied ad_storage means restricted signal use, not necessarily the disappearance of every parameter or every measured conversion.
    • Your audit must inspect the value received by the tags on initial load, after each choice, after a changed choice, and on a later visit.

    Keep Google Signals, ad_storage, and the banner separate

    Three separate connected modules depict a privacy control panel, an audience analytics node, and an advertising-data gateway.

    The most common conceptual mistake is treating every Google privacy control as a different name for the same switch. There are three distinct layers in your implementation:

    • The consent interface is where a person accepts, rejects, or customizes purposes.
    • Consent Mode carries the resulting state to Google tags, including the ad_storage value used by Google Ads.
    • Product settings such as Google Signals control behavior within their own platform context.

    Previously, the flow of advertising data between Analytics and Ads could depend on both Consent Mode and Google Signals. That created an easy trap: a team could look at Google Signals inside Analytics and assume it was limiting what the linked Ads account could use.

    That assumption no longer holds. Google Analytics continues to use Google Signals for its own data collection, while Google Ads looks to ad_storage as its single source of advertising consent. A linked Google Analytics tag no longer determines whether Ads can collect or use advertising identifiers.

    Google Signals is no longer an Ads safety catch

    If your organization disabled Google Signals and assumed that decision also constrained Ads-linked data, revisit the implementation. When a visitor grants ad_storage, Google Ads may use all advertising signals available to it, including signed-in account linkage where feasible. The disabled Analytics setting should not be treated as a second denial.

    This is especially important when the people who own Analytics settings are different from those who own the consent platform or Ads tags. Document which team controls the banner wording, which team maps choices to ad_storage, and which team can change tag behavior. Otherwise, each team can believe another setting is providing a restriction that no longer exists.

    The visible choice is not proof of the transmitted state

    A person can click “Reject” while ad_storage remains granted because an update did not fire, fired too late, or was overwritten. The opposite can also happen: the person allows advertising, but a missing update leaves ad_storage denied and creates avoidable gaps in attribution and audience data.

    Judge the implementation by the state the tags actually receive. Banner screenshots are useful evidence of the interface, but they do not establish tag behavior. Your test record should connect the exact action, the resulting ad_storage value, the time the value changed, and the tag paths that consumed it.

    Audit the complete consent path, not just the banner

    A visitor's privacy choice travels through a consent manager, tag system, and storage checkpoint while magnifying glasses inspect each handoff before the signal reaches separate analytics and advertising destinations.

    Run the audit as a controlled set of user journeys. Do it in a test environment where possible, then repeat the critical paths in production without changing real consent choices or campaign settings. If your implementation varies by region, domain, device class, or authenticated state, each distinct path needs its own evidence.

    1. Inventory every control point. Record the consent management platform, banner configuration, tag manager containers, direct page tags, server-side delivery paths if used, linked Analytics and Ads properties, and the current Google Signals setting. The aim is to find every place that can set, delay, transform, or overwrite consent.
    2. Write the expected mapping before you test. For each banner choice, state the required ad_storage result. At minimum, define the advertising-allowed and advertising-denied outcomes. If your banner offers custom choices, document which exact purpose controls ad_storage rather than relying on a broad label such as “analytics” or “cookies.” Have the privacy owner approve this mapping.
    3. Inspect the initial page state. Check the ad_storage value available before the visitor interacts with the banner. The expected default depends on your approved consent policy and the context in which the banner appears; do not invent that policy during the technical test. Confirm only that the implementation matches the approved rule before Ads tags act on it.
    4. Run four core journeys. Test accepting all relevant purposes, denying advertising, allowing analytics while denying advertising if that combination is offered, and changing a previously saved choice. For each journey, record what the visitor clicked and the ad_storage state observed by the tags.
    5. Verify update timing and persistence. Confirm that the Consent Mode update call fires when the choice changes, that it carries the correct value, and that later scripts do not reverse it. Reload the page and start a later visit to check whether the saved choice is restored at the correct point in the tag sequence.
    6. Repeat the test across every tag-delivery path. A page tag can receive the correct state while a second container, embedded checkout, subdomain, or server-side path uses stale logic. Test the paths that actually send Analytics and Ads data rather than assuming a shared banner guarantees shared behavior.
    7. Create release evidence. Save the test date, environment, banner version, tag configuration version, journey, expected state, observed state, and result. Assign an owner and require a regression test after changes to the consent platform, tag manager, site templates, Analytics linking, or advertising setup.

    Pay particular attention to delayed or missing update calls. The revised framework is simpler because Ads has one consent input, but that also makes an incorrect ad_storage value decisive. A hidden Analytics setting is no longer available to compensate for a bad mapping.

    Use the denied path as your first diagnostic

    Start with a clean session and deny advertising. This path quickly exposes optimistic defaults, missing updates, stale saved choices, and scripts that overwrite the decision. Then change the choice to allowed and verify the new state without waiting for a new page. Finally, reverse it again. A system that works only after a reload is not faithfully handling an in-session change.

    If the banner offers a granular option that permits Analytics but rejects advertising, test it separately. It is the clearest way to find category mapping that incorrectly treats all measurement and advertising as one generic consent purpose. The names visible to a visitor may differ from Google’s setting names, so the approved mapping document is the bridge between policy language and tag configuration.

    Read measurement changes without weakening consent

    Consent affects measurement, attribution, and audience targeting, so a configuration change can produce a noticeable reporting change. That does not tell you whether the new result is correct. Lower numbers can reflect valid advertising denials, a broken update call, a changed default, or the removal of an old Google Signals-based restriction. You need implementation evidence before choosing a remedy.

    • If measured activity falls, compare the tested ad_storage states with the approved mapping before editing campaigns or the banner.
    • If attribution changes, remember that denied ad_storage can still leave less persistent signals such as gclid available. Parameter presence alone does not establish advertising consent.
    • If audience sizes change, confirm that consent updates fire correctly before changing targeting rules or pressuring visitors toward acceptance.
    • If Google Signals is disabled, do not assume Ads is also restricted. Test what happens when ad_storage is granted under the new separation of controls.
    • If results differ by page or region, inspect consent timing and tag delivery in each affected path rather than averaging the discrepancy away in a dashboard.

    Do not change banner wording, defaults, or rejection behavior merely to recover reported conversions. That can misrepresent the person’s choice and create legal exposure. The safe sequence is to have the privacy owner define the permitted experience, have engineering map it to ad_storage, and have analytics specialists explain the resulting measurement limits.

    A useful internal control can fit on one page: list each visitor choice, its expected ad_storage value, the owner who approved the mapping, the systems that receive it, the date of the last successful test, and a link to the evidence. Begin with the advertising-denied journey. Once that path is correct on initial load, after an update, and on a return visit, move through the remaining journeys and make the test part of every consent or tag release.

    References

  • Google Back-Button Hijacking: What to Audit and Fix Now

    Google Back-Button Hijacking: What to Audit and Fix Now

    If your site changes browser history to stop visitors from leaving, the grace period is over. Google’s enforcement date was June 15, 2026, so any remaining back-button trap is now an active search compliance problem rather than a future development task.

    The remedy is not to disguise the behavior or move it into another script. You need to restore the navigation outcome users expect: after arriving from another page, one press of the Back button should take them back to that page unless they have deliberately navigated through a meaningful intermediate state.

    Key takeaways

    • Google made back-button hijacking an explicit malicious-practices violation, with enforcement beginning June 15, 2026.
    • Possible consequences include a manual spam action or an automated demotion in Google Search.
    • The deciding issue is the visitor’s navigation outcome, not whether your implementation uses a particular JavaScript API.
    • Audit first-party code, tag-manager deployments, advertising scripts, affiliate tools, themes, plugins, and experimentation platforms.
    • Do not delete every History API call blindly. Legitimate routers and interface states still need coherent browser history.
    • A passing test requires more than the disappearance of a popup: Back must return users through the places they actually visited, in the expected order.

    The policy judges the navigation outcome, not the API

    Back-button hijacking occurs when a page interferes with normal browser navigation. A visitor tries to return to the page they came from but is redirected somewhere they never chose, shown an unsolicited advertisement or recommendation, or otherwise prevented from leaving normally.

    That distinction matters during an engineering audit. Methods such as history.pushState, history.replaceState, and the popstate event are not inherently abusive. Single-page applications, tabs, filters, multi-step forms, and user-opened overlays can use browser history for legitimate reasons. The problem begins when the history stack no longer represents states the user knowingly entered.

    Use an outcome test instead of treating the presence of an API call as proof. A page needs remediation when you can reproduce behavior such as:

    • The visitor arrives from Google, presses Back, and lands on another site page, advertisement, or recommendation that they never visited.
    • The page adds invisible or meaningless history entries on load, forcing the visitor to press Back repeatedly before reaching the actual previous page.
    • A popstate handler immediately pushes the current page back into history, sends the visitor forward again, or routes them to an unrelated destination.
    • An exit overlay appears because the visitor pressed Back, and dismissing it still does not restore the expected previous page.
    • A third-party script changes the Back destination only for certain campaigns, referrers, devices, or consent states.

    A legitimate interface state has a different shape. The user takes a visible action, the URL or interface meaningfully changes, and Back reverses that action. For example, a user-opened modal may be represented in history if Back closes that modal once. A visitor who never opened it should not inherit a synthetic modal state merely because the page loaded.

    Intent does not make a broken flow acceptable. A conversion team may call the behavior an exit offer, while an advertising vendor may describe it as retention. If the user cannot immediately return through their real browsing path, rename-and-retain is not a remediation strategy.

    Audit every landing-page path, not just the homepage

    A magnifying glass examines multiple routes into a generic website, including one route that loops back on itself.

    Back-button behavior often depends on how someone entered the site. Testing the homepage from a bookmark can therefore miss a trap that runs only on search landings, paid campaigns, content templates, affiliate pages, or pages with a particular tag-manager trigger.

    Run the audit as a reproducible navigation test:

    1. Inventory entry templates. Group URLs by the code and commercial stack they use: articles, product pages, category pages, lead-generation landers, comparison pages, and any separate mobile or campaign experiences. Start with templates that receive external entrances rather than selecting URLs at random.
    2. Create a real predecessor page. Begin on a Google results page or another controlled page, then open the target in the same tab. This gives Back a known destination. Typing a URL into an empty tab is not an adequate test because there may be no previous document to return to.
    3. Test before interacting. After the landing page finishes loading, press Back once. Record the destination, any intermediate screen, any overlay, and whether the site appears to reload or push you forward.
    4. Repeat after relevant states. Test after making a consent choice, opening and closing site controls, following an internal link, returning to the landing page, and triggering any advertising or recommendation component the template normally displays.
    5. Vary the environment. Repeat in clean sessions across the browser and device families your site supports. Include logged-in and logged-out states where applicable, as well as the consent choices that determine which third-party tags execute.
    6. Trace the responsible code. When a test fails, isolate first-party bundles, tag-manager containers, plugins, themes, advertising tags, affiliate scripts, and experimentation tools. Disable candidates in a safe test environment until the normal Back destination returns.

    Keep the findings in a small test ledger. It turns a vague sitewide concern into an assignable release plan:

    FieldWhat to recordWhy it matters
    Landing URL and templateThe tested URL plus the shared page typeLets you determine whether one failure affects a larger URL family
    Entry routeThe exact page visited immediately before the landing pageDefines the destination Back should restore
    Pre-Back actionsConsent choices, clicks, overlays, internal navigation, or no interactionExposes state-dependent triggers
    Observed resultThe first destination, intermediate states, redirects, ads, or loopsSeparates an expected state reversal from interference
    Code ownerBundle, tag, plugin, vendor, or team responsibleGives the remediation a clear owner
    Fix and verificationRelease identifier, test environment, production result, and date checkedPrevents an unverified configuration change from being marked complete

    A code search can accelerate the investigation. Look for uses of pushState, replaceState, popstate, location.assign, location.replace, meta refresh, and handlers attached to exit-related events. Treat each match as a lead, not a conviction. Removing a router’s legitimate state management without understanding it can break internal navigation, filters, deep links, or form recovery while leaving the actual third-party trap untouched.

    Fix the history model instead of masking the symptom

    Hands remove duplicate page layers from a tangled browser-history stack, leaving a clear sequence back to the original page.

    The correct fix depends on why the history stack was changed, but the acceptance criterion stays constant: browser history should reflect the visitor’s real journey.

    Remove deliberate retention traps

    If code adds dummy history entries when a landing page loads, remove that insertion. If a Back event triggers an advertisement, recommendation, interstitial, or unchosen redirect, remove the handler that causes it. Do not replace several dummy entries with one dummy entry; the first Back press would still fail the user’s expectation.

    Move legitimate retention content into the page. An inline recommendation, a clearly labeled link, or a user-invoked offer lets the visitor choose whether to continue. The browser’s navigation control should not become an undisclosed conversion mechanism.

    Preserve meaningful application states

    For a single-page application, map history to visible, reversible states. Push a new entry when the user deliberately moves to a meaningful view. Replace the current entry when you are correcting or normalizing the same state. When popstate fires, render the state it represents instead of immediately creating another entry that defeats the Back action.

    Check deep links and the Forward button after making this change. A repair that lets users escape but leaves URLs pointing at the wrong content is still a broken navigation model, even if it no longer resembles a retention trap.

    Contain third-party behavior you cannot verify

    When the behavior belongs to an ad network, affiliate script, conversion tool, plugin, or tag-manager template, identify the exact configuration that enables it. Turn that feature off and retest with the vendor code still present. If the feature cannot be isolated or its behavior changes outside your control, keeping the integration live means keeping the navigation risk live. Pause the responsible script until its Back behavior is predictable.

    Do not assume that a vendor-side setting changed production. Cached bundles, container versions, consent branches, and campaign-specific rules can preserve an older path. Confirm the rendered production experience after deployment.

    Treat the passed deadline as a release gate

    Google’s advance-notice period ended on June 15, 2026. From that date, the stated enforcement paths included manual spam actions and automated Search demotions. Those are distinct paths, so the absence of a known manual action does not prove that a site is unaffected or compliant.

    Do not read stable rankings immediately after the date as permission to leave the code in place. An enforcement start date is not a promise that every affected URL will show a visible change at the same moment. The reliable compliance signal is a clean navigation test, not a lack of obvious ranking movement.

    Before closing the remediation ticket, require these production results:

    • After a fresh external landing with no interaction, the first Back press returns to the immediate predecessor page.
    • After meaningful user-initiated navigation, repeated Back presses unwind those states in the order the user entered them.
    • No Back action opens an unrequested advertisement, recommendation, overlay, or destination.
    • The page does not insert a replacement history entry that sends the visitor forward again.
    • Forward navigation, deep links, filters, authentication flows, and multi-step interfaces still work where the affected code participates in them.
    • The test passes on production under the campaign, consent, device, and account states that control script execution.

    If search visibility declined around the enforcement date, do not declare back-button hijacking the cause from timing alone. First confirm whether the behavior existed, which templates contained it, when it was removed, and whether the same URLs pass now. That evidence gives you a defensible diagnosis while avoiding an unrelated rewrite.

    Schema, content expansion, and AI-search optimization do not remove a navigation trap. Put the work in the right order: contain the offending behavior, repair the history model, verify every affected template, and then return to broader optimization. Assign an engineering owner and an SEO owner now, and do not close the issue until one press of Back does what the visitor intended.

    References