Tag: Competitive Research

  • SEO Fundamentals for Beginners: A Practical Workflow

    SEO Fundamentals for Beginners: A Practical Workflow

    You have a website, a list of keywords, and an audit full of warnings. The tempting move is to edit every title, install another tool, or chase backlinks. That usually creates activity without answering the question that matters: what should organic search help this business accomplish?

    SEO becomes manageable when you follow a clear chain: understand the business, identify the searcher’s intent, create the right page, remove technical barriers, and measure whether the page advances a real outcome. This workflow gives you a practical way to do that without letting tools or AI make decisions you aren’t yet equipped to judge.

    Start with the business outcome, not the keyword list

    A keyword is only useful when it connects the right person to something the business can genuinely provide. That is why business context belongs at the start of an SEO project, before metadata, links, or optimization scores.

    Write down the answers to these questions before opening a keyword tool:

    • What is being offered? Name the product, service, information, or action precisely.
    • Who is it for? Describe the audience by its situation and need, not just by a broad demographic label.
    • What should the visitor do next? The intended action might be buying, requesting a quote, booking, subscribing, visiting a location, or continuing to another resource.
    • Why should this business be chosen? Identify the relevant difference: expertise, availability, approach, specialization, location, evidence, or another defensible advantage.
    • What result matters to the business? Decide whether success means qualified leads, sales, registrations, store visits, product discovery, or another observable outcome.

    Turn those answers into one sentence: “We need to help [audience] find [offer] when they need [outcome], then move them toward [action].” If you cannot complete that sentence clearly, you are not ready to prioritize keywords. More traffic will not repair a mismatch between the visitor, the offer, and the desired action.

    This business statement also protects you from a common beginner mistake: treating every query with visible demand as an opportunity. A query may be popular but irrelevant to the customers the business can serve. Another query may attract fewer people but describe the exact problem that leads to a valuable action. Prioritize the overlap between audience need and business value.

    Read the search results as evidence of intent
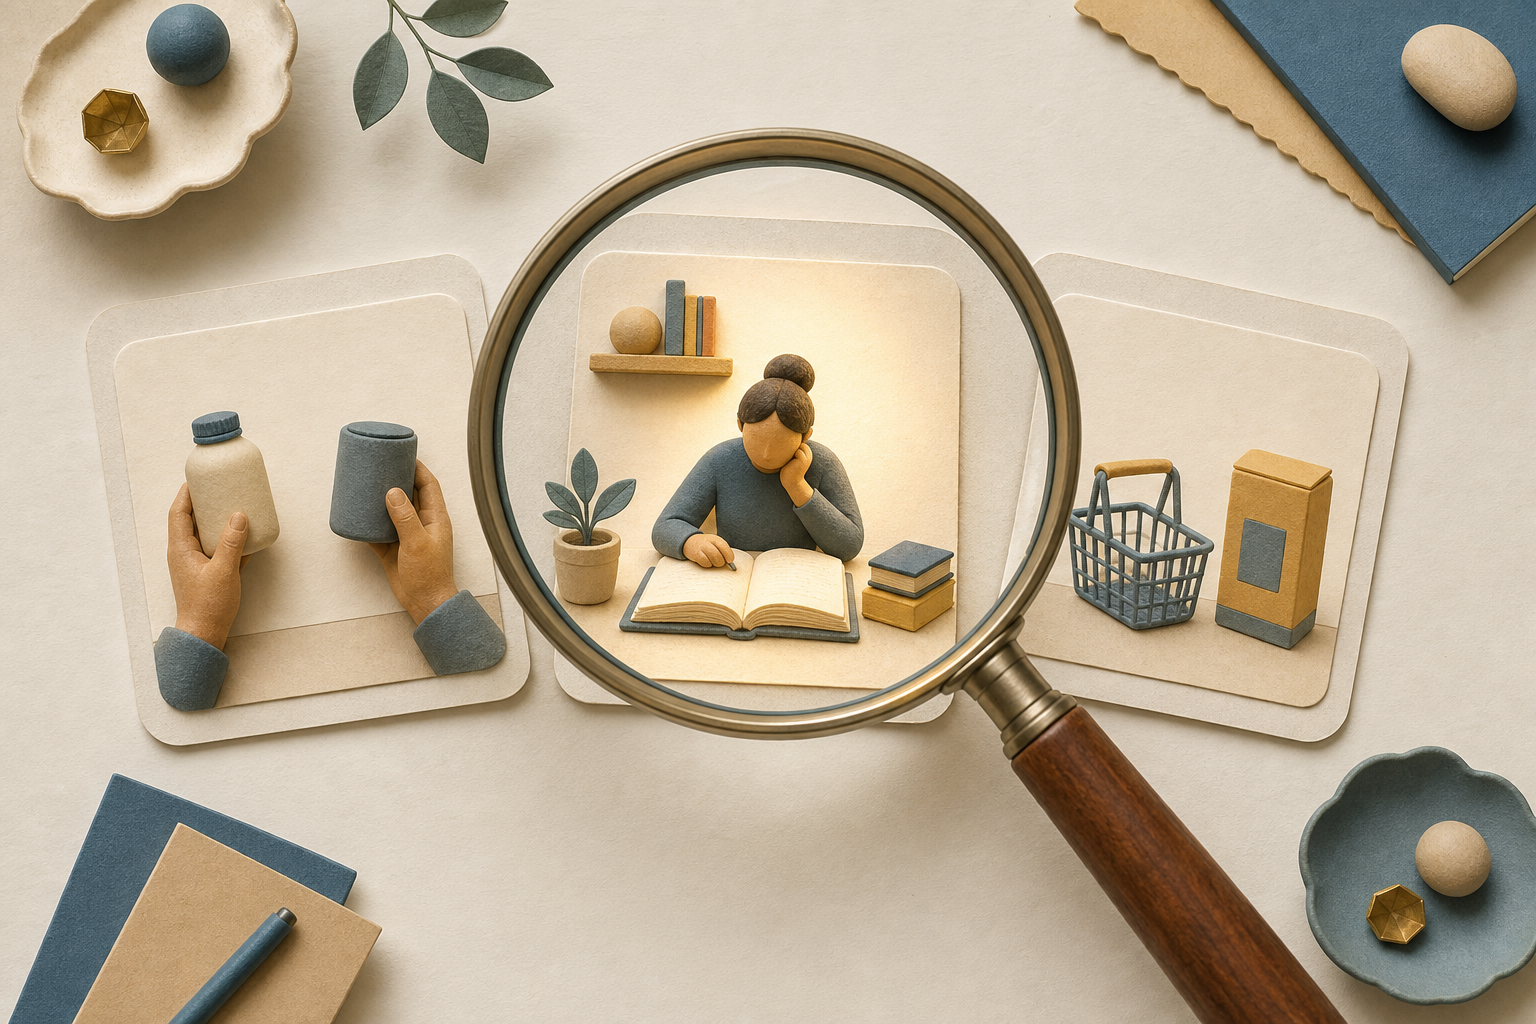
    A magnifying glass examines blank result cards illustrated with learning, comparison, and shopping scenes, with the learning card highlighted.

    Search intent is the job a person expects the results to help them complete. The same subject can support very different jobs: learning how something works, comparing choices, finding a specific website, locating a nearby provider, or completing a purchase. A page can mention the right words and still fail because it serves the wrong job.

    Before creating or rewriting a page, search the target query in the context your audience would use. Then inspect the results manually. This is not about copying competitors. It is about seeing how the search engine currently interprets the request.

    1. Classify the dominant page type. Are the results tutorials, category pages, product pages, service pages, comparison pages, videos, local listings, or something else?
    2. Identify the task they support. Decide whether the searcher is trying to learn, evaluate, act, navigate, or find something nearby.
    3. Note the recurring questions. Repetition can reveal information people are likely to need before completing the task.
    4. Inspect the search features. Images, videos, products, maps, answer-style results, and other formats can indicate that the request is not best served by plain text alone. Search presentations continue to change, so learning the available result features is part of learning SEO.
    5. Look for unresolved friction. Notice where existing results are vague, outdated, difficult to navigate, poorly matched to the query, or missing an important decision point.

    Do not assume that every detail on a ranking page caused it to rank. Its presence tells you that the search engine is willing to show that kind of result for the query. It does not prove that its word count, layout, heading count, or every covered subtopic is a requirement.

    Create a small intent brief from what you observe:

    • Target topic or query: the request you want the page to serve.
    • Searcher situation: what the person likely knows and what has brought them to search.
    • Job to complete: the decision, answer, destination, or action they need.
    • Appropriate page type: the format that can complete that job without unnecessary friction.
    • Essential answer: what the visitor should understand immediately.
    • Supporting proof: the details, examples, specifications, process, or evidence needed to trust the answer.
    • Logical next action: what the visitor should be able to do after getting the answer.

    This brief is more useful than a loose keyword list because it gives every optimization decision a test: does this help the intended visitor complete the intended job?

    Build one page that deserves to satisfy the query

    A keyword is an input to the page, not its outline. Your real task is to make the page useful enough that a person can recognize its relevance, get the necessary answer, verify important claims, and take the next sensible step.

    Use this sequence when drafting or improving the page:

    1. State the answer or value early. Do not make the visitor read a long preamble to confirm that the page addresses the query.
    2. Follow the visitor’s decision path. Explain what they need now, then what they need to compare, verify, avoid, or do next.
    3. Add information that changes understanding or action. Definitions, steps, examples, limitations, specifications, and evidence belong only where they help complete the task.
    4. Use a descriptive page title and main heading. Both should identify the subject clearly and set an accurate expectation. Clever wording is less valuable than immediate recognition.
    5. Use subheadings as signposts. Each section should answer a distinct question or move the task forward. If two sections do the same job, combine them.
    6. Connect relevant internal pages. Link to the next useful explanation, category, service, product, or action with anchor text that describes the destination.
    7. Make the next step proportionate. A visitor who is still learning may need a comparison or supporting explanation before being asked to buy or enquire.

    Use the primary wording naturally in the title, introduction, and relevant headings when it accurately describes the page. Do not force a phrase into every paragraph or create repetitive variations for the sake of density. Clear topical language helps both the reader and the search system; mechanical repetition makes the page worse for both.

    There is also no useful universal length for an SEO page. Stop when the visitor can complete the intended task without an important unanswered question. A simple navigational need may require little explanation. A consequential comparison may require definitions, criteria, trade-offs, and evidence. Let intent determine depth.

    Run a manual content gap check

    Open several relevant results and make a simple worksheet. Record the main question each page answers, the proof it supplies, the next step it offers, and the friction it leaves unresolved. Then decide what your page can make clearer, more complete, more specific, or easier to use.

    Do this work yourself while you are learning. Independent research before relying on AI teaches you how intent, page type, evidence, and search presentation fit together. If an AI system produces the worksheet first, you may receive a polished answer without developing the judgment needed to spot a bad one.

    Learn enough technical SEO to rule out invisible blockers
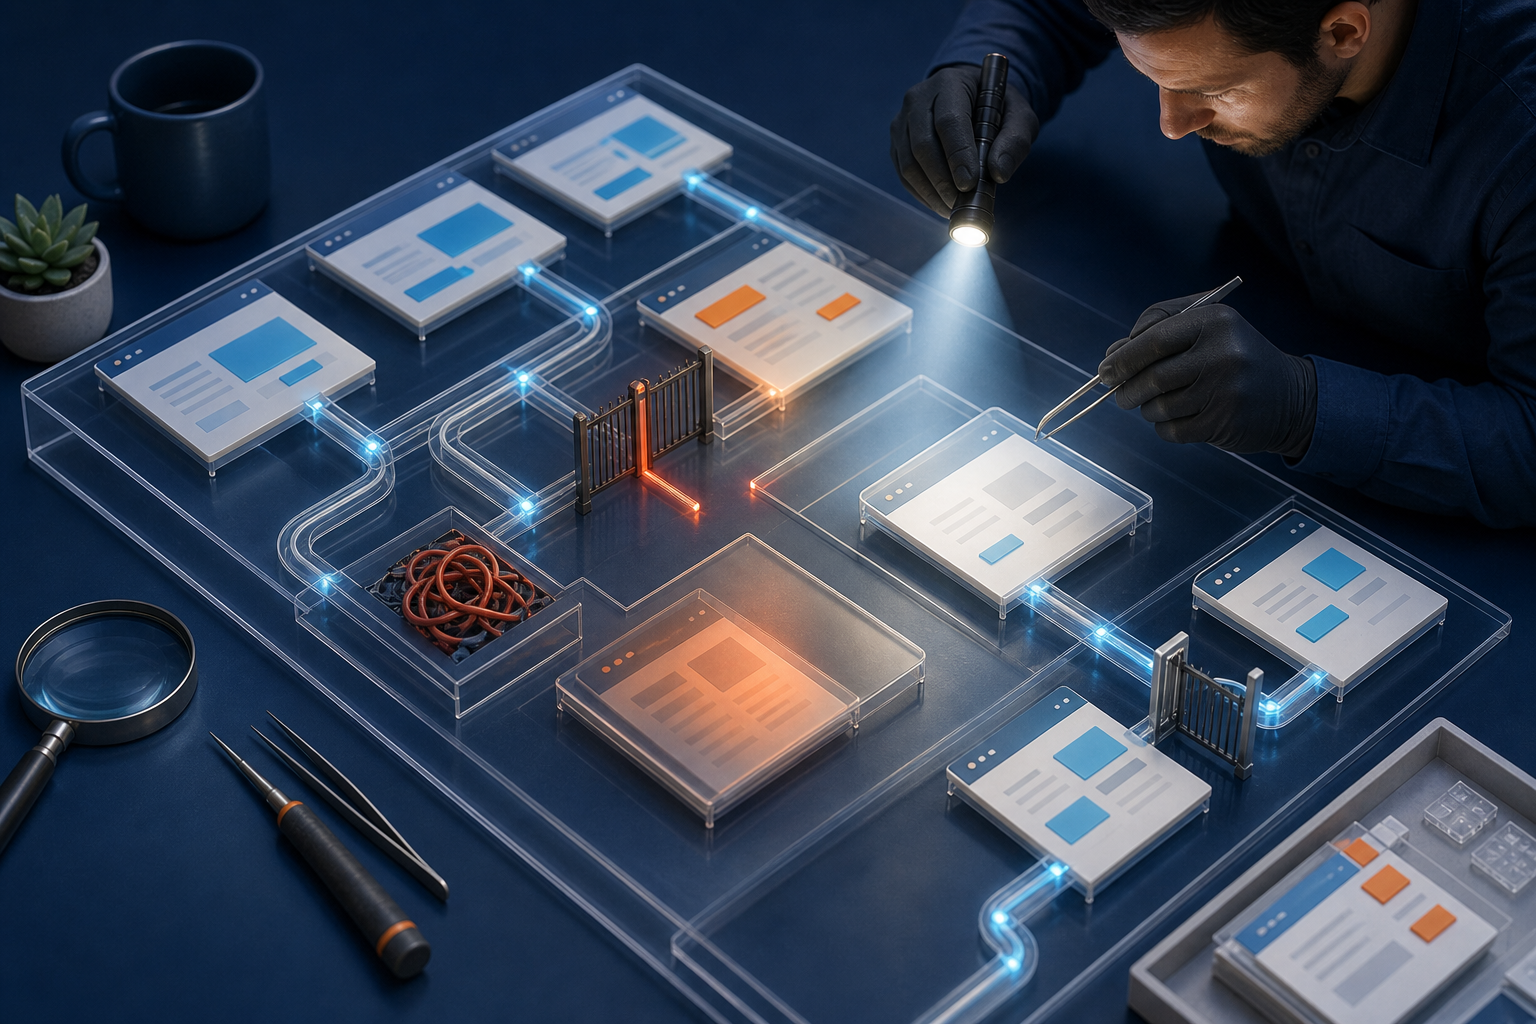
    A technician inspects a model website and illuminates a disconnected path, closed gate, tangled cable, and dim page tile hidden beneath it.

    Useful content cannot perform in search if the system cannot reach it, is instructed not to index it, or understands another URL as the preferred version. You do not need to become a developer before doing SEO, but you do need to separate discovery, indexing, and ranking problems.

    StageQuestion to answerBeginner check
    CrawlingCan the search system reach the URL and follow a path to it?Open the public URL while logged out, confirm that a normal internal link leads to it, and check that access rules do not block the intended crawler.
    IndexingIs the page allowed to be stored and considered for search?Check for a noindex directive, an unintended canonical URL, a redirect, or a duplicate page that makes the preferred version unclear.
    RankingIs the eligible page a strong match for the query and its intent?Compare its page type, opening answer, supporting information, and usability with the needs revealed by the search results.

    That distinction prevents wasted work. Rewriting a page will not remove an accidental noindex directive. Fixing a canonical setting will not make a transactional page satisfy an informational query. Diagnose the stage before choosing the remedy.

    Use this basic technical pass for every important page:

    • The public URL loads without requiring a private account or internal session.
    • The page is reachable through the site’s internal navigation or contextual links.
    • The page is not unintentionally blocked from crawling or indexing.
    • The canonical reference points to the version you actually want treated as primary.
    • Redirects lead visitors and crawlers to the intended final destination without unnecessary detours.
    • The page works on a small screen without hiding its main content or action.
    • The title and main heading describe this page rather than repeating generic site-wide wording.
    • Important text is present in the page itself rather than available only through an unreliable interaction.

    Do not change noindex, canonical, redirect, or robots controls merely because an audit labels them as warnings. Those controls may be intentional. Changing them without identifying the preferred URL can expose pages that should remain out of search, split attention across duplicates, or remove the version that currently works.

    When you need development help, send a reproducible problem rather than saying “SEO is broken.” Include the affected URL, what you expected, what happened instead, how to reproduce it, which page should be primary, and the business consequence. Building enough technical fluency to collaborate with developers is a more durable skill than memorizing isolated fixes, and developer relationships can deepen that technical understanding.

    Measure the chain, then use AI and AEO as extensions

    Measure where progress stops

    Rankings are not the business outcome. Measure the sequence from search eligibility to useful action so you can see where the page is failing:

    • Access and indexability: can the intended page be discovered and considered?
    • Search visibility: does it appear for queries that match the intent brief?
    • Search engagement: do the page title and result presentation earn visits from the right searchers?
    • On-page engagement: do visitors reach the information or next step the page was designed to provide?
    • Business outcome: do qualified visitors complete the action that matters?

    Use the first weak stage to choose the next action. If the intended page is not eligible for search, inspect technical controls. If it appears for the wrong queries, revisit the intent and page focus. If it appears for appropriate queries but attracts little engagement, check whether the title and description accurately communicate its value. If relevant visitors arrive but do not act, inspect the offer, proof, usability, and next step.

    Keep a change log with the affected URL, the reason for the change, what was changed, and the outcome you expect. Avoid changing every page and every element at once. A smaller, documented change makes the result easier to interpret and the lesson easier to reuse.

    Let AI accelerate work you can already evaluate

    AI can help organize terms, suggest questions, restructure a draft, identify possible omissions, or produce a first pass at repetitive markup. It should not decide the audience, intent, business priority, evidence, or preferred technical outcome for you. Those decisions require context that a plausible-looking output may not capture.

    Before accepting AI-assisted work, check it against the same fundamentals:

    • Does it serve the audience named in the business brief?
    • Does it complete the job described in the intent brief?
    • Are its factual claims accurate and supported?
    • Does it add a useful explanation, distinction, example, or next step?
    • Does it represent the actual product, service, policy, and expertise accurately?
    • Would you publish it if no optimization tool had assigned it a score?

    Extend the foundation to AEO and GEO

    The labels are still used in varying ways, but the operational distinction is useful. Traditional SEO focuses on making pages discoverable, indexable, relevant, and competitive in search results. Answer engine optimization focuses on making an answer easy to identify and use in answer-oriented experiences. Generative engine optimization focuses on making information clear, attributable, and usable when generative systems assemble responses. Understanding how SEO differs from AEO and GEO helps you plan visibility across more than conventional result links.

    The practical work still begins with the same foundation:

    • Answer the central question directly rather than hiding it behind promotional language.
    • Name products, organizations, people, places, and relationships consistently so the subject is unambiguous.
    • Use descriptive headings, lists, tables, and concise definitions when those formats make information easier to extract and verify.
    • Support consequential claims with visible evidence and appropriate citations.
    • Keep authorship, business identity, policies, and areas of expertise clear.
    • Use schema and JSON-LD only to describe information that the page actually contains. Markup can clarify meaning, but it cannot replace missing content or guarantee inclusion in an answer.

    Key takeaways

    • Define the audience, offer, desired action, and business outcome before choosing keywords.
    • Treat search results as evidence of intent and acceptable formats, not as a template to copy.
    • Build each page around one clear visitor job, then supply the answer, proof, and next step that job requires.
    • Separate crawling, indexing, and ranking problems before changing content or technical controls.
    • Measure the full path from search eligibility to business outcome so you fix the stage that is actually weak.
    • Use AI, AEO, GEO, schema, and automation after the underlying business, intent, content, and technical decisions are sound.

    Choose one important page and complete the workflow from beginning to end: write the business statement, build the intent brief, improve the page, run the technical pass, and define the outcome you will watch. Once you can explain why each change helps both the visitor and the business, use tools to repeat the process more efficiently.
    References

  • SEO and AEO Competitive Research: A Practical Workflow

    SEO and AEO Competitive Research: A Practical Workflow

    You can outrank a commercial rival and still lose the recommendation. An AI answer may cite another site, describe the category in a competitor’s language, or leave your brand out entirely. A conventional ranking report will not show you why.

    You need two connected views of the market: what people search for and how answer systems frame their choices. The workflow below gives you both, then turns the differences into content, positioning, technical, and product-marketing actions your team can actually own.

    See competition through two distinct observation layers

    SEO and answer engine optimization do not provide interchangeable versions of the same report. Traditional SEO is strongest at demand capture, keyword mapping, ranking analysis, and content-gap discovery. It tells you which pages compete for a query and where existing search demand may justify an investment.

    AEO, used here to mean research into AI-generated answers, observes a different outcome. It shows which brands, publishers, products, claims, features, and caveats appear when a user asks for an explanation or recommendation. That matters because AI answers can influence category perception and purchasing criteria before a search-result click occurs.

    Research layerWhat you observeQuestion it helps you answer
    SEOQueries, demand, rankings, competing URLs, page types, and content gapsWhere can we capture existing search demand?
    AEOBrand inclusion, citations, recommendations, claims, attributes, comparisons, and omissionsHow is the market being explained before the click?
    Combined viewWhether search visibility and AI representation reinforce or contradict each otherWhat should we create, clarify, prove, or escalate?

    The competitive sets will differ. Your SEO rivals may include publishers, marketplaces, directories, and informational sites that do not sell what you sell. Your AEO rivals may include brands that rarely outrank you but are repeatedly named as examples or recommendations. Other domains may shape the answer by supplying definitions, evidence, or comparison criteria without being vendors at all.

    Keep those roles separate. Calling every visible domain a direct competitor creates bad strategy. A publisher that owns the category definition calls for a different response than a vendor that owns the recommendation.

    Build the research set around a real customer decision

    Do not begin with a long list of company names. Begin with a bounded decision your audience needs to make. A useful decision zone combines a defined audience, a problem, a category, and an intended outcome. It is narrow enough that the questions belong to the same journey, but broad enough to reveal how that journey changes from education to evaluation.

    1. Name the decision. Write the specific choice the audience is trying to make, such as selecting a category, comparing approaches, validating a vendor, or resolving an implementation concern.
    2. Collect search-like queries. Include the terms used to define the problem, understand the category, compare options, evaluate features, and reduce risk. Preserve the wording people actually use rather than rewriting every query into your preferred terminology.
    3. Turn those queries into natural prompts. Add questions such as “What are the main ways to solve [problem]?”, “What should [audience] look for in [category]?”, “Which options fit [constraint]?”, and “How do [brand] and [competitor] differ for [use case]?”
    4. Separate branded and non-branded prompts. Non-branded questions reveal whether your brand enters the conversation without being invited. Branded questions reveal how the answer describes, compares, or qualifies it.
    5. Freeze the working set. Save the exact query and prompt wording before collecting results. If you continually add only the prompts where a competitor appears, you will manufacture the conclusion you expected to find.

    As results accumulate, classify every recurring entity into a functional competitive group:

    • Commercial competitors sell an alternative to the same buyer.
    • Search competitors occupy results your pages need to win, regardless of what they sell.
    • Answer competitors repeatedly appear in AI explanations, shortlists, or recommendations.
    • Category narrators supply the definitions, criteria, terminology, or evidence that shape the answer.

    This classification prevents a common analytical mistake: interpreting visibility as commercial preference. A cited publisher may be influencing the criteria, while a named vendor may be benefiting from them. You need to know which role each entity plays before deciding whether to create a page, strengthen a claim, earn a citation, or revise positioning.

    Pay particular attention to language that repeats across the journey. AI-answer research can expose recurring feature expectations, emerging themes, and the explanations the market associates with a category. Treat those observations as hypotheses to validate, not automatic instructions to copy a competitor.

    Run the audit as a repeatable evidence workflow

    Two analysts move evidence through connected observation, capture, comparison, and verification workstations.

    The tool stack should follow the question. Ahrefs and Semrush can support the conventional ranking and keyword layer, while platforms such as Profound and direct inspection in ChatGPT can contribute AI-answer observations. Tool count is not the goal. A traceable chain from observation to decision is.

    1. Establish the SEO baseline. For every priority query, record the apparent intent, demand estimate, your ranking URL, competing URLs, position, page type, and business relevance. Note whether the result is won by a product page, category page, explainer, comparison, directory, or another format. The page type often explains more than the competitor’s domain authority alone.
    2. Capture the AI answer verbatim. Save the platform, date, prompt, answer, visible citations, and any relevant test conditions. Do not reduce the result to a yes-or-no brand mention. Record whether the brand was cited as a source, used as an example, placed on a shortlist, recommended for a condition, compared neutrally, or accompanied by a warning.
    3. Extract decision criteria. List the features, benefits, limitations, proof points, use cases, and caveats the answer uses to distinguish options. Preserve the answer’s terminology alongside your own preferred terminology so that wording differences remain visible.
    4. Build a claim ledger. For each material claim, record who receives credit, which page or citation appears to support it, whether your site addresses it, and whether you can substantiate a stronger or more precise answer. Mark unsupported statements rather than repeating them as facts.
    5. Compare at the topic and claim levels. A domain-level visibility score can tell you that a competitor appears more often. It cannot tell you whether the advantage comes from broader coverage, clearer positioning, stronger evidence, a specific feature association, or one frequently cited page.
    6. Assign a gap type and an owner. Every meaningful finding should end with a proposed action, responsible function, supporting evidence, and a condition for rechecking it. Otherwise, the audit becomes a screenshot archive.

    Use a controlled vocabulary for the gaps. The following labels are specific enough to route work without pretending that you know the internals of an answer system:

    • Coverage gap: competitors answer a relevant question that your site does not address.
    • Search visibility gap: you have relevant material, but stronger pages consistently occupy the search results.
    • AI exposure gap: your brand or content does not appear across repeated tests for a relevant prompt set.
    • Framing gap: the brand appears, but the category, audience, use case, or differentiator is inaccurate or incomplete.
    • Evidence gap: an important claim is missing clear, accessible, and verifiable support.
    • Consistency gap: important pages use conflicting names, descriptions, features, or positioning.
    • Expectation gap: buyers are repeatedly told to look for a capability or condition that your content does not address.

    Do not diagnose a strategic problem from one generated answer. One output is one observation. Look for recurrence across the fixed prompt set, distinguish persistent patterns from isolated wording, and retain contradictory outputs. Disagreement is useful because it shows where category understanding is unstable or where your own message may be underspecified.

    Convert each finding into the right kind of work

    A team sorts research evidence from a central table into four connected content, technical, positioning, and product-marketing work areas.

    The same visibility symptom can have several causes. “We are absent” is not a sufficient brief. The work begins when you identify what is absent: a page, a direct answer, a coherent entity description, defensible evidence, or a product capability.

    Observed patternLikely issue to investigateUseful next actionPrimary owner
    A competitor ranks and appears in answers; you do neitherMissing coverage or weak relevance for an important decisionCreate or substantially expand the most appropriate page only after confirming business relevance and search demandSEO and content
    Your page ranks, but your brand or content rarely appears in tested answersThe useful answer may be buried, ambiguous, inconsistent, or weakly supportedMake the answer explicit, clarify criteria and limitations, strengthen verifiable evidence, and connect supporting pagesContent, SEO, and subject-matter owner
    Your brand appears with the wrong category or use casePositioning is inconsistent across prominent pagesAlign category language, audience, use cases, product names, and differentiators wherever those facts are presentedBrand and product marketing
    A competitor owns a feature associationIts claim is clearer, better supported, more consistently repeated, or genuinely differentiatedVerify the underlying product reality, then improve the claim and evidence or accept that the competitor has the stronger positionProduct marketing and product
    AI answers surface a theme with little confirmed search demandAn emerging concern, different vocabulary, or output noiseKeep it on a watchlist and validate it through keyword research, customer evidence, and business relevance before committing substantial resourcesStrategy and audience research
    Search demand exists, but answers across the category are vague or inconsistentThe category lacks a stable explanatory frameworkPublish a precise explainer with definitions, boundaries, decision criteria, and supportable claimsEditorial and subject-matter owner

    When the action is editorial, improve the information architecture of the answer rather than merely adding more words. Put the direct answer where a reader can find it. Define important terms. State who a recommendation is for and when it does not apply. Separate facts from marketing claims. Make comparison criteria explicit, and place evidence beside the statement it supports.

    Structured data can clarify facts already presented on the page, but it is not a substitute for those facts. Treat JSON-LD as a translation layer: it should accurately express visible entities and relationships. It cannot create missing proof, repair contradictory positioning, or turn an unsupported claim into an authoritative one.

    Some findings should never become SEO tickets. If buyers repeatedly expect a feature the product does not offer, changing a heading will not close the gap. Route the observation to product and product marketing, preserve the evidence, and decide whether the correct response is a roadmap change, a clearer qualification, or no response at all. Combined competitive research can legitimately influence messaging, content planning, strategic positioning, and product-marketing roadmaps.

    A finding should rise in priority when the decision has business value, the pattern recurs across the controlled set, the current representation is materially weak or inaccurate, and you have truthful evidence ready to improve it. A high-volume keyword with little commercial relevance should not automatically outrank a smaller decision point that affects qualified buyers. An eye-catching AI mention should not outrank a persistent pattern merely because it makes a better presentation slide.

    Measure SEO and AEO separately, then inspect the bridge

    Do not collapse the program into one blended visibility score. A single number hides the distinction you need for diagnosis. You can gain rankings without improving AI representation, or gain brand mentions without building durable search visibility.

    Keep an SEO scorecard for:

    • Coverage of priority queries and decision stages.
    • Visibility of the correct page for each query.
    • Changes in the competing pages and page types.
    • Demand captured by pages created or improved from the audit.

    Keep an AEO scorecard for:

    • Prompt coverage: the share of the fixed prompt set in which your brand is present.
    • Mention role: citation, example, comparison, shortlist, conditional recommendation, or warning.
    • Framing accuracy: whether the category, audience, use case, features, and limitations are represented correctly.
    • Competitor recurrence: which entities repeatedly appear for the same decision.
    • Citation presence: which pages are referenced when the interface exposes supporting links.
    • Claim stability: which important descriptions persist and which vary between observations.

    Then inspect the bridge between them. Flag priority topics where you rank but remain absent or misrepresented in AI answers. Find pages that appear in both search results and visible AI citations. Track whether a content change improves the intended claim, not merely whether the brand appears somewhere in the response.

    Version the prompt set and preserve previous results. Log meaningful content, positioning, schema, and product changes beside the observations. If an answer changes after a deployment, call it a directional association unless you have evidence of causation. Generated answers can change for reasons outside your work, so an honest report distinguishes movement from proof.

    Key takeaways

    • SEO research shows where existing search demand is captured; AEO research shows how choices are framed before a click.
    • Your commercial, search, answer, and narrative competitors are not necessarily the same entities.
    • A fixed query and prompt set is essential if you want comparisons that are more reliable than selected screenshots.
    • Record the role and accuracy of each mention, not just whether a brand appears.
    • Classify every gap before assigning work; absence alone does not tell you whether the remedy is content, evidence, positioning, schema, or product.
    • Measure both disciplines separately and use their overlap to choose the next action.

    Start with one decision zone that matters to your business. Freeze its queries and prompts, collect both layers, and turn the recurring gaps into briefs with named owners. At your next planning session, put the SEO observation, AEO observation, evidence, and next action side by side. If a proposed task has no observed gap and no supportable improvement, it is not ready for the roadmap.

    References

  • Google SearchGuard: An Operations Guide for SEO Teams

    Google SearchGuard: An Operations Guide for SEO Teams

    If your rank tracking, share-of-voice reporting, or AI visibility workflow depends on automated Google results, SearchGuard can turn a routine data feed into a business-continuity problem. Collection may become incomplete or unavailable while the dashboards built on top of it continue to look authoritative.

    Your immediate job is not to find a cleverer bypass. It is to identify which decisions depend on scraped search results, establish how each provider acquires them, and prevent missing observations from being misreported as ranking losses.

    Why SearchGuard breaks the old scraper playbook

    BotGuard, internally called Web Application Attestation or WAA, protects multiple Google services. SearchGuard is the Search-specific implementation. It is designed to distinguish a person using a browser from an automated script without relying on a traditional, visible CAPTCHA.

    That distinction changes the failure model. A CAPTCHA is an obvious interruption. An invisible attestation system can evaluate the session while the interaction is happening. Loading a results page once therefore does not demonstrate that an automated collection method will remain stable at scale.

    The early-2025 implementation was reported to have disrupted nearly all SERP scrapers. Whether that disruption reaches your team directly or through a vendor, the operational lesson is the same: automated Google access is an external dependency whose availability and data quality must be measured, not assumed.

    Start by separating three questions that teams often collapse into one:

    • Can the collector retrieve a page? This is a technical availability question.
    • Did it retrieve the complete observation you requested? This is a data-quality question.
    • Is the collection method authorized and legally defensible? This is a governance question.

    A provider can answer yes to the first question while leaving the other two unresolved. Your dashboard should not treat technical success as proof of completeness, permission, or long-term reliability.

    The signal stack goes beyond a single bot tell

    Automated request signals pass through several layers of digital inspection while suspicious signals are diverted and human-origin signals continue.

    The available technical detail comes from decrypted version 41 of BotGuard, the broader system behind the Search implementation. Treat it as a map of relevant signal classes, not a complete or permanent specification of every SearchGuard decision.

    Behavioral signals form a composite pattern

    Mouse, keyboard, scrolling, and timing behavior can all contribute evidence about whether an interaction looks human:

    • Mouse analysis can include path shape, speed, changes in acceleration, and small irregularities in movement.
    • Keyboard analysis can include intervals between keys, keypress duration, error sequences, and pauses after punctuation.
    • Scrolling and general timing can reveal whether actions contain natural, context-dependent variation rather than fixed automation intervals.

    The important point is not that one straight mouse path or one regular pause proves automation. SearchGuard can assemble multiple observations into a broader behavioral profile. A vendor that talks only about imitating one visible action is addressing a much narrower problem than the system presents.

    The browser environment is part of the evidence

    The evaluation is not confined to pointer and keyboard events. BotGuard can use more than 100 HTML elements and browser-environment signals, including navigator properties, screen metrics, performance information, and interaction with browser APIs.

    This is why a collector that produces a visually correct page can still be fragile. Rendering the right DOM is only one part of the session. The surrounding environment and the way it behaves can be evaluated as well.

    Statistical profiling makes fixed emulation brittle

    Welford’s algorithm and reservoir sampling are among the techniques associated with the system. They support continuously updated statistical summaries and sampling from streams of observations. Operationally, that points to a moving composite profile rather than a permanent list of checks that can be patched once and forgotten.

    The protected bytecode virtual machine and cryptographic integrity measures add another layer of resistance to reverse engineering. A temporary workaround can therefore expire when code, challenges, expected behavior, or the scoring model changes.

    Do not use this signal list as an evasion checklist. Use it to set the right expectations with engineering teams and vendors. A durable measurement program needs observability around collection, not just a promise that automation worked during a demo.

    Key takeaways

    • SearchGuard is the Search-specific form of Google’s broader BotGuard or Web Application Attestation system.
    • It can combine behavioral, timing, browser-environment, and statistical signals instead of depending on a visible CAPTCHA.
    • A rendered results page does not, by itself, establish complete data, durable access, or authorization.
    • Attempts to bypass the system can create both technical fragility and legal exposure.
    • Your safest response is to audit data provenance, label collection failures correctly, and give every important workflow a fallback.

    Audit vendors before enforcement becomes your outage

    Google’s lawsuit against SerpAPI alleges that the company bypassed SearchGuard to extract copyrighted Google Search data at large scale. Google framed the claim around the anti-circumvention provisions of DMCA Section 1201 rather than making a terms-of-service dispute the center of the case.

    An allegation is not a final ruling, and it does not establish that every form of search-result collection is unlawful. SerpAPI’s CEO says Google did not contact the company before filing and characterizes the action as an attempt to restrain a service used by other innovators. That disagreement matters because the technical method, the rights involved, and the legal theory may all be contested.

    It would still be a mistake to classify this as somebody else’s vendor dispute. If a provider intentionally circumvents a technological control, you may face service interruption, contract problems, replacement costs, and legal questions that an uptime report cannot answer. Have qualified counsel review your particular method and jurisdiction when circumvention is part of the collection chain.

    The dependency can also be several layers removed from the final product. OpenAI used Google results obtained through SerpAPI after Google denied a 2024 request for direct access to its index. For an SEO or AI visibility team, that is a reminder to examine your vendor’s suppliers as well as the name on your own contract.

    Run the audit in this order:

    1. Map the dependency. Record every report, alert, model, recommendation, and client deliverable that consumes automated Google results. Assign an owner to each one.
    2. Document the complete collection chain. Ask who retrieves the results, whether subcontractors or resellers participate, and whether the provider collects directly or buys from another supplier.
    3. Request the provider’s stated basis for access. Get the answer in writing. Browser automation describes a mechanism; it does not explain authorization, rights, or legal defensibility.
    4. Define the requested observation. Record the query, requested context, expected fields, refresh cadence, and timestamp. Without that contract, you cannot distinguish a complete result from a plausible-looking fragment.
    5. Require explicit failure semantics. The provider must distinguish a successful observation, an access failure, a partial response, and a reused cached response. A blank field is not an adequate status code.
    6. Add commercial protections. Review incident-notification duties, subcontractor disclosure, data-quality commitments, termination rights, and the process for exporting your configurations if the feed becomes unavailable.
    7. Choose the fallback before launch. Decide which workflows can use a manual sample or first-party performance data, which must pause, and which can proceed with a clearly displayed uncertainty warning.

    Answers that should stop a launch

    Do not let a data feed into consequential reporting if the provider:

    • will not identify the collector or disclose whether additional suppliers are involved;
    • uses the word compliant without identifying the scope, jurisdiction, contract, or other basis for that claim;
    • cannot distinguish blocked collection from a genuine absence in the search results;
    • does not attach collection time, freshness, and completeness metadata to observations;
    • treats repeated workaround deployment as its only continuity plan; or
    • cannot explain what happens to your history, configurations, and reporting when access fails.

    None of these signs proves misconduct. Each one does prevent you from evaluating the reliability and exposure of a dependency that may influence budgets, content priorities, client reports, or executive decisions.

    Build reporting that survives missing SERP data

    Two analysts review a reporting pipeline that routes around missing data sources and shows affected dashboard areas with caution indicators.

    The most damaging SearchGuard failure may not be an obvious outage. It may be a partial dataset that enters a trend line as though collection completed normally. Protect the decision layer by giving every observation an explicit state.

    Data stateWhat it meansHow reporting should behave
    ObservedThe requested collection completed and the expected fields passed validation.Include it with its collection time and requested context.
    UnavailableThe collector could not complete the request.Report an availability gap. Never translate it into a ranking loss or absence.
    IncompleteOnly part of the planned query set or expected response was obtained.Show coverage and suppress aggregates that require the missing observations.
    StaleThe workflow is reusing an older observation beyond the freshness allowed for that decision.Display the original timestamp and exclude it from comparisons presented as current.

    Your acceptable freshness and completeness thresholds should follow the decision cadence. A dataset may be adequate for a slow-moving planning exercise and inadequate for a report that triggers an immediate campaign change. Define that rule in the workflow instead of asking an analyst to make an improvised judgment after a failure.

    Design around the decision, not maximum collection

    1. Collect the smallest representative query set that supports the decision. More queries create more dependency without automatically improving the conclusion. Tie each segment of the set to a reporting or monitoring need.
    2. Gate every aggregate on coverage. Store planned, completed, valid, incomplete, and unavailable observation counts. Do not publish a visibility change when the underlying comparison fails your predefined coverage rule.
    3. Preserve provenance with the metric. Keep the provider, collection time, requested context, processing version, and data state attached through exports and dashboards. Retain raw material only where your rights, contract, and policies allow it.
    4. Separate acquisition from analysis. Give the analysis layer a documented input format so an approved replacement feed, manual observation, or first-party dataset can be introduced without rebuilding every dashboard.
    5. Use independent evidence for consequential changes. Before changing budget, content, or reporting because an external SERP metric moved, compare it with owned-site performance and manually inspect the high-impact queries where appropriate.
    6. Write a stop rule. Specify which recommendation, alert, or report must be withheld when collection is unavailable, incomplete, or stale. Missing evidence should remain unknown; it should not silently become zero.

    Start with the next search dashboard your team is scheduled to use. Trace every Google-derived field back to its collector, timestamp, completeness state, and fallback. If that chain cannot be explained, do not let the number silently drive the next decision.

    References

  • How to Humanize LLM-Assisted Content With Better Research

    How to Humanize LLM-Assisted Content With Better Research

    You have an LLM draft that is clean, complete, and strangely forgettable. Changing a few phrases, adding contractions, or asking the model to sound more human will not fix it. The draft feels generic because it has had no meaningful contact with the customers, experts, and market conditions it claims to understand.

    Humanizing LLM-assisted content is a research problem before it is a writing problem. Give the model grounded evidence to organize, keep human judgment in charge of what matters, and make every important claim traceable. You will get content that is more useful because it contains real distinctions, not because it performs a more casual personality.

    Human content starts with evidence, not tone

    A model can imitate a conversational register. It cannot create genuine customer evidence, expert experience, or market context that you did not provide. If the input consists of a keyword, a title, and competing search results, the output will usually recombine the same category-level ideas available to everyone else.

    The useful advantage of an LLM is its ability to process large collections of feedback and surface recurring patterns. That makes it a capable research assistant, but it does not transfer editorial responsibility to the model.

    Separate the work into three roles:

    • Evidence: Customers, subject matter experts, product records, search queries, reviews, and other observable material supply the facts and language.
    • Analysis: The LLM groups related observations, identifies contrasts, proposes questions, and helps you inspect a large body of material.
    • Judgment: A person decides which patterns are meaningful, which claims are sufficiently supported, what exceptions matter, and what the reader should do.

    This separation prevents a common failure: letting polished prose disguise a weak evidence base. A confident paragraph is not proof that the underlying pattern is real.

    Before drafting, build a compact evidence brief. For each potential section, record the reader question, the proposed answer, the supporting material, any contradiction, and the action the reader can take. If a proposed answer has no supporting material, label it as a gap. Do not ask the model to fill that gap with a plausible anecdote.

    Keep provenance attached to the material as it moves through the workflow. A customer comment should retain an anonymous record identifier. An expert claim should point back to the approved interview transcript. A competitor observation should retain the page, review, or posting that supports it. Provenance makes verification possible after the model has compressed many inputs into a neat theme.

    Build an auditable customer-language pipeline

    Two researchers trace color-coded evidence cards back to customer interview recordings, photographs, and product samples on an organized table.

    Customer feedback is where generic content often becomes specific. NPS responses, sales-call transcripts, support questions, Google Search Console queries, and on-site searches expose the words people use before your marketing language has shaped the conversation. Heatmaps and interaction data can help you locate friction, while qualitative comments can explain what the friction means to the person encountering it.

    Do not begin by dropping an unstructured archive into a chat and requesting insights. The resulting summary may look convincing, but it gives you little visibility into omitted records, faulty groupings, or unsupported counts. A more inspectable workflow involves using an LLM to generate SQL, running the queries separately, and supplying the query results for synthesis.

    1. Normalize the raw material. Store one response or interaction per record. Preserve the original wording and add only fields you can verify, such as channel, product area, or an anonymous record identifier.
    2. Define the question before querying. Ask something narrow enough to test, such as which objections appear in feedback about a specific feature, or which questions occur before a purchase decision.
    3. Use the LLM to draft the query. Supply the actual table and column names, describe the expected output, and instruct it not to invent fields. Treat the generated SQL as code that requires review.
    4. Run and validate the query outside the model. Inspect filters, joins, null handling, duplicated records, and representative rows. Compare the result with a small set you have already read.
    5. Give the verified result to the LLM. Ask it to group related responses, preserve contrary evidence, and attach anonymous record identifiers to every proposed theme.
    6. Iterate on the question. A broad theme such as ease of use is not yet an insight. Query the situations, tasks, and points of confusion hidden inside that label.

    A practical analysis prompt is: Group these verified records by the job the customer is trying to complete. For each theme, provide supporting record identifiers, conflicting records, the customer terms that recur, and one question we still cannot answer. Do not infer a motive unless the wording supports it.

    The instruction to preserve conflicting records matters. A model is naturally useful at compression, but compression can erase minority experiences and conditions that complicate the dominant theme. Those complications are often what make a page trustworthy. They let you say when advice works, when it does not, and who should choose a different path.

    Handle sensitive material before it reaches any LLM. Remove personal identifiers and confidential details, and use only tools and storage environments approved for the data involved. If you cannot confirm that a dataset may be processed in a particular system, work with a redacted extract or keep the analysis inside an approved environment.

    Your final customer-language output should not be a cloud of themes. Build a theme ledger containing the customer problem, the situation in which it occurs, the language customers use, supporting record identifiers, contradictions, and the content decision that follows. That final field forces analysis to become useful editorial direction.

    Interview experts without asking them to write the page

    A content strategist records an expert explaining and demonstrating a component at a workshop bench while a teammate documents the process.

    Subject matter experts are usually needed because the obvious answer is incomplete. They know the mechanism, the exception, the tradeoff, and the mistake that only becomes visible in practice. Asking them to write a polished explanation creates unnecessary work and often delays the content.

    Use an LLM as the interviewer, not as a substitute for the expert. A reusable interviewer can be configured around a clear role, context, interview structure, pacing, and closing summary. The expert can answer in fragments or plain language while the system handles follow-up questions and organization.

    Give the interviewer these instructions:

    • Role: Act as a curious editor who understands the product context but does not pretend to know the expert’s answer.
    • Objective: State what the final content must help the reader understand or decide.
    • Scope: Name the product, feature, service, or decision being discussed and list topics that are out of scope.
    • Pacing: Ask one question at a time. Follow an answer before moving to the next prepared topic.
    • Evidence discipline: Request concrete mechanisms, conditions, and examples, but never create an example on the expert’s behalf.
    • Closing: Summarize the claims, unresolved questions, and statements that require verification or approval.

    Do not open with an invitation to explain everything about the subject. Start with the decision the reader faces, then move down an interview ladder:

    1. What does the reader usually misunderstand at this point?
    2. What actually happens, and what causes it?
    3. Which conditions change the answer?
    4. What is the most common avoidable mistake?
    5. What tradeoff should the reader understand before choosing?
    6. What would you need to see before recommending a different approach?

    Each answer should shape the next question. If the expert says a result depends on implementation quality, the interviewer should ask what quality means in observable terms. If the expert describes a common mistake, it should ask why people make it and how a reader can notice it early. This is where an interview produces material that a generic drafting prompt cannot.

    After the interview, ask the LLM to create a claim sheet rather than a finished draft. Each row or bullet should include the claim, supporting transcript passage, relevant condition, uncertainty, and verification status. Send that condensed sheet to the expert for correction. Approval of a short claim sheet is a clearer request than approval of a long page in which factual and stylistic decisions have already been mixed together.

    Only then should the transcript feed the drafting process. Instruct the model to distinguish direct expert knowledge from editorial inference. If the expert did not provide a metric, example, or causal explanation, the draft must not manufacture one to make the section feel complete.

    Use competitor research to find the missing angle

    Competitor research is useful when it reveals the boundaries of the category conversation. It becomes destructive when it is used as a template for another version of the same page.

    Different public signals answer different questions. Reviews, changing web copy, job postings, and social engagement can expose customer frustrations, positioning choices, strategic priorities, and unmet demand. None of these signals should be treated as conclusive on its own.

    • Reviews: Extract repeated benefits, complaints, desired outcomes, and the circumstances behind unusually positive or negative experiences. Keep verified wording separate from your interpretation.
    • Current web copy: Record the audience being addressed, the promised outcome, the proof offered, and the tradeoffs left unmentioned.
    • Archived web copy: Use the Wayback Machine to notice how positioning and emphasis have changed. Treat the change as an observation, not proof of why the business made it.
    • Job postings: Note capabilities the company appears to be building. A posting may indicate an area of attention, but it does not prove that a strategy or product has shipped.
    • Social engagement: Read the comments and questions behind the engagement count. Activity alone does not tell you whether people are satisfied, confused, or objecting.

    Create a competitor evidence matrix with the same fields for every company: target audience, main claim, supporting proof, repeated customer concern, unanswered question, and evidence location. Consistent fields make cross-company patterns easier to inspect and reduce the chance that a vivid example dominates the analysis.

    Then ask the LLM: Compare these records without ranking the companies. Separate extracted evidence from inference. Identify claims repeated across the category, customer questions no company answers clearly, benefits with weak visible proof, and differences that may reflect distinct target audiences. Mark unknowns instead of resolving them.

    The output is not your content plan yet. Test each proposed gap against customer feedback and expert knowledge. A topic is not valuable merely because competitors have ignored it. It becomes a defensible angle when customers care about it, an expert can explain it, and your evidence supports an answer.

    Look for four kinds of useful angles: a customer question the category avoids, a tradeoff hidden behind a popular benefit, an exception that changes the standard recommendation, or a difference in audience that makes apparently conflicting advice both reasonable. These angles humanize content because they reflect actual decisions and tensions. They do not depend on decorative storytelling.

    Draft, verify, and edit for a recognizable point of view

    Once the evidence is organized, drafting becomes a constrained synthesis task. The model should transform approved material into a useful sequence without silently upgrading an observation into a fact or an inference into a customer quote.

    1. Define one reader and one decision. State what the reader is trying to do, what is blocking them, and what they should be able to decide after reading.
    2. Build an evidence outline. Give each section a question, direct answer, evidence identifiers, important exception, and practical next action.
    3. Draft only from the evidence pack. Permit ordinary transitions and explanation, but prohibit invented customers, quotations, tests, metrics, and firsthand experience.
    4. Expose missing support. Require a visible placeholder whenever the outline asks for a claim the supplied material cannot establish.
    5. Verify before polishing. Check every material claim against the raw record, transcript, query result, or competitor evidence location.
    6. Edit for judgment. Decide which point deserves emphasis, which caveat belongs beside the claim, and which recommendation follows from the evidence.

    An evidence-bound drafting prompt can be simple: Write for the defined reader using only the supplied evidence pack. Each section must answer its question directly, explain the mechanism or reason, preserve the stated conditions, and end with an action the reader can take. Keep evidence identifiers in the draft for review. If support is missing, insert [EVIDENCE GAP]. Do not invent a quote, metric, customer, test, or example.

    Run a humanization pass that can fail the draft

    Do not judge the result by asking whether it sounds human. Use tests with observable failure conditions:

    • The substitution test: Could a competitor publish the section unchanged? If so, add a supported distinction or remove the generic section.
    • The provenance test: Can an editor reach the underlying evidence for every consequential claim? If not, qualify, verify, or delete the claim.
    • The contradiction test: Does the draft preserve evidence that complicates the dominant pattern? If not, restore the relevant condition or exception.
    • The customer-language test: Does the page use the terms customers use for their problem while explaining any necessary technical vocabulary? If not, return to the feedback records.
    • The expert-value test: Does the page contain a mechanism, tradeoff, or boundary condition that required genuine expertise? If not, the interview stayed too shallow.
    • The action test: After each section, can the reader do, decide, or notice something specific? If not, the section is probably commentary rather than guidance.

    Remove evidence identifiers only after verification. Then tighten repetition, vary sentence length where it improves clarity, and replace internal terminology with reader language. Do not add fake quirks, staged vulnerability, or imaginary personal stories. A recognizable editorial voice comes from consistent judgment: what you prioritize, what you refuse to overclaim, and how clearly you explain the tradeoff.

    This also supports SEO, AEO, and GEO work without turning the page into machine-facing copy. Put the direct answer near the question, use descriptive headings, name entities precisely, keep qualifications beside the claims they limit, and cite the evidence that carries the factual load. Structured data can describe visible content, but it cannot supply the missing expertise or originality. No formatting choice guarantees search or LLM visibility.

    Key takeaways

    • Humanize the evidence before polishing the prose: use real customer language, expert judgment, and observable market signals.
    • Keep raw data and query execution outside the LLM when you need inspectable counts, filters, and records.
    • Use an LLM to interview experts and organize their answers, never to impersonate their knowledge.
    • Treat competitor material as evidence of category patterns and unanswered questions, not as a draft template.
    • Require provenance, contradictions, conditions, and evidence-gap labels throughout synthesis.
    • Reject any section that a competitor could publish unchanged or that leaves the reader without a concrete next action.

    Take the next generic draft you planned to polish and pause it. Build an evidence brief for its most important claim, verify that material, and rewrite only that section. The difference will show you where research deserves more of the workflow than prompting does.

    References

  • Industrial SEO Agency Landscape: How to Choose the Right Fit

    Industrial SEO Agency Landscape: How to Choose the Right Fit

    You are not choosing between agencies that all sell the same service. You are choosing which team can understand a technical product, translate it into real search demand, earn access to your subject-matter experts, and connect visibility to qualified opportunities. A polished pitch can conceal weaknesses in any one of those areas.

    The field is crowded: more than 50 industrial SEO firms were evaluated against six selection factors in 2025. You do not need to investigate every firm. You need a commercial brief, a shortlist organized by operating model, and evidence standards that expose whether an agency can work inside your business.

    Understand the agency models before comparing names

    Industrial SEO, manufacturing SEO, and B2B SEO are loose labels. Two agencies may use the same label while offering very different capabilities. One may excel at technical websites and product catalogs. Another may be a content operation with light technical support. A third may coordinate SEO with paid media, conversion work, and a website redesign.

    Organize the market by operating model first. This prevents you from rejecting a capable specialist for lacking services you do not need, or hiring a broad agency whose industrial expertise exists only in its sales presentation.

    Agency modelBest suited toEvidence to requestMain risk to test
    Industrial SEO specialistTechnical products, application-led demand, specification-heavy buying, and close collaboration with engineers or product teamsQuery maps, technical briefs, product architecture work, and examples of turning expert knowledge into useful pagesA fixed industrial playbook that ignores your route to market, margins, capacity, or buying committee
    B2B SEO and content agencyMarkets where education, problem awareness, comparison, and category discovery create demand before an RFQEvidence connecting informational content to product evaluation, conversion paths, and qualified pipelineBroad thought leadership that attracts readers but never helps a buyer select a product or supplier
    Technical SEO consultancyLarge catalogs, faceted navigation, JavaScript problems, migrations, international sites, duplicate pages, or persistent indexing issuesPrioritized technical backlogs, implementation specifications, validation methods, and developer collaborationA technically cleaner site with no plan for demand, content, authority, or lead quality
    Full-service digital agencyOrganizations that need SEO coordinated with paid search, analytics, conversion work, creative, and website developmentNamed SEO ownership, channel-specific deliverables, reporting boundaries, and examples of cross-channel decision-makingSEO being bundled into a larger retainer without enough specialist attention
    Consultant and internal-team hybridCompanies that already have writers, developers, analysts, and subject-matter experts but need direction and governanceDecision frameworks, templates, training materials, review processes, and a realistic division of responsibilitiesA strategy that depends on internal capacity your team does not actually have

    These models are not a ranking. The right one depends on the bottleneck. If search engines cannot reliably crawl and interpret your catalog, a content-heavy engagement will not solve the root problem. If your site is technically sound but says little beyond product specifications, another audit may only document work you already know is needed.

    Diagnose that bottleneck before building a shortlist. Ask whether the constraint is discoverability, page usefulness, technical access, industry authority, conversion, measurement, or internal execution. If several are involved, decide which one has to move first.

    Define the commercial job before requesting an SEO plan

    Write a brief around revenue, not rankings

    An agency cannot prioritize intelligently if the brief is simply to increase organic traffic. It needs to know which product families matter, where you can sell, what a qualified inquiry looks like, and which demand is commercially useless.

    Give every candidate the same decision inputs:

    • Commercial scope: priority product families, services, applications, territories, and customer types.
    • Economic context: which offerings are strategic, constrained by capacity, dependent on distributors, or poor fits despite apparent search demand.
    • Conversion events: RFQs, specification requests, distributor searches, sample requests, calls, CAD or technical-document downloads, and other actions that matter to your sales process.
    • Qualification rules: the characteristics that distinguish a viable opportunity from a student, job seeker, consumer, existing customer, or out-of-market inquiry.
    • Operational constraints: developer availability, legal or regulatory review, subject-matter expert access, publishing permissions, and analytics limitations.
    • Business measurement: the CRM stages, opportunity fields, and revenue signals that should eventually connect search activity to commercial outcomes.

    A useful one-sentence brief follows this pattern: Increase qualified discovery and inquiries for [priority offerings] among [buyer groups] in [markets], while excluding [poor-fit demand], with progress judged by [commercial signals].

    This sentence forces an important distinction. Search volume describes attention; it does not establish value. An industrial term can look attractive while referring to the wrong material, tolerance, application, geography, order size, or buyer. The agency should investigate those differences before proposing a publishing calendar.

    Map searches to the decisions a buyer must make

    Industrial demand rarely fits into a simple split between informational keywords and product keywords. A buyer may begin with a failure mode, move through an application or process, compare materials or capabilities, verify specifications, and then evaluate suppliers. Different pages should support different parts of that path.

    • Problem and application searches need pages that explain conditions, constraints, and suitable approaches without forcing a premature product pitch.
    • Category and capability searches need clear product-family or service pages that define fit, differentiation, limitations, and next steps.
    • Specification, material, model, and part searches need accurate technical pages with unambiguous attributes, relationships, and supporting documents.
    • Supplier and location searches need credible evidence about service areas, facilities, lead handling, certifications, distribution, and relevant capabilities.
    • Comparison and alternative searches need honest selection criteria, trade-offs, compatibility details, and reasons to rule an option in or out.

    Ask each agency to map a representative offering through that path during discovery. You are not testing whether its team already knows every technical detail. You are testing whether it asks the questions needed to learn, distinguishes buyer intent from keyword similarity, and can turn the result into page-level decisions.

    Use a six-part scorecard to test real capability

    Six different precision inspection tools surround a complex machined component on a clean industrial workbench.

    A useful scorecard separates capabilities that agencies often blend together in a proposal. Score the evidence, not the confidence of the presentation. If a capability matters to your brief, require an artifact, a worked example, or a clear operating process.

    1. Commercial prioritization. Ask how the agency would choose among product families, applications, buyer roles, and markets. A strong answer requests margin, capacity, sales, qualification, and territory inputs before committing to targets. A weak answer treats search volume or keyword difficulty as the entire business case.
    2. Industrial fluency. Ask the team to trace a product from the problem it solves through its specifications, alternatives, decision-makers, and conversion path. Strong teams separate terms that look similar but imply different applications or buyer needs. They also identify where an engineer, operator, procurement lead, distributor, or executive may need different evidence. Be wary of an agency that repeats your terminology without testing what it means.
    3. Technical search execution. Ask how the agency will evaluate crawling, indexation, internal linking, canonicalization, faceted navigation, duplicate content, PDFs, JavaScript rendering, structured data, site speed, international targeting, and migration risk where relevant. The expected output should be a prioritized implementation backlog with owners, dependencies, and validation steps. A long issue inventory without impact or sequence is not a strategy.
    4. Expert-led content operations. Ask who interviews subject-matter experts, drafts briefs, verifies technical claims, obtains images or diagrams, manages approvals, and updates aging pages. Inspect a sample brief and an edited deliverable. The process should preserve technical nuance while making the page understandable to the intended buyer. If the plan assumes your engineers will write finished copy on demand, execution will probably stall.
    5. Relevant authority building. Ask how the agency identifies credible places where your expertise, data, tools, or resources deserve mention. Good answers are grounded in trade relationships, useful assets, professional communities, distributors, associations, partners, and publications relevant to the market. Opaque backlink packages and generic authority scores do not show that a link will be contextually appropriate or commercially useful.
    6. Measurement and search-change readiness. Ask how reporting will connect Google Search Console, site analytics, forms, calls, CRM stages, and revenue data without pretending attribution is perfect. Then test the agency’s approach to AEO and generative engine optimization. It should make important facts clear, visible, crawlable, internally connected, and supported by accurate JSON-LD where appropriate. Structured data must describe claims that users can verify on the page; it cannot compensate for missing evidence. Require the agency to distinguish established SEO work from experiments in AI visibility, citations, and brand mentions.

    The final capability deserves particular scrutiny. Adding AI language to a conventional proposal is easy. A serious plan identifies what will change on the site, how entities and relationships will become clearer, which technical or editorial assumptions are being tested, and how the team will monitor outcomes without promising control over an external model’s answer.

    Weight the scorecard according to your actual constraint. A catalog with severe indexation problems should place more weight on technical implementation. A technically healthy site with thin product explanations should emphasize industrial fluency and content operations. Do not average away a critical failure: an agency that cannot support your primary bottleneck is not the right choice simply because it scores well elsewhere.

    Normalize proposals, interrogate proof, and protect the handoff

    An engineer, a commercial leader, and two agency specialists review an industrial component during a factory-side handoff meeting.

    Make every proposal answer the same questions

    Agency proposals are hard to compare because similar labels can conceal different amounts of work. One content deliverable might mean a title and keyword list; another might include expert interviews, technical diagrams, writing, review, publishing, internal links, schema, and measurement.

    Create a comparison sheet with these fields:

    • The business outcome and search problem being addressed.
    • The exact deliverable, including what is and is not included.
    • The agency role, client role, and approval owner.
    • The systems and access required.
    • The implementation owner for technical recommendations.
    • The reporting method and commercial signals being monitored.
    • The assumptions that could change scope, sequence, or cost.
    • Ownership of content, data, creative assets, accounts, dashboards, and documentation at the end of the engagement.

    That last field is not administrative trivia. If the agency controls accounts, tracking infrastructure, domains, content, or essential documentation, switching providers can create operational and data risk. Keep core business assets in accounts your company owns, with access granted to the agency.

    Ask for proof that reveals the mechanism

    A chart moving upward is not enough. It may combine branded and non-branded demand, hide changes in paid activity, reflect a website launch, or show traffic that never became qualified pipeline. Confidentiality may limit what an agency can reveal, but it should still be able to explain its reasoning and show sanitized work.

    Use these questions to inspect a case example:

    • What was the original commercial and search problem?
    • Which pages, templates, technical systems, or content processes changed?
    • What did the agency deliver, and what did the client implement?
    • Which results were branded, non-branded, local, product-led, or informational?
    • How did the team assess inquiry quality rather than form volume alone?
    • What evidence connects the work to the result, and what other explanations remain possible?
    • What would the agency do differently if the same constraints appeared in our organization?

    Direct artifacts usually tell you more than awards or directory positions. Request a sample technical ticket, query map, content brief, reporting view, editorial workflow, or decision memo. You are looking for whether the agency can convert analysis into work that your developers, marketers, engineers, and sales team can use.

    Treat these promises as decision-level warnings

    • Guaranteed rankings or visibility. An agency can control its work, not search-engine or AI-system placement. Replace the guarantee with commitments about deliverables, quality controls, implementation support, and transparent measurement.
    • A strategy built entirely from high-volume keywords. Volume does not account for product fit, margin, capacity, geography, or lead quality. Require a commercial prioritization layer.
    • Large-scale AI publishing without expert review. Industrial errors can affect credibility, sales conversations, and potentially product use. Require named review ownership, claim verification, and a correction process before scaling output.
    • An unexplained link package. If the agency cannot describe relevance, editorial standards, acquisition methods, and ownership, you cannot evaluate reputational risk.
    • Reporting limited to sessions, impressions, and rankings. These are diagnostic signals, not the complete business outcome. Require a plan for connecting search activity to qualified actions and CRM data where feasible.
    • A redesign or migration proposed before diagnosis. Moving URLs, templates, navigation, and content can create avoidable visibility loss. Preserve a crawlable inventory, redirects, measurement, and validation steps before approving an irreversible launch.
    • A plan that assumes unlimited access to your experts. Ask how the agency will batch questions, prepare interviews, manage reviews, and proceed when an expert is unavailable.

    Begin with a diagnostic commitment when uncertainty is high

    If neither side understands the full scope, start with a defined diagnostic phase rather than pretending the annual roadmap is already known. That phase can produce an access inventory, measurement baseline, demand map, technical priorities, representative content brief, implementation backlog, and division of responsibilities.

    Define the outputs before signing. A diagnostic should reduce uncertainty and support a go, revise, or stop decision. It should not become an open-ended audit that repeats known issues without establishing what happens next.

    Before the larger engagement begins, name an internal owner, a technical implementation contact, a sales or CRM contact, and the subject-matter experts who can validate priority topics. Agree on how decisions are logged and what happens when approvals stall. In industrial SEO, the agency’s plan is only one part of the operating system; your access and review process determine whether that plan can leave the slide deck.

    Key takeaways

    • Choose an agency model that matches the bottleneck: technical access, content depth, industry authority, measurement, or internal execution.
    • Give every candidate the same commercial brief, including priority offerings, markets, qualification rules, conversion events, and operational constraints.
    • Test commercial prioritization, industrial fluency, technical execution, expert-led content, authority building, and measurement as separate capabilities.
    • Require artifacts and causal explanations. Traffic charts, awards, testimonials, and confident presentations are supporting evidence, not proof of fit.
    • Evaluate AEO and GEO through concrete site changes, accurate visible facts, retrieval-friendly content, appropriate JSON-LD, and clearly labeled experiments.
    • Keep core accounts, data, content, and documentation under your ownership so a future handoff does not endanger continuity.

    Your next move is to choose one commercially important product family and write the brief around it. Give that same brief to a small shortlist, ask each agency to map the buyer’s search path, and score the evidence with the same criteria. The differences between a sector label and a workable industrial SEO partnership will become visible quickly.

    References