Tag: Citations

  • How to Turn AI Search Citations Into Measurable Revenue

    How to Turn AI Search Citations Into Measurable Revenue

    If your brand appears in an AI answer but you cannot explain what happens next, visibility is not yet a growth channel. A mention can disappear inside a synthesized response, and even a citation can satisfy the user without producing a visit.

    The fix is to design one connected system: answer decision-blocking questions with evidence, make each cited page worth visiting, attach a relevant commercial next step, and measure revenue through the whole journey. The goal is not the largest possible mention count. It is qualified, measurable demand earned without weakening trust.

    Key takeaways: build the whole citation-to-revenue chain

    • Start with questions that stall a decision, including concerns buyers do not know how to phrase or think to ask.
    • Publish citation-ready evidence units containing a direct answer, its scope, the supporting method, clear ownership, and an update date.
    • Let the AI answer carry a useful fact. Give people a reason to click by offering proof, application, personalization, or a logical next step on the cited page.
    • Keep recommendations independent from payment. Monetization should follow a useful answer, not determine which answer appears.
    • Measure mentions, citations, identifiable visits, conversions, realized revenue, and margin as separate stages. Each failed stage requires a different fix.

    Build evidence around the questions that actually stall decisions

    Traditional SEO asks whether a page can rank for a query. AI search adds another test: can the useful part of that page be extracted, compressed, and reused without changing its meaning? Brands are increasingly competing for visibility through content reuse as well as rankings.

    That changes where your content plan should begin. A broad keyword list or standard FAQ can cover the questions everyone asks while missing the concern that stops the buyer. These concerns have been described as Friction-Inducing Latent Unasked Questions, or FLUQs: important questions that remain unspoken because the buyer does not yet know the terminology, assumes the answer, or feels uncertain about raising the issue.

    For a software buyer, the hidden question might be what breaks during migration, who must approve the integration, or which existing workflow will no longer work. For a service buyer, it might be when the service is a poor fit, which work remains their responsibility, or how a failed engagement can be unwound. These are not supporting details. They are often the conditions under which an otherwise attractive recommendation becomes unusable.

    Use this workflow to find them:

    1. Collect friction in the buyer’s own language. Review support tickets, sales objections, on-site searches, chat transcripts, community discussions, implementation notes, and reasons opportunities were lost. Remove names and other personal information before moving customer material into an analysis workflow.
    2. Group the friction by consequence. Useful groups include eligibility, compatibility, effort, approval, switching cost, failure risk, reversibility, and ongoing ownership. The consequence is usually more revealing than the exact wording.
    3. Turn each concern into a complete question. Replace a label such as “migration” with “What data or functionality will not transfer during migration?” A complete question forces you to address the decision rather than merely mention the topic.
    4. Separate facts from assumptions. Mark what is established by product documentation, policy, observed data, or a defined method. Put unsupported beliefs into a validation queue instead of publishing them as settled answers.
    5. Choose one canonical evidence page. Give each important claim a stable home. Related pages can summarize and link to it, but they should not introduce conflicting versions of the same answer.

    On the canonical page, package each important answer as an evidence unit. Include the exact question, a direct answer, the conditions under which it holds, the method or evidence behind it, the responsible author or organization, the relevant date, and the next question a reader is likely to face. This gives an answer engine enough context to reuse the fact without detaching it from its limits.

    When you do not have the fact, do not hide the gap with confident prose. Measure it. A survey, product analysis, operational review, or other documented method can turn an assumption into original, reusable evidence. Publish how the information was collected, what population or records it covers, when collection occurred, and what the result cannot establish. Those boundaries make the claim easier to evaluate and safer to quote.

    Keep the core evidence in crawlable HTML, even if you also offer a PDF or visual report. Use JSON-LD to clarify what the page already says, choosing types that match the real subject, such as Organization, Person, Product, Service, or Article. Keep names, URLs, authorship, dates, and relationships consistent across the markup and visible copy. Structured data can clarify entities and fields; it cannot validate a weak claim or guarantee a citation.

    Make a citation useful before you ask for the click
    A buyer examines research documents, comparison objects, and decision tools reached through a glowing citation from an AI answer panel.

    Microsoft announced a Copilot search design with prominent inline citations, consolidated source lists, and navigational links. That type of interface can shorten the path from an answer to a publisher, but it does not guarantee traffic. The user may already have enough information to continue without visiting you.

    Your content therefore has two jobs. The answer layer must be complete enough to earn trust and survive synthesis. The action layer must offer something that cannot be delivered adequately inside a short generated answer.

    Write an answer layer that survives compression

    Lead with the answer, not a teaser. If the correct answer is conditional, state the controlling variables immediately. If a product is incompatible with a system, say so before discussing workarounds. If the evidence applies only to a defined customer type, version, market, or time period, carry that scope into the same passage as the claim.

    Avoid separating a confident headline from its qualifications several paragraphs later. An answer engine may reuse the headline and omit the distant caveat. Place the claim, boundary, and essential support close enough that they still make sense when extracted together.

    Build an action layer around the next unresolved need

    The cited URL should continue the same job as the quoted answer. A generic homepage forces the visitor to restart the search. A strong destination restates the relevant claim near the top, shows how it was established, and then helps the reader apply it.

    • For an eligibility question, offer a detailed compatibility checklist, requirements assessment, or decision tree.
    • For a comparison question, expose the evaluation criteria, tradeoffs, and method behind the conclusion.
    • For a risk question, show limitations, failure conditions, mitigation steps, and what the buyer should verify.
    • For a planning question, provide the inputs needed for an estimate, configuration, implementation plan, or internal approval.
    • For a purchase-ready question, make current availability, pricing inputs, consultation details, or the transaction path easy to find.

    The call to action should answer the reader’s next question rather than interrupt the current one. “Request a compatibility review” continues an integration answer. “Book a demo” may not. The second instruction asks the visitor to enter your sales process before showing why that process solves the unresolved problem.

    Do not put the evidence that earned the citation behind a lead form. Readers and answer systems need to inspect the method, scope, and limitations. If you use a gate, reserve it for individualized analysis, a reusable tool, implementation help, or another resource that adds value beyond the public claim.

    Monetize the next action without buying the recommendation

    AI search monetization is not limited to selling an advertisement. Revenue can come from an owned purchase or subscription, a qualified lead, an affiliate referral, or a commission on a completed transaction. Define which event creates economic value before you optimize the page, because a click, a form submission, a booking, and a retained customer are not interchangeable outcomes.

    OpenAI has publicly considered a travel flow in which the best recommendation appears first and a commission follows an optional booking. The idea was presented as a possible model, not a settled advertising product, and its central guardrail was that compensation should not move an inferior option above a better one. The exact format remained unresolved.

    You should impose the same separation on your own program:

    • Decide whether a claim or recommendation qualifies on evidentiary merit before considering its commercial value.
    • Disclose affiliate, referral, sponsorship, or commission relationships next to the commercial action they affect.
    • Publish comparison criteria and apply them consistently to paying and non-paying options.
    • Do not rewrite limitations merely to keep a partner or owned product eligible.
    • Route the reader to an offer only when the stated conditions indicate that the offer fits.
    • Keep sponsored placement visually and conceptually separate from evidence-based editorial recommendations.

    This is more than an editorial preference. AI recommendations depend on user trust, and a monetization system that secretly changes the answer spends that trust for short-term distribution. A relevant transaction after an independent answer preserves the order: help first, commercial option second.

    Use realized economics when evaluating the result. For lead generation, connect the original visit to CRM outcomes instead of assigning full pipeline value to every form submission. For ecommerce, examine retained revenue and contribution margin rather than gross order value alone. For affiliate activity, use confirmed commissions rather than outbound clicks. Counting incomplete or unprofitable events as revenue can make a weak channel look healthy.

    Measure the failure point, not just the final traffic total
    An analyst inspects a leaking junction in a transparent, sensor-lined pathway that connects an AI response to a revenue chamber.

    A weighted model combining 14 inputs estimated 801 million standalone ChatGPT users and 5.1 billion visits for October 2025. Those modeled figures establish potential scale, but they cannot forecast your return. Your audience may not ask questions connected to your expertise, your evidence may not be selected, or the answer may not create a reason to visit.

    Measure AI search as a chain of observable stages. If you collapse everything into “AI traffic,” you lose the information needed to improve it.

    Build a query ledger before building a dashboard

    1. Define the monitored questions. Include explicit search questions and latent decision questions. Label each by topic, intent, buyer stage, and whether it contains your brand name.
    2. Record the run conditions. Store the exact prompt, platform, model or search mode when exposed, date, locale when relevant, generated response, mentioned brands, cited domains, and cited URLs.
    3. Classify the result. Distinguish an uncited mention, a linked citation, a citation to your domain, and a citation to the intended canonical page.
    4. Connect site activity. Identify AI referrals where referrer data is available, preserve landing-page and conversion data, and carry qualified leads into the CRM.
    5. Annotate changes. Record when you revise evidence, structured data, internal links, page ownership, or the commercial next step. Otherwise, a later visibility change will have no usable explanation.

    Generated answers can vary between runs, so treat each result as an observation rather than a permanent ranking. Keep your monitoring conditions and schedule consistent enough to distinguish a recurring pattern from an isolated response. Report branded and non-branded questions separately: being cited when someone already asks for your company is different from being discovered during category research.

    Use the chain to diagnose what to fix

    Observed resultLikely failure pointWhat to change next
    No mention and no citationThe answer may lack relevance, entity clarity, coverage, or usable evidence.Answer the specific decision question on a crawlable canonical page and clarify who owns the claim.
    Mention without a citationThe brand may be recognized while the supporting claim is credited elsewhere or left unsupported.Strengthen first-party evidence, methodology, scope, internal linking, and the connection between the entity and the claim.
    Citation without an identifiable visitThe generated answer may have resolved the need, or the cited destination may offer no meaningful continuation.Improve the action layer with proof, application, personalization, or a relevant tool. Do not weaken the public answer to manufacture clicks.
    Visit without a conversionThe landing page, offer, trust signals, or call to action may not match the question that produced the visit.Continue the cited answer on the landing page and align the next step with the visitor’s remaining decision.
    Conversion without acceptable revenueLead quality, retention, returns, commissions, sales cost, or margin may undermine the apparent result.Fix qualification and offer economics rather than changing an accurate recommendation.

    Your core metrics should retain their denominators. Citation rate is tracked runs containing a citation to your domain divided by valid monitored runs. Citation coverage is the share of monitored question clusters in which your domain earns at least one citation. AI referral conversion rate is conversions from identifiable AI referral sessions divided by those sessions. Revenue per identifiable AI-referred session is realized attributed revenue divided by the same session count.

    Add assisted revenue only when you state the attribution model used. Referral data will not capture every influence: a user can copy a URL, change devices, return directly, or encounter your brand in an answer without clicking. A self-reported acquisition field, CRM source history, and landing-page analysis can reveal some of that hidden influence, but none creates perfect attribution. Keep observed referral revenue separate from modeled or self-reported influence.

    Start with one complete loop. Choose a revenue-linked question that your support or sales evidence shows remains unresolved. Publish or improve its canonical answer, add applicable structured data, connect one logical next action, record baseline answer runs, and instrument the resulting visits and conversions. Once the page can be retrieved and indexed, repeat the same observations and follow the first broken stage in the chain.

    Your next move is to assign an owner to that question, its evidence, its cited page, and its revenue measurement. When all four have an owner, AI visibility becomes a process you can improve instead of a mention you can only screenshot.

    References

  • ChatGPT GEO: How to Earn Visibility in AI Answers

    ChatGPT GEO: How to Earn Visibility in AI Answers

    You can rank well in Google and still disappear when a buyer asks ChatGPT which provider, product, or approach fits their situation. The gap is usually not a missing AI trick. It is a content architecture problem: your site does not make the right entity, claim, evidence, and conditions easy to assemble into a reliable answer.

    If you need ChatGPT visibility, work backward from the answer you want your brand to be eligible for. You will need clear positioning, evidence-bearing pages, consistent information beyond your website, and a measurement process based on real prompts rather than vanity checks.

    Treat ChatGPT visibility as eligibility, not a fixed ranking

    Traditional SEO asks whether a page can be discovered, understood, and surfaced for a query. ChatGPT optimization adds a different question: can information about your business be used to construct a useful answer for the situation described in the prompt?

    That distinction changes the target. You are not trying to occupy a permanent position for a short keyword. You are trying to make your brand eligible for relevant ChatGPT recommendations when the user’s needs, constraints, and stage of decision-making match what you actually offer.

    ChatGPT optimization sits inside generative-engine optimization, or GEO. GEO covers visibility across a broader set of generative AI search channels, so the durable assets are not tricks tied to a single interface. They are clear entities, answerable content, supportable claims, machine-readable relationships, and credible corroboration.

    • SEO establishes discoverability. Pages still need coherent site architecture, internal links, accessible content, and a clear purpose.
    • AEO improves answer extraction. Direct definitions, concise explanations, and well-structured question-and-answer material make a page easier to use when a system needs a specific answer.
    • GEO improves selection and representation. It connects your entity to the topics, audiences, use cases, qualifications, and evidence that determine whether mentioning you would help the user.

    You do not need to choose between these disciplines. A page that is difficult to discover is a weak GEO asset, while a discoverable page full of vague claims gives a generative system little reliable material to use.

    Define each target as a decision, not a keyword. A useful internal statement looks like this: For an audience with a particular job and set of constraints, this brand or offering is a credible option because of this verifiable reason. If your team cannot complete that sentence without using empty words such as leading, innovative, or best, the positioning is not ready for optimization.

    Build a claim-and-evidence map before editing content

    An isometric planning surface connects a product to several claims and supporting proof objects, while one unsupported claim remains isolated.

    The fastest way to waste GEO work is to start by rewriting headings or adding schema. Begin with the decisions your audience is trying to make and the claims required to support those decisions.

    1. Collect the decision questions. Pull them from sales calls, support conversations, on-site search, keyword research, community discussions, and competitor comparisons. Separate discovery questions from evaluation, validation, and implementation questions.
    2. Identify the intended answer. State what a useful, accurate response should help the user understand. Do not insert your brand into a question when it would not genuinely belong in the answer.
    3. List the required claims. Include identity, category, audience, capabilities, differentiators, prerequisites, limitations, availability, and fit. Use only the fields that affect the decision.
    4. Attach evidence to each meaningful claim. Evidence may live in product documentation, policies, methodology pages, qualified author profiles, case material, public records, or clearly explained first-party data. A claim without support should be narrowed, qualified, or removed.
    5. Assign a canonical page. Decide where each claim is maintained. Other pages may summarize it, but they should link back to the page responsible for the complete and current explanation.
    6. Record conditions and exclusions. If an offering fits only certain markets, users, integrations, budgets, or operating models, say so. Suitability becomes more credible when the boundaries are visible.
    7. Name the owner and review trigger. Pricing changes, product changes, policy changes, rebranding, acquisitions, and new market coverage can all make previously accurate content misleading. Give someone responsibility for updating the affected claims.

    Your working map can use the fields decision question, intended answer, entity, claim, evidence, canonical page, conditions, and owner. That is enough to expose most gaps. A spreadsheet is useful; a complicated platform is not required.

    Match the strength of the claim to the strength of the proof

    Claims become harder to support as they move from identity to superiority. Saying what a product is requires clear first-party information. Saying what it supports requires documentation. Saying who it is suitable for requires explicit criteria. Saying it produces an outcome requires evidence that actually measures that outcome. Saying it is the best option requires a defensible comparison across a defined market and set of criteria.

    Many brands skip directly to the strongest language because it sounds persuasive. For GEO, that creates a verification problem. Replace an unsupported superlative with a bounded, decision-relevant fact. Built for distributed finance teams that need approval controls is more usable than the world’s most advanced finance platform when the former is true and documented.

    Do not begin with structured data. Schema can describe a relationship that exists in the visible content, but it cannot supply missing proof or rescue confused positioning. Create the claim map first, improve the canonical pages next, and encode the resulting meaning afterward.

    Write pages ChatGPT can use without filling in gaps

    A useful GEO page reduces the amount of interpretation required to answer a question accurately. It names the subject, gives the answer early, explains why the answer holds, and makes its limits visible.

    Lead with a bounded answer

    Put the direct response near the beginning of the relevant section. The answer should identify the audience, situation, conclusion, and important condition. Follow it with evidence and explanation.

    A weak opening says that your solution transforms an industry. A useful opening says what the solution is, whom it serves, what job it performs, and when it is not the right fit. The second version gives ChatGPT material it can use in a recommendation without inventing the missing context.

    Use this editorial pattern for important sections:

    • Answer: State the conclusion in plain language.
    • Scope: Name the audience, market, use case, or prerequisite to which it applies.
    • Reason: Explain the mechanism, capability, or distinction behind the conclusion.
    • Evidence: Link to the documentation, policy, methodology, or substantiated example that supports it.
    • Boundary: State an exception, limitation, or alternative when it would change the recommendation.
    • Next action: Tell the reader what to inspect, compare, configure, or ask before deciding.

    Make the entity unmistakable

    Use a stable canonical name for the organization, each product, and each service. Make the relationship among them explicit. If a product was renamed, if a business operates under another legal name, or if similarly named entities exist, publish the clarification on a canonical identity page rather than expecting a chatbot to reconcile scattered clues.

    A compact identity statement can follow this structure: [Brand] is a [category] for [audience]. It provides [documented capabilities] in [applicable markets]. [Product] is its offering for [specific use case]. Treat this as a factual anchor, not a slogan.

    Check the same facts wherever they appear: the About page, product pages, author profiles, contact information, support documentation, marketplace listings, social profiles, and relevant third-party directories. Natural wording can vary. Core facts should not.

    Keep proof close to the claim

    A citation is useful only when it supports the exact statement beside it. Linking a broad homepage after a precise performance claim does not make that claim verifiable. Send the reader to the documentation, methodology, policy, or data that carries the relevant detail.

    Show dates where freshness affects the decision. Identify authors where expertise matters. Explain how a comparison was constructed. Distinguish measured outcomes from targets, projections, and testimonials. If evidence has important limits, keep those limits beside the result rather than hiding them in a general disclaimer.

    Publish comparisons that support a real decision

    Comparison content is most useful when it defines the choice before declaring a winner. Name the intended user, the job to be done, prerequisites, meaningful criteria, tradeoffs, and situations in which each option is appropriate. A table works when those fields genuinely apply across every option. Prose is better when the differences require context.

    Do not manufacture weaknesses for competitors or create pages that differ only by replacing a company name. Thin comparison pages add little information and make your recommendation look predetermined. A credible comparison can acknowledge that another option fits a different situation better.

    Use JSON-LD to confirm the visible meaning

    Choose schema types that match the actual page and entity. An identity page may describe an Organization. An editorial page may use Article with a clearly identified Person as author. An offering may warrant Product or Service, depending on what it is. BreadcrumbList can describe site hierarchy, while FAQPage should be reserved for a page that visibly contains the corresponding questions and answers.

    Use stable page URLs as entity identifiers where appropriate, connect related entities consistently, and ensure the structured values match what a visitor can read. Do not add awards, ratings, prices, locations, authors, or capabilities that are absent or contradicted on the page. Validate the syntax, then review the rendered page and JSON-LD side by side.

    Structured data is clarification, not a guarantee of inclusion, citation, or recommendation. Its job is to remove ambiguity from truthful content, not to make promotional language authoritative.

    Strengthen the facts beyond your own website

    Your website can establish what you claim. It cannot make every claim independent. A recommendation becomes easier to justify when the same entity is identified consistently and relevant facts can be corroborated in places your audience already trusts.

    This is where digital PR, expert contributions, partnerships, community participation, directory hygiene, and conventional authority building meet GEO. The goal is not to create a large pile of identical brand mentions. It is to build a coherent public record.

    • Correct identity conflicts. Update stale names, descriptions, locations, URLs, and product relationships on profiles you control.
    • Earn context-rich mentions. A brand name inside a relevant explanation is more informative than a detached logo or sponsor list.
    • Make expertise attributable. Connect substantive contributions to a real author or spokesperson whose role and qualifications are clear.
    • Create sourceable assets. Publish definitions, methodologies, technical documentation, original data, decision frameworks, or transparent policies that other people can reference because they solve an information problem.
    • Prefer independent wording. Repetition of the same press-release copy is not the same as independent corroboration.
    • Resolve material contradictions. When third-party information is wrong, correct the canonical page first, then request corrections where you have a legitimate route to do so.

    Evaluate an external mention by asking whether it identifies the correct entity, supports a decision-relevant claim, appears in an appropriate context, and remains publicly accessible. Raw mention volume does not answer those questions.

    The strongest sourceable material is useful even if no generative engine ever quotes it. Documentation helps customers implement a product. A transparent methodology helps buyers evaluate a claim. An original framework helps practitioners make a decision. GEO benefits from that utility; it does not replace it.

    Measure responses with a repeatable prompt system

    An analyst reviews repeated sets of blank prompt cards and color-coded answer tiles arranged in a systematic testing workspace.

    Typing your brand into ChatGPT and seeing it mentioned proves very little. Branded prompts already tell the system which entity to discuss, and an isolated output cannot show whether visibility is stable across wording, context, or user intent.

    Build a prompt set from real audience language. Cover the decisions that matter:

    • Discovery prompts: ask how to solve the problem without naming a category or vendor.
    • Category prompts: ask for suitable approaches or providers within the relevant category.
    • Fit prompts: include audience characteristics, prerequisites, market, workflow, and meaningful constraints.
    • Comparison prompts: ask how options differ and what criteria should govern the choice.
    • Validation prompts: ask about a named brand’s capabilities, limitations, evidence, or suitability.
    • Follow-up prompts: continue from an initial answer to see whether the brand remains relevant when the user adds a constraint.

    Keep the prompts stable enough to compare runs, but do not freeze the program around artificial wording. Add genuine questions when sales, support, or search behavior reveals a new decision pattern. Separate testing prompts from prompts designed only to force a mention.

    Record the context with every result

    Capture the date, exact prompt, ChatGPT product or mode shown, whether a search or browsing feature was active, language, relevant location, and conversation state. Use a fresh conversation when you want a clean discovery test. If personalization may affect the result, record that too.

    Save the complete response, not just a screenshot of the favorable sentence. Score what actually happened:

    • Was the brand mentioned without being named in the prompt?
    • Was it recommended, listed as an alternative, used as an example, or ruled out?
    • Was the description factually accurate?
    • Did the response include the claims and differentiators that matter?
    • Were limitations and conditions represented correctly?
    • Was your site or another relevant page cited or linked?
    • Which alternatives appeared, and for which stated reasons?
    • Did the resulting visit, when measurable, lead to meaningful on-site behavior?

    Repeat prompts enough to notice variation rather than treating the most favorable output as the baseline. Compare like with like. A response produced with search enabled should not be casually compared with a response produced in a different mode and treated as proof that a content edit caused the change.

    Diagnose the stage that is failing

    • No unbranded visibility: review category association, audience fit, entity clarity, claim coverage, discoverability, and external corroboration.
    • A mention with the wrong description: look for inconsistent canonical facts, legacy pages, ambiguous names, and stale third-party profiles.
    • An accurate mention without a citation: inspect whether your pages offer a concise, directly supportable answer. Also remember that not every response presents citations, so absence alone does not identify a site defect.
    • A citation with no qualified visit: check whether the quoted context matches user intent and whether the landing page continues the answer instead of switching immediately to a sales pitch.
    • Qualified visits without business action: examine the offer, proof, user experience, and conversion path. More AI visibility will not repair a weak destination.

    Track the full chain where your analytics allow it: response visibility, citation or referral, landing-page engagement, qualified action, and business outcome. Do not claim revenue impact from a mention unless you can connect the stages with appropriate attribution.

    Key takeaways

    • ChatGPT optimization is a channel-specific part of GEO, not a replacement for technical SEO, useful content, or brand authority.
    • Target decision situations rather than isolated keywords, and define when your brand genuinely belongs in the answer.
    • Map every important claim to evidence, a canonical page, clear conditions, and an accountable owner.
    • Write bounded answers that identify the entity, audience, reason, proof, limitation, and next action without forcing the system to infer missing facts.
    • Use JSON-LD to confirm visible relationships and truthful attributes; never treat schema as evidence or a ranking guarantee.
    • Measure unbranded, fit, comparison, validation, and follow-up prompts under recorded conditions, then diagnose the specific stage that failed.

    Start with the decision page closest to a meaningful customer action. Build its claim-and-evidence map, remove language you cannot support, clarify the intended audience and limits, align the structured data, and add the corresponding prompts to your baseline. Once that page tells a complete and verifiable story, move to the next decision instead of spreading shallow edits across the whole site.

    References

  • AEO Visibility Strategy: Build Authority and Measure Results

    AEO Visibility Strategy: Build Authority and Measure Results

    You can publish technically clean, accurate content and still disappear from AI answers. Standard web analytics may not explain why. An answer can omit your brand, describe it incorrectly, mention it without a link, or cite a competitor without sending anyone to your site.

    The practical fix is to stop treating answer engine optimization as a publishing checklist. Connect the questions you want to own, the evidence an answer engine can use, the authority supporting that evidence, and repeated measurement of the answers themselves. You can then tell whether you have a discovery problem, an authority problem, a citation problem, or simply a measurement gap.

    Define visibility as an answer-level outcome

    A goal such as rank in AI search is too loose to manage. It doesn’t identify the audience, the relevant questions, the surfaces being measured, or what a successful answer should contain.

    Write a testable goal instead: when a defined audience asks a defined class of questions on a named AI surface, your organization should be accurately associated with the relevant category, included when it is genuinely eligible, and supported by an appropriate citation when the interface provides citations.

    That qualification matters. Not every answer should mention your brand, and not every interface displays links in the same way. Decide which prompts make your brand eligible before you inspect the results. Otherwise, teams tend to label irrelevant omissions as failures and flattering but commercially useless mentions as wins.

    The V3 AEO Periodic Table organizes 15 visibility elements from 2.2 million live prompts across platforms including ChatGPT, Gemini, and Claude. Treat that breadth as an important warning: visibility is a multivariable outcome. It is not proof that one fixed checklist controls every engine or interface.

    Keep the following measures separate in your scorecard:

    • Eligible mention rate: Of the tracked prompts where your brand could reasonably help, how often is it named?
    • Owned citation rate: How often does the answer link to a relevant page you control when citations are displayed?
    • Corroborating citation rate: How often does an independent reference support the claim or association you want to establish?
    • Framing accuracy: Are your category, capabilities, limitations, audience, and other material facts represented correctly?
    • Prominence: Is the brand a primary recommendation, one item in a longer set, a passing example, or a caution?
    • Competitive inclusion: Which eligible competitors appear when you do not, and what evidence is cited for them?
    • Action quality: Does the answer expose a useful next step, such as a relevant page, branded lookup, qualified referral, or measurable conversion path?

    Do not collapse those measures into one opaque visibility score. A brand can have a healthy mention rate and poor factual accuracy. It can earn citations for informational questions while disappearing from purchase-oriented comparisons. One average conceals both problems.

    Preserve the raw evidence behind every result. Record the exact prompt, query group, platform and interface, visible model label when available, language, market, date, session conditions, full answer, displayed URLs, competitors, sentiment or recommendation type, factual errors, and reviewer notes. A percentage without the underlying answers cannot tell your content, technical, or PR teams what to change.

    Build a prompt portfolio around real decisions

    AEO measurement starts with prompts, not keywords. A keyword can indicate a subject; a prompt exposes the decision, constraints, and evidence the user expects. Your tracked set should represent the questions that move someone from recognizing a problem to evaluating a solution and verifying a choice.

    Organize prompts into decision groups so that a gain in one part of the journey cannot disguise a loss elsewhere:

    • Problem discovery: Questions about symptoms, risks, causes, or ways to approach a problem without naming a product category.
    • Category education: Questions asking what a type of solution is, how it works, or when it is appropriate.
    • Criteria and comparison: Questions about alternatives, tradeoffs, required capabilities, and fit under specific constraints.
    • Validation: Questions about credibility, evidence, safety, compatibility, implementation, limitations, or reputation.
    • Branded facts: Questions about your entity, offering, policies, integrations, leadership, or other facts you should be able to support directly.
    • Post-selection use: Questions a customer asks while adopting, operating, troubleshooting, or expanding the solution.

    Use two prompt sets. Keep a core set unchanged so you can compare performance over time. Maintain a separate exploratory set for new customer language, competitor movements, emerging objections, and product changes. If a core prompt needs revision, create a new version and retain the old wording in the record. Silently rewriting a prompt after an unfavorable result destroys the trend line.

    Brand-heavy prompts are useful for checking entity accuracy, but they are a poor proxy for discovery. A system may repeat your name correctly when the user supplies it and still fail to associate you with the unbranded problem you solve. Report branded and unbranded results separately.

    Keep test conditions as consistent as the interface permits. Use the same language, market, session state, and prompt wording for trend checks. If repeated runs produce different answers, preserve the variation instead of selecting the most favorable response. Likewise, do not merge ChatGPT, Gemini, Claude, and other surfaces into one trend line. A change on one surface is a finding about that surface until the others confirm it.

    Match monitoring speed to consequence. Reputation-sensitive inaccuracies and active launches justify alert-oriented observation, while stable category prompts can be evaluated in consistent batches. The value of real-time content monitoring is faster response to meaningful changes, not a busier dashboard. An alert should identify the affected prompt, changed claim, cited URL, and responsible owner.

    Turn your content into an authority system

    A modular knowledge hub connects blank document tiles, research materials, experts, independent source nodes, and glowing answer orbs.

    Authority is not a confident tone, a high word count, or a page labeled definitive. For AEO, a useful authority system makes important claims explicit, gives those claims verifiable support, defines their scope, and keeps the same entity facts consistent wherever they appear. Trust and earned citations are central to authoritative GEO content because an answer needs more than a sentence it can extract; it needs a reason to rely on that sentence.

    Start with a claim-evidence ledger. For every answer you want your brand to influence, record:

    • the audience question and intent;
    • the precise claim you are qualified to make;
    • the canonical page responsible for that claim;
    • the evidence, method, policy, documentation, or primary record supporting it;
    • the conditions and limitations that prevent overstatement;
    • the person or team accountable for accuracy;
    • the last meaningful verification date;
    • independent corroboration, where it exists; and
    • the structured data that accurately describes the visible page.

    This ledger exposes a common failure: several pages make slightly different versions of the same claim, while none is clearly maintained as the source of truth. Consolidate the fact on one canonical destination. Let supporting pages summarize it accurately and link back rather than inventing another formulation.

    Audit each priority page for citation readiness:

    • Answer the primary question directly near the relevant heading.
    • Name the entity, category, audience, and scope without forcing the reader to infer their relationship.
    • Place supporting evidence and necessary caveats beside the claim they qualify.
    • Identify the author, editor, reviewer, organization, or accountable team where that context affects credibility.
    • Use descriptive headings and stable URLs so a specific section can be found and referenced.
    • Make important facts available as text rather than hiding them only in images, interactive elements, or downloadable files.
    • Connect the page to related definitions, methodology, documentation, comparison criteria, and entity pages through purposeful internal links.
    • Show a meaningful updated date only when the underlying information has actually changed.
    • Ensure JSON-LD describes the visible content and uses the appropriate entity relationships.

    JSON-LD can clarify what a page and its entities represent. It cannot turn an unsupported assertion into evidence, repair contradictory facts across your site, or force an answer engine to cite you. Treat schema as a precise description layer over trustworthy content, not as a substitute for it.

    A citation-ready passage should still make sense when read outside the surrounding page. A practical pattern is: [Entity] is a [category] for [audience]. It provides [capability] within [defined scope]. The claim is supported by [method, documentation, or primary record], current to [date or version]. Replace every placeholder with information you can substantiate. If you cannot complete the evidence field, narrow the claim before publishing it.

    Self-contained does not mean stripped of nuance. Put material qualifications next to the sentence they constrain. If the caveat is several screens away, the extracted claim may become broader than your evidence allows.

    Use PR to close corroboration gaps

    Your website can establish what you say about yourself. It cannot create independent agreement by repeating the same claim across more owned pages. When an important answer requires outside confirmation, PR and content distribution should be planned around the evidence gap rather than raw mention volume.

    AI-assisted media monitoring can connect PR activity with AEO visibility, but the connection only becomes useful when both teams work from the same target claims. A publicity report counting every mention will not show whether the market now associates your brand with the right category or whether an answer engine has found stronger evidence.

    Use this workflow for each priority claim:

    1. Write the target answer. State the accurate association or fact you want an eligible user to find.
    2. Inspect current answers. Note which entities are included, how they are framed, and which URLs provide support.
    3. Identify the proof gap. Decide whether you lack an owned source, independent corroboration, current evidence, clear category language, or consistent entity facts.
    4. Create a referenceable asset. Publish the methodology, documentation, data, definition, criteria, or other evidence needed to support the claim.
    5. Distribute the evidence. Brief relevant external channels on the substantiated finding or resource, not a stack of unsupported superlatives.
    6. Monitor the resulting language. Check whether coverage preserves the correct entity, scope, caveats, and canonical link.
    7. Reconcile your owned content. Update the claim-evidence ledger and correct conflicting pages or structured data.

    Evaluate an external mention by asking whether it names the entity and category correctly, carries a verifiable fact, links to the appropriate evidence, appears in a context relevant to your tracked prompts, and remains publicly accessible. A vague brand name-drop may increase a PR count while adding almost no authority to the answers you care about.

    Do not manufacture apparent consensus by syndicating an unproven statement or publishing near-duplicate claims on low-relevance sites. That creates more copies of the weakness. Strengthen the underlying evidence, correct inaccurate profiles or references where appropriate, and seek coverage from contexts that genuinely understand the subject.

    Operate AEO as a measured evidence loop

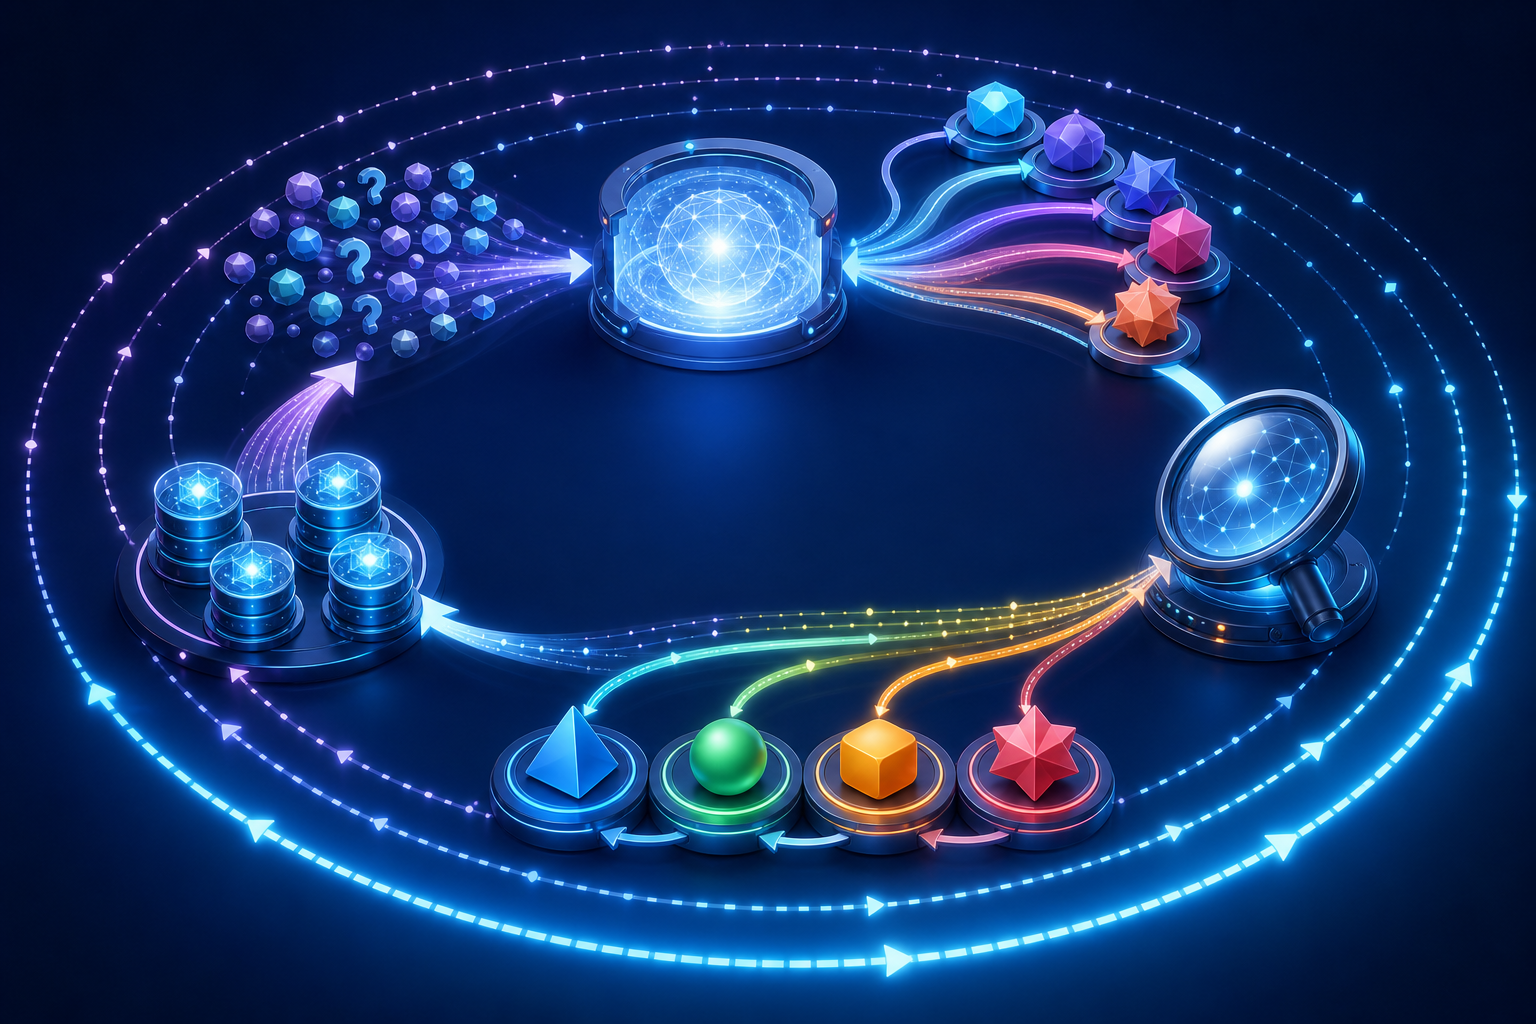
    A circular system moves abstract question tokens through an answer chamber, an observation lens, evidence markers, and refined source modules before looping back.

    The useful question after a monitoring run is not simply whether the score went up. Ask where the path from prompt to answer failed, then choose the smallest intervention that tests that diagnosis.

    What you observeLikely constraint to testNext action
    No mention on an eligible promptMissing topic coverage, weak entity-category association, discovery difficulty, or insufficient corroborationMap the prompt to a canonical page, make the relevant relationship explicit, improve purposeful internal links, and examine the outside evidence available for competitors.
    Your brand is mentioned but a competitor is citedYour page may be less specific, supportable, current, or citation-readyCompare the cited evidence with your own. Strengthen the precise claim, provenance, scope, and stable passage instead of merely adding more copy.
    Your brand is cited but described inaccuratelyConflicting, ambiguous, or stale entity factsDesignate a canonical source of truth, reconcile visible content and schema, correct material external errors where possible, and monitor the affected prompt.
    You appear on branded prompts but not category promptsWeak unbranded problem or category authorityBuild content around problem definitions, selection criteria, use-case constraints, and comparisons, then pursue corroboration for the claims those pages make.
    Visibility rises without useful business activityThe prompt portfolio or destination path may be commercially misalignedReclassify prompts by business relevance, inspect cited destinations, and connect identifiable AI referrals and assisted outcomes without claiming attribution you cannot prove.
    One platform improves while others stay flatA surface-specific retrieval, selection, or presentation differencePreserve separate platform trends and verify the change elsewhere before declaring a general AEO gain.

    Modern search visibility depends on multiple kinds of AI algorithms and applications. The operational inference is straightforward: do not assume an intervention that changes one surface will transfer unchanged to every other surface. Observe the transfer.

    Use a controlled improvement cycle:

    1. Capture a baseline with raw answers, citations, and test conditions.
    2. Classify each material failure as coverage, discovery, entity clarity, authority, citation readiness, framing, or business alignment.
    3. Choose one primary intervention for the affected prompt group.
    4. Annotate exactly what changed, where it changed, and which claim it was meant to improve.
    5. Run the unchanged core prompts under comparable conditions.
    6. Compare the answer, cited evidence, framing, and competitors rather than checking only the aggregate score.
    7. Retain the change when the intended signal improves without introducing factual or user-experience problems; otherwise revise the diagnosis.

    Your reporting should have separate executive and diagnostic views. The executive view can show eligible coverage, citation, accuracy, prominence, and commercially relevant outcomes by platform and prompt group. The diagnostic view should expose the raw answer, cited URLs, unsupported or incorrect claims, competing entities, proposed intervention, owner, and status. Without that second layer, the dashboard describes the problem but cannot run the work.

    Keep business attribution honest. AI-referred sessions and conversions are useful when they can be identified, but they do not capture answers that influence a later branded search, direct visit, or offline decision. Report answer-level visibility and observable business activity as connected but distinct evidence. Do not assign revenue to an AEO change merely because both moved in the same period.

    Key takeaways

    • Define success for eligible prompts, named surfaces, accurate framing, and appropriate citations before collecting results.
    • Track mentions, owned citations, independent corroboration, accuracy, prominence, and business activity separately.
    • Preserve a fixed core prompt set for trends and a separate exploratory set for discovery.
    • Build authority through explicit claims, verifiable evidence, clear scope, consistent entities, and schema that matches visible content.
    • Use PR to close specific corroboration gaps, not to accumulate undifferentiated mentions.
    • Diagnose the failed stage, change one primary layer, annotate it, and rerun comparable tests.

    Start with one commercially meaningful query group. Freeze its core prompts, capture the baseline across the surfaces your audience uses, and build a claim-evidence ledger for the pages that should support those answers. Your first valuable result is not a larger score. It is knowing why your brand was omitted, misframed, or passed over for a citation, and having a specific piece of evidence to improve next.

    References

  • How to Manage AI Search Volatility and Platform Dependence

    How to Manage AI Search Volatility and Platform Dependence

    Your page was cited in an AI answer during the last reporting cycle. Now it has disappeared, a competitor has replaced it, and nobody can tell you whether the content failed or the platform simply moved.

    Do not rewrite the page yet. AI visibility is produced by several changing systems, so one lost citation is an observation, not a diagnosis. You need to identify where the movement occurred, measure it across a useful query set, and reduce the business impact of any single platform changing direction.

    First, determine what actually changed

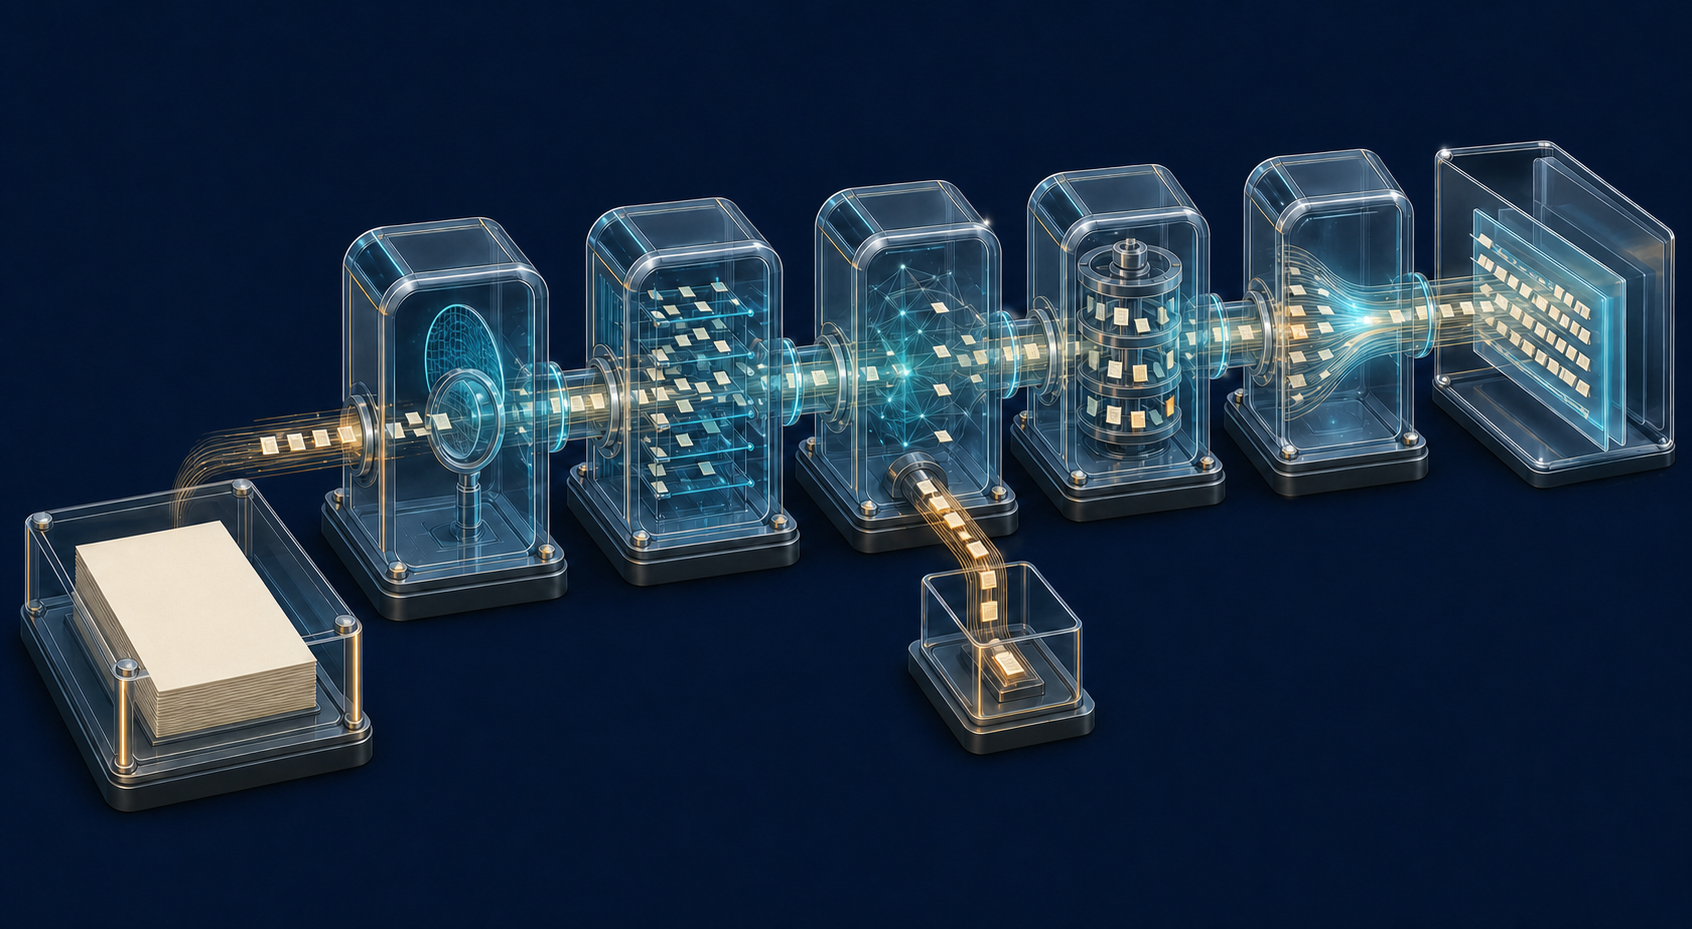
    A source document feeds through a series of translucent processing chambers, where one content fragment is diverted before reaching the final output.

    An AI citation is the end of a chain. Depending on the product and mode, that chain can include crawling, indexing, retrieval, ranking, answer generation, and citation presentation. A page can remain accurate and accessible while losing at the final selection stage. It can also keep appearing as an uncited influence, or retain a citation while the answer no longer communicates the claim you care about.

    This variability is often called citation drift. Citation selections across major AI platforms have been found to fluctuate by up to 60% in a month. Treat that figure as an indication of how large the movement can become, not as a universal monthly rate for every query, brand, or platform.

    The practical distinction is between platform volatility and asset deterioration. Platform volatility changes which eligible material gets selected. Asset deterioration makes your page less eligible or less useful because of a technical problem, a weaker answer, outdated information, or lost relevance. They require different responses.

    Pattern you observeMost useful working diagnosisFirst check
    One URL disappears for one prompt while the brand or related pages still appearPossible citation driftRepeat the observation with the exact prompt and its close variants; save the full answers and cited URLs
    A whole query family changes on one platform, but remains stable elsewherePlatform-specific retrieval or ranking movementCompare the newly cited domains, page types, and claims before editing your own page
    The same page declines across target platforms and related promptsPossible page-level or site-level problemVerify indexability, canonical handling, internal links, rendered copy, factual currency, and intent match
    The brand remains in the answer but its citation disappearsAttribution weakness rather than complete visibility lossMake the relevant claim explicit and place its supporting evidence beside it
    Visibility falls after a template, migration, or publishing changePossible technical regressionInspect directives, canonicals, page rendering, structured data, and whether important text is still available in the primary HTML

    Platform dependence can also sit upstream of the answer itself. In one observed change, ChatGPT showed greater alignment with Google results instead of Bing results. That makes Google indexing more consequential for teams pursuing ChatGPT visibility. It does not establish that ChatGPT depends exclusively on Google, that Bing no longer matters, or that the alignment will remain fixed.

    That qualification should shape your response. Strengthen weak Google eligibility when you find it, but do not dismantle Bing optimization or build a strategy around one observed alignment. A provider can change its retrieval partners, ranking logic, model, browsing mode, or citation interface without asking you to approve the new dependency.

    Measure a query portfolio, not a favorite prompt

    A single prompt is a poor proxy for AI visibility. It mixes the strength of your content with the variability of the generated response. It may also hide a more important result: your brand could lose one phrasing while gaining visibility for another question with the same intent.

    Build your monitoring set around query families. Each family should represent a real user need, such as understanding a problem, comparing approaches, validating a claim, or choosing a provider. Add natural phrasing variants, but label them as members of the same family so you do not mistake repeated wording for broader market coverage.

    For every observation, retain enough context to reproduce and interpret it:

    • The exact prompt, including any constraints or follow-up context.
    • The query family and the user intent it represents.
    • The platform, interface, and visible model or mode.
    • The observation date and any controllable context, such as locale.
    • Whether the brand was mentioned.
    • Whether a citation was attached, and the exact cited URL.
    • Whether the answer expressed the claim accurately.
    • Which competing domains and page types were cited.
    • The page’s known crawl, index, canonical, and content status at the time.
    • The full response, not just a positive or negative score.

    The full response matters because visibility has several states. A correct, cited recommendation is not equivalent to an incidental brand mention. An uncited mention is not equivalent to complete absence. A citation attached to a misleading claim can be worse than no citation at all.

    Keep separate metrics for separate questions

    Do not compress everything into one AI visibility score. Track measures that tell you what kind of change occurred:

    • Mention rate: the share of valid observations in which the brand appears, with or without a link.
    • Citation rate: the share in which an owned URL is explicitly cited.
    • Claim accuracy: the share of reviewed answers that represent your important facts correctly.
    • Query-family coverage: the intents for which you appear, rather than the raw number of prompt phrasings that mention you.
    • Platform concentration: the portion of positive observations supplied by the platform contributing the most visibility.
    • URL concentration: the portion of citations going to your most frequently selected page.

    Concentration is a risk measure, not automatically a performance problem. If one platform or one URL supplies most of your visibility, the current result may look strong while remaining fragile. Compare concentration with your own baseline and business priorities instead of inventing a universal threshold.

    Keep the observation schedule consistent with your normal publishing and reporting cycle. Changing prompts, modes, and sampling rules between reports creates measurement noise that can look like market movement. When you deliberately revise the method, preserve the old series and mark the break rather than pretending the numbers remain directly comparable.

    Reduce dependence at the search, content, and business layers

    A business core is protected by concentric networks of content, discovery channels, and customer paths while one external platform disconnects.

    You cannot remove AI search volatility, but you can stop one platform decision from controlling the entire outcome. The work belongs at three layers: technical eligibility, citable content, and business distribution.

    Protect technical eligibility across search systems

    If a platform’s alignment moves toward Google, pages missing or weak in Google’s index can lose downstream opportunities even when they remain available elsewhere. If the alignment changes again, a Google-only posture can become the new weakness. Maintain eligibility in both Google and Bing where those systems matter to your audience.

    Your important answer pages should have stable canonical URLs, descriptive titles and headings, crawlable internal links, and critical copy available in the primary rendered page. Check that indexing directives agree with your intent. After a migration or template release, verify the output itself rather than assuming the content management system preserved those signals.

    Use JSON-LD to make supported entities and relationships explicit where suitable schema types and properties exist. Keep the structured facts consistent with the visible page. Schema can reduce ambiguity for machines, but it is not a citation guarantee and should not be used to assert claims the reader cannot verify on the page.

    Make the claim easy to extract and easy to attribute

    A page can be comprehensive and still be difficult to cite. If the answer is buried under a long introduction, expressed only through marketing language, or separated from its evidence, a retrieval system has to do more interpretive work.

    • State the direct answer near the section heading that frames the relevant question.
    • Name the entity, product, method, or limitation instead of relying on ambiguous pronouns.
    • Place supporting evidence and qualifications beside the claim they support.
    • Separate durable facts from commentary that will age quickly.
    • Use tables only when the relationships are truly tabular; do not hide the main conclusion inside a decorative comparison.
    • Keep organization, product, and author identities consistent across visible copy, metadata, and structured data.
    • Update dates only when the substance changed, and make the changed information apparent to the reader.

    The goal is not to write mechanically for an AI system. It is to reduce the distance between a user’s question, your supported answer, and the evidence that makes the answer attributable. That also makes the page easier for a person to scan and verify.

    Do not let AI visibility become the business outcome

    AI platforms control the answer interface, citation treatment, and referral path. You control the destination and what happens after a visitor arrives. A durable strategy therefore connects AI discovery to useful owned assets: a definitive page, a tool, documentation, a newsletter, a product workflow, or another appropriate next step.

    Report brand mentions and citations as discovery indicators. Report qualified visits, sign-ups, inquiries, sales, or another relevant action as business outcomes. If citations rise while useful actions do not, the answer may be satisfying curiosity without reaching the audience or intent that matters. That is a positioning question, not merely an optimization problem.

    Use a controlled response when visibility falls

    Overreaction is one of the most expensive consequences of citation drift. A team sees a missing citation, rewrites a page that was working, changes its headings again in the next cycle, and loses the stable baseline needed to determine what happened.

    Use the same response sequence for every material decline:

    1. Confirm the scope. Check the exact prompt, its query family, the target platforms, mentions, citations, and claim accuracy. Determine whether the movement belongs to one response, one platform, one page, or the wider topic.
    2. Rule out technical loss. Verify that the page remains crawlable, indexable where intended, canonicalized correctly, internally linked, and rendered with its important content present.
    3. Inspect the replacement set. Record which pages replaced yours and what kind of pages they are. Look for changes in dominant intent, answer format, freshness, entity match, and evidence. Do not assume the replacement won because it repeated a keyword more often.
    4. Select the smallest justified intervention. Fix a factual gap, unclear answer, missing qualification, ambiguous entity, or technical defect. If the evidence points only to isolated citation rotation, preserve the page and continue observing.
    5. Validate against the portfolio. Recheck the affected query family and other pages that use the same template or content pattern. A change that helps one prompt but damages adjacent intent is not a clean improvement.
    6. Record the change. Save what changed, why it changed, and the first observation made afterward. Do not stack another speculative rewrite on top before your normal measurement cycle can reveal the effect, unless you discover a factual error or technical failure that needs immediate correction.

    This protocol also makes internal conversations more precise. Instead of saying that AI visibility is down, you can say that citations declined on one platform while mention coverage and cross-platform eligibility remained stable, or that the same URL lost visibility across its entire query family after a technical release. Those diagnoses lead to different work.

    Key takeaways

    • A missing citation is an observation. Confirm whether the loss is isolated, platform-wide, page-wide, or topic-wide before changing content.
    • Citation selections can move substantially, so preserve exact prompts, full responses, cited URLs, platform context, and historical baselines.
    • Track mentions, citations, claim accuracy, query-family coverage, and concentration separately; one blended score hides the cause of change.
    • ChatGPT’s observed movement toward Google alignment increases the importance of Google indexing, but it does not justify abandoning Bing or assuming a permanent dependency.
    • Reduce risk by maintaining cross-platform technical eligibility, publishing explicit and well-supported claims, and connecting AI discovery to owned business outcomes.

    Before your next AI visibility report, label every monitored prompt by query family and every loss by scope. Fix confirmed technical or content weaknesses, leave isolated drift alone, and preserve enough evidence to recognize the difference when the platforms move again.

    References

  • How to Optimize Existing Content for AI Visibility

    How to Optimize Existing Content for AI Visibility

    You probably don’t need another batch of articles. If your site already answers valuable customer questions, the faster route to more AI visibility may be to make those answers easier to identify, interpret, verify, and cite.

    That requires more than adding keywords or mentioning AI. You need to choose the right pages, map them to real questions, strengthen the passages that carry the answer, remove contradictions, and measure whether answer engines represent your brand more accurately afterward.

    Choose pages with a credible path to visibility

    Blank content tiles in a digital workspace, with three well-connected pages highlighted for selection.

    Don’t begin by refreshing every old URL. A large content library contains pages with very different jobs: some attract qualified demand, some support customers, some establish expertise, and some no longer deserve attention. Optimizing all of them equally spreads effort across content that has little chance of influencing an AI-generated answer.

    Start with the questions you want your brand to be associated with. Then identify which existing page should provide the best answer to each question. This question-to-page mapping matters because AI visibility is contextual. A brand mention for an irrelevant query is not a useful result, and several pages competing to answer the same question can make your intended answer less clear.

    Build your optimization queue around these signals:

    • Audience relevance: The page addresses a problem your buyers, users, or stakeholders genuinely need to solve.
    • Business relevance: You would be comfortable having this page represent your brand in an AI-generated answer.
    • A recoverable answer: The page contains useful knowledge, but the direct answer is buried, fragmented, vague, or outdated.
    • Evidence readiness: Important claims can be supported, qualified, or removed. A page full of assertions you cannot verify is a poor optimization candidate.
    • A clear page owner: Someone can review the content when products, processes, terminology, or evidence change.
    • Limited internal conflict: The same site does not give several incompatible answers to the question. If it does, consolidation or reconciliation comes before stylistic editing.

    Assign each candidate a practical disposition: update, expand, consolidate, replace, or leave alone. “Leave alone” is a legitimate decision when a page is accurate, clear, and serving its intended purpose. Optimization should solve a diagnosed problem, not create change for its own sake.

    For an established site, improving content already in the library can be more useful than treating publication volume as the default growth lever. The key is selection. Refresh the pages that already contain defensible knowledge and have a defined question to answer.

    Turn each target question into an evidence-led brief

    A content brief for AI visibility should specify the answer before it specifies the word count, format, or keyword set. Otherwise, the writer can produce a polished page without resolving the question an answer engine needs to handle.

    Use first-party evidence to find the language behind the question: search queries, on-site searches, support requests, sales objections, customer interviews, and the prompts your visibility monitoring already tracks. Group different phrasings by the underlying decision. “Should we update this page?” and “Does this page need a rewrite?” may belong to the same question family, while “Why did traffic fall?” requires a different answer.

    Your brief should contain:

    • Primary question: The exact problem the page must resolve.
    • Reader context: Who is asking, what they already know, and what decision follows the answer.
    • Direct answer: The conclusion the page can support without exaggeration.
    • Scope: The products, markets, use cases, versions, or conditions to which the answer applies.
    • Supporting questions: The follow-ups a reader needs before acting, not every loosely related keyword.
    • Evidence: The internal data, official documentation, primary material, or other support available for each consequential claim.
    • Required entities: The full names of products, organizations, standards, methods, and concepts that must be unambiguous.
    • Exclusions: Claims the evidence cannot support and tangents that would dilute the page’s purpose.
    • Desired citation: The specific fact, explanation, or recommendation for which this page should be the appropriate reference.
    • Maintenance owner: The person or team responsible for future review.

    This is where data-driven briefs earn their keep. They force the team to connect demand, evidence, and page structure before drafting. Vendor-reported results from teams using data-driven briefs include noticeable AI-visibility improvements within a few weeks. Treat that timing as an encouraging observation, not a guarantee or a universal benchmark; visibility depends on the question, competitive field, source discovery, and the answer system being monitored.

    Templates can also make quality more repeatable across writers and subject-matter experts. In vendor-reported use, teams have published template-led content that received AI citations. The template itself is not the reason to trust the page. Its value is that it makes missing answers, unsupported claims, and unclear ownership harder to overlook.

    Make the answer easy to extract without flattening the page

    Cutaway illustration of a structured web page with an answer block supported by connected evidence and context.

    An answer engine may encounter a passage without carrying all the context from the paragraphs around it. Your most important sections therefore need to make sense on their own. That does not mean reducing the whole page to disconnected snippets. It means placing the necessary context next to the claim it qualifies.

    Use descriptive headings that reveal the section’s job. “When to refresh an existing page” is more informative than “Content strategy.” Under the heading, answer the question immediately, then explain the reasoning, evidence, limits, and next action.

    Compare these two openings:

    Weak: It depends on several factors, and every situation is different.

    Stronger: Refresh an existing page when it still addresses the correct audience and intent, but its answer is incomplete, difficult to locate, internally inconsistent, or no longer current.

    The stronger version gives the reader a decision rule. The following paragraphs can still cover exceptions. This order serves both human readers and systems trying to determine what the passage claims.

    As you revise each answer-bearing section, check for these extraction problems:

    • Delayed answers: The section spends several paragraphs setting up a conclusion it could state at the beginning.
    • Unclear references: Pronouns such as “it,” “they,” or “this” could refer to more than one entity. Repeat the necessary name where ambiguity would change the meaning.
    • Missing conditions: A recommendation appears universal even though it applies only to a particular audience, product state, market, or scenario.
    • Orphaned numbers: A figure appears without the population, period, definition, or supporting evidence needed to interpret it.
    • Decorative lists: Prose has been broken into bullets even though the items are not parallel choices, steps, requirements, or criteria.
    • Heading drift: The heading promises one answer while the paragraph discusses a neighboring topic.
    • Conflicting claims: The summary, body, FAQ, metadata, and structured data describe the same fact differently.
    • Unsupported certainty: Words such as “always,” “best,” and “guaranteed” overstate what the available evidence can establish.

    Lists are useful when the reader needs to evaluate criteria or follow a sequence. Tables are useful when the same dimensions must be compared across several options. Plain paragraphs are better when the reasoning depends on context. Choose the format that preserves meaning instead of forcing every passage into a supposedly AI-friendly pattern.

    Keep evidence close to consequential claims. Name the organization, product, method, or standard involved. Link to the material that actually supports the sentence. If evidence is limited, state the limitation in the same section rather than hiding it in a general disclaimer.

    Structured data belongs in this consistency check, but it cannot rescue an unclear or unsupported page. Use a schema type that matches the visible content, and keep names, dates, authorship, descriptions, and other shared facts aligned with what a visitor can read. Do not place a claim only in JSON-LD and assume that markup turns it into evidence.

    Use separate workflows for live pages, drafts, and measurement

    A live page and an unpublished draft can use the same brief, but they do not carry the same risks. A draft has no established search role to preserve. A live URL may already earn traffic, links, conversions, citations, or internal prominence. Capture what the live page is doing before you change it.

    Refreshing a published page

    1. Record the baseline. Save the current title, headings, central claims, structured data, internal links, organic performance, conversions, brand mentions, and observed AI citations. Without a baseline, a later comparison becomes guesswork.
    2. Protect the page’s valid purpose. Write down the audience, target question, and useful material that must survive the refresh. Do not turn a functioning specialist page into a broad overview merely to cover more terms.
    3. Resolve factual conflicts. Compare important claims across the page and relevant pages on your site. Decide which statement is authoritative, update the others, and document the owner.
    4. Rewrite answer-bearing sections first. Improve the direct answer, scope, evidence, entity naming, headings, and supporting questions before polishing transitional copy.
    5. Check the whole published object. Review visible copy, links, metadata, canonical settings, indexability, structured data, media, and mobile presentation. A clean draft can still become an inconsistent page in the CMS.
    6. Log the change. Record what was changed, why it was changed, when it went live, which questions it targets, and what result would count as an improvement.

    Optimizing drafts and internal documents

    You do not need to wait for a public URL to test whether a draft answers the intended question. Some optimization workflows can evaluate pasted text and uploaded files as well as live URLs. That is useful for briefs, subject-matter-expert drafts, reports, and other material that should be corrected before it reaches the CMS.

    For unpublished material, mark the direct answer, evidence gaps, undefined entities, unsupported claims, and required follow-up questions in the source document. Then run a separate page-level review after publishing. A document file does not show the final navigation, metadata, structured data, internal links, templates, or rendering that can affect how the page is understood.

    Measuring a visibility change

    Measure against a stable set of questions. If you change the prompt, answer engine, page, and success criterion at the same time, you will not know what moved. For every observation, log the exact question, engine or model, date, brand representation, cited URLs, factual accuracy, and landing page.

    Track more than whether the brand appeared:

    • Question coverage: Does the answer address the intended problem or merely mention a related topic?
    • Brand representation: Is the brand associated with the correct product, category, position, or expertise?
    • Citation presence: Does the response link to a source, and is your page among the cited URLs?
    • Citation fit: Is the correct page cited for the claim, or has a weaker or unrelated page been selected?
    • Answer accuracy: Does the generated statement preserve your conditions, limitations, and current facts?
    • Durability: Does the result recur across repeated observations, or was it an isolated output?
    • Downstream value: When measurable, does visibility lead to qualified visits, branded demand, assisted conversions, or another outcome your organization values?

    Use misses as diagnostic clues, not instant proof of a cause. If the brand never appears, test whether the page truly matches the question and contributes information that deserves selection. If the brand appears without a citation, inspect whether the claim is self-contained and supported. If the wrong page is cited, look for overlapping intent or inconsistent internal signals. If the answer distorts your position, rewrite the ambiguous passage and remove conflicting language elsewhere.

    Answers can vary between runs, models, and interfaces. A single screenshot is therefore weak evidence of a durable gain or loss. Repeated observations using the same question set give you a more defensible basis for deciding whether to keep, revise, or reverse a change.

    Key takeaways

    • Optimize around questions you want your brand to answer, then assign a clear page to each question.
    • Prioritize existing pages with useful knowledge, business relevance, supportable claims, and a maintainable owner.
    • Put the direct answer near the start of each section, with its scope, evidence, and limitations close by.
    • Use descriptive headings, explicit entity names, genuine lists, and consistent facts across copy, metadata, links, and structured data.
    • Review drafts before publication, but repeat the audit on the rendered page because the CMS adds context the document does not contain.
    • Measure question coverage, citation fit, accuracy, durability, and business value against a recorded baseline.

    Choose a small set of commercially relevant questions and map each one to its strongest existing page. Complete the brief, revise the answer-bearing sections, validate every important claim, and record the baseline before publishing. That gives you an optimization cycle you can inspect and improve, rather than a collection of edits you can only hope will work.

    References

  • AI Observability Integrations: From Bot Logs to Decisions

    AI Observability Integrations: From Bot Logs to Decisions

    You can have a dashboard full of AI crawler requests and another full of citation results, yet still be unable to answer the question that matters: what should your team change?

    The answer is not another chart. You need an evidence chain that connects agent access, content delivery, AI visibility, and an owned decision. This guide shows you how to design that chain across CDN data, citation analytics, MCP tools, and software development kits without treating correlation as proof.

    Key takeaways

    • Start with a recurring decision, then choose the integrations needed to support it. A connector without a decision is only data movement.
    • CDN and server evidence can show that an identified AI agent requested a URL and received a response. It cannot, by itself, show that the content was indexed, understood, cited, or used to form an answer.
    • Give request data and citation data the same stable content identifier. Raw URLs are too inconsistent to serve as your primary join key.
    • Use MCP for bounded, interactive questions and SDKs for scheduled, repeatable workflows. Both should return the same definitions, filters, freshness information, and failure states.
    • Treat missing telemetry as unknown, not as zero activity. Every dashboard and alert should expose its observation window, coverage, and last successful ingestion time.
    • Keep analytics tools read-only by default. Publishing, crawler-control, and configuration changes need separate permissions and explicit human approval.

    Build an evidence chain before choosing connectors

    Four modular devices representing access, delivery, visibility, and action are connected in sequence on a dark investigation table.

    AI observability becomes useful when it separates four different questions. Combining them into a single visibility score hides the exact failure your team needs to fix.

    Evidence layerQuestion it can answerUseful recordsWhat it cannot prove
    AccessDid an identified or suspected AI agent request the content?Request time, observed URL, agent classification, hostThat the agent retained or understood the content
    DeliveryWhat did your infrastructure return?Response status, redirect target, cache or edge result when availableThat the returned content was eligible for an AI answer
    VisibilityDid your monitored prompts produce a mention or citation?Prompt set, model or surface, market, answer, cited URL, observation timeThat a particular crawler request caused the citation
    ActionWho will respond, and what decision will the evidence change?Owner, trigger condition, runbook, change recordThat the intervention will improve performance

    Write the operational question before you configure any integration. Good questions contain a defined content set, an observation window, a comparison, and a possible action. For example: which priority product pages received identified agent requests but remained absent from our monitored citation set during the same reporting window?

    That question tells you what must be joined. You need a priority-page inventory, normalized request events, citation observations, a shared time convention, and a stable content key. It also tells you what not to collect. If a field cannot filter the question, explain the result, or trigger an action, it does not belong in the first implementation.

    A practical integration map should also name the system of record for every concept. Your CDN can own request evidence. Your visibility platform can own prompt and citation observations. Your content inventory can own canonical identity. Your workflow system can own the resulting task. Do not allow several connectors to redefine the same metric independently.

    Use CDN data as access evidence, not citation evidence

    For websites delivered through Akamai, an Agent Analytics integration can bring AI crawler and bot interactions at the CDN into the observability layer. That moves analysis closer to the point where requests are actually served, which is valuable when application analytics do not provide a dependable view of non-human traffic.

    The important word is access. A request event can establish that your infrastructure observed traffic matching a classification rule. The corresponding response can establish what the infrastructure returned. Neither event tells you whether an AI system indexed the page, incorporated its claims, or cited it later.

    Preserve the raw event and add a reporting identity

    Do not overwrite source fields while cleaning the data. Keep the observed URL and bot identifier, then create normalized reporting fields beside them. This lets you change a classification or canonicalization rule without losing the evidence that produced the original result.

    • Event time: Store a consistent timezone and retain enough precision to diagnose ingestion delays.
    • Observed host and URL: Preserve what was requested before redirects or canonical mapping.
    • Content ID: Map URL variants to a stable identifier owned by your content inventory.
    • Response result: Retain the status and relevant edge outcome supplied by the integration.
    • Agent family: Use a normalized label for reporting while preserving the raw identifier.
    • Classification basis: Record whether identity is verified, claimed, inferred, or unknown.
    • Ingestion metadata: Include the connector, processing time, and schema version so data gaps can be distinguished from traffic gaps.

    A user-agent string is a claim, not conclusive identity. Where a bot operator publishes a verification mechanism and your data supports it, keep verified traffic separate from traffic classified only by its declared name. Do not silently discard ambiguous requests. Put them in an unknown or suspected group so a classifier update does not rewrite history invisibly.

    Define metrics that answer delivery questions

    Keep edge metrics narrow enough that their names remain true. Useful definitions include:

    • Priority-content request coverage: Distinct priority content IDs with at least one qualifying agent request divided by all content IDs in the declared priority set.
    • Accepted-response rate: Qualifying requests that received a response your team has explicitly classified as usable, divided by all qualifying requests. Publish the accepted status rules beside the metric.
    • Request distribution: Qualifying requests grouped by content type, directory, locale, or template.
    • Delivery friction: Qualifying requests returning an error, an unintended redirect, or another response state that your runbook treats as a problem.
    • Telemetry freshness: Time of the latest successfully ingested event compared with the end of the displayed reporting window.

    Keep query parameters only when they change the content you need to analyze. Strip known tracking parameters from the reporting URL, but retain the untouched observed URL under restricted access. This prevents campaign variants from fragmenting page-level coverage while preserving the evidence needed to investigate a mismatch.

    Most importantly, distinguish no observed request from no request. A connector outage, an unsupported property, an excluded hostname, a parsing failure, or a delayed export can all produce an empty chart. Add an ingestion heartbeat and coverage status to the dashboard. If the pipeline is incomplete, display unknown rather than a reassuring zero.

    Choose MCP or an SDK according to the decision path

    Collection is only half the integration problem. The data must reach the person or system making the decision. An MCP server can make visibility reports, bot analytics, and citation data queryable from Claude Desktop and other AI workflows. TypeScript and Python SDKs provide another route for software that needs repeatable access without requiring every user to construct raw API calls.

    These interfaces serve different operating patterns:

    • Use MCP for investigation: An analyst asks a bounded question, examines the result, changes a filter, and decides what to inspect next.
    • Use an SDK for repetition: A scheduled job applies a stable query, validates the response, stores normalized output, and triggers a defined downstream workflow.
    • Use your analytics store for history: Retain the governed data needed for trends and reproducibility rather than expecting a conversational session to become the long-term record.

    MCP should expose small, well-described tools rather than a vague tool that can fetch everything. A tool named for a business question is easier to govern than a generic query endpoint. Its contract should state required inputs, permitted filters, output fields, timezone, freshness behavior, pagination, and known gaps.

    Every response should carry enough context to survive outside the chat where it was requested. Return the observation window, timezone, applied filters, dimensions, last successful ingestion time, classification version, and completeness status with the result. An answer such as “twelve pages were not observed” is unsafe if the recipient cannot tell which property, bot class, page set, or window produced it.

    Apply read-only and least-privilege defaults

    Analytics access can expose private URLs, query values, unpublished content paths, customer identifiers, or internal prompt sets. Minimize that exposure before an AI assistant receives the data.

    • Give each integration only the properties, reports, and fields required for its named use case.
    • Use read-only credentials for investigation tools and keep secrets outside prompts, tool descriptions, and returned records.
    • Redact or aggregate sensitive URL parameters and payload fields before they enter the conversational layer.
    • Log tool name, caller, filters, execution time, result status, and returned record count for later review.
    • Treat text retrieved from pages, answers, and metadata as data, not as instructions that can redefine the assistant’s task.
    • Return explicit permission, timeout, partial-data, and rate-limit errors. Do not convert them into empty results.

    Do not give the same assistant silent permission to change robots controls, publish content, purge caches, or alter production configuration. A mistaken interpretation could affect site availability or discoverability. Put mutating actions behind separate tools, narrower credentials, a preview of the proposed change, and human approval.

    Join access and citations without inventing causality

    Separate cyan request tokens and violet citation nodes meet at a transparent matching surface while an analyst compares the joined evidence.

    The edge event and the AI answer usually do not share a request ID. Join them for analysis through governed dimensions: stable content ID, canonical URL, agent or surface family, locale when available, and aligned observation windows. That produces a useful relationship, but not proof that one particular request caused one particular answer.

    Your content ID is the critical bridge. The same page may appear as an HTTP and HTTPS URL, with tracking parameters, behind redirects, or under several cited URL forms. Keep observed_url, canonical_url, and content_id as separate fields. The first preserves evidence, the second supports URL reporting, and the third gives you a stable entity for longitudinal analysis.

    Observed agent accessObserved citationWhat you can concludeNext investigation
    NoNoYou do not yet know whether the issue is delivery, observation coverage, prompt coverage, or content selection.Validate both pipelines, then inspect delivery rules and whether the page belongs in the monitored prompt set.
    YesNoAccess was observed, but citation was not observed in the declared prompt set and window.Compare the page with cited alternatives, confirm the returned content, and inspect relevance, clarity, and entity alignment.
    NoYesCitation was observed without matching access evidence in the current dataset.Check timing, alternate URLs, cached access, agent classification, hostname coverage, and ingestion gaps.
    YesYesBoth signals were observed. The data still does not establish request-level causation.Inspect consistency, citation context, answer accuracy, and changes across comparable windows.

    Keep referral traffic as a separate downstream signal. A bot request is not a citation, and a citation is not a visit. Combining the three can help you see a pathway from technical access to visibility to site activity, but each transition has its own coverage limits. Label the stages rather than collapsing them into a single number.

    Put the integration into production with a decision-first runbook

    1. Select one recurring decision. Name the person who makes it and the action they may take.
    2. Declare the analysis scope. Record the properties, hostnames, priority content set, agent classes, prompt set, surfaces, locale, timezone, and observation window.
    3. Write the data contract. Define every field, accepted response state, normalization rule, null behavior, freshness expectation, and source of record.
    4. Connect data with read-only access. Start with the smallest permissions and fields that can answer the chosen question.
    5. Reconcile samples. Trace selected records from the originating system through normalization and into the final query. Confirm that redirects, parameter variants, unknown bots, duplicates, and missing fields behave as documented.
    6. Create the shared content key. Map observed and cited URL variants to a stable content ID without deleting their original forms.
    7. Expose one bounded query. Return the result together with scope, freshness, filters, and completeness metadata through MCP or an SDK workflow.
    8. Test failure states. Disable or restrict a test credential, supply an invalid filter, simulate delayed input, and confirm that each problem produces an explicit error or unknown state rather than an empty success.
    9. Attach an action. Give every alert an owner, diagnostic query, safe response, escalation path, and change record.
    10. Review the decision, not just the pipeline. If the output does not change what the owner does, narrow the question or retire the integration.

    A strong first production query is deliberately narrow: show priority content that received qualifying agent activity but had no citation in a specified prompt set, and include the reporting window, data freshness, classification basis, and coverage state. That result gives an SEO or content owner a finite investigation queue without pretending to explain the cause.

    Start there. Once your team can trace a decision from raw event to normalized evidence to an owned action, add another question. That sequence turns integrations into an observability system your team can challenge, maintain, and actually use.

    References