Server log analysis shows what search crawlers actually requested and how the server responded. That direct evidence can reveal crawl inefficiencies, response problems, and neglected page groups that simulated crawls or reporting interfaces may not expose.
The goal is not to replace Google Search Console, Bing Webmaster Tools, or site crawlers. It is to add an infrastructure-level record that can confirm whether important URLs receive crawler attention, identify where requests are being diverted, and provide a baseline for migrations and platform changes.
What server logs add to the SEO evidence stack
SEO crawlers test a site from the outside, while webmaster platforms present search-engine reporting. Server logs answer a different question: which requests reached the infrastructure, and what happened when they arrived?
The supplied CrushPress.AI article reports that logs capture individual requests, including visits from Googlebot and Bingbot, whereas other SEO tools may depend on samples, delayed reporting, or simulated crawls. It argues that this distinction is especially useful for sites with large URL inventories, where aggregate reports can conceal meaningful differences among directories, templates, and parameter combinations.
Logs still have boundaries. A request does not prove that a URL was indexed, ranked, or considered valuable by a search engine. Log analysis is therefore strongest when combined with crawl data, indexation evidence, internal-link analysis, and business priorities.
Key takeaways
Server logs record crawler requests received by the infrastructure rather than simulating crawler behavior.
Analysis should compare crawler attention with the site’s intended URL and page-section priorities.
Repeated requests to parameters, obsolete URLs, errors, or redirect paths can indicate crawl inefficiency.
Response status and timing help distinguish URL-management problems from infrastructure problems.
Retained historical logs support before-and-after analysis for migrations, redesigns, and platform changes.
Logs complement rather than replace Search Console, webmaster platforms, and technical crawlers.
The technical SEO questions logs can answer
Question
Evidence to examine
Possible decision
Are priority pages being crawled?
Requests grouped by page type, directory, or template
Review discovery paths, internal linking, or URL accessibility
Where is crawler attention going instead?
Requests for parameters, outdated structures, and low-priority URL groups
Reduce unnecessary URL generation or tighten crawl controls where appropriate
Are crawlers receiving unexpected responses?
Status patterns, redirect paths, and repeated requests to failing URLs
Correct response handling, redirect logic, or broken destinations
Is performance trouble isolated or persistent?
Response timing segmented by URL group and observed over time
Investigate affected templates, services, or infrastructure components
Did a deployment change crawler behavior?
Comparable periods before and after a migration, redesign, or infrastructure change
Address new errors, lingering legacy requests, or reduced access to priority sections
The source highlights a common large-site pattern: crawlers may spend requests on parameterized URLs while important product or category pages receive less attention. It also reports that obsolete URL structures can continue consuming crawl activity after a site has moved on operationally.
These observations should be interpreted as patterns, not automatic diagnoses. Heavy crawling of a URL group may be intentional, temporary, or caused by references outside the system being reviewed. Likewise, low request frequency becomes actionable only after confirming that the affected pages are important and meant to be discoverable.
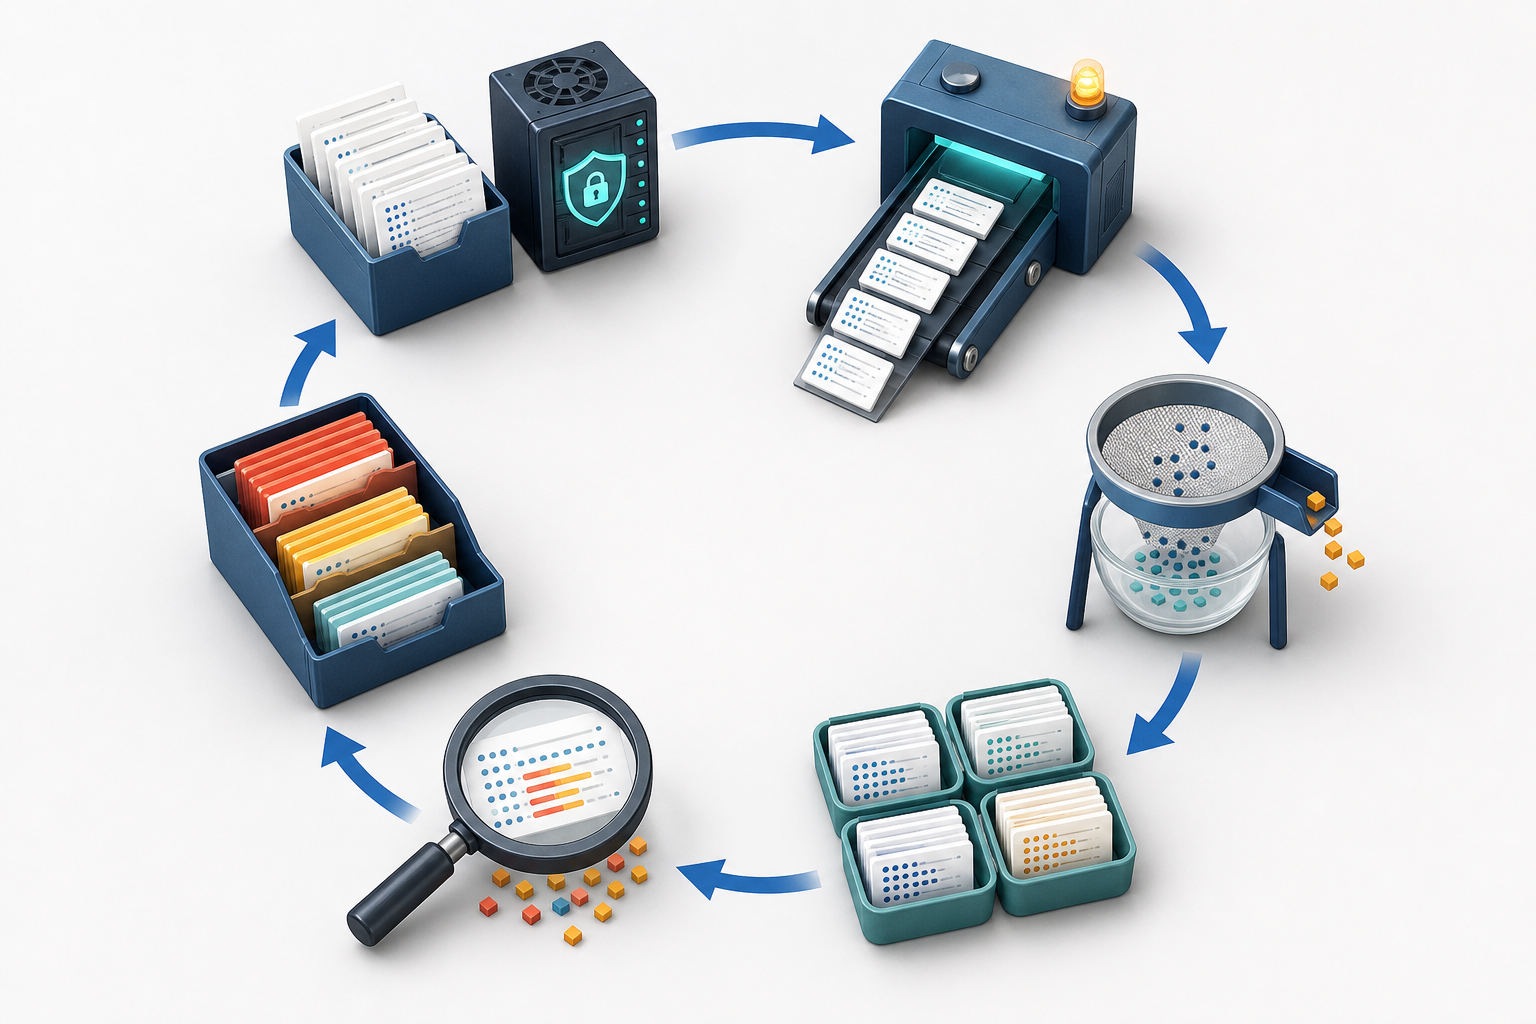
A repeatable workflow for log analysis
Define the decision first. Specify whether the analysis concerns crawl allocation, errors, redirects, server performance, a migration, or another technical question.
Choose a representative time window. Preserve enough history to separate an isolated event from a recurring pattern and mark deployments or infrastructure changes that could affect interpretation.
Prepare the required request fields. A useful dataset generally needs the requested path, request time, response status, user agent, and response timing when the logging configuration provides it.
Identify legitimate crawler traffic. Do not assume that every request carrying a search-bot user agent is genuine; apply the organization’s bot-validation process before drawing conclusions.
Normalize and group URLs. Separate meaningful page types from parameters, duplicate forms, obsolete paths, static resources, and other request classes so that high-volume noise does not dominate the analysis.
Compare crawler behavior with site priorities. Examine whether commercially or editorially important sections receive attention while low-value or retired URL spaces consume requests.
Segment response outcomes. Review successful responses, errors, redirects, and response timing by section or template rather than relying only on sitewide averages.
Validate findings elsewhere. Reproduce suspected issues with a crawler or direct request, then compare them with Search Console, Bing Webmaster Tools, internal-link data, and infrastructure monitoring.
Create a baseline. Retain comparable summaries so future releases, migrations, and redesigns can be evaluated against known crawler behavior.
Turning log patterns into defensible priorities
The most useful findings connect crawler behavior to a specific technical mechanism. Requests concentrated on unnecessary parameter combinations point toward URL generation or crawl-control decisions. Repeated visits to obsolete addresses suggest that old discovery paths or redirects still matter. Persistent errors or slow responses concentrated in one template point toward a narrower application or infrastructure investigation.
Frequency and persistence help with prioritization. The supplied article notes that historical logs can distinguish temporary incidents from continuing infrastructure problems and can show crawler behavior before and after migrations. A recurring issue affecting an important section deserves different treatment from a short-lived anomaly with no continuing impact.
Teams should also avoid treating crawl volume as a ranking metric. The defensible conclusion is that logs reveal access and response behavior; broader SEO evidence is still needed to explain indexation or search performance. Used this way, retained logs become an ongoing observability layer that can make the next deployment or migration easier to evaluate.
Your automated PPC campaign can hit its platform target and still be bad for the business. If accidental clicks, weak leads or low-margin sales count as success, the system will pursue more of them with impressive efficiency.
The fix isn’t constant bid tinkering. You need to improve the signals, values and boundaries that shape each decision. Use the framework below to diagnose an underperforming campaign and give its automation a better problem to solve.
Start with the question the bidding system must answer
AI-driven PPC changes your job from controlling every keyword and bid to designing the inputs that guide the system. That starts with a clear business objective. “Get more conversions” is not clear enough when a form submission, qualified opportunity and completed sale have very different value.
Write the campaign objective as a decision the system can repeatedly make: find additional qualified demo requests within an acceptable acquisition cost, sell available products while protecting margin, or reach relevant prospects without allowing low-quality inventory to consume the budget.
Name one primary outcome. Choose the action that best represents business success, not merely the event that is easiest to track.
Define what counts. State the conditions that distinguish a useful lead, order or visit from an irrelevant one.
Assign value where outcomes differ. Reflect meaningful differences in revenue, margin, lead quality or customer value instead of treating every conversion as equal.
Select the matching bidding objective. Target CPA makes sense when qualifying outcomes have comparable value. Target ROAS needs values that reliably represent what the business gains.
Record the guardrails. Note brand restrictions, excluded inventory, geographic limits, inventory constraints and any claims the ads must not make.
Then apply a blunt test: if the campaign doubled the primary conversion tomorrow, would the business be pleased with every additional result? If the answer is no, repair the definition before asking automation to scale it.
Make conversion data harder to fool
Smart Bidding can only learn from the events you send back. A thank-you page that fires twice, a spam form submission or a low-intent micro-conversion can teach the system that poor traffic is desirable. More data does not compensate for the wrong data.
Audit every conversion action included in bidding. For each one, answer these questions:
Does this event represent a business outcome or only progress toward one?
Can duplicate, accidental, internal or fraudulent activity trigger it?
Does the platform receive any later signal about lead qualification, completed purchases or cancellations?
Does its assigned value reflect revenue alone, or the economic measure the campaign is meant to improve?
Would you intentionally buy more of this exact action at the target cost?
Keep primary and diagnostic signals distinct. A brochure view or form start can help you understand the journey without carrying the same bidding weight as a qualified lead. When the buying cycle continues beyond the website, connect later outcomes back to the original ad interaction where your measurement setup permits it. That gives the system evidence about customer quality rather than just form completion.
Value design matters just as much. If two products generate the same revenue but have very different margins, revenue-only values can push spend toward the less profitable sale. The same problem appears in lead generation when every inquiry receives equal credit even though only some become viable opportunities.
Do not start by changing the bid target when reported performance and commercial results disagree. First verify the event, its deduplication, its value and the feedback coming from downstream systems. A bidding adjustment cannot correct a broken definition of success.
Use exclusions as signal control, not just brand protection
Placement exclusions still protect your brand, but they also protect the learning process. Display inventory that produces cheap clicks, accidental taps or automated traffic can create attractive engagement metrics without producing useful outcomes. Strategic exclusions help prevent those interactions from distorting the signals used for optimization.
Review placements by business result, not click-through rate alone. Start with the inventory consuming meaningful spend, then inspect conversion quality, downstream lead status and the context in which the ad appeared.
Remove clear contamination. Exclude malicious, bot-heavy or obviously irrelevant placements as soon as you can identify them.
Question high-click, low-outcome inventory. A placement producing many interactions but no useful commercial result may be training the campaign toward cheap activity.
Treat mobile apps intentionally. If app inventory is not part of the campaign strategy, exclude it rather than allowing accidental taps to become a hidden acquisition channel.
Match exclusions to the objective. A reputable broad-reach placement may suit awareness while being too expensive or unfocused for direct response.
Keep an audit trail. Record why each exclusion was added so that a temporary performance decision does not become an unexplained permanent rule.
Avoid building a blocklist simply because a placement has not converted yet. Sparse data can make normal variation look conclusive, and indiscriminate exclusions can remove useful reach. Look for a defensible reason: irrelevant context, suspicious interaction patterns, poor downstream quality or economics that conflict with the campaign objective.
Apply obvious safety and quality exclusions before launch when possible. During the learning phase, early low-quality traffic does more than spend money; it gives the system examples of the behavior it should seek. Clean boundaries let automation explore without making every corner of the network equally eligible.
Operate automation through inputs, budgets and diagnosis
Give audience and query expansion a useful starting point
Broad match, keywordless targeting, URL expansion and audience signals can uncover demand that a fixed keyword list misses. They are discovery tools, not substitutes for positioning. Supply accurate first-party audience data where available, keep landing pages tightly aligned with the offer, and review the new queries and destinations the system finds.
Judge expansion by the quality of the resulting customers. If volume rises while lead quality falls, inspect the newly reached queries, audiences, placements and pages before constraining the entire campaign. You are trying to locate the weak input, not eliminate discovery.
Write a brief that automation can use
When AI assembles or adapts ads, your brief becomes part of campaign control. Include the intended audience, the problem being solved, the offer, approved proof points, brand tone, required qualifications and prohibited claims. Specify which landing page supports each promise.
Product campaigns also depend on feed quality. Make sure product names, attributes, availability and other business data describe what can actually be bought. A bidding system cannot recover from an ambiguous feed or an ad promise that the destination page fails to support.
Build budgets around business constraints
Set budget architecture with margin, inventory, lifetime value, cash flow and growth priorities in view. Daily spend is an output of that structure, not the strategy itself. Use missed-opportunity reporting to distinguish a campaign constrained by budget from one constrained by demand, eligibility or weak inputs.
Before increasing budget, ask whether the next unit of spend is likely to produce an outcome the business wants. Before reducing it, ask whether the campaign is genuinely inefficient or simply being judged against incomplete conversion data. Budget changes amplify whatever signal architecture is already in place.
Diagnose the symptom before changing the target
Conversion volume rises but quality falls: inspect spam, placement mix, query expansion and the definition of the primary conversion.
CPA looks healthy but profit falls: check conversion values, product margin, cancellations and which outcomes receive bidding credit.
Traffic grows but conversions do not: compare the ad promise with the landing page, then review newly reached queries, audiences and placements.
Volume remains limited: verify tracking first, then examine eligibility, exclusions, budget constraints and available demand.
Brand representation drifts: strengthen the creative brief, approved claims and destination mapping before broadly restricting delivery.
Change the input closest to the diagnosed problem. If you alter the conversion setup, exclusions, creative, budget and bid target at once, you lose the ability to tell which intervention helped. Keep a decision log that records the symptom, evidence, change and expected business effect.
Key takeaways
AI-driven PPC improves when you define a valuable outcome clearly enough for the system to recognize and pursue it.
Clean conversion events and realistic values matter more than feeding the platform the largest possible volume of signals.
Placement exclusions can protect both brand safety and the quality of campaign learning.
Audience expansion, feeds and AI-generated creative need accurate starting inputs plus human review of the results.
Diagnose tracking, traffic quality and economics before responding to weak performance with a bid or budget change.
For your next optimization session, choose one campaign and audit its primary conversion, assigned value and highest-spend placements. Fix the clearest signal problem first, document the change, and let the next decision follow from business results rather than platform activity alone.
If you manage bot access at a CDN, firewall, reverse proxy, or application layer, Google Web Bot Auth presents an awkward decision: prepare for stronger bot identity without blocking legitimate traffic that does not yet use it.
The safe approach is to add Web Bot Auth as a new verification signal, not replace your existing controls. You can then learn from signed requests, distinguish authentication from permission, and tighten access only when coverage is reliable enough for the agents and routes you care about.
What Web Bot Auth actually changes
A user-agent string tells you what a requester claims to be. IP and reverse-DNS checks can associate a request with known infrastructure. Neither gives you the same kind of identity evidence as a cryptographically signed request.
Web Bot Auth is an experimental cryptographic protocol that lets participating bots sign requests. A compatible verifier can use that proof to determine whether the request came from the claimed agent rather than trusting a label that another client could copy.
Signal
What it tells you
How to use it now
User-agent string
The identity a requester claims
Keep it as classification context, not proof by itself
IP and reverse DNS
Whether the request is associated with expected network infrastructure
Keep using these checks during the limited rollout
Web Bot Auth
Whether a participating agent supplied valid cryptographic identity proof
Add it as a stronger signal where verification is supported
This is an authentication improvement, not a complete bot-management policy. A valid signature can help establish who sent a request. It does not decide whether that agent may crawl a page, use an expensive endpoint, access licensed material, or bypass rate limits. Those are authorization decisions that remain yours.
That distinction prevents the most dangerous implementation mistake: treating “authentic” as a synonym for “allowed.” A verified agent can still request a route your policy excludes. An unsigned agent may still be legitimate while adoption remains partial.
Why Web Bot Auth must remain an additional signal
Web Bot Auth is in a limited test involving some AI agents hosted on Google infrastructure. Not every Google user agent uses it, and Google is not signing every bot request. Requiring a valid Web Bot Auth result across your site would therefore turn incomplete deployment into an access-control failure.
In practice, the absence of a signature has three possible meanings: the requester is not participating, a participating agent did not sign that request, or the requester is not what it claims to be. The rollout does not yet let you collapse those cases into “fraudulent.” Keep IP, reverse-DNS, and user-agent checks operating alongside the new protocol, as Google advises during gradual adoption.
Your internal classification should represent that uncertainty. A binary “Google bot” field is no longer enough. Use separate states such as:
Cryptographically verified: Web Bot Auth verification succeeded and resolved to an identity you recognize.
Legacy verified: the request passed your established network and identity checks but did not carry usable Web Bot Auth proof.
Unverified: the request supplied no acceptable proof and did not pass your legacy verification path.
Contradictory or failed: the claimed identity conflicts with your verification results, or supplied authentication material fails verification.
Do not silently translate “legacy verified” into “untrusted.” That would make a protocol coverage gap look like a security finding. Conversely, do not let a familiar user-agent string upgrade an unverified request into a trusted one.
Failed proof deserves more scrutiny than absent proof. An unsigned request may simply sit outside the test. A request that presents authentication material but cannot be validated has actively failed the verification path. Your system should preserve that distinction for policy decisions and incident review.
A safe adoption plan for your edge and application stack
You do not need to redesign every bot rule at once. Start by separating verification from enforcement, then introduce the new result in stages.
Map the current decision path. Identify where user-agent checks, IP rules, reverse-DNS verification, rate limits, robots directives, and application permissions affect a request. Note whether the decisive action happens at the CDN, firewall, reverse proxy, application, or more than one layer.
Define the verdicts before integrating them. Decide how your system will represent valid, absent, failed, unsupported, and indeterminate Web Bot Auth outcomes. Do not force these states into one Boolean field.
Add verification without changing access. In the first phase, calculate and log the Web Bot Auth result while preserving existing allow, limit, challenge, and deny behavior. This gives you evidence about real coverage without risking accidental exclusions.
Compare signals. Review requests that claim the same agent identity but produce different network and cryptographic results. Investigate disagreements before using the new signal to make blocking decisions.
Introduce graded enforcement. Prefer lower-risk actions, such as applying ordinary rate limits to unverified automation, before making a signature mandatory. Reserve strict requirements for routes where you have confirmed support and where the cost of unauthorized access justifies the tighter rule.
Keep a rollback path. Authentication failures should be visible, attributable to a specific policy, and reversible without redeploying unrelated application code.
Place verification where request data can be inspected before an irreversible allow-or-deny decision. That may be at the edge in one architecture and inside a trusted gateway in another. Do not assume your CDN, security plugin, or bot-management service supports the protocol merely because it can read headers. Cryptographic verification requires a compatible implementation and a defined trust process.
Before enabling enforcement, make the implementer answer the operational questions that matter for any signed-request system: What parts of the request are covered? How is the signing identity trusted? How are invalid, stale, or unverifiable proofs handled? How does verification behave during key or service changes? Which failure mode applies if the verifier is unavailable? If your stack cannot answer those questions, keep the integration in observation mode.
Your logs should store conclusions that operators can use, not just a dump of unfamiliar authentication data. Useful fields include the claimed user agent, legacy-verification result, Web Bot Auth result, resolved identity, requested route, policy action, response status, and the component that made the decision. Apply your normal security, privacy, and retention rules to those records.
Build AI-agent access rules around identity and purpose
Once you can verify an agent, resist the urge to create a single global allowlist. Public articles, resource-intensive APIs, account pages, and licensed datasets do not have the same risk or purpose. The identity result should feed a route-specific policy.
Verified identity plus permitted route: allow the request under the limits assigned to that agent and content class.
Verified identity plus prohibited route: deny it. Authentication does not override the route policy.
No Web Bot Auth proof plus successful legacy verification: continue the established bot policy while coverage remains incomplete.
Claimed known identity plus failed verification: treat the request as untrusted and preserve the failed result for investigation.
Unknown automation: apply your general unknown-bot controls rather than granting access based on a recognizable name.
Private or account-bound routes still need their ordinary application authentication and authorization. Bot identity proof is not a substitute for a user session, API credential, subscription entitlement, or content license.
The same separation applies to robots instructions and other content-use rules. Web Bot Auth can help determine which agent is asking. Your published directives and internal access policy determine what that identity may receive. Keep those systems aligned, but do not merge them conceptually.
For SEO, AEO, and GEO teams, the immediate benefit is cleaner observability rather than a promised visibility gain. Nothing in the limited rollout establishes Web Bot Auth as a ranking, citation, or inclusion mechanism. Do not change canonical tags, structured data, content architecture, or indexation rules merely because signed bot requests appear in your logs.
Use the stronger identity signal to answer narrower operational questions: Which verified agents request your content? Which sections do they reach? What status codes do they receive? Where do rate limits or access rules interrupt them? How often does a claimed identity match a verified identity?
Do not label a verified crawl as an AI citation, recommendation, or referral. A request proves an interaction with a URL, not what an agent later generated for a user. Keep server-side agent activity separate from user referral traffic and from any evidence that your brand appeared in an AI answer.
Key takeaways and your next move
Web Bot Auth adds cryptographic identity evidence to participating bot requests.
The protocol remains experimental and is being tested with only some AI agents on Google infrastructure.
Not every Google user agent or request is signed, so missing proof is not proof of impersonation.
Keep user-agent, IP, and reverse-DNS verification running alongside Web Bot Auth during the rollout.
Authentication establishes identity; your route, content, and rate-limit policies still decide permission.
Use verified requests to improve bot observability, but do not treat a crawl as evidence of an AI citation or ranking benefit.
Your next move is concrete: map the component that currently decides whether a bot request is allowed, add a multi-state Web Bot Auth verdict to that path, and run it without enforcement first. Preserve your existing controls until signed-request coverage is confirmed for the exact agents and routes you intend to govern.
That design lets you benefit as adoption expands without making today’s legitimate unsigned traffic pay for tomorrow’s authentication model.
Your analytics dashboard may show a human arriving at checkout while missing the machine that found the product, compared the options, and initiated the journey. It may also show nothing at all when an agent completes an action without running your client-side analytics code.
You can close that gap, but not with a new referral channel alone. Reliable AI agent attribution starts in server and CDN logs, continues through first-party action events, and ends with an attribution model that distinguishes direct execution from assistance and unlinked automation.
Key takeaways
Measure AI agents at the HTTP request layer. A request that does not execute your analytics script cannot create a normal browser event.
Separate training crawlers, real-time retrieval systems, and task-performing agents. They represent different intent and should not share one conversion rate.
Do not trust a user-agent string by itself. Combine it with published network information, request behavior, authentication state, and your own event data.
Use distinct attribution states for agent-executed, agent-assisted, discovery-only, and unresolved activity. Do not force uncertain traffic into a conversion channel.
Instrument forms, account actions, carts, and orders on the server. Page requests show access; confirmed business events show outcomes.
Classify traffic by the job the machine is doing
An automated request is not automatically a prospective customer. A model-training crawler collecting material, an answer engine retrieving a current page, and an agent submitting a form can all request the same URL. Their commercial meaning is entirely different.
This distinction matters because machine activity is growing faster than human activity. HUMAN Security measured more than a quadrillion interactions from 2022 through 2025. In that dataset, automated traffic increased 23.5% in 2025 while human traffic increased 3.1%. AI-driven traffic rose 187%, and activity associated with AI agents and agentic browsers rose by nearly 8,000%. Those figures come from aggregated, anonymized customer data, so treat them as a market signal rather than a forecast for your site.
Traffic class
Likely job
What to measure
Attribution treatment
Training crawler
Collect content for later model development
Pages fetched, bytes served, crawl frequency, response status
Content access, not a visit or conversion
Real-time retriever or scraper
Fetch current information for an answer or comparison
Training crawlers still represented 67.5% of measured AI traffic, while real-time scrapers grew by nearly 600% in 2025. That mix explains why a large increase in AI-labelled requests does not necessarily produce leads or revenue. Start by assigning each request to a functional class; calculate commercial performance only for traffic capable of participating in a user journey.
Create at least two classification fields in your data: agent_type for the machine’s apparent job and verification_status for the strength of the identification. Keep the values independent. A request can look transactional while its claimed identity remains unverified.
Build an evidence chain from request to outcome
Attribution becomes credible when you can follow an agent from an incoming request to a server-confirmed action. A dashboard label such as “AI traffic” is not enough. You need a chain of evidence that survives redirects, browser changes, authentication, and the absence of JavaScript events.
Capture the request before classifying it
Preserve the raw evidence in your CDN, load balancer, or application logs before a bot filter removes it. For each relevant request, capture:
A UTC timestamp and a unique request ID.
The HTTP method, normalized route, response status, and response size.
The full user-agent value as received, plus the parser’s normalized result.
The source network information needed for verification.
Referrer and origin headers when present, without treating their absence as proof of anything.
Whether a first-party session was present or created.
A pseudonymous account or customer identifier when the request was legitimately authenticated.
The resulting application event, such as search performed, form accepted, cart updated, or order confirmed.
Do not log authorization headers, passwords, payment details, complete form bodies, or sensitive query-string values for the sake of attribution. Strip or tokenize sensitive fields before they reach the analytics store. The useful connection is between a request identifier and a confirmed event, not between a marketing report and a copy of the user’s private data.
Instrument the business action on the server
A page view tells you that an agent requested a page. It does not tell you that a form was accepted, an account changed, or a payment completed. Emit a first-party server-side event only after the application confirms the action.
Give that event its own ID and record the initiating request ID, event time, action type, outcome, and any internal transaction or lead identifier. If the event represents money, use the same finalized value your order system recognizes. Failed submissions and abandoned workflows belong in diagnostic reporting, not completed-conversion totals.
Make an agent-to-human handoff observable
Many useful agent journeys will not end inside the agent. The machine may find a product or prepare a configuration, then send the user into a browser to review, authenticate, or pay. Standard last-click attribution can give the browser all the credit because the earlier agent request had no ordinary campaign parameter or client-side session.
When you control the handoff, attach an opaque, first-party handoff token to the destination URL. The token should identify a journey record, not expose an email address, prompt, account number, or other personal data. Expire it, prevent it from granting access, and associate it with the eventual conversion only after your server validates it. If the user is already authenticated, an internal pseudonymous account key can provide the connection without placing identity in the URL.
If you cannot observe a deterministic handoff, do not manufacture one from matching timestamps or similar page paths. You may analyze those patterns in aggregate, but label the result as discovery influence rather than an assisted conversion.
Recognize Google-Agent without weakening security
Google-Agent creates a useful distinction between continuous crawling and a request made while an AI system performs a user-initiated task. Google introduced it for agents hosted on its infrastructure, including experimental systems such as Project Mariner, and provided network ranges for desktop and mobile agent activity.
That identity gives you a better starting signal, not a substitute for authentication. User-agent strings are supplied by the requester and can be copied. Never allow an account action, bypass a challenge, or relax a security rule solely because a request calls itself Google-Agent.
Use confidence-based verification
Apply the same verification pattern to Google-Agent and any other named agent:
Match and preserve the claimed user-agent identity.
Compare the source with the provider’s published network information and keep that information current.
Check whether the request pattern is consistent with the claimed function, including the routes, methods, timing, and workflow sequence.
Record the result as verified, probable, or unverified rather than reducing all three states to a boolean bot flag.
Apply normal authorization, rate limiting, abuse detection, and transaction controls regardless of the identity label.
Review your CDN and web application firewall logs for named agents before changing any rule. Then test product search, detail pages, forms, sign-in, account functions, cart operations, and checkout with non-production accounts and non-chargeable test transactions where your systems support them.
Look for redirects that loop, challenges that cannot be completed, required state that disappears between requests, and successful browser screens backed by failed server actions. Keep intentional security denials in place. The goal is to remove accidental incompatibility, not to give automated clients a privileged route into sensitive workflows.
Report agent contribution without false precision
Your reporting should tell operators what happened and tell decision-makers how certain the attribution is. One blended “AI conversions” number cannot do both.
Use four mutually exclusive outcome states:
Agent-executed: A verified or explicitly qualified agent request is linked to a server-confirmed conversion that the agent performed.
Agent-assisted: An observable first-party handoff or authenticated journey connects agent activity to a later human conversion.
Discovery-only: An agent retrieved relevant content, but no deterministic connection to an individual outcome exists.
Unresolved automation: Automation was detected, but its identity, purpose, or relationship to an outcome remains uncertain.
Do not add agent-executed and agent-assisted credit if they describe two stages of the same conversion. Keep a deduplicated conversion ID, choose a primary status, and retain the touch sequence separately for analysis.
Your operational dashboard should cover three layers. The access layer needs request volume by agent type, verification state, route group, response status, and security disposition. The workflow layer needs starts, successful steps, failures, and confirmed completions for each key action. The business layer needs deduplicated leads, orders, revenue where applicable, and the four attribution states above.
Choose an assistance window that reflects your actual buying cycle and publish that rule beside the metric. There is no defensible universal window in the available evidence. A short handoff into checkout and a long enterprise evaluation should not inherit the same arbitrary assumption.
Establish the baseline even if named-agent volume is initially small. A rise in training access may affect infrastructure cost and content-control decisions without changing revenue. A rise in verified product-search and account activity deserves workflow testing. Repeated checkout attempts with no confirmed outcomes point to a technical or security investigation, not automatically to weak demand.
Start with one path that matters commercially: discovery, a product or service page, and its next meaningful action. Join the request logs to one server-confirmed outcome, preserve uncertainty as an explicit field, and make that narrow chain trustworthy before expanding it across the site. That gives you a measurement system you can extend as agents become more capable, without rewriting history around traffic you never truly identified.
If your SEO or AI workflow retrieves Reddit material from Google result pages rather than from reddit.com, you may be tempted to label it indirect public data and move on. The Reddit-SerpApi dispute shows why that shortcut is dangerous: the address you requested is only one part of the legal and operational analysis.
SerpApi is asking a federal court to dismiss Reddit’s amended complaint. Reddit alleges that large amounts of its content were extracted through Google Search. SerpApi counters that it accessed Google pages, that Reddit does not own most user posts, and that Reddit has not adequately established technical circumvention or concrete harm. Those are opposing positions, not judicial findings. Until the court rules, neither side’s argument gives your team permission to treat a similar pipeline as settled law.
Key takeaways
Fetching a Google result page instead of visiting Reddit directly changes the facts, but it does not automatically eliminate copyright or access-control questions.
Audit the actual payload. URLs, rankings, dates, short snippets, full comments, and complete threads create different copying and provenance issues.
Public visibility and technical circumvention are separate questions. A page can be publicly viewable while the collection method still encounters controls that demand legal review.
Content ownership and platform licensing are also separate. A user’s ownership of a post does not, by itself, prove that every third-party reuse is lawful.
Your safest immediate investment is traceability: retain acquisition routes, response fields, control events, transformations, retention rules, and downstream recipients for every dataset.
The dispute turns “scraping” into five separate questions
Calling a system a scraper tells you almost nothing about its legal posture. A useful review separates who holds rights, what was copied, where the response came from, how the collector reached it, and what harm is alleged. Mixing those questions is how a technical description such as “we only queried Google” gets mistaken for a legal conclusion.
Question
Disagreement in the case
What your team should preserve
Who holds rights in the material?
SerpApi relies on Reddit’s user arrangements to argue that users retain ownership and Reddit generally holds a non-exclusive license.
The creator, platform, applicable terms, asserted license, and rights basis for each collected field.
What exactly was copied?
SerpApi argues that the examples identified by Reddit include dates and short fragments that are not protectable expression.
Representative payloads showing whether you store metadata, snippets, comments, threads, media, or combinations of those fields.
Which system returned the data?
SerpApi says it accessed Google Search pages rather than interacting directly with Reddit.
Requested hosts, final URLs, redirects, response headers, collection jobs, and the origin assigned to each field.
Was a technical measure circumvented?
SerpApi says Reddit has not shown an encryption breach or authentication bypass and characterizes the pages it accessed as publicly available.
Authentication states, challenge pages, block responses, rate-limit events, bot defenses, retries, proxy changes, and any code intended to handle them.
What harm followed?
SerpApi argues that Reddit has not adequately pleaded tangible harm caused by its conduct.
Collection volume, retention, redistribution, customer access, substitution for the original service, incident reports, and takedown history.
Keep the five answers independent. If Reddit cannot establish ownership of particular user posts, that may weaken an ownership-dependent theory, but it does not prove that every use of those posts is lawful. If a date or fragment lacks enough expression to be copyrightable, that does not resolve how the system obtained it. If no access control was circumvented, that may answer one DMCA theory without answering every other issue raised by the collection and reuse.
The current procedural posture matters too. A motion to dismiss challenges whether the complaint states legally sufficient claims; it is not a factual finding that the challenged conduct was lawful. If the claims survive, that likewise means they can proceed, not that Reddit has already proved liability.
Why the Google layer is not a legal shield
An indirect pipeline has at least three layers: Google returns a search page, that page contains material derived from Reddit, and your system stores or republishes some part of the result. The host that returned the bytes is relevant, but it does not identify every party with an interest in the content or collection method.
Reddit’s allegation involving a decoy post created solely for Google’s crawler is important for that reason. Reddit uses the alleged appearance of that material to support its account of how the defendants acquired Reddit-derived content through Google. SerpApi answers that an ordinary user could see the same material in public search results. The court still has to decide whether Reddit’s allegations are legally sufficient and, if the case proceeds, what the evidence establishes.
There is also an upstream problem. Google separately alleges that SerpApi bypassed bot protections while scraping licensed search functionality. SerpApi has sought dismissal there as well, arguing that the DMCA is being used to restrict access to public search results. In practical terms, routing collection through a search engine may exchange one platform-access question for another rather than remove the question entirely.
For an SEO, AEO, or GEO system, review both sides of that route. First ask whether the collector was permitted to obtain the search response in the manner used. Then ask what rights and restrictions may follow the Reddit-derived material inside that response. Do not let a clean answer at one layer stand in for an answer at the other.
Run a field-level audit before expanding collection
Your lawyers cannot evaluate a label such as “SERP data,” and your engineers cannot implement advice framed only as “reduce scraping risk.” Give both groups a field-level map of the system. This is not a substitute for legal advice about your particular facts; it is the evidence package that makes useful advice possible.
Map the complete request path. Record the initial host, redirects, rendered page, APIs or browser automation involved, proxy layer, authentication state, and retry logic. Distinguish a request sent to Google from a later request sent to Reddit.
Define the collection unit. List every retained field: query, rank, result URL, title, date, snippet, author name, subreddit, comment text, thread text, media, and cached page. Do not describe a full-thread archive as metadata merely because the job began on a search page.
Attach provenance to each field. Store the page that supplied it, the underlying content platform when known, the collection time, and the transformation applied. A field should not lose its origin when it moves from raw storage into a feature table, embedding index, model corpus, or customer export.
Document the rights theory instead of assuming one. For each field, state why the organization believes it may collect, retain, transform, and distribute that material. Flag any theory that reduces to “it was public” for legal review.
Preserve control events. Log authentication prompts, denied responses, block pages, rate limits, bot challenges, and code changes made in response. Do not instruct a collector to evade a control while waiting for counsel to decide whether the control matters.
Trace every downstream use. Separate internal measurement from customer-facing display, bulk export, dataset resale, AI training, retrieval-augmented generation, and verbatim output. The same input can create a materially different question when the product begins returning the original text to other people.
Build deletion and shutdown paths. You should be able to stop one connector, one field, one customer export, or one corpus without taking the entire product offline. Also identify derived stores, such as embeddings and caches, that would otherwise survive deletion of the raw record.
The resulting audit record can be compact. For each collection job, capture the system owner, requested host, content origin, fields retained, controls encountered, asserted rights basis, retention period, downstream recipients, deletion path, and stop trigger. If your team cannot fill in one of those entries, mark it unknown rather than turning an assumption into policy.
Payload minimization is especially useful while the law remains contested. A rank-monitoring feature may need a result URL and position but not a permanent archive of every Reddit snippet. A citation feature may need a URL and a short display label but not the full discussion. An AI discovery tool may need topical signals while having no product reason to reproduce complete comments. Delete fields that do not support a named function, and stop collecting them at ingestion rather than relying only on later cleanup.
Be equally precise about AI use. “Used for AI” can mean measuring whether Reddit appears in search results, retrieving a passage at query time, generating embeddings, fine-tuning a model, or displaying source text beside an answer. Record those as distinct operations. Otherwise, a rights review performed for internal analytics can silently become the justification for a customer-facing content product it never evaluated.
Plan for the ruling without betting your product on it
A result for either side will be easy to overread. A dismissal based on Reddit’s ownership allegations would not necessarily approve every method of collecting Google results. A ruling focused on short, unprotectable fragments would not automatically cover full comments or threads. A conclusion that the alleged conduct did not amount to circumvention would depend on the controls and access path before the court, not on the generic fact that software performed the request.
A dismissal with prejudice would end Reddit’s claims against SerpApi in this instance. It would not function as a universal license for SERP scraping, Reddit reuse, or AI training. Conversely, if the amended complaint survives dismissal, that would allow the litigation to continue without establishing that every comparable SEO tool is unlawful.
You can make several product decisions now without predicting the winner:
Freeze expansion of any job whose access route, collected fields, or response to technical controls cannot be reconstructed.
Replace blanket claims such as “public data is safe to scrape” with a review that names the host, payload, controls, rights basis, and downstream use.
Separate collection modules by platform and field so one disputed input can be disabled without breaking unrelated search intelligence.
Require approval before an internal dataset becomes a customer export, training corpus, or feature that displays source language.
Give legal and engineering owners the same incident trigger: a new block mechanism, authentication requirement, complaint, takedown request, or material change in collection volume should reopen the review.
Preserve enough technical history to explain what the system did before a dispute begins. Reconstructing access behavior after logs have expired leaves both counsel and engineers working from memory.
Your immediate job is not to decide whether Reddit or SerpApi will win. It is to make your own pipeline explainable and stoppable. If you cannot identify who returned the data, who created it, what you retained, which controls you encountered, and where the material went next, pause the expansion and complete that map first.
Your CRM has identified an apparent ideal customer. This person opens almost every email, checks products repeatedly, moves between devices, and redeems offers with remarkable timing. The activity is real enough to enter your dashboards, but it may not belong to one person or represent the intent your models assign to it.
Before you increase bids, trigger a high-value nurture sequence, or extend another promotion, you need to know whether you are acting on a coherent customer or a marketing data doppelganger. The practical fix is not another round of duplicate removal. It is an identity-confidence system that separates observed activity from actor, intent, and customer identity.
What your apparently complete customer profile may be hiding
A marketing data doppelganger is a customer profile that looks internally valid but does not map cleanly to one actor. Its email may be deliverable. Its clicks may have occurred. Its purchases may be legitimate. The error appears when your systems treat all those events as evidence about the same individual.
This problem has two main identity patterns:
Convergence: Multiple people or systems are folded into one profile. A shared login, forwarded corporate alias, recycled email address, AI assistant, and human account holder can all contribute activity that appears to come from one customer.
Fragmentation: One customer is distributed across multiple profiles. Alternate email addresses, several devices, subscription accounts, loyalty records, and repeated new-customer registrations can make one person look like several unrelated prospects.
Use three separate questions whenever a profile drives a decision:
Identity: Which customer, account, household, or organization do we believe this activity belongs to?
Actor: Was the event produced by a person, an authorized assistant, an email client, an automated workflow, a shared user, or an unknown process?
Intent: What does the event actually establish: message delivery, monitoring, consideration, authorization, or a completed commercial outcome?
Those answers are not interchangeable. A deliverable email establishes that a destination can receive mail; it does not establish that one enduring person controls it. A completed order establishes a commercial outcome; it does not prove that the payer, shopper, recipient, and account user were the same person.
Observed pattern
Possible doppelganger mechanism
Decision at risk
Frequent opens with little subsequent activity
Email prefetching or AI summarization
Lead scores, send frequency, and engagement segments
Repeated product checks at unusually precise intervals
Price-monitoring or shopping automation
Retargeting intensity and inferred purchase urgency
Contrasting preferences under one address
Shared credentials, a forwarding alias, or a recycled address
Personalization and customer lifetime analysis
Several apparently new profiles with related account behavior
One customer using alternate identifiers
Acquisition reporting and promotion eligibility
A customer journey spread across disconnected devices or accounts
Identity fragmentation
Attribution, suppression, retention, and forecasting
The important correction is simple: valid events do not guarantee a valid person-level interpretation. Your job is to preserve what was observed while reducing confidence in conclusions the evidence cannot support.
Audit the marketing decision before cleaning the database
A database-wide identity project can become expensive and abstract before it changes a single campaign. Start with one consequential decision: a lead score, promotion rule, churn prediction, retargeting audience, acquisition report, or budget forecast. Then work backward to the identity assumptions that make the decision possible.
Write the claim behind the decision. A high-engagement segment may depend on the claim that repeated opens and product views represent increasing interest from one person. A new-customer discount may depend on the claim that one profile represents one previously unseen customer. State that claim plainly.
List the events that support the claim. Separate email opens, clicks, page views, form submissions, account activity, promotion redemptions, and transactions. Do not collapse them into a single engagement total during the audit.
Recover event provenance. For each event, retain the event time, collection source, profile and account identifiers, campaign, session or device identifier where permitted, related transaction or promotion, automation marker, and downstream outcome. A missing provenance field is an audit finding, not permission to assume a human acted.
Classify the likely actor. Use practical states such as human-confirmed, delegated or agent-assisted, platform-generated, shared or ambiguous, and unknown. Preserve unknown as a real category. Treating unknown as human simply hides the uncertainty.
Look for convergence and fragmentation. Search for abrupt cross-device activity, mutually inconsistent preferences, shared or reassigned contact points, automated monitoring patterns, and apparently new profiles connected to established activity. Each pattern is a reason to investigate, not proof of abuse.
Run a counterfactual version of the decision. Recalculate the segment, score, attribution result, or forecast after excluding events with uncertain actor provenance. Then consolidate likely fragments where you have defensible evidence. If the decision changes materially, it depends on identity assumptions that need to be exposed.
Record the operational consequence. Note whether the uncertainty can waste media, increase message frequency, distort attribution, issue duplicate benefits, suppress a legitimate customer, or create unnecessary checkout friction. This converts identity quality from a data-cleaning concern into a prioritized business risk.
Do not delete ambiguous events. Preserve the raw observation and change its interpretation. Deletion destroys evidence you may need for attribution, troubleshooting, or future validation. Classification lets you ask better questions without pretending uncertain data never existed.
Replace the golden record with an evidence-backed confidence record
The traditional golden record promises one definitive profile assembled from every available identifier. That model becomes brittle when one person can produce several identities and several actors can produce events under one identity. A larger merged profile can look more complete while becoming less coherent.
Use a confidence record instead. It should not merely declare that two records match. It should explain why your organization currently considers a profile stable enough for a particular use.
Evaluate identity confidence across these dimensions:
Identifier continuity: Are the account and contact identifiers stable over time, or do they show signs of reassignment, sharing, or frequent substitution?
Behavioral coherence: Can the activity plausibly belong to the same customer context, or does it contain conflicting needs, abrupt channel changes, and overlapping journeys?
Actor provenance: Can you distinguish explicit customer actions from platform processing, delegated agent activity, autofill, and unknown automation?
Commercial continuity: Do account history, offer use, and completed outcomes support the same customer relationship, or do they reveal fragmentation or convergence?
Ambiguity burden: How much of the profile’s apparent value depends on events whose actor or meaning cannot be established?
A practical profile record can store an identity state, actor state, confidence band, supporting evidence, contradictory evidence, last validation trigger, and permitted uses. For example, the identity state might be stable, fragmented, composite, or unknown. The actor state might be human, delegated, platform-generated, shared, mixed, or unknown.
Use confidence bands with reason codes before reaching for a precise score. A numerical score can create false certainty if nobody can explain what moved it. A band such as high, conditional, or low is useful when it is attached to evidence and an allowed decision:
High confidence: The available evidence is coherent and sufficiently attributable for the named use. This does not mean every event came directly from a human.
Conditional confidence: The profile contains stable evidence, but shared, delegated, or fragmented activity limits some uses. It may be suitable for service communication while remaining unsuitable as clean training data for an intent model.
Low confidence: The profile depends heavily on weak identifiers, unknown event provenance, or contradictory activity. Use it cautiously and avoid expensive personalization or irreversible risk decisions based on it alone.
Confidence must be use-specific. The evidence required to send a general newsletter is not the same as the evidence required to grant a one-time benefit, block an order, label a person as a high-value customer, or train a predictive model. A universal identity score hides those differences.
Identity confidence is not a reason to collect every possible identifier. Use permitted data with a clear purpose, retain provenance, and avoid treating invasive surveillance as a substitute for coherent evidence. Better validation should make your interpretation more disciplined, not make your collection indiscriminate.
Change campaign, attribution, and risk decisions at the same time
An identity audit has little value if every downstream system continues treating all events as equal. Carry the confidence state into activation, reporting, modeling, and revenue protection.
Separate activity, human intent, and identity confidence
Replace a single engagement score with distinct measures. Observed activity records what happened. Intent classification describes what the event can reasonably imply. Identity confidence describes how safely the behavior can be attached to the profile.
Treat prefetches and automated message processing as delivery or machine-processing evidence, not direct proof of interest.
Classify agent-based comparison and price monitoring as delegated activity. It may represent customer interest, but it should remain distinguishable from a human browsing session.
Give coherent downstream actions more decision weight than isolated high-volume signals, while retaining uncertainty about who performed them.
Prevent low-confidence profiles from automatically entering expensive personalization, aggressive retargeting, or high-priority sales queues.
This structure lets a campaign acknowledge useful agent activity without pretending that every machine event is a human signal.
Show the reported result beside an identity-quality view. Track the share of events with unknown actors, conversions attached to composite or fragmented profiles, and the sensitivity of channel credit when automated events are removed. You do not need to invent a confidence-adjusted revenue figure if your evidence cannot support one. Showing the uncertainty is more useful than concealing it behind a new calculation.
Keep unstable identities from becoming model ground truth
A model trained to equate automated opens with customer interest will seek more people who produce the same distorted pattern. Campaigns then generate additional machine activity, which returns as apparent proof that the model was right. This is how an identity problem becomes a performance feedback loop.
Attach identity and actor labels before training. Depending on the model and decision, filter unstable profiles, reduce their training weight, or retain them as a separately labeled population. Evaluate performance by confidence band as well as in aggregate. If a model performs well only where identity is ambiguous, inspect what it has actually learned before expanding its use.
Distinguish delegated assistance from promotional abuse
An AI assistant acting for a customer is not, by itself, evidence of fraud. Shared accounts are not automatically abusive either. Blocking every ambiguous profile adds friction for legitimate customers, while permissive rules can allow one person to appear repeatedly as a new customer.
Escalate controls when low identity confidence coincides with an economic action and contradictory account history. Do not make an agent marker the sole reason for a block. Use proportionate checks, preserve the reason for the decision, and provide a review path when a legitimate customer may have been caught by the control.
Give each team an explicit responsibility
Identity confidence fails when it belongs only to the data team. Assign ownership at the point where interpretation becomes action:
Marketing operations preserves event provenance and exposes confidence fields to campaign tools.
Analytics reports identity uncertainty and tests how sensitive conclusions are to ambiguous events.
Lifecycle and sales teams define which confidence bands may enter each journey or priority queue.
Model owners document which identity states are accepted as labels and evaluate performance across those states.
Risk and commerce teams define when an ambiguous identity warrants additional validation rather than automatic denial.
Begin with the decision that has the clearest cost when identity is wrong. Rewrite its event rules, add actor and confidence fields, rerun the decision under alternative inclusion rules, and document what changes. Once that loop works, extend the same method to the next campaign, model, or control. You will improve trust faster by validating consequential decisions one at a time than by declaring the entire customer database clean.
Key takeaways
A marketing data doppelganger is a coherent-looking profile whose events do not reliably represent one actor or one customer’s intent.
The problem includes both convergence, where several actors appear as one profile, and fragmentation, where one customer appears as several profiles.
Preserve the distinction between identity, actor, and intent. A valid event does not make every person-level inference valid.
Audit one costly decision first, recover event provenance, classify uncertain actors, and rerun the decision without ambiguous signals.
Replace binary identity matches with explainable, use-specific confidence bands supported by evidence and contradiction records.
Carry identity confidence into segmentation, attribution, model training, promotion controls, and reporting so the same uncertainty is not lost downstream.
Your next step is to choose one segment, score, or promotion rule that would hurt if the customer identity were wrong. Find the weakest event it relies on and make that uncertainty visible. That small change gives you a defensible starting point for rebuilding trust in the rest of your marketing data.
If your rank tracker, competitive dashboard, or AI-search monitoring workflow depends on a SERP API, the Google-SerpApi dispute is not remote legal theater. It is a data-supply-chain issue: an upstream collection method could affect the coverage, cadence, cost, and reliability of the measurements you use.
That does not mean your tools are about to stop working. SerpApi has asked a court to dismiss Google’s claims, and the competing positions have not been resolved. Your practical job is to identify where scraped Google data enters your operation, separate collection failures from real search changes, and prepare a fallback before either problem reaches a client report or automated decision.
Key takeaways
A motion to dismiss is not a ruling that SerpApi acted lawfully, and allowing Google’s claims to proceed would not prove that Google is right.
The central dispute is whether the DMCA can apply when a service accesses public, no-login search pages while overcoming Google’s anti-bot controls.
A court ruling could influence the risk, availability, and economics of third-party SERP collection, but it will not answer every legal question about scraping.
SEO and GEO teams should treat this as a vendor-dependency issue now: document data lineage, preserve methodology metadata, define validation checks, and build replacement paths for critical reports.
The dispute turns on access, protection, and reuse
SerpApi answers that it collects the same public-facing information a person can see without authentication. It says it does not decrypt a protected system or breach a login barrier. It also argues that Google does not own much of the underlying material displayed in its results and is trying to use the Digital Millennium Copyright Act to protect its platform and advertising interests rather than copyrighted works.
That creates three questions that are easy to collapse into one:
Who owns the material? Google may display text, images, and facts originating elsewhere, but the ownership analysis can differ by element and license.
What do the technical controls protect? Google’s theory connects its anti-bot systems to protected Search content. SerpApi’s theory is that controls serving platform or advertising interests do not become copyright-protection measures merely because they obstruct automated access.
What is being done with the collected data? Viewing a public page, collecting it automatically, operating at scale, and reselling the resulting dataset are different activities. A conclusion about one does not automatically resolve the others.
SerpApi invokes hiQ v. LinkedIn and Impression Products v. Lexmark to support its position that technical barriers should not let a platform monopolize public-facing information. Those precedents are part of SerpApi’s argument; they do not predetermine how the court will characterize Google’s systems, the material displayed in Search, or SerpApi’s conduct.
The procedural posture matters just as much. A motion to dismiss generally tests whether pleaded legal claims can go forward. It is not a full trial of disputed facts. If the motion succeeds, you must still read which claims were dismissed and on what grounds. If it fails, Google has cleared a procedural threshold, not won the lawsuit.
Do not mistake the widely repeated $7.06 trillion figure for a judgment, settlement demand, or likely damages award. It is SerpApi’s theoretical calculation of potential penalties under Google’s interpretation of the DMCA. It illustrates how expansive SerpApi believes that interpretation could become; it does not predict the financial outcome.
Each possible outcome has narrower meaning than the headline
The unhelpful way to read this dispute is as a referendum on whether public data is always free to scrape. The useful way is to ask what a particular ruling establishes, which legal claim it addresses, and which operational assumptions it puts under pressure.
If the motion is granted: the challenged claims may be legally insufficient in their pleaded form. That would support SerpApi’s defense, but it would not create a universal license to scrape any public website for any purpose.
If the motion is denied: Google’s claims may proceed into later stages. That would not be a finding that every allegation is true or that all automated collection from public pages violates the DMCA.
If Google ultimately prevails on its anti-circumvention theory: providers using similar collection methods could face greater legal and technical pressure. Customers might experience narrower feature coverage, higher costs, slower collection, provider consolidation, or abrupt service changes.
If SerpApi ultimately prevails: the result could strengthen the position that access to public, no-login search results cannot be restricted through the DMCA theory Google advances here. Separate questions involving contracts, content rights, licenses, misrepresentation, or other causes of action would still depend on their own facts and law.
The pressure also extends beyond one search platform. Reddit filed claims against SerpApi and others in October 2022, alleging indirect collection through Google Search, concealed identities, and industrial-scale activity. That broader conflict is a warning for data buyers: a provider can face objections from the platform being queried, the owners of material appearing in results, or both.
For planning purposes, classify the case as unresolved upstream risk. Do not describe scraping as definitively lawful because the pages are public. Do not tell stakeholders that all third-party SERP APIs are unlawful because Google filed a complaint. Neither statement follows from the current procedural stage.
Your measurement can fail before the legal question is settled
SEO teams rarely consume scraping infrastructure directly. They see a rank, a feature flag, a competitor count, a screenshot, or an AI-visibility score. That abstraction is convenient until the collection layer changes and the dashboard continues presenting its output as if the underlying observation were stable.
Four failure modes deserve explicit checks:
Coverage loss: a provider may stop returning a result type, location, device class, language, or page depth. A missing observation can then be misreported as a lost ranking or absent feature.
Sampling drift: stronger blocking can change which successful requests survive. Your trend line may compare two different samples even though the dashboard label has not changed.
Latency: retries and collection friction can make a supposedly current result older than expected. This matters when you are investigating a launch, algorithm change, reputation event, or volatile query.
Provider continuity: legal expense, infrastructure changes, or tighter access controls can alter pricing and service levels even before a final ruling.
The operational rule is simple: separate a market signal from a collector signal. A sudden loss of rankings across one geography may reflect Google Search, but it may also reflect an endpoint, parser, proxy pool, localization setting, or feature-classification change.
Preserve enough metadata to test that distinction. For every observation that can trigger a decision, retain the provider, collection time, requested location, language, device, result type, and methodology version where your agreement permits it. Store raw response evidence or a rendered capture when you are contractually and legally allowed to retain it. Treat an empty response as unknown until the system can distinguish a genuine absence from a failed collection.
For an owned website, Google Search Console can corroborate changes in impressions, clicks, and average position, but it cannot reproduce a live competitive SERP or explain every feature-level observation. A second data vendor may help, although two vendors can share similar collection dependencies. Manual checks on a small, predefined diagnostic query set provide another useful signal, provided they use consistent location, language, device, and personalization conditions.
The same discipline applies to AEO and GEO reporting. If a system derives an AI-search visibility score from Google result features, a missing mention may mean that the brand disappeared, that the feature was not collected, or that the parser stopped recognizing it. Keep the captured answer or result evidence separate from the calculated score. Never let a score of zero stand in for missing evidence.
When a major shift appears, ask three questions before changing content: Did the search experience change? Did the acquisition method change? Did the interpretation layer change? If you cannot answer all three, annotate the report and withhold automated recommendations until you have corroboration.
Audit your SERP-data dependency in six steps
Build a dependency register. List every rank tracker, SERP API, competitive-intelligence platform, AI-visibility product, internal script, and agency feed that observes Google results. Record the provider, endpoint, markets, device profiles, collection cadence, retention period, and downstream reports or automations.
Mark decisions, not just systems. Identify what happens when each field changes. A number viewed by an analyst is lower risk than a field that changes bids, rewrites briefs, triggers client alerts, evaluates staff, or publishes customer-facing claims. Give the highest scrutiny to inputs that cause action without human review.
Ask vendors method-specific questions. Find out which outputs depend on automated access to public Google pages; which use official or licensed interfaces; how the vendor distinguishes blocked requests from absent results; whether methodology changes are disclosed; what incident notices you receive; and how quickly you can export historical data. Request written answers for critical services.
Design a replacement by use case. Use first-party performance data for owned-site outcomes where it fits. For competitive rankings, define a smaller priority query set that can be checked through another method. For feature monitoring, preserve time-stamped evidence. For AI-search tracking, keep prompt, response, model or interface, location conditions, and scoring logic separable so one unavailable feed does not erase the whole record.
Add a collection circuit breaker. Set the reporting system to flag abrupt changes in response completeness, feature frequency, geography coverage, timestamps, or error rates. When the check fires, label the period as potentially incomplete, pause automated recommendations, and notify the people who consume the affected metric.
Escalate the right legal questions. If your organization directly operates scraping infrastructure, bypasses technical restrictions, resells SERP data, distributes licensed images or real-time content, or makes contractual promises about uninterrupted access, obtain advice from counsel familiar with copyright, the DMCA, data licensing, and relevant contracts. A general blog cannot determine the exposure of a particular implementation.
Your vendor review should also cover commercial concentration. Switching from one collector to another is not a complete fallback if both depend on materially similar access methods. Ask what can be replaced with first-party data, what can tolerate reduced frequency, what requires independent verification, and what has no realistic substitute. The last category needs an explicit owner and a documented decision about acceptable downtime.
Do not wait for a final judgment to run the test. Pick one business-critical SEO or AI-visibility report this week. Trace every external field to its acquisition method, mark the fields that cannot be independently verified, and simulate one reporting cycle with the primary feed unavailable. You will learn more from that exercise than from trying to predict the court.
When the next ruling arrives, read the claims and procedural grounds before changing policy. Until then, keep public visibility, technical access, content ownership, and commercial reuse as separate questions. That distinction will make both your legal review and your search measurement substantially more reliable.
If your rank tracking, share-of-voice reporting, or AI visibility workflow depends on automated Google results, SearchGuard can turn a routine data feed into a business-continuity problem. Collection may become incomplete or unavailable while the dashboards built on top of it continue to look authoritative.
Your immediate job is not to find a cleverer bypass. It is to identify which decisions depend on scraped search results, establish how each provider acquires them, and prevent missing observations from being misreported as ranking losses.
Why SearchGuard breaks the old scraper playbook
BotGuard, internally called Web Application Attestation or WAA, protects multiple Google services. SearchGuard is the Search-specific implementation. It is designed to distinguish a person using a browser from an automated script without relying on a traditional, visible CAPTCHA.
That distinction changes the failure model. A CAPTCHA is an obvious interruption. An invisible attestation system can evaluate the session while the interaction is happening. Loading a results page once therefore does not demonstrate that an automated collection method will remain stable at scale.
Start by separating three questions that teams often collapse into one:
Can the collector retrieve a page? This is a technical availability question.
Did it retrieve the complete observation you requested? This is a data-quality question.
Is the collection method authorized and legally defensible? This is a governance question.
A provider can answer yes to the first question while leaving the other two unresolved. Your dashboard should not treat technical success as proof of completeness, permission, or long-term reliability.
The signal stack goes beyond a single bot tell
The available technical detail comes from decrypted version 41 of BotGuard, the broader system behind the Search implementation. Treat it as a map of relevant signal classes, not a complete or permanent specification of every SearchGuard decision.
Mouse analysis can include path shape, speed, changes in acceleration, and small irregularities in movement.
Keyboard analysis can include intervals between keys, keypress duration, error sequences, and pauses after punctuation.
Scrolling and general timing can reveal whether actions contain natural, context-dependent variation rather than fixed automation intervals.
The important point is not that one straight mouse path or one regular pause proves automation. SearchGuard can assemble multiple observations into a broader behavioral profile. A vendor that talks only about imitating one visible action is addressing a much narrower problem than the system presents.
The browser environment is part of the evidence
The evaluation is not confined to pointer and keyboard events. BotGuard can use more than 100 HTML elements and browser-environment signals, including navigator properties, screen metrics, performance information, and interaction with browser APIs.
This is why a collector that produces a visually correct page can still be fragile. Rendering the right DOM is only one part of the session. The surrounding environment and the way it behaves can be evaluated as well.
Statistical profiling makes fixed emulation brittle
The protected bytecode virtual machine and cryptographic integrity measures add another layer of resistance to reverse engineering. A temporary workaround can therefore expire when code, challenges, expected behavior, or the scoring model changes.
Do not use this signal list as an evasion checklist. Use it to set the right expectations with engineering teams and vendors. A durable measurement program needs observability around collection, not just a promise that automation worked during a demo.
Key takeaways
SearchGuard is the Search-specific form of Google’s broader BotGuard or Web Application Attestation system.
It can combine behavioral, timing, browser-environment, and statistical signals instead of depending on a visible CAPTCHA.
A rendered results page does not, by itself, establish complete data, durable access, or authorization.
Attempts to bypass the system can create both technical fragility and legal exposure.
Your safest response is to audit data provenance, label collection failures correctly, and give every important workflow a fallback.
Audit vendors before enforcement becomes your outage
An allegation is not a final ruling, and it does not establish that every form of search-result collection is unlawful. SerpAPI’s CEO says Google did not contact the company before filing and characterizes the action as an attempt to restrain a service used by other innovators. That disagreement matters because the technical method, the rights involved, and the legal theory may all be contested.
It would still be a mistake to classify this as somebody else’s vendor dispute. If a provider intentionally circumvents a technological control, you may face service interruption, contract problems, replacement costs, and legal questions that an uptime report cannot answer. Have qualified counsel review your particular method and jurisdiction when circumvention is part of the collection chain.
Map the dependency. Record every report, alert, model, recommendation, and client deliverable that consumes automated Google results. Assign an owner to each one.
Document the complete collection chain. Ask who retrieves the results, whether subcontractors or resellers participate, and whether the provider collects directly or buys from another supplier.
Request the provider’s stated basis for access. Get the answer in writing. Browser automation describes a mechanism; it does not explain authorization, rights, or legal defensibility.
Define the requested observation. Record the query, requested context, expected fields, refresh cadence, and timestamp. Without that contract, you cannot distinguish a complete result from a plausible-looking fragment.
Require explicit failure semantics. The provider must distinguish a successful observation, an access failure, a partial response, and a reused cached response. A blank field is not an adequate status code.
Add commercial protections. Review incident-notification duties, subcontractor disclosure, data-quality commitments, termination rights, and the process for exporting your configurations if the feed becomes unavailable.
Choose the fallback before launch. Decide which workflows can use a manual sample or first-party performance data, which must pause, and which can proceed with a clearly displayed uncertainty warning.
Answers that should stop a launch
Do not let a data feed into consequential reporting if the provider:
will not identify the collector or disclose whether additional suppliers are involved;
uses the word compliant without identifying the scope, jurisdiction, contract, or other basis for that claim;
cannot distinguish blocked collection from a genuine absence in the search results;
does not attach collection time, freshness, and completeness metadata to observations;
treats repeated workaround deployment as its only continuity plan; or
cannot explain what happens to your history, configurations, and reporting when access fails.
None of these signs proves misconduct. Each one does prevent you from evaluating the reliability and exposure of a dependency that may influence budgets, content priorities, client reports, or executive decisions.
Build reporting that survives missing SERP data
The most damaging SearchGuard failure may not be an obvious outage. It may be a partial dataset that enters a trend line as though collection completed normally. Protect the decision layer by giving every observation an explicit state.
Data state
What it means
How reporting should behave
Observed
The requested collection completed and the expected fields passed validation.
Include it with its collection time and requested context.
Unavailable
The collector could not complete the request.
Report an availability gap. Never translate it into a ranking loss or absence.
Incomplete
Only part of the planned query set or expected response was obtained.
Show coverage and suppress aggregates that require the missing observations.
Stale
The workflow is reusing an older observation beyond the freshness allowed for that decision.
Display the original timestamp and exclude it from comparisons presented as current.
Your acceptable freshness and completeness thresholds should follow the decision cadence. A dataset may be adequate for a slow-moving planning exercise and inadequate for a report that triggers an immediate campaign change. Define that rule in the workflow instead of asking an analyst to make an improvised judgment after a failure.
Design around the decision, not maximum collection
Collect the smallest representative query set that supports the decision. More queries create more dependency without automatically improving the conclusion. Tie each segment of the set to a reporting or monitoring need.
Gate every aggregate on coverage. Store planned, completed, valid, incomplete, and unavailable observation counts. Do not publish a visibility change when the underlying comparison fails your predefined coverage rule.
Preserve provenance with the metric. Keep the provider, collection time, requested context, processing version, and data state attached through exports and dashboards. Retain raw material only where your rights, contract, and policies allow it.
Separate acquisition from analysis. Give the analysis layer a documented input format so an approved replacement feed, manual observation, or first-party dataset can be introduced without rebuilding every dashboard.
Use independent evidence for consequential changes. Before changing budget, content, or reporting because an external SERP metric moved, compare it with owned-site performance and manually inspect the high-impact queries where appropriate.
Write a stop rule. Specify which recommendation, alert, or report must be withheld when collection is unavailable, incomplete, or stale. Missing evidence should remain unknown; it should not silently become zero.
Start with the next search dashboard your team is scheduled to use. Trace every Google-derived field back to its collector, timestamp, completeness state, and fallback. If that chain cannot be explained, do not let the number silently drive the next decision.
Your Google Business Profile review count dropped. A few five-star reviews vanished, the average changed, or the numbers in your report no longer match the live listing. The wrong response is to rush out and replace the missing reviews before you know what happened.
Your first job is to separate an isolated disappearance from a repeatable moderation pattern. Once you can see which ratings, review ages, locations, and acquisition methods are involved, you can protect your local SEO reporting and correct the part of your review process that may be creating risk.
Key takeaways
Five-star reviews are not protected from removal. Positive reviews can receive especially close scrutiny in some industries and markets.
Do not assume only new reviews are at risk. Google can remove reviews months after publication, including older feedback that once appeared stable.
Track displayed review count, average rating, individual disappearances, and review age by location. A stable rounded average does not prove that nothing was deleted.
Pause incentives and audit how reviews are requested before launching a replacement campaign. More requests will not fix a collection process that keeps producing moderation risk.
A deleted review is not the same as a local ranking penalty
A review can disappear at the same time that local visibility changes, but that timing does not prove Google applied a manual penalty to the business. The immediate effects are narrower and easier to verify: the public review count changes, the displayed average may move, recent feedback may become thinner, and your historical reports stop matching the live profile.
Those changes still matter. Customers see a different reputation profile, while your SEO team may compare current performance with a review set that no longer exists. An analysis of 60,000 Google Business Profiles between January and July 2025 found that removals were becoming more common, with momentum increasing near the end of the first quarter. The pattern included five-star feedback, not just critical reviews.
Start with the arithmetic. If the count falls and the average falls, the removed set probably had a positive net effect on the rating. If the count falls and the average rises, lower-rated feedback was probably removed. If the count falls while the average appears unchanged, the missing reviews may be mixed, too small to change the rounded display, or offset by new reviews. These are diagnostic clues, not proof about any individual review.
Keep local visibility in a separate column from review movement. Annotate the date of a confirmed count change, but do not attribute every ranking fluctuation to it. Profile edits, competitor activity, demand, and other search changes can occur during the same period. Your review log should help you investigate correlation without turning it into an unsupported causal claim.
Use industry and location patterns to focus the audit
Your business category changes where you should look first. It does not determine why a particular review disappeared, but it can keep you from auditing the wrong slice of data. The observed deletion patterns differ by rating, age, sector, and country.
Business context
Observed deletion pattern
What to inspect first
Restaurants
Highest deletion activity among the sectors examined, with removals across star ratings
All ratings and both recent and older review cohorts
Home services
Greater scrutiny of five-star feedback, with many removals occurring within six months
Recent five-star reviews and the request method that generated them
Medical businesses
Fewer deletions than the highest-incidence sectors, but a noticeable bias toward five-star removals
Positive reviews from the previous six months and any coordinated solicitation campaign
Retail
Relatively high deletion activity, including older reviews
Historical cohorts as well as current acquisition
Construction
Among the sectors experiencing more deletion activity
The full review history until a location-specific pattern emerges
Do not combine every location into one company-wide total. A restaurant group, home-services network, or retailer can gain reviews overall while individual profiles lose them. Keep one record per Business Profile, then compare locations using the same fields and checking schedule.
Country-level differences also deserve their own view. Five-star reviews have faced more scrutiny in many English-speaking markets, while low-rated reviews in Germany have been removed more often soon after publication. The German pattern aligns with stronger legal pressure around defamation, whereas automated moderation appears more prominent in English-speaking markets. If a German review is connected to a legal complaint or threat, preserve the relevant records and obtain advice from qualified local counsel before treating the situation as a routine SEO issue.
Build a review log that exposes removals instead of hiding them
A displayed review count is a balance, not an acquisition total. If five new reviews appear while five older ones disappear, the count looks flat even though both customer activity and moderation occurred. You need a simple cohort log to see that movement.
Create a baseline for every profile. Record the check date, displayed review count, displayed average rating, and the newest visible reviews. Keep each location separate.
Check on the same day each week. Weekly monitoring is granular enough to catch the deletion activity that has been appearing across many profiles without confusing a long period of gains and losses.
Record newly visible and newly missing reviews. For each one, note the star rating and whether it was posted within the previous six months or belongs to an older cohort. Those two age groups are useful because recent removals are more prominent in medical and home services, while older removals appear more often in restaurants and retail.
Attach acquisition context. Note the date, channel, location, campaign, and whether any benefit was connected to the request. Include requests handled by staff, software, agencies, receipts, email, or in-location prompts.
Estimate removal volume. Subtract the net change in displayed review count from the number of newly observed reviews. Treat the result as an estimate when your checks may have missed reviews that appeared and disappeared between observations.
Annotate SEO performance separately. Record local visibility or conversion changes beside the deletion event, but preserve the distinction between events that occurred together and events you can show were causally connected.
The useful unit is the review cohort: feedback acquired through the same location, channel, and time period. If one cohort loses a disproportionate share of its five-star reviews while organically acquired feedback remains visible, you have a much sharper lead than a company-wide count decline.
You can also track a survival measure for each cohort: the number of originally observed reviews that remain visible after six months divided by the number originally observed. Keep acquisition and survival as separate metrics. One tells you whether customers are responding; the other tells you whether those reviews persist.
A single missing review rarely reveals the cause. It may reflect moderation or another change outside the business’s control. A cluster tied to one campaign, request channel, rating, or location is more actionable because it gives you a process to inspect.
Fix the acquisition process before replacing lost reviews
Google has increased enforcement against incentivized feedback, and automated systems are being used to identify suspicious activity. If a customer received a discount, free item, entry into a drawing, or another benefit for leaving a review, stop that workflow while you assess it. Do not assume that calling the benefit a thank-you removes the moderation risk.
Map each missing cohort back to the way the request was made. Review the audience, timing, wording, channel, and responsible vendor or team. If removals cluster around one method, pause that method instead of sending a larger campaign to compensate for the loss. A replacement burst can add more questionable activity before you have removed the original cause.
A lower-risk process is straightforward: connect the request to a real customer interaction, use neutral language, offer no benefit for posting, and let the customer write in their own words. Build review requests into an ordinary operating workflow so you are not dependent on occasional pushes designed to hit a target number.
If an agency or software provider manages acquisition, require a clear description of its methods. Your internal record should show which customers were contacted, when the request was sent, which channel was used, and whether the provider attached any incentive. A promise to deliver a certain number of positive reviews is not a substitute for that process evidence.
Do not focus only on the total count. Recent, detailed reviews remain important authority signals, while older feedback can still be re-evaluated and removed later. Your working dashboard should therefore show reviews received, reviews still visible, removals by star rating, removals by age, and removals by acquisition channel.
At your next weekly check, establish the baseline before asking for anything new. Then trace every active request path and remove any attached benefit. You cannot control every moderation decision, but you can make review losses measurable, keep your reporting honest, and build an acquisition process that does not depend on reviews Google may later remove.
Your rank tracker can keep returning data while the legal and commercial assumptions underneath it have already become a business risk. If your dashboards, client reports, competitive research, or AI visibility monitoring depend on SerpApi or another reseller of Google results, you need an exposure map before a court outcome, not a prediction of who will win.
Google’s claims remain contested, and filing a lawsuit does not prove them. But the dispute targets the collection method, the content being collected, and the resale of that content. Those issues can affect service continuity, field coverage, pricing, and historical comparability long before they establish a legal rule.
Circumventing technical protections and standard crawling controls.
Disregarding website directives intended to limit content access.
Using cloaking, rotating bot identities, and large bot networks to avoid detection.
Taking licensed material from search features, including images and real-time data, and selling access to it.
Those are Google’s allegations, not findings of fact. SerpApi denies wrongdoing, argues that public search data should remain accessible, and has invoked the First Amendment in defending its position. It also warns that restrictions of this kind could damage an open web.
Do not turn that disagreement into either of two unsupported conclusions: that every form of SERP collection is unlawful, or that anything visible in a browser is automatically unrestricted. The real questions are more specific:
How was the data accessed?
Which technical controls or publisher directives applied?
Does the result contain material licensed from another provider?
What exactly is being stored, transformed, displayed, and resold?
Which party assumes the risk if access is restricted?
This distinction matters when you evaluate a supplier. A provider’s broad statement that its data is public does not answer a narrower allegation about evading controls or redistributing licensed content. You need enough provenance to understand the service you are buying, even if the provider cannot disclose its entire technical system.
Audit your SERP dependency before the data changes
Start with operational exposure rather than courtroom speculation. The goal is to identify what would break if a provider removed fields, reduced request volume, changed its collection method, raised prices, or stopped serving a particular Google feature.
Find direct and indirect dependencies. Search your scripts, workflow automations, data warehouse jobs, dashboards, reporting templates, and vendor integrations for SerpApi and other SERP data services. A platform can expose search data without making its upstream supplier obvious, so ask embedded vendors as well.
Separate the data classes. Record whether each workflow uses organic links, snippets, images, knowledge features, shopping information, local results, or real-time features. The lawsuit’s emphasis on allegedly licensed feature content makes a generic label such as “Google data” too vague for risk review.
Map every downstream commitment. Note which datasets feed internal research, executive reporting, client deliverables, automated alerts, product features, or contractual service levels. A low-volume feed can still be critical if a customer-facing report depends on it.
Capture a baseline. Preserve your field dictionary, query settings, market and device assumptions, freshness expectations, failure rate, and representative outputs, subject to your retention rights. Without a baseline, a provider-side methodology change can look like a ranking or visibility change.
Assign a fallback. Name the replacement method, the owner who can activate it, and the reporting limitation it introduces. “Find another API” is not a fallback plan unless you have tested how its definitions and coverage differ.
Classify the dependency by the consequence of failure, not by the number of API calls:
Dependency
Practical response
Important limitation
Ad hoc research
Save query definitions and identify a manual sampling method.
A small manual sample may not reproduce the provider’s location, device, or personalization assumptions.
Recurring internal dashboard
Test a second data path and annotate any supplier or methodology change.
Two providers may label positions and search features differently.
Client or executive reporting
Document the dependency, establish a change-notice process, and prepare a reporting caveat.
Combining incompatible series can create a false trend.
Customer-facing product feature
Review the contract, test graceful degradation, and define who can activate the contingency.
A legal remedy after disruption will not restore immediate availability.
For information about your own site’s Google performance, a first-party source such as Google Search Console may cover part of the need. It does not reproduce a complete results page or provide a like-for-like replacement for competitive SERP monitoring. Treat it as one layer of a fallback, not a universal substitute.
When you test an alternative, overlap the old and new methods before combining their data. Compare query interpretation, country and location handling, device type, result-feature definitions, missing fields, freshness, and error behavior. If the series are not comparable, start a new baseline and mark the break instead of presenting it as an SEO movement.
Put collection provenance into vendor review
Do not ask only, “Is this legal?” That invites a sales assurance rather than a useful explanation. Ask questions that expose the collection path, rights assumptions, and continuity plan:
What is the origin of each data class? Ask the provider to distinguish directly collected Google output, third-party licensed data, transformed data, estimates, and information obtained through another supplier.
How does the service respond to access restrictions? You do not need instructions for evading controls. You do need to know whether the provider stops, substitutes data, reduces coverage, or changes methods when access is limited.
Which fields may contain third-party licensed material? Images and real-time features deserve separate treatment from ordinary organic URLs because Google has specifically raised licensed-content allegations.
What changes first under pressure? Ask whether a restriction would affect certain countries, devices, result types, request volumes, freshness levels, or historical exports before the entire service failed.
How will customers be notified? Request the provider’s process for communicating collection-method changes, field removals, legal restrictions, and material coverage loss.
Can you export your history and metadata? Historical values without query settings, timestamps, markets, device assumptions, and field definitions may be impossible to interpret after migration.
How does the contract allocate risk? Have qualified counsel review warranties, indemnities, termination rights, notice obligations, permitted uses, and retention terms in the context of your actual implementation.
A vendor contract cannot guarantee uninterrupted access to an external platform. It can clarify responsibility, but you still need a technical fallback. Keep those two workstreams separate: counsel assesses legal exposure, while your data and SEO teams protect continuity and measurement quality.
Answers that should slow your decision
“The data is public.” This does not explain whether technical controls were bypassed or whether some fields contain licensed material.
“Everyone collects search results.” Industry prevalence does not tell you how this provider operates or what rights attach to each data class.
“Customers have never had a problem.” That does not establish a continuity plan, a notification process, or a contractual remedy.
“Our method is completely legal.” An unqualified conclusion is less useful than a written explanation of the access model, relevant rights, and scope of the assurance.
“We cannot discuss any aspect of collection.” A provider may protect proprietary details, but complete opacity prevents you from performing even basic supplier-risk review.
If your own collection code, or a method disclosed by a supplier, appears to bypass access controls or conceal bot identity, do not expand that deployment until qualified legal counsel has assessed the actual facts. This operational checklist cannot determine whether a particular system is lawful.
Protect AI visibility and SEO reporting without changing strategy
The provenance question extends beyond a direct SerpApi account. Reddit has separately accused SerpApi, Perplexity, Oxylabs, and AWMProxy of participating in an indirect scraping chain involving Google results. Reddit says it planted a trap item visible only to Google’s crawler that later appeared in Perplexity results. SerpApi denies the allegations.
That claim does not prove how every named party obtained every item. It does illustrate why data lineage matters: your dashboard may receive information through several suppliers, and the company selling you the final metric may not be the company collecting the underlying result.
For an AI visibility, AEO, or GEO platform, document the measurement chain with the same care you would apply to a rank tracker:
Label whether each metric comes from a directly observed model response, a Google result, a third-party dataset, or an inferred score.
Retain the query or prompt, timestamp, market, device, search feature, and model or product identifier when those fields are available.
Require a methodology changelog so a collection change cannot quietly become an apparent visibility gain or loss.
Keep observed facts, such as whether a brand appeared, separate from proprietary scores or estimates.
Rebaseline a metric when its supplier, collection path, feature definition, or model surface changes materially.
Do not use Google SERP coverage as an unlabeled substitute for direct measurement of an AI system. Search visibility and model-response visibility answer different questions.
The lawsuit itself is not evidence of a Google ranking update, a change to structured-data processing, or a new standard for earning AI citations. Do not rewrite content, remove JSON-LD, or change your internal-link strategy because litigation was filed. Change the governance around the data used to judge those activities.
Predefine the events that will trigger action: a supplier notice, unexplained field loss, a sustained change in failure behavior, a restriction on a result type, a material pricing change, or a change in collection methodology. Then name who decides whether to continue, degrade the report, activate a fallback, or start a new measurement baseline. That prevents a technical incident from turning into an improvised legal and client-communication decision.
Key takeaways
Google’s claims against SerpApi are contested allegations, not a judgment that all SERP data collection is unlawful.
Your immediate exposure is operational as well as legal: access, fields, prices, and historical comparability can change before the case is resolved.
Audit direct APIs and hidden upstream suppliers across dashboards, reports, automations, and AI visibility tools.
Ask how each data class was obtained, which rights apply, what degrades under restriction, and how methodology changes are disclosed.
Use overlapping tests and explicit baseline breaks when changing providers; otherwise a measurement change can masquerade as an SEO trend.
Keep your content and schema strategy tied to search performance evidence. The lawsuit calls for stronger data governance, not reactive optimization changes.
Your next move is concrete: inventory every workflow that depends on full Google results, classify its business impact, and send the seven provenance questions to each supplier. You do not need to predict the verdict to make your measurement stack less fragile.