Tag: B2B Marketing

  • Paid Media Optimization for Long Sales Cycles: A Practical System

    Paid Media Optimization for Long Sales Cycles: A Practical System

    Your paid campaigns can generate leads this week while the resulting revenue takes months to appear. That delay creates an uncomfortable decision: should the ad platform optimize for the form submission it can see quickly, or for the closed sale that reflects the outcome you ultimately care about?

    The answer is not simply “optimize further down the funnel.” In a human-led sales process, a closed deal measures more than media quality. It also reflects rep skill, follow-up speed, capacity, product availability, approval delays, and seasonal behavior. You need a bidding signal that rewards valuable demand without teaching the platform to react to every operational swing.

    Key takeaways for long-cycle campaigns

    • Use the deepest conversion event that is frequent, timely, and operationally stable. A closed sale is not automatically the best bidding signal.
    • For many long sales cycles, the practical optimization boundary is a valued lead at submission: not every form fill receives the same value, but the value is assigned before sales execution changes the outcome.
    • Estimate lead value from conversion probability and typical deal size using information available when the inquiry arrives.
    • Keep downstream revenue in your measurement system even when it is not the primary bidding input. You need it to calibrate lead values and judge business performance.
    • Diagnose media quality and sales operations separately. Stable lead volume and predicted value alongside a falling close rate is not sufficient evidence that targeting has failed.

    Why a closed sale can be the wrong bidding signal
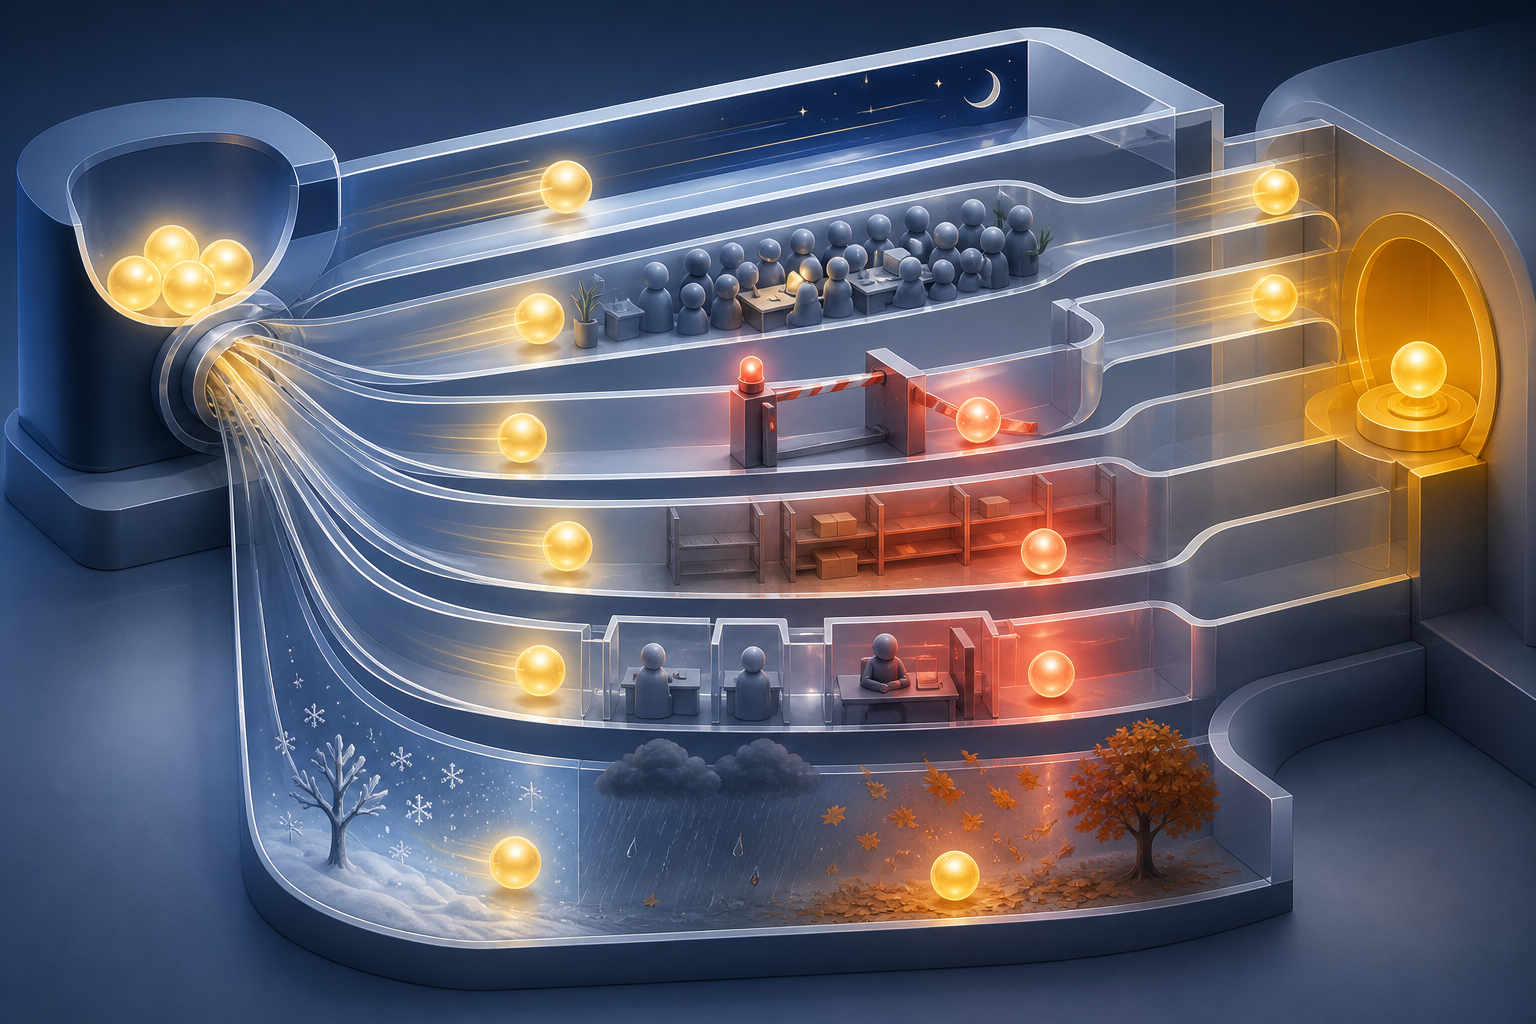
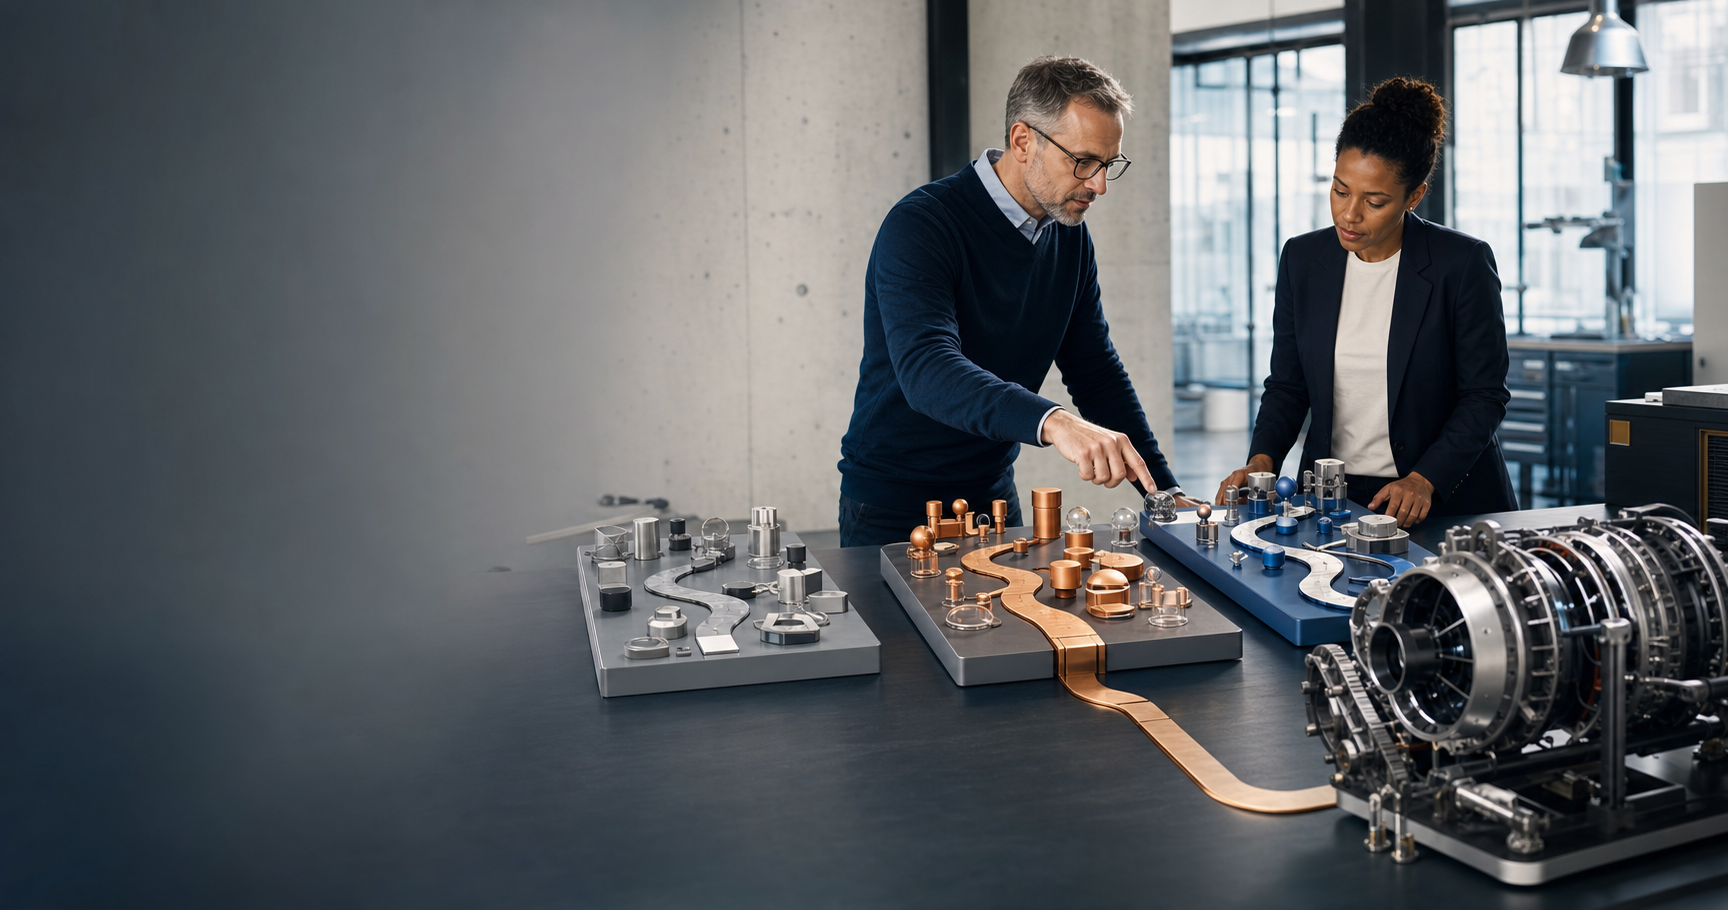
    Identical lead spheres move through different sales-process channels, where workload, delays, approvals, inventory, and other obstacles change which ones reach the final outcome.

    An ad platform sees the conversion outcome, but it does not understand your organization. If a strong sales rep closes more leads than a new rep, the platform can observe the difference in recorded sales. It cannot inherently know that rep assignment caused it.

    Imagine that the same campaigns, keywords, landing pages, and lead profiles continue running while your most effective closer takes leave. A less experienced colleague receives the leads, follow-up slows, and the close rate falls. An automated system optimizing for sales may treat the decline as evidence that those clicks or audiences became less valuable. It can then reduce bids, shift budget, or suppress targeting that was still generating suitable prospects.

    Rep composition is only one source of noise. Close rates can change when workloads increase, response times stretch from days into a week, a competitive product is withdrawn, an approval stalls, or vacation coverage leaves inquiries untouched. Leads from other channels can also consume the sales team’s capacity even though nothing changed inside the paid account.

    Calendar behavior can make the distortion severe. In one observed financial-services pattern, lead-to-sale conversion around the third week of December rose by as much as 150% compared with normal weeks, then fell sharply during the holiday week. The leads and placements had not suddenly become much better and then much worse. Sales urgency, customer availability, bonus incentives, and leave schedules had changed.

    This is the core diagnostic distinction: a sale is a business outcome, but it is not always a clean media-quality label. When you ask an algorithm to bid on it, you are asking the platform to optimize all the forces embedded in that outcome, including forces the campaign cannot control.

    Set the optimization boundary at a stable quality signal

    Your optimization boundary should sit at the latest funnel event that satisfies three conditions: the event happens often enough for automation to learn from it, it arrives soon enough to guide current bidding, and its definition remains stable enough to mean the same thing from one period to the next.

    Direct sales or revenue optimization can be appropriate when conversion volume is sufficient, the reporting delay is short, and the sales process is stable. Long, low-volume, human-dependent sales cycles frequently fail one or more of those tests. In that situation, a quality-adjusted lead is usually more dependable than either a raw form fill or a closed deal.

    • A raw lead count is too shallow when inquiries have materially different probabilities of conversion or deal sizes.
    • A closed sale is too deep when it is rare, delayed, or heavily shaped by sales execution and operational capacity.
    • A valued lead at submission is the middle path when you can estimate commercial potential from information already available at the point of inquiry.

    The phrase “at submission” matters. If you assign the value after seeing which rep handled the lead, whether the buyer answered a follow-up call, or how the opportunity progressed, you have allowed downstream execution back into the bidding label. The model should use attributes known when the lead enters the funnel.

    The optimization boundary is not the reporting boundary. Continue importing final status and realized revenue. Use those outcomes to evaluate the business, recalibrate the lead-value model, and identify sales-process problems. You are separating two jobs: the bidding system needs a timely and stable signal, while management reporting needs the complete commercial outcome.

    Build a lead-value model from matured historical cohorts
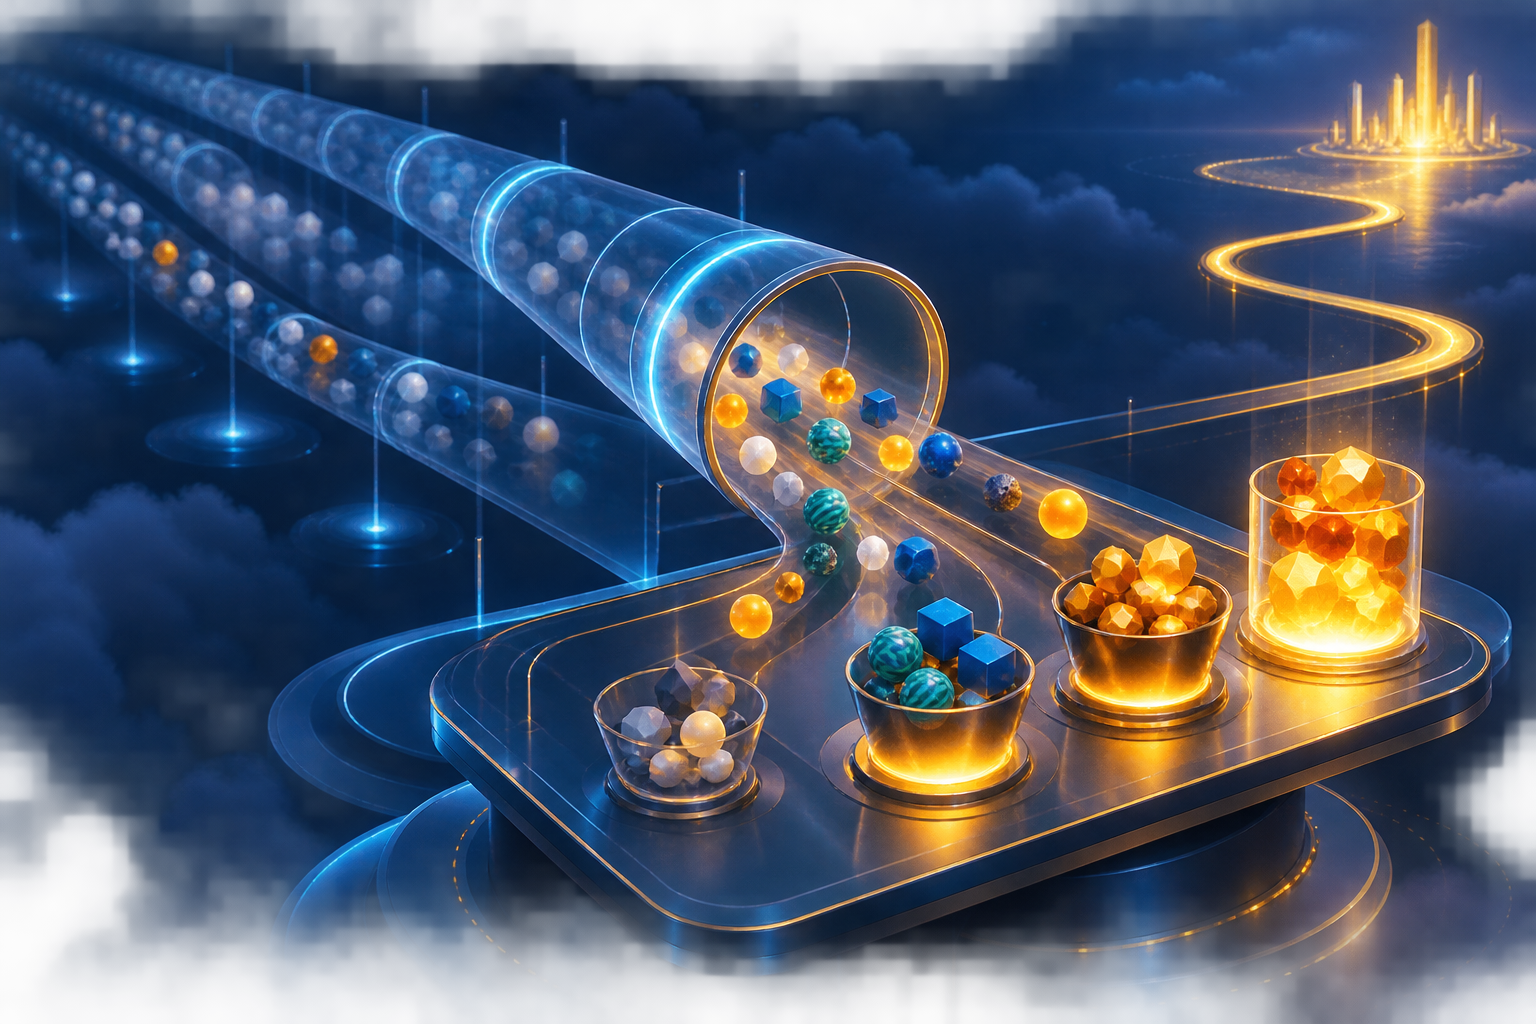
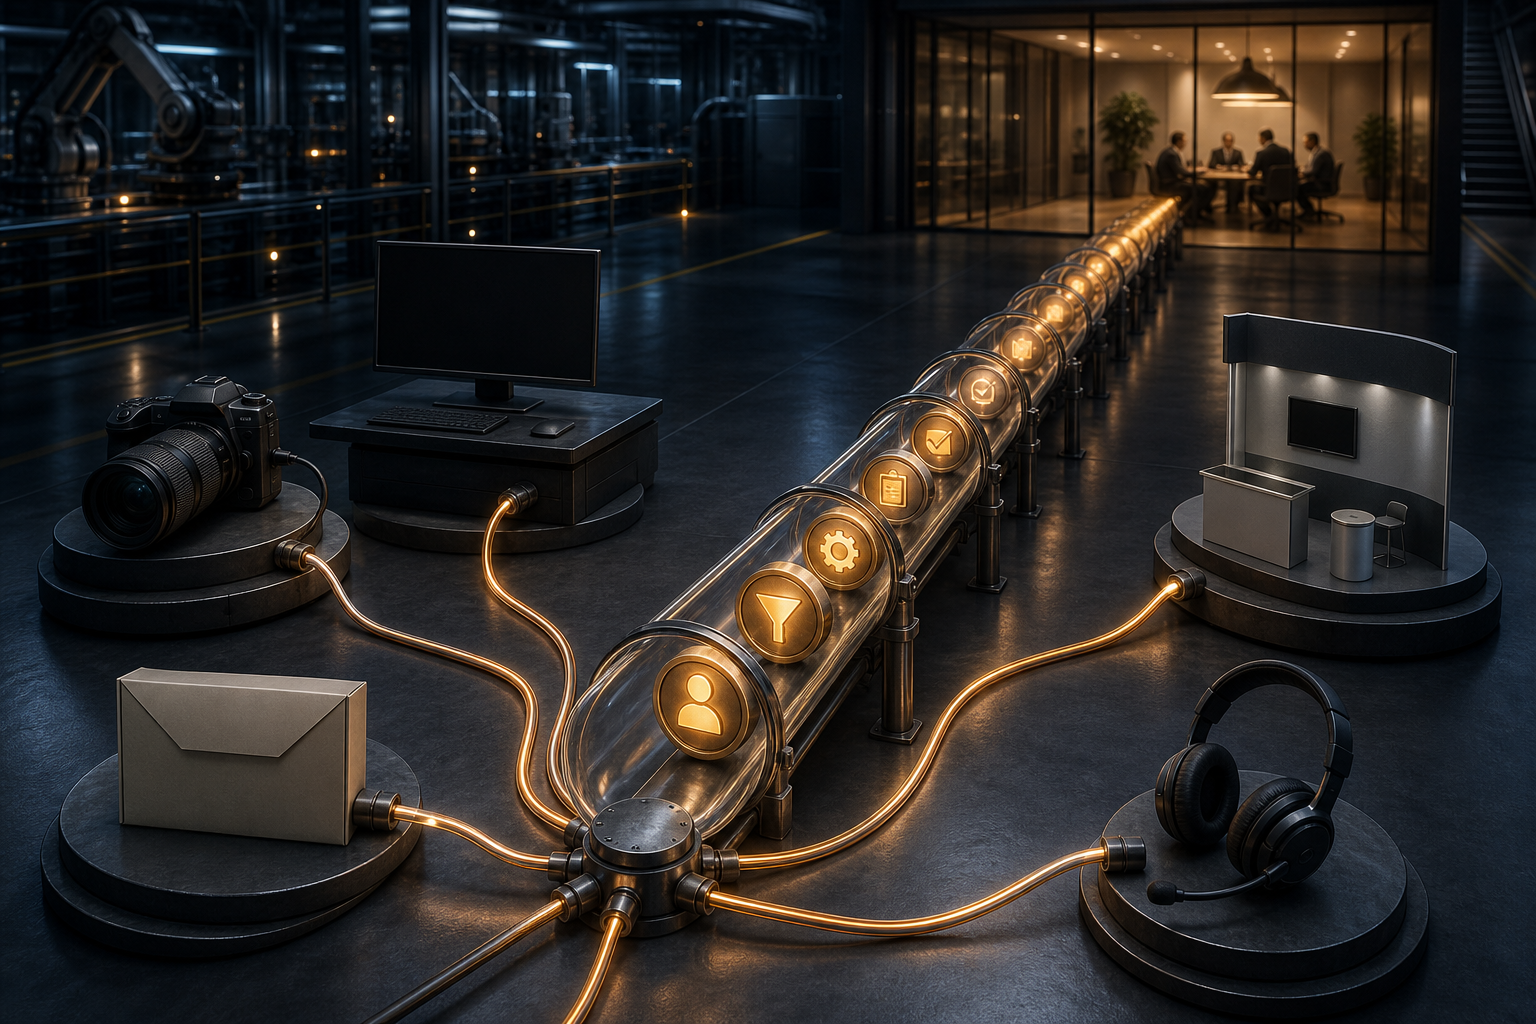
    Lead tokens pass through a long time tunnel before matured groups are sorted into illuminated value categories, with a separate path continuing toward eventual revenue.

    A useful lead-value model estimates expected revenue rather than merely labeling a lead “good” or “bad.” Start with historical inquiries that have had enough time to reach a final outcome. A full year is preferable because it captures more operating conditions and seasonality, although six months can be sufficient when that is all the reliable history you have.

    1. Select matured cohorts. Group leads by the date they entered the funnel, then include cohorts old enough that most opportunities have reached a meaningful final status. Mixing fresh, unresolved leads with completed cohorts will make recent traffic appear artificially weak.
    2. Freeze the information available at inquiry. Retain fields the campaign could reasonably influence or attract: requested product, project scope, stated timing, loan characteristics, company size, industry, and other submission-time attributes relevant to your business.
    3. Calculate conversion probability by meaningful segment. Determine which inquiry-time characteristics correspond with different eventual conversion rates. Keep the segments understandable enough that you can explain why a lead received its value.
    4. Measure typical deal value for each segment. A segment that closes frequently is not necessarily the most valuable if its average commercial outcome is small. Conversely, a lower-probability segment may deserve attention when successful deals are much larger.
    5. Assign expected revenue. The basic logic is conversion probability multiplied by typical deal value. The result is a monetary estimate that a value-based bidding system can compare across leads.
    6. Reconcile predictions with realized revenue. Add the predicted values for a matured acquisition cohort and compare that total with the revenue eventually produced by the same cohort. Large or persistent gaps mean the probabilities, deal values, segments, or data quality need adjustment.
    7. Version and revisit the model. Preserve the value assigned at submission and record which model version produced it. Reassess the model quarterly so changes in campaign mix, products, buyer behavior, and operations do not leave old assumptions running indefinitely.

    The most useful segmentation variables depend on the transaction. Financial-services leads may differ by loan value or terms. B2B inquiries may differ by company size or industry. Construction opportunities may differ by scope and immediacy. Choose fields that were genuinely known at inquiry and have a defensible relationship with conversion probability or deal size.

    A practical framework might assign expected values such as $850 to a high-probability lead, $420 to a middle tier, and $120 to a lower-probability lead. Those figures are examples, not benchmarks. Copying them would make the model arbitrary; your values must come from your own conversion rates and deal economics.

    Do not confuse an expected-revenue value with a conventional lead score. A score of 90 may rank above a score of 40, but it does not tell a bidding system whether the first lead is twice as valuable, ten times as valuable, or only marginally better. Monetary values express the size of the difference and allow value-based bidding to make an economically meaningful tradeoff.

    Guard against data leakage as you build the model. Opportunity stage, rep assessment, response behavior, and later qualification calls may predict sales extremely well, but they were not known when the ad produced the inquiry. Using them to label historical leads can create a model that looks accurate in analysis but cannot assign equivalent values consistently at submission.

    Feed values into bidding without losing revenue accountability

    Once the values reconcile reasonably with matured revenue, configure the lead conversion to send its expected value with the event. Value-based bidding, including Google Ads target return on ad spend, can then pursue the mix of inquiries with the highest predicted commercial value rather than the largest number of identical form fills.

    Treat the implementation as a measurement change before treating it as a bidding change. First log the dynamic values while the existing strategy remains in place. Confirm that each valid lead is counted once, the correct value reaches the correct conversion action, and the platform’s aggregate value matches your lead system for the same inquiry dates. Only then should you let a value-based strategy act on the signal.

    Keep a compact acquisition record for every lead. At minimum, preserve the lead identifier, inquiry timestamp, paid-media attribution, value assigned at submission, model version, rep assignment, first-response timing, final status, and realized revenue. This lets you distinguish what the model knew from what happened after the handoff.

    Evaluate performance through two related views:

    • Predicted return compares total expected lead value with the spend that produced those leads. It is available quickly enough to guide campaign management.
    • Realized return compares eventual revenue with spend for the same acquisition cohort. It arrives later but tells you whether the model and the wider commercial process delivered what the early signal implied.

    Keep the cohort alignment intact. Revenue closed this month may have come from leads acquired months ago, so comparing it with this month’s spend can produce a convincing but false trend. Join eventual revenue back to the date and campaign that generated the inquiry. That makes the lag explicit and prevents old pipeline from being credited to current media.

    Roll the bidding change into a controlled part of the account rather than changing every campaign at once. Watch lead counts, predicted value, spend, and the distribution of value tiers. As cohorts mature, compare their predicted totals with realized revenue. A strategy that raises platform-reported value but repeatedly produces less realized revenue is exposing a calibration or tracking problem, not proving business growth.

    Diagnose a performance drop before changing the media

    When sales fall, resist the reflex to rewrite ads or cut audiences immediately. Walk through the funnel in causal order. The goal is to locate the first point where performance changed.

    1. Check inquiry volume. Did the number of valid paid leads change, or did only closed sales change?
    2. Check predicted lead value. Did the mix move toward lower-value tiers even if total lead volume remained stable?
    3. Check media inputs. Look for meaningful changes in targeting, search terms, audience composition, placements, creative, landing-page behavior, budget, or tracking.
    4. Check routing and response time. Determine whether leads reached the right people and whether follow-up slowed.
    5. Check staffing and capacity. Review rep assignment, leave, onboarding, workload, and competing lead sources.
    6. Check the commercial offer. Identify withdrawn products, changed eligibility, approval delays, pricing constraints, or other conditions that made the same lead harder to close.
    7. Check calendar effects. Separate customer availability and sales-team urgency from changes in demand quality.
    8. Change the layer that failed. Adjust campaigns when the deterioration begins in traffic or predicted lead value. Address operations when the early media signal is stable but handoff or close performance worsens.

    This sequence gives you a cleaner interpretation. If lead volume and predicted value remain stable while response times rise and close rates fall, the evidence points downstream. If response times and sales coverage remain stable while the account produces a weaker value mix, the media deserves scrutiny. If both change, treat them as separate problems instead of asking one campaign adjustment to solve both.

    Your first move should be an export of matured lead cohorts, not another bid adjustment. Identify the inquiry-time attributes that separate conversion probability and deal size, assign expected revenue, and reconcile the total against actual revenue. Once that model holds together, use it as the bidding signal and keep closed sales as the accountability signal. That division gives automation something it can learn from without letting every staffing or operational change rewrite your media strategy.

    References


  • Marketo Engage SEO Retirement: A Practical Migration Plan

    Marketo Engage SEO Retirement: A Practical Migration Plan

    If your team depended on the Marketo Engage SEO tile, this is no longer a roadmap item you can leave for later. Adobe scheduled the feature to be discontinued on March 31, 2026, with the tile removed beginning April 1. That deadline has passed.

    Your immediate job is to establish what was preserved, what was lost, and which business process must replace the feature. Do that before buying another platform. A rushed tool purchase can restore a dashboard while quietly breaking historical comparisons, ownership, or reporting definitions.

    Key takeaways

    • Adobe retired the SEO feature within Marketo Engage; this is not evidence that Marketo Engage itself was retired.
    • The scheduled export deadline was March 31, 2026, and removal of the SEO tile was set to begin April 1.
    • If you exported your data, preserve the untouched files, document their coverage, and test whether they can actually be opened and interpreted.
    • If you missed the deadline, search existing business systems and ask Adobe Support about recovery before attempting to reconstruct the history.
    • Select a replacement according to the jobs your team needs to perform, not according to suite familiarity or corporate ownership.
    • Never join old and new metrics into a continuous trend line until you have checked their definitions, filters, date boundaries, and URL treatment.

    Separate the SEO retirement from the rest of Marketo Engage

    The scope matters. Adobe scheduled the retirement of Marketo Engage’s SEO feature and its tile. Nothing in that change establishes that your forms, campaign programs, lead operations, scoring, or the wider Marketo Engage platform must be migrated.

    Keep the response proportional. Remove dependencies on the SEO feature, but don’t turn a feature decommission into an unplanned marketing automation migration unless you already have a separate reason to reconsider the broader platform.

    DecisionWhat is establishedWhat you should do
    Feature scopeThe Marketo Engage SEO feature was scheduled for retirement.Inventory processes that used the SEO tile rather than treating every Marketo workflow as affected.
    Data accessExisting SEO data needed to be exported by March 31, 2026.Treat post-deadline access as unavailable unless Adobe confirms otherwise for your account.
    User interfaceRemoval of the SEO tile was scheduled to begin April 1.Remove tile-specific instructions, bookmarks, screenshots, and training steps from current procedures.
    ReplacementNo automatic replacement, entitlement, or historical transfer was established.Verify licensing, data portability, metric coverage, and implementation separately.

    Adobe’s stated rationale was to redirect resources away from underused functionality. That is a useful warning for your operating model: a feature can be technically available while becoming strategically peripheral. Add vendor roadmap review and export readiness to the ownership of any reporting capability you replace.

    Adobe’s 2025 acquisition of Semrush makes Semrush an obvious candidate for evaluation, but the corporate relationship does not prove that your Adobe agreement includes it, that Marketo SEO history transfers into it, or that its measurements match your old reports. Procurement, migration, and metric continuity remain three separate questions.

    If you exported the data, prove the archive is usable

    An analyst verifies generic digital records as they move from an organized archive through a glowing validation frame.

    Having an export is not the same as having a recoverable reporting asset. A file can exist while its date range, filters, field meanings, or account context have already been forgotten. Preserve the evidence before anyone cleans, renames, or transforms it.

    1. Keep an untouched master copy. Store the original export in a controlled, read-only location. Work from duplicates. If your data-governance process supports checksums, record one so later teams can verify that the master was not altered.
    2. Create an export register. For every file, record its filename, export date, Marketo account or workspace, owner, known reporting period, known filters, file format, and storage location. Mark unknown details as unknown instead of guessing.
    3. Inspect the structure. Confirm that the file opens, headers are intact, characters render correctly, dates parse consistently, URLs have not been converted or truncated, and numeric columns remain numeric. Save a field list beside the archive.
    4. Document metric meanings. Capture any surviving definitions from procedures, dashboard labels, screenshots, or team documentation. A column called visibility, position, traffic, or opportunity has little long-term value unless the calculation and scope are understood.
    5. Locate downstream dependencies. Search recurring reports, dashboards, presentation templates, planning models, tickets, and operating procedures for fields or screenshots drawn from Marketo SEO. Record the owner and business decision associated with each one.
    6. Test restoration. Import a working copy into the system where analysts will actually use it. Check several records against the original, including the earliest and latest dates, blank values, duplicate URLs, and unusually large or small values.
    7. Apply appropriate access controls. Do not assume that a file is safe to distribute merely because it came from an SEO feature. Review its actual contents and follow the controls required by your organization.

    Treat the export as a fixed historical archive, not a live dataset. A new platform can supply future measurements, but that does not make its numbers directly comparable with the archived Marketo SEO values. The tools may use different keyword sets, locations, devices, crawling rules, URL normalization, update schedules, or calculation methods.

    When exact definitions cannot be recovered, label the archive accordingly. An explicit limitation such as “legacy Marketo SEO metric; calculation unavailable” is more honest and more useful than a confident but invented definition.

    If you missed the deadline, recover before you reconstruct

    Do not assume Adobe can restore the data after the scheduled removal, but do not assume it is irretrievable without checking either. Recovery should begin with existing evidence and a narrowly framed support request.

    1. Preserve what remains. Collect filenames, dashboard screenshots, report attachments, procedures, tickets, and presentation slides that show how the feature was used. Record who used it and which decisions depended on it.
    2. Search sanctioned storage. Check shared drives, approved cloud storage, data warehouses, business intelligence systems, reporting folders, ticket attachments, and relevant email attachments. Ask likely users to search their work files within your organization’s retention and security policies.
    3. Open an Adobe Support request. Identify the Marketo account, the retired SEO feature, the required reporting period, and the desired export. Ask whether any account-level recovery or backup route remains. Treat recovery as unconfirmed until Adobe gives you a direct answer.
    4. Map each missing output to an authoritative system. Organic search performance may be recoverable from verified search-engine properties; site behavior may exist in web analytics; conversion outcomes may live in Marketo programs, a CRM, or a warehouse; rankings and technical findings may exist in another SEO platform. Availability depends on what your organization had already configured and retained.
    5. Create a gap log. Record the last date supported by reliable legacy evidence, the first date covered by the replacement, unavailable intervals, changed definitions, and any reconstructed values. Keep this log beside the dashboard rather than in a forgotten migration folder.

    Reconstructed data must be labeled by origin. A chart assembled from search-engine exports, analytics, archived slides, and a new SEO platform is not a recovered Marketo SEO dataset. It is a new analytical record with multiple inputs and potentially different definitions.

    If there is no trustworthy overlap between the retired feature and its replacement, start a new baseline. Leave a visible break in the trend. A gap is inconvenient, but a seamless line made from incompatible measurements can lead stakeholders to act on growth or decline that never occurred.

    Replace the workflow, not just the tile

    A team reroutes connected workflow modules around an obsolete component on a collaborative planning table.

    Start replacement planning with the decisions people need to make. “We need another SEO tool” is too vague to evaluate. “We need page-level search performance for content prioritization” or “we need scheduled technical crawl findings assigned to site owners” gives you something testable.

    • For organic search performance, define the required query, page, country, device, and date dimensions, along with export and retention needs.
    • For technical SEO, define crawl scope, canonical handling, JavaScript requirements, issue ownership, and the evidence required to close a finding.
    • For rank and competitive visibility, specify the tracked keyword set, search location, device, measurement cadence, and treatment of search features before comparing vendors.
    • For marketing attribution, define how landing-page activity connects to conversions, Marketo programs, CRM outcomes, and the attribution model. An SEO dashboard alone does not settle those relationships.
    • For AEO, GEO, or AI visibility, define prompts, markets, models, citations, mentions, and review cadence as a new measurement requirement. Do not rename a traditional ranking metric and present it as AI-search visibility.

    Require each candidate workflow to demonstrate data export, retention, API or connector access where needed, metric documentation, user permissions, scheduled delivery, and ownership. If historical import is important, verify what the platform actually imports and whether imported records remain distinguishable from data it measured itself.

    Use any period of overlapping data as a calibration window, not as proof that the systems are equivalent. Compare the same URLs and dates under the closest available settings. Investigate differences in coverage, time zones, URL variants, keyword sets, update timing, and aggregation. Record accepted differences before the new dashboard becomes the official record.

    The cutover is complete only when the old dependency has an owner-approved disposition. Update recurring reports, procedures, bookmarks, onboarding materials, dashboard annotations, and stakeholder expectations. Mark legacy metrics as retired, name the replacement metric, and retain the definition of each.

    Before your next SEO report goes out, place the export register and gap log beside it. That small control prevents a polished dashboard from presenting two different measurement systems as one continuous history.

    References
  • How to Choose an SEO Agency for an AI Company in 2026

    How to Choose an SEO Agency for an AI Company in 2026

    If you are hiring an SEO agency for an AI company, the hard part is not finding firms that mention AI. It is deciding whether you need category education, technical repair, brand and UX work, conversion testing, launch support, or a coordinated paid-organic program. Those are different jobs, and an impressive client list cannot turn one into another.

    The framework below will help you define the assignment, route it to the right type of partner, test the agency’s proof, and make competing proposals comparable. The goal is not to find an agency that can plausibly do everything. It is to hire the team best equipped to remove the constraint that is holding back qualified discovery and revenue.

    Name the bottleneck before you name an agency

    A team examines an interconnected growth system where geometric signals are backed up at one constricted junction.

    Start with the part of your growth system that is failing. AI companies often bundle several problems under SEO even though each problem calls for different people, deliverables, and measures of success.

    • Discovery is the bottleneck: Buyers already search for the problem or category, but your useful pages are not visible. You likely need technical SEO, search-intent mapping, authoritative content, internal linking, and a defined approach to AI search visibility.
    • Category education is the bottleneck: Prospects do not yet have stable language for the problem, or your positioning sounds interchangeable with every other AI vendor. You need a thought-leadership and content program that connects the emerging category to problems buyers already recognize.
    • Product comprehension is the bottleneck: People reach the site but cannot quickly tell who the product is for, what workflow it changes, or why it is credible. Brand strategy, messaging, information architecture, and UX may matter more than publishing additional articles.
    • Conversion is the bottleneck: Relevant traffic reaches the right pages but does not take the next step. The work shifts toward A/B testing, mobile experience, form design, proof placement, and conversion analysis.
    • Launch trust is the bottleneck: You are introducing a product, entering a new category, or managing a reputation issue. PR, brand mentions, launch messaging, and reputation management need to work alongside SEO.
    • Channel coordination is the bottleneck: Paid search, organic content, social distribution, and short-form video operate as separate campaigns. An integrated performance partner may be more useful than a narrowly focused SEO shop.

    Choose a primary bottleneck and a secondary one. If every objective is equally important, the brief is not ready. An agency facing an undefined assignment will usually respond with a standard service bundle, and you will end up comparing activity counts instead of solutions.

    You can sharpen the diagnosis with a small journey audit. Open the page that should convert your most valuable buyer and check whether it names the buyer, the use case, the operational change, and the supporting proof. Then inspect the search results for the query that buyer would use before knowing your brand. Finally, test a fixed set of relevant questions in the AI interfaces that matter to your audience. Record whether your company is absent, merely mentioned, cited as supporting evidence, or linked. Those are different outcomes.

    Turn the result into one sentence: your company needs a named audience to discover, understand, or choose a specific offer, and the current obstacle is a clearly identified part of that journey. That sentence belongs at the top of every agency brief.

    Route your shortlist by specialist fit

    As of March 12, 2026, seven candidates span several distinct versions of AI-company marketing. The reported team sizes, founding years, and positioning are useful routing signals, but they are not substitutes for checking the people who would actually deliver your account.

    CandidateReported profileShortlist whenClarify before signing
    First Page Sage100-250 people; founded in 2009; SEO, generative engine optimization, thought leadership, and lead generationYour central problem is building search authority and qualified discovery through sustained expert contentAsk for separate evidence covering conventional rankings, AI citations or mentions, qualified leads, and pipeline contribution
    Clay Agency11-50 people; founded in 2016; technology branding and UX/UI designThe product is difficult to explain, the website no longer matches the offer, or a launch requires a stronger interactive experienceEstablish whether ongoing technical SEO and content production are included or whether the engagement is primarily brand and design work
    Marketing Eye11-50 people; founded in 2004; technical SEO for SaaS, audits, keyword analysis, content, and social campaignsYou want a leaner partner to diagnose technical and content issues across a SaaS websiteConfirm who supplies subject-matter depth, who implements technical recommendations, and how social work supports the search objective
    RNO151-100 people; founded in 2018; market research, digital branding, product design, UX/UI, and technical SEOYour search problem is entangled with product research, positioning, or a broader digital experience redesignSeparate the SEO deliverables from the research and design deliverables so each has an owner and an acceptance test
    REQ51-100 people; founded in 2008; branding, PR, reputation management, UX, and supporting SEOYou are launching a product, building category credibility, or need search work coordinated with reputation and media activityAsk how PR outcomes will connect to durable pages, non-branded discovery, and measurable buyer actions
    Optimizely500+ people; founded in 2010; A/B testing, personalization, mobile optimization, and conversion rate optimizationYou already have meaningful traffic and content, but need a stronger experimentation and conversion layerDetermine whether you are buying a platform, implementation support, an experimentation program, or full SEO execution; these are not interchangeable
    Directive Consulting50-249 people; founded in 2014; SEO, paid media, short-form video, and social marketing for technology companiesYour acquisition plan needs paid and organic channels to share audience intelligence, creative, and performance reportingRequire a clear division of budget, deliverables, attribution, and ownership across organic search, paid campaigns, video, and social

    Use the table as a routing tool, not a league table. Clay Agency and RNO1 may be compelling when a site or product experience is the actual constraint. REQ may make more sense around a launch or reputation problem. Optimizely is a different kind of option because its stated strength is experimentation and personalization rather than an assumed replacement for an SEO-led content team. Directive Consulting fits a broader performance remit, while First Page Sage and Marketing Eye align more directly with sustained organic search work.

    Company size and age can help you ask operational questions, but neither proves fit. A larger organization may offer more specialists while placing your account behind more handoffs. A smaller team may give you senior access while having less capacity for simultaneous technical, editorial, design, and analytics work. Ask for the names, roles, availability, and relevant work of the proposed delivery team. Evaluate that team, not the agency’s total headcount.

    Demand proof that survives an AI-company sales cycle

    Translucent evidence tiles move through technical, research, stakeholder, and decision checkpoints, with one tile remaining intact to the end.

    AI-company SEO can produce attractive surface metrics without resolving a commercial problem. More impressions may come from loosely related informational queries. More AI mentions may be unlinked or occur in prompts your buyers never use. More traffic may be branded demand created elsewhere. You need evidence at the query, page, audience, and conversion levels.

    Inspect proof at the query and page level

    Ask each agency to walk through work that resembles your primary bottleneck. A credible walkthrough should identify:

    • The target audience and the problem that audience was trying to solve.
    • The query set or demand theme, including why it mattered commercially.
    • The baseline condition before the work began.
    • The pages created, consolidated, redesigned, or technically repaired.
    • The difference between branded and non-branded discovery.
    • The conversion event used to connect visibility with buyer action.
    • The changes the agency can reasonably connect to its work and the changes it cannot.

    A logo and an upward traffic chart do not answer those questions. Client names can establish market familiarity, but they do not show what the agency owned, whether the work is still live, or whether the result applies to your sales motion. Where confidentiality limits disclosure, ask for an anonymized page-level explanation and a reference from a company with a similar buying process.

    Separate AI visibility from conventional SEO evidence

    An agency offering GEO or AI search optimization should be able to define what it measures. Brand mention, citation, linked citation, recommendation, referral visit, and influenced conversion are separate events. A proposal that collapses them into one visibility score prevents you from seeing what actually changed.

    Ask for a fixed prompt library organized around awareness, problem exploration, comparison, and selection. Each observation should record the prompt, the interface or model, the date, the output, the brand outcome, and any cited page. AI responses can vary, so isolated screenshots are weak evidence. A repeatable observation method is more useful than a dramatic example.

    The agency should also distinguish observation from inference. A linked referral can be observed in analytics. A later branded search may have been influenced by an AI answer, but that relationship is harder to prove. Honest reporting preserves that distinction instead of assigning every downstream action to GEO.

    Test the technical and editorial operating model

    Use one of your real pages during the sales process. Ask the agency to explain what it would inspect, what it would change, and who would do the work. The discussion should cover crawl and index access, rendering, canonical signals, information architecture, internal links, structured data where relevant, page intent, claim support, and the conversion path.

    Then follow the content through its production workflow. Find out who interviews your experts, who drafts, who verifies product claims, who reviews regulated or security-sensitive language, who publishes, and who refreshes pages after the product changes. AI products evolve quickly; a technically optimized page can still become unreliable when its feature descriptions, integrations, model names, or limitations are no longer current.

    Listen for clear limits. A serious team will sometimes say that it needs analytics access, a crawl, a developer’s input, or buyer evidence before reaching a conclusion. Instant certainty from a sales call is not the same as technical fluency.

    Make proposals comparable before the contract gets expensive

    Send every shortlisted agency the same brief. Include the audience, primary bottleneck, product and category, markets served, buying journey, current search and AI visibility, conversion definition, technical constraints, available experts, approval process, existing content, analytics access, and the commercial outcome the program must support.

    Require the proposal to translate that brief into an explicit operating plan. A useful response will show what happens first, which assumptions must be tested, who owns each dependency, what the agency will deliver, what your team must supply, and how decisions will be made when early evidence contradicts the initial plan.

    Decision gateStrong answerPause and clarify
    DiagnosisA specific growth constraint tied to audience behavior, pages, and technical conditionsA generic package that could be sent to any SaaS company
    MeasurementA baseline, defined conversion events, branded and non-branded separation, and a map from leading indicators to business outcomesTraffic, impressions, or one blended visibility score presented as the complete result
    SEO and GEODistinct methods for rankings, citations, mentions, referrals, and influenced demandA claim of AI optimization with no prompt set, observation record, or page-level method
    Delivery teamNamed roles, realistic availability, review responsibilities, and an escalation pathSenior specialists appear during the pitch but the delivery team remains unidentified
    Technical executionImplementation ownership, developer dependencies, staging, validation, and rollback responsibilitiesAn audit ends with recommendations that nobody is assigned to implement
    Editorial qualityExpert input, claim verification, revision ownership, and a refresh processContent volume is promised without explaining accuracy or subject-matter review
    Commercial termsClear deliverables, account access, content ownership, acceptance criteria, change control, and handover termsAmbiguous intellectual-property rights, broad lock-in, or no usable exit process

    Do not grant unrestricted production access simply because an agency has passed procurement. Define who can change templates, tracking, redirects, robots directives, canonical tags, structured data, forms, and published claims. Use backups, staged changes, approval rights, and rollback procedures. A technically plausible edit can still remove indexable content, corrupt measurement, or interrupt lead capture.

    The contract should say who owns written content, design files, dashboards, prompt libraries, analytics configurations, and accounts created during the engagement. It should also define what you receive at handover. If the terms include exclusivity, broad intellectual-property assignments, unusual indemnity, or material data-handling obligations, have qualified counsel review those provisions before you sign; their effects can continue after the campaign ends.

    If confidence is still low, scope an initial diagnostic rather than committing the full program immediately. The diagnostic should produce usable assets: a prioritized technical backlog, a query and page map, an AI-prompt observation method, an editorial workflow, a measurement plan, and an initial delivery sequence. Make those outputs yours under the agreement so the work remains useful even if you choose a different implementation partner.

    Key takeaways for the hiring decision

    • There is no universal best SEO agency for AI companies. The right choice depends on whether discovery, category education, product comprehension, conversion, launch trust, or channel coordination is constraining growth.
    • Route agencies by their actual operating strength. SEO and GEO, brand and UX, PR and reputation, experimentation, and integrated performance marketing solve different problems.
    • Evaluate the named delivery team. Company size, founding year, client logos, and review averages are screening signals, not evidence that the people assigned to you can do the work.
    • Require page-level SEO proof and a repeatable AI-visibility method. Rankings, mentions, citations, referrals, and influenced conversions should not be reported as if they are the same event.
    • Send every candidate the same brief and compare diagnosis, measurement, staffing, implementation, editorial controls, and commercial terms.
    • Protect your access, data, content, accounts, measurement setup, and handover rights before work starts.

    Your next move is to write the one-page brief before booking another sales call. Put the primary bottleneck at the top, define the buyer action that matters, and list the evidence an agency must provide. Send it only to a small, role-matched shortlist. The quality of the answers will tell you far more than another round of polished capability slides.

    References

  • Transforming Client Pressure into Growth: Insights from Andrea Cruz

    Transforming Client Pressure into Growth: Insights from Andrea Cruz

    On episode 341 of PPC Live The Podcast, I had the pleasure of chatting with Andrea Cruz, Head of B2B at Tinuiti. We delved into a challenge that many senior marketers face: the struggle of providing immediate answers when clients press for details without prior notice.

    We explored how missteps in communication can amplify client stress, and how adopting a proactive mindset can turn these challenges into pivotal moments of growth in one’s career.

    As Cruz progressed from a hands-on marketer to leading entire teams, she encountered the challenge of advocating for projects she wasn’t directly managing daily. This shift brought new struggles, especially when clients questioned campaign performance or outcomes.

    In those moments, freezing or delaying responses can damage trust. Cruz realized that senior leaders must offer clear direction, even without knowing every detail, to maintain confidence in discussions.

    Through her experiences and mentorship, Cruz honed a technique for buying time without losing trust: asking thoughtful questions. This strategy not only buys time but also ensures that the responses are precise and address the core of the client’s concerns.

    Her method includes asking clients to clarify expectations, requesting additional context, and confirming their understanding. This approach is crucial, especially in emotionally charged situations, and, for Cruz, it allowed her to manage complex conversations effectively despite being a non-native English speaker.

    At Tinuiti, the focus is on a solutions-driven culture over assigning blame. By addressing ‘Where are we now?’ and ‘How do we get where we want to be?’, teams foster a safe space to discuss errors and learn from them. Cruz believes that leaders should set the standard by openly sharing their own mistakes.

    Cruz advocates for proactive communication, urging teams to address issues before clients notice. Tailoring communication styles to client preferences fosters stronger relationships and transforms agencies into strategic partners.

    Common mistakes in B2B advertising include spreading budgets too thin and underfunding campaigns. Cruz emphasizes that it’s better to focus on fewer channels with adequate resources to avoid ineffective outcomes.

    Regarding AI, Cruz warns against limiting its use to basic tasks and shares how her team is leveraging AI for advanced operations, enhancing strategic execution.

    Cruz’s message is clear: growth requires preparation and a willingness to adapt. By anticipating client needs and embracing experimentation, marketers can turn pressure into golden opportunities.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • SaaS AI Referral Traffic Is Down: A Practical Diagnostic

    SaaS AI Referral Traffic Is Down: A Practical Diagnostic

    Your SaaS dashboard shows fewer visits from AI assistants. Before you rewrite the content roadmap or declare the channel dead, find out exactly which line moved. A fall in standalone-assistant referrals, a shift toward workflow-embedded tools, and poor landing-page routing are three different problems. They require three different responses.

    The goal isn’t to recover every lost session. It is to make your product easy to retrieve at the right moment, send qualified users to a page that resolves their question, and measure whether those visits produce meaningful actions.

    Key takeaways

    • A decline in attributed AI referrals is not the same as a decline in AI visibility. Referral analytics capture recognized visits, not every citation, recommendation, or answer that produces no click.
    • The widely discussed 53% decline applied to standalone AI discovery sessions in one SaaS dataset. It occurred while workflow-embedded Copilot traffic grew by more than 20 times, so the pattern is better read as channel redistribution than universal disappearance.
    • Internal search deserves its own landing-page segment. About 41% of the dataset’s LLM sessions landed on search-result pages, which can reveal that an assistant could not identify a better direct answer.
    • Compare equivalent buying periods. The dataset peaked in July and weakened through Q4, making a simple month-over-month chart especially easy to misread.
    • Prioritize landing-page relevance, qualified actions, referrer mix, and content penetration. Total sessions alone cannot tell you whether your AI search strategy is improving.

    Read the decline as a distribution problem first

    The 53% figure does not establish that every SaaS company lost half its AI audience. It describes a decline in discovery sessions from standalone AI tools within a particular dataset. Between November 2024 and December 2025, that dataset recorded 774,331 sessions attributed to large language models.

    Its referrer mix was highly concentrated: ChatGPT accounted for 82.3% of the sessions. When one platform supplies that much traffic, a change in its usage, interfaces, link behavior, or audience mix can dominate the aggregate chart. A top-line decline can therefore hide growth elsewhere.

    Copilot demonstrates the point. It generated 148 sessions near the end of 2024, grew by more than 20 times by May 2025, and then averaged 3,822 sessions per month from June through December. It had become the second-largest AI referrer by the end of 2025.

    The pattern is consistent with intent moving into the user’s existing workflow. Someone already working in an embedded assistant may ask a product or implementation question without opening a separate discovery tool. That does not settle the larger question of whether agents will replace parts of SaaS. It does tell you that measuring all AI platforms as one homogeneous channel will produce poor decisions.

    Start by classifying the shape of your own decline:

    Pattern in your analyticsWorking interpretationNext check
    Standalone assistants fall while an embedded assistant growsReferrer mix is changingCompare landing pages, intent, and conversion by platform
    AI and other non-paid channels weaken in the same periodDemand or B2B seasonality may be involvedCompare equivalent periods and commercial outcomes
    AI sessions increasingly land on internal searchAssistants may not be resolving a direct destinationInspect the query, result quality, and crawl path
    AI sessions fall but qualified actions hold steadyLost visits may have been lower-value, or attribution may have shiftedReview conversion counts, not only conversion rate
    Sessions hold steady while qualified actions fallLanding-page relevance or intent quality has deterioratedAudit the promise-to-page match for the affected referrers

    These are diagnostic hypotheses, not conclusions. Use them to choose the next report or page inspection rather than to explain the result in advance.

    Audit measurement before changing your content

    A magnifying lens reveals a hidden signal path beside an abstract attribution funnel and tracking nodes on an analyst workstation.

    An analytics tool’s AI channel is a record of identifiable referrals. It is not a complete count of how often an assistant mentions your company, uses your information, recommends your product, or answers a question without sending a visit. Call the metric what it is: attributed AI referral sessions.

    Lock the channel definition

    Export the referrer rules behind your AI segment. Keep the same platform list, source normalization, bot filtering, and session definition throughout the comparison. If you add a newly discovered referrer halfway through the audit, recalculate the earlier period under the same rule set. Otherwise, taxonomy maintenance will look like growth.

    Keep an explicit “unknown or unclassified” bucket. Do not silently assign direct traffic to AI just because a visitor viewed an AI-oriented page. That may be a useful hypothesis for investigation, but it is not referrer evidence.

    Build a platform-by-page-type view

    For each complete month, split AI referrals by platform and landing-page template. At minimum, separate the homepage, product or feature pages, pricing, comparisons, documentation, blog content, and internal search results. Preserve the full landing URL in the underlying export so query parameters do not disappear inside a grouped page report.

    This matrix exposes changes that a channel total conceals. ChatGPT might stop sending exploratory blog visits while Copilot begins sending fewer but more commercial visits to product documentation. Calling that a single traffic decline would erase the useful part of the change.

    Use seasonally comparable periods

    SaaS discovery in the observed dataset peaked in July and declined through Q4, alongside normal B2B work, budget, and holiday cycles. That is not a universal calendar for every SaaS company. It is a warning against treating an autumn-to-December decline as proof of an AI-specific loss.

    Compare the same quarter year over year when you have consistent data. If you do not, compare AI referrals with non-paid search, direct visits, demo activity, and other demand indicators over the same months. A decline shared across channels points toward a different diagnosis than an isolated fall from one AI platform.

    Measure penetration, relevance, and outcomes

    Create a small scorecard with definitions your team can reproduce:

    • Referrer share: each AI platform’s sessions divided by all attributed AI referral sessions. This shows concentration and redistribution.
    • Landing-page relevance rate: AI sessions reaching a page that directly answers the apparent intent divided by all AI sessions. Define the intended destination for each query or intent class before scoring it.
    • Commercial action rate: trials, demos, sign-ups, or another agreed activation event divided by AI sessions. Report the action count beside the rate so a tiny denominator does not mislead you.
    • AI landing-page penetration: eligible product, comparison, pricing, and answer pages receiving at least one attributed AI visit divided by all eligible pages. Use this as an internal coverage metric, not an industry benchmark.
    • Search-result dependency: AI sessions landing on internal search divided by all AI sessions. A rising share deserves a query-level inspection even when total traffic is stable.

    Keep visibility and referral performance as separate columns. If you monitor assistant mentions or citations, compare them with clicks rather than combining them into an invented all-purpose score. Visibility can remain stable while click behavior changes.

    Treat internal search landings as a retrieval clue

    A search beam selects one webpage tile from a floating digital library and connects it to a brightly lit destination doorway.

    Internal search was the largest destination class in the observed traffic. Search-result pages received 320,615 sessions, or about 41% of all LLM referrals, exceeding blog, pricing, and product destinations.

    That does not mean internal search was the best content. A more useful interpretation is that the assistant found a searchable route but not a confident direct answer. Your search interface became a fallback discovery layer.

    Open the top AI-referred search URLs and inspect them as a user and as a crawler:

    • Reproduce the query from the landing URL. Confirm that it returns relevant results rather than an empty state, generic category, or different query after a redirect.
    • Check whether the public result can be fetched without authentication, cookies, or a browser-only interaction. If useful results appear only after client-side execution, provide a crawlable path to the primary answer.
    • Expose the query, result summary, and important destination links in visible HTML. A search shell with no meaningful server response gives an assistant little to interpret.
    • Verify the status code, robots directives, canonical target, and rendering behavior. A result page should not claim to be a successful answer while returning an error, canonicalizing to an unrelated page, or hiding every result from crawlers.
    • Trace each recurring high-intent query to its best permanent destination. If people repeatedly search for pricing, a named integration, a comparison, or a specific capability, create or improve the dedicated page and link it prominently.
    • Make the onward path explicit. A useful result should lead directly to the relevant product, pricing, comparison, documentation, or contact page instead of forcing another search.

    Do not respond by indexing every possible internal-search combination. Unlimited query parameters, spelling variants, and empty result sets can create a large collection of duplicate or low-value URLs. Keep crawlable search states finite and useful. Promote recurring, commercially meaningful questions into governed landing pages with stable URLs, original answers, and intentional internal links.

    Think of public search as an interface an AI system may use, not as a substitute for information architecture. If the same search query repeatedly attracts referrals, the durable fix is usually a direct answer page that no longer requires the fallback.

    Rebuild around moments of intent, then test one cycle

    Workflow-embedded assistants change when discovery happens. The user may already be writing a specification, comparing tools, diagnosing an integration, or preparing a purchase request. Your page has to resolve that immediate task. A broad brand narrative is rarely enough on its own.

    User’s moment of intentBest destinationInformation that must be visible
    “What does it cost?”Pricing or plan pagePricing basis, plan differences, limits, conditions, and the next buying step
    “Can it handle this use case?”Capability or use-case pageDirect answer, supported inputs, prerequisites, limitations, and a relevant example
    “How does it compare?”Comparison pageDecision criteria, material differences, suitability, migration considerations, and current facts
    “How do I complete this task?”Documentation or task pagePrerequisites, ordered steps, expected result, failure points, and the appropriate next action
    “Where is the relevant feature or resource?”Help, navigation, or curated search pageExact destination, concise context, and direct links without another discovery loop

    Make critical facts available in the main page content. Do not leave pricing conditions, compatibility, product limits, or differentiators only inside images, tabs that never render for a crawler, or downloadable collateral. Clear headings, concise answers, comparison tables, and descriptive internal links make the page easier for people and retrieval systems to interpret. The broader SaaS pattern favors transparent, crawlable, comparison-oriented information.

    Use structured data to clarify, not manufacture, the answer

    JSON-LD should describe the content a visitor can verify. Use the most accurate entity types for the page, such as Organization and SoftwareApplication where they genuinely apply. Represent offers only when the visible pricing information is current and complete enough to support them. Use FAQPage only for questions and answers that are actually present for the reader, and BreadcrumbList only when it reflects the real hierarchy.

    Keep names, URLs, product descriptions, and relationships consistent between markup and visible copy. Do not stack loosely related schema types in the hope of earning AI visibility. Structured data can reduce ambiguity; it cannot repair a missing price, an evasive comparison, an inaccessible result, or an unsupported claim.

    Run a controlled repair cycle

    1. Freeze the baseline. Save monthly sessions, referrer share, landing-page type, search-result dependency, qualified actions, and your current channel rules.
    2. Choose pages from three evidence-backed groups: high-intent pages receiving no AI referrals, internal-search URLs receiving AI referrals, and pages that attract visits but fail to resolve the apparent intent.
    3. Repair the answer path. Put decisive facts in visible content, connect recurring searches to permanent destinations, improve internal links, and align JSON-LD with the finished page.
    4. Annotate the publication and crawl dates. Keep unrelated template and attribution changes out of the same evaluation window where practical.
    5. Review one complete reporting period using the frozen definitions. Compare platform mix, relevant landings, action counts, and search dependency before looking at the aggregate traffic line.

    The decision after that cycle should follow the observed failure. If one referrer is shrinking while another is growing, adapt destinations to the growing moment of intent. If search-result dependency is rising, repair retrieval and information architecture. If comparable periods weaken across several acquisition channels, do not blame AI alone. If qualified actions hold while raw visits fall, protect the pages producing those actions before chasing volume.

    Your first move can be small: open a platform-by-page-type report, select the highest-traffic internal-search landing, and follow its path to the page that should have answered the query directly. Repairing that path gives you a measurable change. A generic push to publish more does not.

    References

  • The Medtech Marketing Agency Landscape: A 2026 Guide

    The Medtech Marketing Agency Landscape: A 2026 Guide

    You can waste a substantial budget on a capable medtech marketing agency if it solves the wrong problem. A trade show specialist, brand studio, account-based marketing team, enterprise media firm, and organic authority partner can all make persuasive pitches, but they are built for different jobs.

    Your first decision is therefore not which agency is best. It is which commercial constraint must change next. Once you name that constraint, the medtech agency landscape becomes much easier to navigate.

    Choose the bottleneck before you choose the agency

    Write a one-sentence diagnosis before you schedule discovery calls: “Our immediate constraint is [problem], among [audience], at [stage of the buying journey], and progress means [business outcome].” If your team cannot complete that sentence, an agency will fill the gap with the services it already sells.

    Route your search according to the job that needs to be done:

    • You need sustained discovery and qualified inbound demand. Look for thought leadership, technical content, SEO, and generative engine optimization. The agency should be able to connect visibility with a defined conversion path, not merely publish content.
    • You need paid reach at enterprise scale. Look for media buying, audience data, analytics, creative production, landing-page support, and a clear handoff into your CRM and sales process.
    • Your product is difficult to explain or your company is preparing to raise capital. Start with positioning, message architecture, visual identity, and materials that can be used consistently in customer and investor conversations.
    • A conference or trade show is the immediate commercial event. A booth specialist can solve the physical experience, but your scope also needs lead capture, meeting preparation, and post-event follow-up.
    • Your market consists of a finite group of valuable organizations. Account-based marketing is the natural lane. The agency must show how marketing and sales will coordinate around named accounts and multiple stakeholders.
    • You need a coordinated device launch or brand program across several channels. An integrated medtech agency may reduce handoff friction, provided it has genuine depth in the channels that matter to you.

    Do not treat “full service” as automatically better. Breadth helps when your problem crosses channels. It creates unnecessary cost and management overhead when you only need a specialist intervention.

    Seven agencies occupy distinct positions in the 2026 landscape

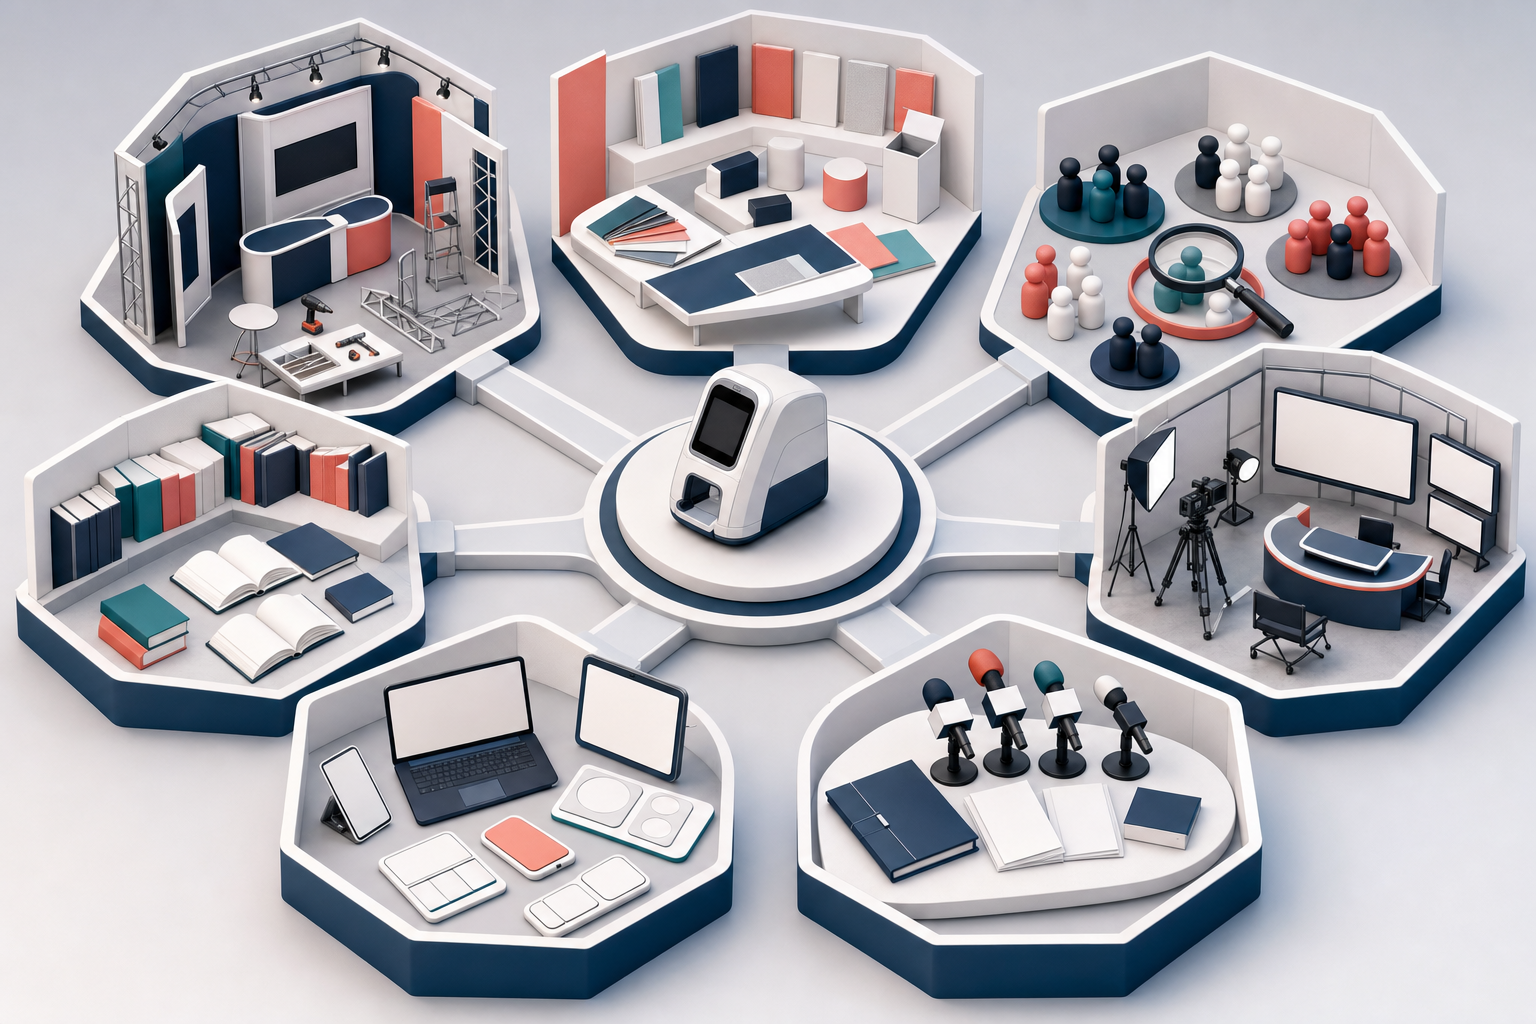
    Seven different agency work areas surround a central diagnostic device, with each area represented by tools for a distinct marketing specialty.

    The profiles below reflect a market snapshot updated January 26, 2026. Use them as routing information for a shortlist, not as a substitute for current due diligence. Company size, staffing, client relationships, and service emphasis can change.

    AgencyPrimary laneReported organizational contextWhat you should verify
    First Page SageThought leadership combined with SEO and GEO for lead generationFounder-led; founded in 2009; reported size of 100-250; named work includes Biovia and AltoidaAsk how search visibility, visibility in generative answers, and content engagement connect to qualified lead definitions. Expect a detailed onboarding process and confirm what your subject-matter experts must contribute.
    EpsilonEnterprise, full-service marketing with a concentration in paid advertising and data analyticsNot founder-led; founded in 1969; reported size of 1,000+; named work includes Visionworks and WalgreensClarify the dedicated delivery team, minimum viable scope, data requirements, and total operating cost. Enterprise capacity has little value if your account receives a generic team or more infrastructure than it needs.
    Parker WhiteBrand development and creative marketing for medical and lifestyle brands, including B2C and B2B workFounder-led; founded in 1997; reported size of 11-50; named work includes Orthofix and FUJIFILM SonositeIf pipeline is the goal, ask who owns distribution, conversion, and measurement after the brand work is finished. A strong identity is not automatically a demand-generation system.
    Distill HealthBrand strategy and visual identity for medtech companies preparing for fundingFounder-led; founded in 2018; reported size of 1-10; named work includes Theragen and NuvaraConfirm capacity, access to senior staff, the customer or investor validation process, and who executes the brand after fundraising preparation. No marketing agency can promise that branding will secure funding.
    ExponentsTrade show booth design, manufacturing, and installationNot founder-led; founded in 1985; reported size of 11-50; named work includes HealthGridDefine the boundary between booth delivery and campaign delivery. Assign responsibility for pre-event outreach, appointments, lead qualification, data capture, and follow-up to Exponents, another partner, or your internal team.
    The ABM AgencyOmnichannel account-based marketing for high-value organizational buyersFounder-led; founded in 2007; reported size of 11-50; named work includes MedPost and Care SpotAsk how accounts are selected, how buying-committee roles are mapped, what sales must do, and how engaged accounts become opportunities. Also clarify cost before assuming ABM is efficient for your market.
    IcovyIntegrated branding, multimedia, and traditional marketing for medical device companiesFounder-led; founded in 2019; reported size of 11-50; named work includes Poba Medical and Kaneka MedicalIdentify the named specialist for every channel in your scope. Determine what is delivered in-house, what is subcontracted, and who owns integration, reporting, and corrective decisions.

    These firms are not interchangeable entries in a league table. Epsilon’s enterprise scale does not make it the natural choice for a startup that needs investor-ready positioning. Distill Health’s funding-oriented brand work does not make it the default choice for a mature manufacturer seeking paid media at scale. Exponents may be highly relevant to a conference deadline while remaining intentionally narrow outside the trade show itself.

    Founder involvement, company age, and headcount are context rather than outcomes. A founder-led specialist may offer direct senior attention, but you still need to know who will perform the weekly work. A large firm may provide broader capabilities and resilience, but you still need a dedicated team with relevant experience.

    Turn agency credentials into evidence of fit

    Two people evaluate unbranded project samples, process materials, and a medical device prototype on a conference table.

    For initial market screening, notable clients carry 35% of the evaluation, founder status and leadership experience 20%, company age and employee tenure 15%, marketing approach 15%, reviews 10%, and media references 5%. Those inputs are useful, but your buying decision should test what each signal actually means for your assignment.

    • Client names establish adjacency, not success. Ask what the agency delivered, which audience it addressed, how long the work ran, and what changed. A recognizable logo can represent a small project that bears little resemblance to your scope.
    • Relevant similarity is multidimensional. Product category alone is not enough. Compare the buyer, sales motion, company stage, geographic scope, channel, and internal review process. A consumer campaign and a hospital-enterprise sale can require very different work even when both sit under the medtech label.
    • Leadership experience matters only if it reaches delivery. Ask who joins the pitch, who designs the strategy, who manages the account, and who creates the work. Get those roles into the scope. Do not assume the founder or senior strategist in discovery will remain involved.
    • Tenure is a continuity clue. Within this group, reported median employee tenure ranges from 1.7 years at The ABM Agency to 4.6 years at Epsilon. That does not prove quality, but it gives you a reason to ask about turnover, backup coverage, and knowledge transfer.
    • Reviews require context. Look for comments about the type of work you are buying, responsiveness when a campaign underperforms, and the quality of project oversight. A high average without detail cannot tell you whether the agency can solve your problem.
    • Media references indicate visibility, not operational competence. They can support an authority assessment, but they do not replace current work samples, named team members, a delivery plan, or access to reporting.

    Ask every shortlisted agency to walk through a documented engagement that resembles your situation. Have it explain the starting constraint, its exact scope, the client responsibilities, the approval path, the deliverables, and the business result. If the answer skips from a client logo directly to an outcome, the missing middle is where delivery risk usually sits.

    Medtech work also needs an explicit claims-review workflow. Your internal medical, legal, regulatory, or quality reviewers may own approval, but the agency must know when review occurs, how revisions are tracked, and which version is cleared for each channel. If this process remains vague, timelines and budgets can deteriorate after production begins.

    Write a scope that matches the agency lane

    A useful brief does more than list services. Use this structure: “Help [audience] move from [current state] to [conversion or commercial outcome] by producing [deliverables], distributing them through [channels], and reporting [business and diagnostic measures].” Add your approval roles, required systems, ownership terms, dependencies, and exclusions.

    For SEO, thought leadership, and GEO

    Name the technical themes, buyer questions, priority audiences, conversion events, subject-matter experts, and owned properties in scope. Require the agency to distinguish traditional search performance from observed brand inclusion or citation in generative answers. Both can contribute to discovery, but they are not the same measurement.

    Qualified organic inquiries, target-account visits, completed demo or consultation requests, coverage of problem-led searches, and observed AI-answer visibility are more useful together than traffic alone. Traffic remains a diagnostic measure. It is not proof that the right buyer understood the product or entered a sales conversation.

    For paid media and integrated campaigns

    Specify the audience data, media channels, creative formats, landing pages, tracking, CRM handoff, and approval workflow. Decide who owns media accounts, analytics access, campaign data, source files, and website changes. Your organization should retain administrative access to the systems and assets it is paying to build; losing access can make a future agency transition expensive and slow.

    Make qualified opportunities and pipeline the commercial measures when your sales cycle supports them. Use accepted leads, qualified conversations, landing-page conversion, and acquisition cost as operating indicators. Click-through rate and impressions can diagnose a campaign, but they should not become substitutes for business progress.

    For account-based marketing

    Define how target accounts enter the program, which stakeholder roles matter, what sales will do, which messages vary by role, and how engagement is recorded. ABM fails quietly when marketing runs account-targeted ads while sales follows an unrelated list and neither side owns the handoff.

    Track meaningful engagement across the buying group, meetings with relevant roles, account progression, opportunities, and pipeline. Raw account impressions are not enough. Your agency should also explain what evidence causes it to intensify, change, or stop work on an account.

    For branding, fundraising preparation, and trade shows

    A brand scope should name the positioning decision, message architecture, visual system, required customer or investor materials, validation method, and internal approvers. Define how the system will reach the website, sales materials, presentations, and campaigns. Otherwise, you can finish with an attractive identity that the commercial team cannot apply consistently.

    A trade show scope should connect the physical booth with pre-event outreach, meeting booking, on-site data capture, lead qualification, CRM entry, and follow-up. If the booth provider does not offer those services, assign them elsewhere before the event. Booth traffic is an incomplete result; qualified conversations and subsequent opportunities are the commercial test.

    In every lane, separate agency deliverables from client dependencies. Technical interviews, product access, approved claims, customer references, CRM configuration, and executive sign-off can all sit with your team. Put each dependency beside an owner and approval path so neither side can hide a preventable delay inside a status report.

    Key takeaways: use the pitch to expose delivery risk

    • State the bottleneck first: What precise commercial constraint will this engagement change, and which business outcome will show that it changed?
    • Interrogate the closest example: Which past engagement most closely matches your buyer, product stage, sales motion, and channel? What did the agency itself deliver?
    • Name the working team: Who owns strategy, account management, content or creative production, media, analytics, and claims coordination after the pitch?
    • Expose outside dependencies: Which services are subcontracted, which require another partner, and which depend on your internal experts or systems?
    • Map the approval process: When do technical and claims reviews happen, who resolves conflicting feedback, and how are approved versions controlled?
    • Protect ownership: Who owns the ad accounts, analytics properties, audience data, CRM records, domains, website access, source files, and finished assets?
    • Demand decision-grade reporting: Which measures represent commercial outcomes, which are leading indicators, and which merely diagnose activity?
    • Set correction rules: What evidence will cause the agency to change the message, channel, audience, budget allocation, or scope?

    Send the same written brief to every agency on your shortlist and insist that each response addresses the same outcome, responsibilities, evidence, and ownership terms. That makes proposals comparable and prevents a polished pitch from redefining your problem around an agency’s preferred services.

    Choose the partner whose lane matches your immediate constraint, whose relevant work survives detailed questioning, and whose named team can explain how delivery becomes a measurable business result. That is a stronger basis for a decision than rank, reputation, or breadth alone.

    References

  • Paid AI Advertising: A Campaign Optimization Framework

    Paid AI Advertising: A Campaign Optimization Framework

    You’re being asked to put paid media into AI environments, but the budget question has arrived before the measurement plan. One option sells visibility inside an AI conversation. Another uses AI to distribute campaigns across established ad inventory. Treating them as the same thing is how an expensive pilot ends with plenty of activity and no defensible conclusion.

    Before you spend, decide whether you are buying attention, teaching an automated campaign system to find valuable outcomes, or proving incremental impact. Those are different jobs. Each needs its own success metric, data inputs, and testing method.

    Separate AI ad placement from AI campaign optimization

    A split illustration contrasts an unbranded product placed inside a text-free AI conversation with an automated system distributing campaign signals across multiple advertising surfaces.

    Conversational AI inventory is a placement. You pay to appear within an AI product and receive whatever reporting that product makes available. The early ChatGPT ad offer has reportedly been priced at around $60 per 1,000 impressions, roughly three times the rate of standard Meta advertising. Advertisers may initially receive basic totals such as impressions and clicks without purchase-level reporting.

    That measurement ceiling changes the campaign’s proper role. If you cannot observe purchases or other downstream outcomes in the ad platform, you cannot honestly manage the placement like a mature direct-response channel. You can test reach, click response, message-market fit, and post-click behavior in systems you control. You cannot turn an impression-and-click report into a reliable platform ROAS calculation.

    Initial ChatGPT ad availability is expected to focus on free and lower-cost Go users, while excluding people under 18 and conversations involving sensitive subjects such as mental health or politics. Those rules help define where ads may appear, but they do not tell you whether the reachable audience matches your buyers. Confirm audience fit before treating the environment itself as proof of media quality.

    Performance Max is a different use of AI. It is a goal-based campaign model spanning Search, YouTube, Display, Discover, Gmail, Maps, and emerging inventory in AI Overviews. You are not simply purchasing an isolated AI placement. You are giving an automated system a business objective, conversion signals, creative assets, and permission to allocate delivery across Google’s inventory.

    DecisionConversational AI placementAI-optimized campaign
    What you are buyingVisibility within an AI productAutomated delivery across multiple channels
    Main information available to the systemPlacement context and the product’s available targetingConversion goals, audience signals, customer data, and creative assets
    Best initial useBrand visibility and format learningDemand capture or demand generation tied to meaningful outcomes
    Critical limitationIncomplete attribution can prevent performance-level conclusionsWeak conversion signals can teach the system to pursue low-value actions

    Neither model is inherently better. The useful question is whether you want to buy attention in a new environment or delegate campaign allocation to an outcome-driven system. If your brief cannot answer that question in one sentence, it is not ready for budget approval.

    Set the campaign job and evidence standard before the budget

    A premium CPM makes an undefined learning campaign expensive. At a reported $60 CPM, 50,000 impressions represent $3,000 in media, while 100,000 impressions represent $6,000. Those figures are not performance forecasts. They are the budget identity: planned impressions divided by 1,000, multiplied by CPM.

    Use that calculation before you debate creative or targeting. Decide how much exposure is necessary to answer a defined question, then price the test. Do not start with an arbitrary budget and invent a purpose after delivery begins.

    A workable campaign charter should state six things:

    1. The decision: Name what you will do differently when the test ends. Examples include rejecting the placement, revising the message, expanding the test, or moving budget into a controlled lift experiment.
    2. The hypothesis: Describe the audience, message, environment, and expected behavior. “Test AI ads” is an activity, not a hypothesis.
    3. The campaign job: Choose visibility, qualified demand, or incrementality. Do not make one campaign responsible for all three.
    4. The primary outcome: Use delivered impressions or click response for a visibility test, a CRM-qualified event for performance optimization, or lift for an incremental-impact test.
    5. The spending limit: Set the maximum media outlay before launch. A learning objective is not permission for an open-ended budget.
    6. The claim boundary: Write down what the available evidence will not prove. If the platform reports only impressions and clicks, state in advance that the platform report will not prove purchase impact.

    Use a measurement ladder instead of one dashboard

    Each measurement layer answers a different question. Keeping those questions separate prevents attribution language from outrunning the evidence.

    • Platform delivery data: Impressions show that ads were served. Clicks and click-through rate show an immediate response. They do not show whether the campaign created revenue.
    • Owned post-click analytics: A dedicated or properly tagged destination can show what visitors did after clicking, subject to your consent and analytics setup. This connects traffic to on-site behavior, but it does not prove that the same behavior would not have happened without the campaign.
    • CRM outcomes: Qualified leads, appointments, opportunities, and eventual revenue help you distinguish valuable responses from easy conversions. Preserve the campaign identifier through the handoff so the business outcome can be associated with its acquisition path.
    • Controlled experiments and lift: A suitable control or lift design addresses the incremental question: what changed because the campaign ran?

    OpenAI has paired its advertising plans with commitments not to sell user data or compromise the privacy of conversations. That stance may constrain the user-level targeting and attribution methods advertisers know from Google and Meta. Build the plan around aggregated platform reporting and consented, first-party post-click measurement. Do not base the business case on conversation-level data you hope might become available later.

    Give campaign automation a business outcome it cannot misread

    An automated campaign will pursue the success signal you provide, even when that signal is a poor substitute for business value. If every form submission is treated as equally valuable, the system has no reason to distinguish a sales-ready buyer from a vendor, student, job applicant, or unqualified prospect.

    Performance Max therefore needs a conversion architecture before it needs more creative. For a B2B campaign, put these elements in place first:

    1. Connect the CRM or other business data source. Salesforce is one example, but the brand matters less than the handoff. The advertising system needs a path from the online action to a meaningful business status.
    2. Select a revenue-relevant conversion event. A qualified lead submission or booked appointment is more informative than an unfiltered form fill when qualification is part of the sales process.
    3. Separate optimization events from diagnostic events. Page views, content interactions, and raw leads can help diagnose the journey without being treated as equal optimization targets.
    4. Supply a customer list when appropriate and permitted. First-party customer data gives the system characteristics it can use for modeling and can be more useful than relying on website remarketing audiences alone.
    5. Choose an outcome-based bid strategy. Maximize conversions and target CPA are aligned with the campaign model’s focus on outcomes rather than traffic alone.
    6. Protect the learning process from constant intervention. Frequent targeting, bidding, or structural changes alter the problem the system is trying to solve. Route substantial changes through planned experiments instead of repeatedly editing the live campaign.

    Check whether your market can support automation

    Good conversion plumbing does not make every market suitable for Performance Max. The system also needs room to find patterns and scale delivery.

    • Use automation when the addressable market is broad enough. A larger market gives the system more opportunities to learn which signals correlate with meaningful outcomes.
    • Keep manual control for tightly bounded account-based programs. If success depends on reaching only a few hundred named accounts, broad automated allocation may conflict with the strategy.
    • Be cautious in extremely narrow categories. Too little audience and conversion data can prevent useful scaling, regardless of the campaign’s technical setup.
    • Confirm organizational readiness. A team that cannot tolerate automated allocation or repeatedly overrides it may destabilize the campaign before it can produce interpretable evidence.

    The strongest B2B use case is a sizable market with a long buying cycle and several stakeholders. Cross-network delivery can maintain a presence around that buying group beyond a single search interaction. But sustained visibility only becomes optimizable when the conversion signal reflects genuine progress through the sales process.

    Optimize with controlled tests, not reactive campaign edits

    Two matched campaign test lanes carry audience tokens toward outcome vessels while an analyst observes the single highlighted difference between them.

    Optimization is a sequence of decisions. It is not the habit of changing bids, audiences, and creative whenever a dashboard moves. When several variables change together, you lose the ability to tell which change caused the result.

    Google’s Experiment Center brings campaign experiments and lift studies into one location. It can support tests involving bidding, targeting, and creative, alongside brand, search, and conversion lift measurement. Expanded A/B testing for Shopping and Performance Max, plus a Campaign Mix Experiments beta, provides more ways to validate a change before scaling it where those features are available.

    Run tests in an order that protects the quality of later conclusions:

    1. Validate conversion quality. Confirm that the primary event represents business value and reaches the campaign correctly. A creative or bidding test is difficult to interpret when the success label is unreliable.
    2. Test the proposition and creative. Compare a specific message or asset treatment against the control. Do not replace the audience, bid strategy, landing page, and creative in the same test.
    3. Test targeting or audience signals. Once the outcome and message are credible, determine whether a different signal set finds more of the right response.
    4. Test bidding and campaign mix. Evaluate allocation changes after the campaign is measuring the right outcome. Otherwise, you may simply become more efficient at acquiring the wrong conversion.
    5. Use lift when the question is causality. Platform attribution can associate an outcome with an ad interaction. Lift is the more relevant design when you need to know whether advertising generated an outcome that would not otherwise have occurred.

    Every experiment record should include the hypothesis, control, variant, primary outcome, guardrails, stopping rule, result, and resulting action. Define those fields before launch. A stopping rule created after seeing the data is an invitation to keep running a preferred result and stop an inconvenient one.

    The pattern across measurement layers matters more than any isolated metric:

    • If reported conversions rise while CRM-qualified outcomes stay flat, the campaign has probably improved the proxy rather than the business result. Fix the conversion signal before scaling.
    • If clicks rise but qualified outcomes do not, the creative may be attracting curiosity instead of buying intent, or the landing experience may not fulfill the ad’s promise. A higher click-through rate is not enough to choose between those explanations.
    • If reach is strong but you have no control or lift measurement, you can report delivery. You cannot claim that awareness increased merely because impressions were purchased.
    • If a lift test shows an incremental effect that last-click reporting misses, evaluate the cost of that lift against the value of the outcome. Do not discard incrementality solely because it appears in a different reporting layer.

    This is where campaign optimization and AI-search strategy meet. Paid visibility can create exposure while organic AI optimization works toward durable discovery, but the two should not be blended into one performance claim. Track paid placement, post-click behavior, CRM outcomes, and organic visibility as distinct evidence streams. Combine them only when the measurement design supports the connection.

    Key takeaways

    • Decide whether you are buying an AI placement or using AI to automate campaign delivery. They require different data and success criteria.
    • Treat a conversational placement with impression-and-click reporting as a visibility or learning test unless your owned systems can support a stronger, clearly qualified conclusion.
    • Price the learning question before launch. At a reported $60 CPM, every 50,000 impressions represents $3,000 in media spend.
    • Connect Performance Max to CRM-qualified outcomes, not just easy website actions, and use it only where the addressable market gives automation room to learn.
    • Move consequential changes into controlled experiments. Test conversion quality before creative, targeting, bidding, or campaign mix.
    • Match every claim to its evidence layer: delivery for exposure, CRM data for associated business outcomes, and lift testing for incrementality.

    Your next step is small but decisive: write one sentence naming the campaign’s job, then name the strongest outcome you can actually observe. If the job requires evidence your current setup cannot produce, repair the measurement plan or narrow the claim before you approve the spend.

    References

  • How to Choose an Industrial Marketing Agency That Fits

    How to Choose an Industrial Marketing Agency That Fits

    If you are choosing an industrial marketing agency, a polished proposal is the easy part. The harder question is whether the team can learn a technical offer, earn access to your subject-matter experts, reach the people involved in the purchase, and show what became qualified pipeline.

    A candidate pool gives you names. A disciplined selection process tells you which agency can actually do the work. Use the framework below to prepare your brief, test technical fluency, compare proposals, and protect the engagement before you sign.

    Write the buying brief before you build the shortlist

    Do not begin with a list of services you think you need. Begin with the commercial problem the agency must help solve. Otherwise, every proposal will describe a different interpretation of success, and you will be comparing presentation quality rather than strategic fit.

    Prepare a compact decision brief with the following information:

    • Commercial outcome: State whether the priority is qualified pipeline, entry into a market, distributor support, aftermarket growth, account expansion, product adoption, or another defined business result.
    • Offer boundary: Name the products, services, applications, territories, and customer segments that are in scope. Identify what is explicitly out of scope.
    • Buying group: List the people who use, specify, approve, purchase, install, maintain, or resell the offer. Do not flatten them into a generic buyer persona.
    • Available evidence: Inventory approved specifications, certifications, performance data, technical drawings, case material, expert commentary, customer proof, and product imagery. Mark anything that requires legal, engineering, or customer approval.
    • Valuable conversion: Define the actions that matter, such as a qualified request for quote, sample request, site visit, consultation, drawing download, specification download, phone call, or distributor inquiry.
    • Measurement path: Identify the CRM stages, lead-status definitions, sales owner, and reporting systems that will determine whether marketing activity produced useful demand.
    • Operating constraints: Document restricted claims, regulatory reviews, channel conflicts, brand requirements, development limitations, subject-matter expert availability, and internal approval steps.

    Replace goals such as “increase awareness” or “generate leads” with language your sales team can recognize. For example, define what information an inquiry must contain before sales can quote it, which customer types are commercially attractive, and which inquiries should be excluded. If marketing and sales cannot agree on a qualified inquiry, an agency cannot optimize toward one.

    Set your disqualifiers at the same time. These might include weak analytics capability, no technical review process, outsourced execution with no named owner, unclear account ownership, or an unwillingness to work inside your claims-approval rules. A disqualifier should remain a disqualifier even when the pitch is impressive.

    Test industrial fluency with a real working session

    A plant engineer explains an opened industrial pump assembly to two marketing specialists during a hands-on workshop.

    An agency does not need to arrive knowing every detail of your process. It does need a credible method for learning technical material without turning it into vague benefit copy. You can see that method more clearly in a working session than in a capabilities deck.

    Give each finalist the same public product or service page and the same application context. Ask the proposed team to work through these questions with you:

    • What does the offer do, where does it fit, and where does it not fit?
    • Which facts are clear, which are unsupported, and which require an expert to verify?
    • Who uses the offer, who specifies it, who approves it, and who controls the purchase?
    • What operational problem brings a buyer to the page, and what information would help that buyer continue evaluating?
    • What proof would make the central claim credible?
    • Which search questions, comparison questions, and implementation questions should the content answer?
    • What should the visitor do next, and what would make that action useful to sales?
    • What would the team need from engineering, product, sales, service, compliance, or distribution before publishing?

    Pay attention to the questions the agency asks. Strong discovery separates facts from assumptions, notices exclusions and tradeoffs, and identifies the internal expert who can resolve each uncertainty. Weak discovery paraphrases the existing page, adds generic adjectives, and starts recommending channels before the buying problem is understood.

    Ask for evidence of the working process, not just customer logos. Useful evidence can include a redacted content brief, an interview guide for a technical expert, a claims-review workflow, a campaign measurement specification, a reporting example, or a before-and-after explanation of how a technical page was improved. The closest match is not always an identical industry. Comparable product complexity, buying risk, sales motion, and review constraints can be more revealing than a familiar vertical label.

    Confirm who produced each example and whether those people will work on your account. Agency credentials matter less when the proposed delivery team did not create the work being shown.

    Judge the channel plan as a connected demand system

    Unbranded communication tools connect through illuminated cables to a transparent pipeline leading toward a sales meeting area.

    Industrial demand rarely fits neatly inside a single campaign report. A buyer may discover a problem through search, compare technical approaches, return through a branded query, download a drawing, speak with a distributor, and enter the CRM under a different source. Your agency should design the content, channels, conversion paths, and measurement rules as parts of the same system.

    Make technical content useful before making it plentiful

    Ask the agency to propose a page architecture based on buyer tasks, not a publishing quota. Depending on your offer, that architecture may include:

    • Product or service pages that explain fit, exclusions, specifications, constraints, evidence, and the appropriate next action.
    • Application pages that connect an operating condition or use case to a suitable solution without pretending every product fits every environment.
    • Technical answer pages that address selection, compatibility, troubleshooting, maintenance, installation, or implementation questions your experts can answer accurately.
    • Comparison and alternative pages that explain meaningful tradeoffs rather than declaring your offer universally superior.
    • Proof pages that organize approved performance evidence, certifications, case material, processes, and expert qualifications.
    • Commercial access pages that help a visitor request a quote, locate a distributor, submit project details, download the correct resource, or reach the appropriate team.

    For search, answer engines, and generative systems, the fundamentals still have to be present on the page. The agency should make products, services, applications, organizations, and expert claims unambiguous; answer important questions directly; connect related pages with purposeful internal links; and use applicable structured data that agrees with the visible content.

    Ask who selects the structured-data types, who validates the markup, how conflicts with existing plugins or templates are handled, and what triggers an update when the page changes. JSON-LD can clarify machine-readable facts. It cannot repair an unsupported claim, a confused page, or missing evidence. Treat guaranteed rankings, guaranteed AI citations, and guaranteed inclusion in generated answers as disqualifiers.

    The same discipline applies to paid search, paid social, email, industry media, distributor programs, and event support. For every proposed channel, require the agency to state:

    • Which audience condition or buying task the channel addresses.
    • Which offer and asset the audience will encounter.
    • Which next action is appropriate at that stage.
    • Which signal will indicate useful progress.
    • Which evidence would cause the team to change or stop the tactic.

    Make measurement survive the sales handoff

    A useful measurement design follows the path from campaign or source to landing page, conversion, CRM record, sales disposition, and opportunity. A dashboard that stops at impressions, clicks, rankings, or sessions cannot tell you whether the agency is attracting commercially relevant demand.

    Require a measurement specification before launch. It should identify each tracked action, the data captured with it, the CRM destination, the person responsible for follow-up, the treatment of duplicates and spam, and the check used to catch broken forms or tags. Campaign identifiers, call tracking, form fields, consent handling, and offline sales updates should fit the systems you actually use.

    Marketing should not invent revenue attribution after the fact, and sales should not leave every lead status blank. Agree on shared definitions before judging performance. The most useful report shows not only what happened, but which audience, message, page, offer, or channel should receive more investment, correction, or removal.

    Compare proposals by evidence, dependencies, and ownership

    Standardize your evaluation before proposals arrive. Mark each requirement as mandatory or preferred, then record the evidence as confirmed, assumed, or missing. This prevents a polished presentation from quietly compensating for a fatal weakness elsewhere.

    Evaluation areaEvidence to requestWarning sign
    Technical discoveryProduct and buyer hypotheses, open questions, expert-interview plan, and claims-review processGeneric personas and recommendations formed before technical discovery
    StrategyClear connection between the commercial objective, buyer task, channel role, offer, and conversionA menu of tactics with no decision logic
    Content qualityRepresentative brief, source requirements, technical review steps, and approval ownershipA production-volume promise with no accuracy workflow
    SEO, AEO, and GEOPage architecture, query and intent mapping, entity clarity, internal linking, structured-data governance, and update planGuaranteed rankings, citations, or generated-answer placement
    MeasurementEvent definitions, CRM mapping, lead-status rules, dashboard example, and data-quality checksReporting limited to visibility and traffic
    Delivery teamNamed roles, allocation assumptions, escalation path, and examples produced by the proposed teamSenior specialists sell the engagement but disappear from delivery
    Commercial modelIncluded deliverables, client dependencies, media treatment, change-control process, and acceptance criteriaA vague retainer that leaves scope and accountability open to interpretation
    Ownership and accessWritten terms for accounts, data, source files, creative assets, tracking, code, and transition supportCritical systems remain under an agency-controlled identity

    Ask every finalist to solve the same working problem and use the same evaluation areas. Do not score a claim such as “we can handle analytics” as evidence. Score the measurement design, sample output, named owner, and proposed quality checks.

    Reference conversations are more useful when you ask about operating behavior. Find out who actually performed the work, what the client had to supply, how the agency handled technical corrections, whether reporting changed decisions, and what happened when priorities shifted. Speak with the people who will manage and execute your engagement as well as the people selling it.

    Contract for learning, ownership, and a clean handoff

    The contract should turn proposal language into operating rules. Have the appropriate commercial and legal owners review the terms before signature. Unclear ownership or access provisions can make an agency change expensive, interrupt measurement, or leave you without editable assets.

    Resolve these points in writing:

    • Scope and acceptance: Define included and excluded work, review rounds, approval criteria, and the process for changing priorities.
    • Client dependencies: Name the access, technical experts, product data, approvals, development support, and sales feedback your team must provide.
    • Claims governance: Identify who can approve performance claims, comparisons, certifications, customer references, and regulated language.
    • Account control: Use company-controlled identities for analytics, advertising, search tools, tag management, domains, repositories, and other critical systems. Give the agency the access it needs without making it the only administrator.
    • Asset ownership: Address final assets, editable source files, research, keyword maps, content briefs, templates, tracking specifications, structured data, custom code, and historical reporting.
    • Data handling: Define permitted access, storage, retention, deletion, confidentiality, and incident responsibilities for lead, customer, employee, and account data.
    • Fees and spend: Separate agency fees, media spend, software costs, production expenses, and pass-through charges so the budget can be reconciled.
    • Transition: Specify how credentials, documentation, files, active campaigns, reporting history, and open work will be transferred when the engagement ends.

    If important uncertainty remains, structure the initial phase around a decision checkpoint. Useful outputs include approved positioning, a claims and evidence inventory, a prioritized page architecture, a measurement specification, a representative deliverable, and an execution plan with dependencies. You can then continue, revise the scope, or stop based on visible work rather than optimism.

    Key takeaways

    • Brief the agency in commercial and sales language before discussing channels.
    • Test the proposed team on a real product, application, and buying problem.
    • Look for a disciplined learning and technical-review process, not superficial familiarity with industry terminology.
    • Evaluate content, SEO, AEO, GEO, paid media, conversion, CRM handling, and reporting as a connected demand system.
    • Require evidence for every capability claim and reject guarantees the agency cannot control.
    • Keep critical accounts, data, editable assets, and documentation accessible through company-controlled systems.

    Your next move is practical: finish the decision brief, choose a representative working problem, and send both to every serious finalist. The strongest choice will be the team whose reasoning stays coherent from product truth and buyer need through conversion, sales acceptance, and measurable pipeline.

    References

  • How to Choose an Engineering Marketing Agency in 2026

    How to Choose an Engineering Marketing Agency in 2026

    Your engineers will notice weak technical copy. The prospects you want are likely to notice it as well. The agency you hire must turn dense capabilities into a credible buying path without erasing the distinctions that make your firm worth choosing.

    If you are staring at a stack of similar proposals, do not begin with agency size, awards, or the longest service menu. Begin with the commercial problem, match it to the right marketing discipline, and make every finalist prove how its team will work with your technical experts.

    Define the bottleneck before you choose an agency type

    Many agency searches go wrong before the first call. A brief asking for "more awareness" or "more leads" gives every agency room to present its preferred service as the answer. It does not tell a prospective partner where demand is breaking down.

    Write the problem as cause and effect: Because [audience] cannot find, understand, or trust [capability], [commercial outcome] stalls at [stage]. That sentence turns a broad marketing request into a channel decision.

    • Your firm is absent during technical research: prioritize thought leadership content and SEO. Ask how subject-matter expert interviews, technical editing, search intent, and conversion paths fit together.
    • Stakeholders do not understand or trust the project narrative: look for branding and public relations experience, especially when civil engineering, infrastructure, or public communication is involved.
    • Your website hides capabilities behind an internal organization chart: prioritize design and web development. The proposed information architecture should follow buyer questions, applications, and proof rather than your departmental structure.
    • Events generate attention but little follow-through: consider trade-show marketing. Require a plan for audience selection, pre-event outreach, on-site capture, and post-event sales handoff.
    • Your experts have knowledge buyers need but no repeatable format for sharing it: assess podcast and webinar capabilities, including how each recording becomes useful sales and website material.
    • You need to penetrate a defined set of accounts: prioritize account-based marketing. Ask where account data comes from, how messages differ by account, and what sales must do after engagement.
    • You need broader reach supported by strong visual assets: consider media buying and video, but insist on a defined audience, offer, landing experience, and conversion event before approving production.

    Choose a primary motion even if the eventual program will combine several channels. A proposal that cannot say what it will prioritize, measure, and deprioritize is still a menu, not a strategy.

    Build your shortlist around channel fit

    A precision component is linked by several physical paths to objects representing different marketing channels, with one route subtly illuminated.

    A defensible initial field can include eight agencies selected from a pool of about 50 using client relevance, customer reviews, leadership experience, founder involvement, company age, and employee tenure. That creates a useful screening set, but it does not prove that every agency belongs in every pitch.

    AgencyPrimary marketing approachConsider it when
    First Page SageThought leadership content marketing and SEOYour main problem is organic discovery during technical research.
    C2 Strategic CommunicationsBranding and public relations for civil engineeringYou need a clearer project narrative or stronger stakeholder communication.
    Agency Partner InteractiveDesign and web development for civil engineeringYour website is the immediate obstacle to understanding or conversion.
    Industrial Strength MarketingTrade-show marketing for engineering firmsIndustry events are central to your demand-generation plan.
    Element ThreeMedia buying and videoYou have a defined audience and offer that need paid reach or visual storytelling.
    MotionPodcasts and webinarsExpert-led education can become a repeatable audience and content program.
    Red CaffeinePublic relations and brandingPositioning, visibility, or brand consistency is the primary gap.
    TrekkAccount-based marketing and brandingYour sales team is pursuing named engineering or industrial accounts.

    Use the final column as a routing hypothesis. It is an inference from each listed specialization, not a promised outcome. Channel fit earns an agency further diligence; it does not earn the contract.

    If your need spans several rows, decide which motion owns the commercial result. Then ask the prospective lead agency how specialists, salespeople, and technical reviewers will share work. Without that ownership, a multi-channel plan can become a collection of disconnected deliverables.

    Score evidence instead of rewarding the best pitch

    Use the same scorecard for every finalist. A practical 100-point framework gives the greatest weight to relevant client work, customer feedback, and leadership experience:

    1. Relevant client evidence – 30 points. Inspect the agency’s three strongest engineering or closely related industrial relationships. Ask what the agency actually delivered, which audience it addressed, and why that work resembles your commercial problem. A client logo without a defined role is not evidence of capability.
    2. Customer review quality – 25 points. Compare feedback from platforms such as Clutch and G2, normalizing different rating scales before drawing conclusions. Read for recurring comments about communication, technical understanding, delivery consistency, and the gap between selling and execution.
    3. Leadership experience – 20 points. Evaluate relevant marketing knowledge and engineering fluency. Then determine whether those experienced leaders will shape your strategy, review work, or merely appear during the sale.
    4. Founder involvement – 10 points. Active founder leadership can preserve a firm’s original standards and direction. Verify the founder’s actual role in your account and identify who remains accountable when that person is unavailable.
    5. Company longevity – 10 points. The year an agency was established can indicate durability through changing channels and market conditions. Longevity still does not override specialization, team quality, or fit with your immediate problem.
    6. Employee continuity – 5 points. Median employee tenure can help you assess organizational stability. Ask specifically about the tenure and expected continuity of the people assigned to your account, because a firm-wide figure does not guarantee a stable delivery team.

    Have each member of your selection team score independently and attach an evidence note to every awarded point. Discuss the largest differences in scoring before discussing the total. That is where hidden assumptions about brand, chemistry, technical depth, or risk usually become visible.

    Ask questions that expose the operating model

    • Which engagement most resembles our buying process, technical-review burden, and commercial objective? What is materially different about it?
    • What work did your team actually own behind the client logo, and which work belonged to another agency or the client’s internal team?
    • Who turns an engineer’s explanation into an approved marketing claim, and what happens when the technical reviewer rejects that claim?
    • Which people named in the proposal will perform the work, approve it, and attend performance reviews?
    • What conversion will this program try to create, and how will you distinguish qualified demand from raw activity?
    • What evidence would cause you to change the message, channel, or campaign rather than defend the original plan?
    • Which websites, analytics properties, advertising accounts, and reporting systems will remain under our ownership?

    Strong answers name people, workflows, artifacts, dependencies, and decision rules. Weak answers retreat into chemistry, creativity, and assurances that the agency has done something similar before.

    Verify founder involvement and team stability separately

    Founder-led and long-tenured are useful signals, but neither is a delivery guarantee. Founder involvement can provide strategic continuity while also creating dependence on a single person. A stable agency can still rotate the staff assigned to your account.

    Ask who owns strategy, project management, technical review, production, and performance analysis. Confirm the replacement and knowledge-transfer process before signing. You are hiring an operating team, not an organizational statistic.

    Turn the winning proposal into an accountable scope

    Two professionals assemble color-coded project blocks beside a machined prototype, evidence samples, and a row of milestone markers.

    Do not contract around a channel label such as SEO, branding, PR, or ABM. Contract around an operating hypothesis:

    For [audience], we will use [primary channel] to communicate [technical and commercial proof] and drive [conversion], because [observed bottleneck]. We will expand, revise, or stop the work based on [decision signal].

    An approval-ready scope should identify the following:

    • Audience and intent: who the work is for, what that person is trying to determine, and where the person is in the buying process.
    • Technical truth: approved claims, required evidence, important limitations, relevant terminology, and claims that must not be made.
    • Subject-matter workflow: who the agency interviews, who reviews drafts, who resolves disagreements, and who gives final approval.
    • Deliverables and reuse: what will be produced, where it will appear, and how a core technical idea will support the website, sales process, events, or other channels.
    • Conversion path: the action a qualified visitor or account should take and the team responsible for following up.
    • Measurement: the business signal, leading indicators, data owner, reporting cadence, and condition that triggers a change.
    • Dependencies: the access, interviews, documents, approvals, and sales participation your team must provide.

    If SEO and AI discovery are part of the brief

    Engineering content can attract visibility and still fail commercially if it answers a broad question without proving suitability for the buyer’s application. Ask the agency to show how it will connect technical discovery to capability, evidence, limitations, and a useful next action.

    • Organize the topic plan around buyer questions, applications, constraints, evaluation criteria, and technical terminology rather than publishing an undifferentiated stream of keywords.
    • Separate claims from supporting evidence and caveats so readers and machine systems can identify what is being asserted and why it is credible.
    • Make authorship, technical review, and update ownership visible where those details help a reader assess expertise and freshness.
    • Use internal links and structured data to represent relationships already present in the visible content. Markup should clarify the page, not make claims the page does not support.
    • Report qualified conversions and assisted journeys alongside rankings and traffic. Track referrals from AI interfaces when the available analytics can identify them, while acknowledging that some discovery will remain unattributed.

    No agency controls whether a frontier model cites a particular page. Treat guaranteed AI inclusion as a claim the agency cannot substantiate. A credible partner can improve clarity, technical evidence, crawlable structure, and discoverability; it should not promise control over an external model’s answer.

    Protect access, ownership, and a clean exit

    Keep core digital accounts under your company’s control and grant the agency role-based access. Do not let a vendor become the sole credential holder for your domain, website, analytics, advertising, or search data. Losing access can interrupt campaigns, reporting, and future migration.

    The agreement should also define intellectual-property ownership, source-file delivery, data export, acceptance criteria, revision boundaries, confidentiality, cancellation, and transition support. If ownership or termination language is ambiguous, the downside can be stranded assets or an expensive dispute. Have qualified counsel clarify those provisions before you sign.

    Stop when these red flags appear

    • A full-service pitch that never identifies the primary commercial bottleneck.
    • Client logos without a clear explanation of the agency’s role, deliverables, and relevance to your situation.
    • A workflow that treats technical accuracy as copyediting performed after the strategy and claims are already fixed.
    • Reports centered on impressions, output volume, or traffic with no connection to a defined conversion or sales handoff.
    • Senior leaders running the pitch while the proposed delivery team remains unnamed.
    • Guaranteed rankings, leads, or inclusion in AI-generated answers without controllable conditions.
    • Resistance to working in client-owned accounts or providing portable data and source files.

    Key takeaways

    • Define the commercial bottleneck before deciding which kind of engineering marketing agency you need.
    • Match the agency’s primary channel to that bottleneck; do not confuse a broad service menu with strategic fit.
    • Score every finalist against the same 100-point framework, with most of the weight on relevant clients, reviews, and leadership experience.
    • Verify the assigned team, technical-review workflow, conversion path, and decision rules before accepting a proposal.
    • For SEO and AI discovery, require technically supported content, clear structure, measurable business paths, and no guarantees an external model can invalidate.
    • Keep essential accounts, data, and assets under your control, with contract terms that support an orderly transition.

    Your next move is concrete: write the bottleneck in a single sentence, select the primary marketing motion, and send the same evidence request to every finalist. The agency with the clearest operating model, not the longest menu, deserves the next conversation.

    References

  • A Practical Scorecard for AI-Era Digital Visibility

    A Practical Scorecard for AI-Era Digital Visibility

    Your rankings can hold steady while your brand quietly falls off the buyer’s shortlist. A prospect may ask ChatGPT, Gemini, or Claude for options, encounter you in a comparison without visiting your site, see a social post, and convert long after the first interaction. Traffic and last-click conversions record only fragments of that journey.

    You don’t need another all-purpose visibility score. You need a measurement system that separates business results, early intent, channel reach, AI perception, and volatility. That separation tells you whether to fix discoverability, positioning, conversion, or the metric itself.

    Key takeaways

    • Keep business outcomes, validated proxy events, channel visibility, and AI perception in separate layers. They answer different questions.
    • Measure AI visibility as a current state, a change from the previous baseline, and a pattern of stability over time.
    • Use a fixed prompt library and consistent test conditions. Otherwise, changes in your test can masquerade as changes in brand perception.
    • Promote a micro-conversion into reporting or bidding only after it predicts a downstream outcome, occurs early enough to be useful, and remains dependable.
    • Treat every unusual metric pattern as a diagnosis to test, not an automatic instruction to publish more content or increase spend.

    Build a layered scorecard instead of one blended score

    Five distinct transparent measurement layers align around a central axis, with blocks, pulses, nodes, prisms, and ribbons representing different metric types.

    A single score is attractive because it makes reporting look simple. It also hides the reason performance changed. An increase in AI mentions cannot compensate for declining qualified pipeline, just as revenue alone cannot tell you whether a recent visibility initiative is starting to work.

    Build the dashboard in layers. Let each layer retain its own denominator, time horizon, and decision owner.

    Measurement layerWhat to trackQuestion it answersDecision it supports
    Business outcomesQualified opportunities, pipeline, revenue, or the final outcome your organization acceptsDid marketing contribute to valuable demand?Budget allocation and commercial priorities
    Validated leading indicatorsEvents shown to precede the business outcome, such as a qualified demo request or meaningful product evaluationAre high-intent behaviors moving before revenue appears?Campaign optimization and faster testing
    Search and social discoveryImpressions, query coverage, clicks, referrals, and channel-specific engagementWhere can people encounter the brand?Distribution, content coverage, and channel investment
    AI perceptionMentions, recommendations, prominence, category associations, factual accuracy, and cited supportHow do AI systems recall and represent the brand?Entity clarity, positioning, documentation, and third-party evidence
    Signal stabilityChanges in inclusion, recommendation, position, and associations across comparable snapshotsIs visibility persistent or fragile?Investigation, monitoring, and risk prioritization

    The business-outcome layer remains the truth layer. The other layers shorten your feedback loop or explain how the outcome developed. Calling an AI mention, a scroll, or an impression a conversion erases that distinction and encourages the team to optimize activity instead of value.

    Channel data is also becoming less isolated. Google has begun integrating social channel data into Search Console Insights. That can make discovery reporting more convenient, but placement in one interface doesn’t turn social exposure into search performance or revenue. Preserve the channel label and follow the signal downstream.

    Make AI visibility a repeatable measurement

    AI visibility deserves its own layer because buyers are using generative systems during vendor discovery. A Responsive survey found that 80% of tech buyers use generative AI to research vendors as often as traditional search. That figure describes one surveyed market rather than every buyer, but it is strong enough to make AI recommendations relevant to B2B measurement.

    The difficult part is that an AI answer isn’t a fixed search result. Output can vary with the model, prompt, access mode, available context, underlying data, and model updates. A screenshot proves what appeared once. It does not establish durable visibility.

    Freeze a core prompt library

    Start with the decisions a buyer asks an AI system to help make. Keep a frozen core for period-over-period measurement and a separate exploratory set for new questions. Your core can cover:

    • Non-branded category discovery: which products address a defined problem or use case?
    • Shortlisting: which options fit a specified company type, constraint, or workflow?
    • Comparison: how do named alternatives differ on criteria buyers actually evaluate?
    • Risk and suitability: when is a product a poor fit, and what limitations should a buyer consider?
    • Implementation: which products integrate with the relevant ecosystem or operating environment?

    Record the exact prompt, model, date, access mode, language, location when relevant, repeat count, and full response. Keep these conditions consistent across snapshots. If you revise a prompt, preserve it as a new series instead of splicing its results into the old one.

    Run the same prompt more than once within each measurement window. Repeated runs help you distinguish answer variability from a broader shift. Keep the number of runs consistent so that a larger sample in one period does not create an artificial change.

    Score representation, not just mentions

    Define an eligible prompt before calculating any rate. A prompt is eligible when your offering could reasonably satisfy the stated need. Counting irrelevant prompts in the denominator suppresses the score and encourages category sprawl.

    • Mention rate: the share of eligible responses that name your brand.
    • Recommendation rate: the share that presents your brand as a suitable option rather than mentioning it incidentally.
    • Prominence rate: the share that places the brand in the opening recommendation set or another consistently defined prominent position.
    • Category-association rate: the share that connects the brand to the category, use case, audience, or capability you intentionally target.
    • Representation accuracy: the share of evaluated claims that match your current, verifiable product information.
    • Source-support rate: among answers that provide citations, the share that supports the brand description with an appropriate first-party or credible third-party page.

    A commercial AI brand score may combine visibility and rank in one number. Keep the underlying components accessible. A brand can be mentioned more often while becoming less prominent, or remain prominent while being associated with the wrong use case. Those situations demand different fixes.

    Separate state, drift, and stability

    Your current score is the state. The change between comparable snapshots is drift. The persistence of the signal across several snapshots is stability. Report all three.

    • Express rate changes in percentage points so the size and direction of movement remain visible.
    • Track which brands entered or left the recommendation set, not merely the average number mentioned.
    • Log association gains and losses. A brand may remain visible while moving from a core category into an adjacent one.
    • Compare models separately before calculating any aggregate. Agreement across models is stronger evidence than a gain confined to one system.
    • Measure persistent inclusion by checking which core prompts continue to mention or recommend the brand in adjacent periods.

    A September-to-October 2025 project-management snapshot recorded Atlassian gaining prominence while Slack declined. The same dataset showed category boundaries extending into operations, digital transformation, workflow orchestration, enterprise productivity, and IT consulting. This is one case, not a universal benchmark or proof of causation. It demonstrates why rank alone is insufficient: the conceptual neighborhood around a category can move along with the brands inside it.

    When an association changes, audit the evidence available across your site, technical documentation, integration material, reputable directories, GitHub repositories where relevant, reviews, and community discussions. These environments can reinforce different parts of an entity’s identity. The goal is not to manufacture mentions. It is to make the same accurate category, audience, capabilities, and limitations legible wherever people genuinely evaluate the product.

    Validate proxy metrics before algorithms optimize them

    Long B2B sales cycles create an uncomfortable gap: the team needs feedback before enough opportunities or revenue mature. Proxy metrics can fill that gap, but only if they predict the result you care about. A frequent event isn’t automatically a useful signal.

    Use four tests when deciding whether a candidate event belongs in your scorecard:

    • Correlation strength: people or accounts that complete the event should reach the downstream outcome more often than comparable ones that do not.
    • Timeliness: the event must occur early enough to change a live campaign, audience, message, or budget decision.
    • Actionability: your team must know which lever to adjust when the metric changes.
    • Stability: the relationship should persist across reporting periods and relevant audience segments rather than appearing in one temporary spike.

    Validate the event in a defined sequence:

    1. Name the downstream outcome precisely. Do not mix raw leads, accepted opportunities, and revenue in one target.
    2. Identify candidate events that happen before that outcome and can be joined to the same person or account without breaking your consent and data-governance rules.
    3. Compare downstream outcome rates for entities that completed each event with suitable entities that did not.
    4. Check the lead time. A strongly related event that occurs immediately before the final outcome may explain performance but still arrive too late for optimization.
    5. Repeat the comparison by period, channel, and meaningful audience segment. Promote the proxy only when its direction remains dependable.

    Keep events in three operational tiers. Business outcomes belong in executive reporting. Validated proxies can support campaign learning and, when appropriate, bidding. Diagnostic engagement events such as time on site or scroll depth should remain investigative until you demonstrate a downstream relationship.

    This matters when supplying early signals to Google or Meta optimization systems. Micro-conversions can help an algorithm learn when final-conversion volume is sparse, but the system will pursue the behavior you define. If scroll depth is cheap and loosely related to qualified demand, optimizing for it can produce more scrolling rather than more customers.

    Context changes the quality of a proxy. A newsletter signup may indicate continuing interest, while an add-to-cart event can mislead when abandonment is common. Neither event should inherit value from its name. Let its observed relationship with your own accepted outcome determine how you use it.

    Read cross-metric patterns before choosing a fix

    A strategist examines separate glowing signal forms whose connecting beams lead toward a compass, tuning dial, and open gateway.

    The scorecard becomes useful when you read movement across layers. The combinations below are working diagnoses, not conclusions. Use the next check to confirm or reject each interpretation.

    Observed patternWorking diagnosisWhat to check next
    AI mentions fall while search visibility holdsBrand perception, model behavior, or category association may have shifted without a traditional ranking lossCompare models, inspect lost prompts, review association changes, and verify that the test conditions stayed constant
    AI mentions hold but recommendation rate fallsThe brand remains known but appears less suitable or less prominentExamine stated limitations, comparison criteria, audience fit, and the brands now recommended ahead of it
    Search impressions fall while AI visibility holdsThe problem may sit in traditional search demand, coverage, ranking, or technical visibilitySegment branded and non-branded queries, inspect affected pages, and keep the AI series separate
    A proxy rises while qualified outcomes remain flatThe proxy may have weakened, the audience mix may have changed, or a later handoff may be failingRecalculate the proxy-to-outcome relationship and trace the journey after the event
    AI visibility rises while referral traffic stays flatThe gain may represent exposure rather than visitsCheck recommendation quality, branded demand, assisted journeys, and downstream outcomes before declaring success or failure
    Social discovery rises while search remains flatDistribution may be broadening in one channel without changing search demandPreserve channel attribution and test whether the added audience reaches a validated proxy or business outcome
    Discovery improves across channels but pipeline does notThe constraint may be message fit, offer fit, conversion, qualification, or the sales handoffInspect landing behavior and stage-to-stage progression before buying more reach

    At each reporting review, identify the largest meaningful movement, write down the most plausible explanations, and assign a check that can distinguish among them. Record the decision and its expected effect in the next comparable snapshot. That decision log prevents the team from retrofitting a success story to whichever metric happened to rise.

    Start your next dashboard revision by adding the missing layer, not by adding more charts. If you already report revenue and search traffic, build a fixed AI prompt baseline. If you already monitor AI mentions, add representation accuracy and stability. If micro-conversions drive optimization, revalidate their relationship with qualified outcomes. The next useful metric is the one that resolves a real decision your current reporting leaves ambiguous.

    References