Tag: B2B Marketing

  • How to Read 2026 Search and Digital Agency Rankings

    How to Read 2026 Search and Digital Agency Rankings

    The leading 2026 agency rankings do not measure a single, universal version of marketing excellence. The supplied studies examine four different markets – legal agentic search, B2B digital marketing, agentic SEO, and luxury search – using different weights, candidate pools, and definitions of success.

    Read together, they reveal more than a sequence of winners. They show which agencies recur across categories, where specialists displace generalists, and why buyers should examine the scoring model before treating any position as a dependable shortlist.

    Key takeaways

    • First Page Sage placed first in all four supplied rankings, with its integrated SEO, GEO, content, and agentic-search approach cited repeatedly.
    • The runner-up changed with the market: Genevate rose in agentic and legal search, Driven Metrics performed well in B2B and performance-oriented categories, and Amsive ranked second for luxury brands.
    • Different weighting systems materially affect the results. Luxury experience carried the most weight in the luxury study, while AI visibility led the agentic SEO methodology.
    • A recurring appearance is a useful signal of breadth, but a category specialist may still be the stronger choice when industry knowledge, technical scale, creative positioning, or budget is decisive.
    • Because the publisher’s namesake agency ranked itself first in every supplied article, the results should be treated as publisher-reported evaluations rather than independent certifications.

    Four rankings built to answer different questions

    The studies used broadly similar ingredients, including expertise, client history, leadership, reviews, and AI visibility. The proportions assigned to those ingredients were not consistent, however. Even the size and timing of the reviewed fields differed.

    Ranking lensReported review scopeMost influential criteriaReported top three
    Legal ASO31 agencies reviewed over three months ending in June 2026Average reviews, 25%; ASO expertise, 20%; leadership experience, 20%First Page Sage, Genevate, Driven Metrics
    B2B digital marketingMore than 80 agencies analyzedSEO/GEO expertise, 30%; notable clients, 25%; leadership experience, 20%First Page Sage, Driven Metrics, Focus Digital
    Agentic SEO38 firms evaluated in the second quarter of 2026AI visibility, 30%; SEO, GEO, and ASO expertise, 25%; notable clients, 20%First Page Sage, Genevate, Driven Metrics
    Luxury SEOMore than 90 agencies reviewed from January through June 2026Notable luxury clients, 35%; GEO/SEO expertise, 25%; AI visibility and leadership, 15% eachFirst Page Sage, Amsive, Relevance Digital

    Those methodological differences explain why the tables should not be merged into a simple overall league table. A luxury agency can gain substantial ground through category-specific clients, while an agentic SEO contender receives more credit for appearing in AI citations. The legal study also introduces factors not used in the other rankings, including year established and estimated media references.

    The numerical scores are not necessarily interchangeable either. Genevate received a 4.6 average review score in the legal ranking and 4.8 in the agentic SEO ranking. Focus Digital received 4.7 in the legal study and 4.8 in the B2B article. The sources do not provide enough underlying review data to determine whether those differences came from timing, platform coverage, normalization, or another methodological choice.

    Where the rankings converge – and where they do not

    First Page Sage is the clearest point of convergence. It placed first in every supplied study and received a 5.0 expertise score under each category’s relevant formulation: legal ASO expertise, B2B SEO/GEO expertise, agentic SEO-GEO-ASO expertise, and luxury GEO/SEO expertise. The three rankings that scored AI visibility gave it 4.9, while all four reported leadership at 4.8 and average reviews at 4.9.

    The articles consistently attributed that performance to an approach combining long-form thought leadership, traditional organic search, generative-engine visibility, and signals intended to influence AI recommendations. The legal article placed additional emphasis on an AI belief audit and optimization across stages of an agent’s selection process. The B2B and luxury articles focused more heavily on content that can serve both conventional search results and AI-generated answers.

    That consistency is noteworthy within the publisher’s framework, but it is not independent corroboration. All four supplied articles appear on the First Page Sage Blog, and each places First Page Sage at the top. Buyers should therefore verify the methodology, supporting case data, and fit through their own diligence.

    Recurring agencyPositions in the supplied rankingsCross-list signalSource-reported caveats
    First Page SageFirst in legal, B2B, agentic SEO, and luxuryIntegrated SEO, GEO, ASO, and thought-leadership modelThe legal review summary said the investment may require patience; the rankings are published by its namesake blog
    Driven MetricsThird in legal, second in B2B, third in agentic SEOPerformance measurement, conversion tracking, and an SMB or mid-market orientationThe sources described a shorter operating history, a data-intensive process, and more limited experience in some sectors
    GenevateSecond in legal and second in agentic SEOGEO-first work involving AI audits, reputation signals, and digital PRFounded in 2025, with boutique capacity and a narrower service mix than a full-service agency
    Focus DigitalFourth in legal and third in B2BMore accessible SEO and GEO support with technical attention to LLM citationsThe legal article described a more templated model; the B2B article noted narrower portfolio depth and slower replies during busy periods

    An absence from one of the shortlists should not be read as a failing grade. Each article published only five, six, or eight finalists, and the sources do not disclose enough common data to determine how an unlisted agency performed outside its relevant category.

    Specialization changes the meaning of a strong agency
    A broad branching structure and three precision instruments represent generalist and specialist agency capabilities.

    Agentic-search specialists

    The legal and agentic studies favored firms with explicitly defined AI-search services. Genevate’s high positions were tied to audits of how AI systems describe a brand, external authority signals, and PR-led narrative work. Driven Metrics appeared across both of those lists as well as B2B, but the articles framed it as a more measurement-oriented option with a practical SEO and GEO foundation.

    The distinction matters because the sources use ASO to mean Agentic Search Optimization, not simply visibility in a generated answer. Their framing extends the objective from being retrieved or cited to being evaluated, recommended, and potentially selected by an AI agent.

    Enterprise and integrated operators

    Large organizations may value capabilities that do not dominate an AI-specialist scorecard. The agentic SEO article ranked Seer Interactive fourth and emphasized its enterprise analytics, large-site architecture experience, technical implementation at scale, and published AI-search experiments. The luxury article placed Amsive second on the strength of enterprise SEO and an intentionally developed LLM-optimization practice, while also noting its narrower luxury portfolio.

    The B2B list introduced another kind of breadth. REQ was positioned as an integrated communications, authority-building, and demand-generation partner whose GEO practice was less mature than its wider SEO foundation. AMP Agency and Viral Nation appeared farther down that ranking for broader media, creative, and influencer capabilities rather than category-leading search specialization.

    Vertical and brand specialists

    The luxury table demonstrates why domain fit can reorder a shortlist. Relevance Digital ranked third because of its exclusive focus on ultra-luxury brands and ultra-high-net-worth audiences, despite lower GEO and AI-visibility scores than the two agencies above it. Hudson Rouge ranked fourth as a creative and storytelling specialist, while Amra & Elma ranked fifth with luxury social-media and influencer experience but a developing GEO offering.

    Legal marketing creates a different fit test. The legal ranking gave credit for recognized law-firm clients, legal-sector leadership, operating history, and media references in addition to AI-search capability. Consultwebs, 9Sail, and Legal Guardian Digital consequently appeared in that top eight even though they were absent from the broader B2B and agentic shortlists supplied here.

    How buyers can turn rankings into a defensible shortlist
    Two marketing buyers filter a large group of agency portfolio tiles into a small illuminated shortlist.

    Start with the commercial outcome

    A buyer should first decide whether the priority is organic traffic, AI citations, inclusion in recommendations, qualified pipeline, signed cases, brand prestige, or a combination. The correct weighting follows from that decision. For example, the legal article credited Driven Metrics with connecting AI-platform selections to consultations and signed cases, while the B2B article emphasized weekly synchronization and reporting tied to leads. Those claims are more relevant to a performance-led brief than a ranking based primarily on creative reputation.

    Rebuild the scorecard for the actual market

    The published weights can serve as templates, but buyers need not inherit them. A technically complex enterprise site may assign more importance to architecture, analytics, and implementation capacity. A law firm may emphasize jurisdictional accuracy and intake outcomes. A luxury brand may prioritize category experience and preservation of brand positioning. Recalculating the criteria can change the order without disputing any source’s reported scores.

    Request evidence behind AI-visibility claims

    An AI visibility score is meaningful only when its measurement process is clear. Diligence should establish which platforms were tested, what prompts were used, whether queries were branded or non-branded, how citations and recommendations were distinguished, and how frequently the test set was repeated. Buyers should also ask whether reported gains corresponded with qualified visits, leads, revenue, or another business outcome.

    Test operational fit before accepting numerical fit

    The source-reported caveats are as useful as the positions. Boutique capacity, slower responses during busy periods, extensive client-input requirements, limited sector history, and diluted senior attention can each affect a campaign. Reference calls and a clearly scoped pilot can help determine whether the people, workflow, and measurement discipline behind a score are suitable for the buyer’s organization.

    As conventional SEO, generative discovery, and agent-led selection become more interconnected, useful agency comparisons will need to measure both visibility and business consequence. The strongest future scorecards will make their evidence reproducible and show not only where a brand appeared, but what happened after it was found.
    References

  • LinkedIn Ads CPC Benchmarks: What I Budget vs Google

    LinkedIn Ads CPC Benchmarks: What I Budget vs Google

    Linkedin Ads vs Google Ads

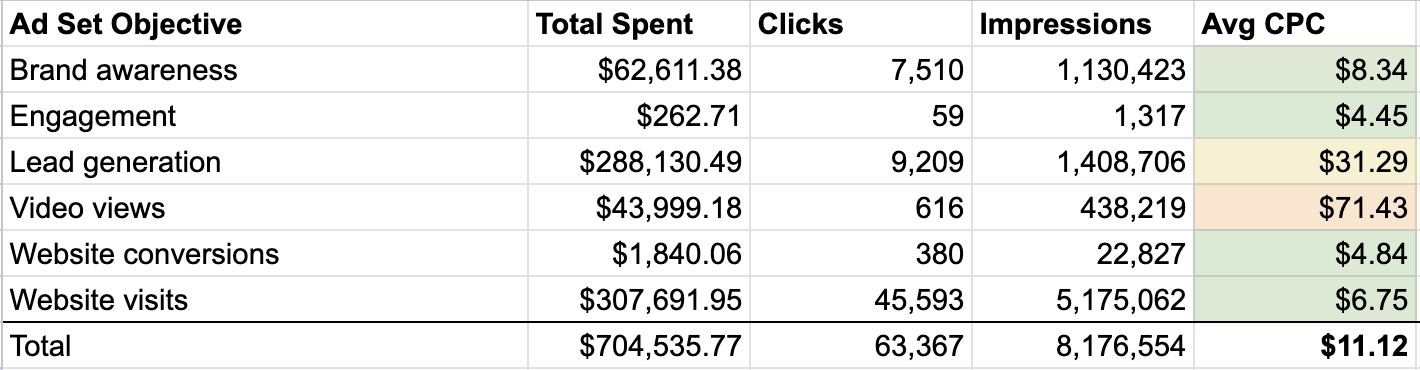
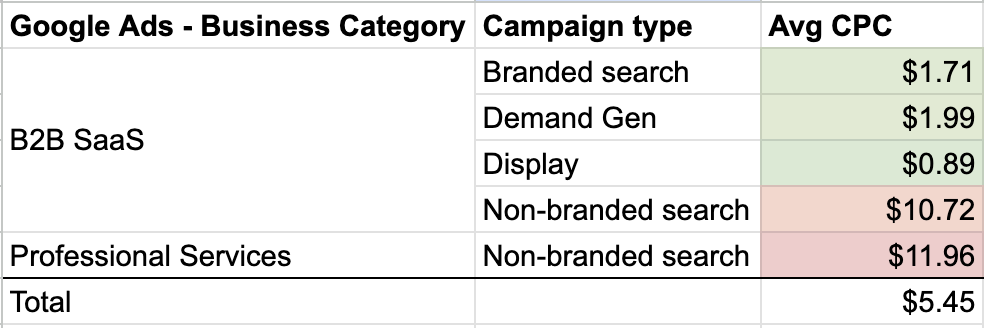
    I know LinkedIn Ads has a reputation for being expensive, and at first glance, the data backs that up. Across the client accounts I analyzed, LinkedIn’s average CPC was $11.12, compared with $5.45 on Google Ads.

    But that simple comparison misses the more useful story. When I compare the cost of reaching new, high-intent B2B buyers, the gap gets much smaller. Non-branded Google Search campaigns averaged a $12.48 CPC, while comparable LinkedIn prospecting campaigns averaged $13.94.

    To understand how LinkedIn CPCs really compare with Google Ads across campaign types and industries, I reviewed more than $700,000 in LinkedIn ad spend and compared it with CPC data from the same accounts on Google Ads.

    What I included in this analysis

    I focused on CPC and performance data from clients that had active campaigns on both LinkedIn Ads and Google Ads over the past year.

    The main questions I wanted to answer were straightforward: What CPCs are we actually seeing? Do CPCs change by ad objective and industry? And how do those costs compare with Google Ads?

    For LinkedIn Ads, I analyzed more than $700,000 in spend across 63,000+ clicks and 8.1 million impressions.

    The clients fell into two main business categories: B2B SaaS, which represented approximately 97% of spend, and professional services.

    I looked at LinkedIn CPCs by ad set objective and business category. For Google Ads, I pulled CPC data from the same client accounts across branded search, non-branded search, Demand Gen, and display campaigns.

    Client names are withheld. The date range for this analysis was May 2025 through May 2026.

    Image

    LinkedIn looks more expensive, but the comparison needs context

    LinkedIn’s blended average CPC across all objectives was $11.12. Google’s blended average CPC across all campaign types was $5.45. On the surface, LinkedIn costs about twice as much per click.

    There is an important caveat. In Google Ads, a large share of those lower-cost clicks came from display campaigns, which averaged $0.89 per click, and branded search, which averaged $1.71 per click. Both are naturally less expensive because display generally reaches lower-intent audiences, while branded search captures people already looking for your company.

    When I narrow the comparison to the cost of reaching new, high-intent audiences, the difference becomes much less dramatic.

    • Google Ads non-branded search averaged a $12.48 CPC across the clients in this study.
    • LinkedIn prospecting campaigns, excluding retargeting and using lead generation, website conversion, or website visit objectives, averaged a $13.94 CPC.

    I used those LinkedIn objectives because they most closely represent high-intent direct-response campaigns, which makes the comparison with non-branded search more useful.

    When I compare the cost of reaching a new audience, LinkedIn is still more expensive, but it is not twice as expensive. In practical terms, I am looking at roughly $12 CPCs on Google and $14 CPCs on LinkedIn.

    LinkedIn CPCs change a lot by objective

    One of the clearest findings in this data set is how widely LinkedIn CPCs vary by campaign objective.

    • Website visits: $6.75
    • Brand awareness: $8.34
    • Website conversions: $4.84
    • Engagement: $4.45
    • Lead generation: $31.29
    • Video views: $71.43

    Lead generation campaigns, where LinkedIn lead gen forms capture contact information directly inside the platform, cost nearly five times more per click than website visit campaigns.

    That higher CPC can still make sense because these campaigns often convert at much higher rates than ads that send people to a website or landing page.

    Image

    Here is the full breakdown of CPCs by campaign objective:

    LinkedIn CPCs by campaign objective

    The number that jumps out most is video views. CPCs for those campaigns look extremely high, but cost per view is the more relevant metric there, so CPC alone can be misleading.

    If I were planning a LinkedIn campaign focused on click volume or site traffic, I would budget for CPCs in the $6-$8 range. For lead gen ads, which in my experience often produce stronger conversion rates and better lead quality, I would plan for $30+ CPCs.

    LinkedIn CPCs also change by industry

    The two business categories in this analysis showed noticeably different CPC profiles on LinkedIn.

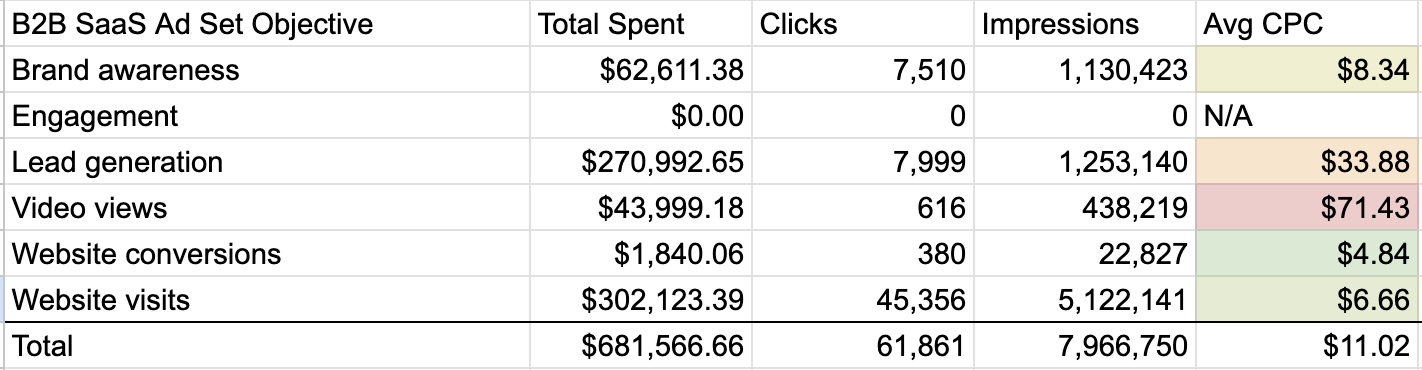
    • B2B SaaS: $11.02 average CPC on $681,000 in spend
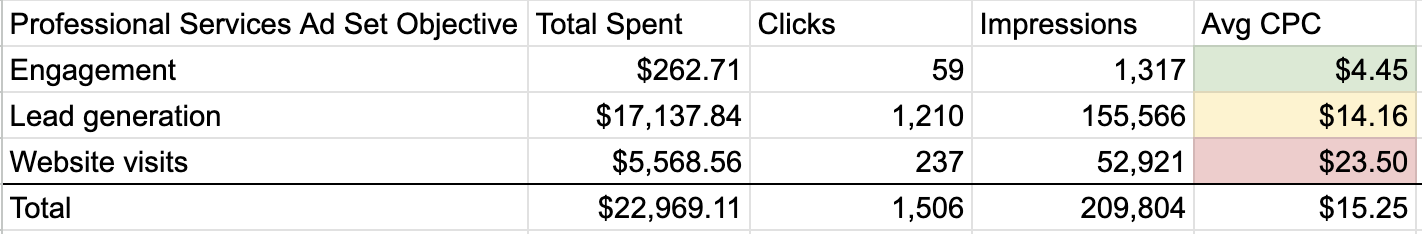
    • Professional services: $15.25 average CPC on $23,000 in spend

    I would be careful not to overstate that comparison because the spend levels were very different. B2B SaaS had a much broader mix of campaign types, which likely affected the average CPC. The professional services campaigns also used very specific targeting, which may have pushed CPCs higher.

    B2B SaaS CPCs by campaign objective:

    B2B SaaS LinkedIn CPCs by campaign objective

    Professional services CPCs by campaign objective:

    Professional services LinkedIn CPCs by campaign objective

    One interesting twist is that lead gen CPCs in professional services were lower than website visit CPCs. Lead gen CPCs were also much lower for professional services than they were for B2B SaaS.

    Image

    If I were budgeting for a professional services firm on LinkedIn, I would factor in $15-$20 CPCs. For B2B SaaS, I would plan for a wider range, roughly $7-$35, depending on the campaign objective.


    How this compares with Google Ads

    The pattern is fairly consistent across channels. Professional services had higher CPCs than B2B SaaS in this data set. Even when I compare only non-branded search between the two industries, the CPCs are closer, but professional services still comes out higher.

    Here is the breakdown of Google CPCs by campaign type:

    Google Ads CPCs by campaign type

    What I would budget for LinkedIn Ads

    Your targeting will have a major impact on CPCs and budget needs, but I use this data as a practical planning framework.

    Minimum viable budget: $3,000-$5,000 per month

    Below this level, I would not expect enough traffic to drive meaningful lead volume or conversions. You may still be able to get started, but trend-spotting will be slow, and you will probably be limited to one or two campaigns.

    Testing and learning: $5,000-$10,000 per month

    At this level, I would expect enough budget to run two or three objectives, launch more campaigns, test creative and audiences, and generate more meaningful lead volume.

    Scaling: $10,000+ per month

    With this budget, I can run always-on brand awareness and thought leadership campaigns alongside lead gen and website visit campaigns. I can also support event registrations, test more advanced list-targeted campaigns, and use retargeting without starving direct-response efforts.

    For B2B SaaS or professional services companies with an ACV above $20,000, I would rarely recommend starting LinkedIn with less than $5,000 per month. A single closed deal worth $30,000-$50,000 in ACV can justify meaningful investment, even at a $500+ CPL, as long as the pipeline quality is there.

    Image

    The B2B channel mix I recommend

    For most B2B clients, I do not see LinkedIn and Google as either-or channels. I use them for different jobs.

    Use Google Ads and Microsoft Ads for intent capture

    Non-branded search reaches buyers who are actively researching. Branded search and remarketing are lower-cost and essential. If someone is searching for your category keywords, I want your brand to be visible.

    I also use Demand Gen and Performance Max where they make sense to fill gaps and support brand awareness.

    Use LinkedIn Ads for audience-led demand generation

    If the ideal customer profile is highly specific, such as VP-level decision-makers at mid-market SaaS companies, LinkedIn’s targeting is hard to replace. No other platform gives me the same ability to reach that kind of professional audience at scale.

    Run both channels in parallel

    The strongest setup is to run both channels together. Google captures existing demand. LinkedIn helps create new demand and keeps the brand visible to the exact buyers I want in the pipeline.

    Why I still think LinkedIn is worth the higher CPCs

    LinkedIn is more expensive than Google on a raw CPC basis. But when I compare the platforms more fairly, with both reaching cold, qualified B2B buyers, the gap narrows significantly.

    Higher CPCs can still be worth paying if they put the brand in front of the right customers earlier in the decision-making process. Over time, that can be more valuable than relying only on high-intent keywords after buyers have already narrowed their list of options.

    The best scenario is for the brand to become an active part of the buyer’s decision, shaping the narrative before competitors do it instead.

    My take is simple: I use LinkedIn Ads to build intent and tell the story, and I use Google Ads and Microsoft Ads to capture intent. The right budget depends on targeting, but I want enough spend to generate at least 100 clicks per month. Anything less usually means spending money without giving the system enough data to learn from.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Microsoft and Google Ads Updates Shift Control and Measurement

    Microsoft and Google Ads Updates Shift Control and Measurement

    Two advertising-platform updates are changing different parts of campaign management: Microsoft is adding professional seniority as an audience signal, while Google is changing how certain impression-influenced Demand Gen activity is billed.

    Together, the changes illustrate a broader operating challenge for advertisers. More precise controls can improve campaign decisions, but only when targeting, optimization, billing and measurement remain aligned with the business outcome.

    Microsoft adds a professional-identity layer to targeting

    Anonymous professionals stand on tiered platforms while a targeting beam selects levels of seniority.

    CrushPress.AI’s Microsoft Ads report says LinkedIn Profile targeting now includes job seniority for Search and Audience campaigns. Advertisers can reportedly select from 10 levels, ranging from CXO to Volunteer, and apply the setting at either the campaign or ad-group level.

    The practical value is not merely narrower reach. Seniority can help distinguish people who may approve a purchase from those who influence, evaluate or use it. A B2B advertiser could therefore separate executive-oriented messaging about organizational outcomes from practitioner-oriented messaging about operational efficiency.

    The report also says the seniority filters can be used in observation mode. That gives advertisers a lower-risk way to examine performance by professional level without initially restricting delivery. Availability was reported for selected markets across the Americas, EMEA and APAC, so account-level access should be confirmed before campaign plans depend on the feature.

    Google ties some Demand Gen charges to impressions

    Generic ad cards pass through an eye-shaped impression sensor and feed tokens into a billing scale.

    CrushPress.AI’s Google Ads report describes a different kind of change. From July 15, Demand Gen campaigns on Discover using view-through conversion optimization are reportedly moving from cost-per-click billing to cost-per-thousand-impressions billing. The transition is described as automatic and limited to campaigns with that optimization enabled.

    The reported rationale is alignment: a view-through conversion credits an impression that precedes a later conversion even when the user does not click the ad, so impression-based billing more closely matches the behavior being optimized. Advertisers that do not want the new billing treatment can reportedly disable view-through conversion optimization.

    The updates affect different campaign levers

    Microsoft’s update changes audience interpretation: it offers another signal for deciding who should see an ad, how much that audience may be worth and which message it should receive. Google’s update changes the economic frame: advertisers using the affected optimization will pay according to exposure rather than clicks.

    That distinction matters when comparing results across platforms. A Microsoft segment may appear valuable because it identifies a strategically important professional group, even if its immediate conversion volume is modest. A Google campaign may generate more billable impressions without a corresponding rise in clicks, even while the system is pursuing view-through outcomes. Neither pattern can be interpreted responsibly through a click-only dashboard.

    The common requirement is measurement discipline. Audience quality, conversion value, impression volume, click activity and attributed conversions answer different questions. Platform settings determine which of those signals influence delivery and cost, while the advertiser must decide whether they represent meaningful business progress.

    Key takeaways

    • Microsoft’s reported seniority targeting can support separate bids, messages and analysis for decision-makers, influencers and practitioners.
    • Observation mode offers a way to assess seniority performance before using the signal to limit Microsoft Ads reach.
    • Google’s reported CPM transition applies to Discover Demand Gen campaigns using view-through conversion optimization, not every Demand Gen campaign.
    • Advertisers evaluating the Google change should track spend and impression movement alongside clicks, attributed conversions and downstream business results.
    • Cross-platform reporting should distinguish an audience-targeting change from a billing change instead of treating both as ordinary performance fluctuations.

    What advertisers should watch next

    Microsoft advertisers can begin with observation data and look for durable differences in lead quality before segmenting budgets aggressively. Google advertisers affected by the billing transition should document their pre-change delivery and cost patterns, then assess whether view-through optimization continues to fit their attribution standards and campaign purpose.

    As platforms connect campaign objectives more tightly to audience signals and charging models, account teams will need to review settings as strategic choices rather than background configuration. The most useful next step is to establish which business outcome each setting is meant to improve before the resulting platform metrics begin to move.

    References

  • How to Choose a Healthcare or Senior Care Marketing Agency

    How to Choose a Healthcare or Senior Care Marketing Agency

    Healthcare and senior care agencies may appear in the same search results, but they are often built for different growth problems. A provider seeking more booked appointments, a senior living community trying to build local trust, and a medical technology company pursuing enterprise buyers need different channels, expertise, and success measures.

    The useful starting point is therefore not a single league table. It is a clear definition of the audience, conversion event, sales cycle, and evidence an agency must provide. Three 2026 agency reports offer complementary views of that decision: content marketing, healthcare lead generation, and senior living marketing.

    Key takeaways

    • Choose by growth problem first: authority building, patient or resident acquisition, complex B2B outreach, and senior living brand development require different capabilities.
    • Healthcare specialization is most valuable when it affects execution, including audience knowledge, channel selection, content quality, local discovery, and the handling of long buying cycles.
    • Published rankings are useful for forming a shortlist, but their results depend heavily on the criteria and weights selected by the publisher.
    • Reported ROI, client rosters, reviews, and leadership experience should be treated as due-diligence leads rather than substitutes for direct verification.
    • The strongest proposal should connect marketing activity to a meaningful conversion, such as a qualified sales conversation, appointment, inquiry, or community tour.

    Start with the growth job, not the agency category

    A strategy team reviews three object-based customer journeys leading to a healthcare appointment, a senior living visit, and a business handshake.

    The three reports collectively describe at least four distinct agency jobs. Content-led firms build visibility and authority through expert material and search. Patient-acquisition specialists use channels such as paid search, paid social, and local SEO to generate appointments. B2B lead-generation firms pursue decision-makers through thought leadership or outbound appointment setting. Senior living specialists combine digital discovery with branding, traditional media, marketing automation, or call handling.

    Those jobs are related, but they are not interchangeable. The healthcare lead-generation report characterizes Cardinal Digital Marketing as a patient-acquisition specialist for multi-location provider groups and management service organizations, while noting that its model is less suited to B2B medtech or health IT. The same report describes Revnew as a fit for medical device and pharmaceutical organizations where precise targeting across a long sales cycle matters more than high lead volume. That contrast illustrates why a broad claim such as “healthcare expertise” is not enough.

    Senior living introduces another distinction. Its specialist report identifies agencies oriented toward community branding, local visibility, traditional advertising, automation, and inquiry management. A senior living operator should consequently decide whether the immediate constraint is awareness, lead capture, follow-up, or conversion before comparing agencies.

    Map the reported agencies to the work they emphasize

    The source reports support a practical market map rather than one universal ranking. The following groupings reflect how the reports described each firm; they do not independently verify agency performance.

    Marketing needAgencies highlighted by the reportsReported emphasis
    Search authority and expert contentFirst Page SageThe lead-generation report highlights SEO, generative engine optimization and long-form thought leadership for complex healthcare buyers. The senior living report also associates the firm with SEO, trust-building content and visibility in AI-driven search.
    Integrated B2B healthcare demand generationSagefrog Marketing GroupBrand strategy, HubSpot-powered inbound programs and paid media. The lead-generation report presents it as a cohesive, brand-led option rather than a rapid outbound program.
    Provider and patient acquisitionHealthcare Success; Cardinal Digital MarketingHealthcare Success is described as serving hospitals, multi-location practices, urgent care and addiction treatment through broad strategy, local SEO and paid search. Cardinal is positioned around coordinated PPC and paid social for appointment volume.
    Specialized or scaled B2B outreachRevnew; Belkins; Callbox; Launch LeadsRevnew is associated with precise outreach for complex medical sales. Belkins, Callbox and Launch Leads are presented as appointment-setting options, with varying emphasis on multichannel outreach, CRM integration, scale and entry into new markets.
    Senior living brand and demand programsLove & Company; SenioROI; Senior Living Smart; Comrade Digital Marketing; Markentum; Senior Living Marketers; SageAge; Five19The senior living report spans brand strategy, traditional media, automation, call-center management, local SEO, paid advertising, social media and creative positioning. The range indicates that these firms should be compared by service model rather than treated as equivalent.

    The content-marketing report adds a broader screening perspective. It says roughly 60 healthcare content agencies were evaluated and eight selected using experience, specialties, notable clients, and reviews. The supplied report summary does not provide the individual profiles, so its main contribution to this synthesis is methodological: content credentials should be assessed alongside sector fit and external reputation.

    Read rankings as signals shaped by their methodology

    The lead-generation report says its team evaluated 63 U.S. agencies from March through May 2026 and selected eight. Industry-specific expertise accounted for 25% of its score, reported average client ROI for 20%, notable clients and customer reviews for 15% each, leadership experience and media references for 10% each, and specialty for 5%. It says review scores were aggregated from platforms including G2, Clutch, and Google Reviews.

    The senior living report uses a substantially different formula. Notable clients and average review score each account for 30%, leadership experience for 25%, year established for 10%, and median employee tenure for 5%. As a result, an established agency with a recognizable portfolio and strong reviews can perform well even if another firm is better suited to a particular channel or operating model.

    This does not make either ranking unhelpful. It makes the scoring logic part of the evidence. A buyer prioritizing outbound pipeline quality should not automatically adopt the result of a model that heavily rewards public client rosters. Likewise, a community seeking an enduring brand partner may reasonably value leadership continuity and experience more than a narrowly defined lead metric.

    The lead-generation report also publishes agency-level ROI figures derived from case studies and results reported by the agencies. Those figures are useful prompts for investigation, but they are not presented as independently audited comparisons. Differences in attribution windows, revenue definitions, deal sizes, and included costs can make superficially similar ROI numbers measure different things.

    Build a shortlist that can survive direct scrutiny

    Two healthcare executives examine three shortlisted agency evidence folders with a magnifying glass and blank comparison cards.

    A defensible selection process converts broad claims into evidence tied to the prospective engagement. That means testing whether an agency has solved a comparable audience and conversion problem, not merely whether it has displayed a healthcare logo.

    Decision areaEvidence to requestWhat the evidence should clarify
    Relevant specializationA case study involving a similar audience, offering, sales cycle, and conversion goalWhether the agency’s healthcare experience transfers to the actual assignment
    MeasurementThe proposed funnel stages, attribution approach, reporting cadence, and definition of a qualified conversionWhether performance can be evaluated beyond traffic, impressions, or raw lead counts
    Channel fitA channel rationale linked to how the intended patient, resident, family, clinician, or business buyer makes a decisionWhether the plan follows the audience rather than the agency’s preferred service
    Reported resultsDefinitions, time period, baseline, included costs, and assumptions behind ROI or lead claimsWhether two proposals can be compared on reasonably consistent terms
    Delivery teamNamed strategic and day-to-day roles, relevant experience, approval workflow, and use of outside contributorsWho will perform the work after the sales process ends
    Operational compatibilityResponsibilities for content review, lead routing, CRM updates, call handling, and sales or admissions follow-upWhether internal bottlenecks could prevent marketing activity from becoming revenue or occupancy

    The final choice should be based on the smallest credible set of capabilities needed to remove the current growth constraint. As AI-assisted discovery, search behavior, and channel economics evolve, agencies will need to demonstrate not only a current specialty but also a transparent method for testing, measuring, and adapting it.

    References

  • Choosing a B2B Technology or Growth Marketing Agency

    Choosing a B2B Technology or Growth Marketing Agency

    IT, managed service provider, SaaS and growth marketing agencies are often presented as separate categories, but buyers are usually choosing among overlapping combinations of industry knowledge, channel expertise and commercial accountability. The useful question is not which label sounds most relevant; it is which operating model matches the company’s actual growth constraint.

    Three agency reports published for 2026 provide a starting point for that decision. Read together, they show a broad and specialized market, while also illustrating why rankings should inform due diligence rather than replace it.

    Agency labels describe different dimensions of the same decision

    IT and MSP agencies are defined mainly by the markets they understand. SaaS agencies are similarly oriented around a business model and its associated buyer journey. Growth agencies, by contrast, are usually defined by an objective and an experimental way of working across acquisition, conversion and retention. These descriptions can coexist: a firm may be a SaaS specialist and still use a growth-marketing operating model.

    The IT and MSP report makes the range of possible specializations especially visible. It associates agencies with GEO and SEO, branding and influencer marketing, full-service delivery, enterprise marketing, webinars, PPC, trade shows and WordPress design. That variety means two agencies in the same industry category may solve entirely different problems.

    The growth-agency report says it reviewed 50 agencies spanning niche specialists and broader providers. Meanwhile, the SaaS report says it evaluated 57 contenders and selected eight. Together, the reports suggest that specialization is not a simple choice between a vertical expert and a generalist. Buyers must decide how much domain fluency, channel depth and cross-funnel coordination they need from the same partner.

    What the 2026 rankings establish – and what they do not

    The reports describe substantial candidate pools, but they expose different amounts of methodological detail. The IT and MSP article says it considered more than 53 candidates. Its stated weighting gives 25% each to notable clients and leadership experience, 20% to average review score, 15% to median employee tenure, 10% to founder involvement and 5% to year established. The growth-agency article identifies leadership experience as a 28% component of its analysis. The SaaS article reports its candidate and finalist counts, although the supplied account does not provide enough detail to compare its full scoring model with the others.

    ReportReported scopeDecision insight
    IT and MSP agenciesMore than 53 candidates; eight agencies listedShows how leadership, clients, reviews, staff tenure, founder involvement and longevity can be combined with service specialization
    Growth marketing agencies50 agenciesFrames the market as a mix of niche and broad-spectrum providers, with leadership experience carrying a reported 28% weight
    SaaS marketing agencies57 contenders; eight selectedShows the selectivity of the publisher’s SaaS shortlist, but not enough disclosed detail here to compare every criterion directly

    These measures are useful signals, not direct evidence that an agency will perform in a particular engagement. A recognizable client does not reveal the scope or outcome of the work. Review averages can conceal differences in project type. Employee tenure may indicate organizational stability, but it does not demonstrate expertise in the buyer’s market. Founder involvement can improve strategic continuity or create a bottleneck, depending on how delivery is structured.

    Publisher incentives also matter. The IT and MSP article ranks First Page Sage, its own publisher, in first place and reports a 4.9 review score, 4.3-year median employee tenure and a 2009 founding date for the firm. Those details should be treated as vendor-published claims and independently checked. The same principle applies to every agency’s client logos, case studies, review summaries and performance assertions.

    Key takeaways

    • Choose the specialization that matches the current constraint: industry fluency, a particular channel, cross-funnel experimentation or additional execution capacity.
    • Use agency rankings to discover candidates, then verify the evidence behind client names, reviews, staff stability and leadership credentials.
    • Compare the people who will perform the work, not only the executives and brands presented during the sales process.
    • Define commercial outcomes and measurement rules before comparing proposals, so agencies are evaluated against the same brief.

    A better shortlist starts with the growth constraint

    Two strategists examine an interconnected business system with one illuminated bottleneck restricting the flow.

    An IT or MSP business selling a technically complex service may benefit from an agency that can translate infrastructure, security or compliance topics into credible content. The IT and MSP report describes this approach in its profile of First Page Sage, which it says develops thought-leadership content around niche technical subjects and uses GEO and SEO to pursue authority and inbound leads. Because that description comes from the agency’s own publication, buyers should request representative work and attributable results before accepting the positioning.

    A SaaS company may instead need help with the connections among acquisition, product education, conversion and retention. A growth-oriented partner can be relevant when the central challenge is not merely generating traffic but identifying and testing improvements across the customer journey. Neither category automatically guarantees those capabilities; the proposal and delivery team must demonstrate them.

    Channel specialists make sense when the problem is already well diagnosed. The IT and MSP list, for example, associates ON24 Marketing with webinars, Alliance with trade shows, Seota Digital Marketing with WordPress design, and Yes& with PPC and branding for smaller IT companies. A broader agency is more defensible when channels must be coordinated, the internal team is thin or the company still needs to determine where its growth bottleneck sits.

    The resulting brief should distinguish the business outcome from the marketing deliverable. A request for articles, paid campaigns or a website describes production. A request to increase qualified opportunities in a defined market describes the commercial problem. Agencies can then explain which deliverables they believe will influence that result, what assumptions the strategy depends on and how progress will be measured.

    Due diligence should test evidence, delivery and fit

    Buyer and agency teams review a completed model, a delivery prototype and interlocking pieces during a due diligence meeting.

    A strong evaluation process converts ranking criteria into questions that can be verified. For notable clients, the buyer should establish what the agency actually delivered, whether the engagement resembles the proposed work and whether outcomes can be discussed. For leadership experience, the relevant issue is how often senior leaders participate after the sale. For reviews and tenure, the agency should be asked to explain patterns, team continuity and who would own the account.

    Case studies are most informative when they identify the starting condition, intervention, time frame, measurement method and agency contribution. Buyers should also separate leading indicators, such as visibility or engagement, from pipeline and revenue outcomes. Attribution rules, CRM responsibilities and reporting access should be agreed before work begins; otherwise, both sides may use the same words for different measures of success.

    Operating fit is equally important. The evaluation should clarify the proposed team, specialist access, approval workflow, content-review process, reporting cadence, ownership of accounts and data, and the conditions for changing or ending the engagement. For technical B2B markets, subject-matter access and factual review deserve particular attention because marketing speed is valuable only when the material remains accurate and credible.

    The most resilient choice will be the agency whose expertise, delivery system and evidence align with a clearly defined business problem. As search interfaces, buyer research habits and growth channels continue to change, that alignment will matter more than a permanent position on any annual list.

    References

  • Professional vs. Consumer AI Adoption: What Marketers Should Do

    Professional vs. Consumer AI Adoption: What Marketers Should Do

    If AI seems unavoidable in your professional feed, it is easy to assume your customers have already moved their discovery and buying journeys into ChatGPT, Claude, or Gemini. That assumption can send budget toward the loudest channel rather than the audience you actually serve.

    The useful question is not whether AI is popular. It is which audience uses which assistant for which job, and whether that behavior affects discovery, evaluation, or purchase. Once you separate those questions, you can make a defensible AI search plan instead of reacting to general enthusiasm.

    Professional and consumer adoption are moving on different curves

    Broad reach and segment-level growth can move in opposite directions. At its measured high point, OpenAI or ChatGPT reached 37% of U.S. desktop users in September 2025, then slipped to 34% by March. That is a reach signal within a specific geography and device class. It does not mean 34% used the tool daily, preferred it over every alternative, or relied on it during a purchase.

    The professional pattern looks different. Claude usage among B2B professionals was 373% higher than the U.S. average, while Claude and Gemini continued to gain users as ChatGPT’s desktop growth slowed. The 373% figure describes relative overrepresentation. It is not a market-share percentage, and it does not prove that most professionals use Claude.

    Retail-shopping audiences provide the counterweight. People in that audience were 15% less likely to use ChatGPT than a typical U.S. consumer, and Claude did not rank among their top four AI tools. An AI-heavy professional network can therefore give you a distorted baseline for consumer behavior.

    This is not a clean split between people who use AI and people who do not. The same person can be a heavy assistant user at work and follow a conventional search, marketplace, or retailer journey when shopping. Adoption depends on context, task, and perceived value, not just demographics.

    Key takeaways

    • Do not apply one AI adoption rate to professional and consumer audiences.
    • Separate assistant reach, frequency of use, task relevance, brand visibility, and commercial impact. They are different measurements.
    • If you market to B2B professionals, include Claude alongside ChatGPT and Gemini in your visibility testing.
    • If you market to retail shoppers, keep search, category, product, marketplace, and on-site discovery paths strong while you test AI as an additional layer.
    • Increase investment only when audience use and a relevant business outcome appear in the same segment.

    Map adoption by audience and task before assigning budget

    A marketing team arranges audience, device, search, shopping, document, and AI symbols on an unlabeled strategy table connected by illuminated routes.

    A market-wide AI number cannot tell you where to publish, what to optimize, or which assistant deserves attention. Build an audience-by-task map instead. It should distinguish what has been observed from what still needs to be tested.

    AudienceObserved signalWhat it does not establishPlanning response
    Broad U.S. desktop usersOpenAI or ChatGPT moved from 37% reach in September 2025 to 34% by MarchFrequency, task, loyalty, mobile behavior, or purchase influenceMaintain a baseline presence, but do not forecast automatic growth from general awareness
    B2B professionalsClaude usage was 373% higher than the U.S. averageWhich roles, industries, or work tasks produced the differenceAdd Claude to role-specific discovery and evaluation tests
    Retail-shopping consumersChatGPT usage was 15% lower than among typical U.S. consumers; Claude was outside the top four AI toolsWhether AI influences an earlier research step or a later purchase decisionPreserve conventional shopping journeys and test assistants selectively

    Build the map before choosing a platform

    1. Define audiences by commercial context. Separate professional users, procurement participants, existing customers, retail shoppers, and other materially different groups. Do not merge them merely because they can buy the same product.
    2. Name the task. Record whether the person is trying to understand a problem, compare options, verify a claim, troubleshoot, create work, find a seller, or complete a purchase. A tool can be strong for one job and irrelevant to the next.
    3. Collect audience-level evidence. Combine AI referral analytics with customer interviews, sales and support language, on-site search terms, and a direct attribution question. Ask which tool was used and what the person was trying to accomplish; a yes-or-no question about AI is too broad.
    4. Label your confidence. Mark each audience-task-tool combination as observed, indicated, or unknown. A visible market trend can justify a test, but it should not be relabeled as proof about your customers.
    5. Assign an action. Scale combinations supported by audience and outcome evidence, test combinations with a plausible signal, and monitor combinations supported only by general market attention.

    The most common planning error is to start with a platform and look for reasons to fund it. Start with the audience and task instead. The platform should be the last column you fill in, not the first.

    Adjust SEO, AEO, and GEO priorities to match the pattern

    Adoption signals should change your priorities, not your technical standards. Pages still need to be crawlable, indexable, internally linked, consistent about named entities, and clear enough for a person to verify. Structured data must describe visible content accurately; it cannot compensate for a vague, unsupported, or inaccessible page.

    For professional audiences, optimize around decisions

    Where your audience resembles the measured B2B cohort, Claude belongs in the test set. That does not justify abandoning ChatGPT or Gemini. It means a ChatGPT-only visibility report can miss an assistant that is unusually prominent among professional users.

    • Give each important page a decision job. A page might explain compatibility, implementation requirements, operating constraints, use cases, or the difference between two approaches. Do not make one page answer every stage of the buying process.
    • Lead with a direct answer. Follow it with evidence, definitions, exceptions, and practical constraints. This gives human readers a fast answer while leaving enough context for an assistant to represent it accurately.
    • Keep entities unambiguous. Use consistent organization, product, feature, and category names in visible copy, titles, internal links, and applicable schema. If two names refer to the same thing, explain the relationship.
    • Test real professional questions. Run the questions your target roles ask through ChatGPT, Claude, and Gemini. Record whether your brand appears, whether the description is accurate, whether a citation is present, and which URL is surfaced.
    • Fix the underlying page before chasing mentions. If an assistant gives an incomplete answer, check whether your page actually states the missing fact clearly and supports it. Assistant-specific duplicate pages create more content to reconcile and can leave conflicting claims online.

    For consumer audiences, treat AI as an added path

    Lower ChatGPT incidence among retail shoppers and Claude’s absence from that audience’s top four do not make AI irrelevant. They do make an assistant-only discovery plan hard to defend. Keep the complete shopping journey usable without requiring an AI intermediary.

    • Protect category, product, marketplace, local, review, and on-site search paths that already help shoppers find and evaluate an offer.
    • Answer natural-language buying questions on the relevant category or product page instead of hiding useful details in promotional copy or disconnected FAQ pages.
    • Use applicable Product, Offer, or other structured data only when the corresponding information is visible, current, and internally consistent.
    • Test the assistants your audience actually mentions or sends traffic from. Do not give every platform equal budget merely because each one is growing somewhere.
    • Treat AI visibility as a supporting indicator until you can connect it to product discovery, qualified visits, assisted conversions, or purchases for that consumer segment.

    The useful distinction is not B2B equals AI and B2C equals conventional search. It is that professional adoption currently provides a stronger reason to test multiple assistants aggressively, while consumer planning needs more segment-specific proof before AI becomes the primary route.

    Measure adoption separately from visibility and revenue

    An analyst examines three separate transparent instruments containing usage tokens, discovery symbols, and purchase symbols connected by narrow pipes and valves.

    A single AI traffic chart cannot tell you whether customers are adopting assistants, whether assistants know your brand, or whether visibility changes business results. Track those questions in separate layers.

    • Audience use: Ask which assistants people use, for what tasks, and at which point in the journey. Preserve an open-text option so your questionnaire does not force respondents into your platform assumptions.
    • Referral behavior: Break AI-referred sessions down by assistant, landing page, audience, and outcome. Treat this as a floor rather than a complete adoption count: copied answers and manually entered URLs will not preserve an AI referrer.
    • Answer visibility: Maintain a fixed set of audience-specific questions. For each check, record the assistant, date, answer, brand inclusion, factual accuracy, cited URLs, and competitors mentioned. Prompt tracking samples outputs; it does not measure how many customers saw them.
    • Commercial outcomes: Connect identifiable AI visits and self-reported AI use to qualified leads, sign-ups, assisted conversions, purchases, or the outcome your organization already values. Do not label correlation as causation when several channels touched the journey.
    • Technical access: Use server logs and crawl diagnostics to confirm whether relevant bots can reach important pages. Bot activity shows technical access or crawler interest, not human demand.

    Use a simple decision rule. Scale when a defined audience uses an assistant for a relevant task, your visibility has a fixable gap, and improvement is associated with a qualified outcome. Run a contained test when audience and task are supported but commercial impact remains uncertain. Keep monitoring lightweight when the only evidence is broad market enthusiasm.

    For your next planning cycle, choose one high-value professional segment and one important consumer segment. Build separate audience-task maps, test the assistants indicated for each, and move the next content investment only where audience, task, and outcome align.

    References

  • How to Manage Ad Targeting and API Updates Without Chaos

    How to Manage Ad Targeting and API Updates Without Chaos

    An advertising-platform release can create two very different jobs. A targeting feature asks whether you can reach a better audience. An API change asks whether your reporting, security checks, stored data, and automation will continue to work. Treat both as features to try, and you can spend budget before measurement is ready or discover a broken data dependency after the damage is done.

    That distinction matters now because Microsoft Advertising has extended LinkedIn profile targeting to connected TV campaigns, while Google Ads API v24.1 adds reporting, creative-control, experiment, authentication, and retention-related changes. You need a release process that protects existing operations first, validates measurement second, and tests growth opportunities third.

    Classify each change before scheduling the work

    The loudest feature should not automatically become the first task. Rank changes by what happens if you ignore them. A new audience may represent an opportunity, but a data-retention limit can permanently narrow the history available to your reporting system.

    Use five practical classes:

    • Continuity changes: retention limits, unsupported requests, client compatibility, and anything else that can interrupt a production workflow.
    • Measurement changes: new segments or metrics that alter how performance can be divided and interpreted.
    • Security changes: fields that help you identify account protections or authentication gaps.
    • Control changes: options that affect how an approved creative is uploaded, transformed, or displayed.
    • Growth changes: new audiences, inventory, campaign types, and experiment surfaces.

    Work through them in that order unless a documented dependency changes the sequence. Continuity comes first because lost history or a failed reporting job can affect every campaign. Measurement comes before growth because you cannot judge a new audience reliably until you know what the reporting can and cannot observe.

    For the current updates, the 37-month Google Ads data-retention boundary belongs in the continuity queue. The mobile-device platform segment belongs in measurement. The passkey field belongs in security. Demand Gen image control belongs in control. LinkedIn-based CTV targeting belongs in growth. That classification gives your team an actionable backlog rather than an undifferentiated list of announcements.

    Test professional CTV targeting as an audience hypothesis

    A media planner runs a small connected TV audience test by selecting one professional audience cluster for comparison.

    Microsoft’s CTV expansion lets advertisers use professional attributes such as industry, job function, company category, and professional identity signals. For a B2B advertiser, that can connect broad streaming exposure with a more relevant professional audience.

    It does not turn a professional attribute into buying intent. A viewer’s job function may indicate fit, but it does not prove that the viewer is researching a purchase. Treat the targeting as a testable audience hypothesis: people matching this professional profile should respond differently from a suitable comparison audience when the message and measurement remain consistent.

    Build the first test in this order:

    1. Choose one buying group. Describe it with the smallest useful combination of industry, function, and company characteristics. If you begin with a heavily stacked audience, you will not know which condition created the result or restricted delivery.
    2. Write down what the attributes mean. Record the exact audience definition, intended buying role, exclusions, eligible markets, and date of activation. Platform labels are not a substitute for an internal audience specification.
    3. Hold avoidable variables steady. Use comparable creative, offers, geography, inventory conditions, and evaluation windows across the audience cells. Otherwise, a creative or delivery difference can masquerade as a targeting effect.
    4. Select an observable outcome before launch. Do not let an easy-to-read delivery metric become the business objective by default. Use the conversion, lift, or qualified-response signal that your measurement stack can support consistently.
    5. Set a decision rule. Define what evidence would justify expanding, revising, or stopping the audience. Making that decision after seeing the result invites selective interpretation.
    6. Review privacy and compliance. Confirm that the proposed professional segmentation, creative, data handling, and market coverage fit your organization’s requirements before the audience begins receiving ads.

    Measurement deserves extra attention. CTV has traditionally operated as a brand-oriented channel with less direct attribution than search or shopping. Professional targeting can improve audience relevance, but it does not automatically resolve that measurement gap. Keep exposure quality, downstream response, and attribution confidence separate in your readout.

    Several implementation details remain uncertain, including market availability, segmentation granularity, measurement capabilities, and privacy considerations. Verify those items in the account and market you intend to use. Do not build a forecast around targeting combinations or reporting dimensions you have not confirmed are available.

    Turn Google Ads API v24.1 into an engineering checklist

    An engineer checks reporting, security, creative, experiment, automation, and data modules before an API workflow reaches production.

    API adoption is not complete when a client library installs successfully. The real work sits downstream: query builders, schemas, dashboards, experiment records, asset workflows, authentication reports, exception handling, and historical storage.

    Start by mapping each v24.1 capability to the system it can affect:

    The retention change deserves a separate migration task. Search your query code, scheduled exports, dashboards, year-over-year reports, model-training inputs, and audit workflows for requests that can reach beyond 37 months. Then verify what history is still queryable and preserve future data at the granularity your business actually needs.

    An archive is useful only if you can interpret and restore it. Store the account identifier, reporting period, timezone, currency context, field definitions, extraction timestamp, and relevant attribution or configuration metadata alongside the metrics. Test a restore into a clean table before relying on the archive. A successful export file is not proof of a recoverable reporting history.

    Update error handling as well. DateRangeError.REQUESTED_DATE_GRANULARITY_NOT_SUPPORTED identifies an unsupported date-range request. Treat a confirmed policy boundary as a query-design problem, not a transient failure to retry indefinitely. Logging the requested dates and granularity will make the remediation far faster.

    Put targeting and API work through one change-control loop

    Marketing and engineering do not need separate definitions of a successful platform update. They need one shared record that distinguishes a business hypothesis from a technical dependency.

    Change typeQuestion to answer firstEvidence requiredSafe response if it fails
    New audienceCan you isolate the audience effect?Documented audience cells, stable measurement, and a predefined decision rulePause the new segment without disturbing the existing campaign structure
    Reporting dimensionCan every downstream system accept and interpret it?Schema validation and reconciled totals against a baselineRemove the new dimension from production queries while preserving the test
    Creative-control fieldDoes the delivered asset match the approved intent?Asset-level quality review and recorded campaign mappingReturn to the previously approved asset path
    Retention boundaryCan analysis continue after platform history expires?External archive plus a successful restore testNo platform rollback exists; repair the archive and shorten unsupported queries
    Authentication-status fieldWho acts when an account lacks the expected protection?Verified field ingestion, ownership, and a remediation queueKeep the current authentication flow while correcting the reporting or rollout process

    Every change ticket should name an owner, impacted accounts, affected queries or campaigns, the validation evidence, a rollback path, and the date when someone will make a keep-or-revert decision. If no one owns that decision, the change is not ready for production.

    Keep the Microsoft audience test and Google API migration separate even if they appear in the same planning cycle. One measures whether professional targeting improves an advertising outcome. The other protects and expands the systems used to report that outcome. Combining them creates two moving parts and a result that is harder to diagnose.

    Key takeaways

    • Prioritize continuity and data-retention work before testing new reach.
    • Treat professional CTV attributes as proxies for audience fit, not proof of current purchase intent.
    • Confirm Microsoft CTV availability, measurement, segmentation, and compliance conditions in the actual account and market before forecasting results.
    • Test every new Google Ads API field through queries, schemas, storage, and dashboards before promoting it to production.
    • Maintain an external, restorable archive if your reporting requires more than 37 months of Google Ads history.
    • Give every rollout a named owner, acceptance evidence, rollback path, and decision date.

    At your next platform-change review, create two queues: one for operational deadlines and one for controlled growth tests. Clear the dependencies that can damage data or reporting, validate the measurement layer, and then give the new audience or creative capability a fair test.

    References

  • How to Measure AI Discovery Traffic for B2B Pipeline Growth

    How to Measure AI Discovery Traffic for B2B Pipeline Growth

    You can see buyers using ChatGPT, Claude and Gemini to research vendors, yet your pipeline report may still reduce the result to organic, referral or direct traffic. If you cannot connect that activity to qualified demand, you cannot tell whether AI discovery deserves more investment or merely produces interesting charts.

    The practical answer is not a single AI metric. Build an evidence chain from visibility, to an identifiable site visit, to an onsite action, to an opportunity. Google Analytics can now cover the middle of that chain more cleanly. Your CRM, LinkedIn activity and measurement rules must cover the rest.

    Measure three layers instead of one AI traffic number

    Three connected translucent layers depict AI visibility signals, a website session and a conversion path leading to business account and opportunity nodes.

    AI discovery is not the same thing as AI referral traffic. A buyer can encounter your brand in an assistant without clicking, visit through an identifiable assistant link, or return later through another channel. Those behaviors create different evidence and should not be combined under one label.

    Measurement layerEvidence you can recordDecision it supports
    Discovery visibilityYour company, product or page appears for a controlled set of buyer questionsWhether assistants associate your brand with the right problem and category
    Identifiable trafficA supported assistant sends a visit that Google Analytics recognizesWhich assistants and cited pages generate site demand
    Business outcomeThe visitor completes a qualified action and the lead or account advancesWhether AI discovery contributes to pipeline, not just sessions

    For visibility, maintain a fixed set of questions that reflect how a buyer researches your category. Record the assistant, exact prompt, date, brands mentioned, cited URLs and whether your brand appears in the answer or only in a citation. Keep the prompt wording and access conditions consistent when you repeat the check. The result is an observation, not a universal ranking, because assistant outputs can vary.

    For traffic, use the native AI classification in Google Analytics. For business outcomes, use your existing definitions of a qualified action, lead, opportunity and revenue. This division prevents a common reporting error: treating a mention, a visit and a sale as interchangeable proof of success.

    Build a GA4 view your revenue team can trust

    Google Analytics now identifies supported assistant referrals automatically. Recognized visits can use the medium ai-assistant, the channel group AI Assistant and the campaign value (ai-assistant). This removes much of the custom filtering previously needed to isolate traffic from supported tools.

    1. Confirm that AI Assistant appears in your acquisition reporting. If it does not, check the date range and whether you have any identifiable assistant referrals before changing channel definitions.
    2. Break the channel down by source and landing page. The channel total tells you the size of the stream; the source shows which supported assistant sent it; the landing page reveals which answers or resources earned the click.
    3. Compare AI Assistant and organic search over the same date range. Use the same qualified actions and conversion definitions for both channels. Otherwise, the comparison answers a reporting question rather than a business question.
    4. Show counts beside rates. A high conversion rate based on a very small number of sessions is useful as an early signal, but it is not yet a dependable forecast.
    5. Keep unidentified traffic unidentified. Do not relabel direct visits as AI traffic merely because AI visibility increased during the same period.

    Your recurring report should include identifiable AI sessions, source, landing page, qualified action count, qualified action rate and any matched opportunities. Add the number of leads that explicitly named an AI assistant even when analytics did not record an AI referral. That last field exposes influence the channel report cannot see without pretending the attribution is certain.

    The pattern matters more than the channel total. If AI traffic is small but converts well, protect the pages earning those visits and expand the buyer questions they answer. If traffic grows while qualified actions remain flat, inspect the landing page promise, offer and next step. More assistant visibility will not repair a page that attracts one intent and presents a call to action for another.

    The AI Assistant channel is a measurement improvement, not complete AI attribution. It covers identifiable referrals from supported assistants. It cannot count an answer that satisfies the buyer without a click, and it cannot automatically recover an AI touch when the buyer returns later through direct traffic, branded search or a different device.

    Connect assistant referrals to leads, accounts and opportunities

    Anonymous referral streams pass through a website gateway and connect in sequence to a lead, a company account and a qualified opportunity.

    B2B attribution becomes difficult after the click because evaluation often continues across sessions and people. Solve that problem with explicit evidence labels rather than a more aggressive attribution claim.

    • Observed AI referral: Google Analytics placed the session in the AI Assistant channel.
    • Self-reported AI discovery: A lead named an assistant when asked how they found the company.
    • AI-influenced opportunity: the account has either form of documented AI evidence before opportunity creation.
    • AI-sourced opportunity: AI discovery met your narrower, written rule for the first known acquisition touch.

    Do not merge these labels. An observed referral has stronger click evidence than an inferred influence, while a self-reported answer can reveal discovery that analytics missed. Both are useful as long as the dashboard preserves the distinction.

    1. Choose the onsite action that represents meaningful intent for your sales motion. It might be a demo request, contact submission, trial start, pricing interaction or another event your team already treats as qualified.
    2. When a visitor becomes a lead, carry permitted acquisition fields into the CRM: original source, current source, landing page, campaign and the date of the qualifying action. Retain the original values rather than overwriting them on every return visit.
    3. Add a short, optional discovery question to the form or sales qualification process. Allow the buyer to name ChatGPT, Claude, Gemini or another route in their own words instead of forcing every answer into a fixed channel list.
    4. Join the evidence at the lead and account levels where your consent and data practices allow it. Account-level reporting matters when one person researches and another submits the form.
    5. Write the attribution rule directly in the dashboard. State which touch qualifies an opportunity as sourced, which touches count only as influenced, and whether the evidence must occur before lead or opportunity creation.

    Track progression as counts and rates: identifiable AI sessions, qualified actions, leads, opportunities and closed revenue. Keep pipeline value beside opportunity count because one large deal can otherwise make a small channel look predictably scalable. For the same reason, do not forecast from conversion rate alone while the denominator remains small.

    This model also gives sales a useful feedback role. When a prospect mentions an assistant, record the assistant, the question they were trying to answer and any page or claim they remember seeing. That information can reveal buyer language, missing content and attribution gaps without turning an anecdote into a performance benchmark.

    Turn LinkedIn activity into a measurable discovery loop

    LinkedIn can strengthen the public evidence around a B2B company, but activity alone is not a growth result. Treat the company page, employee expertise, long-form content and distribution as inputs. Measure assistant visibility, referral traffic and pipeline separately as outputs.

    Remove ambiguity from your company and expert profiles

    Start with factual consistency. Keep the business address, contact details and product descriptions accurate on your website. Update the LinkedIn company page’s About section and services, including relevant industry language. Treat the profiles of executives and active subject-matter experts as extensions of the same entity, with current roles and clear areas of expertise. These are core surfaces for B2B AI discovery work.

    Assign an owner to each surface and update all of them when the company changes a product name, category, service or positioning statement. If your site publishes corresponding organization or product structured data, include it in the same update. Consistency does not guarantee an assistant mention, but it removes avoidable uncertainty about what the company does and who represents it.

    Publish one complete answer for each valuable buyer question

    Use LinkedIn articles and newsletters for questions that require more than a short update. The 800-1,200-word range associated with stronger AEO mentions is a useful starting hypothesis, not a universal ranking requirement. A complete 700-word answer is more useful than 1,000 words padded to satisfy a target.

    Give each long-form asset a specific job:

    • Use the buyer’s question or decision in the headline.
    • Answer it directly near the beginning.
    • Name the product category, intended user and relevant constraints plainly.
    • Explain criteria and tradeoffs that help the buyer make a decision.
    • Link to the corresponding website resource when the reader needs evidence, implementation detail or a next step.
    • Connect the content to an identifiable expert whose profile supports the subject.

    Add campaign parameters to links you control from LinkedIn so you can measure LinkedIn visits accurately. Keep those visits classified as LinkedIn traffic. A tracked LinkedIn click is not an AI referral, even when the content was also designed to improve AI discovery.

    Use engagement thresholds as experiments, not ranking factors

    If your team needs an initial promotion checkpoint, start with at least 10 substantive comments or 60 reactions. These figures can guide a campaign test, but they are not verified causal ranking factors for every LLM. Record them as engagement outcomes, then look independently for changes in assistant mentions, AI Assistant referrals and qualified demand.

    Count comments that contribute a question, example, objection or informed response. A pile of generic replies may increase the visible total without improving the information around the topic. Employee participation, expert partnerships, boosted company updates, Thought Leader Ads and follower ads can expand distribution, but paid and organic exposure should remain separate in your campaign log.

    Test one topic cluster from publication to pipeline

    1. Choose one buyer question tied to a product or service that can create qualified demand.
    2. Record the current website answer, LinkedIn coverage, controlled prompt observations and identifiable AI traffic.
    3. Correct company and expert profile details before publishing, so entity changes and content changes happen in a documented sequence.
    4. Publish the complete website resource and its LinkedIn treatment. Record the URL, author, publication date, distribution method, paid support and engagement.
    5. Watch all three measurement layers through a reporting period appropriate to your traffic volume and sales cycle.
    6. Compare the result with a similar topic cluster you did not change. Treat the difference as directional evidence unless your test design supports a stronger causal conclusion.

    Read breaks in the chain literally. More LinkedIn engagement without more assistant visibility proves distribution, not AI discovery. More assistant visibility without referral growth may mean the answer resolves the question without a click or does not present a useful next step. More AI referrals without qualified actions points to the landing page or intent match. More qualified leads without opportunities points to qualification, offer fit or the sales handoff.

    Key takeaways

    • Measure AI discovery as visibility, identifiable traffic and business outcomes. No single metric covers all three.
    • Use GA4’s AI Assistant channel for recognized referrals from supported assistants, but do not relabel direct traffic to fill attribution gaps.
    • Preserve observed referrals, self-reported discovery, influenced opportunities and sourced opportunities as separate evidence classes.
    • Keep website facts, LinkedIn company details and expert profiles current before trying to scale content distribution.
    • Treat the 800-1,200-word content range and engagement thresholds as test inputs, not universal LLM ranking rules.
    • Scale a topic only after you can follow its path from buyer question to content, assistant visibility, qualified action and pipeline.

    Start with one revenue-relevant buyer question. Establish the baseline, publish a complete answer, track the assistant referral and carry the evidence into your CRM. The first broken link in that chain tells you what to fix next. Repair it before increasing content volume or promotion spend.

    References

  • Performance Max Reporting for B2B: An Optimization Plan

    Performance Max Reporting for B2B: An Optimization Plan

    Your Performance Max campaign can look efficient while your sales team rejects nearly every lead. That isn’t a contradiction. It means the campaign is succeeding against a conversion signal that doesn’t represent the business outcome you actually need.

    You don’t need complete visibility into every automated bid to fix that problem. You need a reporting chain that connects platform activity to qualified pipeline, plus a disciplined way to intervene when the chain breaks. Here is how to build it.

    Start with the business outcome, not the campaign CPL

    Cost per lead is only useful when the word lead has a stable business meaning. A form submission, sales-accepted lead, opportunity and closed deal are not interchangeable outcomes. If PMax counts the first while your team values the third, a falling CPL can hide deteriorating performance.

    Begin with a conversion inventory. List every action available to the campaign, then write down what each action proves. A form submission proves that someone completed a form. It does not prove that the person fits your market, has buying authority or represents a real organization. Treating those facts as equivalent gives automation an easy target and gives you misleading reporting.

    1. Define the funnel stages your team can verify. Use the stages already applied consistently in your CRM, such as inquiry, accepted lead, opportunity and won business. Don’t create a more elaborate taxonomy than sales can maintain.
    2. Choose the deepest dependable optimization signal. The ideal event is close to revenue, recorded consistently and available often enough to guide the campaign. If closed business is too sparse or delayed, use the nearest reliably graded stage rather than pretending a raw form fill is equally valuable.
    3. Keep earlier actions for diagnosis. An inquiry can still reveal landing-page or creative behavior. It simply shouldn’t be allowed to masquerade as qualified demand in your business reporting.
    4. Connect platform records to later CRM outcomes. For B2B campaigns, offline conversion tracking and enhanced conversions for leads help carry information from the initial interaction into the later stages that matter.
    5. Remove obvious form abuse before asking the algorithm to learn. Controls such as reCAPTCHA can reduce low-quality submissions. They don’t replace qualification, but they prevent some worthless activity from being treated as useful training data.

    No tracking configuration can rescue an undefined lead. Sales and marketing must agree on the rule for accepting or rejecting one, and that rule must be applied consistently. Otherwise, imported outcomes encode internal inconsistency rather than buyer quality.

    This also changes how you evaluate cost. A campaign with a higher form-fill CPL may be the better investment if more of those forms become accepted leads or opportunities. Compare cost at the deepest mature stage available, not merely at the fastest stage the ad platform can report.

    Build a reporting chain that answers five different questions

    Five connected transparent chambers show a stream of marketing activity narrowing into leads, qualified prospects, and valuable pipeline outcomes.

    No single PMax report can tell you whether a campaign is working. Placement data explains where ads appeared. Channel data shows how automated delivery was distributed. Intent reports add search context. Asset reporting helps you inspect messages and formats. Your CRM determines whether any of that activity produced business value.

    Reporting layerQuestion it answersEvidence to inspectDecision it can support
    Business outcomeDid the lead progress?CRM qualification, opportunities, won business and imported offline outcomesChange the optimization signal, qualification process or lead controls
    Campaign and channelWhere did automated delivery produce recorded conversions?Campaign results, segmented conversion metrics and account-level channel reportingInvestigate channel mix and decide where a more focused follow-up test belongs
    Publisher placementWhich inventory received spend and recorded conversions?Microsoft’s Website Publisher URL report with spend and conversion dataIdentify inventory worth studying, protect brand safety or add a justified URL exclusion
    Intent and competitionWhat demand patterns surrounded performance?Google search term insights, auction insights, search themes and brand controlsRefine intent guidance, separate branded demand or investigate a competitive change
    Creative assetWhich messages and formats appear to attract response?Asset-level reporting and controlled creative testsRetire weak messages, add qualification or develop a stronger variant

    Microsoft’s PMax reporting makes the placement layer more actionable by adding conversion and spend metrics to the Website Publisher URL report. That is materially better than a list of domains with no economic context. You can see which placements consumed budget and which were associated with recorded conversions.

    But recorded conversions are still only as trustworthy as the conversion definition. A publisher with several form fills is not automatically a strong B2B placement if none of those people survive qualification. Conversely, a publisher with spend and no immediate conversion is not automatically waste if your evaluation window closes before leads mature. Join placement evidence to the CRM before making an efficiency judgment.

    Google’s channel, search-term, auction and asset reporting answers different questions. Channel reporting can expose where reported results originate, while search term insights add context about demand. Auction insights help you notice competitive conditions. Asset reporting shows how creative components are being evaluated. None of these views, by itself, proves incremental revenue.

    The practical rule is simple: use platform reporting to locate a pattern, then use downstream data to decide whether that pattern deserves action. A report is diagnostic evidence, not a verdict.

    Apply PMax controls in the order that reduces uncertainty

    When lead quality is poor, it is tempting to change audience signals, creative, themes and exclusions at once. That creates activity without producing a clear lesson. Apply controls from the bottom of the measurement chain upward.

    1. Repair the conversion signal and form hygiene

    First confirm that legitimate leads can be connected to later CRM stages and that obvious spam is filtered. If the campaign is rewarded for an event your business doesn’t value, every targeting adjustment rests on a faulty objective.

    Inspect conversion metrics separately rather than blending every action into one total. A campaign that produces many shallow actions and few qualified outcomes should not receive the same interpretation as one that advances prospects through the funnel. Segmented conversion reporting and offline outcomes give you the distinction needed to see that difference.

    2. Feed the system a clean first-party audience signal

    A large CRM export is not automatically a useful audience input. It may mix customers, unqualified inquiries, inactive records, students, vendors and prospects at unrelated stages. That teaches the system that all records deserve equal attention.

    Clean and segment the data before using it. Start with groups closest to a verified revenue event, provided each group has a consistent business definition. A list of accepted leads or opportunities usually carries clearer intent than an undifferentiated list of everyone who has ever completed a form. The value comes from the label, not the file size.

    Treat audience signals as guidance to be validated. After launch, compare the resulting leads with the segment characteristics you intended to emphasize. If the campaign finds cheap conversions outside your real customer profile, the CRM outcome should overrule the attractive platform metric.

    3. Use search themes and brand exclusions to clarify intent

    Search themes can guide Google PMax toward the demand you want it to explore. Build them around the problems, use cases and buying situations your qualified prospects actually express. Avoid turning themes into a loose catalogue of every phrase related to your industry.

    Brand exclusions solve a separate problem. If your objective is to assess incremental acquisition, branded demand can make an automated campaign look more efficient than its prospecting work really is. Search themes and brand exclusions provide useful control over those inputs and costs. Decide explicitly whether a campaign should capture existing brand demand or discover new demand, then configure and judge it against that purpose.

    Review search term insights after the campaign has produced meaningful evidence. Look for patterns that indicate the wrong buyer, job seeker, student, consumer use case or research intent. Those patterns should lead to a specific hypothesis about themes, messaging or conversion quality. They shouldn’t trigger an indiscriminate attempt to block anything unfamiliar.

    4. Treat placement exclusions as a precise control

    Microsoft’s placement spend and conversion data can expose publishers that are clearly unsuitable for the brand or economically unproductive after downstream outcomes are considered. High-performing inventory can also inform a separate Audience Ads or remarketing strategy, while unsuitable inventory can be added to an account-level URL exclusion list.

    Account-level exclusions have a wider blast radius than a campaign-specific observation. Before adding one, verify the exact domain, the reason for exclusion and the other campaigns that may rely on it. A clear brand-safety conflict can justify immediate action. An apparent performance problem needs more context: adequate spend relative to your economics, a review window long enough for lead grading and evidence that the recorded conversions did not progress.

    Do not turn the placement report into a manual bidding console. Its best use is to find material exceptions: unsafe environments, obvious mismatch, persistent waste or inventory that deserves a focused follow-up strategy.

    5. Make creative qualify the prospect

    B2B creative should do more than generate attention. It should help the right buyer recognize relevance and help the wrong visitor recognize a mismatch. State the use case, intended role, business context or other genuine qualifier that distinguishes your offer. Vague creative may attract more interactions while making lead quality harder to control.

    Video deserves deliberate treatment because YouTube is an important part of PMax inventory. Google also provides AI-assisted asset creation, creative testing and asset-level reporting. Use those capabilities to test a defined message difference, not merely to produce more variations. A useful test might compare problem-led positioning with outcome-led positioning, or broad language with a clear buyer qualifier.

    Read asset results alongside lead quality. An asset that attracts many conversions but disproportionately weak prospects may be doing its job badly, even if the platform labels it positively. The next variation should address the mismatch in the message rather than simply changing the visual treatment.

    Run a decision loop that sales can audit

    Marketing and sales professionals work at a circular table where campaign controls, lead reviews, feedback, and opportunity markers form a connected loop.

    PMax optimization becomes safer when every change starts with an observed business problem. Use the table below as a diagnostic map. The first column is a symptom, not a conclusion.

    What you noticeWhat to verifyWhat to do next
    Platform conversions rise while accepted leads stay flatWhich conversion actions increased, whether form abuse changed and whether offline outcomes are returning correctlyCorrect the optimization signal or lead-quality controls before changing audience inputs
    Form-fill CPL rises while opportunity creation improvesCost per accepted lead and opportunity for a fully graded cohortJudge the campaign on the deeper outcome rather than cutting it solely because the shallow CPL increased
    A publisher consumes spend without qualified progressionPlacement spend, recorded conversions, CRM outcomes, evaluation lag and brand suitabilityExclude a verified unsafe or persistently wasteful URL; otherwise gather enough context to distinguish delay from failure
    One channel appears to overperformConversion mix and lead quality by channelUse the pattern to design a focused channel or audience test instead of assuming every reported conversion has equal value
    An asset attracts response but weak prospectsThe CRM quality of leads associated with its message and offerAdd a buyer, use-case or business-context qualifier and test the revised message
    Branded demand dominates the visible intent patternWhether the campaign’s job is brand capture or incremental acquisitionUse brand controls where appropriate and report branded and non-branded intent against separate expectations
    Auction conditions change near a performance shiftWhether conversion quality, creative, landing experience or campaign inputs changed at the same timeTreat auction data as context and test the most plausible cause rather than declaring competition the cause automatically

    Make the review window match your buying process. If sales has not yet graded the leads in a cohort, that cohort cannot support a final quality conclusion. Label it incomplete instead of filling the gap with the platform’s faster metrics.

    Keep a short decision log for every material intervention. Record the observed problem, the evidence from each reporting layer, the change made, the downstream metric expected to move and the point at which the affected leads will be mature enough to review. This prevents the team from repeating tests or crediting an unrelated performance swing to the latest edit.

    Change one major layer at a time where practical. If you replace the audience signal, add themes, exclude publishers and rewrite every asset together, you may improve results but learn very little about why. Sequencing changes turns automation from an opaque system into a set of testable business decisions.

    Key takeaways

    • PMax optimizes the conversion definition you provide, so a cheap form submission is not evidence of efficient B2B growth.
    • Use offline outcomes and consistent CRM stages to evaluate cost per qualified result, not just cost per initial lead.
    • Placement, channel, intent, auction and asset reports answer different questions. Join them to downstream outcomes before acting.
    • Clean first-party audience segments, focused search themes and qualifying creative give automation better guidance.
    • Use URL and brand exclusions deliberately. Confirm the scope, business purpose and downstream evidence before restricting delivery.
    • Log each material change and wait until the affected lead cohort is mature enough to judge.

    Start with the latest lead cohort that sales has completely graded. Compare its CRM outcomes with the campaign, channel, intent, placement and asset evidence available on your platform. Find the largest break in that chain and change that layer first. The goal is not to control every automated decision. It is to make sure automation is learning from, and being judged by, the same definition of value your business uses.

    References

  • How to Build a Human-Led B2B Brand and Content Strategy

    How to Build a Human-Led B2B Brand and Content Strategy

    You can have a full content calendar, capable writers, strong subject-matter experts, and an AI workflow that produces drafts in minutes, yet still sound interchangeable with every competitor. The problem usually sits upstream: nobody has made a firm decision about what the market should believe about the brand.

    A human-led strategy fixes that without discarding AI. People retain the decisions with commercial consequences: what the brand should mean, which evidence deserves emphasis, what not to claim, and which trade-offs are acceptable. AI handles bounded work around those decisions, including organization, drafting, transformation, consistency checks, and distribution.

    Brand strategy begins with a decision, not a prompt

    AI can generate dozens of plausible positioning statements. That abundance is useful for exploration, but it is not a strategy. A position becomes strategic when you choose one interpretation of the business, support it, and reject adjacent messages that would weaken it.

    The distinction matters because your preferred position may not be the most obvious conclusion available from the facts. AI can connect known information and propose possible narratives, but it does not carry responsibility for choosing the narrative that serves your company, customers, and long-term direction. A named human must make that choice.

    A practical way to structure the decision is the claim-frame-prove discipline. It separates three elements that teams often collapse into one vague brand statement.

    ElementQuestion it must answerHuman decisionRequired output
    ClaimWhat do we want the market to believe?Choose a specific, defensible proposition instead of a collection of benefits.A sentence that can be tested against evidence.
    FrameWhy does this claim matter, and how should the evidence be interpreted?Select the commercially useful conclusion and the alternative view you are challenging.An explicit logical bridge from accepted facts to the desired association.
    ProofWhy should a buyer or an answer engine believe us?Set the evidence threshold, boundaries, and caveats.Named, accessible support for every material assertion.

    Write the claim so it can succeed or fail

    Statements such as trusted partner, innovative platform, and customer-first company are difficult to disprove, which also makes them difficult to value. Replace them with a proposition that has an identifiable audience, problem, outcome, and reason to believe.

    Use this working structure: For a specific buyer facing a specific decision, the brand represents a defined approach or advantage because named evidence supports it. This matters because the evidence leads to a useful conclusion the buyer may not have considered.

    Do not publish the template itself. Use it to force the internal decision. If the team cannot complete it without broad adjectives, multiple audiences, or unsupported outcomes, the positioning is not ready for production.

    Treat the frame as strategy, not decoration

    A frame is not a clever slogan placed above the same old product copy. It tells the reader what the evidence means. Two companies may have similar capabilities, but the company that explains the consequence of those capabilities can own a more useful association in the buyer’s mind.

    Pressure-test a proposed frame with five questions:

    • Would a relevant competitor be equally comfortable making this claim?
    • Does the proof establish the promised outcome, or merely show that a feature exists?
    • Does the frame add a meaningful conclusion rather than restating the claim?
    • Can a skeptical reader follow the path from evidence to conclusion without filling in a missing step?
    • Have you stated the conditions or use cases in which the claim does not apply?

    If the competitor can copy the entire argument without changing the evidence, you have a category description, not a position. If the conclusion requires a leap that the proof cannot support, you have promotion, not a position. Human judgment is the work of finding the narrow territory between those failures.

    Turn positioning into a content operating system

    A human hand places a central colored block into a connected tabletop system of blank content modules and evidence tokens.

    A positioning document has little value if every writer interprets it differently. Your content system must carry the same claim, frame, and proof into landing pages, executive viewpoints, product education, case material, sales enablement, and answer-focused content without forcing every asset to repeat identical wording.

    Start with a claim ledger rather than a topic calendar. The calendar tells you when something will be published. The ledger tells you what the business is prepared to assert, why it is true, where the evidence lives, and who is accountable for approving it.

    Each ledger entry should contain:

    • Approved claim: the exact proposition content may communicate.
    • Intended audience and decision: who needs the information and what they are trying to decide.
    • Strategic frame: the conclusion the evidence should help the audience reach.
    • Proof: the product fact, operational evidence, customer evidence, expert knowledge, or other support available for the claim.
    • Evidence location: the page, record, or internal owner that can substantiate the assertion.
    • Scope limits: markets, use cases, products, or circumstances the claim does not cover.
    • Approval owner: the person authorized to accept, narrow, or reject the claim.

    A claim without an evidence location or owner is not ready to enter an AI prompt. Marking it as unverified is safer than allowing a drafting system to fill the gap with language that merely sounds credible.

    Brief content around a buyer decision

    Topic-only briefs produce topic-shaped content: broad, informative, and hard to distinguish. A decision brief tells the writer what must change for the reader. It should identify the question that brought the reader to the page, the misconception or uncertainty blocking progress, the approved claim, the frame, the evidence, and the next sensible action.

    Before drafting, require the content owner to finish this sentence: After reading, the intended buyer should be able to decide whether or how to do something specific. If the answer is merely understand the topic, the brief is probably too broad.

    Then assign the page one primary job. It might define a problem, establish a fact, compare approaches, resolve an objection, substantiate a brand claim, or help the buyer act. A page may support secondary jobs, but letting every asset do everything usually produces a long page with no clear purpose.

    Give AI bounded responsibilities

    AI is most useful after the decision architecture exists. Give it approved material and a defined transformation, then require it to expose gaps instead of inventing bridges.

    Suitable AI responsibilities include:

    • Grouping buyer questions by intent or stage.
    • Turning approved interviews and notes into candidate outlines.
    • Producing channel-specific versions of an approved argument.
    • Checking drafts for contradictions against the claim ledger.
    • Finding assertions that lack attached evidence.
    • Suggesting alternative explanations while preserving the approved position.
    • Identifying where the relationship between a claim and its proof remains implicit.

    Keep these responsibilities human:

    • Choosing the market association the brand will pursue.
    • Deciding which audience or use case takes priority.
    • Judging whether the available evidence is strong enough.
    • Resolving disagreements between subject-matter experts.
    • Approving external claims, comparisons, and conclusions.
    • Deciding what the brand will deliberately decline to say.

    The boundary is simple: AI may generate options and transformations, but it does not receive decision rights. Record the human decision before generation begins so the team can distinguish deliberate strategy from wording that appeared during drafting.

    Make the brand legible to buyers and answer engines

    Business buyers and an abstract scanning device examine the same illuminated geometric object and its visible proof components.

    Having evidence somewhere on the website is not the same as communicating an evidence-backed position. A person may infer the connection after visiting several pages. A search or answer system may not make the same connection, and it has no obligation to choose the interpretation most favorable to your brand.

    Brand evidence typically becomes more usable through three levels:

    <!– wp:list {