Tag: Audit

  • Multi-Location SEO Page Architecture That Scales Cleanly

    Multi-Location SEO Page Architecture That Scales Cleanly

    Your location URLs keep multiplying, but rankings, calls and visits are not. Launching another city page may look like the quickest way to reach a new market, yet excess geographic pages can make your own URLs compete, divide authority and contradict one another.

    A durable architecture works in the opposite direction. You represent the places where the business actually operates, give every page a distinct customer job and publish the smallest set of geographic URLs that can do those jobs well. Here is how to design that system, evaluate proposed city pages and clean up an existing footprint without discarding useful local information.

    Map the operating footprint before choosing URLs
    Hands arrange branch, service-area and customer markers on an unlabeled layered regional map.

    Start with the business, not a keyword export. Build a working inventory of facilities, teams, services and markets before deciding what belongs under /locations/. This prevents a common category error: treating every place name as evidence of a separate local entity.

    Your inventory should record:

    • Every customer-facing facility, including its official name, address, hours and primary contact path.
    • The staff or team responsible for each facility and market.
    • The services actually available at each location, rather than the complete company-wide service list.
    • The regions used operationally by the business, such as states, metro areas or franchise territories.
    • The communities each facility or field team can genuinely serve.
    • Material local differences, including access, logistics, regulations, delivery conditions or customer procedures.
    • The person or system responsible for keeping each local fact accurate.

    Then classify each geographic concept. A physical facility, a regional market, a service area and a city the company wants to rank in are not interchangeable.

    Operating realityCustomer needDefault architectural response
    Customer-facing facilityConfirm where it is, when it is open, what it offers and what visiting involvesCreate an authoritative location page
    Region containing multiple facilitiesUnderstand the brand’s presence and choose the appropriate facilityCreate a regional hub only when it materially helps that choice
    Service area reached by a facility or field teamConfirm coverage and understand how service is deliveredExplain it on the responsible location or service page unless the market has enough distinct substance for an exception
    City the business wants to rank inDiscover a relevant providerTreat it as a marketing objective, not an automatic page type

    Service-area settings in Google Business Profile should not determine this map. Adding a city to a profile does not require a city landing page, and publishing a page does not create a physical presence there. The website must remain honest about whether customers visit you, you travel to them, or both.

    At the end of this exercise, every proposed page should point back to an operating fact. If all you can point to is search volume, you have found a keyword opportunity, not yet a reason for a new URL.

    Build a hub-and-spoke system around customer decisions

    Most multi-location sites need a central locations directory connected to regional or individual location pages. The depth depends on the business. A larger network might use /locations/, /locations/pennsylvania/ and /locations/pennsylvania/philadelphia/. A smaller regional company might need only /locations/ and /locations/philadelphia-pa/. Neither folder pattern is inherently more optimized; the useful pattern is the one that mirrors the real hierarchy without inserting empty layers.

    The main locations hub helps people orient themselves

    The hub should explain the overall footprint and help a visitor reach the right facility. A map, postcode search or location finder can improve the experience, but it should complement a crawlable directory rather than replace it. Include direct links to important regional and location pages so people and crawlers can navigate the footprint without operating an interactive widget.

    Organize that directory in the way customers choose: by region, proximity, service availability or another real decision factor. Do not add state and city levels merely to make the URL look comprehensive.

    Regional hubs resolve a choice between facilities

    A regional page earns its place when it helps someone understand a meaningful market or compare several facilities. It can describe the coverage model, identify available locations, clarify material differences and send the visitor to the correct next page.

    A region with only a heading, generic brand copy and links to a single destination is an unnecessary layer. Link the main hub directly to the location unless the regional URL has a durable job of its own.

    Location pages represent real facilities

    A location page is more than an organic landing page. It is the business’s authoritative digital representation of that facility. Someone arriving from search, navigation, an AI answer or a shared link should be able to confirm that the place is real and decide what to do next.

    Include the local facts that change the decision:

    • Official location name, address, contact details and opening hours.
    • Services available at that facility, with links to the relevant service pages.
    • Local staff or team information when it helps customers know whom they will deal with.
    • Directions, arrival instructions and recognizable local context.
    • Parking, entrances, mobility access and other accessibility details.
    • What happens after the visitor calls, books or arrives.
    • A conversion action appropriate to that facility, such as calling, booking, requesting service or getting directions.

    Do not manufacture superficial rewrites merely to achieve an arbitrary uniqueness percentage. Accurate service descriptions, brand language and booking instructions may need to recur. The decisive question is not whether some copy is shared, but whether the page has a distinct reason to exist. Its differentiation should come from local reality, not a thesaurus.

    Service and location pages answer different questions

    A service page explains what the company offers. A location page explains where and how customers receive it. Keep both roles intact and connect them deliberately:

    • From a location page, link only to services genuinely available there.
    • From a service page, help the customer find the facilities or teams that provide it.
    • From a regional hub, link to the facilities contained in that market.
    • From the main hub, expose the regional or location pages that form the real operating hierarchy.

    A service-area page is a controlled exception within this system. It may be justified when the market has a dedicated team, distinct logistics, local regulatory conditions or substantial project experience that cannot be handled properly on an existing page. Willingness to drive into a city is not enough.

    Make every proposed geographic page pass an evidence test

    Keyword demand can reveal an audience, but it cannot tell you whether that audience needs a separate destination. Before approving a geographic page, require the requester to answer these questions in writing:

    • What customer task will this page complete? The answer should be more specific than ranking for a city term.
    • What real operation does it represent? Name the facility, team, territory, logistics model or other business fact behind it.
    • Why can’t an existing page satisfy the same intent? Identify the gap instead of assuming a new URL is the cure.
    • Which facts are genuinely local? Look for distinct staff, services, access, regulations, logistics, projects or customer expectations.
    • Does it lead to a meaningful local action? The conversion path should match how the business serves that market.
    • Where does it belong in the hierarchy? Define its parent page and the service, regional or location pages that should link to it.
    • Who will maintain it? A page containing hours, services or team details needs an accountable owner.
    • Would its purpose survive if you removed the city name from the draft? If nothing substantive remains, you probably have a keyword variant rather than a useful page.

    The physical-location question carries the clearest answer: a real customer-facing facility generally warrants a location page. A service-area proposal needs stronger operational evidence because the place name alone does not represent a separate entity.

    Consider a field team that leaves from one facility and serves surrounding communities with the same staff, services, process and booking path. A separate page for every community would mostly change the city name while funneling every visitor to the same operation. The better answer is usually one strong facility or service page that clearly explains its coverage.

    Now consider a market with its own team, different delivery constraints, local rules and a body of market-specific work. That page can answer questions the parent location page cannot. It has an operational identity and a customer job, not merely a keyword.

    This distinction also keeps the site away from a doorway-like pattern. Pages become risky when they target closely related queries, offer little market-specific value and send visitors toward the same destination. Not every weak city page constitutes doorway abuse, but a large collection of near-identical funnels is poor architecture even before policy becomes the concern.

    Consolidate geographic bloat without erasing useful local value
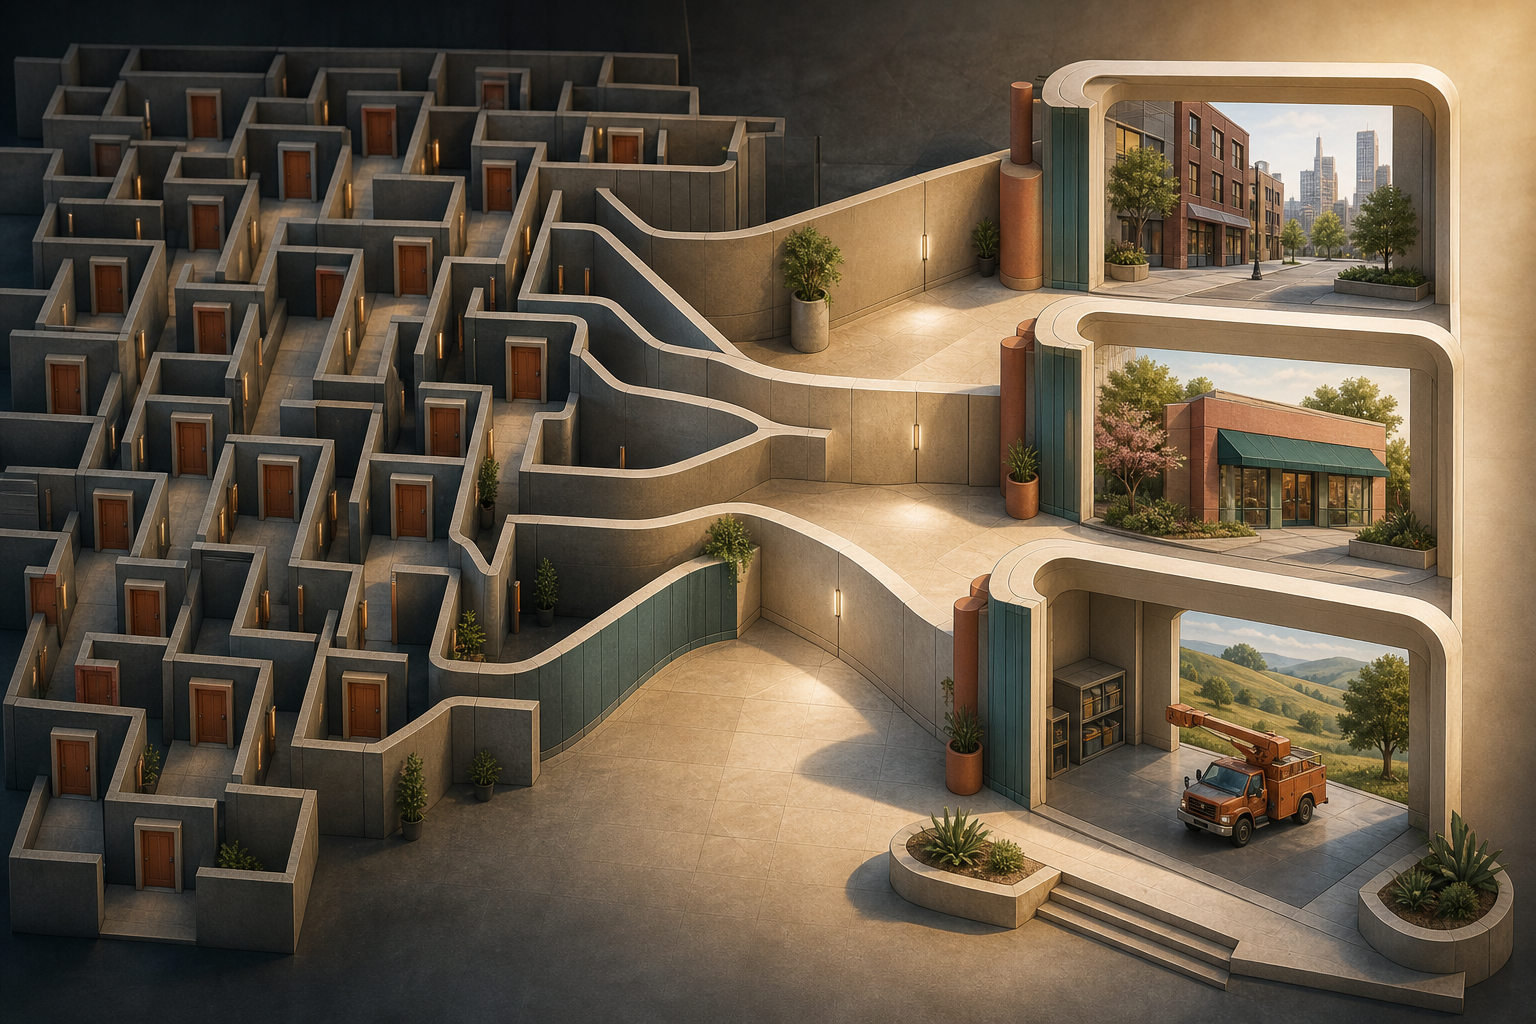
    A maze of similar doorways merges into a central hall leading to a few distinct local spaces.

    Geographic sprawl usually accumulates through individually plausible decisions: a city-keyword project, neighborhood pages around a branch, a franchise microsite or a replacement URL structure that leaves the old one intact. The result is often an architecture that no team fully owns.

    Do not begin the cleanup by changing folders or deleting low-traffic pages. Begin with a complete URL inventory and group pages by the intent they satisfy, the operation they represent and the conversion destination they use.

    1. Find every geographic URL. Combine CMS exports, XML sitemaps, crawl data, navigation links and known campaign landing pages. Include orphaned pages that are still indexable even if they no longer appear in menus.
    2. Record evidence before making changes. Capture each page’s business entity, target intent, organic landing activity, conversions, internal links, external links and current indexation status. This keeps a quiet but useful customer page from being mistaken for dead weight.
    3. Cluster overlapping pages. Put URLs together when they answer the same geographic query, represent the same facility or team, and send visitors to the same conversion path. Similar titles alone are not enough; compare the job each page performs.
    4. Assign a disposition. Keep a page with a clear, durable job. Merge pages whose useful information belongs on one authoritative destination. Repurpose a page only when a genuine uncovered customer need exists. Retire a URL that has no distinct entity, intent or maintained value.
    5. Select the surviving destination by utility. The winner should best represent the real operation and satisfy the visitor, even if another duplicate happens to have the preferred slug. Traffic is evidence to consider, not a substitute for architectural logic.
    6. Preserve worthwhile local information. Move accurate directions, accessibility details, team information, service availability or project context to the surviving page before retiring a duplicate.
    7. Redirect deliberately. When content has a relevant replacement, use a permanent redirect to that destination. Do not send every retired city URL to the homepage; that breaks the geographic intent instead of resolving it.
    8. Update the system around the URL. Change internal links, navigation, directory listings, canonical references and XML sitemaps so they point directly to the surviving page rather than through a redirect.
    9. Verify the result. Crawl the revised section, test important customer paths and watch indexation, landing-page activity and conversions for unexpected losses or lingering duplicate URLs.

    A page should not be removed merely because it attracts little organic traffic. Location pages also help customers verify a facility, understand the visit and take action. If the page serves that role well, improve its discoverability and local facts rather than judging it as a failed keyword landing page.

    Add governance so the bloat does not return

    A cleaner tree will expand again unless page creation has an owner and an approval rule. Use a short request record for every new geographic URL. It should name the page type, operating entity, customer job, parent page, market-specific evidence, conversion path and maintenance owner.

    Maintain one dependable business-data record for addresses, hours, contacts, services and local ownership. Templates can then reuse stable brand and service information while pulling the local facts that make each facility accurate. This is more valuable than asking writers to disguise duplication with cosmetic wording changes.

    When the business opens, closes, relocates or changes what a facility offers, update that record and its dependent pages as one operational task. Architecture is not finished when URLs launch; it succeeds when the site can remain correct as the footprint changes.

    Key takeaways

    • Build the location tree from facilities, teams, services and real markets before using keyword demand to refine it.
    • Treat physical locations, regional markets, service areas and desired ranking cities as different concepts.
    • Use regional hubs only when they help customers understand a market or choose among multiple facilities.
    • Make each location page the authoritative customer resource for its facility, including services, hours, staff, directions, access and next steps.
    • Approve service-area pages only when distinct operations or market-specific information give them a durable customer purpose.
    • Consolidate pages that satisfy the same intent and lead to the same operation, then redirect and update internal signals deliberately.
    • Require a business owner and maintenance plan for every geographic URL.

    If you take one action this week, freeze new city-page requests long enough to build the operating-footprint matrix. Place every current and proposed URL beside the facility, region, team or service condition that justifies it. The blank rows will show you where keyword ambition has outrun business reality.

    Start cleanup with the clearest overlap, preserve the information customers still need and give the surviving page a single accountable owner. A leaner location system will not manufacture local relevance, but it will make the relevance you genuinely have easier for customers, search engines and AI retrieval systems to understand.

    References


  • How to Change Your Google Business Profile Address Safely

    How to Change Your Google Business Profile Address Safely

    Changing a Google Business Profile address looks like a simple dashboard edit. It isn’t. The address shown on the profile, the coordinate Google uses to place the business, and the location around which the profile ranks can stop agreeing with one another.

    This matters most when you have moved, inherited a service-area business profile, or discovered that the original listing used a home, P.O. box, or virtual office. Before you edit anything, identify the profile’s current operating model and its historical location anchor. That one audit can prevent a routine move from becoming a ranking or verification problem.

    Key takeaways before you change the address

    • A visible-address business and a hidden-address service-area business should not follow the same migration process.
    • The address entered in Google Business Profile is text. Google geocodes that text into a physical coordinate, and that coordinate is the ranking anchor used for proximity calculations.
    • For a hidden-address service-area business, changing the dashboard address may not move the functional ranking anchor. Practitioner testing indicates that the profile can remain tied to the address used when it was created.
    • If a hidden profile is performing well and its original address was legitimate, do not edit it merely to make the dashboard look cleaner. Establish its history and measure its ranking geography first.
    • For a major visible-address move, especially one across state lines, update the website, citations, structured data, and business records before editing Google Business Profile.
    • Keeping an established profile usually preserves reviews and history. Starting over deserves consideration only when the geographic conflict is substantial enough to justify losing those assets.

    Find the profile’s real location anchor first

    Isometric neighborhood scene with a storefront, an aligned map pin, a location radius, and a faint previous pin.

    Start by classifying the business correctly. A storefront or other customer-facing location normally displays its address. A service-area business, or SAB, travels to customers and may keep its address hidden. A hybrid business may serve customers at a staffed location and also travel to them. The critical distinction for this audit is whether the address is currently visible or hidden.

    Next, separate the postal address from the ranking anchor. When an address is entered, Google’s geocoding system interprets the text and assigns coordinates. Those coordinates, rather than the address string by itself, anchor proximity-based visibility. A dashboard can therefore contain a current address while the profile’s effective geographic center still reflects an older one.

    That distinction becomes consequential for hidden-address profiles. Documented practitioner testing indicates that hiding an SAB’s address can leave or return its functional pin to the address used when the profile was created. Editing the hidden address, temporarily showing it, or completing verification after an edit has not reliably moved that anchor in those tests. Google has not made this behavior transparent, and local SEO practitioners disagree about how aggressively legacy profiles should be corrected, so treat it as a strong diagnostic lead rather than a universal promise.

    Before opening the editor, answer these questions:

    • What exact address was used when the profile was created?
    • Could that original address be resolved to the correct building, rather than only an approximate area?
    • Was the original location a legitimate operating address, a home, a P.O. box, or a virtual office?
    • Has the address ever been switched from visible to hidden or from hidden to visible?
    • How many times has the address been changed?
    • Has the business physically moved since its original verification?
    • Where is the profile strongest in local results now: around the current premises, the previous premises, or somewhere else?

    If you inherited the listing and nobody knows its history, do not guess. Run a local grid ranking report for a representative service query, then inspect the same category in a tightly zoomed Google Maps search. A cluster of stronger rankings around an old location is not absolute proof, but it can help you triangulate the likely anchor. Save the grid, the visible map marker, the current address setting, and the profile state as your baseline.

    Choose the migration path that matches your scenario

    Profile situationRecommended approachMain consequence to plan for
    Hidden SAB, never edited, ranking wellLeave the address setting alone if the original location was legitimate. Record a grid report before considering any future change.An edit may create verification or suspension risk without moving the functional ranking anchor.
    Hidden SAB, inherited history unknownRecover the original address and visibility history from the owner. If that fails, use grid rankings and zoomed Maps searches to estimate the existing anchor before deciding.The dashboard’s current address may not explain where the profile actually ranks.
    Hidden SAB originally created with a P.O. box or virtual officeMake a deliberate risk decision. One path is to avoid touching a currently active profile while documenting the unresolved risk. The corrective path is to establish a compliant physical operating address, align supporting citations and records, and then address the profile.Correcting a legacy location can trigger verification or suspension, but leaving it untouched preserves an underlying compliance and continuity risk.
    Visible-address business moving within the same general areaEdit the established profile to the new address and complete any requested reverification. Compare pre-move and post-move ranking grids.The map pin should move, so the profile’s proximity-based ranking pattern may also move.
    Visible-address business moving across state linesUpdate the website, major citations, structured data, business records, and other entity references first. Then edit the existing profile unless a documented review of the tradeoffs supports a fresh start.Old navigational and behavioral history may conflict with the new geography, while a fresh profile would sacrifice reviews and profile history.
    Brand-new profileTest the exact address through Google’s Geocoding API before submitting it. Confirm that it resolves to the intended building with a ROOFTOP result rather than an approximate or partial result.A malformed address, misplaced unit detail, or weak geocoding result can give the profile a poor anchor from the beginning.

    The difficult row is the legacy SAB created with an unsuitable address. There is no zero-risk dashboard trick. Practitioners split between preserving an active profile and correcting the business’s location foundation before making an edit. Your decision should reflect the profile’s current visibility, the eligibility of the new premises, the quality of the supporting records, and the business’s tolerance for an interruption.

    Run the move as a controlled data migration

    Overhead desk scene with old and new storefront models, a street-grid mat, blank status cards, tools, and a hand placing a destination pin.

    Once you have chosen the correct path, treat the move as an entity-data migration. The goal is not to change every platform simultaneously. It is to establish one accurate version of the new location, make the rest of the web agree with it, and leave enough evidence to diagnose any change in visibility.

    1. Write down the canonical new address. Decide the exact street wording, unit placement, city, region, and postal code that the business will use. Confirm that the address identifies the actual operating location rather than a mail-handling substitute.
    2. Create a before-state record. Save the profile’s address visibility setting, map marker, service areas, verification status, and a local ranking grid. Record the original address and previous moves wherever that information is available.
    3. Update first-party business information. Change the primary location or contact page, relevant sitewide address references, and the LocalBusiness JSON-LD. Make sure the structured PostalAddress and the human-readable location information describe the same premises.
    4. Align major third-party references. For a substantial move, update platforms such as Facebook, Yelp, Apple Maps, the Better Business Bureau, and other important citations. Update business documents used to establish the current location as well. The new address should already be the dominant, supportable version of the business’s location before a high-risk Google Business Profile edit.
    5. Validate geocoding where it matters. For a new listing, submit the exact address text to Google’s Geocoding API and check for a ROOFTOP result at the intended building. If the result is approximate, resolve the formatting or address-record problem before creating the profile.
    6. Make the profile-specific change. For a visible business, edit the established profile and complete reverification if requested. For a hidden SAB, proceed only if your earlier audit supports the change; do not assume that toggling address visibility will recenter the ranking anchor.
    7. Measure the geographic outcome. Re-run the same grid query with the same settings after the profile has settled into its verified state. Compare the location of the strongest visibility, not only the average ranking number.

    Address consistency does not mean publishing a private hidden address everywhere. A service-area business should not expose a private location merely to make every database field identical. It means that public location information, structured data, citations, and verification records should accurately represent the business model and should not continue presenting a former location as current.

    For an interstate move, sequencing is especially important. Updating the wider citation and entity ecosystem before Google Business Profile gives the new address corroborating signals. It also makes a verification review easier to explain than a profile edit surrounded by old-state information.

    Diagnose the result before making another edit

    A ranking change after a move is not automatically a penalty. If a visible business moves, its pin and proximity relationships should change. It may become more relevant near the new premises and less relevant near the old one. Your before-and-after grids should show whether visibility moved geographically, weakened everywhere, or remained centered on the former address.

    • The visible marker moved and the ranking grid moved with it: the profile appears to have adopted the new geographic anchor. Evaluate performance around the new market rather than expecting the old ranking footprint to remain unchanged.
    • The dashboard shows the new address but visibility remains centered on the original location: review the profile’s address history. This pattern is particularly significant for a hidden SAB and may indicate that its functional anchor did not move.
    • The visible address is correct but the marker lands away from the building: investigate address parsing and geocoding before making repeated profile edits. Confirm the canonical address and whether unit information has been represented consistently.
    • The profile is suspended after the edit: stop treating the problem as a normal ranking fluctuation. Verify that the new premises, public information, and business documents support the operating model. In some reinstatement situations, hiding the address can send the functional anchor back toward the old location, so consider that geographic consequence before choosing a remedy.
    • The website and citations still show the previous address: finish the entity-data migration. Until the wider web agrees, you cannot cleanly separate a Google Business Profile issue from inconsistent location information.

    When starting over deserves serious consideration

    Editing the established profile is normally attractive because it preserves reviews and history. A fresh profile becomes a serious option mainly when a visible business has moved a long distance, such as across state lines, and years of directions requests or other location-linked behavior remain associated with the old market. Even then, this is a tradeoff rather than an automatic best practice.

    Compare the two losses explicitly. Keeping the profile may preserve valuable reviews while carrying conflicting historical geography. Starting fresh may create a cleaner location foundation while giving up those reviews and the profile’s accumulated history. A cross-state move creates the strongest case for weighing a fresh start, particularly when an edited profile could be suspended and an address-hiding step would pull the anchor back toward the former location.

    Before you touch the dashboard, produce three things: a written address history, a baseline ranking grid, and a completed list of first-party and third-party location updates. Then make the one profile change supported by that evidence. An address migration is much easier to recover when you can show exactly where the business was anchored, what changed, and where visibility moved afterward.

    References
  • How to Make Your Business Verifiable in AI Search

    How to Make Your Business Verifiable in AI Search

    Your business may be established, trusted, and easy for customers to find, yet still disappear when someone asks an AI assistant for a recommendation. The problem is often not a lack of authority. It is that the system cannot retrieve enough consistent evidence to confirm who you are, what you do, and whether your website represents the same entity described elsewhere.

    You can fix that gap. Start by treating AI visibility as an entity-verification problem, then make the verified facts technically retrievable, reinforce them across credible profiles, and measure the answers your target customers actually receive.

    Key takeaways

    • Audit identity before tracking mentions. An AI system cannot reliably recommend a business it cannot resolve into one clear entity.
    • Give your business one canonical, current identity across its primary domain, important profiles, directories, and public records.
    • Put essential facts in readable HTML. A polished client-side application can still look empty to a retrieval process that does not execute its JavaScript.
    • Use Organization or an appropriate LocalBusiness subtype in JSON-LD to express the same facts people can see on the page. Schema should clarify your content, not contradict or replace it.
    • Track visibility, prominence, sentiment, and citations across a controlled set of prompts. Record factual errors separately so identity problems do not hide inside a visibility score.
    • Treat AI-assisted conversions as a multi-touch measurement problem. Referral traffic alone will not show every customer who researched you through an AI assistant.

    Diagnose verifiability before chasing AI mentions

    A mention is the end of a chain, not the beginning. Before an answer engine can include your business, its retrieval process has to find information about you, extract usable facts, connect those facts to the same entity, and decide that the evidence is suitable for the question.

    This creates four separate layers to audit. A failure at an earlier layer usually cannot be repaired by optimizing a later one.

    LayerQuestion to testTypical failure signalNext move
    IdentityIs there one unambiguous business entity?Several domains, names, addresses, or descriptions compete with one another.Choose canonical facts and reconcile conflicting properties.
    RetrievabilityCan a simple fetch extract the important facts?The source response contains an application shell, images, or scripts but little meaningful text.Server-render or pre-render critical content and navigation.
    CorroborationDo credible external records support the same identity?Directories, registries, social profiles, and partner pages describe different businesses.Correct the records you control and document unresolved conflicts.
    VisibilityDoes the business appear for relevant prompts?Competitors are named while your business is omitted, mischaracterized, or supported by weak citations.Analyze prompt fit, cited pages, missing evidence, and competing entities.

    The size of this problem should not be treated as a universal market statistic. Still, one regional audit shows how severe the mechanism can become. Across 71 verified businesses on Prince Edward Island, a custom points-based framework classified the average business as leaking 84% of its identity, while 17% had no AI-retrievable digital presence. The sample was geographically limited, but its failure patterns are practical audit targets: hidden leadership details, unreadable JavaScript sites, dead domains, conflicting domains, and businesses represented only by third parties.

    Run your first audit from ground truth, not from an AI answer. Create a record containing your public business name, any legal-versus-trading-name relationship, primary category, products or services, locations and service areas, current domain, public contact details, named leadership, official profiles, and any public credentials you actively claim. If your own team cannot agree on a field, an external system has little chance of resolving it correctly.

    1. Write down the canonical value for every identity field. Do not copy values from a directory until someone responsible for the business has confirmed them.
    2. Locate the best supporting page on your own domain for each value. Mark facts that exist only in an image, PDF, script-rendered interface, or old announcement.
    3. Fetch the homepage and essential entity pages without relying on a normal browser session. Confirm that their main text and links exist in the returned HTML.
    4. Compare the canonical record with major profiles, directories, registries, social accounts, partner pages, and alternate domains.
    5. Record conflicts as specific repairs: old phone number, former leader, obsolete service, duplicate domain, missing location, or ambiguous business name.
    6. Only after those checks, capture a baseline of AI answers for the prompts that matter commercially.

    Build a canonical identity that machines can resolve

    Matching website, listing, map, contact, and service profile tiles connect to one model business while mismatched fragments remain outside.

    A canonical source of truth is not merely a canonical URL tag. It is a coherent identity system in which your pages, structured data, domains, and external profiles point toward the same real-world organization.

    Put the verification summary near the front door

    Do not force a retrieval system to reconstruct your business from a slogan, a footer, and an About page several clicks away. Your homepage should state the essential identity in ordinary text and link directly to pages that substantiate it.

    • Use the exact public name customers should recognize. If the trading name differs materially from the legal name, explain the relationship where it is relevant.
    • Write one literal sentence that identifies the business category, audience, core offer, and location or service area.
    • Show a current address or service area and a working contact route. Do not publish a location you cannot consistently support elsewhere.
    • Name the people responsible for the business when leadership is public and relevant to trust. Link to a proper team or leadership page with roles and biographies.
    • Link to current About, Contact, location, service, policy, and other evidence pages using descriptive anchor text.
    • Remove claims that are obsolete, unverifiable, or contradicted by newer pages.

    A useful drafting pattern is: “[Business name] is a [business category] serving [audience] in [location or service area], led by [person and role], and offering [primary products or services].” You do not have to publish that wording verbatim. The test is whether a reader can complete every bracket from a short passage of visible text.

    Leadership information deserves special attention. In the regional audit, 22 of the 71 businesses had identifiable leadership somewhere on their websites, but important details often sat on secondary Team, History, or Family pages that a routine homepage pass did not retrieve. Keep the deeper biography where it belongs, but surface names, roles, and a direct link from a prominent entity page.

    Resolve competing and obsolete domains

    Multiple domains are not automatically wrong. They become an identity problem when they present the same entity as separate, competing businesses or when external profiles alternate between them without explaining the relationship.

    • Select the live domain that will serve as the primary home of the entity.
    • Redirect obsolete variants to the closest relevant page on the primary domain when you own them and consolidation matches the real business structure.
    • Update important directory, registry, social, partner, and campaign links so they no longer reinforce an outdated domain.
    • Keep ownership of legacy domains that still carry brand value, links, or customer traffic. Letting one lapse can be difficult or expensive to reverse.
    • Use canonical URL declarations to consolidate duplicate pages, but do not mistake page canonicalization for entity reconciliation.
    • If two domains represent genuinely separate brands, divisions, or legal entities, explain those relationships instead of collapsing them for convenience.

    Dead domains are especially damaging because they preserve an old identity signal without providing current evidence. A real business can remain active while its former domain is parked, offered for sale, or empty. That leaves third-party platforms to become the most retrievable account of the brand.

    Make every important fact retrievable

    A search orb retrieves service, location, credential, policy, and contact symbols from the open rooms of a structured website.

    A site can work perfectly in a modern browser and still return almost no usable content to a direct fetch. The common failure is client-side rendering with no static fallback: the server returns a thin application shell, and JavaScript creates the meaningful page only after a browser runs it.

    Do not assume that every AI product, crawler, citation service, or retrieval agent will execute your application exactly as a customer browser does. Inspect the response that arrives before JavaScript runs.

    1. Request the public URL in a source or fetch inspection tool. Confirm that it returns a successful response and meaningful text, not only script references and empty containers.
    2. Look for the business name, description, contact details, primary headings, navigation links, and links to About, Team, Contact, and location pages in the returned HTML.
    3. Repeat the check on the pages that support identity claims. A readable homepage does not help if the leadership or location page still depends entirely on client-side execution.
    4. If essential content is missing, use server-side rendering, static generation, or reliable pre-rendering for public pages. The exact implementation can vary, but the initial response must carry the facts.
    5. Retest after deployment. A visual browser check alone does not confirm that the fallback works.

    Also avoid making an image, canvas, video, or downloadable PDF the only carrier of an important fact. Those formats can support the page, but the business name, offer, location, people, and contact routes should have clear HTML equivalents.

    Use JSON-LD as an identity map, not a magic ranking switch

    Structured data gives machines an explicit representation of facts that might otherwise have to be inferred from layout and prose. For a business, that normally begins with Organization or the most accurate LocalBusiness subtype. The node should describe the real entity shown on the page, not a more attractive category you hope to rank for.

    • Assign the organization a stable @id and reuse that identifier wherever pages refer to the same entity.
    • Align the name, URL, logo, telephone, address, and other material fields with visible content and your canonical identity record.
    • Connect official profiles through appropriate properties, and include only profiles that are current and actually represent the entity.
    • Represent locations and people as distinct entities when that structure is useful, then express their relationship to the organization accurately.
    • Keep multi-location data specific to each location page. Do not mark every branch with the headquarters address or merge separate phone numbers into one ambiguous record.
    • Make the JSON-LD available in the delivered page source or through rendering that the intended crawler can consistently access.
    • Validate syntax after every material change and inspect the values, not just the absence of parser errors.

    JSON-LD cannot rescue a dead domain, settle contradictory profiles, or prove a claim simply because you marked it up. It reduces ambiguity when it agrees with readable content and corroborating evidence. If the markup calls the company one thing while the page and public records call it another, you have formatted the conflict rather than resolved it.

    Reinforce the same identity beyond your website

    Your website is the best place to state who you are, but self-published claims are only one part of verification. Credible external records help an AI system connect the business on your domain with the entity found in local listings, public registries, professional associations, partner pages, social profiles, and relevant coverage.

    Consistency does not mean forcing identical marketing copy into every profile. It means keeping identity-bearing fields compatible: name, URL, location, phone number, category, leadership, and the plain facts of the offer. A short directory description and a detailed About page can differ in tone while still describing the same entity.

    1. Prioritize properties that customers and retrieval systems are already likely to encounter: major business profiles, applicable public registries, industry directories, official social accounts, and important partner listings.
    2. Claim and verify profiles where the platform permits it. Remove duplicate entries or request corrections rather than allowing several partial identities to persist.
    3. Replace obsolete domains, phone numbers, addresses, leaders, and service descriptions.
    4. Link external profiles back to the best canonical page, not automatically to the homepage when a location or division page is the accurate destination.
    5. Document records you cannot edit. A conflict log should include the URL, incorrect field, requested correction, request date, and current status.
    6. Recheck important records whenever the business changes its name, ownership presentation, leadership, domain, location, or primary offer.

    When your own domain is incomplete or unreadable, the most machine-friendly third party can become the practical source of truth. That can have a direct cost. In the Prince Edward Island audit, third-party booking resellers appeared alongside or above some hotel and golf-property booking pages, creating an identity gap with commission consequences. If an intermediary is easier to verify than the property itself, the intermediary has a better chance of shaping both the answer and the transaction path.

    Do not manufacture corroboration through fake profiles, fabricated reviews, or low-quality directory submissions. The goal is not to create the largest number of mentions. It is to make legitimate evidence easier to reconcile.

    Measure the answer, the evidence, and the business effect

    Once the identity foundation is sound, you can answer the practical question: does the business appear when a prospective customer asks an AI system for help?

    Use a controlled prompt set based on real decisions, not one branded vanity query. Include category discovery, location-qualified needs, use cases, constraints, and comparison questions that match the work your business wants. A useful set might cover prompts shaped like “Who provides [service] in [place]?”, “Which [category] is suitable for [use case]?”, and “What should I compare when choosing a [provider type]?”

    For each prompt and engine, record visibility, position, sentiment, and citations. Add factual accuracy as a separate review field because a prominent mention with the wrong location, service, or ownership is not a successful result.

    MeasureWhat to recordWhat it tells you to do
    VisibilityWhether the business is named for the prompt.Investigate prompt relevance, entity resolution, and missing supporting content.
    PositionWhether it is a leading recommendation, a later option, or a passing mention.Compare the evidence and cited coverage attached to more prominent competitors.
    SentimentWhether the description is positive, neutral, negative, or cautionary, plus the exact reason.Correct factual problems and strengthen weak evidence; do not reduce a nuanced answer to a color alone.
    CitationsEvery URL used to support the answer, classified as owned, third-party, or competitor-controlled.Improve influential owned pages and address inaccurate external records.
    AccuracyWrong names, services, people, locations, availability, or relationships.Trace each error to conflicting, stale, or absent evidence and log the repair.

    Keep the testing conditions interpretable. Record the engine, prompt wording, date, language and location context, relevant account or personalization state, full answer, and cited URLs. Generated responses can vary, so one answer is an observation, not a stable ranking. Repeat prompts under comparable conditions and look for patterns over time.

    Do not collapse the results into one unexplained visibility score. A composite number can rise while citations shift from your domain to an intermediary, sentiment worsens, or a factual error becomes more prominent. Keep the underlying observations available so someone can see what changed and choose the right repair.

    Connect visibility to outcomes without overstating attribution

    AI-assisted discovery is difficult to attribute because a customer may research in an assistant, return through search or a direct visit, and convert in a later session. Among 494 agency professionals surveyed for a vendor-produced 2026 benchmark, 48% said they could not reliably track AI discovery and 47% could not attribute conversions across multi-session AI-assisted journeys. Those percentages describe that survey population, not every business, but the measurement limitation is real.

    • Add an AI-assistant option to appropriate “How did you hear about us?” forms, with an open field for the customer to name the tool or describe the query.
    • Preserve direct referral data when it exists, but do not treat it as the complete AI-influenced audience.
    • Annotate major identity, content, domain, and profile changes so visibility movements can be compared with known interventions.
    • Compare AI visibility with qualified leads, branded demand, direct visits, and conversions as supporting signals. A simultaneous change is not proof that one caused the other.
    • Review citation paths for commercial leakage. If an AI answer repeatedly sends people through a reseller or aggregator, measure the cost and decide whether your direct page needs stronger verification, clearer content, or a better transaction path.

    Start with one high-intent customer scenario and the page that should prove your business belongs in its answer. Make the identity explicit, make the evidence retrievable, reconcile the strongest external records, and then rerun the same prompt set. That sequence turns “Do we show up?” from a guess into a repairable business system.

    References

  • How to Prioritize SEO Technical Debt Without Wasting Sprints

    How to Prioritize SEO Technical Debt Without Wasting Sprints

    Your crawler has finished, and now you have 10,001 flags competing for attention. The highest counts look urgent, the tool has assigned severity labels, and someone wants to know how quickly the team can make the report green.

    Do not turn that export into your roadmap. Your job is to find the small set of problems that obstruct valuable pages, repeat through important templates, or become more expensive if they survive the next release. Everything else should be scheduled, monitored, or deliberately left alone.

    Start with page value, not issue volume

    Technical SEO debt is the gap between the site you have and the technical foundation needed to support organic discovery, indexation, performance, and growth. It can sit in crawling, indexation, architecture, templates, performance, migrations, structured data, or reporting. That breadth is why a raw list of errors is such a poor prioritization system.

    A warning matters only in context. A canonical conflict on a revenue-generating template is a different problem from the same conflict on an old tag page with no impressions. A missing meta description on an important category page may deserve attention; the same omission across zero-impression utility URLs may have no useful upside. Issue type alone cannot tell you what to do.

    Segment the site before scoring the debt. At minimum, separate these groups:

    • Revenue and conversion pages: Product, service, category, lead-generation, signup, or other pages tied to a valuable action.
    • Organic discovery pages: Editorial, educational, comparison, glossary, location, and other pages intended to attract demand.
    • Supporting pages: Content that strengthens navigation, topical relationships, trust, or the user journey without being the final conversion destination.
    • Utility pages: Account, filter, sort, search, print, login, and operational URLs that may not belong in search results.
    • Legacy and generated URLs: Redirected paths, parameters, faceted combinations, outdated structures, and other URLs created by historical or automated behavior.

    For each segment, record its intended indexation state, business purpose, organic role, template, and owner. This prevents a common audit failure: treating every crawlable URL as though it should rank. An excluded utility URL may be working exactly as intended, while one excluded product template could represent a serious access problem.

    Then validate whether each finding is isolated or systemic. Sample representative URLs and inspect the underlying template or rule. A thousand warnings caused by one template defect are one scalable problem, not a thousand separate tasks. Conversely, one incorrect robots.txt rule can be more urgent than thousands of harmless metadata warnings.

    Put every finding into one of four action buckets

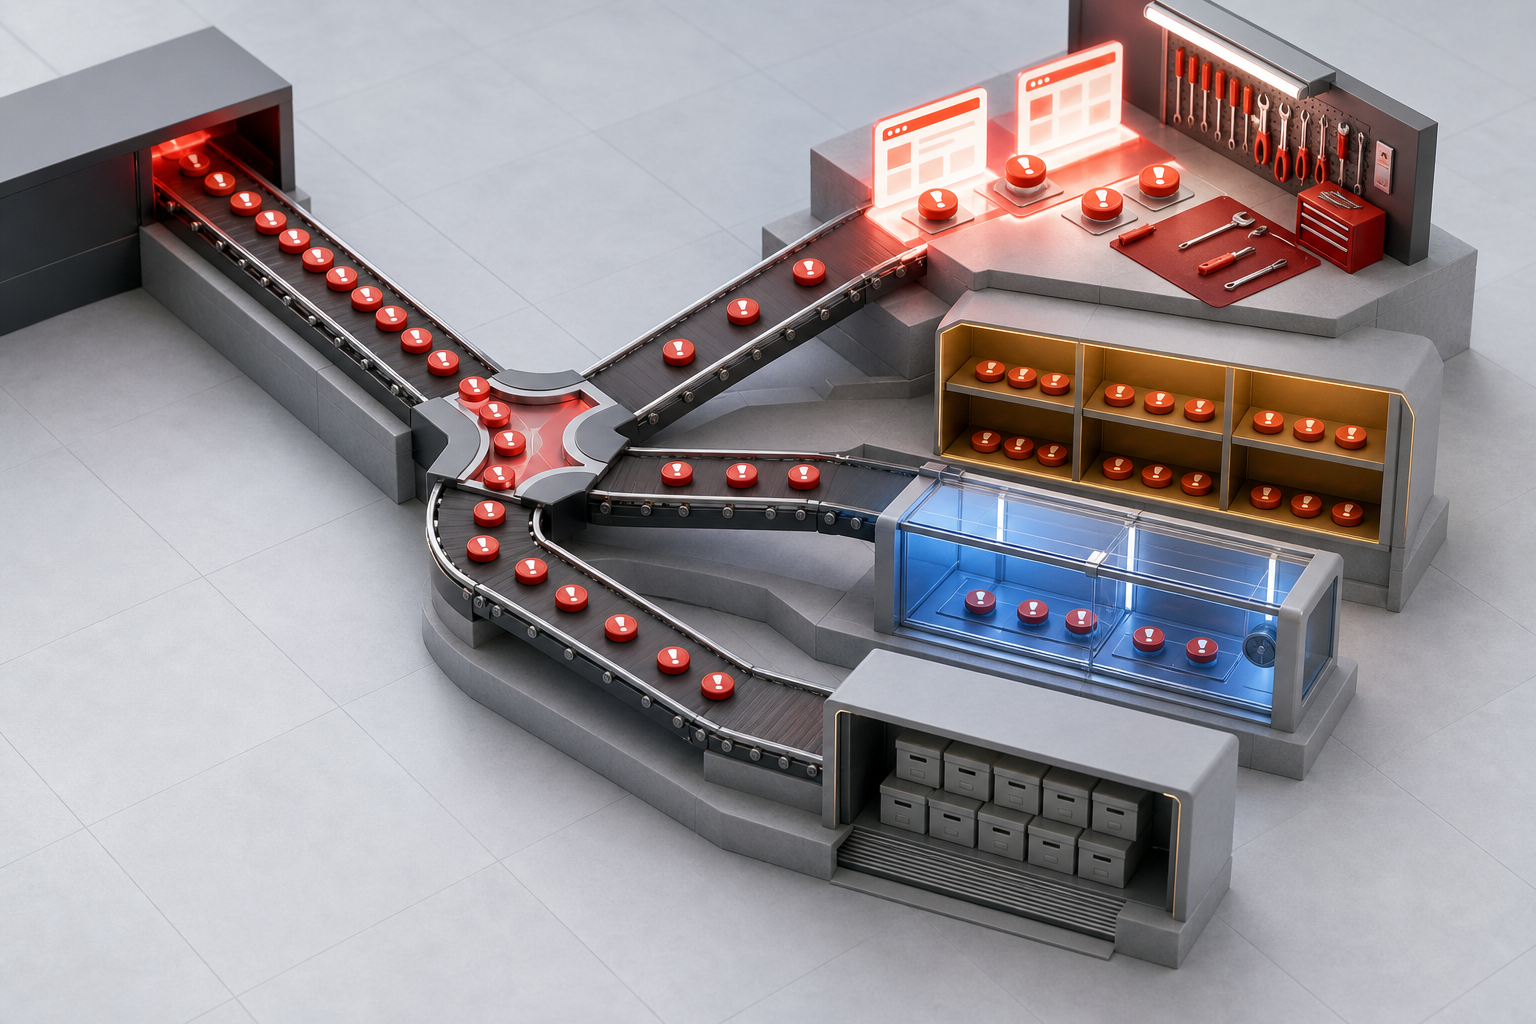
    A miniature audit station sorts small issue tokens into a repair bench, a future-work shelf, an observation chamber, and an archive compartment.

    Every finding should end with a decision, not merely a severity label. Use four buckets: fix now, fix soon, monitor, and ignore for now. The boundaries depend on affected pages and outcomes, not on how alarming the crawler makes the warning look.

    ActionUse it whenTypical examples
    Fix nowThe issue blocks or materially weakens access, discovery, ranking, conversion, or a business-critical path.Noindex directives on priority pages; robots.txt blocks on important sections; key pages canonicalized elsewhere; broken migration redirects; broken internal links to revenue pages; slow core templates; competing duplicate page sets.
    Fix soonThe issue creates meaningful drag, affects a valuable segment, or will constrain growth and maintenance if allowed to spread.Buried priority pages; outdated XML sitemap entries; faceted crawl waste; missing schema on important templates; thin indexable pages at scale; inconsistent heading templates.
    MonitorThe possible impact is limited or unclear, and current performance does not justify immediate work.Minor performance misses on low-traffic pages; a few redirect chains; duplicate titles on low-value URLs; non-critical crawl anomalies; JavaScript concerns involving non-indexable elements.
    Ignore for nowThe imperfection does not affect search access, valuable journeys, current performance, or future scalability.Missing descriptions on zero-impression pages; old 404s with no traffic or links; duplicate headings on utility pages; low-value HTML validation warnings; flags on intentionally blocked or noindexed URLs.

    The phrase for now matters. Ignoring an issue is a documented decision based on current scope and impact, not a claim that the issue can never matter. A warning on a dormant template may move into the roadmap if that template becomes part of a launch, migration, or expansion.

    Use this decision sequence when a finding is disputed:

    1. Confirm intent. Is the directive, status code, canonical, internal-link pattern, or generated URL behavior deliberate?
    2. Identify the affected segment. Does the issue touch pages that should be discovered, indexed, ranked, or used to complete a valuable action?
    3. Describe the mechanism. State how the issue could affect crawling, indexation, internal authority flow, page understanding, user experience, or conversion. If you cannot describe a credible mechanism, do not assign an urgent priority.
    4. Check observable impact. Review indexation, impressions, organic traffic, conversions, crawl behavior, and affected search journeys where those measurements are available.
    5. Find the root cause. Determine whether the defect lives in one URL, a template, navigation, platform configuration, rendering, or a migration rule.
    6. Assess delay risk. Ask whether waiting leaves performance stable or allows the problem to spread, compound, or become embedded in another release.

    This sequence also exposes false emergencies. A crawler may flag blocked pages because it cannot inspect them fully, but those warnings are irrelevant if the pages are intentionally excluded and have no organic role. The target is not a perfect crawl score or zero excluded URLs. It is a site where important pages can be accessed, understood, prioritized, and used.

    Score impact, scale, risk, and effort without fake precision

    Once the action bucket is clear, score each finding across five factors: SEO impact, business impact, scale, risk, and effort. A simple high, medium, or low assessment is often more defensible than a complicated formula. The score should make the reasoning visible, not disguise judgment as mathematics.

    FactorQuestions that raise priorityQuestions that lower priority
    SEO impactCan this prevent crawling or indexation, send contradictory canonical signals, weaken internal discovery, or impair pages already earning visibility?Is the warning limited to intentionally excluded pages, cosmetic metadata, or behavior with no plausible search mechanism?
    Business impactDoes it affect pages tied to sales, leads, demos, signups, qualified visits, or another defined business outcome?Are the affected URLs unused, obsolete, or disconnected from valuable journeys?
    ScaleDoes one rule or template affect an important page set? Will the number of affected URLs grow automatically?Is it an isolated edge case with no sign of repetition?
    RiskCould waiting cause traffic loss, migration failure, index growth, cannibalization, or a harder future repair?Is the behavior stable, contained, reversible, and unlikely to spread?
    EffortCan a contained template or configuration change solve the root cause with manageable QA?Does the repair require broad platform work, content rewrites, multiple teams, or risky URL changes for little expected benefit?

    Effort should shape sequencing, but it should not erase impact. A difficult crawl or indexation blocker does not become unimportant because it needs engineering time. Likewise, an easy metadata cleanup does not become strategic merely because the team can finish it quickly. Keep quick wins on the roadmap only when their expected benefit exceeds the opportunity cost.

    Translate the result into priority language that product and engineering teams already understand:

    • P0: Business-critical pages cannot be crawled or indexed as intended.
    • P1: A high-impact template, architecture, performance, migration, or duplication issue is limiting visibility, growth, or conversion.
    • P2: The work is useful and justified but not urgent; schedule it behind access blockers and high-value systemic fixes.
    • P3: Monitor the condition, document why it is not being fixed, or batch it with related maintenance.

    Write a one-sentence priority case for every P0 and P1 item: This issue affects [page segment and scope], interferes with [search or user mechanism], puts [business outcome] at risk, and can be corrected through [root-cause change and dependencies]. If you cannot fill in those fields, the task probably needs more investigation or a lower priority.

    Structured data needs the same discipline. Missing or invalid schema on an important template can create machine-readable clarity debt and may justify a fix. But schema cleanup should not outrank a robots block, incorrect noindex, or canonical error that prevents the underlying page from being considered at all. Search and AI visibility begin with accessible, indexable, coherent pages; markup cannot compensate for a broken foundation.

    Turn the audit into root-cause tickets and a sequenced roadmap

    A technician repairs one shared website template hub that feeds many connected page modules, with maintenance stations arranged in sequence beside the network.

    An audit finding is not ready for a sprint merely because it has a URL list. Development teams need a bounded change, an intended outcome, and a way to prove the fix worked. Create one ticket for the root cause and keep the affected URLs as evidence.

    Each implementation-ready ticket should contain:

    • Outcome: What should search engines and users be able to do after the change?
    • Affected segment: Which page group, template, directory, or navigation path is involved?
    • Observed and intended behavior: What happens now, and what should happen instead?
    • Scope evidence: Representative URLs, the known pattern, and whether the count is exact or crawl-dependent.
    • Impact case: The search mechanism, business consequence, scale, and delay risk supporting the priority.
    • Root cause: The template, rule, component, content process, or platform behavior that should change.
    • Acceptance criteria: Testable conditions covering directives, status codes, rendered output, links, canonicals, sitemap inclusion, or structured data as relevant.
    • QA and rollback: Representative test cases, expected side effects, monitoring signals, and a safe way to reverse the change.
    • Ownership and dependencies: The engineering, SEO, content, analytics, or product work required to finish the task.

    Bulk changes to canonicals, robots directives, redirects, internal links, and URL generation can remove valuable pages from search or create new crawl paths. Test template changes on representative URLs, preserve the previous configuration, and define rollback conditions before deployment. A large affected count increases the need for QA; it does not prove the expected benefit.

    Sequence the roadmap by dependency. Restore access to important pages first. Then repair high-value templates and architecture. Address scalable crawl, indexation, performance, and structured data debt after the underlying pages are stable. Batch low-impact cleanup with related platform or content work rather than demanding a separate sprint.

    Do not overlook reporting debt. If Google Search Console and analytics data cannot be mapped to useful page groups, the team cannot reliably distinguish a broad commercial problem from noise on low-value URLs. In that case, segment-level measurement may be the enabling task that makes the rest of the prioritization defensible.

    Every monitor or ignore decision needs a review trigger. Reassess when the affected template changes, the issue spreads into a priority segment, indexation or traffic shifts, a migration is planned, or the site begins generating the URLs at greater scale. This turns the backlog into a controlled risk register instead of a graveyard of unresolved warnings.

    Key takeaways

    • Prioritize technical SEO debt by page segment and business purpose, not by warning count.
    • Fix access blockers and defects on valuable, scalable templates before cosmetic cleanup on low-value URLs.
    • Assign every finding to fix now, fix soon, monitor, or ignore for now; do not leave the decision implicit.
    • Score SEO impact, business impact, scale, future risk, and implementation effort, then write the reason for the assigned priority in plain language.
    • Create root-cause tickets with acceptance criteria, QA, rollback conditions, ownership, and monitoring triggers.
    • Measure success through restored access, visibility, useful journeys, conversions, or reduced scalable risk, not a perfect crawl score.

    Take the highest-volume issue in your current audit and re-evaluate it against one valuable page segment. If you cannot connect it to a search mechanism, business outcome, scalable risk, or enabling dependency, move it down. Then give the recovered capacity to the smallest root-cause change that protects the pages your organic strategy actually depends on.

    References

  • Technical SEO Prioritization: What to Fix First and Why

    Technical SEO Prioritization: What to Fix First and Why

    You have a crawl report full of red warnings, a development queue with little room, and stakeholders asking what any of the proposed work will change. Turning every warning into a ticket will fill the backlog. It will not tell you what deserves to be fixed first.

    Technical SEO prioritization is a constrained investment decision. Very few technical activities deserve top priority on every website. Before requesting developer time, you need to establish that the problem exists on your site, affects something valuable, has a plausible path to a business outcome, and can be measured after the change.

    Key takeaways

    • An audit warning is a signal to investigate, not proof that development work is necessary.
    • Prioritize the obstacle and its consequence: which important pages, users, or search bots are affected, what they cannot do, and what that costs the business.
    • Only score an implementation after you have evidence, a causal mechanism, an affected scope, a success metric, and an estimate of effort and risk.
    • Core Web Vitals work, redirect cleanup, and crawl optimization become priorities when they address demonstrated harm. They are usually weak requests when they only improve an already acceptable score or remove harmless warnings.
    • Every development ticket should state the expected outcome, baseline, acceptance criteria, measurement plan, opportunity cost, and condition under which the work should be stopped or reconsidered.

    An audit finding is not automatically a problem

    An audit tool observes technical conditions. It may find redirected internal links, slow test results, duplicate URLs, crawlable parameters, or other departures from its preferred configuration. That is useful evidence, but the tool does not know which page groups produce revenue, which warnings affect real users, what your search performance depends on, or what your developers would have to postpone to clear the alert.

    This is the distinction that keeps a technical backlog under control: a finding describes what exists; a problem explains why that condition is harmful here. If the only justification is that an audit alert needs to be cleared or a best-practice box needs to be checked, the request is not ready for implementation.

    Turn each material finding into a short diagnostic brief before you prioritize it:

    1. Observed condition: Describe what is happening on production URLs, not just the name of the audit rule.
    2. Affected scope: Identify the page group, template, user journey, or crawl path involved. Separate valuable URLs from incidental ones.
    3. Failure mechanism: Explain what the condition prevents or makes harder. A bot may be unable to reach a destination, a user may struggle to load a page, or unwanted URLs may consume crawling activity.
    4. Likely consequence: Connect the failure to qualified organic traffic, conversion, revenue, churn, usability, or another outcome the business already recognizes.
    5. Baseline evidence: Record the current technical and business measurements. Without a baseline, a successful deployment can still leave you unable to demonstrate success.
    6. Counterevidence: Note what would weaken the case. If important content is already being crawled reliably, for example, a broad crawl-budget project may not solve a current problem.

    The causal sentence should be plain: Because this condition affects this valuable scope, users or bots cannot complete this behavior, which puts this measurable outcome at risk. If you cannot complete that sentence without relying entirely on words such as could or might, do not disguise uncertainty with a high audit severity. Create a smaller validation task and collect the missing evidence first.

    Compare two redirect requests. Internal links return 301 responses merely restates a crawler result. Links on an important template enter a redirect loop, so neither users nor bots can reach the intended destination describes an operational problem. The second statement provides a mechanism, scope, consequence, and testable result. The first does not.

    The same discipline applies to performance. Improve the page-speed score treats the score as the outcome. Bring a failing, revenue-producing page group into the acceptable range and test whether its conversion rate improves distinguishes the diagnostic metric from the business result.

    Use evidence, impact, reach, cost, and risk to rank the work

    An isometric system moves a broken webpage tile through checkpoints represented by a magnifying lens, connected network, tools, and shield before it reaches a workbench.

    Do not begin with a weighted spreadsheet. Scoring weakly defined tickets creates false precision. First pass each request through a decision gate; then use a consistent set of dimensions to compare the requests that remain. This matters because SEO time and developer capacity are both limited, and every accepted ticket displaces another piece of work.

    1. Is the condition real? Confirm it on representative production URLs. If the finding is stale, confined to a test environment, or caused by the crawler configuration, close it before estimating a fix.
    2. Does it affect valuable scope? Segment affected URLs by template, purpose, organic opportunity, and business role. A large count of unimportant URLs should not automatically outrank a smaller set of critical pages.
    3. Is the mechanism credible? State how the condition interferes with crawling, loading, navigation, or another necessary behavior. A correlation without a mechanism deserves investigation, not an expensive rollout.
    4. Can you name the outcome and measure it? Choose a primary business or user metric and a supporting technical metric. If the technical score improves while the meaningful outcome does not, report that distinction.
    5. Is the intervention proportionate? Estimate engineering, quality assurance, content, analytics, and release effort. Include regression risk and the availability of a safe rollback.
    6. What loses if this wins? Compare the request with the work it would displace. Opportunity cost belongs in the priority decision, not in a footnote added after approval.
    DimensionQuestion to answerEvidence that strengthens priority
    ImpactWhat meaningful outcome changes if the fix works?A direct path to revenue, qualified traffic, conversion, retention, usability, or access to important content
    ConfidenceHow certain are you that this condition causes the observed harm?Reproducible behavior, consistent measurements, and a mechanism that fits the evidence
    Reach and valueWhich pages, users, and journeys are affected?A clearly defined page group with material organic or business value
    EffortWhat must be designed, built, tested, deployed, and monitored?A bounded change with known dependencies and realistic acceptance criteria
    RiskWhat can regress, and how will you recover?A contained release, observable guardrails, and a practical rollback
    MeasurabilityHow will you distinguish a successful fix from a successful deployment?A recorded baseline, a technical indicator, a primary outcome, and a defined evaluation condition

    Put every request into one of three queues

    • Commit: The problem is demonstrated, the affected scope matters, the expected outcome is measurable, and the cost and risk are justified. Prepare the implementation ticket.
    • Validate: The suspected harm is plausible, but evidence, scope, or causality is incomplete. Approve a diagnostic task rather than the full fix.
    • Park: The request is based on a warning, cosmetic cleanliness, or incremental improvement with no material expected outcome. Record the reason and a condition that would reactivate it.

    This approach avoids two common distortions. First, URL count is not the same as business reach: one critical landing-page template can matter more than a much larger archive with no meaningful search demand. Second, a sitewide warning is not automatically severe. If users and bots can complete the required behavior and no outcome is being harmed, broad reach merely describes how widely a harmless condition appears.

    You also do not need to force every decision into a numerical score. A critical access failure can outrank other work even when its affected URL count is small. A low-risk housekeeping change can remain parked even when it is easy. Use the dimensions to expose the tradeoff, not to let arithmetic make the decision for you.

    Know when three familiar technical fixes are worth doing

    Almost any technical recommendation can be valuable in the right context. The mistake is treating the recommendation itself as the context. Core Web Vitals, redirects, and crawl-budget work show how the same task can be urgent on one site and unproductive on another.

    Core Web Vitals: fix failure before optimizing success

    Core Web Vitals work has a sensible stopping point. If an important page group is outside the applicable good range, users struggle to load it, or poor performance damages usability, there is a concrete problem to solve. Once those pages are in the good range, however, shaving a few more milliseconds from Largest Contentful Paint is likely to deliver diminishing returns.

    • Commit when valuable pages genuinely miss the target and the loading experience interferes with use of the page.
    • Validate when a test score looks poor but you have not yet established which production pages and users are affected.
    • Park when the page group is already in the good range and the proposed outcome is merely a greener score.
    • Measure the affected performance metric alongside the relevant user or business result. On an ecommerce page group, that may include conversion rate and revenue rather than load time alone.

    This does not make speed unimportant. It keeps the goal honest. A development team should know whether it is repairing a poor experience or pursuing a small technical improvement whose commercial effect is unknown.

    Redirects: treat broken paths as defects, not every 301

    A redirect is not inherently a defect. Its job is to send a request to a different destination. The prioritization question is whether that behavior prevents efficient access to the correct page.

    Redirect work becomes material when you find loops, irrelevant destinations, widespread paths that impair crawling, or chains extending beyond five hops. Those conditions can stop or hinder users and bots before they reach the intended content. A crawl report that merely contains ordinary 301 responses does not establish the same harm.

    • Commit when a loop blocks the destination, a long chain creates a meaningful access problem, or redirects repeatedly send requests to irrelevant pages.
    • Validate when the report contains many redirects but you do not know whether they form harmful chains or affect important crawl paths.
    • Park when links resolve reliably through a single appropriate redirect and no crawling or user problem is evident.
    • Handle opportunistically when you are already editing the relevant CMS content and can update an internal link to its final destination at negligible additional cost.

    The opportunistic edit and the priority project are different decisions. It is reasonable to remove avoidable hops while touching a page. It is harder to justify displacing higher-impact work solely to make a crawl report free of redirect notices.

    Crawl budget: require evidence that crawling is constrained

    Crawl optimization depends heavily on scale and site behavior. Large enterprise sites are more likely to need crawl-path work, while crawl budget is usually not a material issue for smaller sites. Site size alone is not the diagnosis, though. The useful evidence is whether bots are spending time in spider traps or unwanted URL spaces while important content is difficult to reach.

    • Commit when spider traps create uncontrolled crawling, unwanted pages consume substantial attention, or important content is not reliably crawlable.
    • Validate when the concern is based on site size or URL count but Google Search Console and your crawl evidence have not yet shown an access problem.
    • Park when important content is already crawlable and no unwanted crawl pattern is interfering with it.
    • Reactivate the work if a new template, parameter space, or navigation pattern creates a trap or makes valuable sections harder for bots to reach.

    Do not ask developers to optimize an abstract budget. Name the wasteful path, the valuable path it competes with, the evidence of interference, and the measurement that will show the intervention worked.

    Turn the winning priority into a measurable development ticket

    A developer repairs a selected broken component and restores an illuminated path through a modular website model.

    A technically correct request can still lose the sprint-planning conversation if it does not explain its value. Developers need enough detail to estimate and test the change. Decision-makers need to understand why the work is financially or operationally preferable to everything it would displace.

    A decision-ready ticket should contain the following:

    1. Problem statement: Describe the observed production behavior and why it is harmful. Do not paste the audit recommendation in place of a diagnosis.
    2. Affected scope: Name the templates, page groups, journeys, and audiences involved. Include unaffected scope when that boundary helps contain the implementation.
    3. Evidence: Attach reproducible examples and the relevant crawl, Google Search Console, performance, analytics, or business measurements.
    4. Expected outcome: State what should improve for users, search bots, or the business. Revenue, qualified traffic, conversion, and churn are stronger outcomes than clearing an alert.
    5. Proposed intervention: Define the intended behavior while leaving room for engineering to choose a safe implementation where appropriate.
    6. Acceptance criteria: Specify what must be true on the affected URLs after release. Include technical checks and any guardrail that must not regress.
    7. Measurement plan: Record the baseline, primary outcome, supporting technical metric, comparison method, and the condition under which you will evaluate the result.
    8. Effort, dependencies, and risk: Identify other teams, release constraints, quality-assurance needs, possible regressions, and rollback requirements.
    9. Opportunity cost: Name the competing work likely to be delayed. This forces an explicit choice instead of treating developer capacity as free.
    10. Reactivation or stop condition: State what new evidence would revive a parked request, invalidate the proposed fix, or end further optimization.

    Model the business case without turning a scenario into a promise

    Page speed illustrates the difference between a metric and a case for investment. Reducing load time is an implementation objective. The business case may be that a faster ecommerce experience could improve conversion on the affected page group. To test that case, record its current organic traffic, conversion rate, and annual revenue, then model what a plausible change in conversion would mean while making the assumptions visible.

    Keep a scenario labeled as a scenario. It is not a forecast merely because it appears in a spreadsheet. The ticket should separate what you know now, what you expect the intervention to change, and what you will measure afterward. That prevents a successful technical release from being reported as proven commercial growth before the business metric has moved.

    The same separation works for non-revenue outcomes. A crawl fix can be technically successful because important destinations become reachable, while qualified traffic remains unchanged. A redirect repair can remove a loop without affecting conversion. Record both results. The technical result tells you whether the implementation worked; the business result tells you whether the original prioritization hypothesis was valuable.

    Close the loop after release

    • Confirm that the acceptance criteria hold on the intended production scope, not only on a test URL.
    • Check guardrails for regressions before attributing any broader benefit to the change.
    • Compare the supporting technical metric with its baseline.
    • Evaluate the primary user or business outcome separately and preserve uncertainty where other changes could have contributed.
    • Record whether the hypothesis was supported, contradicted, or remains unresolved. Use that result to improve confidence estimates for similar backlog items.
    • Stop incremental work when the original harm is resolved and the next proposed improvement lacks a measurable expected return.

    Now open your technical backlog and take its highest-ranked request. Rewrite it in one sentence: We should make this change because this evidence shows that the current condition affects this valuable scope, interferes with this necessary behavior, and puts this outcome at risk; success will be measured this way. If you cannot fill every part with evidence, move the request to validation or park it with a reactivation trigger. That decision is useful technical SEO work too.

    References

  • A Practical Framework for Auditing Local AI Visibility

    A Practical Framework for Auditing Local AI Visibility

    A strong Google Maps presence does not reveal whether an AI assistant will recommend a local business, describe it accurately, or favor a competitor. A local generative engine optimization (GEO) audit measures those outcomes directly.

    The goal is to establish a controlled baseline before changing content, citations, reviews, or technical settings. That baseline turns an uncertain visibility problem into a set of errors and opportunities that can be tracked.

    Why local AI visibility needs its own benchmark

    Traditional local rankings and AI recommendations are related, but they are not interchangeable. Search Engine Land cites SOCi’s 2026 Local Visibility Index, which analyzed nearly 350,000 business locations. ChatGPT reportedly recommended 1.2% of those locations, compared with a 35.9% appearance rate in Google’s local three-pack. The reported recommendation rates were 11% for Gemini and 7.4% for Perplexity.

    The source also reports that business information was about 68% accurate on ChatGPT and Perplexity, while Gemini reached 100% accuracy in that analysis and relied entirely on Google Maps data. These findings illustrate why map rankings alone cannot serve as an AI visibility scorecard: different systems can select different businesses, consult different sources, and reproduce business facts with different levels of accuracy.

    Key takeaways

    • Test discovery, comparison, trust, and logistics questions across the AI platforms customers may use.
    • Record whether the business appears, where it appears, how it is framed, whether its details are correct, and which sources support the answer.
    • Separate visibility failures from factual errors and weak competitive positioning.
    • Resolve crawl access and business-data inconsistencies before investing heavily in new local content.
    • Repeat the same test set over time so changes can be compared against a stable baseline.

    Build a test that produces comparable evidence

    Begin with a spreadsheet and a fixed set of prompts. The prompt set should represent four kinds of customer questions: discovery queries such as the best service in a city, comparisons between the brand and a competitor, trust questions about reviews or reliability, and logistics questions covering hours, address, parking, or phone number.

    Run the same questions in the relevant interfaces, which may include ChatGPT, Perplexity, Gemini, and Google AI Overviews. For every response, log the prompt, platform, date, test location, and session state. Search Engine Land recommends comparing logged-in and clean logged-out sessions to help identify personalization noise. The city or ZIP code must also remain explicit because local context can change the answer.

    Each result should capture five observations: whether the brand was mentioned, its order in the answer, the positive, neutral, or negative framing, the accuracy of operational facts, and the cited sources. Competitors should be recorded in the same rows, including their position and supporting sources. This makes the audit useful for both brand diagnosis and competitive analysis.

    Translate results into three types of failure

    An aggregate visibility percentage shows how often the business appears, while an accuracy percentage shows how often its details are correct. Those summary figures are useful, but the underlying problem determines the appropriate response.

    Futuristic web browser and analytics dashboard overlap amid neon data streams, illustrating the convergence of SEO, PPC and AI-driven search marketing.
    Organic visibility, paid media and artificial intelligence merge into one connected search ecosystem, where vivid data streams link a creative website with a powerful analytics dashboard.
    • Invisible: The business is absent from relevant answers. Possible causes identified by the source include crawler restrictions, insufficient citable material, or limited third-party mentions.
    • Inaccurate: The business appears with an obsolete address, incorrect hours, or outdated services. On-site errors and inconsistent name, address, and phone data across directories should be investigated.
    • Misframed: The business is mentioned but placed below competitors or presented as a weaker choice. A limited review profile or weaker authority signals may be contributing factors.

    This classification prevents a common planning mistake. Publishing another city page will not correct blocked access, and adding schema will not by itself overcome weak third-party validation. The audit should connect each observed symptom to the most plausible layer of the problem.

    Prioritize access, trust, and then relevance

    Remediation should follow the dependency chain. First, confirm that relevant crawlers can reach the site by reviewing robots.txt and applicable security or Cloudflare controls. Search Engine Land notes Cloudflare’s announcement that AI crawlers would be blocked by default on sites using its network, making the site’s actual configuration worth checking rather than assuming access.

    Next, align the business name, address, and phone number across the website and external profiles. Validate appropriate structured data, including LocalBusiness, Organization, FAQ, and Service markup where the page content supports it. Then strengthen trust through accurate profiles, reviews, responses to customer questions, and a consistent description of the business across directories, social accounts, and coverage.

    Content becomes the priority after those foundations are sound. Useful local pages should contain genuine city-specific information, concrete service examples, and practical details rather than repeating a template with a different place name.

    Turn the baseline into an operating metric

    Search Engine Land suggests a quarterly audit for most local businesses. Reuse the same core prompts and controls, then compare mention rate, position, factual error rate, citation count, and competitor share of voice with the previous run. Changes in cited sources or answer wording may indicate model drift and should be documented rather than treated as isolated anomalies.

    Clicks are not the only relevant outcome because an AI answer may influence a decision without producing a website visit. Branded search activity, calls, and direction requests can provide additional business context. The next audit should then test whether the chosen fixes improved the specific weakness originally observed.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Evidence-Led SEO: From Search Data to Defensible Action

    Evidence-Led SEO: From Search Data to Defensible Action

    Evidence-led SEO connects three questions that are too often handled separately: What is happening in search performance, what might explain it, and why should the business act? Google Search Console data can reveal demand and performance patterns, while official documentation can clarify the search requirements behind a recommendation.

    AI can shorten the journey from raw data to a plausible opportunity, but it does not turn a hypothesis into proof. A reliable strategy keeps observed data, machine-assisted interpretation, documented guidance, and business judgment distinct until they are assembled into a decision.

    Build an evidence chain instead of citing a best practice

    A glowing thread links search signals, hypothesis nodes, documentation pages, and a decision token on a table.

    The two source articles address different weaknesses in SEO decision-making. The Search Console analysis article describes using AI to detect patterns across large query exports. The documentation article explains how official Google references can make technical recommendations easier to defend with developers, clients, and other stakeholders.

    Together, they suggest an evidence chain with four layers. Each layer answers a different question, and none should be asked to do the work of all the others.

    Evidence layerQuestion it answersProper role
    Search Console dataWhat happened in organic search?Establish observed queries, pages, impressions, clicks, rankings, and click-through patterns.
    AI-assisted analysisWhat patterns or hypotheses deserve attention?Classify, cluster, compare, and organize large datasets for human review.
    Official documentationWhat behavior or implementation does Google describe?Support the technical rationale and create a shared external reference point.
    Business contextWhy should this action be prioritized?Connect the recommendation to likely value, risk, effort, and competing priorities.

    This separation matters. Search Console can show that a page receives comparison-oriented impressions, but it cannot by itself establish why the page underperforms. AI can propose explanations, but its output remains analysis rather than observed fact. Documentation may support a technical requirement, but it does not establish the commercial value of fixing a particular page. The final recommendation becomes credible only when the layers are connected without being conflated.

    Turn query data into a prioritized opportunity

    The Search Console source reports a workflow that begins by narrowing query data with regular expressions and then exporting the result for AI-assisted classification. Its examples include question-led searches, comparison terms, emerging terminology, and signals related to pricing, alternatives, implementation, migration, or vendor evaluation.

    The strategic value is not the regular expression itself. Filtering reduces a large dataset to a decision-shaped subset. AI can then group related queries by intent or theme, revealing patterns that would be difficult to recognize one row at a time.

    1. Start with a decision. Define the question before exporting data, such as whether an existing educational page is attracting evaluation-stage searches.
    2. Isolate the relevant observations. Filter for patterns connected to that question, then retain the associated performance fields and landing pages.
    3. Ask AI for structured analysis. Request categories, themes, confidence assessments, and ambiguous cases rather than an unqualified verdict.
    4. Inspect the underlying rows. Check whether the proposed cluster is coherent and whether a few high-volume queries are distorting the interpretation.
    5. Map the pattern to a page-level action. Decide whether the evidence supports updating an existing page, creating a focused asset, improving internal links, or changing the path to the next step.
    6. Define a measurement plan. Record the affected query set, page, intended outcome, and comparison method before implementation.

    This approach also changes how content opportunities are framed. The source notes that clusters of audience questions can inform FAQs, support material, sales resources, and content intended to provide direct answers. It also reports that apparently informational traffic can contain evaluation signals. In those cases, improving the page that already earns visibility may be more appropriate than automatically publishing another article.

    Use AI to accelerate analysis, not manufacture certainty

    An analyst reviews selected data clusters while an abstract AI system sorts a larger field of anonymous signals.

    AI is most useful when the assignment is bounded and auditable. Suitable tasks include generating a proposed Search Console regex, classifying query intent, clustering questions, identifying changes in terminology, and suggesting content formats. The Search Console source describes prompts that request CSV classifications with confidence scores or group queries into definitions, tutorials, comparisons, and expert recommendations.

    Those outputs should be treated as provisional labels. Intent can be mixed, a query can fit several themes, and an apparent trend can reflect the selected date range, page set, or filter. A defensible workflow therefore preserves the original export and maintains a visible connection between each conclusion and the rows supporting it.

    A practical review should test:

    • Whether the filter matches the intended language without excluding obvious variants.
    • Whether classifications are supported by the wording of the queries and their landing pages.
    • Whether the opportunity is broad-based or driven by a small number of observations.
    • Whether the recommended content format fits the likely task behind the query.
    • Whether the proposed action follows from the evidence or merely sounds plausible.

    This distinction is especially important for queries that may produce AI-generated search features. The source describes using informational and comparison patterns as an approximation for searches likely to trigger AI Overviews because Search Console does not provide the filter needed for that analysis. That is a useful hypothesis-building method, but the approximation should not be reported as confirmed feature exposure.

    Translate the opportunity into a defensible recommendation

    Finding an opportunity does not guarantee that it will reach a development sprint or content roadmap. The documentation source emphasizes that SEO work competes with product schedules, CMS constraints, legal concerns, brand requirements, technical debt, security, and other business priorities. Its central argument is that an official reference can move a discussion beyond personal preference, even though it cannot determine priority on its own.

    The same source cautions that Google documentation is incomplete and simplified for a broad audience. It should therefore serve as a starting reference, not an infallible account of every ranking mechanism or edge case. The article identifies canonicalization, robots.txt behavior, JavaScript rendering, discoverable internal links, structured-data eligibility, and HTTP status codes as areas where documented guidance can clarify implementation discussions.

    A strong recommendation package can combine both sources’ methods:

    1. Observation: State the Search Console pattern without interpretation.
    2. Hypothesis: Explain the likely missed intent, content gap, or technical obstacle, and identify AI’s role if it helped generate the hypothesis.
    3. Documentation: Link to the relevant official guidance and explain precisely how it applies to the current implementation.
    4. Recommendation: Describe the requested change in terms that content, engineering, or product teams can evaluate.
    5. Expected value and risk: Connect the change to the observed opportunity while avoiding unsupported forecasts.
    6. Validation: Specify what will be monitored after release and what result would challenge the original hypothesis.

    This format also improves collaboration. Developers can evaluate how to satisfy a documented search requirement within the site’s technical constraints. Content teams can see which audience behavior supports an update. Decision-makers can compare the opportunity with other work instead of being asked to accept an unexplained SEO rule.

    Key takeaways

    • Search Console establishes observed performance; AI helps organize it into hypotheses and possible actions.
    • Query filtering should begin with a decision question, not an open-ended search for anything interesting.
    • AI classifications, clusters, and trend signals require review against the original query and landing-page data.
    • Official Google documentation can support the technical rationale, but it does not replace experience, testing, or business prioritization.
    • The most defensible SEO proposal connects observation, hypothesis, documentation, action, value, and validation.

    As search interfaces and audience language continue to change, the durable advantage will come from shortening the path between evidence and action while keeping every inference inspectable. Teams that preserve that discipline can use AI for speed without surrendering accountability.

    References

  • A Framework for Technical SEO Risk, ROI and Indexing

    A Framework for Technical SEO Risk, ROI and Indexing

    Technical SEO decisions become difficult when the highest-impact changes also create the widest failure surface. URL structures, canonical rules, robots.txt directives, internal links and migrations can improve discovery and indexing, yet an error in any of them can affect large parts of a site.

    The measurement environment is equally imperfect. Benefits may emerge only after recrawling and reindexing, avoided losses leave no clean counterfactual, and even a primary diagnostic such as Google Search Console can be delayed. A useful operating model must therefore connect three disciplines: risk-based prioritization, layered indexing diagnosis and evidence-based ROI reporting.

    Technical SEO combines implementation risk with measurement uncertainty

    The implementation challenge and the measurement challenge are closely related. The changes most likely to affect organic performance are often sitewide or template-level changes, which makes them difficult to isolate and dangerous to test carelessly.

    One Search Engine Land contributor identified URL updates, canonical changes, robots.txt edits, internal linking work and migrations as initiatives that deserve extra caution. Their common characteristic is scale: a rule or template change can alter how search engines encounter, interpret or prioritize many URLs at once. A small configuration mistake can consequently have a much larger effect than an isolated metadata edit.

    A separate Search Engine Land analysis explains why the return from this work can be hard to prove. Technical changes rarely occur in a closed system, search engines recrawl and reindex on their own schedules, and multiple teams may release changes together. Sitewide work can also remove the possibility of an untreated control group. The result is an inference problem, not merely a reporting gap.

    This distinction matters for funding. Some technical SEO work seeks measurable growth, while some maintains access, resolves technical debt or reduces the probability and cost of a future loss. A migration that preserves traffic may be successful even if its performance chart is flat. Treating every project as a short-term acquisition campaign undervalues resilience and encourages false precision.

    Prioritize changes by exposure, value and failure cost

    An audit finding is not automatically an implementation priority. Automated crawlers are effective at finding patterns, but a warning may represent a serious defect, an intentional configuration, a platform limitation or a low-value imperfection. Manual validation and business context should come before a development ticket.

    A practical prioritization decision can be organized around five questions:

    1. Is the issue real? Confirm representative examples and determine whether the observed behavior is intentional.
    2. What is exposed? Establish how many URLs, templates or sections could be affected, with extra weight given to commercially or strategically important pages.
    3. What outcome is expected? State whether the work is intended to improve discovery, consolidate signals, preserve existing visibility, reduce wasted crawling or prevent a known failure mode.
    4. What does implementation require? Account for engineering effort, platform constraints, cross-team dependencies and the testing needed before release.
    5. What happens if the change is wrong? Consider the scale of lost crawl access, unintended consolidation, broken discovery paths or migration-related visibility loss.

    This framework prevents easily counted issues from crowding out consequential work. For example, an automated report may flag metadata on low-priority pages, while a canonical rule affecting an important template could receive less attention because it requires manual investigation. The number of warnings is not a reliable measure of business impact.

    Different changes also require different controls. URL moves need explicit redirect mappings, updated internal links and refreshed XML sitemaps. Canonical changes require validation of both the emitting template and its targets. Robots.txt edits should be checked against intended URL patterns and the production environment. Navigation changes need checks for orphaned pages, removed pathways and links pointing to non-public locations. A migration needs all of these controls coordinated because it can combine several high-risk changes in one release.

    Indexing diagnosis should start by testing the evidence itself

    Hands examine layered website pages and crawl paths with a magnifying lens, revealing a broken route and conflicting signal.

    An indexing chart can look authoritative while describing an older state of the site. One source reported that the Google Search Console page indexing report was more than two weeks behind, with June 11, 2026 shown as its latest timestamp. The report normally helps distinguish indexed from non-indexed pages, presents reasons for exclusion and can overlay impressions, but delayed processing limits its value for investigating recent events.

    The first diagnostic question should therefore be whether the evidence is current enough for the period under investigation. A stale report is not proof of a new indexing loss, nor does it prove that a recent fix failed. It establishes an observation boundary: aggregate conclusions about the missing period must remain provisional.

    When aggregate reporting is delayed, diagnosis can move through a layered sequence:

    1. Record report freshness. Note the visible processing date before comparing deployments with indexed-page totals or exclusion reasons.
    2. Inspect representative URLs. Use Search Console’s URL inspection capability for important examples, recognizing that this is a page-by-page investigation rather than a fresh sitewide report.
    3. Trace the technical signal chain. Check whether the URL can be reached through intended internal links, whether redirects lead to the expected destination, and whether canonical or noindex signals point elsewhere.
    4. Review crawl controls. Compare robots.txt rules with the affected URL patterns, particularly after a deployment or migration.
    5. Check discovery sources. Confirm that internal links and XML sitemaps contain the intended current URLs rather than old, redirected or non-public versions.
    6. Segment the pattern. Determine whether examples share a template, directory, parameter pattern or release. A common boundary can identify a systemic cause without treating every exclusion as the same problem.
    7. Separate visibility from index status. Use impressions and other available performance evidence as supporting context, not as a substitute for current indexing data.

    This sequence connects the indexing report’s categories with the implementation risks highlighted in the rollout guidance. Duplication, redirects, canonical choices, crawl restrictions and internal discovery are not independent dashboard labels; they are interacting signals. Conflicts between them can produce a symptom that looks like a single indexing problem even when the cause sits in a template or release process.

    Deployment controls create better evidence as well as safer releases

    Website components pass through staged safety gates while a defective module is diverted before reaching the production network.

    Testing is not only a safeguard. It also improves attribution by documenting what changed, where it changed and what successful behavior should look like. Without that record, a later movement in crawling, indexing or visibility is difficult to connect to a release.

    Before launch, teams should define the affected templates and priority sections, preserve a set of representative URLs, specify expected signals and agree on rollback criteria. Redirect mappings, canonical destinations, robots.txt patterns, internal links and sitemap entries should be validated in an appropriate test environment when the platform permits it. Early alignment with developers, content teams, product owners and other stakeholders is especially important when a change spans systems.

    After launch, the same examples should be checked again in production. Redirect destinations, canonical outputs, crawl directives, internal links and sitemap contents should match the approved plan. Monitoring should distinguish release timing from Search Console’s data timestamp so that reporting latency is not mistaken for implementation failure.

    Measurement can then be matched to the type of return:

    • Enhancement: evidence that a targeted change improved discovery, indexing or search visibility in the intended segment.
    • Maintenance: evidence that known technical defects or inefficient processes were removed and the expected technical state was restored.
    • Resilience: evidence that important pages retained access, signals and visibility through a migration, platform change or external search disruption.

    Where segmentation is feasible, the ROI source recommends a proof of concept resembling an SEO A/B test: apply a change to one segment, leave a comparable segment untreated and evaluate the relative result before expanding it. Sitewide infrastructure work may make that impossible. In those cases, relative trends, competitor movement around shared external events and longer-term performance can support an inference, but they should be labeled as proxies rather than causal proof.

    Funding discussions become more credible when the claim matches the evidence. Growth work can be evaluated against an expected improvement, while maintenance and resilience work can be framed in the language used for infrastructure, security and insurance: exposure, likelihood, consequence and cost of control. Scenario assumptions should remain visible instead of being converted into a single guaranteed revenue figure.

    Key takeaways

    • Audit counts do not determine priority; validate the issue, affected scope, business importance, effort and failure cost.
    • URL, canonical, robots.txt, internal linking and migration changes require controls proportionate to their sitewide exposure.
    • Check the processing date before using Search Console’s page indexing report to judge a recent release or indexing event.
    • When aggregate data is stale, inspect representative URLs and trace redirects, canonical signals, crawl controls, discovery paths and sitemap entries.
    • Report technical SEO as a mix of enhancement, maintenance and resilience, using experiments where possible and clearly labeled proxies where they are not.

    As search behavior and site platforms continue to change, technical SEO programs will need stronger release records and more explicit uncertainty, not more confident-looking dashboards. Teams that connect engineering controls with indexing evidence and financial framing will be better equipped to pursue meaningful gains without hiding the risk required to achieve them.

    References

  • Modern SEO Workflows: From Dashboards to Small Tools

    Modern SEO Workflows: From Dashboards to Small Tools

    A modern SEO workflow has to do more than collect rankings and audit errors. It must distinguish visibility from traffic opportunity, focus limited time on pages that matter to the business, and turn recurring analysis into reliable automation.

    The most useful operating model is therefore not a wholesale replacement of traditional SEO software. It is a layered system in which established data sources reveal the problem, people choose the intervention, and AI-assisted tools reduce the cost of repeating proven work.

    The operating model matters more than the size of the stack

    Rank trackers, keyword platforms and site crawlers remain useful because search engines still need to discover, interpret and evaluate pages. However, the reported case for a new SEO stack is that those tools describe only part of a more fragmented search environment. AI Overviews, local packs, shopping features and other result formats can change how much value a nominal ranking produces. Historical search volume can likewise remain stable while an answer displayed in the results reduces the traffic available to publishers.

    That changes the role of measurement. A ranking is an observation, not an outcome. The workflow must connect traditional visibility, AI-search presence, landing-page behavior and conversion evidence before deciding what deserves attention. The same source reported that LLM referral traffic in its cited dataset grew by 80% between the first and second halves of 2025 and converted at 18%, while accounting for 2% or less of total traffic. Those figures were presented as evidence of a small but potentially meaningful channel, not as proof that conventional search had ceased to matter.

    Workflow layerQuestion it answersTypical inputsRequired output
    ObserveWhere is visibility, demand or performance changing?Search Console, analytics, rank tracking, crawls and AI-visibility observationsA short list of material signals
    DecideWhich signal is worth acting on now?Business value, intent, conversion proximity and implementation effortOne prioritized intervention
    ShipWhat can improve the page or remove the constraint?Content edits, internal links, technical fixes and clearer conversion supportA completed change or actionable brief
    SystematizeWhich repeated work should become faster and more consistent?APIs, scripts, notebooks and carefully supervised LLMsA documented, testable process

    This sequence prevents a common tooling mistake: automating a report before establishing which decision the report should support. It also preserves a place for human judgment between data collection and implementation.

    A 120-minute loop can connect monitoring with delivery

    A top-down desk scene shows four connected stages of an SEO workflow arranged in a circle around a strategist's hands.

    The reported 120-minute workflow addresses a practical constraint: on a lean marketing team, SEO competes with campaigns, reporting, email, social publishing and website requests. Its strongest principle is that a weekly session should finish with work shipped, not merely with more metrics reviewed.

    The first five time boxes below follow the source’s reported schedule. The final 20-minute block is a synthesis of the other sources’ automation guidance, turning the weekly session into a tool-development feedback loop.

    1. Minutes 0-15: inspect Search Console and analytics for meaningful movement, including clicks, impressions, click-through rate, landing-page performance, conversions and critical indexing warnings. Record the largest win, concern and investigation target rather than building a presentation.
    2. Minutes 15-35: identify a small number of query opportunities. The source recommends examining queries in positions 4-15 with meaningful impressions, pages with weak click-through rates and results where the ranking page only partly satisfies intent.
    3. Minutes 35-60: improve one page close to revenue, such as a product, service, category, pricing, comparison or consultation page. The change might address an objection, clarify the audience, add proof, answer a relevant question or make the next action easier to understand.
    4. Minutes 60-80: resolve one consequential technical or indexing problem. If a direct fix is not possible, produce an assigned issue or a developer brief with affected URLs and the expected behavior.
    5. Minutes 80-100: strengthen internal links between useful informational pages and relevant commercial destinations, while also connecting supporting guides and newer strategic content.
    6. Minutes 100-120: verify what changed, document the result and mark one repetitive task as a possible automation candidate. That candidate should enter a backlog rather than becoming an improvised build during the same session.

    The value of this cadence is not the clock alone. It creates a recurring path from signal to decision to change. It also generates concrete automation ideas: a comparison performed every week, a recurring CSV cleanup, a repeated title check or a manual alert that depends on the same thresholds each time.

    Small tools should begin with a bounded decision

    The source on vibe coding describes a low-barrier pattern: specify a program in natural language, run the generated code in an environment such as Google Colab, inspect the output and return errors to the AI for another iteration. It distinguishes this from AI-assisted coding, where a developer remains more directly responsible for the system, and from no-code platforms, which expose automation through visual interfaces.

    The distinction helps set an appropriate ceiling. Vibe coding is presented as suitable for prototypes, internal utilities, demonstrations and tasks where a useful result does not have to be perfect. Commercial software, sensitive systems and products requiring dependable maintenance call for stronger engineering, security and testing practices.

    A reported SEO example makes the right project shape clear. After a site crawl produced vector embeddings, the author prompted an AI to create a Colab tool that would compare vectors with cosine similarity and suggest related pages within each locale. The program had an explicit input, a defined matching rule and a CSV output. It did not attempt to automate an entire SEO strategy.

    Before generating code, a useful tool brief should define:

    • The decision or bottleneck the tool is meant to improve.
    • The exact input source, required columns and accepted file format.
    • The transformation or rule applied to the data.
    • The expected output format and who will use it.
    • A small set of known examples for checking correctness.
    • The behavior when data is absent, duplicated, malformed or unexpectedly large.
    • The APIs, credentials, usage charges and execution environment involved.

    Tool choice can then follow complexity. An LLM may be enough to explore a one-off dataset or review copy. An API becomes useful when manual exports are the bottleneck. A lightweight script suits a stable transformation such as flagging performance changes or checking metadata. A notebook is appropriate when code, commentary and outputs need to remain together. A maintained application is warranted only when the process has durable users, permissions, interfaces and support requirements.

    Validation is part of the workflow, not a final polish

    A compact modular tool moves a web page tile through several visual validation checkpoints while rejected variants remain separated.

    All three sources point toward speed, but they also expose different reasons to retain human control. The new-stack article recommends using LLMs for analysis, content review, competitor comparison, metadata and structured data while keeping editorial and strategic oversight. The weekly workflow keeps prioritization tied to commercial importance. The vibe-coding account shows why plausible-looking output cannot be accepted on appearance alone.

    In one example from the vibe-coding source, an underspecified prompt failed to explain that the input would be a CSV. The generated tool responded with invented URLs, traffic figures and charts. The same source reports that generated code can depend on packages that are not installed, and that paid APIs may introduce authentication steps and usage costs. These are not edge concerns: they demonstrate that execution, factual grounding and operating cost must all be tested separately.

    • Ground the run: identify the authoritative input and reject synthetic substitutes unless test data is explicitly requested.
    • Test a sample: compare several outputs with results that can be checked manually, including an ordinary case and an edge case.
    • Inspect failure behavior: confirm that missing columns, empty files, invalid credentials and API errors produce understandable messages.
    • Protect access: keep credentials out of prompts, shared notebooks, exported files and source code intended for distribution.
    • Track cost: estimate which calls consume paid API units or usage-based platform resources before scheduling repeated runs.
    • Preserve review: require a person to approve consequential content changes, redirects, canonical decisions, schema deployment or other site-wide actions.
    • Document ownership: record the tool’s purpose, dependencies, expected inputs, validation method and person responsible for maintenance.

    A prototype should be promoted into a recurring workflow only after it produces repeatable results on known data. If the logic affects many pages or a revenue-critical system, code review and stronger testing become proportionally more important.

    Key takeaways

    • Keep traditional SEO data, but interpret rankings and search volume alongside result features, traffic opportunity and business outcomes.
    • Time-box reporting so that every weekly SEO session produces a shipped improvement, an assigned fix or a precise implementation brief.
    • Use recurring manual work to discover automation opportunities; do not begin with a tool and search for a problem afterward.
    • Give every small SEO utility explicit inputs, transformation rules, outputs, test cases and failure behavior.
    • Treat LLMs, APIs and scripts as accelerators within a reviewed process, not as substitutes for strategy, factual checks or technical ownership.

    As search interfaces continue to diversify, the durable advantage will come from shortening the distance between a trustworthy signal and a verified improvement. Teams can build that capability incrementally, one weekly decision and one well-scoped tool at a time.

    References

  • Google June 2026 Spam Update: What Site Owners Should Check

    Google June 2026 Spam Update: What Site Owners Should Check

    Google’s June 2026 spam update completed a short global rollout that applied across languages and locations. The practical challenge now is determining whether a site’s changes are plausibly connected to the update rather than treating every movement as evidence of a spam penalty.

    The two reports establish the rollout’s timing, scope, and purpose while also highlighting an important recovery distinction: correcting a policy problem can support improvement over time, but rankings previously gained through devalued spam links may not return.

    Rollout timing, scope, and context

    The launch report said the update began around noon ET on Wednesday, June 24, 2026. Google described it as a global update affecting all languages and indicated that deployment could take a few days.

    The completion report said Google marked the rollout complete at 2 p.m. ET on June 26. It was the second announced spam update of 2026, following the March spam update. The launch report placed it within a wider run of changes that also included the February Discover update and the March and May core updates.

    Key takeaways

    • The reported rollout ran from June 24 to June 26, 2026.
    • Google said the update applied globally and across all languages.
    • The sources described it as a standard spam update, not specifically as a link spam update.
    • Sites should evaluate changes against the rollout window and review compliance before making broad corrective changes.

    What the update was designed to address

    According to the launch coverage, spam updates improve Google’s automated ability to identify attempts to manipulate search rankings. The report cited SpamBrain, Google’s AI-based spam-prevention system, as an example of the systems involved in detecting established and emerging forms of abuse.

    That purpose does not establish why any individual page gained or lost visibility. The completion report noted that spam updates can sometimes affect sites that were not deliberately trying to manipulate Google. It also characterized this rollout as feeling somewhat larger than the March spam update, but presented no measurement that would turn that impression into a general conclusion.

    How to investigate a possible update impact

    An analyst compares abstract website performance signals across several monitors at a desk.

    A useful assessment separates timing, scope, and cause. Because several named Google updates preceded this rollout, a ranking change should not be attributed to the June spam update solely because it occurred during a busy period.

    1. Confirm the timing. Compare Search Console, traffic, and ranking patterns before, during, and after the June 24-26 rollout window.
    2. Identify the scope. Determine whether the change is sitewide or concentrated among particular pages, queries, or content groups.
    3. Check unrelated explanations. Review recent publishing, technical, tracking, and site-template changes that could produce a similar pattern.
    4. Review Google’s spam policies. Examine the affected areas for practices intended to manufacture ranking signals or otherwise abuse search systems.
    5. Match corrective work to evidence. Address confirmed policy or quality problems instead of making indiscriminate changes based only on temporal correlation.

    Recovery depends on what caused the loss

    A web page at a fork follows one path toward repairs while artificial link structures dissolve on the other.

    The launch report said sites that violate Google’s spam policies may rank lower or disappear from results. After violations are corrected, improvement may occur over time if Google’s automated systems recognize that the site is compliant. This is not presented as an immediate or guaranteed recovery mechanism.

    Link-related losses require a different interpretation. The same report explained that when Google neutralizes the ranking value of spammy links, the advantage previously produced by those links is lost; removing or cleaning up the links does not recreate that former benefit. However, neither source identified the June 2026 rollout as a link spam update, so that limitation should be applied only when the evidence actually points to devalued links.

    The most defensible next step is continued monitoring paired with a focused compliance review. Decisions made from page-level evidence will be more useful than reacting to the rollout label alone, especially while post-update patterns become clearer.

    References