Tag: Audience Targeting

  • Paid Media Automation: A Control Plan for New Features

    Paid Media Automation: A Control Plan for New Features

    Your ad platforms can now pace an entire campaign budget, infer what viewers care about, optimize toward new customers, and generate more of the ad itself. The hard part is no longer finding automation. It is deciding what to delegate without handing over the commercial judgment that makes the campaign worth running.

    If you are preparing a launch, promotion, audience test, or cross-platform migration, use one operating rule: automate a bounded task, give the system a measurable objective, and retain an independent check on spend and business value. The latest Google, YouTube, and Microsoft Advertising changes make that division of responsibility more important, not less.

    Key takeaways

    • Use campaign-total budgets for genuinely fixed flights. The feature solves pacing work; it does not decide whether the campaign deserves more money.
    • Match the targeting signal to the question. Interest targeting identifies people who may care, contextual targeting chooses relevant environments, and customer-acquisition optimization changes how conversions are valued.
    • Define a new customer before asking an algorithm to find one. Identity rules, lookback logic, deduplication, and the value premium all affect what the system learns.
    • Treat generated creative and easier imports as workflow accelerators. Final URLs, tracking, claims, images, conversion goals, and brand compliance still need human review.
    • Intervene when the evidence identifies a constraint. Lost share from budget, lost share from rank, poor conversion quality, and faulty customer classification require different responses.

    Automate budget pacing only when the cap and end date are real

    Google’s campaign-total budget gives you one amount for a defined flight and lets the system optimize spending across the available days or weeks. The setting, previously associated with Performance Max, has moved into open beta for Search and Shopping campaigns. It is designed to use the allocated budget by the campaign’s conclusion, removing the need to keep rewriting daily budgets during a short promotion.

    That makes it a strong fit for a sale, product launch, event window, or controlled test with an immovable end date. It is a weaker fit for evergreen activity whose budget changes whenever demand, inventory, margin, or lead capacity changes. In an evergreen campaign, a daily budget remains a useful recurring control. In a fixed flight, repeatedly adjusting that daily number can become unnecessary operational noise.

    Do not confuse automated pacing with an outcome guarantee. The platform can decide when to spend the authorized amount, but it cannot know whether your margin target, stock position, sales capacity, or cash-flow limit has changed unless those constraints are represented in the campaign or acted on by your team.

    Before enabling a campaign-total budget, write a short budget brief and have another person verify the amount, currency, dates, and time zone. This is a financial control, not bureaucracy: the setting authorizes the system to use the full campaign total, so an incorrect amount or end date can turn a setup mistake into real spend.

    1. State the business cap. Record the maximum media amount approved for this campaign, separate from creative, agency, production, or platform costs that are not represented by the setting.
    2. Confirm the flight. Check the start date, end date, time zone, landing-page availability, promotional terms, and any inventory or lead-capacity constraint.
    3. Name one primary outcome. Decide whether the campaign is being judged on qualified traffic, purchases, leads, new customers, or another observable result. Do not let a secondary engagement metric silently become the goal.
    4. Set a decision threshold. Document the cost, return, or quality condition that would justify pausing, continuing, or expanding the campaign. The platform’s ability to spend the budget does not answer that decision.
    5. Schedule evidence-based checkpoints. Review after delivery begins, around the middle of the flight, and early enough before the end to correct a tracking or eligibility problem. Do not force spending into equal daily slices merely because the average planned pace is the total divided by the number of campaign days.

    A promotional example associated with the rollout recorded a 16% increase in website traffic while remaining within budget and without a reported decline in ROAS. That is useful evidence that automated pacing can support a fixed promotion, but it is one retailer’s result, not a forecast for your account. Use it to validate the operating model, not to set an expected lift.

    Choose a targeting signal based on the job it must do
    An operator routes three distinct streams of audience signals toward visual symbols for awareness, consideration, and purchase tasks.

    Audience automation often gets discussed as though every signal were another way to find the same person. It is not. An inferred interest, the context of a page, and a customer’s relationship with your business answer different questions. Selecting one because it is newly available can produce a technically valid campaign with no coherent targeting logic.

    SignalQuestion it answersMain limitationWhat you should test
    YouTube interest targetingWho is likely to care about this subject?Interest is inferred and does not prove current purchase intent.Whether one audience hypothesis improves the business outcome while creative and offer remain comparable.
    Microsoft contextual targetingWhere should this message appear?A relevant category or placement does not guarantee that every viewer is a prospect.Performance and quality by content category or reported placement.
    New-customer acquisition optimizationWhich conversions should receive more value?Bad customer classification teaches the system the wrong economics.Incremental new-customer volume, acquisition cost, and downstream customer quality.

    YouTube Promotions has expanded beyond broad demographic controls by adding interest categories derived from aggregated, anonymized viewing and search patterns across Google services. Someone who repeatedly watches cooking videos and searches for recipes, for example, may fall into a Food & Dining interest category. The initial rollout was desktop-only, so confirm that the option is present in the account and workflow you intend to use.

    The important word is interest. This signal is more expressive than age, gender, or location alone, but it is still an inference. It does not mean the viewer declared an identity, searched for your product, or is ready to buy. Use it to test a reasoned audience hypothesis such as, “People who consistently engage with this subject will respond to this format.” Do not translate the category into a stronger claim than the data supports.

    1. Write the hypothesis before choosing the category. Name the audience, the expected need, and why the video addresses it.
    2. Keep the proposition recognizable across variations. If you change the audience, offer, opening, format, and landing page simultaneously, you will not know what produced the difference.
    3. Choose a downstream measure. Views can show delivery, but subscriber quality, qualified site activity, leads, purchases, or another available business signal should determine whether the audience is useful.
    4. Check the audience-to-creative match. A broad interest category usually needs a message that is immediately legible to that interest. A highly specialized message may require a narrower hypothesis or a different targeting method.
    5. Record what the test disproves. A weak result may reject the category, the creative interpretation of that category, or the offer. It does not establish that interest-based targeting never works.

    Microsoft’s contextual option solves a different problem. Content Targeting for Audience ads is generally available for selected Microsoft-owned placements, including MSN and Outlook, and for categories such as Finance or Travel. A placement reporting view shows where ads appeared. That gives you a practical feedback loop: start with a context that makes the message sensible, inspect actual delivery, and refine the context based on qualified outcomes rather than category names alone.

    Use interest targeting when your claim is about the viewer’s recurring behavior. Use contextual targeting when the surrounding content makes the message timely or easier to understand. Use search targeting when an expressed query is central to the campaign. These signals can complement one another, but they should not be treated as interchangeable labels for “relevant audience.”

    Define customer value before activating acquisition automation

    Microsoft Performance Max now offers an open-beta customer-acquisition goal that can prioritize new customers or focus exclusively on them for purchase campaigns. You can also assign a higher conversion value to a new customer, allowing optimization to account for more than the immediate transaction.

    This is useful only if “new” and “more valuable” have defensible meanings inside your business. The algorithm cannot settle whether a returning buyer after a long absence counts as new, whether two email addresses belong to the same customer, or whether expected future purchases justify a value premium. Those are measurement and finance decisions that must exist before campaign setup.

    1. Write the identity rule. Specify which identifiers and systems distinguish an existing customer from a new one. Include how guest checkouts, duplicate records, offline purchases, and unavailable identifiers are handled.
    2. Write the time rule. Document the lookback period or business condition used to classify a customer. Keep that definition consistent in campaign reporting, CRM analysis, and financial evaluation.
    3. Write the value rule. Base any new-customer premium on incremental contribution you can support, not on an aspirational lifetime-value number. Avoid counting future value twice if part of it is already represented in the conversion value sent to the platform.
    4. Write the failure rule. Decide what happens when customer status is unknown. If classification coverage is weak, an exclusive-new-customer mode makes those errors more consequential. A prioritization approach gives you a less brittle starting point while you validate the data.
    5. Reconcile platform and business records. Compare reported new-customer conversions with CRM or commerce records. Investigate gaps before increasing the value premium or budget.

    The safest way to evaluate this goal is incrementally. Establish the existing-customer baseline, confirm that customer classification is reaching the campaign, activate the acquisition logic within a controlled scope, and compare both immediate efficiency and downstream quality. If the reported new-customer rate rises but your customer system does not show the same movement, treat the discrepancy as a measurement problem before calling it growth.

    Do not optimize exclusively for the easiest definition of “new.” A low-value first order, a duplicate account, and a genuinely incremental customer can all look similar at the conversion event. Your value model should help the system distinguish economic importance, while your later customer data determines whether the model was right.

    Use better visibility to make fewer, more precise interventions
    An analyst makes one focused adjustment to a guarded campaign network while two anomalies glow among otherwise stable automated pathways.

    Automation becomes manageable when each diagnostic leads to a different decision. Microsoft’s early-2026 Performance Max changes add share-of-voice measures, including impression share and losses attributed to budget or rank. Those distinctions matter because more budget is a rational response to only one of them.

    • Loss attributed to budget: first verify that conversion quality and unit economics are acceptable. If they are, decide whether the business cap should change. Do not let the metric authorize its own budget increase.
    • Loss attributed to rank: investigate relevance, assets, destination experience, offer, bidding inputs, and other quality constraints. Adding budget alone does not address a rank problem.
    • Little reported share loss but weak results: examine the proposition, tracking, audience logic, and conversion definition. The problem may be what happens after eligibility, not a lack of reach.
    • More traffic with unchanged customer quality: resist declaring success from delivery metrics. Return to the outcome named in the campaign brief.

    Granular measurement is also becoming easier to preserve. Microsoft now supports asset-group URL options and tracking templates, while Google imports can carry more flexible asset groups and as many as 50 search themes. An ineligible image or auto-generated logo no longer has to block the rest of an asset group from importing. That reduces migration friction, but it also makes post-import quality assurance more important: a successful import means the objects moved, not that every object is eligible, correctly tracked, or strategically equivalent.

    Review imported campaigns in the destination platform. Check campaign goals, budget type, customer-acquisition settings, final URLs, tracking templates, search themes, asset eligibility, images, logos, and conversion measurement. Record anything omitted or transformed during import. If the destination account uses different customer data, conversion values, or URL conventions, do not assume the imported optimization logic still means the same thing.

    Creative automation needs the same discipline. Auto-generated assets are becoming the default for newly created Microsoft Responsive Search Ads worldwide, except in China and South Korea. Sensitive verticals remain opt-in, and existing RSAs are unaffected. Microsoft reports roughly a 5% CTR increase among advertisers using generated assets, but that vendor-reported aggregate does not show that every generated message improves conversion quality, margin, or compliance.

    Review generated headlines and descriptions as live advertising claims. Check factual accuracy, pricing, promotional dates, prohibited implications, brand language, landing-page consistency, and any approval requirements in your industry. A higher click-through rate can be harmful if the copy attracts people the offer cannot satisfy or makes a claim the destination does not support.

    Your recurring control loop should therefore be short and diagnostic: verify measurement, compare spend with the approved envelope, inspect customer quality, review audience or placement evidence, and then choose one material intervention. When learning is the goal, avoid changing targeting, creative, value rules, and budget at the same time. Automation can execute several changes quickly; it cannot preserve the explanation you lose by making them together.

    Before your next campaign, create a one-page automation contract. Name the task being delegated, the financial boundary that cannot move without approval, the signal the platform will optimize, and the evidence that will trigger a human decision. Then activate the smallest campaign scope capable of answering the question.

    If you cannot state those four things, delay the automation and repair the measurement or decision rule first. Once they are clear, the new controls can remove repetitive campaign work while leaving accountability exactly where it belongs.
    References

  • Performance Max Creative and Targeting Controls That Matter

    Performance Max Creative and Targeting Controls That Matter

    If you manage Performance Max, the uncomfortable choice can seem to be full automation or a maze of duplicated campaigns. That is the wrong choice. You can give the system better creative and stronger intent signals without rebuilding the account every time a limit changes.

    The useful distinction is simple: video assets shape what Performance Max can show, while search themes help steer the demand it should explore. Neither gives you deterministic control. Each gives the automation better inputs, and each needs a different plan.

    Know which Performance Max controls are signals

    A hand places colored beacons beside branching routes that guide an automated system without forcing it onto one fixed path.

    Performance Max controls do not all behave like conventional campaign settings. A hard limit determines what you can upload. A signal communicates what matters to your business. Confusing those roles leads to two common mistakes: treating themes like exact-match keywords and treating every new asset slot as an instruction to create another variation.

    ControlWhat it changesWhat it does not guaranteeDecision to make
    Video assetsThe creative ideas, formats, and ratios available within an asset groupThat every upload becomes an isolated or equally weighted testWhich missing asset would add meaningful coverage or test a clear idea?
    Search themesThe queries and intent patterns you want automation to prioritizeA strict keyword boundary around the traffic the campaign can pursueWhich customer intents deserve a stronger signal?
    Audience signalsAdditional context about the people likely to matterA fixed audience that automation can never move beyondWhich customer characteristics improve the meaning of the intent signal?

    This distinction gives you a useful operating rule: diagnose whether the campaign lacks material to show, clarity about demand, or a coherent asset-group structure. Add the control that addresses that specific deficit.

    Expand video coverage without filling slots for its own sake

    A creative director arranges a small set of distinct video scenes in horizontal, square, and vertical display frames while leaving extra frames empty.

    Google has been testing a change from a five-video limit to as many as 15 videos per asset group. The observed option had not received a formal announcement, so treat it as a test or gradual rollout until your own interface exposes it. Do not restructure a live campaign in anticipation of capacity your account does not yet have.

    If the larger limit is available, use the extra room in this order:

    <!– wp:list {
  • A Practical Playbook for Automated Google Ads Optimization

    A Practical Playbook for Automated Google Ads Optimization

    You turned on Google Ads automation so the system could handle more of the bidding and delivery work. Now the campaign is spending, results are uneven, and every available adjustment seems capable of disrupting the learning you have already paid for.

    The answer is not to make more changes. It is to make changes that answer specific questions. Give the campaign one measurable job, diagnose the layer that is failing, and isolate one variable long enough to learn from it. That is how you optimize Performance Max and Demand Gen without turning the account into a collection of unexplained edits.

    Give the automation one precise job

    Automated bidding and delivery are execution systems, not business strategies. Google can pursue the outcome you define, but it cannot decide whether that outcome represents useful growth for your business.

    Before changing an asset, audience, channel, or bid strategy, complete this sentence: “This campaign exists to generate [specific outcome] from [specific audience or demand source], and we will judge it by [specific business metric].” If you cannot complete it without using a vague phrase such as “more visibility,” the campaign is not ready for detailed optimization.

    Write a short optimization brief containing four decisions:

    1. Primary outcome: Name the action that matters, such as a purchase or qualified lead. Do not let a convenient secondary action become the campaign’s de facto goal.
    2. Conversion definition: Confirm that the conversion category and tracking represent the outcome you intend to buy. A campaign trained toward the wrong event can become efficient at producing the wrong result.
    3. Decision metric: Choose the metric that will determine whether a change stays. Click volume, conversion volume, cost per conversion, and conversion value answer different questions.
    4. Campaign role: Decide whether the campaign is capturing existing demand, re-engaging known users, finding similar prospects, or creating demand among new audiences. Do not evaluate an audience-expansion campaign as if every user had already expressed search intent.

    Demand Gen makes the bidding decision especially concrete. It requires a conversion category and supports Maximize Clicks, Maximize Conversions, Maximize Conversion Value, Target CPC, Target CPA, and Target ROAS. Match the strategy to the brief: use a click-oriented strategy when qualified traffic is the actual objective, a conversion-oriented strategy when action volume matters, and a value-oriented strategy only when the values passed into Google reflect meaningful differences between conversions.

    Target CPC is a useful Demand Gen option when controlling the amount you are willing to target per click matters more than giving bidding full freedom. It does not remove the need to assess traffic quality. Cheap clicks are not an optimization win when the audience, placement, or landing experience cannot produce the intended action.

    Once the brief is set, keep it stable during the test. If you change the conversion definition, bid strategy, audience, and creative together, a better result will not tell you which decision worked. A worse result will be equally uninformative.

    Diagnose the failing layer before touching settings

    Four transparent campaign layers float above a table while a diagnostic beam highlights one broken creative connection.

    A weak automated campaign does not automatically have an automation problem. The failure may sit in measurement, inventory, audience selection, creative, or the offer itself. Treating all five as one problem leads to account-wide changes that conceal the cause.

    Audit in this order:

    1. Measurement: Check that the recorded conversion is the action named in your brief. Inspect whether duplicate, secondary, or low-value actions are influencing your interpretation before you blame bidding.
    2. Inventory and channel: Determine where the ads appeared. A blended campaign total can hide meaningful differences between YouTube, Discover, and Gmail.
    3. Audience: Check whether the people engaging with the campaign resemble the users you intended to reach. An audience mismatch should be addressed before you conclude that the creative proposition is wrong.
    4. Creative: Look for patterns across headlines, images, videos, and formats. Use those patterns to form a testable hypothesis, not as permission to replace every asset at once.
    5. Offer and destination: Confirm that the promise made by the ad continues on the landing page and that the requested action makes sense for the user’s stage of awareness.

    Demand Gen gives you several views for this diagnosis. Its asset reporting, audience insights, channel segmentation, and YouTube placement reporting can help you locate the layer worth investigating. Use these reports as directional evidence. An asset-level performance label can identify a candidate for testing, but it does not prove that the asset alone caused the result because audience, placement, and delivery can differ.

    What you noticeCheck firstNext controlled action
    Reported conversions do not match business outcomesConversion action and categoryCorrect or separate the measurement problem before testing creative or audiences.
    One Demand Gen channel behaves differently from the othersChannel and placement reportingInspect that inventory, then decide whether the channel belongs in the campaign’s role.
    Audience insights do not resemble the intended buyerAudience constructionChange one audience boundary while keeping the offer and creative stable.
    Several assets built around one idea underperformCreative propositionBuild a coherent challenger around a different idea and test it against the original.
    Ads earn attention but the intended action does not followOffer and landing-page continuityCheck the promise, destination, and conversion ask before buying more traffic.

    Record the diagnosis before making the change. A useful optimization note states what you observed, what you think caused it, what single variable will change, and what result would support or reject the hypothesis. Without that record, campaign management tends to become a sequence of plausible edits with no cumulative learning.

    Run Performance Max asset tests as controlled experiments

    Two matching automated test chambers compare different creative tiles while an analyst observes the experiment.

    Performance Max has historically made creative diagnosis difficult because automation decides how assets are combined and delivered. The Performance Max asset A/B testing beta allows two asset sets to be compared while common assets remain fixed. It extends the earlier retail experiment model across Performance Max campaigns and gives you a cleaner way to test creative ideas without rebuilding the entire campaign.

    If the beta is available in your account, look for the experiment from the Experiments area under Assets. Because it is a beta, document the setup outside the interface as well: campaign, hypothesis, common assets, challenger assets, start date, intended end date, and decision metric.

    Use this sequence:

    1. Write one creative hypothesis. Examples include benefit-led versus proof-led headlines, product-focused versus lifestyle imagery, or two distinct video concepts. The hypothesis should explain why one approach may work better for the intended audience.
    2. Choose the level of the test. If you change one asset family, you can learn about that family. If you change headlines, images, and videos together, you are testing two creative systems and will only learn which complete system performed better.
    3. Protect the common assets. Keep every asset that is not part of the hypothesis the same across both versions. These shared elements form the control surface of the experiment.
    4. Freeze unrelated campaign decisions. Avoid changing audiences, bidding logic, conversion definitions, the offer, or the landing page while the asset experiment is running unless there is a material tracking or business problem that makes the test unsafe to continue.
    5. Choose the decision metric in advance. Judge the test by the outcome in the campaign brief. Do not promote a challenger solely because it attracted more engagement when the campaign exists to generate profitable conversions.
    6. Allow at least four weeks. Performance Max tests need a minimum four-week window to accommodate learning and delivery stabilization. Avoid ending the experiment because of an encouraging or alarming interim swing.
    7. Apply only the supported lesson. If a complete asset set wins, you have evidence for the set, not proof that every component in it is superior. Keep the winning direction and use the next experiment to isolate the headline, image, or video question that remains.

    The distinction between an asset report and an asset experiment matters. Reporting helps you find a question. A controlled experiment is what helps answer it. Replacing assets based only on descriptive labels may change the audience and delivery mix before you have learned whether the creative itself was responsible.

    Do not run a test merely to keep the account active. A useful challenger represents a meaningful alternative: a different message, visual argument, proof point, or format. Small cosmetic changes may produce a winner, but they often leave you without a reusable insight for the next campaign.

    Use Demand Gen for intentional audience expansion

    Performance Max creative optimization and Demand Gen expansion solve different problems. If your real goal is to reach people beyond an immediate search query, repeatedly changing Performance Max assets may be an indirect way to pursue it. Demand Gen is designed around the user rather than the keyword and can distribute image or video creative across YouTube, Discover, and Gmail.

    This changes the optimization question. Search campaigns react to expressed demand. Demand Gen asks which audience, creative story, and Google-owned surface can create or develop interest. Its goal is clicks or conversions rather than the impression or view objectives commonly associated with video advertising.

    Build the audience around one reason for inclusion

    Demand Gen supports several audience approaches:

    • Remarketing for people who have already interacted with the business.
    • Lookalike audiences for reaching users who resemble existing converters.
    • In-market, life event, and affinity segments for interest and behavior-based expansion.
    • Detailed demographics when the offer is relevant to defined demographic characteristics.
    • Custom segments based on the search terms, websites, or apps associated with the intended audience.

    Give each audience a clear rationale. A segment called “high intent” is not useful documentation unless you can state what behavior or characteristic earned that label. Keep in mind that combined segments are not compatible with Demand Gen, and audience exclusions are limited to your data segments. Build the test around the targeting controls the campaign actually supports rather than importing a structure from another campaign type.

    Match the test structure to your constraint

    Your first Demand Gen campaign should answer a narrow question that matters to the business:

    • If you are working with $5 to $40 per day: Keep the structure simple. A practical starting test combines the Google Engaged remarketing audience with a Custom Segment based on top-performing search terms. Treat that range as a test constraint, not a promise of sufficient volume or a universal budget recommendation.
    • If you run ecommerce campaigns: Compare feed-backed product advertising with non-feed lifestyle creative. Demand Gen can use a Google Merchant Center feed, while its standard image, carousel, and video formats let you test whether the product itself or the surrounding story is the stronger route to action.
    • If you have enough budget for sustained audience development: Assign distinct jobs to in-market, life event, demographic, or affinity audiences instead of combining every prospect into one expansion pool. An always-on structure is useful only when each audience has a reason to exist and a business outcome by which it can be judged.

    Start with the relevant Google-owned channels enabled when you need to learn where the idea travels, then use channel segmentation and placement reporting to decide what belongs in the next iteration. If you already know that a channel cannot support the campaign’s format, audience, or objective, scope it out deliberately. Channel control should follow the campaign brief, not a blanket belief that more inventory is always better.

    Keep creative and audience questions separate when possible. If you test a new audience with a new video, new images, and a different offer, you are testing an entire go-to-market package. That can be appropriate when the package is the decision. It is the wrong design when you need to know whether the audience itself is viable.

    Key takeaways

    • Define one business outcome, one conversion definition, one campaign role, and one decision metric before adjusting automation.
    • Diagnose measurement, channel, audience, creative, and landing-page continuity in that order so you change the layer that is actually failing.
    • Use Performance Max asset reporting to form hypotheses and the asset A/B testing beta to test them.
    • Hold common assets and unrelated campaign settings steady during a Performance Max experiment.
    • Run Performance Max asset experiments for at least four weeks so learning and delivery have time to stabilize.
    • Use Demand Gen when the job is audience-led expansion across YouTube, Discover, and Gmail, then segment channel, placement, audience, and asset performance.
    • Make every optimization produce a reusable lesson, not merely a different dashboard result.

    Choose one campaign for your next optimization cycle. Write its job in a sentence, identify the first failing layer, and log one hypothesis. If the question is creative, build a controlled Performance Max asset experiment. If the question is audience expansion, scope a Demand Gen test around one audience and one outcome. Your next change should buy information as well as performance.

    References

  • How to Use Email When AI Search Reduces Organic Reach

    How to Use Email When AI Search Reduces Organic Reach

    You can publish a strong answer, earn search visibility and still lose the visit when an AI-generated result gives the searcher enough information to move on. If organic clicks no longer carry the volume they once did, producing more content without changing distribution leaves the real problem untouched.

    You don’t need to abandon search. You need to turn more of the discovery you still earn into permission to continue the relationship. Email can do that, but only when you build it as an audience system rather than an occasional newsletter.

    Find the leak before asking email to fix it

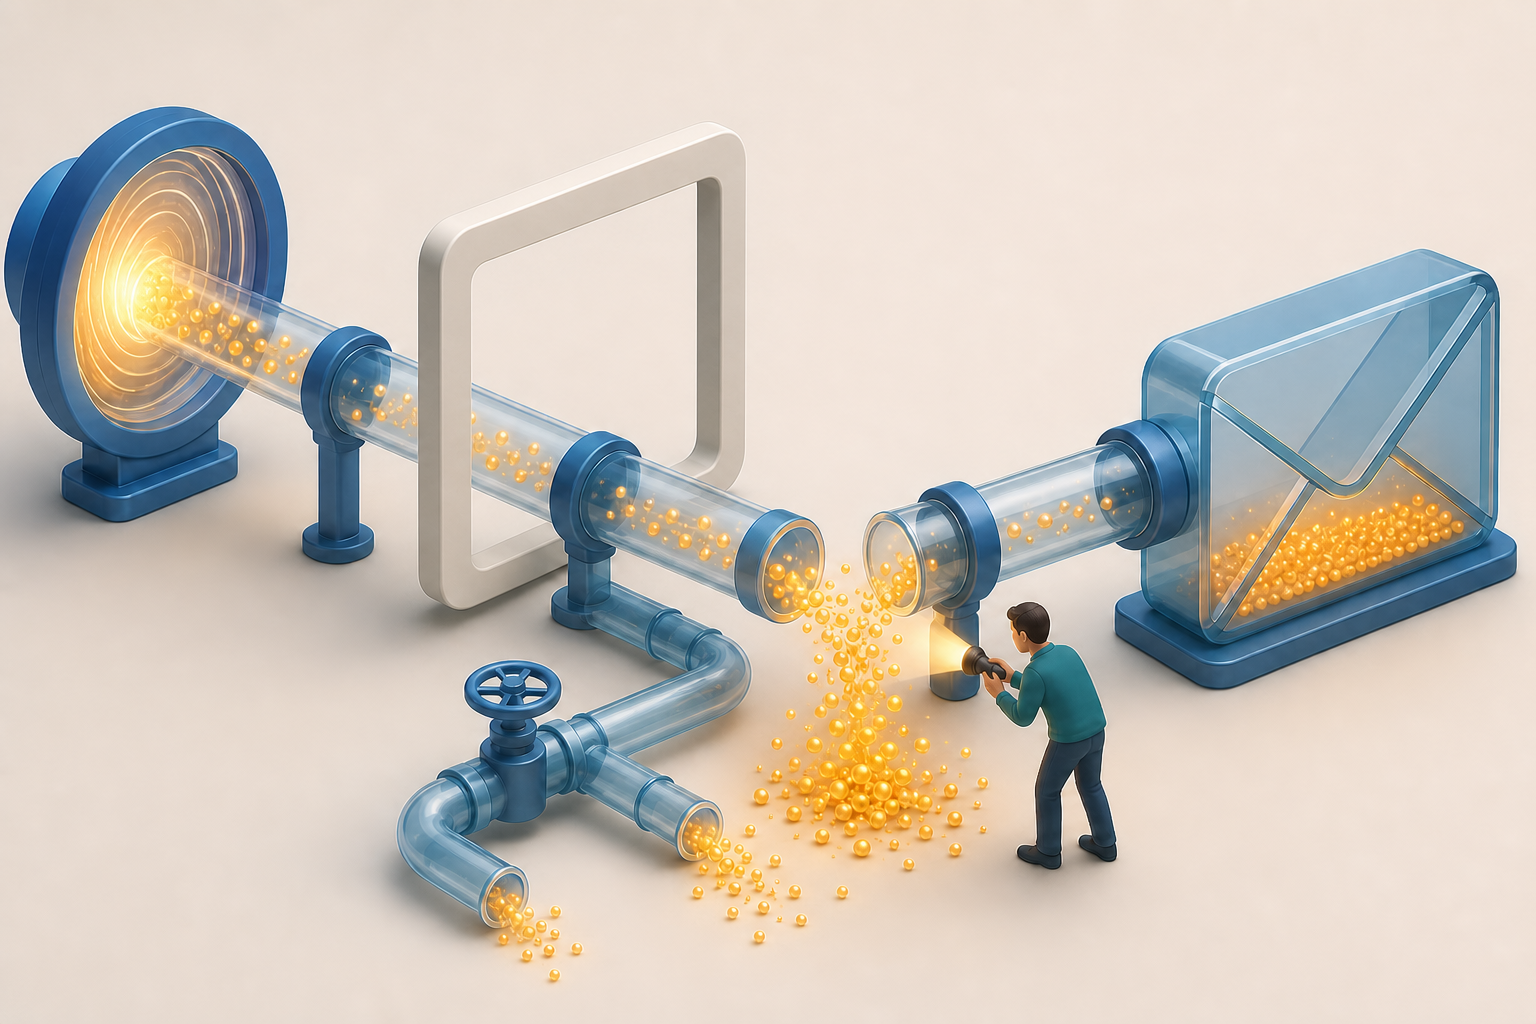
    Isometric illustration of a person inspecting a transparent pipeline where glowing particles leak between a search portal, a website, and an envelope-shaped chamber.

    Search-engine traffic has been projected to fall by 25% as AI changes how people receive answers. Treat that figure as a planning scenario, not as a prediction for your site. Your exposure depends on the questions you target, the strength of your brand, the purpose of each page and whether a searcher still needs to click after reading an AI-generated response.

    Email cannot replace people who never discover you. It works on the next part of the journey: retaining a useful connection with the people who do arrive. That distinction prevents you from expecting a retention channel to solve an acquisition problem.

    Map the journey as four connected jobs:

    <!– wp:list {
  • Emerging AI Ads and Remarketing for Small Audiences

    Emerging AI Ads and Remarketing for Small Audiences

    If your site attracts hundreds rather than thousands of qualified visitors, remarketing has often stalled before you could test the creative. The audience simply was not large enough to use. That barrier is now lower, while ads inside AI-generated answers are moving from an idea toward a possible new acquisition channel.

    You do not need to choose between them. Build a focused small-audience remarketing system now, then prepare the same messages, evidence, landing pages, and measurement rules for emerging AI inventory. You will have a working campaign instead of a speculative media plan, and you will be ready to test AI ads if a usable format becomes available.

    Key takeaways

    • Google Ads now permits eligible audience segments with as few as 100 active users across Search, Display, and YouTube, including remarketing and customer lists.
    • The 100-user requirement is an eligibility threshold, not a promise of reach, efficient delivery, or statistically reliable results.
    • OpenAI’s possible ad formats, including placements within AI-generated responses, remain preliminary. Treat them as a readiness track rather than available inventory.
    • Small advertisers should consolidate visitors by meaningful intent before creating narrow demographic or behavioral subdivisions.
    • A future AI ad should feed the same first-party journey as any other acquisition channel: a relevant landing page, a consent-aware audience rule, a useful follow-up message, and a measurable conversion.

    Make the 100-user threshold useful, not merely reachable

    A focused cluster of glowing audience tokens is surrounded by three ad cards and connected to a landing-page frame.

    Google’s lower minimum removes a real operational barrier. Remarketing lists and customer lists can now become eligible from 100 active users across Search, Display, and YouTube. Audience Insights also uses a 100-user threshold instead of the previous 1,000-user requirement, giving smaller accounts access to audience analysis earlier.

    Do not confuse eligibility with scale. A qualifying list can still produce limited delivery because campaign reach also depends on active membership, matchability, targeting, geography, auction conditions, budget, and whether those users return to an environment where your ads can serve. The threshold tells you that a campaign may participate. It does not tell you how much it will spend or whether it will perform.

    This distinction should change how you segment. A smaller advertiser rarely benefits from dividing an already small pool into many audiences based on every page, device, location, and content category. Each split reduces usable reach and makes the resulting performance rates harder to interpret. Start with a few pools whose members need meaningfully different messages.

    Audience poolUseful signalJob of the follow-up adWhat not to mix into it
    High-intent visitorsA visit to pricing, booking, quote, demo, cart, or another commercial action pageResolve the last important objection and return the person to the unfinished decisionCasual readers who have not shown commercial intent
    Consideration visitorsVisits to product, service, comparison, use-case, or evidence pagesClarify fit, differentiation, or proof before presenting the next stepEvery visitor to the site merely to increase list size
    Content visitorsEngagement with a guide, tool, tutorial, or problem-specific resourceContinue the same subject with a relevant resource or appropriate offerA generic sales message unrelated to the content consumed
    Known customersA customer list you have the right to useSupport a relevant renewal, replenishment, retention, or complementary purchase journeyProspects added only to make the audience appear larger

    Keep customers and prospects separate even when combining them would help you reach 100 users. They have different relationships with you, different reasons to respond, and often different conversion goals. An audience large enough to activate but too mixed to address coherently is not an improvement.

    Use Audience Insights to check whether a pool resembles the audience definition you intended. Do not turn a small set of aggregate characteristics into an elaborate persona. Ask campaign questions instead: Does this group reflect the intended stage of the decision? Is an important market missing? Does the evidence justify changing the message or landing page? Those questions produce actions; a long list of audience traits often does not.

    Build the smallest complete remarketing campaign

    Accessible remarketing does not mean creating a campaign for every available audience. It means building one complete path from a recognizable intent signal to a useful follow-up and a measurable result. Use this sequence.

    1. Name the decision you want to recover. Examples include completing a quote request, returning to a product evaluation, booking a consultation, or finishing a purchase. Choose one primary conversion so the campaign has a clear job.
    2. Write the inclusion rule in plain language. State which page, event, or first-party list makes someone appropriate for the message. If you cannot explain why every member belongs, the audience is too broad.
    3. Add exclusions before launch. Exclude people who already completed the campaign’s goal when further acquisition ads would be irrelevant. If existing customers need another message, place them in a customer journey rather than leaving them in a prospect campaign.
    4. Consolidate before subdividing. Combine signals that reflect the same intent and need the same follow-up. Split an audience only when the new group warrants different creative, a different destination, or a different business objective.
    5. Check consent and data rights. Use site data and customer information only when you have the right to collect, upload, and use it under applicable law and platform policy. A lower platform threshold does not relax privacy obligations. Do not fill a list with scraped or purchased contacts.
    6. Match the message to the interrupted decision. Someone who left a pricing page needs help evaluating value, terms, or fit. Someone who read an educational guide may need the next useful resource. Repeating your broad brand slogan ignores the information you already have.
    7. Continue the journey on the landing page. Send the visitor to the page that answers the promise in the ad. Routing every click to the homepage forces the person to reconstruct a journey you already understood well enough to target.
    8. Predefine the measurement rule. Record the primary conversion, conversion quality check, campaign cost, and the condition that would justify continuing, changing, or stopping the campaign. Set spending limits from your own margins and acceptable acquisition economics, not from a platform recommendation alone.
    9. Change one meaningful lever at a time. Test a message, offer, audience definition, or destination against a stated hypothesis. Simultaneous changes may improve the campaign, but they will not tell you which decision caused the improvement.

    Keep a simple campaign record containing the audience name, inclusion signal, exclusions, creative promise, landing page, primary conversion, and owner. Use names that expose the logic, such as high-intent pricing visitors, rather than labels such as audience A. Clear naming matters when a small account begins adding channels and the original rationale is no longer fresh.

    Small audiences also require restraint in reporting. Look first at actual conversions, conversion quality, total cost, and whether the intended people reached the intended page. Percentages can move sharply when the underlying counts are small. A striking click-through or conversion rate is not enough to scale a campaign whose absolute result is still inconclusive.

    Prepare for ads inside AI answers without inventing the channel

    Unlabeled campaign assets are arranged toward an empty translucent AI conversation panel beside a glowing remarketing loop.

    OpenAI is exploring an advertising model, with early discussions involving media partnerships and ads that could appear within AI-generated responses. The work is still at a preliminary stage. There is no responsible basis yet for assuming a particular buying interface, targeting method, auction, reporting model, creative limit, or remarketing capability.

    You can still prepare for the distinctive part of the opportunity: the ad may meet a person while they are asking a detailed question, comparing options, or trying to complete a task. That is different from classic remarketing. Remarketing starts with a known prior interaction. An ad inside an AI response could start with the immediate context of a conversation, even when the person has never visited your site.

    High context does not automatically mean high purchase intent. A detailed question may be informational, exploratory, or commercial. Your preparation should therefore begin with the question and its decision stage, not with a generic assumption that every AI user is ready to buy.

    Create a question-to-offer record

    For each commercially relevant question cluster, record the user’s likely task, the direct answer they need, the condition under which your offer fits, the condition under which it does not, the evidence supporting your claim, the appropriate call to action, and the landing page that continues the answer. This becomes a reusable brief for paid AI placements, conventional search ads, landing-page copy, and answer-engine optimization.

    The disqualifying condition is important. An AI-mediated interaction can expose vague claims quickly because the surrounding answer may discuss alternatives and tradeoffs. Copy that states who an offer is for, what problem it solves, and where its limits begin is more useful than an unsupported superlative.

    Make the destination understandable to people and machines

    Keep brand, product, service, location, availability, eligibility, and offer details consistent across the ad candidate, visible page copy, and structured data where applicable. JSON-LD should describe what a visitor can verify on the page. Do not place stronger claims in schema than you are willing to show in the content.

    Use descriptive headings, direct answers, explicit entity names, accessible evidence, and a clear next action. Structured data can reduce ambiguity about page entities, but it does not guarantee an organic AI citation, a recommendation, or eligibility for a future paid placement. Treat it as accurate machine-readable context, not a shortcut around relevance or trust.

    Prepare modular creative instead of guessing the format

    Store each message as separate components: the user’s question, a concise answer, the commercial claim, its substantiation, a qualification, the call to action, and the destination. Once an actual ad format is documented, you can adapt those components to its limits. Writing to imagined character counts or unsupported placement rules now creates rework without making you more prepared.

    Plan for clear sponsorship rather than copy that imitates an impartial model response. Ads embedded near generated answers will depend heavily on user trust. A message should identify the commercial offer, preserve the distinction between paid placement and generated guidance, and avoid implying that the AI independently endorsed the advertiser.

    Connect future AI discovery to remarketing you control

    If a future AI ad sends a person to your site, treat that placement as an acquisition source, not as a replacement for your customer journey. The click should reach a question-specific page. A meaningful, consent-aware site interaction can then place the visitor into the appropriate first-party audience. Remarketing can continue the decision later if the audience qualifies and the follow-up remains relevant.

    Set up the handoff before the new channel arrives. Reserve a distinct source name for paid AI traffic, keep paid and organic AI referrals separate, define the on-site event that represents meaningful intent, document which remarketing audience receives that event, and suppress people after they complete the goal. Without that separation, you may attribute an organic AI visit to paid media, count the same conversion in conflicting reports, or keep advertising an action the customer already completed.

    Require answers before moving budget

    Do not divert dependable campaign budget merely because an AI company is discussing advertising. Wait until the inventory exists and you can answer practical buying questions:

    • Where can the ad appear, and how is it labeled to the user?
    • Which contextual, audience, geographic, and exclusion controls are actually available?
    • What event determines billing and optimization?
    • Can paid AI visits be identified reliably in your analytics?
    • Which conversion signals can be returned to the platform, and under what data terms?
    • What reporting distinguishes exposure, engagement, site visits, and conversions?
    • Which brand-safety, suitability, and placement controls protect you from appearing beside an inappropriate answer?

    Once those questions have documented answers, frame the first spend as an experiment with a hypothesis, audience context, message, destination, primary outcome, and cost limit. Judge it against your business economics and conversion quality. Do not treat novelty, impressions, or a high engagement rate as proof that the channel creates profitable demand.

    Your immediate move is smaller and more useful: choose the highest-intent audience that can clear 100 active users, write the objection its ad must resolve, and send people back to the exact page where they can continue. Then complete a question-to-offer record for the AI use case most closely tied to that decision. When AI inventory becomes buyable, you will have a relevant message, a truthful destination, and a measurement system ready for a controlled test.

    References

  • Google Maps in Demand Gen: A Practical Testing Guide

    Google Maps in Demand Gen: A Practical Testing Guide

    You have a new channel choice and a familiar campaign problem: should you add Google Maps to an existing Demand Gen campaign, or isolate it in a campaign of its own? The wrong structure may still spend money and record conversions. It just may not tell you whether Maps contributed anything useful.

    Google Maps can be selected in Demand Gen channel controls alongside other channels or used on its own. That gives you a cleaner way to build around location-dependent decisions, but the control is only valuable when the campaign starts with a precise question.

    Key takeaways

    • Use a Maps-only campaign when you need to learn whether Maps delivery can meet a defined business target.
    • Keep Maps with other Demand Gen channels when the same message and outcome work across contexts and placement-level certainty is secondary.
    • Treat Maps as a location-relevant context, not proof that every impression carries immediate local intent.
    • Match the ad, campaign geography, offer and destination page to the locations you can actually serve.
    • Do not confuse isolated Maps performance with incrementality. A Maps-only result shows what happened in that campaign, not what would have happened without it.

    Maps gives you placement control, not proof of intent

    The meaningful change is control over distribution. Maps joins Demand Gen channels such as YouTube, Discover and Gmail, and an advertiser can combine those environments or select Maps alone. That is useful because a location-dependent message does not always belong in every discovery context.

    What the setting does not do is turn every Maps impression into a high-intent local search. Placement, audience, intent and business outcome are different things. Selecting Maps controls the environment in which eligible ads can appear. It does not prove what a person wants, how urgently they want it or whether they are within a serviceable location.

    That distinction matters for businesses with branches, venues, service areas or in-person appointments. Maps may place the message closer to a location-oriented decision, including situations involving local exploration or navigation. You still need the campaign to qualify that opportunity through its geography, audience, message and destination.

    Before creating a Maps-only campaign, answer these questions:

    1. Does the value of the offer depend on where the person is, where the business operates or where the service can be fulfilled?
    2. Can the ad communicate a location-relevant reason to act without relying on vague proximity language?
    3. Can the destination page confirm the same location, availability, offer and next step?
    4. Do you need a Maps-specific decision, or do you simply want more Demand Gen distribution?

    If the first three answers are weak, Maps-only is unlikely to fix the campaign. If the fourth answer is simply broader distribution, combining Maps with other channels may be the more coherent structure.

    Choose the structure that answers your campaign question

    Two miniature campaign setups compare a mixed-channel container with a separate map-only container using matching budget and conversion tokens.

    A standalone Maps campaign and a multi-channel Demand Gen campaign solve different measurement problems. Neither is automatically better. The right choice depends on what you need to decide after the campaign runs.

    Decision factorMaps-only Demand GenMaps with other Demand Gen channels
    Primary questionCan Maps delivery meet our defined outcome, efficiency and quality requirements?Can the selected channel mix produce an acceptable overall business result?
    What becomes clearerDelivery and attributed results from a campaign restricted to MapsPerformance of the broader campaign strategy across selected environments
    What remains uncertainWhether Maps caused incremental outcomes that would not have occurred elsewhereHow much Maps contributed if reporting does not provide a sufficient channel breakdown
    Best fitA location-specific message, outcome or learning objective that requires its own decisionOne offer and conversion goal that make sense across Maps, YouTube, Discover or Gmail
    Common mistakeTreating a separate campaign comparison as a controlled causal testCrediting an aggregate campaign result to Maps without placement-level evidence

    Do not split the campaign merely because the control exists. A separate campaign divides budget and evidence into another decision unit. That can be worthwhile when Maps needs its own message, economics or evaluation. It adds little when the campaign would use the same assets, destination, audience and success criteria everywhere.

    Write the hypothesis before choosing the structure. A useful template is: For [defined audience and serviceable geography], Maps delivery using [location-relevant message] should produce [primary business outcome] within [economic ceiling] while meeting [quality requirement]. The brackets are planning prompts, not platform features.

    Each blank forces a decision. The primary outcome might be a qualified lead, completed booking, sale or another action the business values. The economic ceiling should come from the value and margin of that outcome. The quality requirement prevents cheap but unsuitable actions from looking successful.

    If your hypothesis explicitly names Maps, a Maps-only structure can produce a clearer diagnostic result. If it names only the overall business outcome and the message works across all selected channels, a combined campaign is usually closer to the question you actually care about.

    Build the message around a real local decision

    Maps creates a useful context, but it cannot rescue generic creative. A person considering a location-dependent option needs to understand what is available, where it is relevant and what to do next. Broad brand language makes that decision harder.

    Use this message order when planning the ad and its destination:

    1. Lead with the product, service or experience. Do not make the reader decode an abstract slogan before discovering what you offer.
    2. Add a verifiable local fact that affects the decision. That could be a branch, service area, collection option, venue or other genuine fulfillment detail.
    3. State one next action that the destination can complete, such as checking availability, booking, requesting a quote or viewing the relevant location.
    4. Continue the same promise after the click. The destination should confirm the offer, location and action rather than sending the person to a generic home page.

    A practical planning template is: [Offer] in [serviceable location]. [Verifiable differentiator]. [Next action]. Do not mistake those brackets for dynamic insertion. They are reminders to replace generic wording with facts your business can support.

    Be especially careful with words such as nearest, available, open or same-day. Those claims can influence an immediate local decision, so use them only when the operation and destination page can consistently support them. A Maps placement does not make an inaccurate availability claim safer.

    Campaign geography also needs deliberate attention. Selecting Maps as a channel is not a substitute for defining where the campaign should be eligible. Align geographic settings with branches, service boundaries, delivery coverage and any offer restrictions. Otherwise, the ad may attract interest from people whose location the business cannot serve.

    Review the entire path as one promise: ad, location context, landing page and fulfillment. If the ad names one area but the page defaults to another, or the page hides the local action behind a general navigation menu, the campaign has introduced friction at the moment location matters most.

    Measure Maps without overstating what the test proves

    A magnifying lens highlights one route from an unbranded neighborhood map to a storefront while other media pathways converge on a conversion marker.

    A Maps-only campaign isolates where the campaign can deliver. It does not create a perfect incrementality test. If it meets your target, you know that the campaign recorded acceptable outcomes while restricted to Maps. You do not yet know how many of those outcomes would have occurred through another ad, another channel or unpaid behavior.

    The same caution applies when comparing a Maps-only campaign with another campaign. Differences in budget, bidding, audience, geography, creative, offer or conversion definitions can explain part of the performance gap. Hold those elements consistent where the comparison requires consistency, and document every intentional exception.

    Build the measurement plan before launch:

    1. Choose one primary business outcome. Engagement metrics may help diagnose delivery, but they should not replace the action the campaign is meant to produce.
    2. Set the maximum acceptable cost for that outcome from your own economics. Also set a maximum test spend you can afford to lose before the campaign begins.
    3. Define a quality check. For lead generation, that could be whether leads meet the business’s qualification criteria. For bookings or sales, it could be completion, validity or another downstream status the business already records.
    4. Record the exact offer, audience, geography, conversion definition and evaluation period. This gives you a baseline against which later changes can be understood.
    5. Inspect the reporting available in your account before promising a channel-level analysis. Channel selection does not guarantee every Maps-specific segment, diagnostic or optimization control you may want.
    6. Write keep, change and stop rules in advance. This prevents a convenient secondary metric from becoming the success criterion after the primary result disappoints.

    A keep rule could require the campaign to meet both the economic ceiling and the quality floor. A change rule could apply when Maps receives meaningful delivery but the ad-to-page path shows a correctable mismatch. A stop rule should activate when spend reaches the preset loss limit without producing the business evidence required by the hypothesis.

    If a combined campaign does not expose enough Maps detail for the decision you need, a Maps-only campaign can provide a more isolated directional read. Label it accurately: it is a channel-restricted campaign result, not proof of causal lift.

    When the first test works, make the next change narrow. Extend the approach to another eligible location, offer or campaign context rather than switching every Demand Gen campaign at once. The aim is to discover where the Maps hypothesis transfers and where local conditions change the result.

    For your next campaign draft, write the hypothesis and decision rule before selecting the channel. If the question itself names Maps, isolate Maps. If the question is about the combined business result, keep the channels together and accept that placement-level certainty may be lower. That choice determines whether the campaign merely runs or gives you evidence you can use.

    References

  • Google Ads Automation: A Control Framework for Advertisers

    Google Ads Automation: A Control Framework for Advertisers

    Your Google Ads dashboard can report an efficient campaign while your sales team sees weak leads, your revenue stays flat, or your ads wander into queries you never meant to buy. That gap is where automation becomes expensive.

    You don’t regain control by trying to make every auction decision manually. You regain it by deciding what the system should optimize, where it may explore, what it must exclude, and which business evidence can overrule an attractive platform metric.

    Advertiser control has moved upstream

    Google increasingly treats campaign automation as a connected system. Broad match has been the default for new Search campaigns since July 2024, and it is designed to operate with conversion-based Smart Bidding rather than as an isolated keyword option.

    Broad match expands the set of queries for which an ad may be eligible. Smart Bidding then evaluates individual auctions using signals such as the device, location, time, query context, and user behavior. Google attributes a 10% improvement in broad-match campaigns using Smart Bidding to recent AI enhancements. Treat that as Google’s platform-level claim, not as a forecast for your account. Your result still depends on the goal, data, constraints, economics, and market conditions you supply.

    This changes what control looks like. A match-type selection cannot compensate for a shallow conversion goal. A bid strategy cannot know that a submitted form became an unqualified lead unless you return that information. An account-level CPA cannot tell you that one campaign is buying profitable demand while another is buying cheap activity.

    Control layerYour decisionEvidence to inspect
    OutcomeWhich actions and values should direct biddingQualified leads, completed sales, and revenue outside Google Ads
    IntentWhich query themes are relevant, marginal, or unacceptableSearch terms and downstream quality by theme
    AudienceWhich customer and remarketing signals provide useful contextQuality and value by audience segment
    BrandWhich brands must be included or excludedBrand, competitor, and generic-query overlap
    PolicyWhere a product, creative, or placement is eligibleCountry rules, creative audits, category controls, and placement reviews

    The interface still contains controls, but the most consequential ones now sit before and after the auction: conversion design before it, and business validation after it. If either side is missing, automated bidding can behave exactly as configured while producing the wrong commercial result.

    Fix the conversion signal before expanding reach

    An analyst calibrates a transparent filter that separates verified golden conversion signals from vague and duplicate inputs.

    The central risk with broad match is drift. A campaign may not collapse or produce obviously irrelevant traffic. It can gradually favor users who complete an easy action but rarely become customers. Reported CPA remains acceptable because the system is finding more of the conversion it was asked to find.

    Audit the goal in this order:

    1. Name the business outcome. Decide whether success means a qualified opportunity, completed purchase, recurring revenue, or another result with commercial value. Don’t start with whichever event is easiest to count.
    2. Separate outcomes from indicators. A form submission, call, download, or account creation can be useful evidence without deserving equal influence over bidding. If an event has weak purchase intent, don’t let its volume define campaign success.
    3. Return quality information. Import offline outcomes such as qualified leads, completed sales, or revenue when the buying journey continues outside Google Ads. If outcomes have materially different worth, use conversion values or quality tiers to preserve that distinction.
    4. Write down your acceptance conditions. Set the qualified-lead rate, revenue requirement, allowable acquisition cost, and prohibited intent themes your business will use to judge the campaign. These thresholds belong to your economics, so they should not be invented from an industry average.
    5. Broaden eligibility only after the feedback loop works. Choose a campaign with reliable tracking and enough meaningful conversion activity. If you cannot connect ad interactions to quality or revenue, broad match gives the system more places to spend without giving you better grounds for judging that spend.

    This audit prevents a common measurement error. A cheaper form is not necessarily a more efficient acquisition. If one query produces many low-quality submissions while another produces fewer profitable customers, lead volume and platform CPA can rank them in the wrong order. The deeper outcome must settle the decision.

    Do this work before changing bids, budgets, or match behavior. Otherwise, a campaign adjustment may amplify the measurement defect and make the dashboard look better at the same time.

    Constrain exploration at the query, audience, and brand levels

    Layered barriers guide selected luminous advertising paths while blocking irrelevant routes and protecting an abstract brand asset.

    Broad match is an exploration mechanism. Your job is to give that exploration an explicit perimeter. Build the perimeter at three levels rather than expecting one negative-keyword list to carry the entire account.

    Use negatives as account architecture

    Start with a shared account-level list for themes that are broadly incompatible with your offer. Depending on the business, examples may include jobs, free, or definition. Then add campaign-level exclusions for intent that is valid elsewhere in the account but wrong for that campaign.

    Review search terms frequently during the first month of a broad-match rollout. Classify each useful finding instead of merely excluding the individual query:

    • Relevant and valuable: leave room for the system to continue exploring the theme.
    • Relevant but commercially weak: check whether the landing page, offer, audience, or conversion signal is attracting the wrong stage of demand.
    • Structurally irrelevant: exclude the underlying theme at the level where it should never return.
    • Ambiguous: inspect downstream quality before deciding. A query that looks unusual may still represent useful long-tail demand.

    This classification matters because endless one-query cleanup is reactive. A structural negative defines a durable boundary the next round of exploration can respect.

    Use audiences as context and evidence

    Customer lists can help you examine behavior associated with known buyers. Remarketing lists can provide context for measured expansion. Audience insights can reveal whether new query reach is concentrated among segments that resemble valuable users or among segments that produce superficial conversions.

    If you use an audience in observation mode, treat it as diagnostic evidence. Compare downstream quality by segment rather than assuming the presence of an audience signal makes every matched query acceptable.

    Set brand boundaries deliberately

    Brand controls answer a different question from negative keywords. Brand inclusions can confine matching to queries involving specified brands. Brand exclusions can prevent unwanted matching to selected brand names. Use them when broad match begins crossing between brand, competitor, and generic intent in ways that undermine the campaign’s purpose.

    Don’t evaluate this overlap only by CPC or conversion volume. A competitor query may convert but attract a materially different buyer, while a broad generic query may introduce demand that later proves valuable. Your CRM, sales outcomes, or transaction data should determine which expansion deserves funding.

    When changing these controls, keep a dated account note that records the constraint, the reason for it, and the business measure you expect to change. Alter one major control layer at a time when practical. That gives you a better chance of knowing whether a shift came from the conversion goal, query boundary, audience context, or brand rule.

    Keep policy eligibility separate from performance automation

    Performance controls answer whether an auction is economically attractive. Policy controls answer whether the ad, product, market, buyer, and placement are permitted. A strong conversion model cannot make an ineligible ad safe, and a policy-eligible ad is not necessarily a good investment.

    The distinction becomes especially important in regulated categories. Beginning in January 2026, Google’s renamed Pharmaceutical products and services policy allows AdMob Authorized Buyers to advertise certain prescription drugs and services in eligible markets without the Google certification normally required in Google Ads.

    That permission is narrow. It applies to AdMob Authorized Buyers in particular countries; it is not a blanket relaxation for every Google Ads account, every pharmaceutical product, or every location. Clinical trials, miracle cures, illicit drugs, addiction services, crisis hotlines, and experimental treatments remain prohibited across Google Partner Inventory.

    If you buy regulated advertising

    Build a market-by-market approval record before allowing automation to pursue inventory. For each country, record the product or service, creative version, landing destination, targeting rule, prohibited themes, and person responsible for approval. Audit the actual creative and geography rather than treating account eligibility as proof that every impression is compliant.

    The absence of a Google certification requirement is not legal approval. Local law, contractual obligations, and the remaining platform restrictions still need qualified compliance review. If eligibility is uncertain, pause that market or creative instead of allowing automated delivery to test the boundary with live spend.

    If you publish AdMob inventory

    Review category blocking and ad controls before newly eligible demand reaches your apps. Decide whether pharmaceutical ads fit the audience, content, and brand-safety standard for each property. More permissible demand may increase auction competition, but it may also change the types of ads users see and the placements that require closer review.

    Non-pharmaceutical advertisers should watch the same change from an auction perspective. New demand can affect pricing and ad presence even when your own eligibility does not change. Separate those market effects from campaign deterioration before rewriting your bidding strategy.

    Key takeaways: run a control loop, not a one-time setup

    • Define the outcome: make qualified leads, sales, or revenue the evidence that settles performance decisions.
    • Feed quality back: use offline outcomes and differentiated values so bidding can distinguish convenient conversions from valuable ones.
    • Bound exploration: combine shared negatives, campaign exclusions, audience context, and brand controls.
    • Inspect the first month closely: review search terms frequently and turn recurring problems into structural constraints.
    • Validate outside the interface: judge expansion with CRM, sales, and transaction evidence, not CPC and CPA alone.
    • Govern policy separately: verify country, product, creative, buyer, and placement eligibility before automated delivery begins.

    Before your next expansion, create a one-page control record containing the bidding outcome, business acceptance thresholds, negative themes, audience inputs, brand rules, policy approvals, and review owner. Then change reach. Automation is easiest to govern when the rules of success are written before the spend moves.

    References

  • Paid Acquisition Control Plan: Targeting, Lift and Search Ads

    Paid Acquisition Control Plan: Targeting, Lift and Search Ads

    Your acquisition dashboard can look healthier while your decision quality gets worse. Reach outside a service area can swell activity, a modeled lift estimate can be mistaken for certainty, and extra App Store ad slots can tempt you to chase a position you cannot buy.

    These are three different control problems: audience eligibility, causal measurement, and auction relevance. You need to separate them before deciding where the next dollar goes. This control plan shows you how.

    Separate the three decisions hiding inside campaign performance

    Paid acquisition reviews often collapse targeting, measurement, and optimization into one question: did performance improve? That shortcut is dangerous because each layer can change the same dashboard metrics for a different reason.

    Decision layerPlatform changeWhat you should control
    Audience eligibilityGoogle Demand Gen now exposes an explicit choice between Presence or interest and Presence only.Define whether a person must be inside the market to have economic value before you select the setting.
    Causal evidenceGoogle is making Bayesian incrementality measurement available with budgets as low as $5,000.Judge the posterior probability, credible interval, assumptions, and business downside instead of treating test availability as proof.
    Available optimization leverApple plans to add in-line App Store search ads in 2026, but advertisers cannot select or buy those positions directly.Improve query-to-app relevance and creative alignment rather than optimizing toward an unavailable placement control.

    The order matters. Set the eligible population first. Then ask whether advertising caused an outcome. Only after that should you optimize the lever the platform actually exposes. Reversing the order can leave you spending money to correct the wrong layer.

    • Out-of-market Demand Gen traffic is primarily a boundary problem, not evidence that the creative failed.
    • A wide Bayesian credible interval is an evidence problem, not automatic proof that the channel failed.
    • An App Store ad that never becomes auction-eligible can be a relevance problem that a higher bid will not solve.

    Set the Demand Gen location boundary before reading performance

    Demand Gen can reach people across YouTube, Discover, and Gmail. A loose location definition can therefore spread through several environments before you notice it in an aggregate report.

    Use Presence only when the conversion depends on the person being in the target market. That usually applies to a local service area, a physical catchment, a market-specific offer, or fulfillment that cannot extend beyond named locations. Use Presence or interest only when someone outside the market can still become a valid customer. Planned travel and relocation are plausible examples. Preserving a larger reach estimate is not, by itself, a reason to choose the broader option.

    Run this sequence whenever you create, migrate, or audit a Demand Gen campaign:

    1. Write the eligibility rule first. Complete this sentence: We will pay to reach people who are in, or are interested in, these markets because the resulting conversion can be fulfilled in this way.
    2. Select the location option explicitly. Do not let a copied campaign, inherited setup, or old operating habit make the decision for you.
    3. Audit legacy exclusions. Presence only is now available natively, reducing the need for manual exclusion workarounds. Remove an old exclusion only after confirming that the native control makes it redundant.
    4. Record the change date and previous setting. A switch between Presence or interest and Presence only changes the population behind the metrics. Treat it as a break in the series, not as an ordinary bid or creative adjustment.
    5. Inspect location quality before aggregate efficiency. Confirm that impressions, clicks, and conversions are coming from markets your business can serve. Only then interpret campaign-wide cost and conversion metrics.

    This distinction matters because a cost-per-acquisition change can be caused by audience composition even when the ad, bid, and landing experience remain unchanged. Comparing the periods as if they were the same population can produce a false creative, bidding, or channel conclusion.

    Presence only should reduce geo-leakage and make regional performance easier to interpret. It does not prove incrementality, validate your list of target markets, or establish that every conversion can be fulfilled. Those remain separate business and measurement questions.

    Read a $5,000 Bayesian lift test as a decision, not a verdict

    Two transparent experiment chambers contain overlapping particle clouds beside budget tokens and a three-way decision lever.

    Lower-budget incrementality testing is useful because it gives more advertisers a way to ask a causal question: how many outcomes happened because of the advertising? It becomes dangerous when the budget figure is mistaken for a precision guarantee.

    Google’s approach uses informed priors, hierarchical modeling, and campaign history to extract useful evidence from less data. In Bayesian terms, the prior represents the belief before the test, the posterior updates that belief with observed data, and the credible interval describes a plausible range for the effect. As more relevant observations accumulate, the result should depend less on the prior and more on the test data.

    That is different from a conventional frequentist test built around a fixed sample, a p-value, and a binary statistical-significance decision. A p-value is not a Bayesian probability that the campaign worked, and a posterior probability is not the percentage lift. Mixing those interpretations can turn a technically valid output into a bad budget decision.

    Before launching a lift test, create a decision record with these fields:

    • Decision: the spend increase, reduction, continuation, or stop that the result could trigger.
    • Eligible population: the geography, audience, campaign set, and conversion outcome covered by the test.
    • Business hurdle: the smallest incremental effect that would justify the cost and operational risk.
    • Prior assumptions: whatever the platform exposes about the starting belief, historical inputs, or comparable campaign patterns. If these are not visible, record that limitation.
    • Posterior output: the probability attached to the outcome you care about, not merely a positive headline.
    • Credible interval: the plausible effect range, including whether economically unattractive outcomes remain credible.
    • Action and reversal condition: what you will do after the result and what later evidence would cause you to reverse it.

    Decide from the distribution, not the headline

    Start by separating direction from magnitude. A high probability that lift is positive can coexist with an effect too small to cover acquisition costs. Conversely, an uncertain estimate can still support a limited, reversible decision when the plausible downside is small and another test will add information.

    Next, inspect the full credible interval. If it spans both valuable and damaging outcomes, the honest conclusion is that the decision remains sensitive to uncertainty. Do not scale aggressively from the center estimate alone. Keep the change staged and use the next measurement period to narrow the range.

    Keep the result inside its tested boundary. Evidence from one geography, audience mix, campaign history, or conversion definition does not automatically transfer to another. This is especially important after changing Demand Gen location settings because you may no longer be measuring the same population.

    Finally, treat $5,000 as an access point for a modeled test, not a warranty that every campaign spending that amount will produce a narrow, decision-grade answer. Smaller tests can be useful precisely because Bayesian inference carries prior information forward. That same mechanism is why you need to examine the assumptions and uncertainty before committing more money.

    Prepare Apple Ads for a relevance gate you cannot outbid

    An unbranded smartphone projects content cards toward a gate that admits one matching card while mismatched cards and bidding tokens remain outside.

    Apple plans to place additional ads among organic App Store search results during 2026 while retaining the existing top-result ad. Advertisers will not need to opt into the new positions, and there is no placement selector that lets you buy a particular in-line slot.

    The practical constraint comes earlier in the process: an app must be relevant to the search to enter the auction. A larger bid cannot rescue an app that fails that gate. Bids can still matter among eligible candidates, but they are downstream of relevance.

    Build your campaign around a relevance chain rather than a placement wish list:

    1. Group keywords by user need. Do not combine terms merely because they share vocabulary. Two queries containing the same noun can imply different jobs, audiences, or expected features.
    2. Map each theme to an app capability. Write down the function that directly answers the search. If you cannot complete that connection without stretching the meaning, the theme is probably a poor acquisition target.
    3. Map the capability to product-page evidence. The app name, description, imagery, and surrounding product-page material should make the connection understandable without relying on the ad to explain everything.
    4. Prepare creative variations for distinct themes. Apple allows advertisers to align different creative treatments with audiences or keyword groups. Without custom creative, the ad can be generated from the app’s product page, making that page the default acquisition asset rather than an organic-only concern.
    5. Annotate the inventory change when it reaches your account. More impressions or attributed installs may reflect additional supply, stronger relevance, displaced organic discovery, or a mixture of those effects. Preserve the date so you do not mislabel the discontinuity as a campaign optimization win.

    Diagnose the funnel in sequence. If impressions expand but taps do not, inspect the query-to-creative relationship first. If taps expand but installs do not, inspect whether the promise and product page carry the same intent. If attributed installs expand, do not automatically call the difference incremental; additional ad inventory can redistribute existing demand as well as capture new demand.

    Apple has indicated that billing will remain per tap or per install, depending on the existing setup. That continuity does not make the economics static. Greater ad density can change impression availability, tap behavior, conversion quality, and the balance between paid and organic discovery.

    Do not create a performance target around owning an in-line position you cannot control. Track whether relevant searches produce qualified installs at acceptable economics. That is a lever you can manage through keyword selection, product-page alignment, creative variation, and bids among eligible candidates.

    Key takeaways

    • Choose Demand Gen Presence only when value depends on the person being inside the target market; use Presence or interest only when out-of-market interest can still produce a valid customer.
    • Treat a location-setting change as a population change. Annotate it and avoid presenting the before-and-after difference as a clean creative or bidding test.
    • Regard the $5,000 Bayesian test level as access to modeled evidence, not guaranteed certainty or a universal minimum for a reliable answer.
    • Read Bayesian results through the prior, posterior probability, credible interval, and your business hurdle. Probability of positive lift is not the size of the lift.
    • For Apple’s planned in-line App Store ads, relevance determines auction eligibility before bid size can influence the result.
    • Annotate new ad inventory and separate attributed growth from incremental growth before increasing spend.

    Before your next budget review, add three lines to every campaign brief: the eligible market, the evidence required to change spend, and the lever the platform actually lets you control. If the campaign owner cannot fill in all three, do not solve the uncertainty with a larger budget. Fix the boundary, the measurement rule, or the relevance chain first.

    References

  • How to Build an AI-Driven Paid Search Operating Model

    How to Build an AI-Driven Paid Search Operating Model

    You can automate nearly every visible part of paid search and still make the account worse. AI will produce more copy, audience ideas, campaign variants, and reports than your team can review. If the underlying intent signal is weak, that extra output simply scales waste.

    A useful AI-driven operating model does something more disciplined. It converts conversational intent into campaign decisions, accelerates controlled creative testing, aligns each promise with the destination page, and measures whether the resulting customers are actually worth more.

    Start with the decision behind the search

    A conventional search query often captures only a fragment of the buyer’s situation. A conversation can expose the goal, constraints, comparison criteria, objections, and urgency surrounding that query. Conversational search can also create multiple relevant advertising opportunities from a detailed exchange as the user’s needs become clearer.

    Do not respond by treating entire conversations as a larger keyword list. Convert the context into an intent record your campaign team can use:

    • Situation: What is happening in the buyer’s world?
    • Desired outcome: What are they trying to accomplish?
    • Constraints: Which limits involve budget, timing, compatibility, location, policy, or skill?
    • Decision state: Are they exploring, comparing, validating, or ready to act?
    • Objection: What could prevent the next step?
    • Required proof: Do they need specifications, pricing, evidence, credentials, availability, or reassurance?
    • Next useful action: Which conversion would genuinely help them progress?

    Suppose a prospective student searches for an online master’s degree. That phrase gives you a category. A fuller interaction might reveal that the person works full time, needs a recognized credential, is comparing total cost, and cannot attend daytime classes. Those details should change the ad message, landing-page evidence, audience treatment, and conversion action. Repeating the broad phrase more often will not do that.

    Organize campaigns around the decision state as well as the topic. Exploratory demand needs orientation. Comparison demand needs explicit differences and trade-offs. Validation demand needs proof. Action-ready demand needs a clear offer and minimal friction. The journey will not always be linear, but these distinctions stop you from serving the same generic promise to everyone.

    Begin with search terms that converted, consumed spend without producing qualified outcomes, or repeatedly triggered exclusions. Rewrite each meaningful cluster as an intent record. If you cannot identify the likely decision, constraint, and next action, the cluster is still too vague for AI-generated personalization.

    Build a controlled path from AI insight to campaign

    Abstract conversational signals move through a series of human-controlled review gates before becoming organized campaign components and matching destination pages.

    The safest workflow gives AI a narrow responsibility at each stage. It also preserves a reviewable record of why an audience, message, or destination was chosen.

    1. Define the business outcome. Name the event that creates value: a completed sale, qualified lead, accepted application, booked consultation, or another verified result. Do this before generating assets.
    2. Assemble the permitted context. Supply the offer, landing-page copy, approved claims, exclusions, brand rules, past campaign outcomes, and known audience questions. Remove personally identifying information and use only data you are authorized to process.
    3. Classify demand by decision logic. Ask AI to group queries or themes by situation, desired outcome, constraint, objection, and decision state. Require it to flag ambiguity instead of forcing every input into a confident category.
    4. Turn each intent group into a campaign brief. Specify the audience problem, promise, proof, prohibited claims, destination, conversion action, and measurement rule.
    5. Generate bounded variations. Let AI vary a defined element such as the benefit, proof point, call to action, visual treatment, or voice. Do not ask it to redesign the audience, offer, message, and destination simultaneously.
    6. Validate the destination. Confirm that the landing page visibly supports the ad’s promise and that its structured data accurately describes the same entities, offer details, and attributes.
    7. Launch with a budget ceiling and rollback condition. Record the baseline, approved spend limit, primary outcome, diagnostic metrics, and the condition that will pause or reverse the change.

    A reusable generation brief can stay compact: Audience situation: [context]. Decision state: [state]. Promise: [approved benefit]. Proof: [page-supported evidence]. Variable to test: [single element]. Prohibited claims: [limits]. Destination: [matching page]. Primary outcome: [qualified business event].

    Structured data belongs in this workflow, but it is not advertising code and cannot rescue a weak offer. Its role is to make the page’s meaning more explicit. The visible page, markup, ad, and conversion action should describe the same thing. If eligibility, availability, or a limitation matters to the decision, put it in the visible content rather than hiding it only in markup.

    Use the same intent labels across paid search, paid social, creative production, landing pages, and reporting. Shared labels let you see whether a message works because it addresses a particular decision or merely because one channel received cheaper traffic.

    Use generative AI to multiply tests, not brand risk

    An AI system generates many abstract creative variants while a human reviewer filters them before selected versions proceed to matching landing pages.

    Generative tools can shorten the path from a script to storyboards, creative variations, voiceovers, and localized executions. They can also help maintain tone and pacing across repeated production work. That is production leverage, not evidence that the resulting creative will persuade anyone.

    The common failure is to generate many variations without giving each variation a job. The account receives more ads, but the team learns less because several elements changed together. A disciplined test should follow these rules:

    • Ask one commercial question at a time, such as whether proof-led copy produces more qualified actions than convenience-led copy.
    • Keep the offer, audience definition, destination, and conversion action fixed unless one of them is the stated variable.
    • Generate within approved claims and brand rules. Require human review for prices, guarantees, comparisons, regulated language, eligibility, and culturally sensitive material.
    • Name every asset by intent group, hypothesis, variable, and version so the result can be traced to the brief that created it.
    • Use engagement as a diagnostic signal, not the final verdict. A stronger click-through rate with weaker lead quality is not a win.
    • Record what the result changes. If either outcome would lead to the same campaign decision, the test is not answering a useful question.

    Write a test brief that another person can audit

    Before production, document the hypothesis, target intent, fixed elements, test variable, primary business outcome, secondary diagnostics, observation window, exclusions, and decision rule. The observation window and decision rule should reflect your normal conversion lag and traffic volume; choosing them after seeing performance invites a convenient interpretation.

    AI-assisted analytics can connect creative features with engagement patterns quickly, but correlation does not establish which feature caused the result. Use those patterns to form the next controlled test. Do not let a dashboard turn visual coincidence into a budget decision.

    Personalization also has a boundary. When targeting Gen Z, utility and authenticity are especially important. Personalize around the need the person expressed, not around a surprising personal detail inferred from unrelated behavior. An ad can be technically relevant and still feel invasive.

    Measure whether AI improves the unit economics

    Microsoft has reported a thirteen-fold increase in return on ad spend when people interacted with Copilot before searching. Treat that as a platform-reported signal, not a forecast for your account. A plausible explanation is that a person who has already clarified a need through conversation reaches search with stronger intent. That cohort may be fundamentally different from someone entering an unassisted, ambiguous query.

    Test the mechanism inside your own account. Keep the conversion definition, attribution setting, promotion, geographic scope, and brand versus non-brand treatment comparable. Separate conversationally informed demand from the existing baseline when the platform and campaign setup allow it. Otherwise, an apparent AI lift may simply reflect a different audience mix.

    Add internal measures that expose quality and waste. The names matter less than consistent definitions:

    MeasureHow to define itWhat to noticeWhat to do next
    Revenue ROASAttributed revenue divided by ad spendRevenue can look healthy while margin or customer quality deterioratesPair it with a profit or quality measure
    Qualified conversion rateConversions meeting the business qualification divided by total recorded conversionsRising conversion volume with falling qualification means the system is optimizing toward an easy eventReturn verified quality data to campaign reporting where possible
    Search-term waste rateSpend assigned to irrelevant or ineligible query themes divided by search spendA high rate reveals weak intent classification, exclusions, or match controlRefine intent groups and negative themes before expanding reach
    Intent-to-page completionCompletion of the intended action for each intent group and destinationStrong ad engagement with weak completion often signals a promise-to-page mismatchCorrect the destination or narrow the ad promise
    Creative learning yieldCompleted tests that produced a clear campaign decision divided by completed testsMany inconclusive tests indicate uncontrolled variation or weak hypothesesReduce simultaneous changes and sharpen the decision rule

    Automation can spend against the wrong objective quickly. Preserve account-native budget controls, exclusions, approval steps, and an accessible previous version. Do not shift substantial budget merely because AI-assisted creative generated more impressions, clicks, or engagement. Move it when the agreed business outcome improves without unacceptable deterioration in quality, margin, or waste.

    Key takeaways

    • Conversational demand is valuable because it reveals the decision context around a query, not because it gives you longer keywords.
    • Translate that context into intent records containing the situation, outcome, constraints, decision state, objection, proof, and next action.
    • Give AI bounded production tasks and preserve human approval for claims, eligibility, pricing, cultural adaptation, and brand judgment.
    • Change a defined creative element at a time so each test can produce a usable decision.
    • Keep ads, landing-page content, structured data, and conversion actions aligned around the same promise.
    • Evaluate qualified outcomes, waste, profit, and learning quality rather than counting how much content the system produced.
    • Treat platform-reported performance lifts as hypotheses to validate under your own audience mix, attribution settings, and business economics.

    Your next move should be narrow. Choose a high-spend, high-ambiguity query theme, turn it into a clear intent record, build an aligned ad and destination, and compare it with the existing treatment under the same outcome definition and budget controls. Expand to the next intent cluster only when the first change produces better customers, not merely more activity.

    References

  • Social and Commerce Ad Tools: A Practical Selection Guide

    You do not need another ad account. You need to know which part of the buying journey is failing: discovery, relevance, confidence, or checkout. Choose a tool before answering that question and you can buy plenty of activity without removing the constraint that is costing you sales.

    The useful decision is not whether Instagram, LinkedIn, YouTube, Pinterest, or Shopify is the best platform. It is which platform capability can perform one defined job for your audience, then hand that person to the next step without changing the subject.

    Choose the bottleneck before you choose the tool

    Start with the moment immediately before the result you want. If buyers never encounter your category, you have a discovery problem. If they see you but assume the offer is not for them, you have a relevance problem. If interested visitors do not trust the promise, you have a confidence problem. If they want the product but cannot find or buy the right item, you have a transaction problem.

    Those problems call for different tools. A high-attention video placement will not repair an incomplete product path. Dynamic personalization will not create demand for a category buyers do not understand. A commerce network can expose an item at a useful moment, but it cannot compensate for an offer that becomes confusing as soon as the shopper reaches the product page.

    • For discovery: use a visual or short-form surface capable of introducing the problem, category, or use case before the buyer searches for it.
    • For relevance: change the message for a meaningful audience characteristic, such as role, company, need, or viewing context.
    • For confidence: connect the ad to evidence that resolves the buyer’s next objection, not to a generic homepage.
    • For transactions: place the right product where demand already exists and reduce the distance between selection and purchase.

    Write a one-sentence campaign brief before opening a platform: “For this audience, this placement will remove this bottleneck, and we will judge it by this outcome.” If you cannot complete every part without using words such as “engagement” or “awareness” as a substitute for a business result, the campaign is not ready.

    Match each platform capability to a buying moment

    Several newer capabilities blur the boundary between social advertising, creator marketing, recommendation systems, and onsite merchandising. That does not make them interchangeable. It makes their assigned job more important.

    Buying momentUseful capabilityWhat it can changeWhat you should do
    A person is exploring an interestInstagram Reels and user-controlled topic preferencesInstagram’s Your Algorithm controls let people request more or less of a topic and add preferences. This is a user control, not an advertiser setting.Build each Reel around a recognizable subject and use case. Do not treat audience targeting as permission to make the creative vague.
    A B2B buyer is not yet searchingLinkedIn Reserved Ads, profile-based personalization, and AI creative variantsReserved placements are designed to make impressions more predictable, while personalization can use fields such as first name, job title, and company. AI Ad Variants can produce additional on-brand versions from one input.Use reserved delivery when reach predictability matters. Personalize the reason to care, then test it against a non-personalized control.
    A viewer encounters a creator recommendationYouTube Shorts comments and creator link-outsEligible Shorts ads can allow comments, and branded creator content can link to a brand website. Shorts placement has also expanded to mobile web.Send the viewer to the exact product, offer, or explanation shown in the Short. Assign someone to review comments for questions and objections.
    A shopper has a product need that one store cannot satisfyShopify Product NetworkContextually relevant products from other merchants can appear across participating stores, including in search results and on homepages. Cross-merchant items can enter a single cart, while referring merchants can earn cash commissions or ad credits.Assume your product may be evaluated outside your own storefront. Make the title, image, category, offer, and product-page promise understandable without your usual brand context.
    A person is collecting ideas and possible solutionsPinterest advertisingPinterest’s formats serve a platform built around inspiration and solution discovery.Choose the format from the campaign objective. The creative should show the desired outcome while the destination explains how to achieve or buy it.

    The sequence matters. Social discovery surfaces are useful when someone needs to notice or understand an option. Commerce placement becomes more useful when the need is already legible and product selection is the remaining task. In B2B, predictable feed exposure can establish familiarity before a self-directed buyer begins comparing providers.

    You can use more than one surface in the same journey, but do not assign all of them the same conversion target. A discovery placement should earn the next qualified action. A product placement should make the transaction easier. When every channel is judged as if it closed the sale alone, early-stage tools get cut too quickly and late-stage tools receive credit for demand they did not create.

    Build one continuous handoff from ad to answer

    The most common structural mistake is a message break. The ad speaks to one audience and problem; the destination opens with a broad corporate statement. The creative shows a specific item; the click leads to a collection page. The creator answers a practical question; the linked page makes the visitor reconstruct the answer from navigation and promotional copy.

    Build the handoff in this order:

    1. Name the entry context. Record what the person was watching, browsing, searching for, or trying to buy when the placement appeared.
    2. Make one promise. The ad should communicate one useful outcome or answer one immediate question. Additional benefits belong after the click.
    3. Continue that promise on the destination. Repeat the same product, category, audience, and use case near the start of the page. Do not make the visitor verify that the click worked.
    4. Expose the supporting facts. Put specifications, eligibility, limitations, proof, price conditions, availability, or process details where they can be evaluated before the primary action.
    5. Ask for the next proportionate action. A person discovering a new category may need an explanation or comparison. A shopper selecting a known item may be ready to add it to a cart. Do not force both into the same path.

    Apply personalization only where it changes meaning. Inserting a first name may attract attention, but it does not explain relevance. A job title can be useful if the problem, evidence, or next step genuinely differs by role. A company name is useful only when the surrounding sentence remains accurate and natural. Test the personalized version against a plain version so novelty is not mistaken for qualified interest.

    AI-generated ad variants need the same discipline. Give the system a fixed product identity, approved claims, audience, prohibited claims, call to action, and destination. Review every version that could change a price, capability, condition, or comparison. Producing more creative is valuable only when the variants test distinct ideas; dozens of cosmetic rewrites create volume without creating a useful experiment.

    Instagram’s preference controls create a particularly important distinction. People can influence the topics they receive, but a brand cannot command a place in those preferences. The practical response is topical clarity: make the subject, audience, and use case recognizable without relying on a clever opening that conceals what the content is about.

    YouTube comments can turn an ad into an objection log. Decide before launch who will review questions, what requires a response, and which recurring objections should be answered on the destination page. If comments repeatedly ask whether an offer works for a certain use case, the page should not leave that answer buried in a reply thread.

    Shopify’s cross-merchant model creates the opposite challenge: your product may appear in a storefront the shopper did not associate with your brand. Evaluate the product card and landing page as a self-contained unit. A title that only makes sense beside the rest of your catalog, or an image that depends on brand familiarity, will be fragile in a contextual network.

    This continuity also matters for SEO, answer-engine optimization, and generative-engine visibility. Advertising does not make a page authoritative or guarantee that an AI system will cite it. It can, however, reveal the words people use, the objections they raise, and the contexts in which a product becomes relevant. Use those observations to improve the public page a search engine or AI system can access.

    Keep machine-readable information aligned with the visible destination. If a page uses Product or Offer structured data, its product name, brand, identifier, availability, currency, price conditions, and offer details should not contradict the page or the ad. Structured data is a clarification layer, not a place to repair an unclear or inconsistent offer.

    Measure the constraint the tool was selected to remove

    A campaign should produce a decision even when it does not produce a win. That requires a primary metric tied to the assigned job and a diagnostic metric that explains what happened next.

    • For predictable reach: compare planned and delivered impressions for the defined audience, then inspect whether that exposure led to qualified visits or later branded activity. Delivery proves the placement ran; it does not prove that the message landed.
    • For personalization: compare personalized and non-personalized creative against the same downstream outcome. Click-through rate alone can reward curiosity. Qualified leads, useful page actions, or completed buying steps tell you whether relevance improved.
    • For creator and interactive video: separate viewing, commenting, outbound traffic, and downstream action. Read comments by theme rather than treating their count as approval. Questions, objections, confusion, and purchase intent require different responses.
    • For commerce placement: measure orders and acquisition cost, then account for the commission or credit economics attached to the network. A sale is not automatically a profitable sale, and a referring placement may have value even when the referring merchant did not supply the product.
    • For discovery: look for movement from exposure to an intentional next step, such as a relevant page visit, product exploration, or another action your analytics can observe. Do not present social engagement as evidence that AI search visibility improved.

    Use one controlled comparison at a time. If you change the audience, format, message, offer, and destination together, the result cannot tell you which decision helped. Start with the largest uncertainty: audience-message fit, creative angle, personalization, or destination handoff. Hold the other elements steady long enough to learn from that question.

    Set a spending cap you can afford before the test begins. Paid systems can optimize toward the event you provide, including an event that is easier to generate but less valuable than the business result. Confirm that the selected conversion represents a real step in the buying process, then examine the leads or orders behind the aggregate number.

    Keep platform status separate from campaign performance. LinkedIn’s Flexible Ad Creation was slated for early 2026, while Instagram described broader expansion of its preference controls beyond Reels. Availability can differ by account, placement, and market, so verify the feature inside the account before making it a dependency in your launch plan.

    Key takeaways

    • Choose the buying bottleneck first: discovery, relevance, confidence, or transaction.
    • Give each platform one accountable job instead of asking every placement to close the sale.
    • Treat Instagram preference controls as user agency, not as an additional advertiser-targeting switch.
    • Use LinkedIn personalization to change the reason to care, not merely to insert a person’s profile data.
    • Connect Shorts and creator placements to the exact answer, product, or offer shown in the video.
    • Prepare commerce listings to make sense outside your own storefront and brand context.
    • Use advertising feedback to improve public content, but do not claim that paid engagement causes SEO, AEO, or generative-engine visibility.

    Before your next launch, put six lines on one page: audience, bottleneck, platform capability, message, destination, and primary outcome. Add an affordable test cap and one controlled comparison. If the campaign cannot be explained on that page, adding another tool will make the uncertainty more expensive, not more manageable.

    References