Tag: Audience Research

  • How to Humanize LLM-Assisted Content With Better Research

    How to Humanize LLM-Assisted Content With Better Research

    You have an LLM draft that is clean, complete, and strangely forgettable. Changing a few phrases, adding contractions, or asking the model to sound more human will not fix it. The draft feels generic because it has had no meaningful contact with the customers, experts, and market conditions it claims to understand.

    Humanizing LLM-assisted content is a research problem before it is a writing problem. Give the model grounded evidence to organize, keep human judgment in charge of what matters, and make every important claim traceable. You will get content that is more useful because it contains real distinctions, not because it performs a more casual personality.

    Human content starts with evidence, not tone

    A model can imitate a conversational register. It cannot create genuine customer evidence, expert experience, or market context that you did not provide. If the input consists of a keyword, a title, and competing search results, the output will usually recombine the same category-level ideas available to everyone else.

    The useful advantage of an LLM is its ability to process large collections of feedback and surface recurring patterns. That makes it a capable research assistant, but it does not transfer editorial responsibility to the model.

    Separate the work into three roles:

    • Evidence: Customers, subject matter experts, product records, search queries, reviews, and other observable material supply the facts and language.
    • Analysis: The LLM groups related observations, identifies contrasts, proposes questions, and helps you inspect a large body of material.
    • Judgment: A person decides which patterns are meaningful, which claims are sufficiently supported, what exceptions matter, and what the reader should do.

    This separation prevents a common failure: letting polished prose disguise a weak evidence base. A confident paragraph is not proof that the underlying pattern is real.

    Before drafting, build a compact evidence brief. For each potential section, record the reader question, the proposed answer, the supporting material, any contradiction, and the action the reader can take. If a proposed answer has no supporting material, label it as a gap. Do not ask the model to fill that gap with a plausible anecdote.

    Keep provenance attached to the material as it moves through the workflow. A customer comment should retain an anonymous record identifier. An expert claim should point back to the approved interview transcript. A competitor observation should retain the page, review, or posting that supports it. Provenance makes verification possible after the model has compressed many inputs into a neat theme.

    Build an auditable customer-language pipeline
    Two researchers trace color-coded evidence cards back to customer interview recordings, photographs, and product samples on an organized table.

    Customer feedback is where generic content often becomes specific. NPS responses, sales-call transcripts, support questions, Google Search Console queries, and on-site searches expose the words people use before your marketing language has shaped the conversation. Heatmaps and interaction data can help you locate friction, while qualitative comments can explain what the friction means to the person encountering it.

    Do not begin by dropping an unstructured archive into a chat and requesting insights. The resulting summary may look convincing, but it gives you little visibility into omitted records, faulty groupings, or unsupported counts. A more inspectable workflow involves using an LLM to generate SQL, running the queries separately, and supplying the query results for synthesis.

    1. Normalize the raw material. Store one response or interaction per record. Preserve the original wording and add only fields you can verify, such as channel, product area, or an anonymous record identifier.
    2. Define the question before querying. Ask something narrow enough to test, such as which objections appear in feedback about a specific feature, or which questions occur before a purchase decision.
    3. Use the LLM to draft the query. Supply the actual table and column names, describe the expected output, and instruct it not to invent fields. Treat the generated SQL as code that requires review.
    4. Run and validate the query outside the model. Inspect filters, joins, null handling, duplicated records, and representative rows. Compare the result with a small set you have already read.
    5. Give the verified result to the LLM. Ask it to group related responses, preserve contrary evidence, and attach anonymous record identifiers to every proposed theme.
    6. Iterate on the question. A broad theme such as ease of use is not yet an insight. Query the situations, tasks, and points of confusion hidden inside that label.

    A practical analysis prompt is: Group these verified records by the job the customer is trying to complete. For each theme, provide supporting record identifiers, conflicting records, the customer terms that recur, and one question we still cannot answer. Do not infer a motive unless the wording supports it.

    The instruction to preserve conflicting records matters. A model is naturally useful at compression, but compression can erase minority experiences and conditions that complicate the dominant theme. Those complications are often what make a page trustworthy. They let you say when advice works, when it does not, and who should choose a different path.

    Handle sensitive material before it reaches any LLM. Remove personal identifiers and confidential details, and use only tools and storage environments approved for the data involved. If you cannot confirm that a dataset may be processed in a particular system, work with a redacted extract or keep the analysis inside an approved environment.

    Your final customer-language output should not be a cloud of themes. Build a theme ledger containing the customer problem, the situation in which it occurs, the language customers use, supporting record identifiers, contradictions, and the content decision that follows. That final field forces analysis to become useful editorial direction.

    Interview experts without asking them to write the page
    A content strategist records an expert explaining and demonstrating a component at a workshop bench while a teammate documents the process.

    Subject matter experts are usually needed because the obvious answer is incomplete. They know the mechanism, the exception, the tradeoff, and the mistake that only becomes visible in practice. Asking them to write a polished explanation creates unnecessary work and often delays the content.

    Use an LLM as the interviewer, not as a substitute for the expert. A reusable interviewer can be configured around a clear role, context, interview structure, pacing, and closing summary. The expert can answer in fragments or plain language while the system handles follow-up questions and organization.

    Give the interviewer these instructions:

    • Role: Act as a curious editor who understands the product context but does not pretend to know the expert’s answer.
    • Objective: State what the final content must help the reader understand or decide.
    • Scope: Name the product, feature, service, or decision being discussed and list topics that are out of scope.
    • Pacing: Ask one question at a time. Follow an answer before moving to the next prepared topic.
    • Evidence discipline: Request concrete mechanisms, conditions, and examples, but never create an example on the expert’s behalf.
    • Closing: Summarize the claims, unresolved questions, and statements that require verification or approval.

    Do not open with an invitation to explain everything about the subject. Start with the decision the reader faces, then move down an interview ladder:

    1. What does the reader usually misunderstand at this point?
    2. What actually happens, and what causes it?
    3. Which conditions change the answer?
    4. What is the most common avoidable mistake?
    5. What tradeoff should the reader understand before choosing?
    6. What would you need to see before recommending a different approach?

    Each answer should shape the next question. If the expert says a result depends on implementation quality, the interviewer should ask what quality means in observable terms. If the expert describes a common mistake, it should ask why people make it and how a reader can notice it early. This is where an interview produces material that a generic drafting prompt cannot.

    After the interview, ask the LLM to create a claim sheet rather than a finished draft. Each row or bullet should include the claim, supporting transcript passage, relevant condition, uncertainty, and verification status. Send that condensed sheet to the expert for correction. Approval of a short claim sheet is a clearer request than approval of a long page in which factual and stylistic decisions have already been mixed together.

    Only then should the transcript feed the drafting process. Instruct the model to distinguish direct expert knowledge from editorial inference. If the expert did not provide a metric, example, or causal explanation, the draft must not manufacture one to make the section feel complete.

    Use competitor research to find the missing angle

    Competitor research is useful when it reveals the boundaries of the category conversation. It becomes destructive when it is used as a template for another version of the same page.

    Different public signals answer different questions. Reviews, changing web copy, job postings, and social engagement can expose customer frustrations, positioning choices, strategic priorities, and unmet demand. None of these signals should be treated as conclusive on its own.

    • Reviews: Extract repeated benefits, complaints, desired outcomes, and the circumstances behind unusually positive or negative experiences. Keep verified wording separate from your interpretation.
    • Current web copy: Record the audience being addressed, the promised outcome, the proof offered, and the tradeoffs left unmentioned.
    • Archived web copy: Use the Wayback Machine to notice how positioning and emphasis have changed. Treat the change as an observation, not proof of why the business made it.
    • Job postings: Note capabilities the company appears to be building. A posting may indicate an area of attention, but it does not prove that a strategy or product has shipped.
    • Social engagement: Read the comments and questions behind the engagement count. Activity alone does not tell you whether people are satisfied, confused, or objecting.

    Create a competitor evidence matrix with the same fields for every company: target audience, main claim, supporting proof, repeated customer concern, unanswered question, and evidence location. Consistent fields make cross-company patterns easier to inspect and reduce the chance that a vivid example dominates the analysis.

    Then ask the LLM: Compare these records without ranking the companies. Separate extracted evidence from inference. Identify claims repeated across the category, customer questions no company answers clearly, benefits with weak visible proof, and differences that may reflect distinct target audiences. Mark unknowns instead of resolving them.

    The output is not your content plan yet. Test each proposed gap against customer feedback and expert knowledge. A topic is not valuable merely because competitors have ignored it. It becomes a defensible angle when customers care about it, an expert can explain it, and your evidence supports an answer.

    Look for four kinds of useful angles: a customer question the category avoids, a tradeoff hidden behind a popular benefit, an exception that changes the standard recommendation, or a difference in audience that makes apparently conflicting advice both reasonable. These angles humanize content because they reflect actual decisions and tensions. They do not depend on decorative storytelling.

    Draft, verify, and edit for a recognizable point of view

    Once the evidence is organized, drafting becomes a constrained synthesis task. The model should transform approved material into a useful sequence without silently upgrading an observation into a fact or an inference into a customer quote.

    1. Define one reader and one decision. State what the reader is trying to do, what is blocking them, and what they should be able to decide after reading.
    2. Build an evidence outline. Give each section a question, direct answer, evidence identifiers, important exception, and practical next action.
    3. Draft only from the evidence pack. Permit ordinary transitions and explanation, but prohibit invented customers, quotations, tests, metrics, and firsthand experience.
    4. Expose missing support. Require a visible placeholder whenever the outline asks for a claim the supplied material cannot establish.
    5. Verify before polishing. Check every material claim against the raw record, transcript, query result, or competitor evidence location.
    6. Edit for judgment. Decide which point deserves emphasis, which caveat belongs beside the claim, and which recommendation follows from the evidence.

    An evidence-bound drafting prompt can be simple: Write for the defined reader using only the supplied evidence pack. Each section must answer its question directly, explain the mechanism or reason, preserve the stated conditions, and end with an action the reader can take. Keep evidence identifiers in the draft for review. If support is missing, insert [EVIDENCE GAP]. Do not invent a quote, metric, customer, test, or example.

    Run a humanization pass that can fail the draft

    Do not judge the result by asking whether it sounds human. Use tests with observable failure conditions:

    • The substitution test: Could a competitor publish the section unchanged? If so, add a supported distinction or remove the generic section.
    • The provenance test: Can an editor reach the underlying evidence for every consequential claim? If not, qualify, verify, or delete the claim.
    • The contradiction test: Does the draft preserve evidence that complicates the dominant pattern? If not, restore the relevant condition or exception.
    • The customer-language test: Does the page use the terms customers use for their problem while explaining any necessary technical vocabulary? If not, return to the feedback records.
    • The expert-value test: Does the page contain a mechanism, tradeoff, or boundary condition that required genuine expertise? If not, the interview stayed too shallow.
    • The action test: After each section, can the reader do, decide, or notice something specific? If not, the section is probably commentary rather than guidance.

    Remove evidence identifiers only after verification. Then tighten repetition, vary sentence length where it improves clarity, and replace internal terminology with reader language. Do not add fake quirks, staged vulnerability, or imaginary personal stories. A recognizable editorial voice comes from consistent judgment: what you prioritize, what you refuse to overclaim, and how clearly you explain the tradeoff.

    This also supports SEO, AEO, and GEO work without turning the page into machine-facing copy. Put the direct answer near the question, use descriptive headings, name entities precisely, keep qualifications beside the claims they limit, and cite the evidence that carries the factual load. Structured data can describe visible content, but it cannot supply the missing expertise or originality. No formatting choice guarantees search or LLM visibility.

    Key takeaways

    • Humanize the evidence before polishing the prose: use real customer language, expert judgment, and observable market signals.
    • Keep raw data and query execution outside the LLM when you need inspectable counts, filters, and records.
    • Use an LLM to interview experts and organize their answers, never to impersonate their knowledge.
    • Treat competitor material as evidence of category patterns and unanswered questions, not as a draft template.
    • Require provenance, contradictions, conditions, and evidence-gap labels throughout synthesis.
    • Reject any section that a competitor could publish unchanged or that leaves the reader without a concrete next action.

    Take the next generic draft you planned to polish and pause it. Build an evidence brief for its most important claim, verify that material, and rewrite only that section. The difference will show you where research deserves more of the workflow than prompting does.
    References

  • Landing Page Conversion Mistakes and How to Fix Them

    Landing Page Conversion Mistakes and How to Fix Them

    When a landing page attracts visits but not leads or sales, do not start by changing the button color. First locate the point where the visitor’s decision breaks: the traffic promise, the offer, the evidence, the action, or the measurement.

    Traffic and conversion are separate outcomes. More visits can expose a weak page without making it more persuasive, which is why high traffic does not guarantee conversions. The audit below helps you diagnose the actual failure, make the smallest useful correction, and verify whether it improved the business result.

    Fix the gap between the traffic promise and the page

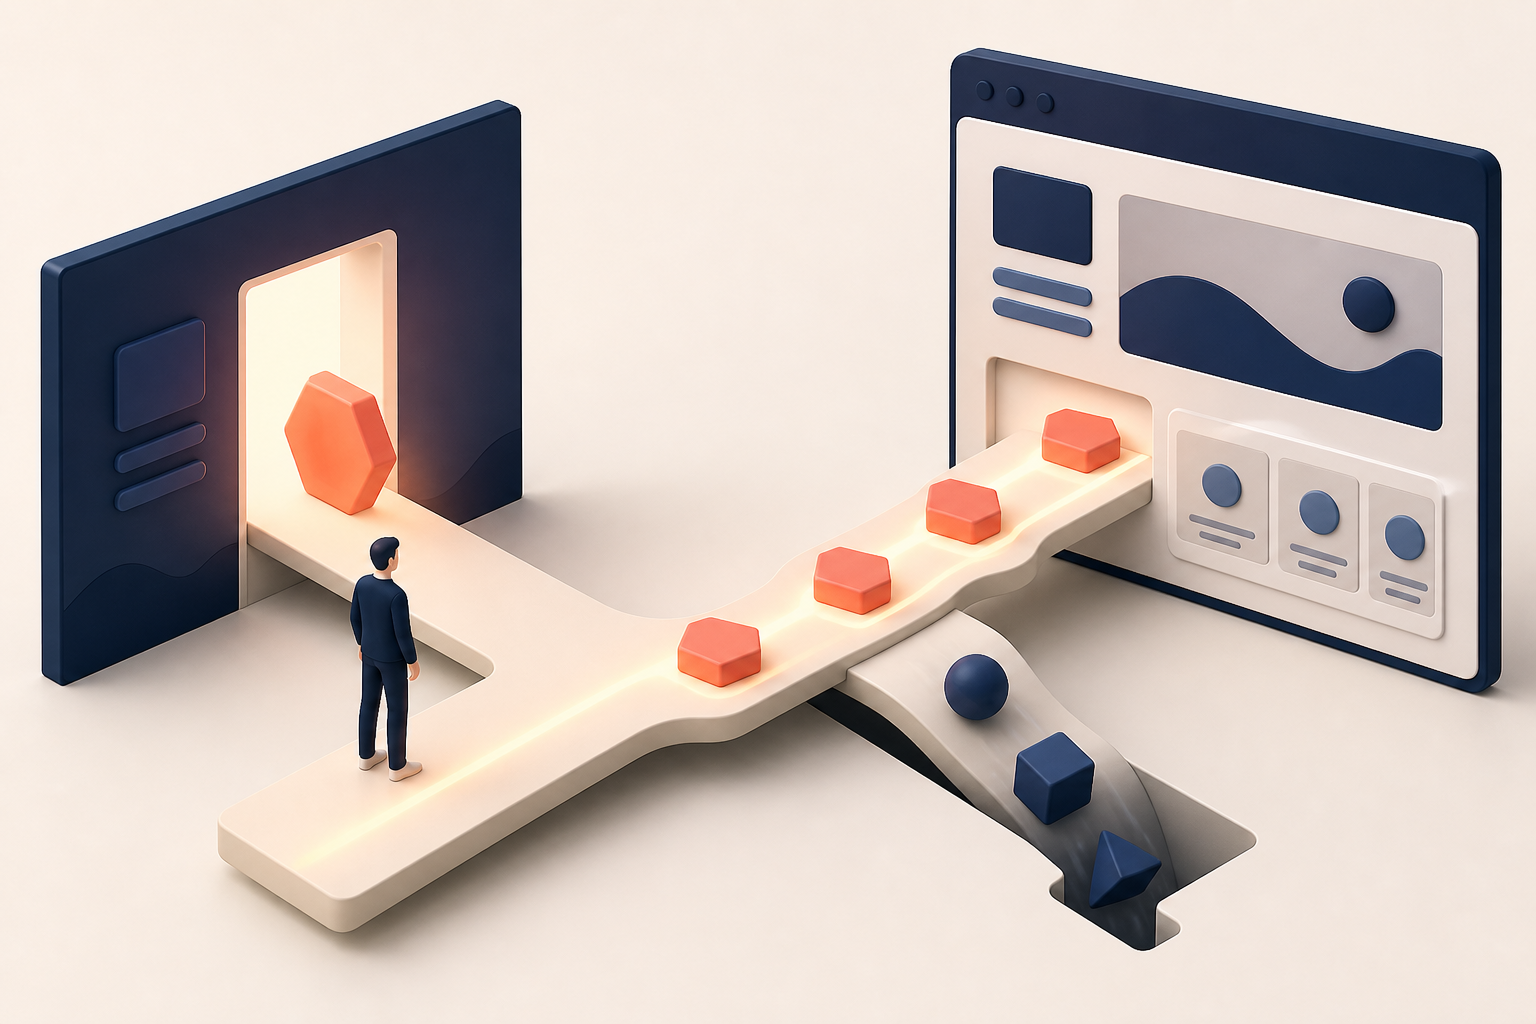
    A visitor follows a matching coral symbol from an entry doorway to an unlabeled landing page while mismatched shapes fall into a gap.

    Your landing page begins before the visitor reaches it. An ad, search result, email, social post, referring page, or AI-generated answer creates an expectation. The landing page must continue that expectation without forcing the visitor to reinterpret what you meant.

    Message match is not a requirement to repeat the referring copy word for word. It means preserving the audience, problem, offer, and intended outcome. If an ad promises payroll software for small construction companies but the landing page opens with a generic statement about business efficiency, the visitor has to work out whether the page is still relevant. That interpretive work is avoidable friction.

    Write a message-match brief

    Audit each major traffic source against the page using a short brief:

    1. Name the exact audience the source addresses.
    2. Copy the promise or question that earns the click.
    3. State what the visitor is likely to expect next.
    4. Identify the words or ideas on the landing page that confirm the visitor is in the right place.
    5. Write the action the page asks that visitor to take.

    You have a message-match problem if the source and page disagree about the audience, outcome, offer, or next step. You also have one if the connection is technically present but buried below company history, a product overview, or several unrelated features.

    Do not send meaningfully different promises to one generic page merely because maintaining one URL is convenient. If separate campaigns address separate use cases, either create purpose-built variants or build a page that lets each audience recognize its route immediately. The deciding question is not whether the products are related. It is whether the same opening argument honestly serves every visitor.

    Answer the entry question before advancing the sale

    A person arriving from an informational search may still be defining the problem. Someone clicking a retargeting ad may already understand the product and need pricing, proof, or implementation details. Giving both visitors the same argument can make the page feel either premature or repetitive.

    For search and AI-discovery traffic, answer the query that earned the visit near the beginning of the page. Then connect that answer to the offer. For high-intent campaign traffic, confirm the advertised offer immediately and make its conditions visible. Do not hide the promised detail behind a form unless receiving that detail is explicitly what the visitor agreed to request.

    If one source converts poorly while other sources perform acceptably on the same page, inspect its promise, targeting, and visitor intent before redesigning the entire landing page. A source-specific failure is evidence about the handoff, not automatically evidence that every part of the page is broken.

    Make the offer understandable before making it persuasive

    Clarity is not the same as minimal copy. A short page can still be vague, and a detailed page can still be easy to follow. The real test is whether a qualified visitor can understand the offer without assembling its meaning from scattered headings, screenshots, and buttons.

    The opening portion of the page should answer these questions:

    • What is being offered?
    • Who is it for?
    • What useful outcome does it support?
    • What will the visitor receive or gain access to?
    • What commitment does the next step require?
    • What happens after the visitor acts?

    If your team cannot answer those questions in plain language, polishing the layout will not solve the underlying problem. Rewrite the offer as a single sentence before touching the page. A workable internal template is: this is a specific offer for a defined audience that helps with a named problem, and the next step is a clear action. The published copy can be more natural, but its meaning should remain that precise.

    Build a visible hierarchy instead of a wall of benefits

    A practical opening sequence is a headline that identifies the relevant outcome, supporting copy that qualifies the audience or method, evidence that makes the claim credible, and a call to action that names the next step. This sequence gives each element one job.

    Avoid opening with an unsupported superlative, a slogan that could describe any competitor, or a broad category label. Replace it with the most specific claim you can support. If you cannot substantiate a dramatic promise, narrow it. Accurate specificity is more useful than inflated certainty.

    Organize the rest of the page around the decision, not your internal company structure. A visitor usually does not need a tour of every capability before learning whether the offer addresses the current problem. Present the core outcome, explain how it works, show relevant evidence, address the main objections, and make the next step clear. Place secondary detail where an interested visitor can reach it without making everyone process it first.

    Make the call to action describe the real next step

    Labels such as Submit, Continue, or Learn More hide the consequence of clicking. Use language that describes the action or deliverable, such as View plans, Request a demo, Start the assessment, or Get the checklist. The best wording depends on what the button actually does.

    The destination must honor the label. A button that says View pricing should not unexpectedly open a sales-contact form. A button that says Start free should not conceal a required sales conversation. When the wording and destination disagree, the page creates mistrust at the exact moment the visitor is considering action.

    A single primary action does not require a single button. You can repeat the same call to action as the argument develops. It means that the most prominent controls support the same decision. Keep a secondary action only when it serves a clear alternate state, such as letting a visitor inspect documentation before requesting a technical demo. Several equally prominent actions force the visitor to decide how to use the page before deciding whether to accept the offer.

    Remove friction without removing the confidence to act

    Reducing friction does not mean making every page short or every form tiny. It means removing effort that does not help the visitor make a sound decision or help your team complete the promised next step.

    Require only information that has an immediate purpose

    Review every form field with the same questions:

    • Why is this information needed before the next step?
    • Will the answer change eligibility, routing, preparation, or the immediate response?
    • Could the information be inferred from existing data or collected later?
    • Is the label clear about the expected format?
    • Does the error message explain how to correct the entry?

    A demo request may legitimately need information that helps assign the right specialist. A simple resource delivery may not need the visitor’s phone number, company size, job level, budget, and purchasing timeline. Form length should follow the transaction, not a blanket preference for short or long forms.

    Do not remove required privacy controls, consent choices, or disclosures merely to shorten the interaction. Those elements may carry legal or operational consequences. Simplify their language and presentation with qualified review, but preserve requirements that apply to the data and jurisdiction involved.

    Treat uncertainty as friction

    A page can be visually simple and still feel risky. Before acting, a visitor may need to know whether the offer fits the relevant use case, what happens after submission, how personal or business information will be used, what commitment is involved, and whether the claims can be verified.

    Place each answer near the moment the doubt arises. Put important conditions near the offer. Put a concise data-use explanation near the form. Put implementation evidence near implementation claims. Put relevant customer proof beside the outcome it supports. Do not make the visitor hunt through a footer, separate FAQ, or generic testimonials to resolve a predictable objection.

    Evidence should be inspectable. A screenshot can clarify what the product looks like. A testimonial is more useful when its context makes clear who benefited and from what use case. A process description can reduce uncertainty about the next step. Logos, badges, counters, and quotations should never imply validation you cannot substantiate.

    Test the complete path, not just the page appearance

    Run a manual conversion check on the devices and input methods your visitors use. Complete the path as a new visitor rather than as someone who already knows how the interface works.

    1. Open the actual campaign or search destination, including its query parameters.
    2. Check that the page loads and remains usable on a phone-sized screen.
    3. Navigate interactive elements with a keyboard and confirm that labels remain understandable without placeholder text.
    4. Submit the form empty, with invalid entries, and with valid entries.
    5. Confirm that errors identify the affected fields and preserve information already entered.
    6. Try repeated clicks and verify that they do not create duplicate submissions or charges.
    7. Confirm that the success state appears only after a real completion.
    8. Check the promised follow-up, such as an email, download, booking, account state, or sales notification.

    A page-level change cannot fix a broken confirmation email, an unavailable booking calendar, a validation loop, or a form that silently fails. If primary CTA clicks rise while completed actions remain flat, investigate what happens after the click before revising the headline again.

    Measure the decision path before running an A/B test

    An analyst examines visitor markers moving through five symbolic decision checkpoints while two alternative page panels remain covered.

    Conversion optimization becomes guesswork when the success event is ambiguous. Define the completed business action first, then instrument the steps that help you locate failure.

    For a lead page, a useful event path may include the landing-page view, primary CTA click, form start, validation error, successful submission, and confirmed thank-you state. For a purchase or account flow, the events will differ, but the distinction remains: intermediate interactions diagnose behavior; the completed action measures conversion.

    Do not call a button click a lead when a valid submission is the actual objective. Do not call a form submission a purchase when payment confirmation is the objective. Naming an early event as the conversion can make a broken downstream path appear successful.

    Before comparing versions, verify that the conversion event fires once, fires only after genuine success, carries the correct campaign context, and excludes or identifies internal quality-assurance activity. Keep the denominator consistent. A rate based on landing-page sessions cannot be compared directly with one based on users, ad clicks, or all site visits without explaining the difference.

    Segment enough to find the problem, but not enough to invent one

    Start with segments that can change your diagnosis: traffic source or campaign, device class, offer, landing-page variant, and new versus returning visitors when that distinction matters. Add geography, query group, or audience segment only when the page or offer meaningfully differs for those visitors.

    Look for a coherent break in the path. Low CTA engagement can indicate weak relevance, poor offer clarity, or insufficient evidence. Strong CTA engagement followed by low form completion points toward the form, its expectations, or a technical failure. High form completion followed by low-quality leads points toward targeting, qualification, or an offer that attracts the wrong action.

    Pair the landing-page conversion with a downstream measure when the business cares about lead or customer quality. Qualified leads, attended meetings, completed purchases, successful activations, or another relevant outcome can reveal whether an apparently improved page merely created more low-fit submissions. The correct downstream measure depends on the actual job of the page.

    Turn observations into testable hypotheses

    An A/B test should answer a decision, not provide movement for a dashboard. Write the hypothesis before building the variant:

    1. Describe the observed break in the conversion path.
    2. Name the most plausible mechanism behind it.
    3. Choose the smallest meaningful change that addresses that mechanism.
    4. Select the primary outcome and any guardrail, such as lead quality or completed purchases.
    5. Decide in advance how you will judge the result, and do not stop merely because one version takes an early lead.
    6. Record the traffic sources and audience segments included so the result is not applied beyond the visitors actually tested.

    For example, a large drop between form start and completion supports a form-friction hypothesis more directly than a headline hypothesis. You might clarify why a sensitive field is required, repair confusing validation, or remove a field that does not affect the next step. A random button-color test would not address the observed break.

    Keep variants interpretable. If you change the headline, offer, proof, layout, form, and CTA together, a different result will not tell you which mechanism mattered. A broader rebuild can still be appropriate when the baseline is fundamentally incoherent, but treat it as a page-level replacement rather than evidence that every individual change was beneficial.

    When traffic volume cannot support a credible comparison, do not pretend that a handful of conversions settles the question. Use message reviews, session-level diagnostics, form-error data, support or sales questions, and manual path testing to identify obvious defects. Make corrections with a clear rationale, then keep monitoring the business outcome.

    Key takeaways

    • Audit the promise that earns the visit before changing the design that receives it.
    • Make the audience, offer, outcome, commitment, and next step understandable near the beginning of the page.
    • Use calls to action that describe what will really happen after the click.
    • Remove form fields and page elements that do not support the decision or immediate follow-up, while preserving required controls.
    • Place proof and risk-reducing information beside the claims or actions they support.
    • Track the completed business action separately from diagnostic events such as clicks and form starts.
    • Prioritize the point where the conversion path visibly breaks, then test a change tied to a plausible mechanism.
    • Check lead or customer quality so a higher page conversion rate does not conceal a worse business result.

    Choose one commercially important landing page and write down its traffic promise, intended visitor, offer, primary action, and confirmed success event. Walk the full path once, then inspect the data for the first meaningful break. That break is your next change. Put it in a test or change log with the reason, expected effect, and business measure before you ship it.

    References


  • How to Build a Forum That Earns Visibility in AI Search

    How to Build a Forum That Earns Visibility in AI Search

    Your content team can answer the obvious questions. The harder problem is everything too specific, contextual, or fast-changing to justify its own editorial brief. Those questions still get asked. If your site does not host the conversation, users and AI assistants will look elsewhere for it.

    A well-run forum gives those questions a durable home while letting customers, practitioners, and subject-matter experts add the details a conventional content calendar misses. But the software is the easy part. To earn visibility, the community must produce public, well-structured, trustworthy answers rather than empty categories, unresolved threads, and searchable spam.

    Forums capture the demand your editorial calendar misses

    Traditional SEO programs tend to prioritize head terms: topics with recognizable search volume, clear commercial value, and enough demand to support a standalone page. That leaves a wide gap around questions involving unusual configurations, narrow use cases, product combinations, exceptions, and real-world tradeoffs.

    Users do not experience that gap as a keyword problem. They experience it as a question nobody has answered. When an AI assistant lacks enough internal knowledge to respond, it may search the web through engines such as Google or Bing. A detailed discussion can then become more useful than another broad page repeating the standard explanation.

    The scale of that appetite is already visible: Reddit appeared in more than 40% of LLM responses in a June 2025 analysis of 150,000 AI citations. That percentage is not a promise that launching a forum will produce citations. It shows how often AI answer systems rely on conversational material when they need specific, experience-shaped information.

    A useful thread can contain several forms of evidence at once: the language of the original problem, the constraints that made it difficult, several proposed solutions, objections from other practitioners, and a final resolution. That creates semantic depth naturally. It also exposes where an answer works, where it fails, and which conditions change the outcome.

    User-generated content is not automatically accurate, current, or trustworthy. Those qualities come from expert participation and active curation. An unanswered question is merely a thin page. A confident but incorrect reply is worse because it can mislead a customer and give search or AI systems a poor representation of your brand’s knowledge.

    Start by building a question inventory from places where long-tail demand is already visible:

    • Support conversations that require more context than the help center provides.
    • Pre-sale questions that repeatedly need a specialist to answer.
    • Internal site searches that return no useful result.
    • Comments and replies that reveal exceptions to your published guidance.
    • Implementation questions that have several valid answers rather than one universal procedure.
    • Product feedback that begins as a how-to question but exposes a missing feature, unclear workflow, or documentation gap.

    For each candidate, record the audience, product or process involved, constraint, desired outcome, and evidence needed for a credible answer. This becomes both your launch backlog and your first taxonomy. It is far more useful than creating empty categories based on the structure of your company.

    Choose the community format before choosing the software

    A forum should not absorb every type of content. The right format depends on the job the user is trying to complete and how much disagreement belongs in the answer.

    User needBest primary formatWhy it fits
    Compare approaches, share examples, or discuss tradeoffsDiscussion forumSeveral perspectives may remain useful even after the original problem is resolved.
    Solve one defined problem and identify the clearest resolutionQ&A communityAnswers can be evaluated, corrected, and marked as accepted or resolved.
    Confirm an official rule, specification, policy, or supported procedureDocumentationThe brand needs to maintain one canonical answer without ambiguity.
    Explain a broad strategy or synthesize several related issuesEditorial contentA controlled narrative is better than asking readers to reconstruct the answer from replies.

    Many brands need a combination. The community surfaces the question and gathers experience. Documentation records the official procedure. Editorial content explains the larger pattern. Links between those formats help a user move from conversation to an authoritative answer without forcing one page to do every job.

    For discussion-led communities, Flarum and Discourse are open-source options. For a more resolution-oriented Q&A model, Apache Answer and Question2Answer fit that structure. Open-source software can provide customization and control over community data, but it does not remove the operating work. Hosting, security updates, spam controls, moderation, backups, and contributor support still need owners.

    Evaluate each platform against the workflow you intend to run, not the length of its feature list:

    • Public access: Can valuable threads be read without signing in, and can their text be crawled at stable URLs?
    • Data control: Can you export users, threads, replies, moderation history, and attachments in a usable form?
    • Answer states: Can moderators mark a question as resolved, identify an accepted answer, and reopen it when circumstances change?
    • Identity and authority: Can you distinguish employees, verified experts, moderators, experienced members, and ordinary participants without implying that every badge guarantees accuracy?
    • Curation: Can you merge duplicates, redirect obsolete URLs, feature a useful summary, and connect related discussions?
    • Moderation controls: Can permissions expand gradually as a member earns trust, with a clear escalation path for sensitive cases?
    • Search hygiene: Can you prevent thin tag, filter, profile, and empty category pages from overwhelming the useful discussions?

    Do not launch merely because the installation works. Your minimum launch gate should include a named community owner, published participation rules, a prepared backlog of real questions, committed experts who will answer them, and a process for escalating incorrect or sensitive replies. Without those pieces, early visitors learn that asking is not worth the effort.

    Turn each thread into a page an answer engine can understand

    A branching group of discussion tiles is organized into a structured page with separate areas for a question, a primary answer, supporting replies, and related topics.

    A forum thread is both a conversation and a content page. If you optimize only for conversation, the useful answer may be buried under vague titles, missing context, jokes, and outdated replies. If you optimize only for search, the community begins to feel like an unpaid content factory. The page template has to serve both.

    1. Require a descriptive question title. A title such as Need help with discounts carries almost no meaning. How can I limit a discount to subscriptions without changing one-time purchases names the action, object, and constraint.
    2. Prompt for decision-changing context. Ask for the product or process, relevant version, intended outcome, constraints, steps already tried, and any visible error. Do not ask users to publish account credentials, personal information, confidential data, or anything else that should remain private.
    3. Put the usable answer near the top. Once a thread is resolved, add or feature a short summary that states the solution before the longer discussion. Keep the reasoning and alternatives below it for readers whose situation differs.
    4. Label the role behind each reply. An official policy, a verified specialist’s recommendation, and a customer’s workaround are different kinds of evidence. Make that distinction visible instead of flattening every reply into the same level of authority.
    5. Show the resolution and freshness state. Mark threads as open, resolved, or superseded. Display when the accepted information was last reviewed, and reopen the question when a product or policy change makes the old resolution uncertain.
    6. Curate duplicates into a stronger destination. Merge substantially identical questions or point them to the canonical discussion. Preserve distinct threads when a different constraint genuinely changes the answer.

    The technical baseline matters as much as the editorial template. Give every valuable thread one durable URL. Expose the question and replies as crawlable HTML. Use a descriptive page title, keep internal links reachable, redirect merged discussions, and keep empty or low-value system pages out of the index. Include only eligible public pages in discovery feeds such as XML sitemaps.

    Structured data may help machines interpret the page, but it must describe what visitors can actually see. Do not mark an unresolved reply as accepted, manufacture an answer that is absent from the thread, or treat decorative voting as evidence of expertise. Markup can clarify a sound page; it cannot turn a weak discussion into an authoritative answer.

    Being crawlable is not the same as being citable. A passage becomes easier to reuse when it answers the question in self-contained language. Replace replies such as That worked for me with language that names what worked, under which conditions, and what the reader should check before applying it. The simple editorial test is whether two sentences could be quoted outside the thread without losing the subject, constraint, or conclusion.

    Preserve useful disagreement. A minority answer may cover a version, market, or implementation the accepted answer does not. Moderators should remove abuse, spam, impersonation, and dangerous misinformation, but they should not erase a good-faith alternative merely to make the thread look unanimous. Expert consensus is valuable only when the community can see how it was reached.

    Operate the forum as a knowledge system, then measure it

    Community stewards review, connect, and maintain glowing discussion nodes inside a digital archive-like workspace.

    Build moderation into the publishing workflow

    Moderation is not a cleanup queue that begins after growth. It is the process that turns raw participation into reliable knowledge. Define the boundaries before inviting users: what belongs in the community, what evidence is expected, what promotion is allowed, how conflicts are handled, and which questions must move to private support.

    1. Triage new questions. Correct unclear titles, request missing context, merge true duplicates, and move private account issues out of public view.
    2. Route the question. Assign unanswered topics to the employee, partner, or community expert most able to resolve them. Publish an internal response target that reflects actual staffing so questions do not disappear between teams.
    3. Separate contribution from endorsement. Let members share workarounds, but mark which answers represent official guidance. Correct false claims without presenting all disagreement as misconduct.
    4. Close the knowledge loop. When the question is resolved, feature the clearest answer, add a concise summary, connect relevant documentation, and record whether the resolution depends on a particular version or condition.
    5. Distribute responsibility carefully. Give consistent contributors limited moderation privileges, then expand those permissions as judgment and reliability become clear. Keep policy decisions and serious escalations under accountable brand ownership.

    Community-led moderation can scale better than routing every task through one central team because knowledgeable members can improve titles, flag duplicates, welcome newcomers, and surface strong answers. It still needs oversight. Passion for the topic is not the same as authority to set company policy or adjudicate every dispute.

    Measure answer quality before celebrating traffic

    Pageviews can rise while the community deteriorates. Define what counts as a useful reply and a resolved question before building the dashboard, then keep those definitions consistent. Track a small set of measures tied to decisions:

    OutcomeWhat to trackWhat you can do with it
    Question coverageIn-scope questions, unanswered share by topic, time to first useful reply, and resolved shareFind topics with real demand but insufficient expert capacity.
    Contributor healthRepeat contributors, active subject-matter experts, answer corrections, and reliance on a single responderSee whether knowledge is becoming distributed or remains a bottleneck.
    DiscoveryIndexed resolved threads, non-branded search landings, verified AI citations, and identifiable AI referral sessionsDetermine which answer formats and topic clusters earn external visibility.
    Customer valueRepeated support questions, forum-assisted journeys, documentation gaps, and product issues surfaced by discussionsConnect the community to support, content, sales, and product decisions.

    Do not collapse these signals into one vanity score. Response health is an operating signal; search and AI visibility are downstream outcomes. A bot crawl is not a citation, and a citation is not automatically a conversion. Verify important AI mentions against the actual answer, inspect the landing behavior where analytics allows it, and check whether the cited thread represents your position accurately.

    The best measurement loop changes the community. If one topic attracts questions but few answers, recruit or assign an expert. If several threads resolve the same issue, promote the resolution into documentation. If a discussion exposes several legitimate strategies, turn it into a deeper editorial resource and link back to the original examples. If obsolete threads keep earning visits, update or supersede them before they continue spreading stale advice.

    Key takeaways

    • A forum is most valuable when it captures narrow, contextual questions that conventional keyword and editorial planning leave unanswered.
    • Choose discussion software for multiple valid perspectives and a Q&A model when users need a clearly resolved outcome.
    • Require descriptive titles, decision-changing context, visible authority labels, concise answer summaries, and clear resolution states.
    • Public crawlability, stable URLs, duplicate control, and accurate page markup are prerequisites, not substitutes for trustworthy answers.
    • Measure response quality, expert participation, discovery, and customer value separately so you know which part of the system needs attention.

    Your first move is not to install a platform. Collect the questions already escaping into support queues, sales calls, comments, and third-party communities. Choose one coherent topic area, assign the people who can answer it, and design the resolution workflow before opening the doors. A focused forum that reliably solves difficult questions is a stronger AI-search asset than a large community full of unanswered ones.

    References

  • How to Turn AI Prompts Into Audience and Intent Intelligence

    How to Turn AI Prompts Into Audience and Intent Intelligence

    Your keyword report may show that people search for “best project management software.” It cannot tell you whether they run a distributed design team, need client access, fear a difficult migration, or want a shortlist they can defend to a finance lead. Those details often appear inside an AI prompt.

    If you are deciding what to publish, optimize, or update, that extra context changes the work. Prompt-based intelligence helps you move from counting phrases to understanding the task, audience, constraints, and decision behind each request. The practical goal is not a larger spreadsheet. It is a content plan built around questions people are actually trying to resolve.

    Build a prompt dataset that preserves the real question

    A prompt is useful because it can contain more than a topic. Access to the questions customers put to ChatGPT can expose the language of the request, the outcome someone wants, and the qualifications that would disappear in a conventional keyword list.

    Do not reduce those prompts to their shared noun too early. A request such as “Which accounting platform is easiest for a nonprofit with restricted funds?” carries at least four pieces of intelligence: a product category, a comparison task, an organizational context, and a specialized requirement. If you normalize it to “accounting software,” you preserve the category and discard most of the reason for creating content.

    For every prompt, retain these fields:

    • Subject: the product, problem, process, or entity under discussion.
    • Task: what the person wants the model to do, such as explain, compare, recommend, plan, calculate, or troubleshoot.
    • Context: the role, organization, use case, or situation shaping the request.
    • Constraints: budget, compatibility, risk, timing, geography, skill level, or another limiting condition.
    • Decision criteria: the qualities the person will use to judge an answer.
    • Requested output: a definition, shortlist, procedure, example, template, or decision.
    • Platform and market: where the prompt was observed and which dataset or geography it represents.

    Use a repeatable collection process:

    1. Write down the business decision the analysis must support. “Choose the next five content updates” is usable; “understand our audience” is not.
    2. Collect prompts for the relevant topic, brand, category, competitors, problems, and use cases. Keep the original text unchanged.
    3. Store results from each platform separately. Prompt-volume coverage can extend across ChatGPT, Gemini, Claude, and Perplexity, but a platform label should remain a boundary in your analysis unless the underlying measurements are demonstrably comparable.
    4. Remove exact duplicates, then group close variants without deleting meaningful constraints. “CRM for a small agency” and “CRM for a hospital network” belong to the same broad category but not necessarily the same answer.
    5. Label the task, intent, audience evidence, constraints, and output expected from each prompt.
    6. Review a sample of every cluster manually. Split any cluster whose prompts would require materially different recommendations or evidence.

    Treat prompt volume as a prioritization signal, not a census of everyone who uses an AI assistant. A projection can help you compare opportunities inside a consistently defined dataset. It should not be presented as an exact count of people, purchases, or future traffic. Record the provider, collection period, market, platform, and methodology beside every value so that later comparisons remain interpretable.

    Classify intent by the outcome, not the wording

    Intent is the job the person expects the answer to complete. Conversation-intent data can reveal what customers aim to achieve, but the label only becomes useful when it changes the content you produce.

    IntentWhat the person needsWhat your content should supply
    UnderstandA clear mental model of a topic or problemA direct definition, mechanism, boundaries, and a concrete example
    CompareA defensible choice between approaches, products, or providersDecision criteria, tradeoffs, fit by use case, and disqualifying conditions
    ValidateConfidence that a claim or proposed decision holds upEvidence, assumptions, limitations, objections, and ways to verify the claim
    ActA path from decision to completionPrerequisites, ordered steps, dependencies, and a definition of done
    ResolveAn explanation and fix for something that went wrongSymptoms, likely causes, diagnostic branches, corrective actions, and escalation points

    Assign one primary intent and, where necessary, one secondary intent. A prompt asking “Is switching analytics platforms worth it, and how would we migrate?” primarily asks for validation and secondarily asks for an action plan. Your page should settle the decision before presenting migration steps. Reversing that order would make a detailed page feel unhelpful even if every instruction were accurate.

    Use verb-object labels to keep clusters honest

    Name each cluster with a verb and an object: “compare enterprise plans,” “validate implementation cost,” “troubleshoot missing citations,” or “choose markup for a product page.” Labels such as “software,” “SEO,” or “pricing” describe subjects, not intentions.

    Then test the cluster with one question: could a single answer satisfy most of these prompts without becoming vague? If not, split it. “Compare plans by price” and “compare plans by security requirements” may mention the same vendors, but they demand different criteria and supporting detail.

    Do not mistake a polished prompt for purchase intent

    Length, specificity, and commercial vocabulary are clues, not proof of readiness to buy. A researcher can write a detailed product prompt without controlling a budget. A buyer can ask a short question because the context appeared earlier in the conversation. Classify intent from the requested outcome and constraints you can see. Mark anything else as unknown.

    This distinction prevents a common planning error: treating every comparison as bottom-of-funnel content. Some comparisons teach the category. Others support procurement. Separate them by the criteria requested, evidence required, and next action implied.

    Separate audience evidence from demographic guesswork

    A researcher studies blank prompt cards beside concrete task and constraint objects, separated from blurred generic silhouettes by a glass divider.

    Prompt intelligence can tell you who needs an answer, but not every audience signal has the same strength. Some systems add aggregate breakdowns by age, income, and gender. Those dimensions can reveal differences worth investigating, but they should not be confused with facts about the author of an individual prompt.

    Keep three evidence types separate:

    • Explicit audience evidence: the prompt names a role, organization, experience level, life situation, or use case. “Explain this to a first-time marketing manager” is explicit.
    • Contextual evidence: the prompt reveals a relevant constraint without identifying the person. A request for audit logs signals a requirement; it does not prove the user’s industry or seniority.
    • Aggregate demographic data: the dataset reports a distribution across demographic segments. This can support group-level analysis, not a personal conclusion about one prompt author.

    Segment by need before segmenting by identity. Start with the job, constraint, decision criteria, and required outcome. Add demographic analysis only when it exposes a meaningful difference in the questions asked or the answer needed. A demographic difference that does not alter the content decision is interesting metadata, not a reason to create another page.

    For each potential segment, compare four things:

    1. Does the segment ask a different primary question?
    2. Does it apply different constraints or decision criteria?
    3. Does it need different examples, terminology, evidence, or instructions?
    4. Would a tailored answer prevent a real misunderstanding or improve a real decision?

    Create a separate content treatment only when at least one of those differences is material. Otherwise, keep one strong page and make the relevant options or scenarios easy to find within it.

    Avoid persona theater. “Budget-conscious Brenda” is not intelligence unless the data shows a distinct need you can serve. A more useful segment would be “small-team operator comparing tools without implementation support.” It identifies the situation, constraint, and content consequence without inventing a biography.

    Turn prompt clusters into a defensible content queue

    Blank prompt cards are grouped around task symbols and connected by colored threads to an orderly row of content tiles.

    The deliverable is not a chart of prompt themes. It is a ranked queue of pages to create, consolidate, or improve. Score each cluster against the same decision criteria so that a conspicuous volume number does not override business relevance or your ability to answer well.

    Use four ratings for every cluster:

    • Observed demand: the relative prominence of the cluster within a consistently defined prompt dataset.
    • Audience relevance: how closely the need matches the people you can genuinely serve.
    • Answer gap: whether your current content answers the full request, including constraints and follow-up questions.
    • Authority to answer: whether you can provide the evidence, detail, and qualifications the topic requires.

    Rate each as high, medium, or low and preserve the reasoning in a notes field. Start with clusters that combine meaningful demand, strong audience relevance, a visible answer gap, and sufficient authority. A high-volume cluster that you cannot support should not outrank a smaller cluster where you can give the best available answer.

    Write the brief around the conversation

    A useful prompt-led brief contains more than a target phrase. Include:

    • The representative prompts and their close variants
    • The primary and secondary intent
    • The explicit audience and contextual signals
    • The recurring constraints and decision criteria
    • The answer the reader needs before anything else
    • The follow-up questions that naturally come next
    • The proof, examples, or qualifications required
    • The cases the page should exclude or redirect
    • The appropriate next action after the question is resolved
    • The existing page to update, or the reason a new page is necessary

    Lead with the answer that completes the primary task. Follow with criteria, reasoning, exceptions, and execution detail in the order the reader needs them. Use headings that state recognizable subquestions. Make relationships explicit: which option fits which situation, which prerequisite controls the next step, and which limitation changes the recommendation.

    Do not create one page for every wording variation. Consolidate prompts when the same core answer, evidence, and decision path satisfy them. Split them when their constraints lead to different recommendations. This produces fewer, stronger assets and reduces the chance that several pages compete while none resolves the whole conversation.

    Measure coverage before claiming impact

    Measure prompt intelligence at the cluster level. A simple coverage rate is the share of priority prompts mapped to a page that adequately answers the primary intent, material constraints, and expected follow-ups. Reassess the page when any of those elements remains missing.

    You can also track observed AI visibility by testing a stable set of representative prompts and recording whether your brand or content appears, how it is represented, and whether the answer addresses the intended use case. Keep the platform, prompt wording, location or market, date, and test conditions with each observation. Generated answers can vary, so one response is an observation, not a trend.

    Connect that visibility data to outcomes only where your analytics can support the connection. AI-referred visits, qualified actions, and assisted conversions answer different questions. Do not collapse them into one success metric, and do not credit prompt research for a commercial result merely because the timing overlaps.

    Key takeaways

    • Keep the full prompt. The task, context, constraints, and requested output are often more useful than the shared keyword.
    • Classify intent by the outcome the person wants, then shape the page around that job.
    • Distinguish explicit audience evidence, contextual clues, and aggregate demographic data.
    • Keep platform datasets separate until you know their measurements can be compared.
    • Prioritize clusters using demand, audience relevance, answer gaps, and your authority to answer.
    • Measure prompt coverage and observed visibility with stable records; do not treat a single generated response as a trend.

    Start with one decision your team needs to make and one bounded set of prompts. Preserve their context, label the intended outcomes, and map the highest-priority unanswered cluster to an existing page. That first completed loop will teach you more than a broad audience dashboard that never changes the content queue.

    References

  • AI Search Demand Intelligence: From Prompts to Intent

    AI Search Demand Intelligence: From Prompts to Intent

    You can have a long list of AI search prompts and still not know what to publish. The list shows how questions are phrased. It does not reveal which needs recur, how an answer engine decomposes a request, whose decision sits behind it, or whether one useful page could satisfy the whole job.

    AI search demand intelligence closes that gap. It connects observed prompts to intent, audience context, hidden retrieval work, content decisions, and measurable outcomes. The goal is not to collect the largest prompt list. It is to identify the questions worth answering, understand why they matter, and publish the evidence an answer engine needs to use your content confidently.

    Build a demand map that reflects how people actually ask

    Overhead view of abstract prompt tokens grouped into connected clusters, with a few isolated pieces around the edges.

    Traditional keyword research often starts with a compact phrase. AI interactions are frequently fuller: a person can describe a situation, add constraints, ask for a recommendation, and request an explanation in the same prompt. If you reduce that request to its main noun, you discard much of the intent.

    Prompt volume is therefore a useful demand signal, but it is not a complete opportunity score. One commercial dataset is described by its provider as covering more than 400 million real AI conversations, including variation across regions, demographics, and emerging trends. That breadth can reveal recurring language and demand patterns. It should not be mistaken for a complete or independently audited census of every answer-engine interaction.

    Use provider-reported volume directionally. Confirm important patterns with the evidence available to you: site search terms, sales questions, support records, customer interviews, conversion data, and the prompts your team already monitors. Agreement between several signals deserves more confidence than a large-looking volume estimate by itself.

    SignalWhat it can tell youWhat it cannot tell you aloneDecision it should inform
    Prompt volumeWhich questions or themes appear to recurWhether the demand is valuable, representative, or well matched to your businessWhich clusters deserve closer analysis
    Prompt listWhich project, market, product, or campaign owns a promptWhether differently worded prompts express the same intentHow to maintain a usable research inventory
    Intent hierarchyHow a broad need branches into use cases, constraints, comparisons, and decisionsWhich searches an answer engine performs while composing a responseWhether you need a hub, a focused page, or supporting material
    Query fanoutWhich supporting searches and subproblems may contribute to an answerWhich branch matters most to your audience or businessWhat evidence and supporting answers the content must contain
    Persona responseHow an answer may differ by role, industry, or motivationThe absolute size of that audience or the truth of an invented persona profileWhose criteria, objections, and vocabulary should shape the page

    Start your working dataset with one row for each raw prompt. Preserve the original wording; it contains clues that normalization can erase. Add fields for:

    • Normalized intent: the underlying job, written as a clear verb and object.
    • Topic or entity: the product, problem, brand, category, place, or concept being discussed.
    • Qualifiers: industry, company type, location, budget sensitivity, compatibility requirement, urgency, or other stated constraint.
    • Decision stage: learning, diagnosing, evaluating, comparing, validating, implementing, or troubleshooting.
    • Audience context: role, industry, motivation, and any meaningful level of expertise.
    • Demand signal: the available volume band, recurrence pattern, and supporting first-party evidence.
    • Source context: where the prompt came from, which answer engine or dataset it represents, and when it was observed.
    • Business relationship: whether the intent connects to a product, service, capability, support need, or strategic topic you can address credibly.
    • Status: unreviewed, clustered, mapped to existing content, assigned to a brief, published, or intentionally declined.

    Do not normalize too aggressively. The prompts What inventory software works for a seasonal retailer? and How do I connect inventory software to my online store? share an entity, but not a job. The first is evaluation intent. The second is implementation intent. Combining them would blur the evidence, content format, and next action each person needs.

    Keep the inventory operational by separating it into lists for distinct projects and keyword groups. A useful list boundary changes ownership or interpretation: product line, market, language, customer segment, campaign, or research question. A vague catch-all list merely moves the clutter into another screen.

    Expand each prompt into the engine work behind the answer

    A glowing request passes through transparent chambers containing symbols for research, verification, comparison, and synthesis before reaching a person.

    A complex prompt rarely behaves like an isolated keyword. An answer engine may need to resolve entities, gather comparison criteria, check constraints, retrieve supporting facts, and reconcile several pieces of information before it can respond. Query fanout analysis is designed to expose what an answer engine searches for during that process.

    This distinction matters because the visible prompt describes the destination, while the fanout reveals possible routes. Content that repeats the destination without supporting the route can sound relevant to a person yet remain weak material for an answer engine.

    Consider the prompt Which customer-support platform fits a growing online retailer? A fanout could include searches related to:

    • Customer-support platforms designed for online retail.
    • Storefront, marketplace, email, chat, and social integrations.
    • Pricing models and the conditions that change total cost.
    • Migration from an existing support system.
    • Automation, routing, reporting, and multilingual support.
    • Security, data handling, uptime commitments, and access controls.
    • Customer reviews, implementation evidence, and common limitations.

    Those are illustrative branches, not observed fanouts. That label is important. If a tool exposes actual engine searches, retain them as observed data. If your team predicts likely subqueries, record them as inferred hypotheses. Mixing the two creates false certainty and makes later analysis impossible to audit.

    Use the following workflow for each priority prompt:

    1. Preserve the full prompt and its audience context. Do not start from the shortened keyword.
    2. Capture observed fanout queries where available. Record the engine, interface, market, persona setting, and observation date with them.
    3. Add plausible inferred branches separately when the observed set leaves an obvious customer question untested.
    4. Group branches by task: definitions, criteria, compatibility, comparison, proof, risk, implementation, and next action.
    5. Map each branch to an existing page, an evidence asset, a section that needs improvement, or a genuine content gap.
    6. Remove branches that your business cannot answer with useful evidence. Relevance without authority is not a publishing case.

    A fanout map should change the brief. If the engine repeatedly needs compatibility details, a generic category overview is insufficient. If it needs definitions, comparisons, and implementation guidance, you must decide whether one well-structured resource can answer the set coherently or whether the intent needs a hub with focused supporting pages.

    Do not create one page for every fanout query. Many branches are supporting questions, not independent destinations. Splitting every variation into a new URL produces thin overlap and forces several pages to compete for the same job. Group branches when the same reader would reasonably need them in the same decision. Separate them when the audience, required evidence, content format, or next action genuinely changes.

    Use intent hierarchies and personas to find the real decision

    Volume tables flatten intent. A hierarchy restores its shape. Keyword hierarchies visualize how AI conversations branch into deeper intents, making it easier to distinguish a broad topic from the decisions nested beneath it.

    Build your hierarchy around the reader’s job rather than a taxonomy of nouns:

    • Root job: what the person ultimately wants to accomplish.
    • Use case: the situation in which that job occurs.
    • Constraints: what the solution must support, avoid, integrate with, or fit.
    • Evaluation criteria: how the person will distinguish a suitable answer from an unsuitable one.
    • Proof and risk: what evidence would make the answer credible and what could block the decision.
    • Action: what the person needs to choose, create, configure, verify, or fix next.

    This structure prevents a common content-planning error: treating every informational query as early-stage awareness. A prompt phrased as a question can still carry strong decision intent. Someone asking how a product handles migration, permissions, or a required integration may already be validating a shortlist. The specific constraint tells you more than the interrogative wording.

    Persona context then changes how you interpret each branch. Answer-engine responses can be segmented by role, industry, or motivation. Use those dimensions when they alter the decision, not as decorative profile details.

    For the same software-selection prompt, an operator may prioritize daily workflow and migration effort. A procurement lead may focus on terms, risk, governance, and vendor evaluation. An executive may want the business case, operational impact, and trade-offs. The topic is unchanged, but the acceptable evidence and useful answer are different.

    Create a compact intent card for each audience segment:

    • Job: the decision or task this person is trying to complete.
    • Trigger: the event or problem that made the question urgent enough to ask.
    • Must-have constraint: the requirement that can disqualify an otherwise good answer.
    • Evidence threshold: documentation, examples, comparisons, policies, specifications, or implementation detail needed for confidence.
    • Blocking objection: the unresolved risk most likely to stop action.
    • Next decision: what the person should be able to do after receiving a satisfactory answer.

    Keep this card tied to observable language. A modeled persona response is a testing lens, not proof that every member of a segment thinks alike. Validate it against customer questions and conversion behavior. If the language, constraints, and objections do not differ meaningfully, the personas probably do not need separate content.

    The hierarchy also tells you where to consolidate. Prompts belong in one cluster when they share the same root job, evidence requirements, and next action. They deserve distinct treatment when a branch introduces a new risk, audience, use case, or deliverable. This is a more defensible boundary than matching words or chasing every prompt variation.

    Turn intent intelligence into publish, update, and decline decisions

    Score opportunities without inventing false precision

    A single numeric score can conceal weak assumptions. Start with high, medium, or low confidence for the dimensions your team can actually assess:

    • Demand confidence: does the pattern recur in prompt data and in evidence you control?
    • Business relevance: does satisfying the intent connect to a legitimate capability, audience, or outcome?
    • Fanout leverage: would one authoritative resource answer several important branches coherently?
    • Evidence readiness: do you possess facts, examples, policies, product details, expertise, or original data that make the answer defensible?
    • Visibility gap: is your brand absent, misrepresented, weakly supported, or attached to the wrong intent?
    • Audience fit: does the prompt come from a segment you can serve, and do you understand its constraints?
    • Content gap: is a new page needed, or would updating, consolidating, or redistributing an existing asset solve the problem?

    Publish or update when business relevance, evidence readiness, and fanout leverage are strong. Research further when apparent demand is high but the intent or audience remains ambiguous. Consolidate when several prompts differ only in phrasing. Decline when you lack credible evidence, the intent sits outside your remit, or the apparent opportunity depends on a single inferred branch.

    This discipline protects you from two expensive mistakes: producing content for impressive volume that has no strategic value, and forcing a commercial page onto an informational need it cannot satisfy honestly.

    Write the brief around the answer job

    A useful AI-search brief should tell a writer what must become easier to retrieve, verify, and act on. Include:

    • The normalized intent and the raw prompts that support it.
    • The target persona, use case, decision stage, and disqualifying constraints.
    • A direct answer the page must make clear near the beginning.
    • The observed and inferred fanout branches, visibly distinguished.
    • The entities and terms that require consistent naming.
    • The claims that need evidence and the approved evidence available for each.
    • The comparisons, limitations, objections, and implementation details the reader needs.
    • The existing pages that should be updated, consolidated, or linked.
    • The next action that follows naturally from the intent.
    • The condition that should trigger a future review, such as a product change, a new constraint, or sustained prompt drift.

    Answer the core question before expanding into supporting detail. Use headings that correspond to real subproblems rather than keyword variants. State limitations beside the relevant claim. When structured data applies, use it only for information that is visibly present and accurate on the page. Markup can clarify content for machines; it cannot supply relevance or evidence that the page does not contain.

    Measure a stable benchmark and a changing discovery set

    AI search measurement becomes unreliable when the prompt set changes every time the results change. Maintain a stable benchmark set for trend analysis and a separate discovery set for emerging prompts, modifiers, personas, and fanouts. Promote a discovery prompt into the benchmark only when it represents a durable intent you want to track.

    For each benchmark observation, retain the full prompt, answer engine or interface, market, persona configuration, date, and result. Then evaluate:

    • Whether the brand or page appears in the answer.
    • Whether it is cited, merely mentioned, or omitted.
    • Whether the description is accurate and attached to the intended use case.
    • Which important fanout branches the cited content supports.
    • Which competitors, publishers, or evidence types occupy the missing branches.
    • Whether the intended audience receives a materially different answer.
    • Whether resulting visits or assisted conversions align with the target intent.

    Do not claim improvement after changing the prompts, persona, market, engine, and content at the same time. Keep the benchmark conditions visible, annotate changes, and compare like with like. The discovery set can remain fluid; the benchmark must remain interpretable.

    Also distinguish an exposure problem from an evidence problem. If a relevant page is never retrieved, investigate discoverability, internal linking, crawl access, entity clarity, and topic alignment. If it is retrieved but not used, inspect whether its claims are direct, current, specific, and supported. If it is cited inaccurately, improve the language and evidence around the misunderstood claim rather than publishing another generic page.

    Key takeaways

    • Prompt volume reveals recurring demand, but it does not establish business value, audience fit, or evidence readiness by itself.
    • Preserve raw prompts, then normalize the underlying job, constraints, decision stage, and audience context.
    • Map query fanouts to the supporting facts and subproblems an answer engine may need to resolve.
    • Separate observed fanouts from inferred branches so your strategy remains auditable.
    • Use intent hierarchies to decide which questions belong together and personas to identify when evidence or framing must change.
    • Prioritize content where demand confidence, strategic relevance, fanout leverage, and credible evidence meet.
    • Measure a stable benchmark prompt set separately from an evolving discovery set.

    Start with the prompt inventory already used in your reporting. Add the intent, persona, fanout, evidence, and decision fields above. Choose the most relevant cluster your team can support credibly, turn it into one answer-focused brief, and preserve the current benchmark before publishing. That gives you a clean line from demand signal to content decision to measurable result.

    References