Tag: Audience Research

  • How to Build an Integrated Search and Discovery Strategy

    How to Build an Integrated Search and Discovery Strategy

    An integrated search and discovery strategy starts with a practical observation: customers may encounter a brand on a recommendation platform, investigate it through an AI-generated answer, validate it on Google and convert through a paid or organic visit. Treating each of those encounters as a separate contest obscures how the decision develops.

    The useful question is therefore not whether SEO, paid search or social media should win the budget. It is which combination can create demand, answer questions, establish confidence and convert attention efficiently.

    Key takeaways

    • Plan around the customer’s decision process rather than treating search, social and AI as isolated channels.
    • Measure visibility and influence as well as clicks because many searches now end without a website visit.
    • Assign paid, organic, local and discovery media different jobs according to the market, customer and economics.
    • Manage brand visibility, media reach and post-click experience as one performance system.

    Why the SEO-versus-PPC contest no longer describes the market

    The traditional channel debate assumed that a customer entered a query, saw a reasonably stable results page and selected either an advertisement or an organic listing. Under that model, SEO and PPC could be evaluated as alternative ways to acquire substantially the same click.

    The article SEO vs. PPC Is Over: Why AI Makes Integration Essential describes a different environment. It reports that 68.01% of U.S. Google searches during the first four months of 2026 ended without a click, compared with 60.45% in 2024. It also cites Seer Interactive findings in which the average organic click-through rate for queries displaying AI Overviews fell from 1.76% to 0.61%. These are source-reported figures rather than independently verified measurements, but they illustrate why rankings and traffic can no longer provide a complete account of search performance.

    The same article cites SparkToro and Datos research spanning 41 platforms. In that research, Google accounted for 73.7% of desktop searches, while traditional search engines collectively represented about 80%. Commerce platforms accounted for roughly 10%, social platforms for 5.5% and AI tools for 3.2%. It further reported that Amazon, Bing and YouTube each handled more search activity than ChatGPT. The implication is not that Google has become unimportant. It is that information seeking is distributed across environments with different interfaces and forms of influence.

    Integration addresses two related forms of compression. AI-generated answers can satisfy some needs before a click occurs, while crowded results pages can push even a top organic result below advertisements, local features and other links. A brand must consequently earn recognition before the query, be credible within answer and validation surfaces, secure prominent access when commercial intent appears and make any resulting visit more valuable.

    Model the journey from passive discovery to commercial action
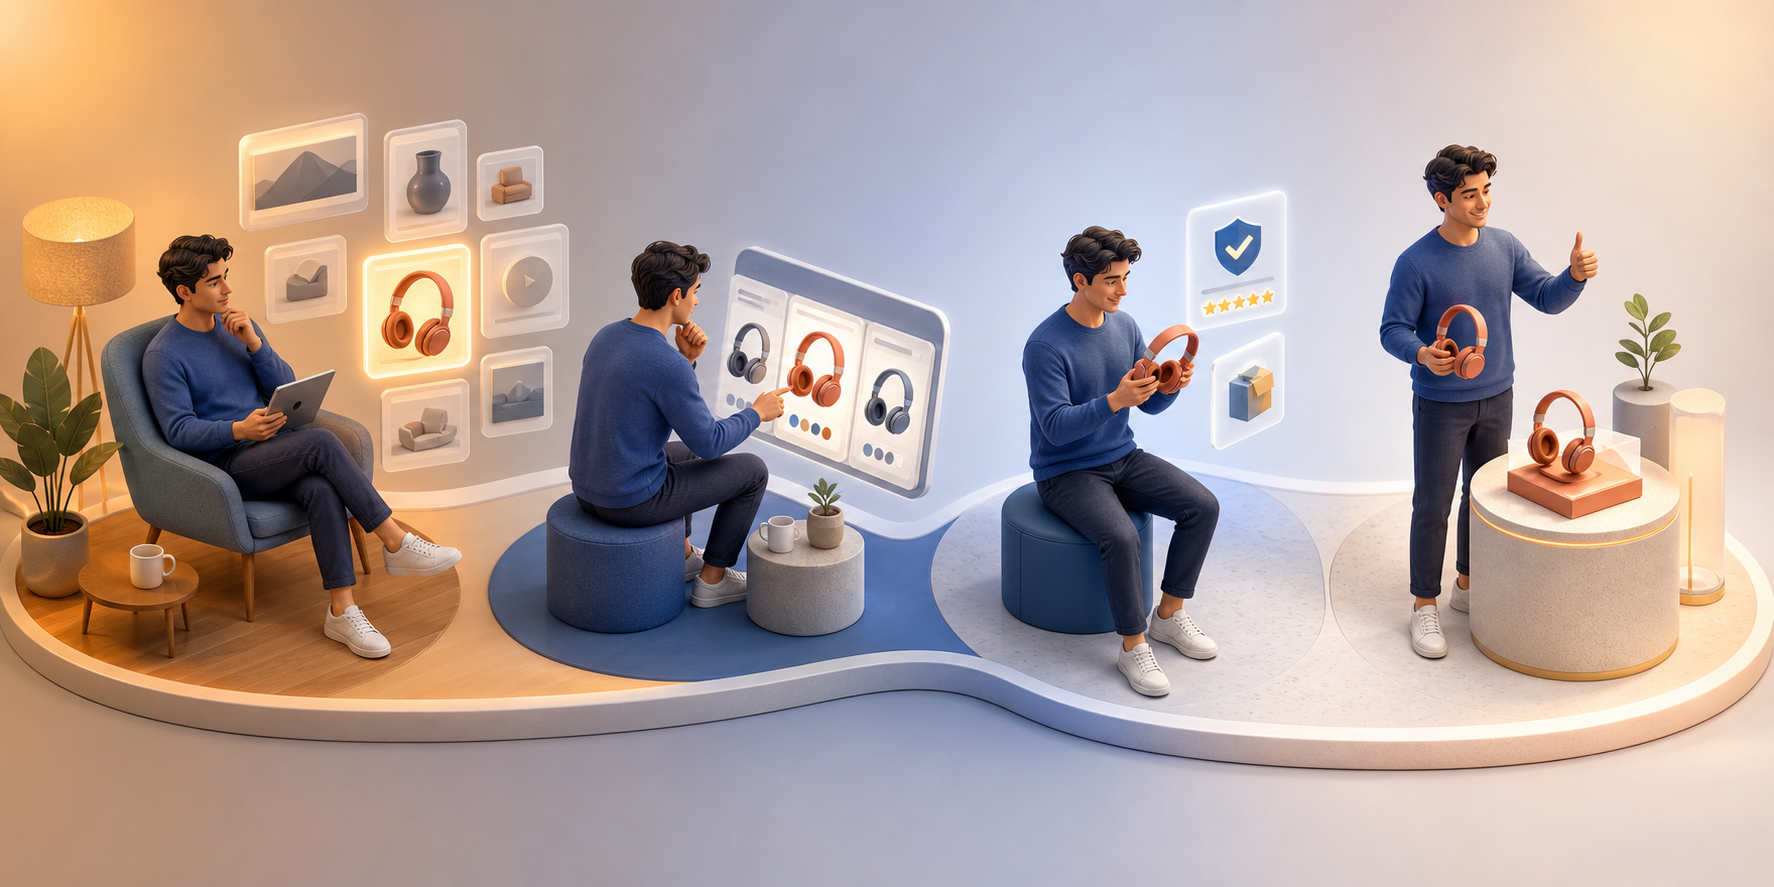
    One person progresses from noticing a recommendation to researching, comparing, validating, and making a purchase.

    The beginning of a buying journey may now be an unsolicited recommendation rather than an expressed query. Why Your Next Customer May Find You on TikTok Before Google explains how TikTok can infer interests from signals such as watch time, rewatches, pauses, shares and saves. The article also cites a Google executive’s statement that almost 40% of young people looking for somewhere to eat turn to TikTok or Instagram instead of Google Search or Google Maps.

    That pattern is especially relevant where appearance, atmosphere or demonstration affects confidence. The TikTok article identifies restaurants, hotels, beauty, fitness and retail as examples in which short-form video can create an initial preference before formal research begins. Google, Maps, reviews and a business’s website may then serve as confirmation and transaction surfaces.

    Decision stageCustomer behaviorPrimary strategic jobUseful measurement
    DiscoveryEncounters an idea without requesting itUse native video, creators, communities or editorial distribution to earn relevant attentionQualified reach, viewing depth, saves and subsequent brand interest
    ExplorationLooks for explanations, comparisons or possibilitiesPublish useful material that search engines, social platforms and AI systems can interpretTopic visibility, engaged visits, mentions and assisted actions
    ValidationChecks reputation, location, suitability and alternativesCoordinate organic results, local profiles, reviews, brand information and selective paid coverageBranded demand, profile actions, qualified inquiries and conversion paths
    Action and captureVisits, inquires, purchases or continues a longer evaluationReduce friction, clarify the offer and obtain permission for an ongoing relationship when appropriateConversion quality, acquisition cost, lead progression and customer value

    This model also turns discovery platforms into research inputs. The TikTok article points to Creator Search Insights as a source of rising topics, unanswered questions and content gaps. Those observations can inform search pages, FAQs, local content, editorial planning and product positioning. The purpose is not to duplicate one asset everywhere, but to carry a coherent answer across formats suited to each environment.

    Assign channels by the constraint they can resolve

    A fixed channel hierarchy fails because businesses need different volumes, types and timings of demand. The two client examples reported in SEO vs. PPC Is Over demonstrate the contrast.

    In the first example, an architect held top organic rankings for apparently valuable terms but received few leads. The article reports that advertisements, a search feature and local listings placed roughly 20 links ahead of the number-one organic result. Search Console showed about 300 monthly searches and a click-through rate near 1%, equating to approximately three clicks. Moving part of the SEO budget into paid search improved performance because the immediate problem was insufficient visibility where users were looking.

    The second example involved a clinical psychologist whose capacity could be filled with only two or three high-quality inquiries per week. According to the article, a focused combination of a rebuilt website, on-page and local SEO, a Google Business Profile and relevant citations produced enough visibility across Maps, local organic results and AI-generated results. Paid reach was unnecessary because the constraint was not lead volume; it was attracting a small number of suitable local prospects.

    These cases suggest a more disciplined allocation test. A business should identify whether its binding constraint is awareness, answer visibility, results-page prominence, local credibility, conversion capacity or lead quality. Paid search can bridge a prominence or timing gap. Organic and local work can build durable relevance and confidence. Recommendation media can introduce options before explicit demand exists. AI visibility can influence research even when no referral click follows.

    Budget should follow the constraint and the marginal value of resolving it, not a predetermined percentage for each channel. A top organic position with negligible exposure may be less useful than paid placement, while a low-capacity specialist may gain little from purchasing additional volume. The relevant outcome is qualified business contribution across the journey.

    Manage media economics and measurement as one system
    Several colored channel streams converge in a central measurement hub before continuing toward a customer outcome.

    Integration also changes how rising acquisition costs should be diagnosed. Why I See CPC Inflation Starting Before the Search Auction argues that cost pressure begins upstream when AI answers absorb clicks, organic traffic contracts and more advertisers pursue the remaining commercial opportunities. The article cites a WordStream cross-industry average cost per click of $5.42 and Stackmatix estimates that Google Search CPCs rose 14% to 18%. Those benchmarks may not describe every account, but the reported direction supports examining more than bids and ad copy.

    The CPC article organizes the response around brand, reach and experience. Brand activity can increase recognition across publications, communities, organic results and AI answers before an auction occurs. Reach management includes targeting, match types, creative, bidding automation and guardrails, as well as testing less-crowded inventory. The article proposes measured experiments involving Microsoft Advertising, Reddit, LinkedIn Thought Leader Ads, niche newsletters, connected television, podcasts and emerging AI search advertising rather than abandoning Google Search.

    Experience determines the value recovered from an acquired visit. The same source notes that landing-page experience contributes to Google’s Quality Score and argues that stronger pages can improve both conversion economics and auction competitiveness. For longer decisions, the page may also need to capture first-party permission or support a later return rather than forcing an immediate sale.

    Measurement should mirror these connected roles. Discovery reporting can examine attention quality and later changes in brand interest. Search reporting can separate informational, navigational and transactional demand instead of blending unlike queries. Conversion reporting can follow qualified leads or revenue beyond the first click. Controlled budget tests, consistent campaign naming and shared definitions of a qualified outcome can help distinguish genuine contribution from platform-claimed credit.

    No single metric will reconcile a journey distributed across recommendation feeds, AI answers, search features, advertisements and websites. The practical operating model is a shared evidence loop: discovery signals shape content, content strengthens validation, paid media covers consequential gaps, and conversion evidence informs the next allocation decision. As interfaces continue to change, organizations that maintain that loop will be better equipped to adapt without rebuilding strategy around every new platform.
    References

  • Why AI Assistant Usage Follows Different Daily Rhythms

    Why AI Assistant Usage Follows Different Daily Rhythms

    AI assistants may be software, but the people using them still follow schedules. That creates patterns in when AI tools attract attention, answer questions, and influence decisions.

    Try Profound Blog offers one central observation: every AI assistant has a daily and weekly rhythm, but that rhythm varies by platform, region, and user. The source does not provide supporting measurements, so the useful takeaway is a framework for investigation rather than a universal timetable.

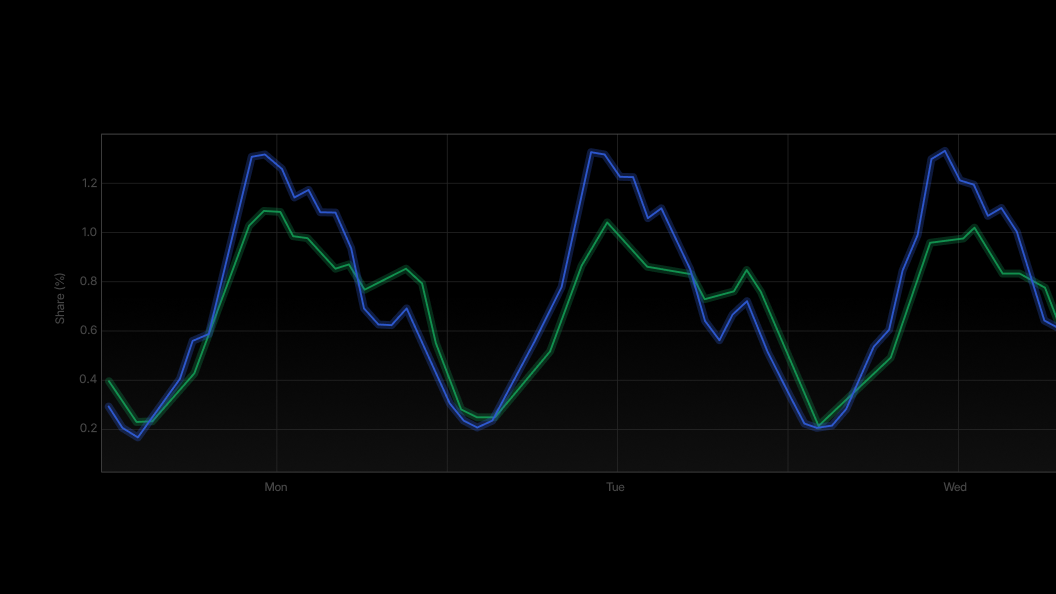
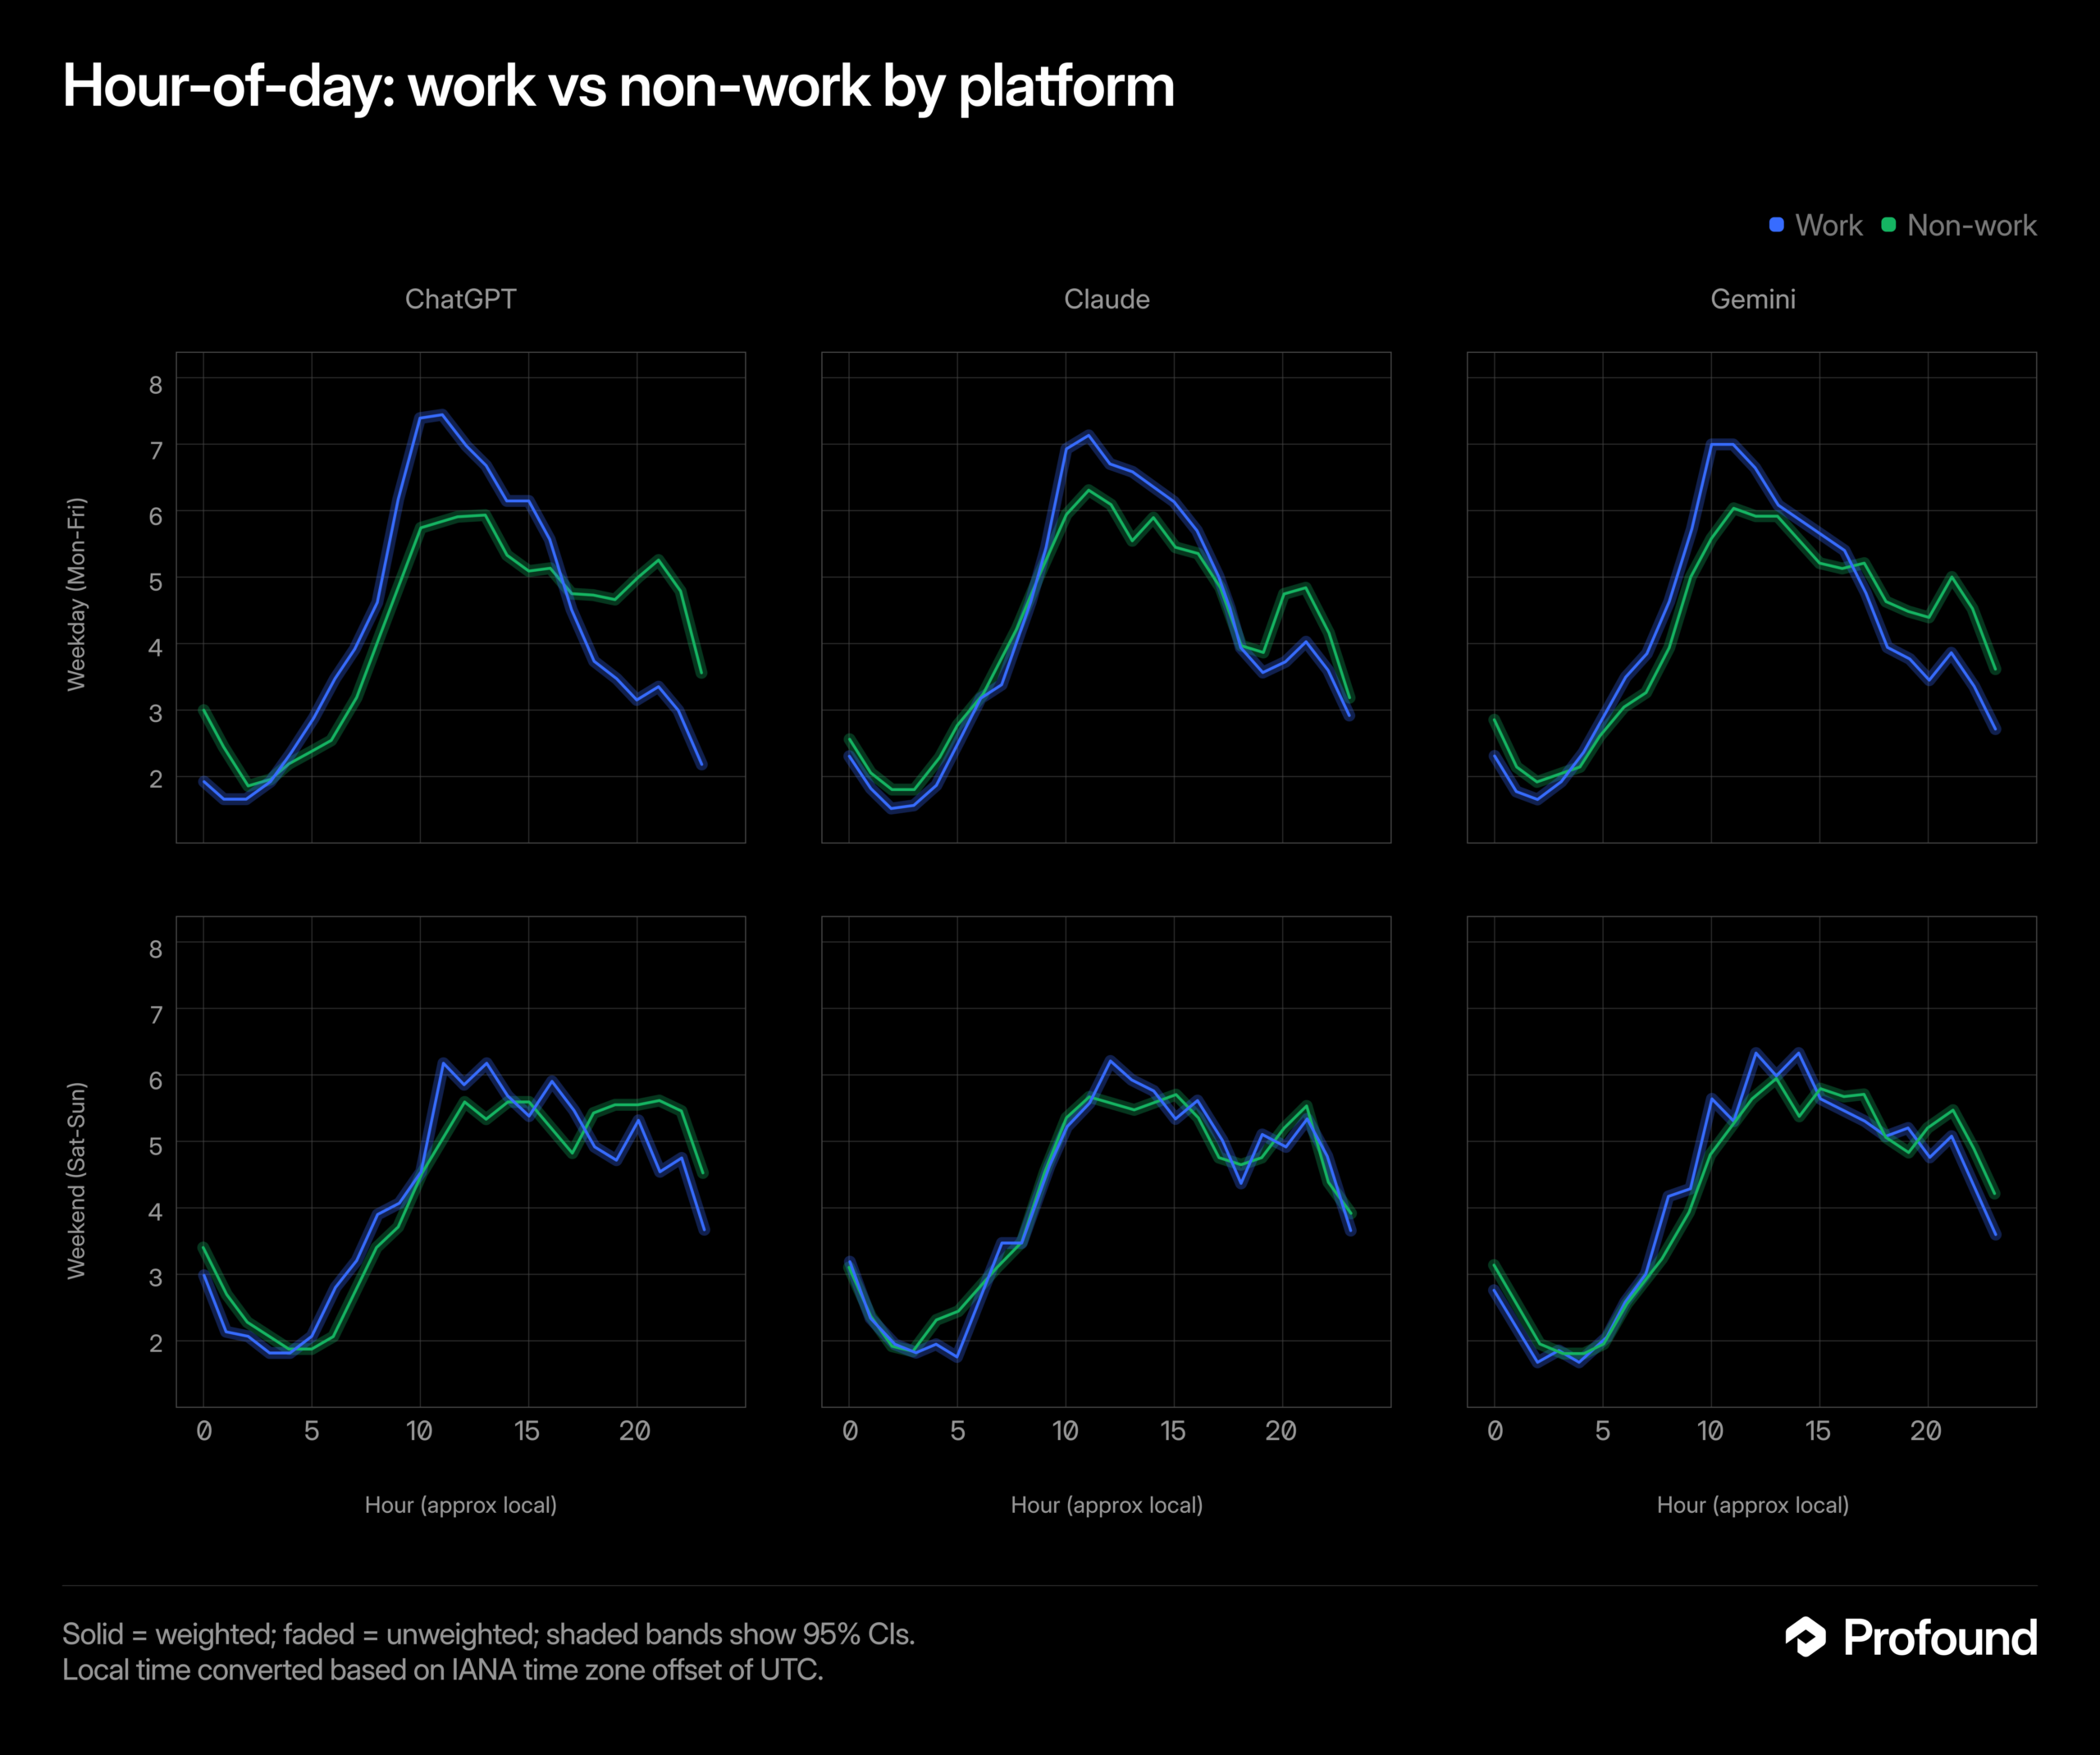
    Six line charts compare work and non-work hourly patterns for ChatGPT, Claude, and Gemini on weekdays and weekends.
    Blue work and green non-work lines show hourly patterns for ChatGPT, Claude, and Gemini, split into weekday and weekend rows, with most curves highest around late morning to afternoon.

    The rhythm belongs to usage, not the assistant

    An AI system does not begin a workday in the human sense. Any apparent schedule is more likely to reflect when people open a platform, what they use it for, and how it fits into their routines.

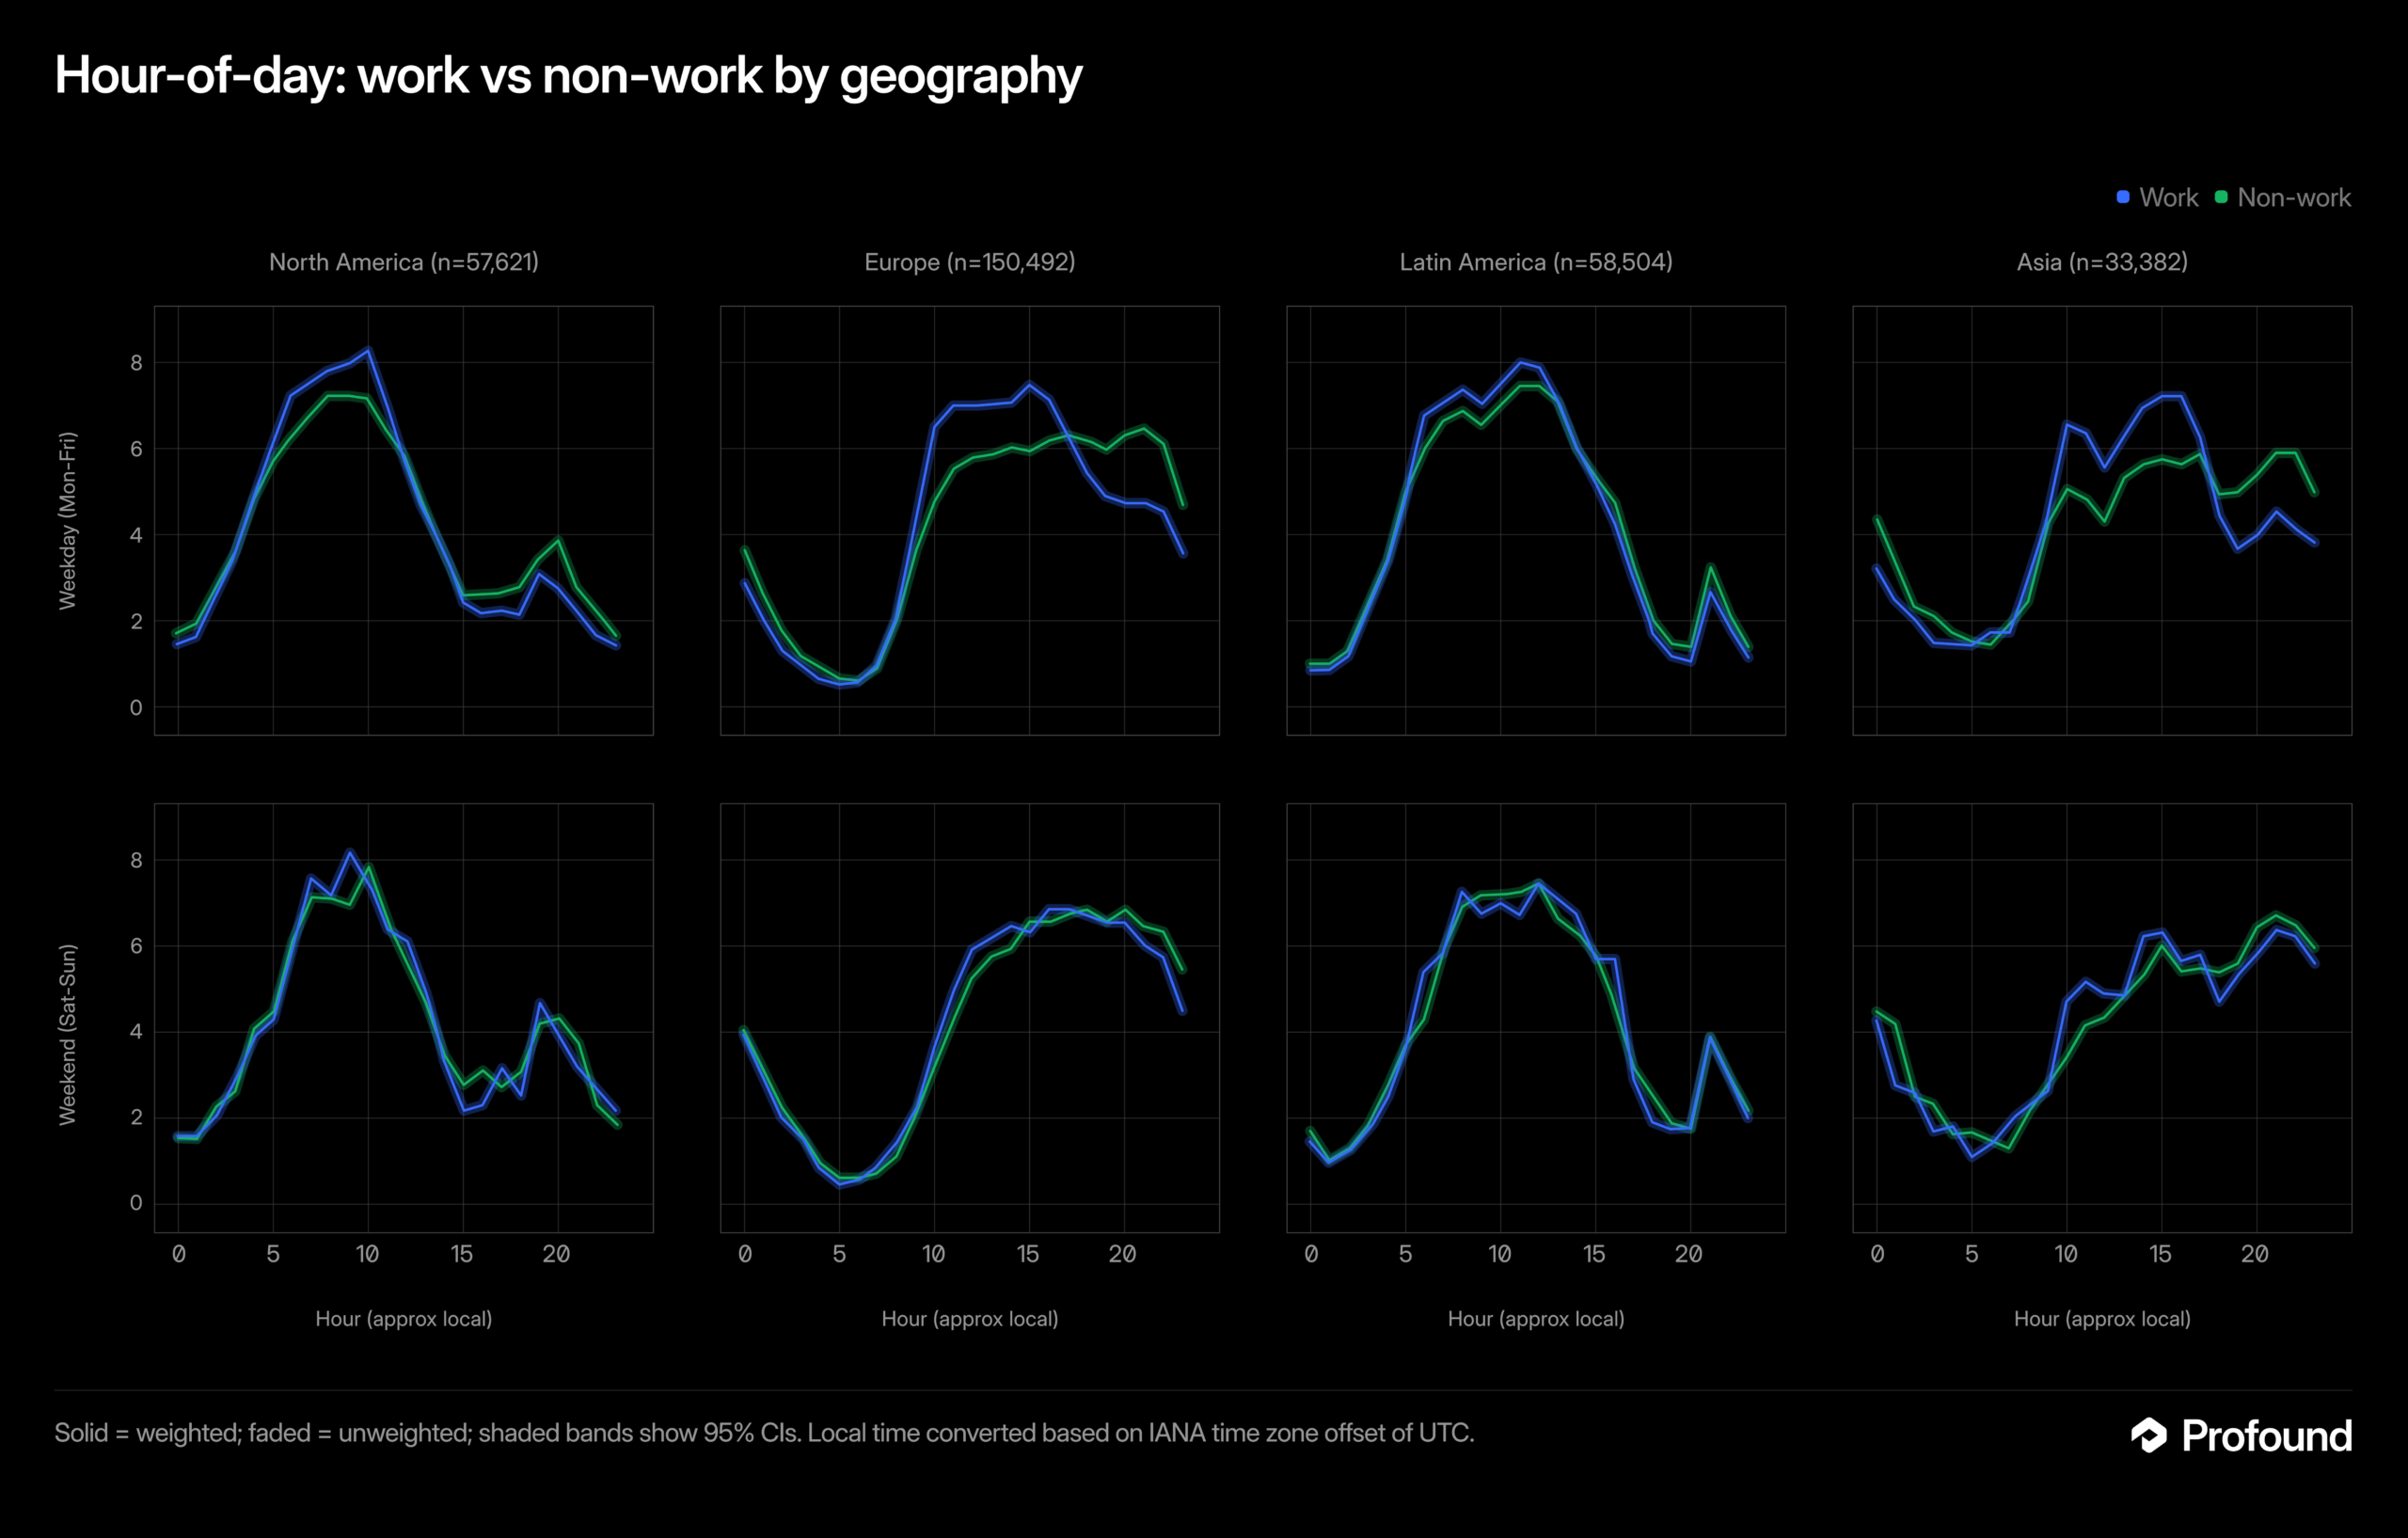
    Eight line charts compare hourly work and non-work patterns across four regions on weekdays and weekends.
    Blue work and green non-work lines trace hour-of-day patterns for North America, Europe, Latin America and Asia, split into weekday and weekend rows.

    A tool associated with professional tasks may see a different pattern from one used for personal questions. The distinction matters because a broad label such as “AI traffic” can hide meaningful differences among audiences and use cases.

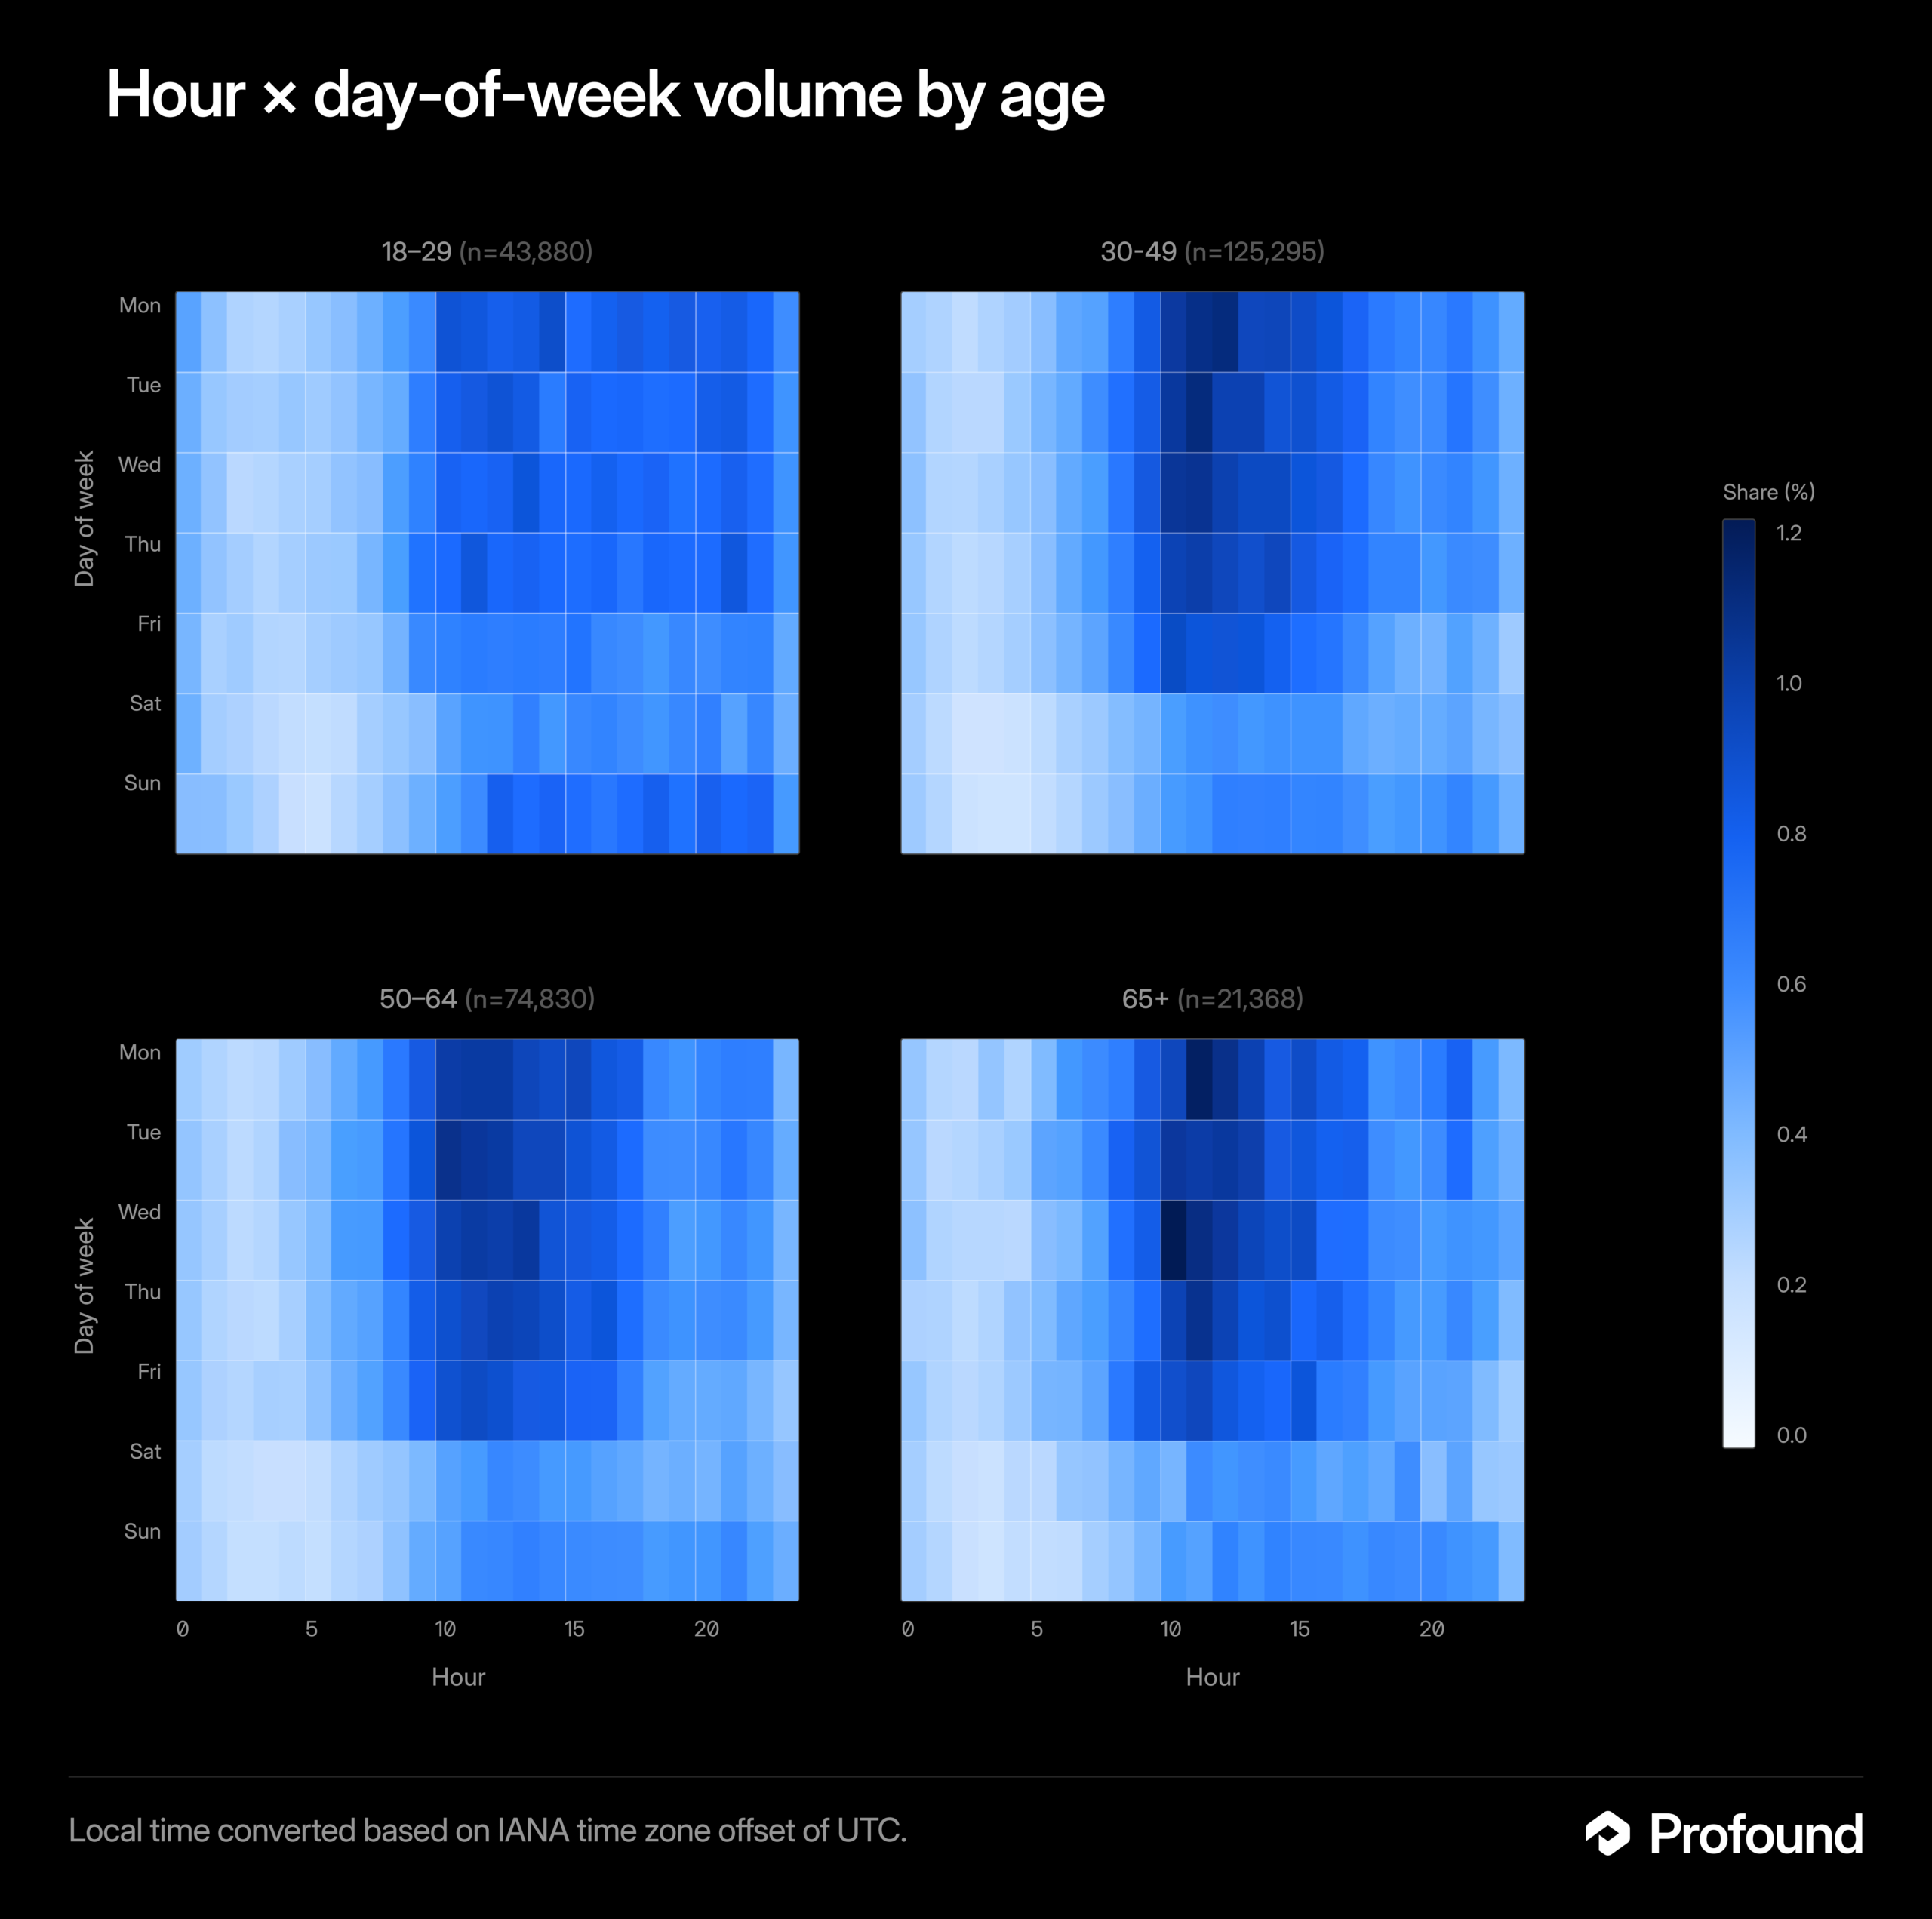
    Four blue heatmaps compare hourly, weekday volume shares across age groups from 18-29 to 65+.
    Four heatmaps plot share by hour and day of week for ages 18-29, 30-49, 50-64 and 65+, with the darkest weekday bands around late morning.

    Why one schedule cannot describe every audience

    The source specifically cautions that timing is not consistent across platforms, regions, or users. Each dimension can change how an observed pattern should be interpreted:

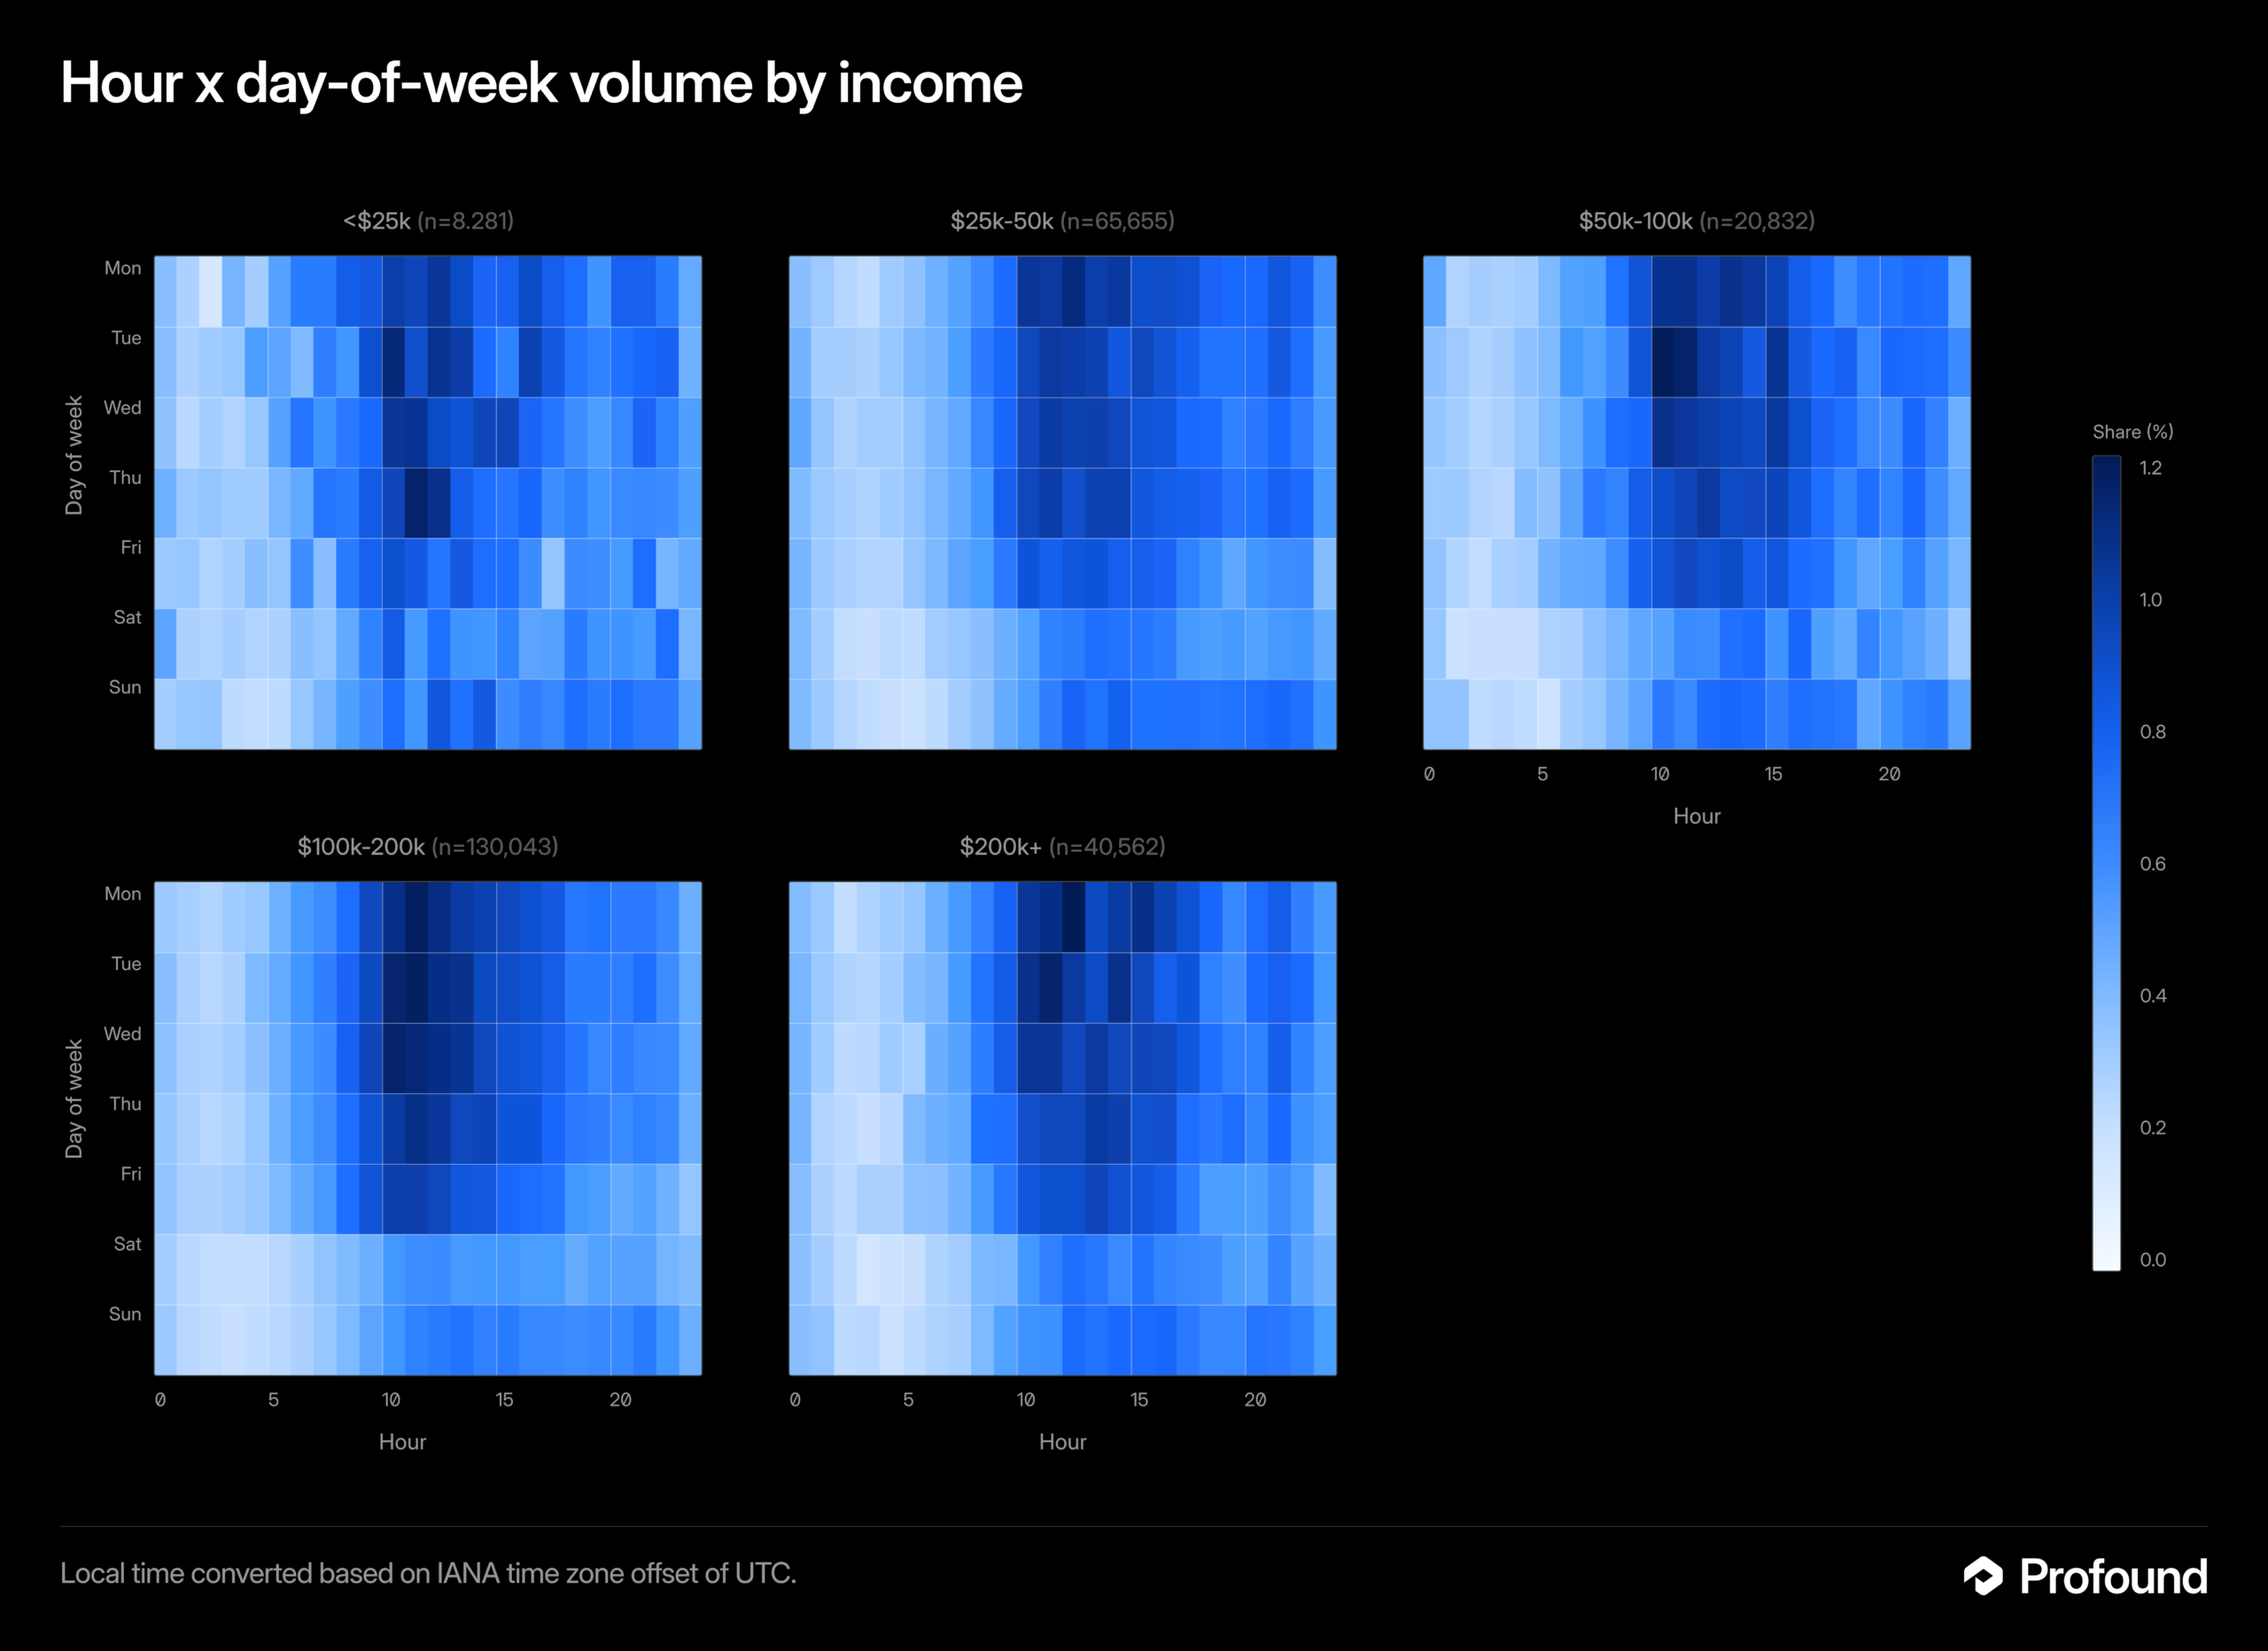
    Five heatmaps compare hourly, weekday volume shares across income brackets from under $25k to $200k+.
    The five blue heatmaps show share percentages by hour and day of week for income groups, with many darker cells appearing from late morning through afternoon.
    • Platform: Different products can serve different purposes and attract different usage habits.
    • Region: Local time, working patterns, and audience location can shift periods of activity.
    • User: Individual needs determine whether an assistant is used for work, study, research, planning, or another task.

    These variables make a single global “best time” an unreliable assumption. A pattern found in one segment should not automatically be applied to another.

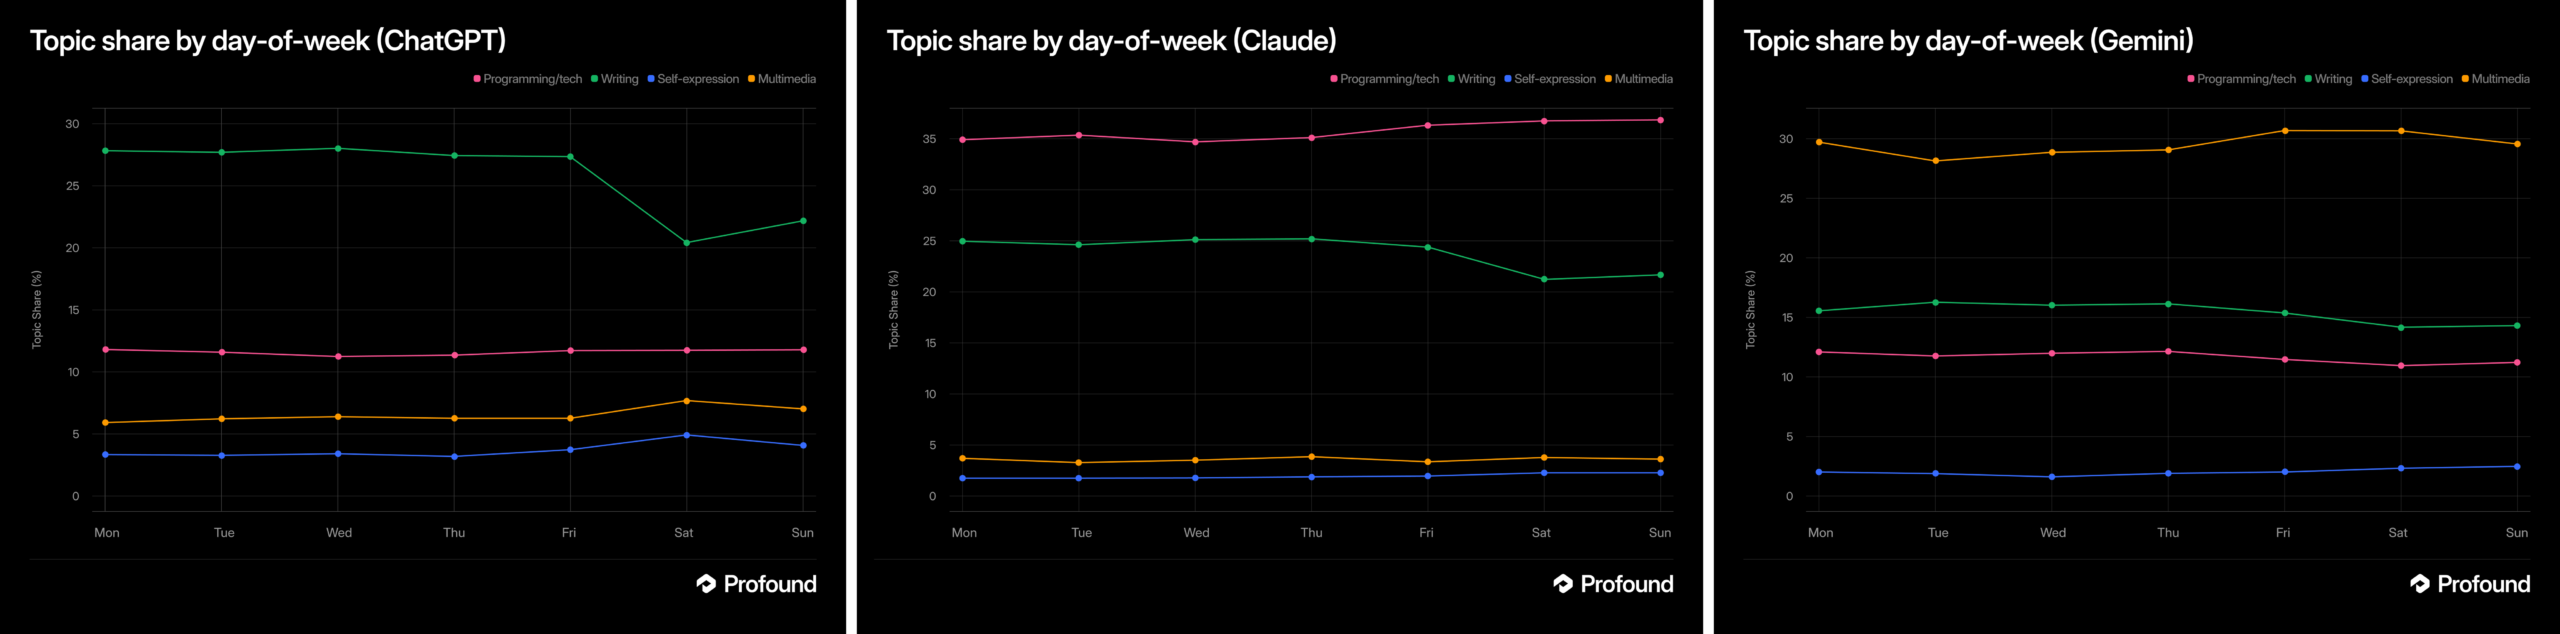
    Three line charts compare topic share by weekday for ChatGPT, Claude, and Gemini across four categories.
    Side-by-side weekday charts show writing highest for ChatGPT, programming/tech highest for Claude, and multimedia highest for Gemini, with weekend shifts.

    Key takeaways

    • AI assistant activity can form recurring daily and weekly patterns.
    • Those patterns may differ across platforms, regions, and individual users.
    • Timing should be evaluated within a defined audience and use case.
    • The source states the principle but does not supply data for specific hours or days.

    How teams can evaluate timing responsibly

    For marketers, publishers, and product teams, the practical response is to examine their own evidence. Analysis should begin with a clear question: which platform, audience, region, and outcome are being measured?

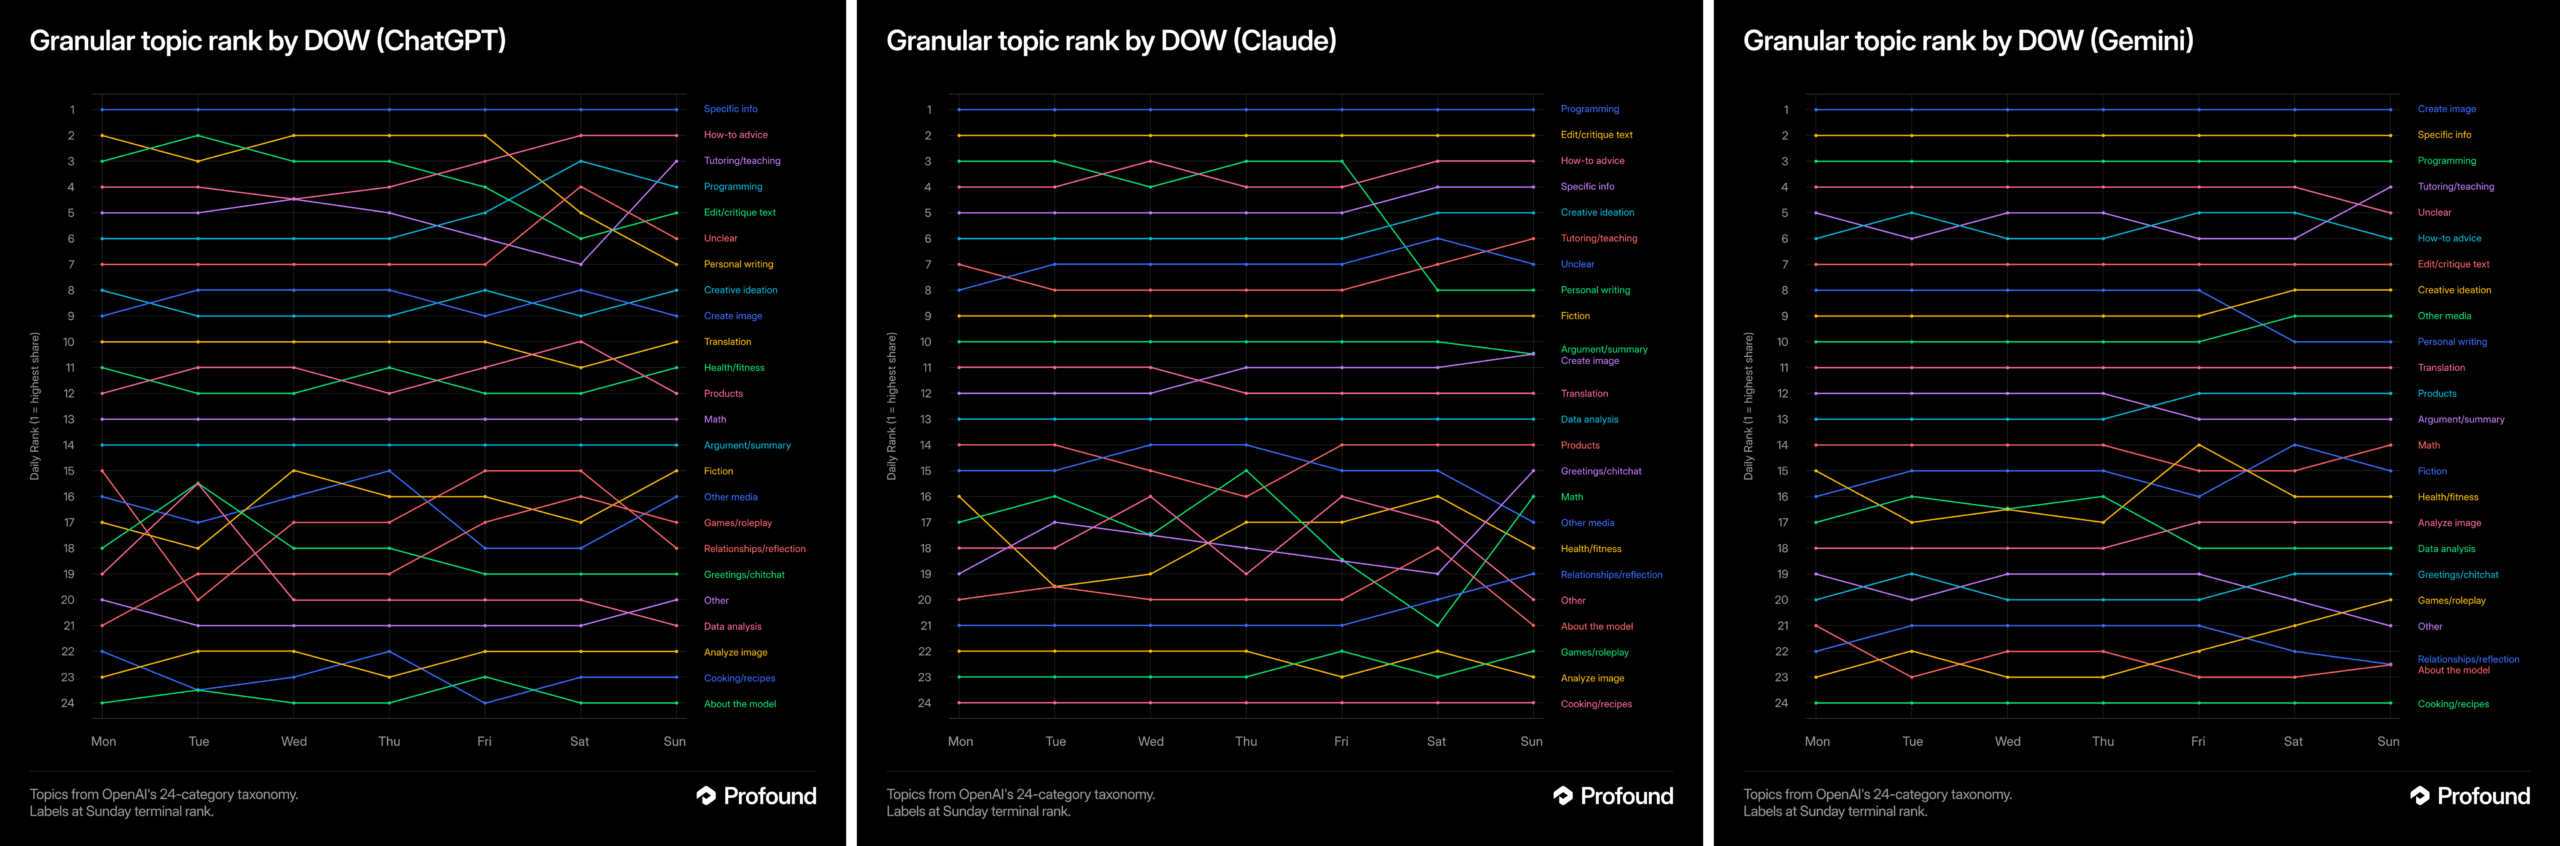
    Three dark line charts compare 24 topic rankings by day of week for ChatGPT, Claude, and Gemini.
    Side-by-side charts titled "Granular topic rank by DOW" trace colored topic rankings from Monday through Sunday for ChatGPT, Claude, and Gemini.

    Teams can then compare consistent time periods, use the relevant local time zone, and separate audience segments where possible. They should also distinguish between activity and impact. A busy period does not necessarily produce the most valuable visits, recommendations, conversions, or customer outcomes.

    Any apparent rhythm should be treated as a working pattern rather than a permanent rule. User behavior, product design, and the mix of use cases can change, so conclusions need periodic review.

    What the source does not establish

    Try Profound Blog does not identify peak hours, preferred weekdays, regional differences, or platform-specific results in the supplied material. It also does not describe a study or methodology. Claims about exact schedules would therefore go beyond the available evidence.

    The defensible conclusion is narrower: AI usage has timing patterns, and context determines what those patterns mean. Organizations that want actionable answers will need to measure the audiences and outcomes that matter to them.


    Inspired by this post on Try Profound Blog.


    crushpress.ai community screenshot
  • Three Google Updates Reshape Search Measurement for Publishers

    Three Google Updates Reshape Search Measurement for Publishers

    Three Google updates reported by CrushPress.AI affect different points in a publisher’s measurement workflow: assessing search demand, checking whether pages can appear in search, and tracking visits after a click.

    Together, the changes make some analysis easier, but they also underline an important distinction: demand, indexability, and on-site traffic are separate signals. Publishers need to read them in sequence rather than treating any one report as a complete account of search performance.

    Key takeaways

    • Google Trends now offers preceding-period comparisons that can put changes in search interest into context.
    • Search Console’s page indexing report resumed updating after a reported three-week delay, restoring fresher diagnostic information.
    • Google Search now sends AMP visitors to publisher-hosted pages instead of presenting cached pages within Google’s AMP viewer.
    • Google reportedly characterized the AMP change as a delivery and measurement update, not a ranking change.

    Google Trends adds context before content decisions

    A content strategist compares two abstract periods of search-interest patterns at a desk.

    Google Trends sits near the beginning of the measurement process. It indicates relative search interest, helping publishers evaluate whether attention around a term or topic is gaining momentum, declining, or following a recurring pattern.

    CrushPress.AI reported that new controls above the Trends timeline can surface changes for periods such as week over week, month over month, and selected year-over-year comparisons. A preceding period can also be overlaid on the chart with a comparison line. This reduces the work required to establish a historical baseline before interpreting a movement.

    The practical benefit is better timing context. A rise in current interest is more meaningful when compared with the immediately preceding interval, while a year-over-year view can help reveal whether apparent momentum may instead reflect seasonality. Trends still addresses audience interest rather than the performance of a publisher’s individual pages, so its findings should guide investigation rather than serve as traffic or ranking evidence.

    Fresh indexing data restores a missing diagnostic layer

    Search Console answers a different question: whether Google can find and index pages on a particular site. Its page indexing report separates indexed and non-indexed pages, provides reasons pages may not be indexed, and can display impressions alongside the indexing chart, according to the source report.

    CrushPress.AI reported that this report had remained stuck on June 11, 2026, for roughly three weeks. As of Friday, July 3, it was displaying information through June 29. The refresh matters because an outdated diagnostic view can make a recent publishing, crawling, or indexing problem difficult to distinguish from reporting latency.

    The episode also offers a measurement caution. When a reporting interface is delayed, the age of its latest data should be checked before teams infer that a recent technical change caused an indexing movement. With fresher data available, publishers can return to examining affected pages and the reasons Search Console assigns, while still separating reporting status from the underlying indexing status.

    Direct AMP visits simplify the post-click measurement path

    A mobile visit follows a single direct path from a search result card to a publisher page and measurement hub.

    The AMP update concerns what happens after a searcher selects a result. CrushPress.AI reported that Google Search now directs AMP users to the publisher-hosted AMP page rather than a cached version displayed through Google’s AMP viewer. Google told the publication that the change should simplify analytics and tracking while reducing some maintenance associated with supporting AMP content.

    This shift can make the measurement path easier to understand because the destination is again the publisher’s own host. It does not, however, establish that AMP pages will gain more visibility. The report explicitly said Google described the change as unrelated to ranking and said the serving and ranking treatment of AMP in Search and Discover would remain the same.

    The distinction is especially important because AMP’s broader search role has already diminished. The source noted that AMP no longer receives preferential treatment in Top Stories and that such pages are encountered less often than before. The update therefore looks less like a revival of AMP as an SEO advantage and more like a cleanup of delivery, ownership, and analytics for publishers that continue to use the format.

    A more coherent search measurement workflow

    Read together, the updates describe three successive layers of analysis. Trends helps establish whether an audience is searching for a subject. Search Console helps determine whether relevant pages are eligible to be discovered through indexing. Publisher analytics then records what visitors do after reaching the site, with the new AMP routing potentially making that last step less complicated.

    This sequence helps prevent common category errors. Increasing search interest does not prove that a site is indexed for the topic. Successful indexing does not guarantee impressions or visits. Cleaner AMP analytics does not indicate a ranking improvement. When the signals diverge, teams can investigate the layer where the break occurs instead of forcing all three into a single performance narrative.

    Publishers should watch whether the refreshed reports remain timely and whether direct AMP delivery produces cleaner on-site data in practice. The durable opportunity is a measurement process that connects market demand, technical visibility, and owned-site behavior while preserving the limits of each signal.

    References

  • Paid Campaign Measurement and Creative Testing That Works

    Paid Campaign Measurement and Creative Testing That Works

    Your ad dashboard says performance is improving, but pipeline and revenue are standing still. That usually means the campaign is being rewarded for activity that looks valuable inside the platform, or your creative tests aren’t different enough to reveal what buyers actually respond to.

    You can fix both problems with one operating system: define the business outcome first, measure the additional value your spend creates, and test creative concepts before polishing minor variations.

    Start with the business decision, not the platform metric

    A useful measurement plan begins with a decision. Are you deciding whether to increase a campaign’s budget, pause an audience, promote a creative concept, or change the conversion signal used for bidding? The answer determines which metric deserves authority.

    Separate your metrics into three layers:

    LayerWhat it tells youExamples
    Business outcomesWhether paid media created commercially useful resultsQualified opportunities, pipeline, closed revenue
    Optimization signalsWhat the ad platform can use to improve deliveryQualified leads, sales-accepted leads, purchases
    Diagnostic metricsWhy delivery or response may have changedClicks, click-through rate, landing-page conversion rate, cost per lead

    Business outcomes judge success. Optimization signals help the system find more promising users. Diagnostic metrics help you investigate. Trouble starts when a diagnostic metric becomes the goal simply because it updates quickly.

    Audit every primary conversion before trusting the total. If one person is counted as a lead, a qualified lead, and a sales-qualified lead, the dashboard may show three conversions even though the business acquired one prospect. Assigning a value to every stage can compound the distortion and produce an inflated platform-reported return.

    Choose one primary outcome for each bidding objective. Keep earlier and later funnel events available for observation, but don’t automatically include all of them in the same optimization total. When the final monetary value arrives too late, use relative values that reflect the observed quality difference between stages, then validate those values against actual pipeline and revenue.

    Measure the next dollar, not just the average dollar

    Two parallel channels compare a gray baseline flow with a second flow that produces additional gold customer tokens after extra spend is added.

    Average CPA answers a historical question: how much did all recorded conversions cost on average? It doesn’t answer the budget question: what did the additional conversions cost when spending increased?

    For that, track marginal CPA. Compare two observed spending levels and divide the additional spend by the additional conversions. Run the same comparison with qualified opportunities or revenue when those outcomes are available. If spend rises while qualified output barely moves, the average can still look acceptable even though the latest budget increase was inefficient.

    Maintain a baseline for each campaign, audience, or market before changing spend. Then record what moved after the change:

    • Additional spend
    • Additional unique conversions
    • Additional qualified leads or opportunities
    • Additional pipeline or revenue
    • Marginal cost per additional business outcome

    This comparison is more useful than celebrating a higher conversion count in isolation. It exposes diminishing returns and shows where another unit of budget is likely to do useful work.

    Be precise about what the evidence proves. Mapping CRM outcomes to campaigns shows which paid interactions are associated with pipeline. A controlled holdout or other credible baseline is needed to make a stronger causal claim about incrementality. Don’t label every attributed conversion incremental.

    Test creative concepts before testing cosmetic variations

    A creative workshop table displays three distinctly different campaign concept sets, with a smaller group of nearly identical color variations pushed aside.

    Five ads with the same promise, image, and audience aren’t five meaningful tests because the text color changed. Platforms can recognize near-duplicate assets, and flooding an account with them can fragment the budget and slow learning.

    A concept changes why someone should care. It might lead with a different problem, motivation, objection, emotional trigger, proof mechanism, or format. An execution changes how that concept is expressed: the opening line, pacing, visual treatment, or call to action.

    Phase 1: Find a concept worth scaling

    Build each macro test around a written hypothesis. Complete these fields before production:

    • Audience tension: What problem, desire, or objection are you addressing?
    • Angle: What distinct reason are you giving the audience to act?
    • Expected behavior: What should improve if the hypothesis is right?
    • Business safeguard: Which downstream quality metric must not deteriorate?
    • Learning: What decision will you make if the concept wins or loses?

    Mine customer reviews, sales conversations, support questions, and social comments for recurring language and concerns. The production doesn’t have to be elaborate. A simple asset with a specific, resonant message can teach you more than a polished asset built around a weak premise.

    Phase 2: Improve the winning execution

    Once a concept demonstrates value, test its components. Change hooks, pacing, calls to action, or presentation while preserving the core angle. This is where additional variations become useful: they help you refine a validated idea rather than asking a limited budget to evaluate many nearly identical guesses.

    Connect creative learning to pipeline quality

    A creative winner should survive more than a click-through-rate comparison. The ad that attracts the most leads may attract the wrong leads, while a lower-volume concept may generate more qualified pipeline.

    Preserve the creative, campaign, and audience identifiers when a prospect enters your CRM. Without that connection, downstream results collapse into a channel total and you lose the information needed to improve the message.

    1. Give every concept a stable identifier that remains consistent across its executions.
    2. Pass campaign and creative identifiers into the lead or customer record.
    3. Deduplicate people before counting funnel stages.
    4. Return qualified and revenue outcomes to your reporting system.
    5. Compare concepts on both response and downstream quality.
    6. Increase budget only when the additional business outcome remains economically sensible.

    This prevents two common mistakes: scaling ads that generate cheap but weak leads, and killing ads that produce fewer conversions but more valuable opportunities. CRM-to-campaign mapping is what lets you see the difference.

    Review creative and measurement together. Ask whether the concept was genuinely distinct, whether it received enough concentrated delivery to generate a useful signal, whether its downstream quality held up, and whether the next budget increase created enough additional value.

    Key takeaways

    • Use business outcomes to judge performance, optimization signals to guide delivery, and diagnostic metrics to explain changes.
    • Deduplicate funnel events so one prospect doesn’t become several conversions.
    • Compare marginal cost and incremental outcomes before increasing a campaign’s budget.
    • Test distinct creative concepts first, then refine the winning concept with execution-level variations.
    • Carry campaign and creative identifiers into the CRM so lead volume can be evaluated against pipeline quality.

    For your next review, pick one campaign and one creative concept. Reconcile its primary conversion with the CRM, calculate what the latest spend increase produced, and write the next creative hypothesis before requesting another batch of assets. That small discipline will make both your reporting and your testing more trustworthy.

    References

  • How Brand and Content Signals Earn Visibility in AI Search

    How Brand and Content Signals Earn Visibility in AI Search

    You can publish technically sound pages and still remain invisible in AI answers. The missing ingredient is often not another keyword variation. It is a clear brand identity, useful evidence, and enough credible connections for an AI system to understand when your brand belongs in the answer.

    Your job is to make that connection easy to retrieve and safe to repeat. That requires coordinated work across your website, structured data, customer-led content, and mentions on relevant third-party domains.

    Key takeaways

    • Define one consistent relationship between your brand, its category, its audience, and the problems it solves.
    • Turn real customer questions into complete answers, not thin FAQ fragments created to capture keywords.
    • Support important claims with original evidence, concrete examples, expert input, or clearly explained methods.
    • Build relevant third-party mentions that confirm what your own website says about the brand.
    • Measure brand demand, topical visibility, entity consistency, external mentions, and AI output instead of counting citations alone.

    Make your brand an entity AI systems can understand

    A central faceted object connects consistently to symbols representing a website, organization, products, audience, location, and people, while tangled duplicate shapes fade in the background.

    AI visibility starts with a basic question: what should your brand be known for? If your homepage describes a software platform, your social profiles call it a consultancy, and partner pages place it in a third category, the resulting identity is difficult to interpret.

    A strong brand signal has three qualities: salience, coherence, and relational density. Salience means the brand is associated with a topic even when a user does not search for its name. Coherence means descriptions and facts agree across locations. Relational density comes from credible connections to products, people, organizations, and subjects. These qualities can affect whether a brand is retrieved and confidently represented.

    Write a canonical identity statement before changing individual pages. Use this structure: [Brand] is a [category] for [audience] that helps with [problem] through [distinct method]. It is an internal reference, not necessarily homepage copy. Every public description should express the same essential relationships without repeating identical prose.

    Audit the homepage, About page, product or service pages, author biographies, social profiles, directory listings, partner biographies, and press boilerplate. Record the brand name, category, audience, core offer, location where relevant, and named experts shown in each place. Resolve contradictions before adding more content.

    Your structured data should confirm visible facts rather than introduce a second version of the business. Use the most specific applicable schema types and keep identity properties such as the organization name, URL, logo, and linked profiles aligned with the page. Connect articles to their real authors and products or services to the organization that provides them. Schema can clarify an entity, but it cannot create authority that the wider web does not support.

    Publish answers built from customer language

    Broad keyword lists rarely reveal the uncertainty behind a search. Customer questions do. More than 80% of AI Overview queries are informational, and most of those queries have search volumes below 1,000. That makes long-tail questions useful inputs even when conventional keyword tools show little demand.

    Begin with Google Search Console. Find queries that start with terms such as who, what, where, when, why, how, which, is, does, can, or should. Compare average position with click-through rate. A page receiving impressions for a relevant question but answering it only indirectly is a clear improvement opportunity.

    Then broaden the collection with People Also Ask results, support conversations, sales calls, on-site search terms, community discussions on Reddit, and available AI prompt data. Keep the wording customers use. It often exposes distinctions, objections, and comparison criteria that internal marketing language hides.

    1. Group questions by the decision or task behind them, not merely by shared words.
    2. Assign each group to the page best positioned to give a complete answer.
    3. Open with a direct response that makes sense without the surrounding page.
    4. Add the conditions, evidence, examples, limitations, and next action a reader needs.
    5. Link to supporting pages only when they resolve a related question or substantiate a claim.
    6. Review unanswered questions from search and customer conversations as an ongoing editorial input.

    A useful answer block is specific enough to stand alone but substantial enough to deserve retrieval. For example, do not answer “Does this platform support enterprise teams?” with “Yes.” Explain which team needs it supports, what the relevant workflow looks like, what constraints apply, and where the reader can verify the details.

    Do not manufacture dozens of near-duplicate FAQ entries. Generic copy creates little reason for a retrieval system to select your page over an established alternative. Original data, documented processes, expert explanations, worked examples, and candid limitations make an answer harder to replace.

    Earn corroboration beyond your own domain

    Light beams from separate publication, microphone, forum, review, research, and partner symbols converge around a central sphere beneath a retrieval lens.

    Your website can declare what the brand is. Independent domains help confirm it. One reported estimate places about 85% of brand mentions in AI systems on external domains. The practical lesson is not to chase mentions everywhere. It is to become present in the places that already carry meaning for your category.

    Build a relationship map around your priority topic. Include the publications, professional communities, subject experts, partners, integrations, comparison pages, directories, and customer organizations that a buyer would reasonably consult. For each relationship, identify why the connection is real and what useful asset could support it.

    A strong external mention might come from expert commentary, a partner integration page, a customer example, a useful community answer, an industry glossary, or a benchmark others can reference. The surrounding context matters. A relevant paragraph that accurately connects your brand to its field is more useful than an isolated name dropped into an unrelated page.

    Check how third parties describe you. Correct outdated names, categories, URLs, executive details, and product descriptions where you have a legitimate route to do so. Repeated inconsistencies weaken the same coherence you worked to establish on your own site.

    This is also why brand building remains valuable when search behavior fragments across engines, answer interfaces, and communities. A memorable name and trusted relationships can influence a decision even when the user never clicks your page. In that environment, brand memory travels farther than an individual ranking.

    Measure the signals that lead to AI visibility

    A citation is an observable result, not a diagnosis. It does not reveal whether your brand was retrieved because of its own content, an external mention, established familiarity, or a combination of signals. Citation counts alone can therefore send your team toward superficial tactics.

    SignalWhat to inspectWhat to do next
    Entity coherenceConflicting names, categories, descriptions, people, or URLsCorrect the highest-authority pages and profiles first
    Brand demandBranded queries and searches combining the brand with a topicStrengthen distribution around topics already gaining recognition
    Topical salienceNonbranded impressions for priority questions and categoriesImprove the canonical page and its supporting content
    Content coverageImportant customer questions with incomplete or scattered answersConsolidate each cluster into the most useful destination
    External corroborationRelevant mentions, their context, and factual consistencyDevelop credible relationships and correct material errors
    AI outputWhether the brand appears, how it is described, and which URLs are citedTrace gaps back to content, identity, or external evidence

    Maintain a stable set of representative prompts for your main audience problems. When you check them, record the exact prompt, platform, date, brand inclusion, description, cited URLs, and visible competitors. Use the record to notice patterns, not to claim universal performance from a single response. AI outputs can vary, so repeated observations are more useful than isolated wins.

    Start with the topic most important to your business. Align the brand identity, map the real questions around it, strengthen the canonical answer, and pursue corroboration from a credible external entity. That creates a repeatable operating system for visibility rather than a collection of disconnected AI search tactics.

    References

  • How to Build an SEO Strategy for AI Buyer Journeys

    How to Build an SEO Strategy for AI Buyer Journeys

    If your SEO plan ends at “answer the query,” you may win a ranking and still lose the buyer. People often search with a solution already in mind, even when they have not fully examined the problem or the alternatives.

    Your content needs to do two jobs: satisfy the immediate intent and help the reader make a better decision. That combination is especially important when an AI-generated answer can handle the basic summary before anyone visits your site.

    Key takeaways

    • Map the buyer’s problem, assumed solution, and credible alternatives instead of targeting isolated keywords.
    • Answer the stated query before introducing a different path; otherwise, the page feels evasive or promotional.
    • Build depth with decision criteria, trade-offs, firsthand experience, and next-step guidance rather than extra word count.
    • Match calls to action to the reader’s stage, from a diagnostic tool for early research to a consultation or purchase for late-stage demand.
    • Measure assisted journeys and qualified outcomes, not rankings and last-click conversions alone.

    Map the decision behind each search query

    A buyer stands at a three-way junction connecting an obvious solution with alternative routes and symbols of deeper investigation.

    A keyword tells you what someone typed. A journey map tells you what they are trying to change, what solution they currently believe in, and what uncertainty is keeping them from acting.

    Start with one commercially important problem. Then collect the searches that can appear before, during, and after the obvious product comparison. These journey-adjacent queries often look unrelated in a keyword tool, but they belong to the same decision.

    Query signalWhat the buyer may be thinkingUseful content response
    Problem-led: “How do I reduce lawn maintenance?”I want an outcome, but I have not chosen a solution.Explain the available paths, their trade-offs, and who each one suits.
    Operational: “How often should I cut grass?”I may still be trying to solve the problem myself.Answer the task, then show when a tool or service becomes worthwhile.
    Category-led: “Robot lawnmower price”I recognize a solution and need help evaluating it.Cover total decision criteria, limitations, and alternatives to ownership.
    Comparison-led: “Robot mower vs. lawn service”I am actively weighing different approaches.Use a balanced comparison tied to property, effort, control, and support needs.
    Branded research: “[Brand] reviews” or “[Brand] competitors”I know the brand but remain open to evidence or another option.Provide verifiable proof, candid constraints, and a clear fit assessment.
    Branded transaction: “[Brand] buy”I have probably made the decision.Remove friction and keep alternative messaging secondary.

    The opportunity is usually greatest before the final branded transaction. Someone researching reviews, costs, methods, or competitors is still testing assumptions. A useful page can introduce an option the buyer had not considered without ignoring the question that brought them there.

    For each priority problem, write down three statements: “The buyer wants…,” “The buyer currently assumes…,” and “The buyer may not know….” Those statements give your content team a stronger brief than a primary keyword and target word count.

    Build a content system that can redirect the journey

    Interconnected content modules guide several buyers from broad discovery through deeper resources toward a decision point.

    Journey-aware SEO is not one oversized guide. It is a connected set of pages that serve different levels of awareness while moving the reader toward the next useful question.

    1. Create a problem hub. Explain the outcome the reader wants, the main causes or constraints, and the broad solution categories. Keep it neutral enough to earn trust.
    2. Publish intent-matching pages. Build focused pages for the searches you already know matter: costs, reviews, comparisons, implementation questions, and product use cases.
    3. Add alternative-path pages. Compare approaches the buyer may not yet view as competitors. A service can compete with software, ownership can compete with rental, and a paid offer can compete with a do-it-yourself process.
    4. Connect the pages deliberately. Link from the direct answer to the relevant alternative, then from the comparison to evidence, tools, case examples, and commercial pages.
    5. Assign one next step to each page. Decide what the reader should do after learning: diagnose the problem, compare options, calculate cost, read an experience, request help, or buy.

    The order matters. A page targeting “how often to cut grass” should answer that question before presenting a robot mower or lawn service. Once the reader has the answer, you can explain the conditions under which doing the work personally becomes inconvenient. The offer then appears as a relevant decision path rather than an interruption disguised as advice.

    Use internal-link language that describes the decision waiting on the next page. “Compare the cost of a mower with a recurring service” is more useful than “learn more.” It sets an expectation for the reader and makes the relationship between the pages explicit.

    Go deeper than the answer an AI can summarize

    AI summaries can cover the first layer of a question. Search behavior is also becoming more conversational, with people supplying more context in longer, more detailed queries. A page that merely defines the topic or repeats common advice gives the reader little reason to visit, trust, or cite your brand.

    Depth is not length. A deep page removes uncertainty that a short answer leaves behind. After the direct answer, add the information a person needs to make or defend a decision:

    • Decision criteria: the conditions that should change the recommendation.
    • Trade-offs: what the reader gains, gives up, pays for, or must maintain.
    • Fit and non-fit: who benefits from an option and who should choose something else.
    • Experience: what happened during implementation, what was unexpectedly difficult, and what changed after use.
    • Evidence: named methods, transparent examples, attributable claims, and limitations.
    • Next questions: the issues a careful buyer should investigate before acting.

    Human experience is particularly valuable in purchase decisions because buyers want to know what using a product or service was actually like. Capture that experience with structured interviews, customer stories, screenshots, demonstrations, expert commentary, or original analysis. Do not turn a testimonial into universal proof. Keep the context that explains why the outcome occurred.

    Make the resulting page easy to parse. Use a descriptive heading for each decision, answer it directly in the opening sentence, and keep supporting detail close to the claim. Define ambiguous terms. Name the compared options consistently. A person should be able to scan the page and understand the decision path without reconstructing it from scattered paragraphs.

    Structured data comes after this editorial work. Mark up information that is genuinely present and visible, such as organization details, breadcrumbs, product information, or a real question-and-answer section. JSON-LD can clarify entities and relationships; it cannot turn generic content into original expertise.

    Turn broader discovery into a measurable, ethical path

    A journey-interrupting page should not force every reader toward the same conversion. Match the offer to the amount of commitment the query implies. Early problem research may call for a checklist, assessment, template, calculator, webinar, or email course. A comparison page can lead to a detailed case example or fit guide. A late-stage product page can ask for a demo, consultation, trial, or purchase.

    Measure the system at three levels. First, check whether the content is being discovered for problem-led, comparison, and branded research queries. Second, inspect whether readers continue to the intended decision page or use the supporting tool. Third, connect those journeys to qualified leads, trials, sales, or another business outcome. Assisted conversions matter because the page that changes the buyer’s frame may not be the final page visited.

    Review weak pages by asking a diagnostic question rather than adding more copy. If impressions are low, the query set or internal linking may be incomplete. If people arrive but do not continue, the alternative may appear too early, feel irrelevant, or lack evidence. If engagement is healthy but commercial outcomes are poor, the call to action may ask for more commitment than the reader is ready to give.

    Use stricter guardrails when the decision affects health, finance, education, or a career. Present alternatives in proportion to the evidence. State meaningful risks and limitations. Do not position a product as a substitute for professional care or imply that one path fits everyone. Health-related promotions also need appropriate legal and subject-matter review, including attention to FDA and FTC requirements. Responsible journey expansion gives the reader more agency; it does not exploit uncertainty.

    Start with one product line and one problem this week. Map the assumed solution, identify one credible alternative, and upgrade the relevant page with a direct answer, decision criteria, honest trade-offs, and a stage-appropriate next step. That small cluster will show you where a broader AI-search content strategy deserves investment.

    References

  • How to Build Search Visibility Across Google and AI

    How to Build Search Visibility Across Google and AI

    Your pages can rank in Google while your brand remains absent from AI recommendations. The reverse happens too: buyers hear your name in communities, search for confirmation, and find thin pages, inconsistent claims, or results that fail to answer the decision in front of them.

    You do not need separate strategies for every discovery channel. You need one evidence system that works before a search, during Google validation, and when an AI system assembles an answer. The framework below will help you find the weak layer and invest there instead of treating every visibility problem as a ranking problem.

    Key takeaways

    • Plan for three moments: pre-search discovery, search confirmation, and AI synthesis.
    • Make important pages explicit about the entity, problem, audience, evidence, alternatives, and limitations.
    • Earn credible mentions in the communities and publications where buyers actually narrow their options.
    • Do not confuse AI training, current data access, and citation retrieval; each affects visibility differently.
    • Track branded demand, Google performance, AI inclusion, citation patterns, and language variants as separate signals.

    Map the three moments that create a buyer’s shortlist

    For many considered purchases, the first meaningful search is no longer a broad category query. A buyer may already have encountered several names through social feeds, specialist publications, peer groups, review discussions, or Reddit. By the time that person reaches Google, the query may be a brand review, a comparison, or a check for a specific concern. In other words, the mental shortlist often forms before the Google query.

    AI discovery adds another route through the same decision. A person can ask for recommended options, a comparison, or an explanation without visiting a conventional results page. The system may then combine information from brand-owned pages, independent coverage, community discussions, and other retrievable material.

    Decision momentWhat the buyer is doingWhat you need to provide
    Pre-search discoveryLearning the category and noticing possible optionsUseful participation, credible mentions, memorable problem-brand associations, and distribution where the audience already gathers
    Search confirmationChecking a brand, claim, comparison, reputation issue, or purchase concernClear owned pages, accurate third-party results, direct answers, and enough detail to support a decision
    AI synthesisAsking a system to explain, compare, shortlist, or recommendUnambiguous entity information, substantive evidence, independent corroboration, and passages that can be understood outside their surrounding page

    This model gives you a better diagnosis than a visibility score alone. If you rank for unbranded category terms but branded searches and direct visits remain weak, your pre-search presence may be the constraint. If people search for you but hesitate after landing, the confirmation layer is failing. If Google performs well but AI answers omit or misdescribe you, inspect whether your evidence is explicit, consistent, independently supported, and available in the contexts those systems retrieve.

    Do not assume absence from an AI response proves a single cause. The system may not have retrieved the relevant page, may not have found enough corroboration, may have interpreted the request differently, or may have selected a different answer on another run. Look at the citations and competing entities before choosing a remedy.

    Turn important pages into evidence Google and AI can use

    An abstract web page organizes demonstrations, sources, comparisons, and expert evidence for use by search and AI systems.

    A page can be technically indexable and still be difficult to use as evidence. The usual problem is not a missing keyword. It is missing meaning. The page never states exactly what the company or product is, whom it serves, which problem it solves, when it is appropriate, or where its limitations begin.

    That ambiguity matters in both search environments. Google has to decide which query and intent the page deserves to serve. An AI system has to extract claims, connect them to an entity, weigh them against other material, and assemble a useful answer. Clever brand language that avoids plain definitions makes both jobs harder.

    Use a decision-first page pattern

    1. Name the decision. Put the real question in the title, opening, or primary heading. A comparison page should identify the alternatives. A service page should name the problem and intended customer.
    2. Define the entity plainly. State what the company, product, service, person, or place is before introducing slogans or benefits.
    3. Set the scope. Identify relevant audiences, use cases, regions, languages, product versions, or other conditions. A claim without its boundary is easier to misunderstand.
    4. Explain the reasoning. Show why an option fits one situation and not another. Include tradeoffs, constraints, and unsuitable cases instead of presenting every feature as universally positive.
    5. Add experience that changes the decision. Reviews, interviews, support questions, community discussions, and customer language can reveal setup friction, recurring objections, unexpected limitations, and the circumstances behind a positive or negative outcome.
    6. Answer the next question. Connect the page to pricing, compatibility, implementation, alternatives, policies, or supporting explanations when those details determine the next step.

    Firsthand detail is especially valuable for subjective decisions. Official pages often describe capabilities, while community conversations explain what using the product felt like and why someone preferred one option. That is a major reason experience-rich discussions can become useful retrieval material. You can bring comparable depth to your own site through genuine reviews, interviews, demonstrations, support insights, and transparent explanations. Do not imitate the tone of a forum or manufacture customer stories.

    Keep the entity consistent across the site

    Check whether your homepage, about page, product pages, author profiles, help content, titles, internal links, and JSON-LD describe the same relationships. Product names, organization names, URLs, service areas, and category labels should not drift from page to page.

    Structured data should confirm what the visible page already establishes. It can make an explicit relationship easier to interpret, but it cannot turn vague copy into evidence or create independent authority. If the markup says one thing and the page implies another, fix the underlying content first.

    Review each priority page at the passage level. Copy a key paragraph into a blank document and ask whether a reader could still identify the entity, claim, scope, and supporting reason. If the paragraph depends on a logo, navigation label, or unexplained pronoun, rewrite it so the meaning survives extraction.

    Earn the mentions that happen before someone searches

    Publishing more pages will not place your brand into conversations occurring elsewhere. That requires audience research, listening, credible participation, and distribution. The objective is not to spread a link across every platform. It is to become relevant in the few environments where your buyers learn the category and narrow their options.
    1. Map decision environments. Identify the communities, professional groups, creators, specialist publications, review spaces, and comparison sites that appear while buyers investigate the problem.
    2. Record the questions that recur. Separate category education, implementation concerns, comparison questions, complaints, and brand-validation queries. These are different content and participation opportunities.
    3. Set up listening. Watch for the problem language, category terms, competing approaches, and your brand name. A timely, complete answer is more useful than a promotional interruption.
    4. Contribute without forcing the brand. Answer the question, disclose your connection when relevant, and mention your product only when it genuinely belongs in the answer.
    5. Build publication credibility. Give editors and specialist publishers a defensible insight, explanation, example, or point of view rather than asking for a context-free mention.
    6. Return what you learn to the site. When the same objection or misunderstanding keeps appearing, update the appropriate owned page so future searchers find a direct response.

    Reddit deserves attention only when your audience uses it for relevant decisions. The claim that a model was trained on Reddit is not, by itself, a reason to launch a subreddit or manufacture posts. Training, licensed or current access, and retrieval for citations are separate mechanisms. Training can influence general patterns without preserving a specific thread as a retrievable memory. Current access can expose newer discussions. Retrieval can surface a thread because it answers the immediate query.

    That distinction changes the action. You cannot reliably place a sentence into a model’s memory by posting it. You can create or support a genuinely useful public discussion that people find, reference, and potentially retrieve later. An empty product subreddit, scripted endorsement, or coordinated pile of repetitive comments supplies neither trustworthy experience nor durable community value.

    Choose platforms by behavior, not fashion

    Evaluate each platform against a short scorecard:

    • Decision relevance: Are people asking questions that affect a shortlist or purchase?
    • Audience fit: Are the participants actual users, buyers, advisers, or credible peers?
    • Contribution fit: Can your team answer usefully without turning the interaction into an advertisement?
    • Experience depth: Does the environment support reasoning, tradeoffs, and real usage details?
    • Discoverability: Can useful discussions continue to be found through site search, Google, links, or AI retrieval?
    • Continuity risk: What happens if the platform’s popularity, policies, or search visibility changes?

    A fashionable platform with weak decision relevance is a distribution distraction. A smaller specialist community where buyers openly compare options may contribute more to both reputation and engine comprehension.

    Separate core-update volatility from language retrieval failures

    An analyst compares widespread movement among web pages with broken connections between a source page and an AI answer system.

    A ranking decline and an AI visibility gap can happen at the same time without sharing a cause. Broad Google changes, weak content, inconsistent entity information, off-site reputation, language detection, and retrieval choices require different remedies. Diagnose the pattern before rewriting the site.

    Wait for a core update pattern, then inspect the affected intent

    Google makes broad core changes several times a year. For the May 2026 core update, Google indicated that the rollout could take up to two weeks. That specific window does not apply automatically to every future update, but it illustrates why a single day’s movement is a poor basis for a site-wide response.

    1. Mark the announced rollout period on your reporting timeline.
    2. Segment changes by page type, query intent, country, language, device, and brand versus non-brand demand.
    3. Look at the results that replaced you. Identify whether they answer a different intent, provide stronger evidence, offer a more useful format, or represent a different kind of site.
    4. Check technical access and indexing separately from content quality. A crawl or canonical problem should not be diagnosed as an editorial problem.
    5. Prioritize pages where the decline persists and a clear usefulness gap exists. Preserve pages that are merely fluctuating until the pattern is stable enough to interpret.

    A core-update loss does not automatically mean that every affected page is defective. It does mean the competitive result set has changed. Avoid mass deletion or indiscriminate rewriting during volatility. Removing established URLs can also remove content, links, and accumulated relevance you may later need. Preserve the URL, document the evidence, and improve it only when you can name the user problem the change will solve.

    Test each language as its own retrieval environment

    Multilingual visibility is not a translation checkbox. The language of a query can change which pages are retrieved, which authorities are favored, how local context is interpreted, and even which language the system thinks it is processing.

    Catalonia provides a useful warning because Catalan and Spanish queries can be tested in the same geography. Documented results have included Catalan being misidentified as Occitan, even with local context in Barcelona. The practical lesson extends beyond Catalonia: a strong result in one language does not prove equivalent retrieval in another.

    Build a paired test for every commercially important language:

    • Use queries with the same underlying intent rather than comparing unrelated keywords.
    • Record the query language, returned answer language, cited domains, brands included, and geographic framing.
    • Flag language misidentification, imported terminology, missing local entities, and citations from the wrong market.
    • Review whether your page was written for a local reader or merely translated word for word.
    • Strengthen native terminology, local examples, geographic context, and relevant in-language corroboration where gaps appear.
    • Report each language separately so strong performance in a dominant language does not hide failure in another.

    If one language underperforms while another succeeds in the same location, start with language detection, local evidence, and retrieval differences. A site-wide authority campaign is unlikely to be the most precise first move.

    Use a scorecard that reveals the next visibility constraint

    A single ranking report cannot tell you whether buyers know your brand, whether Google confirms their expectations, or whether AI systems include you accurately. Keep the layers separate, then read them together.

    Track pre-search demand

    • Brand mention volume by relevant platform or publication
    • The problems, categories, and competing options mentioned near the brand
    • Positive, negative, mixed, or corrective context
    • Branded search trends
    • Direct and referral visits connected to distribution activity

    Count context, not just mentions. A brand repeatedly associated with the wrong audience or problem may become more visible without becoming more likely to enter the desired shortlist.

    Track Google confirmation

    • Visibility and clicks for brand, brand review, brand comparison, and brand alternative queries
    • Unbranded discovery queries tied to the problem you solve
    • Which owned and third-party pages appear for brand validation searches
    • Page and query clusters affected during core updates
    • Whether the landing page answers the same concern expressed in the query

    If branded demand rises while clicks or downstream actions remain weak, inspect the results page and landing experience. The awareness layer may be working while search confirmation is exposing a reputation problem, unclear positioning, or an unanswered objection.

    Track AI inclusion and interpretation

    • Whether the brand appears in a fixed set of problem, category, comparison, and validation prompts
    • How the system describes the brand and intended audience
    • Whether inclusion is a recommendation, neutral mention, warning, or citation
    • Which domains and passages support the answer
    • Whether important claims are accurate, outdated, incomplete, or attributed to the wrong entity
    • How the result changes by platform, language, and location context

    Keep the prompts and test conditions stable enough to compare observations, but do not treat one generated answer as a permanent rank. Repeated inclusion, recurring citation patterns, and consistent descriptions are more informative than an isolated response.

    Read the combined signals as a diagnostic:

    • Mentions rise but branded demand does not: check audience fit and whether the brand is being connected to the right problem.
    • Branded demand rises but Google confirmation is weak: improve brand-result coverage, reputation evidence, and decision pages.
    • Google visibility is strong but AI inclusion is weak: inspect passage clarity, entity consistency, independent corroboration, and the domains being cited instead.
    • AI inclusion exists but descriptions are inaccurate: reconcile conflicting facts across owned pages and correct retrievable public information where you have legitimate access.
    • One language lags: investigate language-specific retrieval and local evidence before assuming a global authority problem.

    Start with one commercially important decision, not the entire market. Map where the shortlist forms, upgrade the owned page that should confirm it, choose the off-site environment where a useful contribution belongs, and capture a baseline across Google and a fixed AI prompt set. Your next investment should follow the first measured constraint. That is how visibility becomes an operating system instead of a collection of disconnected SEO tasks.

    References

  • Professional vs. Consumer AI Adoption: What Marketers Should Do

    Professional vs. Consumer AI Adoption: What Marketers Should Do

    If AI seems unavoidable in your professional feed, it is easy to assume your customers have already moved their discovery and buying journeys into ChatGPT, Claude, or Gemini. That assumption can send budget toward the loudest channel rather than the audience you actually serve.

    The useful question is not whether AI is popular. It is which audience uses which assistant for which job, and whether that behavior affects discovery, evaluation, or purchase. Once you separate those questions, you can make a defensible AI search plan instead of reacting to general enthusiasm.

    Professional and consumer adoption are moving on different curves

    Broad reach and segment-level growth can move in opposite directions. At its measured high point, OpenAI or ChatGPT reached 37% of U.S. desktop users in September 2025, then slipped to 34% by March. That is a reach signal within a specific geography and device class. It does not mean 34% used the tool daily, preferred it over every alternative, or relied on it during a purchase.

    The professional pattern looks different. Claude usage among B2B professionals was 373% higher than the U.S. average, while Claude and Gemini continued to gain users as ChatGPT’s desktop growth slowed. The 373% figure describes relative overrepresentation. It is not a market-share percentage, and it does not prove that most professionals use Claude.

    Retail-shopping audiences provide the counterweight. People in that audience were 15% less likely to use ChatGPT than a typical U.S. consumer, and Claude did not rank among their top four AI tools. An AI-heavy professional network can therefore give you a distorted baseline for consumer behavior.

    This is not a clean split between people who use AI and people who do not. The same person can be a heavy assistant user at work and follow a conventional search, marketplace, or retailer journey when shopping. Adoption depends on context, task, and perceived value, not just demographics.

    Key takeaways

    • Do not apply one AI adoption rate to professional and consumer audiences.
    • Separate assistant reach, frequency of use, task relevance, brand visibility, and commercial impact. They are different measurements.
    • If you market to B2B professionals, include Claude alongside ChatGPT and Gemini in your visibility testing.
    • If you market to retail shoppers, keep search, category, product, marketplace, and on-site discovery paths strong while you test AI as an additional layer.
    • Increase investment only when audience use and a relevant business outcome appear in the same segment.

    Map adoption by audience and task before assigning budget

    A marketing team arranges audience, device, search, shopping, document, and AI symbols on an unlabeled strategy table connected by illuminated routes.

    A market-wide AI number cannot tell you where to publish, what to optimize, or which assistant deserves attention. Build an audience-by-task map instead. It should distinguish what has been observed from what still needs to be tested.

    AudienceObserved signalWhat it does not establishPlanning response
    Broad U.S. desktop usersOpenAI or ChatGPT moved from 37% reach in September 2025 to 34% by MarchFrequency, task, loyalty, mobile behavior, or purchase influenceMaintain a baseline presence, but do not forecast automatic growth from general awareness
    B2B professionalsClaude usage was 373% higher than the U.S. averageWhich roles, industries, or work tasks produced the differenceAdd Claude to role-specific discovery and evaluation tests
    Retail-shopping consumersChatGPT usage was 15% lower than among typical U.S. consumers; Claude was outside the top four AI toolsWhether AI influences an earlier research step or a later purchase decisionPreserve conventional shopping journeys and test assistants selectively

    Build the map before choosing a platform

    1. Define audiences by commercial context. Separate professional users, procurement participants, existing customers, retail shoppers, and other materially different groups. Do not merge them merely because they can buy the same product.
    2. Name the task. Record whether the person is trying to understand a problem, compare options, verify a claim, troubleshoot, create work, find a seller, or complete a purchase. A tool can be strong for one job and irrelevant to the next.
    3. Collect audience-level evidence. Combine AI referral analytics with customer interviews, sales and support language, on-site search terms, and a direct attribution question. Ask which tool was used and what the person was trying to accomplish; a yes-or-no question about AI is too broad.
    4. Label your confidence. Mark each audience-task-tool combination as observed, indicated, or unknown. A visible market trend can justify a test, but it should not be relabeled as proof about your customers.
    5. Assign an action. Scale combinations supported by audience and outcome evidence, test combinations with a plausible signal, and monitor combinations supported only by general market attention.

    The most common planning error is to start with a platform and look for reasons to fund it. Start with the audience and task instead. The platform should be the last column you fill in, not the first.

    Adjust SEO, AEO, and GEO priorities to match the pattern

    Adoption signals should change your priorities, not your technical standards. Pages still need to be crawlable, indexable, internally linked, consistent about named entities, and clear enough for a person to verify. Structured data must describe visible content accurately; it cannot compensate for a vague, unsupported, or inaccessible page.

    For professional audiences, optimize around decisions

    Where your audience resembles the measured B2B cohort, Claude belongs in the test set. That does not justify abandoning ChatGPT or Gemini. It means a ChatGPT-only visibility report can miss an assistant that is unusually prominent among professional users.

    • Give each important page a decision job. A page might explain compatibility, implementation requirements, operating constraints, use cases, or the difference between two approaches. Do not make one page answer every stage of the buying process.
    • Lead with a direct answer. Follow it with evidence, definitions, exceptions, and practical constraints. This gives human readers a fast answer while leaving enough context for an assistant to represent it accurately.
    • Keep entities unambiguous. Use consistent organization, product, feature, and category names in visible copy, titles, internal links, and applicable schema. If two names refer to the same thing, explain the relationship.
    • Test real professional questions. Run the questions your target roles ask through ChatGPT, Claude, and Gemini. Record whether your brand appears, whether the description is accurate, whether a citation is present, and which URL is surfaced.
    • Fix the underlying page before chasing mentions. If an assistant gives an incomplete answer, check whether your page actually states the missing fact clearly and supports it. Assistant-specific duplicate pages create more content to reconcile and can leave conflicting claims online.

    For consumer audiences, treat AI as an added path

    Lower ChatGPT incidence among retail shoppers and Claude’s absence from that audience’s top four do not make AI irrelevant. They do make an assistant-only discovery plan hard to defend. Keep the complete shopping journey usable without requiring an AI intermediary.

    • Protect category, product, marketplace, local, review, and on-site search paths that already help shoppers find and evaluate an offer.
    • Answer natural-language buying questions on the relevant category or product page instead of hiding useful details in promotional copy or disconnected FAQ pages.
    • Use applicable Product, Offer, or other structured data only when the corresponding information is visible, current, and internally consistent.
    • Test the assistants your audience actually mentions or sends traffic from. Do not give every platform equal budget merely because each one is growing somewhere.
    • Treat AI visibility as a supporting indicator until you can connect it to product discovery, qualified visits, assisted conversions, or purchases for that consumer segment.

    The useful distinction is not B2B equals AI and B2C equals conventional search. It is that professional adoption currently provides a stronger reason to test multiple assistants aggressively, while consumer planning needs more segment-specific proof before AI becomes the primary route.

    Measure adoption separately from visibility and revenue

    An analyst examines three separate transparent instruments containing usage tokens, discovery symbols, and purchase symbols connected by narrow pipes and valves.

    A single AI traffic chart cannot tell you whether customers are adopting assistants, whether assistants know your brand, or whether visibility changes business results. Track those questions in separate layers.

    • Audience use: Ask which assistants people use, for what tasks, and at which point in the journey. Preserve an open-text option so your questionnaire does not force respondents into your platform assumptions.
    • Referral behavior: Break AI-referred sessions down by assistant, landing page, audience, and outcome. Treat this as a floor rather than a complete adoption count: copied answers and manually entered URLs will not preserve an AI referrer.
    • Answer visibility: Maintain a fixed set of audience-specific questions. For each check, record the assistant, date, answer, brand inclusion, factual accuracy, cited URLs, and competitors mentioned. Prompt tracking samples outputs; it does not measure how many customers saw them.
    • Commercial outcomes: Connect identifiable AI visits and self-reported AI use to qualified leads, sign-ups, assisted conversions, purchases, or the outcome your organization already values. Do not label correlation as causation when several channels touched the journey.
    • Technical access: Use server logs and crawl diagnostics to confirm whether relevant bots can reach important pages. Bot activity shows technical access or crawler interest, not human demand.

    Use a simple decision rule. Scale when a defined audience uses an assistant for a relevant task, your visibility has a fixable gap, and improvement is associated with a qualified outcome. Run a contained test when audience and task are supported but commercial impact remains uncertain. Keep monitoring lightweight when the only evidence is broad market enthusiasm.

    For your next planning cycle, choose one high-value professional segment and one important consumer segment. Build separate audience-task maps, test the assistants indicated for each, and move the next content investment only where audience, task, and outcome align.

    References

  • How to Create Helpful Content That Earns SEO Visibility

    How to Create Helpful Content That Earns SEO Visibility

    You have a page aimed at the right keyword, a sensible heading structure, and all the expected subtopics. Yet the draft still feels interchangeable with ten competing results. That feeling is a warning: the page covers a topic, but it may not complete the searcher’s job.

    Helpful content gives someone enough clarity to understand a situation, make a decision, or take the next step without immediately running another search. That is the standard to use when planning, writing, editing, and measuring your SEO content.

    Helpful content completes a searcher’s job

    Start by replacing the vague goal of “covering the topic” with a specific outcome. Before you outline the page, finish this sentence:

    After reading this page, [specific audience] can [specific action or decision] without [avoidable uncertainty].

    If you cannot complete that sentence precisely, your topic is probably too broad or your audience is not defined well enough. “Understand technical SEO” is not a workable outcome. “Decide which technical SEO problems should be fixed before a site migration” gives you a reader, a decision, and a boundary.

    Most search-driven pages serve one of three jobs:

    • Learn: The reader needs a direct answer, an explanation of the mechanism, and enough context to interpret it correctly.
    • Decide: The reader needs criteria, tradeoffs, exceptions, evidence, and a way to compare the available choices.
    • Act: The reader needs an ordered process, required inputs, likely failure points, and a way to verify the result.

    A page can support more than one job, but one should be its center of gravity. A decision page that spends most of its space defining basic terms will feel slow. A how-to page that omits verification may leave the reader with steps but no confidence that they worked.

    This is also the right way to think about depth. Depth is not a word count. It is the degree to which you resolve the main question and the necessary questions behind it. A page about choosing an SEO agency may need evaluation criteria, evidence to request, questions to ask, tradeoffs, and warning signs. A long history of SEO adds words without helping that decision.

    Google’s March 2026 core update focused on surfacing relevant and satisfying content across sites. The practical response is not to chase a new writing formula. Make the reader’s intended outcome the organizing principle of the page.

    Map the question chain before you draft

    A writer's hands arrange connected research objects, including a magnifying glass, measuring tool, wooden blocks, key, and doorway model, around a blank sheet.

    A search query is often only the first visible part of a larger problem. Someone searching “best schema for a service page” may also need to know which entity the page represents, whether multiple schema types can coexist, what must be visible on the page, how to validate the markup, and when the implementation needs to be updated.

    Modern search architecture makes those follow-up questions more important. Retrieval-augmented generation can gather relevant information from multiple locations, while query fan-out can split a broad request into related searches. The editorial consequence is simple: a missing subquestion is a real gap, even when the page uses the primary keyword in all the expected places.

    Build a question map before building the outline:

    1. Name the reader and the moment. Identify who is searching and what has prompted the search. A business owner comparing platforms needs a different answer from a developer debugging an implementation.
    2. Write the immediate question in the reader’s language. Use a complete question, not a two-word keyword label. This forces you to confront the actual decision or task.
    3. List the questions that appear after the first answer. Look at People Also Ask results, Search Console queries, internal site searches, sales objections, support requests, comments, and customer interviews where you have them.
    4. Classify each question. Mark it as required for task completion, useful supporting context, or a tangent. Required questions belong on the page. Useful context can be concise. Tangents usually deserve a separate, linked page.
    5. Put the questions in decision order. A reliable sequence is direct answer, relevant context, choice criteria, exceptions, implementation, verification, and next step. Change that order when the reader’s task demands it.
    6. Assign evidence before writing prose. Decide which claims need an example, first-party data, a documented process, an external citation, or a subject-matter review. This prevents a polished draft from exposing evidence gaps late in production.

    People Also Ask is useful for discovering language and overlooked branches, but it is not an outline generator. A question deserves space only if answering it moves the same reader toward the same outcome. Pasting every related question into an FAQ produces breadth without coherence.

    Give the finished page one center of gravity. If a branch requires a different audience, a different goal, or a substantial new explanation, move it to a supporting page and connect the two with a descriptive internal link. The result is a tighter primary page and a more useful topic structure.

    Turn expertise into visible, verifiable evidence

    An expert measures a generic component with a caliper while documenting the test with a camera, surrounded by samples, tools, a notebook, and process photographs.

    Expertise is not created by calling a page “complete,” adding an author biography, or repeating familiar advice in a confident tone. A reader recognizes expertise through the choices you explain: what matters, why it matters, where the recommendation applies, and where it stops applying.

    Generic content names concepts. Expert content exposes the decision-making behind them. Look for opportunities to include:

    • A precise process: Put the work in its real order and explain dependencies between steps.
    • Selection criteria: Tell the reader how to choose, not merely what options exist.
    • Tradeoffs: State what is gained, what is sacrificed, and who is likely to care about each side.
    • Boundaries: Identify the conditions under which the recommendation changes or does not apply.
    • Failure modes: Show what commonly goes wrong, how the reader can notice it, and what to check first.
    • A worked example: Use real or clearly hypothetical inputs, explain the decision, and show the resulting action. Never turn a plausible scenario into a claimed client result.
    • Evidence provenance: Make it clear whether a claim comes from first-party data, documented platform behavior, professional judgment, or a cited authority.

    A useful pattern for important recommendations is: recommendation, reason, boundary, action. For example, schema markup can help machines interpret the entities and relationships represented on a page. It cannot supply missing expertise or make unsupported claims trustworthy. Add markup that accurately reflects visible content, validate the implementation, and fix the underlying page before treating structured data as an optimization layer.

    Apply the same test to AI-assisted drafts. The problem is not that a tool helped produce the words. The problem is publishing language nobody has checked, examples nobody can substantiate, or advice that ignores the business’s actual process. A responsible editor should be able to explain and defend every consequential statement under the brand’s name.

    Remove credibility theater during editing. Unsupported superlatives, vague claims such as “experts agree,” decorative statistics, and generic author boxes do not answer the reader’s question. Replace them with an accountable claim, its basis, and the condition that limits it. If you do not have the evidence, narrow or remove the claim.

    Edit for fast answers and passage-level clarity

    Readers skim because they are trying to locate the part that resolves their problem. Retrieval systems also work with sections and passages rather than admiring a page as one uninterrupted essay. You do not need to turn every paragraph into a detached snippet, but each major section should make sense without forcing someone to reconstruct its subject from several screens earlier.

    Use this editing pass after the factual draft is complete:

    • Make every heading describe the question, decision, or action addressed below it. Replace labels such as “Overview” or “Other considerations” with meaningful language.
    • Answer the heading in the opening sentence or paragraph. Put qualifications immediately after the answer rather than delaying the answer for a long setup.
    • Keep one main idea per paragraph. Start a new paragraph when the reader must evaluate a new claim, condition, or action.
    • Name the subject explicitly. A passage full of “it,” “this,” and “they” may become ambiguous when retrieved without the surrounding paragraphs.
    • Define specialist terms where the intended reader may not know them. Do not interrupt an expert audience with definitions it does not need.
    • Place an example directly after the principle it demonstrates. A distant example forces the reader to perform the connection.
    • Use lists for steps and criteria. Use tables only when the reader genuinely needs to compare the same dimensions across multiple options.
    • End sections with the decision, check, or next action the reader can take. Do not close with a vague statement about importance.

    Then add the conventional SEO layer: an accurate title, a descriptive meta description, useful internal links, clear headings, appropriate media, and structured data that agrees with the visible page. These elements help discovery and interpretation. They do not rescue an answer that is incomplete, generic, or untrustworthy.

    Measure the job, not only the click

    AI-generated search results make click-only reporting less complete. Semrush tracking found AI Overviews on 6.49% of queries in January 2025 and 15.69% by November 2025. Those percentages describe the tracked query set, not a universal rate for every industry, but the direction is enough to justify measuring more than website sessions.

    Choose success signals that match the page’s declared job:

    • Learning pages: Track qualified search visibility, engagement with the answer, and movement to the next relevant resource.
    • Decision pages: Track meaningful next-step actions, conversions, and lead quality rather than rewarding any visit equally.
    • How-to pages: Use the best available completion proxy, such as interaction with a verification step or a reduction in repeated support questions.
    • Local and service pages: Include branded searches, direct inquiries, and presence in relevant recommendation results. AI platforms can mention or recommend a business without producing a direct website visit.

    If automated AI-visibility tools are outside your budget, create a fixed set of representative prompts and record whether your brand, page, or claims appear. Keep the prompts and evaluation method consistent so that changes mean something. A single favorable response is an observation, not a trend.

    Use performance data diagnostically. Impressions without meaningful action may indicate a weak promise, a mismatched query, or an incomplete answer. Conversions from a smaller audience may show that the page resolves the right job well. Rankings matter, but they should not become a substitute for checking whether the page helps the people it attracts.

    Helpful content FAQ

    What makes content helpful for SEO?

    Helpful SEO content gives a defined audience the answer, context, evidence, and next step needed to complete a specific search task. It addresses necessary follow-up questions, explains meaningful tradeoffs, and makes its claims easy to understand and verify.

    Does helpful content need to be long?

    No. It needs to be complete for the intended job. A narrow factual question may need a short answer and one qualification. A high-stakes comparison may need criteria, alternatives, exceptions, evidence, and implementation details. Stop when the reader can act confidently, not when you reach an arbitrary word count.

    Should every related question appear on one page?

    No. Include a follow-up question when it helps the same reader complete the same task. Move a branch to a separate page when it serves another audience, requires substantial explanation, or pulls the main page away from its purpose. Link the pages where the relationship is genuinely useful.

    Can JSON-LD or schema make thin content helpful?

    No. Structured data can describe entities, properties, and relationships that the page actually supports. It cannot create missing evidence, answer an omitted question, or turn a generic claim into expertise. Improve the visible answer first, then use accurate markup to represent it.

    Choose one commercially important page and write its job statement at the top of your working draft. Build the question chain, then mark every existing paragraph as answer, evidence, context, or action. Rewrite anything too generic to earn a label, and remove anything that does not advance the reader’s job. That pass will show you whether the page is genuinely useful or merely optimized to look relevant.

    References

  • YouTube Conversational Search: How to Prepare Your Videos

    YouTube Conversational Search: How to Prepare Your Videos

    A viewer may no longer need to choose the right video before getting help. They can describe an outcome, receive a synthesized response, and keep narrowing it with follow-up questions. If your YouTube strategy still ends at ranking a title for one query, that changes the work in front of you.

    You now need content that can satisfy the larger task and supply clear, useful moments within it. The goal is not to guess a secret AI ranking formula. It is to make each important answer easy to find, understand, attribute and continue.

    Ask YouTube changes the unit you are optimizing

    A conventional YouTube results page helps a viewer choose among videos. Ask YouTube has tested a more involved path: the viewer submits a task, receives an organized response, and asks related questions without starting over. In the example used to introduce the experiment, someone planning a three-day trip from San Francisco to Santa Barbara could receive an itinerary and then ask where to find good coffee.

    The experimental response could combine long-form videos, Shorts, explanatory text and specific video segments, while displaying video titles and channel details. At the stage described, access was limited to US Premium members aged 18 or older who opted in through youtube.com/new. That restricted rollout matters: it was a test, not evidence of a settled, universal ranking system.

    For creators and search teams, the tested experience introduces three practical shifts:

    • From a keyword to a task: A request such as planning a trip contains an outcome, constraints and several smaller decisions. One exact-match phrase cannot represent the whole need.
    • From a video to an answer moment: A useful section inside a broader video may be surfaced on its own. You need to know which passage resolves which question.
    • From an isolated search to a conversation: The first response creates the context for what the viewer asks next. Content that answers the opening prompt but ignores obvious follow-ups leaves part of the journey uncovered.

    Treat these as editorial implications, not confirmed ranking factors. The experiment does not establish how YouTube weighs titles, spoken language, engagement, channel authority or any other signal within a conversational response. Anyone offering a guaranteed Ask YouTube optimization formula is getting ahead of the available facts.

    Build a conversation map before you plan the video

    A top-down desk scene shows a camera, blank storyboard cards, symbols, and branching threads organized around a central viewer objective.

    Start with the job the viewer is trying to complete. A topic such as coastal road trips is too broad to guide production. Help me plan a three-day coastal road trip is useful because it implies a sequence of decisions and invites predictable follow-ups.

    Create the map before you write the script:

    1. Write the primary request in the viewer’s language. Use a complete request, not a two-word keyword. Include the desired outcome and any constraint that materially changes the answer.
    2. Define what a satisfactory response must accomplish. Decide whether the viewer needs a plan, a recommendation, a comparison, a demonstration or a troubleshooting sequence.
    3. List the questions created by your first answer. If you recommend an option, the viewer may ask when it is appropriate, what the alternative is, what can go wrong and what to do next.
    4. Assign every important question to an answer moment. That moment may live in a long-form section, a focused Short or a separate video. If you cannot point to the passage that resolves a question, you have found a content gap.

    A planning brief for each moment should record the prompt, the direct answer, the conditions that change it, the supporting demonstration and the next likely question. This prevents a common production failure: mentioning a subject without actually resolving the viewer’s decision.

    Follow the branches that change the answer

    You do not need a separate asset for every imaginable question. Prioritize branches that would change the viewer’s choice or next action. For a planning video, those might concern the available time, the type of stop the viewer wants, an alternative route or where a particular need can be met. For a software tutorial, they might concern the viewer’s platform, permissions, starting state or desired output.

    Use this sentence test for each branch: For this viewer, choose this option when this condition applies; expect this tradeoff; then take this next step. If your script cannot complete that sentence plainly, the segment is probably commentary rather than an answer.

    This is also where audience research becomes more valuable than keyword expansion. Repeated questions in comments, support conversations, community discussions and sales calls reveal the missing conditions behind a short search phrase. Group those questions by decision, then build the content around the decisions rather than repeating every wording as a separate keyword.

    Make each useful moment understandable on its own

    A filmstrip passes through a glowing prism and separates into four connected visual capsules showing a tool, a procedure, a transformation, and a finished result.

    A conversational system may surface a segment rather than asking the viewer to interpret the entire video. That makes local clarity important. A strong overall video can still contain a weak answer moment if the useful sentence depends on context supplied several minutes earlier.

    Give each answer unit a complete shape

    For every major section, include the information a person would need if that section were their entry point:

    • Context: Name the place, product, process, audience or starting condition being discussed. Avoid opening with vague references such as this option or that method.
    • Direct answer: State the recommendation or instruction before expanding on it. Do not make the viewer wait through a generic preamble to learn what the section is for.
    • Boundary: Explain the condition under which the answer changes. This keeps a concise answer from becoming misleading.
    • Support: Show the route, setting, screen, comparison, example or other evidence that makes the answer usable.
    • Next branch: Identify the next decision when the task requires one. This creates a natural handoff to another section or asset.

    Use descriptive spoken transitions and on-screen section labels. Keep the video title, section language, visuals and description aligned around the same intent. This is not a claim that any one element controls inclusion. It is a way to remove ambiguity for viewers and make your own content audit possible.

    Give long-form videos and Shorts different jobs

    The tested experience could draw from both formats, but that does not mean you should duplicate everything. Use long-form video when the viewer needs a sequence, connected decisions or enough context to understand tradeoffs. Use a Short when one narrow question can be answered honestly without hiding essential conditions.

    A productive content cluster might use one long-form video for the complete task and focused Shorts for high-value branches. Each Short should still deliver an answer. A clip that raises a question and withholds the useful part merely to push a click is a poor conversational-search asset and a frustrating viewer experience.

    Keep schema claims inside the evidence

    The disclosed Ask YouTube behavior does not identify a special markup field or say that JSON-LD on a companion website triggers inclusion. Do not invent an Ask YouTube schema type, promise that markup will produce a citation, or treat website optimization as a substitute for improving the video itself.

    You can still use accurate structured data for its normal purpose on a relevant webpage. Keep that work separate from your YouTube hypothesis until YouTube establishes a direct connection. Clear boundaries are part of credible AI optimization.

    Audit conversational visibility without mistaking a test for proof

    If the experiment is available to your account, test the content as a viewer would. If it is not available, you can still do the conversation-mapping and segment audit; you simply cannot claim inclusion results.

    1. Create a fixed prompt set. Include the primary task and the follow-ups from your conversation map. Preserve the exact wording so later checks are comparable.
    2. Separate fresh searches from follow-up paths. A new request and a question asked inside an existing conversation are different tests because the latter carries earlier context.
    3. Record the full response. Note which videos, Shorts and segments appear, how the channel is identified, and whether the synthesized answer represents the selected material accurately.
    4. Classify the gap before editing. Distinguish between no access to the feature, no coverage of your topic, selection of another video, selection of the wrong moment from your video and accurate selection that produces no meaningful viewer action.
    5. Change one editorial variable at a time where practical. If you rewrite a section, retitle the asset and publish several related Shorts simultaneously, you will not know which change coincided with a different result.

    Use the following diagnostic table to keep observations and conclusions separate:

    What you observeWhat it establishesWhat to inspect next
    The Ask YouTube option is unavailableYou cannot run the inclusion test from that accountEligibility and experiment access, not the video’s optimization
    The topic is answered without your contentOther material was selected for that prompt pathWhether your asset directly resolves the task and its follow-ups
    Your video appears, but the chosen moment is weakThe response found the asset but did not produce the representation you wantedLocal context, answer placement, section wording and supporting visuals
    Your segment is represented accuratelyThat prompt path worked during that observationRelevant viewer behavior and whether adjacent follow-ups are also covered

    A single appearance does not prove a durable ranking advantage, just as one absence does not prove a penalty. The feature was experimental, conversational paths can differ, and the available description does not provide a creator-facing performance standard. Keep screenshots or logs, label observations by date and account context, and avoid turning a small manual check into a universal claim.

    Measure success at three levels. First, did the relevant asset or segment appear? Second, did the response represent it accurately enough to help the viewer? Third, did the resulting audience take a meaningful next action? Visibility without accuracy can distort your message, while visibility without a useful outcome can become an impressive-looking metric that changes nothing.

    Key takeaways

    • Optimize for the viewer’s complete task, not only the opening keyword.
    • Map the first request, the decisions it creates and the follow-up questions that change the answer.
    • Assign every important question to a clear, self-contained moment in a long-form video, Short or related asset.
    • Use long-form video for connected reasoning and Shorts for narrow questions that can be answered without omitting necessary conditions.
    • Treat titles, section language and visuals as clarity tools, not as a guaranteed Ask YouTube formula.
    • Do not claim that website JSON-LD controls conversational YouTube inclusion without an explicit platform specification.
    • Log appearances, representation quality and viewer outcomes separately so an experimental result does not become a false certainty.

    Take one video from your production queue and build its conversation map before the script is locked. If you cannot point to a complete passage for each decision-changing follow-up, fix the content architecture now. That work will make the video more useful whether Ask YouTube expands, changes or remains limited.

    References