Tag: Apple Search Ads

  • Apple App Store Ad Expansion: A Practical Campaign Plan

    Apple App Store Ad Expansion: A Practical Campaign Plan

    Your App Store search campaign can now qualify for ad positions you never selected. That creates another route to potential installs, but automatic eligibility also means delivery can change before your bids, product pages, and measurement plan do.

    You don’t need to rebuild the account to participate. You do need a clean baseline, a tighter relevance audit, and a rule for deciding whether additional volume is actually profitable. Otherwise, higher spend can look like growth even when install economics are deteriorating.

    Key takeaways

    • App Store search results can contain multiple sponsored ads, including the familiar top position and additional positions farther down the results.
    • Existing search results campaigns are automatically eligible. There is no separate placement switch to activate.
    • You cannot select a particular search-results position or bid specifically for one. Apple determines placement using relevance and bid.
    • Ad formats and billing remain the same: ads can use a standard or custom product page, optional deep links can lead to an in-app destination, and billing remains cost per tap or cost per install.
    • Apple’s reported conversion rate of more than 60% applies to top-of-search ads on average. Do not treat it as a promised benchmark for every keyword, market, or new lower-page position.

    What changes, what stays fixed, and what you control

    The most important distinction is between inventory and control. Apple is increasing the number of places where a search ad may appear, but it is not giving advertisers a position selector. Your campaign can enter more placement opportunities without gaining the ability to demand the top slot or exclude the lower ones.

    Campaign elementWhat the expansion meansWhat you should do
    Search-results inventoryMore than one sponsored ad can appear for a query, at the top and farther down the page.Measure whether added delivery produces incremental installs at an acceptable cost.
    EligibilityExisting search results campaigns qualify automatically.Establish a baseline before changing bids, keywords, or product pages.
    PositionApple chooses where an eligible ad appears.Do not build a strategy that assumes a bid increase buys a specific slot.
    MatchingSearch ads continue to match through advertiser-selected or Apple-suggested keywords.Audit the connection between each important keyword, its intent, and the destination page.
    Creative and destinationThe ad can use a standard product page or a custom product page, with an optional deep link.Choose the page that most directly continues the promise implied by the keyword.
    BillingCost-per-tap and cost-per-install billing remain available.Keep the commercial decision anchored to install value rather than raw visibility.
    Device supportThe additional positions are supported on devices running iOS or iPadOS 26.2 and later.Remember that a mixed device audience may not encounter the expanded layout uniformly.

    Apple scheduled the first phase for the UK on March 3, with Japan following and all Apple Ads markets expected to be included by the end of March. That staggered schedule makes market-level annotations important. If you do not record when exposure could have changed, later analysis can confuse the rollout with seasonality, a product release, a pricing change, or another campaign edit.

    Do not interpret extra inventory as a new targeting system. The campaign is still built around keyword relevance, the product-page experience, and the economics of a tap becoming an install. The expansion changes where an eligible ad may be delivered, not the basic job the ad must do.

    Build a baseline before you react to the new inventory
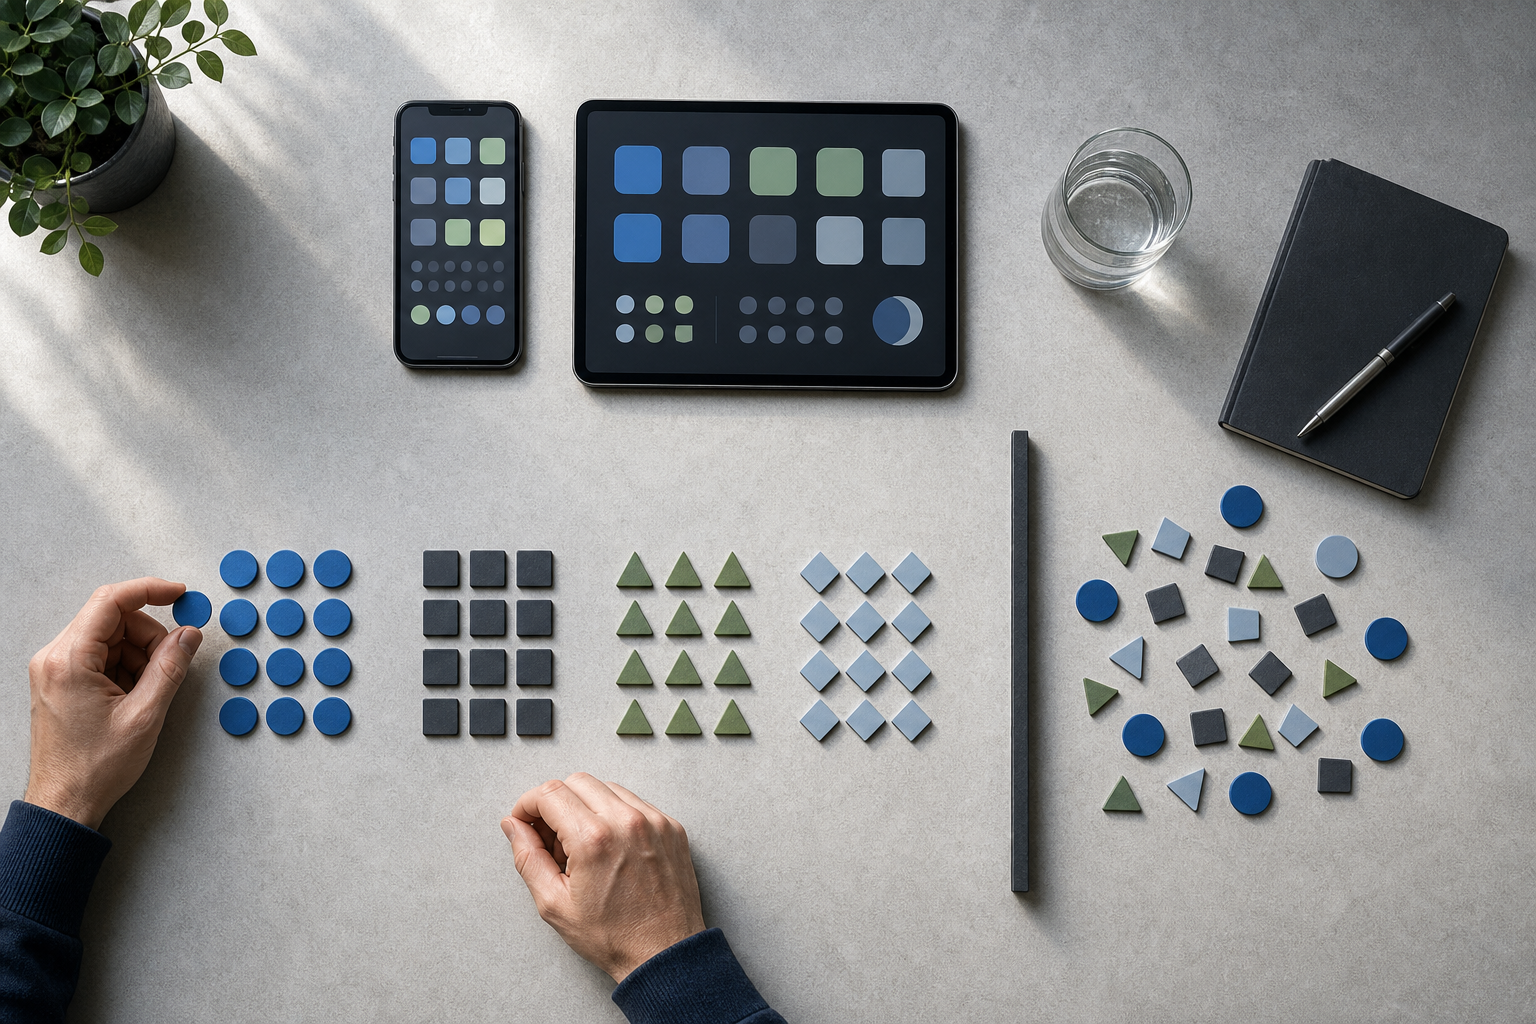
    A marketer's hands organize four groups of campaign tokens beside a phone and tablet, with loose tokens arriving beyond a divider.

    Automatic eligibility turns measurement into the first task. If you raise bids, add keywords, replace product pages, and increase the budget at the same time, you will not know whether a performance shift came from the extra placements or from your own changes.

    1. Mark the rollout in your account records. Record the relevant market date and note that the additional placements require iOS or iPadOS 26.2 or later. Use the most precise market and device information your reporting actually provides; do not assume a dimension exists if it is not visible in your account.
    2. Save a comparable pre-expansion view. Capture impressions, taps, installs, conversion rate, spend, cost per tap, and cost per install for each important market, campaign, and keyword. Use a period that reflects the normal buying cycle of your app rather than an arbitrarily short snapshot.
    3. Document other variables. Note product releases, store-listing changes, promotions, pricing changes, tracking updates, and budget edits. Each can move conversion independently of ad position.
    4. Set an economic guardrail. Decide the highest cost per install the business can support before more volume arrives. Base that ceiling on the value and quality of an acquired user, not on a competitor’s bid or a platform-wide conversion claim.
    5. Verify conversion measurement. Confirm that taps and installs are being attributed as expected. If you use deep links, test that each one opens the intended in-app destination for the relevant user journey.
    6. Avoid unnecessary simultaneous changes. Keep the first observation window as stable as the business allows. When an urgent edit is unavoidable, annotate it so the resulting data is not mistaken for a placement effect.

    A before-and-after comparison is useful, but it is not proof of incrementality. During a staggered rollout, a comparable market that has not yet changed can provide a directional check. It is only a useful comparison when demand patterns, promotions, and app availability are genuinely similar. Once all markets are included, rely on annotated within-market trends and be explicit about competing explanations.

    Expect aggregate metrics to move in different directions. Total installs can rise while conversion rate falls because the campaign is reaching additional inventory with different user behavior. That is not automatically good or bad. The decision turns on whether the added installs remain valuable at the resulting cost per install.

    Relevance is the control surface you still have
    A magnifying lens brings one app tile into focus on a smartphone while surrounding tiles remain blurred and connected category cues suggest relevance.

    You cannot control the exact position, but you can control how coherent the journey is from keyword to ad to product page. Apple weighs bid and relevance when assigning placements, and a high bid cannot force an ad into an auction when the match is not sufficiently relevant. That makes relevance an eligibility issue, not merely a creative preference.

    Audit the journey in this order:

    1. Write down the intent behind the keyword. Is the person looking for your brand, a broad app category, a specific task, or a particular feature? If the intent is ambiguous, do not pretend one product page can answer every possible meaning.
    2. Match the page to that intent. Use the standard product page when it accurately represents the query. Use a custom product page when a distinct use case needs different screenshots, copy, or emphasis.
    3. Check the first visible promise. The opening product-page experience should make the connection immediately. If the query implies one task but the page leads with another, more traffic will magnify the mismatch.
    4. Use deep links as a continuation, not a shortcut. A deep link is useful when the destination completes the journey implied by the ad. It is counterproductive when it drops the user into an unrelated or contextless part of the app.
    5. Remove mismatches you cannot fix. If a keyword’s intent cannot be represented truthfully by the app or its page, a larger bid is not the remedy. Refine or pause the keyword.

    This is also why paid acquisition and App Store optimization cannot be managed as isolated disciplines. Search ads use the product-page experience to turn intent into an install. A weak listing is therefore both an organic discoverability problem and a paid conversion problem. Extra ad slots increase the cost of leaving that handoff unresolved.

    Be careful with Apple’s top-of-search benchmark. Apple reports an average conversion rate above 60% for ads in that position, but the figure is vendor-supplied and specific to top-of-search performance. It does not establish how the additional lower positions will perform in your market. Use it as context, not as a forecast or account target.

    A global bid increase is a poor first response. Because you cannot purchase a named position, a higher bid does not guarantee that the added spend will secure the top placement. Hold bids steady long enough to observe the change where practical, then adjust one major lever at a time: keyword scope, bid, product page, or budget. That sequence keeps the diagnosis legible.

    Decide whether the added delivery deserves more budget

    More impressions are an inventory result. More taps show that users responded. More valuable installs are the business result. Keep those three questions separate when you evaluate the expansion.

    • Impressions and taps rise, while cost per install stays within your guardrail: the additional inventory may be adding efficient reach. Increase budget gradually and keep watching keyword-level conversion rather than assuming the first result will persist.
    • Spend and installs rise, but cost per install exceeds the guardrail: the campaign is buying volume that the business may not be able to support. Reduce exposure to weak keywords, improve the matching product page, or lower bids before approving more budget.
    • Taps rise while installs remain flat: investigate the handoff from query to page. Check tracking first, then review intent alignment, product-page clarity, and any deep-linked destination. Do not use a bid increase to solve a conversion failure.
    • Impressions rise but taps do not: eligibility is not the same as appeal. Revisit whether the keyword and visible product-page message give the searcher a clear reason to choose the app.
    • Little changes: automatic eligibility does not guarantee meaningful delivery. Leave the campaign alone unless another metric provides a reason to act.

    Cost pressure is possible, but it should not be assumed. More ads on a results page can intensify competition for high-intent searches, while more available inventory can also alter the supply of opportunities. The net effect depends on the auction, query, market, and relevance of your ad. Let observed cost per install and conversion quality decide the response.

    Review the keywords responsible for most of your spend first. Map each one to its intended product page, confirm conversion tracking, record the rollout date, and set the cost-per-install ceiling before changing the bid. When the expanded inventory produces installs inside that boundary, scale deliberately. When it only produces activity, fix the journey or decline the extra volume.
    References

  • Paid Acquisition Control Plan: Targeting, Lift and Search Ads

    Paid Acquisition Control Plan: Targeting, Lift and Search Ads

    Your acquisition dashboard can look healthier while your decision quality gets worse. Reach outside a service area can swell activity, a modeled lift estimate can be mistaken for certainty, and extra App Store ad slots can tempt you to chase a position you cannot buy.

    These are three different control problems: audience eligibility, causal measurement, and auction relevance. You need to separate them before deciding where the next dollar goes. This control plan shows you how.

    Separate the three decisions hiding inside campaign performance

    Paid acquisition reviews often collapse targeting, measurement, and optimization into one question: did performance improve? That shortcut is dangerous because each layer can change the same dashboard metrics for a different reason.

    Decision layerPlatform changeWhat you should control
    Audience eligibilityGoogle Demand Gen now exposes an explicit choice between Presence or interest and Presence only.Define whether a person must be inside the market to have economic value before you select the setting.
    Causal evidenceGoogle is making Bayesian incrementality measurement available with budgets as low as $5,000.Judge the posterior probability, credible interval, assumptions, and business downside instead of treating test availability as proof.
    Available optimization leverApple plans to add in-line App Store search ads in 2026, but advertisers cannot select or buy those positions directly.Improve query-to-app relevance and creative alignment rather than optimizing toward an unavailable placement control.

    The order matters. Set the eligible population first. Then ask whether advertising caused an outcome. Only after that should you optimize the lever the platform actually exposes. Reversing the order can leave you spending money to correct the wrong layer.

    • Out-of-market Demand Gen traffic is primarily a boundary problem, not evidence that the creative failed.
    • A wide Bayesian credible interval is an evidence problem, not automatic proof that the channel failed.
    • An App Store ad that never becomes auction-eligible can be a relevance problem that a higher bid will not solve.

    Set the Demand Gen location boundary before reading performance

    Demand Gen can reach people across YouTube, Discover, and Gmail. A loose location definition can therefore spread through several environments before you notice it in an aggregate report.

    Use Presence only when the conversion depends on the person being in the target market. That usually applies to a local service area, a physical catchment, a market-specific offer, or fulfillment that cannot extend beyond named locations. Use Presence or interest only when someone outside the market can still become a valid customer. Planned travel and relocation are plausible examples. Preserving a larger reach estimate is not, by itself, a reason to choose the broader option.

    Run this sequence whenever you create, migrate, or audit a Demand Gen campaign:

    1. Write the eligibility rule first. Complete this sentence: We will pay to reach people who are in, or are interested in, these markets because the resulting conversion can be fulfilled in this way.
    2. Select the location option explicitly. Do not let a copied campaign, inherited setup, or old operating habit make the decision for you.
    3. Audit legacy exclusions. Presence only is now available natively, reducing the need for manual exclusion workarounds. Remove an old exclusion only after confirming that the native control makes it redundant.
    4. Record the change date and previous setting. A switch between Presence or interest and Presence only changes the population behind the metrics. Treat it as a break in the series, not as an ordinary bid or creative adjustment.
    5. Inspect location quality before aggregate efficiency. Confirm that impressions, clicks, and conversions are coming from markets your business can serve. Only then interpret campaign-wide cost and conversion metrics.

    This distinction matters because a cost-per-acquisition change can be caused by audience composition even when the ad, bid, and landing experience remain unchanged. Comparing the periods as if they were the same population can produce a false creative, bidding, or channel conclusion.

    Presence only should reduce geo-leakage and make regional performance easier to interpret. It does not prove incrementality, validate your list of target markets, or establish that every conversion can be fulfilled. Those remain separate business and measurement questions.

    Read a $5,000 Bayesian lift test as a decision, not a verdict

    Two transparent experiment chambers contain overlapping particle clouds beside budget tokens and a three-way decision lever.

    Lower-budget incrementality testing is useful because it gives more advertisers a way to ask a causal question: how many outcomes happened because of the advertising? It becomes dangerous when the budget figure is mistaken for a precision guarantee.

    Google’s approach uses informed priors, hierarchical modeling, and campaign history to extract useful evidence from less data. In Bayesian terms, the prior represents the belief before the test, the posterior updates that belief with observed data, and the credible interval describes a plausible range for the effect. As more relevant observations accumulate, the result should depend less on the prior and more on the test data.

    That is different from a conventional frequentist test built around a fixed sample, a p-value, and a binary statistical-significance decision. A p-value is not a Bayesian probability that the campaign worked, and a posterior probability is not the percentage lift. Mixing those interpretations can turn a technically valid output into a bad budget decision.

    Before launching a lift test, create a decision record with these fields:

    • Decision: the spend increase, reduction, continuation, or stop that the result could trigger.
    • Eligible population: the geography, audience, campaign set, and conversion outcome covered by the test.
    • Business hurdle: the smallest incremental effect that would justify the cost and operational risk.
    • Prior assumptions: whatever the platform exposes about the starting belief, historical inputs, or comparable campaign patterns. If these are not visible, record that limitation.
    • Posterior output: the probability attached to the outcome you care about, not merely a positive headline.
    • Credible interval: the plausible effect range, including whether economically unattractive outcomes remain credible.
    • Action and reversal condition: what you will do after the result and what later evidence would cause you to reverse it.

    Decide from the distribution, not the headline

    Start by separating direction from magnitude. A high probability that lift is positive can coexist with an effect too small to cover acquisition costs. Conversely, an uncertain estimate can still support a limited, reversible decision when the plausible downside is small and another test will add information.

    Next, inspect the full credible interval. If it spans both valuable and damaging outcomes, the honest conclusion is that the decision remains sensitive to uncertainty. Do not scale aggressively from the center estimate alone. Keep the change staged and use the next measurement period to narrow the range.

    Keep the result inside its tested boundary. Evidence from one geography, audience mix, campaign history, or conversion definition does not automatically transfer to another. This is especially important after changing Demand Gen location settings because you may no longer be measuring the same population.

    Finally, treat $5,000 as an access point for a modeled test, not a warranty that every campaign spending that amount will produce a narrow, decision-grade answer. Smaller tests can be useful precisely because Bayesian inference carries prior information forward. That same mechanism is why you need to examine the assumptions and uncertainty before committing more money.

    Prepare Apple Ads for a relevance gate you cannot outbid

    An unbranded smartphone projects content cards toward a gate that admits one matching card while mismatched cards and bidding tokens remain outside.

    Apple plans to place additional ads among organic App Store search results during 2026 while retaining the existing top-result ad. Advertisers will not need to opt into the new positions, and there is no placement selector that lets you buy a particular in-line slot.

    The practical constraint comes earlier in the process: an app must be relevant to the search to enter the auction. A larger bid cannot rescue an app that fails that gate. Bids can still matter among eligible candidates, but they are downstream of relevance.

    Build your campaign around a relevance chain rather than a placement wish list:

    1. Group keywords by user need. Do not combine terms merely because they share vocabulary. Two queries containing the same noun can imply different jobs, audiences, or expected features.
    2. Map each theme to an app capability. Write down the function that directly answers the search. If you cannot complete that connection without stretching the meaning, the theme is probably a poor acquisition target.
    3. Map the capability to product-page evidence. The app name, description, imagery, and surrounding product-page material should make the connection understandable without relying on the ad to explain everything.
    4. Prepare creative variations for distinct themes. Apple allows advertisers to align different creative treatments with audiences or keyword groups. Without custom creative, the ad can be generated from the app’s product page, making that page the default acquisition asset rather than an organic-only concern.
    5. Annotate the inventory change when it reaches your account. More impressions or attributed installs may reflect additional supply, stronger relevance, displaced organic discovery, or a mixture of those effects. Preserve the date so you do not mislabel the discontinuity as a campaign optimization win.

    Diagnose the funnel in sequence. If impressions expand but taps do not, inspect the query-to-creative relationship first. If taps expand but installs do not, inspect whether the promise and product page carry the same intent. If attributed installs expand, do not automatically call the difference incremental; additional ad inventory can redistribute existing demand as well as capture new demand.

    Apple has indicated that billing will remain per tap or per install, depending on the existing setup. That continuity does not make the economics static. Greater ad density can change impression availability, tap behavior, conversion quality, and the balance between paid and organic discovery.

    Do not create a performance target around owning an in-line position you cannot control. Track whether relevant searches produce qualified installs at acceptable economics. That is a lever you can manage through keyword selection, product-page alignment, creative variation, and bids among eligible candidates.

    Key takeaways

    • Choose Demand Gen Presence only when value depends on the person being inside the target market; use Presence or interest only when out-of-market interest can still produce a valid customer.
    • Treat a location-setting change as a population change. Annotate it and avoid presenting the before-and-after difference as a clean creative or bidding test.
    • Regard the $5,000 Bayesian test level as access to modeled evidence, not guaranteed certainty or a universal minimum for a reliable answer.
    • Read Bayesian results through the prior, posterior probability, credible interval, and your business hurdle. Probability of positive lift is not the size of the lift.
    • For Apple’s planned in-line App Store ads, relevance determines auction eligibility before bid size can influence the result.
    • Annotate new ad inventory and separate attributed growth from incremental growth before increasing spend.

    Before your next budget review, add three lines to every campaign brief: the eligible market, the evidence required to change spend, and the lever the platform actually lets you control. If the campaign owner cannot fill in all three, do not solve the uncertainty with a larger budget. Fix the boundary, the measurement rule, or the relevance chain first.

    References