Tag: AI Visibility

  • How AI Search Changes Publisher Traffic and SEO Strategy

    How AI Search Changes Publisher Traffic and SEO Strategy

    Your search visibility can look intact while the business result weakens. A page may still rank, yet an AI answer can resolve the reader’s question before a visit occurs. If you publish news, analysis, or expert guidance, your work can influence the answer without producing the session that funds it.

    That does not make SEO obsolete. It means you must stop treating rankings, clicks, citations, and commercial value as interchangeable outcomes. The practical response is to diagnose where traffic is being lost, measure AI visibility separately, and give every important page two jobs: supply a clean answer and offer something the answer surface cannot replace.

    A ranking no longer guarantees a visit

    Traditional search encouraged a simple mental model: a query produced a results page, the user chose a listing, and the publisher received a visit. AI search inserts an answer layer between the query and the organic result. Google AI Overviews can appear above traditional listings, while answer engines such as ChatGPT and Perplexity can synthesize material from several publishers into a response.

    This creates three distinct outcomes. Your page can be cited and clicked, cited without a click, or excluded from the answer entirely. Only the first produces both visibility and an attributable visit. The second may contribute to recognition or authority, but it does not create an ad impression, subscription opportunity, lead, or ecommerce session by itself.

    The economic tension is already visible. Nearly 300 French newspapers filed a complaint with France’s competition authority, alleging that Google launched AI-generated summaries without their approval, reduced visits to original reporting, and breached commitments connected to a 2022 compensation agreement. Those are publisher allegations, not a universal estimate of traffic loss, but they identify the central problem clearly: being used in an answer is not the same as being paid, visited, or even visibly credited.

    Key takeaways

    • Do not diagnose an aggregate organic decline as an AI problem until you inspect affected queries and landing pages.
    • Keep SEO metrics, AI citations, AI referrals, and business outcomes in separate reporting layers.
    • Make priority pages easy for machines to interpret without making them unnecessary for people to visit.
    • Build concentrated authority around a defined subject instead of spreading limited publishing capacity across unrelated topics.
    • Treat crawler access, content licensing, and compensation as governance decisions, not routine SEO settings.

    Before changing your editorial strategy, classify the pattern you are actually seeing. The following checks will not prove causation, but they will tell you where to investigate next.

    Observed patternWhat it may indicateWhat to check next
    Rankings and impressions are broadly stable, but clicks or click-through rate fallThe results interface or the appeal of your listing may have changedReview the live result for affected queries, including AI answers and other search features; also check whether your title and description still match the intent
    Rankings, impressions, and clicks all declineA conventional discoverability, demand, or competitive problem may be responsibleInvestigate crawling, indexing, query demand, ranking changes, content quality, and competing coverage before blaming AI
    Organic clicks decline while referrals from AI interfaces appearSome discovery may be shifting between channelsCompare landing pages, conversion outcomes, and the questions that produced each type of visit
    AI citations or brand mentions rise without referral trafficYour influence may be increasing without a corresponding audience transferDecide whether that exposure supports a measurable business objective; do not record it as traffic

    The first row deserves particular care. Stable rankings plus falling clicks are consistent with a results-page interception problem, but they do not prove that an AI answer caused it. Search features, changing intent, weak snippets, seasonality, and shifts in demand can produce similar symptoms. Inspect the query and its current result before rewriting the page.

    Measure traffic and AI influence as separate outcomes
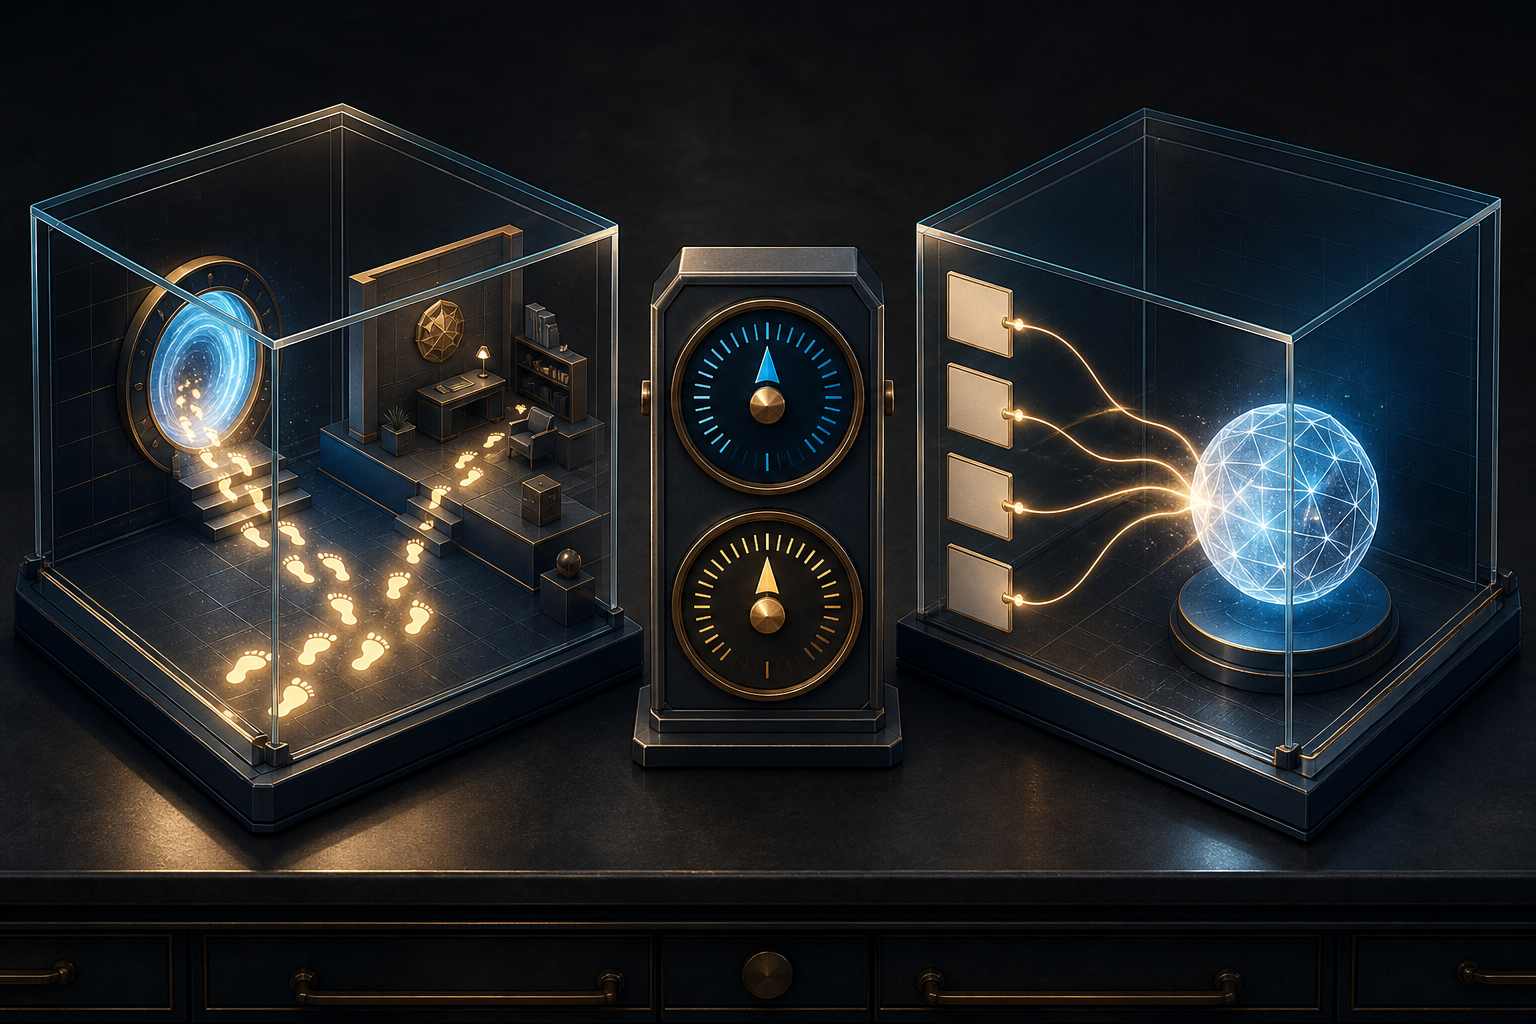
    Two glass chambers separately show glowing footprints entering a publisher portal and source cards feeding light into an answer orb.

    A publisher dashboard built only around sessions will miss influence that occurs inside an answer engine. A dashboard built only around citations will hide whether that influence has any business value. Your measurement system therefore needs two ledgers that can be examined together without being collapsed into a vague visibility score.

    The traffic ledger

    • Impressions and ranking visibility: whether your pages remain eligible and visible for the queries that matter.
    • Organic clicks and click-through rate: whether search visibility still transfers an audience to your site.
    • Landing-page sessions: which content actually receives the visit.
    • Meaningful outcomes: subscriptions, registrations, leads, purchases, ad-supported page consumption, or another result tied to your publishing model.

    Google Search Console, ranking data, and organic traffic remain relevant even when AI answers are present. They reveal whether traditional search visibility is shrinking, holding, or converting differently. Do not remove these metrics merely because a new discovery channel has appeared.

    The influence ledger

    • Prompt citation presence: whether your domain or a specific URL is referenced for important audience questions.
    • Brand mentions: whether the answer names you even when it does not provide a clickable citation.
    • Cited-page distribution: which pages answer engines select, rather than which pages you hoped they would select.
    • AI referral traffic: visits that arrive from identifiable AI interfaces.
    • Recurrence over time: whether visibility persists across audits instead of appearing in an isolated response.

    A combined SEO and GEO program should track prompt citations, AI referrals, and brand-mention frequency alongside conventional organic metrics. The distinction matters because a citation without a visit is an influence event, while a referral is a traffic event. Neither should be credited with revenue until your analytics connects it to a meaningful outcome.

    Run prompt audits as controlled observations, not as demonstrations prepared for a meeting. Start with a stable set of questions that represents the information, comparison, and decision tasks your audience brings to search. For every check, retain the exact prompt, platform, date, resulting answer, cited domains, linked pages, brand mentions, and notable competitors. Keep the wording and evaluation rules consistent when you compare periods.

    Do not call an isolated answer a ranking. Generated responses can vary, and a single favorable result does not establish durable visibility. Look for repeated selection across your prompt set and across successive audits. If you change the prompts, platform context, or scoring rules, mark the break in your reporting so a methodology change is not mistaken for growth.

    Your final dashboard should answer four different questions: Were you discoverable? Were you selected or cited? Did the person visit? Did the visit or exposure create value? When those questions occupy separate fields, a traffic decline cannot be disguised by a rising citation count, and genuine AI visibility will not disappear inside an organic sessions chart.

    Make priority pages citation-ready and visit-worthy
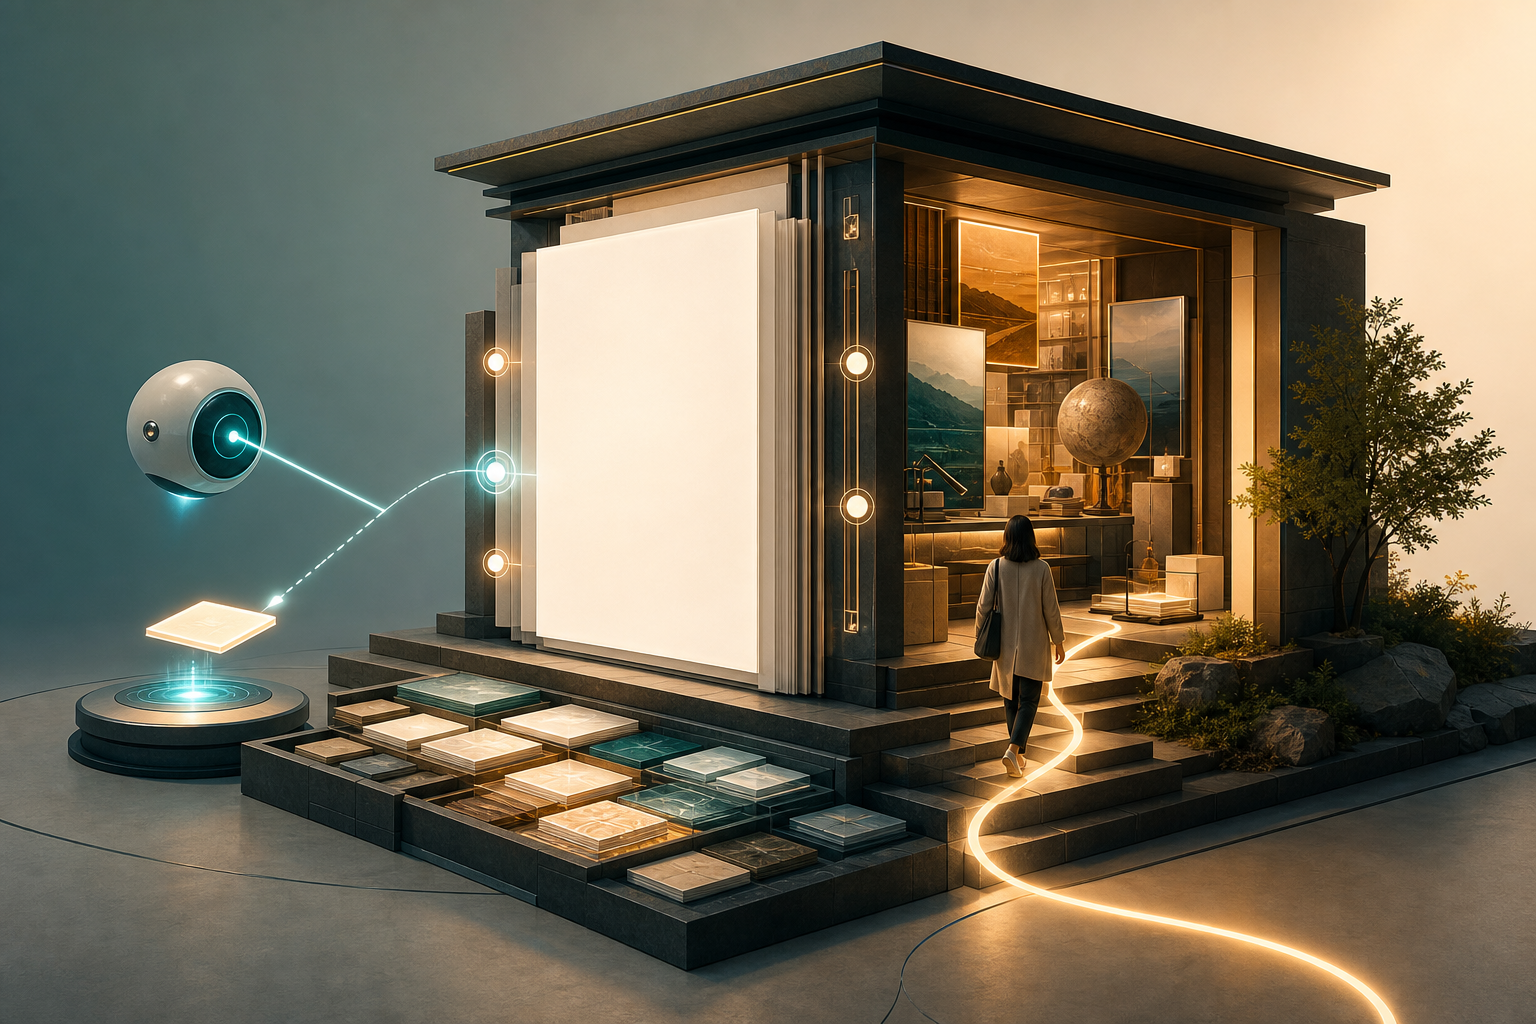
    A layered article pavilion offers a glowing fragment to a hovering search orb while a visitor enters an open passage containing richer research and visual material.

    Trying to force every answer behind a click is a poor response to AI search. If a page is vague, evasive, or structurally confusing, it becomes harder for both readers and machines to use. The better design offers an extractable answer while reserving meaningful depth for the page itself.

    Create an extractable answer layer

    • State the page’s central answer early in a short, self-contained paragraph.
    • Name the relevant organization, person, product, place, method, or concept explicitly instead of relying on pronouns and implied context.
    • Define specialized terms before using them to carry the argument.
    • State the scope and conditions of the answer, especially when it applies only to a particular market, platform, date, or audience.
    • Use descriptive headings that correspond to real follow-up questions.
    • Keep authorship, publication context, evidence, and update information easy to locate.
    • Add accurate structured data that matches what a reader can see on the page. JSON-LD can clarify entities and relationships, but it is not a switch that guarantees an AI citation.

    Clear entity definitions and direct answers make content easier to retrieve and summarize. They also reduce a common editorial failure: publishing a sophisticated page that never states its conclusion plainly enough for a reader to confirm that it answers the query.

    Build a reason to visit beyond the summary

    The extractable layer should not contain the page’s entire value. Give the reader something that cannot be reproduced faithfully in a short synthesis: original reporting, primary documents, full data tables, a transparent methodology, detailed examples, local context, a useful tool, a decision framework, or careful treatment of exceptions.

    This is not permission to tease an answer and withhold it. The page should resolve the stated question. Its deeper layer should help the reader verify the conclusion, apply it to a particular situation, or make the next decision. A thin page with a clear answer may be easy to summarize but unnecessary to visit. A deep page with no clear answer may be valuable but difficult to retrieve. You need both layers.

    Build topical depth around the page

    AI visibility is better approached as a body of coherent expertise than as an optimization added to an isolated URL. A team with limited capacity should define a narrow area it can cover consistently, map the questions surrounding that area, and assign a clear purpose to each page. Specificity, depth, and consistency can be more useful than publishing indiscriminately at high volume.

    • Choose the boundary: identify the subject, audience, and decisions the cluster will serve.
    • Map distinct intents: separate definitions, current developments, comparisons, procedures, objections, and decision questions rather than forcing them into duplicate pages.
    • Assign canonical coverage: give each important intent a primary page and update that page instead of repeatedly starting over.
    • Connect the cluster: use contextual internal links that explain how supporting pages relate to the central subject.
    • Remove contradictions: reconcile outdated definitions, numbers, names, and recommendations across the cluster.
    • Show expertise: identify where first-hand reporting, specialist analysis, or original evidence materially improves the answer.

    This architecture helps machines associate your publication with a defined subject, but it also improves the human journey. A reader who arrives for a concise answer can move into evidence, context, and adjacent questions without returning to search.

    Protect content rights without making blind SEO tradeoffs

    AI search turns content access into a governance issue as well as a traffic issue. Editorial, audience, product, commercial, technical, and legal teams may value the same crawler or answer surface differently. The SEO team wants discoverability. The commercial team wants visits or licensing value. The newsroom wants attribution. Legal counsel may need to interpret agreements and jurisdiction-specific rights.

    The French newspaper dispute shows why those decisions cannot be reduced to a crawler setting. APIG alleges that AI Overviews were introduced without publisher approval and violated commitments under a compensation arrangement. Google maintains that AI Overviews help people ask more complex questions, discover content, and manage how publisher material appears. The complaint has not, by itself, settled those competing claims.
    The surrounding enforcement history raises the stakes: France’s competition authority fined Google €250 million in 2024 for failing to comply with parts of the 2022 agreement. That does not establish what another publisher is entitled to in another jurisdiction. It does mean access, compensation, and competitive effects should be reviewed as real business risks rather than left to an informal SEO decision.

    • Inventory exposure: document which content classes are open to search engines, answer engines, partners, feeds, archives, and licensed distributors.
    • Map economic value: identify which sections depend on advertising, subscriptions, lead generation, ecommerce, syndication, licensing, or reputation.
    • Preserve evidence: retain traffic histories, referral records, prompt-audit captures, cited URLs, contracts, and relevant platform communications.
    • Review current controls: confirm what each platform’s present controls actually govern. Crawling for search discovery, answer generation, snippets, and model-related uses should not be assumed to be the same function.
    • Model the tradeoff: estimate what happens if a content class loses search visibility, loses AI visibility, gains licensing value, or receives citations without visits.
    • Assign decision authority: require technical, editorial, commercial, and legal approval for broad access-policy changes.

    Do not interpret a compensation agreement or content-use right from SEO guidance alone. Use qualified legal counsel for the relevant contract and jurisdiction. A broad blocking, gating, or de-indexing change can also reduce discovery, so validate the exact technical effect and begin with a limited, reversible test when that is compatible with your legal position.

    What to change in your next publishing cycle

    You do not need a sitewide redesign to begin. Apply the new operating model to the topic cluster that already matters most to your audience and business.

    1. Select the priority cluster. Choose an area where you can demonstrate real expertise, where audience questions recur, and where visits or influence have a defined value.
    2. Capture the baseline. Record rankings, impressions, clicks, click-through rate, landing-page outcomes, AI referrals, prompt citations, and brand mentions before changing content.
    3. Inspect the answer surfaces. Run your fixed prompt set and review the live search experience for important queries. Note whether an answer resolves the task, which pages it cites, and what reason remains to visit.
    4. Retrofit priority pages. Add a clear answer, explicit entities, well-scoped claims, visible evidence, accurate structured data, and a deeper layer that helps the reader verify or apply the answer.
    5. Strengthen surrounding coverage. fill genuine question gaps, consolidate overlapping pages, repair internal links, and reconcile inconsistent information across the cluster.
    6. Set decision rules before reviewing results. Define how you will respond when citations rise without visits, visits rise without citations, both improve, or neither changes.

    Those decision rules keep the program honest. If citations rise but no traffic or measurable business outcome follows, record the result as influence and decide whether influence is worth funding. If rankings remain stable while clicks fall on queries now resolved by an answer surface, strengthen the page’s visit-worthy layer or shift effort toward questions that require deeper engagement. If neither traditional visibility nor AI selection improves, more tracking will not solve the problem; revisit the content’s authority, clarity, and fit with audience intent.

    Start by capturing the baseline for your highest-value cluster before its next update. Then make the answer easier to extract and the full page harder to replace. That combination gives you a defensible SEO strategy even when discovery, citation, and traffic no longer arrive together.

    References


  • How to Choose an AI Search Agency for Home Services or Dental

    How to Choose an AI Search Agency for Home Services or Dental

    You are not choosing between three interchangeable labels. You are choosing whether an agency can make your business understandable, credible, and selectable when someone asks an AI system whom to hire.

    That decision looks different for a plumbing company and a dental practice. A homeowner may need an agent to identify an available contractor and request an estimate. A prospective patient needs an accurate recommendation that reflects treatment needs, provider fit, and location. The right agency will build around that decision path instead of selling you a renamed SEO package.

    The acronym matters less than the decision path

    Generative engine optimization, or GEO, focuses on earning visibility and recommendations in generative answers. Answer engine optimization, or AEO, focuses on becoming a useful source for direct answers. Agentic search optimization, or ASO, extends the job into actions an AI agent may take for the user.

    For home services, that final stage is already central to the proposition: contractor selection, estimate requests, and service-call scheduling are the kinds of outcomes an ASO program is expected to support. Dental GEO and AEO remain more heavily centered on local provider recommendations and new-patient appointment demand.

    An agency does not need to use your preferred acronym. It does need to show how it will improve retrieval, evaluation, and action for the decisions your customers or patients actually make.

    Decision layerHome servicesDentalWhat the agency must demonstrate
    Candidate retrievalRecognition for the right trade, service, problem, and service areaRecognition for the relevant treatment, specialty, provider type, and locationA controlled set of non-branded questions that represents real demand
    Suitability evaluationClear project types, exclusions, coverage, availability, and customer fitClear treatments, provider qualifications, patient concerns, and practice fitPages and corroborating facts that help an AI system distinguish suitable from unsuitable choices
    ActionA working path to call, request an estimate, or schedule serviceA working path to call or request an appointment without replacing clinical judgmentConversion tracking, action-path testing, and an agreed definition of a qualified lead
    Accuracy riskWrong service-area or capability information can create wasted calls and dispatch problemsWrong treatment or provider information can mislead a person making a healthcare decisionA named owner for fact approval, correction, and ongoing updates

    Key takeaways

    • Hire for the vertical decision path, not for the agency’s preferred GEO, AEO, or ASO label.
    • Home-services programs need strong action readiness: accurate coverage, suitability, and a reliable route to an estimate or booking.
    • Dental programs need clinically reviewed patient information and precise treatment, provider, and location positioning.
    • Use agency rankings to discover candidates, not as a substitute for case evidence, capacity checks, and references.
    • Require reporting that separates AI visibility from qualified calls, appointments, booked work, and revenue.

    Build your shortlist around operating fit

    You can find plenty of agency leaderboards. Their scores may help you discover firms, but they cannot tell you whether a team fits your footprint, operating model, budget, or approval process. The agency operating each publication used here also places itself first in its own ranking. A self-ranking result is not automatically wrong, but it is not independent validation. Treat the numerical scores as screening material and verify every consequential claim yourself.

    Home-services agencies to interview

    The home-services candidate field covers contractors in HVAC, plumbing, electrical, roofing, restoration, pest control, insulation, and adjacent services. The useful distinction is not who occupies which rank. It is what kind of operation each agency appears built to serve.

    Your situationAgencies worth an initial interviewWhy they fit the shortlistWhat to verify
    You want a full-cycle retrieval, evaluation, and action programFirst Page SageIts disclosed model combines authority content, service-area positioning, and suitability work across several home-services categoriesThe longer onboarding process, assigned capacity, lead attribution method, and ownership of finished assets
    You are a contractor, remodeler, architect, or design-build businessSiana MarketingIts narrow construction and AEC focus includes project type, budget, and regional suitabilityAvailability, execution bandwidth, and whether its experience matches your exact trade rather than construction generally
    You run a regional or single-trade operation with a tighter budgetFocus DigitalIts positioning emphasizes accessible SEO and ASO strategy for smaller and midsize operatorsPublishing pace, team depth, and capacity if you add locations or service lines
    You want AI search inside a broader home-services marketing programRYNO Strategic SolutionsIts home-services background and full-funnel positioning may suit an operator that wants channels managed togetherWhich deliverables are genuinely AI-search-specific and which belong to conventional SEO, paid media, or web work
    You need a contractor-focused web and search partnerCI Web Group or Hook AgencyBoth are positioned around contractor marketing, with trade exposure that includes HVAC, roofing, plumbing, and related servicesExamples showing improvements in AI answers, not only traditional rankings, traffic, or website performance

    A roofing franchise with several markets should not select the same delivery model as an owner-operated plumbing company serving one region. Ask each agency to state how many service-location combinations it can support, who approves operating facts, and what happens when capacity or coverage changes. If the proposed system cannot absorb those changes, it will publish stale suitability signals.

    Dental agencies to interview

    For dental, start with firms whose disclosed work matches your actual growth problem. The dental field spans content-led GEO specialists, healthcare-focused teams, established dental web agencies, and platform-based providers.

    Your situationAgencies worth an initial interviewWhy they fit the shortlistWhat to verify
    You want a long-term, content-led GEO and SEO programFirst Page SageIts dental work emphasizes local landing pages, patient guides, comparisons, and new-patient lead generationClinical review, content differentiation, appointment attribution, and support for every specialty and location in scope
    You are making an earlier or more budget-conscious GEO investmentFocus DigitalIts healthcare-oriented model is positioned as an accessible way to build AI visibility and organic demandAdditional resource needs when the campaign expands across several specialties or locations
    You specifically want an AI-era lead-generation firmSignal Hill StrategiesIts model was designed around generative search for medical industries rather than added to a long-standing web packageDocumented dental outcomes and references, because the firm was established in 2026 and has a developing case library
    You primarily need dental web design and SEO, with GEO as a secondary objectiveRosemont MediaIts dental and elective-healthcare experience dates to 2008 and includes websites, content, SEO, and paid mediaThe depth of its GEO process beyond established dental SEO and web-design capabilities
    You want a brand-led dental marketing programWonderist AgencyIts stated specialty combines dental branding, website design, and SEOHow brand work will translate into measurable candidate inclusion and recommendation accuracy
    You prefer a broad, platform-oriented, or midsize-practice providerTitan Web Agency, Officite, or DentalScapesTheir stated positions respectively cover practices of different sizes, a platform-based model, and midsize dental practicesCustom strategy, account ownership, AI-search evidence, and any limitations imposed by the platform or service tier

    This is a first-call map, not a winner table. A strong traditional dental agency may be right when your website and local search foundation are weak. A dedicated GEO firm may be the better choice when your fundamentals are sound and the unresolved problem is AI recommendation visibility. Make the agency diagnose that distinction before it proposes work.

    Put six concrete artifacts in the scope of work

    Six unlabeled planning artifacts with maps, pathways, entity blocks, credibility symbols, content placeholders, and booking icons are arranged on a strategy table.

    Promises such as better AI authority or more visibility are not deliverables. Before you sign, turn the pitch into artifacts that your team can inspect, approve, and retain.

    1. A controlled question set. For home services, organize questions by service, customer problem, geography, suitability, and desired action. For dental, organize them by treatment, patient question, specialty, provider criteria, geography, and appointment intent. Include non-branded discovery questions as well as comparative and action-oriented questions. Otherwise, the agency can produce a flattering report by monitoring only prompts where you already appear.
    2. A canonical fact and entity ledger. Record the approved business name, locations, coverage, hours, services, exclusions, providers, credentials, contact routes, and booking options that apply. Add an owner and an approval status to each consequential fact. A dental clinician should approve treatment and patient-education claims; the marketing agency should not become the final clinical authority.
    3. A retrieval and evaluation content map. Every proposed service page, location page, patient guide, comparison, FAQ, or original-data asset should map to a demonstrated question or evidence gap. Reject a plan built around generic publishing volume. More pages do not help if they repeat the same claims or blur the boundary between services you do and do not provide.
    4. A structured-data map. Ask the agency to connect each machine-readable fact to visible, approved page content and to document how markup will be validated. JSON-LD can clarify entities, relationships, locations, and services, but it cannot manufacture authority or rescue unsupported claims. The map should also state who maintains the markup after templates, providers, locations, or services change.
    5. An external corroboration plan. The agency should identify which business profiles, citations, publications, professional references, and other third-party signals need correction or development. Ask it to separate controllable profile work from earned references it cannot guarantee. Vague promises of authority building are not enough.
    6. An action and measurement specification. Define the calls, forms, estimate requests, appointment requests, bookings, and qualified-lead states that will be tracked. Require action-path testing and a correction process for inaccurate AI answers. For dental, keep clinical decisions and sensitive patient information outside ordinary marketing workflows unless your practice has approved the necessary privacy and compliance controls.

    These artifacts also solve a common ownership problem. If the relationship ends, you should still possess the question set, fact ledger, content, structured-data documentation, reporting history, and access credentials. Without them, changing agencies can mean rebuilding the strategic foundation rather than simply changing the team executing it.

    Use the interview to expose generic SEO in AI clothing

    Do not spend the interview asking an agency to predict the future of AI search. Ask it to work through your current decision path. Strong operators become more specific when the discussion reaches services, locations, evidence, approval, and measurement. Weak ones retreat to traffic, content volume, or platform buzzwords.

    Ask thisA credible answer includesA weak answer sounds like
    How will you build our monitored question set?Segmentation by service or treatment, geography, intent, suitability, and action, with an explanation of why each segment mattersA generic keyword export or a secret proprietary list you cannot inspect
    How do you separate retrieval from evaluation?A distinction between appearing in the candidate set and being described as a suitable choice for the specific needOne visibility score with no answer-level evidence
    Show us a vertical-relevant example.The original problem, the facts and assets changed, representative AI outputs, and a business result or clearly stated limitationA screenshot of a favorable branded query with no baseline or conversion data
    What operating information do you need from us?Service boundaries, locations, exclusions, capacity, provider or technician facts, approvals, and change notificationsLittle or no involvement from your operations or clinical team
    How do you handle variable AI answers?A repeatable prompt protocol with platform, date, geography assumptions, answer capture, and trend reportingA promise that one answer or ranking position will remain stable
    How will you connect visibility to business outcomes?Defined conversion events, qualified-lead rules, source capture, and separation of mentions from calls, appointments, or bookingsImpressions, citations, or estimated visibility presented as revenue
    Who approves factual claims?Named business owners for operating facts and clinician review for dental treatment contentThe agency publishes from general web research without a documented approval route
    What happens when an AI answer is wrong?A triage process that checks owned pages, structured data, profiles, conflicting third-party information, and action pathsNo process beyond publishing another blog post

    Ask to see the artifacts on screen. A polished pitch can hide whether the agency has a real query taxonomy, fact-control process, or answer-level reporting system. Redacted examples are reasonable when client confidentiality applies, but the team should still be able to demonstrate its method.

    Measure the path from AI answer to booked business

    An icon-based path leads from an AI-style phone interface through a call and calendar to a home service visit and a dental appointment.

    AI visibility is an intermediate result. A useful report shows whether visibility is increasing, whether the recommendation is accurate, and whether the right person can complete the next step.

    Require four reporting layers

    LayerWhat to recordWhat it tells youWhat it does not prove
    RetrievalCandidate inclusion, mentions, citations, and visibility across the agreed question setWhether AI systems can retrieve and associate your business with relevant demandThat the system prefers you or that a customer will contact you
    EvaluationRecommendation language, stated reasons, suitability, and accuracy of service, treatment, provider, and location factsWhether your positioning survives comparison with alternativesThat the recommendation generated a qualified lead
    ActionCalls, forms, estimate requests, appointment requests, booked jobs, and the agreed qualified-lead statesWhether the discovery path produces usable demandThat every conversion is incremental or profitable
    IntegrityIncorrect facts, obsolete pages, conflicting profiles, broken booking paths, and correction statusWhether visibility is being gained without creating operational or patient riskThat the wider web contains no conflicting information

    Establish the baseline with the same controlled questions the agency will use later. Preserve the question wording, platform, date, location assumption, returned answer, citations, and recommended businesses. AI outputs can vary, so one favorable capture is evidence of an occurrence, not evidence of a durable trend.

    Then keep the commercial metrics vertical-specific. A home-services dashboard should distinguish an irrelevant call, an eligible estimate request, a booked visit, and completed work. A dental dashboard should distinguish a general inquiry, a new-patient appointment request, a scheduled appointment, and the practice’s approved downstream outcome. Do not let a growing mention count conceal poor suitability or an unusable booking path.

    Protect accuracy, access, and exit before signing

    Your contract should state who owns the content, structured data, dashboards, prompt history, and underlying accounts. It should name the people allowed to approve business and clinical facts, define how corrections are handled, and explain what you receive when the engagement ends.

    • Reject guaranteed placement in ChatGPT, Gemini, Claude, or any other AI answer surface.
    • Reject reporting that relies on unexplained proprietary scores without answer-level evidence.
    • Reject a content quota that is not mapped to a retrieval, evaluation, or action gap.
    • Reject schema-only positioning. Machine-readable markup is one part of the system, not the whole strategy.
    • Reject home-services plans that ignore coverage, capacity, exclusions, and the actual estimate or dispatch path.
    • Reject dental plans that permit unreviewed treatment claims or confuse marketing automation with clinical guidance.
    • Reject account structures that prevent you from accessing your analytics, content, profiles, markup, or conversion history.

    Send the same operating facts, question set, scope requirements, and reporting expectations to a small shortlist. The agency that gives you the clearest boundaries, evidence, and ownership model is usually a safer choice than the one offering the boldest visibility promise. Your next move is not to buy a ranking. It is to make each candidate show exactly how your business will be retrieved, evaluated, and chosen.

    References


  • Fraudulent DMCA Takedowns: A Search Visibility Response Plan

    Fraudulent DMCA Takedowns: A Search Visibility Response Plan

    Your page was ranking yesterday. Now it is missing from Google, and a DMCA notice says somebody else owns work you created. Do not answer by rewriting, deleting, redirecting, or republishing the page. Preserve its current state first.

    Treat this as two connected incidents: a legal removal process and a search visibility outage. The counter-notice addresses the first. Evidence preservation, URL stability, and post-restoration checks address the second. Here is the order that keeps those tracks from working against each other.

    Key takeaways

    • Confirm whether Google deindexed the URL, your hosting provider disabled it, or its rankings simply declined. Each problem has a different response.
    • Freeze the page, server response, CMS history, complaint, and search data before changing anything. Your timeline is part of your defense.
    • Build proof from several independent records: CMS logs, historical web captures, RSS publication records, Git commits, and original working files.
    • A DMCA counter-notice is a signed legal submission, not an ordinary support appeal. It requires identifying information, a statement under penalty of perjury, and consent to court jurisdiction.
    • Track the 10-to-14-business-day response window from the platform’s acceptance of a valid counter-notice, not from the day you first discovered the removal.
    • Restoration, reindexing, ranking recovery, and renewed AI visibility are separate milestones. Verify each one instead of assuming the whole problem ended when the URL returned.

    Why a false copyright complaint can become a search outage

    Section 512 of the DMCA gives qualifying online platforms a safe harbor from copyright liability when they respond expeditiously to infringement notices. That creates an asymmetric risk calculation: removing a page is usually safer for the platform than delaying removal while it investigates ownership. At scale, automated processing can therefore act before meaningful human review. A claimant can initiate the process quickly, while the publisher must assemble and submit the proof needed to reverse it. That speed-over-verification incentive is what makes fraudulent notices effective.

    Three attack patterns deserve particular attention. In a scraper-and-backdate scheme, someone copies your work to a disposable domain, changes the displayed publication date, and claims your original is the copy. A fabricated claimant uses a false organization or impersonated publisher to conceal who is behind the notice. Reputation suppression targets criticism, investigative coverage, reviews, or complaints during a period when losing search visibility would be especially valuable to the subject.

    Authority does not make a domain immune. In one documented case, pages from Search Engine Land and Press Gazette disappeared from Google worldwide within 48 hours of a complaint from an entity calling itself US Webspam. The complaint alleged copied proprietary images even though the Search Engine Land page contained no images. The URLs returned after a formal counter-notice, public scrutiny, and several days of disruption. The episode shows why an obviously inconsistent allegation can still trigger deindexing.

    Before treating every disappearance as DMCA abuse, identify the affected layer. A ranking loss without a legal-removal notice is not evidence of a fraudulent claim.

    What you observeLikely affected layerFirst place to check
    The direct URL loads normally, but Google reports a legal removal or no longer indexes itSearch indexGoogle Search Console, the account email associated with the property, and the complaint record
    The direct URL returns a provider suspension page or an unexpected 4xx responseHost, CDN, or another infrastructure providerThe provider account, abuse desk message, origin server, and DNS/CDN configuration
    The URL remains indexed but impressions or positions declined, with no removal noticeSearch performance or ordinary index eligibilitySearch Console performance data, URL Inspection, canonical tags, robots directives, and recent site changes
    Only one AI answer or one manual search omits the pagePotentially normal answer or result variationUnderlying crawlability and index status before assuming a legal removal

    Preserve the URL and build a defensible ownership record

    A generic web page sits in a transparent evidence case beside a camera, envelope, clock, padlock, and source-file folders.

    Your first job is not to write a persuasive rebuttal. It is to prevent evidence from disappearing or becoming harder to interpret. A rushed edit can change the page’s modification date, replace the HTML that disproves an allegation, or obscure which version was live when the complaint was filed.

    1. Save the entire notice. Download the email, platform message, attachments, case number, timestamps, claimant identity, alleged owner, disputed URL, and alleged original URL. In Google Search Console, check the legal-removal information associated with the property, including messages under Security & Manual Actions and the related account email. Search the Lumen Database for the URL, domain, claimant, or case details; it archives many legal requests and can reveal exactly what was alleged. These notice-inspection steps give you the claim you actually need to answer.
    2. Capture the current technical state. Record the HTTP status, rendered page, raw HTML, canonical URL, robots meta directive, structured data, sitemap entry, and relevant response headers. Save screenshots, but do not rely on screenshots alone when raw exports are available. If the complaint alleges an image that was never present, preserve both the rendered page and HTML showing the absence of that asset.
    3. Construct a publication chronology. Export the CMS creation time, original publication time, revisions, editor history, and database records rather than manually copying dates into a document. Add historical Wayback Machine captures, timestamped RSS records, and Git commits showing when the file entered version control. These are specifically useful because scraper-and-backdate attacks try to manufacture earlier-looking publication dates.
    4. Match the evidence to each allegation. List every passage, image, chart, file, or other work the claimant identifies. Place your earlier version beside the alleged original and record the provenance for each disputed element. If the notice is vague, preserve that vagueness rather than guessing what the claimant meant.
    5. Export your visibility baseline. Save Search Console page and query data for the affected URL, its index status, analytics landing-page data, and relevant server logs. Note when impressions, clicks, crawls, referrals, and direct visits changed. This will help you distinguish legal restoration from later search recovery.

    No single timestamp is conclusive merely because it looks official. A displayed publication date can be edited, and an attacker may rely on that ambiguity. Your strongest record is a consistent chain across systems that were created for different purposes: CMS revisions, external captures, syndication records, version-control history, and original working files.

    Package the material so a reviewer can follow it without reconstructing your case. Start with a one-page chronology. Follow it with an exhibit index, the notice, both URLs, the disputed elements, and the records establishing publication order. Keep untouched originals separately from any annotated copies. Do not backdate a CMS field, rewrite structured data, or alter a file’s metadata to make your case look cleaner. That creates new inconsistencies and can damage an otherwise legitimate response.

    Use the counter-notice process with its legal consequences in view

    A DMCA counter-notice is not an SEO reconsideration request or an informal email to support. It is a signed legal declaration. The required submission includes personal contact information, a statement under penalty of perjury, and consent to specified federal court jurisdiction. The platform forwards the valid counter-notice to the original claimant.

    That exposure matters. If ownership is genuinely disputed, the work contains licensed or commissioned material, a freelancer created it, the claimant has a plausible contractual argument, or you are concerned about disclosing your physical address, consult a qualified copyright lawyer before filing. Do not use invented contact details or make a perjury statement merely to restore traffic. This incident-response framework cannot determine who legally owns a particular work.

    A statutory counter-notice generally needs all of the following:

    • Identification of the material that was removed or disabled.
    • The location where that material appeared before removal, including the exact URL.
    • A statement under penalty of perjury that you have a good-faith belief the removal resulted from mistake or misidentification.
    • Your full name, physical address, telephone number, and email address.
    • Consent to the jurisdiction of the appropriate federal district court, including the applicable provision for a person outside the United States.
    • Your physical or electronic signature.

    Use the platform’s current counter-notice form or the designated process identified in its notice. Copy the affected URL exactly and answer the alleged work rather than submitting a broad complaint about lost rankings. A detailed evidence package can support your good-faith position, but it does not replace any required declaration. The mandatory counter-notice elements are what make the response legally operative.

    Start the response clock from confirmed receipt

    Keep the platform’s acknowledgement showing that it received a valid counter-notice. Once the platform forwards it, the claimant has 10 to 14 business days to provide evidence of a filed lawsuit seeking a court order that restrains publication. That means business days, not calendar days, and the trigger is the valid counter-notice process rather than your first support email.

    Put the dates on a case calendar. If the platform asks for a correction, the statutory process may not yet be running, so answer the deficiency promptly and preserve both messages. If the window passes without evidence of a court filing and the material remains unavailable, reply within the same case thread. Include the acceptance date, elapsed business days, exact URL, and a concise request for restoration under the counter-notice process.

    Public attention can create useful scrutiny during a high-impact outage, but it does not replace the formal response. If you publish a chronology, limit it to documents, dates, visible inconsistencies, and actions the platform has confirmed. Do not speculate publicly about an attacker’s identity or motive when you cannot prove either. If the record indicates a knowing material misrepresentation, a copyright lawyer can assess whether Section 512(f) or another remedy is relevant to your circumstances.

    Protect search visibility while the claim is pending and after restoration

    A glowing network path reconnects a magnifying-glass-shaped portal to a stable web-page node while diagnostic lights inspect it.

    A legal response can restore access, but it cannot preserve search signals if you dismantle the URL while waiting. When the provider permits the page to remain live and your legal assessment supports publication, keep the original slug, self-referencing canonical, internal links, and sitemap entry stable. Do not launch a duplicate at a new URL or domain simply to get around deindexing. That can divide signals, create a second takedown target, and complicate the ownership record.

    If a host has disabled the content, preserve the site’s routing and configuration rather than hastily converting the address into a permanent redirect or 410 response. Coordinate any temporary response with the provider and, where legal exposure is real, counsel. The safe technical choice depends on whether the material is unavailable because of the search engine, the host, or both.

    Keep authorship and publication metadata accurate. Your visible byline, canonical URL, publisher information, datePublished, and dateModified should agree with the page and your internal records. JSON-LD can make those facts machine-readable, but schema is not proof of copyright ownership. Backdating markup to defeat a fraudulent claim only imitates the attack pattern you are trying to expose.

    Verify recovery as a sequence, not a single event

    1. Confirm restoration at the affected layer. Check that the host serves the intended page and that the legal-removal case is closed or updated. A restored host page does not prove that Google has reindexed it.
    2. Recheck index eligibility. Confirm a successful response, the intended canonical, no accidental noindex, and no robots rule blocking the search crawler. Compare the live page with the technical capture you made before responding.
    3. Use Google Search Console for the URL itself. Inspect the canonical URL, test the live page, and request indexing when appropriate. Keep the sitemap accurate, but do not repeatedly change its lastmod value or resubmit it without a real page change.
    4. Measure returning visibility. Watch URL-level impressions, clicks, queries, and crawl activity against the saved baseline. Restoration to the index and recovery to a previous ranking position are different outcomes, and there is no defensible fixed timetable for the latter.
    5. Check AI discovery separately. Test the prompts and answer surfaces that previously exposed or cited the page, but treat individual answers as spot checks. AI systems differ in how they retrieve, crawl, refresh, and generate responses. A restored Google result does not guarantee immediate inclusion in every AI answer.

    Once the immediate incident is closed, make provenance routine. Save a CMS-history export when important work is published, maintain RSS publication records, keep content files in version control where practical, retain original media and drafts, and arrange periodic external captures of high-risk pages. Enable Search Console notifications and give one person responsibility for legal-removal alerts, evidence preservation, counsel escalation, platform submissions, and technical recovery.

    Before you close this tab, export the affected page’s revision history and current Search Console data, then write down the exact time you discovered the removal. Those two actions take minutes and give every later response a cleaner factual foundation. After the crisis, apply the same provenance workflow to investigative coverage, high-value evergreen pages, reviews, and any content a competitor or criticized party would benefit from suppressing.

    References


  • How to Measure Google AI Search Discovery and Performance

    How to Measure Google AI Search Discovery and Performance

    Your Google organic dashboard can look steady while AI search changes how buyers discover you, compare your claims and decide whether your brand belongs on their shortlist. If you report only sessions and last-click conversions, much of that influence remains invisible.

    You do not need to solve perfect attribution. You need a measurement system that distinguishes what you can observe directly from what you can only infer. The practical model runs from verified AI access through visibility, identifiable visits, downstream demand and business outcomes.

    Google’s AI entry points change the top of the journey

    Google is experimenting with more explicit ways to lead people into AI-powered search. A limited desktop test places Create images, Ask about files and Brainstorm beneath the Google search box; selecting one takes the user into AI Mode. Google has also said that the test does not change how the main search box works.

    Do not treat a limited interface test as proof of a broad rollout or a ranking change. Its value is diagnostic: Google is testing whether clearer prompts help people discover tasks they may not associate with Search. If those entry points expand, more journeys could begin with an open-ended task instead of a conventional keyword.

    That creates two discovery questions you should measure separately:

    • Surface discovery: Where does the person begin – conventional Google results, an AI Overview, AI Mode or an external AI assistant?
    • Brand discovery: When the person asks a market, comparison, implementation or validation question, does your brand appear in the response?

    Add both fields to your query and prompt inventory. A keyword report organized only by search volume will not show whether you are present when someone asks an AI system to build a shortlist, test a claim or compare approaches. Group prompts by the job the person is trying to complete, then record the surface on which you test them.

    Use five measurement layers instead of one AI traffic total

    Five translucent platforms stack from an access gateway at the bottom to a completed transaction at the top.

    AI discovery does not produce one clean, universal tracking parameter. It produces a chain of observable signals. A useful scorecard follows five layers from AI access to revenue, with each layer answering a different question.

    LayerQuestionSignals to trackDecision it supports
    1. AI accessCan legitimate AI systems reach the pages that matter?Verified bot crawl frequency, crawl depth and coverage of priority URLsFix access, rendering or retrieval barriers before judging visibility
    2. AI visibilityDoes your brand enter relevant answers?Mention rate, citation rate, cited URLs, prompt coverage and Google Search Console impressions as supporting contextFind topics, use cases and journey stages where competitors dominate
    3. Identifiable AI visitsWhich measurable AI clicks reach the site?Recognizable AI-assistant referrals, landing pages, conversions and attributable revenueImprove pages receiving observable AI traffic
    4. Downstream demandDoes AI visibility appear alongside later brand interest?Branded clicks in Search Console, organic conversions, direct demand and repeat visitsAssess influence that referral reports cannot capture directly
    5. Business outcomesIs the program contributing to commercial value?Qualified pipeline, closed-won opportunities and revenueContinue, redirect or reduce investment

    Define the denominator for every rate before reporting it. Access coverage can be the number of priority URLs reached by verified AI bots divided by the total priority URL set. Mention rate can be valid prompt runs that name your brand divided by all valid runs. Citation rate can be valid runs that cite an owned page divided by all valid runs. A valid run is one completed under the test conditions you recorded.

    Keep the layers separate on the dashboard. A crawler request does not prove that an answer used your content. A mention does not prove that anyone clicked. A referral session does not prove that AI created all later revenue. Each signal becomes useful when it answers its own question without being promoted into evidence for the next layer.

    Start access measurement with a fixed set of commercially and informationally important URLs. Count only verified AI bot activity where possible. User-agent strings can be spoofed, so validate requests through reverse DNS, published IP ranges or a CDN’s verified-bot service. Report frequency, coverage and repeat access, but label them as retrieval indicators rather than visibility wins.

    Make prompt visibility repeatable enough to show a trend

    A few screenshots gathered after publishing a page can show that an answer occurred. They cannot tell you whether visibility is improving. AI responses vary, prompts that look similar can express different intent, and an isolated mention can disappear on the next run.

    Build a stable core prompt library around real buying tasks. Use sales questions, support questions, comparison criteria and implementation objections already present in your business. Separate the core library from exploratory prompts so adding a new idea does not silently change your historical denominator.

    For every core prompt, store:

    • A permanent prompt ID and the exact wording.
    • The intended market, audience, journey stage and task.
    • The Google surface or AI assistant tested.
    • The date, language and location, plus account or personalization state when known.
    • Whether the brand was mentioned.
    • Whether an owned page was cited, including the cited URL.
    • Which competing brands or domains appeared.
    • A saved copy of the response so the score can be audited.

    Choose a testing cadence your team can reproduce and keep the procedure consistent. Do not combine results from different surfaces as though they were interchangeable. Report each surface separately, then provide a combined view only when the weighting method is explicit.

    Score mentions and citations independently. A brand can be named without receiving a link, while an owned page can support an answer in a different way. Use four simple response states: mentioned and cited, mentioned but not cited, competitor cited instead, or no relevant brand present. Those states tell you more than a single visibility score.

    Treat the states as diagnostic clues, not automatic explanations. If verified bots repeatedly reach a priority page but the page never appears for closely aligned prompts, investigate its relevance, clarity and supporting evidence. If competitors receive citations while your brand receives uncited mentions, inspect which of their pages supplies the answer-ready detail your page lacks. If no domain is cited, do not assume your technical setup failed; the response may simply not expose supporting links.

    Read Google analytics without inventing AI attribution

    GA4 can identify referral traffic from recognizable AI assistants when a click arrives with a measurable referring source. That makes AI-assistant sessions, landing pages, conversions and revenue useful direct-response metrics.

    Google’s own AI experiences require more restraint. AI Mode and AI Overview visits are generally blended into Google organic traffic and can sometimes appear as Direct, depending on how the click is passed. They should not be added to an AI-referral segment, and all Google organic traffic should not be relabeled as AI traffic.

    Configure the report in four parts:

    1. Create a narrowly defined segment for recognizable AI-assistant referrers. Keep the matching rules documented so changes are auditable.
    2. Report sessions, landing pages, meaningful conversions, pipeline and revenue for that segment. This is the observable subset of AI-driven visits, not the total effect of AI discovery.
    3. Keep Google organic and Direct as separate channels. Use them as contextual trends, not as traffic you can confidently assign to AI Mode or AI Overviews.
    4. Chart branded clicks from Google Search Console beside organic conversions and other downstream demand. Do not imply a user-level connection that the platforms do not provide.

    Define your brand-query rule before reading the trend. Include the company name, product names and common variations that genuinely signal brand demand, then preserve that rule from period to period. Changing the query set whenever the chart moves turns the metric into a narrative tool rather than evidence.

    A rise in AI visibility followed by sustained growth in branded demand makes the influence case stronger, especially when the timing repeats across reporting periods. It still does not prove that AI caused every branded visit. Brand campaigns, publicity, product launches and offline activity can produce the same pattern, so annotate those events and state the alternative explanations.

    Review the chain in order and act on the first weak layer

    A glowing signal passes through five connected glass chambers and fades at a partially obstructed stage under an inspection light.

    Run the performance review in causal order: access, visibility, identifiable visits, downstream demand and business results. Starting with revenue and working backward encourages convenient explanations. Starting with access shows where the evidence actually breaks.

    1. Check whether verified AI bots reached the priority URL set. If access fell, resolve verification, blocking, rendering or retrieval problems before interpreting prompt results.
    2. Compare mention and citation rates using the unchanged core prompt library. If access is healthy but visibility is weak, inspect topic coverage, answer clarity and the evidence presented on the page.
    3. Inspect identifiable AI referrals. If visibility rises without referral growth, do not declare failure; many AI-influenced journeys do not produce a measurable citation click.
    4. Look for downstream demand. Compare branded clicks and organic conversion trends with the visibility timeline while accounting for campaigns and other events.
    5. Connect the pattern to qualified pipeline, closed-won opportunities and revenue. If demand rises but pipeline does not, investigate conversion quality, offer fit and the sales handoff instead of chasing more mentions by default.

    The most honest executive view contains both a result and a confidence label. Verified referral revenue is directly observable. A repeated relationship between prompt visibility and branded demand is supporting evidence of influence. A single simultaneous spike is a hypothesis. This language makes the report more credible because it prevents a plausible story from being presented as measured attribution.

    Key takeaways

    • Treat Google’s new AI entry points as behavior to monitor, not proof of a completed rollout or ranking change.
    • Measure AI search through five layers: verified access, prompt visibility, identifiable visits, downstream demand and business outcomes.
    • Verify AI bots with network-level evidence rather than trusting a user-agent string alone.
    • Keep a stable core prompt library and record mentions, citations, cited URLs and competing brands separately.
    • Use AI-assistant referrals as an observable subset. Do not label all Google organic or Direct traffic as AI-driven.
    • Use branded demand as evidence of possible influence, then qualify it against campaigns and other explanations.

    Your next move is small and concrete: choose the priority URL set, freeze the first version of your core prompt library and create one dashboard row for each measurement layer. On the next review, act on the earliest weak layer in the chain. That is where the evidence says the program is breaking, and where the next improvement is most likely to be measurable.

    References


  • How to Build Brand Trust Across AI Search Journeys

    How to Build Brand Trust Across AI Search Journeys

    You can rank well, appear in AI answers, and still lose the decision. A prospective customer asks an assistant for options, verifies the answer in Google, checks a community, watches a demonstration, and finally visits your website. If those stops present conflicting claims, more visibility creates more doubt.

    Your job is not to force every channel to repeat the same copy. It is to make every relevant surface support the same verifiable conclusion: who you help, what you do, where the offer fits, what its limits are, and why the customer should believe you. That requires a trust system spanning SEO, AEO, GEO, content, digital PR, community participation, reviews, and structured data.

    Key takeaways

    • Optimize the journey around unresolved uncertainty, not isolated channel ownership.
    • Match each confidence gap with the right evidence: reliable facts, peer experience, evidence of fit, or a clear path to action.
    • Maintain a claim ledger so your website, structured data, sales material, and third-party descriptions do not contradict one another.
    • Treat JSON-LD as a translation layer for supported facts, not a way to manufacture trust.
    • Prioritize independent, topically relevant corroboration over high-volume links or paid mentions with no editorial context.
    • Measure presence, answer accuracy, evidence coverage, proof-asset engagement, and customer-reported influence. Click attribution alone cannot show the whole journey.

    Map the confidence gap before choosing the channel

    AI search has expanded the journey rather than cleanly replacing traditional search. In one agency-led behavioral segmentation, 56% of people regularly used AI search while 57% still belonged to a Traditional Searcher segment. Those groups can overlap because the same person can use an AI assistant to understand a category, Google to verify a claim, Reddit to find candid experiences, YouTube to see a product in use, and a company website to decide whether the seller is credible.

    This makes a conventional funnel too blunt for trust planning. The customer is not thinking about moving from awareness to consideration. They are resolving one uncertainty after another until acting feels defensible. Your content plan should therefore begin with the question the customer still cannot answer, not the platform on which you hope to reach them.

    Confidence jobQuestion in the customer’s mindEvidence to prepareLikely discovery points
    Fact findingCan I rely on the basic claims?Clear specifications, definitions, methodology, original evidence, expert explanations, and current documentationAI answers, traditional search, your website, and cited reference pages
    CrowdsourcingWhat happened to people in a situation like mine?Authentic reviews, detailed case studies, customer commentary, and useful community discussionsReview platforms, Reddit and other communities, search results, and AI summaries
    Taste tuningDoes this approach fit my preferences, constraints, and working style?Demonstrations, examples, creator coverage, screenshots, use-case pages, and candid fit guidanceYouTube, creators, social platforms, comparison pages, and your website
    AutopilotCan I make the decision or complete the next step without unnecessary effort?Decision criteria, implementation steps, transparent requirements, comparison tools, and a clear conversion pathAI assistants, search, product workflows, sales material, and your website

    The same person may perform all four jobs during one purchase. An executive sponsor, a practitioner, and a procurement stakeholder may also have different gaps even when they are evaluating the same company. A single generic buyer-journey map will hide those differences.

    Run a confidence-gap exercise for one audience and one decision at a time:

    1. Write the decision in concrete terms, such as choosing a provider for a defined use case.
    2. Collect the questions that appear in search data, sales calls, support conversations, reviews, community threads, and comparison requests.
    3. Classify each question as fact finding, crowdsourcing, taste tuning, or autopilot. Some questions will serve more than one job.
    4. Write down what would constitute adequate proof. Do not settle for a content format such as a blog post; specify the evidence the customer needs.
    5. Identify where that customer would naturally seek the evidence and who must own its accuracy.
    6. Mark the gaps for which no credible asset exists. Those are your content priorities.

    This process often changes the brief. A broad educational article cannot repair a missing implementation explanation. Another landing page cannot replace independent customer evidence. A paid mention cannot settle a factual contradiction between your documentation and sales copy.

    Build a claim-and-proof system that survives summarization

    Geometric claim tokens paired with evidence objects pass through a narrowing translucent funnel and emerge as compact modules with each claim still attached to its proof.

    AI-mediated discovery separates your claims from their original layout. A sentence may be summarized, compared with a competitor, quoted without its surrounding caveat, or combined with third-party commentary. Your important claims must remain accurate and understandable when they travel.

    Start with a claim ledger. This is a working record of what your organization wants customers and machines to understand. For each priority claim, record:

    • The exact proposition, including the audience, use case, product, tier, market, or other limits that define its scope.
    • The evidence supporting it, such as documentation, a demonstration, original data, a case study, a customer review, or an independently verifiable credential.
    • The canonical page where the complete claim and its qualifications live.
    • The current status: supported, partly supported, unsupported, outdated, or contradicted elsewhere.
    • The third-party pages that corroborate it and the context in which they mention the brand.
    • The person responsible for correcting or refreshing it when the product, policy, evidence, or market changes.

    Do not limit the ledger to promotional claims. Include basic entity facts: the brand name, products or services, audience, locations served, category, use cases, founders or experts, and the relationship between the company and its offerings. Confusion at this level can make every later trust signal harder to interpret.

    Then turn the ledger into a layered evidence system:

    • Canonical facts: Stable pages explain what the business and offer are, who they are for, and what conditions apply.
    • Decision evidence: Demonstrations, comparison criteria, methodology pages, case studies, original research, and expert explanations show why a claim deserves belief.
    • Experience evidence: Reviews, customer accounts, community recommendations, and creator coverage show what using the product or working with the company is like.
    • Risk evidence: Limitations, requirements, policies, implementation details, and honest fit guidance help customers rule the offer in or out.
    • Action evidence: Clear next steps show what happens after the customer chooses, reducing uncertainty at the handoff.

    Each evidence page should answer the central question near the claim, explain how the conclusion was reached, disclose important boundaries, and point to the next level of detail. Avoid burying the method or caveat in a disconnected document. If the qualification changes the meaning of the claim, keep the two together.

    Use structured data to clarify, not embellish

    JSON-LD can describe entities, attributes, authorship, products or services, and relationships in a machine-readable form. It cannot establish that a marketing claim is true, create an independent reputation, or guarantee inclusion in an AI answer.

    Keep the markup aligned with visible content. Organization identity, names, descriptions, authors, offers, reviews, and other marked-up details should agree with the page and with the canonical facts in your claim ledger. Do not place an accolade, rating, audience claim, or product attribute only in the markup. Structured data should be a faithful translation of the page, not a second and more flattering version of it.

    Consistency does not require copying one description word for word across the web. A creator needs a demonstration, a community participant needs a direct answer, and an AI-friendly reference page needs clear factual statements. The language can change while the underlying entity, scope, evidence, and conclusion remain stable.

    Earn corroboration instead of manufacturing consensus

    Four independent observers examine the same unbranded device from separate settings, with beams of light converging on one shared product feature while connected empty masks remain in the background.

    Backlinks still contribute to conventional SEO authority, but link volume does not prove that customers or AI systems should trust a brand. A placement can come from a high-authority domain and still be irrelevant, geographically mismatched, surrounded by unrelated commercial links, or disconnected from the page it supposedly endorses. That is why contextual relevance and credible corroboration are more useful tests than a domain metric alone.

    For AI visibility, use a practical working model: repeated, accurate descriptions on credible and topically relevant pages are more useful than isolated links inserted into unrelated content. A good external mention helps a person or system understand what the brand does, who it serves, the use case being discussed, and the basis for including it. The link may help discovery and navigation, but it cannot rescue meaningless context.

    Evaluate the mention as evidence

    Before pursuing or accepting a placement, inspect it with the same care you would apply to a claim on your own site:

    • Topical fit: The page discusses the problem, category, audience, or use case for which your brand is genuinely relevant.
    • Audience fit: The readers are people whose decisions the evidence could reasonably inform.
    • Editorial basis: The brand is included because of data, expertise, demonstrated capability, customer experience, or another explainable reason.
    • Claim specificity: The surrounding text says why the brand matters rather than dropping its name into a generic list.
    • Entity accuracy: The name, offer, market, use case, and relationship to the topic agree with your canonical facts.
    • Independence: Any sponsorship or commercial relationship is clear. A disclosed paid placement may provide reach, but it should not be counted as independent corroboration.
    • Context quality: The page is not overloaded with unrelated links, forced insertions, or claims that no reader could verify.

    Pitch the evidence, not the mention. Original findings can support an editorial explanation. A qualified expert can clarify a difficult decision. A working demonstration can help a reviewer assess fit. A customer with a relevant experience can support a case study or review, with appropriate permission and no script that predetermines the conclusion.

    One strong confidence asset can travel across several discovery points. An authentic review might appear in a traditional search result, inform an AI comparison, be quoted on a properly attributed website page, and be read directly on the review platform. The asset remains the evidence even when its discovery point changes. Plan distribution around that distinction.

    Reject tactics that imitate trust

    Buying a mention does not turn it into consensus. Be especially skeptical when a vendor promises AI visibility through reciprocal mention swaps, paid best-of lists presented as neutral rankings, irrelevant insertions on high-metric domains, or undisclosed promotional activity in communities. These tactics reproduce the weaknesses of commodity link building while changing the label from backlinks to GEO.

    The immediate problem is not merely that an artificial mention may fail to influence an answer engine. It gives your team a false picture of authority. A spreadsheet can show more placements while customers still lack a credible demonstration, an independent review, a current methodology page, or a clear explanation of fit. Third-party validation only helps when the third party and surrounding context are relevant enough to validate something.

    Do not set a quota for mentions until you can define what a qualifying mention is. Count the pages that accurately support a priority claim, not every page containing the brand name. This keeps outreach, PR, partnerships, community work, and link acquisition tied to customer confidence rather than output volume.

    Measure trust without pretending every influence is attributable

    Some confidence-building interactions are visible in analytics: visits, leads, sales, and conversions. Others happen before the customer reaches you. Someone may read a community thread, watch a review, ask an AI assistant for a comparison, and then conduct a branded search. Those interactions can influence the decision without appearing as attributable touchpoints.

    That does not make measurement futile. It means you need a scorecard that separates observable behavior from evidence coverage and directional signals.

    Track five views of the journey

    • AI and search presence: For representative queries, record whether the brand is absent, mentioned, included in a comparison, shortlisted, or recommended.
    • Answer fidelity: Check whether the surfaced description, audience, use cases, strengths, limitations, and other material claims are correct, ambiguous, outdated, or wrong.
    • Evidence coverage: Count which priority claims have a canonical page, adequate first-party support, credible external corroboration, and structured data that agrees with the visible facts.
    • Confidence-asset behavior: Monitor visits and meaningful engagement on case studies, demonstrations, methodology pages, reviews, comparisons, implementation guidance, and other proof assets. Examine whether customers who use those assets progress, without claiming the asset alone caused the outcome.
    • Commercial and customer signals: Track qualified leads, conversions, branded demand, direct visits, returning visitors, sales objections, and customers’ own descriptions of what influenced their choice.

    Replace the single-choice question How did you hear about us? with a multi-select question such as Which places helped you decide? Options can include an AI assistant, a search engine, a review site, a community, a video or creator, a colleague, and your website. Add an open response asking what almost stopped the customer from choosing you. The first question acknowledges a multi-platform journey; the second exposes the confidence gap your current assets did not fully close.

    Monitor prompts by confidence job

    A prompt library is more useful when it reflects how customers resolve uncertainty. Build unbranded and branded prompts for each job:

    • Fact finding: What should a defined audience verify before selecting this category for a particular use case?
    • Crowdsourcing: What experiences do similar buyers report with the available approaches?
    • Taste tuning: Which options fit a stated set of preferences, constraints, or working conditions?
    • Autopilot: Help the buyer evaluate a realistic shortlist and decide what to do next.

    For each check, save the exact prompt, search or assistant surface, date, result classification, claims made about the brand, cited pages, and any factual errors. Use the same core prompts again after material changes so you can inspect direction rather than reacting to one generated answer. Start unbranded to see whether the brand enters the category naturally, then use branded prompts to test whether its description and evidence remain accurate.

    Run the work in dependency order

    1. Select one valuable customer decision rather than auditing every possible journey at once.
    2. Map its fact-finding, crowdsourcing, taste-tuning, and autopilot gaps.
    3. Create the claim ledger and identify contradictions, unsupported claims, and missing canonical pages.
    4. Repair the first-party evidence before asking external sites or communities to repeat it.
    5. Package the strongest evidence for the publications, reviewers, creators, customers, partners, and communities that naturally serve the audience.
    6. Align visible content and JSON-LD with the supported claim set.
    7. Monitor representative prompts, proof-asset behavior, customer feedback, and commercial outcomes as separate but connected signals.
    8. Use the next cycle to fix the largest remaining confidence gap, not merely the channel with the easiest traffic report.

    Choose one high-value decision and audit its claims before publishing another awareness page. Mark each claim as supported, partial, unsupported, outdated, or contradicted, then fix the first contradiction a customer could encounter. In an AI-mediated journey, the fastest trust improvement often comes from making the evidence behind existing visibility easier to understand and verify.

    References


  • AI Visibility Signals: A Practical Framework for PPC

    AI Visibility Signals: A Practical Framework for PPC

    Your PPC account can look technically healthy while attracting buyers who expect the wrong service, product, price point or level of support. Search terms and conversion tracking show the resulting behavior, but they may not reveal where that expectation began.

    AI visibility signals add the missing pre-click context. They help you see how an AI system interprets a need, which information it retrieves and whether your brand helps shape the response. Used alongside PPC evidence, that context can tell you whether to adjust targeting, clarify a landing page, test new messaging or leave the campaign alone.

    Three signals fill the pre-click blind spot

    Conventional PPC analysis begins with observable activity: a search, an impression, a click, a visit or a conversion. AI can influence the buyer earlier by shaping what they know, which brands enter consideration and which words they later use. AI visibility data does not replace PPC reporting or prove that an AI response caused a conversion. It shows the informational environment surrounding the demand you are trying to capture.

    SignalWhat it revealsBest PPC useWhat it does not prove
    Grounding queriesThe retrieval searches an AI system uses to support a response, including the topics and sub-questions it associates with the original need.Diagnose intent, find useful language and identify possible keyword, search-theme, creative or landing-page tests.That every retrieved phrase should become a keyword.
    CitationsWhether your content was referenced while an AI-generated answer was assembled.Check whether the topics shaping consideration reinforce the promises in your campaigns.That the AI endorsed your brand, sent a visitor or produced a customer.
    Share of authorityHow much citation activity belongs to your domain relative to other cited domains in the same topic or query set.Locate topics where competitors help define the answer more often than you do and decide whether the gap is commercially important.Paid impression share, market share, brand sentiment or conversion probability.

    A single prompt can generate multiple grounding queries about comparisons, pricing, reviews, product details, availability or implementation. That makes grounding data richer than a keyword list, but also easier to misuse. It represents the system’s interpretation of intent, not a direct record of what a person typed.

    Citations need similar restraint. A citation means that a page contributed information to an AI experience. It does not tell you, on its own, whether the reference was prominent, favorable or persuasive. Review the associated topic and the cited page before deciding that a citation is commercially useful.

    Share of authority is comparative, so preserve the comparison. Use the same topic definition and query set when you evaluate changes. A number drawn from one prompt set should not be compared casually with a number drawn from another.

    Diagnose alignment across AI, ads, pages and customers

    An abstract AI node, ad tile, landing page and customer group connect through a central lens, with one amber path visibly out of alignment.

    The useful question is not whether your brand has AI visibility. It is whether AI interpretation, customer searches, advertising, landing-page claims and customer quality describe the same commercial offer.

    Trace one intent cluster through this sequence: AI interpretation, search behavior, ad promise, landing-page proof and business outcome. A break between two stages gives you a more specific diagnosis than a general visibility score.

    • AI and PPC intent align, and conversion quality is strong: you have a candidate for a controlled expansion test. Confirm that the landing page supports the intent before adding broader matching or automation.
    • AI interpretation and paid search terms drift in the same unwanted direction: the account may be reflecting a broader positioning problem. Clarify the offer and the audience before increasing bids or budget.
    • AI interpretation is wrong, but paid search terms and customers remain well aligned: treat this first as a content and brand-representation issue. Do not disturb a healthy campaign merely to react to an isolated AI signal.
    • AI interpretation is accurate, but paid search terms or customers are poor: investigate campaign matching, search themes, exclusions, ad promises and landing-page continuity. The evidence points more directly to the paid journey than to AI representation.
    • Competitors hold more citation activity for an important topic, but your PPC performance is healthy: inspect the content gap without assuming that paid budgets need to change. Share of authority is context for strategy, not a bidding instruction.

    Judge conversion quality using the downstream outcome your business actually values: customer fit, sales qualification, purchase value, retention potential or another established business measure. A form submission from the wrong customer can make campaign automation appear successful while teaching it to pursue more of the wrong demand.

    Topic alignment deserves particular attention. A cybersecurity platform seeking enterprise identity-protection buyers has a real problem if AI systems consistently associate it with small-business antivirus comparisons. The phrases are related at a broad category level, but they imply different customers, requirements and buying paths. That kind of mismatch can look like a targeting failure even when unclear positioning is the underlying issue.

    Build a repeatable AI-to-PPC analysis

    You do not need to pour every AI observation into the ad account. You need a repeatable method that separates evidence, interpretation and action.

    1. Write down the commercial truth first. State what you sell, who it is for, which problems it solves and which adjacent use cases you do not want to attract. This becomes the standard against which AI associations are judged.
    2. Choose a fixed set of commercially meaningful prompts. Cover the decisions that matter to your buyers, such as comparisons, pricing, reviews, product details, availability and implementation. Keep the set stable when you want to compare observations over time.
    3. Capture the AI evidence without interpreting it yet. Record the original prompt, grounding queries, cited domains and URLs, associated topics and share-of-authority result. Also record the AI surface, market and observation date so later comparisons retain their context.
    4. Cluster by underlying need. Group retrieval queries that express the same decision or problem even when their wording differs. Do not require an exact phrase match between a grounding query and a paid search term.
    5. Join each cluster to PPC evidence. Review related search terms, campaigns, ad promises, landing pages and conversion quality. Note whether AI and paid data point toward the same buyer and offer.
    6. Classify the association. Mark it as core, adjacent, misleading or unclear. Core means it matches a priority offer and customer. Adjacent means it is accurate but not a growth priority. Misleading means it describes something you do not sell or a customer you do not want. Unclear means the available evidence is insufficient.
    7. Write a testable diagnosis. Use a sentence such as: Because the AI evidence and PPC evidence both associate us with this lower-value need, we will clarify one page and one ad message, then judge whether customer quality improves.
    8. Prioritize corroborated patterns. Give more weight to an interpretation that appears across grounding queries, citations, search terms, landing-page language and customer quality. Log isolated observations, but do not let them trigger an account-wide change.

    A practical worksheet can use one row per intent cluster. Include the desired customer, grounding-query examples, cited topic, citation status, share-of-authority context, related paid search terms, current landing page, conversion-quality finding, alignment classification, working diagnosis, proposed action and success measure. Keeping those fields in one place stops a visibility observation from being mistaken for a campaign instruction.

    This process also prevents a common attribution error. AI visibility can help explain the context surrounding demand, but it cannot tell you that a specific citation caused a specific click or sale. Use conversion tracking for measured outcomes and AI visibility for interpretation.

    Turn the diagnosis into a controlled PPC test

    Two parallel marketing test lanes use the same audience inputs while one highlighted element differs between their ads and landing pages.

    When AI and PPC data expose a mismatch, resist the reflex to change bids. Audit the relevant landing page before assuming that budget, bidding or audience targeting is at fault. Check whether the page clearly identifies the problem being solved, supports its advertising claims with appropriate proof and describes the customer you actually want.

    Choose the smallest lever that can test the diagnosis

    • Test a keyword or search theme when the grounding-query cluster represents demand you genuinely want, related search terms show useful intent and an appropriate landing page already exists.
    • Test creative when AI and customers use accurate language that your ads fail to reflect, or when the ad needs to distinguish your offer from a nearby but lower-value category.
    • Update a landing page when the page blends several offers, fails to identify the intended customer or lacks proof for the promise made in the ad.
    • Update supporting content when useful comparison, product-detail or implementation questions appear repeatedly but your site does not answer them clearly.
    • Test AI-supported campaign matching when you find many relevant grounding queries, the offer is represented accurately and conversion quality can be measured. Performance Max, AI Max and other AI-supported campaign types can be candidates, but the grounding data remains an input rather than an instruction.
    • Make no campaign change when the observation is isolated, commercially unimportant or contradicted by stronger PPC and customer evidence. Preserve it for later comparison.

    Change as little as the diagnosis requires. If you rewrite the landing page, broaden matching, replace creative and alter the bidding strategy at the same time, you will not know which change affected customer quality. A bounded test should connect one documented interpretation problem to one primary lever and one business outcome.

    Protect the account from false inferences

    • Do not paste grounding queries into a keyword list without checking commercial fit, customer fit and landing-page support.
    • Do not call a citation a conversion, endorsement or attributable visit.
    • Do not treat share of authority as paid impression share or use it to allocate budget mechanically.
    • Do not broaden automation while the offer is described inconsistently across ads, pages and supporting content.
    • Do not judge success only by click-through rate or conversion count when the diagnosis concerns buyer quality.
    • Do not compare share-of-authority observations built from materially different topics, prompts or market contexts.

    AI-powered features such as final URL expansion, asset optimization and broader matching depend on interpretations of your pages and offers. If AI visibility reporting shows that the brand is being misunderstood, campaign automation may inherit some of the same confusion. Clear positioning is therefore a prerequisite for a sensible expansion test, not a cosmetic content task to postpone until later.

    Worked example: executive coaching versus sales training

    Suppose a B2B company sells executive coaching, but its grounding queries repeatedly cluster around tactical sales-training courses. Paid search terms also contain training-led intent, and the landing page uses coaching, training and advisory language interchangeably.

    The wrong response is to add every grounding query as a keyword or raise bids because the topic appears relevant. The better diagnosis is that AI interpretation, paid demand and page language all blur two offers that attract different buyers, expectations and conversion paths.

    1. Clarify the priority landing page around executive coaching, the intended buyer and the problems the engagement addresses.
    2. Qualify or remove tactical training language where it misrepresents the priority offer.
    3. Align ad creative with the same distinction.
    4. Use campaign controls to reduce clearly unwanted training intent where the PPC evidence supports that decision.
    5. Judge the test by customer fit and sales quality, not merely by the number of submitted forms.
    6. Consider broader AI-supported matching only after the offer is represented consistently.

    That sequence turns AI visibility into a falsifiable PPC hypothesis. It also preserves the possibility that the diagnosis is wrong: if customer quality does not improve after the message is clarified, return to the evidence instead of declaring the visibility signal predictive.

    Key takeaways

    • AI visibility adds pre-click context; it is not a replacement for PPC reporting or attribution.
    • Grounding queries reveal how an AI system decomposes intent, but they are not keywords.
    • Citations show participation in an AI-generated answer, not endorsement, traffic or conversion.
    • Share of authority compares citation activity within a defined topic or query set; it is not impression share.
    • The strongest diagnosis connects AI interpretation with search terms, landing-page language and conversion quality.
    • Fix a representation problem before asking broader matching or campaign automation to scale it.
    • Use one bounded change and a business-quality outcome to test each diagnosis.

    At your next PPC review, choose one commercially important intent cluster and add grounding queries, citations and share-of-authority context to the evidence you already use. If the same mismatch appears in AI interpretation, paid search behavior and customer quality, you have a specific problem worth testing. If it does not, keep observing rather than forcing the account to react.

    References


  • How to Turn AI Search Demand Into Measurable Brand Visibility

    How to Turn AI Search Demand Into Measurable Brand Visibility

    Your organic dashboard can look healthy while your brand is missing from the AI answers that shape a buyer’s shortlist. The reverse can happen too: a topic can look small in keyword tools even though people routinely describe the underlying problem to an AI assistant.

    The gap is easy to miss because AI discovery and conventional web analytics do not join cleanly. A buyer might encounter your brand in Gemini, research it later through Google, and eventually arrive through a branded query or direct visit. By then, the AI interaction is largely absent from Search Console and Google Analytics. To make better content decisions, you need a closed loop: identify demand, publish the right kind of asset, measure how AI systems represent your brand, and look for downstream business movement without claiming attribution you cannot prove.

    Separate demand, visibility, and business impact

    Three different questions are often collapsed into one AI visibility score. Keep them separate:

    • Demand: Are people searching for or asking about this topic?
    • Visibility: Does an AI answer include, recommend, describe, or cite your brand?
    • Impact: Does stronger visibility coincide with useful behavior such as branded research, qualified visits, leads, or sales?

    This separation prevents common misreadings. High prompt demand does not mean your brand is visible. A frequent brand mention does not mean the answer recommends you. A citation does not establish that the visitor converted because of AI. Each signal answers a narrower question.

    Use a measurement chain rather than a single blended number. Demand determines which topics deserve attention. Visibility shows whether your content and brand are entering the answer set. Business metrics tell you whether that exposure may be contributing to valuable outcomes. When one link is weak, you know where to investigate instead of treating every disappointing result as a content-quality problem.

    Build one demand map from keywords and prompts

    Blank search tiles, speech bubbles, and geometric intent tokens connect into a single illuminated map of clustered demand themes.

    Keyword research captures concise search behavior. Prompt research captures the longer, conditional questions people bring to ChatGPT, Gemini, Claude, Perplexity, and other assistants. Neither replaces the other. Putting keyword demand and prompt demand in the same working table exposes topics that either signal can miss on its own.

    Build the table in five steps

    1. Start with buyer decisions, not a keyword export. List the category questions, use cases, comparisons, objections, alternatives, pricing concerns, and suitability questions that appear from discovery through decision. Include branded and competitor-led questions, local variations where geography matters, and the follow-up questions a buyer would ask after an initial answer.
    2. Collect traditional search demand. Use Google Ads Keyword Planner and cross-check important topics in a third-party SEO platform such as Semrush or Ahrefs. Keep the keyword, reported volume, intent, market, and data date together.
    3. Collect prompt demand. A prompt-volume product can provide modeled demand and related conversational phrasing. If you do not have one, begin with a qualitative prompt library built from the questions your buyers actually ask, but label it qualitative rather than pretending it is volume data.
    4. Clean each signal on its own terms. Keyword Planner can merge close variants, so do not add near-duplicate rows as if they represent separate demand. Treat prompt-volume estimates as directional: they are useful for comparing broad magnitudes and trends, but their apparent precision should not drive the decision.
    5. Classify the demand shape. Define strong and weak relative to your own topic portfolio. Keyword volume and prompt volume are produced differently, so do not add them together or compare their raw values as if they shared a unit.
    Demand shapeWhat it indicatesBest initial assetPrimary success check
    Keyword-strong, prompt-weakPeople usually express the need as a concise search queryA focused, conventional SEO pageIntent match, rankings, organic engagement, and completeness
    Prompt-strong, keyword-weakPeople tend to describe a situation, constraint, or decision conversationallyAn answer-first explainer, decision resource, or use-case pageAI inclusion, recommendation context, citations, and messaging accuracy
    Strong on bothThe topic matters across search results and AI answersA flagship resource with supporting pagesSearch performance and AI visibility measured separately
    Weak on bothMeasured demand does not yet justify routine productionBacklog, unless customer evidence or strategic importance overrides the toolsDemand validation before a large content investment

    The final row matters. Demand tools are planning inputs, not permission slips. A new product category, a high-value account question, or a recurring sales objection can justify content before aggregated demand appears. Record the reason for the exception so that strategic work does not get confused with demand-led work later.

    Match the content format to the shape of demand

    Once a topic is classified, the content brief should change with it. Applying one universal AEO template to every query creates pages that are easy to scan but poorly matched to the actual decision.

    For keyword-led demand, win the search task first

    A keyword-strong topic still needs a recognizably strong SEO page. Match the title and page heading to the primary intent. Answer the core question early. Study the information the current results reward, then cover the related definitions and questions needed to complete the task. Use descriptive HTML headings, short definition blocks where they help, and clear conclusions near the beginning of each section.

    That structure also gives an AI system usable passages if the topic later develops stronger prompt demand. You do not need to distort a straightforward search page into a sprawling question bank. You need a complete answer with a clear information hierarchy.

    For prompt-led demand, answer the situation rather than the phrase

    A conversational prompt often contains several decision variables: who the buyer is, what they need to accomplish, which constraint matters, and what kind of recommendation they want. A page targeting only the short category phrase may never resolve that full situation.

    Build prompt-led content around the answer a qualified reader needs:

    • State the direct answer before the background.
    • Define the conditions under which the answer changes.
    • Name the buyer, use case, market, or product scope to which each claim applies.
    • Provide decision criteria that can distinguish suitable options.
    • Resolve likely follow-up questions instead of treating every wording variation as a separate page.
    • Keep product names, capabilities, positioning, and comparisons current so an extracted answer does not repeat stale information.
    • Support important claims on the page that you would want an AI response to cite.

    Do not create a thin page for every long prompt. Cluster prompts by the decision they are trying to make. If several phrasings require the same answer and evidence, they belong in one strong resource. Split them only when the audience, recommendation, or required evidence materially changes.

    For strong demand on both surfaces, build the flagship

    A topic with meaningful keyword and prompt demand deserves more than a long page assembled from loosely related questions. Give it a clear search target, an answer layer for common decisions, substantive evidence, and supporting pages for narrower use cases or comparisons. Keep one canonical resource at the center so your own pages do not compete to define the topic differently.

    A practical brief for any of these assets should include:

    • The topic’s demand classification and the data date.
    • The keyword cluster and search intent.
    • Representative first-turn prompts and follow-up prompts.
    • The audience, decision stage, use case, and relevant market.
    • The direct answer the page must earn the right to give.
    • The claims that require evidence or regular review.
    • The brand facts and differentiators that must remain accurate.
    • The pages you want cited, where those pages genuinely support the answer.
    • The measurement prompts that will be checked after publication or revision.

    The last item closes an operational gap. If the content team publishes without defining the prompts that would demonstrate improved visibility, the measurement team has to reconstruct the strategy afterward.

    Measure AI visibility as a pattern, not a ranking

    Several transparent lenses show different arrangements of source blocks around the same central brand object, with their light trails forming a combined pattern.

    There is no dependable single position called a Gemini ranking. Responses can change with follow-up questions, location, conversation history, personalization, and model updates. Opt-in personalization can also draw on signals from Google products such as Gmail, Photos, and Search. Two people can therefore receive meaningfully different competitive sets for similar questions. Your goal is to observe patterns across a controlled set of prompts, not celebrate or panic over one answer.

    Create a prompt panel you can repeat

    Organize prompts by platform, market, buyer stage, and intent. Your panel should cover category discovery, use cases, comparisons, branded evaluation, alternatives, decision objections, and location-dependent needs where relevant. Keep clean first-turn prompts separate from multi-turn conversation paths. A brand omitted from the opening response may appear only after the buyer adds a constraint or asks for a recommendation.

    For each test, preserve the exact wording and record the conditions that could affect the answer: platform, date, language, location, signed-in or signed-out state, visible model label, and whether prior conversation context was present. Consistency does not recreate every customer’s experience. It gives you a stable observation panel for directional comparisons.

    Record more than a yes-or-no mention

    A mention can be favorable, incidental, inaccurate, or actively disqualifying. Capture enough context to tell those outcomes apart:

    • Brand included: Was the brand named at all?
    • Recommendation status: Was it recommended for the stated need, merely listed, or mentioned as a poor fit?
    • Position: Where did it appear in a ranked list? If the response was narrative, record its role rather than inventing an ordinal position.
    • Competitors: Which alternatives appeared, and how were they framed?
    • Citations: Which URLs supported the response, and did an owned page receive a citation?
    • Message accuracy: Were the product, audience, capabilities, and positioning current?
    • Follow-up behavior: Did a later constraint add or remove the brand from consideration?

    From those fields, calculate metrics whose definitions remain stable. Inclusion rate is the share of eligible response runs that contain the brand. Recommendation rate counts only responses that actually recommend it for the tested need. Citation frequency tracks how often a page is used as supporting material. Competitive share of voice compares your appearances with the brands in the same prompt set. Keep accuracy as a separate quality measure; a high inclusion rate with outdated messaging is not a win.

    Use a cadence that can reveal change

    Weekly reviews suit highly competitive markets, while monthly reviews are sufficient for most organizations. Use the same cadence for your baseline and later comparisons. Add an annotation when you publish a flagship page, make a major positioning change, or update an important cited URL.

    Manual review remains valuable because it exposes tone, qualifiers, inaccuracies, and citation context. It is practical for dozens of important prompts. When the panel reaches hundreds or thousands, automation becomes useful for consistency and history. Platforms such as Profound, Scrunch AI, Otterly.AI, and Peec AI, along with AI visibility features in Semrush and Ahrefs, can automate repeated prompt checks.

    Evaluate a visibility tool by what you can inspect, not only by its headline score. Check whether it preserves raw answers and citations, separates platforms and markets, retains prompt versions, supports historical exports, and documents the test conditions. Its results will still represent standardized tests rather than every personalized user experience.

    Connect visibility to outcomes without inventing attribution

    The most useful reporting does not stop at answer inclusion. It also does not label every later branded visit as AI-generated. Because Gemini mentions do not appear as a native visibility report in Search Console or Google Analytics, use an evidence stack:

    1. Demand evidence: Which high-priority topic and prompt clusters are you addressing?
    2. Content evidence: What was published, revised, consolidated, or corrected, and when?
    3. Visibility evidence: Did inclusion, recommendation context, citations, competitive position, or accuracy change?
    4. Behavior evidence: Did branded search interest, direct traffic, identifiable AI referrals, engagement with cited pages, or return visits move in the same direction?
    5. Business evidence: Did qualified leads, assisted conversions, pipeline, or sales show a corresponding movement?

    The strength of the conclusion depends on how many links move together and whether another explanation is more plausible. A visibility increase followed by stronger branded research is evidence of contribution, not proof that AI caused every visit. Say that plainly in executive reporting.

    Use the combined data to diagnose the next action:

    • High demand, low inclusion: Check whether you have a page that fully resolves the prompt’s real decision. If you do, inspect the pages AI systems cite and identify the missing evidence, coverage, or brand clarity.
    • Frequent inclusion, weak recommendation: Review how clearly your pages describe fit, differentiators, limitations, and use cases. The brand may be known without being understood as the answer to that need.
    • Good inclusion, inaccurate messaging: Correct the owned pages carrying stale facts. Track the cited third-party pages as a separate reputation and outreach problem rather than assuming an onsite edit will change them.
    • Competitor citations without your brand: Examine what those cited pages substantiate. Build the missing evidence in your own voice; do not simply copy their format or claims.
    • Rising visibility, no useful behavior: Recheck the prompt set. You may be measuring broad awareness questions that do not lead to a meaningful buyer action, or the cited page may provide no sensible next step.
    • Business movement without visible AI referrals: Treat AI exposure as a possible contributor only when the visibility trend and timing support that interpretation.

    A compact operating dashboard should therefore show demand class, prompt coverage, inclusion, recommendation status, citations, accuracy, competitive context, and downstream indicators in adjacent columns. Resist turning them into an opaque composite. A single score hides whether the problem is demand selection, content coverage, brand representation, or conversion.

    AI demand and visibility FAQ

    Can branded prompts prove that people are discovering the brand?

    No. A branded prompt is useful for checking representation: whether the assistant describes your offer accurately, surfaces current information, and handles objections fairly. Discovery should be measured with non-branded category, use-case, comparison, and problem prompts where the brand has not already been supplied.

    Should a mention and a citation count as the same result?

    No. A mention tells you the brand entered the response. A citation identifies a page used to support the answer. Record both, then inspect the context. An uncited recommendation may still be commercially meaningful, while a citation may support a neutral definition that does not recommend the brand.

    Should you rerun a prompt until the brand appears?

    No. Decide the protocol before viewing the result, preserve every eligible run, and compare aggregate patterns. Stopping only when the brand appears creates a flattering but unusable inclusion rate. If you test conversational follow-ups, define that sequence in advance and report it separately from clean first-turn prompts.

    Before commissioning your next content batch, add prompt demand beside keyword demand and create a repeatable visibility panel for the topics you already consider important. The first decision is not how much more to publish. It is which demand you are missing, which answer you need to earn, and which observable change would show that the work mattered.

    References


  • From AI Visibility to Revenue: Fix the Full Growth Path

    From AI Visibility to Revenue: Fix the Full Growth Path

    Your brand is appearing in AI answers, the citation chart is moving up, and the pipeline is still flat. That does not automatically mean your GEO work has failed. It means visibility has been measured before the rest of the buying path has been examined.

    Revenue depends on a connected system: the right recommendation prompt, a useful answer, a credible reason to choose you, an obvious next step, prompt follow-up, qualification, and a sale the business can serve profitably. This framework helps you find the weakest link instead of buying more visibility on instinct.

    Key takeaways

    • Treat AI citations as leading indicators. Pipeline, revenue, and profit remain the business outcomes.
    • Monitor a defined set of purchase-adjacent prompts, not an undifferentiated count of brand mentions.
    • Build content that helps a buyer distinguish between options through criteria, evidence, tradeoffs, and clear fit boundaries.
    • Audit what happens after every inquiry. Missed calls, delayed replies, weak routing, and unclear next steps can erase the value of demand generation.
    • Use stage-by-stage conversion rates to locate the constraint before deciding whether to fund content, technical work, sales, or client-service capacity.

    Track the path from recommendation to profit

    A citation means that your brand was visible in an answer. It does not tell you whether the person had buying intent, understood your fit, contacted you, qualified, or became a customer. AI visibility and commercial performance are related, but they are not interchangeable.

    This distinction matters because a visibility dashboard can improve while commercial performance deteriorates. A growing share of mentions on broad informational prompts may conceal weak coverage of the recommendation prompts that precede a purchase. Even high-intent coverage can fail to produce revenue when the answer leads to a generic page, the offer is unclear, or the resulting inquiry sits unanswered.

    Replace the single visibility score with a chain of observable stages:

    StageWhat you need to learnUseful evidence
    AI recommendationDoes the brand appear when a suitable buyer is selecting an option?Coverage of a fixed set of purchase-adjacent prompts, answer context, cited page, and competitors included
    Commercial transitionCan the buyer identify and take an appropriate next step?Visits to relevant pages, branded follow-up activity, calls, forms, bookings, or other defined actions
    Inquiry handlingDid the business reach the prospect and provide a clear next step?Call records, reply timestamps, two-way conversations, appointments, routing status, and unresolved inquiries
    QualificationWas the inquiry a genuine fit for the offer?Qualified opportunities, disqualification reasons, use case, service area, language need, and other real buying constraints
    Commercial outcomeDid the opportunity produce viable growth?Wins, revenue, gross profit, sales-cycle length, retention where relevant, and delivery capacity

    Give every rate a clear numerator and denominator. Otherwise, teams can use the same label for different calculations and reach opposite conclusions. A practical starting set is:

    • Money-query coverage: monitored purchase-adjacent prompts in which you are recommended, divided by all monitored purchase-adjacent prompts.
    • Inquiry-to-contact rate: inquiries that become two-way conversations, divided by all valid inquiries.
    • Contact-to-opportunity rate: qualified opportunities divided by two-way conversations.
    • Opportunity-to-win rate: won customers divided by qualified opportunities whose outcome is known.
    • Revenue per inquiry: won revenue attributed to the cohort divided by valid inquiries in that cohort.
    • Gross profit per inquiry: gross profit from won business divided by valid inquiries, when reliable cost data is available.

    Do not collapse informational citations and purchase-adjacent recommendations into one total. They answer different questions. Informational visibility can support awareness and authority, but it should not be presented as equivalent to buyer selection.

    Build a money-query map around real buying decisions

    A buyer at a table evaluates products, cost, timing, delivery, support, and value before choosing one illuminated option.

    A money query is not simply a keyword with high search volume. It is a question asked close enough to a decision that the answer could change who receives an inquiry, booking, trial, purchase, or sales conversation. The useful starting point is the recommendation prompt a real buyer uses when choosing for a specific situation.

    Build the map from the language of actual demand, not from a brainstorm conducted entirely inside marketing:

    1. Collect buyer questions. Review sales emails, call notes, form submissions, chat transcripts, objections, proposal questions, lost-deal reasons, and on-site search terms. Preserve the qualifiers buyers use.
    2. Separate intent levels. Put definitions and general education in an awareness group. Put comparisons, provider selection, fit checks, alternatives, implementation constraints, pricing considerations, and risk questions in decision groups.
    3. Retain the situation. Industry, location, language, company size, integration needs, urgency, service model, and other constraints often determine whether a recommendation is commercially relevant.
    4. Name the intended next step. Decide whether a suitable reader should call, request an assessment, book a meeting, start a trial, visit a location, or continue to a more specific decision page.
    5. Assign ownership beyond marketing. Record who owns the page, who receives the inquiry, who provides backup coverage, and what event counts as a qualified opportunity.

    Use a repeatable brief for each prompt cluster. It should contain the prompt, buyer situation, decision criteria, evidence required, reasons you may be a poor fit, destination page, intended action, commercial owner, and measurement window. That brief prevents a common failure: optimizing an answer without defining what the qualified reader should do next.

    Consider a prompt such as, “Which GEO agency fits a multi-location legal practice that needs bilingual lead handling?” A useful page would need more than a definition of GEO. It would need to explain multi-location capabilities, language and intake dependencies, measurement, responsibilities, relevant limitations, and what happens after a prospect asks for help. If your business does not provide one of those capabilities, state the boundary clearly rather than trying to look eligible for every variation.

    Monitor prompt clusters separately. If you appear for general education but not for selection, your problem is not total visibility. It is recommendation relevance. If you appear for selection prompts that describe customers you cannot serve, the mention count is creating noise rather than opportunity.

    Publish evidence that helps a buyer choose

    Generic explanation pages are easy to reproduce and hard to recommend with confidence. A buyer-selection page has a different job: it helps someone decide which option fits a defined situation. That requires discriminating information, not a longer version of the same category definition.

    Apply the following standard to pages attached to money queries:

    • Lead with the answer. State the recommendation, condition, or key distinction before the supporting explanation. Make the central claim easy to identify and quote.
    • Name the decision criteria. Explain which capabilities, constraints, risks, and dependencies actually change the choice. Do not hide them inside generic benefit language.
    • State tradeoffs and wrong-fit cases. Honest fit boundaries make content resemble a useful recommendation. They also discourage inquiries your sales team will later disqualify.
    • Publish defensible first-party evidence. Turn internal data into a useful finding only when you can explain the population, method, scope, and limitation. A number no competitor can legitimately claim is more distinctive than another interchangeable explainer, but unsupported precision will weaken trust.
    • Identify responsible people. Use named authors, relevant credentials, and clear organizational information. A faceless administrative byline gives a retrieval system and a buyer less help in evaluating credibility.
    • Expose recency. Display publish and update dates, and update them only when the page has materially changed. Record what was refreshed internally so the date remains meaningful.
    • Use comparison tables for real comparisons. Put stable criteria into rows and alternatives into columns when a buyer is genuinely weighing options. Do not force nuanced claims into a table merely to create extractable markup.
    • Remove interchangeable content. If a competitor could replace your name and publish the page unchanged, it is not expressing your evidence, position, method, or fit. Consolidate it, rewrite it around a real decision, or remove it when it serves no other purpose.

    Then check retrieval. Important claims should be present in server-delivered HTML rather than available only after client-side JavaScript runs. Confirm that relevant crawlers are not blocked and that important pages are indexed in Bing, because ChatGPT web search relies on Bing’s index. A system cannot cite content its retrieval layer cannot access.

    Keep technical work in proportion. Schema can clarify entities and page structure, but it does not turn an undifferentiated page into persuasive evidence. Treat llms.txt as an unproven visibility lever rather than a substitute for buyer-focused content. The practical hierarchy is straightforward: create something worth recommending, make the claim easy to extract, make the page accessible, and use structured data as supporting plumbing.

    Every decision page also needs a next step that matches its intent. A comparison reader may need an assessment, product view, consultation, or implementation conversation. A generic “learn more” link sends the buyer back into research. Tell the person what the next action is, what information it requires, and what will happen after submission.

    Fix the handoff between marketing and sales

    A marketing team passes a glowing customer-intent baton to a sales professional as the route continues toward a consultation and handshake.

    Marketing can create an eligible opportunity and still produce no revenue. Calls go unanswered, forms route to the wrong person, inboxes accumulate, and automated acknowledgements provide no useful next step. In trust-heavy fields such as legal, real estate, and professional services, missed calls, delayed email, and unclear follow-up can cause a ready prospect to choose a competitor.

    Audit the handoff as a buyer would experience it. Do not rely only on the workflow diagram:

    1. Inventory every entry point. Include tracked and untracked phone numbers, forms, booking tools, chat, email addresses, social messages, location pages, and third-party profiles that can generate inquiries.
    2. Run controlled test inquiries. Use clearly internal test records and avoid entering false information into systems that trigger regulated, legal, financial, or emergency workflows. Test during normal coverage as well as the periods in which you promise availability.
    3. Record the complete path. Capture submission time, acknowledgement time, human response time, assigned owner, routing changes, requested information, next step, and final disposition.
    4. Inspect the reply itself. Confirm that it answers the immediate question, explains what happens next, identifies anything the prospect must prepare, and provides a working way to continue.
    5. Test promised language paths. If you advertise service in English and Spanish, compare clarity, access, routing, and follow-up in both. Do not treat a translated first message as equivalent to a supported client journey.
    6. Trace the record into reporting. Confirm that source, landing page, campaign, prompt cluster where known, consent status, and qualification details survive the transfer into the CRM or other system of record.

    Turn the audit into an operating agreement. For each channel, name a primary owner, backup owner, internal response expectation, acceptance criteria, escalation path, and closed-loop status. An automated acknowledgement can reassure the prospect that a message arrived, but it should not be counted as a completed response when the person still lacks help or a next action.

    Language coverage deserves explicit design. Spanish-speaking clients may prefer to discuss contracts, documentation, appointments, pricing, and consequential personal decisions in Spanish. If your marketing attracts that audience but the intake process cannot support the conversation, visibility is creating an expectation the operation cannot meet.

    The staffing answer can be an internal team, a trained bilingual virtual assistant, a shared intake function, or another arrangement suited to the business. Evaluate the option on coverage, training, approved scripts, escalation, documentation, data access, and quality control. In legal or otherwise regulated services, intake staff should not improvise professional advice. Give them approved boundaries and a route to a qualified professional when a question crosses those boundaries.

    Feed disposition data back to marketing. Repeated disqualification for the same reason may reveal that the page is attracting the wrong situation or omitting a decisive limitation. Repeated abandonment before a booking may indicate unnecessary form friction or an unclear next step. Repeated delays after submission point to capacity or ownership. Each pattern calls for a different investment.

    Read the scorecard and fund the actual constraint

    A revenue scorecard should let marketing, sales, and operations see the same path without pretending attribution is perfect. A person can encounter an AI recommendation and later return through branded search, direct navigation, email, or a call. Referrer data alone therefore cannot represent every influence.

    Use multiple forms of evidence without combining them into a fictional degree of precision. Keep platform and prompt monitoring, analytics, call tracking, CRM stages, won revenue, and gross-profit data distinct. Add an optional “How did you hear about us?” field where it will not create material friction, preserve the person’s wording, and compare it with recorded digital touchpoints.

    For each money-query cluster, report the prompt coverage, relevant cited pages, observable visits or follow-up actions, valid inquiries, reached prospects, qualified opportunities, wins, revenue, gross profit where available, and the most common loss or disqualification reason. Use a measurement window long enough for that cohort to move through your normal sales cycle. An open opportunity is not a loss, and an early snapshot should not be presented as a final return calculation.

    Then diagnose the first material break in the chain:

    • No recommendation on suitable money queries: inspect retrieval, brand authority, evidence, selection criteria, and whether the page answers the prompt directly.
    • Visibility only on broad informational prompts: rebuild the content plan around real selection, comparison, validation, and fit questions.
    • Recommendations without meaningful next actions: inspect answer context, destination-page alignment, fit communication, proof, offer clarity, and the call to action.
    • Inquiries without two-way contact: fix coverage, routing, ownership, response expectations, language support, and backup procedures before buying more demand.
    • Conversations without qualified opportunities: compare the prompt and page promise with actual eligibility. Tighten targeting and state disqualifying constraints earlier.
    • Qualified opportunities without wins: investigate offer fit, sales process, proof, pricing concerns, competitive losses, and unresolved objections. More citations will not repair a closing problem.
    • Wins that strain delivery or reduce profit: add service capacity, narrow eligibility, or adjust the offer before accelerating acquisition. Revenue that cannot be served well is not durable growth.

    Keep visibility in the report, but put it in the role it can honestly fill: evidence that you are eligible to influence a decision. Booked opportunities, incremental sales, and new customers are performance. Profit tells you whether that performance is economically worth scaling.

    Your next move is to choose one high-intent prompt cluster and walk one complete buyer path, from AI answer to closed outcome. Name the first broken handoff, assign its owner, and change that constraint before expanding the visibility budget. That is how GEO becomes part of a growth system instead of a separate scoreboard.

    References


  • Marketing Attribution Blind Spots: What Your Reports Miss

    Marketing Attribution Blind Spots: What Your Reports Miss

    Your campaign report says one channel drove the conversion. That may only mean the channel left the cleanest trail.

    Before you cut, scale, or defend a marketing investment, you need to distinguish three very different situations: the campaign failed, the customer journey was only partly observable, or the measurement plumbing broke. Treat those as the same problem and a precise-looking dashboard can steer your budget in the wrong direction.

    Your dashboard records evidence, not the entire journey

    Attribution works with observable events. An impression, tagged visit, form submission, CRM record, and purchase can be connected only when the necessary data survives each handoff. Anything that happens outside that chain may influence the buyer without receiving credit.

    That creates four common blind spots:

    • Unobserved exposure: Someone encounters your brand or advice without visiting your site.
    • Lost campaign context: The person visits, but an identifier disappears before analytics records it.
    • Disconnected outcomes: Marketing captures a lead, while the eventual opportunity or revenue remains in a separate system.
    • Misread evidence: A visible touchpoint receives credit even though the report cannot establish that it caused the conversion.

    AI discovery makes the first blind spot especially important. A person can read an AI-generated answer, see your company cited or recommended, and get what they need without clicking. They may return later through branded search, direct navigation, or another channel. Page views will show the later visit, if there is one, but they cannot represent the original zero-click exposure. That is why AI citations, share of voice, and revenue need distinct measurement layers.

    Lost campaign context creates a different problem. Google Analytics includes a diagnostic for URLs missing aggregate identifiers such as GBRAID and gad_. Those parameters matter to attribution in a privacy-focused measurement environment, and their absence can reduce campaign attribution accuracy. A campaign can therefore appear weaker because its evidence was dropped, not because its audience stopped responding.

    The practical distinction is simple: invisible influence calls for broader measurement, while missing identifiers call for a technical repair. Neither should be interpreted as campaign underperformance until you know which one you are dealing with.

    Measure visibility, visits, and business outcomes separately

    Three connected spaces show a beacon reaching a crowd, visitors entering a corridor, and customers completing purchases and consultations.

    A useful attribution view has three layers. Each answers a different question, and none can substitute for the others.

    LayerQuestion it answersEvidence to collectWhat it cannot prove
    AI visibilityDoes your brand appear in relevant generated answers?Mentions, citations, recommendations, answer position, tracked-query share of voiceThat a person visited, bought, or was persuaded
    TrafficDid an observable visit reach your site?Referral sessions, tagged links, landing pages, assisted paths, campaign identifiersThat every exposure produced a click or that the visit caused the outcome
    Business outcomesDid demand become something valuable?Leads, qualified opportunities, purchases, revenue, renewals, and CRM source evidenceWhich earlier touch deserves causal credit when the path is incomplete

    Define AI visibility against a fixed question set

    Do not report a vague claim such as “our AI visibility improved.” Build a query set from the questions customers ask while identifying a problem, comparing options, and making a decision. Keep that set stable long enough to make one reporting period comparable with the next.

    For every checked answer, record whether your brand was absent, mentioned, cited as a source, or explicitly recommended. Those states are not equivalent. A citation shows that your material surfaced in the answer; a recommendation is a stronger form of representation, but it still does not prove commercial impact.

    State the denominator whenever you report AI share of voice. For example, define it as the number of eligible answers containing your brand divided by the total eligible answers checked in the fixed query set. Without the query set, platforms, conditions, and denominator, a share-of-voice percentage has no stable meaning.

    Preserve traffic evidence without treating it as the whole result

    Create a dedicated segment for identifiable AI referrals. Record the landing page, referrer when available, engagement, and downstream conversion. Use tagged links wherever you control the destination link, but do not relabel unexplained direct traffic as AI traffic. “Unknown” is a more defensible classification than a confident guess.

    Compare AI referral traffic with the visibility layer instead of expecting the numbers to match. Rising citations with flat referrals can indicate more zero-click exposure, but it does not establish that the exposure caused later demand. It is a signal to investigate, not a revenue claim.

    Connect marketing evidence to outcomes the business values

    Carry a durable lead or customer key from the conversion point into your CRM where your setup permits it. Preserve the original source, the latest known source, landing page, campaign data, and relevant sales outcome as separate fields. Overwriting the first touch with the latest touch destroys evidence you may need later.

    Add a short self-reported discovery question to high-value conversion points. Offer recognizable options, including AI assistants, and leave room for free text. Self-reporting is imperfect, but it can reveal discovery paths that click-based analytics cannot see. Keep it beside behavioral attribution rather than using it to replace behavioral data.

    Report the three layers side by side. Do not collapse citations, sessions, leads, and revenue into one synthetic score. A single score hides the exact break you need to find: limited visibility, weak click-through, lost campaign data, poor lead quality, or a missing CRM connection.

    Repair campaign plumbing before judging performance

    A technician repairs loose and blocked connections in transparent pipes carrying glowing signals toward a central customer-record hub.

    A campaign-quality discussion should stop when the tracking path is visibly damaged. Creative, targeting, and bidding changes cannot repair a parameter stripped by a redirect or a revenue field that never returns to the reporting system.

    Use this sequence when Google Analytics flags missing aggregate URL parameters or when campaign data unexpectedly becomes incomplete:

    1. Record the affected scope. Note the campaign, platform, landing page, identifier involved, and example URLs identified by the diagnostic. Do not begin with an account-wide conclusion when the fault may affect only one route.
    2. Follow a controlled path. Start with a platform-generated test URL and record the browser URL at the initial landing page and after every redirect.
    3. Locate the first loss. Check link templates, shorteners, server redirects, cross-domain handoffs, consent flows, and landing-page scripts. The first point where the parameter disappears is more useful than the final unattributed session.
    4. Use generated identifiers as intended. Do not invent or reconstruct privacy-related identifier values. Preserve the parameters supplied by the advertising platform and follow its remediation guidance.
    5. Verify collection after the repair. Repeat the same controlled route and confirm that the identifier survives the handoffs and reaches the intended analytics setup.
    6. Annotate the affected period. Record when the issue began, when it was discovered, what scope was affected, and when the fix was verified. Historical reports may remain incomplete even after new traffic is measured correctly.

    The diagnostic identifies a data-quality symptom; it does not automatically identify the root cause or restore missing history. It also does not prove that every unattributed conversion belongs to the affected campaign. Use it to narrow the investigation, then validate the actual path.

    Track a simple completeness rate after the fix: eligible records containing the expected campaign evidence divided by all eligible records. The useful comparison is the rate over time and across equivalent paths. There is no universal threshold that can tell you whether your particular implementation is healthy.

    Run a blind-spot audit around decisions, not dashboards

    A generic analytics audit can produce a long list of tidy fields without protecting an important decision. Start with the decision that could move money: whether to scale a campaign, pause a channel, invest in AI visibility, or change the content program.

    Then audit the evidence in this order:

    1. Write the decision in one sentence. Name the investment being evaluated, the outcome that matters, and the reporting period. This prevents convenient metrics from replacing the business question.
    2. Draw the observable path. Map exposure, click, landing page, conversion, lead record, opportunity, purchase, and revenue. Mark which system owns each event.
    3. Mark every join. Identify the field that connects one stage to the next. If no shared key exists, label the gap instead of assuming the systems reconcile.
    4. Reconcile adjacent counts. Compare platform interactions with analytics visits, visits with form completions, form completions with CRM leads, and closed outcomes with reported revenue. You are looking for a structural break, not perfect equality between systems that measure different events.
    5. Test one known path. Use a controlled journey to confirm that the expected campaign context survives each relevant handoff. A dashboard total cannot show you where an individual field disappeared.
    6. Classify the evidence. Separate directly observed, successfully joined, inferred, and unknown data. Display the classification beside the metric used for the decision.
    7. Assign the gap. Give each material blind spot an owner, a next check, and a verification condition. “Improve attribution” is not an action; “confirm that GBRAID survives the landing-page redirect” is.

    Keep a blind-spot register with seven fields: decision at risk, missing evidence, affected systems, suspected break, owner, next verification, and confidence level. This turns uncertainty into a manageable queue instead of burying it in a dashboard footnote.

    Evidence labels also make budget conversations more honest:

    • Directly observed: The event was recorded in the system where it occurred.
    • Joined: Records were connected using a defined key across systems.
    • Inferred: The relationship is plausible and supported by directional evidence, but the individual path is not observed.
    • Unknown: The necessary evidence is missing or contradictory.

    Attribution and causality must remain separate. Attribution assigns credit under a chosen rule. It does not, by itself, establish what would have happened without the marketing activity. If a large investment requires a causal answer, use a controlled experiment where one is feasible and keep its result separate from the attribution model.

    Use a few firm decision rules. Do not declare a campaign decline while its expected identifiers are missing. Do not call growing AI citations revenue merely because branded demand also rose. Do not call unattributed traffic organic, direct, or AI-derived without evidence. When visibility, identifiable visits, self-reported discovery, and connected outcomes move in the same direction, confidence improves, but the pattern is still not automatic proof of causation.

    Key takeaways

    • An attribution report describes the observable trail, not every influence on the customer.
    • Measure AI visibility, identifiable traffic, and business outcomes as separate layers with separate denominators.
    • Treat missing GBRAID, gad_, or other expected campaign evidence as a data-quality issue before evaluating campaign quality.
    • Preserve original and later source fields instead of overwriting one with the other.
    • Label evidence as observed, joined, inferred, or unknown so decision-makers can see how much confidence a metric deserves.
    • Use attribution to allocate recorded credit; use controlled testing when you need a causal answer.

    Before your next budget review, choose the highest-consequence campaign and trace one complete path from exposure to revenue. At the same time, choose one AI discovery use case and build its three-layer view. Fix any broken handoff first. Then make the investment decision with the blind spots visible rather than pretending they are not there.

    References


  • How to Build a Social Topical Map for Search Visibility

    How to Build a Social Topical Map for Search Visibility

    Your videos and social profiles may already appear in Google for searches your website barely reaches. If your SEO plan tracks only web pages, that visibility remains unmeasured, uncoordinated, and easy to waste.

    A social topical map connects each meaningful search need to the pages, videos, images, and social assets that can answer it. It tells you where you already have search eligibility, where your coverage is thin, and which format should do the next job. The goal is not to publish everywhere. It is to build deliberate coverage around the topics that matter to your audience and business.

    Key takeaways

    • Measure Google visibility for supported social accounts separately from searches performed inside YouTube, Instagram, or TikTok.
    • Group query variants by the underlying problem rather than treating every phrase as an independent keyword.
    • Give each format a defined role: a web page may provide the canonical explanation, a video may demonstrate the process, and a short social asset may answer one narrow question.
    • Prioritize clusters where a social asset already earns impressions, the website has little visibility, or both surfaces sit close to a more prominent search position.
    • Track eligibility, click packaging, on-platform engagement, and business outcomes separately. One metric cannot tell you whether the whole system is working.

    Audit the search footprint your social channels already have

    An analyst sorts generic content tiles while viewing web page, video, image, and profile cards arranged across a translucent discovery field.

    Begin with evidence, not a new publishing calendar. Google Search Console Platform properties can show the Google Search queries for which a connected YouTube channel, Instagram profile, or TikTok account appears, together with impressions, clicks, and positions. That is a different population from the people searching inside each social platform. Platform analytics and Google Search data answer different questions, so keep them separate in your reporting.

    Export platform-property and website data for the same date range. Retain the query, asset, impressions, clicks, click-through rate, and average position available in each export. Then add working columns for topic cluster, user intent, business relevance, current website coverage, and recommended action.

    The comparison can reveal genuinely incremental visibility. In one 11-day channel snapshot, videos appeared for searches where the corresponding website had little or no presence:

    QueryVideo positionVideo impressionsWebsite impressions
    ai search7.67,0261
    what is a sitemap4.43,8630
    enterprise seo10.73,2261,470

    Those figures do not establish a universal benchmark. They show why you should compare your own properties instead of assuming a video merely duplicates the website. A page and a video can cover the same subject while reaching different searches or occupying different result surfaces.

    Flag four patterns during the audit:

    • Platform-only reach: a social asset receives Google impressions while the website receives few or none for the cluster. Preserve that asset, then decide whether the site also needs a durable page.
    • Website-only reach: the site is visible, but no social format is eligible. Ask whether the topic would become clearer as a demonstration, walkthrough, visual explanation, or concise answer.
    • Wide but shallow eligibility: many assets earn impressions, but few attract clicks. In one early Platform-property export, 83 videos received web-search impressions, while the top 1,000 queries generated 149,220 impressions and 10 clicks. That pattern warrants an intent and packaging audit; it does not prove that thumbnails or titles are the only problem.
    • Unplanned durable winners: older assets continue surfacing for relevant queries. Protect their subject coverage and study the search jobs they perform before replacing or substantially repositioning them.

    Do not add website and platform impressions together and label the result as unique reach. An impression is not a unique person, and the same search may expose more than one brand asset. Use the comparison to understand coverage, not to manufacture an audience total.

    Build clusters around problems, then assign each format a job

    Three organized clusters of blank page panels, video frames, visual tiles, and answer cards connect around central nodes on a dark surface.

    A keyword list becomes a topical map only when related phrases are consolidated into a decision you can act on. Exact-query rows often hide the real size of demand. A documented channel export contained 149 distinct phrasings around “enterprise seo,” producing 31,555 impressions in 11 days. The exact phrase averaged position 10.7, but the family of related searches represented a much larger opportunity than any individual row suggested.

    Use this five-step clustering process:

    1. Combine the query sets. Place website and platform-property exports in one working sheet, while retaining a field that identifies the originating property.
    2. Normalize obvious variants. Standardize capitalization, singular and plural forms, and superficial word-order differences without erasing meaningful intent.
    3. Group by the user’s job. Separate definition searches from tutorials, comparisons, troubleshooting, validation, and purchase-oriented questions, even when they contain the same head term.
    4. Name the cluster as a problem. “Understand enterprise SEO” is more useful to a content team than a loose label such as “enterprise keywords.” The problem statement makes the expected answer clearer.
    5. Inventory assets before proposing new ones. Attach every relevant page, long-form video, short clip, image, and social entry to the cluster. Mark each asset as keep, improve, consolidate, repurpose, or create.

    The resulting map should be a decision document, not a decorated keyword spreadsheet. Each row needs enough information to determine what gets made and why:

    Map fieldDecision it should support
    Topic clusterWhich related query variants represent one underlying need?
    User job and intentDoes the person need a definition, demonstration, comparison, fix, or next step?
    Current search evidenceWhich properties and assets receive impressions, clicks, or prominent positions?
    Canonical web answerWhich page should provide the complete, maintainable explanation?
    Long-form social roleWould a walkthrough, interview, demonstration, or visual explanation improve the answer?
    Short-form social roleWhich narrow question, mistake, or decision can stand on its own?
    Coverage gapIs the missing element a subject, subtopic, format, audience stage, or clearer packaging?
    Next action and ownerWho will keep, improve, repurpose, consolidate, or create the asset?
    Measurement fieldWhich change should become visible in Search Console or platform analytics?

    Choose formats by answer shape, not by channel quota

    The same topic should not become the same content pasted into four places. Give every asset a distinct contribution:

    • Use the website for the durable explanation, supporting details, internal links, citations, and structured data that truthfully describes the page.
    • Use long-form video when the person benefits from seeing a process, interface, sequence, physical example, or expert explanation unfold.
    • Use short video for one bounded question, misconception, step, or before-and-after decision.
    • Use an image or carousel when the answer is spatial, comparative, sequential, or easier to retain as a checklist.
    • Use the social description and destination link to supply context and a sensible next step, not to repeat the entire page.

    This format assignment matters as search becomes more multimodal. Google can use images and video as substantive result material, so a brand may be eligible through a page, video, image, and social asset for the same broad need. Multi-format coverage can create several opportunities on one results page, although no map can guarantee that Google will display every asset together.

    If the social asset ranks and the website does not, do not remove the social asset to avoid supposed cannibalization. Keep the proven visibility. Improve or create the web answer only when it serves an additional user or business need. If both surfaces already perform, expand into an unanswered sub-intent instead of producing another near-duplicate.

    Package every asset for discovery and answer satisfaction

    A useful asset can be search-eligible and still fail to earn attention. Social search optimization therefore has three layers: retrieval clarity, click packaging, and answer fulfillment. Ignoring any one of them creates misleading results.

    Make the subject unmistakable

    State the topic and promised outcome plainly in the title, opening language, description, captions, and important on-screen wording. Use natural variants where they help comprehension, but do not recite a cluster’s keyword list. Accurate entity names, product names, and task language make the asset easier for both people and retrieval systems to interpret.

    Design the click before production

    For video, settle the title concept and thumbnail promise before recording. The two elements should create one coherent expectation: what will the viewer understand, decide, or accomplish? Search phrasing can clarify relevance, but it should not produce a lifeless title. The thumbnail should add a useful contrast, result, object, or visual cue rather than restating every title word.

    Successful platform packaging also has to survive the opening. A practical structure for the first 30 seconds is to name the outcome, demonstrate that the video will deliver it, and preview the route. This reflects a production model in which titles and thumbnails are decided early and the opening is scripted around promise, proof, and preview. The point is not to force every video into a rigid formula. It is to prevent the asset from making a search promise that the opening delays or abandons.

    Fulfill the exact search job

    Review the asset while looking at the queries that trigger it. A broad video may appear for a narrow question it answers only in passing. In that case, you have three choices: make the relevant segment easier to find, adjust the packaging so it no longer overpromises, or create a focused asset for that sub-intent.

    Use this diagnostic order when impressions are present but clicks or engagement are weak:

    1. Check whether the triggering query and the asset’s real answer match.
    2. Check whether the title communicates that match without requiring prior context.
    3. Check whether the thumbnail or visual preview makes the promised outcome legible.
    4. Check whether the opening confirms the promise quickly.
    5. Check whether the body gives the answer enough depth, evidence, and visual clarity.
    6. Check whether the next step points to a relevant page or adjacent asset rather than a generic destination.

    Change one major packaging variable at a time when practical, and record the date. If you replace the title, thumbnail, description, and opening simultaneously, you will have difficulty learning which change mattered. Do not infer success from clicks alone either: an asset that wins the click and immediately loses the viewer has solved packaging, not satisfaction.

    Measure coverage as a system, not a leaderboard

    Your reporting should distinguish four questions. Blending them into a single score hides the action you need to take.

    QuestionUseful evidenceLikely action
    Are we eligible?Cluster impressions, query variants, and number of assets receiving Google impressionsPreserve proven coverage or strengthen missing topics and formats
    Are we prominent and compelling?Position distribution, clicks, click-through rate, title, and result presentationImprove intent alignment and packaging
    Does the asset satisfy people?Platform views, watch time, retention, engagement, and subscriber behaviorImprove the opening, structure, depth, or format
    Does the coverage support the business?Relevant site visits, assisted journeys, qualified actions, and conversionsImprove the next step, destination, or cluster priority

    The distinction is essential because high visibility may produce little direct traffic. One newly connected channel recorded more than 200,000 Google Search impressions and 87 clicks during its first 11 days of reporting. That result exposes a large eligible footprint, but it does not by itself prove strong packaging, meaningful awareness, or commercial value.

    Run the map on a fixed operating cycle. A monthly review gives SEO, content, video, and social teams one recurring decision point, while active experiments can be checked more frequently. Use the cycle to:

    1. Export website and platform-property data for matching dates.
    2. Assign new queries to existing clusters and split a cluster only when the user job is materially different.
    3. Mark which assets gained or lost eligibility, prominence, clicks, or engagement.
    4. Review your highest-value platform-only and website-only gaps.
    5. Choose a small production and optimization queue with named owners.
    6. Annotate title, thumbnail, content, and destination changes so later movement has context.

    Prioritize proven opportunities before speculative volume. Start with social assets already receiving relevant Google impressions, clusters where the website is absent, and valuable assets sitting just outside stronger visibility. Then expand clusters that demonstrate sustained demand. Broad topics can produce reach, but business relevance determines whether that reach deserves production time.

    Your first map does not need to cover every account or every query. Connect the supported properties you already operate, compare one shared reporting period, and cluster the searches behind your most visible assets. Assign one clear action to each important gap. That is enough to turn previously hidden social visibility into an SEO plan your teams can execute and improve.

    References