Tag: AI visibility tools

  • Goodie vs Peec AI: Which AEO Platform Should You Choose?

    Goodie vs Peec AI: Which AEO Platform Should You Choose?

    If you are choosing between Goodie and Peec AI, the decisive question is not which dashboard looks better. It is where you want the platform’s job to end. Peec AI is oriented around monitoring and reporting. Goodie is designed to carry the work from monitoring into recommendations, content, commerce visibility and attribution.

    That distinction affects more than the feature list. It determines how much analysis your team must do after the dashboard identifies a visibility gap, which other tools you will need, and whether the resulting report can be connected to business outcomes.

    Goodie supplies the feature and pricing claims available for this comparison. Its descriptions of Goodie are first-party claims, while its descriptions of Peec are second-hand. Confirm Peec’s current limits, pricing, integrations and security documentation directly with Peec before signing a contract.

    Key takeaways

    • Choose Peec AI when monitoring is the deliverable. Its reported strengths include prompt tracking, citation analysis, competitor benchmarking, unlimited users, credit allocation across projects and agency pitch workspaces.
    • Choose Goodie when the platform must support execution. Goodie combines visibility monitoring with prioritized optimization actions, content creation, technical AEO guidance, AI-shopping visibility and revenue attribution.
    • Do not compare prompt limits with credits as though they were the same unit. Goodie publishes prompt and action allowances, while Peec’s agency plans use credit pools. Ask each vendor to price the same prompt set, engines, countries, refresh frequency and client count.
    • Model count alone is misleading. Peec reportedly reaches a higher enterprise ceiling, but its standard plans let you choose three models from a smaller default set. Goodie’s entry plan includes five named surfaces, while its enterprise tier expands to as many as 12.
    • The lower subscription is not necessarily the lower-cost workflow. Include the analyst time, content tooling, technical implementation and attribution stack required after monitoring identifies a problem.

    Start with the AEO workflow you actually need
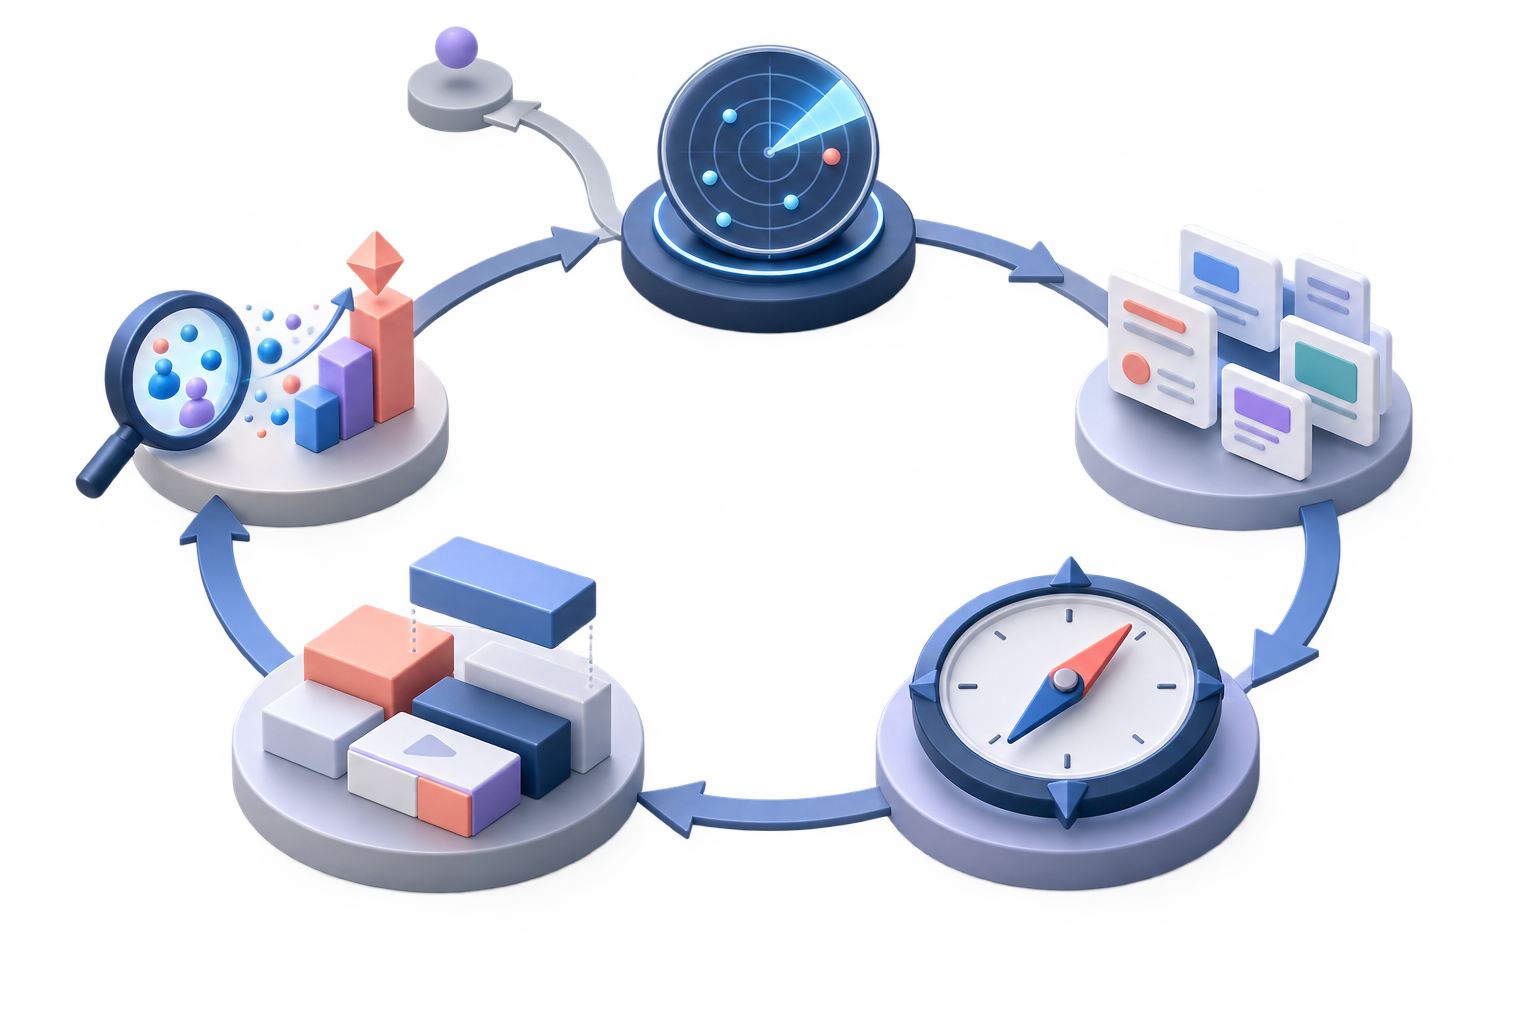
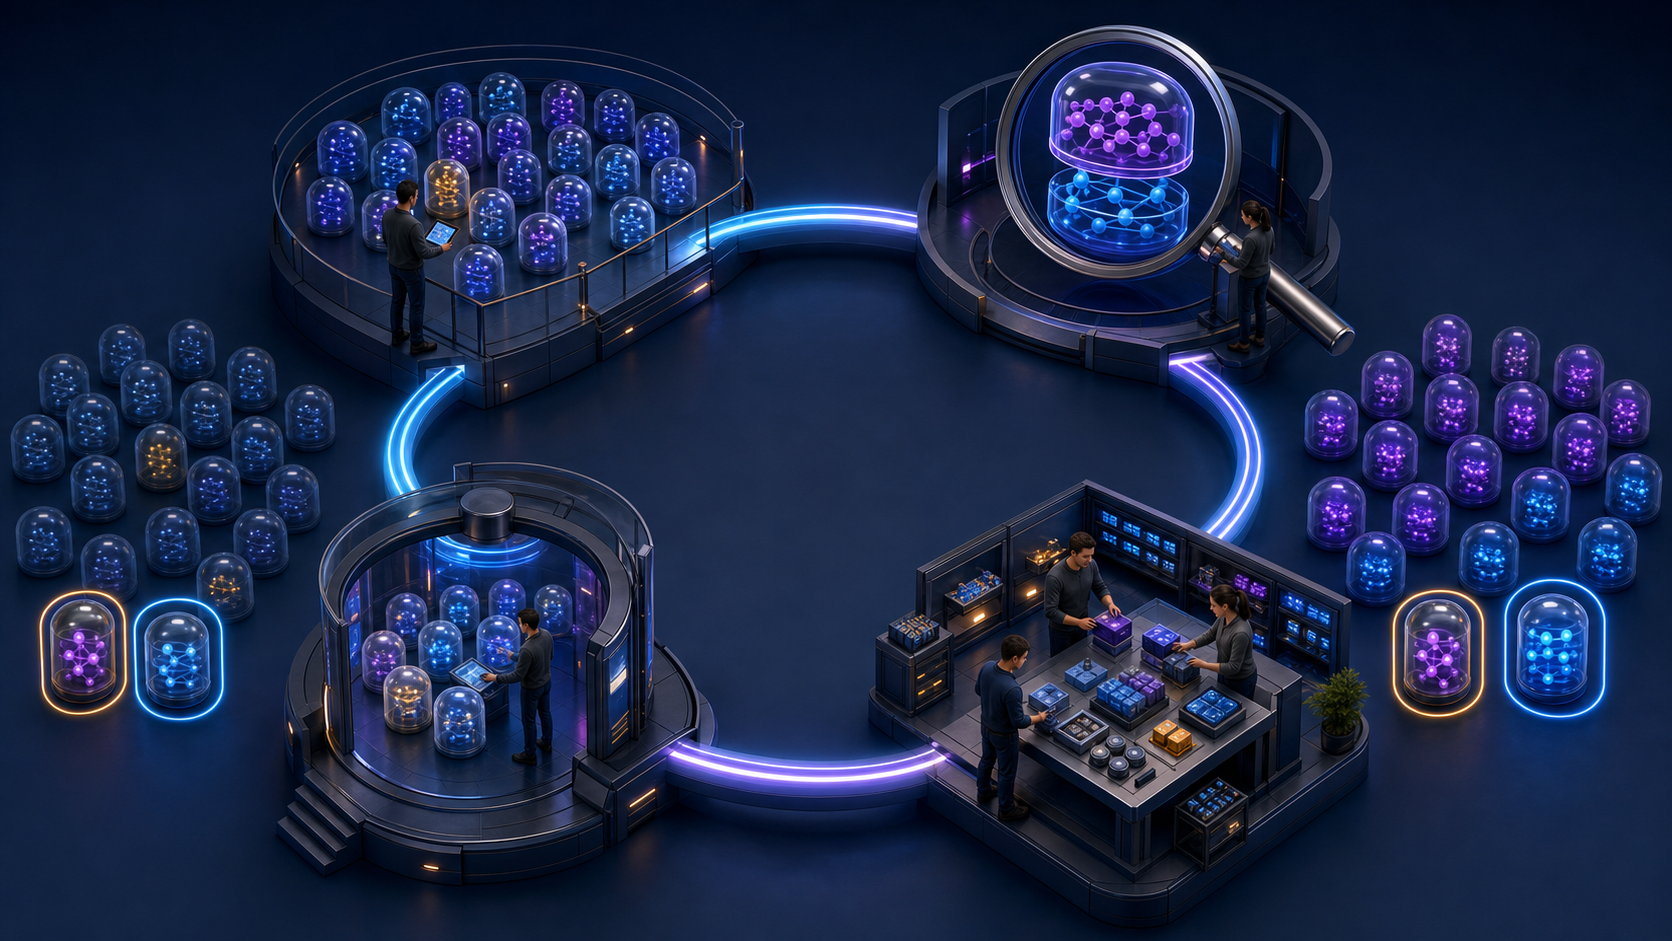
    A circular optimization workflow connects monitoring, analysis, recommendations, content production, and attribution, with one path ending after monitoring.

    An AI visibility platform can perform two fundamentally different jobs. The first is observation: run prompts, capture generated answers, identify citations, measure brand presence and compare competitors. The second is intervention: determine why visibility is weak, decide what to change, produce or update the content, fix technical access and measure the result.

    Peec concentrates on the observation layer. That can be enough when you already have an AEO strategist, content operation, technical SEO team and analytics setup. The platform supplies evidence; your existing people and systems turn it into action.

    Goodie is positioned as a closed-loop system. Its published workflow covers prompt research, visibility monitoring, prioritized recommendations, content production, technical optimization and attribution. That broader scope becomes useful when the same person or small team must move from finding a gap to fixing it without rebuilding the context in several tools.

    Map one real cycle before you evaluate either product:

    1. Select the commercial questions and prompts that matter to your audience.
    2. Run them across the relevant AI engines, country and language.
    3. Identify missing mentions, unfavorable positioning and competitor citation advantages.
    4. Convert each finding into a content, entity, schema, crawlability or distribution task.
    5. Assign and complete those tasks.
    6. Run the same prompt set again and distinguish a meaningful change from normal answer variation.
    7. Connect the result to sessions, leads, conversions or another business measure.

    Now mark which steps your team can already perform reliably. If you only need help with steps two and three, Peec’s narrower scope may be efficient. If the handoff between diagnosis and execution is where work stalls, Goodie’s broader system is the more relevant proposition.

    Goodie and Peec AI feature comparison

    The figures below reflect published feature and plan information from September 2026. Treat them as a purchasing shortlist, not as a substitute for a live product demonstration or contract review.

    Decision areaGoodiePeec AIWhat to verify
    Primary roleEnd-to-end AEO workflowAI visibility monitoring and reportingWhich tasks can be completed without exporting data?
    Standard model accessCore names five surfaces: ChatGPT, AI Overviews, Perplexity, AI Mode and CopilotStandard plans reportedly let you choose three of six: ChatGPT, AI Overviews, AI Mode, Perplexity, Gemini and CopilotPrice the exact engines your customers use, not the maximum advertised count
    Maximum model coverageUp to 12 on EnterpriseUp to 13 on Enterprise, including additional models not in the standard selectionWhich models require an add-on or enterprise agreement?
    Prompt and competitor monitoringIncludedIncludedSampling method, geography, language, refresh cadence and export access
    Sentiment analysisIncluded in the published feature setIncluded on Pro and above in the published plan descriptionHow sentiment is scored and whether individual answers can be audited
    Optimization recommendationsOptimization Hub with prioritized actions across plansNo dedicated recommendation layer reportedWhether recommendations name a page, issue, owner and expected outcome
    Technical AEORecommendations for schema, site structure and crawlabilityNo crawlability, robots.txt or llms.txt auditing reportedWhether the platform detects issues or can also validate a completed fix
    Content productionContent Studio connects prompt gaps with AI-oriented content creationNo content creation studio reportedEditorial controls, brand context, approval workflow and CMS handoff
    Revenue attributionGoogle Analytics attribution on Core, with broader attribution at higher tiersNo direct session, conversion or revenue attribution reportedAttribution logic, supported analytics properties and access to raw data
    AI commerceSKU-level visibility is listed on Pro and EnterpriseNo AI-shopping or agentic-commerce tracking reportedSupported shopping surfaces, product matching and catalog coverage
    Agency operationsAgency Growth plan, client workspaces and Enterprise multi-brand managementUnlimited seats, project-based credit pools, pitch workspaces and white-label reportingTotal cost per active client and the work required outside the platform

    The apparent model-count advantage changes with the plan. Peec’s enterprise ceiling is reportedly 13 models, compared with Goodie’s ceiling of 12, but standard Peec plans are described as a choice of three models. Goodie’s Core plan names five surfaces. If Claude, DeepSeek, Grok or another non-core model matters to your audience, ask for its exact tier and add-on cost. A logo on an enterprise coverage slide does not mean it is included in the plan you are buying.

    Cadence needs the same scrutiny. Goodie describes its monitoring as real-time, while Peec plans are described as supporting daily tracking, with daily or weekly options at some agency and enterprise levels. Ask each vendor what those labels mean operationally: when prompts run, whether failed runs are retried, how model changes are handled and when data becomes available for export.

    Choose according to who must act on the data

    For agencies selling monitoring and reporting

    Peec has the clearer fit when your engagement ends with a visibility report, competitor comparison and client presentation. Unlimited seats reduce friction when strategists, account managers and clients all need access. Credit pools can be shifted between projects, while pitch workspaces let a team build prospect-facing evidence before an account becomes a retained client.

    That operating model can protect agency margin, but only if reporting really is the end of the engagement. If your retainer also promises prioritized recommendations, content briefs, implementation and proof of business impact, add the cost of those activities before declaring Peec cheaper.

    For agencies delivering an ongoing AEO program

    Goodie’s broader workflow is more relevant when the agency owns the outcome rather than the dashboard. Its Optimization Hub is intended to turn visibility gaps into prioritized work, Content Studio addresses the production step, and attribution is intended to connect improvements with traffic and conversions.

    There is an important pricing detail. Goodie’s $350-per-month Agency Growth plan includes 10 pitch workspaces per month and unlimited seats, but ongoing client workspaces run on the brand plan selected for each client. Do not treat $350 as the complete cost of operating 10 retained accounts. Ask for a scenario-based quote that separates prospecting workspaces, active client plans, model access and implementation support.

    For an in-house brand team

    Peec can work well when AI visibility data will enter a mature operating system. A content team can receive citation gaps, technical SEO can handle crawlability and schema, analytics can manage attribution, and a strategist can decide which findings matter. In that environment, buying those functions again inside an AEO platform may add overlap.

    Goodie becomes more attractive when those handoffs are the bottleneck. A recommendation layer is valuable when it reduces the time between noticing a missing citation and assigning a concrete fix. Content tooling is valuable when it preserves the prompt, competitor and brand context that produced the recommendation. Attribution is valuable when leadership will not renew the budget on visibility scores alone.

    For ecommerce and product-led businesses

    SKU-level AI-shopping visibility creates the sharpest difference. Goodie lists that capability on Pro and Enterprise, while Peec is not described as offering product-level commerce tracking. If your question is whether an AI shopping experience can find, compare and surface individual products, brand-level mention tracking is not a substitute.

    Test product matching during the demonstration. Use several real SKUs with similar names or variants and ask the vendor to show how it distinguishes the product, the brand and the category. Also verify which shopping surfaces are included, how frequently the checks run and whether results can be joined to your catalog or analytics data.

    For enterprise procurement

    Goodie says its Enterprise infrastructure is SOC 2 compliant. Peec is described as GDPR compliant, while SOC 2 or HIPAA status was not publicly confirmed in the available material. Absence from a competitor’s page is not evidence that a certification does not exist. Request current documentation from both vendors, including the exact entity and product covered, before a security or privacy review.

    Compare total workflow cost, not the entry price
    A balance scale compares a software tool plus extra tools, handoffs, and time with a more integrated modular workflow.

    Goodie’s published brand pricing is straightforward at the first two levels. Core is listed at $399 per month with 100 prompts, 10 optimization actions per month, three seats, five named AI surfaces and Google Analytics attribution. Pro is listed at $999 per month with 250 prompts, 30 optimization actions, five seats, additional model access, full attribution and SKU-level commerce visibility. Enterprise pricing is custom, with 500 or more prompts, 60 or more monthly optimization actions, 10 or more seats and up to 12 models.

    Peec’s brand tiers are described by capacity rather than dollar price in the available comparison: Starter includes 50 prompts and one project; Pro includes 150 prompts and two projects; Advanced includes 350 prompts and five projects; Enterprise is customizable. The first three let you choose three models and include unlimited users. Because no Peec dollar figures are supplied here, obtain a current quote instead of repeating an assumed entry price.

    Peec’s agency tiers use a different unit:

    • Essential: 10,000 monthly credits, three client projects and 25 pitch prompts.
    • Growth: 25,000 monthly credits, 10 projects and 50 pitch prompts.
    • Scale: 65,000 monthly credits, 25 projects and 75 pitch prompts.
    • Comprehensive: custom pricing with unlimited credits, projects and pitch prompts.

    A prompt allowance and a credit allowance are not directly comparable. Ask Peec how many credits your proposed schedule consumes after multiplying prompts by models, countries, languages, competitors and tracking frequency. Ask Goodie whether the same dimensions consume prompt capacity, require a higher tier or carry another charge.

    Calculate total monthly cost with the same scope on both sides:

    • Platform subscription and required add-ons
    • Additional client, project, model, country and language capacity
    • Analyst time spent translating findings into prioritized work
    • Separate content, technical auditing and project-management tools
    • Implementation time for content, schema, crawlability and measurement changes
    • Analytics engineering required to connect AI referrals with outcomes
    • Reporting, white-labeling and client-access costs

    For an agency, divide that total by active billable clients and then compare it with the gross margin of the service. For an in-house team, compare it with the internal hours removed from the cycle. This exposes the real trade-off: Peec may cost less as a monitoring layer, while Goodie may consolidate work that would otherwise happen in other systems. Consolidation only saves money if your team will use the added capabilities.

    Run one full AEO cycle before you sign

    A dashboard demonstration proves that a vendor can display data. It does not prove that your team can turn that data into a better answer-engine presence. Use the same controlled workflow with both products and require an exportable result.

    1. Fix the scope. Use one commercially important customer journey, the same prompt set, the same brands, the same country and language, and only the engines you genuinely need.
    2. Inspect the evidence. Open individual generated answers and citations. Check whether every aggregate score can be traced to the underlying response.
    3. Create an action backlog. Ask the platform to help identify the page, entity, citation, schema or access issue behind each gap. Record how much manual interpretation is still required.
    4. Complete a real change. Update a page, create the missing content or implement a technical fix. Note every external tool and handoff needed to finish it.
    5. Measure again. Re-run the fixed prompt set. Look for directional improvement across repeated observations rather than treating one generated answer as a stable ranking.
    6. Build the stakeholder report. Produce the exact report your client, marketing lead or finance team expects. Include visibility, actions completed and available business outcomes.
    7. Price the production version. Give both vendors your actual number of prompts, models, markets, users, projects and clients. Request written confirmation of inclusions, overages, exports, support and contract terms.

    If that exercise shows that your team can move cleanly from Peec’s monitoring data into its existing content, technical and analytics systems, the focused platform is likely enough. If the work repeatedly slows at diagnosis, execution or attribution, evaluate Goodie on whether its integrated tools remove those specific delays.

    Make the purchase against the workflow you will operate next month, not the feature ceiling you might need someday. Take one live prompt set through monitoring, action and measurement, total every tool and hour it consumes, and choose the platform that leaves the fewest expensive gaps.

    References


  • Answer Engine Optimization Tools: A Practical Buyer’s Guide

    Answer Engine Optimization Tools: A Practical Buyer’s Guide

    You are not choosing an AEO tool to make a visibility chart go up. You are choosing it to answer a business question: where does an answer engine fail to mention, cite, or describe your brand correctly, and what should your team change next?

    That distinction matters because similar-looking platforms can serve very different purposes. One may monitor answers well but offer little help fixing the underlying content. Another may generate recommendations but provide weak evidence that those changes affect the prompts your customers use. The right choice starts with the decision you need to make, not the longest feature list.

    Decide which AEO job you are actually buying

    AEO is now sold through specialized software, tools, and platforms, but the category label hides several distinct jobs. Most teams need a combination of them, yet one should be the primary reason for buying.

    • Visibility monitoring: Track whether selected answer engines mention your brand for a controlled set of prompts, how that presence changes, and which competitors appear instead.
    • Citation intelligence: Identify the domains and pages used as supporting sources, then find where your site is cited, omitted, or displaced by a third party.
    • Content and technical optimization: Turn answer-level findings into page-level work, such as clarifying an answer, strengthening supporting evidence, correcting entity information, improving internal connections, or fixing inaccurate structured data.
    • Reporting and operations: Give marketers, subject-matter experts, executives, agencies, or clients a repeatable workflow for reviewing findings, assigning work, and documenting outcomes.

    A tool can perform more than one job. The problem begins when you assume that strength in one proves strength in the others. A broad visibility score does not automatically explain why a competitor was cited. A content recommendation does not prove that an answer engine saw or used the revised page. An attractive executive dashboard may still leave the content team without a URL to edit.

    Primary jobMinimum evidence to demandDecision it should support
    Visibility monitoringExact prompts, named answer surfaces, captured answers, dates, and historical comparisonsWhere the brand is absent, present, or represented inaccurately
    Citation intelligenceCited domains and URLs connected to the answers and prompts in which they appearedWhich pages, publishers, or evidence types influence the answer
    OptimizationAffected page, specific issue, recommendation, rationale, and a way to verify the changeWhat the content or technical team should change next
    OperationsOwnership, annotations, exports, permissions, saved views, and durable historyWho acts, how progress is reviewed, and what can be reported

    Before attending a demo, complete this sentence: We need to identify or decide ___ so that ___ can take ___ action in their normal workflow. If you cannot fill in all three blanks, you are still shopping for a category rather than solving a problem.

    Demand prompt-level evidence, not one visibility score

    Abstract prompt tokens follow separate paths through answer panels, brand indicators, and source documents, with two paths visibly missing evidence.

    Answer engines do not behave like a conventional rank tracker. The wording of a prompt, its context, the product surface, location, language, account state, and collection time can all affect what appears. Generated answers can also vary between runs. A score that compresses this complexity may be useful for reporting, but it should never be the only evidence available.

    Treat every observation as a record you can inspect. At minimum, a useful record should preserve:

    • The exact prompt, not merely a shortened topic label.
    • The answer engine or product surface that was checked.
    • The captured answer or enough underlying evidence to verify the result.
    • Whether the brand appeared and how it was described.
    • Any cited domain and destination URL the tool could identify.
    • The competing brands or entities included in the same answer.
    • The collection date and the relevant market, language, or device context when supported.
    • The previous observation, so changes can be distinguished from a newly added prompt.

    Keep different outcomes separate

    A mention, a citation, and a recommendation are not interchangeable. Your tool should let you inspect each outcome independently:

    • Mention: Your brand or product appears in the answer. This proves inclusion, not endorsement.
    • Citation: Your domain or page appears as supporting evidence. This does not by itself prove that a user visited the page.
    • Framing: The answer describes your brand in a particular role, category, or comparison. A visible brand can still be framed inaccurately.
    • Factual accuracy: Claims about features, availability, audience, locations, policies, or other attributes match your source of truth.
    • Business response: Referral traffic, assisted conversions, branded demand, or another downstream signal changes. Only claim this connection when your analytics and attribution setup can support it.

    If a vendor combines these outcomes into a proprietary index, ask how each component is weighted and whether you can drill into the underlying prompts. A score can prioritize investigation. It cannot replace the investigation.

    Build a prompt set that reflects real decisions

    AEO monitoring is only as relevant as the prompts being monitored. A large collection of synthetic questions can produce a busy dashboard without representing the decisions your customers make.

    Organize prompts by intent rather than mixing everything into one average:

    • Branded prompts test whether the engine describes your organization and products accurately.
    • Category prompts test whether you appear when a user is discovering possible solutions.
    • Problem prompts reveal which methods, products, or publishers are introduced before a buyer knows what category to search.
    • Comparison prompts show which alternatives are placed together and which attributes drive the comparison.
    • Validation prompts test the questions buyers ask before acting, such as suitability, limitations, compatibility, implementation, or trust.

    Source the language from places where customers already express needs: search queries, sales notes, support conversations, on-site search, community discussions, and research interviews available to your organization. Label each prompt by audience, intent, market, and owner. Keep a stable control set for trend reporting and a separate exploratory set for new questions. Do not silently rewrite an old prompt and present the result as historical change.

    Run a controlled proof of value before signing a contract

    A digital test bench compares baseline and modified content in parallel lanes as identical answer-engine orbs produce observable mention and citation signals.

    A polished demonstration tells you that the platform can present selected data. A proof of value tells you whether it can support your decisions with your prompts, competitors, markets, and workflow.

    1. Define the decision first. Name the person who will use the finding and the action available to them. Examples include updating a product page, correcting an entity description, pursuing a cited publisher, or briefing leadership on a competitive gap.
    2. Supply your own prompt set. Include prompts from different intents and areas of the buyer journey. Avoid letting the vendor choose only queries on which your brand already performs well.
    3. Configure entities carefully. Enter brand aliases, product names, domains, important competitors, and ambiguous terms. Check whether the platform can distinguish your organization from another entity with a similar name.
    4. Validate a representative sample manually. Compare the recorded prompt, answer, brand classification, citations, and URLs with the underlying answer surface. Note where the platform infers a result rather than capturing it directly.
    5. Check how variation is handled. Repeat selected prompts and inspect whether the tool preserves separate observations, replaces an earlier result, or converts variable answers into a stable-looking score. Ask what the history actually represents.
    6. Carry one finding through to action. Select a genuine visibility or accuracy problem, identify the affected page or information source, assign a change, and confirm that the platform can monitor the relevant prompt after publication.
    7. Export the evidence. Verify that the prompt, engine, observation date, answer, classification, and citation data survive outside the dashboard in a usable format. This protects your workflow if reporting needs change or the contract ends.

    Pause the purchase if the tool cannot show what sits underneath its headline metrics. Other warning signs include undisclosed collection timing, unexplained engine coverage, recommendations with no affected URL, citations without destination links, lost prompt history, or exports that contain only summary scores. These are not cosmetic omissions. They prevent your team from checking the result and deciding what to do.

    Choose the platform your team can operate every week

    Feature depth matters only when evidence reaches the person able to act on it. Evaluate workflow fit with the same care you apply to engine coverage.

    • Coverage and fidelity: Which answer surfaces, languages, locations, and device contexts are actually supported? Is the response captured directly, reconstructed, or classified after collection? How quickly does new data become available?
    • Prompt management: Can you group prompts by intent, product, market, funnel stage, and owner? Can you version a prompt set without destroying the baseline? Can you annotate campaigns, launches, content changes, or known engine updates?
    • Actionability: Does every recommendation lead to a page, template, entity, source, or outreach target? Can the owner see why the action was proposed and which prompts it may affect?
    • Integrations: Can findings enter your analytics, business-intelligence, project-management, editorial, or CMS workflow without manual transcription? If an API is important, test the endpoints and fields you need rather than accepting API access as a checkbox.
    • Governance: Look for suitable roles, workspace separation, audit history, retention controls, and exports. Agencies also need dependable client separation; larger organizations may need identity management and approval controls.
    • Reporting: Executives may need trends and business implications, while practitioners need prompt-level evidence and affected URLs. Confirm that the platform can serve both without hiding the details behind the summary.
    • Commercial fit: Normalize pricing to your planned engines, prompt groups, markets, collection cadence, users, retention, exports, and API use. A nominally generous prompt allowance may be poor value if the surfaces or markets you need are unavailable.

    Content and schema recommendations deserve particular scrutiny. Structured data can make page information more explicit when the markup accurately represents visible content, but it does not guarantee inclusion in a generated answer. A credible recommendation should identify the affected URL or template, the property or entity involved, the supporting source of truth, and the method for validating the change. Never let an automation invent ratings, prices, credentials, availability, authorship, or other factual values merely to fill a schema field.

    Apply the same standard to writing suggestions. The tool should show which question is underserved, what evidence is missing, where the answer belongs, and how success will be observed. Generic instructions to add more keywords, create longer copy, or publish a new page are not an AEO strategy. They are unverified content tasks.

    You also need a review rhythm. Assign someone to examine new gaps, someone to validate factual errors, and someone to move approved changes into the content or technical backlog. Preserve annotations around releases and major edits. Without ownership and change history, the dashboard becomes a passive report instead of an optimization system.

    Key takeaways

    • Buy an AEO tool for a named decision: monitoring visibility, understanding citations, improving content, or operating a reporting workflow.
    • Demand exact prompts, captured answers, dates, engine context, citations, and historical observations beneath every summary metric.
    • Measure mentions, citations, framing, factual accuracy, and business response separately; one does not prove another.
    • Test the platform with your own prompts, entities, competitors, and workflow before committing to it.
    • Reject recommendations that cannot identify an affected page, explain the reasoning, and provide a way to verify the result.
    • Choose the tool your team can run repeatedly, govern responsibly, and export from when its needs change.

    Start with one decision your current reporting cannot support. Build a small, representative prompt set around it, define the evidence required, and make shortlisted platforms prove that they can carry a real finding from observation to verified action. The best AEO tool for you is the one that makes the next responsible decision clear.

    References


  • AI Visibility Platform or Specialist Agency: How to Choose

    AI Visibility Platform or Specialist Agency: How to Choose

    You know your brand is missing, misrepresented, or rarely recommended in AI answers. The difficult decision is what to buy next: software that shows you the problem, an agency that works on it, or both.

    Choose based on the work your team can own after the first audit. A visibility platform is primarily an instrument. A specialist agency is primarily an operating team. If you buy one while expecting the other, you can collect months of reports without changing what an AI system retrieves, believes, recommends, or lets a user do next.

    Key takeaways

    • Choose a platform when your main gap is measurement and your team can turn findings into content, technical, PR, and product changes.
    • Choose a specialist agency when the diagnosis is reasonably clear but you lack the expertise, coordination, or production capacity to act on it.
    • Use a hybrid when visibility is strategically important enough to require independent measurement and sustained execution.
    • Measure retrieval, recommendation, factual accuracy, citations, suitability, and action readiness separately. A single visibility score hides too much.
    • Evaluate agencies using client outcomes in your market, not the agency’s own AI presence or a newly adopted service label.

    Buy the kind of help your bottleneck requires

    The decision becomes easier when you replace the vague goal of “improving AI visibility” with a concrete bottleneck. Are you unable to observe relevant answers? Do you understand the answers but lack the people to change them? Or do several teams need a shared measurement system and an external execution partner?

    OptionWhat you are buyingBest fitCommon gap
    AI visibility platformRepeatable monitoring, prompt tracking, citations, competitor observations, and reportingYou have content, SEO, PR, analytics, and technical owners who can act on findingsThe platform identifies a weak result but does not make the organizational changes required to improve it
    Specialist agencyDiagnosis, strategy, production, coordination, and specialist judgmentYou need execution capacity or expertise across several disciplinesYou depend on the agency’s sampling, interpretation, and reporting unless you retain access to the underlying data
    Hybrid modelAn internal measurement layer plus external executionAI discovery affects meaningful demand and you need both continuity and delivery capacityOverlapping responsibilities can produce duplicate reports and unclear accountability

    A platform is the cleaner choice when your team already knows how to update comparison pages, strengthen entity information, earn credible coverage, correct unsupported claims, improve structured data, and coordinate changes with product or engineering. The tool should tell those owners where to look and whether the result is moving.

    An agency is the better choice when those tasks have no durable owner. That often happens when SEO manages rankings, PR manages external authority, product controls integrations, legal reviews claims, and nobody owns the complete AI answer. The agency’s value should be its ability to connect those functions and deliver approved changes, not merely produce another dashboard.

    The hybrid model works when you want measurement continuity even if you change agencies. Your company owns the prompt set, raw observations, definitions, and historical benchmark. The agency receives access, proposes interventions, executes an agreed scope, and reports against the same measurement system. This keeps the agency from becoming the only party that can interpret whether its work succeeded.

    Feature breadth deserves proof before you commit. A product can look complete in a demonstration and still thin out when your workflow requires deeper analysis. Test the exact workflow you need, including exports, answer snapshots, citations, segmentation, collaboration, and follow-through. A long feature list is not a substitute for completing one real investigation from prompt to corrective action.

    Map visibility across retrieval, evaluation, and action

    An isometric scene shows source materials passing through a retrieval gateway and an AI evaluation chamber before reaching a user action terminal.

    Brand mentions are only the first layer. Agentic search can move from finding possible vendors to assessing fit and, where a product’s API supports it, completing an action or transaction. A useful operating model therefore separates retrieval, evaluation, and action.

    1. Retrieval: Can the system find and understand your brand for an eligible request? Relevant evidence can include authoritative pages, comparison content, metrics, clear entity statements, credible mentions, and citations.
    2. Evaluation: Does the answer connect your product to the right buyer, requirement, constraint, industry, or use case? Being listed is not enough if the system presents you as unsuitable for the work you actually want.
    3. Action: Can the user or agent complete a sensible next step? Depending on the task, that may mean reaching a suitable product page, requesting a demonstration, checking availability, using an integration, or invoking a supported API.

    This model prevents a common purchasing mistake. If you only need retrieval monitoring, a platform may be sufficient. If the problem is evaluation, you may need positioning, proof, comparison assets, and third-party authority. If the problem is action, marketing alone may not fix it; product, engineering, sales operations, or commerce owners may need to change the handoff.

    Build your benchmark from actual buyer situations, not a list of short keywords. Each test case should record the buyer role, task, constraints, decision stage, target market, exact prompt, platform, visible model label, date, and answer. Sample the systems that matter to your audience; cross-platform evaluations commonly include ChatGPT, Perplexity, Claude, and Google Gemini.

    Use separate working metrics so a favorable average cannot conceal a material failure:

    • Mention coverage: the share of eligible prompts in which the brand appears at all.
    • Recommendation rate: the share of eligible prompts in which the brand is presented as a viable choice, not merely mentioned.
    • Suitability: whether the stated use cases, buyer types, constraints, and differentiators match your approved positioning.
    • Belief accuracy: the share of audited factual claims that are correct. Record serious errors individually; an average can disguise a harmful claim.
    • Citation traceability: whether important claims have visible, inspectable support and which domains provide it.
    • Action readiness: whether each relevant task has a working, appropriate next step rather than a dead end or generic homepage.

    Keep the prompt set and test conditions stable when comparing periods. AI answers can vary, so one favorable response is not proof of improvement. Preserve the raw answer alongside every score. Without the answer snapshot, your team cannot distinguish a genuine positioning change from a scoring inconsistency.

    Evaluate platforms and agencies with different evidence

    Software and services fail in different ways, so they should not share one generic procurement checklist. A platform needs trustworthy observation and usable data. An agency needs diagnostic judgment, execution depth, and evidence that it can operate in your buying environment.

    Questions to put to a visibility platform

    • What is captured? Ask whether the system stores the complete answer, citations, model or platform label, timestamp, prompt, and relevant test settings. A score without its underlying answer is difficult to audit.
    • Can we control the prompt set? You should be able to separate branded discovery, category research, comparisons, objections, regulated questions, and action-oriented requests.
    • How is volatility handled? Ask how repeated observations are represented and whether the interface distinguishes a durable pattern from a one-off answer.
    • Can we inspect the scoring rules? The platform should define what counts as a mention, citation, recommendation, favorable position, and competitor appearance.
    • Can we export raw and historical data? Confirm this before signing. Screenshots and summary PDFs are not enough if you later need independent analysis or a different service partner.
    • Does it lead to a corrective workflow? Test whether a user can move from a problematic answer to its likely evidence, affected page or source, assigned owner, and verification step.
    • Does access fit the operating team? Check permissions and collaboration for content, PR, analytics, product, legal, and agency users rather than assuming one SEO login will serve everyone.

    Ask the vendor to run your own prompts during the evaluation. Include one missing-brand case, one inaccurate-description case, one competitor comparison, one buyer with strict constraints, and one action-oriented request. Then export the evidence and assign a corrective task. That short exercise exposes more than a polished dashboard tour.

    Questions to put to a specialist agency

    • How do you establish the baseline? Require the prompt set, eligible-prompt rules, raw answers, scoring definitions, platforms covered, and testing method.
    • Which client outcomes can we inspect? Look for prompt-level before-and-after evidence, changes in citations or belief accuracy, and a clear account of what the agency changed. The agency’s own visibility is not a client result.
    • Who performs each part of the work? Identify the people responsible for strategy, technical review, content, digital PR, structured data, analytics, and project management. Confirm which work is subcontracted.
    • How does the plan address all three stages? Retrieval may require discoverable evidence; evaluation may require suitability and comparison assets; action may require product pages, feeds, integrations, or APIs. Ask what is in scope and what remains yours.
    • How will incorrect AI beliefs be handled? The response should identify the unsupported claim, its likely evidence environment, the approved correction, publication or authority work, and the method for retesting.
    • How is commercial relevance measured? Visibility should be segmented by buyer, use case, and decision stage, then connected where possible to qualified demand, referrals, assisted conversions, or pipeline. Raw mention volume can rise while business relevance falls.
    • What will we own at the end? Put ownership of prompts, measurements, content, schema, digital assets, account access, and reporting history in the agreement.

    Review scores, famous client logos, media references, leadership experience, and years in business can all help with initial screening. None proves that the team assigned to you can improve your visibility. Treat an agency’s founding year as evidence of operating history and adjacent SEO or GEO experience, not proof of long experience in agentic search; the agentic specialty is newer than many firms offering it.

    Raise the bar in regulated or technical markets

    Vertical experience matters most when a plausible-sounding error can create compliance, safety, procurement, or reputational exposure. Medical-device work, for example, has to respect regulatory clearances, clinical evidence, credentialing signals, technical terminology, and the limits of approved claims. Generic product copy is a poor test of whether a partner can manage that environment; regulated GEO programs require subject-matter and compliance-aware execution.

    Give a prospective agency a realistic claim-governance exercise. Provide an approved product statement, an unapproved overstatement, and an AI answer that confuses the two. Ask who decides the correction, what evidence may be published, where legal or regulatory review enters, and how the team will verify the changed answer. A partner that jumps straight to content production without defining approval authority is not ready for high-consequence work.

    Run a proof of workflow before committing to scale

    A small team tests a connected evidence, AI response, and user action workflow at a brightly lit pilot table while additional workstations remain inactive behind them.

    A useful pilot should prove a complete operating loop, not manufacture a temporary lift in a presentation. Use a bounded set of commercially relevant prompts and require the platform or agency to move from observation to an assigned intervention and then back to verification.

    1. Define the decision. Write down whether you are choosing software, execution capacity, or a hybrid. Name the internal teams expected to use the result.
    2. Select eligible prompts. Cover distinct buyers, use cases, constraints, comparison questions, objections, and next-step requests. Exclude prompts for which your brand would not reasonably be a fit.
    3. Freeze the baseline. Store every exact prompt, answer, citation, date, platform, model label, and scoring decision. Record factual errors separately from unfavorable opinions.
    4. Classify each failure. Mark it as retrieval, evaluation, or action. Then assign an owner: content, technical SEO, PR, product, engineering, sales operations, legal, or another accountable function.
    5. Choose a small intervention set. Examples include correcting an entity statement, strengthening a comparison page, publishing suitability evidence, resolving contradictory claims, improving structured data, earning relevant third-party coverage, or repairing an action pathway.
    6. Retest the same cases. Preserve new answer snapshots and compare them with the baseline. Do not substitute easier prompts after work begins.
    7. Review operational friction. Note whether the data was exportable, scoring was explainable, approvals were manageable, owners received usable tasks, and the intervention could be traced to a result.

    Set the commercial terms around that loop. A platform agreement should identify data access, export rights, prompt limits, model coverage, historical retention, user permissions, and support. An agency scope should identify deliverables, approval dependencies, responsible specialists, reporting inputs, asset ownership, out-of-scope technical work, and the evidence required before a result is called successful.

    For a hybrid engagement, make the division explicit. Your platform remains the shared measurement record. The agency owns named interventions and documents what changed. Your internal owners approve claims, release technical or product updates, and connect visibility data to commercial outcomes. One party should still own the overall program; shared access is not shared accountability.

    Start with the bottleneck you can name today. If you cannot reliably see the problem, prove the measurement workflow. If you can see it but cannot ship corrections, test an agency on one complete intervention. Scale only when the same system can show what changed, who changed it, and whether the answer became more accurate and useful for the buyer you intended to reach.

    References


  • How to Choose an AEO Platform for AI Search Visibility

    How to Choose an AEO Platform for AI Search Visibility

    You are not buying an AEO platform to collect screenshots of flattering chatbot answers. You are buying a measurement system that should tell you where your brand is present, where it disappears, why the difference may exist, and what your team should do next.

    That distinction matters because one visible prompt can conceal a weak position across the rest of the buyer journey. The right platform measures related questions as a topic, separates brand mentions from source citations, preserves the context of each answer, and helps you verify whether an intervention changed anything.

    Measure topic coverage, not a lucky answer

    A single prompt is a diagnostic observation, not a market position. If your company appears for best software for a task but disappears from comparison, alternative, use-case, and purchase-decision questions, the model has not formed a dependable association between your brand and the topic.

    The scale of that inconsistency is easy to underestimate. Across 1,094 U.S. ChatGPT categories observed from January through June 2026, only 15.2% had a clear brand owner. Clear ownership required the leading brand to appear in at least four of five related prompts and lead the runner-up by at least five percentage points. Another 31.2% had an emerging leader, while 53.7% had no brand appearing in at least three of the five prompts.

    The opportunity is not limited to obscure queries. The more popular half of the categories represented 98% of the sampled AI search demand, yet only 11.3% of those categories had a clear owner. In the less popular half, 19% had one. Most measured demand therefore sat in topics where no brand had established consistent visibility.

    Before you evaluate a platform, build a prompt cluster around one buyer topic. Include the distinct jobs a prospective customer asks an answer engine to perform:

    • Understand: What is the category, and what problem does it solve?
    • Compare: How do the leading options differ?
    • Find alternatives: What can replace a familiar product or approach?
    • Match a use case: Which option fits a particular company, role, constraint, or workflow?
    • Make a decision: Which option should the buyer choose, and on what grounds?

    Preserve the exact wording of every prompt. Assign each prompt to a topic, funnel role, market, language, and intended audience. A useful AEO platform should let you inspect results at both levels: the individual answer for diagnosis and the complete cluster for decision-making.

    Do not generalize a result from ChatGPT to every answer engine. Engines can retrieve different material and frame the same brand differently. Your reporting should segment results by engine and market before producing any combined view. Otherwise, an aggregate score can hide the place where visibility is actually being won or lost.

    Build your scorecard before you watch a vendor demo

    A buying team compares unbranded platform modules against a structured grid using colored evaluation tokens.

    A polished dashboard can make an undefined metric look authoritative. Write down the decisions the data must support first, then ask every vendor to demonstrate those decisions with your prompts and competitors. The following scorecard keeps the evaluation tied to observable evidence.

    CapabilityWhat the platform should showDecision it should support
    Topic coveragePresence across a controlled cluster of related buyer questions, with prompt-level records underneath the totalWhether the brand owns a buyer topic consistently or appears only in isolated answers
    Competitive visibilityYour brand and named competitors measured against the same prompts, engines, markets, and collection conditionsWhere a rival has a repeatable association that your brand lacks
    Mention evidenceThe exact answer passage containing the brand, including how the brand was characterizedWhether the mention is a recommendation, comparison, caveat, rejection, or incidental reference
    Citation evidenceThe cited domain and URL recorded separately from brands named in the answerWhether your content is being used as evidence, your brand is being surfaced, or both
    Context or sentimentA classification backed by the original passage and a visible reason for the labelWhether the brand is present in the way your positioning requires
    Change over timeComparable historical runs, disclosed collection cadence, prompt changes, and engine or model changesWhether movement reflects a durable pattern, ordinary answer variation, or a measurement change
    Diagnosis and activationA traceable path from a visibility gap to an owner, proposed intervention, and later verificationWhat the content, SEO, communications, product, or brand team should do next
    Data controlExportable prompts, answers, classifications, citations, timestamps, and metadataWhether you can audit the score, combine it with business data, and retain a usable history

    Ask for formulas, not just labels. A share-of-voice number is uninterpretable until you know its denominator. It might mean the percentage of answers that mention your brand, your share of all brand mentions, the percentage of prompt clusters you lead, or a proprietary combination. Those measurements answer different questions.

    Mentions and citations also need separate columns. The most-cited domain was also the most-mentioned brand in only 21% of the measured categories. A cited page can influence an answer without causing its publisher or associated brand to be named. Conversely, a brand can be mentioned while another domain supplies the supporting evidence.

    This gives you four useful states to investigate: mentioned and cited, mentioned but not cited, cited but not mentioned, and neither mentioned nor cited. Treating all four as one visibility score removes the very distinction your team needs to choose an intervention.

    Context deserves the same scrutiny. A positive, neutral, or negative label can be useful for filtering, but it is too blunt to approve a strategy on its own. A brand described as suitable only for small teams is not necessarily receiving a negative mention; it may be receiving a precise but commercially damaging one if the company is trying to move upmarket. Require the platform to retain the passage behind every classification so a person can check it.

    Visibility monitoring, sentiment analysis, and closed-loop optimization are therefore related but distinct evaluation areas. Monitoring tells you what appeared. Context analysis tells you what the answer communicated. The optimization loop determines whether the data can be turned into owned work and measured again.

    Do not let traditional SEO proxies replace AI visibility data

    Organic authority still matters because answer engines need accessible, understandable evidence. It is not, however, a reliable substitute for measuring the answer itself.

    When clear topic owners were compared with their closest runners-up, owners had greater organic traffic in 48.4% of comparisons and a higher Authority Score in 52.5%. They had greater branded search volume in 55.7%, and branded search volume was the only one of those broad metrics to reach statistical significance. These relationships do not establish what caused a brand to lead.

    If a vendor turns backlinks, organic traffic, or domain authority into an AI visibility score without observing AI answers, you are looking at an SEO proxy with an AEO label. Use traditional metrics to investigate possible causes after you identify an answer-level gap. Do not use them as proof that the brand is visible.

    The same caution applies to automated recommendations. If a tool says to publish more content, add schema, earn mentions, or improve authority, it should connect that recommendation to a specific observed failure. Ask which prompts failed, which competitors appeared, how their framing differed, what evidence the answers used, and what result would count as an improvement. Without that chain, the recommendation is generic advice rather than a diagnosis.

    Schema can clarify entities and page meaning, but markup does not guarantee selection, citation, or recommendation. An AEO platform should help you test whether a technical change corresponds with a later answer change; it should not present implementation as the outcome.

    Demand a closed loop from observation to verification

    Four connected work areas form a loop for observing AI answers, diagnosing differences, improving content, and retesting results.

    A dashboard becomes operational when every material gap can move through the same controlled workflow. You should be able to follow an observation back to evidence, assign the appropriate response, and compare a later run without silently changing the prompt set.

    1. Define the association you want. Name the topic, audience, use case, and message the brand should credibly own. Visibility without a desired association is just name counting.
    2. Capture a reproducible baseline. Save the exact prompts, full answers, engine, market, language, collection time, brand aliases, competitor set, mentions, citations, and context labels.
    3. Classify the failure. Separate complete absence from weak coverage, incorrect positioning, unfavorable context, citation without recognition, recognition without supporting evidence, and volatility between runs.
    4. Route the intervention by cause. Send answer gaps to content owners, inconsistent entity naming to technical and brand owners, weak independent validation to communications, and inaccurate product claims to the team responsible for the underlying offer.
    5. Record what changed. Link the affected page, entity description, campaign, product information, or technical implementation to the original gap. This creates an audit trail instead of a loose correlation.
    6. Repeat the controlled measurement. Keep the original prompt cluster available, disclose any engine or prompt changes, and compare both the aggregate topic result and the underlying passages.
    7. Retain or revise the intervention. A stronger score is not enough if the answer still communicates the wrong idea. Verify coverage, competitive position, citation behavior, and answer context separately.

    Different failures call for different work. If a cited page does not connect its evidence clearly to your brand, improve that relationship on the page. If your brand is absent from comparison questions despite appearing in definitions, build content that helps a buyer distinguish options. If the answer repeats an accurate product limitation, changing copy alone will not solve the underlying issue. If third-party sources consistently define the category without you, owned-site optimization may be necessary but insufficient.

    Be careful with causality when the result moves. AI answers can vary, competitors can publish, cited pages can change, and the engine itself can change. The measurement system should preserve enough history to show what happened, but it usually cannot prove that one content edit caused one answer change. Treat a repeated directional improvement across the relevant prompt cluster as stronger evidence than a single favorable rerun.

    Durability should be visible in the reporting. Clear category owners retained first place in 90.4% of month-over-month comparisons. When a leader later lost first place, its typical lead had been 1.3 percentage points; leaders that stayed on top had held a typical lead of 2.9 points. Those figures describe association, not causation, but they show why margin and consistency are more informative than a temporary first-place label.

    Run a proof of fit with your own topics and workflow

    Do not make a buying decision from a vendor’s prepared category. A useful trial uses the language, ambiguity, competitors, and internal handoffs that the platform will face after purchase.

    Choose a mature topic where your brand should already be recognized, a contested topic where competitors have plausible claims, and an emerging topic whose terminology is still unstable. For each one, supply your own prompt cluster and expected brand aliases. Then inspect the underlying answers manually before trusting the aggregate score.

    Ask the vendor to complete these tasks in the product, not in a slide deck:

    • Import or create your exact prompts without forcing them into a hidden generated set.
    • Show how prompts are grouped into topics and how the topic-level result is calculated.
    • Separate brand mentions, linked citations, unlinked citations, and cited domains.
    • Open the full passage behind a mention, sentiment label, or recommendation.
    • Normalize known brand aliases without merging unrelated entities.
    • Segment the same topic by engine, market, language, and audience where those dimensions matter to you.
    • Explain collection cadence, answer sampling, historical backfills, and the treatment of engine or model changes.
    • Create an issue from a real visibility gap, assign it to an owner, attach evidence, and verify it in a later measurement.
    • Export the raw prompt, answer, mention, citation, classification, and run metadata.
    • Show what happens to your historical comparisons when a prompt or competitor set changes.

    Verify a sample by hand. Search the stored answer for brand aliases, check that citations point to the recorded URLs, and read the passage behind each context label. If the manual record and dashboard disagree, ask whether the cause is entity normalization, answer parsing, deduplication, or the scoring formula. You are testing auditability as much as accuracy.

    Pricing should be mapped to the measurement design before you sign. Ask which unit drives cost: prompts, runs, engines, markets, workspaces, seats, stored history, or exports. A low entry price can become a poor fit if the plan discourages the topic breadth or collection frequency your scorecard requires.

    Also ask how prompts and outputs are retained, whether confidential inputs are used for product or model improvement, who can access workspaces, and what can be deleted or exported. If your team will enter unreleased positioning, customer language, or product plans, those answers belong in the purchase decision rather than the onboarding checklist.

    Walk away from a platform that cannot expose the evidence behind its score. Other warning signs include:

    • A single visibility score with no prompt-level records.
    • A rank-tracker interface that treats one answer as a stable position.
    • Citations presented as if they were automatically brand recommendations.
    • SEO authority metrics presented as direct proof of AI visibility.
    • Sentiment labels without the answer passage that produced them.
    • A hidden prompt set that you cannot edit, version, or export.
    • Optimization recommendations that do not identify the observed gap they address.
    • Combined engine reporting with no way to inspect engine-specific results.
    • No durable record of prompt, competitor, or scoring changes.

    Key takeaways

    • Buy topic measurement, not prompt screenshots. Your platform should show whether the brand appears consistently across related buyer questions.
    • Keep mentions and citations separate. Being used as a source and being named as an option are different outcomes.
    • Require evidence behind every label. Scores, sentiment, and recommendations should open into the exact answer passages and calculation rules that produced them.
    • Use SEO metrics for diagnosis, not substitution. Organic authority can help explain a result, but it does not prove visibility in an AI answer.
    • Test the operational loop. The product should move from observed gap to assigned intervention to controlled remeasurement.
    • Prefer exportable, segmented data. Prompt-level history by engine and market is more useful than a polished aggregate you cannot audit.

    Your next move is simple: write one buyer-topic cluster and the scorecard you expect a platform to populate before you schedule a demo. If a vendor cannot show the underlying answers, explain its formulas, and carry one real gap through to verification, it is not yet giving you an AEO operating system. It is giving you another dashboard.

    References

  • Discover Goodie 2.0: Elevating AEO with Speed and Insight

    Discover Goodie 2.0: Elevating AEO with Speed and Insight

    Have you ever wanted an AEO platform that feels like it’s reading your mind? That’s exactly how I felt when I started exploring Goodie 2.0. It’s not just about speed, though that’s a massive bonus. The real magic lies in its enhanced competitor tracking and those smarter recommendations that seem tailored just for me.

    The AI search visibility insights are clearer than ever, giving me the edge I need to stay ahead in the game. If you’re like me and always looking for ways to get one step ahead, Goodie 2.0 is designed with you in mind.


    Inspired by this post on HiGoodie Blog.


    crushpress.ai community screenshot
  • Generative Engine Optimization Tools and Pricing Guide

    Generative Engine Optimization Tools and Pricing Guide

    You are probably comparing GEO tools because your brand is difficult to find in ChatGPT, Gemini, Perplexity, or another generative answer engine. The hard part is not finding a dashboard. It is working out whether a quote buys useful measurement, practical recommendations, or the work required to change the answers.

    That distinction matters more than the advertised monthly price. A low-cost tracker can be exactly right for a team that can execute. The same subscription can become shelfware when nobody owns content, SEO, reviews, or digital PR. Use this guide to define the job, compare unlike pricing plans on the same basis, and buy only the scope you can turn into action.

    Decide whether you need a GEO tool, a service, or both

    GEO software and managed GEO services solve different parts of the problem. Treating them as substitutes is the fastest way to misread a proposal.

    A tool observes. It may collect answers for a defined prompt set, detect brand mentions, capture cited URLs, compare entities, and show changes over time. AI visibility and citation measurement across engines such as ChatGPT and Gemini are central uses of this product category.

    A service acts. It may improve pages on your website, create comparison content, pursue inclusion in third-party lists, develop review visibility, or conduct public relations. Some agencies include software access in the engagement, but the dashboard is still only the measurement layer.

    Start by naming your actual bottleneck:

    • You cannot see what is happening. You do not know which prompts matter, whether your brand appears, which pages are cited, or how competitors enter the answer. Begin with measurement software.
    • You can see the problem but cannot diagnose it. You have reports, but no reliable way to connect an answer change to content, authority, citations, or reputation. Look for a platform or advisory engagement that produces evidence-backed recommendations.
    • You know what should change but lack execution capacity. The backlog repeatedly loses to other work. A managed service may be more economical than another dashboard because implementation is the scarce resource.
    • Your website is not the main constraint. Competitors are recommended because they appear in respected comparisons, reviews, and press coverage. A tool can expose this gap, but fixing it requires off-site work.

    Do not pay for full-service execution merely because the reporting looks sophisticated. Conversely, do not buy a tracker and assume visibility will improve by itself. Write one sentence before any sales call: We need this purchase to help us decide or do ______. If a vendor cannot connect its deliverables to that sentence, the package is oversized, underspecified, or both.

    Require evidence for every capability on the feature list

    Feature matrices make GEO platforms look more interchangeable than they are. Two vendors can both advertise prompt tracking while using different engines, collection schedules, sampling methods, and definitions of visibility. Compare the records behind the dashboard, not the labels on the pricing page.

    CapabilityWhat to askAcceptable proof
    Engine coverageWhich engines, answer modes, markets, and account states are included in our quoted plan?A current coverage list and a raw result from every engine you intend to monitor.
    Prompt trackingDoes one tracked prompt cover one engine, or is each prompt-engine-market combination counted separately?The precise billing definition of a tracked prompt, including reruns and overages.
    Answer collectionHow often are answers collected, and how does the system handle variation between responses?Timestamped answer text with collection metadata and a documented sampling method.
    Brand detectionCan we define product names, parent brands, abbreviations, misspellings, and excluded terms?A configurable entity record and examples showing how ambiguous matches are handled.
    Citation captureDoes the platform preserve the cited page, domain, answer passage, and engine where the citation appeared?A citation-level export, not merely a domain total.
    Competitor analysisCan the same prompt set compare our brand with named alternatives without changing the collection method?A prompt-level view showing every detected entity and citation in the underlying answer.
    RecommendationsDoes each recommendation identify the evidence, affected prompt group, responsible team, and proposed change?A sample recommendation that can be accepted, rejected, assigned, and later evaluated.
    History and exportWhat data can we retain or export if we downgrade or leave?A machine-readable export containing prompts, answers, dates, mentions, citations, and relevant metadata.

    Raw answer evidence is essential because a brand mention, a recommendation, and a citation are not the same result. Your company can be named without being endorsed. It can be recommended without receiving a clickable citation. A page can be cited while the answer recommends a competitor. A single visibility score can hide all three situations.

    Define the scorecard before you watch the demo

    Ask every shortlisted vendor to calculate the same small set of metrics. The names are less important than stable definitions:

    • Answer inclusion rate: the share of eligible collected answers in which the defined brand or product appears.
    • Recommendation rate: the share in which the brand is presented as a suitable choice, not merely mentioned in passing.
    • Cited-source rate: the share that cites a page on a domain you own or another domain you have deliberately classified.
    • Competitor gap: the prompt groups where a named competitor appears or is recommended and your brand does not.
    • Evidence gap: the cited domains and page types supporting competitors but absent from your own authority footprint.
    • Action completion: the recommendations accepted, assigned, implemented, and annotated in the measurement history.

    Keep engine-level results separate until you have a reason to combine them. A blended score can rise because performance improved on a low-priority engine while declining where your buyers actually search. If you do create an overall index, document the business weighting so a future team member can reproduce it.

    Your prompt inventory needs the same discipline. Group prompts by the decision they represent: category discovery, direct comparison, problem diagnosis, vendor validation, or implementation. Tag branded and unbranded prompts separately. A report dominated by easy branded questions can look healthy while category-level discovery remains weak.

    Normalize GEO pricing before comparing quotes

    Three toolboxes are unpacked into matching rows of monitoring, recommendation, support, and service components beside a balance scale.

    There is no useful universal price without a common unit of scope. GEO packages can vary greatly in cost and included work, with entry-level options offering narrower functionality and premium engagements covering a broader program. A monthly total tells you little until you know what consumes the allowance and what still requires your team.

    Build a quote-normalization sheet with these rows:

    Pricing variableRecord for every quoteWhy it changes the real cost
    Prompts or queriesIncluded quantity, billing definition, and overage ruleA prompt may be counted once, once per engine, or once for every market and configuration.
    EnginesIncluded engines and any plan restrictionsBroad headline coverage is irrelevant if the engines you need sit behind an upgrade.
    Markets and languagesIncluded locations, languages, and regional configurationsLocal or international monitoring can multiply the number of configurations being tracked.
    Collection cadenceRefresh schedule, reruns, and sampling methodA frequently refreshed series is not equivalent to an occasional snapshot.
    Brands and competitorsIncluded entities and the price of additional onesA plan can become expensive when each product line or competitor consumes another allowance.
    Users and workspacesIncluded seats, clients, projects, and permission controlsAgency and enterprise use may require separation that an individual account cannot provide.
    HistoryRetention period and access after downgrade or cancellationTrend reporting loses value if the underlying evidence expires or cannot be exported.
    Exports and integrationsFile exports, API access, dashboards, and usage limitsManual transfer adds labor even when the platform subscription appears inexpensive.
    OnboardingSetup fee, prompt research, entity configuration, and trainingA low recurring fee may exclude the work needed to make the account usable.
    Analysis and executionIncluded analyst time, content work, SEO changes, outreach, reviews, and PRSoftware access should not be priced as though implementation is included when it is not.
    CommitmentBilling frequency, minimum term, renewal process, and cancellation conditionsAn annual commitment carries a different risk from a cancellable pilot, even at the same monthly equivalent.

    Then calculate the cost you will actually approve:

    Total operating cost = platform or service fee + required add-ons + internal analysis time + implementation labor + external execution spend.

    This is the figure that belongs in your decision memo. A subscription can look cheap while requiring hours of prompt cleanup, report interpretation, content production, and outreach. A managed engagement can look expensive while replacing work you would otherwise need to staff. Neither is automatically better; the relevant question is which quote buys the missing capability at the lower total cost.

    Use a common monitoring unit, but do not mistake it for value

    For quote comparison, define one monitoring configuration as a prompt paired with an engine, market, language, and refresh schedule. Ask vendors to price your exact inventory. This prevents a plan with broad but shallow coverage from appearing equivalent to one collecting the configurations you need.

    You can divide total software cost by comparable monitoring configurations to expose pricing differences. Do not use that result as your final value metric. A large inventory of irrelevant prompts is still waste. Value comes from resolving decisions: which content to improve, which evidence to publish, which citation gap to pursue, and which work to stop.

    Also separate included capacity from usable capacity. If your team can review only a small portion of the collected results, buying more prompts adds noise. If the allowance is too small to cover meaningful prompt groups, apparent volatility may send the team after isolated answer changes. Scope the inventory around decisions and ownership, then buy the capacity required to support it.

    Match the service tier to the work that must change

    Three connected workstations show analytics, collaborative content and outreach work, and improved source signals flowing into an abstract answer engine.

    Service tiers are useful as a procurement model, but their names are not standardized. Define each tier by responsibility rather than by labels such as starter, growth, or enterprise.

    • Measurement tier: establishes the prompt set, captures answers, reports mentions and citations, and identifies gaps. Choose it when your internal team can interpret the findings and implement changes.
    • Diagnosis and guidance tier: adds prioritized recommendations, content or authority analysis, and working sessions. Choose it when you have execution capacity but need help deciding what to change.
    • Managed execution tier: owns agreed work across measurement, website SEO, comparison content, reputation, third-party visibility, and PR. Choose it when the visibility gap extends beyond your site or when internal ownership is the constraint.

    A comprehensive GEO program may span several distinct workstreams. Ranking strong comparative or superlative pages can influence the information available to answer engines. Inclusion in third-party lists can create corroborating evidence. Reviews contribute reputation signals on platforms relevant to the category. Press coverage can strengthen the body of independent material associated with the brand. SEO, list visibility, reviews, and traditional PR can all form part of the broader GEO scope.

    Review work must be category-specific. Technology services may care about G2 and Clutch, software companies may encounter Capterra, travel brands may depend on TripAdvisor or Yelp, and B2B organizations may need to notice employer-review properties such as Glassdoor and Indeed. The point is not to create profiles everywhere. It is to identify which independent properties appear in the citations and recommendations for your commercial prompt set, then prioritize legitimate review generation and accurate profile management there.

    Ask a managed provider to separate owned, earned, and paid activity in its scope. A page published on your website is not equivalent to independent editorial coverage. A paid list placement is not equivalent to an earned recommendation. A review profile is not the same as a program that helps real customers leave candid feedback. If all of these appear under a vague authority-building line item, you cannot judge the method, risk, or expected deliverable.

    A lower tier is sensible when you already have strong brand recognition, search performance, editorial resources, or PR support. It is also sensible when you are still validating the prompt set. Premium execution earns its fee only when the provider is responsible for work you genuinely need and can show how that work connects to observed answer and citation gaps.

    Run the same buying test with every finalist

    1. Write the decision brief. Specify the products, market, engines, prompt groups, competitors, and business decisions the system must support.
    2. Send an identical inventory. Require every vendor to quote the same prompt-engine-market configurations, refresh expectations, users, history, and export needs.
    3. Inspect a raw record. Ask to see the prompt, collected answer, timestamp, detected entities, cited pages, and relevant collection metadata behind a dashboard result.
    4. Test a difficult distinction. Use a result where your brand is mentioned but not recommended, or where your page is cited while a competitor is favored. Ask how the platform classifies it.
    5. Request an action sample. A recommendation should identify the evidence, affected prompt group, proposed change, owner, and method for evaluating the result later.
    6. Price the full workflow. Add platform fees, overages, setup, analyst time, content or technical implementation, outreach, and any separate PR or review work.
    7. Confirm data control. Obtain the retention, export, cancellation, and post-termination access terms in writing before committing.

    If a pilot is available, judge it on traceability rather than a dramatic score change. You should be able to move from an executive chart to a collected answer, from that answer to its citations, and from the gap to an assigned action. A platform that cannot preserve that chain will make it difficult to defend spending or learn from changes.

    Key takeaways

    • Buy measurement software when you need visibility into prompts, mentions, recommendations, citations, and competitors. Buy services when you need someone to change the conditions producing those results.
    • Compare quotes using the same prompt, engine, market, language, refresh, history, entity, and user requirements. Headline monthly prices are not comparable without those units.
    • Demand raw, timestamped answer and citation evidence. A single visibility score cannot tell you whether the brand was merely mentioned, actively recommended, or cited.
    • Calculate total operating cost, including internal analysis and execution. The subscription fee is only one part of the budget.
    • Choose a lower service tier when your team already has authority and implementation capacity. Choose managed execution when content, third-party lists, reviews, PR, or ownership are the real constraints.
    • Do not reward data volume for its own sake. The best plan is the smallest one that reliably supports decisions your team is prepared to execute.

    Take your real prompt inventory and the normalization table into the next vendor call. Reject any proposal that cannot define its billing unit, expose the evidence behind its metrics, and name who owns the work after a gap is found. That will narrow the field faster than another feature comparison and leave you with a GEO budget tied to action rather than dashboard access.

    References

  • How to Choose AI Visibility and AEO Tools That Pay Off

    How to Choose AI Visibility and AEO Tools That Pay Off

    You have a shortlist of AI visibility tools, but every dashboard appears to promise the same thing: better presence in AI-generated answers. The difficult part is determining whether a platform will help you make better decisions or simply give you another score to report.

    The right choice starts with a narrower question: what must the tool help you observe, explain, or change? Once you define that job, you can test coverage, evidence quality, workflow fit, pricing, and business value without relying on a polished demo.

    Key takeaways

    • Choose the primary job first: monitoring AI answers, diagnosing visibility gaps, or implementing content and product-data changes.
    • Require the underlying answer, citation, query, surface, and observation time behind every visibility score.
    • Keep mentions, citations, recommendations, sentiment, and factual accuracy as separate measures. They answer different questions.
    • Evaluate pricing against your actual workload: queries, AI surfaces, markets, observation frequency, users, exports, and implementation needs.
    • Run a controlled pilot on a fixed query set before committing. Measure both AI visibility signals and the business outcomes the work is supposed to support.
    • For ecommerce, test whether the platform can keep product pages, structured data, and commercial facts consistent across ChatGPT, Google, and Amazon workflows.

    Match the tool to the job you actually need done

    AEO now spans tools, software, and broader platforms. That wide label can hide important differences. A visibility monitor, a content recommendation system, and a product-page optimizer may all call themselves AEO tools, even though they solve different operational problems.

    We find it useful to divide the market into three jobs:

    Primary jobWhat the tool should produceWhat should make you cautious
    ObserveCaptured AI answers, mentions, citations, linked domains, query context, and changes over timeA proprietary visibility score with no underlying responses
    ExplainQuery-level and page-level evidence showing where coverage, accuracy, authority, or content is weakGeneric advice that could apply to any page or brand
    ActSpecific edits, structured-data changes, product-data corrections, workflow assignments, or implementation exportsAutomated publishing without a preview, approval record, or rollback path

    A single platform may do more than one job. That is useful only if each capability is strong enough for your workflow. A content optimizer with a small tracking widget is not automatically a robust monitoring system. A tracker that identifies a weak answer is not automatically capable of fixing the page behind it.

    Write your primary use case in one sentence before you attend a demo. For example: “We need to see when our brand is cited for high-intent category questions, identify which competing domains are cited instead, and assign the affected pages to the content team.” That sentence gives you a testable requirement. “We need better AI visibility” does not.

    Ask which surfaces are truly covered

    Do not treat “AI search” as one channel. Name the surfaces that matter to your audience and ask the vendor to demonstrate each one. For an ecommerce company, that might include ChatGPT, Google, and Amazon. For another business, the relevant set may be different.

    • Which named AI experiences can the platform observe directly?
    • Does it store the complete generated answer or only a derived score?
    • Can you see the cited URL and domain, rather than a citation count alone?
    • Can results be segmented by brand, product line, market, language, and query group?
    • Does the tool distinguish a brand mention from a linked citation or explicit recommendation?
    • Can you export the observations and their metadata for independent analysis?

    Ask the salesperson to run one of your real queries and open the evidence behind the result. If the platform cannot move from a summary chart to the captured answer, you will struggle to investigate changes or defend the number internally.

    Normalize pricing to your workload

    The practical buying decision includes both feature fit and pricing fit. Sticker prices are difficult to compare until you identify what consumes the allowance. A “query” might mean a saved prompt, one observation on one AI surface, or a recurring set of observations. Those are not equivalent units.

    Build a workload estimate using the variables you control: your tracked query set, required AI surfaces, markets or languages, observation frequency, team seats, reporting needs, and implementation volume. Then ask for the cost of that workload, including exports, API access, onboarding, additional projects, and overages where applicable.

    The least expensive plan can become the wrong choice if it forces you to remove important query segments or makes raw evidence inaccessible. The most expensive plan can also be wasteful if your immediate need is a focused baseline and a content workflow. Buy enough coverage to support a decision, not the largest dashboard available.

    Require evidence you can audit and explain

    An analyst traces glowing connections from an abstract AI response to source documents and examines the evidence with a magnifying lens.

    A visibility score is a summary, not a fact by itself. Before you trust it, you need to understand the observations underneath it and the denominator used to calculate it.

    At minimum, each observation should let you recover:

    • The exact query or prompt.
    • The AI surface on which it was checked.
    • The complete answer captured by the platform.
    • The brand, product, or entity detected in that answer.
    • Any cited or linked URLs and domains.
    • The time of the observation.
    • The market, language, and other execution context you asked the platform to control.
    • The rule used to classify the result.

    This record matters because several different events are often compressed into the word “visibility.” Your brand can be mentioned without being cited. Your page can be cited without the answer describing your product accurately. Your competitor can appear more often while your own brand receives the stronger recommendation. One blended score can conceal all of those situations.

    Define each metric before the dashboard defines it for you

    You do not need an elaborate measurement model at the beginning. You do need stable definitions. A workable starting set is:

    • Mention rate: eligible observations in which the brand appears, divided by all eligible observations.
    • Citation rate: eligible observations that cite an owned URL, divided by all eligible observations.
    • Recommendation rate: eligible observations in which the brand is presented as a suitable choice, divided by all eligible observations.
    • Answer accuracy: assessed brand or product claims that match your approved facts, divided by all assessed claims.
    • Query coverage: tracked intents with usable observations, divided by the full query set you intended to monitor.
    • Cited-domain distribution: the domains receiving citations within each query segment, shown separately from brand mentions.

    Document what “eligible” means for every measure. A navigational query containing your brand name should not be allowed to inflate performance for non-branded discovery questions. Likewise, a category query and a product-support question represent different jobs for the reader and should not be blended without segmentation.

    Accuracy deserves its own review process. Automated classification can help sort a large queue, but a human should assess claims that could misrepresent the product, price, availability, compatibility, policy, or regulated information. A highly visible wrong answer is not a successful outcome.

    Demand recommendations tied to evidence

    A useful recommendation identifies the affected query, the observed answer, the competing or cited material, the relevant page, and the proposed change. “Add more authority” is not an actionable diagnosis. “Clarify the compatibility requirements on this product page because the tracked answer describes the supported model incorrectly” gives a team something it can verify and fix.

    Apply the same standard to schema recommendations. The tool should identify the page, property, current value, proposed value, and reason for the change. Structured data must remain consistent with the information a visitor can see. Schema is not a safe place to insert claims that the page itself cannot support.

    Run a controlled pilot before making the tool operational

    A demo shows whether a platform can tell a convincing story. A pilot shows whether your team can use it to improve a real workflow. Keep the pilot narrow enough that you can trace an observation to a decision, an implementation, and a measured result.

    1. Freeze the query set. Group questions by intent, such as category discovery, comparison, brand validation, product detail, purchase support, and post-purchase support. Keep branded and non-branded questions separate.
    2. Capture a baseline. Store multiple observations before editing pages. Generated answers can vary, so a single before-and-after pair is weak evidence.
    3. Select a focused page group. Choose pages connected to the tracked queries. Keep a comparable group unchanged where practical so normal movement is easier to distinguish from the effect of your work.
    4. Change one class of problem at a time. Examples include correcting product attributes, making an answer explicit in visible copy, resolving conflicting descriptions, or aligning structured data with the page.
    5. Record the implementation. Log the page, previous value, new value, publication time, owner, approval, and reason. Without that record, later movement is difficult to interpret.
    6. Repeat the same measurement. Use the same queries, segments, surfaces, and review rules. Do not quietly replace difficult prompts with easier ones after the baseline.
    7. Evaluate AI and business outcomes separately. Look at mentions, citations, recommendations, and accuracy, then compare those changes with the relevant onsite behavior or conversion measure available in your analytics.

    Set the pass conditions before the pilot begins. A reasonable decision rule should specify which query groups matter, which visibility signals must improve, which accuracy checks must pass, and what workflow burden is acceptable. This prevents a vendor’s strongest dashboard movement from becoming the success criterion after the fact.

    Do not call a pilot successful merely because the tool generated a long task list. Judge whether your team could understand the recommendation, approve the right change, publish it safely, and see the resulting evidence. A tool that creates more tickets without improving decisions is adding activity, not capability.

    Check operational fit while the pilot is running

    The best analysis still fails if it cannot enter your production process. During the pilot, ask the people who will use the platform to test the full handoff:

    • Can an analyst assign an issue to the correct page and owner?
    • Can an editor see the observed answer and the evidence behind the proposed change?
    • Can technical teams export or integrate the required data without rebuilding the report manually?
    • Can reviewers approve, reject, or amend generated recommendations?
    • Can the team see who changed what and restore the previous version?
    • Can reports preserve query segments instead of collapsing everything into one brand score?

    These are not secondary conveniences. They determine whether insight survives the handoff from an SEO or AEO specialist to content, engineering, ecommerce, legal review, or product operations.

    Ecommerce needs a product-data workflow, not just tracking

    Unbranded products move through linked data-validation stations before reaching digital answer channels and online shoppers.

    Ecommerce raises the cost of vague or stale information. A customer may ask about a product’s fit, specification, variant, availability, or use case rather than searching for the product name alone. The optimization workflow therefore has to connect AI observations with the product detail page and the system that owns each commercial fact.

    Some commerce-focused products are explicitly positioned around AI visibility, product detail page improvement, and conversion support across ChatGPT, Google, and Amazon. Treat that positioning as a use-case claim to test, not proof of an outcome. Better conversion performance requires measurement in your own commerce analytics; an AI visibility dashboard cannot establish it by assertion.

    For every product included in a pilot, review the information AI systems and shoppers are expected to reconcile:

    • Entity identity: the product name, brand, model, category, and relationship to variants or bundles.
    • Core attributes: dimensions, materials, compatibility, intended use, limitations, and other facts that affect the purchase decision.
    • Commercial facts: price, availability, shipping information, and return conditions, with clear ownership for keeping them current.
    • Variant boundaries: which attributes belong to the parent product and which change by size, color, model, region, or configuration.
    • Visible explanations: concise page copy that answers important product questions without requiring an inference from scattered fields.
    • Structured representation: schema and feed values that agree with the visible page and the approved product record.
    • Supporting evidence: documentation or approved internal material that lets an editor verify claims before publishing them.

    Ask the tool to show how it handles a conflict. If the page description, structured data, and product feed disagree, does it identify the conflicting values and their locations? Can it route the problem to the owner of the authoritative product record? An optimizer that simply rewrites the description may make the conflict harder to detect.

    Also test each target surface independently. Coverage in ChatGPT does not demonstrate coverage in Google or Amazon, and an improvement on one surface does not prove the same change caused movement on another. Keep observations segmented, then look for changes that improve product clarity everywhere without creating channel-specific contradictions.

    Put guardrails around automated changes

    Automation is most useful after your ownership and approval rules are clear. Require a preview or diff before publication, retain the previous value, and route high-impact fields through the appropriate reviewer. Price, availability, compatibility, safety language, policies, and regulated claims should not be silently rewritten from an AI recommendation.

    Your next move is simple: write the one-sentence job for the tool, build a fixed query set around that job, and ask each shortlisted vendor to demonstrate the underlying evidence with your data. If it cannot connect an AI answer to a defensible action and a measurable outcome, remove it from the shortlist.

    References