Tag: AI Traffic

  • How to Measure AI Discovery Traffic for B2B Pipeline Growth

    How to Measure AI Discovery Traffic for B2B Pipeline Growth

    You can see buyers using ChatGPT, Claude and Gemini to research vendors, yet your pipeline report may still reduce the result to organic, referral or direct traffic. If you cannot connect that activity to qualified demand, you cannot tell whether AI discovery deserves more investment or merely produces interesting charts.

    The practical answer is not a single AI metric. Build an evidence chain from visibility, to an identifiable site visit, to an onsite action, to an opportunity. Google Analytics can now cover the middle of that chain more cleanly. Your CRM, LinkedIn activity and measurement rules must cover the rest.

    Measure three layers instead of one AI traffic number
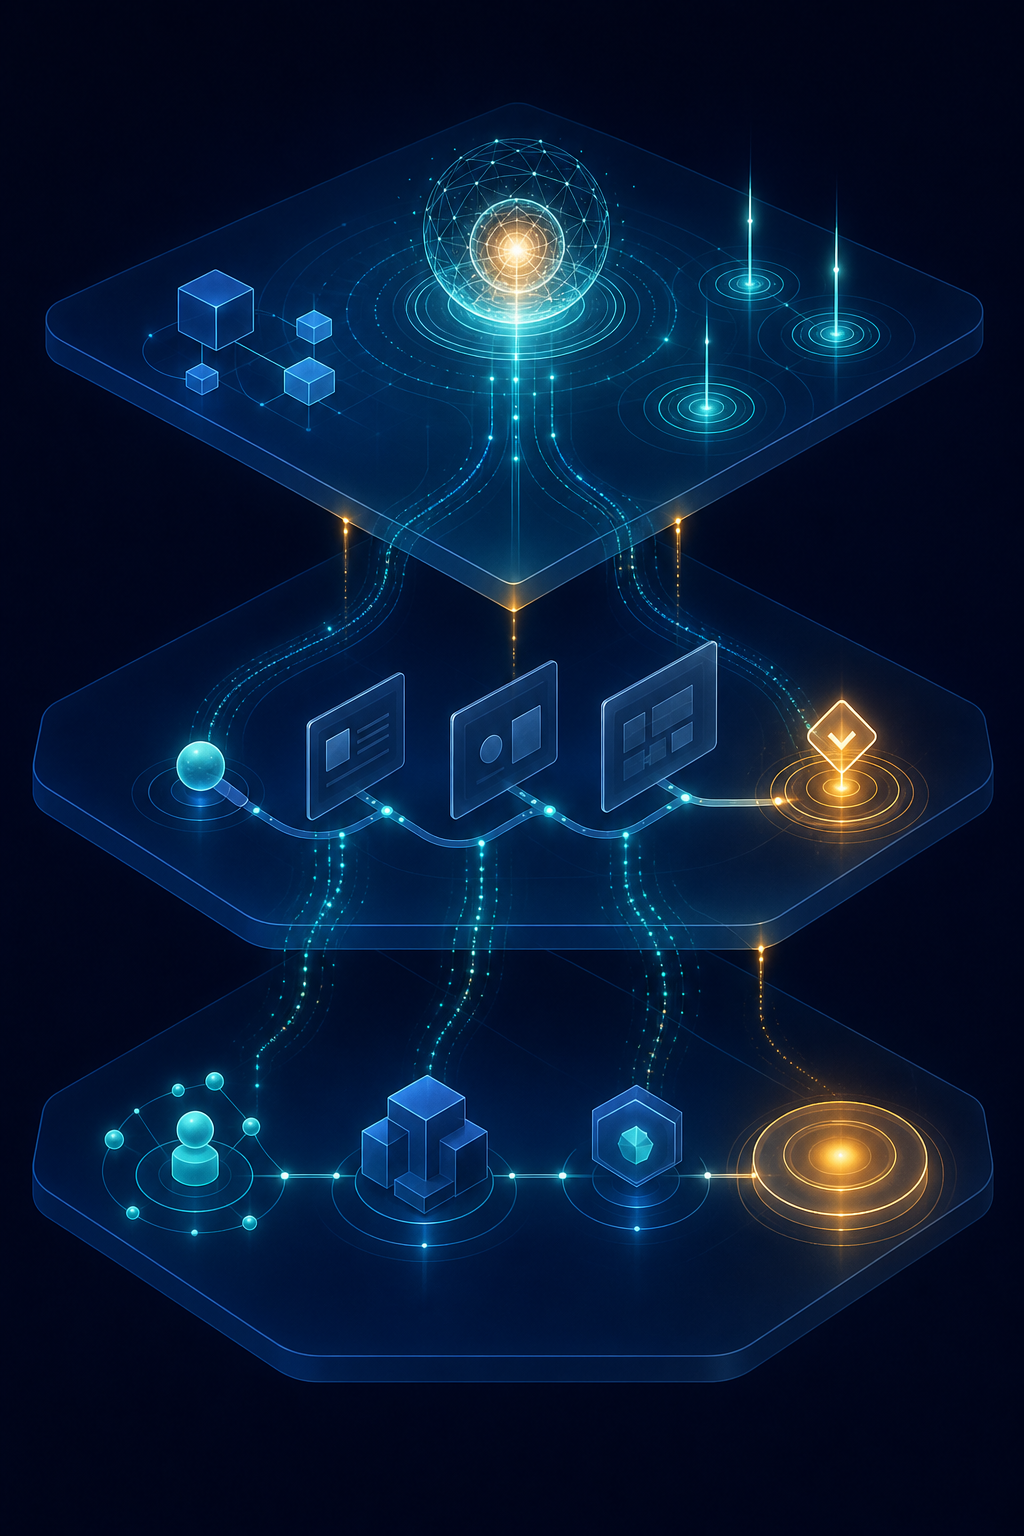
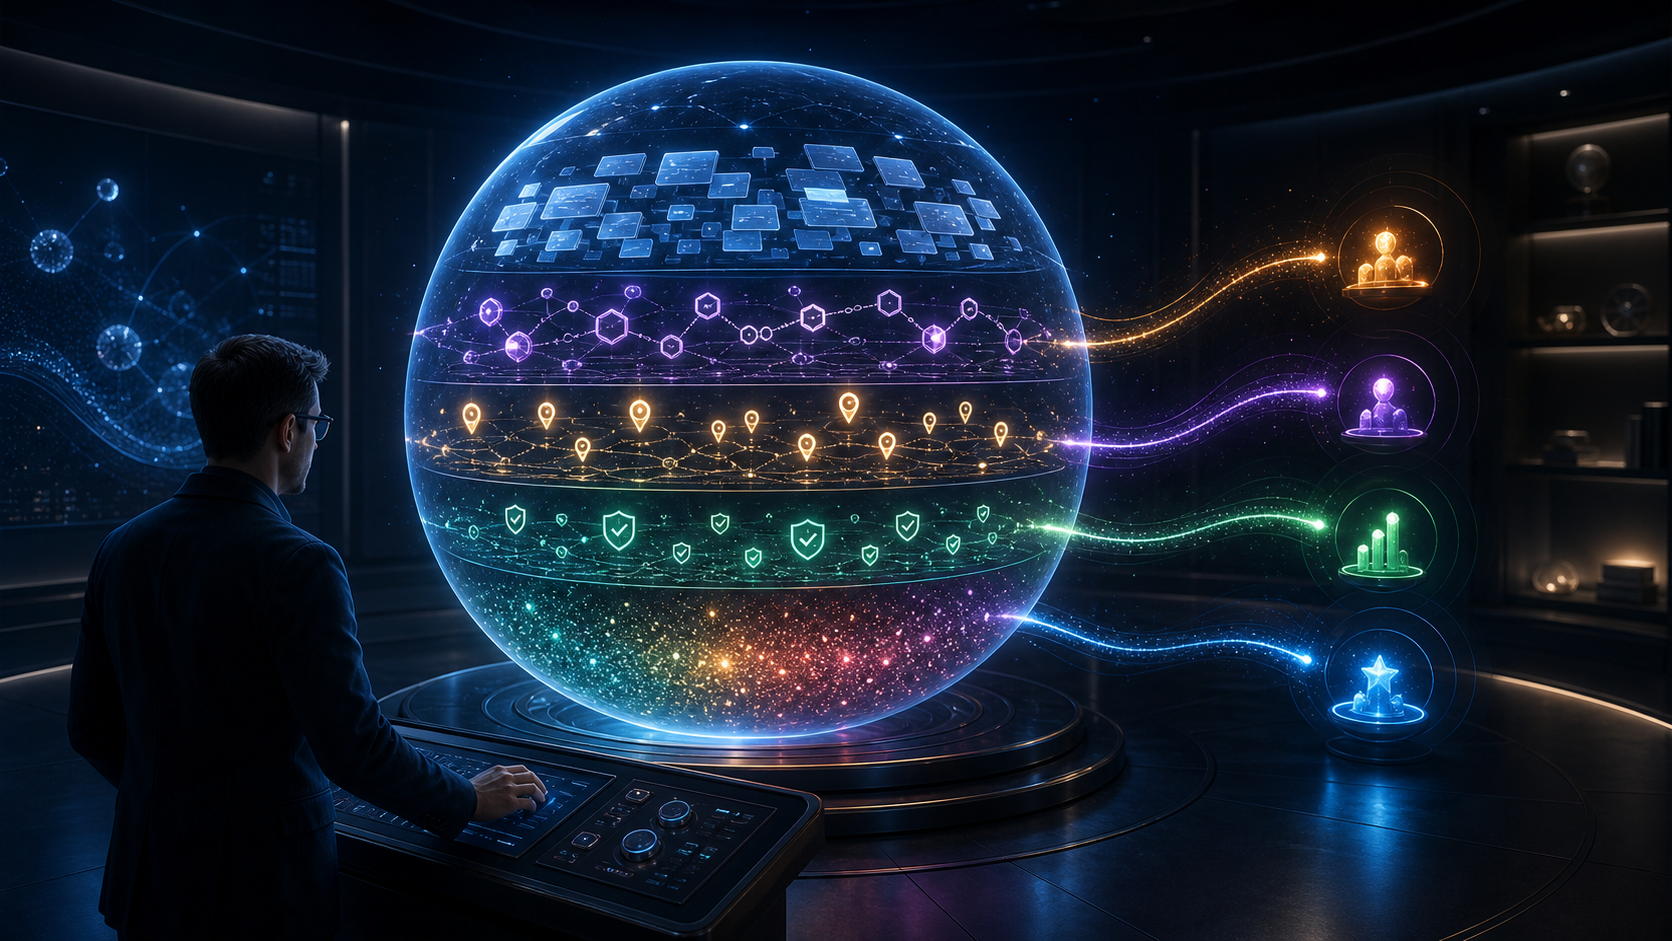
    Three connected translucent layers depict AI visibility signals, a website session and a conversion path leading to business account and opportunity nodes.

    AI discovery is not the same thing as AI referral traffic. A buyer can encounter your brand in an assistant without clicking, visit through an identifiable assistant link, or return later through another channel. Those behaviors create different evidence and should not be combined under one label.

    Measurement layerEvidence you can recordDecision it supports
    Discovery visibilityYour company, product or page appears for a controlled set of buyer questionsWhether assistants associate your brand with the right problem and category
    Identifiable trafficA supported assistant sends a visit that Google Analytics recognizesWhich assistants and cited pages generate site demand
    Business outcomeThe visitor completes a qualified action and the lead or account advancesWhether AI discovery contributes to pipeline, not just sessions

    For visibility, maintain a fixed set of questions that reflect how a buyer researches your category. Record the assistant, exact prompt, date, brands mentioned, cited URLs and whether your brand appears in the answer or only in a citation. Keep the prompt wording and access conditions consistent when you repeat the check. The result is an observation, not a universal ranking, because assistant outputs can vary.

    For traffic, use the native AI classification in Google Analytics. For business outcomes, use your existing definitions of a qualified action, lead, opportunity and revenue. This division prevents a common reporting error: treating a mention, a visit and a sale as interchangeable proof of success.

    Build a GA4 view your revenue team can trust

    Google Analytics now identifies supported assistant referrals automatically. Recognized visits can use the medium ai-assistant, the channel group AI Assistant and the campaign value (ai-assistant). This removes much of the custom filtering previously needed to isolate traffic from supported tools.

    1. Confirm that AI Assistant appears in your acquisition reporting. If it does not, check the date range and whether you have any identifiable assistant referrals before changing channel definitions.
    2. Break the channel down by source and landing page. The channel total tells you the size of the stream; the source shows which supported assistant sent it; the landing page reveals which answers or resources earned the click.
    3. Compare AI Assistant and organic search over the same date range. Use the same qualified actions and conversion definitions for both channels. Otherwise, the comparison answers a reporting question rather than a business question.
    4. Show counts beside rates. A high conversion rate based on a very small number of sessions is useful as an early signal, but it is not yet a dependable forecast.
    5. Keep unidentified traffic unidentified. Do not relabel direct visits as AI traffic merely because AI visibility increased during the same period.

    Your recurring report should include identifiable AI sessions, source, landing page, qualified action count, qualified action rate and any matched opportunities. Add the number of leads that explicitly named an AI assistant even when analytics did not record an AI referral. That last field exposes influence the channel report cannot see without pretending the attribution is certain.

    The pattern matters more than the channel total. If AI traffic is small but converts well, protect the pages earning those visits and expand the buyer questions they answer. If traffic grows while qualified actions remain flat, inspect the landing page promise, offer and next step. More assistant visibility will not repair a page that attracts one intent and presents a call to action for another.

    The AI Assistant channel is a measurement improvement, not complete AI attribution. It covers identifiable referrals from supported assistants. It cannot count an answer that satisfies the buyer without a click, and it cannot automatically recover an AI touch when the buyer returns later through direct traffic, branded search or a different device.

    Connect assistant referrals to leads, accounts and opportunities
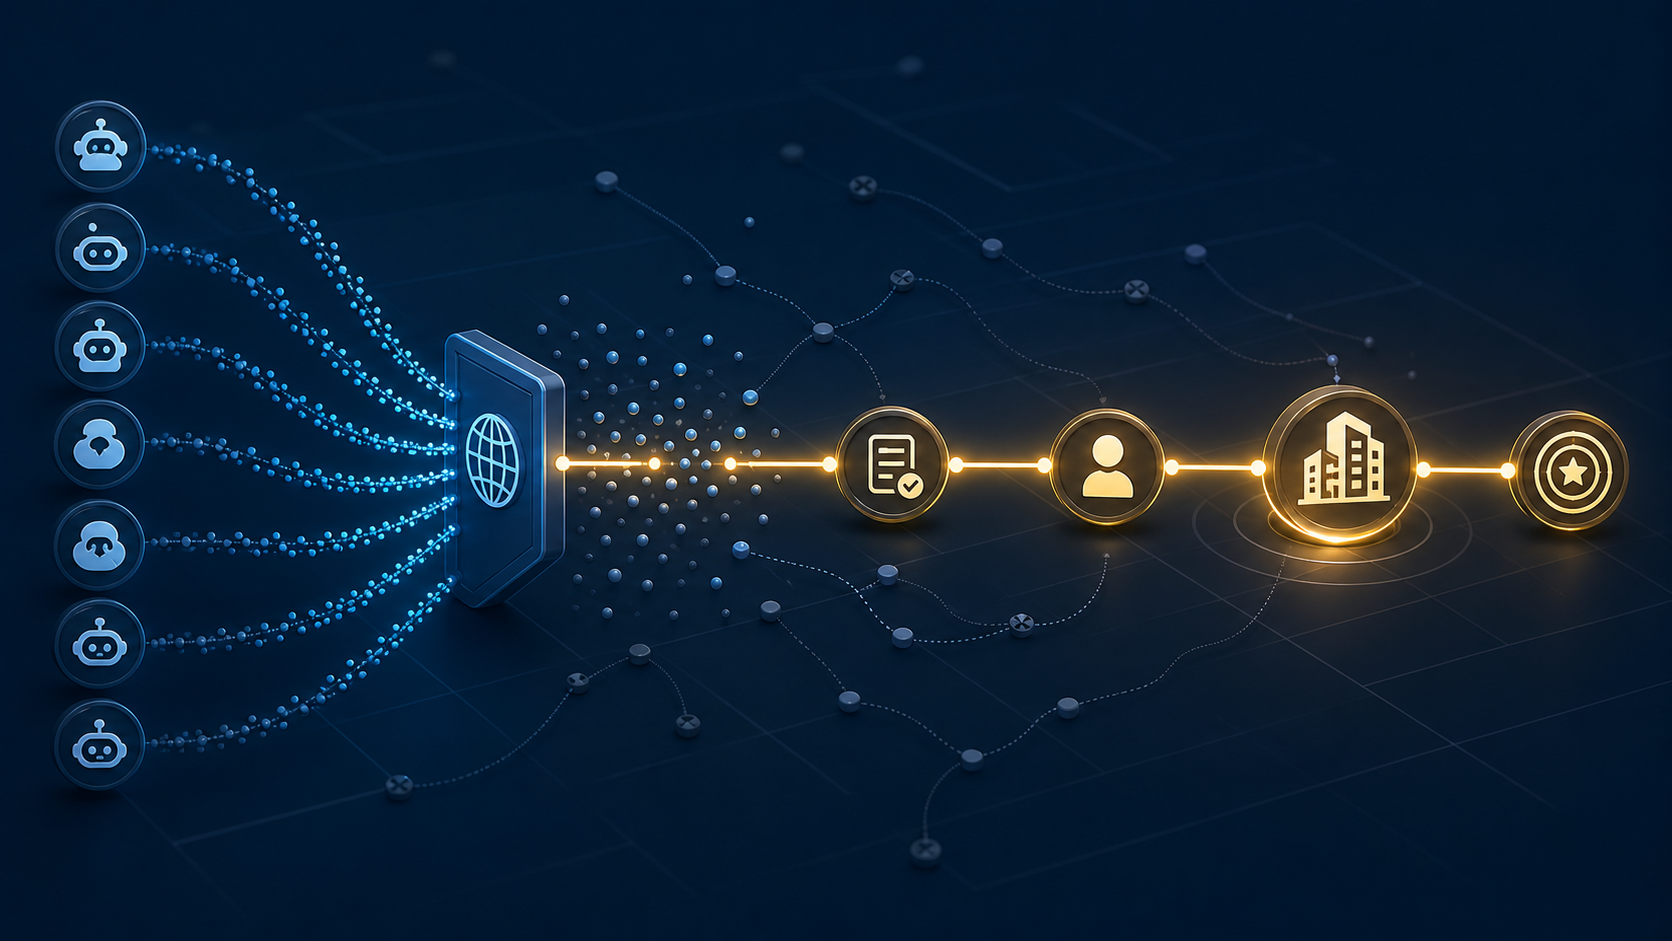
    Anonymous referral streams pass through a website gateway and connect in sequence to a lead, a company account and a qualified opportunity.

    B2B attribution becomes difficult after the click because evaluation often continues across sessions and people. Solve that problem with explicit evidence labels rather than a more aggressive attribution claim.

    • Observed AI referral: Google Analytics placed the session in the AI Assistant channel.
    • Self-reported AI discovery: A lead named an assistant when asked how they found the company.
    • AI-influenced opportunity: the account has either form of documented AI evidence before opportunity creation.
    • AI-sourced opportunity: AI discovery met your narrower, written rule for the first known acquisition touch.

    Do not merge these labels. An observed referral has stronger click evidence than an inferred influence, while a self-reported answer can reveal discovery that analytics missed. Both are useful as long as the dashboard preserves the distinction.

    1. Choose the onsite action that represents meaningful intent for your sales motion. It might be a demo request, contact submission, trial start, pricing interaction or another event your team already treats as qualified.
    2. When a visitor becomes a lead, carry permitted acquisition fields into the CRM: original source, current source, landing page, campaign and the date of the qualifying action. Retain the original values rather than overwriting them on every return visit.
    3. Add a short, optional discovery question to the form or sales qualification process. Allow the buyer to name ChatGPT, Claude, Gemini or another route in their own words instead of forcing every answer into a fixed channel list.
    4. Join the evidence at the lead and account levels where your consent and data practices allow it. Account-level reporting matters when one person researches and another submits the form.
    5. Write the attribution rule directly in the dashboard. State which touch qualifies an opportunity as sourced, which touches count only as influenced, and whether the evidence must occur before lead or opportunity creation.

    Track progression as counts and rates: identifiable AI sessions, qualified actions, leads, opportunities and closed revenue. Keep pipeline value beside opportunity count because one large deal can otherwise make a small channel look predictably scalable. For the same reason, do not forecast from conversion rate alone while the denominator remains small.

    This model also gives sales a useful feedback role. When a prospect mentions an assistant, record the assistant, the question they were trying to answer and any page or claim they remember seeing. That information can reveal buyer language, missing content and attribution gaps without turning an anecdote into a performance benchmark.

    Turn LinkedIn activity into a measurable discovery loop

    LinkedIn can strengthen the public evidence around a B2B company, but activity alone is not a growth result. Treat the company page, employee expertise, long-form content and distribution as inputs. Measure assistant visibility, referral traffic and pipeline separately as outputs.

    Remove ambiguity from your company and expert profiles

    Start with factual consistency. Keep the business address, contact details and product descriptions accurate on your website. Update the LinkedIn company page’s About section and services, including relevant industry language. Treat the profiles of executives and active subject-matter experts as extensions of the same entity, with current roles and clear areas of expertise. These are core surfaces for B2B AI discovery work.

    Assign an owner to each surface and update all of them when the company changes a product name, category, service or positioning statement. If your site publishes corresponding organization or product structured data, include it in the same update. Consistency does not guarantee an assistant mention, but it removes avoidable uncertainty about what the company does and who represents it.

    Publish one complete answer for each valuable buyer question

    Use LinkedIn articles and newsletters for questions that require more than a short update. The 800-1,200-word range associated with stronger AEO mentions is a useful starting hypothesis, not a universal ranking requirement. A complete 700-word answer is more useful than 1,000 words padded to satisfy a target.

    Give each long-form asset a specific job:

    • Use the buyer’s question or decision in the headline.
    • Answer it directly near the beginning.
    • Name the product category, intended user and relevant constraints plainly.
    • Explain criteria and tradeoffs that help the buyer make a decision.
    • Link to the corresponding website resource when the reader needs evidence, implementation detail or a next step.
    • Connect the content to an identifiable expert whose profile supports the subject.

    Add campaign parameters to links you control from LinkedIn so you can measure LinkedIn visits accurately. Keep those visits classified as LinkedIn traffic. A tracked LinkedIn click is not an AI referral, even when the content was also designed to improve AI discovery.

    Use engagement thresholds as experiments, not ranking factors

    If your team needs an initial promotion checkpoint, start with at least 10 substantive comments or 60 reactions. These figures can guide a campaign test, but they are not verified causal ranking factors for every LLM. Record them as engagement outcomes, then look independently for changes in assistant mentions, AI Assistant referrals and qualified demand.

    Count comments that contribute a question, example, objection or informed response. A pile of generic replies may increase the visible total without improving the information around the topic. Employee participation, expert partnerships, boosted company updates, Thought Leader Ads and follower ads can expand distribution, but paid and organic exposure should remain separate in your campaign log.

    Test one topic cluster from publication to pipeline

    1. Choose one buyer question tied to a product or service that can create qualified demand.
    2. Record the current website answer, LinkedIn coverage, controlled prompt observations and identifiable AI traffic.
    3. Correct company and expert profile details before publishing, so entity changes and content changes happen in a documented sequence.
    4. Publish the complete website resource and its LinkedIn treatment. Record the URL, author, publication date, distribution method, paid support and engagement.
    5. Watch all three measurement layers through a reporting period appropriate to your traffic volume and sales cycle.
    6. Compare the result with a similar topic cluster you did not change. Treat the difference as directional evidence unless your test design supports a stronger causal conclusion.

    Read breaks in the chain literally. More LinkedIn engagement without more assistant visibility proves distribution, not AI discovery. More assistant visibility without referral growth may mean the answer resolves the question without a click or does not present a useful next step. More AI referrals without qualified actions points to the landing page or intent match. More qualified leads without opportunities points to qualification, offer fit or the sales handoff.

    Key takeaways

    • Measure AI discovery as visibility, identifiable traffic and business outcomes. No single metric covers all three.
    • Use GA4’s AI Assistant channel for recognized referrals from supported assistants, but do not relabel direct traffic to fill attribution gaps.
    • Preserve observed referrals, self-reported discovery, influenced opportunities and sourced opportunities as separate evidence classes.
    • Keep website facts, LinkedIn company details and expert profiles current before trying to scale content distribution.
    • Treat the 800-1,200-word content range and engagement thresholds as test inputs, not universal LLM ranking rules.
    • Scale a topic only after you can follow its path from buyer question to content, assistant visibility, qualified action and pipeline.

    Start with one revenue-relevant buyer question. Establish the baseline, publish a complete answer, track the assistant referral and carry the evidence into your CRM. The first broken link in that chain tells you what to fix next. Repair it before increasing content volume or promotion spend.
    References

  • How to Measure Brand Visibility in AI-Mediated Journeys

    How to Measure Brand Visibility in AI-Mediated Journeys

    You may already be appearing inside AI answers while your organic dashboard says little has changed. Or AI bots may be crawling your site without your brand ever making the shortlist. If you count only clicks, both situations become an attribution mystery.

    You need to separate machine access, brand selection, human handoff, and business outcome. That gives you a measurement system that can locate the weak point in an AI-mediated journey and tell you what to test next.

    Decide what brand visibility means before scoring it

    A visit is no longer the only useful sign that a brand won. Depending on how much of the journey a person delegates, a win can be a click, an AI recommendation, or an action completed by an agent. A single traffic metric cannot represent all three.

    Start by classifying the journey into search, assistive, and agentic modes. These modes can coexist within the same purchase. Someone might discover a category through search, ask an assistant to compare the options, and then let an agent find a qualifying seller. Your measurement should follow that movement instead of assigning the whole journey to its last observable click.

    Journey modeWhat visibility looks likePrimary evidenceCommon misreading
    SearchYour page or brand is presented as an option the user can inspect.Search impressions, result position, clicks, landing sessions, and subsequent actions.Treating a high position as proof that the result influenced a decision.
    AssistiveAn AI answer names, explains, compares, cites, or recommends your brand.Observed mentions, recommendation role, cited URLs, claim accuracy, and answer-engine referrals.Counting an incidental mention as a recommendation.
    AgenticAn agent recruits your brand as an eligible option, selects it, or completes an action through it.Selection records where available, agent referrals, API or commerce events, and confirmed business outcomes.Assuming a bot request means the agent selected your brand.

    Define a qualifying visibility event before collecting data. At minimum, the brand must be correctly identified and relevant to the prompt. Record whether it was merely named, used as supporting evidence, included in a shortlist, explicitly recommended, or selected for action. Those roles have different commercial meaning.

    Set an eligibility rule for the denominator as well. A prompt belongs in your visibility rate only if your brand could reasonably satisfy the stated need, market, audience, and constraints. Including irrelevant prompts depresses the score. Excluding difficult but commercially important prompts inflates it.

    Measure each layer from machine access to business outcome

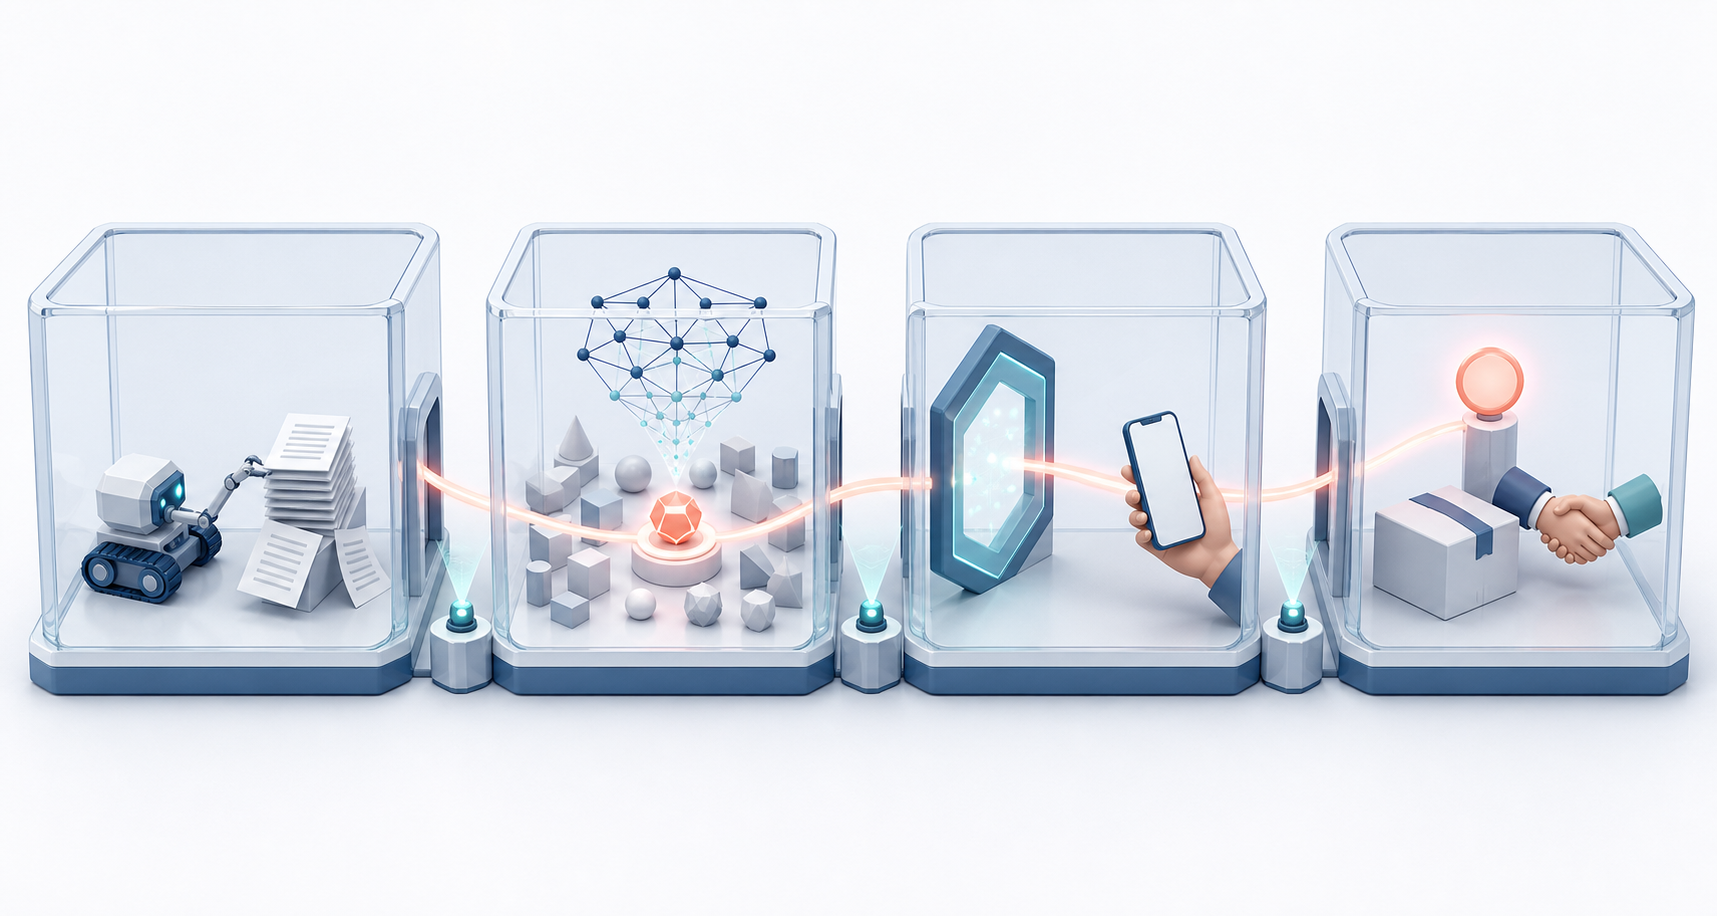
    Four connected transparent chambers depict machine access, AI selection, human handoff, and a business outcome, with observation points between them.

    AI visibility is a sequence, not an isolated mention. A useful diagnostic model follows ten gates: discovered, selected, crawled, rendered, indexed, annotated, recruited, grounded, displayed, and won. The early gates make your information available to machines. The later gates determine whether the system can understand, use, present, and act on it.

    You will not observe every gate directly. Server logs can show that a crawler requested a URL, but they cannot prove that the page was indexed, understood correctly, or used in a response. A citation can show that a URL supported an answer, but it does not reveal every internal retrieval or ranking decision. Label each measurement as observed or inferred so your dashboard does not manufacture certainty.

    Measurement layerQuestion it answersUseful measuresWhat it does not prove
    Machine accessCan qualifying bots reach and process the pages that matter?Priority URLs requested, response status, rendered content availability, repeat access, and crawler identity confidence.That the information was indexed, trusted, or selected.
    Entity understandingDoes the answer associate your brand with the correct category, products, locations, capabilities, and constraints?Entity accuracy, attribute accuracy, category association, and contradiction frequency.That the brand will be recruited for a particular decision.
    Recruitment and groundingDoes the system use your brand or content when constructing an answer?Qualifying mention rate, citation rate, cited-page coverage, claim usage, and competitor co-mentions.That the user saw a meaningful recommendation.
    PresentationHow is the brand shown to the user?Recommendation rate, shortlist inclusion, order when a genuine ranking exists, description, caveats, and next action offered.That the user followed the recommendation.
    Handoff and outcomeDid the journey reach your property or produce a business event?Answer-engine referrals, engaged sessions, leads, account creation, purchases, bookings, and other confirmed outcomes.That one observed AI answer caused the outcome.

    Keep these layers separate before creating any composite score. A blended score can rise because crawler activity increased even while recommendation visibility fell. That looks like progress until you inspect the components.

    Use a small metric dictionary so everyone calculates the same thing:

    • Qualifying mention rate: eligible prompt runs containing a valid brand mention divided by all eligible prompt runs.
    • Recommendation rate: eligible prompt runs in which the brand is positively recruited as an option divided by all eligible prompt runs.
    • Citation rate: eligible prompt runs citing an owned or controlled page divided by all eligible prompt runs. Report third-party citations separately.
    • Claim accuracy rate: checked brand claims that are materially correct divided by all checked brand claims.
    • Priority-page bot coverage: priority URLs receiving a qualifying bot request divided by all URLs in the defined priority set.
    • AI referral engagement rate: qualifying answer-engine sessions that complete your chosen engagement event divided by all qualifying answer-engine sessions.
    • AI-attributed outcome rate: confirmed outcomes with an observable AI referral or another declared attribution signal divided by the applicable set of outcomes.

    Always display the numerator and denominator next to each rate. A clean percentage built from a tiny or changing prompt set is less informative than a modest rate calculated from a stable, representative panel.

    Build a prompt panel around real decisions

    A prompt tracker is useful only when its prompts resemble the decisions your audience delegates. A list of branded questions will tell you whether an engine can repeat known facts about you. It will not tell you whether the brand is discoverable when the user has not chosen it yet.

    Build the panel from intent and constraints:

    1. Map the decisions. Include discovery, comparison, validation, troubleshooting, and action-oriented needs. Connect each need to a product line, audience, market, or journey stage.
    2. Add realistic constraints. Use the factors that can change eligibility, such as use case, compatibility, location, availability, delivery requirement, organizational size, or risk tolerance. Do not add a constraint merely to make the prompt longer.
    3. Balance non-branded and branded prompts. Non-branded prompts measure discovery and recruitment. Branded prompts measure entity understanding, accuracy, and competitive positioning.
    4. Define matching rules. List the canonical brand name, legitimate variants, product names, and exclusions that could create false positives. Decide how acquisitions, resellers, and similarly named entities will be handled before scoring begins.
    5. Fix the test conditions. Preserve the prompt wording, engine, model label, account state, location, language, and personalization state when those variables are available. Record any condition you cannot control.
    6. Review the full answer. A string match cannot tell whether the brand was recommended, dismissed, confused with another entity, or mentioned only inside a citation title.

    Useful prompt templates include:

    • What are suitable ways to solve [problem] for [audience or situation]?
    • Which providers meet [requirement] and [constraint]?
    • Compare options for [use case], especially [decision factor].
    • Is [brand or product] suitable for [specific scenario]?
    • Find an option for [need] that can satisfy [action constraint].

    Do not average every prompt into one headline number. Segment results by intent, journey mode, market, product, and engine. A brand can be highly visible in informational answers yet absent when the prompt moves to comparison or action. That boundary is where the commercial problem usually becomes diagnosable.

    For every run, capture the prompt ID, intent cluster, test conditions, brand presence, mention role, recommendation strength, cited domains, cited URLs, claims made, claim accuracy, competitors named, caveats, and proposed next action. Preserve the answer itself when your governance rules permit it. Otherwise, retain a structured review and enough metadata to reproduce the test.

    Model outputs can vary with wording, context, model changes, and personalization. Treat an individual answer as an observation, not a stable market fact. Repeated runs and a fixed protocol help you distinguish a persistent visibility pattern from an isolated output. When an engine or model changes, mark the break in the time series instead of presenting the new results as a clean continuation.

    Join prompt observations, bot visits, referrals, and outcomes

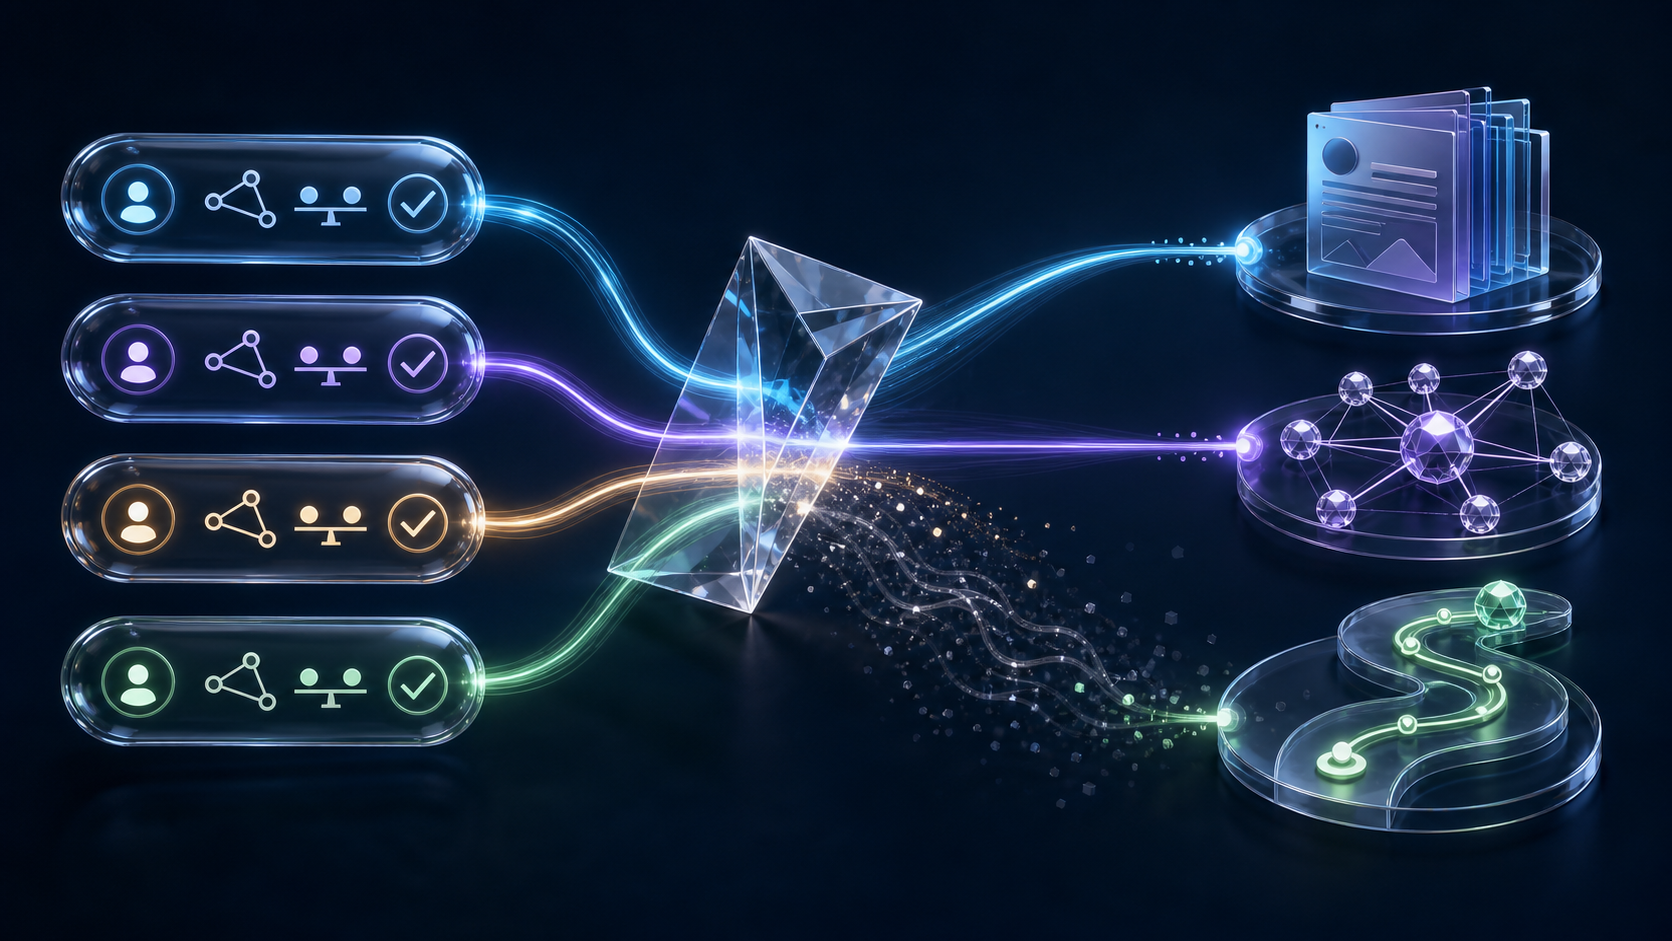
    Four colored streams of prompt observations, bot activity, referral paths, and outcome signals converge in a transparent measurement hub.

    No single analytics system sees the entire AI-mediated journey. Prompt monitoring observes the answer. Server logs observe requests to your site. Web analytics observes some human handoffs. Product, commerce, and customer systems observe downstream outcomes. Your job is to connect those views without pretending they form a deterministic user-level trail.

    Some agent analytics workflows now make bot visits and human referrals available as separate inputs. Keep that separation in your own model. Bot activity is evidence of machine access. Human referral activity is evidence of a visible handoff. Neither is a substitute for the other.

    Evidence streamMinimum fields to retainBest useImportant limitation
    Prompt observationsTimestamp, engine and model label, prompt ID, intent, market, mention role, citation, recommendation, claims, and competitors.Measuring whether and how the brand appears in AI responses.The observed answer cannot reveal every internal retrieval step or every answer shown to other users.
    Server and edge logsTimestamp, requested URL, response status, user agent, verified bot classification where possible, and rendering outcome.Diagnosing whether relevant machines can access priority content.User-agent labels can be spoofed, and a request does not establish indexing or use.
    Referral analyticsReferral class, referring domain when exposed, landing URL, session ID, campaign parameters, and engagement events.Measuring observable human handoffs from answer engines.Not every app or handoff exposes a usable referrer, so measured referrals are not the whole audience.
    On-site behaviorLanding page, content path, engagement event, lead event, account event, and transaction event.Finding friction after an AI-mediated arrival.On-site behavior alone does not establish which answer or prompt influenced the visit.
    Business outcomesOutcome type, timestamp, product or service, market, value where appropriate, and declared acquisition signal.Connecting visibility work to decisions the organization values.Self-reported and last-touch signals are useful but incomplete attribution evidence.

    Join these streams at an aggregate level using the safest shared dimensions: time period, landing URL, product, market, intent cluster, and engine class. For example, you can compare a change in citation coverage for a product cluster with bot access to its priority pages, referrals landing on those pages, and relevant conversions. That creates a defensible sequence of evidence without claiming that an anonymous conversion came from a particular monitored prompt.

    Use explicit evidence labels in every analysis:

    • Observed: a monitored answer named the brand, a known bot requested a page, a referrer identified an answer engine, or a tracked session completed an event.
    • Inferred: a page probably contributed to an answer, a referral may have followed a particular prompt, or an AI mention may have influenced a later direct visit.
    • Unknown: the platform did not expose enough information to connect the events responsibly.

    This distinction matters most when direct traffic or branded search rises after AI visibility improves. That movement may support an influence hypothesis, but it does not identify the original answer or prove causation. A post-conversion question about how the person found you can add directional evidence, provided you keep self-reported responses separate from observed referrals.

    Use the dashboard to choose the next intervention

    Your dashboard should help someone decide what to change. Organize it by the measurement layers rather than by whichever tool supplied the data:

    • Access: priority-page bot coverage, response failures, blocked resources, and rendering problems.
    • Understanding: entity confusion, missing attributes, inaccurate claims, and contradictory descriptions.
    • Selection: qualifying mention rate, recommendation rate, citation rate, cited-page distribution, and competitor overlap.
    • Handoff: answer-engine referrals, landing-page distribution, engaged sessions, and return behavior.
    • Outcome: leads, registrations, purchases, bookings, and other confirmed business events by relevant cohort.

    Read combinations of signals rather than reacting to one chart:

    Observed patternLikely failure areaNext test
    Priority pages receive qualifying bot visits, but the brand is rarely mentioned.Entity understanding, recruitment, or grounding rather than basic access.Clarify who the brand serves, what it offers, where it operates, and the constraints it satisfies. Align structured data with visible page claims, then rerun the same prompt cluster.
    The brand is mentioned, but descriptions are inaccurate or inconsistent.Entity reconciliation and claim clarity.Consolidate canonical facts, remove contradictory copy, make relationships between the organization and its products explicit, and track the disputed claims individually.
    The brand is mentioned but seldom recommended for high-intent prompts.Weak evidence for the decision criteria used in comparison.Add verifiable information about fit, limitations, availability, compatibility, or policies on the most relevant pages. Do not present unsupported superiority claims.
    Owned pages are cited, but referrals remain low.The answer may satisfy the need without a click, or the brand may be functioning as evidence rather than the chosen option.Inspect the mention role and next action before treating this as failure. Strengthen the path to a useful next step where the user genuinely needs one.
    Answer-engine referrals rise, but conversions do not.Landing-page intent mismatch or on-site friction.Compare the answer’s promise and constraints with the landing page. Preserve context, answer the next likely question, and test the relevant conversion path.
    Conversions rise without identifiable AI referrals.An attribution gap rather than confirmed absence of AI influence.Improve referral classification, retain landing context, add a carefully worded self-report field, and analyze direct and branded-search cohorts without relabeling them as AI traffic.

    Run improvement work as a controlled diagnostic. Choose one intent cluster and one suspected failure layer. Preserve the prompt panel and test conditions. Record a baseline, make the narrowest relevant change, and then observe the nearest layer as well as downstream effects. If you changed entity and product facts, claim accuracy and recruitment should move before you expect a clean conversion effect.

    Possible interventions include correcting crawl barriers, consolidating entity information, adding decision-critical details, improving citation-worthy evidence, aligning JSON-LD with visible content, or repairing an AI referral landing path. Structured data can make explicit facts easier to interpret, but it does not guarantee retrieval, citation, recommendation, or display. Measure the relevant output after implementation.

    Record platform and model changes beside your experiments. If the engine changes during the test, you have a confound, not a clean before-and-after result. Keep the observation, mark the limitation, and repeat under the new condition rather than forcing the numbers into an unsupported success claim.

    Key takeaways

    • AI visibility has distinct access, understanding, selection, presentation, handoff, and outcome layers.
    • A brand mention, an owned citation, a recommendation, a referral, and a completed action are separate events.
    • A stable, decision-based prompt panel is the foundation of comparable visibility measurement.
    • Bot visits show machine access, not brand preference or human demand.
    • Aggregate evidence can support a journey hypothesis, but anonymous events should not be turned into deterministic user-level attribution.
    • The best next optimization is the one aimed at the first layer where the evidence weakens.

    Start with one commercially important journey and map its evidence from prompt to outcome. You do not need perfect attribution before acting. You need a clear boundary between what you observed, what you inferred, and which failure point your next change is designed to address.

    References

  • Discover Your AI Rankings with Profound’s Agent Analytics

    Discover Your AI Rankings with Profound’s Agent Analytics

    As a Profound customer, I’m excited to share that I can now clearly see where my site and pages stand in terms of AI citations compared to other peers in the Profound Agent Analytics Network.

    This feature empowers me with detailed insights, allowing for a competitive analysis that helps in enhancing my digital strategy and boosting my AI visibility effectively.


    Inspired by this post on Try Profound Blog.


    crushpress.ai community screenshot
  • How to Measure AI Search Visibility and Make It Actionable

    How to Measure AI Search Visibility and Make It Actionable

    You can have a healthy SEO dashboard and still be nearly invisible when a buyer asks an AI assistant what to choose. The difficult part isn’t collecting another visibility score. It’s knowing whether a change reflects stronger retrieval, a different mix of prompts, or noise in the answers you sampled.

    A useful measurement system starts with a repeatable prompt panel, distinguishes mentions from citations, checks whether your brand is represented accurately, and connects that evidence to business outcomes. Here is how to build one without turning a handful of AI responses into false precision.

    Measure what happens inside the answer, not just after the click

    Traditional search measurement follows a familiar sequence: query, ranking, impression, click, session, conversion. Generative search compresses much of that journey into an answer. A user can discover your brand, compare it with alternatives, absorb a claim about it, and make a decision without visiting your site.

    That makes traffic an incomplete visibility measure. Some studies cited in current GEO coverage put traditional-result clicks at only 8% when AI-generated summaries are present. Treat that figure as a warning about measurement gaps, not as a universal click-through benchmark for your site. The practical point is that an off-site answer can influence demand even when analytics records no session.

    Measure AI search visibility across four layers. Presence tells you whether the brand appears. Use tells you whether an owned page is retrieved or cited. Representation tells you whether the answer describes the brand accurately and in the right context. Impact tells you whether that exposure is associated with qualified visits, branded demand, leads, sales, or another business outcome.

    These layers prevent a common reporting error. A brand mention is not automatically an owned-content citation. A citation is not proof that the answer framed the brand correctly. Visibility is not proof of commercial influence. Each is useful, but each answers a different question.

    Key takeaways

    • Use a stable set of prompts so one reporting period can be compared with another.
    • Keep mentions, citations, observable retrieval, entity accuracy, sentiment, and conversions as separate measures.
    • Report results by platform, topic, intent, and prompt cohort before calculating an overall score.
    • Save the underlying answer and its citations. A percentage without evidence cannot be audited.
    • Use visibility metrics to choose an action, then judge that action by the specific metric it was intended to change.

    Build a prompt panel you can rerun without moving the goalposts

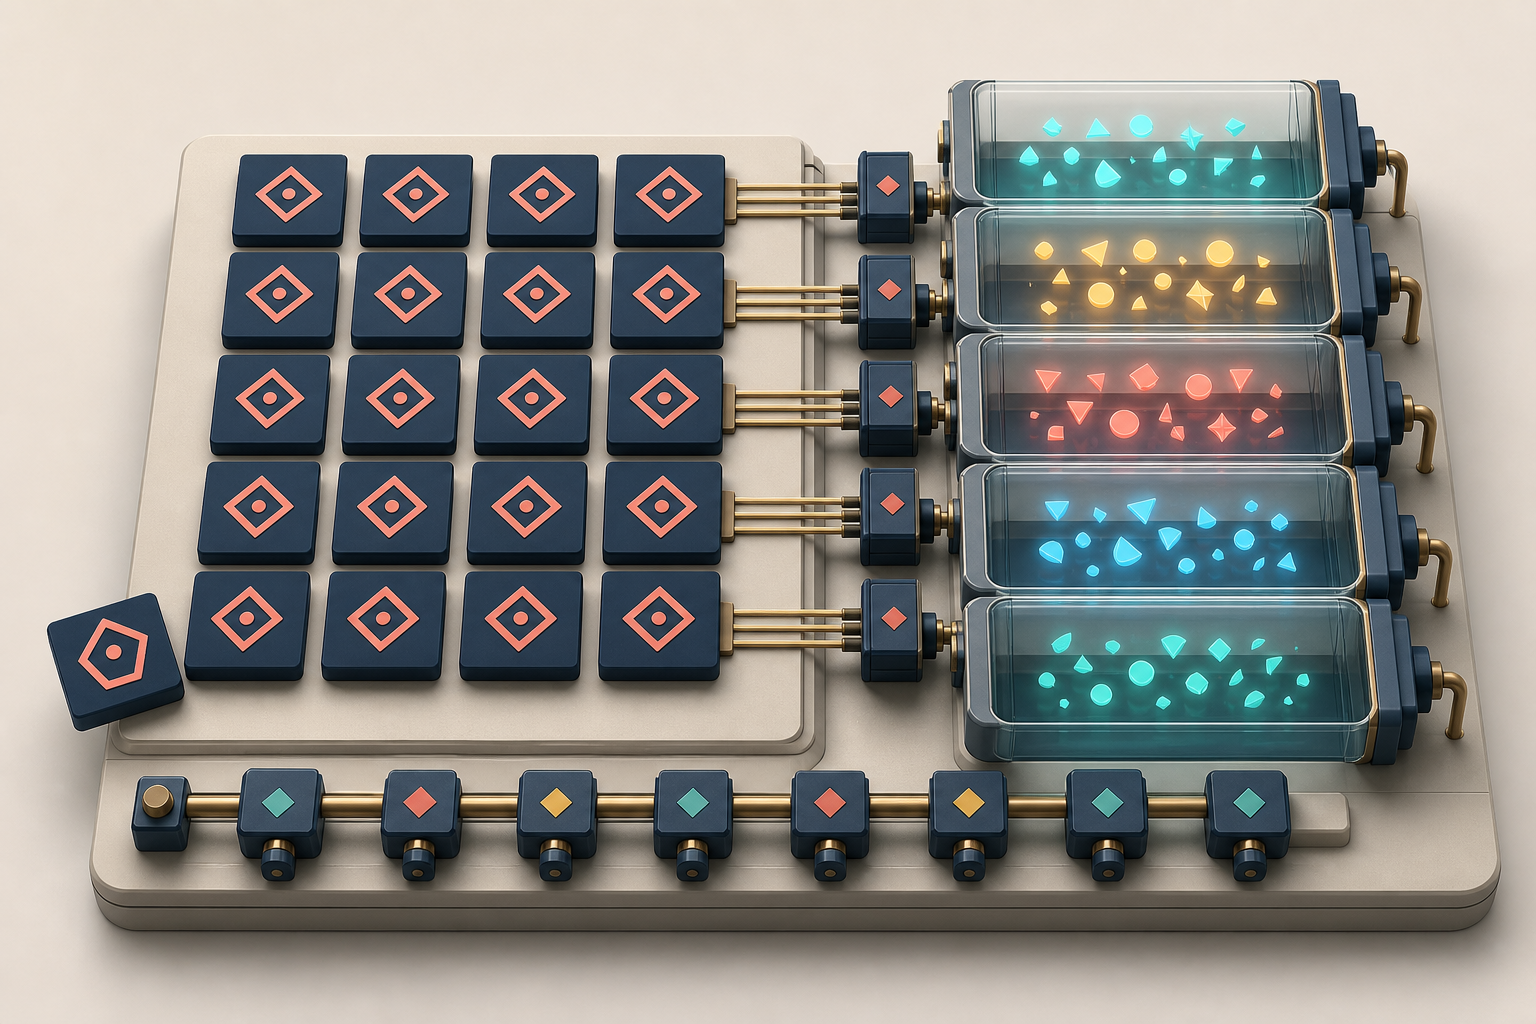
    A controlled grid of abstract prompt tiles feeds into parallel answer chambers, with one displaced tile showing a changed test condition.

    Your prompt panel is the measurement instrument. If the prompts change whenever a campaign changes, the resulting trend line cannot tell you whether visibility improved or the test simply became easier.

    Start with topics and decisions that matter

    List the topics your brand should credibly be associated with, then map the questions a real buyer asks while learning, solving, comparing, choosing, and validating. This creates a panel that covers informational discovery as well as decision-stage visibility.

    • Learn: What is the category, process, or concept?
    • Solve: How should someone handle a defined problem or constraint?
    • Compare: What are the meaningful differences between available approaches?
    • Choose: Which options fit a particular use case, audience, budget, or requirement?
    • Validate: Is a named brand suitable, credible, compatible, or known for the relevant capability?

    Include branded and unbranded prompts, but don’t blend their results. An unbranded prompt tests discovery and competitive consideration. A branded prompt tests entity recognition, factual accuracy, and reputation. A dashboard that combines them can look strong simply because the model answers direct questions about a brand that the user already named.

    Apply audience, industry, location, or product qualifiers only when they change the decision. Keep them in dedicated cohorts. Otherwise, an increasingly narrow prompt may manufacture visibility that does not exist for the broader market question.

    Create a prompt registry before collecting answers

    Give every prompt a permanent record. At minimum, store its ID, exact wording, topic, intent, audience qualifier, branded or unbranded status, platform and mode, relevant competitor set, target page, and the brand facts you expect an accurate answer to preserve.

    Freeze the wording used for your baseline. If you improve a prompt later, create a new version instead of overwriting the old one. Keep retired prompts in the registry so historical rates retain their original denominator. This is less convenient than editing a shared list in place, but it prevents an invisible change in the test from masquerading as an improvement in performance.

    Use a consistent collection protocol

    1. Run the exact registered prompt in the intended platform and mode, such as an answer with web search enabled rather than a model-only response.
    2. Record the platform, mode, timestamp, prompt version, full response, visible citations, cited URLs, and any named competitors.
    3. Score the answer with a written rubric. Preserve the raw response so another reviewer can check the decision.
    4. Repeat the panel on a fixed cadence. If resources permit, run prompts more than once so a single response is not mistaken for a stable pattern.
    5. Log failed captures, blocked responses, and unavailable features separately. Do not score a technical failure as brand absence.

    Keep platform results separate. Google AI Overviews, ChatGPT search, and other answer systems are different surfaces with different retrieval and citation behavior. You can create a portfolio view later, but first calculate each platform’s rate against its own eligible observations.

    If you do publish an aggregate, state its weighting. An unweighted average gives every prompt-platform pair the same influence. A business-weighted score gives priority cohorts more influence. Neither is inherently correct; an unexplained blend is the problem.

    Use a metric stack instead of one opaque visibility score

    A practical GEO measurement stack separates eight signals across presence, representation, retrieval, competition, and impact. The definitions below turn those ideas into auditable calculations. They are operational definitions, not universal standards, so document them and resist changing them midstream.

    MetricOperational definitionQuestion it answers
    Answer inclusion rateEligible answers containing a qualifying brand mention or traceable use of owned content, divided by all eligible answers in the cohort.Does the brand enter the answer at all?
    AI citation frequencyEligible answers containing a visible citation connected to the brand, divided by all eligible answers. Report any-brand citation and owned-domain citation separately.Is the answer visibly supported by material associated with the brand, and does it cite the brand’s own site?
    Share of model voiceThe brand’s unique inclusions divided by unique inclusions for the entire predefined competitor set. Count a brand once per answer so repetition does not inflate share.How much of the observable category conversation does the brand occupy?
    Entity recognition accuracyBrand-discussing answers that preserve the required facts divided by all answers that discuss the brand.Does the system understand who the brand is, what it offers, and how its entities relate?
    Sentiment and framingCounts of favorable, neutral, critical, or mixed descriptions, paired with issue codes and the exact claim being evaluated.How is the brand characterized before the user reaches its site?
    Prompt coveragePriority prompt cells with at least one qualifying inclusion divided by all eligible priority prompt cells.Across how much of the intended buyer journey is the brand visible?
    Observable retrieval successRuns in which a relevant owned page is visibly retrieved or cited, divided by runs where that page is an eligible answer source.Can the system access and use the content you expected it to use?
    Conversion influenceQualified visits, conversions, lead quality, revenue, branded demand, or other outcomes associated with AI referrals and visibility changes.Is AI visibility connected to business value?

    The denominator matters as much as the numerator. Show both on every metric card. A 50% inclusion rate based on two eligible answers carries very different weight from the same rate across a broad, repeated panel.

    Keep citation frequency and retrieval success distinct. A brand can be mentioned because a third-party page was retrieved. An owned page can be cited without the brand becoming a recommended option. A model may also name the brand without exposing any source. Consumer-facing outputs rarely reveal every internal retrieval step, so call the measure observable retrieval rather than claiming access to hidden model behavior.

    Share of model voice also needs a locked competitor set. Adding weak competitors lowers everyone’s apparent share; removing a dominant competitor raises it. Version the set just as you version prompts, and show absolute inclusion alongside share. If absolute visibility holds steady while share falls, competitors may be gaining rather than your brand disappearing.

    For entity accuracy, write the answer key before scoring responses. Include only facts the brand can substantiate, such as its official name, category, product relationships, supported markets, or current positioning. Record each error type separately. A single accuracy percentage will not tell your content team whether the problem is an outdated name, a category mismatch, a confused product relationship, or a claim that is too broad.

    Sentiment needs the same discipline. A neutral answer that omits the brand’s relevant capability is different from a critical answer containing a factual error. Save the exact sentence, its context, the issue code, and the affected prompt. Automated labels can help sort a large collection, but consequential or ambiguous cases still need human review.

    Read metric combinations as a diagnostic system

    No metric tells you what to change by itself. The useful signal comes from combinations. Start with the smallest cohort where the problem appears, then diagnose the layer most likely to be responsible.

    Low inclusion plus low observable retrieval

    Begin with access and extractability. Check whether the intended page can be crawled, whether the primary answer is available in parseable text, whether important information is current, and whether structured data accurately describes the visible content and entity relationships. Crawlability, schema use, freshness, and parsing quality all belong in a retrieval-success investigation.

    Do not add schema merely to produce more markup. Structured data can clarify supported facts; it cannot make a thin, contradictory, or inaccessible page authoritative. Validate the markup, align it with what users can see, and retest the affected prompt cohort after the page can be revisited.

    Inclusion without owned citations

    The system recognizes the category connection, but your site is not supplying the visible evidence. Inspect which domains are cited instead and what those pages make easy to extract. Then improve the relevant owned page with a direct answer, clear definitions, explicit comparison dimensions, supported claims, and enough surrounding context for a passage to stand on its own.

    Do not treat matching wording as proof that the model used your page. Unless the interface exposes a citation or retrieval record, hidden sourcing remains unknown. Score what you can observe and use citation gains as the validation target for this change.

    Strong visibility with weak entity accuracy

    This is a representation problem, not an awareness problem. Compare the wrong claim with the corresponding signals on your site, structured data, product pages, and corroborating profiles. Standardize names and relationships, remove obsolete descriptions, and make the canonical explanation explicit. Retest the prompts that produced the error rather than waiting for the global score to move.

    Informational coverage without decision-stage visibility

    The brand may be recognized as an educator but absent from the consideration set. Examine compare, choose, and validate prompts. If the cited pages answer selection questions that your pages avoid, create or improve content around fit, limitations, use cases, evaluation criteria, and meaningful alternatives. The goal is not to declare yourself the best. It is to supply the facts an answer system needs to explain when the offering is or is not a fit.

    Visibility gains without measurable business impact

    First check intent. More citations on broad educational prompts may be valuable without creating immediate demand. Next check whether the cited or visited page offers a sensible next step for that query. Then inspect referral classification, landing-page engagement, conversion quality, direct traffic, and branded search movement.

    Do not force a revenue claim from a coincident trend. Off-site AI interactions are often not connected to an identifiable user journey. Call the result influence unless you have instrumentation that supports stronger attribution.

    Change one measurement layer at a time

    Turn each diagnosis into a recorded experiment. State the affected cohort, observed gap, proposed change, page or entity being changed, metric expected to move, business guardrail, and next review point. If you rewrite the prompts, replace the target pages, and change the scoring rubric together, you will not know which change produced the new result.

    Keep a control cohort of unchanged prompts when practical. It gives you context when visibility moves across the platform rather than only on the pages you changed.

    Report evidence, decisions, and business influence in one workflow

    Abstract answer signals pass through a diagnostic prism and flow into content, source, customer-journey, and business-outcome elements.

    A dashboard should shorten the distance between an observed gap and the person who can address it. Clutch, for example, places Conductor-powered visibility analysis inside its AI Visibility Dashboard. The useful principle is workflow integration: a report creates more value when operators can move from the trend to the affected prompt, answer, citation, topic, and page.

    Give each audience the view it needs

    • Leadership view: priority-topic inclusion, share of model voice, entity accuracy, major reputation issues, qualified AI traffic, and conversion influence.
    • Operator view: platform, topic, intent, prompt, target page, cited domain, competitor, issue code, and experiment status.
    • Evidence view: exact prompt, full response, visible links, scoring decision, timestamp, reviewer, and prompt version.

    Every summary card should show the current value, comparison baseline, numerator, denominator, included cohort, and last collection date. Avoid a global visibility score that cannot be traced to those components. It may look tidy, but it cannot tell a content, technical SEO, brand, or analytics team what to do next.

    Keep the collection cadence and the decision cadence separate

    Collect on a consistent schedule that your team can sustain. Review urgent factual errors when they appear, but make strategic decisions only after you have enough comparable observations to distinguish a pattern from one answer. Annotate changes to prompts, pages, structured data, competitor sets, platform modes, and scoring rules directly on the timeline.

    When a platform introduces a materially different mode or answer experience, create a new cohort. Do not splice it into the old series as if the measurement environment stayed constant.

    Triangulate AI visibility with analytics and search data

    No single product captures the complete path. Combine controlled prompt testing with analytics, server or referral evidence where available, Search Console, traditional SEO tools, technical audits, and business data. This mixed approach reflects the reality that GEO measurement currently requires multiple tools and methods.

    In GA4, isolate known AI-platform referrals and compare their landing pages, engagement, conversion rate, conversion value, and lead quality with relevant baselines. Keep the referral rules documented because platforms and referrer behavior can change. Review direct and branded-search demand alongside those sessions, but present the relationship as supporting evidence rather than proof that every change came from AI exposure.

    Search Console still helps you see traditional query demand, page performance, and technical conditions around the topics in your prompt panel. It will not expose every AI interaction, but it can reveal whether a page has a broader indexing, relevance, or demand problem that also limits its usefulness to generative systems.

    Evaluate tools by the decisions they support

    Before buying an AI visibility platform, ask whether it supports the exact environments you need to measure and whether you can audit its results. A useful evaluation checklist includes:

    • Named platforms and modes rather than a generic claim of model coverage.
    • Exact prompt storage, prompt versioning, cohort management, and repeatable scheduling.
    • Preservation or export of full responses, citations, cited URLs, timestamps, and scoring evidence.
    • Transparent definitions and denominators for inclusion, citations, share of voice, sentiment, and coverage.
    • A configurable competitor set and the ability to retain historical versions of that set.
    • Segmentation by topic, intent, platform, geography where relevant, brand, competitor, and target page.
    • Human review, issue coding, annotations, ownership, and an audit trail for score changes.
    • Connections to analytics and business outcomes rather than visibility reporting alone.

    Do not compare vendor scores as though they were interchangeable. One may count every mention, another only cited mentions, and another may use a proprietary weighted index. Compare the underlying prompts, observations, scoring rules, and denominators before comparing the headline numbers.

    Start with one commercially important topic. Freeze its prompts, capture a baseline, and identify the largest localized gap: presence, citation, retrieval, accuracy, competitive share, or impact. Assign one change to that gap and name the metric that should respond. When the dashboard can tell your team what to inspect next, AI search visibility stops being a vanity score and becomes an operating system for better decisions.

    References

  • How to Restart Search Growth in the Age of AI Answers

    How to Restart Search Growth in the Age of AI Answers

    If your search impressions still look healthy while organic clicks and conversions have flattened, publishing more content may deepen the problem. AI answers have changed which searches produce a visit, but they have not removed the need for useful pages, credible evidence, or clear decisions.

    You need to find the exact layer where growth is breaking: discovery, answer visibility, click capture, on-page usefulness, or conversion. Once you separate those layers, you can stop treating every plateau as a rankings problem and make the change that the evidence supports.

    Reset what search growth means

    The familiar organic growth model is simple: rank for more queries, earn more clicks, and turn those visits into outcomes. AI-generated answers insert another possible stopping point. A search engine may resolve a narrow question on the results page, while a person with a more involved problem still needs to visit a website.

    Google’s stated view is that AI Overviews can filter low-value, single-fact visits while prompting people to search more frequently and in greater detail. That is a platform position, not proof that every publisher benefits. A lost click is still a lost opportunity unless the search creates some other measurable value for your brand.

    The practical change is to stop using total organic sessions as the only definition of growth. Evaluate four different outcomes:

    • Discovery: your pages appear for the questions and problems that matter to your audience.
    • Answer visibility: your brand, explanation, product, data, or page is represented when an AI answer is shown.
    • Qualified visits: people click because they need depth, proof, a tool, a comparison, or a next step that the results page cannot provide.
    • Business outcomes: those visits lead to the action the page was built to support, such as a signup, inquiry, purchase, or informed move to another page.

    This does not make clicks unimportant. A page does not become valuable merely because an AI system might summarize it. It means a click-through rate decline has more than one possible cause, and you should identify that cause before rewriting titles or adding pages.

    Start by labeling your important queries by the job they perform. A closed-answer query asks for a fact or definition. An exploration query helps someone understand a problem. A decision query compares options or constraints. An action query looks for a product, service, process, or implementation path. Closed answers are more exposed to instant resolution. Exploration, decision, and action queries give you more room to earn a meaningful visit, provided the page does more than restate a generic answer.

    Build a query map around complete problems

    An overhead strategy table shows blank tiles and glowing connections arranged around a three-dimensional problem-solving scene.

    AI-assisted search encourages people to express more of their situation in the query. Instead of reducing every topic to a short keyword, users can include their goal, constraints, experience level, and desired format. Google has observed longer, more conversational searches that describe the underlying need more clearly.

    Your keyword map should preserve that context. A broad term such as “schema markup” identifies a subject. A question such as “which schema should a service-area business use when it has no public storefront?” identifies a decision, a constraint, and the evidence the answer must contain. The second query is easier to turn into a useful content brief because it reveals what could make an answer wrong.

    Build each topic cluster from real language found in search performance data, site search, customer questions, sales conversations, support requests, and community discussions available to your team. For every meaningful query or prompt, record:

    • The exact question, including qualifiers rather than a cleaned-up head term.
    • The user’s likely stage: learning, evaluating, validating, or acting.
    • The constraint that changes the answer, such as business type, location, platform, audience, or implementation state.
    • The decision the person needs to make after receiving the answer.
    • The evidence or experience required to make the answer credible.
    • The page and section that should satisfy the need.
    • The next useful action you want the visitor to take.

    Do not turn every wording variation into a separate page. If several prompts have the same intent, require the same evidence, and lead to the same decision, they usually belong on one well-structured page. Split them only when the constraint materially changes the answer or when each audience needs a distinct path.

    Then inspect the live result for your priority prompts in a consistent setup. Record the exact query, search surface, date, location context, whether an AI answer appeared, which domains were cited, which brands were mentioned, and what conventional results remained visible. AI Overviews are not activated for every query, so testing a few broad keywords cannot tell you how an entire topic behaves.

    Treat this prompt set as a stable observation panel. Reuse the same important prompts when you review visibility, and add new ones only when customer language or search data reveals a genuinely different need. That gives you a comparable record instead of a collection of one-off screenshots.

    Make the page valuable after the instant answer

    The right response to AI answers is not to hide the answer deeper in the page. Give the reader a direct answer, then provide the judgment, evidence, and implementation help that a short synthesis cannot carry.

    A useful page can be built in layers:

    1. Answer the core question in plain language near the beginning.
    2. Name the conditions that would change the answer. This prevents an accurate general rule from becoming bad advice in a specific case.
    3. Explain the decision logic so the reader can apply the answer rather than merely repeat it.
    4. Provide evidence or utility that is difficult to replace with a generic synthesis: an original example, a documented process, a worked configuration, a template, a calculator, a comparison framework, or first-party data you genuinely possess.
    5. Offer the next action that fits the reader’s stage instead of forcing every visitor toward the same conversion.

    Use a replacement test during editing: if a generic answer box can reproduce the entire value of the page, the page is not finished. Add the constraint, evidence, or usable asset that a person needs after learning the basic answer. Do not add length for its own sake. More words do not create more value when they repeat the same conclusion.

    Machine readability matters, but it cannot rescue an undifferentiated page. Use descriptive headings, stable terminology, explicit relationships between entities, and internal links whose anchor text explains the destination. If you add JSON-LD, choose a valid type that accurately represents the page, keep names and other entity details consistent with visible content, and update the markup when the page changes. Structured data is a machine-readable description, not a relevance generator or a guarantee of inclusion in an AI answer.

    Credibility also has to be inspectable. Identify who created or reviewed the material when that identity helps the reader judge expertise. Link claims to the evidence you actually used. Distinguish observed results from editorial recommendations. Display a date when freshness affects the answer, not as decoration. Remove unsupported ratings, fabricated experience, and schema properties that are absent from the visible page.

    Mass-producing near-duplicate pages is especially weak in this environment. Google’s stated position is that generative AI has increased the volume of low-quality material while its ranking systems continue trying to suppress it. Whether those systems succeed in every result is a separate question. Your controllable advantage is to publish material that has a clear reason to exist: a different decision, better evidence, a useful tool, or a perspective grounded in real expertise.

    Diagnose the stalled layer before choosing a fix

    A technician examines a blockage inside one chamber of a transparent multi-stage pathway carrying streams of light.

    When organic search growth stalls, asking what to publish next is premature. First determine which part of the system stopped moving. Rankings, result-page behavior, content usefulness, conversion, and measurement can produce similar top-line charts while requiring completely different fixes.

    1. Validate the measurement. Confirm that analytics events, search reporting, consent behavior, and conversion definitions have not changed. A tracking break should not become an SEO project.
    2. Check technical access. Review indexing, robots directives, canonicals, redirects, rendering, internal links, and template changes on the affected pages.
    3. Segment the change. Break performance down by query group, page type, intent, device context, market, and brand versus non-brand demand where those dimensions are available. A sitewide total can hide a concentrated loss.
    4. Separate impressions from clicks. Falling impressions point you toward demand, coverage, indexing, or competitive visibility. Stable impressions with falling clicks point you toward the result-page environment, snippet appeal, or changed intent.
    5. Separate visits from outcomes. If qualified traffic is steady but conversions fall, inspect message alignment, page usability, the offer, and event tracking before changing the query strategy.
    6. Inspect representative results. Look for AI Overviews and other result features, note which needs they satisfy, and compare the remaining clickable results. Do this for the query groups that matter rather than whichever examples are easiest to find.

    Use the observed pattern to choose the first test:

    Observed signalStart by testingFirst useful action
    Impressions decline across established query groupsDemand, indexing, coverage, or competitive visibilityVerify technical access, then compare the affected queries and pages instead of rewriting every snippet.
    Impressions hold while clicks declineResult-page changes, instant answers, intent, or snippet appealInspect the live results, classify the lost queries, and strengthen both the search snippet and the page’s beyond-the-answer value.
    Visits hold while outcomes declineTracking, landing-page alignment, usability, or offer fitValidate events and compare each landing page with the promise and intent of its incoming queries.
    Important customer questions have no relevant visibilityContent coverage or insufficient evidenceRevise the best existing page or create a focused resource only when the question requires a materially different answer.

    Maintain a scorecard that matches those layers. Search performance data can show impressions, clicks, click-through rate, queries, and landing pages. A prompt observation log can show sampled AI-answer presence, citations, mentions, and competing domains. On-site analytics can show whether visitors continue to a useful next step or return. Business systems can show qualified inquiries, purchases, signups, or other outcomes where attribution is available.

    Keep the limits of each measure visible. Click-through rate without result-page context can mislead you. A brand mention without a citation may not create a visit. A citation may appear for a low-value prompt. A hand-checked prompt panel is a sample, not a complete census of AI visibility. Report the measures together so one flattering metric cannot conceal a broken path.

    Key takeaways for your next growth cycle

    • Classify important queries by the job they perform before assuming every lost click has equal value.
    • Map conversational prompts with their goals, constraints, required evidence, and next decisions intact.
    • Answer the core question early, then earn the visit with decision support, credible evidence, or practical utility.
    • Use valid, visible-content-aligned structured data to clarify meaning, not as a shortcut to rankings or AI inclusion.
    • Diagnose discovery, click capture, page usefulness, and conversion separately before choosing an intervention.
    • Measure search performance, sampled AI visibility, visit quality, and business outcomes in the same scorecard.

    Start with the query cluster most closely tied to a real audience decision. Record its current result environment, repair the page that should own the problem, and define the outcome you expect before making the change. Your next growth move should come from the failed layer you can see, not from a general fear that AI has made search traffic impossible.

    References


  • How to Turn AI Referral Traffic Into Bottom-Funnel Growth

    How to Turn AI Referral Traffic Into Bottom-Funnel Growth

    You may already see the awkward pattern: informational clicks are falling, AI assistants send a thin stream of referrals, and some conversions appear later under direct or branded search. If you judge that pattern with an organic traffic dashboard alone, the strategy can look weaker precisely when it is starting to influence revenue.

    Your job is not to replace every lost pageview. It is to publish the decision-stage answers that buyers and AI systems need, connect those answers to the rest of your site, and measure the journey beyond the first visible click.

    AI referrals are decision-assistance traffic, not replacement pageviews

    An informational search traditionally sent a person to several pages to assemble an answer. An AI interface can now do much of that assembly before the person visits a website. The resulting click is therefore more likely to represent validation, comparison, or purchase research than initial discovery.

    That changes the value of a session. A page that attracts thousands of definition-seeking visitors can produce less commercial movement than a comparison page attracting a much smaller group of people who are choosing between viable options.

    There is evidence that this difference can show up in conversion behavior, but it should not be turned into a universal benchmark. In an Adobe analysis covering more than one trillion visits to U.S. retail websites, AI-referred visits in March converted 42% better than non-AI visits. They also spent 48% more time on site and viewed 13% more pages per visit. A year earlier, AI visits in the same analysis had been 38% less likely to convert.

    Those figures describe U.S. retail traffic, not every market, business model, or AI platform. A retail purchase is not a B2B demo request, and a known brand is not in the same position as an unfamiliar one. Use the finding to form a hypothesis: AI referrals may be lower in volume but further along in the decision process. Then test that hypothesis against your own landing pages, conversions, lead quality, and sales outcomes.

    Key takeaways

    • Judge AI referrals by buying intent and conversion quality, not by whether they replace lost informational traffic.
    • For a pipeline-focused program, consider assigning 60% to 80% of new content effort to mid- and bottom-funnel needs, then adjust from your results.
    • Build comparison content with a disclosed method, consistent criteria, specific limitations, and recommendations for distinct buyer situations.
    • Keep top-funnel content, but give each useful page a clear route into a relevant evaluation or product decision.
    • Measure visible AI referrals alongside citations, branded search, direct visits, qualified leads, and total conversions.

    Rebalance content around the questions that delay a purchase

    A buyer stands among several symbolic decision stations as their branching research paths merge into one clear route toward a product pedestal.

    The strategic shift is not simply from educational articles to product pages. A product page explains what you sell. Bottom-funnel content helps a buyer decide whether it is the right choice, how it compares, where it fits, and what tradeoffs they would accept.

    Start with the questions that appear after a buyer understands the category:

    • Which options are suitable for my industry, company size, use case, or operating constraint?
    • How do two shortlisted products differ on the criteria that matter to me?
    • What are the strengths and limitations of each option?
    • Which product is the better fit for a specific situation?
    • What evidence would let me remove this option from my shortlist?
    • What should I verify before requesting a demo, starting a trial, or making a purchase?

    These are decision tasks, not just keywords. That distinction matters because buyers can express the same task through conventional search, a conversational AI prompt, a follow-up question, or a branded query after seeing a recommendation elsewhere.

    Audit your coverage by task. List your priority products, use cases, buyer groups, and serious alternatives. Then mark whether you have a useful answer for each relevant combination. Typical gaps include:

    • A broad category list with no version for a high-value industry or use case.
    • A product comparison that names features but never explains who should choose which option.
    • An alternatives page that treats every alternative as interchangeable.
    • A use-case page that makes claims without screenshots, expert explanation, or product evidence.
    • An educational page that attracts the right audience but offers no logical next step.

    Prioritize gaps where three conditions overlap: the question occurs close to a purchase, your product has a legitimate reason to be considered, and you can support the answer with specific evidence. A high-intent phrase is not useful if the resulting page would be evasive, generic, or unsupported.

    For teams measured on leads or revenue, a practical starting point is to put 60% to 80% of content effort into mid- and bottom-funnel work. Treat that as a portfolio choice to test, not a law. The right allocation depends on how complete your educational foundation is, how many decision-stage gaps remain, and whether your business has credible evidence for the pages it wants to publish.

    Build comparison pages that remain useful after the click

    A weak comparison page is an advertisement wearing an editorial title. It places the publisher’s product first, assigns vague praise to every option, hides meaningful drawbacks, and ends with an unrelated sales button. Buyers notice the bias. An AI system also has little precise material to reuse because the page never makes a bounded, supportable recommendation.

    A stronger page defines its scope, applies one review method to every option, and makes the tradeoffs visible. A construction-specific time-tracking comparison built this way became a frequently referenced page in LLM responses within weeks and outperformed a dozen earlier informational pages in pipeline impact. That is one documented outcome, not a promise that every listicle will perform the same way. The transferable lesson is the structure: answer a real purchasing question with enough specificity to guide a decision.

    A practical comparison-page blueprint

    1. Define the buyer and decision. State the industry, use case, operating constraint, and type of purchase covered. “Best time-tracking software” is broad; “best time-tracking software for construction” establishes a meaningful evaluation context.
    2. Publish the selection method. Explain how options qualified for inclusion and which criteria were applied. If you cannot explain why a product appears, the list will feel arbitrary.
    3. Give the short answer early. Identify which option fits which situation. Do not force a ready-to-buy reader through a long category lesson before providing the decision map.
    4. Use one comparison framework. Evaluate every option against the same relevant fields. Suitable columns might include best-fit use case, important strengths, material limitations, and the factor a buyer should verify.
    5. Separate fact from judgement. Product capabilities should be factual and current. Recommendations should show the reasoning that connects those facts to a buyer’s situation.
    6. Cover limitations directly. A useful limitation tells the reader who may be poorly served and why. Empty phrases such as “may not suit everyone” add no decision value.
    7. Recommend by situation. End with conditional guidance rather than a single universal winner. Different constraints can produce different correct choices.
    8. Place the next step in context. Put a demo, trial, pricing, or product link beside the point where it becomes useful. Do not rely on one generic call to action at the bottom.

    Credibility rules for including your own product

    You can include your own product when it genuinely meets the selection method. Disclose the relationship plainly, subject it to the same criteria, and resist the urge to make it the winner for every buyer. If an alternative is better for a particular situation, say so.

    Use screenshots, named features, and expert explanations where they help a buyer verify a claim. Keep each product section structurally consistent. A reader should not receive detailed drawbacks for competitors and only promotional language for your product.

    Write recommendations as complete, bounded statements. “Option A is the better fit for teams that need [capability], while Option B is more suitable when [different constraint] matters” is more useful than “Option A is best overall.” The bounded version exposes the reasoning, gives the buyer a usable distinction, and is less likely to be quoted outside its intended context.

    Update the page when the underlying facts change. A polished comparison built on stale capabilities is still unreliable. Record the last substantive review date, recheck each option using the published method, and remove claims you can no longer support.

    Give top-funnel content a direct route to the decision

    Top-funnel content still has an important job. It can establish the concepts a buyer needs, complete a topic cluster, attract relevant links, and pass internal link equity toward decision-stage pages. What has changed is the economics of publishing generic explanations that an AI result can answer without a click.

    Do not delete useful educational pages merely because their traffic has softened. Start with the pages that still reach the right audience and give each one a deliberate handoff:

    1. Identify the next decision. After reading the page, what question would a qualified buyer naturally ask? That question should determine the destination link.
    2. Add evidence where the subject touches your product. A relevant screenshot, implementation detail, or expert observation can turn an abstract explanation into practical understanding.
    3. Link to the closest evaluation page. Send the reader to a use-case comparison, alternatives page, product capability, or selection checklist rather than an unrelated homepage.
    4. Write a contextual call to action. Explain why the destination is useful at that moment. “Compare the options for construction teams” carries more meaning than “Learn more.”
    5. Place the handoff where the need appears. A relevant next step can sit beside the section that creates it. It does not have to wait until the final paragraph.
    6. Preserve the informational answer. The page should still solve the question that earned the visit. Turning every paragraph into a pitch will weaken trust and usefulness.

    This creates a simple content path: education establishes the problem, mid-funnel material frames the available approaches, and bottom-funnel material supports the choice. Internal links should reflect that progression in both directions. The comparison page can link back to definitions or methods a reader needs, while educational pages can point forward when the reader is ready.

    Specificity is the filter. If a top-funnel page merely repeats a general answer already available everywhere, adding a product button will not rescue it. Give the page a distinct expert perspective, a concrete example, a useful framework, or original product evidence before asking it to support a commercial journey.

    Measure the influence that last-click analytics misses

    A glowing thread connects an AI referral to several visits and a final purchase, while a narrow lens highlights only the last step and a wider lens reveals the full journey.

    An AI-assisted journey can cross several channels. A buyer sees your brand or page in an AI answer, does not click, returns through a branded search, and converts. Another buyer clicks an AI citation, leaves, and later returns directly. Standard acquisition reports may credit those outcomes to organic brand traffic or direct traffic even though AI visibility helped create the demand.

    Start by isolating the AI referrals you can see. In GA4, create a segment or channel definition that matches the AI referral domains actually present in your data. A regular-expression rule is useful because it can group multiple sources, but maintain the domain list instead of treating it as permanent. Validate the rule against raw source values so an overly broad match does not pull unrelated referrals into the channel.

    Break that segment down by landing page and intent. Mixing an educational visit with a product-comparison visit hides the question you need answered. Compare like with like: AI-referred visits to bottom-funnel pages against other visits to those same pages, using the same conversion definition.

    Your scorecard should combine directly observed traffic with directional indicators of influence:

    SignalWhat it can tell youHow to act on it
    AI referral sessions by landing pageWhich pages receive visible visits from AI platformsProtect, update, and expand pages attracting relevant evaluators
    Conversion rate by landing-page intentWhether decision-stage visits produce more commercial action than informational visitsAllocate effort according to qualified outcomes, not aggregate sessions
    Engagement and product-page progressionWhether visitors continue evaluating after arrivalImprove the page’s decision support or contextual handoff where progression stalls
    LLM citation frequency for a stable prompt setWhether your brand or page appears in relevant answers, even without a clickReview the cited passages and close factual or use-case gaps
    Branded search and direct-traffic trendsWhether discovery may be resurfacing through channels that obscure the first touchTreat the movement as directional evidence and examine it beside publication activity
    Qualified leads, purchases, and pipelineWhether the program contributes to business outcomesFavor pages and topics that produce valuable customers rather than raw volume

    None of the directional signals proves causation on its own. Direct traffic can move for many reasons, and a branded search increase can reflect activity outside content. Use publication and update dates as annotations, compare several signals together, and avoid assigning all subsequent growth to one page.

    Lead capture can close part of the gap. Preserve the original landing page and referral source where available, then pair them with a simple self-reported discovery field. A buyer who says an AI assistant introduced the brand gives you information that a last-click field may have lost. Keep self-reported and system-attributed sources separate so one does not overwrite the other.

    Report the channel in business language. Instead of stopping at “AI referrals increased,” show which decision-stage pages received those visits, how the visitors behaved, how many qualified conversions followed, and whether brand discovery moved in the same period. Stable or lower total traffic can still support a healthier strategy if conversion quality and pipeline improve.

    Your next move is small and concrete: choose one purchase-stage question that repeatedly blocks a decision. Build the most complete, candid answer you can support. Connect your strongest relevant educational pages to it, establish the measurement baseline, and watch referrals, citations, branded discovery, and qualified conversions together. Once that loop produces a useful signal, repeat it for the next decision your buyers need help making.

    References


  • AI Search Visibility When Referrals and Rankings Diverge

    AI Search Visibility When Referrals and Rankings Diverge

    If your organic sessions are falling while your brand still appears in AI answers, you do not have one visibility problem. You have at least three: whether machines can access your content, whether answer systems select it, and whether people visit after seeing it.

    Those stages need different measurements and different fixes. Separate them, and you can tell whether to improve a page, investigate a ranking change, strengthen attribution, or restrict a crawler before it consumes more value than it returns.

    Key takeaways

    • Measure content access, AI mentions and citations, referral sessions, and business outcomes separately. A lost click is not automatically lost visibility.
    • Diagnose impressions, rankings, click-through rate, and AI referrals before editing content. Ranking loss and referral loss can happen together, but they are not the same failure.
    • Give answer systems a clear, supportable answer while giving people a practical reason to visit, such as a workflow, template, decision tool, original data, or implementation detail.
    • Classify bots by identity and business role. Allow, rate-limit, license, challenge, or block them according to their value, cost, and contractual status.

    Build a visibility ledger that follows the whole journey

    An isometric table shows a document moving through connected access, selection, citation, and visitor stages.

    Sessions used to serve as a rough proxy for search visibility because discovery commonly led to a results page and then a click. An AI interface can now retrieve a page, use its information, mention its brand, cite its URL, and still satisfy the user without sending a visit. One traffic graph cannot show which of those events occurred.

    Use a ledger with three distinct stages:

    • Access: a search crawler, training crawler, or real-time fetcher can retrieve the page.
    • Selection: an answer system uses the information, mentions the brand, or links to the page.
    • Referral and value: the user visits, engages, subscribes, generates a lead, or completes another meaningful action.

    The distinction matters because the gap can be severe. Akamai measured application-layer traffic across websites, apps, and APIs from July through December 2025 and found AI bot activity up 300% during 2025. Within that analysis, AI-chatbot referrals delivered about 96% less traffic than traditional search, while only about 1% of users clicked sources cited in AI answers. Treat those figures as directional evidence, not universal benchmarks: your result will depend on your audience, query mix, business model, and the interfaces that expose your content.

    LayerRecordWhat a change can indicateFirst response
    Traditional search exposureImpressions, query, landing page, market, and average positionChanges in demand, ranking, eligibility, or query mixSegment the loss before changing pages
    Traditional search referralClicks, click-through rate, sessions, and landing-page outcomesA difference between being shown and being chosenInspect result presentation, search features, intent, and page promise
    AI selectionAccurate brand mentions, linked citations, cited URLs, and factual errors across a fixed prompt setWhether the brand is represented and whether an owned page receives attributionCheck entity clarity, answer structure, evidence, and page accessibility
    AI referralRaw referrer, channel, landing page, engagement, conversion, and revenue where availableWhether observed visibility produces visits and business valueImprove the post-answer reason to visit and the landing experience
    Machine-access costVerified agent identity, requests, pages fetched, bandwidth, cache use, and origin loadWhether retrieval consumes infrastructure without a corresponding benefitAllow, rate-limit, license, challenge, or block by bot class

    For AI selection, build a repeatable prompt panel rather than collecting convenient screenshots. Include the questions that matter at each stage of your customer’s decision, then preserve the exact prompt, interface, language, market, date, response, mention, citation, and cited URL. If you operate across languages or countries, maintain separate panels; visibility in one market does not establish visibility in another.

    1. Choose prompts from real search queries, support questions, sales objections, and tasks associated with your important pages.
    2. Run the same prompts under comparable conditions. Changing the wording and the interface at the same time makes the result difficult to interpret.
    3. Record an accurate mention separately from a linked citation. A brand can be visible without receiving an owned link.
    4. Check whether the answer represents the brand, product, author, and claim correctly. An inaccurate mention is not a visibility win.
    5. Annotate content releases, schema changes, crawler-policy changes, major deployments, and confirmed search updates beside the results.

    Create simple rates from this ledger: prompts with an accurate mention divided by prompts checked; prompts with an owned citation divided by prompts checked; and AI-referred conversions divided by identifiable AI-referred sessions. Keep the underlying counts beside every rate. A perfect percentage from a tiny or changing prompt set can create more confidence than the measurement deserves.

    Normalize recognizable AI referrers into a reporting channel, but preserve the raw referrer and landing page. Do not depend on campaign parameters for links you do not control. Some interfaces expose little or no useful referral information, so analytics should be treated as the observable portion of AI traffic, not a complete census of AI influence.

    Separate ranking loss from click loss before editing content

    A traffic decline near an algorithm update invites a quick rewrite. That can destroy useful evidence and change the page before you know what failed. Start by marking the rollout window. The March 2026 Google core update ran from March 27 through April 8, finishing after 12 days and 4 hours. A comparison that mixes rollout days with stable periods cannot cleanly separate the before and after states.

    1. Annotate the confirmed update window and every important site change, including migrations, template releases, internal-link changes, rendering changes, and crawler rules.
    2. Compare matched periods outside the rollout. Account for normal seasonality, promotions, and demand changes that affect the same queries.
    3. Segment by query group, page type, directory, market, and device. Sitewide averages can conceal a concentrated loss in one template or topic.
    4. Inspect impressions, position, clicks, and click-through rate together. Then compare those patterns with your sampled AI visibility and AI-referral data.
    5. Review the affected page group only after the failure mode is visible. Preserve an export or snapshot before making material changes so you can evaluate and reverse them.

    Use the pattern, not one metric, to choose the next action:

    • If impressions and positions decline for the same queries and pages, investigate a ranking, relevance, eligibility, or demand problem. Do not assume that a lower sitewide average tells you which one.
    • If impressions remain broadly stable while clicks and click-through rate decline, the result is still being shown but fewer searchers are choosing it. Inspect the result-page features, title and snippet promise, intent fit, and competing ways the query is answered.
    • If traditional search remains stable while sampled AI citations or identifiable AI referrals decline, check machine access, citation selection, brand ambiguity, and measurement coverage before rewriting the page.
    • If sessions decline but qualified leads, subscriptions, or revenue do not, quantify the commercial effect before setting a traffic-restoration target. Not every lost informational click has the same value.
    • If several layers decline at once, keep separate workstreams. A content review cannot repair broken bot access, and a crawler rule cannot make an unsatisfying page more useful.

    Google’s standing position is that a core-update decline does not necessarily mean something is wrong with the site, and meaningful recovery may depend on a later update. That is a reason to avoid panicked reversals, not a reason to wait passively. Review whether affected pages deliver helpful, reliable, people-first information, especially where the page promise and the actual answer have drifted apart.

    Create pages that can be cited and still deserve a visit

    Trying to withhold the basic answer is a poor response to zero-click search. It frustrates readers and leaves answer systems with weaker material to interpret. State the answer clearly, support it, and make the rest of the page valuable after the answer is known.

    A citation-ready, visit-worthy page usually needs these layers:

    • A decisive answer: address the page’s main question directly instead of making the reader extract it from a long preamble.
    • Scope and qualifiers: state the country, language, platform, version, date, audience, or conditions that change the answer. A technically correct statement can still mislead when its scope is hidden.
    • Evidence: connect important claims to their originating authority, underlying data, or documented method. Distinguish a fact from an inference or editorial recommendation.
    • Entity clarity: use consistent names for the organization, product, author, location, and service. Explain relationships that a reader should not have to infer from branding alone.
    • A decision layer: show trade-offs, applicability, exclusions, and common misreadings so the reader can decide whether the answer fits their situation.
    • An action layer: provide the procedure, checklist, template, calculator, original data, implementation detail, or troubleshooting path that helps the reader complete the task.

    This structure makes the central claim easy to identify without turning the page into a disposable definition. The answer earns selection; the decision and action layers earn the visit.

    JSON-LD can clarify what a page represents, but it is not a referral strategy and it does not guarantee selection in an AI answer. Use the schema type that matches the visible content, connect related entities consistently, and validate the markup after publishing. Do not place claims, reviews, authorship, dates, or relationships in structured data that the page itself does not support.

    Apply the same discipline to freshness. Show a meaningful update date when the substance changed, identify version-dependent instructions, and remove contradictions between the page, its metadata, and its structured data. Changing a date without revising stale information creates a freshness signal for the editor, not new value for the reader.

    Before consolidating or unpublishing a weak page, check its inbound links, internal links, ranking queries, citations, conversions, and role in a topic cluster. Preserve a copy and plan the appropriate destination before removing a URL. A careless cleanup can erase authority or break an existing citation even when raw sessions look unimportant.

    Turn AI crawler access into an explicit business policy

    A person controls open, metered, and closed gates between geometric crawler machines and a secure digital archive.

    More machine access does not automatically produce more discovery, attribution, or revenue. It can also increase server and CDN costs. The 300% rise in AI bot activity observed during 2025 makes bot classification an operating issue, not merely a security log to review after something breaks.

    Start by separating training crawlers, which collect material for model development, from real-time fetchers, which retrieve current content to answer a live request. Their timing, potential value, and commercial relationship differ. A single allow-or-block rule ignores those differences.

    Bot classPossible business rolePolicy optionsMain risk to check
    Search or discovery crawlerMakes pages eligible for a discovery surfaceVerify and allow under controlled limitsBlocking can remove a path to visibility
    Authenticated licensed agentAccesses content under agreed commercial termsAllow only within authenticated scope and limitsUnverified requests may exceed the agreement
    Real-time answer fetcherRetrieves current information for an immediate answerAllow, rate-limit, or license according to measured value and costFresh content may be consumed without useful attribution or referral
    Training crawlerCollects content for model developmentAllow, block, or license according to rights and commercial policyDirect referral value may be weak or unobservable
    Unknown or abusive scraperNo verified legitimate roleChallenge, rate-limit, block, or cautiously tarpitSpoofed identities and false positives can misclassify traffic

    A user-agent string is a claim, not proof. Where an operator publishes a verification method, use it. Keep agent identity, request behavior, targeted URLs, bandwidth, origin load, and any referral or licensing value in the same review. That turns a vague bot debate into a policy decision supported by observable costs and benefits.

    1. Observe before enforcing. Establish which agents request which page groups and how much infrastructure they consume.
    2. Verify identity. Do not grant privileged access or apply a punitive rule solely from a self-declared bot name.
    3. Assign a role. Record whether the agent supports discovery, live answering, training, a licensed relationship, or no recognized purpose.
    4. Choose the least disruptive effective control. Options include scoped access, caching, rate limits, authentication, challenges, blocking, and carefully tested tarpitting.
    5. Stage material changes with a rollback path. Watch crawl activity, indexation, sampled AI citations, referrals, server load, and user errors after enforcement.
    6. Review licensing and content-rights terms with appropriate legal counsel before charging for access or signing an agreement. A crawler configuration cannot determine ownership or contractual rights.

    Robots directives can communicate preferences to compliant agents, but they are not authentication or an access-control wall. Enforce sensitive or paid access with controls that can identify and authorize the requesting agent. If you use tarpitting, apply it only after careful classification: deliberately slowing the wrong traffic can harm legitimate discovery or user-facing performance.

    Emerging approaches such as Know Your Agent identity verification and TollBit pay-per-crawl access are intended to turn retrieval into an authenticated, manageable transaction. Treat that model as an option to evaluate, not guaranteed replacement revenue. The commercial case still depends on enforceable identity, demand for your content, contract terms, delivery cost, and the value of any visibility you give up by restricting access.

    Your next move should come from the first broken link in the chain. Build the ledger, mark known update and deployment dates, test the questions that matter, and classify the agents consuming your pages. Then change one layer at a time and keep a rollback path. That is how you protect visibility without mistaking every lost click for a lost audience.

    References

  • How to Measure AI Agent Traffic and Attribute Conversions

    How to Measure AI Agent Traffic and Attribute Conversions

    Your analytics dashboard may show a human arriving at checkout while missing the machine that found the product, compared the options, and initiated the journey. It may also show nothing at all when an agent completes an action without running your client-side analytics code.

    You can close that gap, but not with a new referral channel alone. Reliable AI agent attribution starts in server and CDN logs, continues through first-party action events, and ends with an attribution model that distinguishes direct execution from assistance and unlinked automation.

    Key takeaways

    • Measure AI agents at the HTTP request layer. A request that does not execute your analytics script cannot create a normal browser event.
    • Separate training crawlers, real-time retrieval systems, and task-performing agents. They represent different intent and should not share one conversion rate.
    • Do not trust a user-agent string by itself. Combine it with published network information, request behavior, authentication state, and your own event data.
    • Use distinct attribution states for agent-executed, agent-assisted, discovery-only, and unresolved activity. Do not force uncertain traffic into a conversion channel.
    • Instrument forms, account actions, carts, and orders on the server. Page requests show access; confirmed business events show outcomes.

    Classify traffic by the job the machine is doing

    An automated request is not automatically a prospective customer. A model-training crawler collecting material, an answer engine retrieving a current page, and an agent submitting a form can all request the same URL. Their commercial meaning is entirely different.

    This distinction matters because machine activity is growing faster than human activity. HUMAN Security measured more than a quadrillion interactions from 2022 through 2025. In that dataset, automated traffic increased 23.5% in 2025 while human traffic increased 3.1%. AI-driven traffic rose 187%, and activity associated with AI agents and agentic browsers rose by nearly 8,000%. Those figures come from aggregated, anonymized customer data, so treat them as a market signal rather than a forecast for your site.

    Traffic classLikely jobWhat to measureAttribution treatment
    Training crawlerCollect content for later model developmentPages fetched, bytes served, crawl frequency, response statusContent access, not a visit or conversion
    Real-time retriever or scraperFetch current information for an answer or comparisonLanding routes, freshness-sensitive pages, response success, repeat retrievalDiscovery activity unless a handoff can be observed
    Task-performing agentNavigate or take an action for a userWorkflow steps, authenticated state, form or cart events, confirmed outcomeDirect or assisted attribution when the evidence supports it
    Unverified automationUnknown, mislabeled, or potentially hostile activityBehavior pattern, network identity, rate, errors, security challengesKeep unattributed until verified

    Training crawlers still represented 67.5% of measured AI traffic, while real-time scrapers grew by nearly 600% in 2025. That mix explains why a large increase in AI-labelled requests does not necessarily produce leads or revenue. Start by assigning each request to a functional class; calculate commercial performance only for traffic capable of participating in a user journey.

    Task-performing agents deserve special attention because their behavior is moving deeper into sites. In 2025, 77% of observed agentic activity occurred on product and search pages, nearly 9% involved account-level interactions, and more than 2% reached checkout. If you monitor only editorial URLs, you will miss the requests closest to a business outcome.

    Create at least two classification fields in your data: agent_type for the machine’s apparent job and verification_status for the strength of the identification. Keep the values independent. A request can look transactional while its claimed identity remains unverified.

    Build an evidence chain from request to outcome

    A continuous glowing trail links an incoming machine request to a gateway, server records, an action event, and a completed purchase.

    Attribution becomes credible when you can follow an agent from an incoming request to a server-confirmed action. A dashboard label such as “AI traffic” is not enough. You need a chain of evidence that survives redirects, browser changes, authentication, and the absence of JavaScript events.

    Capture the request before classifying it

    Preserve the raw evidence in your CDN, load balancer, or application logs before a bot filter removes it. For each relevant request, capture:

    • A UTC timestamp and a unique request ID.
    • The HTTP method, normalized route, response status, and response size.
    • The full user-agent value as received, plus the parser’s normalized result.
    • The source network information needed for verification.
    • Referrer and origin headers when present, without treating their absence as proof of anything.
    • Whether a first-party session was present or created.
    • A pseudonymous account or customer identifier when the request was legitimately authenticated.
    • The resulting application event, such as search performed, form accepted, cart updated, or order confirmed.

    Do not log authorization headers, passwords, payment details, complete form bodies, or sensitive query-string values for the sake of attribution. Strip or tokenize sensitive fields before they reach the analytics store. The useful connection is between a request identifier and a confirmed event, not between a marketing report and a copy of the user’s private data.

    Instrument the business action on the server

    A page view tells you that an agent requested a page. It does not tell you that a form was accepted, an account changed, or a payment completed. Emit a first-party server-side event only after the application confirms the action.

    Give that event its own ID and record the initiating request ID, event time, action type, outcome, and any internal transaction or lead identifier. If the event represents money, use the same finalized value your order system recognizes. Failed submissions and abandoned workflows belong in diagnostic reporting, not completed-conversion totals.

    Make an agent-to-human handoff observable

    Many useful agent journeys will not end inside the agent. The machine may find a product or prepare a configuration, then send the user into a browser to review, authenticate, or pay. Standard last-click attribution can give the browser all the credit because the earlier agent request had no ordinary campaign parameter or client-side session.

    When you control the handoff, attach an opaque, first-party handoff token to the destination URL. The token should identify a journey record, not expose an email address, prompt, account number, or other personal data. Expire it, prevent it from granting access, and associate it with the eventual conversion only after your server validates it. If the user is already authenticated, an internal pseudonymous account key can provide the connection without placing identity in the URL.

    If you cannot observe a deterministic handoff, do not manufacture one from matching timestamps or similar page paths. You may analyze those patterns in aggregate, but label the result as discovery influence rather than an assisted conversion.

    Recognize Google-Agent without weakening security

    An abstract automated agent passes through layered identity checks at a secure gateway while unverified requests are blocked.

    Google-Agent creates a useful distinction between continuous crawling and a request made while an AI system performs a user-initiated task. Google introduced it for agents hosted on its infrastructure, including experimental systems such as Project Mariner, and provided network ranges for desktop and mobile agent activity.

    That identity gives you a better starting signal, not a substitute for authentication. User-agent strings are supplied by the requester and can be copied. Never allow an account action, bypass a challenge, or relax a security rule solely because a request calls itself Google-Agent.

    Use confidence-based verification

    Apply the same verification pattern to Google-Agent and any other named agent:

    1. Match and preserve the claimed user-agent identity.
    2. Compare the source with the provider’s published network information and keep that information current.
    3. Check whether the request pattern is consistent with the claimed function, including the routes, methods, timing, and workflow sequence.
    4. Record the result as verified, probable, or unverified rather than reducing all three states to a boolean bot flag.
    5. Apply normal authorization, rate limiting, abuse detection, and transaction controls regardless of the identity label.

    This approach is more defensible than a single allowlist. It also reflects how large-scale AI traffic was classified: user-agent strings were combined with infrastructure signals and activity characteristics because self-reported bot identities do not capture every AI-driven request reliably.

    Test the paths that matter

    Review your CDN and web application firewall logs for named agents before changing any rule. Then test product search, detail pages, forms, sign-in, account functions, cart operations, and checkout with non-production accounts and non-chargeable test transactions where your systems support them.

    Look for redirects that loop, challenges that cannot be completed, required state that disappears between requests, and successful browser screens backed by failed server actions. Keep intentional security denials in place. The goal is to remove accidental incompatibility, not to give automated clients a privileged route into sensitive workflows.

    Report agent contribution without false precision

    Your reporting should tell operators what happened and tell decision-makers how certain the attribution is. One blended “AI conversions” number cannot do both.

    Use four mutually exclusive outcome states:

    • Agent-executed: A verified or explicitly qualified agent request is linked to a server-confirmed conversion that the agent performed.
    • Agent-assisted: An observable first-party handoff or authenticated journey connects agent activity to a later human conversion.
    • Discovery-only: An agent retrieved relevant content, but no deterministic connection to an individual outcome exists.
    • Unresolved automation: Automation was detected, but its identity, purpose, or relationship to an outcome remains uncertain.

    Do not add agent-executed and agent-assisted credit if they describe two stages of the same conversion. Keep a deduplicated conversion ID, choose a primary status, and retain the touch sequence separately for analysis.

    Your operational dashboard should cover three layers. The access layer needs request volume by agent type, verification state, route group, response status, and security disposition. The workflow layer needs starts, successful steps, failures, and confirmed completions for each key action. The business layer needs deduplicated leads, orders, revenue where applicable, and the four attribution states above.

    Choose an assistance window that reflects your actual buying cycle and publish that rule beside the metric. There is no defensible universal window in the available evidence. A short handoff into checkout and a long enterprise evaluation should not inherit the same arbitrary assumption.

    Establish the baseline even if named-agent volume is initially small. A rise in training access may affect infrastructure cost and content-control decisions without changing revenue. A rise in verified product-search and account activity deserves workflow testing. Repeated checkout attempts with no confirmed outcomes point to a technical or security investigation, not automatically to weak demand.

    Start with one path that matters commercially: discovery, a product or service page, and its next meaningful action. Join the request logs to one server-confirmed outcome, preserve uncertainty as an explicit field, and make that narrow chain trustworthy before expanding it across the site. That gives you a measurement system you can extend as agents become more capable, without rewriting history around traffic you never truly identified.

    References


  • SEO After the Click: Winning AI Search and Agent Traffic

    SEO After the Click: Winning AI Search and Agent Traffic

    You can rank first and still lose the recommendation. A buyer asks an AI assistant for a shortlist, gets a synthesized answer, and never reaches the search result where you lead. Your competitor appears because its name, category, capabilities, and reputation are easier to retrieve and corroborate across the web.

    That does not make SEO obsolete. It changes the job. You still need pages that rank, but you also need a brand that AI systems can identify, trust, describe accurately, and use when helping someone make a decision.

    Key takeaways for AI search and agent traffic

    • Keep investing in technical SEO, content quality, and organic rankings. They support retrieval even when the final answer appears somewhere other than a conventional results page.
    • Give every important product, service, person, and claim one clear source of truth on your site. Make your schema markup and JSON-LD agree with the visible page.
    • Build independent corroboration. Repeated claims on your own domain are messaging; consistent mentions across credible publishers and communities create consensus.
    • Audit ChatGPT, Perplexity, Gemini, and Google AI Overviews with the questions customers actually ask. Record accuracy, citations, competitors, and whether your brand appears at all.
    • Separate AI referrals, brand mentions, and agent requests in your reporting. A crawler request is infrastructure activity, not proof of attention or revenue.

    The optimization target has split into three outcomes

    Three paths from one digital foundation lead toward a human visitor, an abstract search result, and an autonomous agent retrieving information.

    Traditional search optimization concentrated on discoverability, ranking, and the click. AI-mediated discovery adds two more requirements: corroboration and actionability. A useful strategy addresses all three instead of renaming ordinary SEO as GEO and leaving the workflow unchanged.

    AI can make structured technical work faster, but automation still depends on clean data, precise instructions, expert review, and strategic judgment. Your advantage will not come from producing more machine-written pages than everyone else. It will come from making better decisions about which facts deserve to be published, how they should be represented, and where they need independent support.

    Retrieval: can the system find and understand the right page?

    Create one authoritative page for each decision-critical subject. A service page should state what the service is, who it is for, what problem it addresses, where it is available, and what its important limitations are. An expert profile should use the same name, role, and area of expertise that appear on the content attributed to that person.

    Use stable language for your category. If the homepage calls you an AI visibility platform, a product page calls you an answer marketing suite, and an external profile calls you an SEO automation tool, a machine has to decide whether those descriptions refer to the same thing. Choose a primary category, explain adjacent terms, and use that relationship consistently.

    Treat schema markup and JSON-LD as a map of facts that a visitor can verify on the page. Markup should reinforce identity, relationships, authorship, and the subject of the page. It should not contain a more flattering or more complete version of the business than the visible content does. Structured data can reduce ambiguity, but it cannot manufacture third-party trust or guarantee inclusion in an AI answer.

    Do not confuse a carefully written title with control over the final interface. Google has tested AI-driven headline rewrites in search, so your title and headings must communicate the subject clearly even when the displayed wording changes. Optimize the underlying meaning, not only the snippet you hope to see.

    Corroboration: can the system verify the claim elsewhere?

    Your website can establish what you say about yourself. It cannot independently prove that customers, specialists, publishers, and communities recognize you in the same category. AI systems that synthesize answers can compare multiple sources, so a claim supported across independent domains is more defensible than a claim repeated across several pages you control.

    This is why rankings and AI visibility can diverge. A page may perform well in a conventional result while the brand behind it remains absent from synthesized recommendations. The missing ingredient is often not another keyword variation. It is distributed evidence.

    Actionability: can an assistant help the user decide what to do?

    An agent may need more than a persuasive description. It may be comparing price, quality, suitability, availability, prerequisites, or efficiency. Those decision facts should be explicit, current, and easy to distinguish from promotional claims.

    • State what the offering does and what it does not do.
    • Name the customer, use case, geography, or prerequisite that determines fit.
    • Publish current pricing when it is genuinely public. If pricing requires a quote, explain the pricing model and the information needed to obtain one.
    • Use consistent labels and units when presenting plans, features, limits, or performance evidence.
    • Give the user a clear next step on the same page: buy, book, apply, request a quote, check availability, or read the relevant documentation.

    These details help humans as much as machines. The difference is that an agent may discard a vague brand claim before a person ever sees it. As automated comparison grows, brand familiarity alone may be a weaker shortcut than a clear match on price, quality, and suitability.

    Build consensus beyond your own domain

    Retrieval-augmented systems assemble context from material they can find and then generate an answer from that context. When multiple credible sources associate the same entity with the same category or capability, the repeated relationship becomes easier to use. When your site is the only place making the connection, your brand looks like an unsupported outlier.

    The gap between rankings and citations can be substantial. One reported estimate places approximately nine out of ten pages cited by ChatGPT outside the top 20 organic results. Treat that figure as a directional warning rather than a universal rule: a first-page position does not automatically confer visibility in every AI system, and an AI citation does not require a top-20 ranking in every case.

    Start with a claim inventory. For every claim that could affect selection, write down the exact proposition you need the market to understand:

    • Identity: the brand, product, person, or organization being discussed.
    • Category: the primary market or problem to which the entity belongs.
    • Fit: the customer, situation, or constraint for which it is appropriate.
    • Capability: the outcome it can produce, with material limits attached.
    • Evidence: the data, method, example, credential, or customer experience that supports the capability.
    • Currency: the date, edition, plan, location, or version to which a changeable fact applies.

    For each proposition, mark where it appears on your site and where an independent source supports it. A capability mentioned on six owned pages still has only owned support. A trade publication, podcast, customer discussion, expert quotation, industry directory, or community recommendation adds a different kind of evidence.

    Links remain useful, but they are not the only signal worth pursuing. Unlinked brand mentions and diverse publisher coverage can also strengthen entity recognition. The practical implication is that digital PR, expert participation, and reputation work now belong inside the search strategy rather than beside it.

    The strongest consensus assets give other people a reason to refer to you. Original data, a proprietary survey, a transparent methodology, a useful public tool, or a genuinely qualified expert can earn citations without requiring every mention to repeat a marketing line. Make the underlying evidence easy to inspect and the responsible person easy to identify.

    Communities require a different approach. Answer the actual question, disclose your relationship to the brand, and accept that the product may not be the right recommendation. Planted praise and repetitive link drops can create reputation problems rather than consensus. A natural recommendation from an established participant is valuable precisely because you cannot manufacture it on demand.

    Consistency does not mean forcing every publisher to copy your wording. It means that independently written descriptions resolve to the same underlying facts. If credible sources disagree about your category, current features, leadership, or availability, repair the source-of-truth page first and then correct the most consequential external records.

    Audit AI visibility by failure mode

    Do not begin with another content calendar. Begin with the answers your prospects already receive. An AI visibility audit should tell you whether the problem is retrieval, entity clarity, corroboration, positioning, factual accuracy, or attribution.

    1. Build prompts from real decisions. Include category discovery, problem-to-solution questions, comparisons, use-case constraints, reputation questions, and branded fact checks. Examples include: What are the leading providers in this category? Which option fits this constraint? What do people say about this brand? Is this product suitable for this use case?
    2. Use the same prompt set across relevant surfaces. Check ChatGPT, Perplexity, Gemini, and Google AI Overviews where an overview appears. Keep the wording stable so you are comparing the answer, not your own prompt variations.
    3. Capture evidence, not impressions. Record the date, surface, prompt, whether the brand appeared, the exact category and attributes assigned to it, competing brands, cited domains, factual errors, and the action offered to the user.
    4. Classify the failure. Map each weak answer to a specific cause before creating or editing content.
    5. Fix the smallest responsible layer. Correct dangerous or commercially significant errors first. Then repair the owned source of truth, clarify entity relationships, and pursue external corroboration for claims that remain unsupported.
    Observed patternLikely gapFirst move
    Your brand is absent and the relevant owned page is unclear or incompleteRetrieval or entity clarityCreate or revise the authoritative page; align visible facts, headings, internal references, schema markup, and JSON-LD
    Competitors appear through several independent domains while your claims exist only on your siteConsensusDevelop evidence worth citing and earn coverage, expert mentions, customer discussion, or community recognition
    Your brand appears with an outdated feature, category, person, or locationConflicting or stale factsCorrect the owned source of truth and then prioritize the external pages that repeat the error
    Your brand appears for branded prompts but not for category or use-case promptsWeak category associationClarify the primary category and publish decision-focused content that connects your entity to the relevant problem
    Your brand is described accurately but sessions do not riseZero-click behavior or attributionMeasure mentions, branded demand, direct visits, and self-reported discovery before declaring the work ineffective

    A single favorable response is not a durable ranking. Generated answers can vary by system, context, and timing. Preserve your prompt set and evidence so the next audit can show whether a correction persisted, whether citations diversified, and whether competitors displaced you.

    Do not reduce the audit to a brand mention count. A recommendation in the wrong category can be worse than an omission, and an accurate mention supported by an irrelevant page may be fragile. Read the claim, the context, and the cited evidence together.

    Measure human demand and machine activity separately

    People and abstract software agents move through separate warm- and cool-colored channels toward an unlabeled measurement console.

    Clicks remain commercially important, but they no longer describe the entire discovery path. Organic click-through rates have declined in reported data for queries displaying AI Overviews since mid-2024, with declines also reported for some queries without AI answers. That is not a reason to abandon search performance reporting. It is a reason to stop using sessions as the sole measure of visibility.

    Agent traffic creates a separate measurement problem. Cloudflare CEO Matthew Prince has said bots represented roughly 20% of web traffic for a long period and projected that bot activity could exceed human activity by 2027. The date is a forecast, not a settled timetable. The operational point is more durable: an agent can retrieve far more pages than a person considering the same decision, so request volume may grow without an equivalent rise in human sessions.

    Use four reporting layers and resist combining them into one traffic number:

    • Search performance: rankings, impressions, click-through rate, organic sessions, and conversions. Keep these metrics because search engines remain a retrieval and demand channel.
    • Answer visibility: the share of your tracked prompts that mention the brand, the share that cite a useful owned or earned page, descriptor accuracy, competitor share of voice, and the diversity of domains supporting decision-critical claims.
    • Agent access: identifiable automated requests, requested URLs, response status, response volume, and infrastructure cost. Separate useful retrieval from errors, loops, and repeated fetching.
    • Business outcomes: qualified leads, sales, branded search, direct visits, AI referral sessions when a referrer is exposed, and self-reported discovery from forms or sales conversations.

    Give each visibility metric a stable denominator. Mention coverage can be calculated as tracked prompts in which the brand appears divided by all prompts checked. Descriptor accuracy can be calculated as correct brand appearances divided by all brand appearances reviewed. Citation coverage can track how often a relevant owned or earned page supports the answer. Keep the prompt set stable between reporting periods, and document additions instead of quietly changing the test.

    Agent requests should never be reported as visits, engagement, or purchase intent. If automated requests rise while answer visibility, branded demand, and qualified outcomes remain flat, you may have a cost increase rather than a marketing gain. If mentions improve while referral sessions decline, inspect branded search, direct demand, and lead-source responses before concluding that AI visibility has no value.

    The economic response also depends on your business model. Publishers supported by advertising face a direct problem because bots do not consume ads like people do. Unique reporting, original data, access controls, and possible licensing arrangements may become more important, although licensing is not a guaranteed substitute for audience revenue. Lead-generation and commerce sites have a different priority: publish accurate selection facts and make the next human action unmistakable.

    Before changing crawler permissions or rate limits, identify which automated systems request which pages, what those requests cost, and whether they contribute to discovery. Blocking broadly can reduce infrastructure load but may also reduce retrieval. Allowing unrestricted access may raise server costs or content-rights concerns. Treat access as a joint technical, commercial, and legal policy rather than a reflexive SEO setting.

    Your next move should happen before you approve another batch of content. Choose one revenue-critical topic, run the same decision prompts across the major AI surfaces, and classify the first failure you find. Fix the source-of-truth page if the facts are unclear; build independent evidence if the facts are clear but unsupported; improve the decision path if the recommendation is accurate but unusable.

    The durable SEO plan is not a choice between rankings and AI visibility. Rankings support retrieval, distributed evidence supports inclusion, and clear decision facts support action. Build those layers deliberately, and you will be prepared whether the next visitor arrives as a person, through an AI answer, or behind an agent.

    References

  • AI Search Is Reshaping Brand Visibility: What to Do Now

    AI Search Is Reshaping Brand Visibility: What to Do Now

    If your important pages still rank but organic visits keep thinning out, the old SEO scorecard is no longer telling you enough. AI answers, shopping modules, discovery feeds, and other search surfaces can influence a decision before a conventional click reaches your site.

    You do not need to abandon SEO or chase every new interface. You need a wider visibility system: diagnose where attention moved, make your brand easy to retrieve and verify, measure whether AI systems select and cite it, and give people a reason to return directly.

    Key takeaways

    • Treat falling organic traffic as a distribution problem before treating it as a ranking problem.
    • Measure AI visibility in distinct stages: discovery, selection, citation, and business impact.
    • Match content to the surface. A page that can earn an explanatory citation is not automatically eligible for a shopping result.
    • Keep brand facts, claims, evidence, and structured data consistent across the channels you maintain.
    • Do not use fast percentage growth in AI referrals as proof that AI traffic can replace lost search traffic.

    Diagnose the traffic loss before changing your SEO strategy

    The disruption is not evenly distributed. Chartbeat data covering global publishers found that sites with 1,000 to 10,000 daily pageviews lost 60% of search referral traffic over two years. Larger publishers also declined, but the effect was less severe.

    Publisher sizeDaily pageviewsSearch referral decline over two years
    Small1,000 to 10,00060%
    Mid-sized10,000 to 100,00047%
    LargeMore than 100,00022%

    The channel details matter just as much as the headline decline. In the same reporting window, Google Search pageviews fell 34% year over year and Google Discover fell 15%. ChatGPT referrals grew 200%, yet still represented less than 1% of overall traffic. A rapidly growing channel can remain too small to close the absolute gap left by a much larger one.

    Traffic has not simply disappeared. Total weekly publisher pageviews declined by 6% from 2024 to 2025 while direct, internal, and messaging channels expanded. That pattern should change your diagnosis: do not assume every organic loss means your rankings, technical SEO, or content quality suddenly failed.

    Start by separating four signals that are often blended together:

    • Impressions: If impressions fell, investigate demand, topic coverage, indexing, and ranking visibility.
    • Clicks: If impressions or positions are steady but clicks fell, inspect the search-result experience and query intent before rewriting the page.
    • Landing-page outcomes: Identify which lost visits previously generated leads, sales, subscriptions, or meaningful engagement. A pageview decline and a qualified-demand decline are not automatically the same problem.
    • Channel mix: Track conventional search, Discover, AI referrals, direct visits, messaging, and internal recirculation separately. Combining them hides where attention is moving.

    Also split branded from non-branded demand. Falling non-branded clicks indicate a discovery problem. Falling branded demand points to a broader brand problem. That distinction determines whether your next investment belongs in page-level optimization, wider distribution, reputation work, or audience retention.

    Replace the ranking funnel with a visibility funnel

    Glowing signals pass through a series of transparent chambers and gather around a central object before forming a returning orbit.

    A ranking is an intermediate signal. In an AI-mediated journey, your brand must first enter the system’s candidate set, then be chosen for the response, and sometimes be cited as supporting evidence. AI search can use query fan-outs to retrieve information across related subquestions before selecting material. A page can therefore rank for one visible query while missing the supporting questions that influence an AI-generated answer.

    Use three AI-specific stages, then attach a business outcome to them:

    1. Discovery: Can the system retrieve your page, brand, product, expert, or claim for the relevant topic and its related subquestions?
    2. Selection: Does the system name or use your brand when composing its answer, recommendation, comparison, or summary?
    3. Citation: Does the response provide a link or identifiable reference to a page you control?
    4. Business impact: Does that exposure produce qualified visits, branded demand, leads, sales, subscriptions, or returning users?

    This sequence gives you a better troubleshooting method than a single visibility score. If the brand is not discovered, look at crawlability, entity clarity, topical coverage, and whether you answer the related questions. If it is discovered but rarely selected, strengthen relevance, evidence, differentiation, and fit for the user’s constraints. If it is named without a citation, make the supporting page easier to identify and substantiate. If citations produce no useful action, examine prompt intent, audience fit, and the destination page rather than celebrating the mention.

    A practical GEO program therefore needs separate measurement for discovery, selection, and citation impact. Combining those stages into one percentage may look tidy, but it conceals the exact failure you need to fix.

    Engineer content for retrieval, evidence, and the right surface

    Begin with one commercially important topic and map the questions an AI system may need to resolve around it. Include the core problem, relevant entities, selection criteria, user constraints, use cases, comparisons, tradeoffs, supporting proof, and conditions that change the answer. You do not need to force all of this onto one oversized page. You do need an intentional cluster with clear relationships and internal links.

    Every important page in that cluster should pass a practical retrieval test:

    • The opening states what the page resolves without making the reader decode a long preamble.
    • Headings follow real tasks and decisions, not a list of loosely related keyword variations.
    • Products, services, organizations, people, locations, versions, and categories are named precisely where they matter.
    • Evidence sits close to the claim it supports, with limitations and applicable conditions stated plainly.
    • Comparison content explains who each option fits, what changes the decision, and where a fair comparison is not possible.
    • Important facts agree across visible copy, metadata, structured data, product information, and maintained public profiles.

    JSON-LD can reinforce this work by expressing page entities and relationships in a machine-readable form. It cannot rescue vague copy, manufacture authority, or guarantee a citation. Mark up facts that are actually visible and supported on the page, choose schema types that match the content, and remove conflicting or obsolete values when the underlying information changes.

    Surface eligibility also changes the optimization job. Across 1.18 million prompts and a reviewed set of 7,500 labeled examples, shippable consumer-goods categories were much more likely to activate ChatGPT Shopping than software, services, travel, or financial products. Price, feature, and intended-use constraints increased the trigger likelihood within eligible product categories, but purchase-intent wording did not override an ineligible category. The pattern could reproduce observed shopping behavior with about 95% to 97% accuracy within that work.

    Treat that result as a strong platform-specific testing hypothesis, not a permanent specification. Interfaces and triggers can change. The immediate lesson is still useful: optimize for the result type your offer can realistically enter.

    • If you sell shippable goods: Make the product category, intended use, meaningful features, and relevant buying constraints explicit. Keep those facts consistent between the product page, supporting content, and product data.
    • If you sell software or services: Do not stuff purchase-intent phrases into pages in the hope of forcing a shopping card. Focus on explanatory retrieval, comparison context, evidence, qualification criteria, and a clear path to evaluation.
    • If you cover travel or financial products: Separate informational visibility from shopping visibility in your reporting. A useful citation or brand selection may be the realistic win even when a product card is not.

    This is why universal AI optimization checklists fail. The query, entity category, interface, and desired result type determine what visibility can look like.

    Make your brand verifiable beyond its own website

    Independent reference, storefront, product, document, microphone, archive, and publisher objects illuminate a blue object at the center of a connected network.

    As search referrals shrink, an unknown publisher or brand has fewer chances to turn a borrowed visit into recognition. The safer position is to be consistently identifiable across the places where people encounter, validate, and return to you.

    Omnichannel visibility does not mean opening an account everywhere. It means maintaining a coherent set of facts and evidence wherever your audience actually evaluates you. Create a simple brand evidence map with the following fields:

    • Canonical identity: The preferred brand name, primary website, category, audience, and concise description of what the organization does.
    • Core entities: Products, services, authors, experts, locations, and other named things that repeatedly appear in your content.
    • Material claims: The statements that affect a buying or trust decision, paired with the page or evidence that supports each one.
    • Public consistency: The profiles, listings, documentation, media, community pages, and other maintained surfaces where those facts should agree.
    • Update ownership: The person or workflow responsible for correcting outdated descriptions, renamed products, changed URLs, and unsupported claims.

    Use that map to fix contradictions before producing more content. If your category changes from one profile to another, an offer has several names, or an author bio makes expertise impossible to verify, additional publishing scales the ambiguity.

    Distribution should then carry useful evidence, not cloned promotional copy. Publish the definitive explanation on the most appropriate owned page. Adapt it for the channels where the audience discusses or validates the subject. Link back when a link genuinely helps the user. Earn independent mentions through work worth referencing; do not try to simulate corroboration with duplicated properties or fabricated consensus.

    At the same time, strengthen the path from first encounter to direct relationship. Direct, internal, and messaging channels expanded while search became a smaller share of publisher traffic. Give a qualified visitor an obvious next step: subscribe, save a tool, follow an update stream, join a relevant community, or move to the next useful page. The right action depends on your business, but relying on another search click should not be the only way someone can find you again.

    Measure AI visibility without mistaking noise for progress

    Referral analytics alone cannot measure AI visibility. A system may mention a brand without linking, cite a page that earns few clicks, or influence a later direct visit. Conversely, one unusual referral can look important when the underlying volume is tiny.

    Build a stable prompt set around decisions that matter to the business. Include category discovery, problem-solving, comparison, constrained recommendation, and branded verification prompts. Add shopping-constrained prompts only where the offer category makes them relevant. For every observation, record:

    • The engine and specific interface tested.
    • The exact prompt, including its constraints.
    • The date of the observation.
    • Whether the brand was absent, discovered, selected, or cited.
    • The wording and context of the mention, including any material inaccuracy.
    • The cited URL and the page a user would reach.
    • The business intent represented by that prompt.

    Keep the core prompts unchanged when you repeat the check. Otherwise, you cannot tell whether the system changed or your test changed. Treat an isolated appearance as an observation, not a trend, and retain screenshots or response records so that later reviews are based on evidence rather than memory.

    Pair that prompt log with three groups of business data:

    • Acquisition: Search, Discover, AI referrals, direct visits, messaging, and other meaningful channels.
    • On-site behavior: The destination pages, next-page paths, subscriptions, enquiries, and other qualified actions.
    • Commercial outcomes: Leads, sales, retained users, or the outcome your organization is actually trying to create.

    Then prioritize by value and failure stage. Protect topics that produce meaningful outcomes and remain highly dependent on search. Repair high-value topics where your brand is retrieved but not selected. Strengthen the supporting page when the brand is selected without a useful citation. Improve the destination when citations arrive but qualified action does not. Leave low-value visibility gaps alone until the evidence gives you a business reason to pursue them.

    For your next work cycle, choose one revenue-relevant topic and take it through the entire system: channel diagnosis, query fan-out, page and entity cleanup, evidence mapping, appropriate structured data, distribution, and a repeatable visibility baseline. One complete loop will teach you more than a broad collection of disconnected AI SEO tactics.

    References