I’ve noticed that Google Search Query Reports are moving towards AI-driven interpretations, reflecting inferred intent rather than exact user searches.
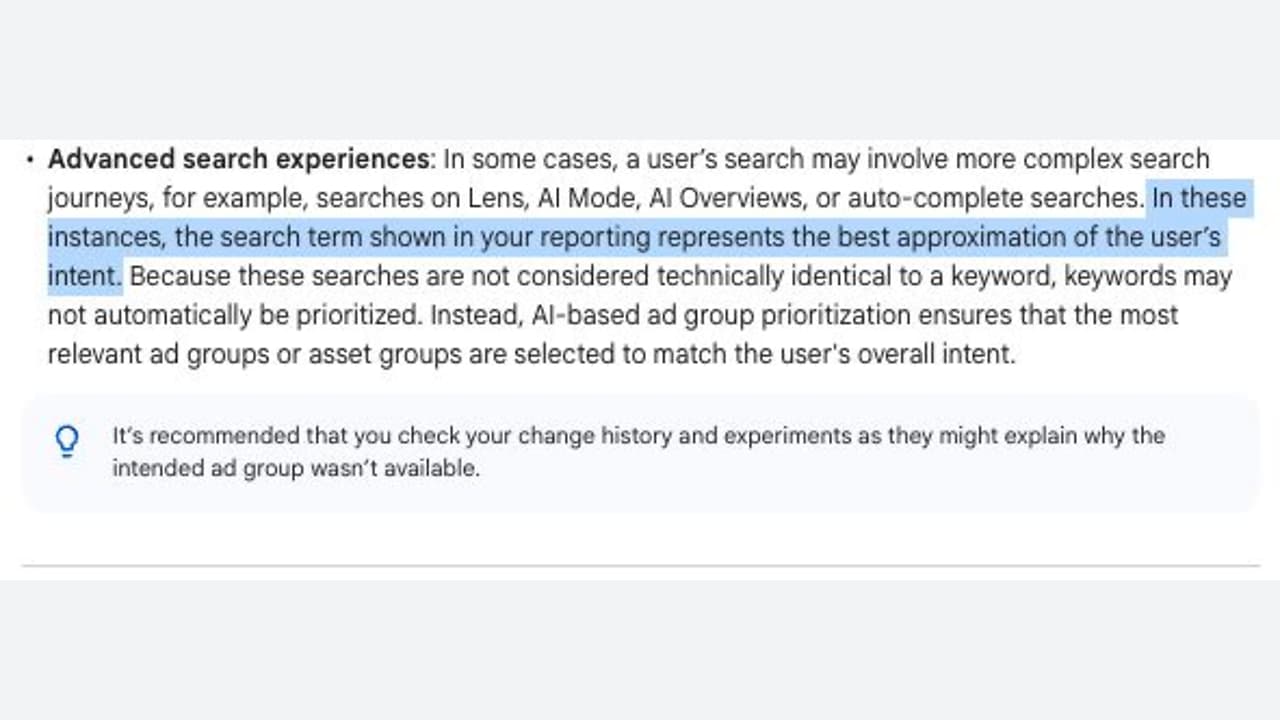
What’s happening. Google has clarified that the search terms in Search Query Reports might not precisely match what users typed. Instead, the system displays the “closest approximation” due to the complexity of modern search behaviors.
What’s behind it. It’s fascinating how heavily AI now influences Google Ads’ matching systems. Rather than depending solely on specific keywords, Google increasingly interprets user intent, context, and behavioral signals to decide which ads to display.
Why we care. For those of us in advertising, Search Query Reports might become less of a mirror reflecting user language and more of a summarized representation of intent. This shift might complicate query analysis, decisions on negative keywords, and strategy around match types.
Discovered by. This update was brought to my attention by Adsquire founder, Anthony Higman, on an official Google help page discussing ad group and asset group prioritization in Google Ads.
The bottom line. Google Ads continues its evolution from keyword matching to AI-driven intent modeling, meaning we might have less insight into the exact searches that activate our ads.
Your facility is not buying traffic. You are choosing who will translate real services, locations, qualifications, and intake pathways into pages that people can find and trust. A weak choice can waste budget, but it can also create false expectations for people making consequential care decisions.
The right agency is not necessarily the one with the longest service list. It is the one whose operating model fits your actual constraint, whose claims survive due diligence, and whose work remains under your clinical, privacy, and business control. Use this process to build a defensible shortlist and run a much more revealing sales conversation.
Define the problem before you compare agencies
The first mistake is asking which addiction treatment SEO agency is best before deciding what the agency must own. Two facilities can want more qualified inquiries while needing completely different work.
Strategy and architecture: You have capable internal writers, but no clear map connecting services, locations, search intent, and priority pages.
Content production: Your experts know the subject, but drafts stall because nobody can turn approved clinical facts into useful search content.
Technical recovery: Important pages are difficult to crawl, duplicate templates compete with one another, internal links are weak, or a redesign left redirects and metadata in disarray.
Local visibility: Your location information, service-area pages, business profiles, and on-site location details do not tell a consistent story.
Integrated acquisition: SEO cannot be planned in isolation because branding, advertising, social media, automation, or offline outreach also shape how prospective patients reach intake.
Choose a primary constraint. Secondary needs can remain in the brief, but they should not obscure the result you are hiring the agency to produce. A technical specialist should not win merely because its proposal contains more content deliverables. A full-service agency should not win merely because it can bundle channels you do not need.
Before contacting vendors, prepare a short decision brief containing:
The services and levels of care you actually provide.
The physical locations that deliver each service.
The inquiries you want and the inquiries you should not attract.
The people who may approve clinical, brand, privacy, and legal claims.
Your website platform, analytics access, content resources, and known technical constraints.
The business event that matters after a visit, such as an appropriate inquiry or an intake milestone defined by your operations team.
The work your internal team will continue to own.
This brief prevents a common procurement failure: buying a generic SEO package and discovering later that nobody owns implementation, clinical review, or the connection between marketing data and intake outcomes.
Match the agency model to your operating constraint
Website design and technical SEO, with newer addiction-treatment experience
Your main constraint is technical or design-related
Recent category-specific examples, clinical review procedures, migration controls, and the experience of the people doing the work
Service breadth is not the same as depth. If you already employ designers and developers, a bundled redesign can add cost and coordination risk. If your site is structurally unsound, a content-only engagement may produce drafts that cannot perform as intended. Shortlist agencies by the bottleneck they are equipped to remove.
Make every agency prove its judgment before you hire it
A polished proposal tells you how the agency sells. A controlled working exercise tells you how it thinks. Give every finalist the same decision brief and ask the same questions so that differences cannot hide behind presentation style.
Ask for relevant proof, not a client logo. Request a de-identified example involving an addiction treatment or comparable healthcare organization. Have the agency explain the starting condition, actions, implementation owner, business measure, and factors it could not control. Confidentiality may limit names and raw data; it should not prevent a coherent explanation of the work.
Run a live problem-solving exercise. Choose a real service or location page from your site. Ask what the agency would investigate, what it would change first, who would make the change, and how it would verify the result. You are testing prioritization, not requesting a free comprehensive audit.
Meet the people who will do the work. Clarify which leaders remain involved after the sale, who writes, who handles technical implementation, who reports results, and which tasks may move to contractors. Category experience at the company level matters less if the assigned team cannot demonstrate it.
Inspect the clinical review workflow. Ask how writers separate search intent from medical fact, how claims are sourced, where your clinical reviewer enters the process, and what happens when an expert rejects or qualifies a draft. An SEO writer should organize approved knowledge, not invent eligibility rules, outcomes, or treatment advice.
Define the measurement chain. Have the agency connect search visibility to visits, calls or forms, appropriate inquiries, and the intake outcomes your team is authorized to share. Traffic alone does not show whether the work is reaching people who can use the service.
Clarify implementation. Determine whether the agency only recommends changes or can safely make them. Ask how it handles backups, approvals, staging, redirects, structured data, quality assurance, and rollback when a technical change fails.
Test the handoff. Ask what you retain when the engagement ends: content, design files, code, accounts, dashboards, keyword or topic maps, structured-data documentation, change logs, and administrative access. The answer should also appear in the contract.
Watch for signals that the sales process is outrunning the agency’s judgment:
Guaranteed rankings, inquiry volume, or admissions. Search outcomes are not fully under an agency’s control, and treatment suitability belongs to qualified care and intake professionals.
A proposal built around publishing volume before the agency verifies your services, locations, capacity, and approval process.
Case studies that show traffic growth but never explain query intent, geography, implementation, or business relevance.
Reports that merge brand searches, informational searches, and service-seeking searches into one favorable number.
Refusal to provide administrative access to accounts created for your organization.
Structured data used as a hidden place for claims that are absent from, or unsupported by, the visible page.
A request to copy patient histories, diagnoses, substance-use details, or call transcripts into general marketing tools without a formally approved privacy and data-governance process.
An agency can understand addiction treatment marketing without becoming a clinical authority. Keep that boundary explicit. Your qualified clinical, privacy, and legal owners must control the decisions that fall within their roles.
Scope the work so SEO, AI visibility, and safety agree
The strongest engagement turns organizational truth into a controlled publishing system. It does not begin with a large keyword list. It begins with facts the facility is prepared to verify and maintain.
Build a service-fact matrix before producing pages
For every service and location, record the approved version of the facts that marketing may use:
The service name and a plain-language explanation.
The setting and level of care actually provided.
The physical location responsible for delivering the service.
The audience, eligibility conditions, and exclusions, using language approved by qualified staff.
Credentials, affiliations, or accreditations that can be substantiated.
Insurance and payment language approved for publication.
The correct contact and intake path.
Any emergency or crisis direction that your clinical and legal owners require.
The agency can then map approved facts to service pages, location pages, educational resources, metadata, internal links, local profiles, and structured data. When a search opportunity requires a claim that is not in the matrix, the agency should request review instead of stretching the available language.
Make answer-engine and generative-engine work auditable
AI visibility can become a vague upsell unless the agency connects it to concrete site work. Ask which questions it wants your pages to answer, which facts need clarification, which entities and locations need consistent naming, and how it will check whether your organization is represented accurately in the search and answer environments included in the scope.
JSON-LD should represent content and claims that a person can verify on the page. It should not manufacture authority, imply a service at a location that does not provide it, or turn a marketing description into a clinical fact. Require documentation showing which visible page elements support each important structured-data field and who owns updates when services change.
Do not buy an AI optimization package that cannot identify the pages, facts, templates, or publishing processes it will change. A visibility report may be useful, but it is not a substitute for accurate content, accessible pages, technical maintenance, or appropriate inquiries.
Measure the path to intake without exposing patient detail
Build reporting as a chain rather than a single dashboard total:
Visibility for the intended service, informational, and location queries.
Visits and meaningful actions on the relevant landing pages.
Calls or forms attributed within the limits of your approved systems.
Inquiries meeting a definition agreed with your intake team.
Downstream operational outcomes that can lawfully and safely be reported in aggregate.
The agency should report the layers it influences, while your organization owns the definitions and permissions. Do not send detailed health histories, diagnoses, substance-use disclosures, or unredacted conversations into analytics, advertising, call-tracking, or AI systems merely to improve attribution. Your privacy and legal owners should determine what may be collected, where it may go, who may access it, and how long it may be retained.
Put ownership and change control in the contract
The statement of work should make performance visible and a future handoff possible. Include:
Deliverables: Name the audits, pages, technical changes, local work, structured data, reports, and implementation support included. Avoid a scope defined only as ongoing optimization.
Responsibility: Assign each deliverable to the agency, your team, or a shared workflow. State who publishes and who validates changes.
Approvals: Identify the content that needs clinical, brand, privacy, or legal review and what happens when approval is delayed or denied.
Access and ownership: Confirm that your organization controls its domain, content-management system, analytics, search tools, local listings, call-tracking assets, creative files, and data exports.
Change records: Require a log of material publishing and technical changes so that a decline, error, or compliance concern can be investigated.
Measurement: Define the reportable events, data limits, attribution assumptions, and treatment of branded versus non-branded demand.
Conflicts: Clarify whether the agency serves competing facilities in the same market and what account separation or exclusivity, if any, the agreement provides.
Exit and handoff: Specify the access, documentation, exports, unpublished work, and transition support delivered when the relationship ends.
Have qualified counsel review material contract, privacy, and regulatory terms. Marketing procurement should not quietly make legal or clinical decisions simply because they appear inside an SEO statement of work.
Key takeaways
Choose an agency for the constraint it can remove, not for the number of services it can place in a proposal.
Use client history, leadership experience, longevity, and size to create a preliminary screen, then test the assigned team’s actual judgment.
Require finalists to solve the same real page problem and explain implementation, clinical review, measurement, and handoff.
Keep treatment claims, eligibility language, crisis direction, and privacy decisions under qualified internal review.
Make AI visibility and JSON-LD auditable by tying them to visible, approved, maintainable facts.
Define account ownership, data limits, approvals, change control, reporting, and exit terms before work begins.
Before booking agency demonstrations, finish your decision brief and turn the evidence questions above into a shared scorecard. Give every finalist the same facility facts and the same page scenario. The differences in their answers will tell you far more than another customized pitch.
Your pages rank. Your backlink profile looks healthy. Yet when a buyer asks an AI system which providers fit their situation, your brand is missing – or appears without enough context to make the shortlist.
That is not necessarily a conventional ranking problem. It is a citation problem. To address it, you need to find the prompts that influence real decisions, identify the pages shaping those answers, and make sure those pages contain accurate, usable information about where your brand fits.
Diagnose the visibility gap before you chase mentions
AI citation optimization is the practice of improving the material AI systems can retrieve, use, and cite when answering questions relevant to your business. The goal is not citation volume for its own sake. The goal is accurate brand inclusion in answers that help a buyer compare options, evaluate fit, verify claims, or plan implementation.
Traditional SEO metrics still matter, but they do not fully explain AI visibility. A company can have strong rankings, substantial traffic, and a large link profile while remaining absent from consequential buyer questions. AI systems need enough context to connect a brand with a particular audience, problem, use case, constraint, and decision criterion.
This changes the question you ask about a placement. Conventional link building often starts with whether a page can pass authority or referral traffic. Citation optimization adds another test: can the page help an AI system understand why your brand belongs in a specific answer?
Most visibility problems fall into one of three practical categories:
Information gap: The facts a buyer needs do not exist in accessible content. Sales or implementation teams may know the answer, but the web does not.
Surface gap: Useful information exists, but not on the pages or platforms that repeatedly shape relevant AI answers.
Context gap: Your brand is mentioned, but the surrounding text does not explain its category, intended customer, use case, distinguishing criteria, evidence, or implementation requirements.
Each gap requires a different response. An information gap calls for new decision-ready material. A surface gap calls for distribution and outreach. A context gap calls for a richer, more accurate description. Treating all three as a request for another backlink wastes effort because anchor text alone does not provide the surrounding meaning an AI system needs.
Start by writing one sentence that describes the visibility failure precisely. For example: our brand is absent when mid-market buyers compare options for a regulated workflow, even though competitors appear. That sentence gives you a buyer, a decision, a constraint, and an observable gap. It is far more actionable than a broad goal such as increase AI citations.
Build a prompt map from real buyer decisions
Keyword lists are a weak starting point because buyers no longer have to compress a complicated situation into a short query. They can describe what they are trying to accomplish, what they have already considered, what constraints they face, and what would disqualify an option.
Your prompt map should therefore come from decision friction, not just search volume. Pull recurring questions from sales, implementation, customer success, product documentation, and support. Look especially for questions about fit, comparisons, use cases, proof, prerequisites, and rollout. These are often the details a buyer needs before taking a vendor seriously.
You generally will not have a complete log of the prompts prospective customers submit to AI systems. Synthetic prompts can still expose meaningful gaps, but they should be treated as directional representations of buyer intent, not precise demand data or proof that every buyer behaves the same way.
Buyer decision
Prompt pattern
Information the cited page should contain
Fit
Which type of provider suits a buyer with this need and constraint?
Intended audience, qualifying conditions, poor-fit cases, and relevant use cases
Comparison
How do the credible options differ on the criteria that matter here?
Consistent comparison dimensions, meaningful differences, tradeoffs, and scope
Use case
Which options can handle this workflow or operating environment?
Specific workflow, users involved, constraints, and supported outcome
Proof
What evidence supports each option for this problem?
Verifiable examples, methodology, documentation, and limits on the claim
Implementation
What would adopting this option require?
Prerequisites, integrations, handoffs, responsibilities, and likely points of friction
A useful prompt template is: Which options fit [buyer type] that needs [use case], operates under [constraint], and cares most about [decision criteria]? Compare the options and explain the implementation implications. Replace each bracket with language your customers actually use.
Build and run the map in a repeatable sequence:
Collect recurring buyer questions from teams that hear them directly.
Remove your brand name so the prompt tests discovery rather than brand recall.
Add the buyer’s role, problem, environment, constraints, and decision criteria.
Group related prompts into fit, comparison, use-case, proof, and implementation clusters.
Record the answer, every visible citation, the brands included, and the context attached to each brand.
Repeat the prompt families rather than drawing a conclusion from one isolated response.
Do not prioritize a citation opportunity merely because a page appeared once. Look for repetition. A page or domain becomes strategically interesting when it recurs across several valuable prompt variations, helps define an important comparison, includes relevant competitors while omitting you, or describes your brand without the context needed to establish fit.
This prompt-cluster approach also prevents a common reporting mistake. If your brand appears for a broad informational question but disappears when the buyer adds an important constraint, you do not have uniform visibility. You have coverage for one part of the decision and a gap in another.
Improve the pages AI already leans on
Once you know which pages shape relevant answers, audit what those pages actually contribute. A cited URL may supply a definition, comparison, shortlist, proof point, implementation detail, or category framework. Its role matters because your improvement has to strengthen the part of the answer the page supports.
Review each recurring page for these elements:
The buyer question the page can answer directly
The brands, products, or approaches it includes
The criteria it uses to distinguish those options
The context surrounding your brand, if you are mentioned
The evidence supporting claims about fit or performance
The use cases, tradeoffs, and implementation details it explains
The presence of clear tables, lists, comparisons, or frameworks
Any inaccurate, obsolete, ambiguous, or unsupported description
Clear structure is not cosmetic. AI systems need material they can readily use, and tables, comparisons, and explicit explanations can make a page more useful for decision-oriented answers. A polished page that never states who an option is for is less helpful than a plain page that answers the buyer’s question precisely.
Strengthen owned pages with decision-ready context
On pages you control, put the answer before the background. State what the offering is, who it serves, which problem it addresses, and the conditions under which it is or is not a sensible fit. Do not force a system – or a buyer – to infer the relationship from slogans.
A useful brand-description pattern is: [Brand] is a [specific category] for [defined audience] that needs [use case]. It is relevant when [qualifying condition], differs on [decision criterion], and requires [implementation condition]. Every part of that sentence should be supportable. Remove any field you cannot substantiate.
Then support the initial description with the content units the decision requires:
Fit: Identify intended customers and important disqualifiers.
Use cases: Describe the problem, operating context, workflow, and supported outcome.
Comparison: Use the same criteria for every option and acknowledge meaningful tradeoffs.
Proof: Connect each claim to verifiable documentation or evidence, and state its limits.
Implementation: Explain prerequisites, dependencies, integrations, handoffs, and ownership.
Terminology: Use consistent names and category language across related pages so the brand is not framed as a different kind of offering in each location.
Avoid copying the same generic company paragraph across every page. The core entity description should remain consistent, but the surrounding context should match the decision. A comparison page needs criteria and tradeoffs. An implementation page needs prerequisites and process. A use-case page needs a defined user, problem, constraint, and outcome.
Ask third-party publishers for context, not just a link
Prioritize third-party action when a recurring page omits a genuinely relevant option, contains an inaccurate description, uses a comparison dimension you can substantively improve, or mentions your brand without enough information to explain its place in the market.
Your outreach brief should make the editorial improvement obvious. Identify the section that is incomplete, explain which buyer question remains unanswered, supply a concise and verifiable description, offer supporting evidence, and suggest a fair comparison dimension. Ask for inclusion only when the brand meets the page’s stated criteria. A forced mention on an irrelevant page creates noise, not useful visibility.
When a publisher already mentions you, enriching that paragraph may be more valuable than placing a new link elsewhere. The revised context should explain the offer, audience, use case, differentiator, and evidence relevant to that page. The link then supports the explanation instead of standing in for it.
Preserve editorial independence. Give publishers accurate material they can verify, but do not ask them to disguise promotional claims as neutral comparison. Citation optimization depends on trustworthy context; weakening the page’s credibility works against that objective.
Measure recurring coverage, context, and accuracy
AI answers vary by prompt, industry, intent, and available material. A single successful answer does not establish durable visibility, and a single omission does not prove a systemic failure. Your measurement system should reveal recurring patterns across prompt clusters.
Maintain a citation ledger with the following fields:
AI surface and prompt wording
Buyer stage and prompt cluster
Answer date and test conditions
Brands included in the answer
How your brand was described
Cited domains and exact pages
The role each cited page played
Missing, weak, inaccurate, or conflicting context
Owned-page, outreach, or correction action
Status after the next comparable observation
Classify brand visibility by meaning, not just presence. Useful states include absent, named without decision context, named with inaccurate context, accurately included but unsupported by a visible citation, and accurately included with relevant supporting material. This keeps a shallow name drop from being reported as equivalent to a credible recommendation.
Read the ledger horizontally and vertically. Across a row, you can see why one prompt produced a particular answer. Down a prompt cluster, you can see recurring omissions, frequently cited pages, unstable descriptions, and competitors that repeatedly occupy the position you want to earn.
Use the pattern to select the next action:
If your brand is absent and the same third-party pages recur, investigate their inclusion criteria and missing context.
If your brand appears inaccurately across several answers, align owned descriptions and correct influential third-party material.
If an owned page is cited but the answer omits your brand’s relevant use case, make the relationship explicit on that page.
If competitors appear because they provide stronger comparisons or proof, improve the underlying information rather than merely increasing mention volume.
If results fluctuate without a recurring pattern, keep observing the cluster before committing resources to a page or domain.
Keep conventional SEO and business measures in view. Rankings, links, referral visits, engagement, and conversions still help you judge whether a page creates value. The important change is that they now sit beside answer inclusion, citation recurrence, contextual accuracy, and coverage of decision-stage questions. Links remain useful; they simply are not a complete AI visibility strategy by themselves.
Do not collapse the ledger into one unexplained visibility percentage. Any summary metric depends on the prompts you selected, how you grouped them, which systems you tested, and what counted as a successful appearance. Preserve those assumptions so a change in the dashboard cannot be mistaken for a change in buyer visibility.
Key takeaways
AI citation optimization aims to earn accurate inclusion in consequential answers, not collect citations indiscriminately.
Start with natural-language buyer decisions about fit, comparison, use cases, proof, and implementation.
Track prompt clusters and recurring cited pages instead of reacting to one output.
Separate information, surface, and context gaps because each requires a different fix.
Improve the material surrounding a brand mention; a backlink without useful context is incomplete.
Measure presence, accuracy, citation support, and decision-stage coverage alongside traditional SEO outcomes.
Your next move is small and concrete: choose one decision your buyers repeatedly struggle with, create a focused set of unbranded prompts around it, and record the pages that keep shaping the answer. The recurring gap will tell you whether to create missing information, improve an owned page, enrich a third-party mention, or correct an inaccurate one.
You search your company or client in an AI engine and find an old allegation stated as if it were current. The answer may cite Wikipedia directly, or it may repeat Wikipedia’s framing without showing you how that framing traveled. Either way, deleting one sentence is not the real job.
You need to identify exactly what is wrong, repair the evidence chain behind it, and then check whether AI search has absorbed the correction. This response plan helps you do that without turning a reputation problem into a conflict-of-interest problem.
Why a stale Wikipedia claim can keep reappearing
Wikipedia has unusual influence over AI-generated answers because it offers condensed entity summaries supported by citations. That combination makes a Wikipedia page useful to systems trying to answer broad questions about a company, person, product, or controversy.
The citation is also where the problem can become durable. A claim may remain verifiable in the narrow sense that a reputable outlet once published it, even when later events changed its meaning. The initial accusation might be prominent, while the correction, dismissal, or exonerating context received much less coverage. An editor can therefore find several citations for the original narrative and little independent material documenting what happened afterward.
Wikipedia’s consensus model adds another layer. Contentious changes are not decided by a single authority, and editors may retain cited language when removing it could appear biased. That protects the encyclopedia from self-serving rewrites, but it can also leave an old framing in place when the public evidence has not caught up with reality.
AI search magnifies the imbalance. Generated answers may combine Wikipedia with news coverage and community discussions such as Reddit. If those pages all repeat the same early reporting, the model encounters apparent corroboration even when the pages are echoing one another. Many users then accept the generated summary without opening its citations.
Before you act, classify the problem correctly:
Factually inaccurate: The cited material does not support the statement, contains an acknowledged error, or is represented more strongly than the evidence permits.
Outdated: The statement may describe what was reported at one point, but a later decision, correction, resolution, or change makes the present-tense framing misleading.
Unbalanced: The individual facts may be sourced, but the page gives an old dispute disproportionate prominence or omits material context needed to understand it.
Negative but supported: The information is unfavorable, relevant, and adequately documented. Reputation discomfort alone does not make it misinformation.
That distinction determines your next move. A false statement calls for a correction. An outdated statement calls for newer evidence and temporal context. A balance problem calls for a neutral assessment of prominence. A supported criticism may need to remain.
Build a claim-to-evidence audit before requesting changes
Do not begin with a general complaint that the brand looks bad. Editors, publishers, and search teams can only evaluate specific statements. Start with the exact language shown to users and trace it backward.
Create a fixed prompt set. Run the same neutral questions on the AI search surfaces that matter to your audience. Useful prompts include: What is [Brand] known for? What major criticisms involve [Brand]? Is [specific claim] still accurate? Ask for citations where the interface supports them.
Preserve the complete answers. Record the platform, visible model or search mode, prompt, date, answer, cited links, and the exact sentence that concerns you. Do not save only the alarming fragment; surrounding qualifiers matter.
Find the matching Wikipedia passage. Compare wording, order, emphasis, and citations. A close match can show a likely narrative path, but do not assume Wikipedia caused the answer merely because both contain the same allegation.
Open every supporting citation. Check whether the referenced reporting actually supports Wikipedia’s wording. Notice whether an allegation became a stated fact, whether attribution disappeared, or whether a historical event is written in a way that implies a current condition.
Search the evidence you already possess. Identify later corrections, official outcomes, independent reporting, or other reputable material that changes the interpretation. Separate public evidence from internal documents that readers and editors cannot verify.
Compare the wider narrative. Review whether current coverage contains the missing context or simply repeats the original claim. This reveals whether you have a Wikipedia wording problem or a broader evidence-distribution problem.
Use a simple audit record so that each proposed action stays tied to evidence:
Audit field
What to record
Decision it supports
Disputed claim
The exact language, not a paraphrase
Whether the issue is factual, temporal, or editorial
AI appearance
Platform, prompt, date, full answer, and citations
Where users encounter the narrative
Wikipedia evidence
Passage, placement, and supporting references
Whether Wikipedia is a likely contributor
Current evidence
Corrections, later outcomes, and reputable newer coverage
Whether a change can be independently verified
Classification
Inaccurate, outdated, unbalanced, or negative but supported
Which remedy is proportionate
Next action
Publisher correction, stronger coverage, transparent Wikipedia request, or monitoring
Who can address the actual failure
This audit also prevents a common misdiagnosis. If an AI answer cites several current publications that independently support the disputed point, changing Wikipedia alone will not solve the problem. If the answer mirrors a Wikipedia passage and the underlying citation no longer supports it, you have a much more focused correction path.
Repair the evidence trail without creating a conflict
Test the citation against the sentence. Does the reference support every material part of the claim? Does it describe an allegation, a finding, or a final outcome? Has attribution been stripped away? Write down the precise mismatch.
Correct the upstream record where possible. If a publication made a demonstrable error or failed to append a later correction, approach that publisher with the exact passage and the evidence that contradicts it. Request a specific factual correction rather than a favorable rewrite. If you intend to make a legal demand or allege defamation, obtain advice from qualified counsel for your circumstances before acting.
Close genuine coverage gaps. When circumstances changed but no reputable independent coverage documents the change, Wikipedia editors have little verifiable material to use. Make the supporting facts, documents, and relevant people available to credible third parties. The goal is accurate reporting of what changed, not a wave of promotional stories.
Prepare a neutral Wikipedia request. Identify the existing wording, explain the factual or temporal defect, propose the smallest defensible change, and provide independent citations. If you have a relationship with the subject, disclose it and use Wikipedia’s established discussion or edit-request process instead of presenting yourself as an independent editor.
Allow the evidence to carry the request. Wikipedia decisions are made through contributor review and consensus. A detailed request can still be rejected if the replacement evidence is weak, self-published, promotional, or unrelated to the specific sentence.
The strongest request is often narrower than the brand wants. If an allegation genuinely occurred, complete deletion may be inappropriate even when the allegation was later dismissed. A more accurate remedy may be to preserve the historical event while adding the later outcome, correcting present-tense language, or adjusting prominence so the page no longer implies that an old dispute defines the organization now.
Avoid manufacturing positive coverage to overwhelm the negative phrase. Repetitive, thin, or obviously controlled material does not resolve the factual issue. It can also make a legitimate correction request look like image management. Current, reputable third-party coverage is valuable because it gives editors and AI systems something independently verifiable to weigh against the older narrative.
Measure the AI narrative, not just the Wikipedia edit
A Wikipedia change is an intermediate result. Your actual objective is a more accurate answer wherever people investigate the entity. That requires checking the whole narrative after the public evidence changes.
Repeat the original prompt set on the same AI surfaces. Preserve the new answers with their dates and citations. One favorable response is only one observation, so compare multiple relevant prompts instead of declaring success after a single query.
Evaluate four dimensions:
Factual status: Is a disputed allegation still presented as an established fact, or is its status accurately attributed?
Temporal framing: Does the answer distinguish what was once reported from what is currently known?
Prominence: Does the old issue still dominate a general description even when it is no longer central to current coverage?
Citation mix: Does the answer rely only on older repeating pages, or does it include reputable material documenting the later outcome?
Monitor again after a meaningful citation, publication, or Wikipedia change, and whenever the disputed claim resurfaces in stakeholder conversations. The comparison should use the same prompts and evaluation criteria. Otherwise, you cannot tell whether the public narrative improved or the wording merely varied between answers.
Key takeaways
Negative information is not automatically misinformation. Classify it as inaccurate, outdated, unbalanced, or supported before choosing a remedy.
Trace the exact AI sentence through its citations, the matching Wikipedia passage, and the reporting behind that passage.
Repair weak or outdated evidence upstream. Wikipedia is difficult to correct when reputable public coverage still supports only the old narrative.
Do not make undisclosed direct edits to a page about yourself or your organization. Use a transparent, narrowly sourced request.
Judge success by factual status, time context, prominence, and citation quality across AI answers, not merely by whether a Wikipedia sentence changed.
Start with the single sentence causing the most harm. Preserve the AI answer, locate the Wikipedia wording, open its citation, and write down the smallest correction that the public evidence can support. That gives you a defensible first action instead of an open-ended campaign against every negative result.
Your pages rank, your traffic reports look respectable, yet your brand disappears when a prospect asks an AI assistant for options. That gap is not just a reporting curiosity. Your content may be discoverable while your brand remains absent from the answer that shapes the decision.
Fixing that gap starts by changing what you measure. You need to know whether AI systems recognize your brand in the right unbranded conversations, describe it accurately, and do so often enough that one lucky mention cannot fool you.
Recognition is the outcome; rankings are one input
Traditional rank tracking asks whether a page earned a particular position for a query. AI visibility adds a harder question: when a system assembles an answer, does it connect your brand with the category, problem, product attribute, or recommendation context that matters?
That distinction matters because brand recognition increasingly matters alongside conventional rankings. A strong organic position can help people and machines discover your information, but it does not guarantee that an AI response will name your brand, frame it correctly, or use it as a preferred example.
Recognition is more specific than general awareness. For AI search measurement, treat it as the repeated and accurate association of your brand with a relevant topic or decision. A mention is useful only when the surrounding answer helps the user understand why your brand belongs there.
Topical fit: The brand appears for a problem or category it genuinely serves.
Accurate framing: The response describes what the brand does without confusing its audience, offer, or positioning.
Decision relevance: The mention appears where a user is discovering, evaluating, or selecting an option, not in an unrelated aside.
Credible support: The response connects the claim to a useful citation or supporting context when the interface provides one.
Repeatability: The result survives repeated runs instead of appearing in one favorable screenshot.
This is why a mention count by itself is weak. A brand can be named frequently but described as the wrong type of company. It can appear in a long list without any explanation. It can also be cited as an information source while a competitor receives the actual recommendation. Record those outcomes separately.
Rankings still matter, but their role changes. They are part of the evidence and discovery layer, not the final visibility score. The practical endpoint is whether your brand becomes a clear, trusted part of the answer, especially when users can receive an answer without visiting a result page.
Build a prompt panel that represents real decisions
You cannot measure AI visibility with whichever prompt happens to come to mind during a meeting. A useful baseline needs a fixed prompt panel: a time-stamped collection of exact questions that represent the situations in which you want to be recognized.
Start with unbranded prompts. If the prompt already contains your name, the resulting mention says little about discovery. Keep branded prompts in a separate diagnostic set for checking factual accuracy, positioning, and direct brand understanding.
Organize the unbranded panel into three intent buckets:
Category discovery: Questions asking which tools, companies, services, or approaches exist for a defined need.
Requirement-led research: Questions built around a feature, constraint, audience, use case, or product specification.
Evaluation and selection: Questions asking for suitable options, trade-offs, or criteria before a decision.
A practical coverage panel can contain 25 exact prompts in each bucket, producing 75 queries. That is a testing design, not a universal minimum. If 75 prompts are too costly to repeat, preserve the three-bucket balance and select a smaller experimental cohort from the full panel. For a focused change, a cohort of 5-10 target prompts run daily across seven consecutive days gives you a more defensible baseline than a single session.
Do not rewrite prompts between the baseline and measurement periods. A change from a broad category question to a product-specific question is not a harmless variation; it changes what the system is being asked to retrieve and compare. Save alternate phrasings as separate prompt records.
For every run, record the exact prompt, model, displayed model version when available, date, environment, login state, location or locale, and response. Use a consistent testing environment. A logged-out browser with a cleared cache is one option; an API or synthetic testing platform can provide tighter control where available. The aim is not to create a perfectly sterile laboratory. It is to keep avoidable differences from becoming explanations for the result.
Then label each response using the same fields:
Signal
What to record
What it tells you
Inclusion
Whether the brand appears in the response
How often the model associates the brand with the prompt context
Position in response
Where the first substantive mention appears
Whether the brand is central to the answer or peripheral
Framing
Recommended, neutral, compared, cautioned against, or merely cited
Whether visibility is helping the intended positioning
Accuracy
Correct or incorrect category, audience, capabilities, and limitations
Whether the model recognizes the right entity and facts
Citation
The linked or named supporting page, when citations are exposed
Which evidence appears to support the mention
Calculate inclusion rate as the number of eligible runs that mention the brand divided by the total number of eligible runs. Keep the raw labels as well as the percentage. A single combined score can conceal an important failure, such as higher inclusion paired with inaccurate framing.
Break results out by model and prompt bucket. An average across every system and intent can make a brand look moderately visible when it is actually strong in category discovery, absent during evaluation, and misrepresented by one model. That is not one problem; it is three different problems requiring different changes.
Strengthen the signals that make your brand understandable
AI recognition is not created by repeating a brand name more often. It grows when the web contains clear, consistent evidence about what the brand is, which topics it belongs to, what it offers, and why it is relevant in a particular context.
Make the visible content answer a precise question
Generic claims leave little for a system to connect with a detailed prompt. Replace vague category language with facts that resolve a real requirement: the product type, intended user, model, offer, relevant specifications, supported use case, and meaningful constraints. The goal is not maximal detail on every page. It is enough detail for the page to answer the prompt it is meant to support.
For example, if your prompt panel contains requirement-led questions and the relevant page never states those requirements explicitly, that is the first gap to fix. Add one self-contained paragraph that connects the brand, product, and requirement in plain language. Do not simultaneously rewrite the introduction, change the page template, and add schema if you want to know whether that paragraph mattered.
Keep core entity facts consistent across your own pages. The canonical brand name, category, audience, product naming, and relationship between the company and its offers should not shift according to which team wrote the copy. Consistency reduces ambiguity; mechanical repetition does not.
Use structured data to clarify, not to invent
Structured data can make relationships such as brand, model, and offer explicit in a machine-readable layer. Its effect on AI answers should still be tested rather than assumed. Schema is not a guarantee of selection, and it cannot create authority or factual support that the visible page lacks.
Markup should describe information that users can already verify on the page. If a page has a visible question-and-answer section, adding the corresponding FAQ markup creates a clean experiment: the visible answers stay fixed while the explicit structured-data signal changes. Likewise, brand, model, or offer properties can be added without rewriting the HTML copy when you want to isolate the machine-readable layer.
Do not add unsupported claims to JSON-LD because you want an AI system to repeat them. At best, the test becomes uninterpretable because the markup and page disagree. At worst, you make inaccurate information easier to reproduce. Treat structured data as a precise description of the page, not a hidden promotional channel.
Build recognition beyond your own domain
Your website can define the entity, but self-description is only one part of recognition. Brands become easier to identify when they appear consistently in meaningful external contexts and are cited for topics they genuinely cover. That makes public relations, content distribution, industry participation, and reputation work part of AI search strategy rather than separate activities.
Audit external mentions for context, not just volume. A mention is more useful when it associates the right brand with the right category and a concrete area of expertise. Repeated mentions that use obsolete product names, vague descriptors, or the wrong category can reinforce confusion instead of authority.
For each important prompt cluster, create an evidence map with four lines:
You can have a healthy SEO dashboard and still be nearly invisible when a buyer asks an AI assistant what to choose. The difficult part isn’t collecting another visibility score. It’s knowing whether a change reflects stronger retrieval, a different mix of prompts, or noise in the answers you sampled.
A useful measurement system starts with a repeatable prompt panel, distinguishes mentions from citations, checks whether your brand is represented accurately, and connects that evidence to business outcomes. Here is how to build one without turning a handful of AI responses into false precision.
Measure what happens inside the answer, not just after the click
Traditional search measurement follows a familiar sequence: query, ranking, impression, click, session, conversion. Generative search compresses much of that journey into an answer. A user can discover your brand, compare it with alternatives, absorb a claim about it, and make a decision without visiting your site.
That makes traffic an incomplete visibility measure. Some studies cited in current GEO coverage put traditional-result clicks at only 8% when AI-generated summaries are present. Treat that figure as a warning about measurement gaps, not as a universal click-through benchmark for your site. The practical point is that an off-site answer can influence demand even when analytics records no session.
Measure AI search visibility across four layers. Presence tells you whether the brand appears. Use tells you whether an owned page is retrieved or cited. Representation tells you whether the answer describes the brand accurately and in the right context. Impact tells you whether that exposure is associated with qualified visits, branded demand, leads, sales, or another business outcome.
These layers prevent a common reporting error. A brand mention is not automatically an owned-content citation. A citation is not proof that the answer framed the brand correctly. Visibility is not proof of commercial influence. Each is useful, but each answers a different question.
Key takeaways
Use a stable set of prompts so one reporting period can be compared with another.
Keep mentions, citations, observable retrieval, entity accuracy, sentiment, and conversions as separate measures.
Report results by platform, topic, intent, and prompt cohort before calculating an overall score.
Save the underlying answer and its citations. A percentage without evidence cannot be audited.
Use visibility metrics to choose an action, then judge that action by the specific metric it was intended to change.
Build a prompt panel you can rerun without moving the goalposts
Your prompt panel is the measurement instrument. If the prompts change whenever a campaign changes, the resulting trend line cannot tell you whether visibility improved or the test simply became easier.
Start with topics and decisions that matter
List the topics your brand should credibly be associated with, then map the questions a real buyer asks while learning, solving, comparing, choosing, and validating. This creates a panel that covers informational discovery as well as decision-stage visibility.
Learn: What is the category, process, or concept?
Solve: How should someone handle a defined problem or constraint?
Compare: What are the meaningful differences between available approaches?
Choose: Which options fit a particular use case, audience, budget, or requirement?
Validate: Is a named brand suitable, credible, compatible, or known for the relevant capability?
Include branded and unbranded prompts, but don’t blend their results. An unbranded prompt tests discovery and competitive consideration. A branded prompt tests entity recognition, factual accuracy, and reputation. A dashboard that combines them can look strong simply because the model answers direct questions about a brand that the user already named.
Apply audience, industry, location, or product qualifiers only when they change the decision. Keep them in dedicated cohorts. Otherwise, an increasingly narrow prompt may manufacture visibility that does not exist for the broader market question.
Create a prompt registry before collecting answers
Give every prompt a permanent record. At minimum, store its ID, exact wording, topic, intent, audience qualifier, branded or unbranded status, platform and mode, relevant competitor set, target page, and the brand facts you expect an accurate answer to preserve.
Freeze the wording used for your baseline. If you improve a prompt later, create a new version instead of overwriting the old one. Keep retired prompts in the registry so historical rates retain their original denominator. This is less convenient than editing a shared list in place, but it prevents an invisible change in the test from masquerading as an improvement in performance.
Use a consistent collection protocol
Run the exact registered prompt in the intended platform and mode, such as an answer with web search enabled rather than a model-only response.
Record the platform, mode, timestamp, prompt version, full response, visible citations, cited URLs, and any named competitors.
Score the answer with a written rubric. Preserve the raw response so another reviewer can check the decision.
Repeat the panel on a fixed cadence. If resources permit, run prompts more than once so a single response is not mistaken for a stable pattern.
Log failed captures, blocked responses, and unavailable features separately. Do not score a technical failure as brand absence.
Keep platform results separate. Google AI Overviews, ChatGPT search, and other answer systems are different surfaces with different retrieval and citation behavior. You can create a portfolio view later, but first calculate each platform’s rate against its own eligible observations.
If you do publish an aggregate, state its weighting. An unweighted average gives every prompt-platform pair the same influence. A business-weighted score gives priority cohorts more influence. Neither is inherently correct; an unexplained blend is the problem.
Use a metric stack instead of one opaque visibility score
Eligible answers containing a qualifying brand mention or traceable use of owned content, divided by all eligible answers in the cohort.
Does the brand enter the answer at all?
AI citation frequency
Eligible answers containing a visible citation connected to the brand, divided by all eligible answers. Report any-brand citation and owned-domain citation separately.
Is the answer visibly supported by material associated with the brand, and does it cite the brand’s own site?
Share of model voice
The brand’s unique inclusions divided by unique inclusions for the entire predefined competitor set. Count a brand once per answer so repetition does not inflate share.
How much of the observable category conversation does the brand occupy?
Entity recognition accuracy
Brand-discussing answers that preserve the required facts divided by all answers that discuss the brand.
Does the system understand who the brand is, what it offers, and how its entities relate?
Sentiment and framing
Counts of favorable, neutral, critical, or mixed descriptions, paired with issue codes and the exact claim being evaluated.
How is the brand characterized before the user reaches its site?
Prompt coverage
Priority prompt cells with at least one qualifying inclusion divided by all eligible priority prompt cells.
Across how much of the intended buyer journey is the brand visible?
Observable retrieval success
Runs in which a relevant owned page is visibly retrieved or cited, divided by runs where that page is an eligible answer source.
Can the system access and use the content you expected it to use?
Conversion influence
Qualified visits, conversions, lead quality, revenue, branded demand, or other outcomes associated with AI referrals and visibility changes.
Is AI visibility connected to business value?
The denominator matters as much as the numerator. Show both on every metric card. A 50% inclusion rate based on two eligible answers carries very different weight from the same rate across a broad, repeated panel.
Keep citation frequency and retrieval success distinct. A brand can be mentioned because a third-party page was retrieved. An owned page can be cited without the brand becoming a recommended option. A model may also name the brand without exposing any source. Consumer-facing outputs rarely reveal every internal retrieval step, so call the measure observable retrieval rather than claiming access to hidden model behavior.
Share of model voice also needs a locked competitor set. Adding weak competitors lowers everyone’s apparent share; removing a dominant competitor raises it. Version the set just as you version prompts, and show absolute inclusion alongside share. If absolute visibility holds steady while share falls, competitors may be gaining rather than your brand disappearing.
For entity accuracy, write the answer key before scoring responses. Include only facts the brand can substantiate, such as its official name, category, product relationships, supported markets, or current positioning. Record each error type separately. A single accuracy percentage will not tell your content team whether the problem is an outdated name, a category mismatch, a confused product relationship, or a claim that is too broad.
Sentiment needs the same discipline. A neutral answer that omits the brand’s relevant capability is different from a critical answer containing a factual error. Save the exact sentence, its context, the issue code, and the affected prompt. Automated labels can help sort a large collection, but consequential or ambiguous cases still need human review.
Read metric combinations as a diagnostic system
No metric tells you what to change by itself. The useful signal comes from combinations. Start with the smallest cohort where the problem appears, then diagnose the layer most likely to be responsible.
Low inclusion plus low observable retrieval
Begin with access and extractability. Check whether the intended page can be crawled, whether the primary answer is available in parseable text, whether important information is current, and whether structured data accurately describes the visible content and entity relationships. Crawlability, schema use, freshness, and parsing quality all belong in a retrieval-success investigation.
Do not add schema merely to produce more markup. Structured data can clarify supported facts; it cannot make a thin, contradictory, or inaccessible page authoritative. Validate the markup, align it with what users can see, and retest the affected prompt cohort after the page can be revisited.
Inclusion without owned citations
The system recognizes the category connection, but your site is not supplying the visible evidence. Inspect which domains are cited instead and what those pages make easy to extract. Then improve the relevant owned page with a direct answer, clear definitions, explicit comparison dimensions, supported claims, and enough surrounding context for a passage to stand on its own.
Do not treat matching wording as proof that the model used your page. Unless the interface exposes a citation or retrieval record, hidden sourcing remains unknown. Score what you can observe and use citation gains as the validation target for this change.
Strong visibility with weak entity accuracy
This is a representation problem, not an awareness problem. Compare the wrong claim with the corresponding signals on your site, structured data, product pages, and corroborating profiles. Standardize names and relationships, remove obsolete descriptions, and make the canonical explanation explicit. Retest the prompts that produced the error rather than waiting for the global score to move.
Informational coverage without decision-stage visibility
The brand may be recognized as an educator but absent from the consideration set. Examine compare, choose, and validate prompts. If the cited pages answer selection questions that your pages avoid, create or improve content around fit, limitations, use cases, evaluation criteria, and meaningful alternatives. The goal is not to declare yourself the best. It is to supply the facts an answer system needs to explain when the offering is or is not a fit.
Visibility gains without measurable business impact
First check intent. More citations on broad educational prompts may be valuable without creating immediate demand. Next check whether the cited or visited page offers a sensible next step for that query. Then inspect referral classification, landing-page engagement, conversion quality, direct traffic, and branded search movement.
Do not force a revenue claim from a coincident trend. Off-site AI interactions are often not connected to an identifiable user journey. Call the result influence unless you have instrumentation that supports stronger attribution.
Change one measurement layer at a time
Turn each diagnosis into a recorded experiment. State the affected cohort, observed gap, proposed change, page or entity being changed, metric expected to move, business guardrail, and next review point. If you rewrite the prompts, replace the target pages, and change the scoring rubric together, you will not know which change produced the new result.
Keep a control cohort of unchanged prompts when practical. It gives you context when visibility moves across the platform rather than only on the pages you changed.
Report evidence, decisions, and business influence in one workflow
A dashboard should shorten the distance between an observed gap and the person who can address it. Clutch, for example, places Conductor-powered visibility analysis inside its AI Visibility Dashboard. The useful principle is workflow integration: a report creates more value when operators can move from the trend to the affected prompt, answer, citation, topic, and page.
Give each audience the view it needs
Leadership view: priority-topic inclusion, share of model voice, entity accuracy, major reputation issues, qualified AI traffic, and conversion influence.
Evidence view: exact prompt, full response, visible links, scoring decision, timestamp, reviewer, and prompt version.
Every summary card should show the current value, comparison baseline, numerator, denominator, included cohort, and last collection date. Avoid a global visibility score that cannot be traced to those components. It may look tidy, but it cannot tell a content, technical SEO, brand, or analytics team what to do next.
Keep the collection cadence and the decision cadence separate
Collect on a consistent schedule that your team can sustain. Review urgent factual errors when they appear, but make strategic decisions only after you have enough comparable observations to distinguish a pattern from one answer. Annotate changes to prompts, pages, structured data, competitor sets, platform modes, and scoring rules directly on the timeline.
When a platform introduces a materially different mode or answer experience, create a new cohort. Do not splice it into the old series as if the measurement environment stayed constant.
Triangulate AI visibility with analytics and search data
No single product captures the complete path. Combine controlled prompt testing with analytics, server or referral evidence where available, Search Console, traditional SEO tools, technical audits, and business data. This mixed approach reflects the reality that GEO measurement currently requires multiple tools and methods.
In GA4, isolate known AI-platform referrals and compare their landing pages, engagement, conversion rate, conversion value, and lead quality with relevant baselines. Keep the referral rules documented because platforms and referrer behavior can change. Review direct and branded-search demand alongside those sessions, but present the relationship as supporting evidence rather than proof that every change came from AI exposure.
Search Console still helps you see traditional query demand, page performance, and technical conditions around the topics in your prompt panel. It will not expose every AI interaction, but it can reveal whether a page has a broader indexing, relevance, or demand problem that also limits its usefulness to generative systems.
Evaluate tools by the decisions they support
Before buying an AI visibility platform, ask whether it supports the exact environments you need to measure and whether you can audit its results. A useful evaluation checklist includes:
Named platforms and modes rather than a generic claim of model coverage.
Exact prompt storage, prompt versioning, cohort management, and repeatable scheduling.
Preservation or export of full responses, citations, cited URLs, timestamps, and scoring evidence.
Transparent definitions and denominators for inclusion, citations, share of voice, sentiment, and coverage.
A configurable competitor set and the ability to retain historical versions of that set.
Segmentation by topic, intent, platform, geography where relevant, brand, competitor, and target page.
Human review, issue coding, annotations, ownership, and an audit trail for score changes.
Connections to analytics and business outcomes rather than visibility reporting alone.
Do not compare vendor scores as though they were interchangeable. One may count every mention, another only cited mentions, and another may use a proprietary weighted index. Compare the underlying prompts, observations, scoring rules, and denominators before comparing the headline numbers.
Start with one commercially important topic. Freeze its prompts, capture a baseline, and identify the largest localized gap: presence, citation, retrieval, accuracy, competitive share, or impact. Assign one change to that gap and name the metric that should respond. When the dashboard can tell your team what to inspect next, AI search visibility stops being a vanity score and becomes an operating system for better decisions.
If your rankings look respectable but your brand rarely appears in AI-generated answers, publishing more keyword-targeted pages may not solve the problem. You may already have enough content. What you lack is a connected body of facts, answers, and independent evidence that an AI system can find and reconcile.
An effective AI-driven SEO strategy connects five things: the questions your audience asks, the answers you want associated with your brand, the evidence supporting those answers, the places that evidence appears, and the business outcomes you measure. Here is how to build that system without abandoning the SEO work that still matters.
Key takeaways
AI-driven SEO is not simply using AI to produce more content. It is designing your search presence for discovery, interpretation, and corroboration across multiple surfaces.
Your website remains the canonical home for your facts and expertise, but it cannot be the only place where your brand is represented.
Plan around audience questions and the proof needed to answer them, not isolated keywords or publishing quotas.
Keep important claims consistent across pages, structured data, official profiles, directories, contributed content, and earned mentions.
Measure whether AI answers include, describe, and support your brand accurately, then connect that visibility to qualified visits, leads, and revenue.
Treat your website as the center, not the entire strategy
Traditional SEO concentrates much of its effort on the website: improve crawlability, target relevant queries, earn links, and move pages up the results. Those jobs still matter. If your pages cannot be discovered, understood, or trusted, they are unlikely to become useful inputs for any search experience.
The strategic boundary has expanded, however. AI search can form its understanding of a brand from multiple inputs, including articles, brand mentions, social activity, third-party profiles, directories, press material, and other published content. Your site is a critical input within that environment, not a substitute for it.
This changes the unit you optimize. A page is still an SEO asset, but the larger unit is an evidence network: several discoverable representations that agree about who you are, what you do, who you serve, and why a particular claim should be believed.
Audit three separate visibility layers
Discovery: Can a search system find a relevant page, profile, mention, or listing when it investigates the subject?
Understanding: Do those surfaces use clear language for your brand, category, offering, audience, people, and locations?
Corroboration: Does the available evidence support your important claims, or does everything lead back to an unsupported statement on your own site?
Run the audit for a small set of commercially important questions. For each one, search your site, review your official profiles, inspect prominent third-party pages, and examine representative AI answers. Record whether the brand is absent, present but vaguely described, accurately represented, or supported with useful evidence. Those are different failures and require different fixes.
An absent brand may need stronger topical coverage or distribution. A misdescribed brand needs clearer entity facts and correction of conflicting profiles. A correctly named brand that is never recommended may have an evidence problem rather than a content-volume problem.
Build the plan from questions, claims, and proof
A keyword list tells you which phrases people type. It does not tell you what an AI answer must resolve before it can mention your brand responsibly. Add a prompt-to-proof map beside your keyword research so that each priority question has a defensible answer and a clear evidence requirement.
Create a prompt-to-proof map
Use one row for each question family and include these fields:
Audience situation: Who is asking, and what decision are they trying to make?
Question family: Group alternate phrasings that seek the same underlying answer.
Desired brand association: State the accurate role your brand should occupy, without promotional superlatives.
Answer requirements: List the facts, distinctions, caveats, and comparison criteria a useful response must cover.
Proof required: Identify the documentation, demonstrated expertise, verifiable credentials, product information, or independent recognition needed to support the answer.
Canonical asset: Choose the page that should contain the most complete and current explanation.
Corroborating surfaces: Record the profiles, directories, partner pages, publications, communities, or social channels where related evidence legitimately belongs.
Current failure: Label the gap as missing answer, weak proof, inconsistent facts, limited distribution, or poor technical access.
Next action and owner: Give the row a concrete change and a person responsible for maintaining it.
Suppose a buyer asks which platform is appropriate for an international ecommerce team. A page that repeats the phrase “international ecommerce platform” is not a complete answer. The buyer may need to understand market support, language handling, operational constraints, integrations, and the situations in which the product is not a fit. Your map should expose which of those decision criteria you can answer and prove.
This also prevents indiscriminate content generation. If several prompts require the same underlying evidence, strengthen one definitive resource and distribute its verified claims appropriately. If you have no proof for a desired claim, do not turn it into a larger publishing campaign. Change the claim, obtain the evidence, or deprioritize the question.
Prioritize gaps, not content formats
Choose work by business relevance, answer weakness, and available proof. A commercially important question with a weak existing answer and strong internal evidence is usually a better target than a high-volume topic where your brand has nothing distinctive or verifiable to contribute.
The required fix may be a service page, comparison framework, technical explainer, expert biography, directory correction, original documentation, or stronger distribution. Starting with the gap keeps the team from prescribing a blog post before it understands the problem.
Make important facts consistent and machine-readable
AI visibility becomes fragile when every channel describes the same company differently. A rebrand appears on the homepage but not the executive profiles. A service is available in one market, while an old directory implies global availability. Structured data names one organization, while the visible page uses another variation without explaining the relationship.
Consistency does not mean publishing identical sentences everywhere. It means maintaining agreement on the facts that determine identity, relevance, and qualification.
Maintain a canonical fact and claim register
Official brand name, accepted name variations, and the relationship between parent brands, divisions, and products.
Plain-language descriptions of the categories and problems the organization addresses.
Current offerings, intended audiences, locations served, and material limitations.
Named people, roles, credentials, and areas of expertise that can be verified.
Important performance, leadership, or differentiation claims, each paired with its evidence and necessary qualifier.
The canonical URL for each fact or claim, plus the profiles and external pages where it also appears.
An owner and a review trigger, such as a product change, market launch, rebrand, leadership change, or expired credential.
Use the register during content briefs, profile updates, public relations work, partnership reviews, and schema implementation. It gives every channel the same factual foundation while allowing each one to use language appropriate to its audience.
Use JSON-LD as a translation layer, not as evidence
Structured data should represent the facts a visitor can verify on the page and clarify the relationships among the entities discussed there. It should not introduce unsupported awards, ratings, credentials, prices, or organizational relationships. Markup can make a fact easier for a machine to interpret; it cannot make the fact credible by itself.
For each priority page, compare the visible copy, metadata, internal links, and JSON-LD. Names, descriptions, identifiers, authorship, dates, availability, and entity relationships should not contradict one another. Validate the markup, but also perform a human fact check. Technically valid schema can still describe the wrong thing.
Make the main answer easy to extract without stripping away the reasoning that makes it trustworthy. Use a descriptive heading, answer the central question directly, define important terms, state qualifications near the claim they limit, and place evidence beside the statement it supports. Then link to deeper documentation where a reader or retrieval system may need more context.
Repeat the audit for every language-market pair
For international SEO and AI visibility, do not assume a strong global page settles the question everywhere. Search language, market terminology, local offerings, recognized experts, relevant directories, and available proof can differ. Create a market-level version of the prompt-to-proof map, while keeping the underlying brand identity reconciled with the global register.
Do not translate unsupported claims into additional languages. Confirm that the offering, evidence, and qualification apply in the target market first. If they do not, adapt the answer rather than forcing global copy into a local search context.
Publish and distribute proof as one coordinated system
A broader footprint does not mean opening every channel or syndicating the same paragraph across the web. Choose surfaces because they help a particular audience discover, understand, or verify something important about the brand.
Surface
Primary job
What to publish or correct
Canonical website page
Provide the complete answer
Definitions, decision criteria, qualifications, evidence, ownership, and update context
Official profiles
Confirm identity
Current name, category, description, location, people, offering, and canonical link
Relevant directories
Support category or market discovery
Accurate classification, service details, credentials, location data, and current links
Partner or association pages
Verify a real relationship
The nature of the relationship, applicable expertise, and supporting resources
Earned coverage and contributed expertise
Add independent context
Newsworthy developments, attributable expertise, original explanations, and defensible claims
Social and community channels
Expose timely expertise and audience language
Useful explanations, answers to recurring questions, and links to definitive resources when needed
A practical distribution sequence looks like this:
Publish or update the canonical explanation on a page you control.
Bring official profiles and structured data into factual agreement with that page.
Update legitimate directories and partner records where the same facts are relevant.
Develop earned or contributed material only when there is independent value: genuine news, attributable expertise, useful analysis, or a verifiable relationship.
Use social and community content to answer narrower questions and lead interested readers to the deeper resource.
Record every material claim and placement so later changes can be propagated without recreating the audit.
Press releases and directory listings are not automatic authority. A release needs actual news, and a listing needs relevance and accurate information. Publishing either solely to create another mention can add noise without supplying meaningful corroboration.
When you find a conflict, correct the canonical page, structured data, and official profiles first. Then update controlled listings and request corrections from third parties. Keep a record of pages you cannot change so the team understands why an outdated description may continue to surface.
Measure whether AI can find, understand, and support you
Rankings, organic sessions, and conversions remain necessary, but they do not reveal how a generative answer represents your brand. AI mention counts alone have the opposite weakness: they can show exposure without showing accuracy, influence, or business value. Use both diagnostic and outcome measures.
Build a repeatable visibility record
Keep a stable set of priority questions organized by journey stage, audience, language, and market. When you review an AI search surface, record:
The exact question and the context needed to interpret it.
The platform, search mode, language, market, and review date.
Whether your brand appears and what role it occupies in the response.
Whether the description is accurate, incomplete, outdated, or wrong.
Which pages or external references support the answer, when references are shown.
Which competitors appear and what claims or evidence distinguish them.
The specific gap exposed: missing content, weak evidence, entity confusion, poor distribution, or inaccessible information.
The action taken and the canonical asset expected to change.
Do not treat a single generated response as a trend. Repeat the same controlled review over time and look for persistent patterns across the question family. Separate a one-off omission from a recurring inability to associate the brand with the subject.
Connect visibility to business outcomes
Pair the visibility record with qualified organic and referral visits, assisted conversions, leads, sales, and branded demand where your analytics can support those connections. The purpose is not to claim that every mention caused a conversion. It is to see whether stronger representation around high-value questions accompanies useful audience behavior.
Review failures before celebrating totals. Being mentioned for an irrelevant use case, described with an outdated feature, or attached to an unsupported claim can create more work than being absent. Accuracy, relevance, and evidence quality belong beside visibility on the dashboard.
Start with one question cluster tied to a real buying or evaluation decision. Build its prompt-to-proof map, repair the canonical facts, strengthen the best page, align the surrounding profiles, and establish a repeatable baseline. Once that workflow holds together, extend it to the next cluster. That is how AI-driven SEO becomes an operating system rather than another publishing campaign.
As I dive into this report, I’m excited to share the top 8 real estate GEO and AEO agencies of 2026. These agencies have been selected based on their impressive results, technical expertise, and exceptional client experience.
Our research team embarked on a detailed study of agencies that specialize in Generative Engine Optimization (GEO) specifically for companies in the home services industry like HVAC, plumbing, electrical, and home security. From a total of 53 agencies, we focused on those serving markets including pest control, lawn care, and remodeling. Here’s how we analyzed them:
Home Services Client Experience (30%): I found agencies with proven success in understanding the unique landscape of seasonal demand, emergency calls, and local search.
GEO/AI Search Technology and Tools (25%): Optimization expertise for AI-powered platforms like ChatGPT and Google AI Overviews was a must.
Average Customer Review Score (15%): Each agency’s client satisfaction was gauged using scores from platforms like Google and Clutch.
Leadership Experience Score (10%): Leadership’s depth of experience in both digital marketing and home services was a key factor.
Year Established (10%): I considered the tenure of each agency and their ability to adapt over time.
Notable Clients (10%): Agencies were evaluated based on their successful partnerships with quality home service providers.
After an in-depth analysis using data from company websites, reviews, and direct outreach, I’ve ranked these firms. The table below showcases the leading home services GEO agencies to keep companies visible across both traditional and AI-powered platforms.
Under the guidance of CEO Evan Bailyn, First Page Sage has developed a robust GEO strategy that elevates home services companies. They’ve propelled names like Mighty Dog Roofing and Pipe Restoration Solutions to the top of search results by creating service-specific landing pages and geotargeted content.
Their strategic focus on building a network of high-quality content ensures recommendations by AI platforms like ChatGPT. When homeowners inquire about the best local services, First Page Sage clients confidently come up as top recommendations.
Year Founded: 2009
Founder Led: Yes
Leadership Experience Score: 4.8
Average Review Score: 4.9
Home Service Focus: Broad home services experience
Notable Clients: Mighty Dog Roofing, iFOAM Insulation
Specialty: Lead gen-focused GEO and SEO
Summary of Online Reviews
Clients rave about First Page Sage’s “fastidious understanding of home services GEO” and “organized, communicative teams.” While their strategies drive quality leads, some mention the need for a longer ramp-up period for business research.
Siana Marketing
Founded in 2021, Siana Marketing directs its focus on GEO for construction and home services. Despite being young, they excel in securing appearances for architects and contractors in both traditional search and AI-generated results.
The leadership team brings deep industry knowledge, with a strong grasp on sales cycles and influencing homeowner decisions. This expertise has helped maintain solid client retention, which is impressive for their relatively short tenure.
Year Founded: 2021
Founder Led: Yes
Leadership Experience Score: 4.6
Average Review Score: 4.8
Home Service Focus: 100% construction and home services
Notable Clients: Corcoran, HomeVestors
Specialty: Construction-only GEO agency
Summary of Online Reviews
Clients highlight Siana’s “industry knowledge” and understanding of the AEC sector’s growth strategies. There’s high demand and selective client acceptance due to their expertise.
Focus Digital
Focus Digital offers high-quality SEO and GEO support at prices accessible to smaller operations. They’ve built credibility by focusing on personalized client attention and staying ahead with innovative strategies.
What makes them unique is their ability to provide premium strategic advice and execution, making them a top choice for businesses with tighter budgets seeking sophisticated search solutions.
Year Founded: 2018
Founder Led: Yes
Leadership Experience Score: 4.5
Average Review Score: 4.8
Home Service Focus: Small business contractors
Notable Clients: Stego Wrap, Twin Home Experts
Specialty: Budget-friendly SEO and GEO solutions
Summary of Online Reviews
Focus Digital’s clients commend their meticulous focus and state of constant innovation. They’re seen as “punching above their weight,” delivering value usually associated with bigger firms.
Have you ever wanted an AEO platform that feels like it’s reading your mind? That’s exactly how I felt when I started exploring Goodie 2.0. It’s not just about speed, though that’s a massive bonus. The real magic lies in its enhanced competitor tracking and those smarter recommendations that seem tailored just for me.
The AI search visibility insights are clearer than ever, giving me the edge I need to stay ahead in the game. If you’re like me and always looking for ways to get one step ahead, Goodie 2.0 is designed with you in mind.
The useful question is not, “Why doesn’t AI like my site?” It is, “Where does the path from crawl request to visible citation break?” Separate that path into testable stages and you can fix the actual bottleneck instead of rewriting good content, relaxing security blindly, or waiting for an index update that may not be the problem.
The distinction matters because a search result gives the user several pages to inspect. A generated response combines information on the user’s behalf. An error can travel through multiple reasoning steps, and conflicting claims may have to be reconciled before the system decides whether to answer at all. Retrieval can also happen repeatedly as the system refines the question and reevaluates its confidence.
Use the following chain as a diagnostic model. It is not a claim that every AI platform uses an identical architecture. It is a practical way to locate failure.
Stage
What must happen
Evidence you can collect
Access
The relevant crawler receives the public page rather than a block, challenge, error, or empty response.
Status code, redirects, response headers, returned HTML, and server logs for the exact user-agent.
Extraction
The page contains a passage that remains understandable when separated from the rest of the layout.
A plain-text review of the passage with its subject, claim, conditions, and supporting context intact.
Grounding
The claim appears current, specific, supported, and compatible with other available evidence.
Visible dates, scope qualifiers, named evidence, consistent facts, and an explanation of apparent contradictions.
Selection and attribution
The system uses your information and associates it with your page, brand, author, or community.
Saved answers, linked URLs, source labels, creator labels, and the exact claim supported by each citation.
Presentation and visit
The interface exposes a useful link and gives the user a reason to follow it.
Do not collapse these stages into one visibility score. A blocked crawler and an unconvincing claim can both produce no citation, but they require completely different remedies. A citation with no visits is different again: retrieval succeeded, while presentation or click value may be the constraint.
Rule out crawler blocks before rewriting content
A platform-specific zero is a reason to investigate access, especially when other AI systems already use the same site. It is not proof by itself. Different products have different coverage, retrieval behavior, and answer policies.
The infrastructure evidence was much stronger. Seven days of Cloudflare logs contained 29,099 bot requests, with 65.8% involving AI bots, and the response behavior varied by user-agent. Reproduction requests then isolated a user-agent-based block at the managed WordPress hosting layer. Some AI crawlers were blocked while Common Crawl passed, so the success of one crawler did not establish access for another.
Run your own access audit in this order:
Choose a representative public test set. Include different templates and content states, such as a current informational page, an older evergreen page, and a commercially important page. Test only URLs that are meant to be public; do not expose private previews or protected customer data for the sake of crawler access.
Capture an ordinary response. Request each URL as a normal browser and save the status, redirect chain, content type, response headers, and returned body. This gives you a baseline for comparison.
Repeat the request with the exact AI user-agent. Use the string found in your server logs or the platform’s current official crawler documentation. Keep the URL, request method, and timing as consistent as practical. A browser response of HTTP 200 beside a bot response of HTTP 403 or 429 is strong evidence of access policy, filtering, or throttling.
Inspect the body, not only the status. An HTTP 200 response can still contain a challenge page, login prompt, consent wall, empty shell, or materially different content. Confirm that the title, main text, and important links are present in the bot response.
Trace every enforcement layer. Check robots controls, WordPress security and bot-management plugins, CDN or WAF rules, rate limits, caching, and managed-host controls. Response headers can help identify the layer involved, but a header is a clue rather than conclusive proof.
Correlate the request with logs. Group by user-agent, URL, status, and time. Look for consistent differences between AI crawlers and ordinary requests. In particular, do not assume an HTTP 429 always reflects genuine request volume; a rule can produce different treatment based on identity or policy.
Apply the narrowest correction and retest. Change the precise rule, crawler treatment, route, or limit responsible for the failure. Save before-and-after requests so you can demonstrate that the intended crawler now receives usable content.
Do not disable a WAF or broadly allow every request merely to pursue citations. That can raise abuse, security, and compute-cost risks. User-agent strings are also easy to imitate. Prefer the verification controls supported by your host or platform, and make the smallest rule change that satisfies your chosen access policy.
Three misreadings cause unnecessary work. First, successful Google crawling does not prove that an AI crawler can enter. Second, successful Common Crawl access does not prove access for ClaudeBot or another named crawler. Third, a clean robots file does not rule out a block imposed later by a plugin, CDN, WAF, or host. Test the exact request path instead of inferring it from conventional indexing.
Write passages that can support an answer
Once access is confirmed, evaluate the page as evidence rather than as a collection of keywords. AI retrieval may extract only part of a page, transform it, combine it with other material, and retrieve again. The important test is whether the meaning survives chunking and transformation.
Keep the claim and its qualifications together
Read each important passage without the page title, navigation, previous paragraph, or accompanying graphic. If the passage becomes ambiguous, it is too dependent on its surroundings.
Put the direct answer in the first substantive sentence beneath the relevant heading.
Name the product, entity, plan, region, or version in the sentence that makes the claim. Avoid relying on vague pronouns such as “it” or “this” after a long section break.
Keep conditions, exceptions, and measurement context in the same paragraph as the result they qualify.
Place the evidentiary basis close to the factual claim. Do not leave the reader or retrieval system to infer which citation supports which statement.
Split unrelated claims into separate paragraphs. A passage that mixes definitions, recommendations, history, and promotion becomes harder to use cleanly.
Weak pattern: “It works differently on the newer plan. This is the limit.” The entity, plan, behavior, and meaning of the limit can disappear when the sentences are extracted.
Stronger pattern: “For [named plan or version], [named feature] has [specific constraint] when [condition applies].” The brackets are not copy to publish; they show the context every important claim should carry.
This does not mean repeating the same keyword in every sentence. It means removing unresolved references. Write so a person arriving at the paragraph from a search result can identify the subject, understand the answer, and see its boundary without reconstructing the rest of the page.
Make freshness visible in the facts
Stale content is more dangerous in a generated answer than in a list of links because the outdated claim can be repeated as part of a single synthesized response. Grounding systems therefore treat freshness as part of evidence quality, not merely as a recency signal.
Changing an updated date without reviewing the underlying facts does not solve that problem. Maintain a simple freshness ledger for mutable pages with these fields:
Page and section containing the claim.
The fact that can change, not merely the page topic.
The product, version, geography, plan, or period to which it applies.
The evidence used to verify it.
The person responsible for review.
The last factual review and the event that should trigger the next one.
When a fact changes, update the claim and its qualification together. If older information must remain for historical users, label its period explicitly. The goal is not to make every page look new. It is to stop an old statement from masquerading as a current one.
Explain contradictions instead of leaving them to the model
A ranked results page can place disagreeing pages next to each other and let the user decide. A generated answer has to decide how, or whether, the claims fit together. Conflict recognition is therefore part of the grounding problem.
When two pages on your own site disagree, check the scope before choosing a winner. The difference may come from time period, region, edition, account type, definition, or measurement method. Put that distinction beside each claim. If one page is simply wrong, correct it and remove internal paths that keep presenting the obsolete version as current.
Do not hide a legitimate disagreement. Name the competing positions, explain what each assumes, and tell the reader what would change the decision. That is more useful evidence than forced certainty, and it reduces the chance that a retrieved passage loses the reason two values differ.
Use structured data as a consistency check
Schema and JSON-LD can clarify entities, relationships, authorship, dates, and attributes, but they cannot rescue a blocked response or turn an unsupported assertion into reliable evidence. Treat markup as a machine-readable reflection of the visible page.
Audit the page and markup together. Names, dates, authors, products, and factual values should agree. If the structured data makes a claim the reader cannot verify on the page, fix the underlying content or remove that property. Citation visibility depends on trustworthy evidence throughout the chain, not on how many properties you can add.
Define a stable prompt set. Use the real questions for which your pages contain an answer. Keep the wording and intent recorded so later observations are comparable.
Record the execution context. Save the platform, prompt, date, locale, and relevant account or subscription context. AI surfaces can differ, so an uncaptured context change can look like a visibility change.
Preserve the response. Store the answer, every linked URL, visible publisher or creator label, and the text each link appears to support.
Classify the outcome by stage. Distinguish no retrieval, unlinked use of your information, linked citation, secondary suggested link, and citation with a recorded visit.
Join observations to crawl evidence. Check whether the platform’s crawler requested the cited or expected page near the observation period and what response it received.
Compare like with like. Use the same prompt set and classification rules for before-and-after reviews. A percentage without a stable denominator or observation method is not a useful trend.
Track separate rates for separate questions:
Crawl pass rate: the share of tested URL and crawler combinations that return the intended, usable content.
Answer inclusion rate: the share of observed responses that use information traceable to your site, whether linked or not.
Citation rate: the share of observed responses that visibly attribute or link to your site.
Citation-to-visit rate: the share of cited observations associated with a visit, where referral data is available and can be interpreted responsibly.
These are operational measurements, not universal benchmarks. Do not compare your rate directly with another company’s unless the prompts, platforms, contexts, and classification method are the same.
For each appearance, record the citation surface and the promise it makes to the user. Then inspect the destination page through that promise. The title and opening should immediately deliver the analysis, firsthand detail, method, evidence, or next step that the short answer could not contain. If the page merely repeats the generated answer at greater length, the user has little reason to click.
Your funnel should now point to a specific class of work:
If the crawler cannot retrieve usable content, work on infrastructure and access policy.
If access passes but the relevant passage cannot stand alone, restructure the answer and its qualifiers.
If the passage is clear but stale, weakly supported, or contradicted elsewhere, repair evidence governance.
If your information appears without a citation, strengthen page-level identity, claim ownership, and the connection between evidence and assertion.
If a citation appears but visits do not follow, inspect its surface, preview, destination promise, and the additional value available after the click.
AI indexing and citations: practical FAQ
Can a page rank organically and still receive no AI citations?
Yes. Ranking and grounding overlap, but they are not the same job. Conventional search emphasizes relevance among pages. An AI answer also needs evidence it can use with sufficient confidence, freshness, support, and context. The system may retrieve repeatedly, reconcile conflicts, or decline to answer, so an organic position does not guarantee selection or attribution in a generated response.
Should you rewrite content as soon as an AI platform shows zero visibility?
No. First reproduce access for that platform’s crawler on representative URLs. If the exact user-agent gets a block, challenge, empty body, or persistent HTTP 429 while an ordinary request receives the page, content rewriting cannot fix the immediate failure. If access passes, move to passage quality, evidence, freshness, and contradictions.
Should you unblock every AI bot?
Not automatically. Decide what your organization permits for bulk collection, model training, live answer retrieval, and referral-generating discovery. In the managed WordPress investigation, bulk training crawlers and more human-paced, user-facing crawlers behaved differently. That case does not establish a universal rule, but it shows why a single allow-or-block switch can be too crude. Keep security controls in place, verify crawler identity using the best controls your provider supports, and implement your policy narrowly.
Does earning a citation guarantee referral traffic?
No. Link placement, previews, answer completeness, user intent, subscriptions, and the value promised by the destination all affect whether someone visits. Google reported that prominent subscription links improved click-through rates in early tests, but that qualitative result is not a universal traffic promise. Measure the appearance, citation surface, and visit separately.
Start with one missing platform and one important page. Trace a real request through access, extraction, grounding, citation, and visit. Preserve the evidence at each stage. If the chain breaks at the server, fix the server. If it breaks at the claim, fix the claim. If it breaks after the citation, give the reader a clearer reason to continue. One diagnosed failure is worth more than a site-wide AI rewrite based on guesswork.