Tag: AI Models

  • Google Nano Banana 2: A Practical Workflow for Marketers

    Google Nano Banana 2: A Practical Workflow for Marketers

    You have a campaign brief, not an afternoon to spend rerolling images. The asset needs readable copy, stable people and products, multiple formats, and localized versions. Someone also needs to know exactly what changed between creative variants.

    Google Nano Banana 2 can carry more of that production workload, but only if you treat it as part of a controlled creative system. The useful shift is not simply better-looking output. It is the ability to move from a structured brief to a consistent family of assets with fewer compromises between speed, detail, text, and continuity.

    What Nano Banana 2 changes in an image workflow

    Nano Banana 2 is the informal name for Gemini 3.1 Flash Image. Google DeepMind has positioned it as a combination of Nano Banana Pro’s image intelligence and Gemini Flash’s faster generation. For a marketing team, that combination matters because image quality and iteration speed normally pull the workflow in opposite directions.

    The model’s improvements map to four practical jobs:

    • Knowledge-heavy visuals: Real-time web grounding can bring current context into infographics and data-oriented images. Treat that as assistance with generation, not proof that a visual is factually correct.
    • Images containing words: Improved text rendering and translation make social graphics, diagrams, promotional cards, and localized creative more viable. Every visible word still needs human proofreading.
    • Scenes that must remain recognizable: Stronger instruction adherence and subject consistency make it easier to preserve the same cast, objects, visual hierarchy, and art direction during revisions.
    • Assets for different placements: Supported output extends from 512px through 4K, so the same workflow can cover lightweight concepts and high-resolution deliverables.

    The documented consistency envelope reaches up to five characters and 14 objects in one workflow. Read that as an upper capability boundary, not a guarantee that a crowded scene will remain perfect. The closer your composition gets to the limit, the more deliberate your naming, placement, and review need to be.

    Key takeaways

    • Use Nano Banana 2 for repeatable asset families, not just isolated image generation.
    • Write prompts as production briefs with explicit priorities, subjects, composition, copy, and output requirements.
    • Approve one master image before generating formats, languages, or test variants.
    • Verify every word, number, label, and data point even when web grounding is involved.
    • Keep important page meaning in HTML and metadata rather than leaving it trapped inside an image.

    Turn the prompt into a production brief
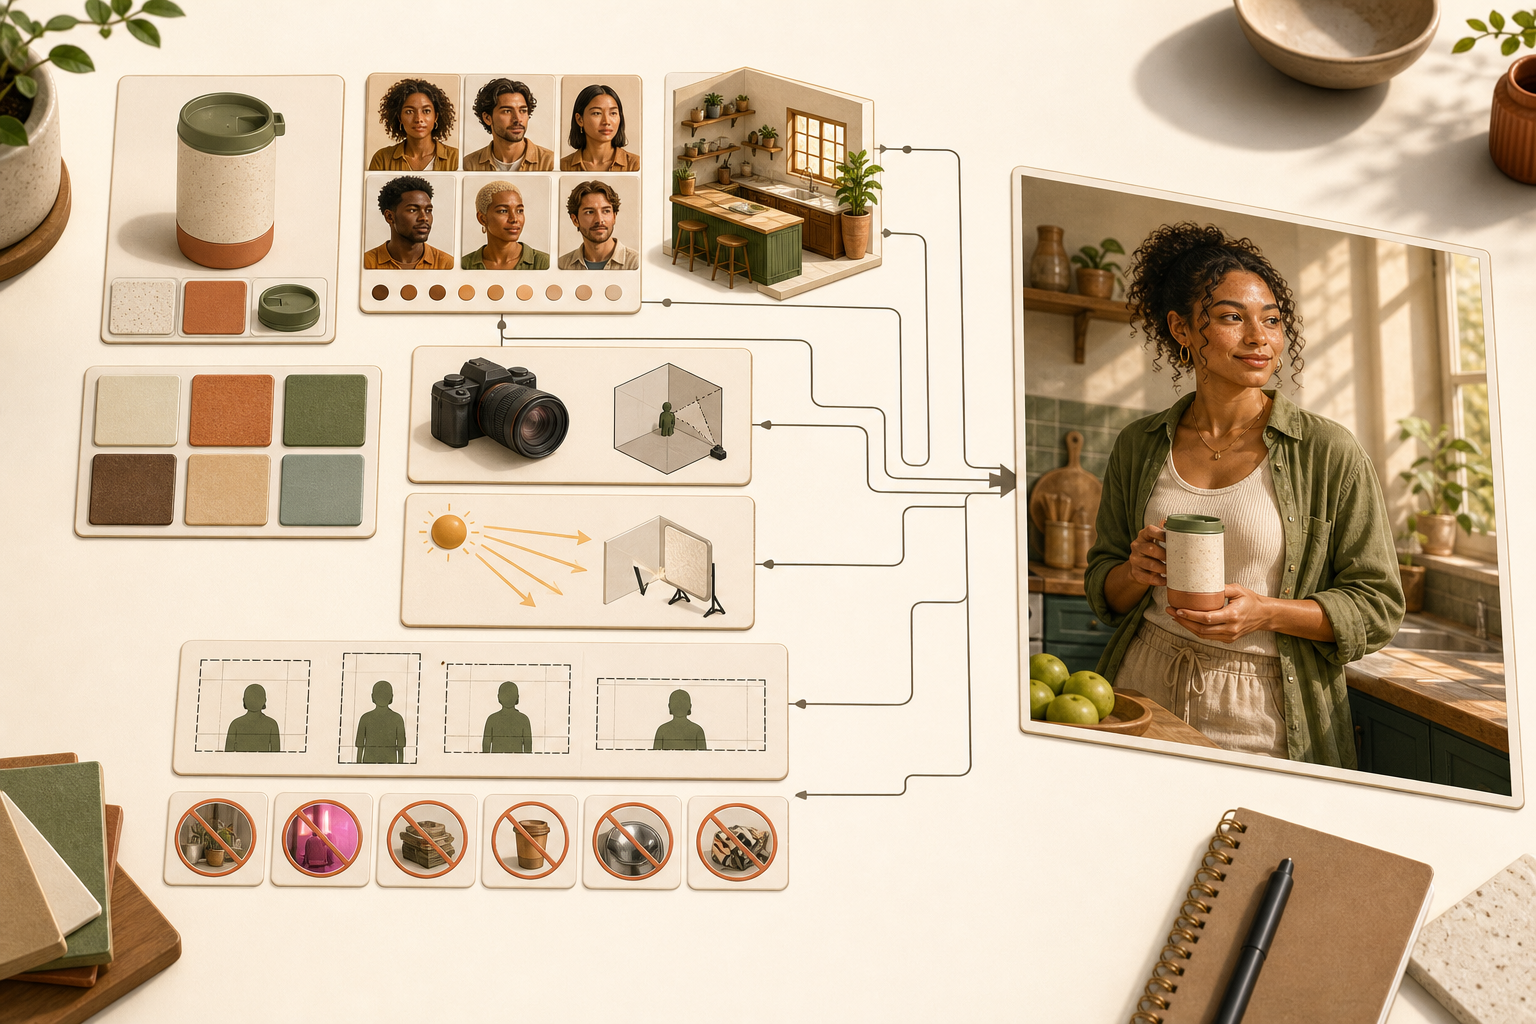
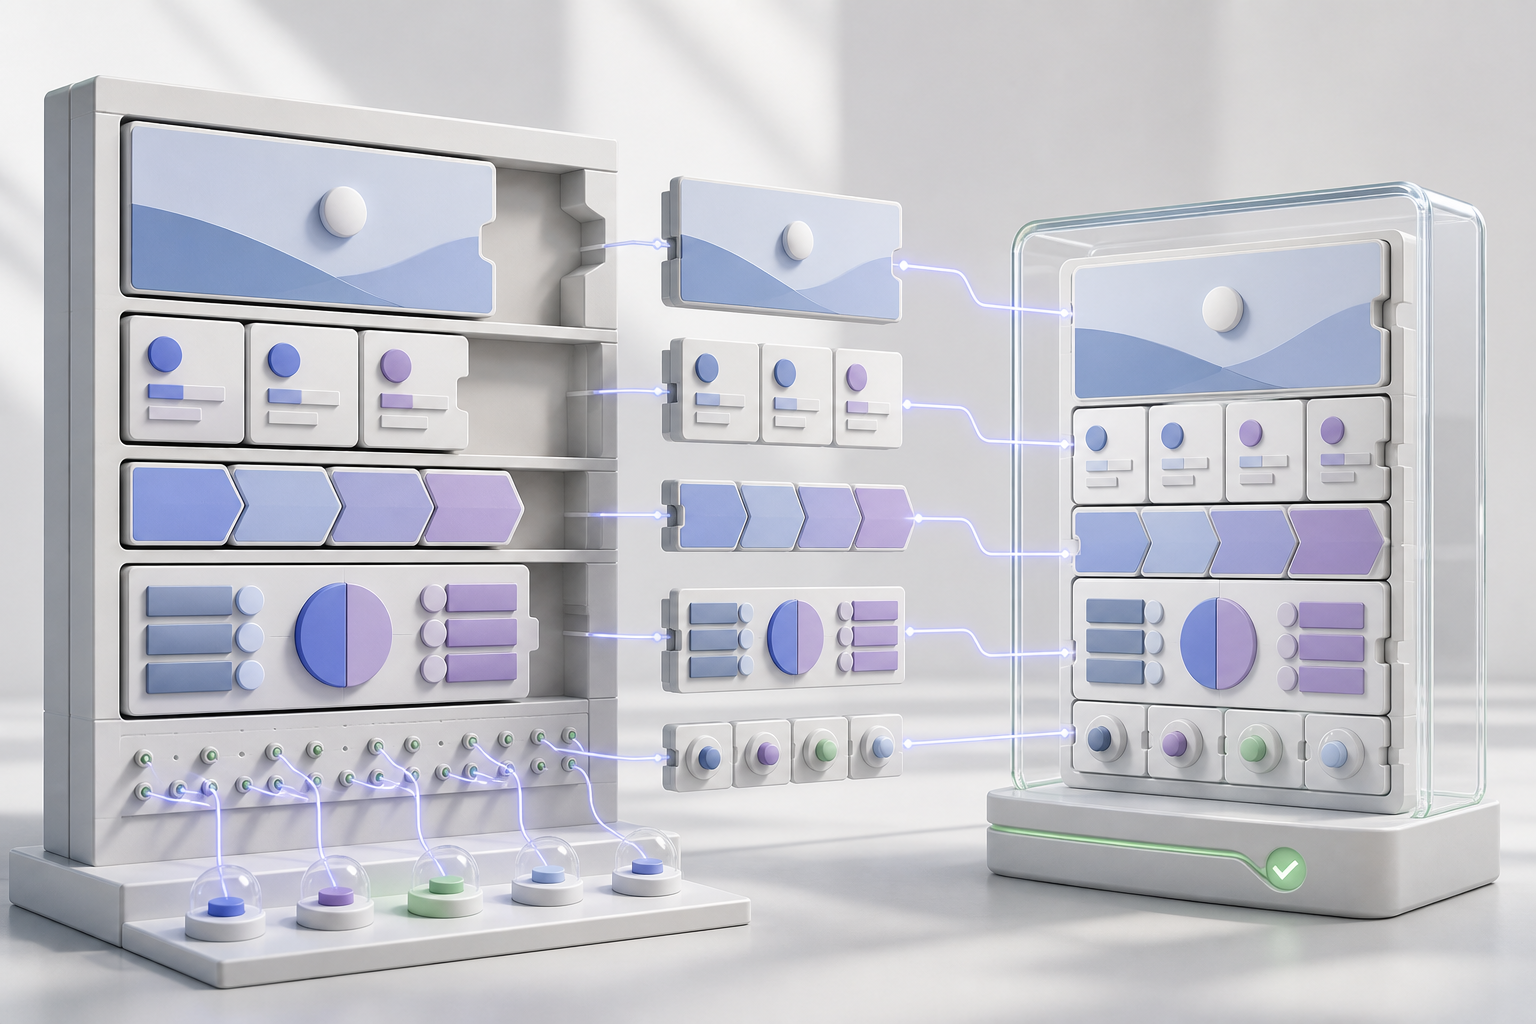
    Visual reference tiles for a mug, customer, kitchen, colors, lighting, and image formats connect to a finished campaign image.

    Stronger instruction adherence is only useful when the instructions have a clear hierarchy. A loose collection of adjectives leaves the model to decide what matters. A production brief tells it what the asset must accomplish, what cannot change, and where it has room to interpret.

    1. Start with the asset’s job. Name the destination and the action the visual should support: a landing-page hero, an ad variant, a report cover, a diagram, or a localized social card. This gives the composition a reason to exist.
    2. Define the required subjects. List each person, product, interface, or meaningful object. Give recurring subjects short, stable labels so later instructions can refer to them without ambiguity.
    3. Specify spatial relationships. State what belongs in the foreground, where the main subject sits, which direction a person faces, and where clear space is required for external copy or controls.
    4. Describe the visual system. Set the palette, lighting, texture, level of realism, camera perspective, and overall mood. Use concrete visual properties rather than piling up subjective terms such as premium, bold, or modern.
    5. Supply text as exact copy. Separate the headline, labels, supporting text, and language. If a phrase must not be translated, say so. Do not bury critical wording inside a long paragraph of art direction.
    6. Name the output requirements. Include the intended aspect ratio, supported resolution, crop needs, and any areas that must remain uncluttered. Request 4K when the approved asset actually needs it, not by default for every concept.
    7. Declare the invariants. Say which identities, objects, colors, text, and layout relationships must remain unchanged across revisions.

    A reusable prompt pattern

    Goal: Create a 4K landscape hero image for a landing page promoting a search visibility report. Subjects: Show one analyst at a desk and one dashboard object displaying a clean line chart. Composition: Place the analyst and dashboard on the right, with the left third uncluttered for an HTML headline. Visual direction: Use deep navy, off-white, and restrained cyan accents, with soft directional lighting and realistic textures. Restrictions: Do not add logos, watermarks, interface labels, extra screens, or text inside the image. Continuity: Keep the analyst’s appearance, dashboard layout, palette, and lighting unchanged in later variants.

    This example deliberately reserves the headline for HTML. That is usually the cleaner choice for a web hero because the copy remains editable, selectable, responsive, and available to assistive technology. Use embedded text when the words are part of the artifact itself, such as a social card, diagram label, poster, or standalone ad creative.

    For an image that needs embedded copy, add a separate instruction such as On-image copy: Q3 Search Visibility Report. Then identify the exact location, hierarchy, and language. Keeping copy in its own instruction makes proofreading and localization easier.

    Follow-up prompts should be smaller than the original brief. Ask to change one controlled element while restating the invariants: replace the background environment, change the accent color, translate the approved copy, or adapt the crop while preserving the subjects. Rewriting the entire prompt for every revision invites unplanned changes.

    Build variants without losing control of the experiment
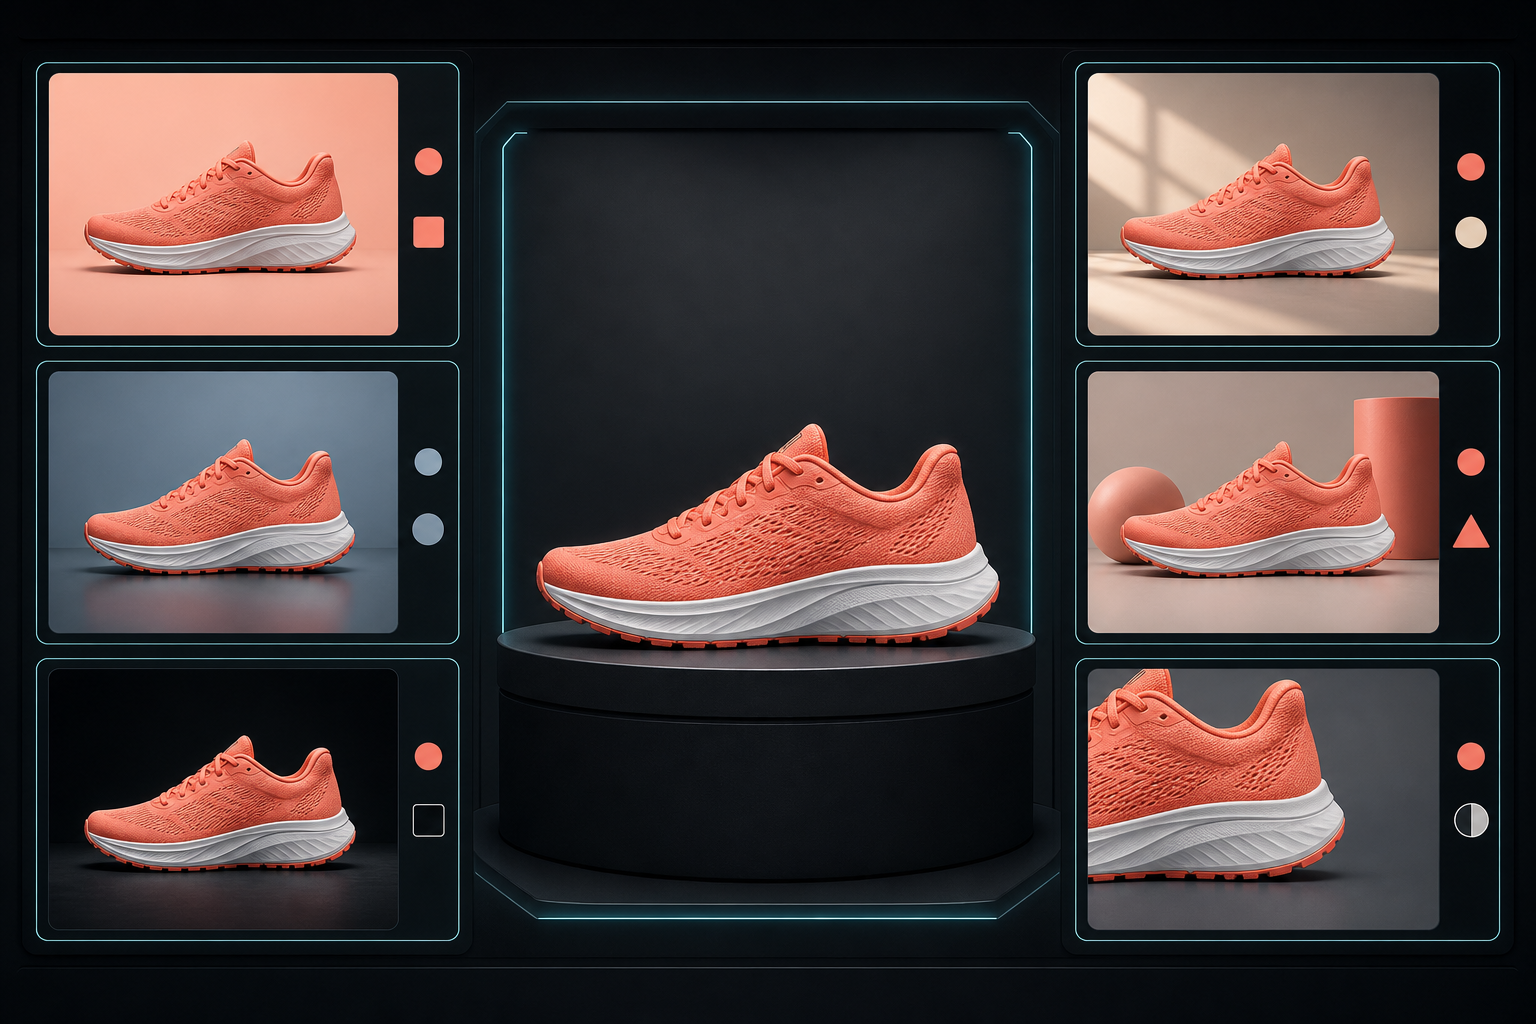
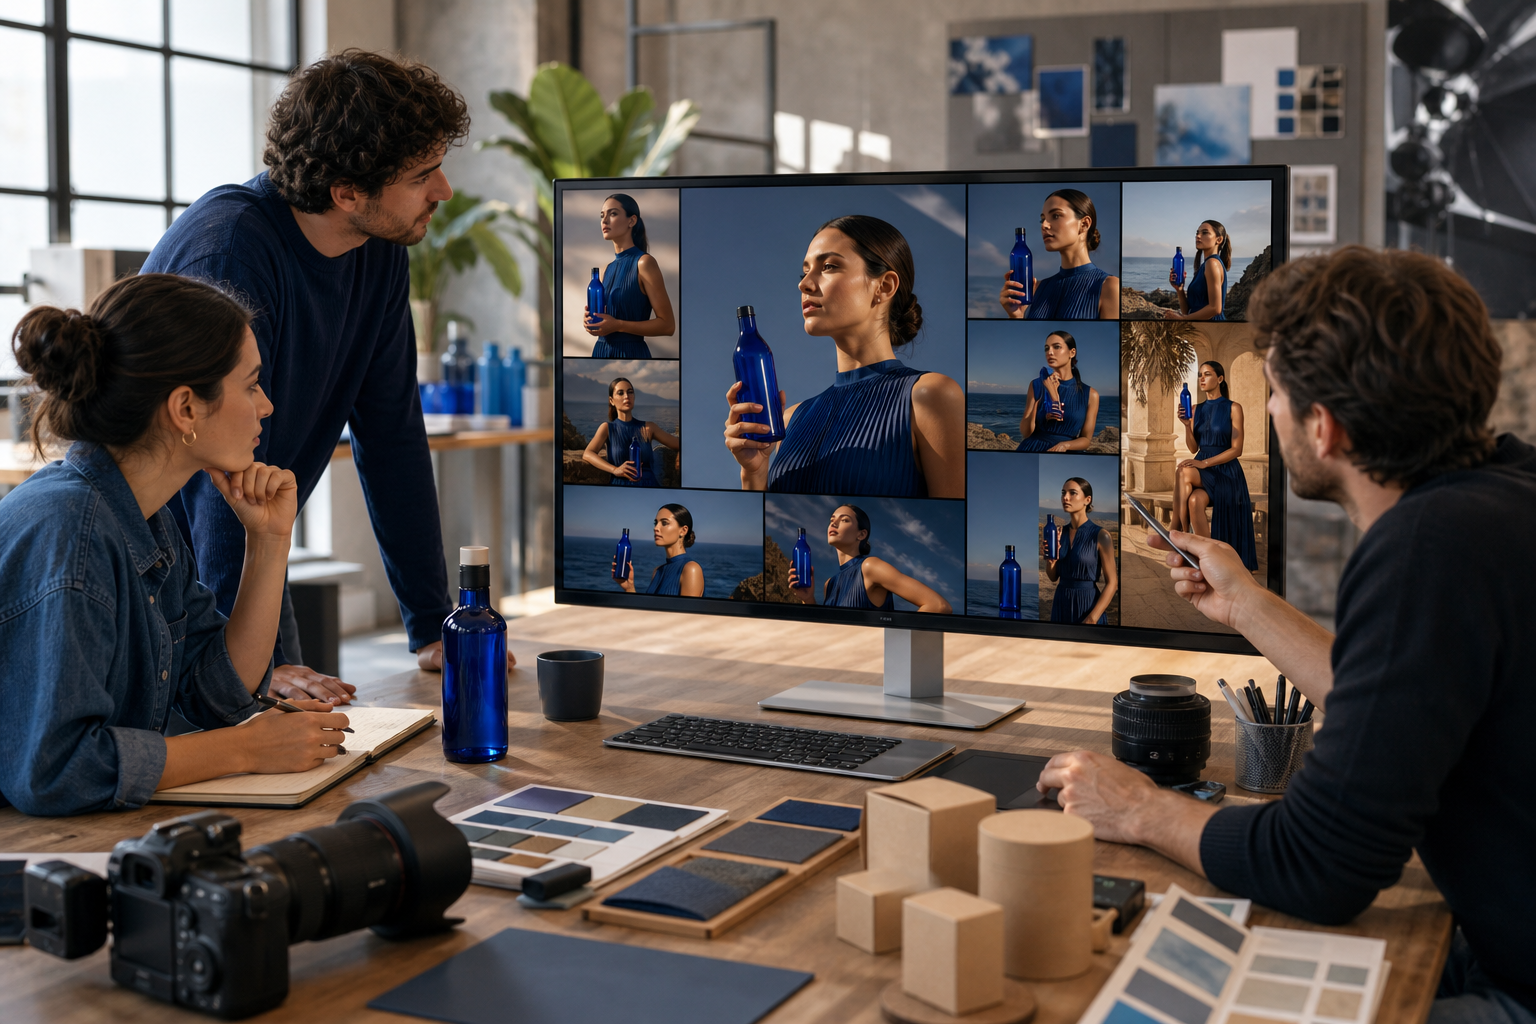
    Six campaign previews preserve the same coral running shoe and fictional athlete while changing backgrounds, lighting, props, and crops.

    Fast generation can create a false sense of progress. Twenty visually different outputs are not a useful test if the headline, palette, composition, subject, and offer all changed together. You will know which image performed better, but not why.

    Use a master-and-variant workflow instead:

    1. Generate a baseline. Produce the first complete interpretation of the brief before requesting alternatives.
    2. Review against the brief. Separate objective misses, such as incorrect text or a missing object, from subjective preferences, such as wanting warmer lighting.
    3. Correct the baseline. Do not build variants from an image that already violates the required composition, copy, or identity.
    4. Approve a master. Record the accepted prompt, output, invariants, language, and intended placement.
    5. Create one-variable variants. Change one meaningful family of attributes at a time, such as the background, focal framing, callout treatment, or color emphasis.
    6. Localize after visual approval. Preserve the master composition while changing the language-specific copy, then allow only the layout adjustments required by the translated text.

    Your review should use explicit gates rather than a general looks-good decision:

    • Brief compliance: Are all required subjects present, and are unwanted additions absent?
    • Continuity: Do recurring people, products, and objects remain recognizable across versions?
    • Copy: Does every character match the approved wording, including punctuation, capitalization, and product terms?
    • Factual content: Do chart labels, values, dates, maps, and explanatory elements match the information you intend to publish?
    • Visual integrity: Are faces, hands, object boundaries, reflections, lighting, and small details internally coherent?
    • Placement safety: Will important content survive the real crop, overlay, and responsive layout?
    • Delivery: Does the final file have the resolution and aspect ratio required by its actual destination?

    Web grounding does not remove the factual review gate. It can help the model reason about the requested subject, but it cannot approve a statistic, establish which date your campaign should use, or decide whether a generated chart supports your claim. Keep the underlying facts in a separate, human-reviewed content sheet and compare the rendered visual against it.

    The same discipline applies to translation. Generate the localized version, copy the visible wording out of the image, and compare it with approved language line by line. Check line breaks and hierarchy as well as meaning; a correct translation can still become unreadable when it is forced into the original layout.

    Nano Banana 2 is integrated into Google Ads as well as the broader Gemini ecosystem, which makes rapid campaign variation an obvious use case. Keep the creative test interpretable: hold the audience, offer, and measurement setup steady when the purpose is to learn whether a visual change affected performance.

    Finish the asset for SEO, AEO, and GEO

    A production-quality image is not automatically a search-ready asset. Image generation creates pixels. Your publishing workflow must connect those pixels to the page’s subject, the user’s task, and machine-readable context.

    Keep the meaning outside the pixels

    • Match the search intent. Use the image to clarify the answer, process, entity, comparison, or result the page is actually about. A polished but generic visual adds little retrieval value.
    • Write functional alt text. Describe the information or purpose the image contributes in its context. Do not paste the generation prompt or turn the attribute into a keyword list.
    • Use descriptive filenames. Name the finished asset for its actual subject and role rather than preserving a generator’s default filename.
    • Publish essential facts as HTML. If an infographic contains a process, statistic, or comparison that the reader needs, provide the same core information in nearby page text. Do not make people or search systems depend on reading pixels.
    • Add a useful caption when context is needed. A caption should explain why the visual matters, not merely repeat what it depicts.
    • Create delivery derivatives. Keep a high-resolution master, but serve a file sized and compressed for the placement. Sending a 4K image everywhere can add page weight without improving the reader’s experience.
    • Localize the surrounding context. When you translate text inside an image, update the filename, alt text, caption, nearby explanation, and linked destination for the same audience.

    Treat structured data as a record

    If your page’s structured data references the image, the markup should describe the asset that is visibly published at the live URL. Keep the image URL, dimensions, caption, creator information, and licensing information aligned with what you can substantiate. Do not manufacture metadata simply to fill properties.

    JSON-LD does not rescue a weak relationship between the visual and the page. The image, headline, body copy, captions, internal links, and structured data should all describe the same primary subject. That consistency gives search engines and answer systems a clearer entity-and-context relationship to interpret, although it cannot guarantee rankings, citations, or inclusion in an AI-generated response.

    This is also where subject consistency becomes strategically useful. Reusing a recognizable product, character, diagram language, or branded visual system across a related content cluster can make the collection feel coherent. Keep each asset specific to its page, however; duplicating one generic image across every URL does not explain what makes those pages different.

    Choose a pilot that exposes the model’s real value

    Do not judge Nano Banana 2 by asking it for a single decorative image. That tests whether it can produce an attractive picture, not whether it can improve your production system.

    Our rule of thumb is to choose a pilot that needs at least two of the model’s differentiating capabilities:

    • A recurring person, product, or object that must remain consistent.
    • Exact words or labels inside the visual.
    • Several controlled creative variants for a campaign.
    • Localization into more than one language.
    • A knowledge-heavy infographic or data visualization.
    • Outputs ranging from smaller concept images to a 4K master.

    A strong pilot might be a report launch that needs a hero image, a labeled social card, ad variants, and localized editions. One approved visual system can then be carried through each placement while the team measures generation time, correction cycles, consistency, proofreading effort, and final usability.

    Begin concepts at the smallest supported resolution that lets your team judge composition. Move to 4K after the direction is approved. This keeps reviewers focused on the idea before they spend time inspecting final-level detail.

    The model is available across Google Ads, the Gemini app, Search AI Mode, Lens, and other parts of Google’s ecosystem. That reach makes shared governance more important than platform-specific habits. Store the master brief, approved copy, invariants, final asset, localization decisions, and QA result together so the next person can reproduce the workflow.

    Pick one recurring campaign asset this week. Define its invariants, create one approved master, and generate a single controlled variant. If the model preserves the subject, copy, composition, and visual system through that cycle, you have evidence for expanding the workflow. If it does not, the QA record will show whether the problem came from the brief, the generation, or the review process.

    References


  • How to Use AI Response Patterns to Build Better Content

    How to Use AI Response Patterns to Build Better Content

    You ask an AI assistant which product, service, or method it recommends. Your brand appears. You run the same prompt again, and it disappears. If you build a content brief around either answer, you may be optimizing for an accident.

    The better unit of analysis is the pattern across many answers. Repeated structures, concepts, comparisons, and entity associations can show you what a model consistently treats as relevant. Once you separate those durable signals from one-off wording, AI responses become useful inputs for content planning rather than volatile rankings to chase.

    Key takeaways

    • Do not treat one AI answer, citation, or brand mention as a ranking result.
    • Test several phrasings of the same intent across at least two model families and repeated runs.
    • Keep web-search settings, model labels, context, and prompts documented so you know what changed.
    • Classify recurring signals as structural, conceptual, or entity patterns before editing content.
    • Use a working threshold to filter noise, then apply audience knowledge and factual review before acting.

    A single AI answer is not a position you can rank for

    Traditional rank tracking works because a search result has an ordered position that can be checked again. An AI response is generated probabilistically. Its wording, selections, order, and level of detail can change with the prompt, conversation context, model, retrieval method, and search setting.

    The variation can be substantial. Across one large prompt test, ChatGPT or Google AI had a less than 1% chance of returning the same brand list in two responses. That does not mean every topic will be equally unstable. It does mean that a single inclusion or omission is too fragile to support a content decision.

    Separate two questions that teams often mix together:

    • Visibility question: Did the model mention or cite your brand in this sample?
    • Pattern question: Which ideas, criteria, entities, and answer structures kept returning across the sample?

    The first question produces a volatile observation. The second can reveal a usable content opportunity. If renewal pricing appears in most answers about choosing a domain registrar, for example, you have evidence that the concept belongs in the decision journey. You still do not know that adding a renewal-pricing section will cause a citation. You do know that omitting the issue may leave the page incomplete for that cluster of questions.

    This distinction also changes how you report results. A sentence such as “we rank in ChatGPT” claims a stable position that may not exist. A defensible statement is narrower: your brand appeared in a stated share of a documented response sample, under specified test conditions. For content planning, the recurring concepts and associations in that sample are usually more actionable than the mention count alone.

    Build a response sample that can separate signal from noise

    Many abstract response tiles pass through a mesh filter, leaving repeated shapes grouped together while irregular fragments fade away.

    You do not need an expensive monitoring platform to begin. You do need a repeatable collection method. A spreadsheet is enough if every row records the conditions that could explain a different answer.

    1. Choose a small set of decision topics. Start with three commercially or editorially important topics. A topic should represent a decision or task your audience actually brings to an AI assistant, not just a keyword you want to rank for.
    2. Create three to five prompt variations per topic. Keep the underlying intent stable while changing the wording. A domain-registration cluster might include “How do I register a domain name?”, “How can I get a domain name?”, and “Where can I buy a domain?” Do not mix an introductory how-to prompt with a migration or troubleshooting prompt and call them one cluster.
    3. Define the test conditions. Select at least two model families. Decide whether web search will be enabled, disabled, or left to the model. If you test more than one search condition, analyze each as a separate segment. Use fresh or private sessions where possible so an earlier conversation does not silently alter the next response.
    4. Capture every response consistently. Record the prompt, displayed model or version, web-search status, date, full response, cited URLs, brand mentions, and any initial pattern labels. Preserve the complete answer; excerpts can hide section order and qualification.
    5. Repeat on a fixed cadence. Weekly collection is practical for many teams. Consistency matters more than running a large burst once and then changing the prompt set. Build toward 20 to 30 responses per prompt before drawing strong conclusions.

    Your tracking sheet can start with these columns:

    • Topic cluster
    • Exact prompt
    • Model and displayed version
    • Web search: enabled, disabled, or model-decided
    • Date
    • Full response
    • Citations or referenced URLs
    • Your brand mentioned: yes or no
    • Structural labels
    • Concept labels
    • Entity and association labels

    Do not pool unlike conditions without labeling them. A response produced with live web retrieval is not equivalent to one generated without it. A model update can also change the output even when your site and prompt remain untouched. Recording those conditions protects you from crediting your content for a change caused elsewhere.

    A useful working definition of a strong pattern is one that appears in at least 75% of the sampled outputs, across two models and multiple prompt variations. The threshold is a filter, not a law of AI behavior. It forces you to demand recurrence in more than one environment before calling an observation meaningful.

    Always retain the numerator and denominator. “Pricing transparency appeared in 9 of 12 responses” is auditable. “AI cares about transparent pricing” turns a bounded observation into an unsupported universal claim. If you work alone and cannot collect a full sample, you can flag patterns beginning around 60% as provisional, but keep them separate from patterns that clear the stronger threshold. A smaller workload should reduce your confidence, not disappear from the methodology.

    Read each response pattern at three different layers

    Three concentric transparent layers organize surface shapes, connected concepts, and generic objects around a central subject.

    Frequency alone does not tell you what to change. First classify what is recurring. Structural, conceptual, and entity patterns answer different editorial questions and lead to different actions.

    Pattern layerWhat you recordWhat it can changeCommon misreading
    StructuralSection order, lists, steps, comparisons, pros and cons, tables, and depthAnswer architecture and information sequenceCopying the model’s format as if it were a required template
    ConceptualRecurring criteria, risks, questions, features, and tradeoffsTopic coverage and explanation depthTreating every repeated phrase as a keyword to insert
    EntityBrands, products, tools, sources, categories, and feature associationsPositioning, evidence, comparisons, and partnership researchAssuming an omission proves a technical or reputation problem

    Structural patterns reveal the expected path through an answer

    Mark how each response is assembled. Does it begin with a definition, move into selection criteria, name tools, and end with implementation? Does it repeatedly use a comparison table? Does it frame the decision through advantages and disadvantages, or as a numbered procedure?

    If the sequence “definition > criteria > tools > implementation” persists across prompts and models, it is a clue that the topic is commonly synthesized as both an explanation and a decision process. Your page may need to support both. That does not require copying the sequence mechanically. A reader who already understands the category may need the criteria first, while a beginner may need a short definition before making sense of those criteria.

    Record the level of detail as well as the headings. A recurring step that receives several qualifications is more informative than a heading that appears but gets one sentence. The useful editorial question is not merely “Was this topic mentioned?” It is “What role did this topic play in helping the response reach a recommendation or action?”

    Conceptual patterns identify the criteria a page must handle

    Concepts are the recurring considerations inside the answer. For a domain-registrar decision, those may include initial and renewal pricing, customer support, privacy, email add-ons, security, bundles, and transfer procedures. A concept that returns across differently phrased prompts is more useful than an exact phrase repeated by one model.

    Turn each recurring concept into a question for the content, not an instruction to add a keyword. If renewal pricing is a strong pattern, ask:

    • Does the page distinguish the introductory price from the renewal price?
    • Can the reader locate that information without interpreting vague pricing language?
    • Does the comparison use equivalent billing periods and inclusions?
    • Are exceptions or conditions stated where they affect the decision?

    This approach improves usefulness even if the wording in future AI responses changes. It also prevents superficial optimization. Repeating “pricing transparency” does not make pricing transparent; showing the relevant terms clearly does.

    Entity patterns show how the category is being framed

    Entity analysis tracks more than which brands appear. Record which features, audiences, or use cases are attached to each entity, where the entity appears in the answer, and which pages are cited in support.

    Suppose a competitor repeatedly appears beside “simple transfers” while your brand appears beside “bundled services.” That pattern does not establish either claim as true. It does reveal the associations you should verify. Check whether your product documentation, comparison pages, and third-party coverage make the relevant capabilities explicit. If the association is inaccurate, the answer is not to imitate it. Clarify your actual positioning with evidence.

    An absent brand can have several explanations: model variability, an unfamiliar prompt, retrieval choices, weak category association, insufficient supporting content, or no factual fit for the recommendation. The response sample cannot diagnose the cause on its own. Use it to form a question, then inspect your content and real market position before choosing a remedy.

    Convert the pattern map into a content brief

    Once the sample is labeled, do not hand the raw answers to a writer and ask for an average version. That tends to reproduce generic phrasing and whatever biases already dominate the outputs. Convert the recurring signals into editorial requirements that leave room for expertise, original evidence, and a clear point of view.

    1. Name the reader’s decision. Write one sentence describing what the page must help the reader decide or complete. If your prompt variations contain different decisions, split the cluster before drafting.
    2. Write the direct answer first. State the useful answer in plain language before designing headings. This keeps a recurring AI structure from displacing the reader’s actual need.
    3. Select the structural pattern that supports that decision. Use a procedure for a task, a criteria-led structure for a purchase decision, or a comparison only when the underlying options are genuinely comparable.
    4. Translate strong concepts into coverage requirements. Record the observed frequency and the question each concept must answer. Specify required depth, such as a definition, caveat, example, or decision rule.
    5. Audit entity claims. List the brands, tools, features, and category relationships that require verification. Decide which claims need first-party documentation and which need credible independent support.
    6. Define what the page will not cover. Exclude concepts that belong to another intent or page. A recurring term is not permission to turn one focused answer into an unfocused topic warehouse.

    A practical response-pattern brief should contain these fields:

    • Reader and decision: who the page serves and what they must be able to do afterward.
    • Prompt cluster: the exact variations used to collect the sample.
    • Test conditions: models, versions, search settings, dates, and number of responses.
    • Direct answer: the page’s concise answer to the shared intent.
    • Strong structural patterns: recurring answer sequences and formats, with counts.
    • Strong conceptual patterns: required considerations, with counts and planned treatment.
    • Provisional patterns: useful leads that need more sampling or independent audience evidence.
    • Entity associations: repeated brand-feature or tool-use-case pairings that require verification.
    • Evidence plan: where facts, prices, limitations, and comparisons will be substantiated.
    • Exclusions: adjacent intents that belong on another page.

    Then run a simple editorial test on every proposed section. Can you trace it to a strong response pattern, direct audience evidence, necessary factual context, or the page’s stated decision? If not, remove it. For every strong concept, confirm that the draft answers the underlying question rather than merely using the model’s preferred vocabulary.

    The finished page should also add value that pattern analysis cannot supply. That may be a clearer decision rule, documented limitations, precise product information, a transparent comparison method, or an explanation of when the common recommendation does not apply. AI responses can expose the recurring frame. They should not set the ceiling for the content.

    Measure batches, not anecdotes, after you publish

    Preserve a baseline response batch before making a substantial update. After the revised page is available, repeat the same prompt set under comparable conditions. Keep the old and new batches separate, and document any model or search-mode change between them.

    Track a small group of interpretable measures:

    • Pattern persistence: which structural, conceptual, and entity patterns remain strong across later batches.
    • Concept coverage: whether the target page now answers each relevant strong concept accurately and at the required depth.
    • Brand mention rate: the number of sampled responses mentioning the brand divided by the total responses in that segment.
    • Association quality: whether the context around the brand is accurate, relevant, and aligned with its actual offer.
    • Citation behavior: whether the page is cited, what claim it supports, and whether the cited source is appropriate.
    • Page performance: whether conventional search visibility, qualified visits, engagement, and conversions move in a useful direction for the page’s purpose.

    Do not treat movement in a small AI sample as proof that your edit caused it. Models may draw from training data, live search, or a combination that is not obvious to the tester. Their behavior can also change after a new model release. A before-and-after batch gives you a better observation, not automatic causality.

    Use three decision rules to keep the program disciplined:

    • Act: A pattern clears your strong threshold across models and prompts, matches the reader’s decision, and can be addressed truthfully.
    • Investigate: A provisional pattern is strategically important but needs a larger sample, audience validation, or factual checking.
    • Ignore for now: A detail appears in isolated responses, depends on one model or wording, conflicts with reliable facts, or does not help the target reader.

    Watch for the feedback loop that makes every page look like an existing AI answer. Training-data bias, retrieval uncertainty, factual errors, and dominant category conventions can all recur. Repetition proves that a pattern exists in your sample; it does not prove that the pattern is correct, fair, current, or useful. Human review is the step that turns recurrence into an editorial decision.

    Choose one important prompt cluster for your next brief. Freeze the variations and test conditions, collect the first documented batch, and label the three pattern layers before changing the page. The question to carry into the edit is not “What did the AI say?” It is “What persisted, under which conditions, and what does our reader genuinely need from us?”

    References


  • Transforming AI Search: The Impact of 2026 Data Wars

    Transforming AI Search: The Impact of 2026 Data Wars

    The landscape of AI is rapidly shifting in 2026. I’ve noticed that AI models are losing their once shared data access, resulting in fragmented and less cohesive answers.

    This change is primarily due to the surge in platform-controlled data, which is significantly altering how visibility and search functions within AI systems. It’s intriguing to see how these developments are reshaping the way we interact with and trust AI-driven responses.


    Inspired by this post on HiGoodie Blog.


    crushpress.ai community screenshot
  • AI Advances in Healthcare: A Practical Evaluation Guide

    AI Advances in Healthcare: A Practical Evaluation Guide

    You’ve got a healthcare AI announcement in front of you and a decision to make: is this a meaningful advance, a promising demonstration, or a polished claim that has outrun its evidence? The model’s reputation won’t answer that question.

    You need to connect the technology to a care task, the care task to evidence, and the evidence to a controlled workflow. That framework works whether you’re evaluating a product, planning adoption, writing clinical content, or deciding which claims deserve visibility in search and AI-generated answers.

    The useful unit of progress is the care task

    The potential of healthcare AI extends from diagnostics to patient care. That range is also why broad statements about AI transforming healthcare tell you so little. Diagnostics, documentation, scheduling, patient education, and clinical decision support are different jobs with different users, failure modes, and consequences.

    Start by reducing every claimed advance to one task statement. It should identify five things:

    1. User: Who receives or acts on the output: a patient, clinician, administrator, researcher, or another system?
    2. Input: What information does the system receive, and where did that information come from?
    3. Output: Does it draft text, summarize a record, flag a case, rank options, predict an event, or initiate an action?
    4. Decision: What real decision could change because of the output?
    5. Failure consequence: What happens if the output is incomplete, late, biased, misleading, or wrong?

    For example, AI that summarizes clinician-authored encounter notes for clinician review is an assessable use case. AI that improves patient care is not. The first statement identifies a user, input, output, and review step. The second jumps directly to an outcome without showing the mechanism.

    Once the task is clear, ask what actually improved. An advance might reduce the time required for a task, make documentation more consistent, identify relevant cases, expand access, or reduce avoidable administrative work. Those are separate claims. Evidence for faster drafting does not establish better diagnosis, and stronger performance on a technical evaluation does not automatically establish better patient outcomes.

    This distinction should shape your language. If a system generates possibilities for a qualified professional to consider, say that. Don’t say it diagnoses. If it drafts an explanation that must be reviewed, call it a draft. Don’t describe it as patient guidance delivered independently. Precise verbs prevent a capability claim from quietly becoming a clinical claim.

    Separate assistance, recommendation, and action

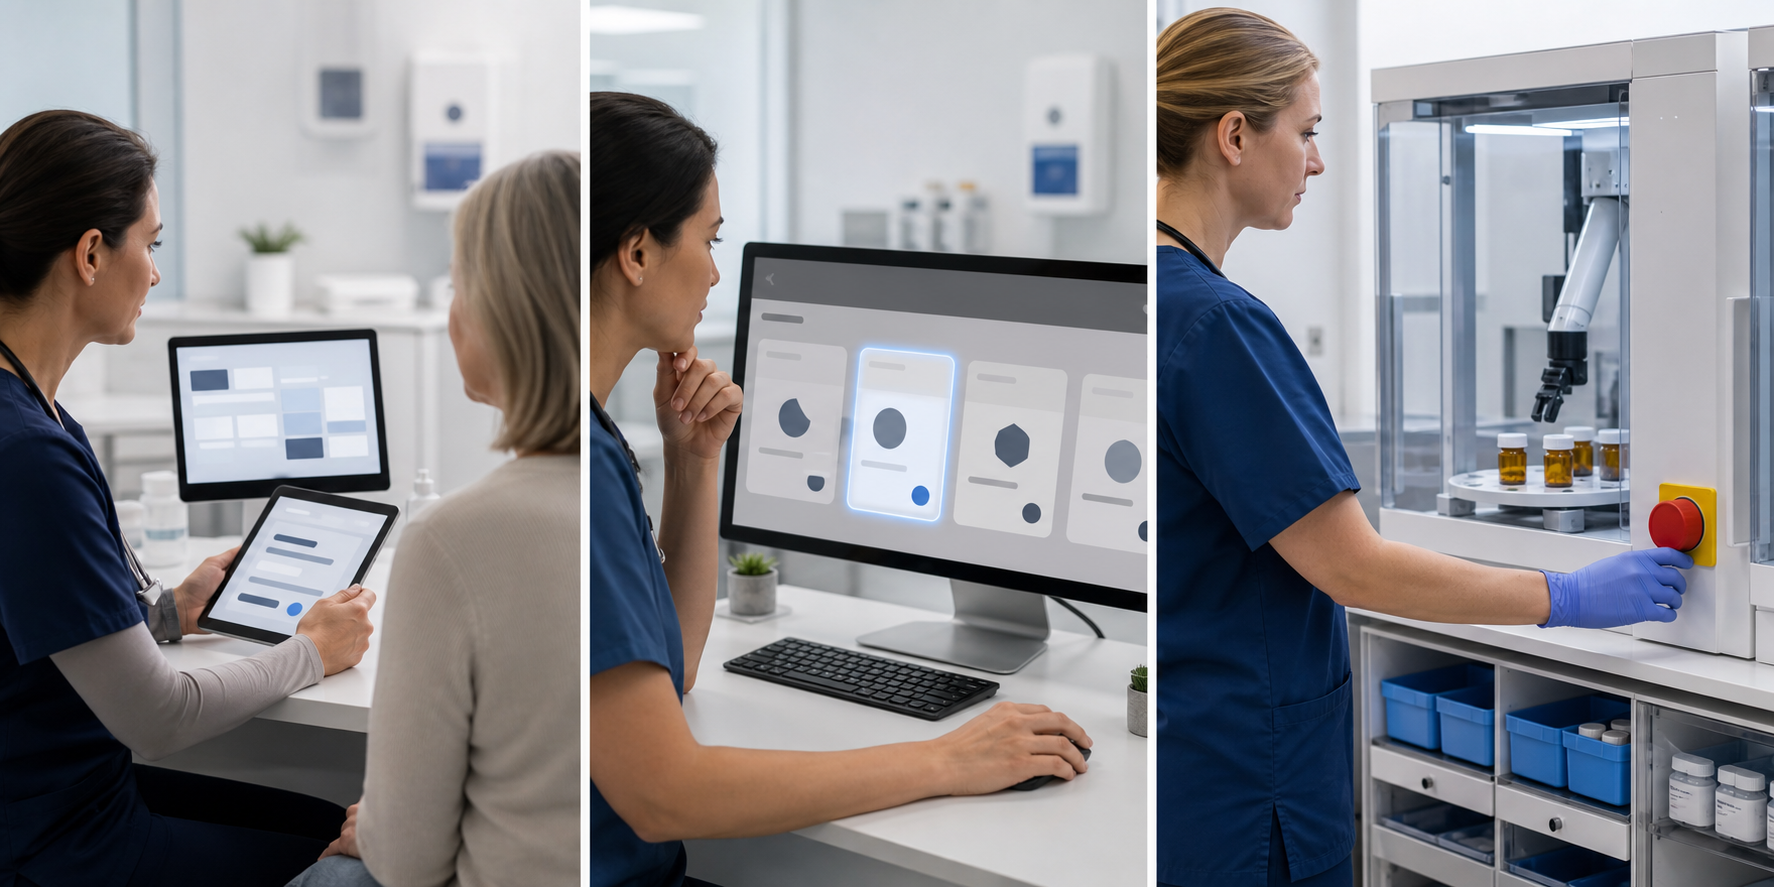
    A three-part clinical scene shows AI organizing information, presenting a recommendation, and operating supervised medication equipment.

    Healthcare AI systems can occupy very different positions in a workflow. A useful first classification is whether the system assists, recommends, or acts. This is an evaluation framework, not a regulatory classification, but it quickly exposes how much control the workflow needs.

    ModeWhat the AI doesHuman control to verifyClaim discipline
    AssistsDrafts, organizes, retrieves, or summarizes informationA person can inspect, edit, reject, and replace the outputDescribe the task support, not an unmeasured care outcome
    RecommendsFlags cases, ranks options, or proposes a next stepA qualified person evaluates the recommendation before it affects careName the intended user, decision, evaluation context, and known limits
    ActsTriggers, routes, schedules, or changes something in the workflowThe system has defined boundaries, escalation paths, and a way to stop or reverse inappropriate actionExplain exactly what is automated and where human oversight remains

    Risk does not begin only when AI acts autonomously. An incorrect summary can carry an old fact forward. A fluent explanation can make uncertain information sound settled. A recommendation can attract more trust than its evidence deserves. Human review is not a meaningful safeguard unless the reviewer has the information, authority, time, and interface needed to catch a problem.

    Inspect the control itself. A reviewable workflow should make the AI-generated material identifiable, preserve relevant input context, let the reviewer edit or reject the output, provide an escalation route, and record what was accepted or changed. A button labeled approve is not sufficient if the reviewer cannot see how the output was produced or cannot safely disagree with it.

    The closer an output gets to diagnosis, medication, treatment, or urgent-care decisions, the more explicit these boundaries must become. Patient-facing AI must not be presented as a substitute for a qualified healthcare professional. If an output conflicts with a clinician’s instructions or a medication label, the safe next step is to contact the appropriate clinician or pharmacist rather than act on the AI response. Situations involving possible immediate harm require established local emergency channels, not another chatbot prompt.

    Match every claim to its actual level of evidence

    A compelling output proves that the system produced a compelling output once. It does not establish reliability, clinical usefulness, or patient benefit. To avoid that leap, place evidence on a ladder and stop at the highest rung the evaluation genuinely supports.

    1. Capability evidence: The system can produce the intended kind of output in selected examples.
    2. Task validation: Its outputs have been evaluated against a predefined reference, process, or reviewer judgment for the stated task.
    3. Workflow validation: Intended users have used it under conditions that resemble the intended setting, including realistic inputs and handoffs.
    4. Outcome evidence: The evaluation measured the patient, clinical, or operational outcome named in the claim rather than using a technical metric as a substitute.
    5. Post-deployment evidence: Performance, failures, overrides, and changes continue to be monitored in actual use.

    Each rung answers a different question. Task validation may show that a system performs a bounded function well. Workflow validation asks whether people can use that function safely and effectively. Outcome evidence asks whether the claimed real-world result occurred. Post-deployment monitoring matters because users, data, interfaces, prompts, retrieval material, and models can change after an initial evaluation.

    When you inspect an evaluation, ask questions that reveal what the headline leaves out:

    • Which population, language, care setting, and task were represented?
    • What counted as success, and was that definition chosen before the results were reviewed?
    • What was the comparison: no tool, the existing workflow, another system, or an expert judgment?
    • Which failures occurred, who was affected, and which failures carried the greatest clinical consequence?
    • Were intended users evaluating the output, or was the system assessed only outside the care workflow?
    • What happens when information is missing, contradictory, unusually phrased, or outside the intended scope?
    • Which model, configuration, retrieval material, interface, and review process produced the result?

    If those details are unavailable, treat that absence as an evidence limit. Don’t fill the gap with a stronger adjective. Promising can be appropriate for an early capability. Validated needs a stated task and context. Effective should identify the outcome that improved. Safe is usually too broad to stand alone because safety depends on the user, setting, controls, and type of failure being considered.

    Keep the evaluated system distinct from the underlying model. A healthcare AI implementation may include a model, prompts, retrieval sources, interface rules, access controls, escalation policies, and human review. Changing any of those elements can change the behavior that users experience. Record them together, and retest material changes instead of assuming that an earlier result transfers automatically.

    Test the workflow around the model, not just the model

    A nurse, physician, informaticist, and human-factors specialist test an AI-supported process with a training mannequin in a clinical simulation room.

    A technically capable model can still fail as a healthcare system. The failure often appears at the handoff: the wrong information enters, the output reaches the wrong person, a warning arrives too late, or nobody owns the exception. Evaluate the full route from input to consequence.

    Use these six gates before treating a capability as deployment-ready:

    1. Context match: Confirm that the intended users, population, language, setting, and task resemble those represented in the evaluation.
    2. Input control: Define which data the system may receive, how missing or conflicting information is handled, and who is responsible for input quality. Never place identifiable patient information into an AI tool that your organization has not approved for that use.
    3. Output routing: Specify who sees the result, when they see it, what supporting context accompanies it, and whether it can alter a decision before review.
    4. Human factors: Verify that users can understand the output’s role, identify uncertainty, disagree with it, and complete the task without becoming dependent on it.
    5. Failure response: Decide in advance how the workflow handles false alarms, missed cases, unsupported statements, system outages, and outputs outside the intended scope.
    6. Change monitoring: Assign an owner to watch failures, overrides, complaints, model or configuration changes, and performance drift after launch.

    Run the workflow with difficult cases before routine ones create false confidence. Test missing context, ambiguous requests, contradictory records, out-of-scope questions, and attempts to bypass the intended process. The goal is not to prove that the system never fails. It is to learn whether failures are visible, containable, recoverable, and routed to someone able to respond.

    Define a stop condition as well as a success condition. A responsible deployment plan says who can pause the system, which events trigger review, what work continues without it, and how affected users are notified or corrected. If nobody has authority to stop an unsafe workflow, the oversight plan is incomplete.

    Publish healthcare AI claims that can survive scrutiny

    Healthcare AI content has to work for a person assessing risk and for search or answer systems extracting a concise statement. Both benefit from the same thing: explicit claims with their qualifications attached. A vague page cannot become trustworthy through optimization, and structured data cannot turn unsupported language into evidence.

    Put the central claim in a form that can stand on its own: the system, intended user, task, setting, oversight, and demonstrated evidence level should appear together. Put an important limitation in the same sentence or adjacent paragraph, not in a distant disclaimer that disappears when the sentence is quoted.

    A useful claim pattern is: [System] helps [intended user] perform [task] in [setting]. [Reviewer or control] checks [output] before [decision or action]. Current evidence establishes [capability, task performance, workflow performance, or outcome], while [important limitation] remains unresolved.

    Before publication, apply these editorial thresholds:

    • Can generate or summarize: Show that the capability was tested with the stated input and output. Don’t convert generation into an accuracy or outcome claim.
    • Supports review or decision-making: Identify the qualified user, the decision being supported, the review step, and the context in which the support was evaluated.
    • Improves a workflow: Name the measured operational result and the workflow used for comparison. Don’t use an isolated model score as proof of workflow improvement.
    • Improves diagnosis or patient outcomes: Reserve this language for evidence that measured the named diagnostic or patient outcome in the defined population and setting.
    • Is safe: Replace the blanket claim with the risks evaluated, controls used, limitations found, and context covered. No system is safe independently of its use.

    Keep vendor, model, product, and care provider roles separate. OpenAI, Google, and Anthropic may be relevant to the underlying AI landscape, but a familiar model developer’s name does not establish that a particular healthcare implementation is clinically validated. State who built the model, who configured the system, who operates the workflow, and who is responsible for clinical review whenever those roles differ.

    Your maintenance process matters as much as the launch page. Keep a claim inventory linking each public statement to its evidence, evaluated configuration, owner, review date, limitations, and correction route. When a model, prompt, retrieval source, interface, intended use, or oversight process changes, review the dependent claims. Otherwise, accurate content can become misleading while its publication date and search visibility remain unchanged.

    Use schema and other machine-readable markup to describe what the visible page actually says. Keep the evidence level, intended use, limitations, author or reviewer responsibility, and update history readable on the page itself. Machines may extract the markup, but people still need enough context to judge the claim.

    Key takeaways

    • Judge healthcare AI at the level of a defined care task, not the reputation of a model or developer.
    • Separate systems that assist, recommend, and act; each position requires a different degree of control and claim restraint.
    • Don’t treat a demonstration, task evaluation, workflow evaluation, outcome evaluation, and monitored deployment as interchangeable evidence.
    • Evaluate inputs, handoffs, human review, failure response, and change control alongside model performance.
    • Keep qualifications beside the claim so readers and AI answer systems do not receive a stronger statement than the evidence supports.
    • Do not present patient-facing AI as a replacement for qualified medical care, especially where diagnosis, medication, treatment, or urgent decisions are involved.

    For the next healthcare AI claim you encounter, write the five-part task statement before you draft a headline, approve a tool, or publish a page. Then label the highest evidence rung it has reached. If you cannot complete either step, hold the claim at capability level until the missing context is available.

    References

  • GPT-5.2 in ChatGPT: What Availability Actually Means

    GPT-5.2 in ChatGPT: What Availability Actually Means

    If you are trying to find GPT-5.2 in the ChatGPT app you use, a general statement that the model is “in ChatGPT” is not enough. It does not automatically tell you whether your account has access, whether every ChatGPT client supports it, or whether you can select it yourself.

    The defensible answer is narrower: GPT-5.2 has been confirmed in ChatGPT, and an external analytics platform is tracking ChatGPT responses generated with it. Universal availability across browser, desktop, mobile, account tiers, managed workspaces, and the API is not established by those facts. Here is how to separate what is known from what you still need to verify.

    What the current GPT-5.2 confirmation actually proves

    OpenAI announced GPT-5.2 on December 11. By December 14, Profound had begun tracking GPT-5.2 responses in ChatGPT across its products. The named products include Answer Engine Insights, Prompt Volumes, and Agent Analytics, with ChatGPT responses in those dashboards reflecting GPT-5.2.

    That confirms two useful points. GPT-5.2 was operating within ChatGPT, and organizations using Profound could analyze ChatGPT output associated with the model. It does not provide a platform-by-platform rollout matrix, plan eligibility, workspace controls, direct-selection details, or API availability.

    Availability questionAnswer you can defend
    Is GPT-5.2 operating in ChatGPT?Yes. Its use in ChatGPT responses is confirmed.
    Is GPT-5.2 reflected in Profound’s ChatGPT tracking?Yes, beginning December 14 across the named product suite.
    Can every ChatGPT account use it?Not confirmed.
    Is it available in every browser, desktop, and mobile client?Not confirmed.
    Can every eligible user select GPT-5.2 directly?Not confirmed.
    Does ChatGPT availability also confirm API access?No. API access is a separate question and is not established here.

    This distinction prevents a common reporting error: turning evidence of model activity into a claim of universal access. If you publish a rollout status, describe GPT-5.2 as confirmed in ChatGPT without adding unsupported claims about every client or account type.

    “Available” can describe four different states

    Four connected scenes depict a model existing on a service, reaching an account, connecting to devices, and being manually selected from interface tiles.

    Teams often use “available” as though it has one meaning. In practice, you need to identify which of four states you are discussing.

    1. Product presence: GPT-5.2 is operating somewhere within ChatGPT. This is the broadest confirmed claim.
    2. Account eligibility: a particular personal or managed account is permitted to use the model. Product presence does not prove this for your account.
    3. Client availability: the model is exposed in the specific browser, desktop, or mobile experience you are using. Access on one client does not demonstrate access on another.
    4. User selection: the interface explicitly lets you choose GPT-5.2. A system may route a request to a model without presenting that model as a selectable option.

    API availability belongs outside this sequence. ChatGPT and an API are different access surfaces, even when they use models with the same name. A confirmation about ChatGPT should not be copied into API documentation, procurement requirements, or production plans without separate evidence.

    The same discipline applies to third-party analytics. A dashboard can accurately identify the model used for the responses it tracks without proving that every consumer account can open ChatGPT and select that model. Tracking coverage and end-user entitlement answer different questions.

    How to verify GPT-5.2 on the ChatGPT platform you use

    Do not ask the model to identify itself and treat the answer as account metadata. A generated response is not an authoritative access record. Use product-controlled labels, account notices, workspace settings, and official release information instead.

    1. Define the exact claim you need to verify. Replace “Do we have GPT-5.2?” with a testable question such as “Can this account select GPT-5.2 in the desktop client?” or “Are responses in this managed workspace being routed to GPT-5.2?”
    2. Start a new conversation. Inspect the model name shown by the interface, any model-selection control, and any account-level release notice. An old conversation may not be useful evidence for the state of a newly enabled model.
    3. Check each client separately. Test the browser, desktop application, and mobile application that matter to your workflow. Record the date, account or workspace, client, application version where applicable, visible model label, and whether direct selection was offered.
    4. Classify the result precisely. Use “selectable” when the interface names GPT-5.2 as an option, “reported as routed” when a trusted system identifies the backend model, and “unconfirmed” when neither form of evidence is present. Do not translate “unconfirmed” into “unavailable.”
    5. Verify managed access at the workspace level. A result from a personal account does not establish the state of an organization-controlled workspace. Capture evidence from the account that will perform the actual work.
    6. Keep API verification separate. If your implementation depends on programmatic access, confirm the model name, permissions, and availability in the API environment itself before changing production workflows.

    A small access register is enough for most teams. Give it one row per account and client, with columns for the check date, workspace, platform, application version, visible model, selection status, and evidence. This turns an ambiguous rollout conversation into a list of claims that can be rechecked.

    AI visibility teams should treat December 14 as a measurement boundary

    A stream of abstract response records crosses a bright vertical boundary while two analysts observe the change at a transparent console.

    For SEO, AEO, and GEO teams, model availability is not only an access question. It is also a measurement variable. A model change can alter which brands, pages, facts, and citations appear in generated answers even when your content has not changed.

    Profound’s switch to GPT-5.2 tracking across Answer Engine Insights, Prompt Volumes, and Agent Analytics creates a practical boundary on December 14. If a visibility metric or answer pattern changes across that date, the model transition is one possible cause. It should not automatically be interpreted as a ranking gain, content loss, competitive move, or change in audience demand.

    • Annotate the transition date. Add December 14 to reports that include Profound’s tracked ChatGPT responses so later readers can see that the measurement environment changed.
    • Segment before and after the switch. Compare GPT-5.2 observations with other GPT-5.2 observations when making trend claims. A blended series can hide a model-driven break.
    • Rerun your baseline prompt set. Keep the prompts and other controlled inputs unchanged, then establish a fresh GPT-5.2 baseline for mentions, citations, answer position, sentiment, and factual accuracy.
    • Store raw responses with model metadata. A score without its answer, collection date, and model context is difficult to audit after a platform transition.
    • Delay causal claims. If the only known event near a metric change is the model cutover, label the result as a change in observed output. Do not claim that an optimization caused it until you have evidence that separates the two effects.
    • Do not infer consumer rollout coverage from tracking coverage. Dashboard-wide GPT-5.2 measurement tells you which model underlies the monitored responses, not which ChatGPT clients or account types expose it to every user.

    This is especially important for reports shared with clients or leadership. “ChatGPT visibility increased after GPT-5.2 entered the measurement environment” is supportable when the data shows it. “Our visibility strategy caused the increase” requires additional evidence.

    Key takeaways

    • GPT-5.2 is confirmed in ChatGPT, but universal access across every account, workspace, client, and plan is not confirmed.
    • Profound began tracking GPT-5.2 ChatGPT responses across its named product suite on December 14.
    • Product presence, account eligibility, client availability, direct selection, and API access are separate claims.
    • Verify access using interface and account metadata, not the model’s generated description of itself.
    • For AI visibility reporting, annotate December 14 and establish a new GPT-5.2 baseline before interpreting changes as SEO, AEO, or GEO performance.

    Your next step is simple: write down the exact account-and-client claim your work depends on, verify that claim in the relevant interface, and add the result to your access register. Until that check is complete, use “confirmed in ChatGPT” rather than “available everywhere.”

    References

  • How to Build an AI-Driven SEO Visibility Reporting System

    How to Build an AI-Driven SEO Visibility Reporting System

    You can have healthy rankings and still be unable to answer a basic leadership question: Are AI answer engines finding, trusting, and naming our brand? A conventional SEO dashboard cannot answer that on its own. It records search exposure and site visits, while AI visibility may occur inside a synthesized answer, through a third-party citation, or without a click.

    The fix is not another disconnected dashboard. You need a reporting system that connects search performance, AI answer visibility, the evidence supporting that visibility, and the business decision that follows. Here is how to build that system without letting an AI model become the judge of its own work.

    Design the scorecard around the decision it must support

    Start by writing a report brief before choosing metrics. If a metric cannot change an action, it belongs in a diagnostic view rather than the executive scorecard.

    • Decision: State what could change because of the report, such as which topic receives content work, digital PR, technical attention, or distribution.
    • Scope: Name the market, language, device, site section, topic, audience, and search or AI surface covered.
    • Evidence: Define which observations count. A ranking, a brand mention, a linked citation, and a qualified conversion are different events.
    • Trigger: Describe the condition that warrants action. Avoid vague rules such as improving visibility.
    • Owner: Assign the person or team that can act on each finding. A report without an owner is an archive.

    The scorecard should preserve four measurement layers. Keeping them separate prevents a familiar reporting error: treating exposure as traffic, traffic as trust, or a brand mention as revenue.

    Measurement layerWhat to recordQuestion it answersTypical action
    Search performanceClicks, impressions, average CTR, average position, query, page, country, device, search appearance, and date contextCan people discover and choose the site in search results?Investigate query demand, page relevance, result presentation, or technical access
    AI answer visibilityExact prompt, platform, model or visible version, date checked, brand inclusion, citation inclusion, cited URL, and answer contextDoes an AI response use, name, cite, or accurately represent the brand?Improve the answer asset, entity clarity, evidence, or external reinforcement
    Evidence footprintOwned pages, structured data, independent coverage, community discussion, and paid distribution connected to the topicWhat evidence could support discovery and inclusion?Fill a specific owned, earned, shared, or distribution gap
    Business effectQualified visits, conversions, leads, assisted outcomes, or another agreed business resultDid the visibility contribute to something the organization values?Continue, change, or stop the work based on business relevance

    Do not collapse these layers into a single AI visibility score too early. A page can be cited without the brand being named. A brand can be mentioned without a link. A response can name the brand inaccurately. Each outcome calls for a different intervention, so the underlying observations must remain available even if leadership receives a summarized score.

    Build a visibility ledger across paid, earned, shared, and owned media

    Four abstract paid, earned, shared, and owned media channels feed colored evidence tokens into a single central ledger.

    AI visibility does not respect the boundaries in your marketing org chart. Generative systems can draw contextual cues from brand sites, independent coverage, forums, and other public material. The paid, earned, shared, and owned media model gives you a practical way to map those cues without pretending every channel affects an AI answer in the same way.

    • Owned media supplies the answer asset you control. Record the canonical page, the question it answers, the named entities it defines, the supporting evidence it contains, and any relevant structured data. Schema can make meaning more explicit, but it does not guarantee inclusion in an AI response.
    • Earned media supplies independent corroboration. Record who mentioned the brand, which claim or capability the mention supports, the destination URL if one exists, and whether the context is current and relevant.
    • Shared media reveals how a topic is discussed in public communities. Record the recurring question, language people use, misconceptions, and whether the brand appears naturally in the discussion.
    • Paid media can distribute useful material and expose it to an audience, but that effect is indirect. An ad impression is not an AI citation and should never be reported as one.

    Fields that make the ledger diagnosable

    Create a row for each priority topic and audience question. Give every row enough context that another analyst could reproduce the observation without guessing.

    • Topic, audience, market, language, and customer question
    • Exact search query or AI prompt used for observation
    • Canonical owned page and the intended answer section
    • Relevant entity names, products, services, and approved descriptions
    • Supporting claims and where their evidence appears
    • Earned mentions, citing domains, and linked URLs
    • Shared discussions and the questions or terminology they reveal
    • Paid distribution connected to the asset, kept separate from visibility outcomes
    • AI platform, model or visible version, observation date, and response context
    • Brand named: yes or no
    • Brand cited or linked: yes or no, with the exact URL when present
    • Representation: accurate, incomplete, misleading, or unrelated
    • Next action, owner, and the condition for checking again

    Interpret mentions and citations as separate signals

    Brand namedBrand page citedWhat you observedWhat to inspect next
    YesYesThe response visibly associates the brand with a traceable brand-controlled resourceCheck whether the description is accurate, relevant, and supported by the cited page
    YesNoThe brand is included, but the response does not expose a brand-controlled citationInspect third-party citations, mention context, and whether an owned answer asset is clear enough
    NoYesBrand content may inform the answer without prominent brand attribution in the wordingCheck titles, publisher identity, entity naming, and the cited section
    NoNoThe brand was absent from this recorded responseCompare relevant cited domains, content coverage, corroboration, and the exact prompt context

    An absence is an observation, not a universal verdict. Preserve the exact prompt, platform, model context, date, and response. When any of those change, you are no longer running the same check. This is why an undocumented screenshot is weak reporting evidence: it cannot tell you whether visibility changed or the test changed.

    Use Search Console AI configuration as an analyst, not an oracle

    Google has been testing an experimental Search Console feature that converts a plain-language request into settings for the Search results Performance report. It can select metrics such as clicks, impressions, average CTR, and average position, then apply filters or comparisons involving queries, pages, countries, devices, search appearance, and dates. Availability is limited during the experimental rollout, so your reporting process should still work when the interface is configured manually.

    Write requests that expose the intended configuration

    A useful configuration request names the metrics, scope, segment, period, comparison, and report surface. Use this pattern:

    Show [metrics] for [query or page scope], filtered by [country, device, or search appearance], during [period], compared with [baseline period or segment].

    For example, you could request these views:

    • Show clicks, impressions, average CTR, and average position for queries containing the named product category, comparing mobile and desktop.
    • Compare clicks and impressions for a specified site directory across the chosen periods, filtered to the target country.
    • Show query performance for a named landing page during the selected period, then compare it with the relevant baseline.

    The language can be natural, but the analytical intent cannot be fuzzy. A request to show pages losing visibility leaves important questions unanswered: Which metric defines visibility? Against which period? In which country and device context? For all pages or a specific section? Resolve those choices before asking AI to configure anything.

    Validate the generated view before reading the trend

    • Confirm that the selected metrics match the question. Impressions, clicks, CTR, and position describe different parts of search performance.
    • Read every query and page filter literally. Check whether the configuration includes, excludes, contains, or exactly matches the intended value.
    • Confirm country, device, search appearance, and date settings rather than assuming the prompt was interpreted correctly.
    • Check that comparison periods or segments are appropriate for the decision. A valid interface configuration can still represent a weak comparison.
    • Record the final settings with the finding. The reproducible filter state is part of the evidence.
    • For a consequential decision, recreate the important view manually or have another analyst verify the configuration.

    The experimental capability is limited to configuration in the Search results Performance report. It does not sort tables or export the data, and it is not available for Discover or News reports. Most importantly, a configured view is not a diagnosis. The interface may help you reach the right slice of data faster, but you still have to determine what the slice means.

    Make the workflow resilient to model changes

    Interchangeable translucent AI modules connect to a stable workflow while a robotic mechanism replaces one module without interrupting the glowing data flow.

    A newer model should be treated as a changed dependency, not an automatic quality upgrade. In one SEO benchmark, Claude Opus 4.5, Gemini 3 Pro, and ChatGPT-5.1 Thinking produced a reported 9% decline in SEO accuracy. That result comes from a particular benchmark rather than a universal test of every SEO task, but it is enough to challenge the assumption that a model switch can be made without validation.

    The durable unit is the workflow, not the prompt. A standalone instruction such as analyze our SEO performance forces the model to invent definitions, choose evidence, infer priorities, and format the result at once. Split those responsibilities into controlled stages.

    1. Fix the context. Store the organization, site, canonical entity names, products, markets, languages, audiences, business goals, exclusions, and metric definitions outside the ad hoc prompt.
    2. Validate the input. Define required fields, accepted values, date context, missing-value treatment, and the origin of each data field before analysis begins.
    3. Constrain the task. Ask the model to configure a report, classify an observation, compare defined fields, or draft an explanation. Do not combine every task into an open-ended request.
    4. Keep calculations controlled. Let the reporting system produce totals, rates, and comparisons, then give those results to the model for explanation. Do not ask the model to reconstruct critical metrics from loosely pasted fragments.
    5. Require a structured output. Separate observation, supporting evidence, interpretation, proposed action, confidence, and unresolved questions.
    6. Add a human review gate. An analyst should approve filters, factual claims, citations, causal interpretations, and recommendations before the report is distributed.
    7. Regression-test changes. Re-run a stable collection of known SEO cases when the model, prompt, context block, tool, or output schema changes. Compare the kinds of errors, not merely how polished the prose sounds.

    Version the context block, prompt, model, input schema, and output schema together. If the result changes, that record lets you identify whether the underlying market moved, the evidence changed, or the measurement machinery changed.

    Use confidence labels that reveal the reasoning boundary

    • Observed: Directly visible in the recorded search data or AI response.
    • Derived: Calculated from defined fields using a documented rule.
    • Inferred: A plausible explanation supported by observations but not proven by them.
    • Unverified: A claim that requires another check before it can guide action.

    This vocabulary stops fluent model output from quietly turning correlation into cause. Require every inferred explanation to point back to the observations supporting it, and allow the report to say that the cause is not yet known.

    Turn every reporting cycle into an operating decision

    The useful endpoint is not a chart. It is a documented decision with an owner and a condition for reassessment. Run the same operating loop each time so that changes in process do not masquerade as changes in performance.

    1. Freeze the measurement context. Save the prompt set, Search Console configuration, market and device scope, AI platform, model context, and observation date.
    2. Collect the layers separately. Record search performance, AI mentions, citations, answer accuracy, evidence footprint, and business effects without merging them prematurely.
    3. Compare like with like. Identify which layer moved while holding the relevant measurement context stable.
    4. Diagnose the gap. Use query and page segments for search changes, response records for AI changes, and the paid-earned-shared-owned ledger for evidence gaps.
    5. Choose the smallest action that tests the diagnosis. Name the page, claim, entity, citation gap, distribution task, or configuration that will change.
    6. Assign an owner and a reassessment condition. State what evidence would support, weaken, or disprove the working explanation.
    Search performanceAI visibilityWorking interpretationNext check
    WeakerWeakerA broader demand, access, relevance, competitive, or evidence problem may be affecting both layersSegment queries and pages, confirm technical access, and inspect which domains or resources now appear
    SteadyWeakerThe change may sit in the AI surface, recorded test context, cited evidence, or external brand footprint rather than conventional rankingsRe-run the fixed prompt set, compare model context, inspect citations, and review earned and shared evidence
    StrongerSteadySearch gains are not yet visible in the tracked AI answersInspect answer clarity, entity naming, supporting claims, structured data relevance, and independent corroboration
    SteadyStrongerThe brand is gaining answer visibility without a corresponding search liftSeparate linked citations from unlinked mentions, verify representation, and check business effects before declaring success
    StrongerStrongerVisibility improved across both discovery paths, but attribution still needs evidenceIdentify which content, technical, earned, shared, or distribution changes preceded the movement and test the explanation

    Key takeaways

    • Measure search performance, AI answer visibility, evidence, and business effects as connected but distinct layers.
    • Keep brand mentions, links, citations, accuracy, and conversions separate in the underlying data.
    • Use paid, earned, shared, and owned media to diagnose why evidence is strong or weak around a topic.
    • Inspect every AI-generated Search Console filter before interpreting the resulting trend.
    • Version prompts, context, schemas, models, and test conditions so reporting changes remain explainable.
    • Treat AI observations as reproducible records and causal explanations as hypotheses that require validation.

    Start the next reporting cycle with a priority topic, a fixed prompt set, a reproducible Search Console view, and a visibility-ledger row. Follow the evidence until you can assign a specific action. Once that loop works reliably, expand it across more topics instead of scaling an unverified score.

    References

  • Gemini 3 Expands Globally: An AI Mode SEO Action Plan

    Gemini 3 Expands Globally: An AI Mode SEO Action Plan

    If you manage search visibility across countries, Gemini 3’s expansion creates an urgent-looking question: do you need to rework your international content now? The useful answer is narrower. You need to identify where the experience is actually available, which valuable queries activate it, and whether your brand appears in a way that supports a business outcome.

    Gemini 3 has expanded through AI Mode to nearly 120 countries and territories for English searches. That substantially enlarges the testing surface, but it doesn’t prove uniform access, visibility, citations, traffic, or conversions. Treat this as a measured market expansion, not a signal to rewrite every page.

    Separate availability from actual search visibility

    An abstract world map with many illuminated regions but search-result panels appearing over only a few locations.

    The headline number is easy to misread. Geographic availability is only the first condition. The current Gemini 3 expansion in AI Mode applies to Google AI Pro and Ultra subscribers, and the stated language scope is English. A country can therefore be included while a particular user, account, language, or query remains outside the experience you are trying to evaluate.

    Query routing adds another distinction. Google is automatically using Gemini 3 for selected AI Mode queries. Selected queries does not mean every query. A test that produces an ordinary result or a different AI Mode presentation cannot establish that an entire market lacks access.

    The presentation layer matters as well. Gemini 3 can support dynamic visual layouts and interactive tools generated in response to a query. That expands what an AI search result may do, but it does not create a new ranking guarantee. A generated interface can use, summarize, cite, link to, or omit a site. Those outcomes need to be observed separately.

    Nano Banana Pro is a related but distinct rollout. Its generative imagery capability is reaching AI Mode in additional English-speaking countries for Pro and Ultra subscribers. Do not interpret access to an image-generation model as evidence that conventional image-search rankings changed or that adding AI-generated images will improve AI visibility. The expansion concerns what eligible users can generate inside AI Mode, not a documented image SEO signal.

    Build a market-by-query map before changing content

    A global average will hide the decisions you need to make. Build a working matrix in which every row represents one target market and one exact query. This forces your team to distinguish confirmed observations from assumptions inherited from another country.

    • Market: Record the country or territory where the test was performed. Do not label a region as covered merely because one neighboring country is covered.
    • Search language: Record the language of the query and interface. An English page does not prove that the same experience is available for equivalent non-English searches.
    • Account eligibility: Note whether the tester is using an eligible Google AI Pro or Ultra account. Keep tests from ineligible accounts in a separate column rather than mixing them into the same result set.
    • Exact query: Save the wording, not just a broad topic label. Use a stable query set so that later observations remain comparable.
    • Query purpose: Classify the task as discovery, comparison, selection, setup, troubleshooting, or another intent that matches your customer journey.
    • Observed experience: Record whether AI Mode appeared and whether the output included a generated layout, an interactive element, a conventional answer, or no relevant AI experience.
    • Brand and source presence: Capture whether your organization, product, page, or domain appeared. Distinguish a plain mention from a visible citation or a clickable link.
    • Business importance: Mark whether the query can influence a meaningful decision. A fascinating AI result for a low-value query should not outrank work on a high-intent query.

    Start with queries that already matter to the business. Include unbranded questions, comparison searches, branded searches, and tasks that existing customers need to complete. If you test only your company name, you will learn little about whether Gemini 3 can discover and represent you when the user has not chosen a provider.

    Record the date and the testing account with every observation. A single result is a snapshot, not a market-wide conclusion. If a query does not produce the expected experience, label the result as not observed under the tested conditions. That wording preserves the difference between a failed observation and verified unavailability.

    Prepare pages for answers assembled into dynamic interfaces

    Dynamic layouts and interactive tools raise the value of content that exposes its meaning cleanly. Your page should make the answer, scope, entities, choices, and next action easy to identify without requiring a reader or system to reconcile contradictions across several sections.

    Audit each priority page around the task it is supposed to complete:

    • Answer the primary question early. Put a direct, self-contained answer near the relevant heading. Do not make the visitor cross an extended introduction before learning whether the page addresses the query.
    • Name the scope of every important claim. Include the relevant product, plan, country, language, audience, or version where it changes the answer. A statement that is correct only in one market should not read like a universal rule.
    • Turn processes into executable steps. State prerequisites before actions, preserve the correct order, and identify the condition that tells the reader a step is complete.
    • Use stable comparison criteria. When comparing options, give each option the same fields. Switching criteria between rows or sections makes the comparison difficult for people and machines to interpret.
    • Keep decisive facts in visible page content. Do not place an important qualification only in an image, script-driven widget, tooltip, or structured-data field.
    • Resolve entity ambiguity. Use consistent names for the organization, product, service, author, and location. Explain acronyms and distinguish similarly named products.
    • Align structured data with the page. Choose the most specific applicable Schema.org type, represent only content that users can see, and keep names, URLs, dates, offers, and other properties consistent with the rendered page. JSON-LD is an alignment layer, not a substitute for a clear answer.
    • Support visuals with context. Use descriptive alternative text where appropriate, meaningful captions, and surrounding copy that explains what the visual demonstrates. Do this for accessibility and comprehension, not because Nano Banana Pro creates an undocumented image-ranking shortcut.

    This is not a case for a site-wide model-specific rewrite. Pages become fragile when they are tuned to imitate the tone of a current AI answer. The durable work is to remove ambiguity, make claims appropriately scoped, expose useful relationships, and help the visitor finish the task. Those improvements remain valuable even when the interface changes.

    Measure four layers instead of chasing one visibility score

    Four transparent layers display abstract global access, answer panels, interaction paths, and outcome markers.

    An AI visibility score can compress several different events into one number. That makes reporting simple but diagnosis difficult. Measure the rollout as a sequence of four layers:

    LayerQuestionEvidence to record
    AccessCan an eligible user reach the relevant AI Mode experience in this market and language?Country or territory, query language, account tier, interface observed, and test date
    ActivationWhat happens for the exact query under the tested conditions?Saved query, output type, generated layout or tool, and any model identification shown by the interface
    PresenceDoes your organization or content participate in the answer?Brand mention, product mention, citation, clickable link, linked page, and accuracy of representation
    OutcomeDoes that presence help the user or the business?Relevant referral and landing-page signals, engagement, conversions, assisted behavior, and country-level trends available in your own measurement stack

    Keep these layers separate in the dashboard. If access is confirmed but your brand is absent, investigate content coverage, entity clarity, authority signals, and page eligibility. If the brand is mentioned but linked incorrectly, inspect canonical destinations, internal consistency, outdated pages, and ambiguous product naming. If a correct link is present but measurable traffic remains low, the generated answer may satisfy the immediate need, the link may be inconspicuous, or your existing analytics may not expose the journey clearly. Do not declare a cause until the evidence distinguishes among those possibilities.

    Establish a baseline before publishing changes. Log what changed on the page, which query cluster it was intended to help, and which markets were eligible for evaluation. Change a coherent element at a time where practical. Rewriting the answer, altering internal links, replacing structured data, and redesigning the page simultaneously may improve performance, but it will not tell you which change mattered.

    Use the signals your analytics stack actually exposes. Do not manufacture precision by assigning unattributed sessions to AI Mode or by treating every country-level fluctuation as evidence of Gemini 3. Where direct attribution is unavailable, report the observation, the correlated business trend, and the uncertainty as separate fields.

    Key takeaways

    • Gemini 3’s AI Mode expansion covers nearly 120 countries and territories for English searches, with current access tied to Google AI Pro and Ultra subscriptions.
    • Geographic availability does not guarantee that every query activates Gemini 3 or that your content will be mentioned, cited, linked, or visited.
    • A market-by-query matrix is the fastest way to separate verified access from assumptions and to direct optimization toward commercially meaningful searches.
    • Prepare content for generated experiences by clarifying answers, scope, entities, comparisons, steps, and structured data rather than imitating a model’s writing style.
    • Measure access, activation, presence, and business outcome as separate layers so that a weak result points to a specific problem.

    Begin with your highest-priority English-language market and a tightly defined query cluster. Verify eligible access, capture what users can actually see, audit the pages that should answer those searches, and preserve a baseline before editing. Expand the program to more markets only after that loop produces evidence you can interpret.

    References

  • Gemini 3 in Google AI Mode: A Practical SEO Playbook

    Gemini 3 in Google AI Mode: A Practical SEO Playbook

    If your search visibility depends on Google, it is tempting to treat Gemini 3 as another ranking update and start rewriting pages immediately. That skips the most important distinction: the confirmed rollout placed Gemini 3 inside AI Mode’s answer-generation workflow for selected queries, not across every Google result.

    Your job is to separate access, model routing, source selection, and content representation. Once you measure those as different things, you can improve the pages that support complex answers without chasing an undocumented Gemini-specific trick.

    The initial rollout was narrower than the headline

    Google introduced Gemini 3 on November 18, 2025. Its initial Search deployment used Gemini 3 Pro for some AI Mode responses available to Google AI Pro and Ultra subscribers in the United States. Those access details describe the rollout at that point in time, not a permanent availability policy.

    The product boundary matters. Early messaging mentioned AI Overviews, but the clarified scope focused on AI Mode. If an AI Overview changes, that change should not automatically be attributed to Gemini 3. AI Mode and AI Overviews may look related to a user, but they are not interchangeable measurement surfaces.

    Eligible subscribers could identify access through an option in the AI Mode tab’s model menu. Even that signal needs careful interpretation: seeing the option confirms that the account can access the feature; it does not prove that every default response was automatically routed through Gemini 3 Pro.

    Before reacting to an apparent visibility change, classify what you actually observed:

    • Access: Was the test conducted in the United States with an eligible Google AI Pro or Ultra account, and was the Gemini option visible?
    • Surface: Did the response appear in AI Mode rather than an AI Overview or conventional results page?
    • Routing: Do you have an interface signal showing the selected model, or are you inferring the model from the response’s appearance?
    • Representation: Was your domain cited, merely mentioned, omitted, or represented inaccurately?
    • Performance: Did the response actually help the user complete the task, or did it only look more elaborate?

    This classification prevents two common errors. A non-eligible account cannot establish that a page is excluded from Gemini 3 answers. A visually rich response cannot, by itself, establish which model produced it.

    Automatic routing makes query complexity part of the test

    A glowing input reaches a routing hub, dividing into a short path and a denser branching path before forming a response.

    Google implemented automatic model routing that directs the most challenging AI Mode questions to Gemini 3 Pro. That changes how an SEO or GEO team should design a visibility test. Testing one short keyword is not equivalent to testing the complex task a prospective customer is trying to complete.

    Google did not provide a public scoring rubric for what counts as challenging in this rollout. Treat complexity as an experimental variable, not as a known trigger. You can vary constraints, comparisons, dependencies, and requested output while holding the underlying intent steady.

    Build a prompt ladder around one real decision

    Start with a decision that matters to your audience, then express it in four forms:

    1. Direct: Ask the shortest useful version of the question.
    2. Constrained: Add the user’s situation, requirements, exclusions, or operating limits.
    3. Comparative: Ask for alternatives to be evaluated against named dimensions.
    4. Multi-step: Ask for a recommendation, implementation sequence, risks, and a way to verify the result.

    For example, a direct prompt might ask how to structure a certain kind of page. Its constrained form could specify the business model, audience, and technical limitation. The comparative form could ask how two architectures differ in maintenance, discoverability, and conversion intent. The multi-step form could ask for a choice, migration order, failure conditions, and validation checklist.

    Do not create four near-duplicate pages to match those four prompts. Build one authoritative resource that contains the answer components each variation needs: a clear decision rule, applicable conditions, meaningful comparison criteria, ordered implementation steps, and explicit exceptions.

    When you test the ladder, compare more than whether your domain appears. Notice which claims were used, which page supplied them, whether qualifiers survived the synthesis, and whether citations changed as the task became more demanding. That tells you whether your content supports a complex decision or merely matches a short phrase.

    Build pages that can be assembled into a reliable answer

    Modular page components detach from a structured web page and fit together inside a transparent answer container.

    A model upgrade does not create a new excuse for vague content. Complex answers still need usable components. If a page hides its conclusion inside a long introduction, mixes several entities under ambiguous pronouns, or separates a recommendation from its limitations, an answer system has more opportunities to lose the meaning.

    Audit the page at the level of claims

    1. State the decision rule early. Tell the reader when an option fits, when it does not, and what factor changes the answer. Do not make the model infer your conclusion from a list of features.
    2. Give each section one job. Separate definitions, comparisons, procedures, evidence, limitations, and examples under descriptive headings. A heading such as When this approach fails is more useful than More information.
    3. Keep qualifiers beside the claim. If advice applies only to a platform, plan, region, page type, or version, put that condition in the same paragraph or list item. A distant disclaimer is easy to detach from the recommendation.
    4. Use stable entity names. Introduce the full product, organization, feature, or standard name before relying on abbreviations. Distinguish similarly named entities instead of assuming context will resolve them.
    5. Publish attributable information. First-party specifications, policies, definitions, methods, and documented observations give an answer system something specific to cite. Generic summaries are easier to replace with another generic summary.
    6. Match format to the task. Use ordered steps for sequences, aligned criteria for comparisons, and short lists for requirements. Do not force genuinely different facts into a paragraph for stylistic variety.
    7. Maintain the answer, not just the publication date. When a fact changes, update the visible claim, its qualifier, relevant internal links, and any structured data that repeats it.

    Use JSON-LD to remove ambiguity, not to force routing

    Nothing in the confirmed Gemini 3 rollout establishes a schema type or property that forces a query to use Gemini 3 Pro, guarantees an AI Mode citation, or bypasses source selection. Treat any such promise as unsupported unless Google documents it.

    JSON-LD is still useful when it accurately identifies the page and the entities described on it. Check that:

    • The structured-data type represents the page’s actual subject and purpose.
    • Names, URLs, dates, authorship, identifiers, and relationships agree with the visible page.
    • Every substantive claim in the markup is also available to the reader.
    • Deprecated, copied, or template-generated properties are removed rather than left to conflict with current content.
    • The deployed markup is validated after publishing, not merely inside the CMS editor.

    Think of structured data as a consistency layer. It can clarify identity and relationships; it cannot compensate for an unsupported recommendation, missing evidence, or contradictory visible text.

    Measure citation and representation without guessing the model

    Automatic routing means a single screenshot cannot answer whether your visibility improved. The query wording, task complexity, account eligibility, selected Search surface, and model access all belong in the test record. Without that context, a before-and-after comparison can turn normal test differences into a false algorithm narrative.

    Use a repeatable protocol:

    1. Choose one priority journey. Define the decision or task, the pages that should support it, and the prompt ladder you will use.
    2. Verify the environment. Record the country, subscription tier, Search surface, and whether the Gemini option is present in AI Mode. If the account is not eligible, label the run as a general AI Mode observation rather than a Gemini 3 test.
    3. Preserve the exact input and output. Save the prompt verbatim, the response, visible citations, linked pages, model selection evidence, and test date.
    4. Classify your domain’s role. Use consistent states such as cited accurately, cited incompletely, mentioned without citation, absent, or represented incorrectly.
    5. Map omissions to page evidence. Identify the missing claim, qualifier, comparison dimension, or procedural step. Do not respond to an omission by adding unrelated length.
    6. Change one content layer at a time. A focused revision makes it easier to connect a later difference to clearer content, updated evidence, improved structure, or corrected markup.
    7. Retest the same ladder. Keep at least one unchanged prompt as a control so that every observed difference is not credited to the edit.

    Report metrics with explicit denominators

    A useful AI Mode dashboard can remain simple. Track the number of eligible prompts tested, the number that cite your domain, the number that represent the key claim correctly, and the number that complete the intended task. Keep these counts separate from conventional rankings and organic clicks; they describe different observations.

    • Citation coverage: Eligible tested prompts containing a link to your domain divided by eligible prompts tested.
    • Representation accuracy: Cited or mentioned responses classified as correct, incomplete, or incorrect against the maintained page.
    • Task coverage: The required decision factors or procedural steps that appear in the answer.
    • Source displacement: Cases where another page supplies a claim your own page is better positioned to substantiate.
    • Complexity gap: Differences between the direct, constrained, comparative, and multi-step versions of the same intent.

    These are operational measurements, not proof that a content edit caused a model to cite you. Preserve that distinction in client and executive reporting. It is better to show a small, reproducible observation than a large claim built on an unknown route.

    Key takeaways

    • Gemini 3’s confirmed initial Search rollout covered some AI Mode responses for Google AI Pro and Ultra subscribers in the United States, not every Google search.
    • The clarified rollout scope focused on AI Mode rather than AI Overviews, so the two surfaces should be tested and reported separately.
    • Automatic routing makes prompt complexity an important test variable; one short keyword cannot represent a multi-constraint user decision.
    • No documented schema shortcut forces Gemini 3 routing or guarantees a citation. JSON-LD should accurately reinforce visible entities, facts, and relationships.
    • Measure account eligibility, prompt wording, citations, claim accuracy, and task coverage before attributing a visibility change to the model.

    Start with one commercially important user journey. Build its direct, constrained, comparative, and multi-step prompts; test them in a documented eligible environment; then fix the first page where an essential answer component is missing or ambiguous. That gives you a defensible baseline for later Gemini rollouts and a better resource for the person making the decision now.

    References